Search Results: "xam"

24 August 2026

Vincent Bernat: A non-interactive tour of the spanning tree protocol

Imagine you rent office space for a three-day event. You quickly set up a few Ethernet switches and tape some cables on the floor to get everyone online. Unfortunately, Stan, your clumsiest coworker, kicks out a cable every time he gets up for coffee. Spare cables would fix that, but a loop turns into a broadcast storm: Ethernet packets multiply until nothing else gets through. That s where the spanning tree protocol comes in: it blocks just enough of the spare cables to leave a loop-free tree, and rebuilds it in a second each time Stan strikes again.1
This content is also available as a text version, with interactive demos that run a real implementation directly in your browser!
This video is an experiment.2 Honestly, except for Radia Perlman reading her poem,3 you should read the original article instead. It presents the same content, but you can play with the interactive examples, which are the main contribution. On the other hand, if you happen to like the video, be sure to tell me in the comments!

  1. The sprites for Stan and Blobby come from Craftpix. The background music is Sonatina No. 2 in G Major III. Allegro by Aaron Dunn.
  2. I thought automated tools would produce this video in a couple of hours. In the end, it was another rabbit hole and it took me more than 12.
  3. The audio was extracted from a Youtube video and cleaned up.

23 August 2026

Sergio Cipriano: Two Debian Days in one week

Two Debian Days in one week The Debian Project was officially founded by Ian Murdock on August 16, 1993. The Debian community celebrates its birthday, Debian Day, on or around this date every year. This year, I had the chance to attend two of them: one in Jo o Pessoa, Para ba, and another in Bras lia, the capital of Brazil.

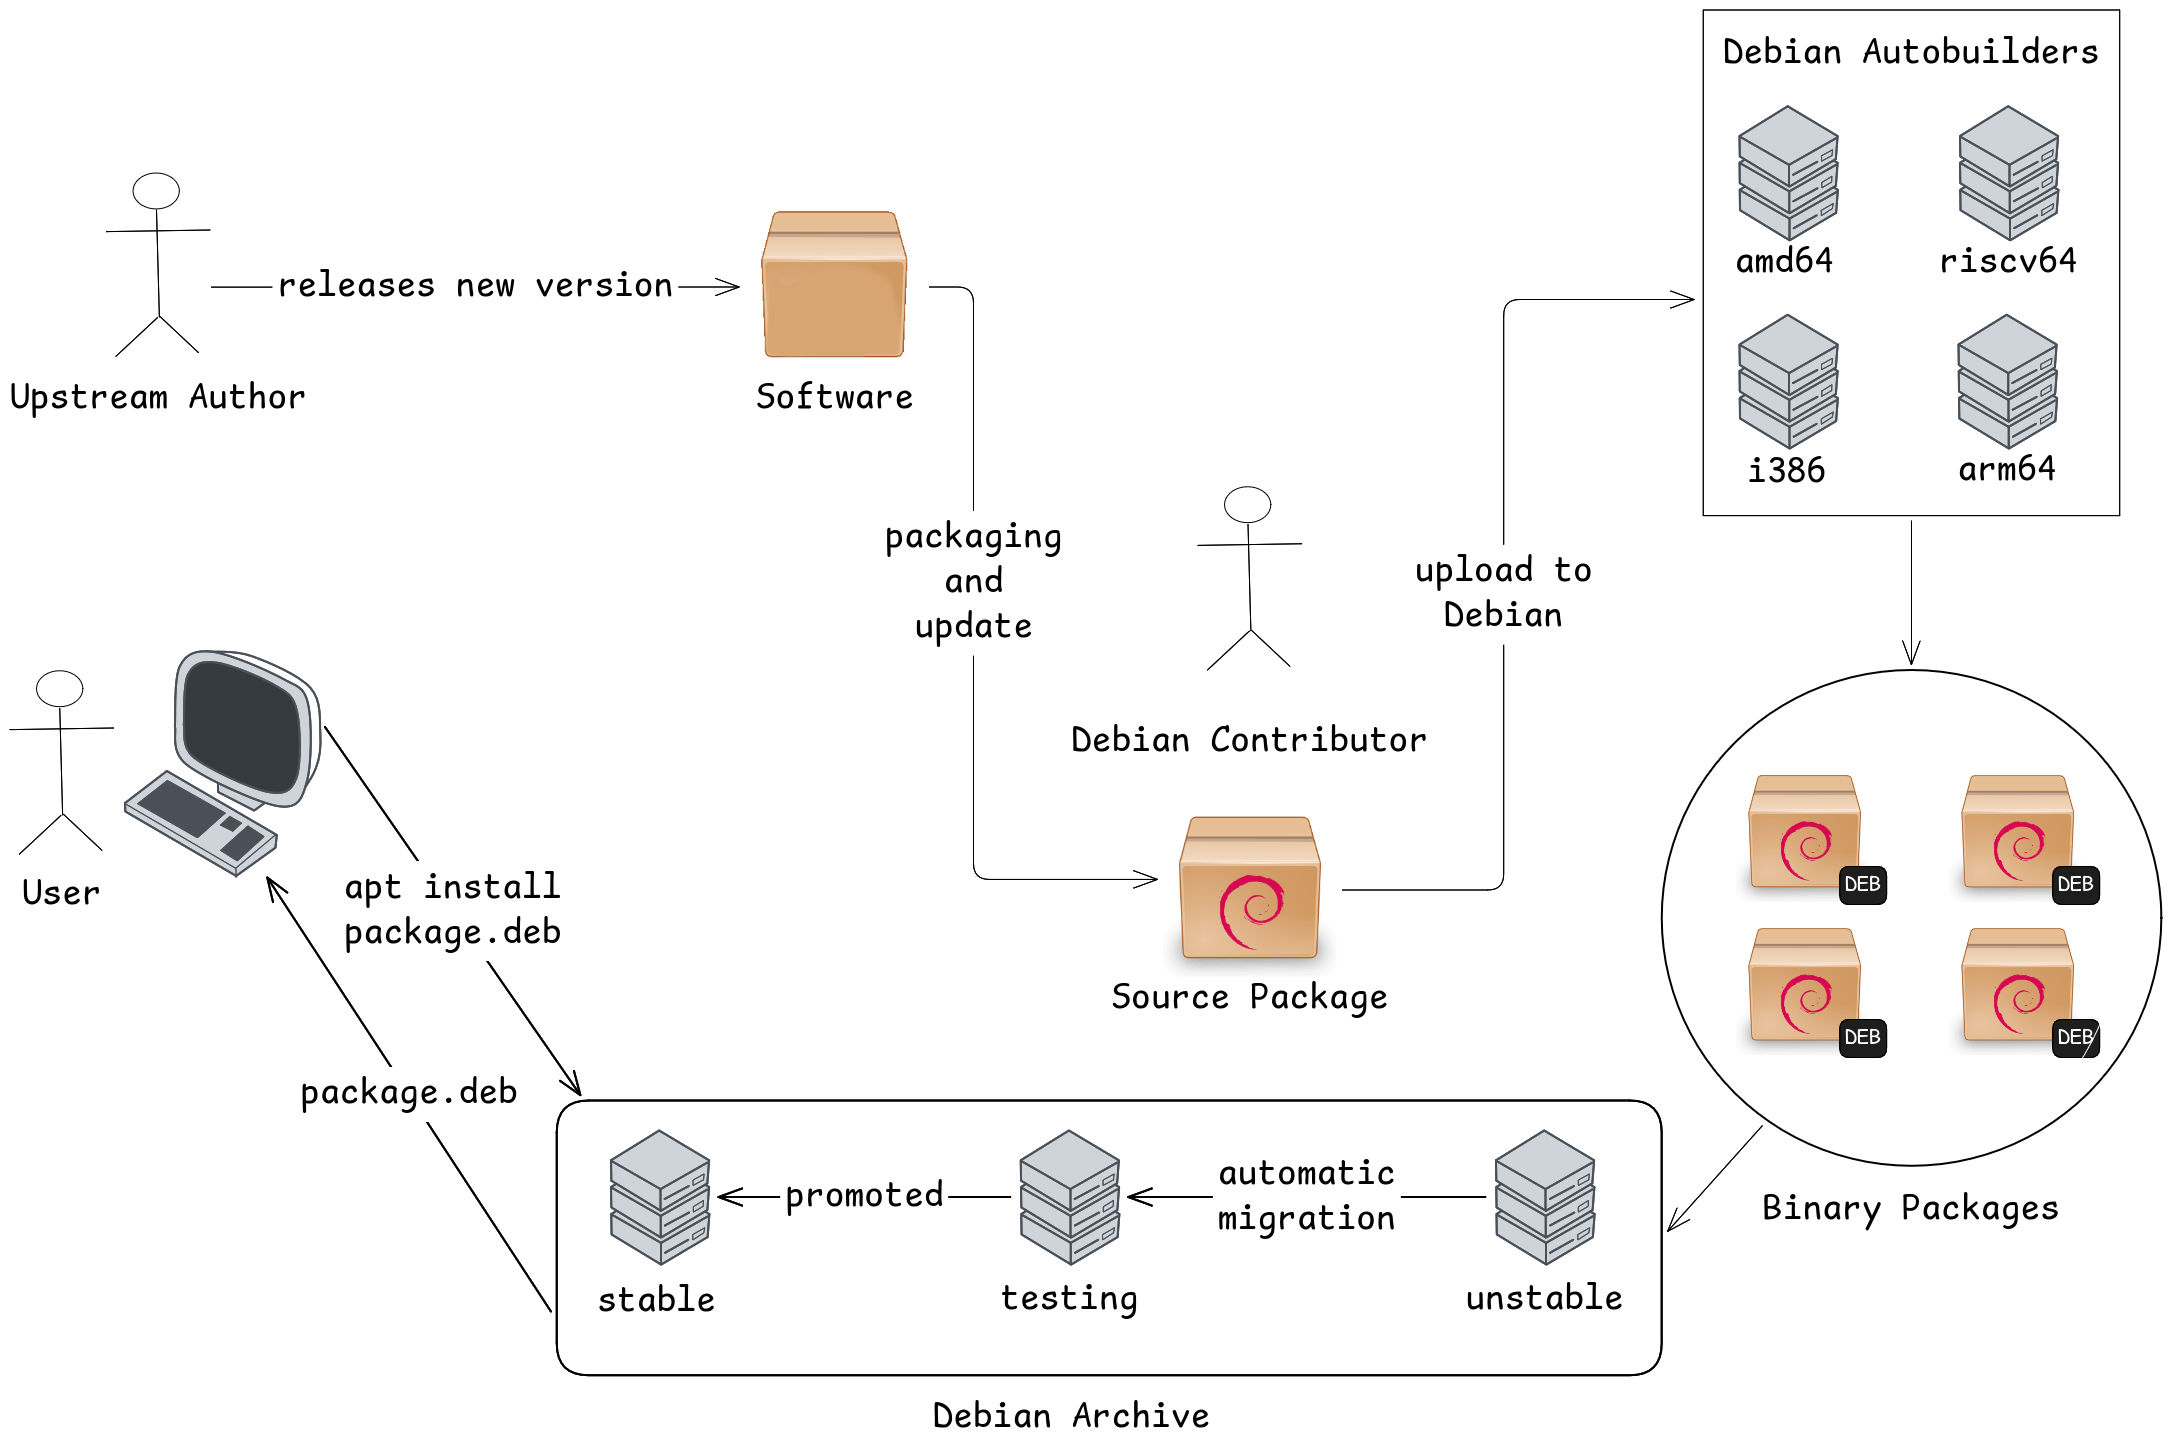
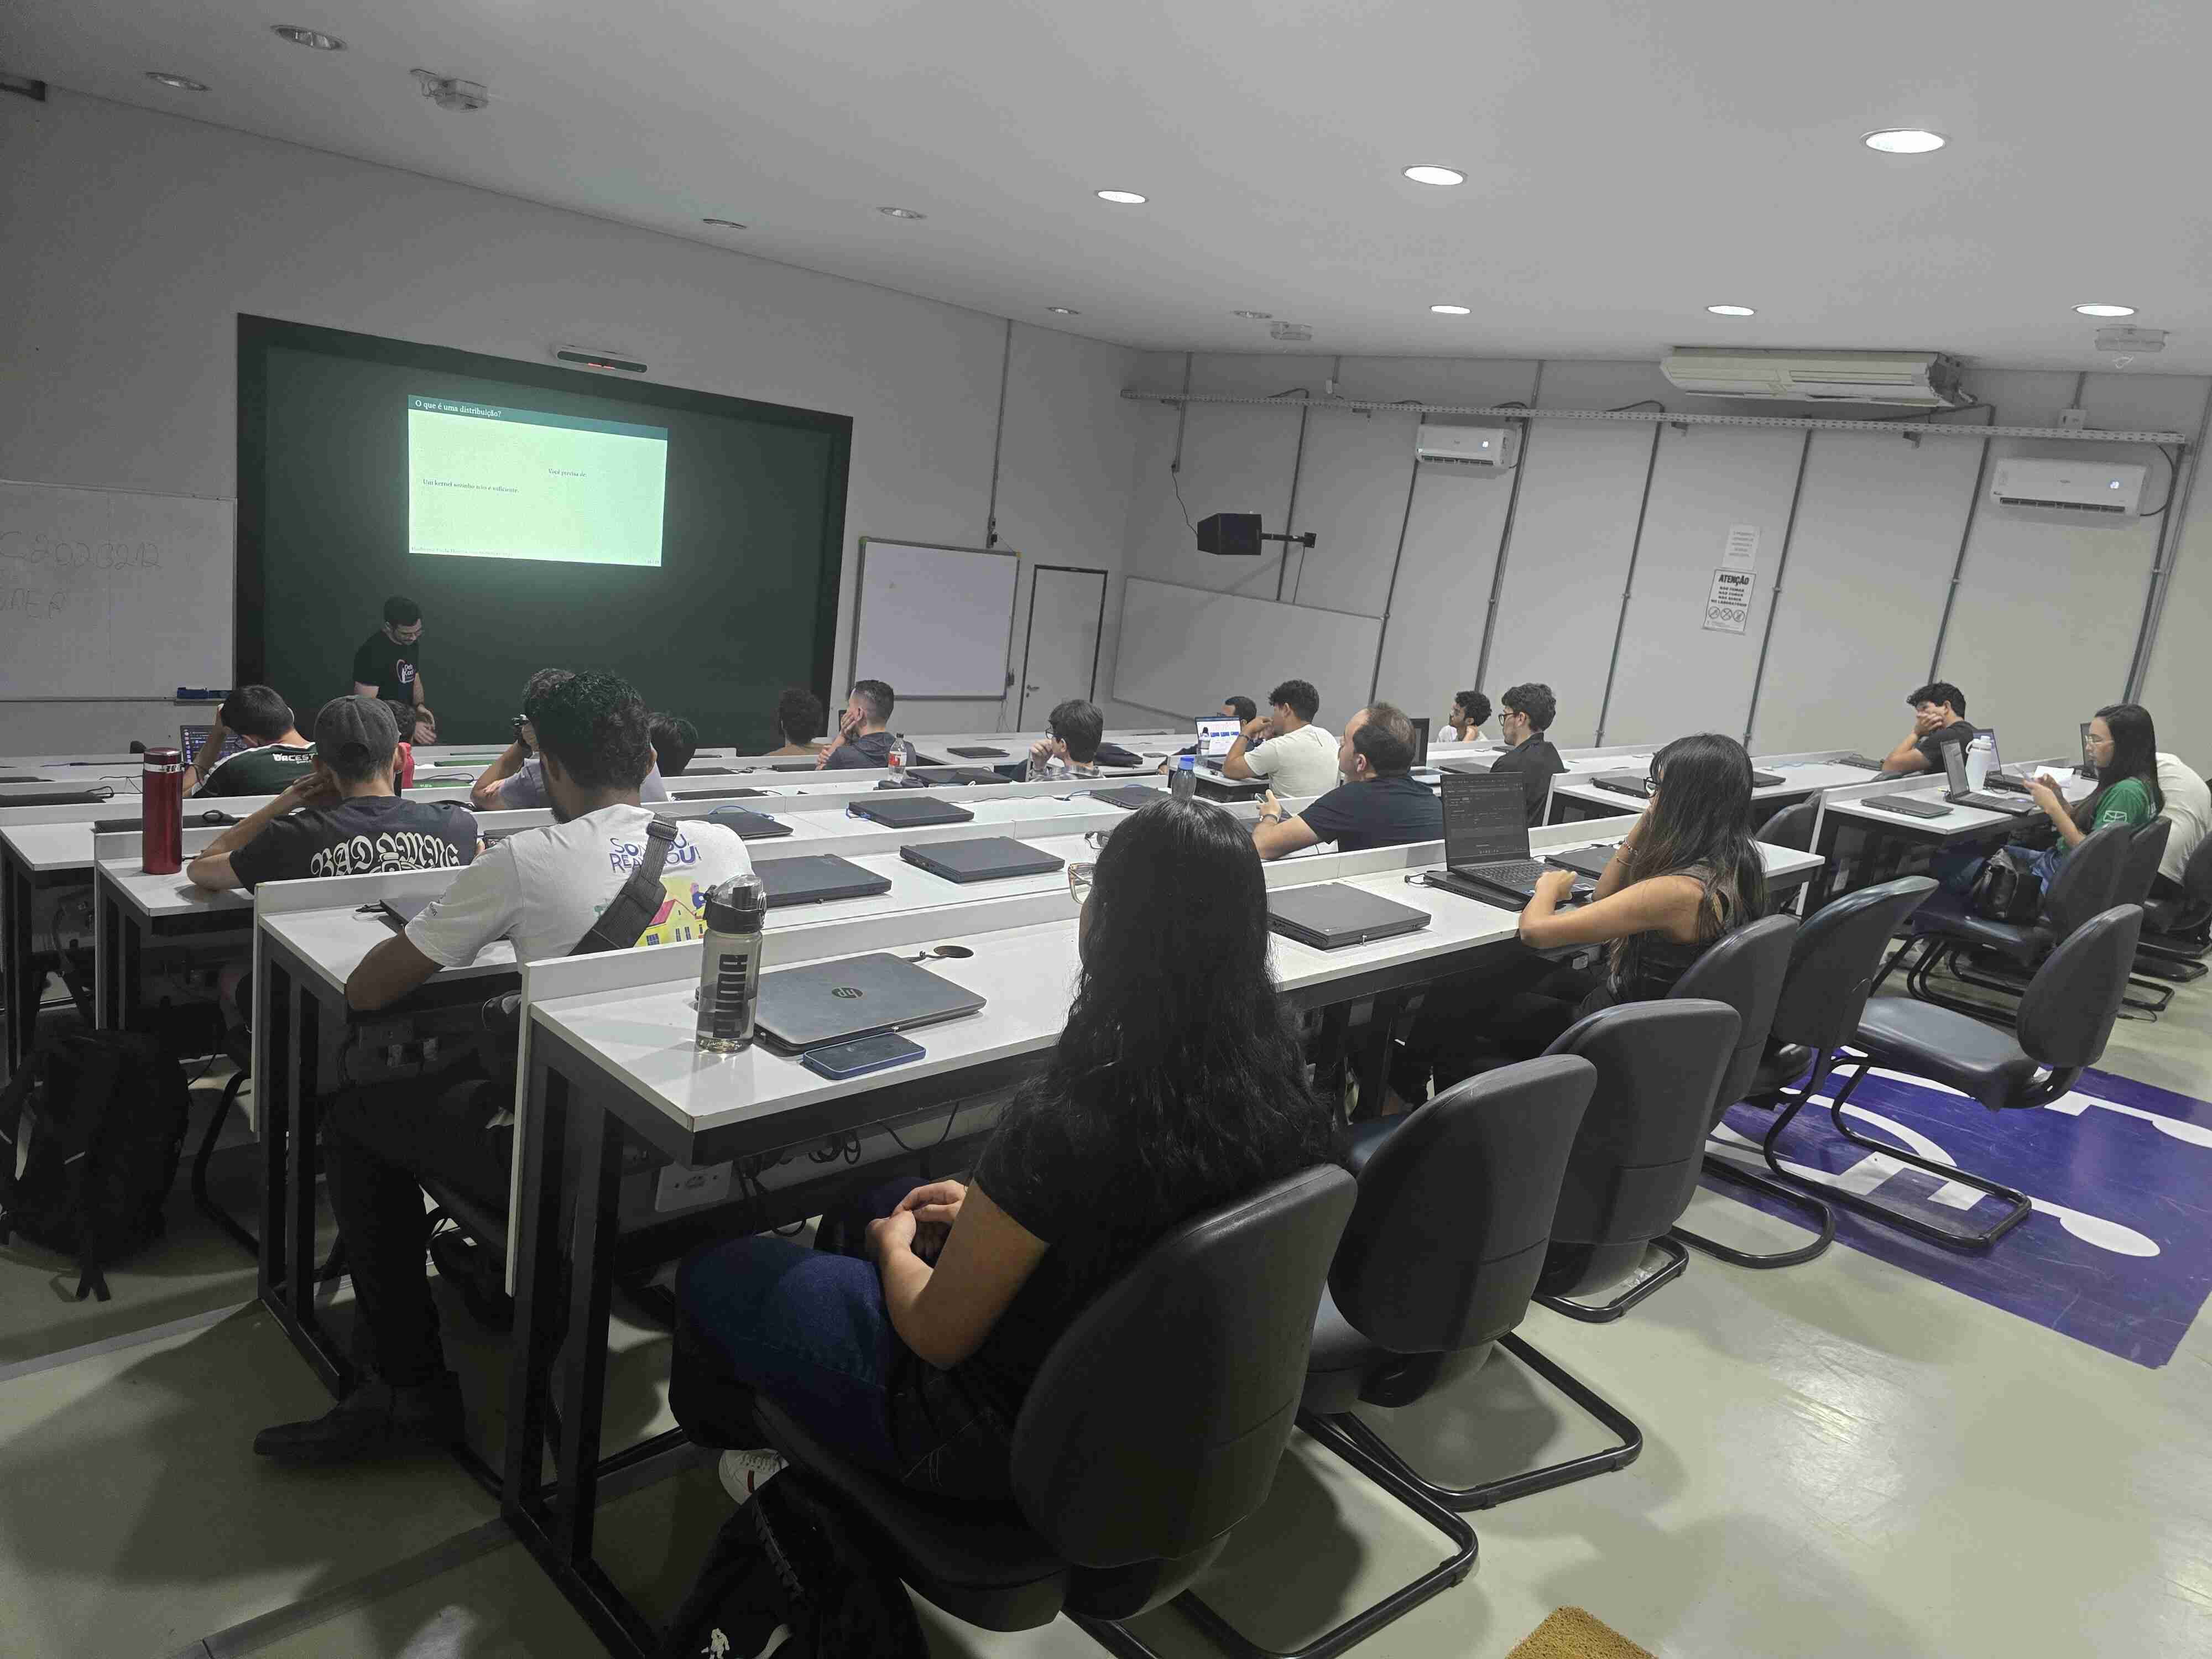
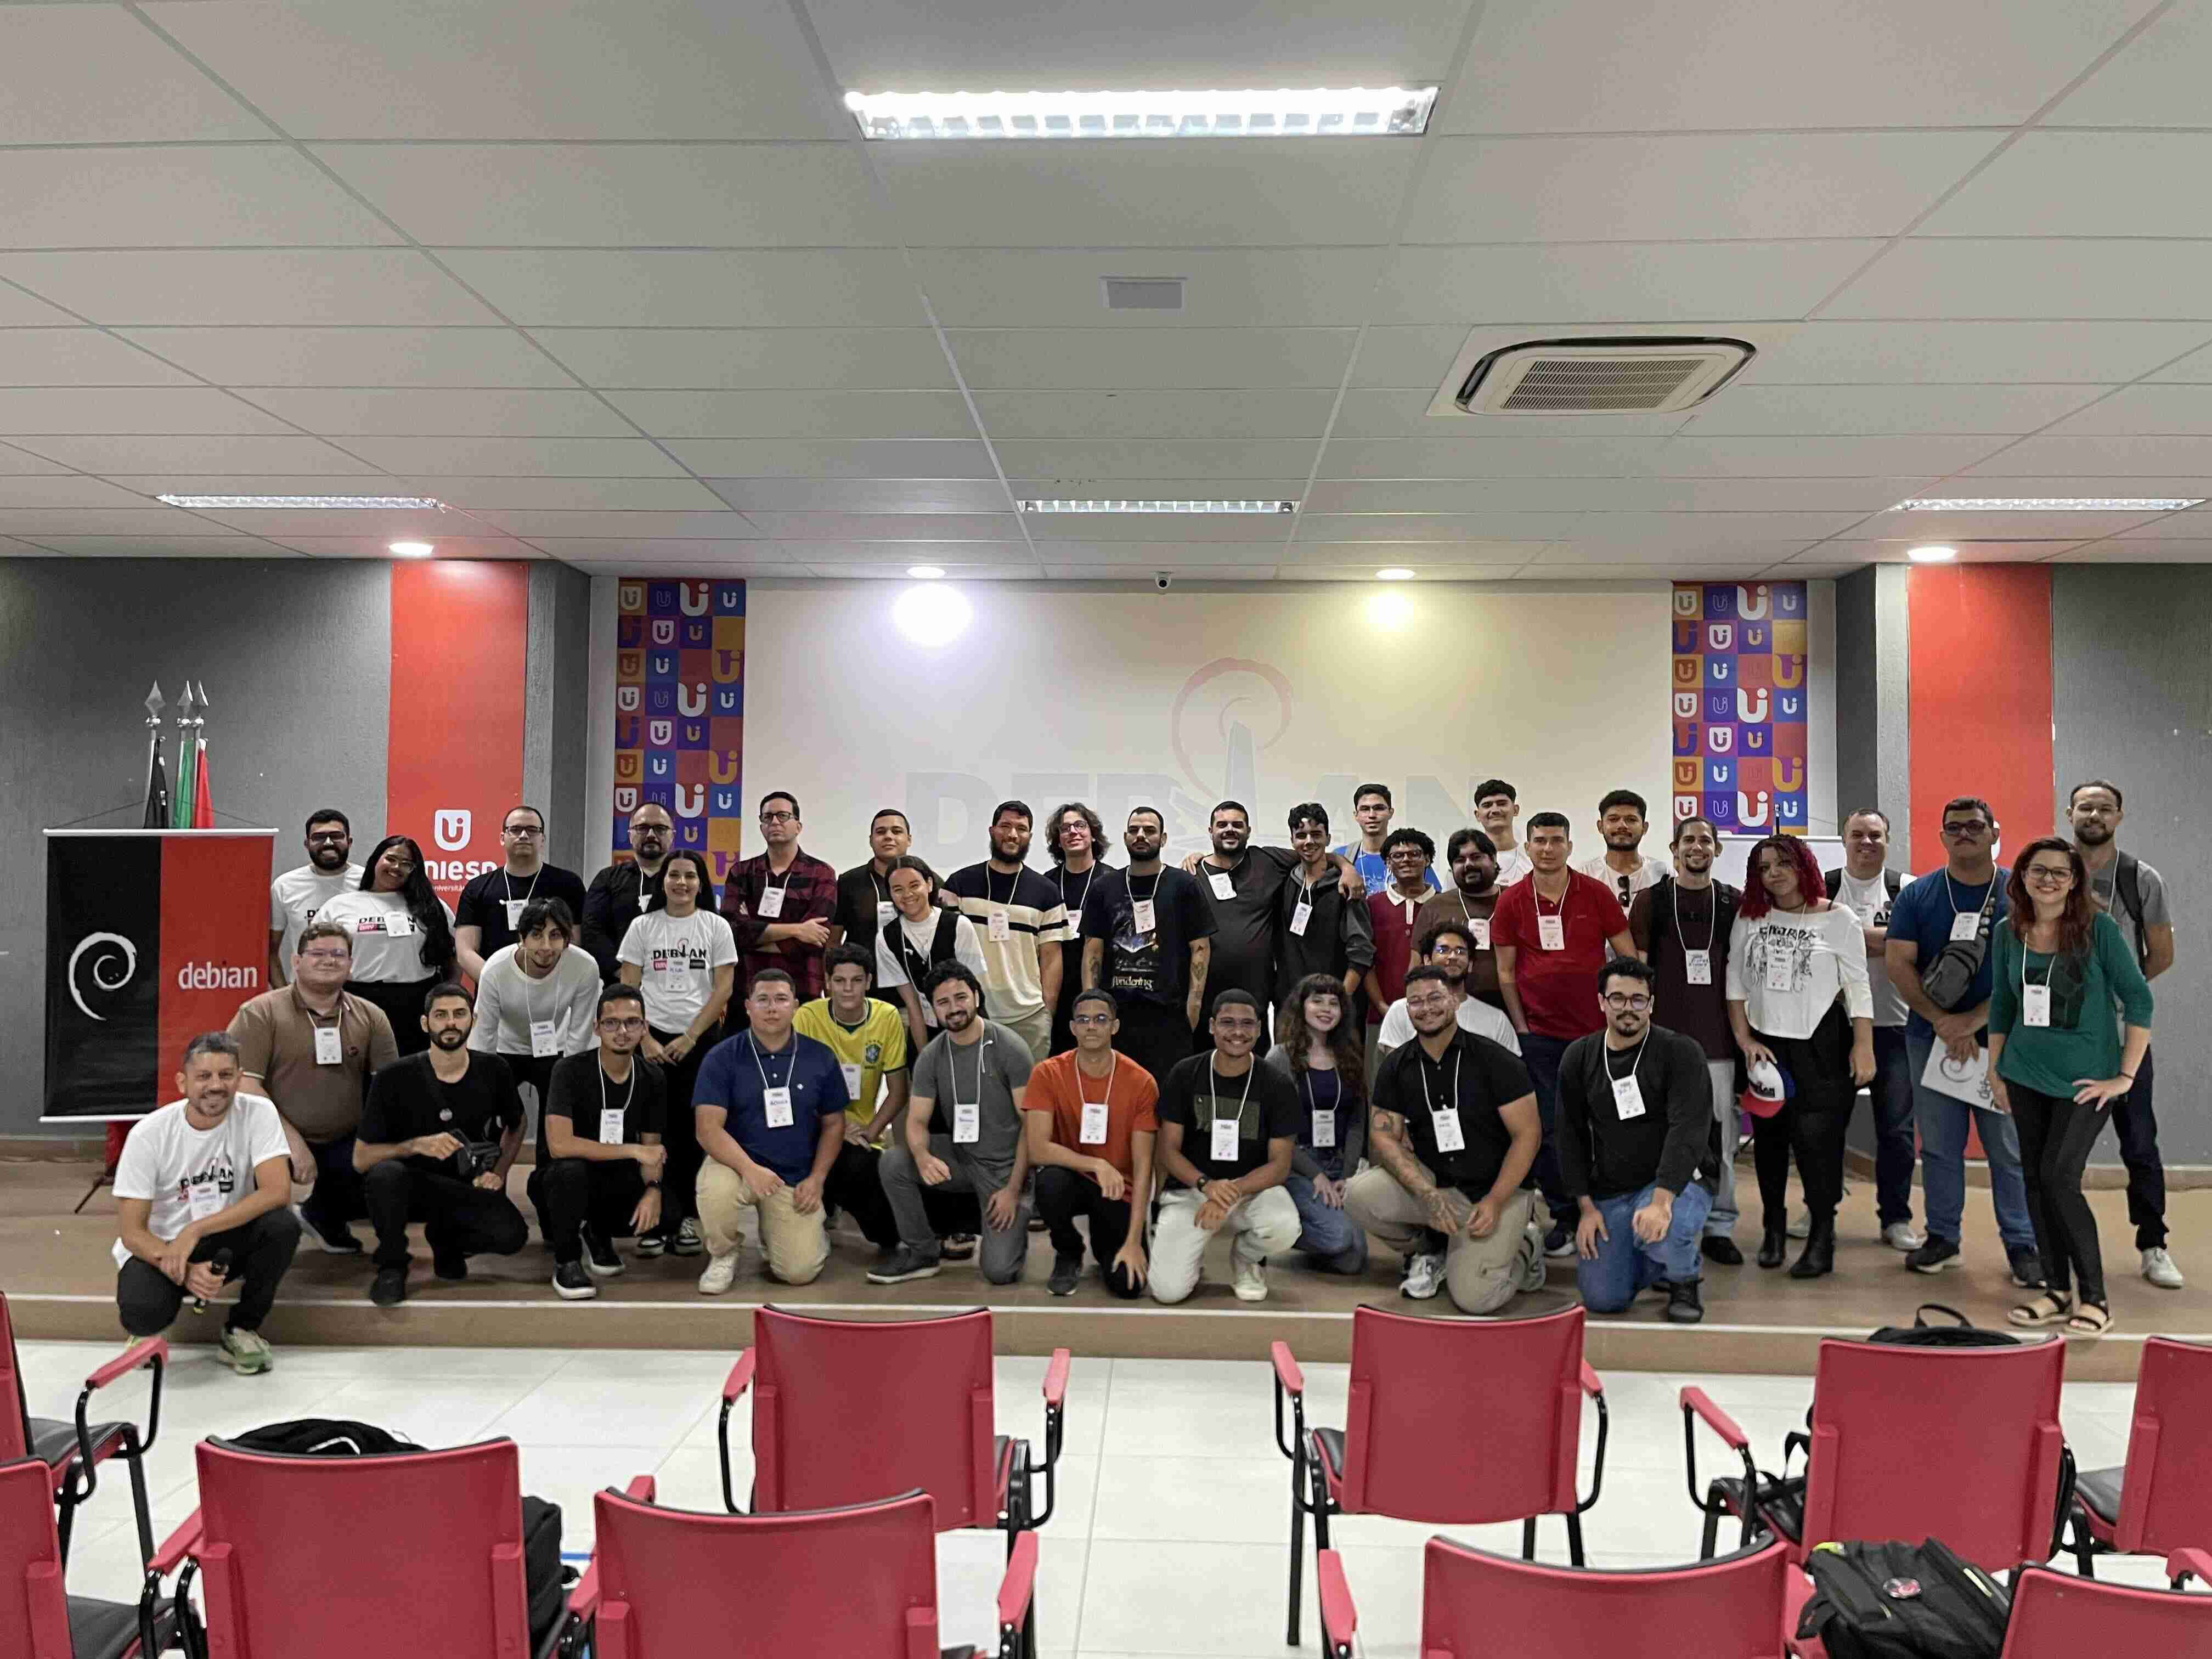
Jo o Pessoa Debian Day Jo o Pessoa Group Photo In Jo o Pessoa, we had a two-day event. The first day was dedicated entirely to workshops, and I ran a packaging workshop for newcomers. It was the first time I had been responsible for a workshop, and it was a great experience. We didn't have a lot of time, so I decided to start with a 30-minute talk explaining a few things about Debian. For example, I made this image to explain the packaging workflow: Debian upload workflow This image was based on The Debian Administrator's Handbook, and I think the participants really enjoyed learning about this workflow. When I showed the slide with this image, it was the moment when I received the most questions. After the talk, I explained my way of working and what they were going to do. The hardest part was setting up the environment, since my approach uses sbuild + gbp. They were running different Debian releases and, because of my inexperience with workshops, I had some of them configure sbuild with unshare, even though it is only available in stable through backports. Some of them even managed to learn how to use backports, while others decided to start again using the "old" way. One thing that helped a lot was the Debian Brasil Wiki. It has all the instructions for configuring sbuild in Portuguese, along with great examples. The Brazilian wiki is an opinionated version of the Debian Wiki. We generally prefer to use it for the convenience of having the exact workflow we follow, as well as an up-to-date Portuguese version of our process. If you want to learn more about the Brazilian community, you can find more details in the schedules from previous DebConfs. We almost always had a talk about the community and its activities. In the end, everyone successfully set up their development environment, and all six participants made their first contribution to Debian. If you take a look at my upload tracking page, you will see that every upload made on August 15, 2026 was a sponsored upload from this event. One of them appear twice in the list because I sponsored the upload and also made some other changes. I also asked all of them to put this in their changelog:
* My first contribution!
The idea was to make it clear to other people that they were only working on small Lintian issues as a way of learning and understanding the process. By the way, I made a UDD query to find packages with the following Lintian tag: redundant-rules-requires-root-no-field. To fix this issue, they only had to remove one line from the debian/control file. It is obvious that these uploads are not particularly useful. I call them "motivational uploads" because my goal is to help newcomers understand the process and immediately give them the reward of having made a contribution to Debian. I'll try to keep in touch with them. My plan is to hold another session, this time remotetly, to help them continue contributing to Debian. In fact, I already have another package prepared by one of them waiting for my review. The second day was a full-day event featuring a bunch of talks from the local community. I gave a talk explaining the new members process. I was the only Debian Developer at the event, and I think having a DD there made a real difference. Being there to answer questions, and simply being present, makes Debian feel more tangible and accessible to people. A big shout-out to Rafael Rocha, who put in a lot of work to make this event happen, with the help of many volunteers who contributed along the way.

Bras lia Debian Day talk in Bras lia One thing I really like about Debian Days is that each place has its own way of doing things. In Jo o Pessoa, we had a MiniDebConf-like event, while in Bras lia, we had something smaller but still very valuable. We decided to keep things simple: talk to a few students at the University of Bras lia (UnB) and then go somewhere to eat and have a few drinks.

A bit of history For those who don't know, the DebConf 19 was held in Curitiba, Brazil. After the event, Arthur Diniz got really excited about Debian and decided to go back to his University, UnB, to share his experience and encourage more people to contribute to Debian. I attended one of his talks, thanks to Joenio Costa, who invited Arthur to give the talk. Joenio was also my professor at the time and a Debian contributor. I really liked what Arthur had to say about free software, and he did a great job of presenting the Debian community as a friendly and welcoming place. So I decided to attend local meetings of the Debian Bras lia community, which had been inactive for a long time. Lucas Kanashiro was the Debian Developer who answered our questions and, as I mentioned earlier, simply being there made Debian feel more tangible. Everything stopped when the pandemic began. Then, towards the end of 2020, I saw a message in the Debian Bras lia channel saying that the meetings were back, this time remotely. I was hesitant to join because, back in 2019, I hadn't managed to make a packaging contribution, even with their help. I had eventually given up on the process. So this time, I decided to join the meeting with something already prepared for review. I watched all of Eriberto's packaging videos, picked a random package, and joined the meeting. I remember Kanashiro being excited that someone had just shown up with something ready for review. At the time, it was only the second meeting since Debian Bras lia had come back online, and none of the newcomers had started working on contributions yet. During the same meeting, he also convinced us, the newcomers, to give a talk about Debian just three days later. The MiniDebConf Online Brazil 2020 was happening on Sunday, and the meeting was on the Thursday before it. Since he has great convincing skills, I went along with the idea and prepared the talk with Francisco Ferreira. That was the rebirth of the Debian Bras lia community. Since then, we have maintained a close connection with the University of Bras lia, and today, at least seven Debian Developers are from UnB, whether as former students or former professors. The reason I told this story is that, even though the Debian Day we held in Bras lia was smaller, it is part of something that has been working for us for several years: staying close to an University. We've managed to attract and retain many people who share the same values and interests. I've hope you all had a great Debian Day. If you're reading this and aren't part of the Debian community but would like to join, get in touch!

Iustin Pop: Another optimistic take on AI

Disclaimers The current discussion in Debian around the AI GR is very heated, and I won t add to that, however, I am very confused about some of the viewpoints there. But, I had no idea how to even try to write this, so did shut up, until I saw Aigars excellent Optimistic take on AI, which motivated me to try, at least. For the record, I fully subscribe to the post, and to the voting suggestions (and I just voted). Also, for full disclosure, I don t think I did any contribution to Debian until now using AI, neither packaging, nor emails, nor bug reports. And this blog post specifically is 100% hand written. With that out of the way there are two points I want to make in this post.

AI is useful, even if it has risks First is, that even if we could put the genie back in the metaphorical bottle, we should not. We do need to continue working towards safe AI, and efficient AI (less environmental impact), but we should not work towards removing the usage of AI. There are already significant advancements in sciences and technology thanks to the use of AI, so desiring AI to not exist (assuming we had a magical wand) is the wrong approach. Sure, AI has significant risks and I can see ways in which AI can do significant damage to society but I don t think we can go from Kardashev I to II without the use of AI, and definitely not to III. And I think, that should be the goal. A few simple examples: Do we want to rollback all the 20 years old security issues that AI found? Do we want to rollback the recent Moderna cancer findings? Do we want to rollback the concept of extremely large scale pattern matchings , just because it runs on chips and no longer in one person s head?

Reading Debian lists The second point is, lately I found less and less enjoyment in reading Debian lists. Even with that already being the case, I feel so disconnected from many of the opinions being voiced in this discussion. On one hand, it s normal and healthy that people have different opinions, disagree, and move forward. On the other hand, looking at one of the proposed options:
  • Moderators and disciplinary teams may make narrow and tailored exceptions to rule 4, and decide on interpretation .
  • Violations of these requirements should be treated as violations of the relevant Code of Conduct and should result in swift and proportionate disciplinary action .
I already knew Debian, and some large parts of the OSS world, is left leaning. But those phrasings, to me, are too close to socialism/communism. As someone who grew up under communism, this is a much more slippery slope (disciplinary teams? really?) than AI usage. Ask me in person for more details. So, it is possible that Debian continues to evolve in such a way that I don t find myself in any way close to its ongoing culture. I will be sad at that point, but it will be what it is.

Where to? I think that, until such a time that an AI bubble bursts, what any organization should do is try to logically see where and if AI can help. And in an organization that is about computer software, I see hundreds of places that are subject to very large scale pattern matching so the half of the discussion is, to me, mind-boggling. To be clear, it s not about if you can t beat them, join them . As I wrote above, I think AI is useful, so the point is how to use it effectively. Well, will see what Debian votes. I am half curious, half sad already.

22 August 2026

Aigars Mahinovs: Optimistic take on AI

As I am writing this, there is a vote ongoing in the Debian project on how to deal with AI in general and AI-assisted contributions to Debian specifically. Massive discussions have happened in debian-vote and other locations. I have also asked questions there and offered my perspective. IMHO now is the time to summarize that, after all the discussions that I've had with people on multiple sides of this debate both online and offline, and explain how I will be voting and why. Hopefully that will be helpful to someone else as well. None of this has been compiled with AI assistance, but only because I think that forming opinions is not something where AI can really be helpful. Spellcheck was used though. So, first I will describe how I see each of the 8 proposals, then what my vote will be, and then a bit more detail on the reasoning and thinking behind this. WARNING - this went long. With all the above considered I will vote like this (earlier options are preferred over later options): Details on rationale Hypocrisy - I find any proposal that would ban AI-assisted contributions to Debian, but at the same time not ban including AI-assisted contributions from upstream projects to be inherently hypocritical. If LLMs and AI are the very incarnation of evil (a puppy-killing machine, as the analogy went in some emails), then any rational proposal would involve excluding any and ALL code contaminated by this evil from the project. What does it matter if puppies were killed in writing the debian subfolder of the source code or the src subfolder? No proposals went there because everyone knows that such a ban would be the death of the relevance of the project for the future. Debian would be frozen on some old version of the Linux kernel forever and other software would be falling to the same problem too, for example as projects on GitHub start enabling AI-supported reviews with patch suggestions. Soon the "development" of Debian could just be stopped as there is nothing to develop without any upstreams. Assumptions - a lot of proposals mention various "concerns" with at most one word, like "practical" or "community" without an explanation of what exactly they mean by that. The proposers assumed that everyone lives in the same info bubble as they do and already know everything that they mean and already agree to that. That is false. Proposal A was a positive stand-out in this area. Debian has contributors all over the world with very different exposure to different information sources and very different world views. If you want to convince the project as a whole that LLMs are bad because of "ethics", then you do really need to explain what you mean by that and give links to sources, at least as well as Proposal A did. All other proposals were really weak in this area. Copyright - the question on how copyright law interacts with training LLMs and their outputs is still not settled law. The closest legal statements we have so far are that - just because an LLM is trained on copyrighted material does not make that LLM itself be a derivative work of the training data (you, however, cannot just create and distribute a "library" of copyrighted materials just because you plan to train LLMs on it). The output of the LLM might not be subject to copyright law at all, like a photo taken by a monkey. It would then be public domain and thus can be modified and then licensed by the user of the LLM. It might also be a derived work of the context of the inference (so for software - if you refactor a GPL project, the refactoring itself is likely GPL too). Any stricter interpretations would break a lot of existing copyright doctrine, such as raising questions like: "does the output of any programmer now become a derived work of the programming manual books they read in college?". In any case it is really not up to Debian to legislate the nuances of copyright law. And I strongly disagree with the concept that an author can tell me how I am allowed to use the learnings that I gained by reading their work. That is not how either copyright or society works. I can look at 10 pictures of a sunset and draw my own, inspired by the ones I saw. No one can forbid me that expression. The same must be true for a machine learning and replicating patterns. Ethics - I've re-read all proposals and emails and the only real specifically ethical concern I could find was the complaint that some LLMs (or their training farms) are running their web scrapers too aggressively and that causes extra load on services. Like that is not an LLM problem. Scraping the web is not an inherent part of the LLM training or inference process. It's just a few misconfigured scripts. We saw the exact same thing in the early days of web search engine proliferation. Then we banned/blocked the misconfigured engines and the survivors learned that obeying robots.txt is one of the rules for surviving. Literally the exact same problem and it will be solved the same way. Did we ban all search engines back then just because some of them were misconfigured? No. Some claims (like in Proposal C) are just bombastic hyperbole ("hazards to users' mental health", "fraud", ...) and on top of that have zero relevance to the topic at hand - AI-assisted contributions to Debian. What "hazard to users' mental health" is created when a Coderabbit spots that a lock is not taken before accessing a resource in a particular function and suggests an AI-generated patch to fix it? What "fraud" is committed by this? There is no sane answer. I get that some people are very busy fighting some culture wars and sometimes, some AI-bros happen to be on the other side of one such war, so it is useful to label everything coming from the AI sphere as "bad" in all possible and impossible ways. You do you. In private. Why pull Debian into that? Why force your position on everyone else in the project? Why deny everyone in the project access to useful tooling, just because you have strong feelings about some of the people promoting some of those tools? This seems to me a repeating pattern here - blaming the technology as a whole or blaming all providers of this type of technology for failings (ethical or technical) of some of those providers. Like refusing to wear all shoes and condemning all shoemakers and sellers, just because some American billionaires figured out a way to make and sell cheap shoes by killing puppies. Not refusing and condemning those providers, but condemning all for the actions of a few. Resource usage - this is a big topic for many and it has reasonable points to it. The LLM and AI technology has no inherent need to be damaging to the environment in any way for it to function. It does not need to burn oil or dig up cobalt. It does not need to sacrifice a ton of water to the Gods. It is perfectly possible to run AI (both inference and training) purely from green, electrical energy and cool data centers in equally sustainable ways, like with simple air-source heat pumps (also known as air conditioning) or even use it beneficially (many data centers are used for heating surrounding buildings via district heating). However, some AI companies do use non-green power for their data centers, some do use locally-limited fresh water for evaporative cooling (evaporated water still rains down as rain, it is not really lost, but that may happen in another location so lack of water can still happen locally). Some even run unlicensed natural gas turbines in their data centers to provide them with power. And those specific providers can and should be shunned and condemned. Not the other ones, who are doing the right things. Not the technology or its users or its outputs. There is a very wide spectrum of options on how an AI system could be powered: starting from local execution on already existing private hardware powered by one's own local solar power (good), to a data center stuffed with borrowed AI-only cards powered by a gas turbine or coal power station that operates solely to supply this data center (bad). Proposals that talk about ecological impact, but do not even consider where on that (very wide) spectrum to draw the line between "good", "acceptable", "discouraged" and "bad" well, I cannot see those proposals being actually serious about the environment to begin with. It feels like they just refer to it for points. And if we go into the power question deeper, well the grid dynamics and economics become very, very complex and often also non-intuitive. Like, all large software companies with data centers (that also happen to provide AI services), like Google, Meta, Apple, Microsoft and others do actually care about sustainability (in part because their customers care and vote with their wallets) and so all of them use 100% green energy for their data centers (including AI data centers) .... "on an annual scale". Wait, what does that mean? Well, the electrical grid is special - the amount of electricity produced and consumed on the whole electrical grid together has to match almost exactly every second. If there is just a single second where there is significantly more energy consumed from the grid than is produced, the frequency will plummet and you get a brownout and risk a grid collapse. The same is true in reverse - that causes a voltage swell. So grid operators manage energy flows every second and command power stations to increase and decrease generation all the time. Some power stations are easier to regulate dynamically than others. In the end, all that means is that even if your data center has a contract for 100% green energy with your power company, at some seconds across the year there might not be enough green energy in the grid to fully supply ALL people and companies that have 100% green energy contracts. This gets compensated in other seconds, so that across the year ("on an annual scale") for each kWh that your data center pulled from the grid, the same amount of kWh of 100% green energy flows into the grid. But it might not happen at the exact same second. Pedantic companies, like Google, take that discrepancy and count that as CO2 emissions for themselves. And then they and the power companies (they have contracts with) invest billions into new green energy projects, better grids and better batteries so that eventually this discrepancy goes down to zero. In this way green AI data centers with their increasing consumption of green energy are actually doing a lot of good work in making our electrical grid more green. They are making more resources than they are consuming. And that is just the tip of the iceberg. This is a deep topic that really abhors generalizations like "more consumption = bad". I've heard similar discussions in the context of electric cars - "so you got an electric car? you'd have fewer emissions if you drove no car at all!". That might be so. And I would also reduce my emissions to zero if I stopped breathing, but I really do not want that kind of thinking to be propagated further, especially when impressionable young people are around who may take it to its logical (but wrong!) conclusion. Instead I talk about how early adopters use electric cars to gather experience and achieve volume to start the network effects working. Once network effects of many electric cars on the roads are sufficient, it becomes an economically logical choice to get an electric car. People who cannot avoid having a car start to switch over. And at the point of mass switchover the reduction of emissions is so massive that those early adopters failing to go all the way to riding a bicycle becomes a rounding error. But surely that does not apply to LLMs? They are only increasing consumption and bring no benefit? Benefit - and here we have to actually talk about benefits. Because you cannot make any cost-benefit analysis if you do not actually fully investigate the benefits. Are there environmental benefits from running those AI models? Yes, in a lot of very diverse ways. Hard to measure, however. There are projects that are easy to quantify - like that Google AI project on contrail avoidance. An advanced, special model trained and executed in Google AI data centers was able to predict where in the air contrails would be produced and could generate proposed course adjustments to commercial flights to avoid specific heights in specific locations at specific times. This stopped these aircraft from creating contrails and those contrails did not make a further contribution to global warming. That benefit in a year was many times higher than the environmental cost of training and running that AI model. And it can keep running for many years accumulating further benefits. On a personal scale, I've had problems that I bashed my head (and computer and CI resources) against without much success years ago solved with a few minutes of compute. Having a good enough candidate solution quickly is much cheaper from a resource perspective than spending days trying different things, running my PC for it, trying different patches on CI executions, doing different rebuilds. I've seen very significant benefits in AI-assisted development in enterprise environments where code way more complex than what is in Debian (especially in Debian tools and packaging) gets analysed, reviewed, modified or even refactored or rewritten in another language with AI assistance. And it generally works. The commonly mentioned "hallucinations" are a thing of last year in the coding context. Nowadays the AIs work in special coding harnesses and use real tools as foundational facts. You cannot "hallucinate" an API call or parameter if you have to run and pass the unit tests and integration tests by your harness before you can return "success" to the caller. I've personally seen high-level AI models read very complex software projects across multiple repositories and point out a very specific design consideration that was encoded in the code logic, but never mentioned in comments or documentation. It was so obscure that even I did not immediately know what it was talking about (and I wrote that code). Only on close inspection of code interaction across three repos did I remember that there was indeed that bug 2 years ago that I fixed by doing the change that this AI picked up (it wasn't in the history of this git repo due to repo migration). It mentioned this because it was very relevant to the task I initially gave it to review. These LLMs in a proper harness with proper system instructions and usage approach are not just fancy spell checkers or auto-complete. They function more like very advanced pattern matchers. They have learned millions of patterns from training data. When they look at the code, they see hundreds or thousands of overlapping patterns. When you ask them to make or change something, they pull out a pattern (or ten) from their training and apply those patterns to the context of your program. You get something that looks just like the surrounding code, same style choices, same language, same comment voice, but it implements something new there, based on other patterns learned. If you've studied design patterns in your CS class, this will be familiar. But people can learn and remember maybe 20-30 patterns, while an LLM can have a million patterns and can combine them when needed. So it takes a pattern of Python code, pattern of standalone script, pattern of parsing command line parameters, pattern of classes, pattern for background threads, pattern for file tree traversing, pattern for pipes, ... and squishes them together to make a solution for your query. And then tries to debug it with compilation, tests and execution until it works as expected. Even if there is zero LLM development going forward, it will take many years to fully appreciate the benefits we can extract from the already trained models. They don't even have to be retrained - for existing languages they just keep working. For new language variations, like a new Python version, you can feed the changelog into context and they will be able to work with a Python version that they never saw in training. And patterns are mostly abstract, so not really specific to any language - human or programming. This is another big enabler that LLMs have created that we have not really explored yet. LLMs have created really free software. People can actually create software that is perfectly suited just for them and no one else. They don't even have to know how to program and don't even need to speak English. I've seen people writing prompts in their native language and LLMs creating and then adjusting web apps or Android/iPhone apps and deploying them to the user's own phone. It was too buggy to work last year, but this year it is actually very functional for simpler use-cases. And the code looks just fine too - I've seen external contractors in a business setting deliver far worse. If you start with a good initial system prompt, the project will have architecture documentation, use-case documentation, unit tests, integration tests, deployment harness, testing and production deployments, audit logs, monitoring, clear git commits, CI validation on commit, ... Modern AI systems have the capabilty to deliver software freedom to people who are not coders. I really can not overstate the consequences this may have on the world. Community - I find the concerns that new people will be using LLMs so much that they will no longer be understanding the actual code they are contributing a bit regressive. I don't see any significant difference between this and people relying on compilers, on high-level languages or on debhelper. Writing modern debhelper packaging feels more like writing configuration and not writing code. It takes really significant effort to dig down through layers of abstraction to find what actually is being executed in debian/rules. AI does not really make this worse. In fact, I find that AI can make it much easier to understand arcane syntax because you can ask an LLM to explain what is happening in any part of the code and it will do a pretty good job of it, digging down through the layers of abstraction for you. All the pro-AI proposals include the requirement that each human contributor needs to understand and stand behind their AI-assisted contribution and I believe that is a good requirement and also a sufficient requirement. Modern LLMs not only produce clear and concise code, but they are also capable of producing good comments explaining why the code is how it is, good commit messages explaining the change and reason behind it and also making corresponding changes to test suites and documentation. You know - the housekeeping stuff that is often skipped because it slows down the actual feature development, but then its lack becomes a problem for future contributors. Responsible use of AI assistance is a great chance to actually strengthen our community and make our software easier to maintain. That said, I have no qualms about flat-out rejecting contributions that do not make sense. And it does not matter if they are made with or without AI assistance. If the contributor will not explain their patch, it might be they do not understand what their AI produced or it could be that the contribution is deliberately hiding a backdoor being planted. It is also quite common for a contribution of a new feature to be rejected because the author/maintainer does not believe that it is a good fit for the project. Featuritis is a real disease. AI or not. There have always been drive-by contributions to various projects. They will continue to exist. Each of them should be evaluated on its merits - is this feature valuable to our users and is the added complexity (if any) worth the functionality? A lot of security bug reports are "drive-by" contributions as well. And many of them nowadays are discovered, exploited and patched with AI assistance. We could reject them, but that just leaves us holding the bag on the now-known exploits. And the New Maintainer process should be able to figure out if an upcoming Developer has actually understood the nuances of Debian packaging or not. A contributor with upload rights to the archive has to be able to create a basic package with no support tooling (maybe even without using debhelper?) and be able to understand and modify more complex packages (possibly with tooling support). IMHO that is a separate discussion that is worth having, involving experts from the educational sector. Conclusion IMHO the Debian project should not restrict what tooling individual contributors use to contribute. Expecting high-quality contributions and that contributors understand what they are contributing (as a first level of review) is enough. However, Debian should provide its contributors (internal or external) with guidance on how to contribute in the best way possible. That could include: In addition to that it would be helpful for Debian, as a project, to reach out to AI service providers to: Questions? Feedback? Just ask here or here.
19 August 2026

Antoine Beaupr : The people vs the AI overlords

Also in this series:
In a post to oss-security, my (Debian) co-developer Russ Allbery stated that "open source software [OSS] is coming face to face with a motivation crisis that has been building for a long time". His point is essentially that large language models (LLMs1) are making the existing OSS community crisis worse. For him, it's the flood of code reviews, but he argues that varies according to people's desires, for others it's security issues and so on. I think Russ is right, but I would argue there's something much bigger than our open communities going on here, and it's about the entire field of computing. This pressure is on all of us, regardless of whether we work on open source software or not.

How people use models People using LLMs in their workflow have radically changed how programming works, even for people who claim to avoid vibe-coding. And I'm sorry to single out one poor maintainer here: it's not you, Brian, you're just one example among many. But this is typical use of those models nowadays:
Once it s done, I ll use /code-review and let Claude spawn sub-agents to do a full review of the new code. This usually finds some problems, even problems that the main Claude instance didn t find during its validation. I usually keep running /code-review again and again after finding and fixing issues, until there aren t any left.
Think about what that means for a minute. This is automation built to fire up dozens of agents crunching at a problem for minutes if not hours of GPU compute time, in parallel. This is essentially a couple of shelves in a datacenter rack, totally maxed out on power and cooling, abstracted behind a cute little /code-review command. The author, here, is rightly concerned that "Anthropic could pull the rug out and require API pricing", which is perhaps a code word for "charging something closer to actual costs". Brian also pays lip service to environmental and societal costs but those are largely abstracted away, so let's keep that conversation aside here as well, as we have discussed it before anyways. But clearly, this way of working has an (externalized) cost, to say the least.

Paying for non-free tools For decades my work has been focused on free and open source software. I've long stopped using proprietary operating systems like Windows or Mac, and even before that switch, I was mostly using free software on those platforms, partly out of principle, but also because I was too poor. So the tools of my trade are free, and I build free tools with them. It feels like we're going backwards: when I was in school, a millennia ago, my classmates didn't have access to a compiler and were wondering how they would scrape the money to buy a compiler like Borland's or Microsoft's. I had a compiler built into my operating system (FreeBSD at the time), so that wasn't a problem for me. For them, it was a significant expense, but at least those expenses (or more shady sourcing of programs) were a one-shot deal. Fast forward 30 years, and software is rented: you pay monthly for Adobe's Photoshop and Microsoft's office suite just like you pay for Netflix, Disney+ or Spotify2. And now you need to add dozens (if not hundreds of dollars) of monthly credits to access LLMs on top of that. So, now we have to pay to get anything done? This is peak enshitification of our job: first they steal our work to train their models, and then they sell it back to us at a profit.

Attacking the engineers AI is coming for our jobs, as engineers, if not everyone, according to the narrative. For a while now, our job market has deteriorated: less jobs, for less pay. Lots of skilled engineers looking for work and finding crap jobs then still looking while working. This is not by accident.3 We engineers have a lot of power, it is not organized, but that's just a couple of unions away (easy!). Tech overlords know this, so they are attacking our profession, directly, by forcing us to train and use models that they can control. Even in environments where programmers are not forced to use LLMs, the mere pressure of other people's LLM-generated work is huge. One can be forced to review LLM outputs, or just peer pressured you into producing more. We're now supposed to accelerate delivery, because models can presumably do things so much better and faster. With supply chain security becoming such a large vector that we now have worms crawling around developers accounts on NPM, increasing the delivery cadence seems like a really bad idea.4 The LLM hype is part of the larger wave of cyberwar against workers, against water, against the Earth, against all the people. This is not a matter of individually "adapting to the reality" or personal choice, but a political, social, hard problem we need to address collectively.

  1. I again prefer the term LLM to "AI" because models do not possess intelligence. I did use it in the title because click baiting is apparently important, but I stopped short of calling this one "Rage Against the Machines" because that would be the title of every blog post I have ever made.
  2. Yes, I know that Visual Studio is kind of free now, but I wouldn't be surprised if they turn that into a rental as well, because why not.
  3. Beyond sabotaging the job market, Sam Altman event wants to sell "intelligence as a utility" something that is just a really bad idea but especially shows how megalomaniac those people are.
  4. This brings back memories of another era, walking us back decades in terms of computer security.

18 August 2026

John Goerzen: AI in Debian: The Vote, Proposals, and Nuance

Let me start with a hypothesis:
For human developers, using coding LLMs magnifies their difference in skill levels.
I am one that rarely thinks things are always black and white. Back in March, I wrote Artifial Intelligence: Shades of Gray. Since then, I ve had more of a chance to experiment with LLMs myself. I also happen to work for an employer that is taking a very pragmatic approach to LLMs: teams and individuals use it as they see fit, but if they are causing considerable expense, they have to justify it. In various settings, I have seen the egregious examples of AI slop we all know about. As I wrote in March, I have seen it both waste more time than it saves, and save a ton of time. I have come to see that, as a tool, it is most valuable when it is running under the supervision of an experienced engineer. It is at its worst when it has no such supervision; the vibe coding and other low-quality slop we see. A coding agent is like a junior developer or research assistant. When properly supervised, they help projects move along more quickly by letting a senior developer focus on the more difficult, less mundane aspects of the project. But one couldn t expect a junior developer to consistently deliver high-quality code and architecture on their own. Let s put a pin in this idea and look at the story in Debian. LLM use in Debian There is a vote happening in Debian around the use of LLMs. In typical Debian fashion, there are 8 options to choose from, many of them similar. Most of these proposals acknowledge there are different types of tasks done in Debian, but the proposals don t differentiate between them well. Let me do so here. These are some of the LLM-relevant tasks people in Debian perform: I m going to focus my remarks here on packaging upstream software for Debian, since this is by far the most time-consuming developer task project-wide. It matters to our users that we get this right, and packaging quality is one of the things that sets Debian apart from other distros. Packaging things for Debian requires knowledge of some specific tools, such as debhelper, that aren t widely used anywhere else. In most cases, it is fairly rote time-consuming work. In other words, by its design, it requires people with senior-level skills to do grunt work. I can t overstate how massive a burden this grunt work is. I maintain some packages for Go and Rust. By Debian policy, all of those packages dependencies must also exist as Debian packages, and be used to build against. When upstream adopts a newer version of some library, it can unleash cascading dependencies that can take hours to sort out. Worse, the Rust team and the Go team use entirely different ways of managing packages (Go uses one Git repo per package, while Rust has a monorepo with specialized scripts to import Cargo packages and generate Debian ones). On top of that, we can t just modify things like usual; we have to use quilt. And on top of that, I m also a backports maintainer, so all the work (and usually even more) has to be done there also. Now let s pull on that pin from the earlier conversation. This is exactly the kind of scenario that a well-supervised coding LLM is most effective in. I could see a seasoned developer saving hours, maybe even days, by turning over the mundane tasks of managing trees of cascading dependencies over to a coding tool and verifying and directing the process. (Yes, I have been using em-dashes for years; LLMs have copied people like me, not the other way around! This post was not written with any AI assistance.) Actually, this is almost a dream scenario for a coding assistant. The result is time-consuming to formulate but easy to review, which is the opposite of the way these things often go. I can assure you with 100% certainty that humans aren t adding a lot of value in this process. It would be wrong to believe that a human is carefully reading every line of code in dozens of updated or new library packages. The problem set is too big, the time too short, and the code too varied and complex. Coding agents seem to be most effective when there are strong test suites that they can test changes against. Debian builds, especially of modern packages, tend to have this property. Many packages have test suites that are run during build. And, if the package builds in an isolated environment (and especially if its downstream dependencies do also), then there is a decent chance that it s fairly correct. Maybe needing some manual tweaking here and there, but generally a successful build is a reasonable indicator. You can argue that it would make more sense for Debian to just include dependencies in source packages, along with some version information to support security rebuilds, and I d tend to agree with you. But we are where we are. This would be one of the more significant leaps forward in developer productivity, but it complicates things like copyright reviews. Where are LLMs run? What is the environmental impact? Most of the proposals seem to make the assumption that LLMs must always run in some large, hosted datacenter. As I noted in my March article, I have had credible results on even an older GPU running on solar power. That said, it is undeniable that LLMs are fueling a datacenter boom, and this in turn is producing a significant new demand for resources. Most notably for the global scale: electricity, which is sometimes generated using carbon-emitting technologies. Bill McKibben, who has been a leading voice in the fight against climate change since the 1980s, has made some interesting points recently: he s noted that solar power is the fastest kind of generation we can build, and a number of large AI companies are investing heavily in solar, even to the point of fully offsetting new datacenter s needs. On the other hand, he s also noted that some companies are buying inefficient and dirty gas turbines. It is decidedly a mixed bag. The heavy investment in solar can have knock-on positive effects for infrastructure. Obviously, not every picture here is rosy. This analysis doesn t touch on the real land and water use situation, either. On the other hand, if an LLM allows me to do in an hour what I would have done in a day, that s a day of not heating or cooling the work area generally not sustaining a human for the purpose of writing code for Debian. HVAC energy consumption dwarfs my GPU, and I d imagine probably also the slice of LLM energy used. Holistically, I would have to conclude the picture is mixed. It is possible to use LLMs in a pretty green way, and also in a pretty dirty way. Assuming Conditions Never Change A flaw in most of these proposals is they assume that the conditions at this present moment will always hold. In fact, that the conditions at the present moment will not continue is something both AI cheerleaders and AI skeptics agree on. For instance: Ed Zitron has done a ton of research into the financing side of AI, and has concluded that the current model is unsustainable and headed for a significant bubble burst. I m not positioned to personally evaluate those claims, but if that happens, what is the result? Perhaps it is a steeply increasing cost of inference for the frontier models, slower pace of training/evolution for them, etc. In a recent episode of Oxide and Friends, Simon Willison discussed the open weight models that are now available. They have been making remarkable strides in efficiency and capabilities, to the point where $50,000 of hardware can now run high-end open weight models with capabilities that are at least in the same ballpark as the American frontier models. This puts running high-end models locally squarely within reach of universities and small- to medium-sized businesses, with power requirements that can be met with standard commercial solar and wind installations. The lack of nuance in the more restrictive proposals is particularly concerning. Proposal A doesn t allow the use or assitance of LLMs . So it bans my solar-powered GPU. It bans using LLMs to find security issues. It bans all sorts of things that don t seem to be ban-worthy, alongside the things that do. And it codifies it in the very hard-to-change social contract. That proposal, and some like it, seem to imply that all LLM output is bad. I grant you that AI slop is a real and legitimate concern, and many Open Source projects have to deal with it. On the other hand, we have all seen first-hand how the security of the Linux kernel has benefited dramatically from AI analysis. It is certain that black hats are using these tools. If we refuse to use modern security tools, our security will be compromised (and what is the environmental and social impact of THAT?) I find the statement Generative AI is characterized by producing output of a nature that would ordinarily be produced and consumed by humans to be particularly interesting. The same was once said of compilers. The Real Concerns You might think from reading this that I am some AI cheerleader. I m not. I share the ethics of the FLOSS movement, and have for decades. I abhor the power and lack of ethics that many big names in the field are running with at the moment. I ve had to put up Anubis on this blog, for instance. I have personally experienced the effects of AI slop, especially at review time. This is a real problem, though I don t think the more draconian policies are likely to help (the looser you must disclose stand a fighting chance, but I m not sure they would help, either.) Done poorly, AI threatens developer burnout by overwhelming them with poor code and verbose but useless explanations. Done well, AI can help prevent developer burnout by automating tedious and low-value tasks. Shouldn t our goal be that humans submit work to Debian, using tools they prefer, and take responsibility for it? Does it matter if someone uses ed, vim, emacs, or vscode? If they use LSP or just run gcc manually? I d say we benefit from the diversity. Wouldn t we be better off to benefit from the diversity here, and judge work as we always have: on its merits, not what tools were used to create it? Fundamentally, a GR is a long and arduous process. It s not easy to reverse later. Amending the Social Contract is even longer and more arduous (I should know; I may have been the first one to try). The LLM landscape is fast-moving. None of us can really predict where it will be in a year. Will the current market leading companies even still exist? Will it be at all credible to refuse to use AI-assisted security tools? What is the most effective way to deal with AI slop? What level of utility will we be able to achieve with models run locally? Some of these proposals would make sense if drafted in some way short of a GR, which would allow more maneuverability as the landscape changes. Brief analysis of the options Considering the proposals: In favor of nuance I find that black-and-white thinking is almost always something to be avoided. I see it too often. I see it in politics, I see it in our software, I see it in discussions around AI. Are there deeply unethical things happening in AI? Absolutely. Are they doing some impressive things? Also yes. We have accepted this nuance in other areas. For instance, almost all the hardware Debian runs on has closed-source hardware, and has components manufactured or assembled in countries with some of the worst human rights records on the planet. I m not saying this is a great state of affairs. It is something we should speak up about and act upon. But the worse state of affairs would be no Debian because the hardware is impure .

16 August 2026

Bits from Debian: Debian turns 33!

It has now been thirty-three years since the Debian project was announced to the world by Ian Murdock, on August 16, 1993. This anniversary is an opportunity to reaffirm the goals, characteristics, and qualities of the Debian project: it s an association of individuals who have made common cause to create a free operating system. Our distribution is characterized by a commitment to software freedom, as enshrined in the Debian Social Contract and the Debian Free Software Guidelines. It focuses on security and stability. This stability is crucial to Debian position in the free software ecosystem. With our users as our priority, Debian makes special efforts regarding accessibility with Debian-Accessibility and diversity with our Outreach Programs. Debian Day is a great opportunity to get together, whether for a local meetup, or simply to grab a coffee with other members of the Debian community. Check out the Debian Day wiki to see if there is a celebration near you. And if there isn't, maybe you can organize it next year! Today is also an opportunity for you to start or resume your contributions to Debian. For example, you can install the how-can-i-help package and see if there is a bug in any of the software that you use that you can help to fix, contribute small tips on how to install Debian on your machines to our wiki pages, or put a Debian live image in an USB memory and give it to some person near you, who still didn't discover Debian. Thanks to everybody who has contributed to develop our beloved operating system in these 33 years, and Happy birthday Debian!
9 August 2026

Reproducible Builds: Reproducible Builds in July 2026

Welcome to the July 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. If you are interested in contributing to the project, please visit the Contribute page on our website. In this month s report, we cover:

  1. Tool development
  2. Distribution work
  3. Three new scholarly papers
  4. Patches
  5. Misc news

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 324, 325 and 326 to Debian:
  • Fix tests to work with zipdetails 4.0008. (#1141359)
  • Bump debhelper compatibility level to 13. [ ]
  • Update copyright years. [ ]
In addition, Paul Spooren made changes to allow trailing garbage in Gzip files [ ] and Vagrant Cascadian added an external tool reference for the pedump binary to use the mono package under GNU Guix. [ ]
disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues. This month, Christelle Gloor added the option to sort by ctime as returned by the lstat(2) syscall. [ ], which Chris Lamb uploaded whilst bumping the Standards-Version to version 4.7.4 [ ]. Bernhard Wiedemann also updated disorderfs to version 0.7.0 in openSUSE.
Yet again, there were a number of improvements made to our website this month as well. For example, Chris Lamb, by request of Digital Ocean, changed the target of a referral link so that they can manage incoming referrers [ ] and pushed a number of changes to the Tools page [ ].

Distribution work In Debian this month, 32 reviews of Debian packages were added, 26 were updated and a total of 21 were removed this month, adding to our extensive knowledge about identified issues. A number of issue types were added by Chris Lamb, including:
  • python_towncrier_build_date [ ][ ]
  • log_files_installed_in_package [ ]
  • fontforge_varies_by_timezone [ ][ ]
Chris also added a further note for the build_date_in_manpage_generated_by_spf13_cobra issue. [ ]
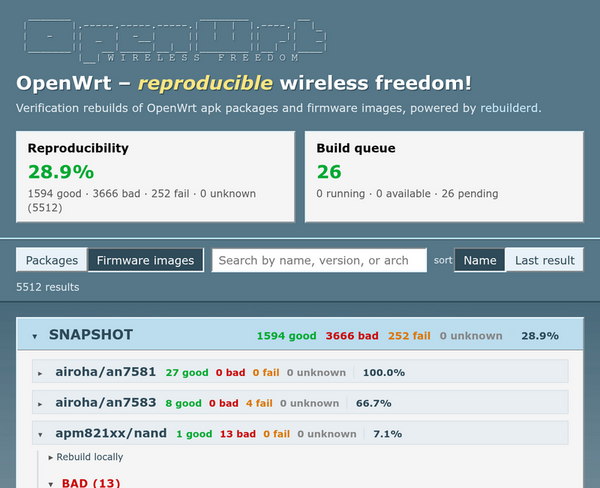
In addition, there is a new page showing verification rebuilds of OpenWrt APK packages and firmware images, powered by rebuilderd:

Three new scholarly papers Yan Li, Nan Jiang, Qihang Zhou, Shaowen Xu, Yamin Xie and Xiaoqi Jia of the Chinese Academy of Sciences published a paper titled VCAligner: Aligning Source Distribution Versions with Upstream Git Commits to Secure Supply Chain:
We present VCAligner, a content-based alignment methodology that constructs inverted indexes over VCS histories to precisely map released artifacts to their originating commits, independent of fragile version tags. We evaluated VCAligner on a dataset of 2,984 verifiable PyPI packages derived from the 4,000 most-downloaded projects linked to public GitHub upstreams. Our results reveal a critical weakness in conventional tag-based heuristics: while they appear effective on 85% of the dataset, the residual 15% failure rate generates a catastrophic downstream audit workload of over 10.3 million commits. In contrast, VCAligner reduces this burden by two orders of magnitude ( 158 ), bounding the total workload to under 65,000 commits. Furthermore, we provide the large-scale characterization of Packaging Noise, classifying artifact divergence into structural additions (Path Phantoms) and content mutations (Blob Phantoms), thereby isolating the distinct attack surfaces of malicious injection and code tampering.

Jens Dietrich and Spencer Sun from the Victoria University of Wellington together with Tim W. White and Behnaz Hassanshahi from Oracle Inc pre-published their paper No Snake Oil: Verifying Python Package Builds (PDF):
Python has become the default language for interacting with AI, with packages being distributed through registries like the Python Package Index (PyPI). This creates a need to analyse supply chains comprising such packages. One such analysis is to rebuild packages in order to identify compromised builds injecting malware. Independent rebuilds in hardened environments have the added advantage that they can generate and record provenance in order to increase the trustworthiness of packages. Two tools that are designed to automate such rebuilds and run them at scale are macaron and oss-rebuild. We study 12,180 popular releases from PyPI and find that the byte-for-byte equivalence rate is generally low. We analyse the reasons why they produce different wheels, and find that equivalence between the original and rebuilt wheels can often still be established, preserving most of the guarantees users expect from rebuildable releases. We present and evaluate daleq4py, a tool to establish the equivalence of Python wheels through the kernel of a normalisation function that is based on provenance-preserving datalog rules. Experimental results show that daleq4py substantially expands the set of rebuilds that can be accepted as equivalent. Although only 15.4% of macaron rebuilds and 19.1% of oss-rebuild rebuilds are byte-for-byte identical to the published PyPI wheels, daleq4py establishes wheel equivalence for 60.2% and 78.9% of source-equivalent rebuilds, respectively.

Denise Nanni, Julien Malka, Stefano Zacchiroli and Th o Zimmermann from T l com Paris together with Gabriele D Angelo from the University of Bologna pre-published their paper Understanding Build Reproducibility in the F-Droid Ecosystem (PDF), which was accepted at the 2026 ACM Conference on Reproducibility and Replicability:
The security of open source applications benefits considerably from the possibility of rebuilding their source and verifying the output. F-Droid, a prominent distribution for open source Android applications, systematically rebuilds them from source and tests their bitwise reproducibility at app publishing time. However, F-Droid offers no guarantee that app reproducibility will continue to hold in the future. As software ecosystems evolve, reproducibility may degrade, with potential negative consequences for software preservation and security. We present the first empirical study of build reproducibility in the F-Droid app ecosystem. Analyzing historical reproducibility logs, we find that the overall bitwise reproducibility rate has been steadily increasing over time (as new versions of apps are published). We then evaluate how reproducibility holds in time for fixed app versions, by attempting to rebuild 18 904 app versions that F-Droid had previously confirmed bitwise reproducible, published between September 2018 and February 2026, achieving an 83% rebuild success rate, and identify missing dependencies as the dominant cause of failure, accounting for 76% of non-rebuildable cases. Among successfully rebuilt apps, 94% are also bitwise reproducible-i.e., they still yield bitwise identical artifacts upon rebuild. Together, these results show that while bitwise reproducibility largely holds for apps that can be rebuilt, rebuildability itself is highly sensitive to temporal decay.

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Misc news On our mailing list this month, Colin Winter of Markovian Protocol wrote to our mailing list on the topic of Reproducible verification for retained logs:
Reproducible builds remove trust in the builder: anyone re-derives the same artifact from the same source, byte for byte. The same shape applies one layer over, to a retained record. Most record-keeping regimes (the EU AI Act s Article 12 logging is the current example) require that events be recorded and logs retained, but not that a retained log be verifiable, by a party who was not present, as unaltered and existing when claimed. That leaves an integrity obligation resting on trusting the party being audited.
(Full thread)

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

3 August 2026

Bernhard R. Link: I learned something new about URLs today

Today I stumbled over some behavior that I found quite surprising:
$ ipython3 -c 'import httpx;print(httpx.URL("https://example.com/foo/bar/../../baz"))'
https://example.com/baz
Even more surprising that behavior is actually standards-compliant, even mandated by RFC 3986. The underlying motivation is relative reverences. If some resource reachable by "https://example.com/foo/bar" references another resource relatively as "../../baz" then this is of course the intended result. Getting from this problem to what RFC 3986 suggests might be surprising in the result, but somewhat understandable if you look at the consequences of that problem: Giving the path components ".." (and ".") special meaning at the start of the relative reference means that if you allowed them in absolute URLs those would be impossible (or at least very convoluted) to address as relative URLs. So RFC 3986 describes a way to handle them everywhere: Just join the path of the base URL and the path of the relative reference and normalize the result. Or normalize the absolute on either side if only that is to be taken. This makes things very convenient: Multiple reference URLs can just be joined without special handling for relative references starting with dots, making writing applications handling them easier. Programmers don't have to care how to handle relative references and can just join everything in whatever way they want. For maximum elegance there is still some corner case left: What happens if an absolute URL has a path starting with double-dot components? Or an relative path starting with more of them then the base URL's path has components. You just ignore them:
$ ipython3 -c 'import httpx;print(httpx.URL("https://example.com/../../baz"))'
https://example.com/baz
With that last point every URL is valid and has well-defined meaning. Handling relative references and relative paths is very easy and convenient. So this shows a high regard for simplicity, elegance and convenience. And a total and uncompromising disregard of security. After all the most convenient it is for an attacker; If they are allowed to supply a path component for a request a system does in their behalf, then they can easily escape anything they were supposed to be limited to. The ignoring of dots at the start means they don't even have to know exactly how deep their request is:
$ python3 -c 'import httpx;print(httpx.URL("https://example.com/public/api/public/resources/harmless/../../../../../../../../../internal/data"))'
https://example.com/internal/data
So even if the resource server securely handles request (unless you consider not having any way to lower your permissions for one request to a specific subset), your fully RFC conforming client library will already request the permission they should not have permission for. Even worse dots are usually not characters you can easily forbid so once slashes are to be allowed things get complicated. There also would have been a simple, elegant and secure way: Consider every path element ".." or "." in an (absolute) URL an error. Define a reference resolution that allows the relative reference to only start with "./" or one or multiple "../" and consider every appearance of a dot or two dots as path components after than an error. Everything joining two paths has to either use an implementation of that path joining algorithm, but only if they want to joins paths in the potentially dangerous way allowing leading "../". Otherwise they can just use the normal join and even if an attacker gets those dots that will just cause the generated URL to be rejected as invalid. Of course using a secure implementation is now even more inconvenient thanks to RFC 3986 being around: If you have no control over the generator of relative references, it is always possible that they generate relative references with ".." components after non-dot components. And if you check all code to properly filter out "/../", keep in mind that convienence does not stop there. After all it is not unheared of for server implementations to helpfully normalize unicode characters, too, or translate them to their nearest ASCII equivalents. Or translate percent escaped characters back before doing path splitting. Or you might think there was some unicode codepoints between those two dots, but they that those were some meaningless control characters that can be omitted. So you need some really restrictive allow lists...

31 July 2026

Otto Kek l inen: Estonia, the country of the fit and the wit

Featured image of post Estonia, the country of the fit and the witWhile many Western democracies seem to be in a state of decay and are no longer the safe, civilized and prosperous countries they once were, there are still some European countries that are governed well. One of those that stand out is Estonia. Estonia is probably most well known for multiple software companies that originated from there, such as Wise, Bolt, Pipedrive and Skype. The government itself is also famous for being early in issuing government IDs with an embedded smart chip for online authentication already in the 1990s. Via the national portal at eesti.ee all residents can access extensive eServices ranging from viewing their health benefits to filing taxes. Estonia has also been running an e-Residency program since 2014, where they issue digital ID cards to foreigners, making it easy for them to remotely log into the government portals and for example, establish businesses, file annual reports and so forth. Note that the e-Residency is not a path to physical residency. Estonia does, however, have a separate Digital Nomad visa program that makes it easy for non-EU citizens to also physically establish themselves in Estonia, assuming, of course, you meet the criteria, which includes, among others, a minimum monthly income of 3960 from outside Estonia. EU citizens naturally have free mobility inside the EU and can simply get an apartment and register as a resident in Estonia if they so choose. And there are plenty of reasons to do so.
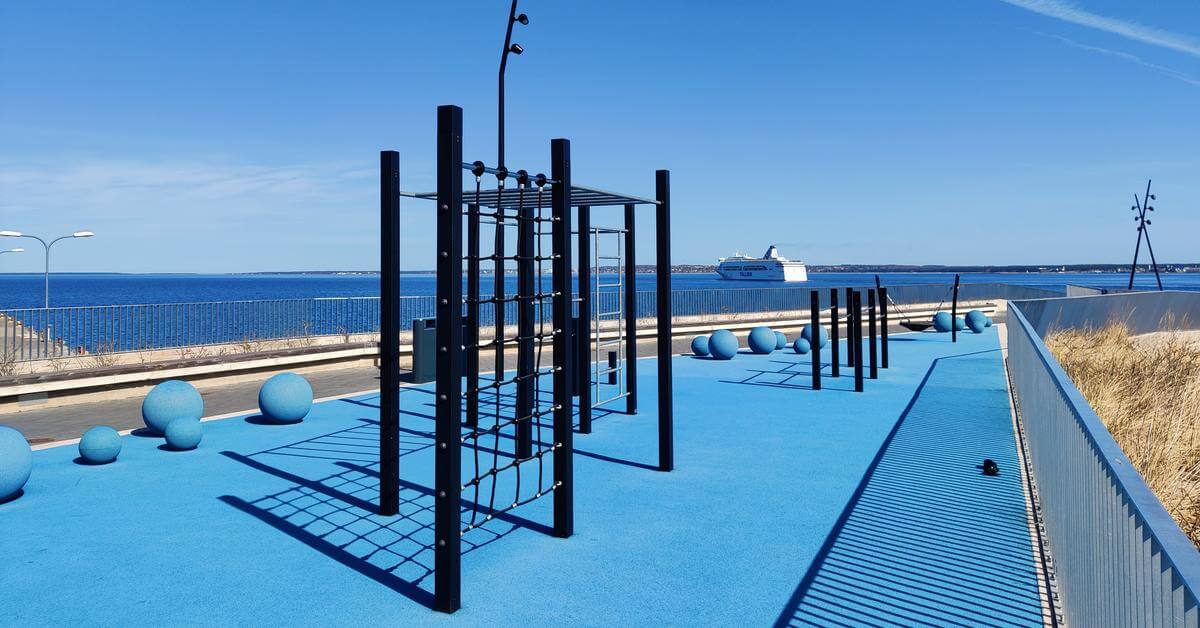
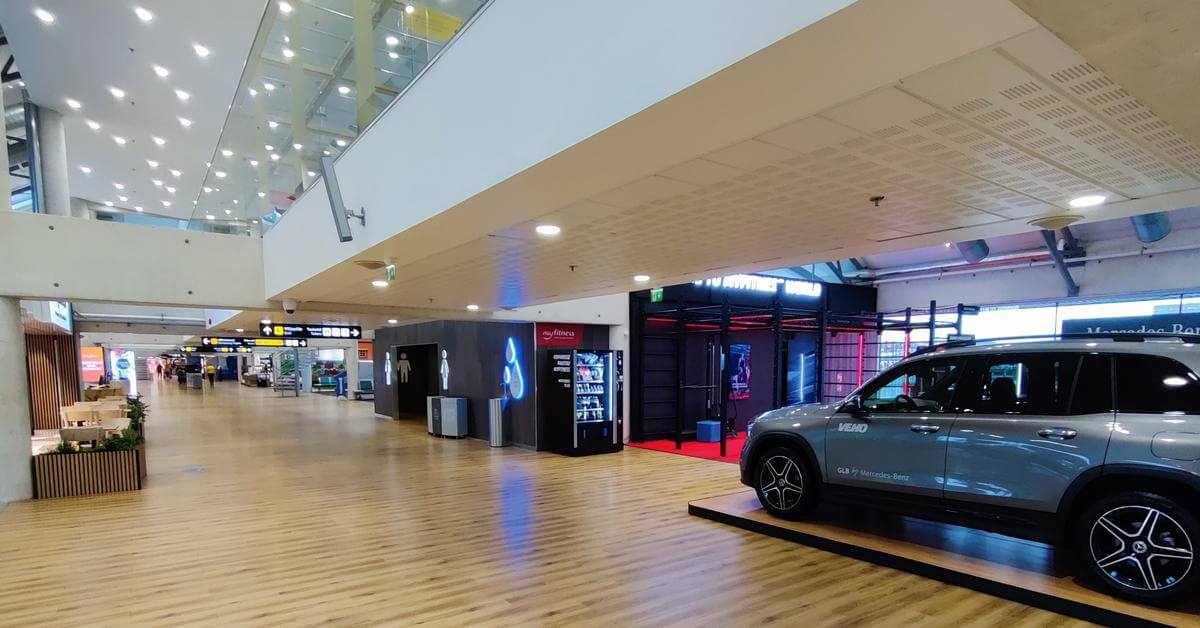
Estonians value health, education and entrepreneurship I moved to Estonia about one and a half years ago. In my observations Estonia strikes me as a country that values health, education (in particular programming and natural sciences) and entrepreneurship highly. I don t know how Estonians achieve it, but they look pretty fit and rarely obese. Estonia has rye bread and sauna in their culture just like Finland, and in addition the flat terrain and well-planned bike routes and extensive network of parks (and pull-up bars everywhere) seem to create an environment where it is easy to live in a healthier way. The consumption of processed foods and candy also seems relatively low among Estonians. The gym chain MyFitness also seems to be present everywhere. Even the Tallinn airport has a calisthenics workout station right at the departure gates, which anyone is free to use while waiting for their flight to take off. One of the top longevity influencers in Europe, Siim Land, is Estonian. Estonia has lots of good bike paths, parks and outdoor gyms There is even a calisthenics station with pull-up bar and more at the departure gates at Tallinn airport Estonians also seem to value the school system highly. The government has been actively raising teacher pay and has a stated goal of reaching 120% of the national average by 2027. The students are also expected to value the education and respect their teachers. According to the TALIS 2024 survey (OECD s international teacher survey), Estonian teachers spend significantly more time on actual teaching and learning and waste less time on interruptions or keeping classroom order compared to the OECD average. This is among the highest rates internationally, meaning they spend relatively little time on maintaining order or dealing with disruptions. While the international education benchmark PISA scores have been dropping globally, Estonia has consistently been climbing the ranks in past decades. In the latest PISA study (from 2022), Estonia ranked number one in Europe for reading, mathematics and science. In the overall results, Estonia ranked seventh globally, only behind countries such as Japan, Korea and Singapore. Valuing entrepreneurship is evident in how the taxation system is set up in Estonia. Famously, in Estonia, companies can defer taxes on annual earnings and reinvest all of their profit in growing the company. Taxes are due only later, when paid out from the company, for example as dividends. For individuals, receiving dividends from any Estonian or foreign company is tax-free as long as the company paying dividends already paid corporate tax on the same income. The tax system is also very simple. For all individuals, all types of income, including salary and capital gains, are always taxed at a flat rate of 22%. This removes the incentive for anyone to try to convert income into different types, setting up holding company structures and other optimizations as there is no gain. All entrepreneurs can simply focus on growing their business and forget extra bureaucracy. There is also no marginal tax rate cliff to stop working at everyone is encouraged to always try to produce as much value as they can. A simple tax system is also reflected in the fact that anyone can easily read all tax rules that apply to individuals in plain English on the Estonian tax authority website, and one does not need to hire any accountants simply to file taxes. Estonia also has a very straightforward investment account system: any person can freely open a self-directed investment account at any brokerage at no extra cost and report it as such to the tax authority, and then use it to save for an apartment, retirement, or other purposes, and defer all income taxes until withdrawal. There are no caps or time limits, and all residents are encouraged to save and invest as much as they can and thus take responsibility for their own wealth accumulation. It seems that culturally Estonians respect people who are active and progress in their careers and businesses more than in other countries. Unlike in Finland, successful people are admired and living on government welfare is not romanticized. At the same time, the government benefits are less generous so people can t live comfortably on them and, for example, many of the asylum seekers Estonia accepted have since left on their own initiative to other European countries in search of better benefits.
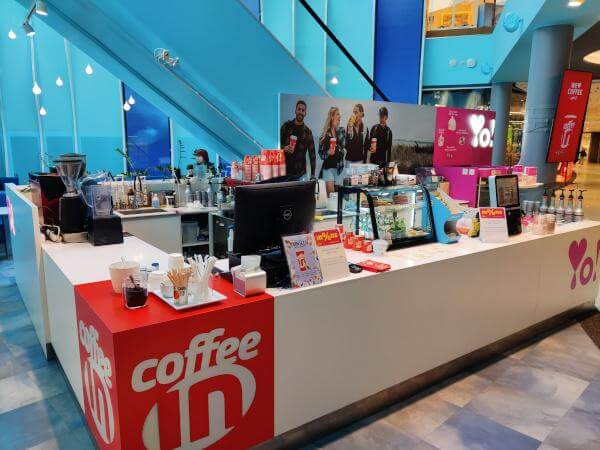
Low crime, high trust Another thing that strikes me when walking the streets of Tallinn is that there are no drug addicts, beggars, thugs or the like. The difference compared to, for example, Vancouver (where I lived previously) is stark. In public buildings, people leave their coats and bags hanging in the lobby while visiting. Private houses and apartment block yards are not fenced. In my building, I noticed people even leave their bikes unlocked in the bike shed. I have also seen the staff of a coffee stall in a shopping mall going for a break and leaving everything unattended, not worrying that anyone would take anything while the staff is away. Nobody is stealing anything from the unattended coffee shop while staff is having a break at  lemiste shopping mall This is not just my personal experience. According to the Numbeo crime index, Estonia has one of the lowest crime rates in the world. Also, comparing drug and property crime stats, for example, Finland has twice as much crime per capita, and places like Vancouver in Canada almost five times more. I don t have any clear explanation for why crime is so much lower in Estonia, but some suggest that higher social cohesion and lower levels of welfare contribute to people standing to lose more if they behave antisocially. Compared to Finland, Estonia also more readily jails repeat offenders, and those who are put on trial will experience a swifter court process thanks to simplified legal processes and more efficient governance.
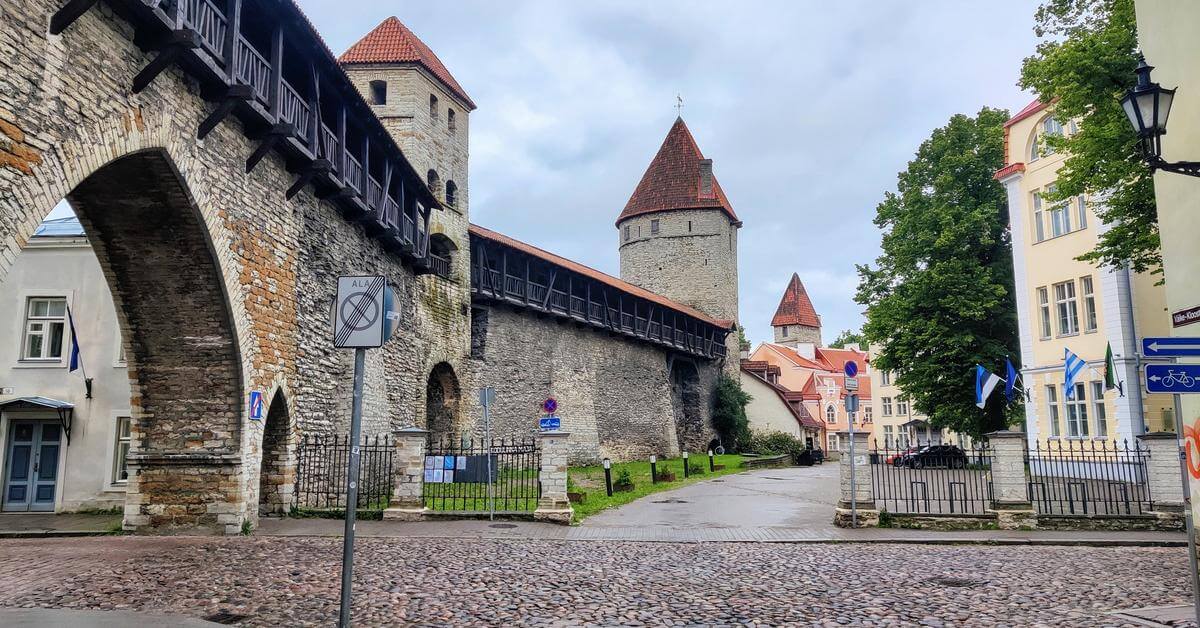
Moving to Estonia: quick checklist Moving to Estonia is very easy for any EU citizen, in particular if your work is not location-dependent (e.g., remote work or an online business) and you are simply looking for the cleanest and safest environment to live in. First, check into a hotel in Tallinn, check out various neighborhoods to figure out what area you like (my favorites are Kalaranna, Kalamaja, Noblessner and Volta) and start browsing available apartments in English at kv.ee. Most professionals speak fluent English, so there should not be any difficulty in reaching out to people by email or phone. Tallinn is famous for the old town The economic boom of recent decades created a lot of new construction, with Kalaranna being among the newest areas The next step is to buy a local prepaid SIM card at e.g., an R-Kiosk or a convenience store as signing up for other matters later on will require an Estonian phone number. Once you have an apartment and e.g., signed a rental agreement, you can register in the population registry online. After that, you have proof you are a local resident with an address and telephone number in Estonia. With local resident status, you can go to the police station to get a local ID card. Don t bother scheduling an appointment, just go to the Tammesaare police station in Tallinn, take a queue number and wait. Once it is your turn, they will guide you on how to use the photo booth, fingerprint registration device, and file your application. A few days later you will receive an email confirming whether your application was accepted, and after a few more days, you will get another email notifying you that your ID card has been printed and is available for pick-up at the same location. This will also be your first practical experience of how fast and efficient the government in Estonia is. Once you have the local ID card, you can use the smart card feature to log into all the government eServices and sort out the rest of the relocation process, such as registering tax residency and getting a family doctor. The main eServices portal in Estonia: eesti.ee
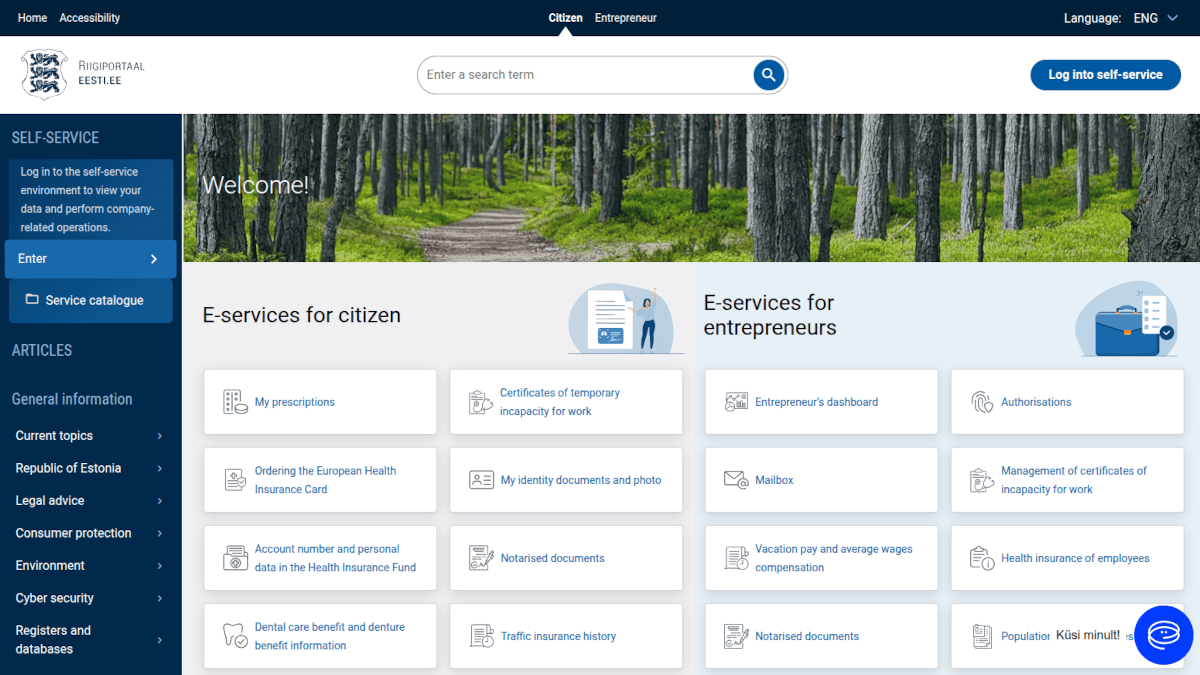
How did Estonia evolve to be like this? After Estonia regained its independence after the fall of the Soviet Union in 1991, the first elected government in 1992 was led by a very progressive 31-year-old Prime Minister Mart Laar, who managed to set up some very good policies and laid the foundation of a society that has evolved well in the decades since. Estonia was very lucky to have people in power in the 1990s who didn t simply copy what other Western countries were doing, but who tried to think about things from first principles and create Estonia s own model for efficient and fair governance. As a post-Soviet country, the population had also been vaccinated against overly socialist and unrealistic ideals, and everyone had a healthy distrust of the government s ability to solve problems and emphasis was placed on people s liberty to work for themselves as they best see fit. The improvement in living standards over the past 35+ years has also been witnessed by the population, and voting behavior supports keeping the country on the same trajectory. General living standards still continue to improve as the nominal wage growth sits at around 6%, clearly above the annual inflation rate of about 3%. In 2026, the Estonian economy is expected to grow about 2.4%, which is faster than the EU average. The growth in Estonia is not the result of any accounting tricks - Estonia is part of the euro and can t print its own currency, nor has it been funding the public sector with excessive debt. With a 24% debt-to-GDP ratio, Estonia consistently ranks as one of the most responsibly managed countries among advanced Western economies. As wages in Estonia soon catch up with the EU average, and higher defence spending has forced the government to raise taxes in recent years, the economic growth that Estonia has enjoyed for 35+ years since it exited the Soviet Union might slow down a bit in future years. The policies that fueled this growth in living standards, however, are likely to stay.

The tiger leap There is one specific government policy in Estonia s history that I think should be highlighted in particular. Estonia was very progressive by announcing the Tiigrih pe (Tiger Leap) program in 1996 with the goal of equipping all schools with computers and teaching all students the basics of programming. This surely had a large influence on why Estonia has so many successful software companies, why the government eServices are so mature that even neighboring countries like Finland are striving to copy the Estonian government s IT architecture called X-road. The Tiigrih pe project was originally suggested in the mid-1990s by Toomas Hendrik Ilves, then ambassador of Estonia to the United States, Canada and Mexico, and later President of Estonia in 2006 2016. While he was a psychologist by education, he was also a self-taught amateur programmer and used his political influence to promote sensible adoption of information technology in both Estonia and the EU. The history of Estonia has several prominent figures who were not lawyers by profession but engineers, scientists and historians who were very practical in their political decisions, which I think is now reflected in how government processes were formed. The video below shows how the Estonian government advertises itself and what values they choose to highlight:

Should other countries adopt policies from Estonia? Of course, not everything is perfect in Estonia either. The fertility rate of 1.16 in Estonia is very low. This trend is present globally, but in Estonia it is way below the EU average. Also, the service culture is something that needs to improve in Estonia. While services are in general fast and efficient, the attitude of people working in cafes and stores does not reflect a willingness to fill in gaps if the standard process falls short, nor are visitors actively made to feel welcome as individual humans, but are treated as mere process inputs. However, many of the things listed earlier I think should be studied by policymakers elsewhere. Societies are complex systems and there is of course no guarantee that copying a single policy to another country with different ethnicities, history and ingrained culture would lead to the same policy outcomes. But considering that Estonia is a small country without favorable geography and no natural resources, and that it started out from a place of total chaos, low economic activity and high crime in 1992 to rise to what it is now in 2026, the success it has seen is surely largely a result of good policies, governance and culture that other countries can and should mimic.

29 July 2026

Joey Hess: my harddrive is probably not full

I enjoyed reading this post by Marginalia "Your harddrive is probably full"
You can construct an entropic argument that there are simply more ways for a harddrive to be full than ways in which it can be empty.
Of course it made me check how full my laptop drive is, and indeed it was more than 75% full, as predicted. But, I almost never feel that my hard drive is full. I can very easily free up almost any amount of disk space at any time, without any thought. While writing this blog post, I ran a single command and now my harddrive is 50% empty.
The other part of the equation is that a full disk isn t a problem until it s so full you can t put more stuff on it, and at the point it s so irredeemably cluttered that when you do clean it up, you only have the patience to clean up enough to bide your time, judging the fate of every file on the harddrive is simply too much work.
Why doesn't this apply to me? Because I have put in the up-front thought to organize things, so that I never have to do that anymore. I have 3 categories of files that I can remove at any time I need more space, without any thought:
  1. Any files that are stored in git-annex. This is one of git-annex's superpowers; you can git-annex drop any file and stop it using disk space, but the file is still there (as a broken symlink) so you don't risk losing or forgetting about it.
  2. Caches.
  3. Files in ~/tmp/, which is reserved for any files I only want to have a passing acquaintance with. If I'm not comfortable with something being deleted at any time, I don't put it there.
Not only do I only have these 3 categories, these are the only 3 categories for everything except OS files and files I have decided I never want to remove (eg dotfiles and other files stored in git repos). Computer scientists invented caches (and of course cache invalidation is no problem lol) so I only needed to learn about that one. Unix gave me /tmp/ as an example that I long ago used as the basis for the rules for my ~/tmp/. I hope that git-annex might also serve as an example that moving files between drives is not the best way to manage disk space use.

27 July 2026

Dirk Eddelbuettel: #057: Conditionally Quieten Compilers

Welcome to post 57 in the R4 series. R packages with compiled codes can use the file src/Makevars to set compilation flags. We often rely on this to set libraries, include directories or compilation options. When using external libraries, be it header-only or via headers and linking, we are often experiencing compilation noise when these libraries tickle warnings under generally-recommended flags such as -Wall -pedantic. Two packages I maintain are clearly repeat offenders here: Eigen, and BH. Both cam generate pages and pages of compiler output. This is generally not great as it may hide genuine warnings from our own code. What makes matters worse is that some of the available and specific options for the compilers are treated by R CMD check as non-portable leading to a nag on package checking. Examples are -Wno-parentheses, -Wno-maybe-uninitialize or -Wno-nunnull. I have long resorted to adding these to my per-user ~/.R/Makevars. When added there, compilation is quieter, but R CMD check still nags here where the option is set but not at CRAN or r-universe. A situation that is not ideal but what somewhat stable . More recently, I realized there was an available check we can use to conditionally add extra compilation flags but leave them off by default. That makes local development quiet allowing us to focus on the quality of our additions here without noise from third-party libraries we may use. At the same time we do not need to do anything else to let CRAN do its work. The check we now use is whether there is a .git/ directory present. If so, we are indeed building from local sources and can add extra flags. If not, we are likely building from a tar.gz source archive which is the case for CRAN and hence do not set these. An example use is this recent additional to package qlcal where this bit of R code is invoked from a minimal shell script configure and replaces the stub @XTRAFLAGS@ in src/Makevars.in (or src/Makevars.win.in)
if (dir.exists(".git"))  
    ## development from a .git directory can use these flags
    xtraflags <- "-Wno-nonnull -Wno-deprecated-declarations"
  else  
    ## else build from tarball so stick with existing flags
    xtraflags <- ""
 
win <- if (Sys.info()[["sysname"]] == "Windows") ".win" else ""
infile <- file.path("src", paste0("Makevars", win, ".in"))
outfile <- file.path("src", paste0("Makevars", win))
lines <- readLines(infile)
lines <- gsub("@XTRAFLAGS@", xtraflags, lines)
writeLines(lines, outfile)
With this change, local compilation is quiet, yet CRAN has nothing to nag about (as seen at the qlcal results page). Similarly, one can also check from an actual configure file written in autoconf. Here is a similar example from RcppEigen (showing some relevants parts of the whole file)
# PKG_CXXFLAGS initialized earlier ...

## Check if building locally
AC_MSG_CHECKING([whether .git/ exists])
if test -d "$srcdir/.git"; then
    AC_MSG_RESULT([yes, adding extra flags])
    AC_SUBST([PKG_CXXFLAGS],["$ PKG_CXXFLAGS  -Wno-ignored-attributes -Wno-maybe-uninitialized"])
else
    AC_MSG_RESULT([no, consider adding '-Wno-ignored-attributes -Wno-maybe-uninitialized' to ~/.R/Makevars])
fi

AC_SUBST([PKG_CXXFLAGS], ["$ PKG_CXXFLAGS "])
AC_CONFIG_FILES([src/Makevars])
AC_OUTPUT
Once again, with this change compilation is quiet locally, yet unaffected at CRAN. Just what we want. Give it a try in your packages.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

21 July 2026

Dirk Eddelbuettel: qlcal 0.1.3 on CRAN: Micro Bugfix, Build Tweak

The twenty-first release of the qlcal package arrivied at CRAN just now, and has been built for r2u. It comes a week after the 0.1.2 release. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over seventy country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases includes a one-line fix we also sent upstream as a now-merged PR: one of the calendar files added in QuantLib 1.43 also needed to include the vector header file. And every compiler appears to be lenient (QuantLib itself has fourty different continuous integration jobs, we test with all builds at r-universe) apart from the CRAN macOS x86-64 machine. Sigh. This is now fixed. We also included a neat little local trick I should blog about: if the build is detected as a non-CRAN local build (simply by checking for a .git directory) then compiler flags can be updated to quieten the build. We cannot do that in the package because we would get our fingers slapped over so-called non-portable compiler flags . Sigh again. Anyway, the trick helps. The full details from NEWS.Rd follow.

Changes in version 0.1.3 (2026-07-21)
  • Add missing 'vector' header to new IslamicHolidays calendar file, also PRed upstream and merged there
  • In local compilation out of git repo add additional compiler flags

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

20 July 2026

Tim Retout: Renewal relationships between AWS certifications

When you pass an AWS certification exam, sometimes it can extend the life of related lesser AWS certifications. But I could not find an illustration of exactly which ones, so here s an up-to-date diagram: AWS Certification renewal dependencies Figure: Renewal relationships between AWS certifications. Each arrow is a renews relation there s no obligation to pass lesser exams before the harder ones, but you could also follow the arrows backwards if you want to learn easier material before sitting the more difficult exams. I have made two important simplifications to the graph:

  1. The Advanced Networking Specialty certification is being retired soon, so I ve omitted it entirely. The last date to take that exam is 25th August 2026. But Specialty certs don t renew anything else anyway.
  2. I have left out transitive relationships in order to simplify the graph so e.g. if you pass a Solutions Architect Professional exam, it also renews any Cloud Practitioner certificate you might hold, even if you do not currently hold the relevant Associate certificate.
You also have the option of sitting each exam again to renew of course, and there s a new scheme to maintain various certs via AWS Skill Builder which can extend them by one year rather than three.

15 July 2026

Dirk Eddelbuettel: qlcal 0.1.2 on CRAN: Fresh Upstream Updates

The twentieth release of the qlcal package arrivied at CRAN today, and has been built for r2u. This version synchronises with QuantLib 1.43 released today as well. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over seventy country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases updates to several new calendars (see below), and extends the calendars for Israel to some added new conventions, updates a few helper functions, and turns on ccache for continuous integration builds. The full details from NEWS.Rd follow.

Changes in version 0.1.2 (2026-07-14)
  • Synchronized with QuantLib 1.43
  • Calendar updates for India, Israel, and South Korea; small interface update for Israle
  • New calendars for Croatia, Malta, Montenegro, North Macedonia, Serbia, Slovenia, Uzebekistan
  • Updates to a number of QuantLib helper functions
  • Continuous integration now uses ccache via a setup action

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Freexian Collaborators: Debian Contributions: Python 3.14 as default transition, DebConf 26 preparations, debvm, pconr and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-06 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Python 3.14 as default transition, by Stefano Rivera Debian has had Python 3.13 and 3.14 in unstable and testing since December 2025, with Python 3.13 as the default version (/usr/bin/python3 = 3.13). This gave time for packages to implement support and detect issues in their test suites. A slot to transition to 3.14 as default was requested from the release team in March, and they indicated that we would likely be able to schedule it in late June. In preparation, Stefano reviewed the open bugs against Python interpreters and squashed some in uploads of the latest point releases of Python: 3.13.14 and 3.14.6. Also in June, Python 3.15.0 beta 2 and beta 3 released. Stefano uploaded these to Debian experimental. The 3.15 betas were reason to attempt to revive review of a blocked upstream patch to support Debian multiarch in stable ABI Python extensions, now that Python 3.15 is adding a new stable ABI abi3t.

DebConf 26 preparations, by Stefano Rivera, Antonio Terceiro, Lucas Kanashiro, Santiago Ruano Rinc n and Anupa Ann Joseph DebConf 26, the annual Debian Developer Conference, is being held in Santa Fe, Argentina, in July. Stefano Rivera, Antonio Terceiro, Lucas Kanashiro, Santiago Ruano and Anupa Ann Joseph contributed to the preparations for the event.
  • As usual, Stefano has been supporting the conference website and registration, helping the local team to get accurate data on attendee numbers.
  • Antonio has been supporting the conference website and helping the content team to put together the conference schedule.
  • Santiago has been helping the local team on different topics regarding logistics.
  • Anupa assisted with the accommodation arrangements for DebCamp and DebConf, working alongside Nattie.
  • Lucas has been coordinating the conference schedule and communicating with some speakers.

debvm, by Helmut Grohne The debvm tool used for creating and running ephemeral virtual machines saw a number of small improvements. The requirement of having a filesystem label has been removed in favor of using a uuid and /etc/fstab is no longer created. A memory balloon is enabled by default and this enables qemu to automatically release free guest memory to the host. Booting Ubuntu VMs regressed as a result of their use of uutils and has been fixed. The --architecture flag is back to be able to better support Hurd, which is a work-in-progress of Johannes Schauer Marin Rodrigues. Thanks to Jochen Sprickerhof, you can more easily create VMs for autopkgtest-virt-qemu using --hook-dir=/usr/share/mmdebstrap/hooks/autopkgtest-create-qemu. There also are a few documentation and error message improvements. All of this is pending in git waiting to be uploaded once development slows down. While booting a machine from virtiofsd succeeded, turning the proof-of-concept into production remains for later.

pconr, by Helmut Grohne At DebConf25, Helmut reported on a schroot substitute called unschroot. The second iteration uses varlink IPC to construct a container. That varlink API is now separated into a new project called programmable container runtime. It is meant to provide more flexibility in constructing containers than established solutions such as the unshare command from util-linux, bubblewrap or podman provide while still managing repetitive complexity such as process orchestration for the developer. A new example that uses this infrastructure is a better containment for mmdebstrap eliminating chroot escape. There also is an asyncvarlink/0.3.2 release taking steps to become more maintainable in Debian to eventually get pconr into Debian.

Miscellaneous contributions
  • Stefano did routine uploads (mostly new upstream versions) of python-pip, python-pipx, hatchling, dh-python, beautifulsoup4, python-virtualenv, python-mitogen.
  • Stefano uploaded a snowball mini-transition: snowball, snowball-data, and pystemmer
  • Stefano did some debian.net team admin, setting up a container and later a VM for vote.debian.net.
  • Stefano responded to a semi-escalation to the Debian Technical Committee, after some communication between an upstream, a bug reporter, and a Debian package maintainer went sideways and got heated.
  • Emilio managed several transitions, and filed bugs against the few remaining GCC 13 rdeps.
  • Antonio did salsa maintenance work, debugging service issues, approving user registrations, and processing support requests.
  • Antonio worked on Debian CI maintenance, including but not limited to deploying new armhf and armel workers, fixing bugs and preparing an upcoming release of debci.
  • Antonio did several maintenance tasks for MiniDebConf websites.
  • Antonio uploaded ruby-bunny, ruby-sinatra and ruby-mustermann, fixing a few FTBFS bugs among them.
  • Carles using po-debconf-manager: Reviewed Catalan translations for 5 packages, submitted 6 packages. Added a draft blog/update about the po-debconf-manager project.
  • Carles submitted a new Geeqie Catalan translation: it had accumulated a large number of untranslated strings over the last 4 years.
  • Carles contributed to the Debian wiki: improved documentation for the Framework Laptop and added a new section Battery charging control (after doing some debugging and testing). He wrote a page about Signal Desktop. Carles started looking at testing/documenting Mailman2 -> Mailman3 migration.
  • Carles, in relation to the migration process, double checked old pages without relevant information in the Debian wiki.
  • Thorsten did another upload of package hplip to fix some bugs.
  • In the context of the Google Summer of Code 2026 project, Santiago continued co-mentoring Aryan Karamtoth, who is working on the Linux live-patching project. As part of the team, Santiago guided Aryan to help design the different workflows and to study the different tools available, including the upstream klp-build (that was introduced in v6.19), and compare it with SUSE s klp-build.
  • Colin clarified the bug tracking system s documentation to indicate that maintainers may sometimes reasonably ask users to file bugs upstream themselves.
  • Colin fixed 15 packages for pytest 9.1.
  • Colin fixed a depthcharge-tools regression with Python 3.14 as default that broke debian-installer builds.
  • Helmut continued to report undeclared file conflicts and correspond about them.
  • Helmut wrote patches for strace to enable cross building and a 32bit personality on arm64.
  • Helmut continued maintaining rebootstrap working fixing build failures in fontconfig, gettext and sqlite3 as well as changing the way packages from gcc builds are installed to better serve a need reported by Samuel Thibault.

11 July 2026

Reproducible Builds: Reproducible Builds in June 2026

Welcome to the June 2026 report from the Reproducible Builds project! In these reports, we outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. If you are interested in contributing to the project, please visit our Contribute page on our website. In this month s report, we cover:

  1. Only installing reproducible packages with repro-threshold
  2. Distribution work
  3. diffoscope development
  4. From our mailing list
  5. Documentation updates
  6. Patches
  7. Four new scholarly papers


Only installing reproducible packages with repro-threshold A very interesting demonstration is now available showing how you might configure your Debian system to only install packages that have been reproduced by m/n rebuilders. This is implemented via a reproduced+https:// APT transport ( a mechanism for communicating between the APT client and its repository source commonly HTTP):
Every package download is intercepted by repro-threshold, which queries two independent rebuilders for a signed attestation before allowing installation to proceed. [It] is important to note that [an] install will only succeed if all package dependencies are also reproducible.
The demo gives examples of how to quickly experiment with this using a Docker container.

Distribution work In Debian this month: The IzzyOnDroid Android APK repository reached its next milestone this month, now covering 2 out of every 3 apps (66.7%) with reproducible builds. Their documentation for debugging and fixing failed builds has steadily grown as well. More clients have picked up showing reproducibility results (e.g. Droid-ify), and Neo Store now can be configured to stick to only reproducible applications. Further, an independent builder has been added to the build farm, increasing the trust level even more as APK builds can have multiple confirmations now. At the same time, IzzyOnDroid s rbtlog got several new features. The most outstanding is caching for frequently used resources such as reproducible-apk-tools, command-line tools and NodeJS in order to counter ongoing issues with GitHub availability, while at the same time saving bandwidth and build time. This change also enables some other some smaller enhancements such as being able to configure build timeouts per recipe for those builds running longer than the average, release pattern filtering for update checks or having a field for maintainer notes to shortly summing up e.g. why a reproducible build failed.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

diffoscope development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 319, 320, 321, 322 and 323 to Debian:
  • Debian adds an extra Flags: line in the output of ocamlobjinfo, so adjust the test for cross-distribution compatibility. [ ]
  • Bump debhelper compatibility level to 14. [ ]
  • Fix compatibility with Ocaml 5.4.1. [ ]
  • Use --long-form-style arguments when calling apktool in order to support apktool version 3. [ ]
  • Support Androguard version 4 and previous versions at the same time. [ ]
  • Update copyright years. [ ]
In addition, Jochen Sprickerhof added better header detection for the Sphinx documentation system [ ], Michael Daniels fixed the tests when run with zipdetails version 4.006 [ ] and Zbigniew J drzejewski-Szmek added a version of the deprecated os.path.commonprefix method [ ]. In addition, Vagrant Cascadian updated diffoscope in GNU Guix to version 321 and 323.
Chris Lamb also made the following changes to strip-nondeterminism, our tool to remove specific non-deterministic results from a completed build:
  • Skip symlinks when manually called via /usr/bin/strip-nondeterminism. (#1139000)
  • Update debian/watch format. [ ]
  • Drop Rules-Requires-Root: no and Priority: optional fields. [ ]
  • Bump Standards-Version to version 4.7.4. [ ]

From our mailing list On our mailing list this month:
  • kpcyrd posted to our mailing list regarding the waves of malware uploads to aur.archlinux.org . Curiously, every incident I looked at used npmjs.com for malware delivery , specifically where the npm package includes an (automatically executed) preinstall script that is an ELF binary.
  • kpcyrd also announced the release of debian-repro-status version 0.4.0, a tool written to give you an approximate idea of how viable it would be to enforce a reproducible packages only update policy for the computer system you ve built :
    The change updates dependencies to the latest versions, and adds support for multiple -H options, to query results from multiple rebuilderd instances. The results are also now fetched concurrently.
  • kpcyrd also reported that, whilst taking a screenshot for the above release, they noticed that the debian:sid container now is 100% reproducible.
  • Finally, kpcyrd also created a pull request against the add-determinism package to update the itertools and zip Python dependencies.

Documentation updates Yet again, there were a number of improvements made to our website this month including:
  • Chris Lamb added a reminder re. using the UTC variants of the Javascript Date methods. [ ]
  • Mattia Rizzolo moved OTF to the old sponsors list. Thank you for your support!. [ ]
  • kpcyrd updated the Rust documentation to recommend using the --release argument for consistency. [ ]

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Four new scholarly papers Kenichiro Muto and Kuniyasu Suzaki of the Institute of Information Security in Yokohama, Japan published an interesting paper this month titled Attestable Build Chain: Enabling Trust in Reproducible Builds (PDF). Their abstract is as follows: Ensuring trust in software supply chains requires verifying not only artifacts but also the processes that produce them. Although Reproducible Builds (R-B) require rebuilding to validate artifacts, they cannot verify whether the build was executed with the intended toolchain and inputs and may reproduce unintended or compromised builds without detection. We present Attestable Build Chain, a framework for externally verifying build-time execution without rebuilding. Rather than preventing compromise, it provides verifiable, tamper-evident evidence of actual build-time execution, enabling verification of build process integrity from observed file accesses during the build. [ ]
Julien Malka, Stefano Zacchiroli and Th o Zimmermann published a 50-page report detailing A Decade of Software Reproducibility in the Nix Package Ecosystem:
We find that functional package management enables extremely high rebuildability over time (near-universal ability to reconstitute historical build environments and rebuild software packages), while bitwise reproducibility has steadily improved and reaches a high point in recent years (up to 93% in 2024). Early years show substantially lower bitwise reproducibility, indicating that functional package management alone does not guarantee bitwise-identical outputs, and that the observed high level of bitwise reproducibility is not solely due to the package management approach. Common causes of unreproducibility, both in the rebuildability and bitwise reproducibility dimensions, include management of dates in build and test processes; we quantify their prevalence and other common causes using manual analysis of logs of rebuild failures and automated analysis of diffoscope.
A PDF of their report is available online
Tim Bastin of L3montree GmbH and Jacek Galowicz of Applicative Systems GmbH from DevGuard published a paper detailing How We Built a Sovereign, Reproducible Container Supply Chain for DevGuard:
This paper presents how the DevGuard project rebuilt its OCI container pipeline around reproducible Nix builds and independent dual-platform digest verification. DevGuard images are built hermetically from pinned source revisions, signed with Sigstore/Cosign, and verified through digest comparison across GitHub Actions and sovereign GitLab infrastructure hosted on container.gov.de. We describe the practical integration of reproducible OCI image builds into existing CI/CD workflows and argue that independently reproducible container digests provide a stronger integrity guarantee against build tampering than provenance alone. The paper further discusses remaining trust assumptions and the relevance of sovereign build infrastructure for government and regulated environments.

Finally, Yiseul Choi, Junga Kim, Jun-Ho Hong and Seongmin Kim of the Department of Convergence Security Engineering at the Sungshin Women s University in Seoul, Korea titled Attestation-based verification of SBOM integrity via consumer-side reproducibility:
Software bills of materials (SBOMs) support supply chain transparency, but they do not prove that a delivered SBOM reproducibly corresponds to its software artifact. Existing signing and provenance mechanisms protect integrity and traceability, yet lack consumer-side reproducible verification. We propose an SBOM integrity verification framework combining procedure disclosure, consumer-side reproduction, authority-generated reference evidence, and digest comparison. A trusted authority records a reference digest, and consumers compare it with locally reproduced and delivered SBOM digests. Experiments on 100 real-world container images show detection of artifact tampering, SBOM substitution, distribution modification, and adaptive tampering beyond signature-based approaches


Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

10 July 2026

Tim Retout: Blocking distracting news links

You are what you eat but perhaps this is even more true of our information diet. It is hard to strike a balance between remaining a well-informed citizen versus spending hours ingesting unnecessary news about issues and events we can t affect. But I m increasingly convinced that my hours lost to doomscrolling are down to design choices by web publishers rather than a failure of individual willpower.

We have created an obesogenic information environment I don t think it is just me I think our information environment has been progressively altered over time as news sites look to maximize engagement. Even outside of social media, the invisible hand of the market for eyeballs forces sites to optimize for browse time or risk irrelevance. Even as newspapers find it increasingly difficult to fund good journalism through advertising in an online world, especially local journalism, they need to keep readers on their sites, clicking through as many articles as possible. Clickbait headlines, urgent flashing live icons to draw the attention, and many opportunities to leap from one article to another, and another. But this design approach even extends to news organisations with a different funding model, like BBC News, which is a public service (state-owned but arms-length) organisation funded through a mandatory television licence a matter of controversy in some quarters. And it extends even to sites where I pay a subscription fee; I might get adverts removed, but I am still bombarded with the same design philosophy; too many opportunities to be pulled away from what I m reading towards some other unrelated article. Even if I try and limit my exposure to algorithmic discovery of new news, via RSS feeds or similar, if I m reading the full article in a browser then I am prompted to read more stuff that I didn t intend. This defeats the benefit of curating a set of feeds, because you still get dragged away to random articles.

Only 44% of BBC News is news To show you what I mean, I m going to pick on the BBC, although I love them dearly and the same issue very much applies elsewhere. I ve taken a screenshot of a random BBC News article in mobile view (my preferred doomscrolling user access device), and measured approximately what proportion of the full length of the page is taken up by each section. This is a fairly in-depth news article, so I reckon if anything the figures would be worse than this on shorter articles. A full-length screenshot of a BBC News article showing proportions of the page allocated to the main article vs. related links etc. (These numbers will not sum to 100% for reasons which are obvious if you look at the crossbars. Also they re approximations.) Less than half of the page (44% if you exclude the inline related links) is actual news text/images; the rest are links trying to help you find the next thing to read/watch. I do not want this. I m sure this A/B tests well in terms of reader figures, but it sometimes leaves me exhausted it must take subconscious mental energy to ignore, or I spend too much time trying to keep on top of things. And remember, this is a publicly-funded site that does not rely on advertising!

Blocking out the noise If you are technically-minded, you can use an ad-blocker such as uBlock Origin to take back some control. Applying the following lines as a custom filter (Settings > My filters) brutally cuts out almost all of these links:
bbc.co.uk##aside
bbc.co.uk##footer>div:has(h2)
bbc.co.uk##[data-block="uploaderEmbed"]
bbc.co.uk##[data-block="links"]
Caveat emptor: I have not road-tested this for more than half an hour, so who knows what consequences this could have on your web browsing. In particular, international readers outside the UK will likely be redirected to bbc.com, the commercial arm of the BBC, where these rules will need adapting. Is it unethical to use an ad-blocker to remove these links? I would argue not. I am not depriving the BBC of any revenue, because I pay my licence fee. I might reduce the amount of time I spend on their website, but if anything the subjectively better experience might encourage me to consume more news from them, not less. In other circumstances (outside the UK for instance, where the BBC relies on advertising), the balance might be different.

Product managers, please find better metrics I lament the state of the internet in 2026. I now can t unsee these innocuous related stories links as a mechanism to grab my attention, and it s gone too far. If you are a normal person just browsing the news and looking to discover the latest important stories relatively quickly, I can see that these types of links might actually be useful for discovery; but I m actually reasonably sure that I m not going to miss out on anything major. You still have the option of the news home page if you want to be presented with more news for example, and it feels natural to go back to there when you ve run out of stories to consume. But it shouldn t be down to individual responsibility to ignore or geekily block these types of link; news sites with alternative funding models should find better metrics for engagement than hours spent on site how about optimizing for customer mental wellbeing, or minimizing time required to catch up with the news? There s no need to maximize clicks and eyeballs. This is a societal level issue, because we are all going mad with news over-engagement. Product managers, over to you.

6 July 2026

Aigars Mahinovs: How to make a good group photo

Taking a good group photo consists of multiple aspects: I can say with confidence that nearly everything here comes from having failed to do these things right at least once, even on the latest attempts, so this is an ideal to reach towards, not something we expect to hit every time. The Goal The main goal of a big event group photo is capture both the moment itself and each individual person inside that moment. We want people, who were not there to see all the people involved and get an impression of what it was like being there. It needs to show the breadth and depth of people that make up this group, this project. And we want people who were there to be able to look back the next week, the next year or in ten years and remember - ah, yes, I was there, I was standing right there with this grin on my face next to this wonderful person and I was feeling great. Hardware Based on the goal we want to have high level photographic gear that is able to capture both a broad enough picture to encompass all the people and some of their surroundings to communicate the context (without undue distortions) and to deliver enough detail and resolution so that faces and facial expressions and underlying feelings of every single person in that group could be clearly seen and preserved. To both capture the context and minimise distortion the final picture should be just a bit wider than normal human field of view. That is about 50mm for a full-frame camera or 35mm for a typical 1.6 crop camera. You can go a bit wider if there are no better alternatives (as detailed in the scouting section), but be prepared that corners of the image will be distorted and not really usable (but we can fix that in processing step). Or you can go to unusual aspect ratios, like we did in Debconf 10. In the absence of a 100MP+ camera, you will need to be stitching together multiple frames to achieve resolution high enough to have enough pixels-per-face to see emotions clearly. This means that the photos you will actually be taking will be tighter than the overall field of view mentioned above. Still, a higher resolution camera body is preferable - nowadays 24MP-32MP cameras APS-C provide a good compromise between resolution and price, but 45-67MP full-frame cameras also exist on the market. Assume that we will be shooting in a bright environment, so most likely with quite low ISO settings, that means that high-ISO noise characteristics of more expensive cameras will not really play a role here. You will also not need very fast burst modes, even manual speed of one frame per second is sufficient. You will also want to get as much detail as possible out of your lens, and this is the most important part. You can do amazing work in all other steps of the process and have a great camera too, but if you pair it with a lens that is not sharp, then the end result will be disappointing. You want the lens that is sharpest corner-to-corner when stepped down to about f/8-f/11, that you can get for your system. You also want that lens to be about 85mm full-size sensor or 50mm for 1.6 crop size. Luckily that kind of range is also a great range for optical design and sharpest lenses are typically available in exactly these kinds of sizes. You absolutely want to have a fixed focal length lens, not a zoom lens. Even profession grade zoom lenses often deliver worse image quality compared to fixed lenses that cost less 1/10th of their price (when shooting in the same focal length). Newer design lenses are better than older lenses - optical design, coatings and precision manufacturing have advanced a lot over the decades. Retro look is great for mood, but not as good for actual resolution and clarity. You don't need to overpay for most expensive lenses because those often only improve image quality on lower F-stops. To encompass the whole group we will need to shoot at f/8 and in bright light, so the extra benefits of those f/1.2-capable super expensive lenses will not come into play here. We will have no use for a flash here. A tripod will be too restrictive when rapidly repositioning the camera between different parts of the panorama shoot. But a monopod might help with stability - I have not tried that myself, however. For my last photos I used a Canon EOS R7 (32.5MP) with Canon RF 50mm f/1.8 STM lens and considering an upgrade to Sigma 56mm f/1.4 DC DN for the next time. Scouting Scouting a good location for the group photo is another big chunk of a successful picture. The critical piece of the puzzle is lens-to-face distance. In order to keep everyone's face in-focus and have enough resolution on the farthest faces (without making nearest faces truly massive) we want to do everything possible to reduce the variance in lens-to-face distance - to reduce the difference in distance between closest and farthest face. The most effective way to do that is to have the photographer climb higher. To see this in action on the Debconf photos, compare Debconf6 (very high camera position, group on level ground - good) to Debconf10 (camera not too high, group on stairs, still good) and to Debconf17 (camera could not get high enough and the group is on flat ground - not great). Even the Debconf25 photo was suboptimal from this perspective. The Debconf23 photo was a very good example from the recent years - good height and also the group was positioned in a semi-circle so there were no people directly in front and very near to the camera. So you are looking for the highest point you could get to (even if that requires a special permission of key or a ladder) with a field large enough to fit the whole group comfortably. How to check that? Normally I simply take a photo from the top of the whole area and note down from there where the extreme corners of the group could be and still be fully seen in the shot - not blocked by trees, buildings and shadows. Then I go down and measure that space. Rule of thumb being - people in one horizontal line can stand 1 normal length step from each other and two horizontal lines can be half a step from each other vertically. So I can just measure a rough rectangle in steps, multiply the sides, multiply that by two and I have the rough number of people that can fit there for the photo. Once you have a candidate location or two, it is important to check them at the same time-of-day as you plan to do the photo (see organization section for that). You want to make sure that the whole area of the group is in the same illumination - if half of the group is in the sun and half in a shadow, then you will be having a very bad time later. The absolute ideal positioning for the group photo is to have everyone be in shadow, but still have enough bright skies and bright buildings in front of the people to give good illumination of the faces. Worst you can do is have the sun be behind the people (so all the faces are really dark) and second worst is have the sun be directly in front of the group, so that the faces are very well illuminated, but everyone's eyes are closed because they are being blinded by the sun. And sometimes all you can do is pray for some light clouds to provide for even and dispersed light. Debconf23 was very lucky that way. Another consideration is to how people are going to get to that place. You need to consider accessibility needs of people (it is ok, if it takes more effort or time, but it needs to be organized and communicated well in advance). And you need to consider how the big masses of people will be getting there - how to tell people where exactly it is and how to get there from various locations where people might be hanging out during the event? Having an alternate location indoors might be necessary if the weather report for the next days is not sufficiently predictable. We had to use that contingency in Debconf9, for example. Organization It's hard to take a good group photo if half of the group does not show up or is too late, so this needs some organization to happen smoothly. First of all you need to choose date and time for the photo. The photo does not take too much time from the schedule of the event and can be squeezed in after all the other events are already scheduled. In fact I prefer that as it allows you the flexibility of choosing the date based on weather conditions and time based on light and shadow conditions in potential photo spots. You don't want to choose the daytrip day as most people will be away and return times are not really predictable. You do not want to choose the morning after Cheese and Wine party for obvious reasons. First day and last two days are also sub-optimal as some people arrive late and some leave early for various personal reasons. Also you don't want it to happen just before Cheese and Wine either because then you'd have very little time and clarity to do the processing of the image on the same day. For timing, the best way, in my experience, is to schedule the photo directly after the end of talk sessions before a meal break - lunch or dinner. Typically in the Debconf schedule there are 2-3 daily breaks planned, say for Debconf25 there was lunch, afternoon break and dinner. Talks are planned to end ~10 minutes before those breaks (and meals) begin, so for example, afternoon break starts at 16:00 and all talks in the previous block end at 15:50. In such a case just schedule the "Group photo" event from 15:50 to 16:05. This gives people the info to go there directly from the end of all talks and that they will have sufficient time for break/meal afterwards. Do not forget to specify the location (as exactly as possible) in that event entry and make sure to post it at least two days in advance. People often want to wear something specific for the photo and thus need to know about it in advance. This also makes sure that people do not make alternate food plans for that specific break and don't leave the venue. Announce the date, time and the exact location as wide as possible, don't be shy. Announce and discuss mailing lists, IRC, Signal, Telegram, make sure the front desk knows in case anyone asks in-person, ... Check that it is again included in the announcements email on the day preceding the photo date. When the date has arrived, it is a good idea to check in early with people with special mobility needs to make sure they know where to go, how to get there and how much time they will need to be able to get there on time. As the final round of talks before the group photo is starting up, it is time to recruit "runners". I've had great success with this technique. The idea is pretty simple - for each room where people congregate (talk rooms, hacklabs, cafeteria, outside hackspace, front-desk, ...) go there and choose one person. You want to choose a person that you will recognise and remember among everyone else in the group, either because of who they are or what they are wearing, whatever works best for you. If they agree to help, instruct them to: "at end of talk, announce that the group photo happening now and the location, herd people towards the photo location, be the last person out, make sure there are no stragglers from this area behind you, when you arrive to the photo place I will assume that everyone else from this room is also now there, when you are there catch my attention and show this sign so I know for sure that it is all good and make sure that I did see it from you". With that sorted out all you will need to remember is how many runners you recruited and how many have reported in to figure out if everyone has now arrived or if we still have to wait for someone or some group. Then you will only have one last point of organization left - shaping the crowd into a group. People will not know what your vision for the group photo is, so you will have to give clear and LOUD instructions on where people should not be standing. Use clear, large gestures to support your words. You want to compact the group, have the people that just joined in the last moment and are standing to the side come deeper in and join the crowd. Have any holes in the middle of the crowd filled in. Forming a semi-circle instead of a blob helps with averaging face-to-lens distances. Make sure people are not in unexpected shadows. Make sure carried objects, like umbrellas of flags do not cover the faces of other people. Take the time to look at everyone face to make sure there are no people hiding behind someone's shoulder - typically they are not aware that their face is in fact not really visible. If there are such people, call them out and point directly at them and encourage them to step forward, if they wish to do so. You are the only one seeing the final picture now and only you can correct it before capturing the moment. So a few extra seconds here are worth taking, even if 300+ people are standing in scorching heat and waiting on you. When you are happy with what you are seeing, make sure to tell people clearly that you are now about to take the pictures and again remind them not to move and explicitly not to turn their heads to the side until you are done (this is the source of most of the extra work in processing). Be very loud and clear and make sure you have everyone's undivided attention before you start saying the important stuff. When done - say so. There will be other groups that will want to also have a photo taken after the main group is a bit more dispersed, so don't run away. Typically at least the T-shirt group will want a picture and also all the organizers. Final bit of organization during the group photo shooting itself is the sneaky self-insert. You may choose not to bother with it, or do it in the simplest way, like I did in Debconf6, but if you really want to blend in with the crowd, you need to have someone else take a photo of you in the exact same location at the same date and time from the same location. So you should already during shaping the crowd decide where you would fit in, it is easiest to blend in at the back of the crowd and to one or other side, so that it appears like you are just standing behind the shoulders of a couple peoples. Remember that spot - it is easiest if you stand in the exact same ground spot when your photo is taken. Just go down, recruit a volunteer to take your photo, make sure the settings are fixed to the same ones as for the group photo shots and have them take a handful of shots of you - one of you centered in the camera frame and a couple more with you more towards the corners of the frame. This distortion from being off-center in the frame may be important later. Preparation In addition to preparing the crowd for the photo, you also need to prepare yourself and the equipment. Make sure you have dusted your camera sensor and cleaned both inside and outside glass of your lens. It is usually a good idea to remove any filters from the lens. Install the hood, if that could help with blocking the sun flares. Make sure you have the right lens and that you have installed the right lens. For fixed settings I typically shoot in JPEG with RAW being there more like an emergency backup. The extra dynamic range of RAW could be used, but it is really complex to do that in combination with image blending and it is hard to get right, so I prefer an all-JPEG workflow and fix the dynamic range in the scene itself, before shooting. For Canon I am using the Standard profile that boosts the color saturation and sharpness a bit as I just enjoy that look and find it hard to get anything significantly better from RAW data even with a lot of effort. In any case make sure you have enough space on the cards to take at least 100 images and that you have a full battery. Do not use high speed burst setting because it is then too easy to take too many pictures at the start of the sequence and be stuck with your camera still in "Busy" state writing big RAW files to slowish SD cards and not allowing you to finish the full picture rapidly. You want to have the shutter speed at at least 1/100th of a second to prevent blur from both your hand movements and also from people in the shot moving around a bit (image stabilisation will not help you there). And you want to have the aperture to be around f/8 - lower apertures risk people in front or behind falling out of focus, make the lenses look less sharp. Higher apertures also start to become less sharp due to diffraction effects above f/8. ISO should stay as low as possible, ideally at ISO 100, but if there is not enough light then upping the ISO to 400 would be the first step that I would try to do and second would be decreasing the aperture to f/5.6. If there is too much light, then increasing the shutter speed should be the safe thing to do. As people start to arrive into the shooting location - check the exposure and nail down the settings, ideally in manual mode. Consider that left side could be a bit lighter or darker than right side. Err on the side of making the picture a bit too dark as there is more depth to darkness before cut-off compared to clipping on the high end. However, do not trust the exposure detection, instead take a picture and look specifically at skin tones in faces of people that already are standing in the photo area. Faces are the key bit and the exposure needs to be adjusted just to the faces and ignore darker of lighter clothing. Do some test shots and find settings where faces look not too bright, but also not very dark and fix those settings in manual mode. Now you are ready for the action. Shape the crowd, check the faces and the action can start! Execution During taking of the group photo you want to finish it fast, but at the same time you have to take the time to make it right. If you hurry too much under pressure, you risk being left with unusably blurry images and the whole effort wasted. Having already prepared and verified the manual settings makes it easier. When you are taking pictures, you have to remain as still as possible - even at very high shutter speeds even slow hand movements are still bad for image quality. So think of the movement as of biathlon athlete shooting the very middle of five, very separate targets - take a burst, reframe, then steady up for a second and only then take the next burst. 3 frames per burst are sufficient. 90% of the time the very first photo of a burst will be best. As you move from frame to frame, aim for just a bit more than half-frame overlap. This will give the opportunity to skip frames if all is good, but also have backup coverage of every face in case of problems. Proceed systematically, I typically start off on the top left of the crowd, then go right until the end of the line, then shift down half a frame and go left until the end and repeat until I am done with the crowd. After that it is very helpful to also immediately take photos of a "frame" around the whole crowd. Stitching process often distorts the frames in weird ways that leave holes in the resulting image that you can fill if you have a wide frame around the crowd. It is possible to compensate with creative cutouts in the final image (like Debconf9), but the more framing room you make, the more flexible you will be able to be with cropping of the final photo. The frame also gives you the opportunity to capture more of the context of the place and space. As an example, Debconf25 group photo in the end consisted from 9 images + 1 for sick people + 1 for me. I ended up missing the framing shots for bottom left, top left and top right corners. To get there I took 68 images. And in some years it was more than a hundred. Processing This part might be less stressful than taking the pictures from intensity perspective, but it lasts longer. Depending on you luck, skill and perfectionism it can take anywhere from 3 to 9 hours of work to complete. Before you start, however, you should first request things that you will need for other people. This can even be done before taking the actual group photo, but usually I forget. To finish the photo you will need three things: The first two you should be able to get from the respective organizers. The motto is harder. I typically try to ask the current DPL to come up with something describing the current mood of the project or of the event, but it is rare that it is that easy. Most of the time I came up with something as I was editing the photo and reflecting on what was the mood, the feeling, the mojo of this conference and of this year was like. Bend that around a recognisable phrase or expression, make it a bit more insider-relevant and you are on the right path. Some years this was the hardest part. For the panorama stitching I will describe the workflow that has served me good for years, but maybe there are better ways possible nowadays. Feel free to let me know! First I would save all photos taken and select one sharpest photo from every burst. Next I would select the minimal number of photos that appear to be covering the entire crowd. The fewer images you use, the better in the end because the most quality problems crop up in the areas where photos are getting stitched together. Fewer seams leads to fewer issues. Open Hugin (you will also need enblend and enfuse installed) and import your minimal set of images into it. Click the "Align" button and wait a while - the processor will be trying to figure out keypoints in each image and then try to match these points between the images to try to fit them all together into a single projection. To do that it will distort the images. This is the trial and error process part. You may need to add, remove or replace images to get the stitching to work or to work better. You may want to add more of the frame images to fill the ragged holes around the image. After initial alignment, go to "Move/Drag" tab and move the image a bit up in the projected field of view and make it a bit more central visually. That will help a bit with the distortions in the near-by people and people in the corners of the image. In the "Crop" tab set the initial crop - leave it generous, you can always crop more in later steps. Do not be afraid of leaving in sizable chunks of black homes, empty skies or grass. All of that can be filled in later as well. Go back to the "Assistant" tab and click "Create panorama". It is good enough to have JPEG output at 100% quality using exposure corrected low dynamic range output option. Make sure to check the "Keep intermediate images" option. This will not only generate the final, merged panorama, but also keep around the individual images after perspective correction and exposure blending steps. These are critical for fixing blending error in the next step. You might need to go back a forth a few times with a different sets of source images, maybe adding some image between other two, maybe removing another to reach a better starting point. The key part to pay attention - how many ugly stitches are there in the image. Check every face, the blending algorithms do not recognise faces and sometimes try to stitch one face from two or more images creating very weird effects. They can be fixed in the next step, but it is rather hard manual work, so the fewer such faces are in the blended image, the less work you will have. In some years I've managed to find a combination where all faces were good and in other years I had to manually fix 13-15 faces. Do not try to blend the extra pictures (like with you or with sick people) into the main panorama with Hugin - it will get very confused with the parts of the grass that it is able to see where other people were standing. The next is the final processing in GIMP. Think of it like a large and complex project - do as much as possible in separate layers, save often. Fixing wrongly stitched faces and also putting yourself into the photo are very similar activities in the end. Just the scale and the source differ. For yourself you just cut out yourself (upper torso is enough) from the separate photo. For corrupted face, choose one of two intermediate images that the Hugin created where the face is transformed, but not yet merged (with a different version of itself). In either case crop the photo to roughly the interesting size and put roughly in the right spot as a separate layer on top of the group photo background. Reduce the opacity of the small layer to 30-40% and zoom in to 400%. With that it is much simpler to position the layer with pixel precision. Then all you need to do is add a layer mask to this layer and paint it just right. Basically in layer mask black means transparent and white means non-transparent. So you need to just make everything that is you have white mask and everything that is not you have black mask. And smudge the border a bit with finger tool or blur to make the transition smoother. Easy to say. Hard to do. This is what takes most of the actual work hours in post-processing. You might miss someone. I am sure Phill is just thrilled to see me in the very middle of the Debconf25 final picture .... But do try to fix them all. Use large, sweeping geometric figures to cover up black holes, empty grass fields and other sub-optimal corner features. And then use that newly created free space to put in a large version of the logo of this years conference, decently sized motto and slightly smaller invitation to the next years conference. Do not forget to add a copyright and license statement somewhere in the corner in smaller, but still well readable font. I am using a text like: "Photo by: Full Name, Email: fullemail@debian.org, License: GPLv2+ or CCv3-BY" This ensures that this image may be used in any press coverage (with basic attribution) and also can be included in any GPL-licensed software, if that ever comes up. The same statement is also in the metadata of the image file (see Image-Metadata-Edit metadata in GIMP) along with information that states that this is "Debian Developer Conference Group photo, City, Country, Year". Image->Image properties->Comment is another place where GIMP hides this EXIF information. For ease of use, in addition to a full-resolution image it is also useful to make a lower resolution version that would still fit on a 4K screen at full resolution, so about 3840px wide. Some photo hosting services set other limits for image size as well, so it might be needed to scale the image down below 100Mpix to upload it to Google Photos, for example. Publishing So, it is finally 1AM and the group photo is ready! How do you push it out to people? Well, in all possible ways and places. Again - don't be shy, people do really want to see it. Push it to whatever you use for your shared photos. Push it to Debconf shared git (note that this is GIT-LFS repo, make sure you know how to add content to the LFS specifically). All permanent links to that in GroupPhotosAll wiki. And then send those links to IRC, Signal, Telegram groups, debconf-announce mailing list. Publish it in your blog and push that to Debian Planet. Push it in Threads, Bluesky and Mastodon. Send an email separately to Debconf orga team. And one to Debian Publicity Team so they can put it into the Debian Home Page and push via Debian micronews accounts. And that is about it. Now you can go back to enjoying the rest of the conference. Or running around doing other things that you think need to be done. It's up to you. You did it. This moment will remain with people for a very long time. And you helped. Questions? Feedback? Just ask here or here.

Russ Allbery: Review: The Player of Games

Review: The Player of Games, by Iain M. Banks
Series: Culture #2
Publisher: HarperPrism
Copyright: 1989
Printing: February 1987
ISBN: 0-06-105356-2
Format: Trade paperback
Pages: 295
The Player of Games is political space opera and the second book in the shared Culture setting. As with most Culture books, the reading order is not particularly important. It won the 1989 Locus Award for best science fiction novel and sometimes competes with Use of Weapons as the consensus best Culture novel. This review is a re-read and yet another experiment in how to re-review a book. This time, I decided to write a full second review with substantial spoilers so that I can talk in more detail about the book. If you want to avoid spoilers, or just want to see how my thoughts have evolved from my first reading, see my original review from 2005. Gurgeh plays games. He is probably the best strategy game player in the entirety of the galaxy-spanning Culture. He has written papers on game theory, won innumerable major championships, and is a celebrity in the circle of like-minded aficionados. Gurgeh is also bored and in the middle of the Culture equivalent of a mid-life crisis. As the story opens, he's vaguely unsatisfied and adrift, unenthused by his normal activities, and searching vaguely for something that will break through his ennui. He is caught by surprise by the thrill he gets from a moment's misunderstanding in which an opponent suspects him of cheating, which sets him up to be (apparently) clumsily blackmailed by a deeply unpleasant drone named Mawhrin-Skel. SPOILERS BELOW. If you have not read this book, consider stopping here and instead reading my original no spoiler review. The first hundred pages of The Player of Games is a slow, somewhat plodding introduction to Gurgeh, his social circle, and life in (one part of) the Culture. I remember being fascinated by this part the first time I read this book. It was only the second Culture novel I read and the first set in the Culture proper, so the world-building underlying this odd post-scarcity utopia on a vast intelligent habitat with sentient drones, complex privacy rules, endless cocktail parties, and apparently directionless socialites was intriguingly unlike the other science fiction I was reading at the time. This time through, I have to admit I was less impressed. Gurgeh is not very likable, and his desultory mid-life crisis is a little boring. None of his friends have enough depth to appear as more than side notes, in part because Gurgeh doesn't seem to care enough about any of them to make them interesting to the reader. I've since read seven other Culture novels, so Banks's cocktail parties hold less charm and I was impatient for the real action to begin. These chapters are still important, though, because they establish how utterly average Gurgeh is. He has one unique talent, a deep affinity with and obsession with strategy games, and is otherwise a bit of a depressed narcissist with a few casual relationships, a friend that he barely confides in, and a comfortable and familiar life. He is not in any way a hero or a charismatic figure; he just happens to be exceptionally good at one thing, enough to make him famous among people who care about that one thing and probably unknown to anyone else apart from the occasional idly perused news headline. He is the Culture's equivalent of the world chess champion. The Contact division of the Culture has a problem. The Empire of Azad in the Lesser Magellanic Cloud is a nasty, expansionist culture of the sort that Contact would like to deal with before it causes broader problems. The Culture's normal approaches are thwarted by an unusual organizing principle: The empire is built around and takes its name from the game of Azad, a highly complex strategy game developed over thousands of years. Azad is the civil service exams, means of political and religious dispute resolution, selection mechanism for the emperor, and civic religion. Faced with that oddity, Contact turned to Special Circumstances, the Culture's more aggressive and less restrained way of dealing with tricky problems. Special Circumstances, in turn, needs someone who can learn how to play the game of Azad. They want Gurgeh to take a very long trip. For all of Gurgeh's dissatisfaction, he's not impulsive enough to take a five year journey away from his life and everyone he knows just to play a novel game. Conveniently, Mawhrin-Skel's blackmail resolves this reluctance. The game of Azad requires some suspension of disbelief. Banks provides a few glimpses at the mechanics of the game, but those details are insufficient to reconstruct the rules, and some of the claims made about its properties are improbable at best. The best mental model I could build for it is a strategy or simulation game built around units and territory control, with supplemental side games used to build up resources for the main boards, but it's more of a plot device and a set piece than a world-building invention. The significance of Azad the game is its role in society: The Empire of Azad believes they have constructed a game whose complexity so closely models reality that the skills required for success in the game are precisely the skills required for success in the empire. The Empire of Azad is wrong, and this is one of the core themes of The Player of Games. As with many Culture novels, what Special Circumstances tells Gurgeh is, at best, incomplete. Gurgeh is a refutation of the basis of belief in Azad; this is why it is important thematically that he is an average, somewhat unlikable citizen of the Culture whose only special characteristic is skill at learning and playing games. Azad is the myth of meritocracy given physical form as a game. It provides the anchor of the empire for the same reason that societies on Earth place enormous weight on standardized tests, capitalist success, or public debates. All societies face the problem of selecting good leaders and testing opposing beliefs, and all societies attempt to find some form of shortcut, some set of general principles, tests, or objective metrics used to select the best person via a process that people consider plausible and fair. The game of Azad is a paragon of apparently meritocratic process. No matter who you are or what your background is, if you excel at the game that, in theory, objectively tests your skills, you are given a position of power. In practice, the Empire of Azad is not that naive. Manipulation outside of the game happens, only some players have the opportunity and resources to spend years learning the game at a deep level, and only their dominant sex truly stands a chance in games that matter. But neither is Azad's place in society a fiction. There is corruption around the edges, and a lot of people are filtered out before the games begin, but the highest echelons of society are true believers. The game does decide both rank and policy; Banks is arguing against a strong form of apparently working meritocracy. Gurgeh represents a refutation of this meritocracy through the mechanism that breaks every supposed meritocracy: The map is not and cannot be the territory. Any objective evaluation criteria is necessarily separate from what it is trying to measure, and in that separation there is always an opportunity. Gurgeh has none of the background, training, or mindset expected for a player of Azad because he could not possibly care less about any of the things Azad represents to the Empire. What he has instead is a preternatural skill at games and vast experience with the most intricate strategy games the Culture, a much larger society, has been able to devise. He also has both the patience and the resources to devote himself entirely to learning a game for several years, and past experience in doing that with other games. If Azad represents the civil service exams, Gurgeh is the person who has no interest in ruling but adores memorizing facts and taking tests. The theory behind the exams is that the skills to pass the exam only come with the correct mindset to do the job for which the exam is testing. Gurgeh is an existence proof that this is not always the case. Banks also uses Azad to show another aspect of the failure of meritocracy: A society whose rulers are chosen through a competition takes on the shape of that competition. The Empire of Azad is run by the winners of competitive games, so the empire is a winner-take-all system of dominance and status hierarchy. Here, I think Banks lays the point on a little thick; the empire is an irredeemable hellhole of misogyny, sexual abuse, slavery, genocide, and military colonialism to a degree that is a bit hard to justify solely from the game. There is a beautiful turning point about two-thirds of the way through the book where Gurgeh's face is shoved into just how vile Azad society is and reconsiders his approach to the tournament as a result, and I think it may have been a bit stronger if the morality had been a little less blatant and absolute. To the extent that Gurgeh has political beliefs, he represents a Culture flavor of soft liberalism. He has opinions about acceptable and unacceptable ways to treat people, but he grew up in a utopia and his opinions are mostly theoretical. When he sees just how vile people can be outside of that utopia, he is revolted and appalled and redoubles his efforts to fight that society in the only way he knows how, inside of a game. This part of the book follows the standard, if enjoyable, plot of a flawed but fundamentally decent person discovering a true injustice and becoming enraged at it. In a lot of books, that would have been where the plot stops. Banks is doing something more subtle and more interesting, though. Gurgeh wipes the board with his next challenger, but that soft liberalism eventually proves inadequate. To learn the game of Azad and to play in the tournament, Gurgeh has been wrapping himself in Azad culture and its language, and in that frame of mind he is losing the climactic game of the book. It's only when he is pushed to think in Marain, the native language of the Culture, that he understands what is happening in the game and how to defeat Nicosar, the emperor. This, on the surface, is a bit too close to the strong hypothesis of linguistic relativity to be entirely plausible, but such an objection would miss the point that Banks is making here. Marain is a construct, the product of considerable effort within the Culture to match language to the most nuance and complexity that brains can understand, and it is a language, one of the most social and collective artifacts a society can produce. Gurgeh is a remarkable individual with an impressive talent, but individual skill and achievement can only take him so far. The critical final piece is the support of societal infrastructure intentionally built and maintained to help him make better decisions. Once I noticed that point, I saw it everywhere in the book. The empire repeatedly attempts to subvert or distract Gurgeh with drugs, pleasure, politics, or danger, and at each point there is some critical piece of Culture social infrastructure that blunts the attack. Illicit substances and forbidden vices are less tempting to someone for whom the illicit has been demystified by the Culture's gentler approach to rules and boundaries. Embedded biological mechanisms allow him to divert drugs so that they don't affect him. At first, it's easy to read this as an exercise of self-control, but on this re-read I saw how much behind-the-scenes infrastructure supports Gurgeh's ability to ignore temptation. This social support notably does not take the form of some ideological principle or moral framework. Gurgeh is not a monk or an ascetic, as is obvious from the first third of the book, and he has no political ideology to speak of. He is a flawed person with a streak of danger-seeking and self-aggrandizement, which the Culture exploited to get him involved in Azad. But through a lot of hard work, technological and social, the Culture has given him a robust foundation and a set of mental and biological tools that make him remarkably hard to corrupt. The implication is that if Gurgeh has that support, so does every other member of the Culture. It's neither a religion or an ideology; it's well-maintained infrastructure, complex and nuanced and pragmatic, and composed of innumerable small solutions to specific problems. I think the true climax of this book takes place the night before the final day of the game, in the tower meeting between Gurgeh and Nicosar. Gurgeh has realized that he's already won; there's nothing Nicosar can do to salvage the game. He's also seen that the game represents a cultural conflict and conversation between the Culture and Azad and he's overwhelmed by the beauty of that communication and sadness that the game is about to be over. Gurgeh's true passion is the game. It is doubtless easier for him to be magnanimous because he's winning, but he also loves the structure of the game itself and what two players can create in a sort of collaborative competition. Gurgeh tries to express all of this to Nicosar. It is one of the most centrist liberal moments I've ever read in a novel, the pure essence of "reaching across the aisle" or "disagreeing agreeably." Gurgeh has seen something beautiful, something he's created with Nicosar, a moment of true communication, and he wants to share it. Surely Nicosar sees the same thing; surely now that he sees Gurgeh has won, he can appreciate the board structure, savor the moment, understand the transient beauty of a game that is about to end and how perfectly it captures the meeting of their different cultures. That moment does Gurgeh real credit. It's a rare sign of emotional and spiritual depth in a character who often seems superficial. Nicosar meets this outreach with unhinged, furious contempt. He despises everything Gurgeh represents, everything the Culture is, and the next day he tries to kill Gurgeh on the board of the game. It is a devastating critique of liberal tolerance, all the more so because Gurgeh's attitude and outreach is truly admirable. It is perhaps the most sympathetic moment that Gurgeh has in the entire book, the moment where the reader thinks "oh, I get it, I understand what he really cares about." Gurgeh assumes that Nicosar is not his position or culture, that they have made a moment of connection that transcends all the awful things he previously learned about the empire of Azad. That Nicosar, despite being the emperor of the society that is currently doing so many things Gurgeh finds repulsive, cannot be as bad as his society. And Nicosar considers that outreach to be weak, disgusting, and vile, and does everything that he can to destroy it. One of the oddest twists of our current moment is the obsession that some billionaires have with stories that are moral arguments against exactly what those billionaires are currently doing. The most obvious example is Peter Thiel, who is obsessed with The Lord of the Rings and has devoted his life to becoming Saruman, a character who is notably not one of the protagonists. It's as if something in them recognizes the power of the story, but some deep shame or narcissism or simple aversion allows them to completely ignore what the story means. Elon Musk is obsessed with the Culture novels. He names the SpaceX rockets following Culture Ship naming conventions and has claimed that one of his goals is to bring about a Culture-style utopia. And in 1989, years before anyone had ever heard of him, Banks cast him as the villain of The Player of Games. There is so much of Nicosar in Musk: the superficial charm, the limited brilliance (Nicosar is a very good Azad player), the ambition, the pride, and the vicious, spitting contempt for everything the Culture represents at every level deeper than superficial materialism. And Banks is as clear about his opinion of Nicosar as he is about anything in any Culture novel. One of the oldest fictional answers to what a society does with people like Nicosar is the consequences of hubris. By being unable to accept defeat, by holding a vision of the world so tightly, they become brittle and unstable and bring about their own collapse. In a broad sense, that is what happens in The Player of Games with a bit of pushing from Special Circumstances. By the politics of the game, Nicosar had already won; the results of Gurgeh's earlier games had already been faked, the final game had no political consequences, and everyone who knew its true outcome could be disposed of. Gurgeh's win could have been covered up and ignored. But Nicosar could not endure the thought that he would be beaten by someone like Gurgeh, playing Azad the way that Gurgeh was playing it. Gurgeh had to be destroyed on the board of the game; Nicosar's pride did not allow any other outcome, even if it meant Nicosar's death. However, Special Circumstances didn't let hubris be the end of the story. In the climax of the book, the drone protecting Gurgeh also makes sure that Nicosar dies. There is a fig leaf of plausible deniability, but it's so obvious that even the unobservant Gurgeh sees through it immediately. It's hard to escape the feeling that was Banks's answer to what to do with people like Nicosar: They cannot live within society, because they will not live peacefully within society. I enjoyed The Player of Games as much this time through as I did the first time, but for entirely different reasons. In my first read, I focused on the world-building of the Culture, the political machinations, and the concept of games as conversations between the players. This time, I was struck by the political commentary just below the surface. Special Circumstances wanted to resolve the problem of the Empire of Azad without a military conflict and occupation that would be long, brutal, expensive, and demoralizing. They found an answer that relied on the diversity of the Culture. A vast, utopian civilization in which people can pursue whatever interests make them happy produces innumerable microspecialized oddities, people with astonishing talents in some small field that only a tiny fraction of people care about. It produces, in other words, innumerable keys for locks that you may never encounter, but which are invaluable if you happen to stumble across that lock. Gurgeh is not a hero. He is not a paragon of moral virtue, or even a charming charismatic, He is an entirely average member of an extraordinary society, the beneficiary of thousands of years of concerted effort at producing a robust, flexible foundation on which to raise robust, flexible citizens with a shared sense of basic morality. Those people, by themselves, do not solve all of life's problems; the structure of Special Circumstances and its willingness to bend rules in order to maintain them is the tension and deus ex machina in all of the Culture novels. But much of the strength of Special Circumstances is that it has an entire civilization of people like Gurgeh to draw upon when it needs them. It has those people because the Culture comprehensively rejects competitive meritocracy, something that some readers of the Culture novels appear incapable of comprehending. Rating: 9 out of 10

Next.

Previous.