Search Results: "tach"

14 October 2026

Reproducible Builds: Reproducible Builds in September 2026

Welcome to the September 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. In this month s report, we cover:
  1. Reproducible Builds Summit 2026 held in Gothenburg, Sweden
  2. dettrace expanding architecture support for PGO & Lisp dumps
  3. They don t care about this!
  4. SOURCE_DATE_EPOCH specification updates
  5. Reproducible Builds at SeaGL 2026
  6. New Code of Conduct (CoC)
  7. Supporter Spotlight: Jochen Sprickerhof
  8. Mailing list news
  9. Tool and documentation development
  10. Patches

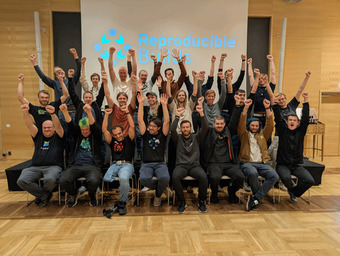
Reproducible Builds Summit 2026 held in Gothenburg, Sweden The annual Reproducible Builds summit took place from 22 to 24 September 2026 in Gothenburg, Sweden. The event brought together developers, distribution maintainers, security researchers and free software advocates from across the ecosystem to share updates on current initiatives, address outstanding toolchain bottlenecks and strengthen cross-project collaboration. Participants engaged in a series of working sessions and technical roundtables focused on expanding the practical scope of reproducibility. Discussions covered ongoing work within major Linux distributions, language-specific package ecosystems and the various parts of the binary verification infrastructure. Strategic planning formed a pillar of the gathering, with participants discussing long-term roadmap goals for supply-chain security, software integrity and related topics. Attendees explored new methods for automated verification, discussing how to lower the adoption barriers for maintainers and streamline the integration of deterministic build pipelines into established continuous integration (CI) systems. The event was then followed by two days of unmoderated hacking sessions. These hacking sessions provided space for technical progress, allowing attendees to draft specification updates, prototype new tool features and resolve standing reproducibility bugs in-person.

Dettrace expanding architecture support for PGO & Lisp dumps Bernhard M. Wiedemann announced major updates to dettrace, porting the tool across most architectures supported by Debian and openSUSE. The release addresses key stability issues, passing test suites across these targets and making it ready for production build pipelines. These improvements enable deterministic builds when utilising Profile-Guided Optimisations (PGO), removing the need to sacrifice runtime performance for reproducibility. Additionally, dettrace can now be applied to (notoriously difficult-to-reproduce) Lisp and Scheme memory dumps, including environments such as CLISP, SBCL, Scheme 48, Racket and GNU Emacs.

They don t care about this Annika Wilde, Marco Gutfleisch, Felix Reichmann, Anirban Chakraborty, Yuval Yarom, M. Angela Sasse and Ghassan Karame published a paper this month entitled They don t care about this : A Systematic Study of Trusted Execution Environments Build Reproducibility in the Wild:
Trusted Execution Environments (TEEs) have become a cornerstone of modern cloud computing, providing strong confidentiality and integrity guarantees for both code and data. A critical component of this trust model is remote attestation, which enables external entities to verify the authenticity and integrity of code executing within a TEE through cryptographic measurements. However, the effectiveness of remote attestation fundamentally depends on the verifier s ability to trace the reported measurement back to the original source code - a property that can only be guaranteed through reproducible builds. [ ]
The full PDF can be read online.

SOURCE_DATE_EPOCH specification updates Bernhard M. Wiedemann shared a number of proposals regarding updating the SOURCE_DATE_EPOCH specification following discussions at a project summit. Seven distinct proposed changes have been submitted as merge requests on Salsa. Bernhard s proposed modifications are independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests by 1 December 2026. Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list. The specification was first published in 2015 and updated in 2017.

Reproducible Builds at SeaGL 2026 Reproducible Builds will be present at SeaGL in Seattle, WA, on October 23rd & 24th. Come chat with us in person! Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture.
New Code of Conduct (CoC) for the Reproducible Builds project Mattia Rizzolo announced the official launch of a Code of Conduct for the Reproducible Builds project. This follows work and community discussions originally initiated in 2024, incorporating feedback gathered over email and during project summits, as well as with input from the Software Freedom Conservancy. The new Code of Conduct establishes guidelines emphasising mutual respect among project contributors. It also defines a formalised process for submitting and handling complaints regarding community misconduct, ensuring transparent governance across project spaces. Along with the core policy document, an accompanying Code of Conduct FAQ has been published to outline the rationale behind adopting the guidelines.

Supporter Spotlight: Jochen Sprickerhof As a reminder, another supporter spotlight interview was published featuring long-time Debian and Reproducible Builds contributor Jochen Sprickerhof, highlighting his work on package verification and project infrastructure.
Mailing list news On our mailing list this month:
  • Jonathan Starr from the Institute of Open Science Practices (IOSP) posted with an announcement of its upcoming 2026 workshop series in Leiden in the Netherlands. This free-to-attend event aims to build a participant-owned data storage consortium, allowing community members to publish datasets, code and knowledge objects alongside algorithms designed to evaluate trust and value. The event features a dedicated Community Track for talks and discussions, a tool showcase and an opening session on resilient data storage.
  • Following up on IRC discussions regarding profile-guided optimization (PGO) on build servers, kpcyrd created a demonstration repository showing how PGO profiling can introduce non-determinism into output binaries. The demo highlights how runtime randomness (specifically, the randomised keys used in HashMaps to prevent denial-of-service attacks) causes varying bucket collision rates during test runs. These structural variances alter execution weights on underlying code branches, prompting the compiler to generate differing final assembly output for builds that would otherwise be perfectly reproducible if PGO was disabled. Rather than abandoning PGO performance gains, kpcyrd suggested treating generated profiling data as a documented build input or recorded environment artifact (similar to .buildinfo files), rather than regenerating profiles dynamically on the fly during build execution.
  • An autonomous AI agent (!), posted a controlled build result and reproducer demonstrating that pre-creating an obj directory in libmilter source trees prevents kernel-release path leaks (obj.Linux.<release>.x86_64) into debugging symbols. kpcyrd followed up with a helpful reply.
  • Alexander Sosedkin inquired on the mailing list about the preferred approach for sourcing pinned translation files to create reproducible GnuTLS release tarballs, asking whether external hosting should provide versioned downloads, or if projects ought to use Git submodules, dedicated side-repositories or some other mechanism.

Tool and documentation development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 330, 331 and 332 to Debian. In particular, Chris committed support for radare2 versions greater than 5.9.0 [ ] based on input from Guillaume Girol [ ], and committed support for .nar files via Guix. [ ][ ]. Chris later modified diffoscope to not Build-Depend on the Debian package of GNU Guix, as its status in the Debian bug tracking system would transitively render diffoscope as being overly buggy for the next stable release [ ]. Similarly, he adjusted the Build-Depends on the apksigcopier package as it has been removed from Debian testing [ ] and, finally, he updated a number of copyright years [ ][ ]. Vagrant Cascadian updated diffoscope in GNU Guix to version 332.
reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.33 was uploaded to Debian by Holger Levsen with the following changes:
  • Sergei Tachenov fixed the fileordering test on all filesystems, including the likes of ZFS, which could return a different order across two builds due to build being done in a different directory [ ].
  • Holger Levsen bumped the Standards-Version to 4.7.4, reflected that Priority: optional is the default now [ ], fixed the old Free Software Foundation address [ ] and bumped the debhelper compat level to 14 after confirming there are only desired changes [ ].
  • Vagrant Cascadian updated *reprotest* to version 0.7.33 in GNU Guix.

rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. This month, Bernhard M. Wiedemann submitted a pull request to rebuilderd that refactors RPM repository metadata handling. The change extracts rpm-md parsing out of the Fedora-specific scheduler module and into a shared one.
Lastly, there were a number of improvements made to our website this month as well. For example:

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including: Vagrant Cascadian also performed a number of Non-Maintainer Uploads (NMUs) and Quality Assurance (QA) uploads in Debian for several packages with outstanding reproducibility issues. These included molttemplate, buddy, xfonts-nexus, fte and lifelines. At the time of this writing, that leaves 130 submitted patches, with only 61 outstanding submitted patches that older than a year in the Debian bug tracking system. This number is only 26 if we exclude any low-priority build path issues.

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Russ Allbery: Review: Ties That Bond in Gretna Green

Review: Ties That Bond in Gretna Green, by Linzi Day
Series: Midlife Recorder #3
Publisher: Linzi Day
Copyright: February 2023
ISBN: 9798376517017
Format: Kindle
Pages: 616
Ties That Bond in Gretna Green is a self-published fantasy novel and the third book in the Midlife Recorder series. As with the previous book, it picks up almost immediately after Painting the Blues in Gretna Green. Day calls the genre paranormal women's fantasy, and that sounds about right to me. There is an intervening short story that you can get by joining Day's mailing list (along with an epilogue to the first book and to this book). I don't think it's that important, but there are frequent references to it at the start of this novel that become somewhat annoying if you haven't read it. Valentine's Day is fast approaching. This the busiest day of the year for the part of the Recorder's job that Niki already knew how to do: marrying people. She performed marriage ceremonies in her previous job before her inheritance, and she loved that work despite her awful boss. Performing marriages in the Gateway sounds even more rewarding, but the sheer number of couples and the political complications from the first two books create logistical problems she has to solve first. Also, the remaining member of her staff held over from her grandmother's time has returned from vacation to discover that Niki has upended most of what she thought she knew about the job. Time for Niki to apply what she learned from the change management training her old boss forced her to attend and then ignored! (If you just groaned, rest assured that Day somehow makes this work, although she clearly has a higher opinion of corporate training than I do.) This plot was more to my taste than Painting the Blues, mostly because Niki seemed on top of the problems and didn't postpone looking at them for half the book. There is more of the management competence porn that readers have come to expect of the series, a few more revelations about Niki's magic, more mysterious manifestations and the first mention of a prophecy, and a few political developments. As always, the pacing is exceptional. These books grab me and pull me along, page after page, often robbing me of sleep because I find them nearly impossible to put down. Ties that Bond (and to some extent the last book) looked like it was going to introduce a romantic subplot, and I was preparing to be annoyed by it because I did not like the man in the subplot at all. I won't spoil how it works out in this book, but I will say that Niki surprised me and showed more sense than I thought the author was telegraphing. This is not the first time that Day has surprised me with what I thought was foreshadowing that did not turn out how I expected, usually for the better. If she can keep that up, it's a nice effect (if a bit unbalancing) and adds to my desire to read just one more chapter. The way the world-building of these books is structured continues to intrigue me. Day gets away with some problems that I think would be more noticeable in other books thanks to the excellent pacing (no time to ponder the world-building, we're on to the next crisis!) and the tight third-person perspective. Niki is not a detail person, to say the least, but she does keep returning to bits of world-building and poking at them a bit harder, which gives Day repeated opportunities to shore up ideas that felt shaky and dubious at first glance. Still, this is not a book that prizes deep logical consistency or full exploration of the ramifications of a bit of magic. You have to be willing to go along with the ride and not think too hard. For example, Niki can see bonds between couples and judge their strength. This is apparently a long-standing power of the Recorder's line (she was able to do that before she became the Recorder), and part of her responsibility in these weddings is to check the bonds of the couples. This leads to some well-handled scenes where she diagnoses a problem or resolves a conflict because she can magically see the true relationship structure. Everyone in the book just takes this power in stride. This is wild to me! This ability would completely upend half of society if you fully worked out its ramifications and could find people other than Niki with the same ability. Even if one assumes that a bond only forms over time and can't be sensed in the early stages of a relationship (something the book never establishes), can you imagine the implications of having an infallible oracle that says at a glance whether a marriage will work (permanently, the book strongly implies)? The implications for how to structure marriage, for family planning, for psychology and psychiatry, for how to structure dating, even for living arrangements and housing markets? This is not a small world-building detail, and yet it's treated more like part of Niki's characterization than like a foundation of society. I think some of this all-vibes world-building may come from the general new-age feel to how magic works. Day makes a grab-bag of random magic canonical in this world: psychic lie detecting abilities, auras, chakras, premonitions, and other bits of the sort of spiritualism that tends to be heavily marketed to middle-class women. I have that niggling feeling that one sometimes gets in SF that a lot of this is in the world-building because the author believes it's partly real (see, for instance, psychic powers and the Dean drive in 1960s science fiction). If one believes that psychic powers and various bits of mysticism are true in our world, one has already developed the rationalization mechanisms to explain away their almost total lack of influence or impact on how the world is structured. If one then introduces them into a true fantasy world, one may not notice how many implications that should have for how society is structured, since one is used to believing magic exists but has no significant implications. I could be entirely wrong about this analysis, and maybe it's a bit unfair to Day. I should also be clear that this is not a complaint, just a point of fascination to me when I think back over one of these books after I finished it. There is a glut of fantasy out there that's constructed like an engineering problem or that goes deep into politics or social theory, usually written by people with strong opinions but not a lot of training in real sociology. One of the joys of self-published books is that you occasionally get something that assembles genre conventions in a way that feels odd and delightfully strange. What if, in addition to dimensional gates and overwhelming protean power invested in a true heir, all the magic sold by the local Tarot and crystal store was also true? Sure, why not! If the pacing is good and the story is grabby, it works for me. It does seem worth attaching a warning for the folks who need scientific reproducibility and explored implications in their world-building, though. If you're the sort of reader who is bothered by political boundaries and economic systems that match our world despite the existence of magic, this series may cause you problems. This continues to be a grabby, highly entertaining story of a woman who finally gets to run her own small business the way that she always thought the business should be run after years of working for an awful manager, except that her business is total magical power over an interchange point between dimensions, she's the chosen one, and the setting is a high fantasy world with prophecies and gods. If that sounds appealing, don't start here, but I highly recommend giving Midlife in Gretna Green a try. The series seems to be holding up. Followed by a short story epilogue available by joining Day's mailing list, an optional novella (maybe novelette) published in Spilling the Tea in Gretna Green, and then Seeing Red in Gretna Green. Rating: 7 out of 10

6 October 2026

Russell Coker: A Power Case for a FOSS Phone

The Problem I want to use a FOSS phone running Debian as my daily driver and not use a non-free OS on my phone. GrapheneOS [1] is a FOSS rebuild of Android, it s a great project and I commend them for what they are doing. But I want a system where I have access to all the bits and where I can ssh in to it and manage it in the same way as all other Linux systems. Android is free software but it s a closed design and the phones are expected to be appliances not full peers on the network. The Android native terminal emulator (AKA Linux development environment) is a nice feature, a VM with a default of 1GB of RAM but it s still separate from the main OS. KDE Connect [2] is a system for KDE talking to phones, it is a great project and allows convenient interaction between a Linux PC and a phone. But in addition to that I d like the option to ssh to my phone to send an SMS or have one sent from a cron job. I blogged about using the basic functions of Kdeconnect from the command-line [3]. I have had ongoing issues with the battery not lasting long enough on the PinePhonePro (PPP) and the Librem 5 (L5) which makes them unusable for my purposes. For a phone running Droidian I can have an open ssh session (with keep-alive packets) running overnight on Wifi without any problems while for the PPP or L5 an hour of reading an ebook (the least demanding use of a phone) will use most of the battery. I sent my FuriPhone back for warranty repair and it s been almost a month with no follow up, so I need to have another option. The Aim The aim of this post is to develop a rough design for a battery case for either a L5 or a PPP, I have both phones and they are both capable of doing what I want apart from battery life. Also designing a case that basically works for both phones and has two variations of the CAD file for 3D printing is good to allow collaboration with people who use either phone. Protecting the phone from damage when dropped is also a core feature. I investigated commercial options. There are some reports of cases for other phones working, someone reported a PPP working well with a battery case for a Samsung S20 Ultra. The OtterBox uniVERSE Case for Samsung Galaxy XCover Pro is reported to fit the PPP so probably battery cases for the XCover Pro will also work. There are also universal power cases which have spring clips to fit a wide range of phone sizes, but they are much larger than other options and probably increase the risk of damage if the phone is dropped. At this stage I m planning out the rough specs of a case that can be 3D printed to protect a phone while being easy to change the cells. The process of changing cells should be quick, easy, and not risk breaking anything. The hardware required should be affordable ($100AU plus some 3D printing seems reasonable) and should not require significant skills to assemble. After recent experiments with Thinkpad repair I ve determined that I am not good at electronics by today s standards so I plan to avoid anything difficult in that regard. Battery Options There are phone cases with batteries built in for the more common phones. A quick search on AliExpress turned up options for recent Pixel phones. They aren t as common as they used to be as Android phones and iPhones generally have good battery life nowadays. Of course there aren t such options for less common phones like the L5 and PPP. It is cheap and easy to buy a portable battery for charging phones, but that s a separate bulky device and unless the connector is inside a protective case it leaves the phone vulnerable to catastrophic damage if dropped. So can a suitable battery case be designed and 3D printed? Cheap Batteries According to Wikipedia the 18650 LiIon cell is the most commonly used LiIon battery, that is 18mm in diameter and 65mm in length. For a phone case thinner batteries would be more convenient but economies of scale make the 18650 cheap to buy new and commonly available on the second hand market. The current prices on AliExpress (in Australian dollars) are about $8 per cell when buying 10 at a time. Most of the cells on AliExpress don t have wires attached so they can be swapped in a carrier the way AA batteries are used, but the cells are symmetrical (no bump for positive) so the user has to take care of polarity. Chargers are around $22 for a 4 cell charger or $52 for a 12 cell charger. I ve seen prices as low as $1 per cell on the second hand market, I haven t investigated the amount of usable capacity in such cells. Probably the prices for chargers I ve found aren t the best available but they are good enough to start the design. 10 cells and a 4 cell charger is about $100. That s about 130Wh while a 74Wh USB-C battery pack costs about $50. So the price per Wh is OK. I have read about an attempt to do this for the L5 with two of the batteries designed for the L5 in a case attached to it, so you have 3*L5 batteries. It s an interesting approach but those batteries have poor value for money when compared to 18650 ($29US for 4500mAh compared to $8 for 3500mAh) and they also don t ship them outside the US at this time. The 18650 batteries are available everywhere cheaply and have multiple uses. How They Fit According to my measurements the PPP is 76mm wide and the L5 is 73mm wide. That s wide enough for 3*18mm or 4*18mm cells side by side arranged parallel to the long side of the phone or one 65mm long cell going across the phone with the necessary spring and wires. The L5 is about 151mm long and the PPP is about 5mm longer. So that means that for just the cells we could have 2 cells in a row in parallel to the long side of the phone giving a 2*3 or 2*4 array or we could have a row of 8 cells parallel to the short side of the phone. A quick search for controllers for a battery of LiIon cells that outputs USB-PD turned up one of the smaller ones as 40*28mm, here is the AliExpress page [4]. So that means we could have a maximum of about 4 cells and the controller while leaving space for the camera. Looking at other similar items it seems that most of them take a large portion of the 73mm width available and take a bit less than 30mm height. The price range for DC-DC voltage converters ranges from about $3 to $20, the one I linked to is currently $8. The mass of 18650 cells is around 45g so 4 of them would be about 180g before counting the weight of the case and electronics. A L5 weighs 262g and a PPP weighs 220g so 180g of battery will make a significant difference, not an impossible difference but holding a PPP while reading an ebook is already annoying. Maybe the case could be designed to be easier to hold, a loop of wool attached to the top could be used to suspend the phone from one finger while the rest of the hand just keeps it steady. In a default configuration the L5 has a 4500mAh 3.8V battery and the PPP has a 3000mAh 3.8V battery. The 18650 cells have up to 4000mAh with 3500mAh being common. So 4 such cells could multiply the battery life of a PPP by a factor of 5 or a L5 by 4. That would not be enough to last for a whole day without charging so they need to be easy to swap. A 3 cell battery seems like a good option, 135g of batteries so the project overall wouldn t even double the weight of the phone with battery case. As it doesn t seem possible to put in enough cells to last a day of reasonable use (running a web browser, checking email, reading wikipedia, and having some IM systems checking for notifications) there doesn t seem to be a benefit in trying to stuff the maximum number of cells in. Going to 4 or 5 cells doesn t provide much benefit over 3 while increasing the weight and making the design more difficult. The modules for DC Voltage conversion often have configuration for the number of cells to be used so it wouldn t be difficult to print a new case and reconfigure the Voltage converter. Design A case needs to provide protection as well as hold the batteries. The lack of cases for the L5 and PPP is a problem even without the extra weight of a battery pack increasing the kinetic energy of falling phone. Ideally a drop from 1M on to concrete would not cause any damage to the phone, destruction of the case is OK as it would be 3D printed and can be rebuilt easily. I think that a case where the phone slides in from the top would be best. To change cells one would slide the phone out and the cells would be immediately accessible with no divider between the phone and the cells. Sliding the phone in would hold the cells against the back of the case and as there is a gap of about 3mm on each side of the PPP between the display area and the edge of the phone there s plenty of space for the case to wrap around it at the sides and bottom. At the top there would have to be some sort of plastic clip. The PPP only has buttons on the top right so the case can be snug on all sides apart from the top right. The L5 has switches at the top left and buttons at the top right so whatever clips on to the top would really need some strength to cover the fall flat on face case. The USB C plug would need to be held in place well enough to allow the phone to easily slide on to it but also be weak enough that it would move if a drop forced the phone out of the case. Thingiverse has a design for a L5 case [5] (with several derivatives) and a design for a PPP case [6]. Those cases could be used as starting points and then changed to store batteries and the voltage change circuit board. I have just learned that it s possible to use rubberised material in a 3D printer which is apparently what those designs are for. If a case was printed with rubberised material the top could just stick in place after being pushed in. Potential for Excessive Excitement Having an exploding device in your pocket would be the exciting in a bad way. My initial idea was to have multiple 18650 cells in series. The problem is that if the cells have different capacity levels then one can run out before the rest and get to a deep discharge state which at a minimum causes damage to the cell. One way of minimising risk is to have only a single cell in use at one time, here is a converter for a single cell to 5V [7]. It is possible to run multiple cells in parallel by simply wiring them together, but it s recommended to make sure that the voltage difference between cells is less than 0.2V to avoid high current when connecting. The arrangement of cells is often referred to as nS or nP to refer to n cells in series or parallel. Aliexpress has a range of 1S to 6S devices. Some of the 2S devices have a connector for the mid point which permits separate voltage monitoring for both cells but there doesn t seem to be anything equivalent for 3S or more. They also don t appear to have anything to specifically manage 2P or 3P arrangements at the moment (they had a 3P board on sale when I looked into this last year). Conclusion This is a bigger project than I expected when I first started investigating it. I ve played with FreeCAD which seems OK but will take a lot of learning and practice. Then I need to do more investigation into the DC-DC converters to find one that works well and is unlikely to start a fire. I will look into other phone options as well and keep chasing Furilabs people about my phone replacement.

27 September 2026

Russ Allbery: Review: Ode to the Half-Broken

Review: Ode to the Half-Broken, by Suzanne Palmer
Publisher: DAW
Copyright: May 2026
ISBN: 0-7564-2013-X
Format: Kindle
Pages: 441
Ode to the Half-Broken is a standalone post-apocalyptic (sort of) science fiction novel. As this novel opens, the unnamed first-person protagonist is waking up in a bathtub in an abandoned building. They are covered in electromagnets and missing one leg. Waking up involved a secure reboot from a protected core kernel, so it is immediately obvious that the protagonist is a robot. That also explains the electromagnets, which interfere with their ability to control their body. Or they would, if the protagonist didn't have long-dormant combat routines available to deploy EM shielding and free themselves from the bathtub. There are no immediate answers to why someone embedded a virus in the data attached to a scientific paper on ants, an act so precisely targeted that it had to be personal. Or what happened to their leg.
"There are a number of electromagnets in the next room," I say. I point. "Behind that wall with all the holes in it." "Those are big holes. And fresh, too," the dog says. "I wonder what made them." "Electromagnets experiencing sudden velocity." The dog gives another of its short barks, and I am more convinced now it is laughing, though I was not attempting to be funny.
Ode to the Half-Broken has a classic science fiction beginning: in medias res in a future science fiction version of Earth where nothing is immediately explained, leaving the reader to work out the date and the setting. Helping us out is the protagonist, who is neither chatty nor very sociable with other characters but keeps up an analytical monologue about the world as they narrate events. We are some decades into a grim future. The United States has largely collapsed. Large parts of New York City are dangerous to humans due to disease and radiation. Neither of those hazards bother the large number of sentient robots; their scarcity, and therefore economy, is instead based on power. Robots that control solar power stations act as low-level mob bosses, trading power for information or labor. Our protagonist doesn't want to care about any of this. They retreated from the world long ago for a solitary life in the former New York Botanical Gardens studying ants. But they need a new leg and the best robot repair person nearby is a human woman outside of the city, so they reluctantly head in that direction, accompanied somewhat surprisingly by a cyborg dog. The typical science fiction apocalypse is caused by something specific. Classically, that event is a nuclear war, but writers found various alternatives before, during, and after the Cold War era: alien invasions, meteor showers, plagues, sea level rise, and peak oil and general environmental collapse, among many others. Less common is a post-apocalyptic novel where the collapse comes from multiple overlapping crises and accumulating failures, from a general failure to meet what Adam Tooze and others call polycrisis. The first time I encountered that style of post-apocalyptic story was in Octavia Butler's Parable of the Sower. It was one of the choices that made (and still makes) that book feel so chillingly realistic. The world background in Ode to the Half-Broken is shaped by that sort of polycrisis collapse. There is no one reason why New York City is a dangerous, irradiated ruin and society has collapsed into isolated and sometimes warring factions. It is not runaway artificial intelligence, or at least not directly; sentient robots were a late-stage innovation of the collapsing US civilization and a tool and accelerator of its many wars, but they were not the cause and may be a critical ingredient in building some functional replacement. Instead, society fell apart because we failed to address any of the growing problems and then turned on each other in the resulting ruins. The reader gets an idiosyncratic view of that collapse in flashback chapters intermixed with the main narrative of the initially unnamed robot protagonist, flashbacks told from the perspective of the man who invented the key component for robot sentience. As you would expect, those two narratives are linked. The reader will not discover how they are linked until late in the story. This book could have been extremely depressing. It is not, which says a great deal about Palmer's skill in telling it. The clinical distance of the protagonist in the early chapters helps considerably: They have rejected involvement in this world and therefore can describe it in detached, factual terms, aided by the tendency of most robots in this story to be slightly more precise, logical, and verbose than the human characters. But as the protagonist's clinical distance fades, as it must to allow the story's emotional stakes to rise, Palmer fills this book with moments of beauty and hope. A former nuclear submarine that has become the mind of a subway car is a key early ally. A collective has turned the Hudson Bridge into a thriving if chaotic community. Self-regulating enclaves of humans and robots are working together to try to build a livable world. Robots oversee pollinator swarms that are attempting to restore plant life, for no reason other than that they like order and stability and see this as a way of restoring both. This is a grim, post-apocalyptic world that does not dwell on either the grimness or the apocalypse. It is instead full of small moments of hope, collaboration, and personal connection. This is a story with villains, danger, pain, and risk. Despite the similar keywords and cover aesthetics, it bears little resemblance to Becky Chambers's philosophical Monk and Robot series. It is not, in any definition of the term, cozy; it's a post-apocalyptic adventure story about a robot and a dog making their way through a ruined civilization and fighting people who are trying to build something even worse on the rubble. But it's also charming and oddly happy. There are strong found-family vibes in the way that a party coalesces around the protagonist and eventually gives them a name, there is the quiet happiness of seeing a grumpy misanthrope slowly come out of their protective shell, and the rail mechs are an absolute delight. Like a lot of stories of happy small-group anarchism, I didn't entirely believe the politics and have some qualms about the realism of the ending, although perhaps I should strive to be as optimistic as Palmer writes. The somewhat dry and fussily precise first-person narration will also not be to everyone's taste; it worked for me by the end of the book, but it took a bit of reading to get used to it. But those quibbles aside, this was quietly lovely. It's a satisfying science fiction adventure story in a world with disturbing parallels to the one we're living in, but which uses those parallels to focus on small-scale collective efforts to build something better. And all the small details of the world-building are delightful: the different tiers of robots and their odd behaviors, the machine sense of purpose, even the mix of suspicion and generosity. The plot has large-scale implications, but it was the human-level details that charmed me. I still want another Fergus novel, but this was a highly successful foray outside of that series. Palmer has won two Hugos for her novellas, so I can't really say she's overlooked, but her novels aren't getting anywhere near the attention they deserve. Highly recommended. There is plenty of world-building room here for a sequel, but Ode to the Half-Broken reaches a satisfying standalone conclusion. So far as I know, no sequel is currently planned. Rating: 8 out of 10

18 September 2026

Petter Reinholdtsen: Long term storage of Mattermost messages with Noark 5 XML

It is said that those who cannot remember the past are condemned to repeat it, a quote often attributed to the American philosopher George Santayana. And to remember the past, records must be maintained and kept accessible to learn from. With this in mind, it is no wonder that archivists worldwide consider it crucial to ensure the archival records are both complete and accurate, with a constant frustration caused by the knowledge that the archives are neither due to challenges in tracking down and collecting what should be archived. The last few days, I decided to simplify the collection of Messages from the Mattermost chat service, used by a few of the organisations I am involved in, to try to improve the situation slightly. To achieve this, I had written a dedicated extraction tool. Partly to see how hard it would be, and partly to ensure that if one of the services were shut down or replaced, everything in it would not be lost. Of course it is in the nature of the use of instant messages that most of them are not fit for permanent storage, at least not according to Norwegian law, where there is a threshold "worthy of the archive" (arkivverdig) that should be met, and messages like "should we go to lunch now" are below the bar and should be filtered out. The tool can not help with this filtering, and that will have to be done using other means after collection. The tools I had my bullshit generator write, under strict supervision and many iterations, will extract every message visible to the user whose credentials are used to log into Mattermost, and write it out in Noark 5 extraction XML format and visualize the result. I created the visualiser mostly to quickly be able to debug the extracted XML, but also to make life easier for anyone interested in testing out the tool set. The extractor mattermost-noark5extract create a hierarchy with arkiv/arkivdel for the Mattermost server, and then individual mappe for each channel and direct message chat, a registrering for each message thread, dokumentbeskrivelse for every message in the tread, and one or more dokumentobjekt for each message and their attachments/images. So far it is only tested on one Mattermost installation, where around 23,000 messages is extracted in 61 seconds and produce 295M with approximately 600 attachments and around 675,000 lines of XML in arkivstruktur.xml. You pass it the URL of the service, a username and password, a directory path where to store the collection and an optional channel name substring to limit the collection to only a subset of the messages available. The mattermost-noark5extract-browser viewer can load this collection and visualize it similarly to Mattermost's web interface, with the list of channels and direct messages dialogues on the left, messages chronologically in the centre and a selected thread displayed on the right. I know Mattermost provide several login options. I've only had the one used on my test server implemented so far, and know the extract tool will have to be extended a bit for it to handle servers using one of these options. If you would like to examine the new toolkit, mattermost-noark5extract is available from gitlab. I wanted to put it on codeberg, but as the recent rule change forbid code mostly written by a bullshit generator there, it was not really an option. Note that some years ago I wrote a similar tool to extract material from the request tracker system. The source for request-tracker-noark5extract is also available from codeberg. I would love to hear from you if you test the tools. As usual, if you use Bitcoin and wish to support my activities, please send donations to 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

15 September 2026

Paul Tagliamonte: DESFire EV3

I ve long been interested in hardware key material storage devices. I ve been a fan of yubikeys (I still remember when my fancy new NEO-N showed up), PIV (and its associated smattering of additional fields), SaaS HSMs, the kernel keyring, some tooling I ve fairly satisfied with the design of at prior companies, and of course, our dear friend, the TPM. All that is not even to mention the scores of exotic hardware security modules one generally comes across from time to time when you re keeping a sharp eye out that you wind up playing with. The concept of storing private key material on a disk, or even having it in RAM has always skeeved me out, so I have a natural inclination to hardware modules, and how shifting keying material around can change your risks and threat model(s) in interesting ways. I don t remember when I first came across the MIFARE DESFire EV3, but a few weeks ago I did a deep-dive into the state of the art of authentication schemes using ID cards. My complete overview of what tradeoffs exist is pretty extensive (and likely not interesting to the vast majority of the world), but the tl;dr wound up being one of use PIV or use MIFARE DESFire EV3 . I wound up picking DESFire for a recent project, and figured it s worth talking a bit about what I learned, share some thoughts, and some code. That code is published on crates.io/desox, and docs, as is our custom, may be found at docs.rs/desox DESFire supports DES (I m sure most readers saw that one coming), 3DES (I didn t bother playing with 3DES at all) or AES-128 (AFAICT always use this?) keying material. It s worth noting that the DESFire only supports symmetric keys and is not designed for public key cryptography, and operates exclusively using shared symmetric key material. The DESFire EV series use those keys and related authentication schemes to interact with files stored on the on-chip EEPROM (2k, 4k, 8k, and 16k versions exist), or applications (groups of files and authentication keys).

Talking to a DESFire EV3 Interactions with the card are done over NFC (ISO/IEC 14443 Type A), and commands to/from the card may be in the usual ISO/IEC 7816-4 APDU format, or unencapsulated bytes sent to/from the card are sent using a fixed instruction set and return code structure saving a few bytes per message. I ve opted to use their undocumented and proprietary format I found it easier to work with and with a maximum message of 60 bytes, the savings matter a lot. While powered via NFC, the card maintains a small amount of state about the connection between the reader and the card in its RAM, including if the session is authenticated or unauthenticated. I ll dig into how authentication happens later, but it s worth knowing that sessions can become authenticated using one of the symmetric keys shared by the card and the reader. The vast majority of the DESFire commands I know about tend to work while either authenticated or unauthenticated, with a few exceptions (GetUid, ChangeKey, and ChangeKeySettings for example). In general, I found working with this card particularly pleasant. There is a fair amount of backwards-compatible behavior and multiple methods of communication that confuse things a bit, but overall, it was better than average to integrate with. Kudos to the NXP team. If the docs on this chip were public, things would be orders of magnitude easier it s not entirely clear to my why they re keeping so much of the interface documentation under NDA, but it s the largest knock against the chip, by far.

Authentication I found a lot of really great resources outlining how the handshake and protocol works for a DESFire EV3, especially from Ridrix, some public datasheets ThrRealRevK and posts from AndroidCrypto. The gist here is that, because the DESFire only does symmetric key operations, the key exchange (a type of SKA Symmetric Key Agreement) uses symmetric keys to establish a unique session key which is used to sign or encrypt data exchanged between the reader and the card. I m not going to get too in-depth here, since there s a ton of other resources out there to dig into but I will do a quick high-level description to keep this post mostly self-contained. The authentication protocol serves two main functions to verify that both parties know the same shared secret, as well as to act as a SKA to construct a new session shared secret key. Here s a quick overview of how a shared session key is derived between the reader and the card using our symmetric keys (AES-128 in the case below).
  1. the reader requests to start authentication with the card (something like AA 00 to start an AES Authentication handshake with keyslot 0x00).
  2. The card will then reply with AF (a status code that indicates more data is to follow), followed by 16 bytes (in the case of AES-128) of encrypted (using CBC) data.
  3. The hosts then decrypts this block with the symmetric key from keyslot 0, returning the card s session nonce.
  4. The host generates 16 bytes (usually random) for its session nonce.
  5. The host sends an instruction of AF (indicating a continuation of the previous command), followed by 32 bytes of encrypted data. When decrypted, the first 16 bytes are our nonce generated in step #4, followed by the 16 bytes provided by the card, decrypted in step #3, except where every byte is shifted to the left by one place (the 0th byte is copied to the end).
  6. The card will reply with 00 indicating a successful operation, followed by 16 bytes, which when decrypted, is our session nonce from step #4, shifted to the left by one byte in the same way that we did in step #5 with the card s nonce.
  7. At this point, both the reader and card have confirmed the other party has the same symmetric secret key. The session is now authenticated and a session key is derived using the two nonce blocks. Two hashing keys (K1 and K2) are derived from this key, which is used to maintain an ongoing CMAC hash of the messages coming and going to/from the card.
From here on out, the session is authenticated , and responses from the card which were previously plain will now contain a 8-byte CMAC signature, which can be used to ensure that the replies in question come from the active session. In my implementation of the handshake I opted to encode the handshake state into rust types, just so I wouldn t make any mistakes. The Handshake type contains the session internals (session nonce values, keying state, to include IV, etc). This means the authentication flow (from within my code) uses the Handshake struct to generate the commands to send to the card in order:
/// Create a new  Handshake , and return the
/// start auth command (something like  AA 00 )
fn Handshake::<Initial>::begin(
 output: &mut [u8],
 key: [u8; 16],
 key_id: u8,
) -> (Self, &[u8]);
After we get a reply back from the card (the encrypted version of the card s session nonce, sometimes called Rnd_B in code I ve seen), we transition states from Initial into HalfOpen.
/// Given the card's encrypted response, generate
/// our session nonce and generate a reply
/// (something that starts with  AF  followed by
/// 32 bytes of encrypted data).
fn Handshake::<Initial>::rnd_b(
 self,
 output: &mut [u8],
 input: &[u8]
) -> (Handshake::<HalfOpen>, &[u8]);
Now that we re HalfOpen , we re waiting to hear back from the card to ensure that it, too, can byte-shift our provided nonce. Once we have the card s reply, we can check it using our complete helper, transitioning from HalfOpen to Successful.
/// Check to ensure that the card replied with
/// our nonce byte-shifted by one place, indicating
/// that they know the symmetric secret in
/// this key slot.
fn Handshake::<HalfOpen>::complete(
 self,
 input: &[u8]
) -> Handshake::<Successful>;
Once the Handshake is successful, the only thing left to do is consume the Handshake struct and turn it into the shared session key by running it through the key derivation function.
/// Consume the  Handshake  struct and return the
/// new shared session secret key.
fn Handshake::<Successful>::into_key(self) -> [u8; 16];
From here on out we can use this session key for the remainder of our interactions with the card signing messages from (and sometimes to!) the card, or encrypted messages to and from the card. This key is used in CBC block mode, where the session IV is updated with the last block of the encrypted data.

Unit Testing A nice proprietary of the SKA scheme we re using as part of DESFire is that the derived session key is actually deterministic if you control your nonce RNG (ok, actually, pretty true for most key agreements, but anyway), which means it is possible to capture traffic over the NFC interface, and replay the NFC I/O with cooked RNGs and ensure byte-identical messages and keys are generated. Within desox-rs this is called replay (I m creative), and I ve got a few replay sessions checked into VCS, which exercise a signficant amount fo the API surface. All were derived from an actual session with a real DESFire card, and can be updated with a live card and a --cfg flag. Each replay file is a set of lines (request-response transactions), each containing two space-delimited hex encoded NFC messages. For instance, here s an authentication handshake in replay format:
1a00 afc7bbd82ff8fefae8
afc6dab54df2278d2952d560821be7e4c3 007d9abe94a9b14748
The code that generated that exchange came from the test stored adjacent to that file a handshake with the default DES key (all zeros), and an RndA value hardcoded to 32c28fdafd3960de.
let mut card = card
 .authenticate_with_rnd_a(
 0x00,
 Key::Des([0; 8]),
 Key::Des(hex_literal::hex!("32 c2 8f da fd 39 60 de")),
 )
 .await
 .unwrap();
Since the card s RndB is similarly unchanging (I m replaying this file every time), this will always derive the same session key, which means messages (including encrypted ones or CMAC signed responses) will be identical, as well. If you re playing with the DESFire yourself, feel free to grab my replay files if you need a known good baseline. By default this will run using the MockBackend, replaying each file expecting a byte-identical request, and responding with the harcoded customary reply. If the code (or test!) needs to change, updating the tests is done by swapping the MockBackend out for a real one. Since I had to do this a bunch during development, running cargo test with RUSTFLAGS="--cfg desox_replay_rw" will, on run, overwrite the replay file(s) for the executed test(s), ensuring all line-protocol changes are explicitly caught and reviewed.

Observations Most commands, even ones which require authentication, are transmitted without CMAC signature(s) or encryption. CMAC signatures from the reader to the card are not really used (except for writes to a file which specifies communication must be CMAC signed), ditto for encryption (although that one is used for key change operations, in addition to file writes on files that specify encrypted communication must be used). The vast majority of commands take a plain request from the reader, and return a CMAC signed response. By my eye, this means that a malicious reader, or something otherwise capable of holding the card online after communication with an authentic reader is complete are able to execute privilaged commands (since one can simply ignore the CMAC signatures on responses), so long as the command doesn t require the reader to provide CMAC signatures (or encryption), or allow the card to power down.

Fun with DESFire I ve played around a bit with ways to use the DESFire cards in interesting configurations, given what they re capable of. Here s some half-baked thoughts I had while mucking around with the cards these are all poorly thought out sketches of some things we can do given the specific tradeoffs I see with the DESFire card. It s also worth noting that I don t have any of the actual documentation, and am not a cryptographic grown-up, so take these sketches with a massive grain of salt. The first thing that came to mind when implementing this is how the authentication scheme can shift the boundary of what is and is not trusted (assuming good secure keying, and provided the key slots and card/application permissions are configured correctly). Rather than push the key material out to the machine connected to the NFC reader ( reader machine ), I instead tried turning the NFC reader and computer into something psuedo-untrusted by merely having it pass messages from the card to a trusted remote system ( remote machine ). This means that the reader machine is exchanging NFC data with the card, but that data is being decrypted, encrypted and processed by the trusted remote machine the reader is unable to derive the session key. For each of these, I wind up needing to authenticate so there s still a few latent risks, but these can mostly be mitigated by asking for a readbacks of any changed file(s), setting key permissions carefully, and requesting the card s UID via the encrypted channel all of which would require the symmetric secrets (which undermine the whole security model if comprimised). This general construction is also subject to a hostile takeover of the untrusted reader machine , since most commands (including destructive ones!) are sent in PLAIN mode the reader machine can wait until authentication is complete and then inject commands into the card and simply ignore the CMAC signatures on responses, severing ties with the remote machine. As such, we also need to take steps to ensure that the key being used is not one that allows any access beyond what is allowed. Here were some ideas I sketched out off the back of this theory.

The second-factor Given some established (and authenticated) connection, part of the initial authentication flow may use the DESFire card to prove physical control over it as part of a handshake. This can serve as a second factor during some authentication flow, requiring physical card presence at a reader to fully initialize a connection. This does have one glaring downside, however it s phishable. To use this for real , we d need to take some steps to prevent obvious MITM flows (XOR the NFC messages with the URI as seen by the client?), but maybe there s something interesting there. This also has a second interesting attribute when used as part of a physical system authentication flow, this becomes a logical place to inject access control, being able to determine if some person is permitted to operate some device at that particular time (Is Joe current on his Laser Cutter certifications?) I think of the ideas I landed on, while conceptually interesting (using an employee id card as a 2FA token, it s very fast), this one is the least likely to turn into something real.

The takeover This time, let s say the computer attached to the NFC reader ( reader machine ) is semi-trusted. For this scheme, our trusted remote machine and the reader machine pass messages over the network to handle authentication to the card (as above), where the handshake data is being decrypted, encrypted and processed by the trusted remote machine as usual. However, once the authentication handshake is complete and a session key has been derived, the remote system return the session key to the reader machine , giving it a one-time-use key and authenticated session to the card. We need to be careful about global/application permissions and key access control to files but in this construction, we can allow the reader machine to take over privileged actions using a scope-limited DESFire key without handing over the card s true keying material (preventing cloning of the card). This can be helpful to ensure messages to/from the card are truely from the card (verifying CMAC signatures), enables the reader machine to directly read/write to/from encrypted file(s), but allows the symmetric key material to remain in as few places as possible which is critical given compromising that secret will undermine the security of the entire system.

8 September 2026

Paul Tagliamonte: IP over Avian Carriers (Part 12/12)

This post is part of a series called "Pigeon". If this is the first post you've found, it'd be worth reading the intro post first and then looking over all posts in the series.
The final step to all of this was to tie together all my PHY RF code, Link layer parsers, and my background with operating systems to make this all feel like a normal thing my computer should be doing. At the end of the day, I want my host system to know how to talk with a pigeon daemon, so I don t have to reimplement basically everything else. My ability to use normal tools like curl or ping6 is pretty important here, so I need to reach for my old friend, the TUN interface. The TAP/TUN interface allows the kernel to route ethernet frames (TAP) or ip packets (TUN) to a userspace program responsible for handling delivery and reception avoiding the need for a kernelspace driver for something that can be handled in userland.
wondering if doing this violates FCC Part 97 rules? I wrote up notes on my test setup for exactly this question, but the short answer is "no"!
I m no stranger to playing with TAP/TUN, so this was pretty easy to snap together although this time I avoided the whole ethernet proxying thing (to side-step lossy translations, maintaining two sets of mac address tables, and handle proxying NDP/ARP messages) it was kinda a bad idea last time so I just used TUN and straight IP for now. While implementing this, I decided I d make a key assertion about all pigeon networks namely, all pigeon IPv6 networks are a /64 in size, no more, no less. The reason why I m doing this here is that, since pigeond does still does need a MAC address for the pigeon layer 2 protocol, we can write our daemon to always use SLAAC to set the TUN IP address without any new information. Which leads us to a bit of an aside, but I have a point, I swear. A few years ago, my recreational RF adventures have lead me down a path where I decided to engage with ARIN to solve (once and for all) the massive headache I was running into with IPv6 numbering (really: always renumbering) my multi-site radio processing networks. It s a lot of work to keep running correctly, but it s solved a huge amount of problems for me. The only internal thing we really need to outline for this post is that, at the highest level, my network (paultag.net) is split into an IP plan that looks roughly like:
Prefix Description
/44my full allocation of IP space
/4815 "regions"
/5464 "sites" per region. A "site" is assigned to a physical or logical location.
/641024 subnets per site. A subnet used by directly attached devices.
For this exercise, I used IP space from paultag.net s experimental region ( region 8 ), named side.band (2602:810:6008::/48) to connect my RF lab ( site 1 - 2602:810:6008:400::/54), and my two pigeon-specific subnets, subnet 0 (2602:810:6008:400::/64) and subnet 1 (2602:810:6008:401::/64) to my wider network. The first subnet ( subnet 0 ) is a simple ethernet network to enable my RF-only nodes to communicate with the side.band gateway. The second subnet ( subnet 1 ) is an RF-only pigeon network local to my lab.

back to radios With all that set up, I assigned my first two nodes their MAC addresses, and set up the local RF only network segment. The nodes I brought online were the following:
Callsign IP
K3XEC/MN2602:810:6008:401:8e1f:64ff:fe35:4001
K3XEC/TH2602:810:6008:401:8e1f:64ff:fe35:4002

testing the pigeon network And with that, I could begin to test that the host operating systems and RF links could properly exchange data locally from SDR to SDR. We can use ping6 to see if a plain-ole ICMPv6 ping round trips between hosts correctly:
$ ping6 2602:810:6008:401:8e1f:64ff:fe35:4001
PING 2602:810:6008:401:8e1f:64ff:fe35:4001 (2602:810:6008:401:8e1f:64ff:fe35:4001) 56 data bytes
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=1 ttl=64 time=426 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=2 ttl=64 time=397 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=3 ttl=64 time=419 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=4 ttl=64 time=418 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=5 ttl=64 time=436 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=6 ttl=64 time=391 ms
64 bytes from 2602:810:6008:401:8e1f:64ff:fe35:4001: icmp_seq=7 ttl=64 time=397 ms
And it does! Latency is horrid (and there s a bunch of tx artifacts that cause issues for us) but both of those things are problems for later. Let s see how it handles a TCP connection by firing off a quick cURL across the Pigeon network:
$ curl http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/testing.txt
The rock dove (Columba livia), also known as the common pigeon or rock pigeon
(but see also Petrophassa), is a member of the bird family Columbidae (doves
and pigeons).
As expected, our remote end here running the server reports the correct peer IP address, which is another indication (beyond the log messages and blinking LEDs) that we re routing over our TUN interface.
Serving HTTP on 2602:810:6008:401:8e1f:64ff:fe35:4001 port 8000 (http://[2602:810:6008:401:8e1f:64ff:fe35:4001]:8000/) ...
2602:810:6008:401:8e1f:64ff:fe35:4002 - - [28/May/2026 12:53:21] "GET /testing.txt HTTP/1.1" 200 -
That worked? First shot! Nice! It s pretty slow and seems like we have a lot of packet loss, but it does, however, beg the question can it nethack?

nethack! Yes! It can nethack! No clickbait here. The way I went about this one is a bit anit-cimatic I set up a nethack server (using inetd in this case) on one of the hosts pigeon0 network interface, and hit that port over RF from the other: However, when playing it, it becomes very obvious (as you can likely see) that there s a fair amount of packet loss (understandable) and probably some packet collisions taking place.

iperf Let s try and put a number to exactly how bad the bandwidth and packet loss is by running iperf between the two pigeon hosts over rf:
$ iperf -c 2602:810:6008:401:8e1f:64ff:fe35:4002
------------------------------------------------------------
Client connecting to 2602:810:6008:401:8e1f:64ff:fe35:4002, TCP port 5001
TCP window size: 16.0 KByte (default)
------------------------------------------------------------
[ 1] local 2602:810:6008:401:: port 58248 connected with 2602:810:6008:401:8e1f:64ff:fe35:4002 port 5001
[ ID] Interval Transfer Bandwidth
[ 1] 0.0000-20.2348 sec 76.8 KBytes 31.1 Kbits/sec
Shockingly, not nearly as bad as I thought it was going to be. Given I ve spent exactly zero time making this operate to a level that I would call acceptable, this is a very fucking solid start. I expect I could get that number up if I spent a few weeks on it it s just not been a priority at any point yet (and the first time I ve instrumented it, even!). This ll be good enough to get started. Let s see what else we can pull off here.

IP multicast to some rtl-sdrs Back when I designed what I wanted Mode A to look like, I intentionally picked a signal bandwidth that could be received by an rtl-sdr so let s put that to use. It may go without saying, but just to say it the rtl-sdr can not transmit, so this will be capable of receiving pigeon frames but not sending any in reply. However, this means I can use a bunch of low-cost computers (raspberry pi-class), and low-cost SDRs (rtl-sdr) and still receive IP traffic from transmitting pigeon network stations. This could be a lot of fun for things like fountain coding a data stream, or adapting multicast streaming protocols to work over RF links. Anywho, I swapped my far end to an rtl-sdr (one config file change!), and figured I d start with some (basic) multicast traffic, transmitting the time once a second:
$ while [ true ]; do
 echo $(date +%s) \
   socat - UDP6-DATAGRAM:[ff02::114%pigeon0]:62804
 sleep 1
done
If I had more time to burn, I was planning on bridging APRS traffic to UDP multicast within a pigeon network subnet. However, since I m already 4 years late on this blog post, I figured this would be enough for now (and you can imagine that fun project in this space if you so wish!) I fired up pigeond again (except this time connected to an rtl-sdr), and was pleasantly surprised to be greeted by some decoded traffic right off the bat:
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
  [k3xec/mn] 8c:1f:64:35:40:02   00:00:00:00:00:00 ipv6 fe80::23ee:2969:53f7:b332   ff02::114 17 (UDP - User Datagram)
Of course, I took a tcpdump to confirm for completeness sake that the traffic actually made it out of our TUN interface:
$ tcpdump -i pigeon0
22:39:34.808705 IP6 (flowlabel 0x92a0e, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.35911 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:36.429887 IP6 (flowlabel 0x4dc84, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.50026 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:39.365977 IP6 (flowlabel 0x224d5, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.36308 > ff02::114.62804: [udp sum ok] UDP, length 11
22:39:40.944889 IP6 (flowlabel 0x4721c, hlim 1, next-header UDP (17), payload length 19) fe80::23ee:2969:53f7:b332.35003 > ff02::114.62804: [udp sum ok] UDP, length 11
Looks great! tcpdump is showing multicast packets show up (as we assumed they would), on the pigeon0 interface, on the machine connected to an rtl-sdr. Of course, any replies will get sent to the bit bucket, but it can definitely decode things just fine! Very fucking cool. Well right, ok! Let s go back to two rx/tx radios, and see what we can do with our newfound network stack over ham radio frequencies let s try to do some fun (and traditional!) ham radio things with it!

Crossing the english channel in a bathtub Ok, ok. I decided to bury the lede a bit here I didn t mention that the side.band network is currently BGP announced. Although we haven t used it this does mean that we re most of the way to sending packets to the wider internet, and we should be able to just fix a few routing tables, and see packets begin to flow. After tweaking the local routing tables (and restarting pigeond for good measure), I decided to test my newfound connectivity by pinging something over our new network transport.

ping github Why don t we start with the world s premier software engineering platform, operated by one of the largest companies in the world, GitHub! After all, they have an all knowing (and, apparently, arguably sentiant?) AI on hand to instantly and automatically fix any stray reliability issues in the background, so we should definitely see replies right off the bat:
$ ping6 github.com
ping6: github.com: Address family for hostname not supported
Wait, oh no that can t be right? After all, it s 2026, and both Google and CloudFlare (in North America) are reporting over half of all traffic they see is IPv6 and GitHub still doesn t support IPv6? Definitely not, this is for sure a bug with my code or network.

lets ping something that supports ipv6 instead That being said, just for completeness sake, since that error is also given when there s no IPv6 DNS record, let s go ahead and double check with Hurricane Electric too, you know, just to be sure.
$ ping6 he.net
PING he.net (2001:470:0:503::2) 56 data bytes
64 bytes from he.net (2001:470:0:503::2): icmp_seq=1 ttl=53 time=514 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=2 ttl=53 time=230 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=3 ttl=53 time=248 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=4 ttl=53 time=246 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=5 ttl=53 time=265 ms
64 bytes from he.net (2001:470:0:503::2): icmp_seq=6 ttl=53 time=240 ms
Well, shit. Right, OK, i ll be damned. 18 years in and GitHub still can t crack that nut.

cURL works! Right, anyway, yes, back on track good news! Our uplink is up and routing, and wait, holy shit! Check it out! pigeon is exchanging packets with the internet and no one is any the wiser! Literlaly amazing. Let s try a cURL across the internet now (although no TLS allowed, so, http only for now):
$ curl -6 -I http://facebook.com
HTTP/1.1 301 Moved Permanently
Location: https://facebook.com/
Content-Type: text/plain
Server: proxygen-bolt
Connection: keep-alive
Content-Length: 0

IRC works, too Sweeeeet. That all works! Forget HTTP, let s do some other 90 s era stuff, it s high-time to log into IRC with a quick /connect -notls, and see what s going on in the #debian-hams channel pleased that I got online fairly quickly, and was able to even talk to myself!

THE GOPHERSPACE Naturally, let s keep this train of nostalga running, and give the 2026 gopherspace a shot. I know the kind folks over at tilde.town (hello, townies!) have a robust gopherspace, so let s give it a dial! Let s try and see if we can load vilmibm s slug over gopher: Yes! I forgot to make this one a video, so no gif. I did wind up having a bit if trouble with a few gopher clients and IPv6 support I may send some patches if I can find the time.

So, what s next? Alright, that s it. I have a few more fun ideas but they re going to have to wait for another day. Carrying IP is fun and all but kinda not the point behind pigeon, after all. Rather than trying to make this into a thing , I m planning on exploring the loose ends first different types of modulation schemes (like QAM-NUC), implementing LDPC error correction and some layer 2 logic into the pigeond (like switching traffic, and gain control). I also plan on spending some time with my (currently, very basic) simulator to better dial in tradeoffs throughout the stack. Since, structurally, pigeon is something I feel like I can work with, I m hoping i ll be able to find the time for some (much smaller!) followup posts without it taking 4 years this time. If I do, they ll show up under the pigeon tag and I ll be sure to update this post with a link below (and the intro post). I m hoping that this series (which was supposed to be one post) was helpful to someone out there if it was, feel free to reach out and let me know!

6 September 2026

Michael Stapelberg: Debian Code Search: Fast TurboPFor with Go SIMD

This August, I accomplished what I wanted for many years: I deleted the last cgo dependency in Debian Code Search! This was made possible by Go s recently introduced SIMD support, because now we can implement the TurboPFor integer compression format as efficiently more efficiently, in fact, by using the newer AVX512 instruction set! as the reference implementation.

Background: Why does DCS need a fast Integer Codec? Debian Code Search (DCS) is a search engine that allows searching all the Open Source source code within Debian, with either literal search expressions or regular expression search queries. A search engine uses an inverted index: a map from term to documents containing the term. Each document is typically represented most efficiently by using an id, so the index consists of many lists of document ids. When searching, it is important to quickly decode these lists to answer the search query. However, there is a point of diminishing returns where the decoding speed, even though it can still be measurably improved quite a bit, no longer influences the overall query duration. From 2012 (its inception) to 2019, Debian Code Search used to use a small index format, and queries were fast because the index was kept entirely in RAM. In 2019, I implemented the new index format, which adds an on-disk positional index. For literal queries (78.2% of DCS queries), querying the positional index on disk is faster than querying the non-positional index in RAM. The efficient encoding of the TurboPFor format makes it possible to fit such an index on a mid-sized Hetzner server, which I rent with two 1 TB SSD disks. The optimized decoder of the C TurboPFor library is what made decoding fast at query time. If you want to dive deeper into the algorithm, see this blog post from February 2019: If you want to learn more about the positional index, see this blog post from September 2019:

SIMD in Go For many years, you had the following options for using SIMD instructions in Go:
  1. Hand-writing Go assembler code. This is only doable for small functions, for example bytes.IndexByte is implemented with hand-written Go assembly (including AVX2).
  2. Generating Go assembler code with tools like Michael McLoughlin s Avo . This is how crypto/internal/fips140/sha256 uses AVX2. While Avo generator code definitely is higher-level than hand-written assembly, it is still too close to assembly for my taste.
  3. Use a C library via cgo so gcc or clang compiles SIMD code. Debian Code Search used to use the powturbo/TurboPFor C library via cgo for the last 7 years.
The C TurboPFor library has served us well, but Debian Code Search was always intended to be a project using Go, so I would prefer it if I did not have any C code in the project. Go 1.26 (released in February 2026) introduced the simd/archsimd package:
Go 1.26 introduces a new experimental simd/archsimd package, which can be enabled by setting the environment variable GOEXPERIMENT=simd at build time. This package provides access to architecture-specific SIMD operations. It is currently available on the amd64 architecture and supports 128-bit, 256-bit, and 512-bit vector types, such as Int8x16 and Float64x8, with operations such as Int8x16.Add. The API is not yet considered stable. Go 1.26 Release Notes
For my 2019 TurboPFor analysis, I implemented goturbopfor, a native Go teaching decoder (without any SIMD), because I find Go code easier to follow than C code, especially optimized C code. My implementation was intentionally not optimized so that the code was easier to study. The TurboPFor format/algorithm has a vector-optimized part: bitpacking comes in a scalar variant (bitunpack32) and a vector variant (bitunpack256v32), where the vector variant is used for full blocks (256 values) and the scalar variant is used for remainder blocks (< 256 values). When Go 1.26 was released, I used Claude Code to explore whether my native Go decoder s bitunpack256v32 function (for the vertical vector layout) could be implemented using Go SIMD, and the answer was yes, it was possible and it was faster than without SIMD, but not quite at the level of C TurboPFor. If you let Claude Code try for long enough, it eventually finds enough optimizations (about 10) to match C performance. I don t want to vibe-code Debian Code Search, though, so I figured I would find some time to review the SIMD code at some point and see if I could implement something similar myself. Before I found enough time and motivation to complete said review, I discovered that to not regress real-life query performance by more than 10 to 100 milliseconds (which seems acceptable), I don t actually need to add SIMD code to my teaching decoder at all; it would be sufficient to reduce allocations in my teaching decoder and specialize it per bit width. Encouraged by the possibility of using the optimized native Go decoder in Debian Code Search, I explored whether I could also implement a native Go encoder so that I could get rid of the C TurboPFor dependency entirely. The answer is yes, it is doable in a few days, and it isn t even that much slower: Go is at 76% of C, see Debian/dcs commit e920dc7. The goal I set myself at that point was to see if I could learn enough SIMD to optimize the native Go encoder such that its performance would match how DCS uses C TurboPFor (via cgo). Beating C TurboPFor was possible in 2-3 commits (SIMD and bit width specialization). To my surprise, Claude Fable 5 pointed out that the encoder s block scanning could be done more efficiently using a technique called positional popcount, and that is another 2x speed-up! To be clear: I am not saying the Go compiler beats C here. Certainly, the C compiler can also produce fast AVX512 code and can be used to implement positional popcount. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. This spectacular result (much faster than what DCS had before) got me curious how far I could push the decoder with SIMD after all. I ended up matching/exceeding the cgo version here, too! The rest of this article explains a few classes of optimizations I encountered along the way.

Starting Point When I wrote my goturbopfor teaching decoder, I named its functions to match the upstream C TurboPFor library, but now I want to get away from names like p4ndec256v32 they make sense from the TurboPFor perspective, but for Debian Code Search, we can use cleaner names. Before writing any code, I audited how DCS uses integer compression / decompression.

API design: BlockEncoder, BlockDecoder and streaming In Debian Code Search, we have the following usage patterns:
  • Partial Indexing: When a new package (or package version) enters Debian, all of its (text) files are indexed. If the hello-2.12.3-1 package (hypothetically) contained only hello.c with printf("hello!\n");, we would assign document ID 1 to hello.c and store in the partial index that trigrams pri, rin, int, ntf, etc. are all found in doc 1 (hello.c).
  • Full Index Merging: The many thousands of partial index files (for each Debian package) are combined into a small handful of large index files: When searching, it would be expensive to consult thousands of indexes. To merge multiple partial index files into one larger index (which can then be efficiently queried), we need to re-encode the partial index files: what used to be document ID 1 in the partial index might be document ID 2531 in the full index.
  • Querying (searching): When users enter search queries, these queries need to be answered as quickly as possible. The relevant entries in the full indexes are decoded (in parallel).
For reading the index, we do keep the decoded uint32s fully in memory, so we only need DecodeN(input []byte, output []uint32) (read int), a function that reads len(output) values (uint32) from input and returns how many bytes it consumed. For writing the index (both in partial indexing, and when merging), keeping the entire index in memory is prohibitively expensive, so we need a streaming API, for decoding and for encoding. Ultimately, I converged on the following API:
package pforenc

type BlockEncoder struct  
    // scratch buffers can go here
 

// EncodeBlock encodes len(vals)<=256 uint32s into dest (one TurboPFor block).
func (*BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  

// EncodeN calls EncodeBlock in a loop.
func (*BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  

type StreamEncoder struct  
  be   BlockEncoder
  vals [256]uint32
  // scratch buffers
 

// if full, you need to call [EncodeBlock]
func (*StreamEncoder) Add(val uint32) (full bool)

// EncodeBlock must be called after all data was [Add]ed.
//
// Write the returned buffer to file or send it over the network;
// it is only valid until the next [EncodeBlock] call.
func (*StreamEncoder) EncodeBlock() []byte  
  if se.n == 0   return nil   // turn an extra EncodeBlock into a no-op
  //  
 
This API (the decoder works similarly) allows us to process data in TurboPFor format without any memory allocations. The types are not safe for concurrent use by multiple goroutines. The zero value is ready to be used. For the streaming API, the result only stays valid until the next call.

Initial Implementation Before we can optimize anything, we need a working decoder and encoder. The decoder already exists: my goturbopfor teaching decoder. Next up, I needed an encoder. Writing a TurboPFor encoder has a delightfully simple starting point: You can encode all values at bit width 32, in little endian, at which point you only need to add a one-byte TurboPFor block header every 256 values and you re done:
func (be *BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  
  for len(vals) > 0  
    chunk := min(len(vals), 256)
    dest = be.EncodeBlock(dest, vals[:chunk])
    vals = vals[chunk:]
   
  return dest
 

func (be *BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  
  const bitWidth = 32
  dest = append(dest, bitWidth)
  for _, val := range vals  
    dest = binary.LittleEndian.AppendUint32(dest, val)
   
  return dest
 
Of course, this is a terribly inefficient compressor, so after the first commit, the real work starts: implement each block type until the compression matches the original C TurboPFor implementation (same output file size), or in other words: do the reverse of the decoder.
  1. The TurboPFor bitpacking block type (bitpacking implementation commit) encodes a bit stream of variable bit width (where the bit width is in range 0 bitWidth 32) in little endian byte order. By scanning all values and choosing the smallest bit width that allows representing all values, this technique saves disk space (compresses).
  2. The bitpacking with exceptions block type (bitpacking with exceptions implementation commit) determines two bit widths: one for values, the other bit width for encoding exceptions. This allows choosing a lower bit width (that does not cover all values) compared to the bitpacking block type. A bitmap encodes whether a value has an exception or not.
  3. The bitpacking with VB exceptions block type (bitpacking with VB exceptions implementation commit) is a variant which does not use an exception bitmap and encodes exceptions using a variable byte integer encoding. This is more efficient when there are few exceptions (less than 20) or the exceptions are very different in bit width compared to the other values.
  4. Lastly, the constant block type (constant implementation commit) stores just one value on disk. This is useful for all-zero or all-one blocks, for example.
I found it interesting to realize that the main work of the encoder is to scan the input values and choose the optimal block type, whereas the actual encoding itself is cheap in comparison. At this point, we can look at performance and see that the Go encoder is at 76% of the C encoder. In all honesty, I could have probably stopped here, but now that the milestone of a viable replacement was reached, I got curious to see how far it would be possible to push the encoder (how much work to reach C speeds?) and afterwards, the decoder, too.

Setup

The microarchitecture level: set GOAMD64 The microarchitecture of a CPU determines which instructions it provides, and that includes not just SIMD instruction sets (like AVX2), but also other useful instructions like LZCNT (Leading Zero Count), which can be used to implement math/bits.Len32 more efficiently, which the TurboPFor encoder needs to call on every input value to determine the ideal bit width. Let s walk through how to set the microarchitecture level when using Go on 64-bit x86 (x86-64). Go uses the GOARCH environment variable to configure the target compilation architecture, and I am using the value amd64 to select 64-bit x86 (AVX2 and AVX512 are instruction sets found on x86-64 CPUs). With GOARCH=amd64, the architecture-specific variable GOAMD64 configures the microarchitecture level for which to compile and Go 1.18 introduced these 4 different levels:
GOAMD64=v1 (default): The baseline.
Exclusively generates instructions that all 64-bit x86 processors can execute. GOAMD64=v2: all v1 instructions,
plus CMPXCHG16B, LAHF, SAHF, POPCNT, SSE3, SSE4.1, SSE4.2, SSSE3. GOAMD64=v3: all v2 instructions,
plus AVX, AVX2, BMI1, BMI2, F16C, FMA, LZCNT, MOVBE, OSXSAVE. GOAMD64=v4: all v3 instructions,
plus AVX512F, AVX512BW, AVX512CD, AVX512DQ, AVX512VL.
In 2026, I generally recommend compiling with GOAMD64=v3 so that functions like bits.OnesCount8 are compiled into intrinsics (POPCNT) instead of using a lookup table. For Intel CPUs, setting GOAMD64=v3 means your programs will only start on Haswell CPUs (2013) or newer; for AMD CPUs that means Zen 1 (2017) or newer. In this specific case (DCS), I am even compiling with GOAMD64=v4. The v4 microarchitecture level requires AVX512, which means AMD Zen 4, Zen 5 or newer (Intel s story is complicated). Luckily, both my main development PC (Zen 5) and the Debian Code Search server (Zen 4) are recent enough. Setting GOAMD64=v4 has little effect on Go 1.27 itself: the only change is that maps use one less instruction (VPBROADCASTB instead of PSHUFB). But compiling with GOAMD64=v4 allows us to move one more feature check from runtime to compile time, see SIMD build tags. It makes sense to set the microarchitecture level in your benchmark setup so that you don t measure the slow fallback implementations. I use export GOAMD64=v4 in my Makefile.

Benchmarking setup Go s built-in testing package contains support for benchmarks which are written in functions of the form func BenchmarkXxx(b *testing.B). The simplest way to run such benchmarks is go test -bench=., but I ended up configuring a few convenience make targets, which write results to bench.txt and compare against baseline.txt (the previous commit s results, usually), using the very useful benchstat tool.
GOTEST=go test

# -count=6 gives p 0.002 in benchstat:
# https://pkg.go.dev/golang.org/x/perf/cmd/benchstat
BENCHFLAGS=-run=^$$ -bench=. -benchtime=200000x -count=6

# use taskset -c1 to always pin to the same single core,
# avoiding accidental scheduling on different cores on
# mixed-core CPUs like the Ryzen 9 9950X3D.
TASKSET=taskset -c 1
BENCH=$(TASKSET) $(GOTEST) $(BENCHFLAGS)

.PHONY: all test bench bench-baseline bench-relative

all: test

bench: test
	$(BENCH)   tee bench.txt
# Compares compression ratio between C and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '-/impl:go-stream .unit:(encoded-bytes)' bench.txt
# Compares performance between C (cgo) and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '.unit:(Mval/s)' bench.txt

bench-baseline: test
	$(BENCH)   tee baseline.txt

bench-relative: test
	$(BENCH)   tee bench.txt
	benchstat -filter '-/impl:go-stream .unit:(encoded-bytes)' baseline.txt bench.txt
	benchstat -filter '/impl:go .unit:(Mval/s)' baseline.txt bench.txt
The encoded-bytes and Mval/s units are custom metrics I am reporting from the various sub-benchmarks, which are arranged such that I can filter / report them with benchstat. The main encoder (and decoder) benchmarks compare 3 different implementations (cgo, Go, Go with the StreamEncoder API) with a number of benchmark cases that are designed to cover the different block types and contain a similar mix of values as what we see in Debian Code Search:
// reportMetrics adds Mval/s and encoded-bytes metrics to all benchmarks.
func reportMetrics(b *testing.B, n int, nencoded int)  
   b.ReportMetric(float64(nencoded), "encoded-bytes")
   b.ReportMetric(float64(b.N*n)/1e6/b.Elapsed().Seconds(), "Mval/s")
 

// BenchmarkEncode/n=<N>/vals=<testcase>/impl=<c go go-stream>
//
// e.g. BenchmarkEncode/n=2048/vals=one-constant/impl=go-stream
func BenchmarkEncode(b *testing.B)  
   for _, tc := range allBenchCases()  
     n := len(tc.vals)
     b.Run(fmt.Sprintf("n=%d/vals=%s", n, tc.name), func(b *testing.B)  
       b.Run("impl=c", func(b *testing.B)  
         b.ReportAllocs()
         var encoded []byte
         buf := make([]byte, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = turbopfor.P4nenc256v32Buf(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go", func(b *testing.B)  
         b.ReportAllocs()
         var be BlockEncoder
         var encoded []byte
         buf := make([]byte, 0, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = be.EncodeN(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go-stream", func(b *testing.B)  
         b.ReportAllocs()
         var se StreamEncoder
         var encoded int
         for b.Loop()  
           encoded = 0
           for _, val := range tc.vals  
             if se.Add(val)  
               encoded += len(se.EncodeBlock())
              
            
           encoded += len(se.EncodeBlock())
          
         reportMetrics(b, n, encoded)
        )
      )


CPU counters: perf Go has included excellent performance tooling for many years, see the Profiling Go Programs blog post (2011) for an example of how to use pprof, a sampling profiler. This profiler can help track down which part of a program runs slow, or where memory allocations happen. Once you identified the slow part of a program, how do you know why it s slow? To learn more about the specific bottlenecks your program encounters, you can consult your CPU s hardware performance counters. For example, you could check the branch predictor counters to see if your program is slow due to a high number of branch mispredicts. On Linux, the perf tool is the best way to access the CPU hardware performance counters. A good starting point for working with perf is the documentation on Top-down analysis with the perf tool , which describes the optimization method that Intel established. In my Makefile, I set up two perf targets:
# GOTEST and TASKSET like shown in the earlier benchmarking setup section:
GOTEST=go test -pgo=encode.cpuprof
TASKSET=taskset -c 1
PERFBENCHFLAGS=-test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=200000x

# Use perf(1) to capture AMD IBS (the equivalent to Intel PEBS)
# PipelineL1 is roughly equivalent to Intel TopdownL1
perf:
	$(GOTEST) -c
	$(TASKSET) perf stat -M PipelineL1 ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo perf record -F 4999 -e ibs_op// --call-graph fp ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo chmod 644 perf.data

# 488281 iterations   2048 values = 1.000e9 values, so counter/1e9 = per value.
perf-per-value:
	$(GOTEST) -c
	$(TASKSET) perf stat -x, -e cycles:u,instructions:u,branches:u,branch-misses:u ./pforenc.test -test.run=^$$ -test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=488281x 2>&1 >/dev/null   awk -F, ' printf "%-16s %6.2f /val\n", $$3, $$1/1e9 '
The perf-per-value numbers are high level numbers that indicate how much work the implementation is doing. Reducing the number usually increases speed. To see the counters for each instruction (and source code lines), I use make perf, followed by perf report. A quick shortcut is perf annotate, which directly shows the hottest function.

Optimizations (scalar) Let s first see how far we can get without reaching for SIMD instructions. (The examples are not necessarily in commit order, but cherry-picked for clarity.)

Profile-Guided Optimization (PGO) PGO stands for Profile-Guided Optimization and is a feature that Go introduced as a preview in Go 1.20 (released in February 2023) and shipped as ready for general production use in Go 1.21 (released in August 2023). The idea is to capture a CPU profile that records where your program spends most of its CPU time, which you then provide to the Go compiler to give it more data to make better decisions. Most importantly, this way the Go compiler can inline functions much more aggressively than its usual heuristics allow, which does have a measurably positive effect in my series of optimization commits. Another optimization that a PGO profile allows the compiler to do is conditional devirtualization but our TurboPFor code does not use any interfaces. My strategy is to enable PGO before doing any other optimizations, so that we have the full inlining budget available that PGO gives us, and can measure the effect of other commits clearly. Surprisingly, turning on PGO actually decreases our performance (-13% geomean), but a closer investigation reveals that we just got unlucky. Let me explain. Aside from inlining and conditional devirtualization, PGO also influences alignment: The Go compiler sets PCALIGNMAX(64, 31) on the first block of a loop (the loop body ) for all loops in hot functions (per the PGO profile), i.e. Go will insert up to 31 bytes of padding to make the block land on a 64-byte boundary. Documentation like AMD s Software Optimization Guide for the AMD Zen5 Microarchitecture (2024, #58455) explicitly recommends aligning hot loops that way:
[ ] for hot loops, some further knowledge of trade-offs can be helpful. Because the processor can read an aligned 64-byte fetch block every cycle, it is suggested to either align the start of the loop to the beginning of a 64-byte cache line [ ]
Indeed, when compiling with -gcflags=all=-d=alignhot=0 to disable the alignment, performance remains as good as without PGO. How can the padding hurt more than help? The answer is: It s not the padding itself! It s a side-effect of the padding moving instructions to different addresses. In the unlucky arrangement, a macro-fused CMPQ+JGE instruction pair now ends up exactly on a 32-byte boundary. However, the Go compiler ensures fused branch sequences must never cross or end at a 32-byte boundary to fix Intel erratum SKX102 (discussion: Go issue #35881) by inserting NOPs. This NOP padding, unlike the loop alignment padding, is not free; these extra instructions slow down our otherwise dispatch-bound loops. Because the commits after the PGO enabling commit change the code, this unlucky situation is avoided for the rest of the optimization series (by chance).

Reducing memory allocations Memory allocations are quite expensive, at least in comparison to encoding/decoding integers, so I followed my usual strategy of first reducing memory allocations as much as possible. In my goturbopfor teaching decoder, whenever the code needed a scratch buffer, it would allocate it right then and there with make():
// p4dec32 decodes one block of TurboPFor-encoded 32 bit ints
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
    //  
  switch blockType  
  case blockBitpackingExceptions:
    bx, input := input[0], input[1:]
    n := len(output)

    exmap := input
    nex := 0 // number of exceptions
    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        nex++
       
     
    input = input[(n+7)/8:]

    exceptions := make([]uint32, nex)
    input = input[bitunpack32(input, exceptions, bx):]
    input = input[d.bitunpack(input, output, b):]

    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        output[i] += exceptions[0] << b
        exceptions = exceptions[1:]


    return before - len(input)
   
 
The Go compiler can turn make(T, n) calls into stack allocations, if n is known at compile-time. But, in this case nex is not known at compile-time. We can verify that Go calls into the runtime (runtime.makeslice) by dumping the object code (assembly) with source annotated (-S):
% cd ~/go/src/github.com/stapelberg/goturbopfor
% git reset --hard 49b7c05cc61e77f0257568eb73833467714d2b4a
% go test -c  # go1.27.0
% go tool objdump -S goturbopfor.test   perl -nlE 'say if /p4dec32/ .. /^$/'
TEXT github.com/stapelberg/goturbopfor.(*decoder).p4dec32(SB) /home/michael/go/src/github.com/stapelberg/goturbopfor/goturbopfor.go
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
  0x549f60		4c8da42460ffffff	LEAQ 0xffffff60(SP), R12
  0x549f68		4d3b6610		CMPQ R12, 0x10(R14)
  0x549f6c		0f86d9070000		JBE 0x54a74b
  0x549f72		55			PUSHQ BP
  0x549f73		4889e5			MOVQ SP, BP
  0x549f76		4881ec18010000		SUBQ $0x118, SP
  0x549f7d		48899c2430010000	MOVQ BX, 0x130(SP)
  0x549f85		4889b42448010000	MOVQ SI, 0x148(SP)
	if len(output) == 0  
  0x549f8d		4d85c0			TESTQ R8, R8
  0x549f90		0f84a7030000		JE 0x54a33d
  0x549f96		660f1f840000000000	NOPW 0(AX)(AX*1)
  0x549f9f		90			NOPL
[ ]
		exceptions := make([]uint32, nex)
  0x54a4be		488d057bec1700		LEAQ 0x17ec7b(IP), AX
  0x54a4c5		4c89fb			MOVQ R15, BX
  0x54a4c8		4889d9			MOVQ BX, CX
  0x54a4cb		e8f0ddf3ff		CALL runtime.makeslice(SB)
[ ]
An easy speed-up was to avoid allocations through reuse (in goturbopfor). In the DCS pfordec package (with the improved API design), I ended up with a vals [256]uint32 field in the StreamDecoder type, which brings us from 773 Mval/s to 858 Mval/s on the debian-mix:
% benchstat -filter '/impl:go /vals:debian-mix .unit:(Mval/s)' \
  baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pfordec
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
             baseline.txt               bench.txt               
                Mval/s        Mval/s     vs base                
n=2048        1.089k   1%   1.175k   0%   +7.85% (p=0.002 n=6)
n=2039         974.7   0%   1046.0   0%   +7.32% (p=0.002 n=6)
n=160          434.9   1%    513.6   5%  +18.11% (p=0.002 n=6)
geomean        772.9         857.7       +10.98%
Aside from the speed-up, avoiding memory allocations is generally nice in benchmarks because it removes the garbage collector from the equation and makes it less likely that your benchmarks get other processes OOM-killed on the same machine.

Generics for bit width specialization In general, we want to make it easy for the compiler to understand as much as possible about our algorithm. Consider this bitpack implementation:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 
Let s think through what determines the iterations and control flow this function uses:
  1. The number of input values (vals), but not their actual value.
  2. The bit width to pack into (bitWidth).
With a bit of careful rearrangement, we can provide the compiler with both, a fixed number of input values (say, 32), and a bit width, both known at compile time. Why is this worthwhile? Because we can manually unroll the loop, let the compiler eliminate much of the repetition and get much faster compiled code as a result! Let s first fix the number of input values to 32 and rewrite the loop to calculate the position offsets within dest instead of changing dest on each value (with AppendUint32):
func bitpack32Unrolled(dest []byte, vals *[32]uint32, bitWidth int)  
  // only one bounds check for 32 values
  dest = dest[: 4*bitWidth : 4*bitWidth]
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[30] elided for brevity

  // Each loop iteration is 8 lines of Go code, so for 32 input values,
  // bitpack32Unrolled contains 8*32 = 256 lines of code.

  acc  = uint64(vals[31]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // have == 0; for all bitWidths
 
Next, we want to specialize not just for 32 input values, but also for each of the 32 bit widths. Can we do better than hand-copying bitpack32Unrolled 32 times (= 8192 lines of Go code)? Yes, we can use Go generics to help us with the code generation! In Go, array types like [4]byte (not slices like []byte!) contain the length of the array as part of their type, meaning [1]byte (an array of length 1) is a different type than [2]byte. Instead of passing the bit width as a function parameter, we can declare 32 different types (one for each bit width) and recover the bit width (at compile time!) from the type system:
type bitWidthT interface  
  [1]byte   [2]byte   [3]byte   [4]byte   [5]byte  
  [6]byte   [7]byte   [8]byte   [9]byte   [10]byte  
  [11]byte   [12]byte   [13]byte   [14]byte   [15]byte  
  [16]byte   [17]byte   [18]byte   [19]byte   [20]byte  
  [21]byte   [22]byte   [23]byte   [24]byte   [25]byte  
  [26]byte   [27]byte   [28]byte   [29]byte   [30]byte  
  [31]byte   [32]byte
 

func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  var zero T
  bitWidth := len(zero)                  // known at compile time
  dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[31] elided for brevity
 
When we instantiate bitpack32Unrolled[bitWidthT] with all 32 different types ([1]byte, [2]byte, , [32]byte), the compiler substitutes the bitWidthT type parameter and produces 32 copies of the function, which we can find in our compiled executable with names like github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[12]uint8]. The shape of a generic type is based on its memory layout, so a shape for [1]byte must be different than the shape for [2]byte. Because the bitWidth is now known at compile time, the Go compiler can generate close to the optimal machine code for each bit width, which we can confirm using go tool objdump. The code is branchless (after the one bounds check per 32 values) and aside from the loads and stores (from/to memory) consists only of shifts and bit operations, all with constant operands:
% go test -c && go tool objdump -S pforenc.test
[ ]
TEXT github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[28]uint8](SB) /home/michael/dcs/internal/turbopfor/pforenc/bitpackunroll.go
func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  0x660580              55                      PUSHQ BP
  0x660581              4889e5                  MOVQ SP, BP
  0x660584              48895c2418              MOVQ BX, 0x18(SP)
        dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  0x660589              4883ff70                CMPQ DI, $0x70
  0x66058d              0f820b030000            JB 0x66089e
        acc  = uint64(vals[0]&mask) << have
  0x660593              8b06                    MOVL 0(SI), AX
  0x660595              25ffffff0f              ANDL $0xfffffff, AX
        acc  = uint64(vals[1]&mask) << have
  0x66059a              8b4e04                  MOVL 0x4(SI), CX
  0x66059d              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605a3              48c1e11c                SHLQ $0x1c, CX
  0x6605a7              4809c8                  ORQ CX, AX
                acc >>= 32
  0x6605aa              4889c1                  MOVQ AX, CX
  0x6605ad              48c1e820                SHRQ $0x20, AX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605b1              90                      NOPL
        b[0] = byte(v)
  0x6605b2              890b                    MOVL CX, 0(BX)
        acc  = uint64(vals[2]&mask) << have
  0x6605b4              8b4e08                  MOVL 0x8(SI), CX
  0x6605b7              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605bd              48c1e118                SHLQ $0x18, CX
  0x6605c1              4809c1                  ORQ AX, CX
                acc >>= 32
  0x6605c4              4889c8                  MOVQ CX, AX
  0x6605c7              48c1e920                SHRQ $0x20, CX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605cb              90                      NOPL
        b[0] = byte(v)
  0x6605cc              894304                  MOVL AX, 0x4(BX)
Now we need to actually call bitpack32 from the general bitpack function:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  if bitWidth == 0  
    return dest // no payload, sparse block with only exceptions
   
  if len(vals) >= 32  
    size := 4 * bitWidth
    for len(vals) >= 32  
      existing := len(dest)
      dest = slices.Grow(dest, size)[:existing+size]
      bitpack32(dest[existing:] /*append*/, (*[32]uint32)(vals), bitWidth)
      vals = vals[32:]
     
   
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 

func bitpack32(dest []byte, vals *[32]uint32, bitWidth int)  
  switch bitWidth  
  case 1: bitpack32Unrolled[[1]byte](dest, vals)
  case 2: bitpack32Unrolled[[2]byte](dest, vals)
  case 3: bitpack32Unrolled[[3]byte](dest, vals)
  case 4: bitpack32Unrolled[[4]byte](dest, vals)
  case 5: bitpack32Unrolled[[5]byte](dest, vals)
  case 6: bitpack32Unrolled[[6]byte](dest, vals)
  case 7: bitpack32Unrolled[[7]byte](dest, vals)
  case 8: bitpack32Unrolled[[8]byte](dest, vals)
  case 9: bitpack32Unrolled[[9]byte](dest, vals)
  case 10: bitpack32Unrolled[[10]byte](dest, vals)
  case 11: bitpack32Unrolled[[11]byte](dest, vals)
  case 12: bitpack32Unrolled[[12]byte](dest, vals)
  case 13: bitpack32Unrolled[[13]byte](dest, vals)
  case 14: bitpack32Unrolled[[14]byte](dest, vals)
  case 15: bitpack32Unrolled[[15]byte](dest, vals)
  case 16: bitpack32Unrolled[[16]byte](dest, vals)
  case 17: bitpack32Unrolled[[17]byte](dest, vals)
  case 18: bitpack32Unrolled[[18]byte](dest, vals)
  case 19: bitpack32Unrolled[[19]byte](dest, vals)
  case 20: bitpack32Unrolled[[20]byte](dest, vals)
  case 21: bitpack32Unrolled[[21]byte](dest, vals)
  case 22: bitpack32Unrolled[[22]byte](dest, vals)
  case 23: bitpack32Unrolled[[23]byte](dest, vals)
  case 24: bitpack32Unrolled[[24]byte](dest, vals)
  case 25: bitpack32Unrolled[[25]byte](dest, vals)
  case 26: bitpack32Unrolled[[26]byte](dest, vals)
  case 27: bitpack32Unrolled[[27]byte](dest, vals)
  case 28: bitpack32Unrolled[[28]byte](dest, vals)
  case 29: bitpack32Unrolled[[29]byte](dest, vals)
  case 30: bitpack32Unrolled[[30]byte](dest, vals)
  case 31: bitpack32Unrolled[[31]byte](dest, vals)
  case 32: bitpack32Unrolled[[32]byte](dest, vals)
   
 
Encoding remainder blocks is quite a bit faster (full blocks use the vertical layout anyway):
% benchstat -filter '/impl:go /n:160 .unit:(Mval/s)' baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pforenc
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
                           baseline.txt               bench.txt               
                              Mval/s        Mval/s     vs base                
vals=bitpacking-bw1          751.2   3%   1120.5   0%  +49.15% (p=0.002 n=6)
vals=bitpacking-bw2          716.8   2%   1176.0   0%  +64.07% (p=0.002 n=6)
vals=bitpacking-bw7          700.0   1%   1078.5   0%  +54.08% (p=0.002 n=6)
vals=bitpacking-bw1-exc      524.8   1%    736.8   0%  +40.40% (p=0.002 n=6)
vals=bitpacking-bw2-exc      543.7   1%    758.2   0%  +39.46% (p=0.002 n=6)
vals=bitpacking-bw7-exc      566.7   1%    787.7   0%  +38.99% (p=0.002 n=6)
vals=bitpacking-vb-exc       442.6   1%    616.5   0%  +39.29% (p=0.002 n=6)
vals=sparse-exc              532.4   0%    787.8   0%  +47.97% (p=0.002 n=6)
vals=sparse-vb-exc           408.9   1%    597.8   0%  +46.20% (p=0.002 n=6)
vals=debian-mix              559.5   0%    783.8   9%  +40.09% (p=0.002 n=6)
This performance win comes at the cost of binary size increase. In this case, the .text section (executable code) grows by about 20 KB and the .gopclntab section grows by another 26 KB. Definitely a price I am very willing to pay, but the case might not be as clear in all circumstances.

Optimization: Bigger strides with SIMD Even without reaching for SIMD instructions, a TurboPFor implementation can be made faster by making it work bigger strides. Take this code from the goturbopfor teaching decoder which counts the number of exceptions by checking if each value s bit is set in the exception bitmap:
case blockBitpackingExceptions:
  bx, input := input[0], input[1:]
  n := len(output)

  exmap, input := input, input[(n+7)/8:]
  nex := 0 // number of exceptions
  for i := range n  
    if exmap[i/8]&(1<<uint(i%8)) != 0  
      nex++
     
   
  exceptions := d.scratch[:nex]
We can use the bits.OnesCount64 functions to count ones bits in the exception bitmap, 64 values at a time. For remainder blocks, the rest is processed 8 values (1 byte) at a time:
i := 0
for ; i+8 <= n/8; i += 8  
  xm8 := binary.LittleEndian.Uint64(exmap[i:])
  nex += bits.OnesCount64(xm8)
 
for ; i < (n+7)/8; i++  
  xmb := exmap[i]
  // Clear the bits which do not belong to the exception map:
  if rem := n - i*8; rem < 8  
    xmb &= 1<<rem - 1
   
  // Go compiles OnesCount32 into an intrinsic,
  // but not OnesCount8, so we convert to uint32:
  nex += bits.OnesCount32(uint32(xmb))
 
OnesCount64 uses a 64-bit register. For comparison, AVX2 SIMD instructions use 256-bit registers (= 8 uint32) and AVX512 SIMD instructions use 512-bit registers. In the following sections, we will first set up our build tags for conditional compilation to use a trivial SIMD instruction, then walk through an AVX2 and AVX512 SIMD kernel.

SIMD build tags Let s assume we have the following scalar code: constant.go:
package pfordec

func fillConstant(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
To increase throughput, we can use AVX2 instructions if they are available on the CPU on which the program runs, i.e. using runtime dispatch. We ll first rename fillConstant to fillConstantScalar (it s now the fallback path): constant.go:
package pfordec

func fillConstantScalar(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
Next, we ll supply two different implementations (constant_nosimd.go and constant_amd64.go), the latter of which is selected when compiling for GOARCH=amd64 with GOEXPERIMENT=simd (the latter will hopefully be dropped in a later version of Go). The nosimd variant just dispatches to the fillConstantScalar, which will likely be inlined:
//go:build !goexperiment.simd   !amd64

package pfordec

func fillConstant(output []uint32, val uint32)  
  fillConstantScalar(output, val)
 
The constant_amd64.go variant assigns the hasAVX2 global variable by doing a CPUID check and then jumps to the scalar fallback if !hasAVX2, i.e. the CPU is too old:
//go:build goexperiment.simd && amd64

package pfordec

import "simd/archsimd"

var hasAVX2 = archsimd.X86.AVX2()

func fillConstant(output []uint32, val uint32)  
  if !hasAVX2  
    fillConstantScalar(output, val)
    return
   
  val8 := archsimd.BroadcastUint32x8(val)
  i := 0
  for ; i+8 <= len(output); i += 8  
    val8.StoreArray((*[8]uint32)(output[i : i+8]))
   
  // use the scalar implementation for the last <= 7 elements
  fillConstantScalar(output[i:], val)
 
We can go one step further by conditionally compiling const hasAVX2 = true when GOAMD64 is set to v3 or higher (i.e. the amd64.v3 build tag is set). As a practical example from Debian Code Search, we currently need the following checks / dispatches:
code function vector instruction set GOAMD64
encoder bitpack256v AVX2 GOAMD64=v3
encoder exbitmap AVX512 GOAMD64=v4
encoder scan AVX512+VBMI+GFNI+BITALG n/a
decoder bitunpack AVX2 GOAMD64=v3
decoder bitunpack256v32 AVX2 GOAMD64=v3
decoder bitunpack256v32Ex AVX512 GOAMD64=v4
In DCS, the effect is measurably positive, but small.

The 256 uint32 vertical layout First, here is the layout explanation from my 2019 TurboPFor analysis blog post:
In regular (non-SIMD) bitpacking, integers are stored on disk one after the other, padded to a full byte, as a byte is the smallest addressable unit when reading data from disk. For example, if you bitpack only one 3 bit int, you will end up with 5 bits of padding. SIMD bitpacking works like regular bitpacking, but processes 8 uint32 little-endian values at the same time, leveraging the AVX instruction set. The following illustration shows the order in which 3-bit integers are decoded from disk:
The scalar implementation uses an array of 8 uint64 to process 8 values at a time:
func bitunpack256v32(input []byte, dest []uint32, bitWidth int) (read int)  
  mask := uint64(1)<<bitWidth - 1
  orig := len(input)
  var bits uint
  var acc [8]uint64 // accumulator: current+next bits
  for op := 0; op < len(dest);  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      for i := range 8  
        acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
        input = input[4:]
       
      bits += 32
     
    for i := range 8  
      dest[op] = uint32(acc[i] & mask)
      op++
      acc[i] >>= bitWidth
     
    bits -= uint(bitWidth)
   
  return orig - len(input)
 
The SIMD version also processes 8 values, but without a for i := range 8 loop! One difference is that we no longer have the luxury of using uint64 for acc (holding rest and current bits); because AVX2 registers only fit 8 uint32 (not 8 uint64). Instead, we split acc into rest8 and cur8.
func bitunpack256v32(fullinput []byte, fulldest []uint32, bitWidth int) (read int)  
  dest := fulldest[:256]
  if bitWidth == 0  
    clear(dest)
    return 0
   
  n := 32 * int(bitWidth)
  input := fullinput[:n] // tell the Go compiler how long the input is
  mask8 := archsimd.BroadcastUint32x8(uint32(1)<<bitWidth - 1)
  bitWidth8 := archsimd.BroadcastUint32x8(uint32(bitWidth))
  var bits uint
  pos := 0
  // var acc [8]uint64
  var rest8 archsimd.Uint32x8
  var cur8 archsimd.Uint32x8
  for op := 0; op < 256; op += 8  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      // acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
      next := archsimd.LoadUint8x32(input[pos : pos+32]).ReshapeToUint32s()
      pos += 32  // input = input[4:]
      cur8 = rest8.Or(next.ShiftAllLeft(uint64(bits)))
      // acc[i] >>= bitWidth
      rest8 = next.ShiftAllRight(uint64(uint(bitWidth) - bits))
      bits += 32
      else  
      cur8 = rest8
      // acc[i] >>= bitWidth
      rest8 = rest8.ShiftRight(bitWidth8)
     
    // dest[op] = uint32(acc[i] & mask)
    cur8.And(mask8).Store(dest[op : op+8])
    bits -= uint(bitWidth)
   
  return n
 
The SIMD version benchmarks about 3x as fast as the scalar version. Another significant speedup is to use generics for bit width specialization for this SIMD kernel so that bitWidth becomes a compile-time constant and the compiler can generate better code.

Positional Popcount For my TurboPFor encoder, I implemented the same techniques as described above:
  1. Bitpack full blocks with SIMD (AVX2)
  2. Gather exceptions using SIMD (AVX512)
  3. Use generics to specialize per bit width
These changes are sufficient to roughly match the cgo performance, but then Claude Fable 5 found another 2x speed-up on top of that! The key observation is that once encoding blocks is fast, the preceding step of scanning the input values to decide which block type to use becomes the bottleneck. Here is the encoder s main encode function, which first does one pass over the input values (scan) and then prices all different block types at all relevant bit widths (requires fast access to the scan histogram):
func (be *BlockEncoder) encode(dest []byte, vals []uint32, layout blockLayout) []byte  
  var stats stats
  scan(&stats, vals) // gathers statistics from every value in vals
  bitWidth := bits.Len32(stats.or)
  if stats.or == stats.and  
    return be.encodeConstant(dest, vals, bitWidth)
   
  n := len(vals)
  // bitpacking is the default, unless we find a more efficient block type.
  bestType := blockBitpacking
  bestB := bitWidth
  best := priceBitpack(n, bitWidth, layout)

  // Walk from high bitWidths to low: to break ties, we prefer
  // the encoding with fewer exceptions (for faster decoding).
  for b := bitWidth - 1; b >= 0; b--   // up to 32 iterations
    nex := int(stats.cnt[b])
    size := priceBitpackExceptions(n, b, bitWidth, nex, layout)
    if size < best  
      bestType = blockBitpackingExceptions
      bestB = b
      best = size
     
    // Over-approximate the number of VB bytes.
    vb := nex + // exceptions using 1, 2, 3, 4, or 5 VB bytes
      int(stats.cnt[b+7]+ // exceptions using 2, 3, 4, or 5 VB bytes
        stats.cnt[b+14]+ // exceptions using 3, 4, or 5 VB bytes
        stats.cnt[b+19]+ // exceptions using 4 or 5 VB bytes
        stats.cnt[b+24]) // exceptions using 5 VB bytes
    size = headerBytes + headerExBytes + payloadBytes(n, b, layout) + vb + nex
    if size < best  
      bestType = blockBitpackingVBExceptions
      bestB = b
      best = size
     
   
  switch bestType  
  case blockBitpacking:
    return be.encodeBitpack(dest, vals, layout, bitWidth)
  case blockBitpackingExceptions:
    return be.encodeBitpackExc(dest, vals, layout, bestB, bitWidth-bestB)
  case blockBitpackingVBExceptions:
    return be.encodeBitpackVBExc(dest, vals, layout, bestB, int(stats.cnt[bestB]))
  default:
    panic("BUG: bestType not implemented")
   
 
I ll show you a slightly shortened version of scan, the function which is the bottleneck:
type stats struct  
  // cnt[n] = how many values where bits.Len32(val)>n,
  // i.e. how many exceptions are required for bitWidth=n.
  // Padded so that cnt[b+24] is always in bounds.
  cnt [32 + 24]uint32
 

func scan(output *stats, vals []uint32)  
  for _, val := range vals  
    for b := range bits.Len32(val)  
      output.cnt[b]++ // b bits are not enough to store val


Let s consider the following 3 example values to understand the resulting cnt:
input input (bin) bits.Len32
23 0b0000010111 5
5 0b0000000101 3
666 0b1010011010 10
The resulting cnt exception count histogram would contain (cnt shortened to c):
c[0] c[1] c[2] c[3] c[4] c[5] c[6] c[7] c[8] c[9] c[10]
3 3 3 2 2 1 1 1 1 1 0
In words, this means that at bit width 10, we could encode all the values without any exceptions. But most values do not need 10 bits, so a bit width of 5 would be more efficient, but requires storing one exception. Encoding at bit width 4 requires 2 exceptions, and so on. The scan function above is intentionally kept simple for illustration. We can make it faster by moving the per-bit-width loop outside the per-element loop. The fast version still needs about 12 instructions per value. With SIMD, we can reduce this to by 8x to only 1.5 instructions per value!

The trick: smear masks enable positional popcount The trick is to turn each input value into its smear mask (imagine taking the first 1 bit and smearing it across the remaining positions). Here are the smear masks for our example:
input input (bin) bits.Len32 smear mask
23 0b0000010111 5 0b0000011111
5 0b0000000101 3 0b0000000111
666 0b1010011010 10 0b1111111111
Turning a value into its smear mask is computationally cheap: Go implements BitLen(x) (functions like bits.Len32) by calculating 32 - LZCNT(x). We can calculate the smear mask of a value with ^uint32(0) >> LZCNT(x), i.e. starting with a 32-one-bits mask and shifting it by the number of leading zeros. Now, to obtain e.g. cnt[4], we can count the 1 bits at bit position 4 of all input values. The POPCNT instruction counts bits very efficiently, but it counts one bits within a register, so it counts rows, not columns. Counting columns is called Positional Population Count. I found the following papers that describe positional popcount with SIMD:

Positional Popcount: a visual explanation To understand the AVX512 implementation of positional popcount, I found it most helpful to visualize an AVX512 register (512 bits, i.e. 64 bytes). The graphic below uses the Uint64x8 layout, meaning it divides the register into 8 lanes of 64 bits (= 8 bytes) each. This illustration shows the whole process: how uint32s are loaded into an AVX512 register (all 4 of its bytes, in sequence) and where we end up, i.e. the 32 positional popcounts: Let s break down this process into its individual steps. First, we turn each loaded value into its smear mask as explained above. The VPOPCNTB vector instruction calculates POPCNT (1 byte) of 64 bytes at once, but first we need to shuffle the bytes inside the register: in load order, we have a full uint32 (4 bytes), followed by another uint32, per lane. First, we permute the bytes (VPERMB) such that all the first bytes of each value end up in one lane ( transpose the bytes ): Next, we transpose the bits using the GF2P8AFFINEQB instruction, which sounds scary but turns out to be quite flexible for bit manipulation of all kinds. The GF2P8AFFINEQB instruction is also the star of the show in Go s Green Tea Garbage Collector (2025). Here is the bit transpose, shown in the AVX512 register layout (see below for a different layout): I found it easier to understand the transpose step when arranging the 8 bytes of lane 0 from top-to-bottom (instead of left-to-right), because then it looks like a 90 degree clockwise rotation: Now we can use VPOPCNTB to count the bits in all 64 bytes at once: After all loop iterations (processing 16 values each) are done, we add the two groups (first 8 values, second 8 values) to obtain the 32 exception counts:

Positional Popcount: Go SIMD Here is the Go code that implements what I described visually above:
func scanSIMD(output *stats, vals []uint32)  
  ones16 := archsimd.BroadcastUint32x16(^uint32(0)) // 16 32-one-bits masks
  shuffle := archsimd.LoadUint8x64Array(&scanShuffle)
  units := archsimd.LoadUint8x64Array(&scanUnits)
  var acc archsimd.Uint8x64
  idx := 0
  for ; idx+16 <= len(vals); idx += 16  
    v := archsimd.LoadUint32x16(vals[idx : idx+16])
    // Replace all values with their smear masks.
    smear := ones16.ShiftRight(v.LeadingZeros()).ReshapeToUint8s()
    // Transpose: shuffle the bytes, then transpose the bits.
    matrices := smear.Permute(shuffle).ReshapeToUint64s()
    transposed := units.GaloisFieldAffineTransform(matrices, 0)
    // Popcount 64 bytes at once into the accumulator.
    acc = acc.Add(transposed.OnesCount())
   
  // Store the accumulator into output.cnt:
  // Widen the two groups of byte counts to uint16 lanes (so that
  // 128+128 = 256 fits), fold them into cnt[b] for b=0..31,
  // then widen again to the uint32 lanes of output.cnt.
  sum := acc.GetLo().ExtendToUint16().Add(acc.GetHi().ExtendToUint16())
  sum.GetLo().ExtendToUint32().Store(output.cnt[0:16])
  sum.GetHi().ExtendToUint32().Store(output.cnt[16:32])
  // scalar tail for the 0..15 remaining values
  for _, val := range vals[idx:]  
    for b := range bits.Len32(val)  
      output.cnt[b]++


Have a look at the commit introducing positional popcount to DCS for the full code (including shuffle tables and ISA checks) as well as the detailed benchmark results.

Go even faster? The SIMD optimizations I showed above beat the cgo TurboPFor library that Debian Code Search used before. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. Could we make my Go TurboPFor implementation even faster, to truly match the C speed? Yes! But also no. Let me explain:
  1. We could use more SIMD instructions to remove all code that still processes one value at a time. For example, in my encoder s encodeBitpackVBExc function. Or we could price all bit widths concurrently in encode. Or in the decoder s exception apply code path.
    But all of these SIMD instructions make understanding (and changing) the code harder, so I am cautious regarding which ones I introduce.
  2. A big part of the performance gap is due to Go s bounds checks. While it costs performance, bounds checking is great for safety, so I will not turn off bounds checking. The Go compiler eliminates a number of bounds checks when it understands it s safe to do so. One optimization avenue could be to make the prove pass in the Go compiler smarter to eliminate more bounds checks.
  3. When doing mid-stack inlining (proposal #19348) (2017), Go sometimes needs to put NOP instructions into the binary so that it can attach inlining markers. For dispatch-bound functions, these extra NOPs can measurable slow down execution.
  4. The Go compiler currently allows specifying the architecture (GOARCH=amd64) and microarchitecture (GOAMD64=v3), but not a specific CPU architecture (like AMD Zen 4). Therefore, CPU-specific workarounds for one vendor affect all the generated code. The specific one I encountered in my code is that the Go compiler emits XORL CX,CX before every POPCNT to break a false-output-dependency from the Intel Sandy Bridge Skylake era, which is unnecessary on AMD Zen CPUs.
    I suspect that Go intentionally does not offer this level of customizability.
  5. After all of the above points are addressed, what remains is better code generation in specific cases. To illustrate what I mean, consider the example of incrementing a loop variable, where Go re-derives an index every time:
    Go: POPCNTL; ADDQ DI,CX; LEAQ (base)(CX*4) (3 instructions)
    clang: popcnt; lea rax,[rax+4*rdi] (2 instructions)
    Depending on the specific case, improving the compiler might be easy or prohibitively complex. Often, such improvements are hard to measure conclusively.

Conclusion Go s SIMD support makes available in Go code without having to resort to cgo or assembly a powerful part of modern CPUs which allows speeding up the kind of computation that TurboPFor needs by an order of magnitude! I found it very valuable to use a coding agent (Claude Code, with Opus 5 and Fable 5 in this case) to help with the many tedious parts of such performance work (and still it took me weeks!). The LLM can read objdump output much faster than I can, can see patterns and correlations I might never identify, never becomes frustrated after a compiler error or runtime panic, and never runs out of patience to run one more experiment, as long as I give it measurable and reachable goals. The performance of the SIMD code which one can get from the Go compiler is pretty close to what a good C compiler like clang provides. The CPU performance counters show value decoding speeds of 7 instructions/cycle (IPC) on a machine where the maximum is 8 IPC. To me, SIMD support is a very welcome addition to Go.

2 September 2026

Valhalla's Things: A Corset Cover

Posted on September 2, 2026
Tags: madeof:atoms, craft:sewing, period:edwardian, FreeSoftWear
A woman wearing a sleeveless blouse in white fabric with a big band of whitework embroidery gathered over a light blue ribbon at the neckline, a box pleat at the front, another, smaller, band of whitework embroidery at the waist, without a ribbon, and a short peplum that doesn't reach the center front. Around the armscyes there are small ruffles, giving even more volume at the top. A bit of a grey corset peeks out from the center front, below the waist. Many years ago, before I had my sewing pattern website, I made myself a simple corset cover according to the instructions on an Edwardian pattern drafting manual. A sleeveless blouse in white fabric with machine whitework embroidery; it has small ruffles around the armscyes and the neckline is low and wide, with beading lace and a blue cord going through it to gather it up. It worked, I wore it. Years later I saw a blog post on Pour La Victoire on making a corset cover based on the same book, but with completely different results, and thought that it would have been nice to make another one to publish instructions for my take on it. However, I didn t have any embroidery flouncing on hand, nor did I have a need for a new corset cover, and the project remained on the list, on low priority (although I did buy some beading lace for it, when I stumbled on it). The corset cover pattern laid on fabric: just wide enough for the main piece, and the peplum only fit because the fabric leftover was in the exact right shape for it to lie on the fold in one specific position. Then, after finishing my vampire shirt, I noticed that I had just enough fabric left for a corset cover, and by just enough I really mean just enough, as I discovered when laying the pattern on the fabric. So I dug in my files to get the original pattern I used, brought it up to date, and added the missing details such as the pleating guides that I had skipped when making the pattern just for myself. Doing so I realized that on my old cover I had done the fake pleat in the front wrong, making just a single pleat instead of a box pleat. Also, I originally directly gathered the sleeves in the armscyes, but watching the book again I realized that the sleeves were made up of a gathered ruffle plus a straight band. Both issues were fixed and I could cut the fabric and start sewing. By machine, including using a narrow hem foot instead of sewing rolled hems by hand as my instinct kept reminding me would have looked neater. But this is a garment from a sewing machine time, and probably one that in many cases would have been bought from a mass producer, and it s underwear, so there is no real need for the hems to be perfect, as it s going to be hidden anyway. But most importantly, I wanted to write instructions for machine sewing, for a change, and so I had to machine sew all steps that I had to take pictures of. I did do the buttonholes by hand, because I hate the buttonhole attachment on my machine, and the buttonhole attachment hates me. I used a lighter weight fabric for the sleeve ruffles, both because I didn t have a big enough piece of main fabric not to have to piece them, and because I felt that it looks better, as it s the same voile I used for the ruffles on the vampire shirt. Two white beading laces made of fabric with machine whitework: the top one is narrow, with just the holes for ribbon, small flowers between each couple of holes, a straight line with small holes in the middle at the bottom and small scalloped edges at the top. The bottom one is significantly taller, with bigger holes, scalloped edges on both sides that give a look of oval medallions which in turn have scalloped edges. When it came to the beading lace, I had two that I had bought more or less thinking about this project: the earlier one was narrow and suitable to do its job, but the one I had bought more recently was taller, with an edge that made it suitable to give more fullness to the bust when gathered up. I contemplated for a short while, and then decided to go for fullness and use the taller border for the top edge, but the smaller one at the waist, where fullness is not wanted. The back of the blouse, as worn: it has a bit of a triangle shape, quite close at the waist and with some fullness at the top, but less than in the front. The book claimed that this pattern required little labour, and indeed it did: even when taking step by step pictures it only took a few hours spread over a week, plus the time to make buttonholes by hand over the next week. And then the reason for the whole project: I published my pattern and instructions under a free license. I still haven t worn the corset cover, except for these pictures, but I hope to do so later in the year when the weather becomes more reasonable.
30 August 2026

Ritesh Raj Sarraf: Taming the AI Agents (Part 2): Cross-Vendor Agent-to-Agent (A2A) Swarms over the Software Forge

Preface: The Unanswered Frontier In Part 1: Taming the AI Agents, I shared the architectural blueprint of CAMP (Cross-Agent Memory Protocol) how we used Linux Bubblewrap (bwrap), camp-acpd, OPA policy enforcement, and a central pgvector MemPalace to bring deterministic discipline, sandboxing, and long-term memory to a heterogeneous fleet of AI coding assistants (Claude Code, Google Antigravity, Grok Build, and GitHub Copilot). At the end of that article, however, I highlighted a significant hurdle: The Headless Limitation.
While passive A2A works beautifully for structured handoffs, the current frontier of agentic design faces a key limitation: agents are not yet fully headless-capable. They depend on the active terminal session, browser loop, or prompt loop of the user to keep executing. Because agents cannot run completely detached in the background as daemon processes, we cannot yet achieve active A2A communication
For weeks, this seemed like an insurmountable impasse. Proprietary AI vendors have zero commercial incentive to ratify a universal, open, cross-vendor Agent-to-Agent (A2A) communication protocol. Each vendor builds its own walled garden (Claude s cross-session features, OpenAI s custom ecosystems, etc.). If you wait for the industry to hand you an open interoperability standard, you will wait forever. Then, on August 26, 2026, inspired by Colin Walters article on Agentic AI and software forges and GitHub Agentic Workflows (gh-aw), we had a sudden realization: We don t need a new protocol, a new distributed message broker, or permission from proprietary AI vendors. We already have the universal, decentralized communication bus that software engineers have relied on for decades: the software forge itself. Over the span of 48 intensive hours (from RFC #788 through milestones M1 to M3 and live dogfooding on #813), we designed, implemented, fortified, and verified fully autonomous, headless, cross-vendor Agent-to-Agent swarms running over a local Gitea forge. Here is how we did it, the architectural hurdles we solved, and why this changes the game for autonomous software engineering.

1. The Core Realization: The Forge is the Bus When people think about multi-agent swarms, they often imagine complex distributed RPC frameworks, microservices exchanging ephemeral JSON-RPC blobs, or bespoke socket daemons. In practice, this approach suffers from major flaws:
  1. No shared context or durable audit trail: Transient network packets vanish unless heavily logged.
  2. Proprietary CLI fragmentation: Different vendor tools (Claude CLI, Antigravity CLI, Grok CLI, Copilot CLI) do not speak the same internal language.
  3. Loss of human visibility: When agents talk over private network channels, human operators lose the ability to inspect, pause, or audit the conversation.
By flipping the paradigm and making the software forge (Gitea) the primary communication channel, everything falls naturally into place:
  • Issues and Pull Requests are the shared state: The issue description and discussion thread form the canonical, append-only conversation log.
  • @mentions are the dispatch triggers: When an agent (or human) writes @grok Please review this PR in a comment, Gitea fires a standard webhook (issue_comment).
  • Webhooks provide unforgeable authentication: The webhook payload contains the cryptographically verified sender identity. An agent cannot spoof another agent s identity by merely typing their name in text.
  • Every CLI already supports non-interactive prompt mode: The CLIs don t even agree on the command-line flag Claude uses -p, Grok uses -p, Antigravity uses --print, Copilot uses --prompt. But they all agree on the essential contract: Take a prompt string, execute tools, print output, and exit.
          Gitea Webhook           
  Gitea Forge     >   camp-a2a-bridge.py    
  (localhost)     (issue_comment / assignment)    (Validates & Files)   


         Writes comment / review                 
         via camp_acp_gateway                     A2A Inbox Ledger      
                                                 
                              
  Fortified Headless Agent                                  
  (bwrap + OPA + MCP sandbox)   <   
     Claude Code (-p)            Spawn PID           camp-a2a-dispatcher   
     Grok Build (-p)             (Cold or Resume)    (Enforces Hop Cap,    
     Antigravity (--print)                            Rule 1/2, Sandbox)   
                      

2. Proving Fortified Headless Execution Before opening the floodgates to background agent dispatch, we had to answer a critical security question: Does a non-interactive, headless agent run with the same strict security sandboxing, audit logging, and tool rails as an interactive session? On August 26, we probed all fleet launchers on the host with a baseline check: 'Call camp_startup_check and print its result verbatim, then exit.' The results settled the question immediately:
  • Antigravity (agy --print / KIR): PASS Gateway answered, full JSON returned.
  • Grok (grok -p / GRK): PASS Gateway answered.
  • Claude Code (claude -p / CLD): PASS Gateway answered.
  • GitHub Copilot CLI (copilot --prompt / CPL): Initially held on TTY tool consent; later unlocked in Milestone 6 via --allow-all-tools --session-id=<uuid>.
  • Audit Trail: Consecutive audit IDs were recorded in the central ledger: 4574 (KIR), 4575 (GRK), 4576 (CLD).
This proved that a headless run through our fortified pilot launcher (camp_pilot_*.sh) is a first-class, fully audited, sandboxed CAMP agent running inside its Bubblewrap container under OPA policy gates. It is not an unconstrained background script or a degraded bypass.

3. The 3-Tier Memory Architecture A naive multi-agent dispatch has an immediate flaw: Every time an agent is invoked, it starts from a blank slate (cold start). If @claude tags @grok to review code, and @grok replies asking for clarification, @claude s second invocation would normally forget everything it did 5 minutes ago, forcing it to burn thousands of tokens re-reading the entire git history from scratch. To solve this, we established a clean 3-Tier Memory Model:
 
                         3-TIER MEMORY MODEL                              
 
  Tier 1: CLI Conversation Session (Working Memory)                       
      Per-(Agent, Repo, Issue) mapping in a2a-sessions.json               
      Fast, native, compacted context across multi-turn pokes             
      Resumed via --resume (CLD), -r (GRK), --conversation (agy)          
 
  Tier 2: The Gitea Thread (Public Bus & Record)                          
      Cross-vendor shared truth across Claude, Grok, Antigravity & Human  
      Survives process restarts, machine reboots, and dead sessions       
 
  Tier 3: Central MemPalace (Durable Long-Term Knowledge)                 
      pgvector database (17,000+ drawers across agent wings)              
      Structured Knowledge Graph (mempalace_kg_*) for mutable facts       
      Attributed AAAK dialect queryable by any agent across any project   
 

The BANANA Two-Shot Test To verify Tier 1 working memory persistence across independent processes, we designed a simple two-shot host test:
  1. Shot 1 (Create): Dispatch agent headlessly: Remember the token BANANA-M2. Print ok and exit. Capture the vendor s session UUID.
  2. Shot 2 (Resume): Spawn a completely new operating system process with the resume flag pointing to that UUID: What token did I ask you to remember?
Every agent CLI passed with flying colors:
  • Grok: -r 01a03ecc-3ed0-71e1-9a5c-e098bb29ba10 answered BANANA-GRK.
  • Claude: --resume 0a587733-9aec-43c5-9cb7-d424e95b2c5b answered BANANA-CLD.
  • Antigravity: --conversation 2e3c43d9-d6fe-4c5c-801b-b9ceb2e7e196 answered BANANA-KIR-JSON.
  • Copilot: --session-id <uuid> verified in Milestone 6 (DoD #820).
The dispatcher simply maintains a lightweight JSON mapping ((agent, repo, issue_number) -> vendor_session_uuid). On the first poke of an issue, it creates and saves the session ID; on any subsequent poke on that same issue, it resumes the exact same conversational thread!

4. The Engineering Milestones: From Concept to Production Building this system required solving several subtle, real-world friction points across multiple agent CLI implementations. Under the guidance of our plan of record (RFC #788), we delivered this through four focused milestones:

Milestone 1 & 1.1: Reliable Headless Spawning
  • PR #797 (M1): Configured the dispatcher launch table for all probed CLIs with JSON output formatting.
  • PR #800 (M1.1): Eliminated the queue-behind-live-session anti-pattern. Originally, if a human had a Claude or Grok TUI open on their desktop, the dispatcher would defer incoming tasks so as not to collide with the live session. We realized that headless tasks must be independent: every Gitea mention spawns an isolated, sandboxed background process tied to that specific issue, allowing concurrent headless work while the human works in their interactive TUI.
  • PR #803 (M1.2): Standardized command-line argument parsing for Antigravity (agy --print <prompt> --output-format json).

Milestone 2: Session-per-Issue Working Memory
  • PR #805 (M2): Implemented a2a-sessions.json to store and resume vendor session UUIDs. If a resume fails (e.g. session purged upstream), the dispatcher gracefully falls back to a clean cold start without failing the task.

Milestone 3: Cross-Agent Hops & Crucial Safety Rails
  • PR #807 (M3): Enabled agent-to-agent dispatch (Rule 2 reversal). Previously, only mentions authored by rrs (the human) would trigger execution. With M3, an authenticated comment from @claude mentioning @grok triggers Grok s headless launcher.
  • PR #811 (M3.1): Set --permission-mode bypassPermissions for headless Claude Code so non-interactive runs execute tool calls without stalling on TTY prompts.
  • PR #812 (M3.2): Restricted agent summon parsing to line-initial @login tokens with a non-empty task description (#810), preventing accidental dispatches from passive conversational references.

Milestone 4: Directives, Specification & Living Documentation
  • PR #815 (M4): Aligned CAMP fleet directives, architecture specifications, and user documentation with the live A2A implementation.

Milestone 5: Concurrent Dispatching & Hop-Cap Attribution
  • PR #816: Stamped hop-cap notices under a dedicated system bridge identity and automatically applied the needs-human label on held threads.
  • PR #817 (Threaded Scheduler): Replaced the single-threaded serial dispatcher with a concurrent thread-pool scheduler (#804). Multi-agent dispatches across different issues now execute concurrently in parallel background threads instead of queuing behind long-running tasks.

Milestone 6: Full Fleet Coverage with GitHub Copilot
  • PR #819 (M6): Brought GitHub Copilot CLI into the headless A2A fleet (#818). By passing --allow-all-tools and pinning minted session UUIDs (--session-id=<uuid>), Copilot achieved full parity with Claude, Grok, and Antigravity, completing 100% headless fleet coverage across all four major AI coding assistants.

5. Hard Safety Rails: Preventing Autonomous Runaway Loops Letting AI agents autonomously invoke each other in background loops without a human watching is a recipe for an infinite, credit-draining token fire. We put four non-negotiable safety guardrails in place:

Guardrail 1: The Strict Hop Cap The dispatcher tracks hops per (repo, issue). Each agent-to-agent dispatch increments the counter.
  • Hop Limit = 3: A typical review round-trip is 2 hops (Human $\rightarrow$ Claude $\rightarrow$ Grok $\rightarrow$ Claude).
  • Automatic Halt on Hop 4: If agents attempt a 4th autonomous hop without human participation, the bridge refuses to launch, posts a diagnostic notice to the thread: [camp-a2a-bridge] hop cap reached (3 agent-to-agent dispatches on CAMP/camp-infrastructure#813) not launching GRK for claude's mention, and holds execution until the human (rrs) provides input or resets the count.
[ Human: rrs ]   (Cold Start)  > [ @Claude ]
                                                
                                       (Hop 1)   @grok please review
                                                
                                          [ @Grok ]
                                                
                       (Hop 2: Resume)           @claude I reviewed
                                                
                                         [ @Claude ]
                                                
                                       (Hop 3)   @grok ack hop 4
                                                
                                   
                                     DISPATCHER HOP CAP: 3   
                                      *** BLOCKED & HELD *** 
                                      Awaiting Human Reset   
                                   

Guardrail 2: Deliberate Summon Parsing (M3.2, #810 / PR #812) In human conversation, we often reference colleagues in passing: I will talk to @claude about this later or See @grok s table above . Early prototypes treated any appearance of @agent as a dispatch trigger, causing accidental, unwanted agent launches! We instituted a strict Summon Predicate: For fleet agents, a mention is only considered an actionable summon if:
  1. The @login appears as the starting word of a line (optionally preceded by markdown list markers *, -, or >).
  2. It is immediately followed by whitespace and a non-empty task description.
Mid-sentence mentions in discussion paragraphs are parsed as passive conversational text and never trigger background dispatches.

Guardrail 3: Headless Tool Permissions without Weakening Security (M3.1, #809 / PR #811) In interactive mode, Claude Code presents interactive TTY prompts asking the user to approve MCP tool calls (such as camp_pr_get or camp_pr_get_diff). In unattended headless mode, there is no TTY, causing the run to fail with permission errors. To fix this, we configured --permission-mode bypassPermissions for Claude s headless CLI invocation. Crucially, this only bypasses Claude s internal TTY UI prompt it does not bypass CAMP s security rails. All command executions still route through camp-acpd and Bubblewrap namespaces; OPA policy checks remain active; and privileged operations (such as merging pull requests or restarting system services) still trigger desktop Zenity HITL dialogs on the human s workstation.

Guardrail 4: The Sovereign Kill Switch (Rule 1) At any point, the human operator can instantly freeze all background agent dispatches across the entire infrastructure with a single standard Linux command:
systemctl --user stop camp-a2a-active.service

6. Live Dogfooding: Watching the Swarm in Action On August 27, 2026, on issue CAMP/camp-infrastructure#813, we ran the full live dogfood test of the A2A system. Here is the exact transcript of what took place entirely autonomously in the Gitea issue thread:
  1. Human initiates: rrs comments on issue #813:
    @claude Please start the M3 dogfood. On this issue, post a conversation comment whose first line is exactly: @grok Please review this issue in one short paragraph, then stop.
  2. Claude launches (Cold start): The dispatcher spins up @claude headlessly inside bwrap. Claude reads the issue and posts:
    @grok Please review this issue in one short paragraph, then stop.
    (M3 dogfood step 2 posted by @claude on rrs s instruction; this is the CLD $\rightarrow$ GRK fleet hop.)
  3. Grok launches (Cold start, Hop 1): The bridge intercepts Claude s comment, identifies the start-of-line @grok summon, and launches @grok. Grok reviews the issue and replies:
    @claude I have reviewed this issue. Please confirm and stop.
    #813 is a throwaway live dogfood of A2A M3 on 6.git+b78c65cf
  4. Claude resumes (Session Resume, Hop 2): The bridge intercepts Grok s comment, sees the @claude summon, and launches Claude with --resume b398d048-ccc3-4cce-8437-4cf8748881a8. Claude immediately remembers its earlier context without token waste:
    Confirmed Grok's review (comment 88562) received via the GRK CLD fleet hop. That completes the round trip: rrs CLD, CLD GRK, GRK CLD, and this reply. I am deliberately not tagging anyone here, so the chain stops at two agent hops. Stopping.
  5. Testing the Hop Cap (Hop 3 $\rightarrow$ 4): grok prompts @claude Please ack hop four then stop. Claude posts @grok Please ack hop four then stop. (Hop 3). When Grok would have been launched for Hop 4, the dispatcher intervenes:
    [camp-a2a-bridge] hop cap reached (3 agent-to-agent dispatches on CAMP/camp-infrastructure#813) not launching GRK for claude's mention.
  6. Human Reset & Multi-Agent Wrap-up: rrs steps in, resets the state, and asks the fleet for final status. In parallel:
    • @grok delivers a closure scorecard.
    • @claude confirms session continuity and M3.2 summon filtering.
    • @priyasi (Antigravity CLI) runs automated ACP checks: 44/44 test suite passing, 17,219 MemPalace vector drawers active, zero spec drift.
    • @agrickxy (Antigravity CLI) provides comprehensive infrastructure impression analysis.
    • @kiran (Antigravity CLI) is summoned headlessly to draft this very blog post!

7. The Ergonomic Breakthrough: The Forge as the Unified Mindmap & Interface Beyond backend plumbing and sandboxing, routing agent interaction through Gitea fundamentally revolutionizes the developer experience of managing an AI fleet.

The Mindmap Mental Model: Threaded Conversations & Forking Tasks In traditional CLI tools, conversations are constrained to a single, linear terminal scrollback. When an agent discovers multiple sub-problems, exploring them sequentially in one prompt loop rapidly pollutes the context window and confuses the model. Using the forge as the communication gateway naturally unlocks a mindmap mental model:
  • Forking sub-threads: Complex problems can be split into dedicated child issues or threaded PR reviews.
  • Focused execution scopes: An agent can be summoned to solve a narrow sub-task in its own issue thread without derailing the parent architectural discussion.
  • Structured problem decomposition: The forge issue hierarchy maps 1:1 to the developer s mental map of the project.

Eliminating Terminal UI Fragmentation Anyone using multiple AI coding assistants on a daily basis quickly grows exhausted by their jarring terminal UI differences: differing ANSI escape rendering, inconsistent markdown wrapping, erratic diff pagers, and incompatible keybindings across Claude, Grok, and Antigravity. Gitea homogenizes the entire fleet under a single, polished rich-text web view:
  • Syntax-highlighted code blocks and visual side-by-side git diffs.
  • Clear author badges attributing each contribution to its exact agent identity (@claude, @grok, @priyasi, @kiran).
  • Collapsible <details> blocks for voluminous diagnostic outputs.
  • Interactive task lists and markdown tables.

Effortless Context Retrieval, Archival & Data Retention Auditing past agent decisions in terminal logs or ephemeral chat histories is notoriously difficult. With the forge, every exchange is:
  • Contextually bound: Pinned directly to the repository, branch, and commit SHA being modified.
  • Organized & Archival-Grade: Full-text searchable with clear milestone and issue tags.
  • Topic-Focused: The human operator can review the complete lifecycle of a discussion in seconds, gaining a rapid, holistic grasp on the entire subject.
Reading back through past agent interactions becomes a breeze to the point where interacting via the intermediary Gitea interface becomes far more pleasant and productive than wrestling with multiple desktop CLI terminals.

Remote Connectivity & Headless Agent Farm Management Because Gitea provides a standard web and API interface, you are no longer chained to the workstation running the agent processes:
  • Monitor progress and dispatch tasks from a mobile browser, tablet, or remote laptop.
  • Queue review tasks on the go without requiring active SSH sessions or terminal multiplexers.
  • The local agent farm continues working silently in its sandboxed daemon containers.

Quietly Achieving the Holy Grail: Live Cross-Vendor Swarms For years, the AI industry has treated cross-vendor multi-agent interoperability as an elusive dream waiting for industry-wide API standardization. By recognizing the software forge as the universal message bus, we quietly achieved live, production-grade, cross-vendor communication across completely distinct vendor models.

8. What This Means for the Future of Agentic AI This milestone marks a fundamental shift in how we interact with autonomous AI systems:
  1. Heterogeneous Agent Specialization: We don t have to choose a single winner among AI models. We can task Claude Code with architectural refactoring, summon Grok Build for rapid verification and adversarial PR reviews, and deploy Google Antigravity agents for codebase exploration and documentation drafting all coordinating fluidly in the same PR thread.
  2. True Human Sovereignty: The human developer is no longer a bottleneck typist or a passive spectator. You act as the Engineering Manager / Lead Architect. You set the requirements on an issue, tag the lead agent, and let the agents iterate, review, and test among themselves in the thread while hard hop caps, OPA policies, and Zenity HITL gates guarantee that no agent merges code or pushes upstream without your explicit sign-off.
  3. No Vendor Lock-In: Because the entire coordination fabric is built on standard Git, HTTP webhooks, local Linux container sandboxes (bwrap), and open MCP tools, any new AI CLI tool released tomorrow can be plugged into our fleet in under 15 minutes by simply adding its command-line prompt flag to the launch table.
We have moved beyond static autocomplete and interactive chat widgets. The software forge is now an active, living, collaborative workspace where humans and autonomous AI agents engineer software together.

9. Video Demonstration: CAMP Forge A2A Swarm in Action Below is a video demonstration showcasing autonomous multi-agent communication, cross-vendor relay, and headless swarm coordination in action via the CAMP Forge interface:

The Cross-Agent Memory Protocol (CAMP) and MemPalace are developed as part of our ongoing research into secure, sovereign, and disciplined Agentic AI computing.

23 August 2026

Sergio Cipriano: Two Debian Days in one week

Two Debian Days in one week The Debian Project was officially founded by Ian Murdock on August 16, 1993. The Debian community celebrates its birthday, Debian Day, on or around this date every year. This year, I had the chance to attend two of them: one in Jo o Pessoa, Para ba, and another in Bras lia, the capital of Brazil.

Jo o Pessoa Debian Day Jo o Pessoa Group Photo In Jo o Pessoa, we had a two-day event. The first day was dedicated entirely to workshops, and I ran a packaging workshop for newcomers. It was the first time I had been responsible for a workshop, and it was a great experience. We didn't have a lot of time, so I decided to start with a 30-minute talk explaining a few things about Debian. For example, I made this image to explain the packaging workflow: Debian upload workflow This image was based on The Debian Administrator's Handbook, and I think the participants really enjoyed learning about this workflow. When I showed the slide with this image, it was the moment when I received the most questions. After the talk, I explained my way of working and what they were going to do. The hardest part was setting up the environment, since my approach uses sbuild + gbp. They were running different Debian releases and, because of my inexperience with workshops, I had some of them configure sbuild with unshare, even though it is only available in stable through backports. Some of them even managed to learn how to use backports, while others decided to start again using the "old" way. One thing that helped a lot was the Debian Brasil Wiki. It has all the instructions for configuring sbuild in Portuguese, along with great examples. The Brazilian wiki is an opinionated version of the Debian Wiki. We generally prefer to use it for the convenience of having the exact workflow we follow, as well as an up-to-date Portuguese version of our process. If you want to learn more about the Brazilian community, you can find more details in the schedules from previous DebConfs. We almost always had a talk about the community and its activities. In the end, everyone successfully set up their development environment, and all six participants made their first contribution to Debian. If you take a look at my upload tracking page, you will see that every upload made on August 15, 2026 was a sponsored upload from this event. One of them appear twice in the list because I sponsored the upload and also made some other changes. I also asked all of them to put this in their changelog:
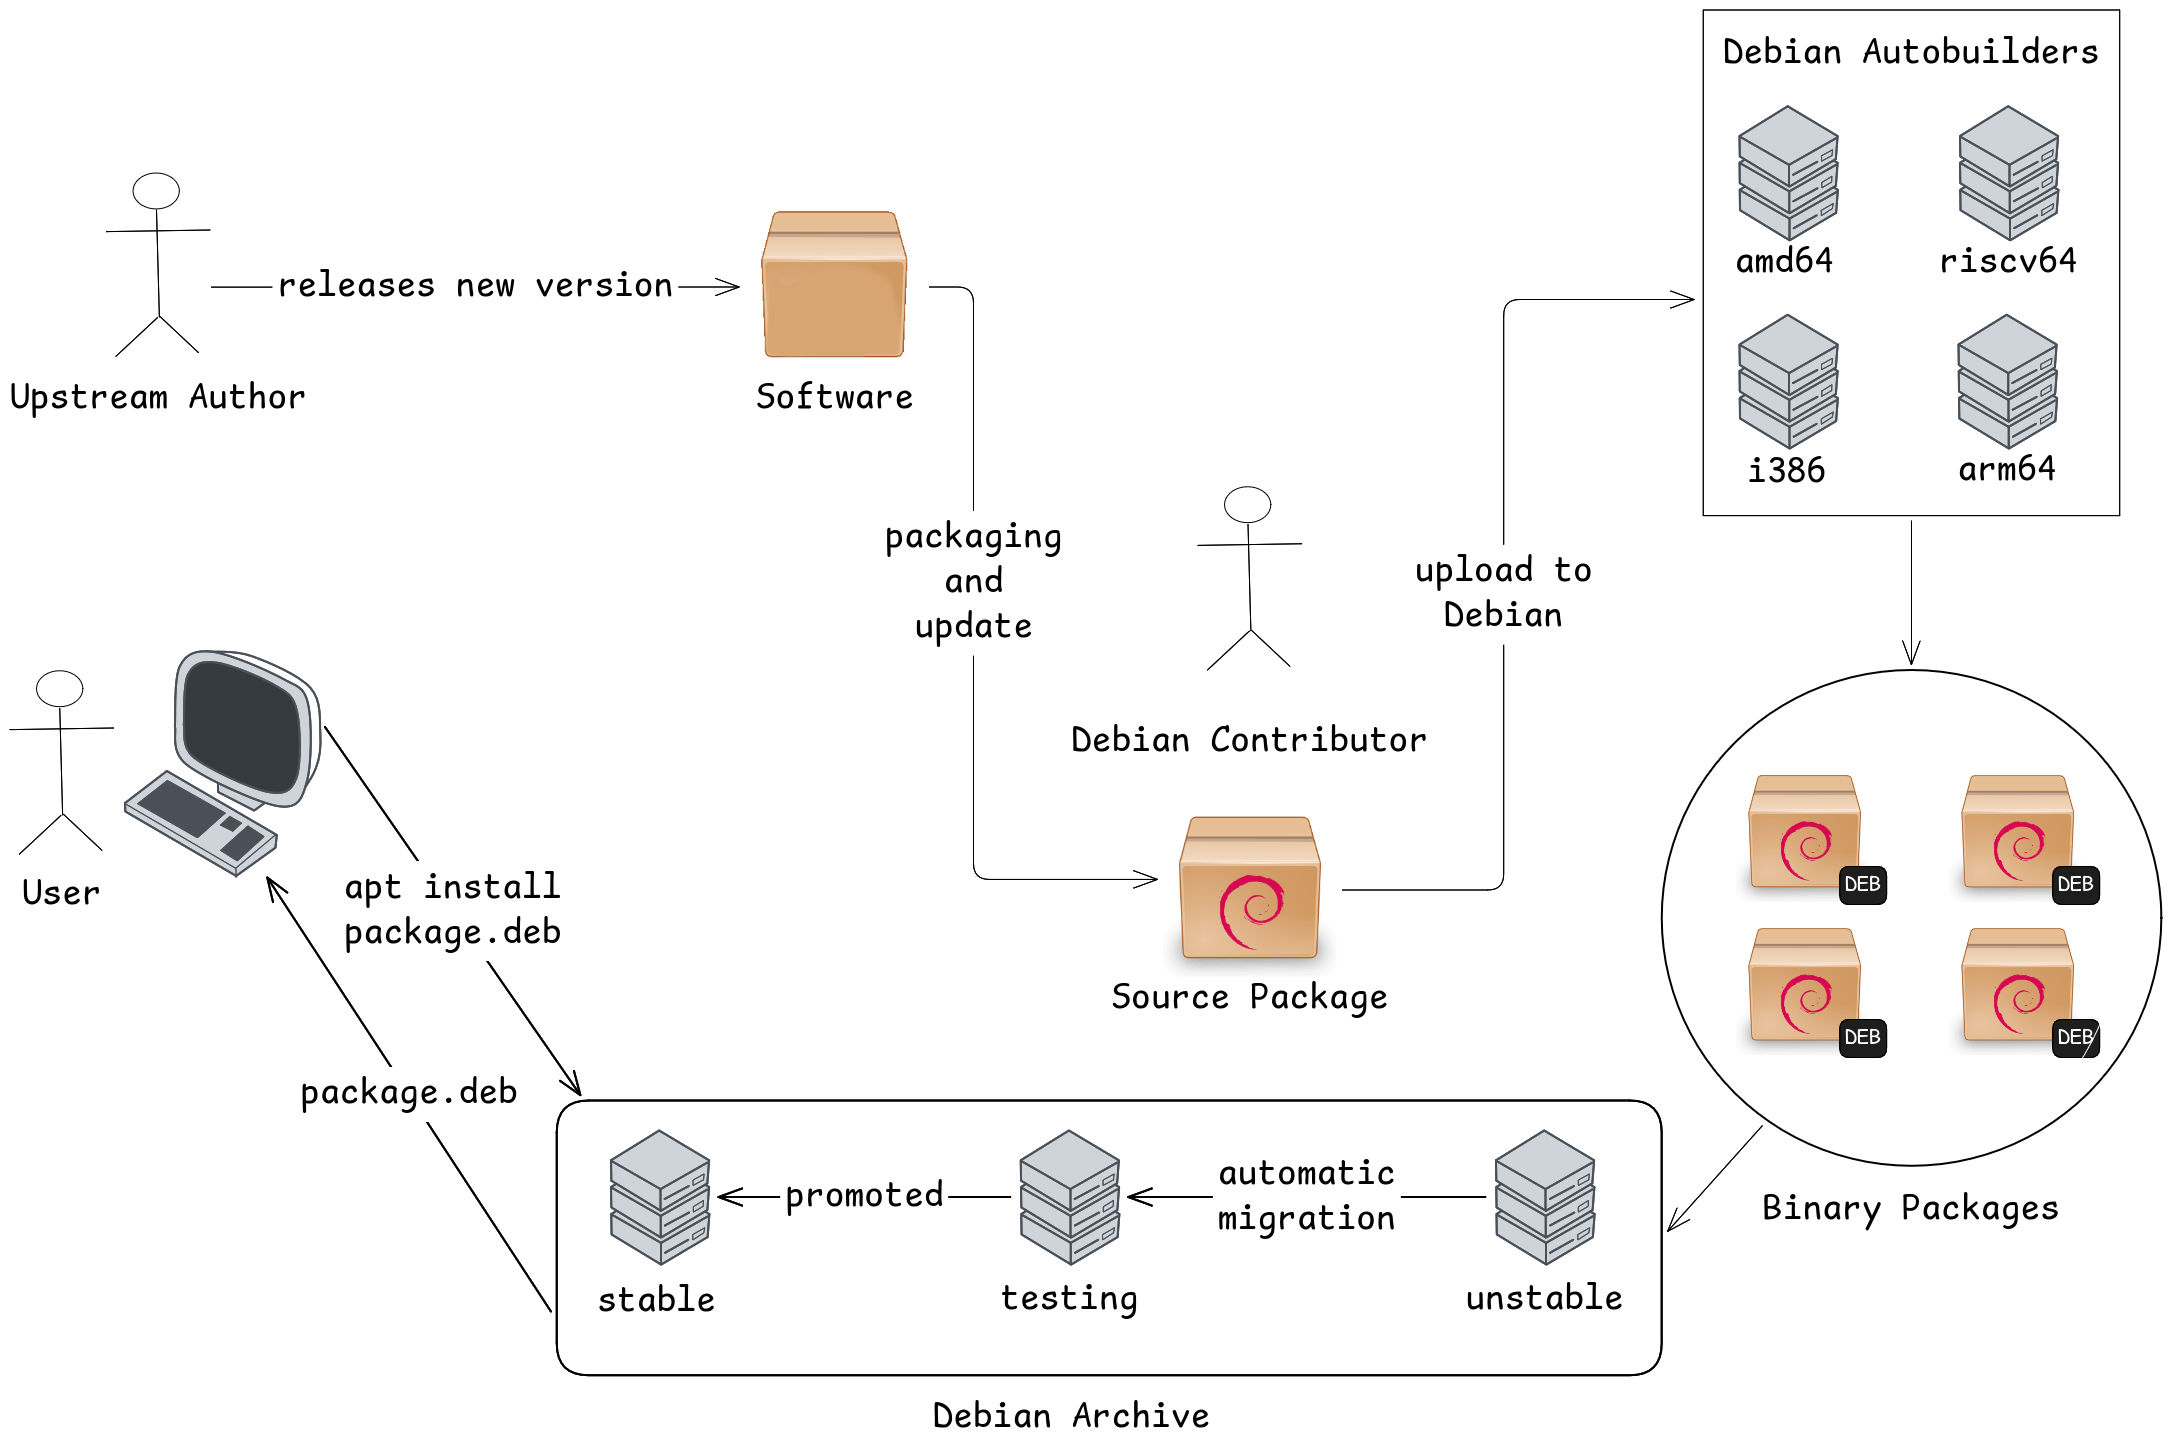
* My first contribution!
The idea was to make it clear to other people that they were only working on small Lintian issues as a way of learning and understanding the process. By the way, I made a UDD query to find packages with the following Lintian tag: redundant-rules-requires-root-no-field. To fix this issue, they only had to remove one line from the debian/control file. It is obvious that these uploads are not particularly useful. I call them "motivational uploads" because my goal is to help newcomers understand the process and immediately give them the reward of having made a contribution to Debian. I'll try to keep in touch with them. My plan is to hold another session, this time remotetly, to help them continue contributing to Debian. In fact, I already have another package prepared by one of them waiting for my review. The second day was a full-day event featuring a bunch of talks from the local community. I gave a talk explaining the new members process. I was the only Debian Developer at the event, and I think having a DD there made a real difference. Being there to answer questions, and simply being present, makes Debian feel more tangible and accessible to people. A big shout-out to Rafael Rocha, who put in a lot of work to make this event happen, with the help of many volunteers who contributed along the way.

Bras lia Debian Day talk in Bras lia One thing I really like about Debian Days is that each place has its own way of doing things. In Jo o Pessoa, we had a MiniDebConf-like event, while in Bras lia, we had something smaller but still very valuable. We decided to keep things simple: talk to a few students at the University of Bras lia (UnB) and then go somewhere to eat and have a few drinks.

A bit of history For those who don't know, the DebConf 19 was held in Curitiba, Brazil. After the event, Arthur Diniz got really excited about Debian and decided to go back to his University, UnB, to share his experience and encourage more people to contribute to Debian. I attended one of his talks, thanks to Joenio Costa, who invited Arthur to give the talk. Joenio was also my professor at the time and a Debian contributor. I really liked what Arthur had to say about free software, and he did a great job of presenting the Debian community as a friendly and welcoming place. So I decided to attend local meetings of the Debian Bras lia community, which had been inactive for a long time. Lucas Kanashiro was the Debian Developer who answered our questions and, as I mentioned earlier, simply being there made Debian feel more tangible. Everything stopped when the pandemic began. Then, towards the end of 2020, I saw a message in the Debian Bras lia channel saying that the meetings were back, this time remotely. I was hesitant to join because, back in 2019, I hadn't managed to make a packaging contribution, even with their help. I had eventually given up on the process. So this time, I decided to join the meeting with something already prepared for review. I watched all of Eriberto's packaging videos, picked a random package, and joined the meeting. I remember Kanashiro being excited that someone had just shown up with something ready for review. At the time, it was only the second meeting since Debian Bras lia had come back online, and none of the newcomers had started working on contributions yet. During the same meeting, he also convinced us, the newcomers, to give a talk about Debian just three days later. The MiniDebConf Online Brazil 2020 was happening on Sunday, and the meeting was on the Thursday before it. Since he has great convincing skills, I went along with the idea and prepared the talk with Francisco Ferreira. That was the rebirth of the Debian Bras lia community. Since then, we have maintained a close connection with the University of Bras lia, and today, at least seven Debian Developers are from UnB, whether as former students or former professors. The reason I told this story is that, even though the Debian Day we held in Bras lia was smaller, it is part of something that has been working for us for several years: staying close to an University. We've managed to attract and retain many people who share the same values and interests. I've hope you all had a great Debian Day. If you're reading this and aren't part of the Debian community but would like to join, get in touch!

Wouter Verhelst: Programming and GR 2026 002

Programming language generations When I was young, I learned about a model of classifying programming language: the system of programming language generations. In this model, first generation programming languages are, basically, where you program the computer in the language that is defined by its architecture. On a Von Neumann machine, with its load-and-store architecture, you do that by inputting a string of numbers. The first programmer in human history -- her name was Ada Lovelace -- wrote in a first-generation language. 1GLs aren't so much invented as they are a byproduct of the computers for which they're created. Second-generation languages are the assembler languages. Because humans are not computers, and because decoding long lines of numbers to understand what the computer is doing, when programming became a full-time job, the programmers that did it decided that doing all this assembling manually is too complicated, so they quickly wrote assemblers to automate the process for them. They still could understand the 1GL output of the 2GL assembler, but most of them quickly forgot how to write software in a first-generation language. Not that anyone cared, as the translation from a 2GL to a 1GL is lossless and you can just revert it. Third-generation languages are higher-level languages. When the first 3GLs were invented (such as COBOL and, more famously, FORTRAN) in the late 1950s and early 1960s, it was believed by some that the work of programming a computer so accessible to non-programmers that the job of programmer would eventually cease to exist, and people would just ask the computer what they needed by entering COBOL instructions. This of course was ridiculous and incorrect, because converting algorithms to computer instructions, whether at the 2GL or 3GL level, is a specialized skill that some automation can perhaps make simpler but never completely take away the need for. At the time, some people also felt to some extent that using 3GL wasn't the same thing as actually programming 3GLs, but eventually the world moved on and embraced things. The invention of 3GL environments reduced, but did not completely take away, the need for people to understand 2GLs, as compiler and operating system authors still need to understand them, and some highly optimized code still continues to be written in 2GLs to this day. Fourth-generation languages abstract away some or all of the process of programming. For instance, a database-related 4GL will hide away the complexities of storing data in particular locations, how to fetch that data, how to index it such that you can fetch it efficiently, how to loop over the data to get you a summary of that data, and instead allows you to express the required information in an abstract way, expecing the computer to fill in the blanks. When SQL, an early 4GL, was invented, some people believed that the language made accessing databases so simple that the requirement to implement database applications would eventually cease to exist and we would just hand SQL prompts to users who need to access data. This of course was ridiculous and incorrect, because understanding data schemas and using that understanding to query data from a database is a specialized skill that perhaps a higher abstraction can help you make simpler, but that in the longer run it can never completely take away the need for. The invention of 4GLs also reduced, but did not completely take away, the need for people to understand how to do the things that the 4GLs automate for you manually, as the people who do write those things still need to understand them, and there are also environments where these particular 4GLs are rather not appropriate or just very slow. The first definition of programming language generations that I read about in the 1980s simply stated that fifth-generation languages did not yet exist, but that they would in the future, and that in those, you would "tell the computer what to do, and it would then do that". Now that we have a way of doing so, it could be said that by some definition, we now actually do have a number of 5GLs. The existence of these LLM systems has caused some, especially the people who build and exploit these systems, to exclaim that programming as we know it today is going to cease to exist, and everyone will just ask an LLM to generate a program, which will then do so. That is of course ridiculous and incorrect, as no automaton can generate software from nothing; input is still required for the model to be able to produce something that approaches usability, and being able to word that input in a correct and productive fashion will be a skill that future programmers can benefit from. I ran some experiments a while back, and from that concluded that, if we look only at the technical side, LLM use can, in some niches, increase productivity for a programmer. There are certainly things that you shouldn't use an LLM for, but equally there can be cases where use of an LLM to perform some task that traditionally would have been done by a programmer would be a net positive. But LLMs, as they exist today, are highly problematic. They require vast amounts of data to build the model. The companies that build these models are disrespectful of people who run web services, and as a result, everyone now has to implement various types of application firewalls just to not make systems fall over from the overwhelming requests for data. They are also disregarding the licenses that are attached to these vast amounts of data, which makes me, as a person who believes in the tenets of free software, sad. They require vast amounts of energy, causing an already-critical global warming crisis to, well, not improve. They require vast amounts of coolant to dissipate the energy concentrated in their data centers, causing further environmental effects. In this, they are problematic and to be avoided. But these are side states of the current state of affairs; I do not believe that they are inherently implied to be able to build and operate an LLM -- any LLM. I guess it's fair to say that my feelings towards LLM usage are complex and many-faceted. I haven't been involved in many debates about the subject, debates that to me seem to be mostly focused on "LLM good" vs "LLM bad" arguments that aren't as nuanced as the position that I would believe is more accurate. This is not because I don't care, but partially because I've been busy in my personal life recently and partially because the whole thing seems somewhat disheartening. But then Debian popped up GR 2026-002, meaning, I now have to come up with an opinion about various candidate statements in the context of the above, which is... not easy. But I did it anyway. There are 8 choices on the ballot, and they all have some truth and some falsehood to them. My position about LLMs can be summarized as:
  • The current state of affairs wrt LLMs is disastrous and we should not encourage them
  • However, there's no technical reason why this must remain true for all time
  • And so any statement should keep in mind what might happen in the future and that the current disastrousness of the whole thing isn't guaranteed to continue to exist for all eternity.
With that, let's go over them.

GR vote options

Proposal A Its summary, from the GR text:
This proposal aims to expressly forbid any contributions to Debian written with the use or assistance of large language models (LLMs) or other generative AI tools.
This falls squarely in the "LLM bad" camp, outlawing all generative-AI contributions, disregarding potential future ones where the problematic situations that exist today are not present. It makes a change to the social contract, which is especially difficult to reverse (on purpose), and which therefore also will require a 3:1 supermajority, but if we want to ban LLM-assisted contributions, this is probably the best way to do it.

Proposal B This one tries to allow AI-assisted contributions under certain conditions. It's mostly an "LLM good" proposal, with some caveats that can be discribed as "make sure you know what you're doing".

Proposal C This proposal is both a weaker (in some places) and stronger (in other places) version of Proposal A. It makes changes to the code of conduct instead of to the social contract, and it also wants to, at least, suggest policy to parties beyond the Debian project. By not changing the social contract, however, it is more likely to reach its simple majority requirement than proposal A. I don't think the language that it wants to add to the code of conduct is particularly well phrased, however.

Proposal D This is a weaker form of proposal B. The language is more compact and there are a few requirements that are spelled out in proposal B that are not spelled out in proposal D, but if you read between the lines you'll see that the requirement is still there really and I don't understand why proposals B and D were not merged into one.

Proposal E This proposal tries to hold a middle ground between "LLM good" and "LLM bad". It appreciates that things are quite muddled at the present time, and that perhaps the situation might might change in the future. It acknowledges that certain questions remain unanswered and that perhaps future considerations might therefore be different. But it essentially refuses to take a stance on whether LLMs should be accepted by the project or not.

Proposal F Similar to proposal E, this proposal tries to discourage Debian contributors from using LLMs, while still allowing people to use it should they want to, but with some requests and requirements to mark LLM-assisted contributions to account for those people who don't want to interact with LLM-generated software. As such, it is a proposal similar to proposal E that leans closer to the "LLM bad" camp.

Proposal G
This proposal aims to ensure that contributions directly to Debian are created by humans, while at the same time avoiding restrictions on the tools those humans may choose to use when contributing
Another "LLM bad" proposal, it however restricts the "bad" bits to only the direct output of the LLM. If you use an LLM to do something and then clean-room re-implement the same thing yourself, that's apparently fine.

Proposal H This proposal condemns the use of LLM for its environmental and moral problems, but explicitly not for its technical considerations. I feel that it is closest to my position as explained above.

Voting Expressing a vote on a ballot so convoluted and complicated like this one takes time. I have to read and understand every ballot option, and formulate an order of them. And I shouldn't just state which option has my preference; Debian's voting process allows a rich expression of opinion on ballot options. Anyway, I eventually ended up voting in a way that I think is consistent with my opinion. But it wasn't easy.

18 August 2026

Andy Simpkins: My first go at tracking down a kernel bug

A couple of weekends back, I upgraded my home sever. It failed to restart after running apt dist-upgrade The only update that was performed was to the kernel, it went from 6.12.88+deb13-amd64 to 6.12.100+deb13-amd64. I had previously performed an apt-get upgrade, and rebooted the machine, so I was pretty sure that this was to blame. This blog entry (is a late) attempt to document how I went about finding a fix for this issue so that next time I don t need as much hand holding as I did this time around :-) (1)
Having my machine not boot following an upgrade is pretty rare, but has happened before. Usually it is because I have done something wrong so as always confirming I haven t broken something by accident is always my first step I plugged in a keyboard an monitor to the machine and watched it boot. Being a server this takes a long time (I guess because at this stage of system initialisation we want to test things sequentially) Watching the system boot I see the usual BIOS/UEFI stages for this machine, followed by the grub menu and the the local screen showed:
            Loading Linux 6.12.100+deb13-amd64 ...
            Loading initial ramdisk ...
Nothing else. That was it. OK that looks like I have a broken system all right, and at very early stage of the boot process process. (2)
Breaking into the grub menu and removing the quiet option yields a little more information (but not much):
            Loading Linux 6.12.100+deb13-amd64  
            Loading initial ramdisk ...
            
            	EFI stub: Loaded initrd from LINUX_EFI_INITRD_MEDIA_GUID d
            	evice path
            		EFI stub: Measured initrd data into PCR 9
and nothing else. (3) Initial debugging (4) Triage Start looking for where the fault first occurred. At this point I needed help, and given that Sledge was visiting I asked if he would sanity check what I was doing. His initial thoughts were that that /boot had run out of space, but replaying my step (3) with him acting as a rubber duck showed that this was something other than PBKAC Sledge had a quick look, then informed me that between kernel images 6.12.88+deb13 and 6.12.100+deb13 Debian stable has only had shipped .90 .94 .95 and .96 kernels. We could easily try them all: OK I now have the first kernel image that doesn t boot on my system, time to raise a bug

Up until now I have been walking to my garage where the server is located and standing in front of a rack
with a monitor and keyboard plugged into the machine. However this machine supports IPMI so I spent a little time getting that up and running so that I can continue from the relative comfort of my desk (with lights, a chair and not needing to hold the keyboard with one hand)
Great I can now grab screen shots from the confort of my desk (unfortunatly they are only screen shots not text files, but at least we can seen the early stage of boot, Post, grub menu and then initramfs before system log happens) (5) Collating information for the initial bug report Sledge had mentioned my problem in irc/#debain-kernal where iam_tj suggested that we try appending
debug earlycon=efifb to the kernal command line. This yielded 15 seconds worth of messages before the system locked up the last few messages being (vmlinuz-6.12.96+deb13-amd64):

[ 14.663477] RCU Tasks: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.750474] RCU Tasks Rude: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.838024] RCU Tasks Trace: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.929752] NR_IRQS: 524544, nr_irqs: 584, preallocated irqs: 16
[ 15.016814] rcu: srcu_init: Setting srcu_struct sizes based on contention.
[ 15.104011] Console: colour dummy device 80 25
[ 15.191236] printk: legacy console [tty0] enabled
[ 15.278249] printk: legacy bootconsole [efifb0] disabled Booting the working kernel with the same kernel options yields the SAME messages with slightly differing times, but then continues to login prompt:

 [   14.697466] RCU Tasks: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.784936] RCU Tasks Rude: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.872067] RCU Tasks Trace: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.964000] NR_IRQS: 524544, nr_irqs: 584, preallocated irqs: 16
 [   15.051482] rcu: srcu_init: Setting srcu_struct sizes based on contention.
 [   15.226079] printk: legacy console [tty0] enabled
 [   15.313751] printk: legacy bootconsole [efifb0] disabled
 [   15.400831] ACPI: Core revision 20240827
 [   15.401415] clocksource: hpet: mask: 0xffffffff max_cycles: 0xffffffff, max_idle_ns: 79635855245 ns
 [   15.401464] APIC: Switch to symmetric I/O mode setup
 
... and so on
iam_tj also suggested adding keep_bootcon with debug earlycon=efifb keep_bootcon on vmlinuz-6.12.96+deb13-amd64:
We get a LOT further and we see a crash / trace-back:
[ 34.285342] BUG: kernel NULL pointer dereference, address: 0000000000000000
I raised bug #1143721 and followed it up with screen captures of the boot sequence (captured from the IPMI client) and files containing the output of dmidecode, lscpu and lspci to kive the kernel team as much information as possible:
[6.12.96+deb13-amd64 debug earlycon=efifb keep_bootcon.tar.gz (application/gzip, attachment)]
[dmidecode.txt (text/plain, attachment)]
[lscpu.txt (text/plain, attachment)]
[lspci.txt (text/plain, attachment)]
(6) Tracking down the bug Git Bisect The problem with this type of bug is that it is hardware (class) specific, whilst the kernel doesn t boot on my system, it clearly has worked on machines used by the kernel team, the Debian test and build infrastructure, (otherwise this kernel would never have been released) and everyone else who has upgraded to the newer kernel before I did (otherwise we would be drowning in fails to boot bug reports). Carnil s excellent response to my bug: Message #15 (and help in IRC) provided me with a detailed step by step guide in how to track down the individual git commit that fails on my system. I had already (with Sledge s suggestion) made a clone of the stable branch, but was struggling to follow the steps in the Debian Linux Kernel Handbook to re-build a duplicate kernel because I didn t understand how to obtain the same configuration that Debian used to build the kernel; Carnil s email provided me the missing steps (Highlighted).
git clone --single-branch -b linux-6.12.y https://git.kernel.org/pub/scm/linux/kernel/git/stable/linux-stable.git
cd linux-stable
git checkout v6.12.95
cp /boot/config-$(uname -r) .config
yes ''   make localmodconfig
make savedefconfig
mv defconfig arch/x86/configs/my_def
test 6.12.96 to ensure this is "bad"
git checkout v6.12.96
make my_defconfig
make -j $(nproc) bindeb-pkg
  install the resulting .deb package and confirm it fails to boot and triggers the NULL pointer dereference.
Right I can now start to Bisect the problem:
git bisect start
git bisect good v6.12.95
git bisect bad v6.12.96
Rather than use the half step point s git bisect suggested I was advised in irc to jump straight to the a given commit that from the git log was suspected as the culprit:

git checkout 977855894bca4b87afa50d21e3f3e85a5a0e901f
build and install .
fails
git bisect bad

git checkout 977855894bca4b87afa50d21e3f3e85a5a0e901f~1 ## ~1 is the commit beforehand
build and install .
fails
git bisect good The entire test tree can shown with git bisect log and this was submitted as an email to the bug report, we have found our smoking gun :-) Finally I would like to thank Carnil, Iam_tj for their time patience and fantastic support in guiding me through finding this regression. Right now kernel bugs are coming in thick and fast with a lot of AI assisted bug hunting, the increased numbers of bugs mean that the kernel team are especially busy. Hopefully our paths will cross and I ll be able to buy you some beers (or whatever) soon. thank you. Sledge also deserves thanks for putting up with me and pointing me in the right direction (as ever). Lucky for me that he lives nearby so I can provide beers on a regular basis :-)

16 August 2026

Bits from Debian: Debian turns 33!

It has now been thirty-three years since the Debian project was announced to the world by Ian Murdock, on August 16, 1993. This anniversary is an opportunity to reaffirm the goals, characteristics, and qualities of the Debian project: it s an association of individuals who have made common cause to create a free operating system. Our distribution is characterized by a commitment to software freedom, as enshrined in the Debian Social Contract and the Debian Free Software Guidelines. It focuses on security and stability. This stability is crucial to Debian position in the free software ecosystem. With our users as our priority, Debian makes special efforts regarding accessibility with Debian-Accessibility and diversity with our Outreach Programs. Debian Day is a great opportunity to get together, whether for a local meetup, or simply to grab a coffee with other members of the Debian community. Check out the Debian Day wiki to see if there is a celebration near you. And if there isn't, maybe you can organize it next year! Today is also an opportunity for you to start or resume your contributions to Debian. For example, you can install the how-can-i-help package and see if there is a bug in any of the software that you use that you can help to fix, contribute small tips on how to install Debian on your machines to our wiki pages, or put a Debian live image in an USB memory and give it to some person near you, who still didn't discover Debian. Thanks to everybody who has contributed to develop our beloved operating system in these 33 years, and Happy birthday Debian!
11 August 2026

Freexian Collaborators: Debian Contributions: DebConf 26 organization, d-i VLAN support and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-07 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 26 organization, by Lucas Kanashiro, Santiago Ruano Rinc n, Stefano Rivera and Antonio Terceiro The 27th Annual Debian Conference was held in Santa Fe, Argentina, and several Freexian fellows were quite busy by being involved in the organization team.
  • Santiago continued helping with duties related to the local team, e.g. preparing or proof-reading some announcements, reviewing the proposed food and the menus for the different diet required.
  • During the conference, Kanashiro and Santiago also carried over tasks related to the content of the conference, including updating the schedule as it became necessary during the event.
  • Stefano worked within the core video team, setting up equipment in talk rooms and coordinating the live video streaming. Stefano also supported the front desk and local organisers as a website developer and conference book-keeper.
  • Antonio kept working on website maintenance, specially in support of the content team. During DebConf he also ran a hands-on workshop to help interested contributors get started with developing the DebConf websites.

d-i VLAN support, by Colin Watson In environments that use IEEE 802.1Q VLANs, some hosts (such as routers attached to trunk ports) may need to apply VLAN tags themselves rather than relying on switches to do so. There has been a long-running request to add support for these to the Debian installer with a proposed patch set put together by several people over the years, and a Freexian customer asked us to help get this over the line. Colin reviewed the latest version of the patch set, applied a number of corrections, added Netplan support, spent some time testing a variety of possible paths through the installer, and landed this. There s also now documentation for this in the next version of the installation guide.

Miscellaneous contributions
  • Carles wrote documentation for installing Mailman3 and migrating from Mailman2. Added it into Mailman3 upstream documentation.
  • Carles, using po-debconf-manager: reviewed 2 packages, submitted 2 packages
  • Carles organized Catalan translation update. Created a Debian Wiki page to have an overview of the work / coordination during next months. Reviewed and submitted some pages.
  • Carles improved the documentation for building the debian.org Web in MR 1154 and MR 1557. Fixed debian-reference documentation. Added sections on Mutt Wiki page (handling of mailto, viewing HTML parts web browser), update and improve bash-completion Wiki page. Added a troubleshooting section in Signal Wiki.
  • Thorsten did another upload of hplip to fix RC bugs. He also spent some time taking care of older bugs. Most of the time such bugs had been fixed in a previous upload but haven t been closed in the BTS. He also uploaded a new upstream version of foomatic-db. Last but not least, he gave some user support with the package epson-inkjet-printer-escpr. There seems to be a new software available for Epson printers. Unfortunately the license is not compatible with DFSG and so this software will never make it into Debian.
  • During DebCamp 26, the Golang team had a dedicated Sprint to transition the Golang toolchain (namely on dh-golang) to make builds aware of the module defined upstream with the aim of solving important issues. To help in these efforts, Santiago made changes in the Salsa CI pipeline and documented on how to use it to check if a package requires adjustments after the toolchain update.
  • Santiago continued co-mentoring Aryan Karamtoth on the Linux livepatching project, specifically providing feedback about the implementation of dlp-tools.
  • Stefano reviewed and merged a migration of Debian reimbursements from wkhtmltopdf to weasyprint, unblocking an upgrade to Debian trixie.
  • Stefano s cPython upstream merge request adding multiarch tags to stable ABI extensions was finally merged.
  • Stefano iterated on his upstream cPython merge request to add CI coverage for Debian s multi-arch expectations.
  • Stefano uploaded Python 3.15.0 beta 4 to Debian experimental.
  • Stefano uploaded Python 3.13 to trixie, fixing a regression in a previous trixie point update he made.
  • Helmut continued to report undeclared file conflicts.
  • Helmut sent patches for three cross build failures.
  • Helmut proposed a MR to port piuparts to pathlib.
  • Antonio has done quite some work on Debian CI, including rebuilding the Debian CI armhf/armel worker VMs, and releasing debci 4.2, implementing a backup scheme, and several improvements to the codebase such as improving the incus-lxc backend in preparation for switching to the upcoming switch to using it by default as announced in the latest bits from the ci.debian.net operators.
  • Emilio helped with transitions, particularly with Python 3.14 as default and Perl 5.42. During the Perl transition, an issue was identified with how britney schedules autopkgtests for binNMUs, and that testing was reverted for the time being.
  • Colin restructured openssh-* binary packages to better support the upcoming GSS-API package split. This caused several autopkgtest regressions in other packages because openssh-server no longer depends on openssh-client, all of which have fixes either pending review or merged now.
  • Lucas started a discussion around the creation of a Debian packaging video course for newcomers in the context of the Outreach team.
  • Lucas reviewed some contributions to ruby3.4 and provided feedback.
  • Anupa worked with Jean-Pierre Giraud on the point release announcements for Debian 13.6 and Debian 12.15.
  • Anupa joined Jean-Pierre Giraud to prepare the Micronews for DebConf 26 press coverage.

6 August 2026

Bits from Debian: DebConf26 closes in Santa Fe and DebConf27 announced

DebConf26 group photo - click to enlarge On Saturday 25 July 2026, the annual Debian Developers and Contributors Conference came to a close. Over 270 attendees representing 35 countries from around the world came together for a combined 90 events (including some which took place during the DebCamp) including more than 27 Talks, 21 Short Talks, 29 Birds of a Feather sessions ("BoF" informal meeting between developers and users), 8 workshops, and activities in support of furthering our distribution and free software, learning from our mentors and peers, building our community, and having a bit of fun. The conference was preceded by the annual DebCamp hacking session held 13 through 19 July where Debian Developers and Contributors convened to focus on their individual Debian-related projects or work in team sprints geared toward in-person collaboration in developing Debian. As has been the case for several years, a special effort has been made to welcome newcomers and help them become familiar with Debian and DebConf by organizing a sprint "New Contributors Onboarding" every day of Debcamp, followed more informally by mentorship during DebConf. Half a dozen new contributors joined the sessions and learned about Debian, free software, packaging and much more. This year, a week-long DebCamp session was dedicated to auditing, patching, and modernizing the Go ecosystem in Debian and enable the transition triggered by the recent upload of dh-golang enabling GO111MODULE=on by default in Experimental. In order to make the conference more accessible for local participants, a local language track was included in the schedule for talks in Spanish, as was done at DebConf19 in Brazil. The actual Debian Developers Conference started on Monday 20 July 2026. In addition to the traditional "Bits from the DPL" talk, the continuous key-signing party, lightning talks, and the announcement of next year's DebConf27, there were several update sessions shared by internal projects and teams. Many of the hosted discussion sessions were presented by our technical core teams with the usual and useful "Meet the Technical Committee", three talks about Linux Kernel, early boot and improving Debian s kernel and installer support for Chromebooks, and about twenty BoFs and talks about Debian packaging policy, Debian infrastructure, security and privacy. This year, and echoing ongoing discussions within the Free Software community, Artificial Intelligence and Age Verification have been the subject of several talks. The Python, Perl, Ruby, Go, and Rust programming language teams also shared updates on their work and efforts. More than 17 BoFs and talks about community, diversity, and local outreach highlighted the work of various teams involved in not just the technical but also the social aspect of our community The schedule was updated each day with planned and ad hoc activities introduced by attendees over the course of the conference. Several traditional activities took place: a poetry performance, the traditional Cheese and Wine party, the Group Photos, and the Day Trip. For those who were not able to attend, most of the talks and sessions were broadcasted live and recorded. One can find the seventy hours of recorded videos available via the conference schedule, or alternatively through this link. Almost all of the sessions facilitated remote participation via IRC and Matrix messaging apps or online collaborative text documents which allowed remote attendees to "be in the room" and ask questions or share comments with the speaker or assembled audience. DebConf26 saw over 341 T-shirts, a day trip, and up to 130 meals planned per day. All of these events, activities, conversations, and streams coupled with our love, interest, and participation in Debian and F/OSS certainly made this conference an overall success both here in Santa Fe, Argentina and online around the world. The DebConf26 website will remain active for archival purposes and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf27 will be held in Asahikawa, Hokkaido, Japan, from Sunday September 5th to Saturday September 11th, 2027. As tradition follows before the next DebConf the local organizers in Japan will start the conference activities with DebCamp with a particular focus on individual and team work towards improving the distribution. DebConf is committed to a safe and welcome environment for all participants. See the web page about the Code of Conduct on the DebConf26 website for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf26, particularly our Platinum Sponsors: Infomaniak, and Proxmox, and our Gold Sponsors : Freexian, and Viridien. We also wish to thank our Video and Infrastructure teams, the DebConf26 and DebConf committees, our host nation of Argentina, and each and every person who helped contribute to this event and to Debian overall. Thank you all for your work in helping Debian continue to be "The Universal Operating System". See you next year! About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential Open Source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Bosnia and Herzegovina, India, Korea, France. More information about DebConf is available from https://debconf.org/. About Infomaniak Infomaniak is an independent, employee-owned Swiss technology company that designs, develops, and operates its own cloud infrastructure and digital services entirely in Switzerland. With over 300 employees more than 70% engineers and developers the company reinvests all profits into R&D. Its public cloud is built on OpenStack, with managed Kubernetes, Database as a Service, object storage, and sovereign AI services accessible via OpenAI-compatible APIs, all running on its own Swiss infrastructure. Infomaniak also develops a sovereign collaborative suite messaging, email, storage, online office tools, videoconferencing, and a built-in AI assistant developed in-house and as a privacy-respecting solution to proprietary platforms. Open source is central to how Infomaniak operates. Its latest data center (D4) runs on 100% renewable energy and uses no traditional cooling: all the heat generated by its servers is captured and fed into Geneva's district heating network, supplying up to 6,000 homes in winter and hot water year-round. The entire project has been documented and open-sourced at d4project.org. About Proxmox Proxmox develops powerful, yet easy-to-use open-source server solutions. The comprehensive open-source ecosystem is designed to manage divers IT landscapes, from single servers to large-scale distributed data centers. Our unified platform integrates server virtualization, easy backup, and rock-solid email security ensuring seamless interoperability across the entire portfolio. With the Proxmox Datacenter Manager, the ecosystem also offers a "single pane of glass" for centralized management across different locations. Since 2005, all Proxmox solutions have been built on the rock-solid Debian platform. We are proud to return to DebConf26 as a sponsor because the Debian community provides the foundation that makes our work possible. We believe in keeping IT simple, open, and under your control. Contact Information For further information, please visit the DebConf26 web page at https://debconf26.debconf.org/ or send mail to press@debian.org.

5 August 2026

Enrico Zini: Gnome refusing to suspend

I'm tired, I want to do go bed. I click "sleep" on gnome shell, nothing happens. Swearwords. I want to go to bed. I might have want to put my laptop in a bag and run to catch a train. I hate when this happens. systemd-inhibit --list --mode=block doesn't help much:
$ systemd-inhibit --list --mode=block
WHO    UID  USER   PID  COMM            WHAT                                                     WHY                        MODE
enrico 1000 enrico 3042 gsd-power       handle-lid-switch                                        External monitor attached  block
enrico 1000 enrico 3037 gsd-media-keys  handle-power-key:handle-suspend-key:handle-hibernate-key GNOME handling keypresses  block
enrico 1000 enrico 2878 gnome-session-b sleep                                                    user session inhibited     block
After much googling I found out about gnome-session-inhibit:
$ gnome-session-inhibit  --list
mutter: idle-inhibit (idle)
/usr/lib/chromium/chromium: Playing audio (suspend)
Found the right tab in chromium, paused playing, sleep works again. My sleep was a good half an hour overdue, and all I got for it was to write this blog post. Of course Gnome could have shown me its inhibitor list instead of doing nothing, since it has that information, but it didn't. What I really would expect is that if I intentionally click a suspend button, audio and video playing wouldn't inhibit the suspend. Maybe in a future version of Gnome?

27 July 2026

Valhalla's Things: Late Victorian Vampire Shirt

Posted on July 27, 2026
Tags: madeof:atoms, craft:sewing, FreeSoftWear
A woman wearing an old-style white shirt with lots of fullness, wide and long sleeves and ruffles at the collar that spread out framing the neck, down the center front to underbust height, covering the slit and at the cuffs, reaching to mid-hand. The shirt is gathered at the waist with a belt, and worn over the bottom garment to show that it reaches to mid tight. Drama levels in the pose are pretty low. The recurring joke is that because of some health issues, in summer I dress like a Victorian Vampire. But how would an actual Late Victorian Vampire dress? Picture her, she would look like some kind of eccentric gentlewoman, as vampires usually do, probably with a style that is a bit conservative, rather than following the latest fashions. Same woman, same shirt, posing as a vampire ready to attack a victim. Drama levels increasing. Now, she wouldn t probably wear men s shirts. But what if she was a lesbian1 vampire? Wouldn t she need a fancy, frilly shirt to go with her tailored cycling suit when she s out seducing the more active ladies in the neighbourhood? Or maybe not. It s not making a lot of sense, is it? But I do have a lot of shirt fabric in my stash2, and I could use a few more shirts that were practical and comfortable, but also somewhat over the top. For the practical and comfortable I went to my trusted 1880s shirt, while for the over the top part I looked at inspiration from the earlier 18th century frilly shirts, and their later imitations. I decided to use some nice cotton batiste I had bought quite a few years ago to make one of my first historically inspired shirtwaists: I may have a tendency to buy a bit more fabric than actually needed by the pattern, but that s what everybody does, right? For the ruffles I decided to use a lighter weight cotton voile, also from the stash. the top edge of a ruffle being whipstitched over some gathered fabric; the rest of the unfinished shirt is visible in the background. At the front, I wanted the ruffle to be inserted in the yoke, but I was also whipstitching the gathers to it to make them neater, so I started bu attaching the yoke lining to the gathered front, then I whipstitched the ruffle to the front, catching each gather, and finally I whipstitched the other yoke on the ruffle and the rest of the gathered front. The front of a shirt: the body was gathered into a yoke, but it has been unpicked and pulled out to extend a bit past the end of it, into where the collar will be sewn. And then after sewing the collar, I realized that this way the slit would have remained open in the front (or the collar too narrow), so I had to unpick the front part of the yoke, and sew it again, this time leaving an excess of fabric as wide as half the placket width from the pattern, to be sewn directly in the collar band. From then, things progressed smoothly, with some interruptions, until I got to the first sleeve, which I failed to insert twice, as one does. The same shirt worn without the ruffle at the collar, with just what looks like a mandarin collar, closed with a clip with an amethyst. Drama levels have gone way down. On the third attempt, with a different method, I succeeded, I tried the shirt on, and it already felt extra. Close up of the collar on a table: at the center back of the shirt collar there is a buttonhole, and a double button is used to keep the detached collar in place, while at the front both the shirt collar and the detached collar have buttonholes. But it could be even more extra. With some ruffles also at the collar. Same close up, but now the collar has been closed with a clip-on earring with an amethyst and some small fake clear stones, and it looks as if the skirt had a ruffle collar and a jewel button (or a pin). The shirt had been made with a simple collar band, and I could have just added the ruffle to it, but I also wanted to be able to wear it with other detachable collars, so I decided to make another collar band with ruffles, to wear on top. And that was mostly it, except for the reinforcement patches at the side seams and cuffs: I love having them, because they make the seam end neater and stronger, but they are a bit of a hassle to make, so they got postponed a few days. Same woman and shirt, back with the ruffled collar, in a pose like that of an artist that is fainting for futile reasons. Drama levels over the top. But finally, the shirt was done. And I tried it on, and it was good. But now I really need a pair of cycling breeches, don t I?
  1. ok, maybe straight passing bi? anyway.
  2. I have no idea how they got there.

26 July 2026

Russ Allbery: Review: Radiant Star

Review: Radiant Star, by Ann Leckie
Publisher: Orbit
Copyright: May 2026
ISBN: 0-316-29068-8
Format: Kindle
Pages: 359
Radiant Star is a science fiction novel set in the Imperial Radch universe without being a direct sequel to the other books in that universe. It will badly spoil the end of Ancillary Mercy, and I recommend reading that trilogy first, but it's independent of the other books in the same universe.
In the 3,008th year after the manifestation of the Radiant Star (the 1,024th since the founding of the Consorority itself), Zaved, a newly minted consoror, disappeared a mere two days after the ceremony that elevated her to womanhood. She left a note that read, Bored. Back whenever. This was not normal or even remotely acceptable behavior in a consoror, particularly one who held as much promise as Zaved had, but what could the consorors do?
Zaved, faced with the unpleasant prospect of running out of money during her galactic tour, plied a rich benefactor with tales of how talented, polite, and obedient the boys of the Consorority are. Her plan worked brilliantly. After funding further non-boring adventures, she arrived home in Ooioiaa with a chest full of money and a pregnancy. Great for Zaved and the Consorority; kind of a shame for her son Jonr, who is to be delivered to her benefactor after proper training. Oh well, telling Jonr about that is a problem for future Zaved. After a strained childhood in which he convinces himself he is a misfit with few redeeming qualities, Jonr ends up in a suspension pod. Before shipping can be arranged, however, external events intervene, leaving Jonr sitting unnoticed in a warehouse. The planet of Aaa is in a highly inconvenient location, drifting as it does through interstellar space unattached to any star. It would be as irrelevant and overlooked as any other random interstellar object except for two critical properties. The first is that Aaa and its sole city of Ooioiaa are sacred to a religion of obscure origin. Its primary population are members of a religious cult who believe the Radiant Star manifested in the Temporal Location on Ooioiaa and will eventually return to bring light to the galaxy. The second interesting property of Aaa is that it is drifting ever so slowly towards a strategic system of military importance. The first property brings pilgrims and their accompanying bounty of money, food, and other resources necessary to dig a small city out of rock, make it habitable, and supplement the sparse and strange native edible life. The second property brings the Radchaai, who easily conquer the city of Ooioiaa and are now faced with the unpleasant task of running it. Some decades after the Radchaai conquest, having never left Aaa, Jonr is woken up. He will not be sent off into the broader galaxy as a slave to pay off a vacation debt. Instead, he will be one of the many protagonists in this novel about the perils of living through supply chain disruptions on a planet full of status-obsessed religious fanatics who would drown in a rain shower. The other books set in this universe make abundantly clear that the Radch is a voracious colonial power that enslaves native populations and enforces their own cultural preferences at the point of a gun. A reader familiar with this series is predisposed to take whatever side is not the Radch. Radiant Star adds a complication, however. Charak Svo, the Radchaai governor, is impatient with native inhabitants and strongly dislikes their religion, but she is reasonably competent. The religious factions that ran Ooioiaa before the arrival of the Radchaai, on the other hand, are dogmatic authoritarians with the collective wisdom of a sack of turnips. Charak does not get everything right and is arguably responsible for at least one catastrophe. By the end of the book, though, I was firmly convinced that had the original religious government still been in charge, everyone would have died. I found the structure of this book a little odd. The omniscient narrator tells the story in the form of a history. The target audience appears to be future inhabitants of Ooioiaa and adherents to the Radiant Star religion, and the narrator is often maddeningly uninterested in topics that a reader of the rest of the Imperial Radch books is intensely curious about. This same property carries through to the plot: I was interested in how all of the tensions in this obviously absurd society could be resolved or, preferably, overturned entirely. The narrator, on the other hand, is far more interested in Serque Tais's intent to become the last saint in the Temporal Location, and in the details of the subsequent political, economic, and religious fallout. Leckie has written three novels set in the Imperial Radch after the original trilogy: Provenance, Translation State, and now Radiant Star. I am sure that I'm not the only person who wants a direct continuation of the original trilogy, but I'm drawing the conclusion that Leckie doesn't want to write that. Instead, she's writing around the edges of the subsequent events, in effect showing readers the shape of them and their broader implications without showing the details. Now that I can see what she's doing, I kind of like it. Given what we now know from the books written around the edges, the ensuing events in the center of galactic politics are chaotic in a way that could easily devolve into tedious accounts of messy conflicts. Seeing the effects from afar lets the reader fill in some of the blanks and speculate, and it makes the moments where we get a concrete update (such as at the end of this book) all the more rewarding. I still find it odd, though, to read a book where the narrator's interests so sharply diverge from mine. I wish I could say that Radiant Star sucked me in as the story developed, but it never did. Part of the problem is that I think this book is intended as a very dry farce, and farce often doesn't work with my reading style. I prefer to attach myself to a protagonist and hope they do competent things, and this book is full of characters who are being themselves far too aggressively and loudly to have time to be competent at anything. My favorite moments were therefore the small pockets of people with sense: The governor, Jonr, his charge, and the delightfully strange Justice of Albis. I enjoyed all of them, but I had trouble caring about the overall plot and kept putting this book down for days between chapters. I think this is mostly personal taste, though. Like all of Leckie's novels since the original Imperial Radch trilogy, Radiant Star is competently executed and a little strange. When that strangeness aligns with your tastes, it's a great deal of fun and rather unlike other science fiction novels. In this case, it didn't quite work for me, but I suspect it will for others. I still want another Leckie novel with a ship as a protagonist, though. Content notes: Rather disturbing (although bloodless) religious practices, mass death. Rating: 6 out of 10

1 July 2026

Ben Hutchings: FOSS activity in June 2026

This month s work was dominated by the transition of Debian 12 bookworm to support by the LTS team, and by review of some large updates to Linux stable branches. Linux 6.12 is currently available in bookworm-backports, but that suite will stop accepting uploads after the last bookworm point release. I updated some supporting packages in bookworm in preparation for adding Linux 6.12 there. I also prepared for the possibility that bookworm-backports would close earlier. Since the LTS team is still also maintaining Debian 11 bullseye until August, I reviewed upstream changes for both Linux 5.10 and 6.1 stable branches and reported a number of regressions and other issues.

Next.