Search Results: "storm"

9 October 2026

Colin Watson: Free software activity in September 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH I worked with upstream to remove libselinux linkage from /usr/sbin/sshd. I applied a fix from Mark Robillard Jr to fix reload logic when using sysvinit. groff I upgraded from 1.24.1 to 1.24.2, which fixed a few command injection security vulnerabilities. parted I upgraded from 3.7 to 3.8, which fixed CVE-2026-89085 and CVE-2026-89088. Python packaging New upstream versions: setuptools 84 is now in Debian and no longer contains pkg_resources. Removing uses of that module has been an ongoing project for a while now, but I did another batch of fixes this month: A new python-coverage version triggered several build regressions due to a known problem in pytest-cov. I worked around these by setting COVERAGE_CORE=ctrace: Other build/test failures: I investigated a build failure in python-proton-vpn-local-agent and proposed a fix upstream, but I m not comfortable applying this in Debian without review. If you re familiar with this code, please take a look. I fixed some other bugs: Rust packaging rust-derivre had an invalid Section field, which I cleaned up.

24 August 2026

Vincent Bernat: An interactive tour of the spanning tree protocol

Warning This post contains interactive examples. To visualize and interact with them, you need to leave your RSS reader.

Imagine you rent office space for a three-day event. You quickly set up a few Ethernet switches and tape some cables on the floor to get everyone online. Unfortunately, Stan, your clumsiest coworker, kicks out a cable every time he gets up for coffee. You could add extra cables, but then you d get a broadcast storm: Ethernet packets that loop and multiply until nothing else gets through. That s where the spanning tree protocol (STP) comes in. STP blocks just enough of your spare cables to leave a loop-free tree. When Stan strikes again, it rebuilds the tree in a second, leaving some time for Blobby, your one-person support crew, to reconnect the cable.1 See for yourself: the diagram below runs a real STP implementation in your browser!
:demo
A1 @0,0 prio=4096
A2 @0,1
A3 @0,2
A4 @0,3
B1 @1,0 prio=8192
B2 @1,1
B3 @1,2
B4 @1,3
C1 @2,0 prio=8192
C2 @2,1
C3 @2,2
C4 @2,3
A1 -- A2 hazard=0
A2 -- A3 hazard=0
A3 -- A4 hazard=0
B1 -- B2
B2 -- B3
B3 -- B4
C1 -- C2 hazard=0
C2 -- C3 hazard=0
C3 -- C4 hazard=0
A1 -- B1 cost=10
B1 -- C1 cost=10
A4 -- B4 cost=20
B4 -- C4 cost=20
Leo @-0.3,0.7 proto=none icon= 
Mia @-0.3,1.3 proto=none icon= 
Joy @0.3,0.7  proto=none icon= 
Roy @0.3,1.3  proto=none icon= 
A2 -- Leo hazard=0 A2:edge
A2 -- Mia hazard=0 A2:edge
A2 -- Joy hazard=0 A2:edge
A2 -- Roy hazard=0 A2:edge
Max @-0.3,1.7 proto=none icon= 
Zoe @-0.3,2.3 proto=none icon= 
Ada @0.3,1.7  proto=none icon= 
Amy @0.3,2.3  proto=none icon= 
A3 -- Max hazard=0 A3:edge
A3 -- Zoe hazard=0 A3:edge
A3 -- Ada hazard=0 A3:edge
A3 -- Amy hazard=0 A3:edge
Eli @0.7,0.7 proto=none icon= 
Jay @0.7,1.3 proto=none icon= 
Kai @1.3,0.7  proto=none icon= 
Ben @1.3,1.3  proto=none icon= 
B2 -- Eli hazard=0.2 B2:edge
B2 -- Jay hazard=0.2 B2:edge
B2 -- Kai hazard=0.2 B2:edge
B2 -- Ben hazard=0.2 B2:edge
Ava @0.7,1.7 proto=none icon= 
Lea @0.7,2.3 proto=none icon= 
Ivy @1.3,1.7  proto=none icon= 
Rex @1.3,2.3  proto=none icon= 
B3 -- Ava hazard=0.2 B3:edge
B3 -- Lea hazard=0.2 B3:edge
B3 -- Ivy hazard=0.2 B3:edge
B3 -- Rex hazard=0.2 B3:edge
Ana @1.7,0.7 proto=none icon= 
Eve @1.7,1.3 proto=none icon= 
Abe @2.3,0.7  proto=none icon= 
Ian @2.3,1.3  proto=none icon= 
C2 -- Ana hazard=0 C2:edge
C2 -- Eve hazard=0 C2:edge
C2 -- Abe hazard=0 C2:edge
C2 -- Ian hazard=0 C2:edge
Ned @1.7,1.7 proto=none icon= 
Lou @1.7,2.3 proto=none icon= 
Fay @2.3,1.7  proto=none icon= 
Sue @2.3,2.3  proto=none icon= 
C3 -- Ned hazard=0 C3:edge
C3 -- Lou hazard=0 C3:edge
C3 -- Fay hazard=0 C3:edge
C3 -- Sue hazard=0 C3:edge

Note This article is also available as a video, but I advise you to keep reading here to try the interactive demonstrations.

The basics Designed in the 80s, the spanning tree protocol has evolved into a rapid flavor (RSTP) and a VLAN-aware variation (MSTP).2 Any sound-minded network engineer knows there are better alternatives, like BGP EVPN VXLAN. Yet, because any switch speaks it, the venerable spanning tree protocol still fills a niche. We focus on RSTP: it replaced the original protocol in 2004. To eliminate network loops, RSTP implements a complex state machine. Timers, link state changes, and the link-local control frames a bridge receives from its neighbors drive its transitions. These Ethernet frames are the Bridge Protocol Data Units (BPDUs). You can watch them in action below: hit the Start button.
:protocol rstp
:tx-hold 10
A1 @0,1
C11 @1,0 prio=4096 icon= 
C12 @1,2 prio=4096 icon= 
C21 @2,0 prio=4096 icon= 
C22 @2,2 prio=4096 icon= 
A2 @3,1
H1 @0,0.2 proto=none icon= 
H2 @0,1.8 proto=none icon= 
H3 @3,0.2 proto=none icon= 
H4 @3,1.8 proto=none icon= 
A1 -- C11
A1 -- C12
A2 -- C21
A2 -- C22
C11 -- C12
C11 -- C21
C11 -- C21
C11 -- C22
C12 -- C21
C12 -- C22
C21 -- C22
A1 -- H1 A1:edge
A1 -- H2 A1:edge
A2 -- H3 A2:edge
A2 -- H4 A2:edge
After some time, the topology converges to a tree: from the root C11, there is a path to each bridge3 and no loop. In the upper right corner, the interface displays a tree icon followed by the time it took to reach this state. Cut a link and see how the protocol finds an alternate path to reach C12 in less than a second. You can stop the simulation, move it forward step by step, reset it to its initial state, or slow it down with the snail mode . Don t worry about all the displayed information: I explain it later.

Note While you scroll, the current simulation stays in view so you can look at it while reading. Uncheck this box to disable this behavior: .

All examples run in your browser, powered by MSTPD an open-source user-space4 implementation of RSTP.5

Historical interlude Radia Perlman, an inductee of the Internet Hall of Fame in 2014, summarized the ancestor of STP she invented at DEC with this poem, later included in a US patent:
I think that I shall never see
A graph more lovely than a tree.
A tree whose crucial property
Is loop-free connectivity.
A tree which must be sure to span
So packets can reach every LAN.
First, the root must be selected.
By ID, it is elected.
Least cost paths from root are traced.
In the tree, these paths are placed.
A mesh is made by folks like me,
Then bridges find a spanning tree. Radia Perlman, Algorhyme.

Electing the root bridge To build a tree, RSTP first elects the bridge with the lowest bridge identifier as the root bridge. The bridge identifier combines the priority and the MAC address: 8192.6e:2b:10:a0:5f:29. In the example below, S1 and S2 have priorities of 4,096 and 8,192: S1 becomes root. S4 has a priority of 12,288, while S3 keeps the default priority of 32,768:6 S4 becomes root. S5 and S6 don t have a specific priority, so the lowest MAC address wins and S5 becomes root.
:protocol rstp
S1 @0,0 prio=4096
S2 @0,1 prio=8192
S1 -- S2
S3 @1,0
S4 @1,1 prio=12288
S3 -- S4
S5 @2,0
S6 @2,1
S5 -- S6
Initially, each bridge advertises itself as root:7
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    Root Identifier: 8192.02:00:00:01:00:01
    Bridge Identifier: 8192.02:00:00:01:00:01
Once a bridge receives a BPDU advertising a better root bridge, it propagates this new information to its neighbors.
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    Root Identifier: 4096.02:00:00:00:00:00
    Bridge Identifier: 8192.02:00:00:00:00:01

Assigning roles to ports The second step is to assign a role to each port. RSTP defines five roles, each denoted by a letter:
  • root (R),
  • designated (D),
  • alternate (A),
  • disabled (X), or
  • backup (B).8
Each non-root bridge chooses its root port, the one with the lowest-cost path to the root. Unless you override it, each bridge derives the link cost from the speed: 20,000 for 1 Gbps. In case of equality, the lowest port identifier wins. Each remaining port becomes a designated port if the BPDU it sends is better than the BPDU it receives. Otherwise, it becomes an alternate port. Later, if the root port goes down, the best alternate port becomes the new root port. The tiebreakers for the best BPDU are:
  1. the lowest root bridge identifier,
  2. the lowest accumulated cost to the root,
  3. the lowest bridge identifier, and
  4. the lowest port identifier.
:protocol rstp
S1 @1,0  prio=4096 icon= 
S2 @0,1
S3 @2,1
S1 -- S2
S1 -- S3
S1 -- S3
S2 -- S3
In the example above, after convergence, S1 is the root bridge because it has a priority of 4,096, while the other bridges have a priority of 32,768. All its ports are designated ports because the accumulated cost to the root is 0. S2 s port facing S1 becomes a root port because it has the lowest accumulated cost to the root 20,000 vs 40,000. S3 has two ports facing S1, and the one with the lowest port identifier becomes the root port 0x8000 vs 0x8001. The other candidate is an alternate port because the remote port on the link sends a better BPDU, with an accumulated cost of 0. On the segment between S2 and S3, S2 s port wins: while both bridges have the same accumulated cost to the root (20,000), S2 s bridge identifier is smaller 32768.02:00:00:00:00:01 vs 32768.02:00:00:00:00:02.
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 20000
    Bridge Identifier: 32768.02:00:00:00:00:01
    Port identifier: 0x8002
If you cut the active link between S1 and S3, S3 promotes the best alternate port to root port. If you also disable the second link, S3 chooses the remaining alternate port as a root port. But if you disable the link between S1 and S2, S2 needs a bit more work to elect a new root port because it does not have an alternate port. Unless a specific event happens, designated ports send BPDUs every 2 seconds.9 If a bridge does not receive BPDUs from its neighbor for 3 consecutive hello periods, it considers the neighbor dead and removes the port information.

Port state transition Each port can have one of three states. The diagram displays a background color for each state:
  • discarding (red),
  • learning (yellow), or
  • forwarding (green).
A root port transitions automatically to the forwarding state. An alternate port stays in the discarding state. A designated port has two options to transition from the discarding state to the forwarding state:
  • If the port is an edge port, either through configuration or because the remote device does not speak any flavor of STP, the bridge assumes the device won t participate in the protocol and cannot create a loop. In this case, the designated port immediately transitions to the forwarding state.
  • Otherwise, it sends a proposal to its downstream neighbor. If the remote bridge agrees that the received BPDU is better than any other BPDU stored for other ports, it elects the receiving port as its root port and starts the synchronization process: it transitions all non-edge non-synced designated ports to the discarding state to avoid a loop. Then, it sends back an agreement. Upon receiving the agreement, the peer designated port transitions to the forwarding state.10
:protocol rstp
S1 @1,0 prio=4096 icon= 
S2 @1,1
S3 @0,2
S4 @2,2
S5 @0,3 prio=8192 icon= 
S6 @2,3
H1 @0,1.2   proto=none icon= 
H2 @2,1.2   proto=none icon= 
H3 @2.5,1.3 proto=none icon= 
H4 @2.5,2.3 proto=none icon= 
S1 -- S2
S2 -- S3
S2 -- S4
S3 -- S5
S4 -- S6
S4 -- S3
S5 -- S6
S3 -- H1 S3:edge
S4 -- H2 S4:edge
S4 -- H3 S4:edge
S6 -- H4 S6:edge
In the topology above, H1, H2, H3, and H4 are end devices not participating in the protocol. We configure the ports they connect to as edge ports, so these ports immediately move to the forwarding state. Use the step button to move the simulation forward. The clock moves to 1 second. Step again and S1 and S2 send a proposal to each other. Here is the proposal from S2:
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x4e, Agreement, Port Role: Designated, Proposal
        0... .... = Topology Change Acknowledgment: No
        .1.. .... = Agreement: Yes
        ..0. .... = Forwarding: No
        ...0 .... = Learning: No
        .... 11.. = Port Role: Designated (3)
        .... ..1. = Proposal: Yes
        .... ...0 = Topology Change: No
    Root Identifier: 32768.02:00:00:00:00:01
    Root Path Cost: 0
    Bridge Identifier: 32768.02:00:00:00:00:01
    Port identifier: 0x8001
S1 ignores it: its own root identifier is lower. When S2 receives a similar proposal from S1, it accepts S1 as its root bridge. It also elects the port to S1 as the root port and starts the synchronization process. The two designated ports are already discarding, so no change here. Step again and S2 sends two BPDUs to S1. In one of them, the agreement bit is 1 and the proposal bit is 0. It also shows that S2 accepted S1 as the root bridge and its root port is now in the forwarding state. When receiving this BPDU, S1 transitions its own designated port to the forwarding state. From this point, the link between S1 and S2 forwards user traffic.
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x79, Agreement, Forwarding, Learning, Port Role: Root, Topology Change
        0... .... = Topology Change Acknowledgment: No
        .1.. .... = Agreement: Yes
        ..1. .... = Forwarding: Yes
        ...1 .... = Learning: Yes
        .... 10.. = Port Role: Root (2)
        .... ..0. = Proposal: No
        .... ...1 = Topology Change: Yes
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 20000
    Bridge Identifier: 32768.02:00:00:00:00:01
    Port identifier: 0x8001
Let s look at what happened to S5. Reset the simulation and step twice. S5 exchanges BPDUs with both S3 and S6. Since S5 has a lower root identifier than S3 and S6, it stays the root bridge, while S3 and S6 accept the proposal and elect their root ports. S3 and S6 start the synchronization process. S6 s port to H4 keeps forwarding because it is an edge port. Move one step. Both S3 and S6 send an agreement back to S5, which transitions both designated ports to the forwarding state. Yet, the link between S5 and S3 keeps discarding user traffic! If you look carefully, S3 s port toward S5 is now a designated port, not a root port. During the same step, S3 also receives a better BPDU from S2 with S1 as the root bridge. It elects its port to S2 as the root port and downgrades the port to S5 to a designated port, which stays in the discarding state. On the next step, things get a bit tricky. S3 sends a proposal to S5:11
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x4f, Agreement, Port Role: Designated, Proposal, Topology Change
        0... .... = Topology Change Acknowledgment: No
        .1.. .... = Agreement: Yes
        ..0. .... = Forwarding: No
        ...0 .... = Learning: No
        .... 11.. = Port Role: Designated (3)
        .... ..1. = Proposal: Yes
        .... ...1 = Topology Change: Yes
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 40000
    Bridge Identifier: 32768.02:00:00:00:00:02
    Port identifier: 0x8002
S5 elects S1 as its root bridge and the port toward S3 as its root port. It starts its synchronization process, but the designated port to S6 does not move into the discarding state. Why? That port stays a designated port and its neighbor S6 has already sent an agreement on the link, so the port keeps its synced status. Now, let s step back to look at what happens to S6. At this point, S6 believes S5 is the root bridge. Step once and S4 sends a new proposal to S6. S6 accepts the proposal, elects S1 as the root bridge and the port to S4 as its root port. The role of the port facing S5 changes: from a root port, it becomes a designated port. Because its peer keeps advertising an inferior BPDU on the link, this port becomes disputed and moves to the discarding state. The root port transitions to the forwarding state and the link starts forwarding immediately because S4 s designated port is already in the forwarding state. If we step one more time, S5 and S6 exchange two BPDUs. The one from S5 is better because of its lower bridge identifier. S5 s port stays a designated port, while S6 downgrades its own port to an alternate port. Let s rewind to the start one last time: cut the link between S1 and S2, run the simulation until the topology is stable, stop the simulation, and restore the link between S1 and S2. During the first step, S1 and S2 exchange proposals. S2 elects S1 as the root bridge instead of S5 and the port to S1 as the root port. It downgrades the previous root port to a designated port and moves it into the discarding state. The other designated port stays synced and keeps its forwarding state. At the next step, S2 sends an agreement to S1 and the link between them starts forwarding user traffic. It also sends a proposal to S3, but not to S4. Instead, it sends a regular BPDU to S4. S4 still elects S1 as its root bridge and the port to S2 as its root port. It demotes its previous root port, the one to S3, to a designated port, which transitions to the discarding state because of the root port change. The other alternate port, to S6, also becomes a designated port and stays in the discarding state. The new root port moves to the forwarding state. On the next step, S4 s port to S3 settles as an alternate port after receiving a better BPDU from S3. RSTP is a giant state machine split into smaller ones: bridge detection, port information, port protocol migration, port role selection, port role transitions, port receive, port state transitions, port timers, port transmit, and topology change. Some of them are per bridge, some per port. Each bridge runs an instance. Time, operational port state changes, and the BPDUs it receives from other instances drive the transitions. Being event-driven makes RSTP more efficient but also more difficult to understand.
Western Australian Government Railways class Msa Garratt articulated steam locomotive: elevation and plan drawing
Placeholder for the Port Information state machine extracted from IEEE 802.1Q-2005, page 182. Pending IEEE authorization for reproduction, this is the blueprint for the Western Australian Government Railways class Msa Garratt articulated steam locomotive.

Topology change notification A bridge populates a MAC address table: it associates each source MAC address with the port that last received it. When forwarding an Ethernet frame, it looks up this table to choose the right port.12 When a link fails, a connected fridge reachable through one port may become reachable through another one. The affected bridges should flush the MAC addresses they learned, because these entries may now be wrong. For this purpose, RSTP implements topology change notifications using a flooding mechanism. When a non-edge port transitions to the forwarding state, a bridge generates BPDUs with the topology change (TC) bit set. It sends them to all the non-edge designated ports and to the root port. It also flushes the MAC address table on these ports. When a bridge receives such a BPDU, it propagates the notification to all non-edge designated ports and the root port, except the one the notification came from. It also flushes the MAC address table on these ports. In the examples, the BPDUs with the TC bit set to 1 have a red circle.
:protocol rstp
S1 @1,0 prio=4096 icon= 
S2 @0,1
S3 @1,1
S4 @2,1
S5 @1,2
LPT @0.1,2 proto=none icon= 
S1 -- S2
S1 -- S3
S1 -- S4
S2 -- S3
S2 -- S5
S4 -- S5
S5 -- LPT S5:edge
Start the simulation and wait a few seconds for the topology to settle. Stop the simulation and disable the link between S2 and S5. S5 elects the port facing S4 as the root port, which transitions immediately to the forwarding state. Step once and S5 emits a BPDU with the TC bit set to 1:
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x79, Agreement, Forwarding, Learning, Port Role: Root, Topology Change
        0... .... = Topology Change Acknowledgment: No
        .1.. .... = Agreement: Yes
        ..1. .... = Forwarding: Yes
        ...1 .... = Learning: Yes
        .... 10.. = Port Role: Root (2)
        .... ..0. = Proposal: No
        .... ...1 = Topology Change: Yes
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 40000
    Bridge Identifier: 32768.02:00:00:00:00:04
    Port identifier: 0x8002
S4 receives this BPDU. It flushes the MAC address table on the port facing S1: while LPT was previously reachable through this port, it is now reachable through S5. Step once. S4 sends S1 a BPDU with the TC bit set to 1. When S1 receives this BPDU, it flushes the MAC address table on the ports facing S2 and S3. Step once and S1 sends a notification to S2 and S3. Step once again and S2 sends a notification to S3, while S3 does nothing because the port toward S2 is an alternate port. S3 does not flush any MAC address table: LPT is still reachable through its port to S1. If you step a bit more, you will see that some of the periodic BPDUs keep the TC bit set to 1. Each port runs a timer equal to the hello timer plus one second.13 The timer starts when the port emits a notification. Until it expires, the port sets the TC bit to 1 in every BPDU it sends. You can also see some periodic BPDUs without the TC bit: they originate from a port that only received a notification and therefore did not arm its timer.

Security RSTP is weak against configuration errors and malicious actors. A bridge not talking RSTP can create a loop. An attacker can insert themselves into the topology to disrupt the service, spy on the traffic, or alter it. To mitigate such problems, you need to identify the edge ports. An edge port connects to an end device, like a PC or a printer. Such devices do not generate BPDUs and cannot create a loop. RSTP defines two related flags:
  • When true, AdminEdge initializes a port as an edge port. It defaults to false.
  • When true, AutoEdge lets a port become an edge port when it does not receive BPDUs for 3 seconds. It defaults to true.
If an edge port receives a BPDU, regardless of the values of these two flags, it reverts to a non-edge port.
R0 @1.5,1.5 prio=8192
# AutoEdge=true, AdminEdge=false, bridge
S1 @3,1.58
R0 -- S1
# AutoEdge=true, AdminEdge=false, end device
H1 @2.84,2.18 icon=  proto=none
R0 -- H1
# AutoEdge=true, AdminEdge=true, bridge
S2 @2.18,2.84
R0 -- S2 R0:edge
# AutoEdge=true, AdminEdge=true, end device
H2 @1.58,3 icon=  proto=none
R0 -- H2 R0:edge
# AutoEdge=false, AdminEdge=true, bridge
S3 @0.68,2.76
R0 -- S3 R0:edge R0:no-auto-edge
# AutoEdge=false, AdminEdge=true, end device
H3 @0.24,2.32 icon=  proto=none
R0 -- H3 R0:edge R0:no-auto-edge
# AutoEdge=false, AdminEdge=false, bridge
S4 @0,1.42
R0 -- S4 R0:no-auto-edge
# AutoEdge=false, AdminEdge=false, end device
H4 @0.16,0.82 icon=  proto=none
R0 -- H4 R0:no-auto-edge
# Network port, bridge
S5 @0.82,0.16
R0 -- S5 R0:network S5:network
# Network port, end device
H5 @1.42,0 icon=  proto=none
R0 -- H5 R0:network
# AdminEdge=true, bpdu-guard=true, bridge
S6 @2.32,0.24
R0 -- S6 R0:bpdu-guard R0:edge
# AdminEdge=true, bpdu-guard=true, end device
H6 @2.76,0.68 icon=  proto=none
R0 -- H6 R0:bpdu-guard R0:edge
In the topology above, S1, S2, S3, S4, S5, and S6 act as bridges, while H1, H2, H3, H4, H5, and H6 act as end devices:
  • S1 and H1 are on a port without a specific configuration: AutoEdge is true, AdminEdge is false,
  • S2 and H2 are on a port where AdminEdge is true,
  • S3 and H3 are on a port where AutoEdge is false and AdminEdge is true,
  • S4 and H4 are on a port where AutoEdge is false.
If you start the simulation and wait about 20 seconds, links to S1, S2, S3, S4, H1, H2, H3, and H4 eventually forward user traffic: none of the flags matter. But what about the two remaining pairs? S5 and H5 connect to a network port. Such a port enables a non-standard feature: bridge assurance. The port transmits BPDUs regardless of its role. If it does not receive BPDUs for 3 consecutive hello periods, it transitions to the discarding state. On the link between R0 and S5, you can see BPDUs traveling in both directions, unlike the other links, where only designated ports send BPDUs. S6 and H6 connect to a port where AdminEdge is true and BPDU guard is enabled. This is another non-standard feature that shuts down a port if it receives a BPDU. In summary, if you expect a port to be an edge port, you should set AdminEdge to true and enable BPDU guard. Otherwise, declare it as a network port.

Why RSTP today? A compelling use case for RSTP today is an out-of-band network for a datacenter, since you can tolerate an outage of a few seconds. The configuration is minimal and you can use cheap switches, like a Cisco 2960X.14 You need two switches acting as root bridges, and you build several loops to connect OOB switches in each cabinet. This simple design survives one failure on each loop.15
:protocol rstp
:tx-hold 10
# Root bridges
R1 @0,1 prio=0
R2 @0,2 prio=4096
R1 -- R2 cost=200 R1:network R2:network
# First loop
C1  @1,0 icon= 
C4  @2,0 icon= 
C7  @3,0 icon= 
C10 @4,0 icon= 
C12 @5,0 icon= 
C13 @5,3 icon= 
C15 @4,3 icon= 
C18 @3,3 icon= 
C21 @2,3 icon= 
C24 @1,3 icon= 
R1  -- C1  R1:network C1:network
C1  -- C4  C1:network C4:network
C4  -- C7  C4:network C7:network
C7  -- C10 C7:network C10:network
C10 -- C12 C10:network C12:network
C12 -- C13 C12:network C13:network
C13 -- C15 C13:network C15:network
C15 -- C18 C15:network C18:network
C18 -- C21 C18:network C21:network
C21 -- C24 C21:network C24:network
C24 -- R2  C24:network R2:network
# Second loop
C2  @1,0.5 icon= 
C5  @2,0.5 icon= 
C8  @3,0.5 icon= 
C11 @4,0.5 icon= 
C14 @4,2.5 icon= 
C17 @3,2.5 icon= 
C20 @2,2.5 icon= 
C23 @1,2.5 icon= 
R1  -- C2  R1:network C2:network
C2  -- C5  C2:network C5:network
C5  -- C8  C5:network C8:network
C8  -- C11 C8:network C11:network
C11 -- C14 C11:network C14:network
C14 -- C17 C14:network C17:network
C17 -- C20 C17:network C20:network
C20 -- C23 C20:network C23:network
C23 -- R2  C23:network R2:network
# Third loop
C3  @1,1 icon= 
C6  @2,1 icon= 
C9  @3,1 icon= 
C16 @3,2 icon= 
C19 @2,2 icon= 
C22 @1,2 icon= 
R1  -- C3  R1:network C3:network
C3  -- C6  C3:network C6:network
C6  -- C9  C6:network C9:network
C9  -- C16 C9:network C16:network
C16 -- C19 C16:network C19:network
C19 -- C22 C19:network C22:network
C22 -- R2  C22:network R2:network
This topology converges in about 6 seconds. Each loop should stay small (around 16 bridges) to reduce the probability of a double failure and to avoid sharing too much bandwidth. The design can evolve a bit without adding too much complexity: one VLAN per loop or one bridge domain per loop.

How large can a network be? The maximum age, whose default value is 20, governs the maximum distance of a bridge from the root. The topology below is too big for BPDUs from R1 to reach beyond S20.16
:protocol rstp
:tx-hold 10
:max-age 20
R1 @0,0 prio=4096 icon= 
R2 @0,5 prio=4096 icon= 
S1  @1,0
S2  @2,0
S3  @3,0
S4  @4,0
S5  @5,0
S6  @6,0
S7  @6,1
S8  @5,1
S9  @4,1
S10 @3,1
S11 @2,1
S12 @1,1
S13 @1,2
S14 @2,2
S15 @3,2
S16 @4,2
S17 @5,2
S18 @6,2
S19 @6,3
S20 @5,3
S21 @4,3
S22 @3,3
S23 @2,3
S24 @1,3
S25 @1,4
S26 @2,4
S27 @3,4
S28 @4,4
S29 @5,4
S30 @6,4
S31 @6,5
S32 @5,5
S33 @4,5
S34 @3,5
S35 @2,5
S36 @1,5
R1  -- S1
S1  -- S2
S2  -- S3
S3  -- S4
S4  -- S5
S5  -- S6
S6  -- S7
S7  -- S8
S8  -- S9
S9  -- S10
S10 -- S11
S11 -- S12
S12 -- S13
S13 -- S14
S14 -- S15
S15 -- S16
S16 -- S17
S17 -- S18
S18 -- S19
S19 -- S20
S20 -- S21
S21 -- S22
S22 -- S23
S23 -- S24
S24 -- S25
S25 -- S26
S26 -- S27
S27 -- S28
S28 -- S29
S29 -- S30
S30 -- S31
S31 -- S32
S32 -- S33
S33 -- S34
S34 -- S35
S35 -- S36
S36 -- R2
R1  -- R2 cost=200 down
Once the topology settles, part of the network considers R1 the root, while the other votes for R2. At the boundary, S20 tries to start a synchronization with S21 to move its designated port to the forwarding state. The BPDU looks like this:
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x4e, Agreement, Port Role: Designated, Proposal
    Root Identifier: 4096.02:00:00:00:00:00
    Root Path Cost: 400000
    Bridge Identifier: 32768.02:00:00:00:00:15
    Port identifier: 0x8002
    Message Age: 20
    Max Age: 20
S21 rejects it because the message age equals the maximum age. On the other hand, the BPDU S21 sends to S20 looks like this:
Spanning Tree Protocol
    Protocol Identifier: Spanning Tree Protocol (0x0000)
    Protocol Version Identifier: Rapid Spanning Tree (2)
    BPDU Type: Rapid/Multiple Spanning Tree (0x02)
    BPDU flags: 0x7c, Agreement, Forwarding, Learning, Port Role: Designated
    Root Identifier: 4096.02:00:00:00:00:01
    Root Path Cost: 320000
    Bridge Identifier: 32768.02:00:00:00:00:16
    Port identifier: 0x8001
    Message Age: 16
    Max Age: 20
This is not enough to change S20 s root port because S20 has a lower root identifier 4096.02:00:00:00:00:00 vs 4096.02:00:00:00:00:01. Fixing the link between R1 and R2 resolves the issue. The maximum message age any packet carries is now 18, below the configured maximum age. But it only works until another link breaks. A plausible fix is to increase the maximum age to 40.17

How fast is RSTP? RSTP usually converges in a couple of seconds at startup. It often repairs a tree in less than a second. Even the 38-bridge topology takes less than 10 seconds to converge.18 Some topologies can take a bit more time to recover when the root bridge becomes unavailable.19
:protocol rstp
R0 @1,0 prio=0
S1 @1,1 prio=4096
S2 @0,2 prio=8192
S3 @2,2
R0 -- S1
S1 -- S2
S2 -- S3
S3 -- S1
In the topology above, start the simulation, wait for convergence, hit stop, and cut the link between R0 and S1. The topology is already optimal, but RSTP has a hard time converging again. First, S1 loses its root port. It has no more information about R0 and elects itself as the root bridge. It keeps its ports to S2 and S3 as designated ports in the forwarding state. Step once and it sends a BPDU to both S2 and S3 to let them know about the root change. When receiving it, S2 accepts S1 as its root because it does not have a better root on another port. It elects the port to S1 as its root port. The other port stays a designated port. Both ports keep forwarding. When receiving the BPDU from S1, S3 behaves differently: it knows R0 as a better root than S1 through its alternate port to S2. It promotes this port to a root port and demotes the port facing S1 to a designated port, which requires a new agreement. Step once and S3 sends a proposal to S1 with R0 as the root bridge. S1 elects R0 as the root bridge and promotes its port to S3 as a root port. During the same step, S3 also receives a BPDU from S2 stating that S1 is the root bridge. Therefore, S3 has no port left with R0 as the root bridge: it elects S1 as the root bridge and its port to S2 as the root port. Step once and its next BPDU to S1 includes this information: S1 elects itself again as the root bridge. But during the same wave, S1 sends a proposal to S2 with R0 as the root bridge. While S1 and S3 agree that S1 is the root bridge, S2 now believes this is R0! In turn, S2 again convinces S3 that R0 is the root bridge, S3 convinces S1, S1 convinces S2, and S2 convinces S3. This could go on forever, but it does not. The BPDUs saying R0 is root eventually age out when the message age goes past the maximum age. In the example above, at the eleventh second, S2 sends a BPDU to S3 with R0 as root, but S3 drops it because its message age reached the maximum. With some luck, the topology can also converge faster if a port stops transmitting new BPDUs after tripping the transmit hold count, whose default value is 6 per second.

About MSTP MSTP is the VLAN-aware version of RSTP: it runs several instances of RSTP and lets the administrator map each VLAN to a specific instance. For example, you can map VLANs 100 to 200 to a first instance, and 300 to 400 to a second instance. The remaining VLANs map to a special instance named the Internal Spanning Tree (IST). MSTP adds its own complexity, but the gist is that you have several logical topologies acting independently. If you want to dig deeper, have a look at MSTP Tutorial Part I: Inside a Region.

About the interactive examples The interactive examples run MSTPD directly in your browser, compiled to WebAssembly with emscripten. A C API replaces the code talking to the Linux kernel: it manages bridges and ports, exports state as JSON, and drives time deterministically. A JavaScript wrapper makes it more user-friendly:
import   loadMSTPD   from "./dist/mstpd.mjs";
const mstp = await loadMSTPD();
// Create 3 bridges
const a = mstp.createBridge("A",   priority: 4096  );
const b = mstp.createBridge("B",   priority: 8192  );
const c = mstp.createBridge("C");
// Each bridge has two ports
const a1 = a.addPort("a-b",   portno: 1  );
const a2 = a.addPort("a-c",   portno: 2  );
const b1 = b.addPort("b-a",   portno: 1  );
const b2 = b.addPort("b-c",   portno: 2  );
const c1 = c.addPort("c-a",   portno: 1  );
const c2 = c.addPort("c-b",   portno: 2  );
// Build a triangle topology
mstp.link(a1, b1);
mstp.link(a2, c1);
mstp.link(b2, c2);
// Enable all bridges and ports
for (const br of [a, b, c]) br.enable();
for (const p of [a1, a2, b1, b2, c1, c2]) p.enable();
// Execute 40 seconds' worth of wall clock and display the topology
mstp.step(40);
console.log("Topology:", mstp.topology());
Several dozen unit tests explore the features of MSTPD and check that they work correctly in this environment:
$ node --test *.test.mjs
  two bridges: lower priority becomes root (41.657342ms)
  triangle loop: exactly one port blocks and all agree on the root (5.832ms)
  breaking the active link reconverges and restoring recovers (18.730753ms)
[ ]
  tests 40
  pass 40
  fail 0
[ ]
  duration_ms 396.190897
Additional JavaScript code looks for specific <pre> blocks containing a topology definition and turns them into interactive widgets. You can inspect and modify the definition by hitting the edit button. There is also a cool trick to tell whether the topology has converged. After each step, we save a snapshot of the simulation memory, play 50 seconds worth of simulation to check if the topology is stable, and travel back in time by restoring that snapshot. The complete code lives on GitHub. I am happy with the result. It can be difficult to follow everything happening during a single step, but stepping forward and backward helps. I plan to use the same approach in future blog posts about networking features.

Note Michael Lynch reviewed a first draft of this article. He authored Refactoring English, a book to sharpen your writing for blog posts, documentation, commit messages, and tutorials. Any errors are still mine!


  1. The sprites for Stan and Blobby come from Craftpix, the coffee cups from Yanin.
  2. STP was introduced in IEEE 802.1D-1990. It is still present in IEEE 802.1D-1998 but was withdrawn in IEEE 802.1D-2004 in favor of RSTP, introduced in IEEE 802.1w-2001. MSTP was introduced in IEEE 802.1s-2002 and merged into IEEE 802.1Q-2003. Both of them are part of IEEE 802.1Q-2022 along with SPB a protocol I had never heard of until writing this article.
  3. From here, I use bridge instead of the more common word switch.
  4. The Linux kernel only runs STP. It delegates the other protocols to user space.
  5. MSTPD implements the state machine from IEEE 802.1Q-2005, but on Linux it runs RSTP only. Linux 5.18 added support for forwarding multiple spanning tree, but MSTPD does not use it yet. See PR #150 for progress on this front.
  6. The priority is a multiple of 4,096: with MSTP, the lower 12 bits of the bridge priority encode the MST instance identifier, leaving only the upper 4 bits for the configured priority.
  7. To inspect the BPDUs crossing a link, select it, click the Download packets button, and open the file with Wireshark.
  8. A backup port only exists if the bridge has several ports on the same collision domain. This should not happen in a switched network.
  9. This is the value of the hello timer. It used to be configurable, but IEEE 802.1Q-2005 pins it to 2. MSTPD does not allow another value.
  10. If the peer port does not receive an agreement after the hello timer elapses or the maximum age if the port has just come up it falls back to the timer-based method for compatibility with STP: it transitions to the learning state, waits again for the hello timer to expire, and transitions to the forwarding state.
  11. As in many proposals, S3 also sets the agreement bit to 1. The proposal bit says I am the designated port on this link and I want to transition to the forwarding state. The agreement bit says I am already in sync with the rest of my bridge on this root information. Both can be true.
  12. If it finds no entry, the bridge duplicates the Ethernet frame on all ports, except the incoming one. The same happens if the destination MAC address is the broadcast one (ff:ff:ff:ff:ff:ff). This behavior bootstraps the learning process.
  13. This timer makes RSTP resistant to packet loss.
  14. You can get them for less than US$100 through a broker. All the ports run PVST+ by default and automatically fall back to plain RSTP.
  15. An alternative would be Ethernet Ring Protection Switching (ERPS) another protocol I had never heard of until researching this article.
  16. If you look closely at what happens at t=2s, you can see that R2 is gaining popularity as root: S17 to S36 believe R2 is the root bridge. S16 does not follow because we hit the maximum age. Later, S17 to S20 reverse their position. I ll let you explore the state of the various bridges to understand the root cause.
  17. When increasing the maximum age to 40, you also need to increase the forward delay to 21 (:forward-delay 21), as the standard enforces this condition: 2 (Forward Delay 1) Max Age. For this specific topology, you could also increase the maximum age to 37 and forward-delay to 20.
  18. The simulation may seem slow, but it does not run in real time. Look at the current timestamp in the upper right corner to know the wall clock, e.g. t=8s. Once the topology stabilizes, the same corner shows the convergence time, e.g. 2s.
  19. Khaled Elmeleegy, Alan Cox, and Eugene Ng formalized this phenomenon in On Count-to-Infinity Induced Forwarding Loops in Ethernet Networks and later in Understanding and Mitigating the Effects of Count to Infinity in Ethernet Networks. They propose a fix that did not find its way into a standard.

Vincent Bernat: A non-interactive tour of the spanning tree protocol

Imagine you rent office space for a three-day event. You quickly set up a few Ethernet switches and tape some cables on the floor to get everyone online. Unfortunately, Stan, your clumsiest coworker, kicks out a cable every time he gets up for coffee. Spare cables would fix that, but a loop turns into a broadcast storm: Ethernet packets multiply until nothing else gets through. That s where the spanning tree protocol comes in: it blocks just enough of the spare cables to leave a loop-free tree, and rebuilds it in a second each time Stan strikes again.1
This content is also available as a text version, with interactive demos that run a real implementation directly in your browser!
This video is an experiment.2 Honestly, except for Radia Perlman reading her poem,3 you should read the original article instead. It presents the same content, but you can play with the interactive examples, which are the main contribution. On the other hand, if you happen to like the video, be sure to tell me in the comments!

  1. The sprites for Stan and Blobby come from Craftpix. The background music is Sonatina No. 2 in G Major III. Allegro by Aaron Dunn.
  2. I thought automated tools would produce this video in a couple of hours. In the end, it was another rabbit hole and it took me more than 12.
  3. The audio was extracted from a Youtube video and cleaned up.

15 August 2026

Sven Hoexter: FrOSCon 2026: TLS Talk

Info: German content only, sorry. I was pondering for the past three years if I should give some sort of TLS basics talk at FrOSCon. I finally stepped up this year and gave that talk today, with the title "TLS, mTLS, SNI, ECH, CAA, HTTPS, PKI, Zertifikate und ein bisschen PQC". I was too optimistic with my 50 slides, and had to drop the Post Quantum Cryptography part at the end. Still got positive feedback from Zugschlus and others - thanks a lot for that <3 - and was asked for the slides. It's not a piece of art, but maybe it helps to release the LibreOffice odp file as well, so others can use it as a base for other events or corp internal talks. So here is the froscon-tls-2026.pdf and froscon-tls-2026.odp, both released under the CC BY-NC license. The video is also available at media.ccc.de if you want to watch it. Thanks to everyone who made FrOSCon happen for the 21th time!

12 August 2026

Reproducible Builds: Reproducible Builds summit 2026 to take place in Gothenburg

This event is happening soon see below for registration instructions!

We are extremely pleased to announce the upcoming Reproducible Builds summit, which will take place from September 22nd 24th 2026 in the city of Gothenburg, Sweden. This year, we are thrilled to host the tenth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Vienna (2025), Hamburg (2023 2024), Venice (2022), Marrakesh (2019), Paris (2018), Berlin (2017), Berlin (2016) and Athens (2015). If you re excited about joining us this year, please make sure to read the event page which has more details about the event and location. As in previous years, we will be sending invitations to all those who attended our previous summit events or expressed interest to do so. However, even if you do not receive a personal invitation, please do email the organizers and we will find a way to accommodate you.

About the event The Reproducible Builds Summit is a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving.

Schedule Although the exact content of the meeting will be shaped by the participants, the main goals will include:
  • Update & exchange about the status of reproducible builds in various projects.
  • Improve collaboration both between and inside projects.
  • Expand the scope and reach of reproducible builds to more projects.
  • Work together and hack on solutions.
  • Establish space for more strategic and long-term thinking than is possible in virtual channels.
  • Brainstorm designs on tools enabling users to get the most benefits from reproducible builds.
  • Discuss how reproducible builds will be usable and meaningful to users and developers alike.
Logs and minutes will be published after the meeting.

Location & date

Registration instructions Please reach out if you d like to participate in hopefully interesting, inspiring and intense technical sessions about reproducible builds and beyond! We look forward to what we anticipate to be yet another extraordinary event!

11 August 2026

Colin Watson: Free software activity in July 2026

About 95% of my Debian contributions this month were sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH Now that Ubuntu 26.04 LTS has been released, I ve been getting back to the GSS-API key exchange package split in our OpenSSH packaging. Once I started testing my draft openssh-gssapi source package, I realized that I needed to make some changes in the main openssh source package first in order to support it. The dependency from openssh-server to openssh-client was awkward, as was the (related) fact that openssh-client contained shared documentation for other OpenSSH binary packages. After some thought, I created a new openssh-common binary package, moved shared documentation and the ssh-keygen program to that, and dropped dependencies on openssh-client which were no longer necessary (fixing #699473 and #1070098 in the process). This caused a couple of regressions (#1141420 and #1141550) that I had to fix, and more subtly it also caused a number of autopkgtest regressions in other packages because openssh-client is no longer in base images as a result of a dependency from openssh-server. I believe I have fixes for all of these either pending review or merged (one of which I did in August rather than July): I upgraded from 10.3p1 to 10.4p1, and in the process contributed a GSS-API option handling fix upstream. I made openssh-ssh1 s package description more accurately describe the package, thanks to suggestions from Matthias Lang. Installer team With support from a Freexian customer, I reviewed, tested, edited, and merged a patch to add VLAN support. I described the details of what I did in a comment. This has been vaguely on my to-do list since, er, about 2014, so it was very satisfying to get it sorted out. Python packaging New upstream versions: Other build/test failures: I fixed some other bugs: I adopted transaction for the Python team. I attended the Python BoF at DebConf remotely, although a badly-timed fibre outage in the village I live in really didn t help. Code reviews Other bits and pieces Dan Poltawski pointed out in a Fediverse post that the project history didn t list Sruthi as the current DPL. I fixed that, although it doesn t look as though the fix is in the published version yet. I upgraded yubihsm-shell to 2.8.0.

21 July 2026

Vasudev Kamath: Releasing debvulns-exporter: Prometheus exporter for Debian System Vulnerabilities

Following up on my previous post, I am releasing debvulns-exporter, a Prometheus exporter for tracking Debian system vulnerabilities. The underlying vulnerability analysis logic remains identical to the previously released MCP server and CLI utility.
Why an Exporter? In my engineering workflows, I frequently deal with Debian and vulnerability management. Most enterprise environments rely on commercial, paid vulnerability platforms like Tenable or Rapid7. While these platforms provide extensive feature sets, I noticed a distinct lack of open-source tools tailored for this specific pipeline. While debsecan exists, it lacks a structured, parseable format suitable for building dashboards aimed at management consumption. What started as an experimental MCP server for learning purposes evolved into a practical question: why not convert it into a Prometheus exporter? Given that Prometheus is the de facto standard metrics platform across the industry, this architecture was the logical next step.
Design and Exported Metrics The exporter is implemented as a native Prometheus exporter utilizing the prometheus-client library. It operates using two threads: one handles fetching the vulnerability data, parsing EPSS feeds, and cross-referencing installed packages to identify local vulnerabilities; the second handles serving the metrics endpoint. The full architecture details and metrics specifications can be found in the design doc. The specification was drafted during a technical brainstorming session with Claude 4.6 Sonnet on Antigravity prior to writing the implementation.
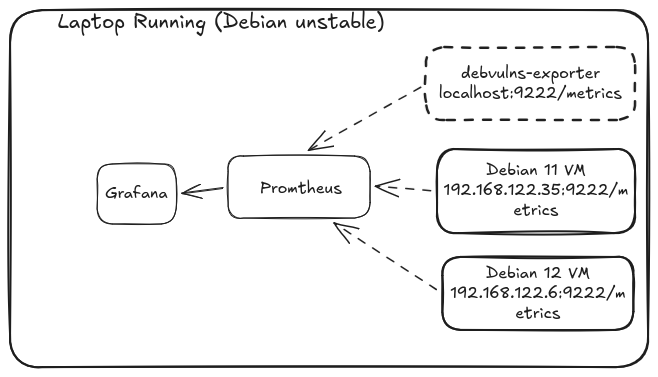
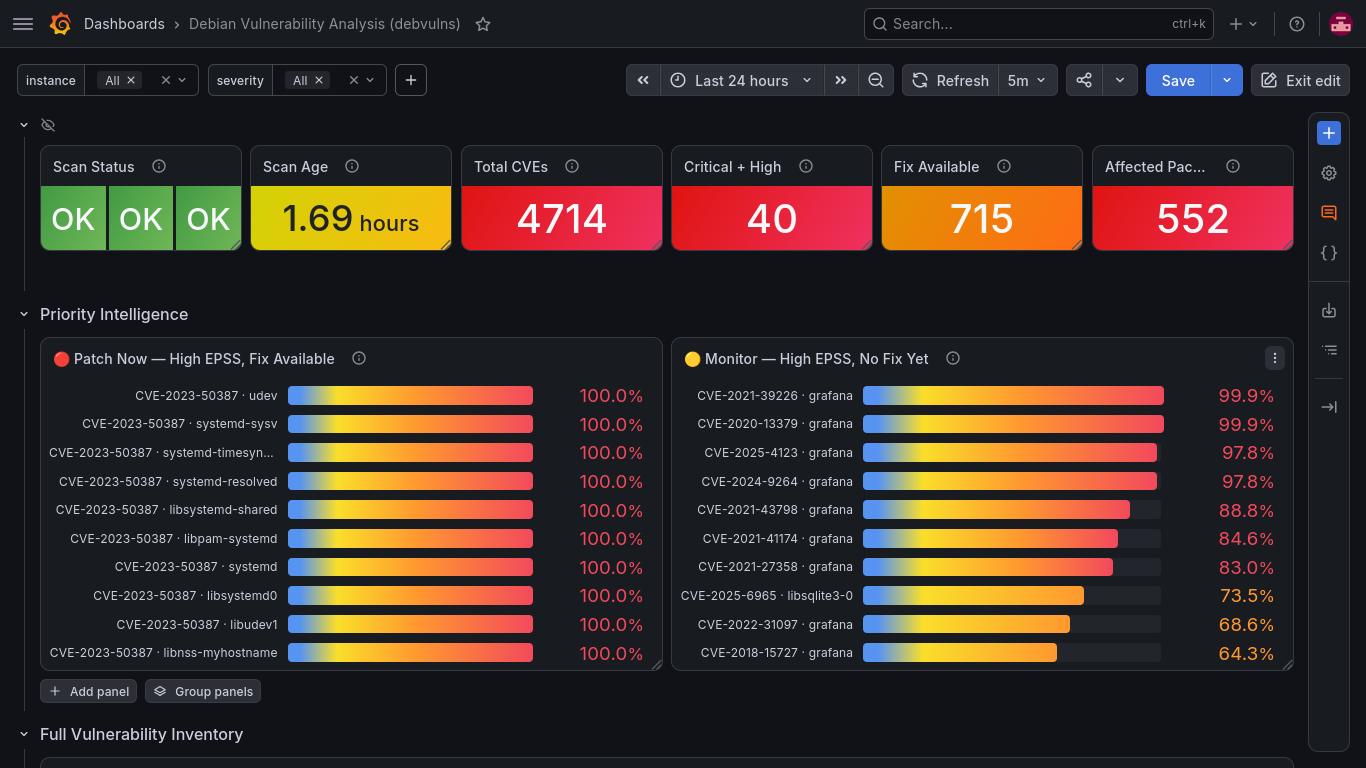
Testing and Dashboarding To validate the exporter, I spun up older Debian 11 and Debian 12 cloud images sourced from the Debian Cloud team. The older image was intentionally selected to guarantee a standard baseline of unpatched vulnerabilities for testing. The local evaluation topology is structured as shown below: Rather than constructing the Grafana dashboard from scratch, I used Claude 4.6 Sonnet via Antigravity to generate the layout configuration. The generated dashboard for the local testbed functions effectively: The complete, ready-to-import Grafana dashboard configuration is included directly in the debvulns source code.
Renaming the project To prevent namespace conflicts and confusion with the native debsecan utility in Debian, I have unified the ecosystem under the debvulns moniker. The core CLI is named debvulns, the exporter is debvulns-exporter, and the MCP component is debvulns-mcp. The migration release has been published to PyPI, and the new consolidated repository is active at debvulns.
Conclusion While this began as a personal utility to fill a niche tool gap, I expect it will be useful for others managing Debian infrastructure at scale. My next objective is to formalize Debian packaging for both the CLI and the exporter. The MCP component will likely remain available as an independent artifact. Until then, happy hacking. Note: As a core design choice, debvulns still uses native debsecan as its ground-truth standard. The tool continuously cross-verifies its output against debsecan to ensure perfect functional parity and data consistency.

14 July 2026

Jonas Meurer: zed-xdebug

Nextcloud PHP debugging with Xdebug in Zed editor I started to switch from PhpStorm to Zed as IDE recently as Zed is open source and has a much smaller footprint and is more slick than PhpStorm. One thing that I didn't get running immediately was Xdebug integration, so I did a bit of research and asked Claude for help. Here's a quick writeup of how to get it running. I have Zed installed as Flatpak on a Debian Trixie host system. The PHP process runs in a nextcloud-docker-dev Docker container.

Install Zed and configure debugging there Install Zed: flatpak install flathub dev.zed.Zed In Zed: open the Extensions view and install PHP. Configure the debugger: Create ~/.var/app/dev.zed.Zed/config/zed/debug.json:
[
   
    "label": "PHP: Listen to Xdebug",
    "adapter": "Xdebug",
    "request": "launch",
    "port": 9003,
    "pathMappings":  
      "/var/www/html":             "/home/<user>/devel/nextcloud/server",
      "/var/www/html/apps-extra":  "/home/<user>/devel/nextcloud/server/apps-extra",
      "/var/www/html/apps-shared": "/home/<user>/devel/nextcloud/apps-shared"
     
   
]
Add one entry per bind-mounted app directory. After creating the file, restart Zed. Inside Zed, select "debugger: start" from command palette and then "PHP: Listen to Xdebug". Verify Zed is listening. Running ss -tlnp grep 9003 on the host should show *:9003 with Zed as the process.

Configure Xdebug inside the container /usr/local/etc/php/conf.d/xdebug.ini:
xdebug.mode = debug
xdebug.idekey = PHPSTORM
xdebug.trace_output_name=trace.%R.%u
xdebug.profiler_output_name=profile.%R.%u
xdebug.output_dir=/shared/xdebug
xdebug.log = /var/log/xdebug.log
xdebug.log_level = 3
; Try to discover the client host, otherwise fall back to the docker host
xdebug.discover_client_host=true
xdebug.client_host=host.docker.internal
; When you cannot specify a trigger, use "xdebug.start_with_request = yes" to autostart debugging for all requests
; https://xdebug.org/docs/all_settings#start_with_request
xdebug.start_with_request = trigger
; Set xdebug.mode trace to use this
; More details at https://derickrethans.nl/flamboyant-flamegraphs.html
xdebug.trace_format=3
xdebug.trace_output_name=xdebug.%R.%u
Apply changes by restarting apache in the container: apache2ctl -k graceful Notes:
  • host.docker.internal resolves on Linux Docker only if the container was started with --add-host=host.docker.internal:host-gateway (nextcloud-docker-dev already does this).
  • discover_client_host = true makes xdebug follow X-Forwarded-For - useful behind Nextcloud's dev reverse proxy.

Test xdebug with a PHP command inside the container Run XDEBUG_SESSION=PHPSTORM php occ status inside the container and check /var/log/xdebug.log.

Install the browser extension Install Xdebug Helper (Firefox/Chrome). In its preferences, set the IDE Key to PhpStorm. It will set the XDEBUG_SESSION cookie when toggled to Debug. Click the Xdebug Helper icon in the browser and set it to Debug.

Test Xdebug with browser extension Load the URL that exercises the code path with the breakpoint. Zed should stop the code exection at the breakpoint.

13 March 2026

Sven Hoexter: container image with ECH enabled curl

As an opportunity to rewire my brain from "docker" to "podman" and "buildah" I started to create an image build with an ECH enabled curl at https://gitlab.com/hoexter/ech. Not sure if it helps anyone, but setup should be like this:
git clone https://gitlab.com/hoexter-experiments/ech
cd ech
buildah build --layers -f Dockerfile -t echtest
podman run -ti echtest /usr/local/bin/curl \
  --ech true --doh-url https://one.one.one.one/dns-query \
  https://crypto.cloudflare.com/cdn-cgi/trace.cgi
fl=48f121
h=crypto.cloudflare.com
ip=2.205.251.187
ts=1773410985.168
visit_scheme=https
uag=curl/8.19.0
colo=DUS
sliver=none
http=http/2
loc=DE
tls=TLSv1.3
sni=encrypted
warp=off
gateway=off
rbi=off
kex=X25519
It also builds nginx and you can use that for a local test within the image. More details in the README.

11 March 2026

Sven Hoexter: RFC 9849 - Encrypted Client Hello

Now that ECH is standardized I started to look into it to understand what's coming. While generally desirable to not leak the SNI information, I'm not sure if it will ever make it to the masses of (web)servers outside of big CDNs. Beside of the extension of the TLS protocol to have an inner and outer ClientHello, you also need (frequent) updates to your HTTPS/SVCB DNS records. The idea is to rotate the key quickly, the OpenSSL APIs document talks about hourly rotation. Which means you've to have encrypted DNS in place (I guess these days DNSoverHTTPS is the most common case), and you need to be able to distribute the private key between all involved hosts + update DNS records in time. In addition to that you can also use a "shared mode" where you handle the outer ClientHello (the one using the public key from DNS) centrally and the inner ClientHello on your backend servers. I'm not yet sure if that makes it easier or even harder to get it right. That all makes sense, and is feasible for setups like those at Cloudflare where the common case is that they provide you NS servers for your domain, and terminate your HTTPS connections. But for the average webserver setup I guess we will not see a huge adoption rate. Or we soon see something like a Caddy webserver on steroids which integrates a DNS server for DoH with not only automatic certificate renewal build in, but also automatic ECHConfig updates. If you want to read up yourself here are my starting points: RFC 9849 TLS Encrypted Client Hello RFC 9848 Bootstrapping TLS Encrypted ClientHello with DNS Service Bindings RFC 9934 Privacy-Enhanced Mail (PEM) File Format for Encrypted ClientHello (ECH) OpenSSL 4.0 ECH APIs curl ECH Support nginx ECH Support Cloudflare Good-bye ESNI, hello ECH! If you're looking for a test endpoint, I see one hosted by Cloudflare:
$ dig +short IN HTTPS cloudflare-ech.com
1 . alpn="h3,h2" ipv4hint=104.18.10.118,104.18.11.118 ech=AEX+DQBBFQAgACDBFqmr34YRf/8Ymf+N5ZJCtNkLm3qnjylCCLZc8rUZcwAEAAEAAQASY2xvdWRmbGFyZS1lY2guY29tAAA= ipv6hint=2606:4700::6812:a76,2606:4700::6812:b76

9 March 2026

Sven Hoexter: Latest pflogsumm from unstable on trixie

If you want the latest pflogsumm release form unstable on your Debian trixie/stable mailserver you've to rely on pining (Hint for the future: Starting with apt 3.1 there is a new Include and Exclude option for your sources.list). For trixie you've to use e.g.:
$ cat /etc/apt/sources.list.d/unstable.sources
Types: deb
URIs: http://deb.debian.org/debian
Suites: unstable 
Components: main
#This will work with apt 3.1 or later:
#Include: pflogsumm
Signed-By: /usr/share/keyrings/debian-archive-keyring.pgp
$ cat /etc/apt/preferences.d/pflogsumm-unstable.pref 
Package: pflogsumm
Pin: release a=unstable
Pin-Priority: 950
Package: *
Pin: release a=unstable
Pin-Priority: 50
Should result in:
$ apt-cache policy pflogsumm
pflogsumm:
  Installed: (none)
  Candidate: 1.1.14-1
  Version table:
     1.1.14-1 950
        50 http://deb.debian.org/debian unstable/main amd64 Packages
     1.1.5-8 500
       500 http://deb.debian.org/debian trixie/main amd64 Packages
Why would you want to do that? Beside of some new features and improvements in the newer releases, the pflogsumm version in stable has an issue with parsing the timestamps generated by postfix itself when you write to a file via maillog_file. Since the Debian default setup uses logging to stdout and writing out to /var/log/mail.log via rsyslog, I never invested time to fix that case. But since Jim picked up pflogsumm development in 2025 that was fixed in pflogsumm 1.1.6. Bug is #1129958, originally reported in #1068425 Since it's an arch:all package you can just pick from unstable, I don't think it's a good candidate for backports, and just fetching the fixed version from unstable is a compromise for those who run into that issue.

21 February 2026

Thomas Goirand: Seamlessly upgrading a production OpenStack cluster in 4 hours : with 2k lines shell script


tl;dr: To the question: what does it take to upgrade OpenStack , my personal answer is: less than 2K lines of dash script. I ll here describe its internals, and why I believe it is the correct solution. Why writing this blog post During FOSSDEM 2024, I was asked how to you handle upgrades . I answered with a big smile and a short with a very small shell script as I couldn t explain in 2 minutes how it was done. Just saying it is great this way doesn t help giving readers enough hints to be trusted. Why and how did I do it the right way ? This blog post is an attempt to reply better to this question more deeply. Upgrading OpenStack in production I wrote this script maybe a 2 or 3 years ago. Though I m only blogging about it today, because I did such an upgrade in a public cloud in production last Thuesday evening (ie: the first region of the Infomaniak public cloud). I d say the cluster is moderately large (as of today: about 8K+ VMs running, 83 compute nodes, 12 network nodes, for a total of 10880 physical CPU cores and 125 TB of RAM if I only count the compute servers). It took only 4 hours to do the upgrade (though I already wore some more code to speed this up for the next time ). It went super smooth without a glitch. I mostly just sat, reading the script output and went to bed once it finished running. The next day, all my colleagues at Infomaniak were nicely congratulating me that it went that smooth (a big thanks to all of you who did). I couldn t dream of an upgrade that smooth! :) Still not impressed? Boring read? Yeah let s dive into more technical details. Intention behind the implementation My script isn t perfect. I wont ever pretend it is. But at least, it does minimize down time of every OpenStack service. It also is a by the book implementation of what s written in the OpenStack doc, following every upstream advice. As a result, it is fully seamless for some OpenStack services, and as HA as OpenStack can be for others. The upgrade process is of course idempotent and can be re-run in case of failure. Here s why. General idea My upgrade script does thing in a certain order, respecting what is documented about upgrades in the OpenStack documentation. It basically does: Installing dependencies The first thing the upgrade script does is: For this last thing, a static list of all needed dependency upgrade is maintained between each release of OpenStack, and for each type of nodes. Then for all packages in this list, the script checks with dpkg-query that the package is really installed, and with apt-cache policy that it really is going to be upgraded (Maybe there s an easier way to do this?). This way, no package is marked as manually installed by mistake during the upgrade process. This ensure that apt-get purge autoremove really does what it should, and that the script is really idempotent. The idea then, is that once all dependencies are installed, upgrading and restarting leaf packages (ie: OpenStack services like Nova, Glance, Cinder, etc.) is very fast, because the apt-get command doesn t need to install all dependencies. So at this point, doing apt-get install python3-cinder for example (which will also, thanks to dependencies, upgrade cinder-api and cinder-scheduler, if it s in a controller node) only takes a few seconds. This principle applies to all nodes (controller nodes, network nodes, compute nodes, etc.), which helps a lot speeding-up the upgrade and reduce unavailability. hapc At its core, the oci-cluster-upgrade-openstack-release script uses haproxy-cmd (ie: /usr/bin/hapc) to drain each API server to-be-upgraded from haproxy. Hapc is a simple Python wrapper around the haproxy admin socket: it sends command to it with an easy to understand CLI. So it is possible to reliably upgrade one API service only after it s drained away. Draining means one just wait for the last query to finish and the client to disconnect from http before giving the backend server some more queries. If you do not know hapc / haproxy-cmd, I recommend trying it: it s going to be hard for you to stop using it once you tested it. Its bash-completion script makes it VERY easy to use, and it is helpful in production. But not only: it is also nice to have when writing this type of upgrade script. Let s dive into haproxy-cmd. Example on how to use haproxy-cmd Let me show you. First, ssh one of the 3 controller and search where the virtual IP (VIP) is located with crm resource locate openstack-api-vip or with a (more simple) crm status . Let s ssh that server who got the VIP, and now, let s drain it away from haproxy. $ hapc list-backends
$ hapc drain-server --backend glancebe --server cl1-controller-1.infomaniak.ch --verbose --wait --timeout 50
$ apt-get install glance-api
$ hapc enable-server --backend glancebe --server cl1-controller-1.infomaniak.ch
Upgrading the control plane My upgrade script leverages hapc just like above. For each OpenStack project, it s done in this order on the first node holding the VIP: Starting at [1], the risk is that other nodes may have a new version of the database schema, but an old version of the code that isn t compatible with it. But it doesn t take long, because the next step is to take care of the other (usually 2) nodes of the OpenStack control plane: So while there s technically zero down time, still some issues between [1] and [2] above may happen because of the new DB schema and the old code (both for API and other services) are up and running at the same time. It is however supposed to be rare cases (some OpenStack project don t even have db change between some OpenStack releases, and it often continues to work on most queries with the upgraded db), and the cluster will be like that for a very short time, so that s fine, and better than an full API down time. Satellite services Then there s satellite services, that needs to be upgraded. Like Neutron, Nova, Cinder. Nova is the least offender as it has all the code to rewrite Json object schema on-the-fly so that it continues to work during an upgrade. Though it s a known issue that Cinder doesn t have the feature (last time I checked), and it s also probably the same for Neutron (maybe recent-ish versions of OpenStack do use oslo.versionnedobjects ?). Anyways, upgrade on these nodes are done just right after the control plane for each service. Parallelism and upgrade timings As we re dealing with potentially hundreds of nodes per cluster, a lot of operations are performed in parallel. I choose to simply use the & shell thingy with some wait shell stuff so that not too many jobs are done in parallel. For example, when disabling SSH on all nodes, this is done 24 nodes at a time. Which is fine. And the number of nodes is all depending on the type of thing that s being done. For example, while it s perfectly OK to disable puppet on 24 nodes at the same time, but it is not OK to do that with Neutron services. In fact, each time a Neutron agent is restarted, the script explicitly waits for 30 seconds. This conveniently avoids a hailstorm of messages in RabbitMQ, and neutron-rpc-server to become too busy. All of these waiting are necessary, and this is one of the reasons why can sometimes take that long to upgrade a (moderately big) cluster. Not using config management tooling Some of my colleagues would have prefer that I used something like Ansible. Whever, there s no reason to use such tool if the idea is just to perform some shell script commands on every servers. It is a way more efficient (in terms of programming) to just use bash / dash to do the work. And if you want my point of view about Ansible: using yaml for doing such programming would be crasy. Yaml is simply not adapted for a job where if, case, and loops are needed. I am well aware that Ansible has workarounds and it could be done, but it wasn t my choice.

16 February 2026

Antoine Beaupr : Keeping track of decisions using the ADR model
In the Tor Project system Administrator's team (colloquially known as TPA), we've recently changed how we take decisions, which means you'll get clearer communications from us about upcoming changes or targeted questions about a proposal. Note that this change only affects the TPA team. At Tor, each team has its own way of coordinating and making decisions, and so far this process is only used inside TPA. We encourage other teams inside and outside Tor to evaluate this process to see if it can improve your processes and documentation.

The new process We had traditionally been using a "RFC" ("Request For Comments") process and have recently switched to "ADR" ("Architecture Decision Record"). The ADR process is, for us, pretty simple. It consists of three things:
  1. a simpler template
  2. a simpler process
  3. communication guidelines separate from the decision record

The template As team lead, the first thing I did was to propose a new template (in ADR-100), a variation of the Nygard template. The TPA variation of the template is similarly simple, as it has only 5 headings, and is worth quoting in full:
  • Context: What is the issue that we're seeing that is motivating this decision or change?
  • Decision: What is the change that we're proposing and/or doing?
  • Consequences: What becomes easier or more difficult to do because of this change?
  • More Information (optional): What else should we know? For larger projects, consider including a timeline and cost estimate, along with the impact on affected users (perhaps including existing Personas). Generally, this includes a short evaluation of alternatives considered.
  • Metadata: status, decision date, decision makers, consulted, informed users, and link to a discussion forum
The previous RFC template had 17 (seventeen!) headings, which encouraged much longer documents. Now, the decision record will be easier to read and digest at one glance. An immediate effect of this is that I've started using GitLab issues more for comparisons and brainstorming. Instead of dumping in a document all sorts of details like pricing or in-depth alternatives comparison, we record those in the discussion issue, keeping the document shorter.

The process The whole process is simple enough that it's worth quoting in full as well:
Major decisions are introduced to stakeholders in a meeting, smaller ones by email. A delay allows people to submit final comments before adoption.
Now, of course, the devil is in the details (and ADR-101), but the point is to keep things simple. A crucial aspect of the proposal, which Jacob Kaplan-Moss calls the one weird trick, is to "decide who decides". Our previous process was vague about who makes the decision and the new template (and process) clarifies decision makers, for each decision. Inversely, some decisions degenerate into endless discussions around trivial issues because too many stakeholders are consulted, a problem known as the Law of triviality, also known as the "Bike Shed syndrome". The new process better identifies stakeholders:
  • "informed" users (previously "affected users")
  • "consulted" (previously undefined!)
  • "decision maker" (instead of the vague "approval")
Picking those stakeholders is still tricky, but our definitions are more explicit and aligned to the classic RACI matrix (Responsible, Accountable, Consulted, Informed).

Communication guidelines Finally, a crucial part of the process (ADR-102) is to decouple the act of making and recording decisions from communicating about the decision. Those are two radically different problems to solve. We have found that a single document can't serve both purposes. Because ADRs can affect a wide range of things, we don't have a specific template for communications. We suggest the Five Ws method (Who? What? When? Where? Why?) and, again, to keep things simple.

How we got there The ADR process is not something I invented. I first stumbled upon it in the Thunderbird Android project. Then, in parallel, I was in the process of reviewing the RFC process, following Jacob Kaplan-Moss's criticism of the RFC process. Essentially, he argues that:
  1. the RFC process "doesn't include any sort of decision-making framework"
  2. "RFC processes tend to lead to endless discussion"
  3. the process "rewards people who can write to exhaustion"
  4. "these processes are insensitive to expertise", "power dynamics and power structures"
And, indeed, I have been guilty of a lot of those issues. A verbose writer, I have written extremely long proposals that I suspect no one has ever fully read. Some proposals were adopted by exhaustion, or ignored because not looping in the right stakeholders. Our discussion issue on the topic has more details on the issues I found with our RFC process. But to give credit to the old process, it did serve us well while it was there: it's better than nothing, and it allowed us to document a staggering number of changes and decisions (95 RFCs!) made over the course of 6 years of work.

What's next? We're still experimenting with the communication around decisions, as this text might suggest. Because it's a separate step, we also have a tendency to forget or postpone it, like this post, which comes a couple of months late. Previously, we'd just ship a copy of the RFC to everyone, which was easy and quick, but incomprehensible to most. Now we need to write a separate communication, which is more work but, hopefully, worth the as the result is more digestible. We can't wait to hear what you think of the new process and how it works for you, here or in the discussion issue! We're particularly interested in people that are already using a similar process, or that will adopt one after reading this.
Note: this article was also published on the Tor Blog.

28 January 2026

Sven Hoexter: Decrypt TLS Connection with wireshark and curl

With TLS 1.3 more parts of the handshake got encrypted (e.g. the certificate), but sometimes it's still helpful to look at the complete handshake. curl uses the somewhat standardized env variable for the key log file called SSLKEYLOGFILE, which is also supported by Firefox and Chrome. wireshark hides the setting in the UI behind Edit -> Preferences -> Protocols -> TLS -> (Pre)-Master-Secret log filename which is uncomfortable to reach. Looking up the config setting in the Advanced settings one can learn that it's called internally tls.keylog_file. Thus we can set it up with:
sudo wireshark -o "tls.keylog_file:/home/sven/curl.keylog"
SSLKEYLOGFILE=/home/sven/curl.keylog curl -v https://www.cloudflare.com/cdn-cgi/trace
Depending on the setup root might be unable to access the wayland session, that can be worked around by letting sudo keep the relevant env variables:
$ cat /etc/sudoers.d/wayland 
Defaults   env_keep += "XDG_RUNTIME_DIR"
Defaults   env_keep += "WAYLAND_DISPLAY"
Or setup wireshark properly and use the wireshark group to be able to dump traffic. Might require a sudo dpkg-reconfigure wireshark-common. Regarding curl: In some situations it could be desirable to force a specific older TLS version for testing, which requires a minimal and maximal version. E.g. to force TLS 1.2 only:
curl -v --tlsv1.2 --tls-max 1.2 https://www.cloudflare.com/cdn-cgi/trace

8 January 2026

Sven Hoexter: Moving from hexchat to Halloy

I'm not hanging around on IRC a lot these days, but when I do I used hexchat (and xchat before). Probably a bad habbit of clinging to what I got used to for the past 25 years. But in the light of the planned removal of GTK2, it felt like it was time to look for an alternative. Halloy looked interesting, albeit not packaged for Debian. But upstream references a flatpak (another party I did not join so far), good enough to give it a try.
$ sudo apt install flatpak
$ flatpak remote-add --if-not-exists flathub https://dl.flathub.org/repo/flathub.flatpakrepo
$ flatpak install org.squidowl.halloy
$ flatpak run org.squidowl.halloy
Configuration ends up at ~/.var/app/org.squidowl.halloy/config/halloy/config.toml, which I linked for convenience to ~/.halloy.toml. Since I connect via ZNC in an odd old setup without those virtual networks, but several accounts, and of course never bothered to replace the self signed certificate, it requires some additional configuration to be able to connect. Each account gets its own servers.<foo> block like this:
[servers.bnc-oftc]
nickname = "my-znc-user-for-this-network"
server = "sven.stormbind.net"
dangerously_accept_invalid_certs = true
password = "mypasssowrd"
port = 4711
use_tls = true
Halloy has also a small ZNC guide. I'm growing old, so a bigger font size is useful. Be aware that font changes require an application restart to take effect.
[font]
size = 16
family = "Noto Mono"
I also prefer the single-pane mode which could be copy & pasted as documented. Works good enough for now. hexchat was also the last none wayland application I've been using (xlsclients output is finally empty).

5 January 2026

Colin Watson: Free software activity in December 2025

About 95% of my Debian contributions this month were sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. Python packaging I upgraded these packages to new upstream versions: Python 3.14 is now a supported version in unstable, and we re working to get that into testing. As usual this is a pretty arduous effort because it requires going round and fixing lots of odds and ends across the whole ecosystem. We can deal with a fair number of problems by keeping up with upstream (see above), but there tends to be a long tail of packages whose upstreams are less active and where we need to chase them, or where problems only show up in Debian for one reason or another. I spent a lot of time working on this: Fixes for pytest 9: I filed lintian: Report Python egg-info files/directories to help us track the migration to pybuild-plugin-pyproject. I did some work on dh-python: Normalize names in pydist lookups and pyproject plugin: Support headers (the latter of which allowed converting python-persistent and zope.proxy to pybuild-plugin-pyproject, although it needed a follow-up fix). I fixed or helped to fix several other build/test failures: Other bugs: Other bits and pieces Code reviews

3 January 2026

Russ Allbery: Review: Challenges of the Deeps

Review: Challenges of the Deeps, by Ryk E. Spoor
Series: Arenaverse #3
Publisher: Baen
Copyright: March 2017
ISBN: 1-62579-564-5
Format: Kindle
Pages: 438
Challenges of the Deeps is the third book in the throwback space opera Arenaverse series. It is a direct sequel to Spheres of Influence, but Spoor provides a substantial recap of the previous volumes for those who did not read the series in close succession (thank you!). Ariane has stabilized humanity's position in the Arena with yet another improbable victory. (If this is a spoiler for previous volumes, so was telling you the genre of the book.) Now is a good opportunity to fulfill the promise humanity made to their ally Orphan: accompaniment on a journey into the uncharted deeps of the Arena for reasons that Orphan refuses to explain in advance. Her experienced crew provide multiple options to serve as acting Leader of Humanity until she gets back. What can go wrong? The conceit of this series is that as soon as a species achieves warp drive technology, their ships are instead transported into the vast extradimensional structure of the Arena where a godlike entity controls the laws of nature and enforces a formal conflict resolution process that looks alternatingly like a sporting event, a dueling code, and technology-capped total war. Each inhabitable system in the real universe seems to correspond to an Arena sphere, but the space between them is breathable atmosphere filled with often-massive storms. In other words, this is an airship adventure as written by E.E. "Doc" Smith. Sort of. There is an adventure, and there are a lot of airships (although they fight mostly like spaceships), but much of the action involves tense mental and physical sparring with a previously unknown Arena power with unclear motives. My general experience with this series is that I find the Arena concept fascinating and want to read more about it, Spoor finds his much-less-original Hyperion Project in the backstory of the characters more fascinating and wants to write about that, and we reach a sort of indirect, grumbling (on my part) truce where I eagerly wait for more revelations about the Arena and roll my eyes at the Hyperion stuff. Talking about Hyperion in detail is probably a spoiler for at least the first book, but I will say that it's an excuse to embed versions of literary characters into the story and works about as well as most such excuses (not very). The characters in question are an E.E. "Doc" Smith mash-up, a Monkey King mash-up, and a number of other characters that are obviously references to something but for whom I lack enough hints to place (which is frustrating). Thankfully we get far less human politics and a decent amount of Arena world-building in this installment. Hyperion plays a role, but mostly as foreshadowing for the next volume and the cause of a surprising interaction with Arena rules. One of the interesting wrinkles of this series is that humanity have an odd edge against the other civilizations in part because we're borderline insane sociopaths from the perspective of the established powers. That's an old science fiction trope, but I prefer it to the Campbell-style belief in inherent human superiority. Old science fiction tropes are what you need to be in the mood for to enjoy this series. This is an unapologetic and intentional throwback to early pulp: individuals who can be trusted with the entire future of humanity because they're just that moral, super-science, psychic warfare, and even coruscating beams that would make E.E. "Doc" Smith proud. It's an occasionally glorious but mostly silly pile of technobabble, but Spoor takes advantage of the weird, constructed nature of the Arena to provide more complex rules than competitive superlatives. The trick is that while this is certainly science fiction pulp, it's also a sort of isekai novel. There's a lot of anime and manga influence just beneath the surface. I'm not sure why it never occurred to me before reading this series that melodramatic anime and old SF pulps have substantial aesthetic overlap, but of course they do. I loved the Star Blazers translated anime that I watched as a kid precisely because it had the sort of dramatic set pieces that make the Lensman novels so much fun. There is a bit too much Wu Kong in this book for me (although the character is growing on me a little), and some of the maneuvering around the mysterious new Arena actor drags on longer than was ideal, but the climax is great stuff if you're in the mood for dramatic pulp adventure. The politics do not bear close examination and the writing is serviceable at best, but something about this series is just fun. I liked this book much better than Spheres of Influence, although I wish Spoor would stop being so coy about the nature of the Arena and give us more substantial revelations. I'm also now tempted to re-read Lensman, which is probably a horrible idea. (Spoor leaves the sexism out of his modern pulp.) If you got through Spheres of Influence with your curiosity about the Arena intact, consider this one when you're in the mood for modern pulp, although don't expect any huge revelations. It's not the best-written book, but it sits squarely in the center of a genre and mood that's otherwise a bit hard to find. Followed by the Kickstarter-funded Shadows of Hyperion, which sadly looks like it's going to concentrate on the Hyperion Project again. I will probably pick that up... eventually. Rating: 6 out of 10
Louis-Philippe V ronneau: 2025 A Musical Retrospective

2026 already! The winter weather here has really been beautiful and I always enjoy this time of year. Writing this yearly musical retrospective has now become a beloved tradition of mine1 and I enjoy retracing the year's various events through albums I listened to and concerts I went to. Albums In 2025, I added 141 new albums to my collection, around 60% more than last year's haul. I think this might have been too much? I feel like I didn't have time to properly enjoy all of them and as such, I decided to slow down my acquisition spree sometimes in early December, around the time I normally do the complete opposite. This year again, I bought the vast majority of my music on Bandcamp. Most of the other albums I bought as CDs and ripped them. Concerts In 2025, I went to the following 25 (!!) concerts: Although I haven't touched metalfinder's code in a good while, my instance still works very well and I get the occasional match when a big-name artist in my collection comes in town. Most the venues that advertise on Bandsintown are tied to Ticketmaster though, which means most underground artists (i.e. most of the music I listen to) end up playing elsewhere. As such, shout out again to the Gancio project and to the folks running the Montreal instance. It continues to be a smash hit and most of the interesting concerts end up being advertised there. See you all in 2026!

  1. see the 2022, 2023 and 2024 entries

17 December 2025

Sven Hoexter: exfatprogs: Do not try defrag.exfat / mkfs.exfat Windows compatibility in Trixie

exfatprogs 1.3.0 added a new defrag.exfat utility which turned out to be not reliable and cause data loss. exfatprogs 1.3.1 disabled the utility, and I followed that decision with the upload to Debian/unstable yesterday. But as usual it will take some time until it's migrating to testing. Thus if you use testing do not try defag.exfat! At least not without a vetted and current backup. Beside of that there is a compatibility issue with the way mkfs.exfat, as shipped in trixie (exfatprogs 1.2.9), handles drives which have a physical sector size of 4096 bytes but emulate a logical size of 512 bytes. With exfatprogs 1.2.6 a change was implemented to prefer the physical sector size on those devices. That turned out to be not compatible with Windows, and was reverted in exfatprogs 1.3.0. Sadly John Ogness ran into the issue and spent some time to debug it. I've to admit that I missed the relevance of that change. Huge kudos to John for the bug report. Based on that I prepared an update for the next trixie point release. If you hit that issue on trixie with exfatprogs 1.2.9-1 you can work around it by formating with mkfs.exfat -s 512 /dev/sdX to get Windows compatibility. If you use exfatprogs 1.2.9-1+deb13u1 or later, and want the performance gain back, and do not need Windows compatibility, you can format with mkfs.exfat -s 4096 /dev/sdX.

18 November 2025

Sahil Dhiman: Anchors in Life

Just like a ship needs an anchor to stabilize and hold it to port, humans too, I feel, have and require anchors to hold them in life. It could be an emotional anchor, a physical anchor, an anchor that stimulates your curiosity, a family member, a friend or a partner or a spiritual being. An anchor holds you and helps you stabilize in stormy weather. An anchor can keep you going or stop you from going. An anchor orients you, helps you formulate your values and beliefs. An anchor could be someone or something or oneself (thanks Saswata for the thought). Writing here is one of my anchors; what s your anchor?

Next.