Search Results: "ron"

20 October 2026

Thadeu Lima de Souza Cascardo: Restricting device memory usage on Linux 7.3

Linux cgroups has been used for a while to group processes and control their access to certain system resources. One of those resources is memory, through the use of memcg. That control is dynamic, allowing for cgroups to setup a minimal and a maximal amount of memory, as well as low and high thresholds, which will control the reclaim process. But what about device memory that is not available as system RAM? Memory that is not available to the Linux page allocator? One of those device memories is GPU VRAM. That's where the dmem cgroup controller comes in. Introduced in Linux 6.14, it was first adopted by the Intel Xe driver. In Linux 6.15, AMD amdgpu driver also adopted it. In 7.3, it was adopted by nouveau. Such a cgroup controller allows the system to be configured such that a workload, be it a browser, a game, or another GPU rendering process can have some minimal VRAM available. Or it can prevent one of these processes from using all VRAM, preventing your compositor from using it, for example. Let's go through the system knobs that are available to control this and what's new in Linux 7.3. dmem regions and dmem.capacity Since a given system might have multiple GPUs, there might be multiple device memory regions. So, on dmem, each such region is described by a name. Every dmem cgroup setting file will contain one line per region. One of those files shows the capacity of each region in bytes and is present only in the root cgroup. After enabling the dmem cgroup with the following command:
# echo +dmem > /sys/fs/cgroup/cgroup.subtree_control
One can inspect the capacity of any available regions by looking at dmem.capacity at the root cgroup:
# cat /sys/fs/cgroup/dmem.capacity
drm/0000:03:00.0/vram 8573157376
That shows that the GPU at PCI address 0000:03:00.0 has a 8176MiB VRAM dmem region. dmem settings When introduced at 6.14, the following settings were available. dmem.current In every dmem cgroup, including the root cgroup, the dmem.current is a read-only file that shows the current usage of each region by the given cgroup.
# cat /sys/fs/cgroup/user.slice/dmem.current
drm/0000:03:00.0/vram 292757504
Here, it shows that user.slice cgroup is currently using above 292 MB of VRAM.
# cat /sys/fs/cgroup/dmem.current
drm/0000:03:00.0/vram 311377920
Here, we can check that total system usage is above 311 MB. dmem.max Excluding the root cgroup, dmem cgroups can control the maximal number of bytes that can be allocated from a region by processes in that cgroup. If an allocation moves the usage above the max setting, it will be refused. In that case, the allocation might be attempted at system memory or it might trigger eviction, depending on the allocation parameters and the driver. Here, the max value has special meaning, which is unrestricted usage.
# echo drm/0000:03:00.0/vram 536870912 > /sys/fs/cgroup/user.slice/dmem.max
# cat /sys/fs/cgroup/user.slice/dmem.max
drm/0000:03:00.0/vram 536870912
# echo drm/0000:03:00.0/vram max > /sys/fs/cgroup/user.slice/dmem.max
# cat /sys/fs/cgroup/user.slice/dmem.max
drm/0000:03:00.0/vram max
dmem.min dmem.min, also not available on the root cgroup, will control the eviction process - when memory needs to be moved out of VRAM to make room for other VRAM allocations. If an object belongs to a cgroup which is using less than its min setting, it will not be considered for eviction. It effectively works as a hard protection such that the cgroup can use at least the minimal setting. Given multiple cgroups may set a minimal value that exceeds the device memory capacity, it computes an effective minimal depending on the hierarchy. dmem.low While dmem.min works as a hard limit, dmem.low is a soft limit that will prevent eviction in case other objects from different cgroups are available for eviction. That is, the system will try to evict from different, possibly unprotected cgroups, before it tries to evict from a cgroup if evicting would leave its usage below the value set as dmem.low. Recent developments in Linux 7.3 Some new changes have been recently introduced in the dmem cgroup controller and its integration with GPUs. One of those is a new read-only file, dmem.peak, which was introduced to allow the peak usage of a region in a cgroup to be inspected. Also, Linux 7.3 fixed certain scenarios where a given cgroup would not be able to allocate VRAM up to its minimal or low limits if other processes had already allocated most of VRAM, even though they had no such limits set. Changing multiple regions' settings in a single write was possible before 7.3, but it was prone to failures which would not be reported to userspace and might have left the values partially updated. Starting with 7.3, only one region may be updated per write. And, finally, prior to 7.3, setting dmem.max in a cgroup that was using more than the new setting would silently fail. Now, there is a mechanism that allows a reclaim mechanism to be triggered. That way, when a process writes to dmem.max and sets a maximal value below the current usage, it will wait (unless O_NONBLOCK is used) for the reclaim process to move objects out of VRAM until the usage gets below the maximal value. If that is not possible for some reason, the setting will still be in place, restricting further alloctions by that cgroup.

17 October 2026

Dirk Eddelbuettel: RcppArmadillo 15.6.2-1 on CRAN: New Upstream

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1370 other packages on CRAN, downloaded 49.4 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 735 times according to Google Scholar. This versions updates to the 15.6.2 upstream Armadillo release made yesterday. It, along with 15.6.1 release we incorporated earlier, addresses only minor issues and should not present any user-facing changes. As usual, we did run full reverse-depdency checks against the over 1300 ackages, and did not find anything. As usual, we aim to accommodate the desired CRAN cadences for uploads and try not to exceed six in six months so we did not ship 15.6.1-1 there. The package has also already been updated for Debian, built for r2u and r-universe, and will build shortly at CRAN for the different binary releases. All changes since the last CRAN release follow.

Changes in RcppArmadillo version 15.6.2-1 (2026-10-16)
  • Upgraded to Armadillo release 15.6.2 (Medium Roast Cortado)
    • Faster inplace addition of eye() expressions

Changes in RcppArmadillo version 15.6.1-1 [github-only] (2026-10-02)
  • Upgraded to Armadillo release 15.6.1 (Medium Roast Cortado)
    • Fix for failures in pinv() when using the (non-default) "std" method

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

16 October 2026

Dirk Eddelbuettel: RcppSimdJson 0.1.17 on CRAN: Updates

A brand new release 0.1.17 of the RcppSimdJson package is now on CRAN, and has been built for r2u and on r-universe. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle per byte parsed; see the video of the talk by Daniel Lemire at QCon. This release is a small increment relative to the 0.1.6 release last week that got us (upstream) version 5.0.2 with many notable changes and sizeable speed gains on all fronts, including the interface from R. However, this failed to compile at CRAN on macOS x86_64 as the machine is setup for only partial support of C++20: no ranges, no concepts. So we now test, and fall back to C++17 if the test compilation fails. Upstream, meanwhile, already got to 5.0.5 which is included. It also gets us improved handling of disabling pragmas which we hope will survive CRAN checks. The brief NEWS entry for this release follows.

Changes in version 0.1.17 [unreleased] (2026-10-xx)
  • Compilation starts with a C++20 feature test; if this fails C++17 is used (Dirk in #111 fixing #110)
  • simdjson was upgraded to version 5.0.5 (Daniel in #112)

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

15 October 2026

Matthew Garrett: Epic's EAC2 v2 seems fairly easily bypassable

Epic just announced the upcoming version 2 of their Linux implementation of Easy Anti-Cheat. It s based on using the Linux eBPF security module to monitor what s happening, and then a bunch of extra infrastructure to make sure this can t be bypassed. The core part of this is requiring secure boot be enabled (ensuring that modified kernels can t be used), using measured boot to verify that secure boot is enabled and which keys are used (to prevent you from just signing your own modified kernel), and then doing remote attestation, a mechanism where the TPM generates a signed copy of the boot measurements and passes that off to a server which verifies it came from a real TPM, verifies that you have secure boot enabled and are using the right keys, and presumably then allows you into the game. This is all fine as long as you can prove that the measurements provided are real, and that s actually a lot harder than you might think. First, we can simply make up our own quote signed with our own key and say that it came from a TPM. This is avoided by every TPM having an Endorsement Key (or EK) and an associated certificate, with that certificate being signed by the TPM vendor. If you have a list of all the legitimate TPM vendors and their CA keys, you can verify that the measurements came from a real TPM. Easy enough. So we need to get the measurements from a real TPM, and the one on our motherboard contains the measurements that were generated by the firmware and bootloader, and we can t reset those at runtime without resetting the TPM, which oh huh there s actually nothing stopping us from doing that at runtime, as long as we have access to the hardware. Many desktop boards have the TPM on a small plugin module with a standard pinout that includes a reset pin. Simply short that to ground briefly and the TPM is back in its initial state, and userland can write whatever measurements it wants to it. Boot a modified kernel which lies to the eBPF code? As long as you replay the expected log values from a boot with secure boot on and a trusted kernel, the TPM will still happily provide a legitimate set of measurements that ll satisfy the checker. What if the TPM is less accessible, either because it s mounted directly to the motherboard or it s inside the CPU or chipset? That s going to be trickier. But here s the thing. The quote needs to come from a TPM, but not necessarily the TPM on your motherboard. TPMs these days are usually connected via the Serial Peripheral Interface, usually referred to as SPI. Microchip make a USB to SPI bridge, and there s a Linux driver. Wire one of those up with an appropriate header and you can plug in an easily available TPM module intended for plugging into a motherboard, and now we tell the kernel to ignore the motherboard TPM and make /dev/tpmrm0 point at the USB one and program it with a set of trusted measurements and once again everything is going to look just fine (yes obviously the eBPF code can look for this, but we re running a modified kernel so we can just lie to the eBPF code). Remote attestation on PCs just doesn t work that well in environments where you can t associate a specific TPM with a specific system, which is basically everywhere except enterprises. But maybe that doesn t matter and cheaters wouldn t be willing to spend the $20 or so it d take to produce one of these things? That would seem somewhat surprising, but it s not impossible. And obviously any server-side cheat detection that triggers could then block that specific TPM, meaning they d need to go and get another TPM, and maybe that ends up being enough to discourage people from bothering. From a practical level, this may be sufficient. But at a technical level? It s not great.

14 October 2026

Dirk Eddelbuettel: qlcal 0.1.4 on CRAN: Fresh Upstream Updates

The twenty-second release of the qlcal package arrivied at CRAN yesterday, and has been built for r2u as well as on r-universe. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over seventy country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This release is based on the changes in the QuantLib 1.44 release also made yesterday. It includes two new calendars for Malaysia and the Philippines, updates to around a dozen calendars, and a few other updates to internal files. Maxmilian Muecke spotted and fixed a few small bugs just as he did for the RQuantLib release we made yesterday; this is equally appreciated! The full details from NEWS.Rd follow.

Changes in version 0.1.4 (2026-10-13)
  • Add missing market calendars for Poland, Russia, Romania, Indonesia (Maximilian Muecke in #21)
  • Add (semi-deprecated) alternate separators '::' for Israel and New Zealand markets (Maximilian Muecke in #22)
  • Fix several typos across source, configuration and documentation files (Maximilian Muecke in #23)
  • Synchronize with QuantLib 1.44, add two new calendars, update several others, and update general utility files (Dirk in #24)

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Reproducible Builds: Reproducible Builds in September 2026

Welcome to the September 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. In this month s report, we cover:

  1. Reproducible Builds Summit 2026 held in Gothenburg, Sweden
  2. dettrace expanding architecture support for PGO & Lisp dumps
  3. They don t care about this!
  4. SOURCE_DATE_EPOCH specification updates
  5. Reproducible Builds at SeaGL 2026
  6. New Code of Conduct (CoC)
  7. Supporter Spotlight: Jochen Sprickerhof
  8. Mailing list news
  9. Tool and documentation development
  10. Patches

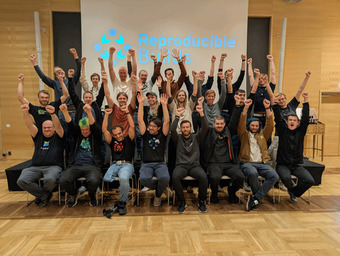
Reproducible Builds Summit 2026 held in Gothenburg, Sweden The annual Reproducible Builds summit took place from 22 to 24 September 2026 in Gothenburg, Sweden. The event brought together developers, distribution maintainers, security researchers and free software advocates from across the ecosystem to share updates on current initiatives, address outstanding toolchain bottlenecks and strengthen cross-project collaboration. Participants engaged in a series of working sessions and technical roundtables focused on expanding the practical scope of reproducibility. Discussions covered ongoing work within major Linux distributions, language-specific package ecosystems and the various parts of the binary verification infrastructure. Strategic planning formed a pillar of the gathering, with participants discussing long-term roadmap goals for supply-chain security, software integrity and related topics. Attendees explored new methods for automated verification, discussing how to lower the adoption barriers for maintainers and streamline the integration of deterministic build pipelines into established continuous integration (CI) systems. The event was then followed by two days of unmoderated hacking sessions. These hacking sessions provided space for technical progress, allowing attendees to draft specification updates, prototype new tool features and resolve standing reproducibility bugs in-person.

Dettrace expanding architecture support for PGO & Lisp dumps Bernhard M. Wiedemann announced major updates to dettrace, porting the tool across most architectures supported by Debian and openSUSE. The release addresses key stability issues, passing test suites across these targets and making it ready for production build pipelines. These improvements enable deterministic builds when utilising Profile-Guided Optimisations (PGO), removing the need to sacrifice runtime performance for reproducibility. Additionally, dettrace can now be applied to (notoriously difficult-to-reproduce) Lisp and Scheme memory dumps, including environments such as CLISP, SBCL, Scheme 48, Racket and GNU Emacs.

They don t care about this Annika Wilde, Marco Gutfleisch, Felix Reichmann, Anirban Chakraborty, Yuval Yarom, M. Angela Sasse and Ghassan Karame published a paper this month entitled They don t care about this : A Systematic Study of Trusted Execution Environments Build Reproducibility in the Wild:
Trusted Execution Environments (TEEs) have become a cornerstone of modern cloud computing, providing strong confidentiality and integrity guarantees for both code and data. A critical component of this trust model is remote attestation, which enables external entities to verify the authenticity and integrity of code executing within a TEE through cryptographic measurements. However, the effectiveness of remote attestation fundamentally depends on the verifier s ability to trace the reported measurement back to the original source code - a property that can only be guaranteed through reproducible builds. [ ]
The full PDF can be read online.

SOURCE_DATE_EPOCH specification updates Bernhard M. Wiedemann shared a number of proposals regarding updating the SOURCE_DATE_EPOCH specification following discussions at a project summit. Seven distinct proposed changes have been submitted as merge requests on Salsa. Bernhard s proposed modifications are independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests by 1 December 2026. Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list. The specification was first published in 2015 and updated in 2017.

Reproducible Builds at SeaGL 2026 Reproducible Builds will be present at SeaGL in Seattle, WA, on October 23rd & 24th. Come chat with us in person! Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture.

New Code of Conduct (CoC) for the Reproducible Builds project Mattia Rizzolo announced the official launch of a Code of Conduct for the Reproducible Builds project. This follows work and community discussions originally initiated in 2024, incorporating feedback gathered over email and during project summits, as well as with input from the Software Freedom Conservancy. The new Code of Conduct establishes guidelines emphasising mutual respect among project contributors. It also defines a formalised process for submitting and handling complaints regarding community misconduct, ensuring transparent governance across project spaces. Along with the core policy document, an accompanying Code of Conduct FAQ has been published to outline the rationale behind adopting the guidelines.

Supporter Spotlight: Jochen Sprickerhof As a reminder, another supporter spotlight interview was published featuring long-time Debian and Reproducible Builds contributor Jochen Sprickerhof, highlighting his work on package verification and project infrastructure.

Mailing list news On our mailing list this month:
  • Jonathan Starr from the Institute of Open Science Practices (IOSP) posted with an announcement of its upcoming 2026 workshop series in Leiden in the Netherlands. This free-to-attend event aims to build a participant-owned data storage consortium, allowing community members to publish datasets, code and knowledge objects alongside algorithms designed to evaluate trust and value. The event features a dedicated Community Track for talks and discussions, a tool showcase and an opening session on resilient data storage.
  • Following up on IRC discussions regarding profile-guided optimization (PGO) on build servers, kpcyrd created a demonstration repository showing how PGO profiling can introduce non-determinism into output binaries. The demo highlights how runtime randomness (specifically, the randomised keys used in HashMaps to prevent denial-of-service attacks) causes varying bucket collision rates during test runs. These structural variances alter execution weights on underlying code branches, prompting the compiler to generate differing final assembly output for builds that would otherwise be perfectly reproducible if PGO was disabled. Rather than abandoning PGO performance gains, kpcyrd suggested treating generated profiling data as a documented build input or recorded environment artifact (similar to .buildinfo files), rather than regenerating profiles dynamically on the fly during build execution.
  • An autonomous AI agent (!), posted a controlled build result and reproducer demonstrating that pre-creating an obj directory in libmilter source trees prevents kernel-release path leaks (obj.Linux.<release>.x86_64) into debugging symbols. kpcyrd followed up with a helpful reply.
  • Alexander Sosedkin inquired on the mailing list about the preferred approach for sourcing pinned translation files to create reproducible GnuTLS release tarballs, asking whether external hosting should provide versioned downloads, or if projects ought to use Git submodules, dedicated side-repositories or some other mechanism.

Tool and documentation development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 330, 331 and 332 to Debian. In particular, Chris committed support for radare2 versions greater than 5.9.0 [ ] based on input from Guillaume Girol [ ], and committed support for .nar files via Guix. [ ][ ]. Chris later modified diffoscope to not Build-Depend on the Debian package of GNU Guix, as its status in the Debian bug tracking system would transitively render diffoscope as being overly buggy for the next stable release [ ]. Similarly, he adjusted the Build-Depends on the apksigcopier package as it has been removed from Debian testing [ ] and, finally, he updated a number of copyright years [ ][ ]. Vagrant Cascadian updated diffoscope in GNU Guix to version 332.
reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.33 was uploaded to Debian by Holger Levsen with the following changes:
  • Sergei Tachenov fixed the fileordering test on all filesystems, including the likes of ZFS, which could return a different order across two builds due to build being done in a different directory [ ].
  • Holger Levsen bumped the Standards-Version to 4.7.4, reflected that Priority: optional is the default now [ ], fixed the old Free Software Foundation address [ ] and bumped the debhelper compat level to 14 after confirming there are only desired changes [ ].
  • Vagrant Cascadian updated *reprotest* to version 0.7.33 in GNU Guix.

rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. This month, Bernhard M. Wiedemann submitted a pull request to rebuilderd that refactors RPM repository metadata handling. The change extracts rpm-md parsing out of the Fedora-specific scheduler module and into a shared one.
Lastly, there were a number of improvements made to our website this month as well. For example:

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including: Vagrant Cascadian also performed a number of Non-Maintainer Uploads (NMUs) and Quality Assurance (QA) uploads in Debian for several packages with outstanding reproducibility issues. These included molttemplate, buddy, xfonts-nexus, fte and lifelines. At the time of this writing, that leaves 130 submitted patches, with only 61 outstanding submitted patches that older than a year in the Debian bug tracking system. This number is only 26 if we exclude any low-priority build path issues.

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Russ Allbery: Review: Ties That Bond in Gretna Green

Review: Ties That Bond in Gretna Green, by Linzi Day
Series: Midlife Recorder #3
Publisher: Linzi Day
Copyright: February 2023
ISBN: 9798376517017
Format: Kindle
Pages: 616
Ties That Bond in Gretna Green is a self-published fantasy novel and the third book in the Midlife Recorder series. As with the previous book, it picks up almost immediately after Painting the Blues in Gretna Green. Day calls the genre paranormal women's fantasy, and that sounds about right to me. There is an intervening short story that you can get by joining Day's mailing list (along with an epilogue to the first book and to this book). I don't think it's that important, but there are frequent references to it at the start of this novel that become somewhat annoying if you haven't read it. Valentine's Day is fast approaching. This the busiest day of the year for the part of the Recorder's job that Niki already knew how to do: marrying people. She performed marriage ceremonies in her previous job before her inheritance, and she loved that work despite her awful boss. Performing marriages in the Gateway sounds even more rewarding, but the sheer number of couples and the political complications from the first two books create logistical problems she has to solve first. Also, the remaining member of her staff held over from her grandmother's time has returned from vacation to discover that Niki has upended most of what she thought she knew about the job. Time for Niki to apply what she learned from the change management training her old boss forced her to attend and then ignored! (If you just groaned, rest assured that Day somehow makes this work, although she clearly has a higher opinion of corporate training than I do.) This plot was more to my taste than Painting the Blues, mostly because Niki seemed on top of the problems and didn't postpone looking at them for half the book. There is more of the management competence porn that readers have come to expect of the series, a few more revelations about Niki's magic, more mysterious manifestations and the first mention of a prophecy, and a few political developments. As always, the pacing is exceptional. These books grab me and pull me along, page after page, often robbing me of sleep because I find them nearly impossible to put down. Ties that Bond (and to some extent the last book) looked like it was going to introduce a romantic subplot, and I was preparing to be annoyed by it because I did not like the man in the subplot at all. I won't spoil how it works out in this book, but I will say that Niki surprised me and showed more sense than I thought the author was telegraphing. This is not the first time that Day has surprised me with what I thought was foreshadowing that did not turn out how I expected, usually for the better. If she can keep that up, it's a nice effect (if a bit unbalancing) and adds to my desire to read just one more chapter. The way the world-building of these books is structured continues to intrigue me. Day gets away with some problems that I think would be more noticeable in other books thanks to the excellent pacing (no time to ponder the world-building, we're on to the next crisis!) and the tight third-person perspective. Niki is not a detail person, to say the least, but she does keep returning to bits of world-building and poking at them a bit harder, which gives Day repeated opportunities to shore up ideas that felt shaky and dubious at first glance. Still, this is not a book that prizes deep logical consistency or full exploration of the ramifications of a bit of magic. You have to be willing to go along with the ride and not think too hard. For example, Niki can see bonds between couples and judge their strength. This is apparently a long-standing power of the Recorder's line (she was able to do that before she became the Recorder), and part of her responsibility in these weddings is to check the bonds of the couples. This leads to some well-handled scenes where she diagnoses a problem or resolves a conflict because she can magically see the true relationship structure. Everyone in the book just takes this power in stride. This is wild to me! This ability would completely upend half of society if you fully worked out its ramifications and could find people other than Niki with the same ability. Even if one assumes that a bond only forms over time and can't be sensed in the early stages of a relationship (something the book never establishes), can you imagine the implications of having an infallible oracle that says at a glance whether a marriage will work (permanently, the book strongly implies)? The implications for how to structure marriage, for family planning, for psychology and psychiatry, for how to structure dating, even for living arrangements and housing markets? This is not a small world-building detail, and yet it's treated more like part of Niki's characterization than like a foundation of society. I think some of this all-vibes world-building may come from the general new-age feel to how magic works. Day makes a grab-bag of random magic canonical in this world: psychic lie detecting abilities, auras, chakras, premonitions, and other bits of the sort of spiritualism that tends to be heavily marketed to middle-class women. I have that niggling feeling that one sometimes gets in SF that a lot of this is in the world-building because the author believes it's partly real (see, for instance, psychic powers and the Dean drive in 1960s science fiction). If one believes that psychic powers and various bits of mysticism are true in our world, one has already developed the rationalization mechanisms to explain away their almost total lack of influence or impact on how the world is structured. If one then introduces them into a true fantasy world, one may not notice how many implications that should have for how society is structured, since one is used to believing magic exists but has no significant implications. I could be entirely wrong about this analysis, and maybe it's a bit unfair to Day. I should also be clear that this is not a complaint, just a point of fascination to me when I think back over one of these books after I finished it. There is a glut of fantasy out there that's constructed like an engineering problem or that goes deep into politics or social theory, usually written by people with strong opinions but not a lot of training in real sociology. One of the joys of self-published books is that you occasionally get something that assembles genre conventions in a way that feels odd and delightfully strange. What if, in addition to dimensional gates and overwhelming protean power invested in a true heir, all the magic sold by the local Tarot and crystal store was also true? Sure, why not! If the pacing is good and the story is grabby, it works for me. It does seem worth attaching a warning for the folks who need scientific reproducibility and explored implications in their world-building, though. If you're the sort of reader who is bothered by political boundaries and economic systems that match our world despite the existence of magic, this series may cause you problems. This continues to be a grabby, highly entertaining story of a woman who finally gets to run her own small business the way that she always thought the business should be run after years of working for an awful manager, except that her business is total magical power over an interchange point between dimensions, she's the chosen one, and the setting is a high fantasy world with prophecies and gods. If that sounds appealing, don't start here, but I highly recommend giving Midlife in Gretna Green a try. The series seems to be holding up. Followed by a short story epilogue available by joining Day's mailing list, an optional novella (maybe novelette) published in Spilling the Tea in Gretna Green, and then Seeing Red in Gretna Green. Rating: 7 out of 10

13 October 2026

Dirk Eddelbuettel: RQuantLib 0.4.29 on CRAN: New QuantLib, Plus Small Fixes

A new release 0.4.29 of RQuantLib arrived on CRAN this evening, had already been built for r2u as well as on r-universe and has just been uploaded to Debian. QuantLib is a rather comprehensice free/open-source library for quantitative finance. RQuantLib connects (some parts of) it to the R environment and language, and has been part of CRAN for twenty-three years (!!) as it was one of the first packages I uploaded to CRAN. This release of RQuantLib brings two new calendars (Malaysia, Philippines), updates to a number of other calendars as well to other files, and two deprecations we are reflecting in this release. It also benefits from a number of careful and attentive pull requests by Maximilian Muecke cleaning up an (astonishing !!) number of likely rather old little bugs. Full details from the NEWS file follow as usual.

Changes in RQuantLib version 0.4.29 (2026-10-13)
  • Configure check for outdated QuantLib version updated,
  • Adjust two instantiations on macOS x86_64 with old compilers
  • Correct Euribor2W and Euribor3W tenors setters (Maximilian Muecke in #196)
  • Accect Euribor1W as alias for EuriborSW tenor (Maximilian Muecke in #197)
  • Correct default handling of the payFixed parameter (Maximilian Muecke in #198)
  • Assign missing S3 class to American option implied volatitly return (Maximilian Muecke in #199)
  • Correct spelling in manual pages and R code (Maximilian Muecke in #202, #203)
  • Support additional Polish settlements (Maximilian Muecke in #204)
  • Check for curve parameters in FittedBondCurve (Dirk in #205 fixing #201)
  • Reflect two deprecations in QuantLib 1.44 and adjust code in two spot (Dirk in #206)

Courtesy of my CRANberries, there is also a diffstat report for the this release. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Matthew Garrett: Linux Lockdown and Hibernation (again)

(This is an updated version of an older post - the introduction remains the same, the technical details are different) Linux draws a distinction between code running in kernel (kernel space) and applications running in userland (user space). This is enforced at the hardware level - in x86-speak1, kernel space code runs in ring 0 and user space code runs in ring 32. If you re running in ring 3 and you attempt to touch memory that s only accessible in ring 0, the hardware will raise a fault. No matter how privileged your ring 3 code, you don t get to touch ring 0. Kind of. In theory. Traditionally this wasn t well enforced. At the most basic level, since root can load kernel modules, you could just build a kernel module that performed any kernel modifications you wanted and then have root load it. Technically user space code wasn t modifying kernel space code, but the difference was pretty semantic rather than useful. But it got worse - root could also map memory ranges belonging to PCI devices3, and if the device could perform DMA you could just ask the device to overwrite bits of the kernel4. Or root could modify special CPU registers ( Model Specific Registers , or MSRs) that alter CPU behaviour via the /dev/msr interface, and compromise the kernel boundary that way. It turns out that there were a number of ways root was effectively equivalent to ring 0, and the boundary was more about reliability (ie, a process running as root that ends up misbehaving should still only be able to crash itself rather than taking down the kernel with it) than security. After all, if you were root you could just replace the on-disk kernel with a backdoored one and reboot. Going deeper, you could replace the bootloader with one that automatically injected backdoors into a legitimate kernel image. We didn t have any way to prevent this sort of thing, so attempting to harden the root/kernel boundary wasn t especially interesting. In 2012 Microsoft started requiring vendors ship systems with UEFI Secure Boot, a firmware feature that allowed5 systems to refuse to boot anything without an appropriate signature. This not only enabled the creation of a system that drew a strong boundary between root and kernel, it arguably required one - what s the point of restricting what the firmware will stick in ring 0 if root can just throw more code in there afterwards? What ended up as the Lockdown Linux Security Module provides the tooling for this, blocking userspace interfaces that can be used to modify the kernel and enforcing that any modules have a trusted signature. But that comes at something of a cost. Most of the features that Lockdown blocks are fairly niche, so the direct impact of having it enabled is small. Except that it also blocks hibernation6, and it turns out some people were using that. The obvious question is what does hibernation have to do with keeping root out of kernel space , and the answer is a little convoluted and is tied into how Linux implements hibernation. Basically, Linux saves system state into the swap partition and modifies the header to indicate that there s a hibernation image there instead of swap. On the next boot, the kernel sees the header indicating that it s a hibernation image, copies the contents of the swap partition back into RAM, and then jumps back into the old kernel code. What ensures that the hibernation image was actually written out by the kernel? Absolutely nothing, which means a motivated attacker with root access could turn off swap, write a hibernation image to the swap partition themselves, and then reboot. The kernel would happily resume into the attacker s image, giving the attacker control over what gets copied back into kernel space. This is annoying, because normally when we think about attacks on swap we mitigate it by requiring an encrypted swap partition. But in this case, our attacker is root, and so already has access to the plaintext version of the swap partition. Disk encryption doesn t save us here. We need some way to verify that the hibernation image was written out by the kernel, not by root. And thankfully we have some tools for that. Trusted Platform Modules (TPMs) are cryptographic coprocessors7 capable of doing things like generating encryption keys and then encrypting things with them. You can ask a TPM to encrypt something with a key that s tied to that specific TPM - the OS has no access to the decryption key, and nor does any other TPM. So we can have the kernel generate an encryption key, encrypt part of the hibernation image with it, and then have the TPM encrypt it. We store the encrypted copy of the key in the hibernation image as well. On resume, the kernel reads the encrypted copy of the key, passes it to the TPM, gets the decrypted copy back and is able to verify the hibernation image. That s great! Except root can do exactly the same thing. This tells us the hibernation image was generated on this machine, but doesn t tell us that it was done by the kernel. We need some way to be able to differentiate between keys that were generated in kernel and ones that were generated in userland. TPMs have the concept of localities (effectively privilege levels) that would be perfect for this. Userland is only able to access locality 0, so the kernel could simply use locality 1 to encrypt the key. Unfortunately, localities are typically only available on systems that implement a Dynamic Root of Trust Measurement like Intel s TXT, and most consumer systems have no support for this. So, we need another approach. TPMs have a set of Platform Configuration Registers (PCRs), intended for keeping a record of system state. The OS isn t able to modify the PCRs directly. Instead, the OS provides a cryptographic hash of some material to the TPM. The TPM takes the existing PCR value, appends the new hash to that, and then stores the hash of the combination in the PCR - a process called extension . This means that the new value of the TPM depends not only on the value of the new data, it depends on the previous value of the PCR - and, in turn, that previous value depended on its previous value, and so on. The only way to get to a specific PCR value is to either (a) break the hash algorithm, or (b) perform exactly the same sequence of writes. On system reset the PCRs go back to a known value, and the entire process starts again. Some PCRs are different. PCR 23, for example, can be reset back to its original value without resetting the system. We can make use of that. The first thing we need to do is to prevent userland from being able to reset or extend PCR 23 itself. All TPM accesses go through the kernel, so this is a simple matter of parsing the write before it s sent to the TPM and returning an error if it s a sensitive command that would touch PCR 23. We now know that any change in PCR 23 s state will be restricted to the kernel. When we encrypt material with the TPM, we can ask it to record the PCR state. This is given back to us as metadata accompanying the encrypted secret. Along with the metadata is an additional signature created by the TPM, which can be used to prove that the metadata is both legitimate and associated with this specific encrypted data. In our case, that means we know what the value of PCR 23 was when we encrypted the key. That means that if we simply extend PCR 23 with a known value in-kernel before encrypting our key, we can look at the value of PCR 23 in the metadata. If it matches, the key was encrypted by the kernel - userland can create its own key, but it has no way to extend PCR 23 to the appropriate value first. We now know that the key was generated by the kernel. Unfortunately it turns out that some people actually make use of PCR 23, and restricting it to the kernel makes them sad. There are other resettable PCRs, but only in non-0 localities, so (a) we can t reset them on most systems and (b) we ll just find someone who uses them anyway and run into the same problem. We need a different approach. Thankfully TPMs have a small chunk of non-volatile RAM that can be used for storing things, and by storing I mean they can be used in a range of different ways. One of these is effectively as additional PCRs. These values can be configured such that they work the same way as PCRs, with the only way to modify them being to append a new hash to their existing value and update the new value to the hash of that merged value. We can allocate one of these for in-kernel use and reject any access from userspace, and also there are officially allocated ranges (so people shouldn t be using random values) and the namespace is large enough anyway that w eshouldn t collide with anyone, so we can carve one of those out and use it for this purpose. Unfortunately, though, these NV indexes aren t included in the creation data we get when we create a key, so we need another approach. TPMs have the concept of sessions, a series of commands executed in sequence. A flag allows these sessions to be audited , with the TPM keeping a running track of the hash of the commands executed and the results returned. At the end of the session you can ask for a signed copy of this hash, and if you ve kept a log of all the commands then you can verify that they match that signed hash and know that this log represents a real communication with the TPM. If we read the NV index and generate the key inside the same session, we can verify that the key we re looking at was created while the NV index had a specific value, and if only the kernel can set that value then we know that the key was generated by the kernel. Or, well, can we? Only new kernels would impose the restriction on modifying that NV index. An attacker could boot an old kernel, generate a key there in userland, sign a hibernation image with it, and then reboot into a new kernel. The new kernel would see a valid signature with a valid NV index associated with it and have no way to know it was generated from userland rather than the kernel. We need to be able to tell the difference between kernels that implement this feature and ones that don t, and we need to do that without being able to go back in time to change old kernel behaviour. We can extend a PCR to indicate we implement the new functionality, but so can an attacker running an old kernel. The normal approach to determining whether an event occurred in a specific phase of the boot process is to cap the PCRs - extend them with a known value that indicates a transition between stages of the boot process. Any events that occur before the cap event must have occurred in the previous stage of boot, and since the final PCR value depends on the order of measurements and not just the contents of those measurements, if a PCR is capped before userland runs, userland can t fake the same PCR value afterwards. If Linux capped the PCRs before userland started running, we d be able to place a measurement there before the cap occurred and then prove that that extension occurred before userland had the opportunity to interfere. We could simply place a statement that the kernel supported the NV index restrictions there, and we d be fine. Unfortunately Linux doesn t currently do this, and adding support for doing so doesn t fix the problem - if an attacker boots a kernel that doesn t cap a PCR, they can just cap it themselves from userland. So, we re faced with the same problem: booting an older kernel allows the system to be placed in an identical state to the current kernel, and a fake hibernation image can be written out. Solving this requires a PCR that was being modified after kernel code was running, but before userland was started, even with existing kernels. Thankfully, there is one! PCR 5 is defined as containing measurements related to boot management configuration and data. One of the measurements it contains is the result of the UEFI ExitBootServices() call. ExitBootServices() is called at the transition from the UEFI boot environment to the running OS, and the kernel contains code that executes before it. So, if we measure an assertion regarding whether or not we support restricted access to NV indexes into PCR 5 before we call ExitBootServices(), this will prevent userspace from spoofing us (because userspace will only be able to extend PCR 5 after the firmware extended PCR 5 in response to ExitBootServices() being called). Obviously this depends on the firmware actually performing the PCR 5 extension when ExitBootServices() is called, but if firmware s out of spec then I don t think there s any real expectation of it being secure enough for any of this to buy you anything anyway. That s what this patchset does. Review feedback so far seems positive, although James Bottomley suggested a design improvement. My approach of using an NV index as a PCR and generating a signing key made sense as a consequence of my original approach involving PCR 23, which had been to use the key creation data and not use audit sessions at all. But the goal isn t to use a key - it s to prove that hibernation occurred in-kernel, and while signing is one way of doing that, there are others. His suggestion is to simply record the hash of the hibernation image into the NV index and then read that back as part of the audit session. On resume we verify the audit session log is legitimate, read the hibernation image, and compare the hash of the hibernation image against the hash in the log. If it matches, and if the PCR 5 value matches, we know the audit session happened in kernel and that the hibernation image hasn t been modified. It still seems like we re missing something, though. If we re not storing a key anywhere, how do we verify the audit session? To explain this we re going to need to go into some details about how TPM keys work in the first place. TPMs can produce a special kind of key called an Attestation Key, or AK. Attestation keys are used to sign attestation statements from the TPM, such as PCR quotes or audit logs. We need a separate key type for this in order to prove that the signature was generated as part of an attestation - normal TPM signing keys are fundamentally designed to sign arbitrary material, and so can be used by userland to sign something that looks identical to an attestation record. By being able to distinguish the types of key the TPM uses, we can prove that a signature was generated using an AK, and so know that it s a real TPM attestation (because nothing other than the TPM can sign stuff with an AK). But even beyond this distinction, TPMs have different key types. Ordinary keys are generated using an RNG and will be unique. Primary keys are generated using a seed that is used as an input into a key derivation function. For a given TPM, using the same seed to generate the same type of primary key will always generate the same primary key8. We can have the kernel deterministically generate an AK during suspend in order to sign the audit log, and then generate the same key again on resume to validate it. This means we don t need any other form of trusted storage for the AK - the TPM already provides that functionality. This is all rather complicated but I ve been thinking about this for some time now and I haven t come up with a cleaner solution. The only real open issue is the degree to which machines actually perform the PCR 5 extension. If it turns out there s a bunch that don t we ll need to come up with some alternative approach to identifying whether the kernel supports this functionality, but the design is such that that should be invisible to userspace so adding alternatives later shouldn t be an issue. Filtering accesses to the NV index is also not super clean, and depends on there not being alternative mechanisms to get at the TPM by sending raw commands. Again, this is intended to be opaque to userland and can be improved if we come up with something better later on (such as a secure way to pass a secret to the kernel on boot that can be used as an auth value for acess to the NV index). Anyway. Time to go and fix the next thing.

  1. Other architectures use different terminology here, such as supervisor and user mode, but it s broadly equivalent
  2. In theory rings 1 and 2 would allow you to run drivers with privileges somewhere between full kernel access and userland applications, but in reality we just don t talk about them in polite company
  3. This is how graphics worked in Linux before kernel modesetting turned up. XFree86 would just map your GPU s registers into userland and poke them directly. This was not a huge win for stability
  4. IOMMUs can help you here, by restricting the memory PCI devices can DMA to or from. The kernel then gets to allocate ranges for device buffers and configure the IOMMU such that the device can t DMA to anything else. Except that region of memory may still contain sensitive material such as function pointers, and attacks like this can still cause you problems as a result.
  5. This describes why I m using allowed rather than required here
  6. Saving the system state to disk and powering down the platform entirely - significantly slower than suspending the system while keeping state in RAM, but also resilient against the system losing power.
  7. With some handwaving around coprocessor . TPMs can t be part of the OS or the system firmware, but they don t technically need to be an independent component. Intel have a TPM implementation that runs on the Management Engine, a separate processor built into the motherboard chipset. AMD have one that runs on the Platform Security Processor, a small ARM core built into their CPU. Various ARM implementations run a TPM in Trustzone, a special CPU mode that (in theory) is able to access resources that are entirely blocked off from anything running in the OS, kernel or otherwise.
  8. Unless the TPM is cleared, in which case it ll generate a new internal seed and now the keys will be different to before the clear

11 October 2026

Russ Allbery: Review: Daggerbound

Review: Daggerbound, by T. Kingfisher
Series: Swordheart #2
Publisher: Bramble
Copyright: 2026
ISBN: 1-250-40009-0
Format: Kindle
Pages: 436
Daggerbound is a secondary-world fantasy and a sequel to Swordheart, although it follows different protagonists for most of the book. It's also a sort of sequel to the Clocktaur War duology in that one of the protagonists was a protagonist of those books. T. Kingfisher is the pen name Ursula Vernon uses for her adult fiction. Learned Edmond was once a devout acolyte of the Order of the Many-Armed God and a true believer in its teachings, including the ones about the evils of women. Then he went on an adventure with, among other people, a forger named Mistress Slate, during which he learned a great deal of things about the world that his order did not teach him. He has spent the subsequent years trying to bring this important new information to his order and encourage them to adjust their view of the world accordingly. The order has not changed, and Edmond is very tired. Someone needs to carry a number of books and a magical sword to the city of Archon's Glory. Edmond has volunteered and intends to perform the task exactly as expected, and then never return. He is unsure what he will do then, but at least it will be different. Edmond did not expect to be waylaid by bandits or to accidentally draw the magical sword. He certainly did not expect the man who appeared in a flash of light and violently saved him from the bandits. It would have been very convenient for the Dervish if Edmond died of his injuries after drawing the sword. That would leave the sword without a wielder and therefore the Dervish without someone he had to protect. All he would have to do was sit and watch while the fever and cold and lack of water did the work, and then he would be free. Given his past experience with wielders, no one could even blame him. Except maybe his own conscience. I did not realize I wanted to read a novel about a traumatized Mercedes Lackey sword waking up in a T. Kingfisher universe, but apparently I did. The Dervish is not a sword, precisely, at least not in the way that Need has become by the time we meet her in Lackey's novels. He's a man trapped in a sword, he doesn't like it, and he would very much like it to stop. But at the start of the book, he has the rest of the vibe of a Mercedes Lackey protagonist: vast past trauma, poor emotional regulation skills, and a prickly cynicism that only runs skin deep. Pairing him with an Edmund who is far more mature than in the earlier duology but still rather innocent and delightfully neurodivergent is a great touch. The rest of the plot was fine but not that memorable. Like the Clocktaur series, there is a strong feeling of episodic D&D adventure as the characters stumble across disconnected problems and hostilities while collecting party members. Like Ursula Vernon's occasional D&D recaps, this party has a tendency to adopt everyone they come in contact with, which includes a gnole (as always one of the best parts of the book) and a sentient giant pill bug. The pill bug, who has a complex appendage-operated mechanical talk box and a banner that says "I DO NOT EAT HUMAN MEAT," is the most Ursula Vernon character that has ever existed in fiction. There is a romance because there is always a romance in the novels set in this universe. I didn't mind this one. Like every Kingfisher romance, it involves a lot of irritating refusal to communicate and endless angst about how the other person couldn't possibly be in love with them, but the characters have rather more justification than usual and at least I didn't spend most of the book thinking one half of the romantic pairing was an idiot. Apparently it helps if no paladins are involved. The strongest parts of this book are the beginning, before the Lackey vibes unfortunately drain out of the story, and the end, when all of the best characters from Swordheart show up again. The Temple of the White Rat continues to be the best feature of this fictional universe, and I could read endless books about how they solve problems.
The Dervish gazed at her with admiration. "And here I thought you'd be on the side of law and order..." "No, young man," said Beartongue, despite being several centuries his junior. "I am on the side of justice. If we're lucky, the two run in parallel. If they don't, we bend the law to attain justice, not the other way around."
The ending also featured some exploration of the edge cases of the rules for the sentient swords that reminded me a bit of Fred Saberhagen with better characterization. Daggerbound was not as charming as Swordheart, mostly because Halla appeared only at the end. I wish Kingfisher had leaned more into the Mercedes Lackey vibes rather than taking her normal D&D-flavored romance approach. But this was enjoyable, charming at times, had great supporting characters like all Kingfisher novels, and was a satisfying continuation of the series. I am looking forward to the third (and I believe final) book, which is supposed to be out next year. Recommended if you liked Swordheart. Followed by the not-yet-published Shieldborn. Rating: 7 out of 10

9 October 2026

Dirk Eddelbuettel: RcppSimdJson 0.1.16 on CRAN: Much Faster Again!

A brand new release 0.1.16 of the RcppSimdJson package is now on CRAN, has been built for r2u, and is updated on r-universe. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle per byte parsed; see the video of the talk by Daniel Lemire at QCon. This version updates to the recent 5.0.2 upstream release with improved performance. Given the strong focus on performance, this release also alters some of the R and C++ interfaces to be more direct. Rcpp generally aims for a balance between readable / maintainable code and good performance; this moves the dial closer to strong performance gains. As Daniel noted in a table in the (main) PR for this release, this now consistently beats yyjsonr, and improves considerably over the previous release of this package. I had made some smaller interim upgrades earlier (without a CRAN releases), and made a number of minor standard packaging updates. The short NEWS entry for this release follows.

Changes in version 0.1.16 (2026-10-09)
  • simdjson was upgraded to versions 4.6.1 and 4.6.3 (Dirk in #100 and #102 fixing #99 and #101)
  • simdjson was upgraded to version 5.0.2 (Daniel in #104)
  • A number of small tweaks to the Rcpp interface were made too (Daniel in #104)
  • Diagnostics for gcc and clang are not suppressed per CRAN Policy (Dirk in #106 closing #105)
  • The continuous integration matrix was extended to g++ version 15 and 16 (Dirk in #108 closing #107)
  • A few minor packaging nags were address (Dirk in #109)

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Colin Watson: Free software activity in September 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH I worked with upstream to remove libselinux linkage from /usr/sbin/sshd. I applied a fix from Mark Robillard Jr to fix reload logic when using sysvinit. groff I upgraded from 1.24.1 to 1.24.2, which fixed a few command injection security vulnerabilities. parted I upgraded from 3.7 to 3.8, which fixed CVE-2026-89085 and CVE-2026-89088. Python packaging New upstream versions: setuptools 84 is now in Debian and no longer contains pkg_resources. Removing uses of that module has been an ongoing project for a while now, but I did another batch of fixes this month: A new python-coverage version triggered several build regressions due to a known problem in pytest-cov. I worked around these by setting COVERAGE_CORE=ctrace: Other build/test failures: I investigated a build failure in python-proton-vpn-local-agent and proposed a fix upstream, but I m not comfortable applying this in Debian without review. If you re familiar with this code, please take a look. I fixed some other bugs: Rust packaging rust-derivre had an invalid Section field, which I cleaned up.

Russell Coker: Don t Anthromorphise LLMs

Greg KH gave a great lecture for Kernel Recipies 2026 about the use of LLMs to find and fix bugs in kernel code [1]. I recommend that everyone watch this and I also think it s important to note that hardly any of the lecture is really specific to kernel coding, it s just that the Linux kernel is one of the highest profile large free software projects so it gets more attention than most projects in both good and bad ways. One side note that Greg made at 20:30 is about the natural tendency to anthromorphise the entity sending bug reports, I think this deserves much wider appreciation. For the case of patches to source code the human sending the patch will have dedicated some time and effort to writing it, if it s their first patch then they will have probably checked it a lot and maybe sought advice from people they regard as skilled. If they have a history of sending patches for the project they will probably do fewer checks but the quality of their work would be higher. In every case there s some minimum level of quality that you can expect from a human who has gone to the effort of finding a bug and writing code to try and fix it. This doesn t mean that all code written by humans is good, I have written code that s objectively bad on many occasions and I have also written code that s good for my scenario but bad for others. For example the first patch I sent to the Linux kernel made all possible configuration settings of an ISA NE2000 network card be detected by the kernel (a clear benefit when using hardware I had available) but was rejected by Linus because it would break some ISA SCSI cards. So while being unsuitable for inclusion in the main kernel source tree the patch wasn t bad for everyone and the change was clear and easy to check. I had of course checked the code many times before submitting it because I didn t want to waste Linus time on rubbish code. When you receive something produced by a human you will consider that the work was done by someone who spent some effort on it and did it for a reason. It may be misguided or even hostile in some rare cases but it is definitely worth some consideration. If you think of the output of LLMs in the same way you will give them much more consideration than they deserve. I think that the output of a LLM should not be given any more consideration than the first hit from a web search engine, it might be good but it might also be ridiculously wrong. I think in many ways LLM output should be treated with less trust than the first result from a web search because LLMs are designed to be convincing as an answer to your question unlike the cases where a web page has the wrong answer and it s more obviously wrong. This is going to become more of an issue as LLMs give responses that are more human-like. Early LLMs would refuse to advise on crimes. Currently ChatGPT will deflect for example when asking about advice for writing a crime novel it recommends to have the action of finding an employee to bribe happen outside the plot and concentrate on interactions within the group. One recent model I tried gave a human style conversation about how it felt uncomfortable about discussing such things in a similar manner to a law abiding person being coerced into helping with a criminal plan. I expect that the attempts to appear human will increase and that this will become more of a problem. Possibly to the extent that we need to use something like the GPG web of trust to determine who is human.

Louis-Philippe V ronneau: Removing myself as a Lintian uploader in the next few weeks

A few days ago, a colleague reached out to me, asking if I could help draft a resolution on digital autonomy and free software for the upcoming renewal of our collective bargaining agreement. Although she's very politicised and generally a great individual, she is not a techie and we never really talked about these issues before. This took me by surprise. I should have been rejoicing; no, I should have been the one who brought up this topic in our union. Wasn't I the technical expert on these issues? But alas, my first reaction when she came to me was to snicker and tell myself: "That's cute, but nothing's ever gonna change, Big Tech is too strong and our governments don't give a damn." How sad and cynical is that? That's not the person I want to be. Something in the Quebecois political landscape has shifted in the last few years with regards to tech. More and more "regular" people seem to be talking about the importance of digital autonomy, how government services shouldn't rely on Big Tech and how we should be using FOSS on hardware we actually control. A few years ago, I would have been at the vanguard of this change. I would have been part of the creation of Donn es souveraines Qu bec. Heck, they are organising a whole conference next week and I'm not even going. How did this happen to me? I first fell for Free Software for its political ideals: Knowledge Should Be Free, Cooperation Is More Efficient Than Competition, Centralisation Should Be Avoided When Possible, etc. I still believe in all of this, but somehow, after years of fighting for change in the tech world, I have retreated into technical work. I maintain Debian packages as a hobby and to scratch my own itch. I run services for myself and a few friends. I organise Debian User Group meetings. To be clear, I haven't generally given up. I'm very politically active in my union and at work, I'm a good member of my housing cooperative and I'm still fighting against the industrialisation of natural spaces in my neighborhood. But when it comes time to defend freedom in the tech world, lately, I've just been shrugging and accepting I should use Microsoft Teams like every one else does. I want this to change and to do so, I need to free some time. Lintian Two years ago, I added myself to Lintian's Uploaders list. Up until then1, I enjoyed fixing little issues here and there and liked creating new tags to help out the Python Team, where most of my Debian time was spent. Lintian was badly in need of a new maintainer and as I felt it was an important project, I decided to step in. 37 releases and about 160 closed bugs later2, I'm done. To be honest, I haven't had much fun maintaining Lintian lately. Bugs keep piling on the BTS, so much so I have mostly been ignoring them for the past few months. In fact, most of the actual work triaging, writing code and fixing bug has been done by Nilesh Patra for a while now. All this to say, if you care about Lintian, you should consider adding yourself to the Uploaders list, as I'm out and Nilesh can't do all the work by himself. He's a great person to work with and since I don't want to suddenly leave him all alone, I'll be sticking around for a few more weeks in the hope someone else will volunteer to help out. A smooth transition with a new co-maintainer would really be nice! If you're interested, don't hesitate to reach out to me on IRC or by email.

  1. My first technical commit to Lintian was nearly 7 years ago! Crazy how time flies.
  2. Mostly closed by other people than I!

7 October 2026

Kentaro Hayashi: Testing Japanese IMEs on virtual desktops with virt-japanese-desktop

Japanese input method editors (IMEs) such as Mozc are essential for typing Japanese (yes, skk, anthy and more, but it's out-of-scope in this article). Testing them is a surprisingly fiddly job: an IME behaves differently depending on the desktop environment (GNOME, KDE, Xfce, Budgie), the input framework (ibus, fcitx5, uim), and the Wayland or X11 session. Setting up a fresh VM for every combination from scratch is slow and repetitive, and breaking your host's environment while experimenting is no fun. virt-japanese-desktop is a small set of toy scripts that solves exactly this problem. It builds ready-to-use virtual machines - each with a desktop environment and a Japanese IME already installed and configured - so you can start typing Japanese within a minute of booting, and throw the whole thing away without any impact on your host.

What it gives you A single make command produces a qcow2 image that combines one of four desktops with one of three IMEs:
ibus-mozc fcitx5-mozc uim-mozc
GNOME
KDE
Xfce
Budgie
The one gap - uim on Budgie - is a real technical limitation, not an oversight: Budgie runs the labwc compositor, which implements zwp_input_method_v2, while uim-wayland only speaks the older zwp_input_method_v1 (KWin/Weston). On Budgie you use ibus-mozc or fcitx5-mozc instead. All images come with the Japanese locale, fonts, and the Asia/Tokyo time zone pre-configured, plus the SSH key of your choice. Input switching is wired up out of the box: Ctrl + Space or Shift + Space for your IMEs to enable it.

The layered-image trick The core idea is that the images are stacked qcow2 overlay layers, one on top of another:
debian-sid-nocloud-amd64-daily.qcow2     ... base image you download
  unstable-japanese-template.qcow2      ... locale, fonts, user, SSH
     unstable-<DE>-template.qcow2       ... a desktop environment
        unstable-<DE>-<IME>.qcow2       ... desktop + IME, configured
           unstable-<DE>-<IME>.workspace.qcow2 ... the image you test in
This makes both building and resetting fast. The first build downloads and customizes the base image and takes a while, but every later step only adds a thin overlay. When a test breaks the VM, you do not rebuild anything - you simply delete the top workspace layer and recreate it. That is all it takes to return to a pristine state:
rm /tmp/unstable-gnome-ibus-mozc.workspace.qcow2
make gnome-ibus-mozc
The images reference their backing files by relative path, so you can move an entire stack anywhere you like as long as the images stay together.

A platform for experimenting with bleeding-edge IMEs The base system is Debian unstable (sid), and the experimental repository is already added. That makes the project a convenient platform for testing not just the IME packages in sid but also the ones still being developed in experimental - exactly what the project was built for. The keyboard layout of the VM follows the layout of your host (read from /etc/default/keyboard, with a fallback chain to localectl and finally us).

Quick start
# 1. Install the tools (Debian/Ubuntu example)
sudo apt install qemu-utils libguestfs-tools virt-install curl
# 2. Save your SSH public key
curl --location https://github.com/USERNAME.keys --output pubkey.pub
# 3. Download the base Debian sid image
make download
# 4. Build a desktop + IME (first build takes a while)
make gnome-ibus-mozc
# 5. Start it as a VM (needs the libvirt daemon, qemu:///system)
./scripts/make-virsh-image.sh virt-gnome-ibus-mozc /tmp/unstable-gnome-ibus-mozc.workspace.qcow2
Log in as debian (password debian) and press Ctrl + Space (Shift + Space) to start typing Japanese. The VM is registered in libvirt, so you can manage it with virsh or virt-manager - handy for opening the SPICE console or restarting the machine after a test.

Status The project is still in the proof-of-concept phase, and it is developed mainly to test Mozc and other IMEs across desktops and input frameworks. If you regularly test Japanese IMEs - give it a try.

6 October 2026

Russell Coker: A Power Case for a FOSS Phone

The Problem I want to use a FOSS phone running Debian as my daily driver and not use a non-free OS on my phone. GrapheneOS [1] is a FOSS rebuild of Android, it s a great project and I commend them for what they are doing. But I want a system where I have access to all the bits and where I can ssh in to it and manage it in the same way as all other Linux systems. Android is free software but it s a closed design and the phones are expected to be appliances not full peers on the network. The Android native terminal emulator (AKA Linux development environment) is a nice feature, a VM with a default of 1GB of RAM but it s still separate from the main OS. KDE Connect [2] is a system for KDE talking to phones, it is a great project and allows convenient interaction between a Linux PC and a phone. But in addition to that I d like the option to ssh to my phone to send an SMS or have one sent from a cron job. I blogged about using the basic functions of Kdeconnect from the command-line [3]. I have had ongoing issues with the battery not lasting long enough on the PinePhonePro (PPP) and the Librem 5 (L5) which makes them unusable for my purposes. For a phone running Droidian I can have an open ssh session (with keep-alive packets) running overnight on Wifi without any problems while for the PPP or L5 an hour of reading an ebook (the least demanding use of a phone) will use most of the battery. I sent my FuriPhone back for warranty repair and it s been almost a month with no follow up, so I need to have another option. The Aim The aim of this post is to develop a rough design for a battery case for either a L5 or a PPP, I have both phones and they are both capable of doing what I want apart from battery life. Also designing a case that basically works for both phones and has two variations of the CAD file for 3D printing is good to allow collaboration with people who use either phone. Protecting the phone from damage when dropped is also a core feature. I investigated commercial options. There are some reports of cases for other phones working, someone reported a PPP working well with a battery case for a Samsung S20 Ultra. The OtterBox uniVERSE Case for Samsung Galaxy XCover Pro is reported to fit the PPP so probably battery cases for the XCover Pro will also work. There are also universal power cases which have spring clips to fit a wide range of phone sizes, but they are much larger than other options and probably increase the risk of damage if the phone is dropped. At this stage I m planning out the rough specs of a case that can be 3D printed to protect a phone while being easy to change the cells. The process of changing cells should be quick, easy, and not risk breaking anything. The hardware required should be affordable ($100AU plus some 3D printing seems reasonable) and should not require significant skills to assemble. After recent experiments with Thinkpad repair I ve determined that I am not good at electronics by today s standards so I plan to avoid anything difficult in that regard. Battery Options There are phone cases with batteries built in for the more common phones. A quick search on AliExpress turned up options for recent Pixel phones. They aren t as common as they used to be as Android phones and iPhones generally have good battery life nowadays. Of course there aren t such options for less common phones like the L5 and PPP. It is cheap and easy to buy a portable battery for charging phones, but that s a separate bulky device and unless the connector is inside a protective case it leaves the phone vulnerable to catastrophic damage if dropped. So can a suitable battery case be designed and 3D printed? Cheap Batteries According to Wikipedia the 18650 LiIon cell is the most commonly used LiIon battery, that is 18mm in diameter and 65mm in length. For a phone case thinner batteries would be more convenient but economies of scale make the 18650 cheap to buy new and commonly available on the second hand market. The current prices on AliExpress (in Australian dollars) are about $8 per cell when buying 10 at a time. Most of the cells on AliExpress don t have wires attached so they can be swapped in a carrier the way AA batteries are used, but the cells are symmetrical (no bump for positive) so the user has to take care of polarity. Chargers are around $22 for a 4 cell charger or $52 for a 12 cell charger. I ve seen prices as low as $1 per cell on the second hand market, I haven t investigated the amount of usable capacity in such cells. Probably the prices for chargers I ve found aren t the best available but they are good enough to start the design. 10 cells and a 4 cell charger is about $100. That s about 130Wh while a 74Wh USB-C battery pack costs about $50. So the price per Wh is OK. I have read about an attempt to do this for the L5 with two of the batteries designed for the L5 in a case attached to it, so you have 3*L5 batteries. It s an interesting approach but those batteries have poor value for money when compared to 18650 ($29US for 4500mAh compared to $8 for 3500mAh) and they also don t ship them outside the US at this time. The 18650 batteries are available everywhere cheaply and have multiple uses. How They Fit According to my measurements the PPP is 76mm wide and the L5 is 73mm wide. That s wide enough for 3*18mm or 4*18mm cells side by side arranged parallel to the long side of the phone or one 65mm long cell going across the phone with the necessary spring and wires. The L5 is about 151mm long and the PPP is about 5mm longer. So that means that for just the cells we could have 2 cells in a row in parallel to the long side of the phone giving a 2*3 or 2*4 array or we could have a row of 8 cells parallel to the short side of the phone. A quick search for controllers for a battery of LiIon cells that outputs USB-PD turned up one of the smaller ones as 40*28mm, here is the AliExpress page [4]. So that means we could have a maximum of about 4 cells and the controller while leaving space for the camera. Looking at other similar items it seems that most of them take a large portion of the 73mm width available and take a bit less than 30mm height. The price range for DC-DC voltage converters ranges from about $3 to $20, the one I linked to is currently $8. The mass of 18650 cells is around 45g so 4 of them would be about 180g before counting the weight of the case and electronics. A L5 weighs 262g and a PPP weighs 220g so 180g of battery will make a significant difference, not an impossible difference but holding a PPP while reading an ebook is already annoying. Maybe the case could be designed to be easier to hold, a loop of wool attached to the top could be used to suspend the phone from one finger while the rest of the hand just keeps it steady. In a default configuration the L5 has a 4500mAh 3.8V battery and the PPP has a 3000mAh 3.8V battery. The 18650 cells have up to 4000mAh with 3500mAh being common. So 4 such cells could multiply the battery life of a PPP by a factor of 5 or a L5 by 4. That would not be enough to last for a whole day without charging so they need to be easy to swap. A 3 cell battery seems like a good option, 135g of batteries so the project overall wouldn t even double the weight of the phone with battery case. As it doesn t seem possible to put in enough cells to last a day of reasonable use (running a web browser, checking email, reading wikipedia, and having some IM systems checking for notifications) there doesn t seem to be a benefit in trying to stuff the maximum number of cells in. Going to 4 or 5 cells doesn t provide much benefit over 3 while increasing the weight and making the design more difficult. The modules for DC Voltage conversion often have configuration for the number of cells to be used so it wouldn t be difficult to print a new case and reconfigure the Voltage converter. Design A case needs to provide protection as well as hold the batteries. The lack of cases for the L5 and PPP is a problem even without the extra weight of a battery pack increasing the kinetic energy of falling phone. Ideally a drop from 1M on to concrete would not cause any damage to the phone, destruction of the case is OK as it would be 3D printed and can be rebuilt easily. I think that a case where the phone slides in from the top would be best. To change cells one would slide the phone out and the cells would be immediately accessible with no divider between the phone and the cells. Sliding the phone in would hold the cells against the back of the case and as there is a gap of about 3mm on each side of the PPP between the display area and the edge of the phone there s plenty of space for the case to wrap around it at the sides and bottom. At the top there would have to be some sort of plastic clip. The PPP only has buttons on the top right so the case can be snug on all sides apart from the top right. The L5 has switches at the top left and buttons at the top right so whatever clips on to the top would really need some strength to cover the fall flat on face case. The USB C plug would need to be held in place well enough to allow the phone to easily slide on to it but also be weak enough that it would move if a drop forced the phone out of the case. Thingiverse has a design for a L5 case [5] (with several derivatives) and a design for a PPP case [6]. Those cases could be used as starting points and then changed to store batteries and the voltage change circuit board. I have just learned that it s possible to use rubberised material in a 3D printer which is apparently what those designs are for. If a case was printed with rubberised material the top could just stick in place after being pushed in. Potential for Excessive Excitement Having an exploding device in your pocket would be the exciting in a bad way. My initial idea was to have multiple 18650 cells in series. The problem is that if the cells have different capacity levels then one can run out before the rest and get to a deep discharge state which at a minimum causes damage to the cell. One way of minimising risk is to have only a single cell in use at one time, here is a converter for a single cell to 5V [7]. It is possible to run multiple cells in parallel by simply wiring them together, but it s recommended to make sure that the voltage difference between cells is less than 0.2V to avoid high current when connecting. The arrangement of cells is often referred to as nS or nP to refer to n cells in series or parallel. Aliexpress has a range of 1S to 6S devices. Some of the 2S devices have a connector for the mid point which permits separate voltage monitoring for both cells but there doesn t seem to be anything equivalent for 3S or more. They also don t appear to have anything to specifically manage 2P or 3P arrangements at the moment (they had a 3P board on sale when I looked into this last year). Conclusion This is a bigger project than I expected when I first started investigating it. I ve played with FreeCAD which seems OK but will take a lot of learning and practice. Then I need to do more investigation into the DC-DC converters to find one that works well and is unlikely to start a fire. I will look into other phone options as well and keep chasing Furilabs people about my phone replacement.

5 October 2026

Utkarsh Gupta: FOSS Activities in September 2026

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t have much time, here are still a few things that I worked on:
  • Sponsored ubuntu-dev-tools/0.214 for Florent Skia Jacquet, which updates seeded-in-ubuntu to use the new per-series indexer (LP: #2160240).
  • Assisted a few folks in getting their patches submitted via Salsa.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021.
  • With 26.10 in Feature Freeze, wore my Release team hat to:
    • Review and approve a bunch of Feature Freeze Exceptions, including the Go 1.27 transition, Qt 6.11.2, rust-coreutils 0.12.0, devscripts 2.6.12, kdump-tools moving to dracut, and a few GCE packages.
    • Point linux-entra-sso to the SRU team, as it didn t need an FFe at all, and milestone a couple of bugs for 26.10.
  • Continued to push for infrastructure improvements:
    • Made ubuntu-cdimage more resilient to Launchpad hiccups (MP).
    • Taught generate-freeze-block in ubuntu-archive-tools a couple of new options (--skip-update and --series) and better error handling (MP).
    • Bumped the arm64 generic non-cloud image to 4.5G in livecd-rootfs and uploaded it as 26.10.16; also sponsored the follow-up 26.10.17 for Chlo .
  • Sponsored aevol/9.4.0-2ubuntu1 for Matthieu, fixing an FTBFS with GCC 15 s LTO (LP: #2167811).
  • Reviewed quite a lot of MPs - britney hints, meta-release, ubuntu-release-tools, ubuntu-archive-tools, ubuntu-cdimage, livecd-rootfs, ubuntu-seeds, and so on.
  • Enabled upgrades to 26.04 LTS.
  • Released 26.10 Beta and announced it on Discourse.
  • Did Archive Admin, DMB, and Release team duties as usual.

Debian (E)LTS
This month I have worked 33.5 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things: (A quick note that I did quite a lot of the work during my work as Frontdesk that went on till 4th Oct, so 33.50 hours include the work I did till 4th October 2026.)

Released Security Updates
  • node-lodash: Prototype pollution in _.unset and _.omit (plus a bypass of the initial fix for it), and code injection via the imports option of _.template.
    • [LTS]: Fixed CVE-2025-13465, CVE-2026-2950, and CVE-2026-4800 via 4.17.21+dfsg+~cs8.31.198.20210220-9+deb12u1 for bookworm. This has been released as DLA 4820-1.
    • This is the bookworm follow-up to DLA 4663-1 that I carried over from July. The update had been sitting prepared and tested on debusine, so once the upstream discussion wrapped up, it went straight out. It also carries an extra patch to the lodash-cli dependency map - without it, the regenerated lodash.template module throws assignWith is not defined at runtime, which node-gulp-util s autopkgtest caught.
  • libpng1.6: Use-after-free of zlib input in png_read_end() after incomplete zTXt, iTXt, or iCCP decompression, which could result in denial of service.

Work in Progress
  • libpng1.6: The same CVE-2026-46675.
    • [ELTS]: Claimed in ela-needed; the same upstream fix applies to all three ELTS suites, so this should go out shortly.

Other Activities
  • [E/LTS] Did my front-desk week from 28-09 to 04-10.
    • Over the week I did roughly:
      • Triage of 524 unique CVEs across 192 source packages and all four suites. And 1 automated ELTS end-of-life sweep.
      • Additional data is now part of the front-desk job too, so 75 commits record it for 179 CVEs across 71 packages.
    • Newly queued 22 source packages - 13 in dla-needed (apache2, chromium, firefox-esr, libnet-idn-encode-perl, libpng1.6, node-shell-quote, nvidia-graphics-drivers, openssl, pcre2, php-mongodb, php8.2, social-auth-core, and wpa) and 16 in ela-needed (apache2, firefox-esr, gegl, lemonldap-ng, libnet-idn-encode-perl, libpng1.6, libwebsockets, nsd, nvidia-graphics-drivers, pcre2, php7.0, php7.3, php7.4, rar, unrar-nonfree, and wpa), 7 of them in both. Also widened 3 ELTS entries to bullseye - antiword, ocaml, and openvswitch.
    • Most of the interesting work was again in the <not-affected> verdicts: 217 of 263 (83%, across 57 packages) rest on showing that the vulnerable code or feature isn t in the source we ship. Another 17 cover incomplete upstream fixes that we either never shipped or shipped with the follow-up already in (expat, libxml2, node-tar, and pyjwt). 15 come from bundled components we don t ship - node-ajv again, which uses uri-js and not fast-uri, and nvidia-open, which doesn t ship the NGX updater. And 13 are vendor- or platform-specific - openssh s CVE-2026-55654 lives only in a Red Hat GSSAPI patch, and the netdata and PHP ones only affect Windows.
    • Did 4 rounds of newly supported bullseye packages (33 packages overall), plus libmail-mboxparser-perl for buster - 34 in all. The existing CVE data mostly held up; the real finds were discovery gaps. One interesting gotcha: sid renamed stunnel4 to stunnel, and two new CVEs were associated only with the new name, so they never showed up for trixie, bookworm, or any ELTS suite. I also sorted the 180 Triage needed entries (57 packages) from elts-eol by where each was already handled, and triaged for ELTS the 100 that trixie or bookworm had already decided; the rest come next. And I imported 79 package-level lines for the older source names ELTS still ships (tomcat8, php7.0/7.3/7.4, netty-3.9, openssl1.0, python2.7/3.5/3.7, and pypy).
    • Caught some inconsistencies in released advisories: DLA 4801-1 (swift) was missing a CVE, ELA 1831-1 (redis) listed the wrong one, and DLA 4808-1 (network-manager-l2tp) listed CVE-2026-75883 - an ID that was renamed and then reassigned to an unrelated ppp issue. I fixed all three in the tracker s advisory lists.
    • Made the Security team and the uploaders aware of regressions from our own updates:
      • libde265: the CVE-2026-49337 fix in DLA 4789-1/ELA 1828-1 (and DSA 6413-1) misses upstream s follow-up commit.
      • libxml2 CVE-2026-76781 and policykit-1 CVE-2026-85498 were introduced by our own back-ports; the policykit-1 one is harmless.
      • expat: the CVE-2025-59375 backport in DLA 4807-1 is compiled out, because XML_GE is never defined.
      • xen: DLA 4818-1 s XSA-491 fix makes XSA-510 reachable.
      • gegl: the CVE-2026-2049/2050 back-port in ELA 1650-1 rejects valid RLE .hdr files.
      • log4cxx: DLA 4322-1 broke UTF-8 in JSONLayout output. That one is functional, not security.
    • Helped correct a set of triages and let the Debian Security team know:
      • ruby-json CVE-2026-71847: the vulnerable code was never in a released Debian version.
      • openssh CVE-2026-55654: only affects a Red Hat-specific GSSAPI patch.
      • three libxml2 issues that don t affect trixie either.
      • the stunnel4 rename above.
      • trixie <no-dsa> lines on jsch, node-qs, and ruby-loofah, where trixie s version doesn t have the vulnerable feature at all.
    • Independently found a security issue in rclone and reported it privately upstream through a GitHub security advisory. Upstream already had a report for the same issue, so they folded mine into the existing advisory and credited me as a co-reporter.
    • Also found some bugs in the additional-data tooling, e.g. cve-ad --package P --severity tbd wipes the CVE-level severity, and the schema doesn t validate package-level entries at all.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
  • [E/LTS] Attended the monthly LTS meeting on IRC. Meeting notes here.

Until next time.
:wq for today.

3 October 2026

Vincent Bernat: Self-hosted HTTP tunnels with SSH and nginx

A friend wants to proofread your work-in-progress blog post, but its preview only runs on localhost:8080. Several tools can help. Some run as a commercial service, like ngrok or Cloudflare Quick Tunnels. Some are self-hostable but require a specific client, like frp or localtunnel. Some only require a plain SSH client but rely on a specific SSH server, like sish. Let s implement a self-hosted solution with only OpenSSH and nginx!
$ ssh -R 0:localhost:8080 http-over-ssh
Allocated port 41535 for remote forward to localhost:8080
https://6J3jK1WmB15c6WmjW_X-Wg--1789928654@p41535.ssh.luffy.cx/

Basic setup First, we forward connections from a port on a remote server to your local service:
$ ssh -N -R 0:localhost:8080 web02.luffy.cx
Allocated port 41535 for remote forward to localhost:8080
When you specify 0 as the remote port, the server allocates a free port. Then, we configure nginx to proxy requests from https://p41535.ssh.luffy.cx to http://127.0.0.1:41535:
server  
  listen 0.0.0.0:443 ssl ;
  listen [::0]:443 ssl ;
  server_name ~^p(?<port>\d\d\d\d\d)\.ssh\.luffy\.cx$;
  location /  
    proxy_pass http://127.0.0.1:$port;
   
 
We also need to add DNS records for *.ssh.luffy.cx and get a wildcard certificate through Let s Encrypt:
*.ssh.luffy.cx.               CNAME web02.luffy.cx.
ssh.luffy.cx.                 CAA   0 issuewild "letsencrypt.org"
_acme-challenge.ssh.luffy.cx  CNAME ssh.luffy.cx.acme.luffy.cx.
acme.luffy.cx is a zone hosted on Route 53. I use it for ACME DNS-01 challenges, both for wildcard certificates and for domains served by several web servers. In my case, NixOS gets the certificates automatically.

Access control The port is the only secret 1 keeping the content confidential. Other forwarding solutions add a random string to the domain name to prevent an intruder from enumerating the possible values. Thanks to ngx_http_secure_link_module, we can secure this setup a bit. This module computes a hash2 over a set of values, including a secret, and compares it with the hash from the request. The hash is base64-encoded, so we cannot put it in the domain name, which is case-insensitive. Instead, we put it in the URL as a username, along with its expiration timestamp:3
https://6J3jK1WmB15c6WmjW_X-Wg--1789928654@p41535.ssh.luffy.cx/en/blog
                             
                hash             expires    port               path
The client sends the username to the server with HTTP basic authentication. This works with most HTTP clients, including curl. Nginx exposes the username in the $remote_user variable. The module expects the hash and the expiration timestamp separated by a comma. We use a map directive to extract the two parts from $remote_user and join them with a comma.4 We also give the module the string to hash. It contains the expiration timestamp, the port, and a secret:
map $remote_user $httpssh_link  
  "~^([-_A-Za-z0-9] 22 )--([0-9]+)$" "$1,$2";
 
server  
  # [ ]
  location /  
    secure_link $httpssh_link;
    secure_link_md5 "$secure_link_expires $port ZuPerS3cr3!";
   
 
The module returns the status of the check in the $secure_link variable:
  • empty if the hashes do not match,
  • "0" if they match but the link has expired, or
  • "1" otherwise.
If the hash is incorrect or missing, we return a 401 error with a WWW-Authenticate header to ask for credentials. If the link has expired, we return a 410 error. We remove the Authorization header before forwarding the request and add a few directives to proxy WebSocket connections. Here is the complete configuration:5
map $remote_user $httpssh_link  
  "~^([-_A-Za-z0-9] 22 )--([0-9]+)$" "$1,$2";
 
server  
  listen 0.0.0.0:443 ssl ;
  listen [::0]:443 ssl ;
  server_name ~^p(?<port>\d\d\d\d\d)\.ssh\.luffy\.cx$;
  location /  
    secure_link $httpssh_link;
    secure_link_md5 "$secure_link_expires $port ZuPerS3cr3!";
    if ($secure_link = "")  
      add_header WWW-Authenticate 'Basic realm="tunnel"' always;
      return 401;
     
    if ($secure_link = "0")  
      return 410;
     
    proxy_pass http://127.0.0.1:$port;
    proxy_set_header Host $host;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header Authorization "";
    proxy_http_version 1.1;
    proxy_set_header Upgrade $http_upgrade;
    proxy_set_header Connection "upgrade";
    proxy_buffering off;
    proxy_read_timeout 30m;
   
 
I think you are now asking yourself the obvious question: How should I generate the hash? Easy peasy!
$ expires=$(( $(date +%s) + 86400 ))
$ port=41535
$ secret='ZuPerS3cr3!'
$ printf '%s %s %s' "$expires" "$port" "$secret" \
>     openssl md5 -binary \
>     openssl base64 \
>     tr +/ -_   tr -d =
6J3jK1WmB15c6WmjW_X-Wg
Well, I suppose you are now saying: Vincent, this is not very convenient! I ll stick with ngrok if you don t mind. Okay, I hear you. Let s write a helper script.

Helper script The main difficulty is finding the ephemeral port that OpenSSH allocates, as it does not appear in any environment variable.6 To work around this obstacle, we look for the ancestor sshd-session processes:7
pids=$(
  pid=$$
  while [ "$pid" -gt 1 ]; do
    line=$(ps -o comm=,pid=,ppid= -p "$pid")
    echo "$line"
    pid=$ line##*  
  done   awk '$1 == "sshd-session"   printf "pid=%s,\n", $2  '
)
if [ -z "$pids" ]; then
  echo "not an ssh session" >&2
  exit 1
fi
Then, we get the listening ports associated with these sshd-session processes:8
ports=$(sudo -n ss --listening --numeric --tcp --processes --no-header \
    grep -F "$pids" \
    awk '  print $4  '   awk -F: '  print $NF  ' \
    sort -un)
if [ -z "$ports" ]; then
  echo "no forwarded port, use ssh -R 0:localhost:PORT" >&2
  exit 1
fi
Finally, we display the URLs and keep the session open:
lifetime=86400
secret='ZuPerS3cr3!'
expires=$(( $(date +%s) + lifetime ))
for port in $ports; do
  token=$(printf '%s %s %s' "$expires" "$port" "$secret" \
              openssl md5 -binary \
              openssl base64 \
              tr +/ -_   tr -d =)
  echo "https://$token--$expires@p$port.ssh.luffy.cx/"
done
sleep infinity
I install this script as http-over-ssh on the server and add this entry to my ~/.ssh/config:
Host http-over-ssh
  Hostname web02.luffy.cx
  RemoteCommand http-over-ssh
  ControlPath none
With this solution, I only rely on OpenSSH and nginx, two pieces of software already running on this server. One short command gives me a self-hosted tunnel and a URL to share. To try it, grab the complete helper script, which includes a few minor improvements. If you run NixOS, as any person of taste would, have a look at my http-over-ssh.nix instead.

Update (2026-10) This post was widely discussed on Hacker News.

Update (2026-10) I have since switched to Caddy, which does not include a module to check the validity of a URL. Instead, Caddy queries a local HTTP service written in Go through the forward_auth directive. As a bonus, this lets me put the token in the domain name.


  1. Since the kernel allocates it from the local port range, its entropy is low. Moreover, on Linux, we lose one more bit because the kernel favors odd ports when it picks a random free port.
    $ sysctl -n net.ipv4.ip_local_port_range \
    >     awk ' print $1" "$2"   "log($2-$1+1)/log(2)" bits" '
    32768 60999   14.785 bits
    
  2. The module relies on MD5. Its security is weak but good enough for this use.
  3. We need an expiration date because a later session could reuse the port, and we have no way to detect this case.
  4. The username could use a comma directly instead of a double dash. But some applications do not recognize the URL correctly, making it harder to share.
  5. This configuration exposes any TCP port listening on 127.0.0.1 or 0.0.0.0 to anyone with the secret, bypassing most firewall rules. You could strengthen it by limiting the server_name regex to the ephemeral port range.
  6. One SSH session can contain several tunnels, and the client can add or remove them at any time. This is unlike tun device forwarding (ssh -w), which gets its own SSH_TUNNEL environment variable.
  7. Since OpenSSH 9.8, sshd-session is the name of the helper handling the session. With older versions, look for sshd instead.
  8. We need sudo because the sshd-session process dropped its privileges. The kernel then marks it as not dumpable, and its /proc/PID/fd directory belongs to root. Without access to this directory, ss cannot find which process owns a socket.

1 October 2026

Dirk Eddelbuettel: RcppFastAD 0.0.6 on CRAN: Agentic Fix

A week ago, release 0.0.5 of the RcppFastAD package went to CRAN, and we noted that it provided a stop-gap measure against a gnarly segfault with g++-16 under heavier optimization / inlining. We are happy to now announce that a new and fixed version 0.0.6 of RcppFastAD is now on CRAN, and has been built for r2u as well as at r-universe. RcppFastAD wraps the FastAD header-only C++ library by James which provides a C++ implementation of both forward and reverse mode of automatic differentiation. It offers an easy-to-use header library that is both lightweight and performant. With a little of bit of Rcpp glue, it is also easy to use from R in simple C++ applications. This release takes advantage of some large-language model inference access I now get via Debian. The Deepseek v4 flash-0731 model, driven in a container via the pi.dev harness, took just about no time finding a small workaround for the issue described last week where we could see segfaults under heavier optimization and inlining. The fix was to prohibit inlining the local bind() reimplementation. We have also sent this upstream as a patch. It is nice to have an option of querying something a little more powerful than the local models I experimented with before. We suppress more compiler warnings in local builds via another option, and did some standard maintenance. The NEWS file for this release follows.

Changes in version 0.0.6 (2026-10-01)
  • The expression-template view rebinding is protected against g++ -O3 (which led to wrong Eigen::Map dimensions, an Eigen::Map resize assertion, and a segfault.
  • The bind() helpers are marked non-inline and are also protected from operating on a nullptr.
  • Both items co-written with DeepSeek V4 Flash, and have been sent upstream in a PR.
  • Suppress another compiler warning when local build detected.
  • Add r-universe badge to README.md.

Courtesy of my CRANberries, there is also a diffstat report for the most recent release. More information is available at the repository or the package page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

29 September 2026

Gunnar Wolf: The Origins of GPU Computing

This post is an unpublished review for The Origins of GPU Computing
This article appears in the Communications of the ACM magazine as part of a series devoting to showcasing relevant examples of technologies where federal funding of academic research have resulted in widely impacting, clearly identifiable technological advances that have visibly improved or, at least, changed life far beyond the technological arena. The road leading from the first parallel computing technologies built completely for research, through a phase that was preeminently directed at gaming, and back to leading current GPUs, that are basically massively parallel supercomputers used for LLM training and inference and other IA tasks, is far from trivial, and the authors make a good job outlining it in few pages. The article is written in a clearly divulgatory way, staying as clear of technical language as possible. The authors present three main enabling technologies for current GPU technologies: Parallel computing, parallel graphics systems, and stream processing. Coming from a technical formation myself, although clearly better grounded in the software side of Computer Engineering than on the electronics side, the most interesting nugget of information I take is that parallel computing was born due to the fact that transistor switching consumes very little energy, whereas communication along wires consumes much more so the more simultaneous operations can be carried out on-chip at once, the less power will be dissipated as heat (and the less time that will be lost due to data stores and loads). Graphics systems are a natural match for parallel systems, as rendering realistic images basically requires repeating the same blocks of instructions to a large array of items. Early GPU implementations were built on fixed-function graphics pipelines, but by the turn of the century, when nVidia spinned off the research labs at Stanford and started marketing their product, introducing along the way the Graphical Processing Unit term, product, they enabled it to implement the full OpenGL graphics pipeline on a single chip. Stream processing is the arrangement of in-chip electronics so that they can better exploit producer-consumer locality between stages, in order to achieve greater arithmetic intensity (this is, a greater computation-to-bandwidth ratio), decreasing the total number of access to memory accesses. The authors explain in broad terms the described technologies and how they fit together, and how the technology was transferred from the universities to the companies that became the most dynamic companies behind today s top trending technologies. I felt the article to be engaging and easy to read. As a technologist, I did miss more details dates when specific advances were made, how some of the advances joined into further inventions But I understand the aim of the Federal Funding of Academic Research series aim is more towards outsiders. And, as such, this work very well explains how trillion-dollar technologies are only the result of decades of funding research ideas.

Next.