Search Results: "rkd"

28 August 2025

Samuel Henrique: Debian 13: My list of exciting new features
A bunch of screenshots overlaid on top of each other showing different tools: lazygit, gnome settings, gnome system monitor, powerline-go, and the wcurl logo, the text at the top says 'Debian 13: My list of exciting new features', and there's a Debian logo in the middle of image

Beyond Debian: Useful for other distros too Every two years Debian releases a new major version of its Stable series, meaning the differences between consecutive Debian Stable releases represent two years of new developments both in Debian as an organization and its native packages, but also in all other packages which are also shipped by other distributions (which are getting into this new Stable release). If you're not paying close attention to everything that's going on all the time in the Linux world, you miss a lot of the nice new features and tools. It's common for people to only realize there's a cool new trick available only years after it was first introduced. Given these considerations, the tips that I'm describing will eventually be available in whatever other distribution you use, be it because it's a Debian derivative or because it just got the same feature from the upstream project. I'm not going to list "passive" features (as good as they can be), the focus here is on new features that might change how you configure and use your machine, with a mix between productivity and performance.

Debian 13 - Trixie I have been a Debian Testing user for longer than 10 years now (and I recommend it for non-server users), so I'm not usually keeping track of all the cool features arriving in the new Stable releases because I'm continuously receiving them through the Debian Testing rolling release. Nonetheless, as a Debian Developer I'm in a good position to point out the ones I can remember. I would also like other Debian Developers to do the same as I'm sure I would learn something new. The Debian 13 release notes contain a "What's new" section , which lists the first two items here and a few other things, in other words, take my list as an addition to the release notes. Debian 13 was released on 2025-08-09, and these are nice things you shouldn't miss in the new release, with a bonus one not tied to the Debian 13 release.

1) wcurl wcurl logo Have you ever had to download a file from your terminal using curl and didn't remember the parameters needed? I did. Nowadays you can use wcurl; "a command line tool which lets you download URLs without having to remember any parameters." Simply call wcurl with one or more URLs as parameters and it will download all of them in parallel, performing retries, choosing the correct output file name, following redirects, and more. Try it out:
wcurl example.com
wcurl comes installed as part of the curl package on Debian 13 and in any other distribution you can imagine, starting with curl 8.14.0. I've written more about wcurl in its release announcement and I've done a lightning talk presentation in DebConf24, which is linked in the release announcement.

2) HTTP/3 support in curl Debian has become the first stable Linux distribution to ship curl with support for HTTP/3. I've written about this in July 2024, when we first enabled it. Note that we first switched the curl CLI to GnuTLS, but then ended up releasing the curl CLI linked with OpenSSL (as support arrived later). Debian was the first stable Linux distro to enable it, and within rolling-release-based distros; Gentoo enabled it first in their non-default flavor of the package and Arch Linux did it three months before we pushed it to Debian Unstable/Testing/Stable-backports, kudos to them! HTTP/3 is not used by default by the curl CLI, you have to enable it with --http3 or --http3-only. Try it out:
curl --http3 https://www.example.org
curl --http3-only https://www.example.org

3) systemd soft-reboot Starting with systemd v254, there's a new soft-reboot option, it's an userspace-only reboot, much faster than a full reboot if you don't need to reboot the kernel. You can read the announcement from the systemd v254 GitHub release Try it out:
# This will reboot your machine!
systemctl soft-reboot

4) apt --update Are you tired of being required to run sudo apt update just before sudo apt upgrade or sudo apt install $PACKAGE? So am I! The new --update option lets you do both things in a single command:
sudo apt --update upgrade
sudo apt --update install $PACKAGE
I love this, but it's still not yet where it should be, fingers crossed for a simple apt upgrade to behave like other package managers by updating its cache as part of the task, maybe in Debian 14? Try it out:
sudo apt upgrade --update
# The order doesn't matter
sudo apt --update upgrade
This is especially handy for container usage, where you have to update the apt cache before installing anything, for example:
podman run debian:stable bin/bash -c 'apt install --update -y curl'

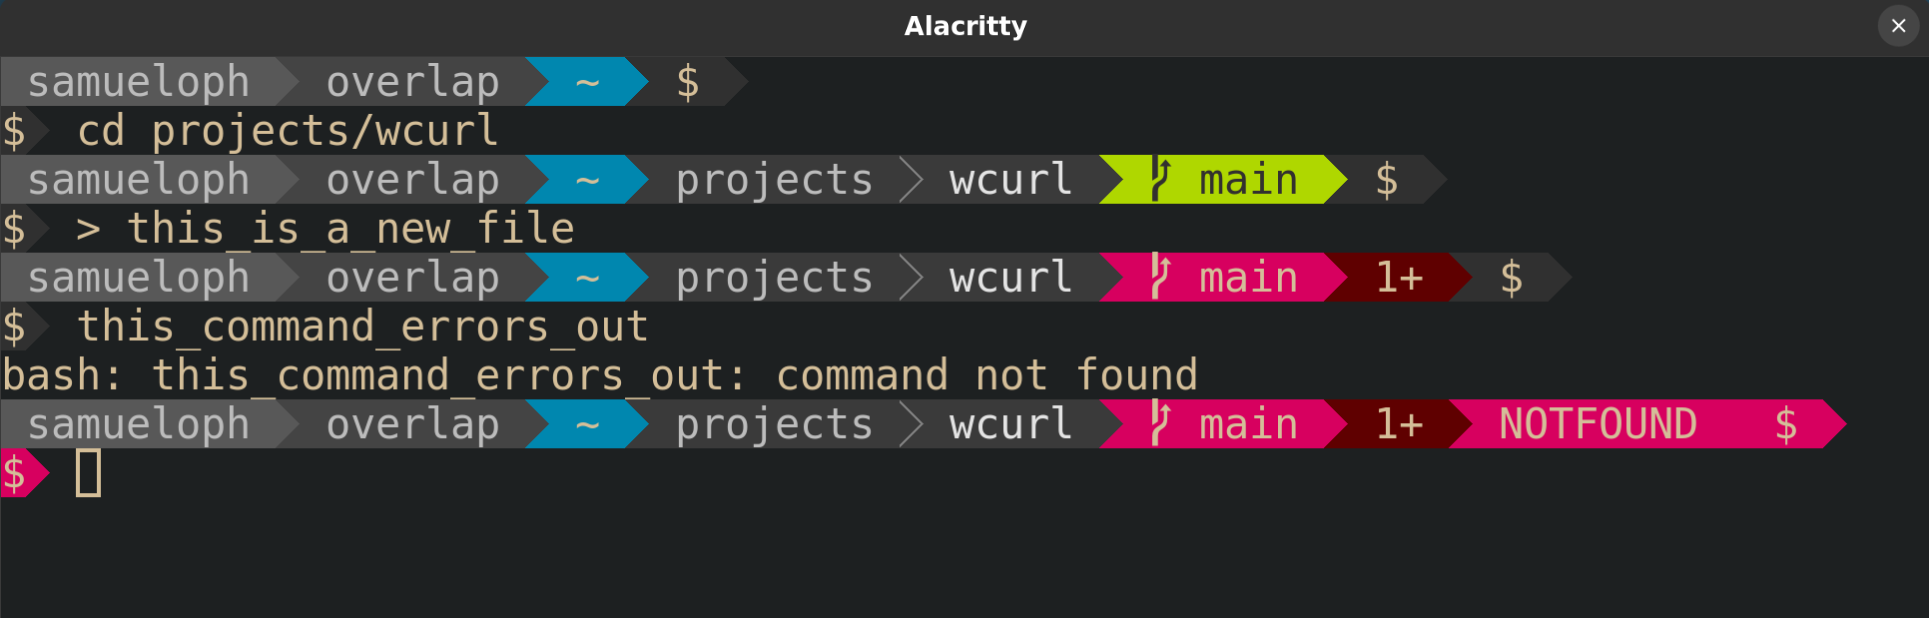
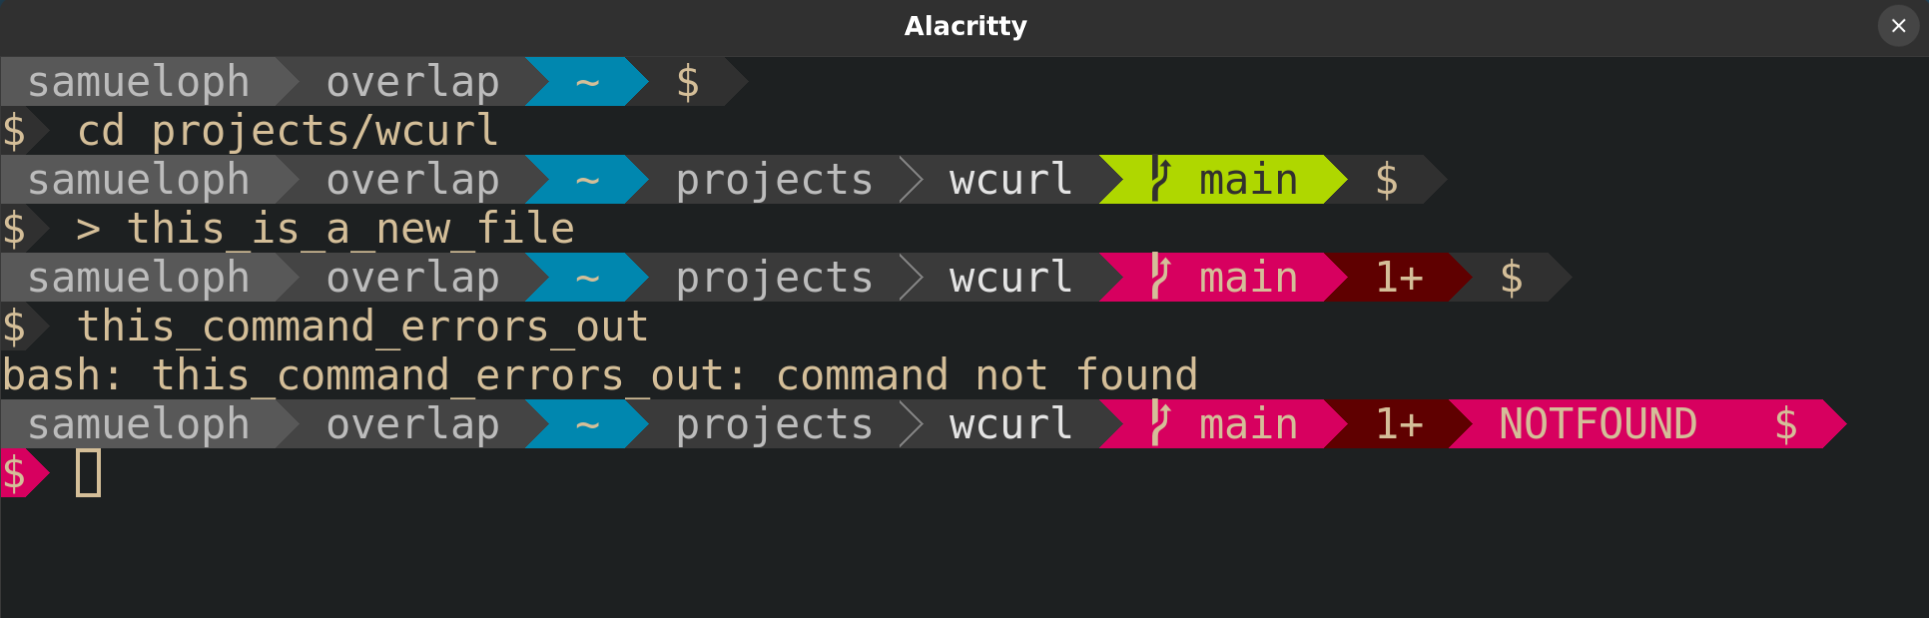
5) powerline-go powerline-go is a powerline-style prompt written in Golang, so it's much more performant than its Python alternative powerline. powerline-style prompts are quite useful to show things like the current status of the git repo in your working directory, exit code of the previous command, presence of jobs in the background, whether or not you're in an ssh session, and more. A screenshot of a terminal with powerline-go enabled, showing how the PS1 changes inside a git repository and when the last command fails Try it out:
sudo apt install powerline-go
Then add this to your .bashrc:
function _update_ps1()  
    PS1="$(/usr/bin/powerline-go -error $? -jobs $(jobs -p   wc -l))"

    # Uncomment the following line to automatically clear errors after showing
    # them once. This not only clears the error for powerline-go, but also for
    # everything else you run in that shell. Don't enable this if you're not
    # sure this is what you want.

    #set "?"
 

if [ "$TERM" != "linux" ] && [ -f "/usr/bin/powerline-go" ]; then
    PROMPT_COMMAND="_update_ps1; $PROMPT_COMMAND"
fi
Or this to .zshrc:
function powerline_precmd()  
    PS1="$(/usr/bin/powerline-go -error $? -jobs $ $ (%):%j :-0 )"

    # Uncomment the following line to automatically clear errors after showing
    # them once. This not only clears the error for powerline-go, but also for
    # everything else you run in that shell. Don't enable this if you're not
    # sure this is what you want.

    #set "?"
 
If you'd like to have your prompt start in a newline, like I have in the screenshot above, you just need to set -newline in the powerline-go invocation in your .bashrc/.zshrc.

6) Gnome System Monitor Extension Tips number 6 and 7 are for Gnome users. Gnome is now shipping a system monitor extension which lets you get a glance of the current load of your machine from the top bar. Screenshot of the top bar of Gnome with the system monitor extension enabled, showing the load of: CPU, memory, network and disk I've found this quite useful for machines where I'm required to install third-party monitoring software that tends to randomly consume more resources than it should. If I feel like my machine is struggling, I can quickly glance at its load to verify if it's getting overloaded by some process. The extension is not as complete as system-monitor-next, not showing temperatures or histograms, but at least it's officially part of Gnome, easy to install and supported by them. Try it out:

sudo apt install gnome-system-monitor gnome-shell-extension-manager
And then enable the extension from the "Extension Manager" application.

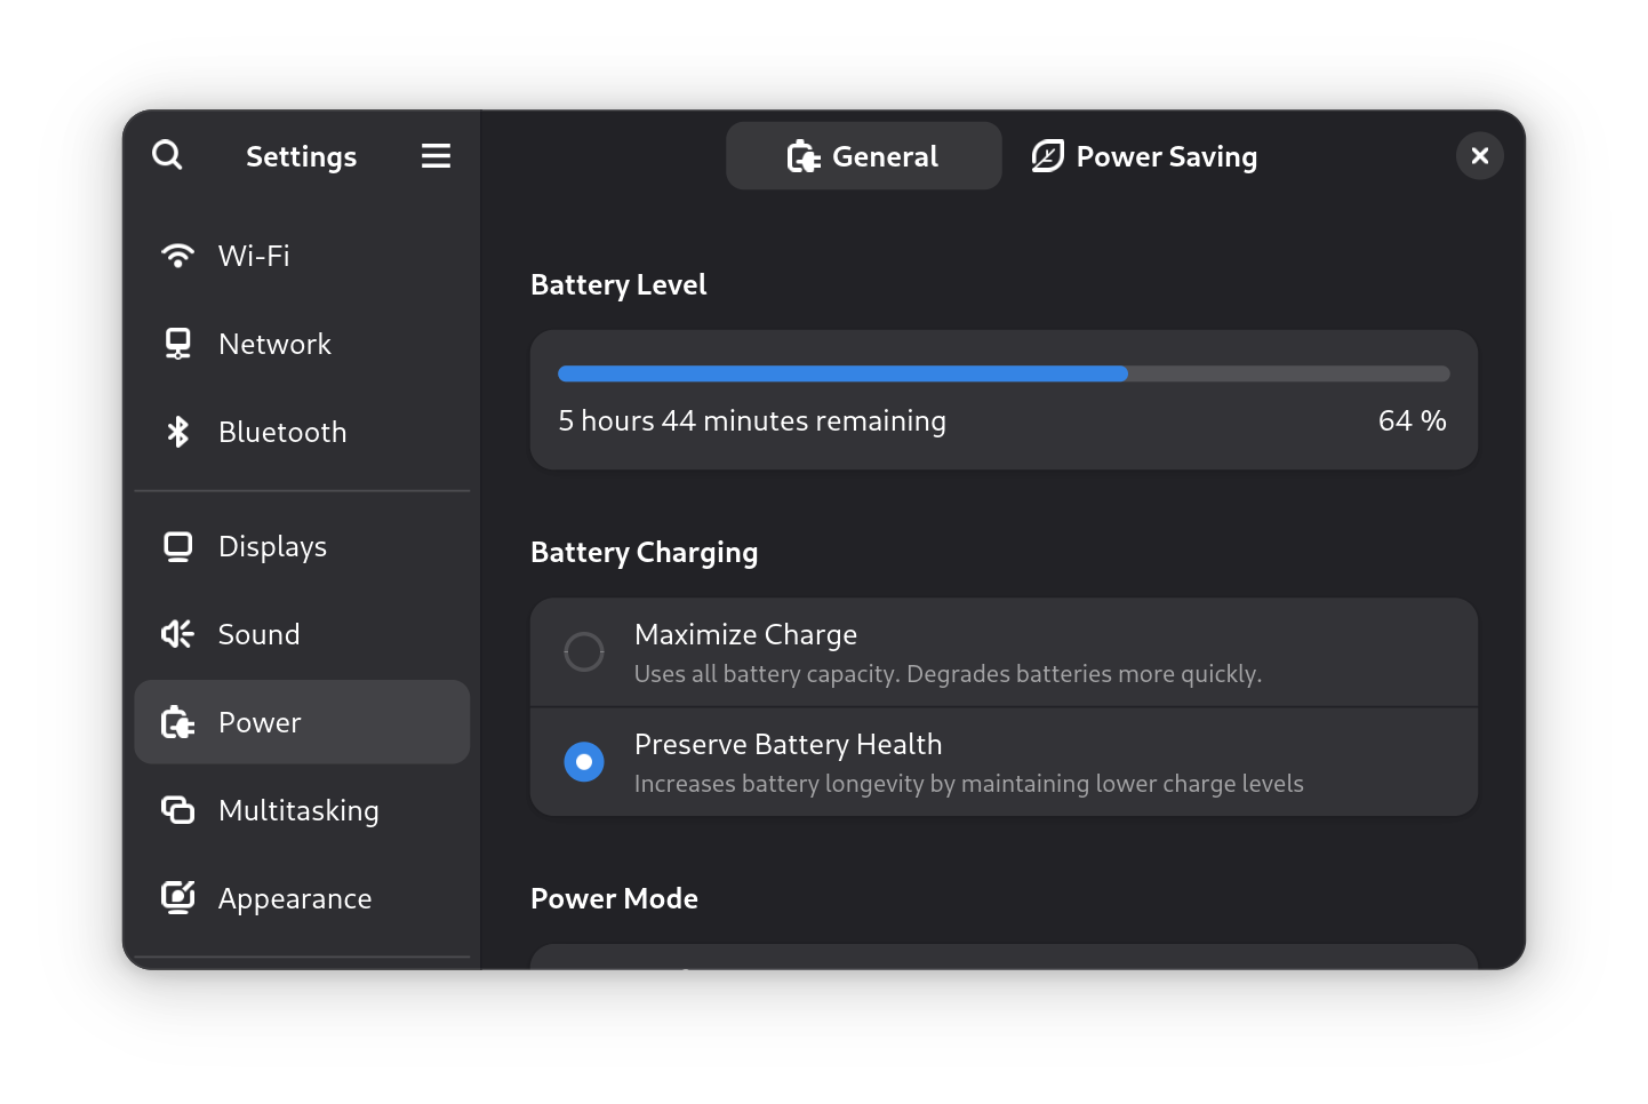
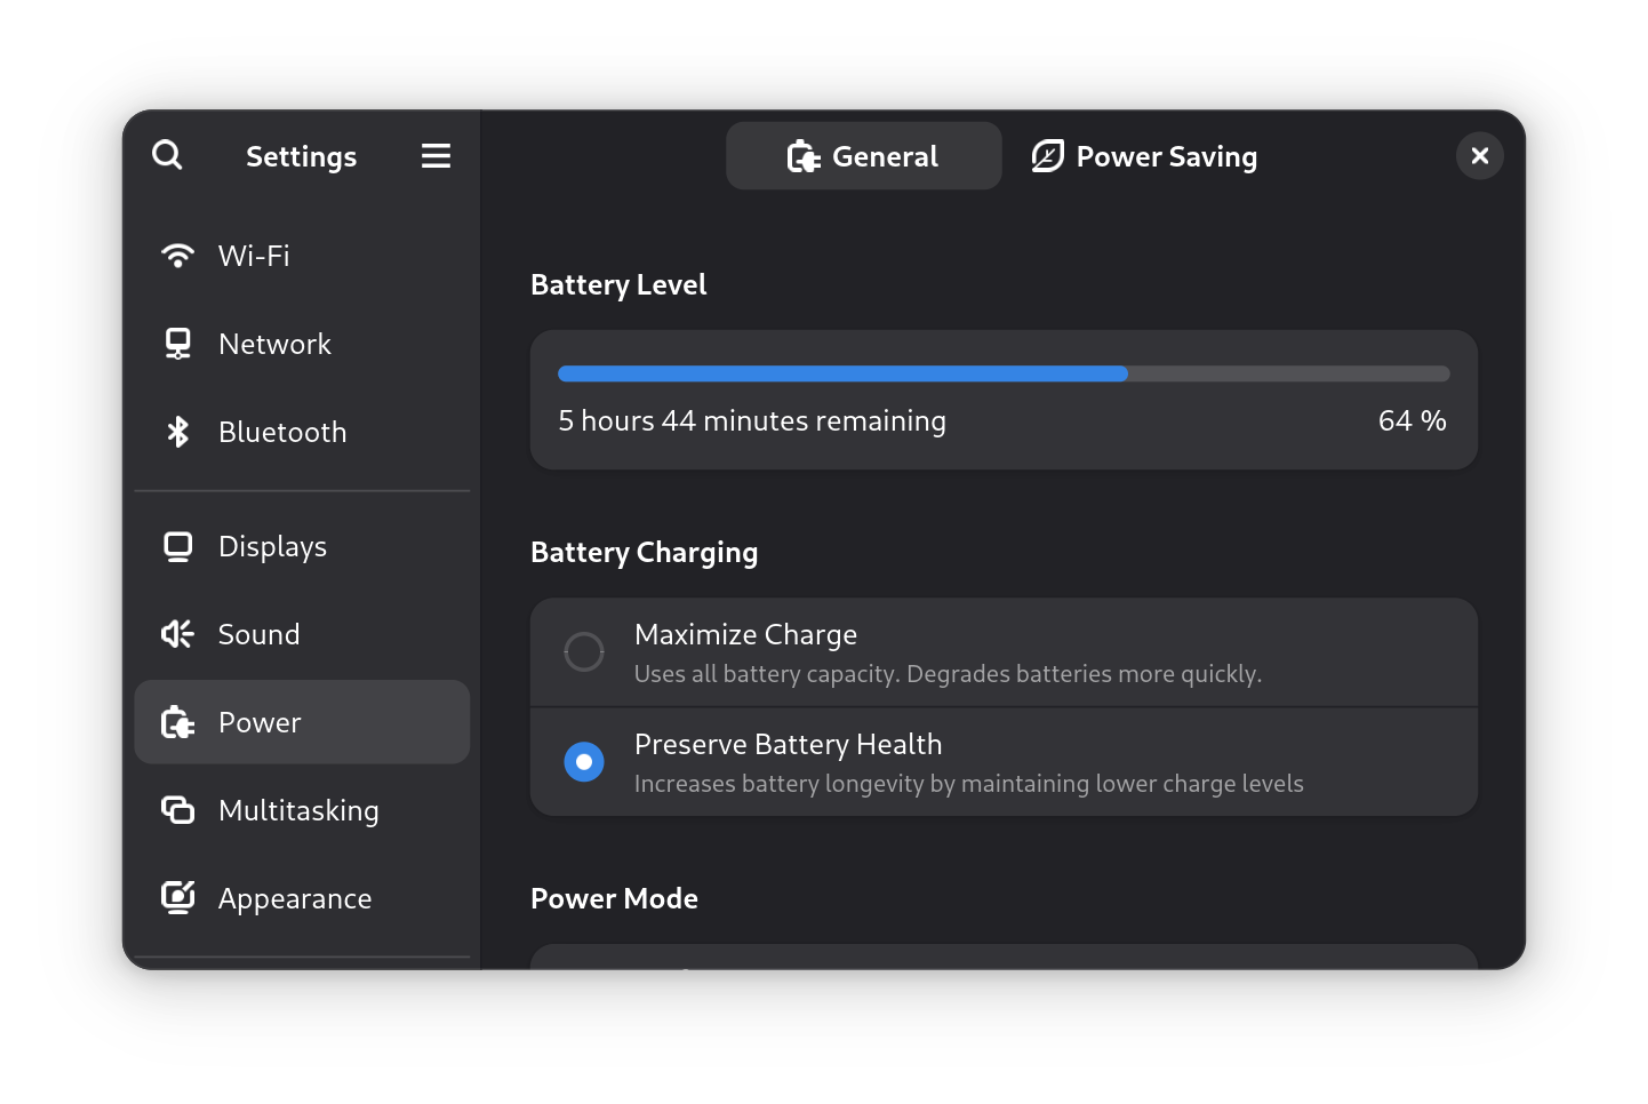
7) Gnome setting for battery charging profile After having to learn more about batteries in order to get into FPV drones, I've come to have a bigger appreciation for solutions that minimize the inevitable loss of capacity that accrues over time. There's now a "Battery Charging" setting (under the "Power") section which lets you choose between two different profiles: "Maximize Charge" and "Preserve Battery Health". A screenshot of the Gnome settings for Power showing the options for Battery Charging On supported laptops, this setting is an easy way to set thresholds for when charging should start and stop, just like you could do it with the tlp package, but now from the Gnome settings. To increase the longevity of my laptop battery, I always keep it at "Preserve Battery Health" unless I'm traveling. What I would like to see next is support for choosing different "Power Modes" based on whether the laptop is plugged-in, and based on the battery charge percentage. There's a GNOME issue tracking this feature, but there's some pushback on whether this is the right thing to expose to users. In the meantime, there are some workarounds mentioned in that issue which people who really want this feature can follow. If you would like to learn more about batteries; Battery University is a great starting point, besides getting into FPV drones and being forced to handle batteries without a Battery Management System (BMS). And if by any chance this sparks your interest in FPV drones, Joshua Bardwell's YouTube channel is a great resource: @JoshuaBardwell.
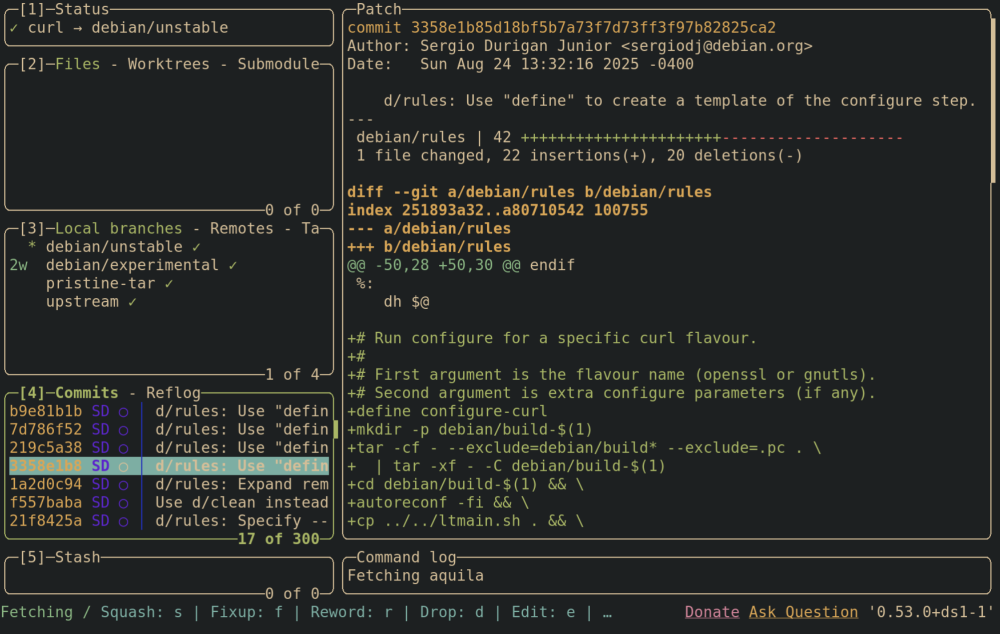
8) Lazygit Emacs users are already familiar with the legendary magit; a terminal-based UI for git. Lazygit is an alternative for non-emacs users, you can integrate it with neovim or just use it directly. I'm still playing with lazygit and haven't integrated it into my workflows, but so far it has been a pleasant experience. Screenshot of lazygit from the Debian curl repository, showing a selected commit and its diff, besides the other things from the lazygit UI You should check out the demos from the lazygit GitHub page. Try it out:
sudo apt install lazygit
And then call lazygit from within a git repository.

9) neovim neovim has been shipped in Debian since 2016, but upstream has been doing a lot of work to improve the experience out-of-the-box in the last couple of years. If you're a neovim poweruser, you're likely not installing it from the official repositories, but for those that are, Debian 13 comes with version 0.10.4, which brings the following improvements compared to the version in Debian 12:
  • Treesitter support for C, Lua, Markdown, with the possibility of adding any other languages as needed;
  • Better spellchecking due to treesitter integration (spellsitter);
  • Mouse support enabled by default;
  • Commenting support out-of-the-box; Check :h commenting for details, but the tl;dr is that you can use gcc to comment the current line and gc to comment the current selection.
  • OSC52 support. Especially handy for those using neovim over an ssh connection, this protocol lets you copy something from within the neovim process into the clipboard of the machine you're using to connect through ssh. In other words, you can copy from neovim running in a host over ssh and paste it in the "outside" machine.

10) [Bonus] Running old Debian releases The bonus tip is not specific to the Debian 13 release, but something I've recently learned in the #debian-devel IRC channel. Did you know there are usable container images for all past Debian releases? I'm not talking "past" as in "some of the older releases", I'm talking past as in "literally every Debian release, including the very first one". Tianon Gravi "tianon" is the Debian Developer responsible for making this happen, kudos to him! There's a small gotcha that the releases Buzz (1.1) and Rex (1.2) require a 32-bit host, otherwise you will get the error Out of virtual memory!, but starting with Bo (1.3) all should work in amd64/arm64. Try it out:
sudo apt install podman

podman run -it docker.io/debian/eol:bo
Don't be surprised when noticing that apt/apt-get is not available inside the container, that's because apt first appeared in Debian Slink (2.1).

Changes since publication

2025-08-30
  • Mention that Arch also enabled HTTP/3.
Samuel Henrique: Debian 13: My list of exciting new features

A bunch of screenshots overlaid on top of each other showing different tools: lazygit, gnome settings, gnome system monitor, powerline-go, and the wcurl logo, the text at the top says 'Debian 13: My list of exciting new features', and there's a Debian logo in the middle of image

Beyond Debian: Useful for other distros too Every two years Debian releases a new major version of its Stable series, meaning the differences between consecutive Debian Stable releases represent two years of new developments both in Debian as an organization and its native packages, but also in all other packages which are also shipped by other distributions (which are getting into this new Stable release). If you're not paying close attention to everything that's going on all the time in the Linux world, you miss a lot of the nice new features and tools. It's common for people to only realize there's a cool new trick available only years after it was first introduced. Given these considerations, the tips that I'm describing will eventually be available in whatever other distribution you use, be it because it's a Debian derivative or because it just got the same feature from the upstream project. I'm not going to list "passive" features (as good as they can be), the focus here is on new features that might change how you configure and use your machine, with a mix between productivity and performance.

Debian 13 - Trixie I have been a Debian Testing user for longer than 10 years now (and I recommend it for non-server users), so I'm not usually keeping track of all the cool features arriving in the new Stable releases because I'm continuously receiving them through the Debian Testing rolling release. Nonetheless, as a Debian Developer I'm in a good position to point out the ones I can remember. I would also like other Debian Developers to do the same as I'm sure I would learn something new. The Debian 13 release notes contain a "What's new" section , which lists the first two items here and a few other things, in other words, take my list as an addition to the release notes. Debian 13 was released on 2025-08-09, and these are nice things you shouldn't miss in the new release, with a bonus one not tied to the Debian 13 release.

1) wcurl wcurl logo Have you ever had to download a file from your terminal using curl and didn't remember the parameters needed? I did. Nowadays you can use wcurl; "a command line tool which lets you download URLs without having to remember any parameters." Simply call wcurl with one or more URLs as parameters and it will download all of them in parallel, performing retries, choosing the correct output file name, following redirects, and more. Try it out:
wcurl example.com
wcurl comes installed as part of the curl package on Debian 13 and in any other distribution you can imagine, starting with curl 8.14.0. I've written more about wcurl in its release announcement and I've done a lightning talk presentation in DebConf24, which is linked in the release announcement.

2) HTTP/3 support in curl Debian has become the first stable Linux distribution to ship curl with support for HTTP/3. I've written about this in July 2024, when we first enabled it. Note that we first switched the curl CLI to GnuTLS, but then ended up releasing the curl CLI linked with OpenSSL (as support arrived later). Debian was the first Linux distro to enable it in the default build of the curl package, but Gentoo enabled it a few weeks earlier in their non-default flavor of the package, kudos to them! HTTP/3 is not used by default by the curl CLI, you have to enable it with --http3 or --http3-only. Try it out:
curl --http3 https://www.example.org
curl --http3-only https://www.example.org

3) systemd soft-reboot Starting with systemd v254, there's a new soft-reboot option, it's an userspace-only reboot, much faster than a full reboot if you don't need to reboot the kernel. You can read the announcement from the systemd v254 GitHub release Try it out:
# This will reboot your machine!
systemctl soft-reboot

4) apt --update Are you tired of being required to run sudo apt update just before sudo apt upgrade or sudo apt install $PACKAGE? So am I! The new --update option lets you do both things in a single command:
sudo apt --update upgrade
sudo apt --update install $PACKAGE
I love this, but it's still not yet where it should be, fingers crossed for a simple apt upgrade to behave like other package managers by updating its cache as part of the task, maybe in Debian 14? Try it out:
sudo apt upgrade --update
# The order doesn't matter
sudo apt --update upgrade
This is especially handy for container usage, where you have to update the apt cache before installing anything, for example:
podman run debian:stable bin/bash -c 'apt install --update -y curl'

5) powerline-go powerline-go is a powerline-style prompt written in Golang, so it's much more performant than its Python alternative powerline. powerline-style prompts are quite useful to show things like the current status of the git repo in your working directory, exit code of the previous command, presence of jobs in the background, whether or not you're in an ssh session, and more. A screenshot of a terminal with powerline-go enabled, showing how the PS1 changes inside a git repository and when the last command fails Try it out:
sudo apt install powerline-go
Then add this to your .bashrc:
function _update_ps1()  
    PS1="$(/usr/bin/powerline-go -error $? -jobs $(jobs -p   wc -l))"

    # Uncomment the following line to automatically clear errors after showing
    # them once. This not only clears the error for powerline-go, but also for
    # everything else you run in that shell. Don't enable this if you're not
    # sure this is what you want.

    #set "?"
 

if [ "$TERM" != "linux" ] && [ -f "/usr/bin/powerline-go" ]; then
    PROMPT_COMMAND="_update_ps1; $PROMPT_COMMAND"
fi
Or this to .zshrc:
function powerline_precmd()  
    PS1="$(/usr/bin/powerline-go -error $? -jobs $ $ (%):%j :-0 )"

    # Uncomment the following line to automatically clear errors after showing
    # them once. This not only clears the error for powerline-go, but also for
    # everything else you run in that shell. Don't enable this if you're not
    # sure this is what you want.

    #set "?"
 
If you'd like to have your prompt start in a newline, like I have in the screenshot above, you just need to set -newline in the powerline-go invocation in your .bashrc/.zshrc.

6) Gnome System Monitor Extension Tips number 6 and 7 are for Gnome users. Gnome is now shipping a system monitor extension which lets you get a glance of the current load of your machine from the top bar. Screenshot of the top bar of Gnome with the system monitor extension enabled, showing the load of: CPU, memory, network and disk I've found this quite useful for machines where I'm required to install third-party monitoring software that tends to randomly consume more resources than it should. If I feel like my machine is struggling, I can quickly glance at its load to verify if it's getting overloaded by some process. The extension is not as complete as system-monitor-next, not showing temperatures or histograms, but at least it's officially part of Gnome, easy to install and supported by them. Try it out:
sudo apt install gnome-system-monitor gnome-shell-extension-manager
And then enable the extension from the "Extension Manager" application.

7) Gnome setting for battery charging profile After having to learn more about batteries in order to get into FPV drones, I've come to have a bigger appreciation for solutions that minimize the inevitable loss of capacity that accrues over time. There's now a "Battery Charging" setting (under the "Power") section which lets you choose between two different profiles: "Maximize Charge" and "Preserve Battery Health". A screenshot of the Gnome settings for Power showing the options for Battery Charging On supported laptops, this setting is an easy way to set thresholds for when charging should start and stop, just like you could do it with the tlp package, but now from the Gnome settings. To increase the longevity of my laptop battery, I always keep it at "Preserve Battery Health" unless I'm traveling. What I would like to see next is support for choosing different "Power Modes" based on whether the laptop is plugged-in, and based on the battery charge percentage. There's a GNOME issue tracking this feature, but there's some pushback on whether this is the right thing to expose to users. In the meantime, there are some workarounds mentioned in that issue which people who really want this feature can follow. If you would like to learn more about batteries; Battery University is a great starting point, besides getting into FPV drones and being forced to handle batteries without a Battery Management System (BMS). And if by any chance this sparks your interest in FPV drones, Joshua Bardwell's YouTube channel is a great resource: @JoshuaBardwell.
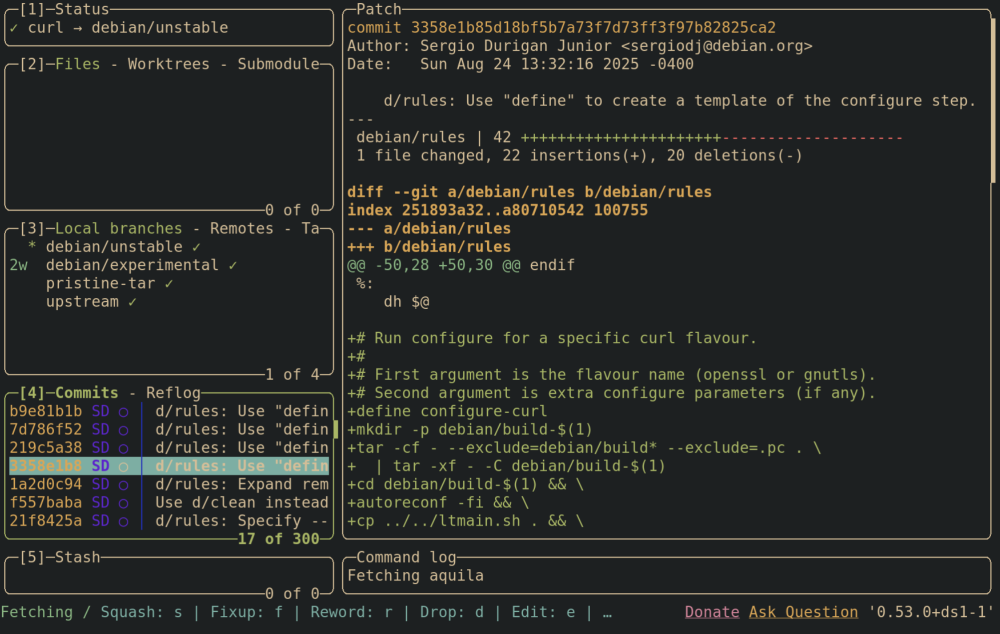
8) Lazygit Emacs users are already familiar with the legendary magit; a terminal-based UI for git. Lazygit is an alternative for non-emacs users, you can integrate it with neovim or just use it directly. I'm still playing with lazygit and haven't integrated it into my workflows, but so far it has been a pleasant experience. Screenshot of lazygit from the Debian curl repository, showing a selected commit and its diff, besides the other things from the lazygit UI You should check out the demos from the lazygit GitHub page. Try it out:
sudo apt install lazygit
And then call lazygit from within a git repository.

9) neovim neovim has been shipped in Debian since 2016, but upstream has been doing a lot of work to improve the experience out-of-the-box in the last couple of years. If you're a neovim poweruser, you're likely not installing it from the official repositories, but for those that are, Debian 13 comes with version 0.10.4, which brings the following improvements compared to the version in Debian 12:
  • Treesitter support for C, Lua, Markdown, with the possibility of adding any other languages as needed;
  • Better spellchecking due to treesitter integration (spellsitter);
  • Mouse support enabled by default;
  • Commenting support out-of-the-box; Check :h commenting for details, but the tl;dr is that you can use gcc to comment the current line and gc to comment the current selection.
  • OSC52 support. Especially handy for those using neovim over an ssh connection, this protocol lets you copy something from within the neovim process into the clipboard of the machine you're using to connect through ssh. In other words, you can copy from neovim running in a host over ssh and paste it in the "outside" machine.

10) [Bonus] Running old Debian releases The bonus tip is not specific to the Debian 13 release, but something I've recently learned in the #debian-devel IRC channel. Did you know there are usable container images for all past Debian releases? I'm not talking "past" as in "some of the older releases", I'm talking past as in "literally every Debian release, including the very first one". Tianon Gravi "tianon" is the Debian Developer responsible for making this happen, kudos to him! There's a small gotcha that the releases Buzz (1.1) and Rex (1.2) require a 32-bit host, otherwise you will get the error Out of virtual memory!, but starting with Bo (1.3) all should work in amd64/arm64. Try it out:
sudo apt install podman

podman run -it docker.io/debian/eol:bo
Don't be surprised when noticing that apt/apt-get is not available inside the container, that's because apt first appeared in Debian Slink (2.1).

20 August 2025

Emmanuel Kasper: Benchmarking 3D graphic cards and their drivers

I have in the past benchmarked network links and disks, so as to have a rough idea of the performance of the hardware I am confronted at $WORK. As I started to dabble into Linux gaming (on non-PC hardware !), I wanted to have some numbers from the graphic stack as well. I am using the command glmark2 --size 1920x1080 which is testing the performance of an OpenGL implementation, hardware + drivers. OpenGL is the classic 3D API used by most opensource gaming on Linux (Doom3 Engine, SuperTuxCart, 0AD, Cube 2 Engine). Vulkan is getting traction as a newer 3D API however the equivalent Vulkan vkmark benchmark was crashing using the NVIDIA semi-proprietary drivers. (vkmark --size 1920x1080 was throwing an ugly Error: Selected present mode Mailbox is not supported by the used Vulkan physical device. )
# apt install glmark2
$ lspci   grep -i vga # integrated GPU
00:02.0 VGA compatible controller: Intel Corporation HD Graphics 615 (rev 02)
$ glmark2 --size 1920x1080
...
...
glmark2 Score: 2063
$ lspci   grep -i vga # integrated GPU
00:02.0 VGA compatible controller: Intel Corporation Meteor Lake-P [Intel Graphics] (rev 08)
glmark2 Score: 3095
$ lspci   grep -i vga # discrete GPU, using nouveau
0000:01:00.0 VGA compatible controller: NVIDIA Corporation AD107GL [RTX 2000 / 2000E Ada Generation] (rev a1)
glmark2 Score: 2463
$ lspci   grep -i vga # discrete GPU, using nvidia-open semi-proprietary driver
0000:01:00.0 VGA compatible controller: NVIDIA Corporation AD107GL [RTX 2000 / 2000E Ada Generation] (rev a1)
glmark2 score: 4960
Nouveau has currently some graphical glitches with Doom3 so I am using the nvidia-open driver for this hardware. In my testing with Doom3 and SuperTuxKart, post 2015 integrated Intel Hardware is more than enough to play in HD resolution.

18 August 2025

Otto Kek l inen: Best Practices for Submitting and Reviewing Merge Requests in Debian

Featured image of post Best Practices for Submitting and Reviewing Merge Requests in DebianHistorically the primary way to contribute to Debian has been to email the Debian bug tracker with a code patch. Now that 92% of all Debian source packages are hosted at salsa.debian.org the GitLab instance of Debian more and more developers are using Merge Requests, but not necessarily in the optimal way. In this post I share what I ve found the best practice to be, presented in the natural workflow from forking to merging.
Why use Merge Requests? Compared to sending patches back and forth in email, using a git forge to review code contributions brings several benefits:
  • Contributors can see the latest version of the code immediately when the maintainer pushes it to git, without having to wait for an upload to Debian archives.
  • Contributors can fork the development version and easily base their patches on the correct version and help test that the software continues to function correctly at that specific version.
  • Both maintainer and other contributors can easily see what was already submitted and avoid doing duplicate work.
  • It is easy for anyone to comment on a Merge Request and participate in the review.
  • Integrating CI testing is easy in Merge Requests by activating Salsa CI.
  • Tracking the state of a Merge Request is much easier than browsing Debian bug reports tagged patch , and the cycle of submit review re-submit re-review is much easier to manage in the dedicated Merge Request view compared to participants setting up their own email plugins for code reviews.
  • Merge Requests can have extra metadata, such as Approved , and the metadata often updates automatically, such as a Merge Request being closed automatically when the Git commit ID from it is pushed to the target branch.
Keeping these benefits in mind will help ensure that the best practices make sense and are aligned with maximizing these benefits.

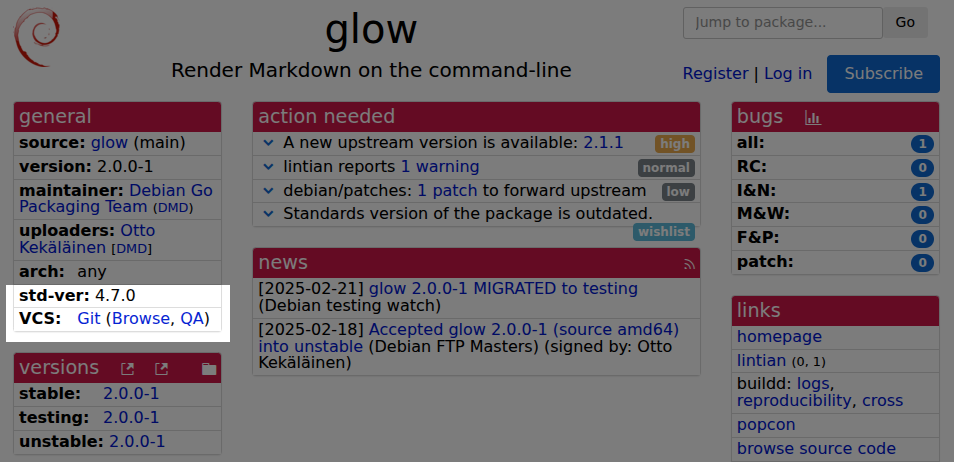
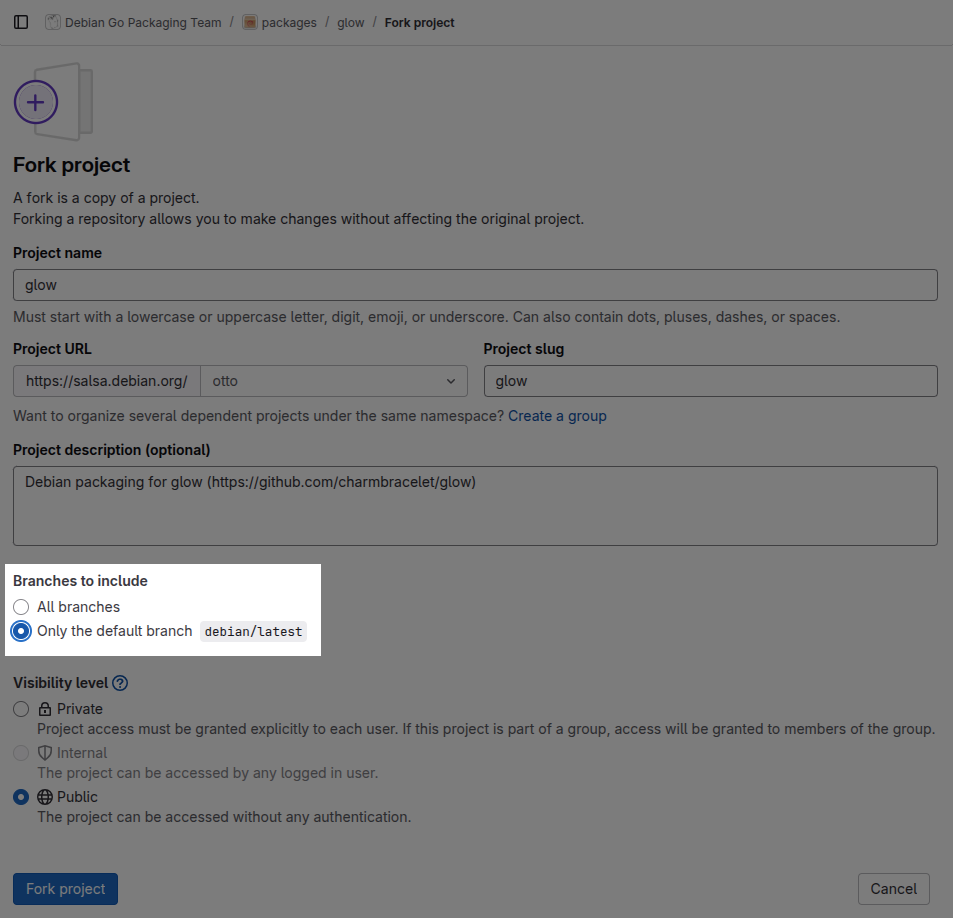
Finding the Debian packaging source repository and preparing to make a contribution Before sinking any effort into a package, start by checking its overall status at the excellent Debian Package Tracker. This provides a clear overview of the package s general health in Debian, when it was last uploaded and by whom, and if there is anything special affecting the package right now. This page also has quick links to the Debian bug tracker of the package, the build status overview and more. Most importantly, in the General section, the VCS row links to the version control repository the package advertises. Before opening that page, note the version most recently uploaded to Debian. This is relevant because nothing in Debian currently enforces that the package in version control is actually the same as the latest uploaded to Debian. Packaging source code repository links at tracker.debian.org Following the Browse link opens the Debian package source repository, which is usually a project page on Salsa. To contribute, start by clicking the Fork button, select your own personal namespace and, under Branches to include, pick Only the default branch to avoid including unnecessary temporary development branches. View after pressing Fork Once forking is complete, clone it with git-buildpackage. For this example repository, the exact command would be gbp clone --verbose git@salsa.debian.org:otto/glow.git. Next, add the original repository as a new remote and pull from it to make sure you have all relevant branches. Using the same fork as an example, the commands would be:
git remote add go-team https://salsa.debian.org/go-team/packages/glow.git
gbp pull --verbose --track-missing go-team
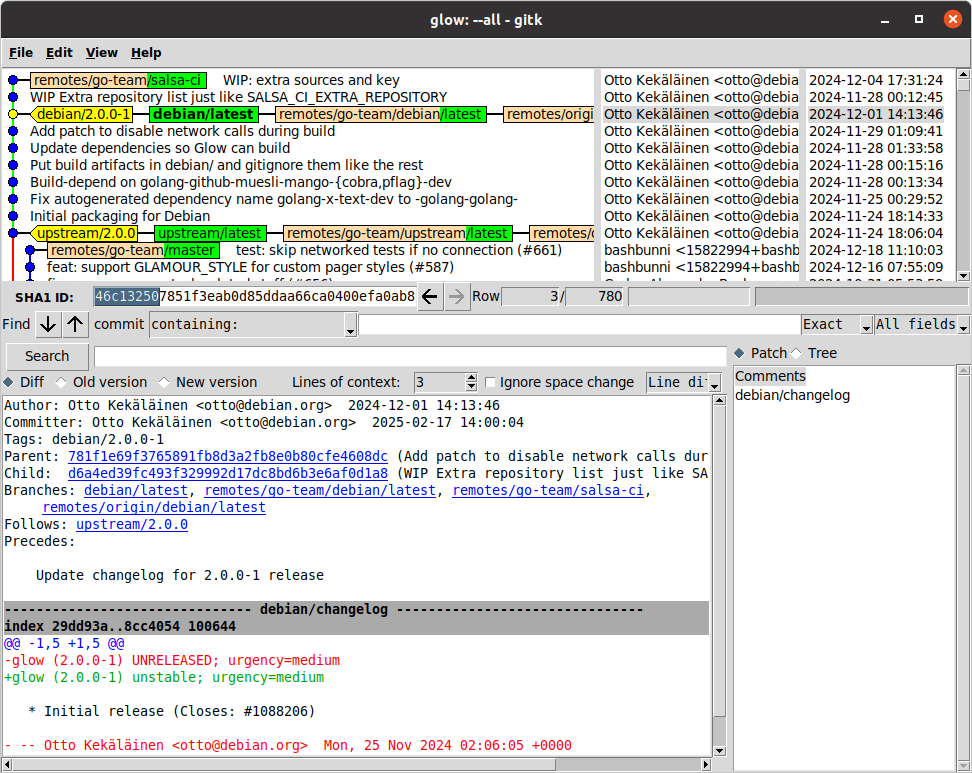
The gbp pull command can be repeated whenever you want to make sure the main branches are in sync with the original repository. Finally, run gitk --all & to visually browse the Git history and note the various branches and their states in the two remotes. Note the style in comments and repository structure the project has and make sure your contributions follow the same conventions to maximize the chances of the maintainer accepting your contribution. It may also be good to build the source package to establish a baseline of the current state and what kind of binaries and .deb packages it produces. If using Debcraft, one can simply run debcraft build in the Git repository.
Submitting a Merge Request for a Debian packaging improvement Always start by making a development branch by running git checkout -b <branch name> to clearly separate your work from the main branch. When making changes, remember to follow the conventions you already see in the package. It is also important to be aware of general guidelines on how to make good Git commits. If you are not able to immediately finish coding, it may be useful to publish the Merge Request as a draft so that the maintainer and others can see that you started working on something and what general direction your change is heading in. If you don t finish the Merge Request in one sitting and return to it another day, you should remember to pull the Debian branch from the original Debian repository in case it has received new commits. This can be done easily with these commands (assuming the same remote and branch names as in the example above):
git fetch go-team
git rebase -i go-team/debian/latest
Frequent rebasing is a great habit to help keep the Git history linear, and restructuring and rewording your commits will make the Git history easier to follow and understand why the changes were made. When pushing improved versions of your branch, use git push --force. While GitLab does allow squashing, I recommend against it. It is better that the submitter makes sure the final version is a neat and clean set of commits that the receiver can easily merge without having to do any rebasing or squashing themselves. When ready, remove the draft status of the Merge Request and wait patiently for review. If the maintainer does not respond in several days, try sending an email to <source package name>@packages.debian.org, which is the official way to contact maintainers. You could also post a comment on the MR and tag the last few committers in the same repository so that a notification email is triggered. As a last resort, submit a bug report to the Debian bug tracker to announce that a Merge Request is pending review. This leaves a permanent record for posterity (or the Debian QA team) of your contribution. However, most of the time simply posting the Merge Request in Salsa is enough; excessive communication might be perceived as spammy, and someone needs to remember to check that the bug report is closed.

Respect the review feedback, respond quickly and avoid Merge Requests getting stale Once you get feedback, try to respond as quickly as possible. When people participating have everything fresh in their minds, it is much easier for the submitter to rework it and for the reviewer to re-review. If the Merge Request becomes stale, it can be challenging to revive it. Also, if it looks like the MR is only waiting for re-review but nothing happens, re-read the previous feedback and make sure you actually address everything. After that, post a friendly comment where you explicitly say you have addressed all feedback and are only waiting for re-review.

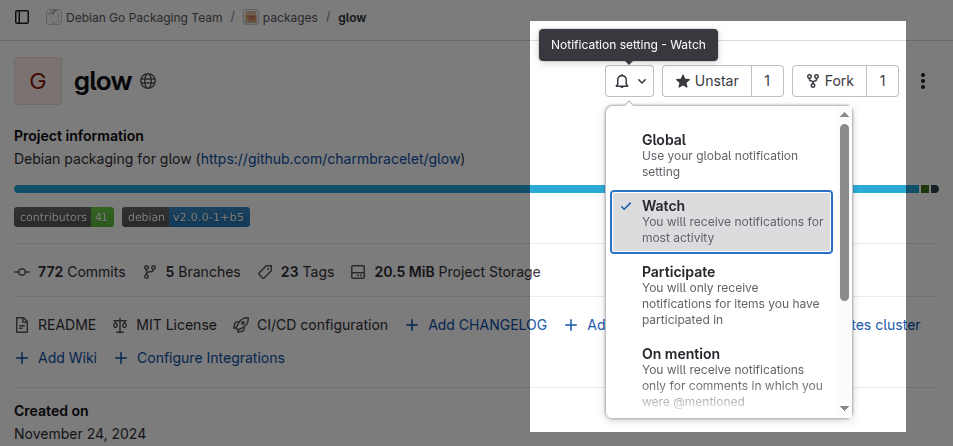
Reviewing Merge Requests This section about reviewing is not exclusive to Debian package maintainers anyone can contribute to Debian by reviewing open Merge Requests. Typically, the larger an open source project gets, the more help is needed in reviewing and testing changes to avoid regressions, and all diligently done work is welcome. As the famous Linus quote goes, given enough eyeballs, all bugs are shallow . On salsa.debian.org, you can browse open Merge Requests per project or for a whole group, just like on any GitLab instance. Reviewing Merge Requests is, however, most fun when they are fresh and the submitter is active. Thus, the best strategy is to ensure you have subscribed to email notifications in the repositories you care about so you get an email for any new Merge Request (or Issue) immediately when posted. Change notification settings from Global to Watch to get an email on new Merge Requests When you see a new Merge Request, try to review it within a couple of days. If you cannot review in a reasonable time, posting a small note that you intend to review it later will feel better to the submitter compared to not getting any response. Personally, I have a habit of assigning myself as a reviewer so that I can keep track of my whole review queue at https://salsa.debian.org/dashboard/merge_requests?reviewer_username=otto, and I recommend the same to others. Seeing the review assignment happen is also a good way to signal to the submitter that their submission was noted.
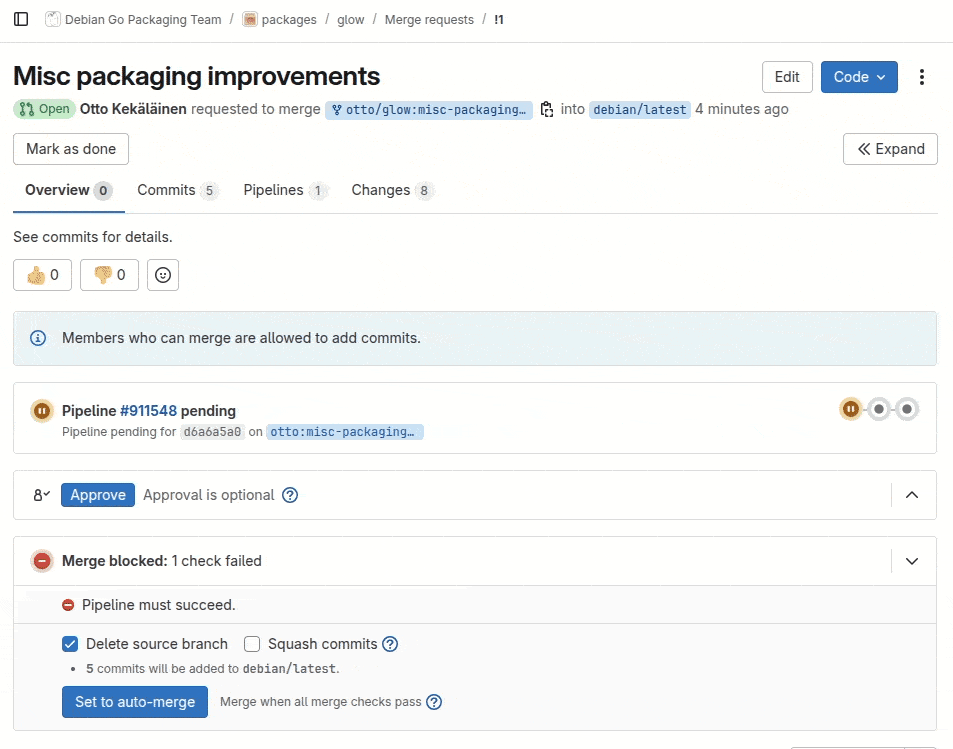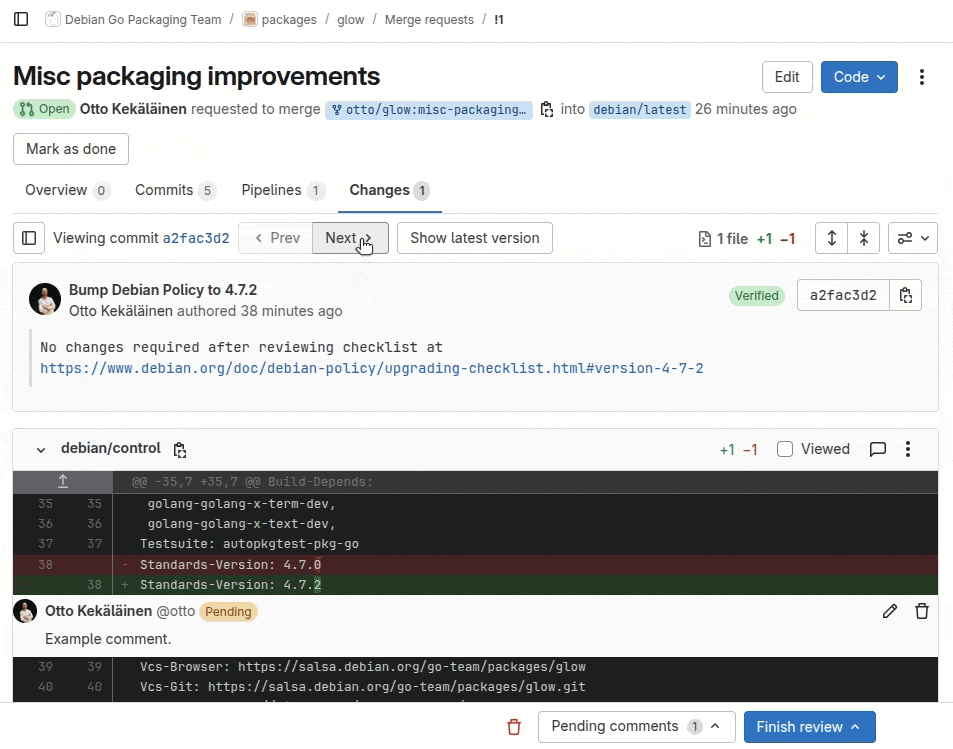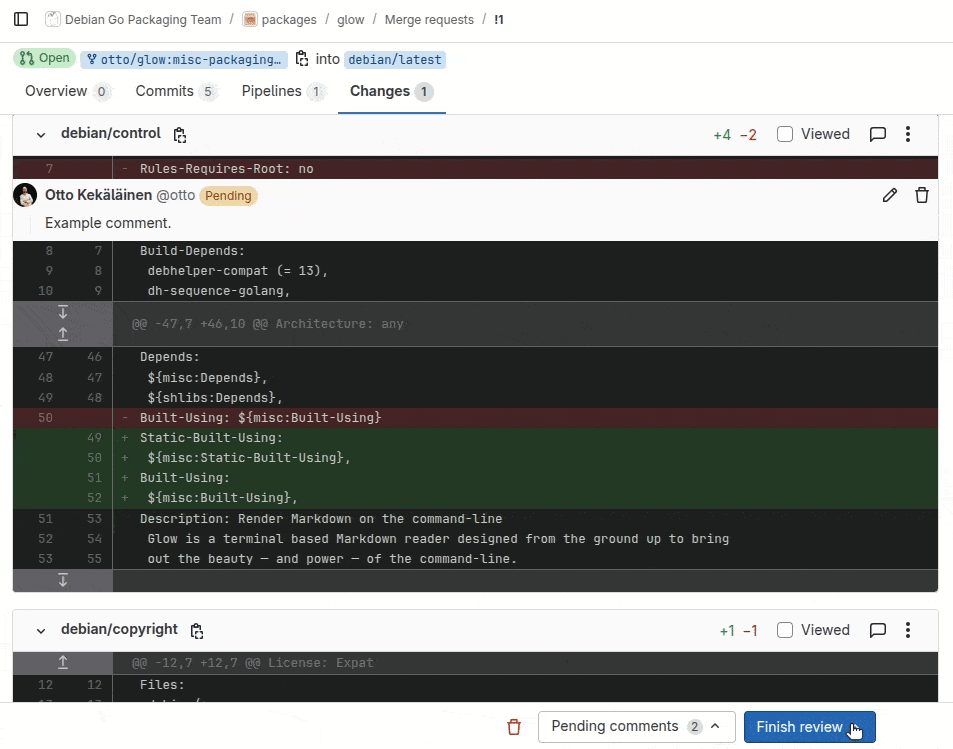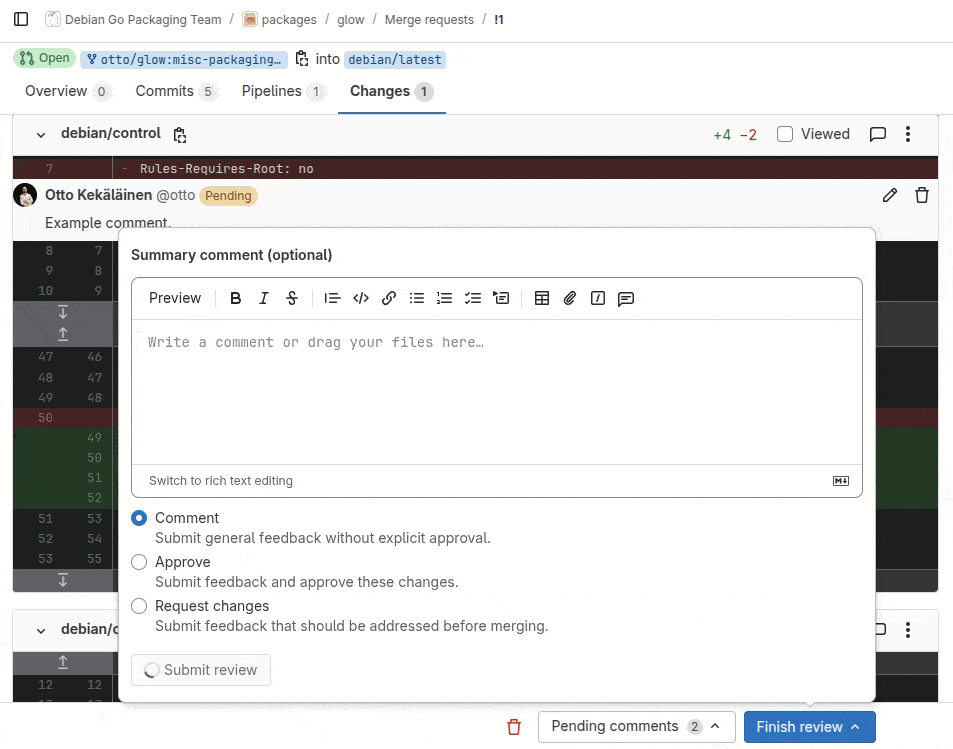
Reviewing commit-by-commit in the web interface Reviewing using the web interface works well in general, but I find that the way GitLab designed it is not ideal. In my ideal review workflow, I first read the Git commit message to understand what the submitter tried to do and why; only then do I look at the code changes in the commit. In GitLab, to do this one must first open the Commits tab and then click on the last commit in the list, as it is sorted in reverse chronological order with the first commit at the bottom. Only after that do I see the commit message and contents. Getting to the next commit is easy by simply clicking Next. Example review to demonstrate location of buttons and functionality When adding the first comment, I choose Start review and for the following remarks Add to review. Finally, I click Finish review and Submit review, which will trigger one single email to the submitter with all my feedback. I try to avoid using the Add comment now option, as each such comment triggers a separate notification email to the submitter.
Reviewing and testing on your own computer locally For the most thorough review, I pull the code to my laptop for local review with git pull <remote url> <branch name>. There is no need to run git remote add as pulling using a URL directly works too and saves from needing to clean up old remotes later. Pulling the Merge Request contents locally allows me to build, run and inspect the code deeply and review the commits with full metadata in gitk or equivalent.

Investing enough time in writing feedback, but not too much See my other post for more in-depth advice on how to structure your code review feedback. In Debian, I would emphasize patience, to allow the submitter time to rework their submission. Debian packaging is notoriously complex, and even experienced developers often need more feedback and time to get everything right. Avoid the temptation to rush the fix in yourself. In open source, Git credits are often the only salary the submitter gets. If you take the idea from the submission and implement it yourself, you rob the submitter of the opportunity to get feedback, try to improve and finally feel accomplished. Sure, it takes extra effort to give feedback, but the contributor is likely to feel ownership of their work and later return to further improve it. If a submission looks hopelessly low quality and you feel that giving feedback is a waste of time, you can simply respond with something along the lines of: Thanks for your contribution and interest in helping Debian. Unfortunately, looking at the commits, I see several shortcomings, and it is unlikely a normal review process is enough to help you finalize this. Please reach out to Debian Mentors to get a mentor who can give you more personalized feedback. There might also be contributors who just dump the code , ignore your feedback and never return to finalize their submission. If a contributor does not return to finalize their submission in 3-6 months, I will in my own projects simply finalize it myself and thank the contributor in the commit message (but not mark them as the author). Despite best practices, you will occasionally still end up doing some things in vain, but that is how volunteer collaboration works. We all just need to accept that some communication will inevitably feel like wasted effort, but it should be viewed as a necessary investment in order to get the benefits from the times when the communication led to real and valuable collaboration. Please just do not treat all contributors as if they are unlikely to ever contribute again; otherwise, your behavior will cause them not to contribute again. If you want to grow a tree, you need to plant several seeds.

Approving and merging Assuming review goes well and you are ready to approve, and if you are the only maintainer, you can proceed to merge right away. If there are multiple maintainers, or if you otherwise think that someone else might want to chime in before it is merged, use the Approve button to show that you approve the change but leave it unmerged. The person who approved does not necessarily have to be the person who merges. The point of the Merge Request review is not separation of duties in committing and merging the main purpose of a code review is to have a different set of eyeballs looking at the change before it is committed into the main development branch for all eternity. In some packages, the submitter might actually merge themselves once they see another developer has approved. In some rare Debian projects, there might even be separate people taking the roles of submitting, approving and merging, but most of the time these three roles are filled by two people either as submitter and approver+merger or submitter+merger and approver. If you are not a maintainer at all and do not have permissions to click Approve, simply post a comment summarizing your review and that you approve it and support merging it. This can help the maintainers review and merge faster.

Making a Merge Request for a new upstream version import Unlike many other Linux distributions, in Debian each source package has its own version control repository. The Debian sources consist of the upstream sources with an additional debian/ subdirectory that contains the actual Debian packaging. For the same reason, a typical Debian packaging Git repository has a debian/latest branch that has changes only in the debian/ subdirectory while the surrounding upstream files are the actual upstream files and have the actual upstream Git history. For details, see my post explaining Debian source packages in Git. Because of this Git branch structure, importing a new upstream version will typically modify three branches: debian/latest, upstream/latest and pristine-tar. When doing a Merge Request for a new upstream import, only submit one Merge Request for one branch: which means merging your new changes to the debian/latest branch. There is no need to submit the upstream/latest branch or the pristine-tar branch. Their contents are fixed and mechanically imported into Debian. There are no changes that the reviewer in Debian can request the submitter to do on these branches, so asking for feedback and comments on them is useless. All review, comments and re-reviews concern the content of the debian/latest branch only. It is not even necessary to use the debian/latest branch for a new upstream version. Personally, I always execute the new version import (with gbp import-orig --verbose --uscan) and prepare and test everything on debian/latest, but when it is time to submit it for review, I run git checkout -b import/$(dpkg-parsechangelog -SVersion) to get a branch named e.g. import/1.0.1 and then push that for review.

Reviewing a Merge Request for a new upstream version import Reviewing and testing a new upstream version import is a bit tricky currently, but possible. The key is to use gbp pull to automate fetching all branches from the submitter s fork. Assume you are reviewing a submission targeting the Glow package repository and there is a Merge Request from user otto s fork. As the maintainer, you would run the commands:
git remote add otto https://salsa.debian.org/otto/glow.git
gbp pull --verbose otto
If there was feedback in the first round and you later need to pull a new version for re-review, running gbp pull --force will not suffice, and this trick of manually fetching each branch and resetting them to the submitter s version is needed:
for BRANCH in pristine-tar upstream debian/latest
do
git checkout $BRANCH
git reset --hard origin/$BRANCH
git pull --force https://salsa.debian.org/otto/glow.git $BRANCH
done
Once review is done, either click Approve and let the submitter push everything, or alternatively, push all the branches you pulled locally yourself. In GitLab and other forges, the Merge Request will automatically be marked as Merged once the commit ID that was the head of the Merge Request is pushed to the target branch.

Please allow enough time for everyone to participate When working on Debian, keep in mind that it is a community of volunteers. It is common for people to do Debian stuff only on weekends, so you should patiently wait for at least a week so that enough workdays and weekend days have passed for the people you interact with to have had time to respond on their own Debian time. Having to wait may feel annoying and disruptive, but try to look at the upside: you do not need to do extra work simply while waiting for others. In some cases, that waiting can be useful thanks to the sleep on it phenomenon: when you yourself look at your own submission some days later with fresh eyes, you might notice something you overlooked earlier and improve your code change even without other people s feedback!

Contribute reviews! The last but not least suggestion is to make a habit of contributing reviews to packages you do not maintain. As we already see in large open source projects, such as the Linux kernel, they have far more code submissions than they can handle. The bottleneck for progress and maintaining quality becomes the reviews themselves. For Debian, as an organization and as a community, to be able to renew and grow new contributors, we need more of the senior contributors to shift focus from merely maintaining their packages and writing code to also intentionally interact with new contributors and guide them through the process of creating great open source software. Reviewing code is an effective way to both get tangible progress on individual development items and to transfer culture to a new generation of developers.

Why aren t 100% of all Debian source packages hosted on Salsa? As seen at trends.debian.net, more and more packages are using Salsa. Debian does not, however, have any policy about it. In fact, the Debian Policy Manual does not even mention the word Salsa anywhere. Adoption of Salsa has so far been purely organic, as in Debian each package maintainer has full freedom to choose whatever preferences they have regarding version control. I hope the trend to use Salsa will continue and more shared workflows emerge so that collaboration gets easier. To drive the culture of using Merge Requests and more, I drafted the Debian proposal DEP-18: Encourage Continuous Integration and Merge Request based Collaboration for Debian packages. If you are active in Debian and you think DEP-18 is beneficial for Debian, please give a thumbs up at dep-team/deps!21.

20 July 2025

Michael Prokop: What to expect from Debian/trixie #newintrixie

Trixie Banner, Copyright 2024 Elise Couper Update on 2025-07-28: added note about Debian 13/trixie support for OpenVox (thanks, Ben Ford!) Debian v13 with codename trixie is scheduled to be published as new stable release on 9th of August 2025. I was the driving force at several of my customers to be well prepared for the upcoming stable release (my efforts for trixie started in August 2024). On the one hand, to make sure packages we care about are available and actually make it into the release. On the other hand, to ensure there are no severe issues that make it into the release and to get proper and working upgrades. So far everything is looking pretty well and working fine, the efforts seemed to have payed off. :) As usual with major upgrades, there are some things to be aware of, and hereby I m starting my public notes on trixie that might be worth for other folks. My focus is primarily on server systems and looking at things from a sysadmin perspective. Further readings As usual start at the official Debian release notes, make sure to especially go through What s new in Debian 13 + issues to be aware of for trixie (strongly recommended read!). Package versions As a starting point, let s look at some selected packages and their versions in bookworm vs. trixie as of 2025-07-20 (mainly having amd64 in mind):
Package bookworm/v12 trixie/v13
ansible 2.14.3 2.19.0
apache 2.4.62 2.4.64
apt 2.6.1 3.0.3
bash 5.2.15 5.2.37
ceph 16.2.11 18.2.7
docker 20.10.24 26.1.5
dovecot 2.3.19 2.4.1
dpkg 1.21.22 1.22.21
emacs 28.2 30.1
gcc 12.2.0 14.2.0
git 2.39.5 2.47.2
golang 1.19 1.24
libc 2.36 2.41
linux kernel 6.1 6.12
llvm 14.0 19.0
lxc 5.0.2 6.0.4
mariadb 10.11 11.8
nginx 1.22.1 1.26.3
nodejs 18.13 20.19
openjdk 17.0 21.0
openssh 9.2p1 10.0p1
openssl 3.0 3.5
perl 5.36.0 5.40.1
php 8.2+93 8.4+96
podman 4.3.1 5.4.2
postfix 3.7.11 3.10.3
postgres 15 17
puppet 7.23.0 8.10.0
python3 3.11.2 3.13.5
qemu/kvm 7.2 10.0
rsync 3.2.7 3.4.1
ruby 3.1 3.3
rust 1.63.0 1.85.0
samba 4.17.12 4.22.3
systemd 252.36 257.7-1
unattended-upgrades 2.9.1 2.12
util-linux 2.38.1 2.41
vagrant 2.3.4 2.3.7
vim 9.0.1378 9.1.1230
zsh 5.9 5.9
Misc unsorted apt The new apt version 3.0 brings several new features, including: systemd systemd got upgraded from v252.36-1~deb12u1 to 257.7-1 and there are lots of changes. Be aware that systemd v257 has a new net.naming_scheme, v257 being PCI slot number is now read from firmware_node/sun sysfs file. The naming scheme based on devicetree aliases was extended to support aliases for individual interfaces of controllers with multiple ports. This might affect you, see e.g. #1092176 and #1107187, the Debian Wiki provides further useful information. There are new systemd tools available: The tools provided by systemd gained several new options: Debian s systemd ships new binary packages: Linux Kernel The trixie release ships a Linux kernel based on latest longterm version 6.12. As usual there are lots of changes in the kernel area, including better hardware support, and this might warrant a separate blog entry. To highlight some changes with Debian trixie: See Kernelnewbies.org for further changes between kernel versions. Configuration management For puppet users, Debian provides the puppet-agent (v8.10.0), puppetserver (v8.7.0) and puppetdb (v8.4.1) packages. Puppet s upstream does not provide packages for trixie, yet. Given how long it took them for Debian bookworm, and with their recent Plans for Open Source Puppet in 2025, it s unclear when (and whether at all) we might get something. As a result of upstream behavior, also the OpenVox project evolved, and they already provide Debian 13/trixie support (https://apt.voxpupuli.org/openvox8-release-debian13.deb). FYI: the AIO puppet-agent package for bookworm (v7.34.0-1bookworm) so far works fine for me on Debian/trixie. Be aware that due to the apt-key removal you need a recent version of the puppetlabs-apt for usage with trixie. The puppetlabs-ntp module isn t yet ready for trixie (regarding ntp/ntpsec), if you should depend on that. ansible is available and made it with version 2.19 into trixie. Prometheus stack Prometheus server was updated from v2.42.0 to v2.53, and all the exporters that got shipped with bookworm are still around (in more recent versions of course). Trixie gained some new exporters: Virtualization docker (v26.1.5), ganeti (v3.1.0), libvirt (v11.3.0, be aware of significant changes to libvirt packaging), lxc (v6.0.4), podman (v5.4.2), openstack (see openstack-team on Salsa), qemu/kvm (v10.0.2), xen (v4.20.0) are all still around. Proxmox already announced their PVE 9.0 BETA, being based on trixie and providing 6.14.8-1 kernel, QEMU 10.0.2, LXC 6.0.4, OpenZFS 2.3.3. Vagrant is available in version 2.3.7, but Vagrant upstream does not provide packages for trixie yet. Given that HashiCorp adopted the BSL, the future of vagrant in Debian is unclear. If you re relying on VirtualBox, be aware that upstream doesn t provide packages for trixie, yet. VirtualBox is available from Debian/unstable (version 7.1.12-dfsg-1 as of 2025-07-20), but not shipped with stable release since quite some time (due to lack of cooperation from upstream on security support for older releases, see #794466). Be aware that starting with Linux kernel 6.12, KVM initializes virtualization on module loading by default. This prevents VirtualBox VMs from starting. In order to avoid this, either add kvm.enable_virt_at_load=0 parameter into kernel command line or unload the corresponding kvm_intel / kvm_amd module. If you want to use Vagrant with VirtualBox on trixie, be aware that Debian s vagrant package as present in trixie doesn t support the VirtualBox package version 7.1 as present in Debian/unstable (manually patching vagrant s meta.rb and rebuilding the package without Breaks: virtualbox (>= 7.1) is known to be working). util-linux The are plenty of new options available in the tools provided by util-linux: Now no longer present in util-linux as of trixie: The following binaries got moved from util-linux to the util-linux-extra package: And the util-linux-extra package also provides new tools: OpenSSH OpenSSH was updated from v9.2p1 to 10.0p1-5, so if you re interested in all the changes, check out the release notes between those versions (9.3, 9.4, 9.5, 9.6, 9.7, 9.8, 9.9 + 10.0). Let s highlight some notable behavior changes in Debian: There are some notable new features: Thanks to everyone involved in the release, looking forward to trixie + and happy upgrading!
Let s continue with working towards Debian/forky. :)

24 June 2025

Matthew Garrett: Why is there no consistent single signon API flow?

Single signon is a pretty vital part of modern enterprise security. You have users who need access to a bewildering array of services, and you want to be able to avoid the fallout of one of those services being compromised and your users having to change their passwords everywhere (because they're clearly going to be using the same password everywhere), or you want to be able to enforce some reasonable MFA policy without needing to configure it in 300 different places, or you want to be able to disable all user access in one place when someone leaves the company, or, well, all of the above. There's any number of providers for this, ranging from it being integrated with a more general app service platform (eg, Microsoft or Google) or a third party vendor (Okta, Ping, any number of bizarre companies). And, in general, they'll offer a straightforward mechanism to either issue OIDC tokens or manage SAML login flows, requiring users present whatever set of authentication mechanisms you've configured.
This is largely optimised for web authentication, which doesn't seem like a huge deal - if I'm logging into Workday then being bounced to another site for auth seems entirely reasonable. The problem is when you're trying to gate access to a non-web app, at which point consistency in login flow is usually achieved by spawning a browser and somehow managing submitting the result back to the remote server. And this makes some degree of sense - browsers are where webauthn token support tends to live, and it also ensures the user always has the same experience.

But it works poorly for CLI-based setups. There's basically two options - you can use the device code authorisation flow, where you perform authentication on what is nominally a separate machine to the one requesting it (but in this case is actually the same) and as a result end up with a straightforward mechanism to have your users socially engineered into giving Johnny Badman a valid auth token despite webauthn nominally being unphisable (as described years ago), or you reduce that risk somewhat by spawning a local server and POSTing the token back to it - which works locally but doesn't work well if you're dealing with trying to auth on a remote device. The user experience for both scenarios sucks, and it reduces a bunch of the worthwhile security properties that modern MFA supposedly gives us.

There's a third approach, which is in some ways the obviously good approach and in other ways is obviously a screaming nightmare. All the browser is doing is sending a bunch of requests to a remote service and handling the response locally. Why don't we just do the same? Okta, for instance, has an API for auth. We just need to submit the username and password to that and see what answer comes back. This is great until you enable any kind of MFA, at which point the additional authz step is something that's only supported via the browser. And basically everyone else is the same.

Of course, when we say "That's only supported via the browser", the browser is still just running some code of some form and we can figure out what it's doing and do the same. Which is how you end up scraping constants out of Javascript embedded in the API response in order to submit that data back in the appropriate way. This is all possible but it's incredibly annoying and fragile - the contract with the identity provider is that a browser is pointed at a URL, not that any of the internal implementation remains consistent.

I've done this. I've implemented code to scrape an identity provider's auth responses to extract the webauthn challenges and feed those to a local security token without using a browser. I've also written support for forwarding those challenges over the SSH agent protocol to make this work with remote systems that aren't running a GUI. This week I'm working on doing the same again, because every identity provider does all of this differently.

There's no fundamental reason all of this needs to be custom. It could be a straightforward "POST username and password, receive list of UUIDs describing MFA mechanisms, define how those MFA mechanisms work". That even gives space for custom auth factors (I'm looking at you, Okta Fastpass). But instead I'm left scraping JSON blobs out of Javascript and hoping nobody renames a field, even though I only care about extremely standard MFA mechanisms that shouldn't differ across different identity providers.

Someone, please, write a spec for this. Please don't make it be me.

comment count unavailable comments

15 June 2025

Iustin Pop: Markdown lint and site cleanup

I was not aware that one can write bad Markdown, since Markdown has such a simple syntax, that I thought you just write, and it s fine. Na ve, I know! I ve started editing the files for this blog/site with Visual Studio Code too, and I had from another project the markdown lint extension installed, so as I was opening old files, more and more problems appeared. On a whim, I searched and found the lint all files command, and after running it, oops more than 400 problems! Now, some of them were entirely trivial and a matter of subjective style, like mixing both underscore and asterisk for emphasis in a single file, and asterisks and dashes for list items. Others, seemingly trivial like tab indentation, were actually also causing rendering issues, so fixing that solved a real cosmetic issue. But some of the issues flagged were actual problems. For example, one sentence that I had, was:
there seems to be some race condition between <something> and ntp
Here something was interpreted as an (invalid) HTML tag, and not rendered at all. Another problem, but more minor, was that I had links to Wikipedia with spaces in the link name, which Visual Studio Code breaks at first space, rather than encoded spaces or underscores-based, as Wikipedia generates today. In the rendered output, Pandoc seemed to do the right think though. However, the most interesting issue that was flagged was no details in HTML links, i.e. links of the form:
for more details, see [here](http://example.com).
Which works for non-visually impaired people, but not for people using assistive technologies. And while trying to fix this, it turns out that you can do much better, for everyone, because here is really non-descriptive. You can use either the content as label ( an article about configuring BIND ), or the destination ( an article on this-website ), rather than the plain here . The only, really only check I disabled, was tweaking the trailing punctuation checks in headers, as I really like to write a header that ends with exclamation marks. I like exclamation marks in general! So why not use them in headers too. The question mark is allowlisted by default, though that I use rarely. During the changes/tweaks, I also did random improvements, but I didn t change the updated tag, since most of them were minor. But a non-minor thing was tweaking the CSS for code blocks, since I had a really stupid non-symmetry between top and bottom padding (5px vs 0), and which I don t know where it came from. But the MDN article on padding has as an example exactly what I had (except combined, I had it split). Did I just copy blindly? Possible So, all good and then, and I hope this doesn t trigger a flow of updates on any aggregators, since all the changes were really trivial. And while I don t write often, I did touch about 60 posts or pages, ouch! Who knew that changing editors can have such a large impact

11 June 2025

Iustin Pop: This blog finally goes git-annex!

A long, long time ago I have a few pictures on this blog, mostly in earlier years, because even with small pictures, the git repository became 80MiB soon this is not much in absolute terms, but the actual Markdown/Haskell/CSS/HTML total size is tiny compared to the picture, PDFs and fonts. I realised I need a better solution, probably about ten years ago, and that I should investigate git-annex. Then time passed, and I heard about git-lfs, so I thought that s the way forward. Now, I recently got interested again into doing something about this repository, and started researching.

Detour: git-lfs I was sure that git-lfs, being supported by large providers, would be the modern solution. But to my surprise, git-lfs is very server centric, which in hindsight makes sense, but for a home setup, it s not very good. Maybe I misunderstood, but git-lfs is more a protocol/method for a forge to store files, rather than an end-user solution. But then you need to backup those files separately (together with the rest of the forge), or implement another way of safeguarding them. Further details such as the fact that it keeps two copies of the files (one in the actual checked-out tree, one in internal storage) means it s not a good solution. Well, for my blog yes, but not in general. Then posts on Reddit about horror stories people being locked out of github due to quota, as an example, or this Stack Overflow post about git-lfs constraining how one uses git, convinced me that s not what I want. To each their own, but not for me I might want to push this blog s repo to github, but I definitely wouldn t want in that case to pay for github storage for my blog images (which are copies, not originals). And yes, even in 2025, those quotas are real GitHub limits and I agree with GitHub, storage and large bandwidth can t be free.

Back to the future: git-annex So back to git-annex. I thought it s going to be a simple thing, but oh boy, was I wrong. It took me half a week of continuous (well, in free time) reading and discussions with LLMs to understand a bit how it works. I think, honestly, it s a bit too complex, which is why the workflows page lists seven (!) levels of workflow complexity, from fully-managed, to fully-manual. IMHO, respect to the author for the awesome tool, but if you need a web app to help you manage git, it hints that the tool is too complex. I made the mistake of running git annex sync once, to realise it actually starts pushing to my upstream repo and creating new branches and whatnot, so after enough reading, I settled on workflow 6/7, since I don t want another tool to manage my git history. Maybe I m an outlier here, but everything automatic is a bit too much for me. Once you do managed yourself how git-annex works (on the surface, at least), it is a pretty cool thing. It uses a git-annex git branch to store metainformation, and that is relatively clean. If you do run git annex sync, it creates some extra branches, which I don t like, but meh.

Trick question: what is a remote? One of the most confusing things about git-annex was understanding its remote concept. I thought a remote is a place where you replicate your data. But not, that s a special remote. A normal remote is a git remote, but which is expected to be git/ssh/with command line access. So if you have a git+ssh remote, git-annex will not only try to push it s above-mentioned branch, but also copy the files. If such a remote is on a forge that doesn t support git-annex, then it will complain and get confused. Of course, if you read the extensive docs, you just do git config remote.<name>.annex-ignore true, and it will understand that it should not sync to it. But, aside, from this case, git-annex expects that all checkouts and clones of the repository are both metadata and data. And if you do any annex commands in them, all other clones will know about them! This can be unexpected, and you find people complaining about it, but nowadays there s a solution:
git clone   dir && cd dir
git config annex.private true
git annex init "temp copy"
This is important. Any leaf git clone must be followed by that annex.private true config, especially on CI/CD machines. Honestly, I don t understand why by default clones should be official data stores, but it is what it is. I settled on not making any of my checkouts stable , but only the actual storage places. Except those are not git repositories, but just git-annex storage things. I.e., special remotes. Is it confusing enough yet ?

Special remotes The special remotes, as said, is what I expected to be the normal git annex remotes, i.e. places where the data is stored. But well, they exist, and while I m only using a couple simple ones, there is a large number of them. Among the interesting ones: git-lfs, a remote that allows also storing the git repository itself (git-remote-annex), although I m bit confused about this one, and most of the common storage providers via the rclone remote. Plus, all of the special remotes support encryption, so this is a really neat way to store your files across a large number of things, and handle replication, number of copies, from which copy to retrieve, etc. as you with.

And many of other features git-annex has tons of other features, so to some extent, the sky s the limit. Automatic selection of what to add git it vs plain git, encryption handling, number of copies, clusters, computed files, etc. etc. etc. I still think it s cool but too complex, though!

Uses Aside from my blog post, of course. I ve seen blog posts/comments about people using git-annex to track/store their photo collection, and I could see very well how the remote encrypted repos any of the services supported by rclone could be an N+2 copy or so. For me, tracking photos would be a bit too tedious, but it could maybe work after more research. A more practical thing would probably be replicating my local movie collection (all legal, to be clear) better than just run rsync from time to time and tracking the large files in it via git-annex. That s an exercise for another day, though, once I get more mileage with it - my blog pictures are copies, so I don t care much if they get lost, but movies are primary online copies, and I don t want to re-dump the discs. Anyway, for later.

Migrating to git-annex Migrating here means ending in a state where all large files are in git-annex, and the plain git repo is small. Just moving the files to git annex at the current head doesn t remove them from history, so your git repository is still large; it won t grow in the future, but remains with old size (and contains the large files in its history). In my mind, a nice migration would be: run a custom command, and all the history is migrated to git-annex, so I can go back in time and the still use git-annex. I na vely expected this would be easy and already available, only to find comments on the git-annex site with unsure git-filter-branch calls and some web discussions. This is the discussion on the git annex website, but it didn t make me confident it would do the right thing. But that discussion is now 8 years old. Surely in 2025, with git-filter-repo, it s easier? And, maybe I m missing something, but it is not. Not from the point of view of plain git, that s easy, but because interacting with git-annex, which stores its data in git itself, so doing this properly across successive steps of a repo (when replaying the commits) is, I think, not well defined behaviour. So I was stuck here for a few days, until I got an epiphany: As I m going to rewrite the repository, of course I m keeping a copy of it from before git-annex. If so, I don t need the history, back in time, to be correct in the sense of being able to retrieve the binary files too. It just needs to be correct from the point of view of the actual Markdown and Haskell files that represent the meat of the blog. This simplified the problem a lot. At first, I wanted to just skip these files, but this could also drop commits (git-filter-repo, by default, drops the commits if they re empty), and removing the files loses information - when they were added, what were the paths, etc. So instead I came up with a rather clever idea, if I might say so: since git-annex replaces files with symlinks already, just replace the files with symlinks in the whole history, except symlinks that are dangling (to represent the fact that files are missing). One could also use empty files, but empty files are more valid in a sense than dangling symlinks, hence why I settled on those. Doing this with git-filter-repo is easy, in newer versions, with the new --file-info-callback. Here is the simple code I used:
import os
import os.path
import pathlib

SKIP_EXTENSIONS= 'jpg', 'jpeg', 'png', 'pdf', 'woff', 'woff2' 
FILE_MODES =  b"100644", b"100755" 
SYMLINK_MODE = b"120000"

fas_string = filename.decode()
path = pathlib.PurePosixPath(fas_string)
ext = path.suffix.removeprefix('.')

if ext not in SKIP_EXTENSIONS:
  return (filename, mode, blob_id)

if mode not in FILE_MODES:
  return (filename, mode, blob_id)

print(f"Replacing ' filename ' (extension '. ext ') in  os.getcwd() ")

symlink_target = '/none/binary-file-removed-from-git-history'.encode()
new_blob_id = value.insert_file_with_contents(symlink_target)
return (filename, SYMLINK_MODE, new_blob_id)
This goes and replaces files with a symlink to nowhere, but the symlink should explain why it s dangling. Then later renames or moving the files around work naturally , as the rename/mv doesn t care about file contents. Then, when the filtering is done via:
git-filter-repo --file-info-callback <(cat ~/filter-big.py ) --force
It is easy to onboard to git annex:
  • remove all dangling symlinks
  • copy the (binary) files from the original repository
  • since they re named the same, and in the same places, git sees a type change
  • then simply run git annex add on those files
For me it was easy as all such files were in a few directories, so just copying those directories back, a few git-annex add commands, and done. Of course, then adding a few rsync remotes, git annex copy --to, and the repository was ready. Well, I also found a bug in my own Hakyll setup: on a fresh clone, when the large files are just dangling symlinks, the builder doesn t complain, just ignores the images. Will have to fix.

Other resources This is a blog that I read at the beginning, and I found it very useful as an intro: https://switowski.com/blog/git-annex/. It didn t help me understand how it works under the covers, but it is well written. The author does use the sync command though, which is too magic for me, but also agrees about its complexity

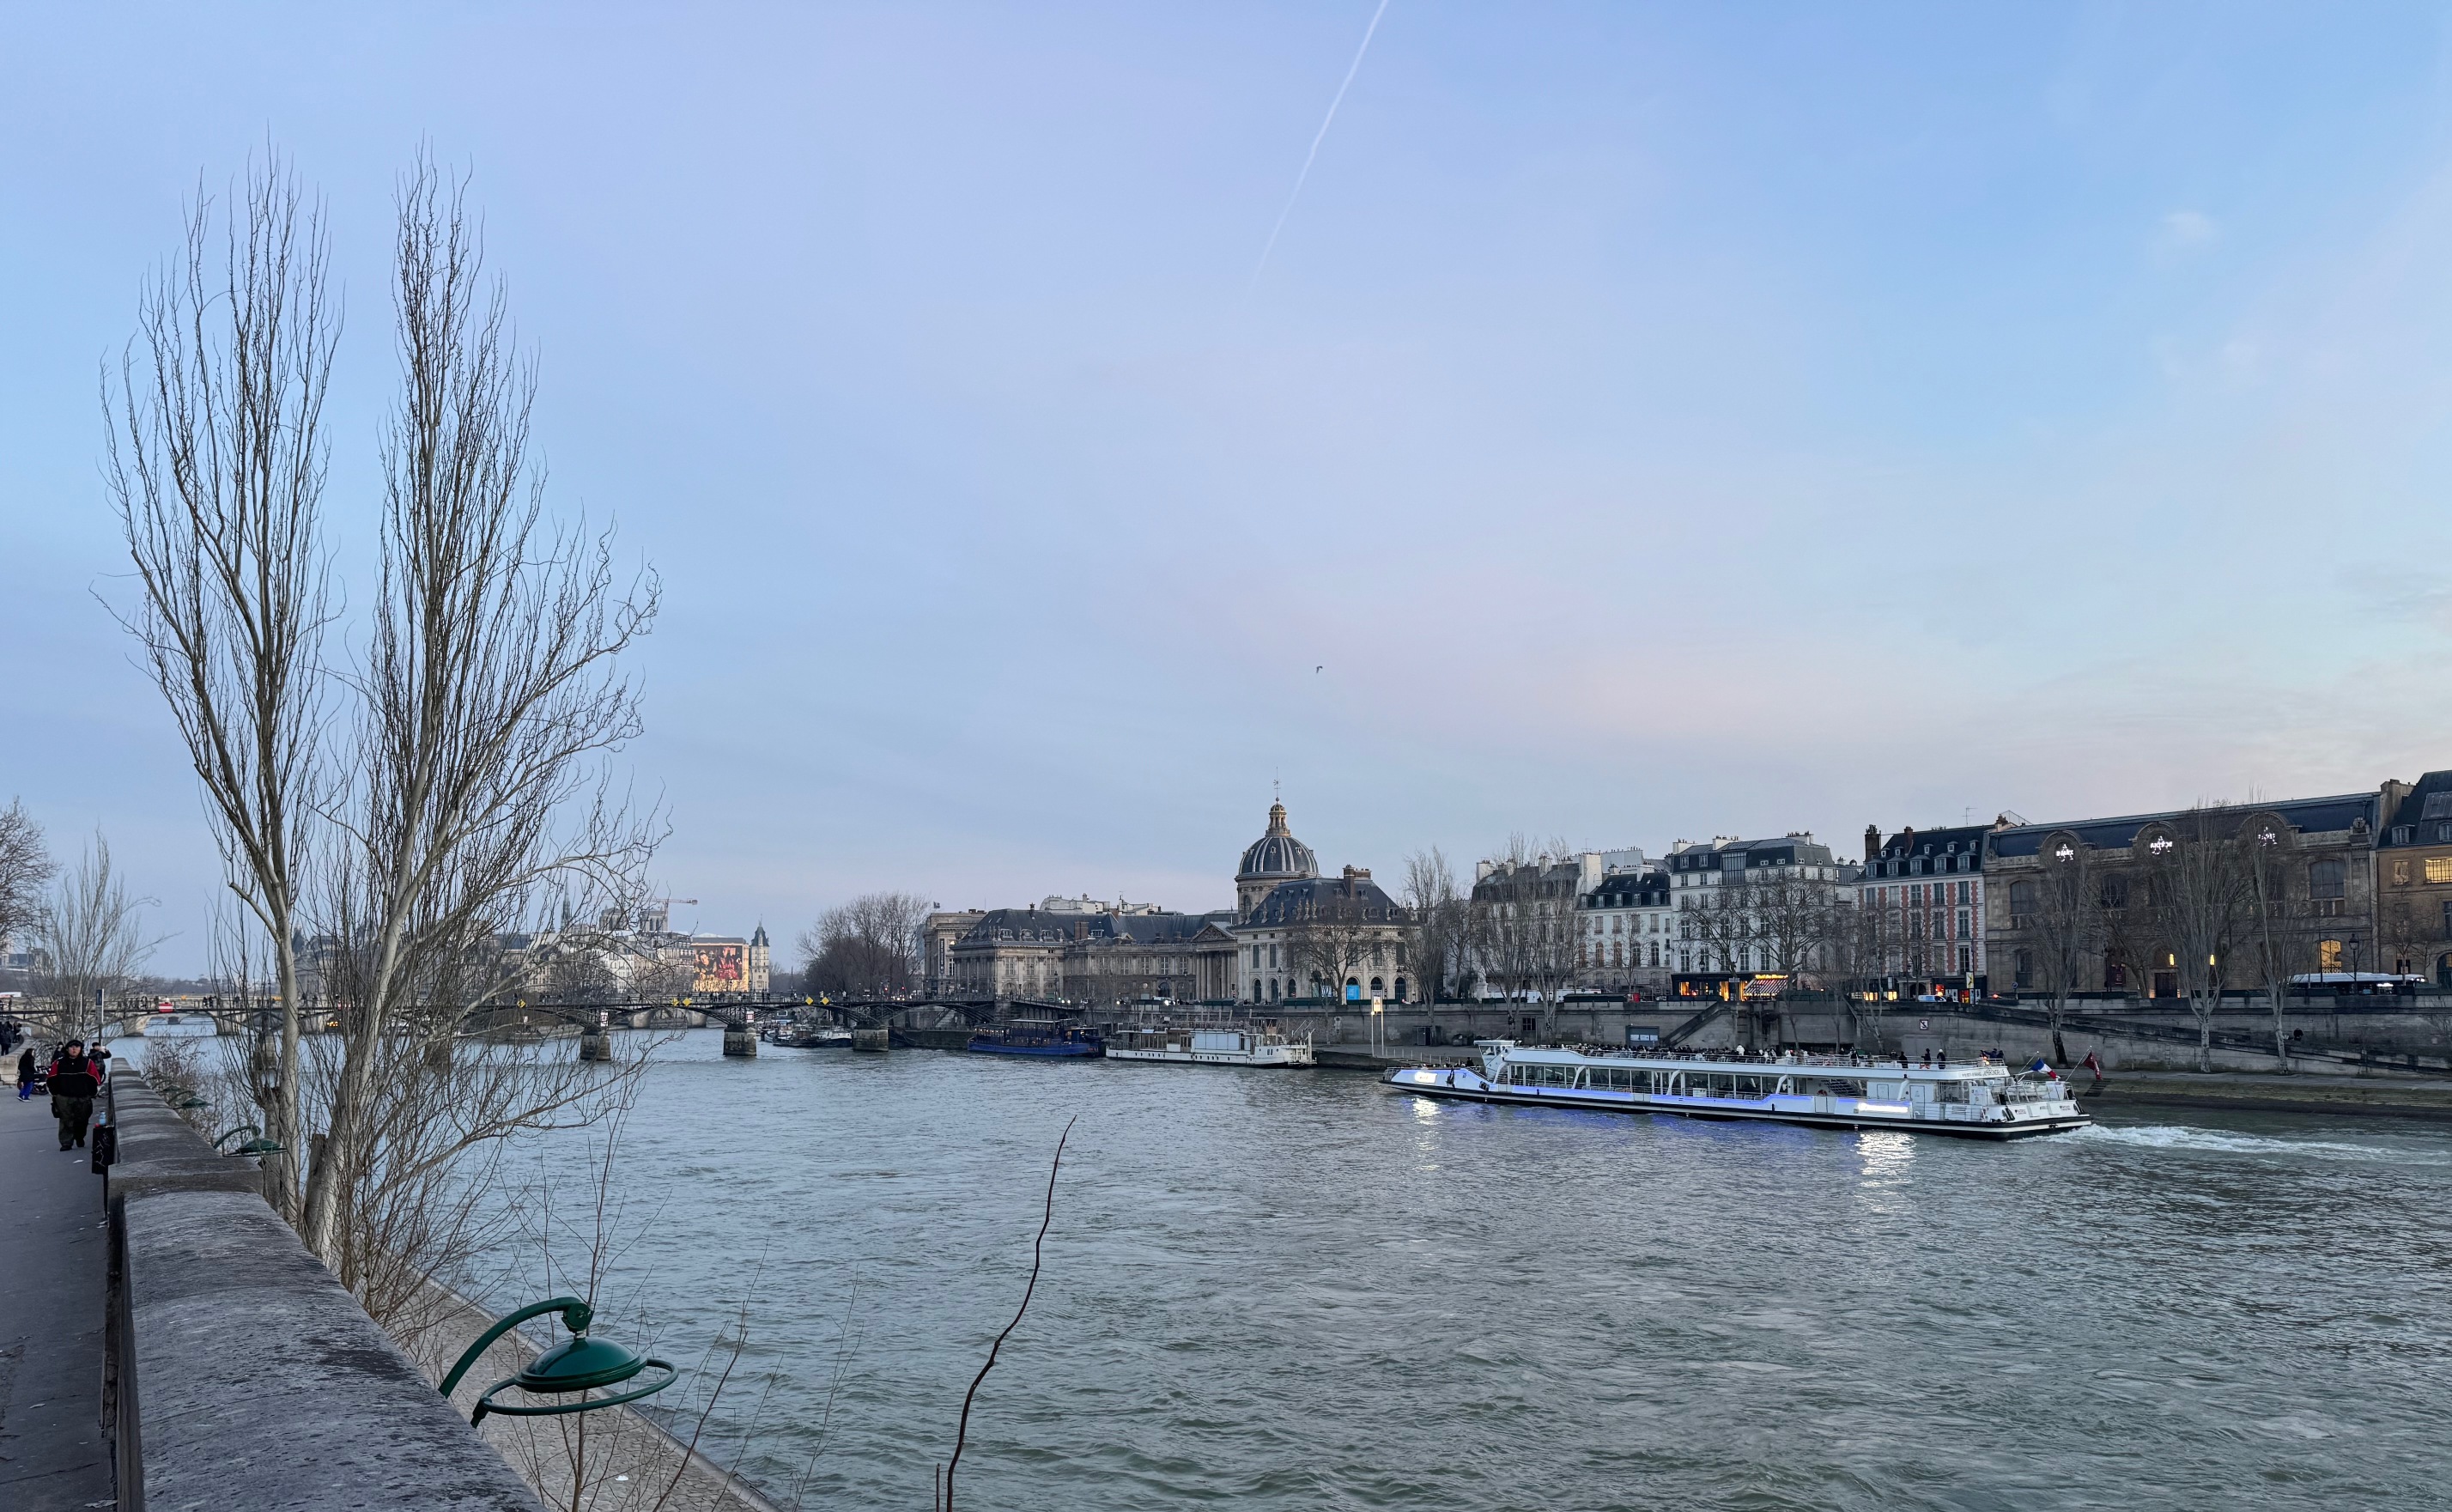
The proof is in the pudding And now, for the actual first image to be added that never lived in the old plain git repository. It s not full-res/full-size, it s cropped a bit on the bottom. Earlier in the year, I went to Paris for a very brief work trip, and I walked around a bit it was more beautiful than what I remembered from way way back. So a bit random selection of a picture, but here it is:
Un bateau sur la Seine Un bateau sur la Seine
Enjoy!

1 June 2025

Emmanuel Kasper: ARM64 desktop as daily driver

I have bought myself an expensive ARM64 workstation, the System 76 Thelio Astra that I intend to use as my main desktop computer for the next 15 years, running Debian. The box is basically a server motherboard repurposed in a good desktop chassis. In Europe it seems you can order similar ready systems here. The hardware is well supported by Debian 12 and Debian testing.I had some initial issues with graphics, due to the board being designed for a server use, but I am solving these as we go. Annoyances I got so far:
  • When you power on the machine using the power supply switch, you have to wait for the BMC to finished its startup sequence, before the front power button does anything. As starting the BMC can take 90 seconds, I thought initially the machine was dead on arrival.
  • The default graphical output is redirected to the BMC Serial over LAN, which means if you want to install Debian using an attached display you need to force the output on the attached display passing console=tty0 as an installer parameter.
  • Finally the Xorg Nouveau driver does not work with the Nvidia A400 GPU I got with the machine. After passing nodemodeset as a kernel parameter, I can force Xorg to use an unaccelerated framebuffer, which at least displays something. I passed this parameter to the installer, so that I could install in graphical mode. The driver from Nvidia works, but I d like very much to get Nouveau running.
Ugly point
  • A server mother board we said. This mean there is NO suspend to RAM, you have to power off if you don t want to keep the machine on all the time. As the boot sequence is long (server board again) I am pondering setting a startup time in the UEFI firmware to turn the box on at specific usage time.
Good points
  • The firmware of the machine is a standard EFI, which means you can use the debian arm64 installer on an USB stick straight away, without any kind of device tree / bootloader fiddling.
  • The 3 Nics, Wifi, bluetooth were all recognized on first boot.
  • I was afraid the machine would be loud. However it is quiet, you hear the humming of a fan, but it is quieter than most desktops I owned, from the Atari TT to an all in one Lenovo M92z I used for 10 years. I am certainly not a hardware and cooling specialist, but meseems the quietness comes from slow rotating but very large fans.
  • Due the clean design of Linux and Debian, thousands of packages working correctly on ARM64, starting with the Gnome desktop environment and Firefox.
  • The documentation from system76 is fine, their Ubuntu 20.04 setup guide was helpful to understand the needed parameters mentioned above.
Update: The display is working correctly with the nouveau driver after installing the non-free Nvidia firmware. See the Debian wiki.

26 May 2025

Otto Kek l inen: Creating Debian packages from upstream Git

Featured image of post Creating Debian packages from upstream GitIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:
  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

25 May 2025

Otto Kek l inen: New Debian package creation from upstream git repository

Featured image of post New Debian package creation from upstream git repositoryIn this post, I demonstrate the optimal workflow for creating new Debian packages in 2025, preserving the upstream git history. The motivation for this is to lower the barrier for sharing improvements to and from upstream, and to improve software provenance and supply-chain security by making it easy to inspect every change at any level using standard git tooling. Key elements of this workflow include: To make the instructions so concrete that anyone can repeat all the steps themselves on a real package, I demonstrate the steps by packaging the command-line tool Entr. It is written in C, has very few dependencies, and its final Debian source package structure is simple, yet exemplifies all the important parts that go into a complete Debian package:

  1. Creating a new packaging repository and publishing it under your personal namespace on salsa.debian.org.
  2. Using dh_make to create the initial Debian packaging.
  3. Posting the first draft of the Debian packaging as a Merge Request (MR) and using Salsa CI to verify Debian packaging quality.
  4. Running local builds efficiently and iterating on the packaging process.

Create new Debian packaging repository from the existing upstream project git repository First, create a new empty directory, then clone the upstream Git repository inside it:
shell
mkdir debian-entr
cd debian-entr
git clone --origin upstreamvcs --branch master \
 --single-branch https://github.com/eradman/entr.git
Using a clean directory makes it easier to inspect the build artifacts of a Debian package, which will be output in the parent directory of the Debian source directory. The extra parameters given to git clone lay the foundation for the Debian packaging git repository structure where the upstream git remote name is upstreamvcs. Only the upstream main branch is tracked to avoid cluttering git history with upstream development branches that are irrelevant for packaging in Debian. Next, enter the git repository directory and list the git tags. Pick the latest upstream release tag as the commit to start the branch upstream/latest. This latest refers to the upstream release, not the upstream development branch. Immediately after, branch off the debian/latest branch, which will have the actual Debian packaging files in the debian/ subdirectory.
shell
cd entr
git tag # shows the latest upstream release tag was '5.6'
git checkout -b upstream/latest 5.6
git checkout -b debian/latest
%% init:   'gitGraph':   'mainBranchName': 'master'      %%
gitGraph:
checkout master
commit id: "Upstream 5.6 release" tag: "5.6"
branch upstream/latest
checkout upstream/latest
commit id: "New upstream version 5.6" tag: "upstream/5.6"
branch debian/latest
checkout debian/latest
commit id: "Initial Debian packaging"
commit id: "Additional change 1"
commit id: "Additional change 2"
commit id: "Additional change 3"
At this point, the repository is structured according to DEP-14 conventions, ensuring a clear separation between upstream and Debian packaging changes, but there are no Debian changes yet. Next, add the Salsa repository as a new remote which called origin, the same as the default remote name in git.
shell
git remote add origin git@salsa.debian.org:otto/entr-demo.git
git push --set-upstream origin debian/latest
This is an important preparation step to later be able to create a Merge Request on Salsa that targets the debian/latest branch, which does not yet have any debian/ directory.

Launch a Debian Sid (unstable) container to run builds in To ensure that all packaging tools are of the latest versions, run everything inside a fresh Sid container. This has two benefits: you are guaranteed to have the most up-to-date toolchain, and your host system stays clean without getting polluted by various extra packages. Additionally, this approach works even if your host system is not Debian/Ubuntu.
shell
cd ..
podman run --interactive --tty --rm --shm-size=1G --cap-add SYS_PTRACE \
 --env='DEB*' --volume=$PWD:/tmp/test --workdir=/tmp/test debian:sid bash
Note that the container should be started from the parent directory of the git repository, not inside it. The --volume parameter will loop-mount the current directory inside the container. Thus all files created and modified are on the host system, and will persist after the container shuts down. Once inside the container, install the basic dependencies:
shell
apt update -q && apt install -q --yes git-buildpackage dpkg-dev dh-make

Automate creating the debian/ files with dh-make To create the files needed for the actual Debian packaging, use dh_make:
shell
# dh_make --packagename entr_5.6 --single --createorig
Maintainer Name : Otto Kek l inen
Email-Address : otto@debian.org
Date : Sat, 15 Feb 2025 01:17:51 +0000
Package Name : entr
Version : 5.6
License : blank
Package Type : single
Are the details correct? [Y/n/q]

Done. Please edit the files in the debian/ subdirectory now.
Due to how dh_make works, the package name and version need to be written as a single underscore separated string. In this case, you should choose --single to specify that the package type is a single binary package. Other options would be --library for library packages (see libgda5 sources as an example) or --indep (see dns-root-data sources as an example). The --createorig will create a mock upstream release tarball (entr_5.6.orig.tar.xz) from the current release directory, which is necessary due to historical reasons and how dh_make worked before git repositories became common and Debian source packages were based off upstream release tarballs (e.g. *.tar.gz). At this stage, a debian/ directory has been created with template files, and you can start modifying the files and iterating towards actual working packaging.
shell
git add debian/
git commit -a -m "Initial Debian packaging"

Review the files The full list of files after the above steps with dh_make would be:
 -- entr
   -- LICENSE
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- configure
   -- data.h
   -- debian
     -- README.Debian
     -- README.source
     -- changelog
     -- control
     -- copyright
     -- gbp.conf
     -- entr-docs.docs
     -- entr.cron.d.ex
     -- entr.doc-base.ex
     -- manpage.1.ex
     -- manpage.md.ex
     -- manpage.sgml.ex
     -- manpage.xml.ex
     -- postinst.ex
     -- postrm.ex
     -- preinst.ex
     -- prerm.ex
     -- rules
     -- salsa-ci.yml.ex
     -- source
       -- format
     -- upstream
       -- metadata.ex
     -- watch.ex
   -- entr.1
   -- entr.c
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- system_test.sh
 -- entr_5.6.orig.tar.xz
You can browse these files in the demo repository. The mandatory files in the debian/ directory are:
  • changelog,
  • control,
  • copyright,
  • and rules.
All the other files have been created for convenience so the packager has template files to work from. The files with the suffix .ex are example files that won t have any effect until their content is adjusted and the suffix removed. For detailed explanations of the purpose of each file in the debian/ subdirectory, see the following resources:
  • The Debian Policy Manual: Describes the structure of the operating system, the package archive and requirements for packages to be included in the Debian archive.
  • The Developer s Reference: A collection of best practices and process descriptions Debian packagers are expected to follow while interacting with one another.
  • Debhelper man pages: Detailed information of how the Debian package build system works, and how the contents of the various files in debian/ affect the end result.
As Entr, the package used in this example, is a real package that already exists in the Debian archive, you may want to browse the actual Debian packaging source at https://salsa.debian.org/debian/entr/-/tree/debian/latest/debian for reference. Most of these files have standardized formatting conventions to make collaboration easier. To automatically format the files following the most popular conventions, simply run wrap-and-sort -vast or debputy reformat --style=black.

Identify build dependencies The most common reason for builds to fail is missing dependencies. The easiest way to identify which Debian package ships the required dependency is using apt-file. If, for example, a build fails complaining that pcre2posix.h cannot be found or that libcre2-posix.so is missing, you can use these commands:
shell
$ apt install -q --yes apt-file && apt-file update
$ apt-file search pcre2posix.h
libpcre2-dev: /usr/include/pcre2posix.h
$ apt-file search libpcre2-posix.so
libpcre2-dev: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3
libpcre2-posix3: /usr/lib/x86_64-linux-gnu/libpcre2-posix.so.3.0.6
The output above implies that the debian/control should be extended to define a Build-Depends: libpcre2-dev relationship. There is also dpkg-depcheck that uses strace to trace the files the build process tries to access, and lists what Debian packages those files belong to. Example usage:
shell
dpkg-depcheck -b debian/rules build

Build the Debian sources to generate the .deb package After the first pass of refining the contents of the files in debian/, test the build by running dpkg-buildpackage inside the container:
shell
dpkg-buildpackage -uc -us -b
The options -uc -us will skip signing the resulting Debian source package and other build artifacts. The -b option will skip creating a source package and only build the (binary) *.deb packages. The output is very verbose and gives a large amount of context about what is happening during the build to make debugging build failures easier. In the build log of entr you will see for example the line dh binary --buildsystem=makefile. This and other dh commands can also be run manually if there is a need to quickly repeat only a part of the build while debugging build failures. To see what files were generated or modified by the build simply run git status --ignored:
shell
$ git status --ignored
On branch debian/latest

Untracked files:
 (use "git add <file>..." to include in what will be committed)
 debian/debhelper-build-stamp
 debian/entr.debhelper.log
 debian/entr.substvars
 debian/files

Ignored files:
 (use "git add -f <file>..." to include in what will be committed)
 Makefile
 compat.c
 compat.o
 debian/.debhelper/
 debian/entr/
 entr
 entr.o
 status.o
Re-running dpkg-buildpackage will include running the command dh clean, which assuming it is configured correctly in the debian/rules file will reset the source directory to the original pristine state. The same can of course also be done with regular git commands git reset --hard; git clean -fdx. To avoid accidentally committing unnecessary build artifacts in git, a debian/.gitignore can be useful and it would typically include all four files listed as untracked above. After a successful build you would have the following files:
shell
 -- entr
   -- LICENSE
   -- Makefile -> Makefile.linux
   -- Makefile.bsd
   -- Makefile.linux
   -- Makefile.linux-compat
   -- Makefile.macos
   -- NEWS
   -- README.md
   -- compat.c
   -- compat.o
   -- configure
   -- data.h
   -- debian
     -- README.source.md
     -- changelog
     -- control
     -- copyright
     -- debhelper-build-stamp
     -- docs
     -- entr
       -- DEBIAN
         -- control
         -- md5sums
       -- usr
       -- bin
         -- entr
       -- share
       -- doc
         -- entr
         -- NEWS.gz
         -- README.md
         -- changelog.Debian.gz
         -- copyright
       -- man
       -- man1
       -- entr.1.gz
     -- entr.debhelper.log
     -- entr.substvars
     -- files
     -- gbp.conf
     -- patches
       -- PR149-expand-aliases-in-system-test-script.patch
       -- series
       -- system-test-skip-no-tty.patch
       -- system-test-with-system-binary.patch
     -- rules
     -- salsa-ci.yml
     -- source
       -- format
     -- tests
       -- control
     -- upstream
       -- metadata
       -- signing-key.asc
     -- watch
   -- entr
   -- entr.1
   -- entr.c
   -- entr.o
   -- missing
     -- compat.h
     -- kqueue_inotify.c
     -- strlcpy.c
     -- sys
     -- event.h
   -- status.c
   -- status.h
   -- status.o
   -- system_test.sh
 -- entr-dbgsym_5.6-1_amd64.deb
 -- entr_5.6-1.debian.tar.xz
 -- entr_5.6-1.dsc
 -- entr_5.6-1_amd64.buildinfo
 -- entr_5.6-1_amd64.changes
 -- entr_5.6-1_amd64.deb
 -- entr_5.6.orig.tar.xz
The contents of debian/entr are essentially what goes into the resulting entr_5.6-1_amd64.deb package. Familiarizing yourself with the majority of the files in the original upstream source as well as all the resulting build artifacts is time consuming, but it is a necessary investment to get high-quality Debian packages. There are also tools such as Debcraft that automate generating the build artifacts in separate output directories for each build, thus making it easy to compare the changes to correlate what change in the Debian packaging led to what change in the resulting build artifacts.

Re-run the initial import with git-buildpackage When upstreams publish releases as tarballs, they should also be imported for optimal software supply-chain security, in particular if upstream also publishes cryptographic signatures that can be used to verify the authenticity of the tarballs. To achieve this, the files debian/watch, debian/upstream/signing-key.asc, and debian/gbp.conf need to be present with the correct options. In the gbp.conf file, ensure you have the correct options based on:
  1. Does upstream release tarballs? If so, enforce pristine-tar = True.
  2. Does upstream sign the tarballs? If so, configure explicit signature checking with upstream-signatures = on.
  3. Does upstream have a git repository, and does it have release git tags? If so, configure the release git tag format, e.g. upstream-vcs-tag = %(version%~%.)s.
To validate that the above files are working correctly, run gbp import-orig with the current version explicitly defined:
shell
$ gbp import-orig --uscan --upstream-version 5.6
gbp:info: Launching uscan...
gpgv: Signature made 7. Aug 2024 07.43.27 PDT
gpgv: using RSA key 519151D83E83D40A232B4D615C418B8631BC7C26
gpgv: Good signature from "Eric Radman <ericshane@eradman.com>"
gbp:info: Using uscan downloaded tarball ../entr_5.6.orig.tar.gz
gbp:info: Importing '../entr_5.6.orig.tar.gz' to branch 'upstream/latest'...
gbp:info: Source package is entr
gbp:info: Upstream version is 5.6
gbp:info: Replacing upstream source on 'debian/latest'
gbp:info: Running Postimport hook
gbp:info: Successfully imported version 5.6 of ../entr_5.6.orig.tar.gz
As the original packaging was done based on the upstream release git tag, the above command will fetch the tarball release, create the pristine-tar branch, and store the tarball delta on it. This command will also attempt to create the tag upstream/5.6 on the upstream/latest branch.

Import new upstream versions in the future Forking the upstream git repository, creating the initial packaging, and creating the DEP-14 branch structure are all one-off work needed only when creating the initial packaging. Going forward, to import new upstream releases, one would simply run git fetch upstreamvcs; gbp import-orig --uscan, which fetches the upstream git tags, checks for new upstream tarballs, and automatically downloads, verifies, and imports the new version. See the galera-4-demo example in the Debian source packages in git explained post as a demo you can try running yourself and examine in detail. You can also try running gbp import-orig --uscan without specifying a version. It would fetch it, as it will notice there is now Entr version 5.7 available, and import it.

Build using git-buildpackage From this stage onwards you should build the package using gbp buildpackage, which will do a more comprehensive build.
shell
gbp buildpackage -uc -us
The git-buildpackage build also includes running Lintian to find potential Debian policy violations in the sources or in the resulting .deb binary packages. Many Debian Developers run lintian -EviIL +pedantic after every build to check that there are no new nags, and to validate that changes intended to previous Lintian nags were correct.

Open a Merge Request on Salsa for Debian packaging review Getting everything perfectly right takes a lot of effort, and may require reaching out to an experienced Debian Developers for review and guidance. Thus, you should aim to publish your initial packaging work on Salsa, Debian s GitLab instance, for review and feedback as early as possible. For somebody to be able to easily see what you have done, you should rename your debian/latest branch to another name, for example next/debian/latest, and open a Merge Request that targets the debian/latest branch on your Salsa fork, which still has only the unmodified upstream files. If you have followed the workflow in this post so far, you can simply run:
  1. git checkout -b next/debian/latest
  2. git push --set-upstream origin next/debian/latest
  3. Open in a browser the URL visible in the git remote response
  4. Write the Merge Request description in case the default text from your commit is not enough
  5. Mark the MR as Draft using the checkbox
  6. Publish the MR and request feedback
Once a Merge Request exists, discussion regarding what additional changes are needed can be conducted as MR comments. With an MR, you can easily iterate on the contents of next/debian/latest, rebase, force push, and request re-review as many times as you want. While at it, make sure the Settings > CI/CD page has under CI/CD configuration file the value debian/salsa-ci.yml so that the CI can run and give you immediate automated feedback. For an example of an initial packaging Merge Request, see https://salsa.debian.org/otto/entr-demo/-/merge_requests/1.

Open a Merge Request / Pull Request to fix upstream code Due to the high quality requirements in Debian, it is fairly common that while doing the initial Debian packaging of an open source project, issues are found that stem from the upstream source code. While it is possible to carry extra patches in Debian, it is not good practice to deviate too much from upstream code with custom Debian patches. Instead, the Debian packager should try to get the fixes applied directly upstream. Using git-buildpackage patch queues is the most convenient way to make modifications to the upstream source code so that they automatically convert into Debian patches (stored at debian/patches), and can also easily be submitted upstream as any regular git commit (and rebased and resubmitted many times over). First, decide if you want to work out of the upstream development branch and later cherry-pick to the Debian packaging branch, or work out of the Debian packaging branch and cherry-pick to an upstream branch. The example below starts from the upstream development branch and then cherry-picks the commit into the git-buildpackage patch queue:
shell
git checkout -b bugfix-branch master
nano entr.c
make
./entr # verify change works as expected
git commit -a -m "Commit title" -m "Commit body"
git push # submit upstream
gbp pq import --force --time-machine=10
git cherry-pick <commit id>
git commit --amend # extend commit message with DEP-3 metadata
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
The example below starts by making the fix on a git-buildpackage patch queue branch, and then cherry-picking it onto the upstream development branch:
shell
gbp pq import --force --time-machine=10
nano entr.c
git commit -a -m "Commit title" -m "Commit body"
gbp buildpackage -uc -us -b
./entr # verify change works as expected
gbp pq export --drop --commit
git commit --amend # Write commit message along lines "Add patch to .."
git checkout -b bugfix-branch master
git cherry-pick <commit id>
git commit --amend # prepare commit message for upstream submission
git push # submit upstream
The key git-buildpackage commands to enter and exit the patch-queue mode are:
shell
gbp pq import --force --time-machine=10
gbp pq export --drop --commit
%% init:   'gitGraph':   'mainBranchName': 'debian/latest'      %%
gitGraph
checkout debian/latest
commit id: "Initial packaging"
branch patch-queue/debian/latest
checkout patch-queue/debian/latest
commit id: "Delete debian/patches/..."
commit id: "Patch 1 title"
commit id: "Patch 2 title"
commit id: "Patch 3 title"
These can be run at any time, regardless if any debian/patches existed prior, or if existing patches applied cleanly or not, or if there were old patch queue branches around. Note that the extra -b in gbp buildpackage -uc -us -b instructs to build only binary packages, avoiding any nags from dpkg-source that there are modifications in the upstream sources while building in the patches-applied mode.

Programming-language specific dh-make alternatives As each programming language has its specific way of building the source code, and many other conventions regarding the file layout and more, Debian has multiple custom tools to create new Debian source packages for specific programming languages. Notably, Python does not have its own tool, but there is an dh_make --python option for Python support directly in dh_make itself. The list is not complete and many more tools exist. For some languages, there are even competing options, such as for Go there is in addition to dh-make-golang also Gophian. When learning Debian packaging, there is no need to learn these tools upfront. Being aware that they exist is enough, and one can learn them only if and when one starts to package a project in a new programming language.

The difference between source git repository vs source packages vs binary packages As seen in earlier example, running gbp buildpackage on the Entr packaging repository above will result in several files:
entr_5.6-1_amd64.changes
entr_5.6-1_amd64.deb
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The entr_5.6-1_amd64.deb is the binary package, which can be installed on a Debian/Ubuntu system. The rest of the files constitute the source package. To do a source-only build, run gbp buildpackage -S and note the files produced:
entr_5.6-1_source.changes
entr_5.6-1.debian.tar.xz
entr_5.6-1.dsc
entr_5.6.orig.tar.gz
entr_5.6.orig.tar.gz.asc
The source package files can be used to build the binary .deb for amd64, or any architecture that the package supports. It is important to grasp that the Debian source package is the preferred form to be able to build the binary packages on various Debian build systems, and the Debian source package is not the same thing as the Debian packaging git repository contents.
flowchart LR
git[Git repository<br>branch debian/latest] --> gbp buildpackage -S  src[Source Package<br>.dsc + .tar.xz]
src --> dpkg-buildpackage  bin[Binary Packages<br>.deb]
If the package is large and complex, the build could result in multiple binary packages. One set of package definition files in debian/ will however only ever result in a single source package.

Option to repackage source packages with Files-Excluded lists in the debian/copyright file Some upstream projects may include binary files in their release, or other undesirable content that needs to be omitted from the source package in Debian. The easiest way to filter them out is by adding to the debian/copyright file a Files-Excluded field listing the undesired files. The debian/copyright file is read by uscan, which will repackage the upstream sources on-the-fly when importing new upstream releases. For a real-life example, see the debian/copyright files in the Godot package that lists:
debian
Files-Excluded: platform/android/java/gradle/wrapper/gradle-wrapper.jar
The resulting repackaged upstream source tarball, as well as the upstream version component, will have an extra +ds to signify that it is not the true original upstream source but has been modified by Debian:
godot_4.3+ds.orig.tar.xz
godot_4.3+ds-1_amd64.deb

Creating one Debian source package from multiple upstream source packages also possible In some rare cases the upstream project may be split across multiple git repositories or the upstream release may consist of multiple components each in their own separate tarball. Usually these are very large projects that get some benefits from releasing components separately. If in Debian these are deemed to go into a single source package, it is technically possible using the component system in git-buildpackage and uscan. For an example see the gbp.conf and watch files in the node-cacache package. Using this type of structure should be a last resort, as it creates complexity and inter-dependencies that are bound to cause issues later on. It is usually better to work with upstream and champion universal best practices with clear releases and version schemes.

When not to start the Debian packaging repository as a fork of the upstream one Not all upstreams use Git for version control. It is by far the most popular, but there are still some that use e.g. Subversion or Mercurial. Who knows maybe in the future some new version control systems will start to compete with Git. There are also projects that use Git in massive monorepos and with complex submodule setups that invalidate the basic assumptions required to map an upstream Git repository into a Debian packaging repository. In those cases one can t use a debian/latest branch on a clone of the upstream git repository as the starting point for the Debian packaging, but one must revert the traditional way of starting from an upstream release tarball with gbp import-orig package-1.0.tar.gz.

Conclusion Created in August 1993, Debian is one of the oldest Linux distributions. In the 32 years since inception, the .deb packaging format and the tooling to work with it have evolved several generations. In the past 10 years, more and more Debian Developers have converged on certain core practices evidenced by https://trends.debian.net/, but there is still a lot of variance in workflows even for identical tasks. Hopefully, you find this post useful in giving practical guidance on how exactly to do the most common things when packaging software for Debian. Happy packaging!

14 May 2025

Evgeni Golov: running modified containers with podman

Everybody (who runs containers) knows this situation: you've been running happycontainer:stable for a while and it's been great but now something external changed and you need to adjust the code while there is still no release with the patch. I've encountered exactly this when our Home-Assistant stopped showing the presence of our cat correctly, but we've also been discussing this at work recently. Now the most obvious (to me?) solution would be to build a new container, based on the original one, and perform the modifications at build time. Something like this:
FROM happycontainer:stable
RUN curl     patch -p1
But that's not interactive, and if you don't have a patch readily available, that's not what you want. (And I'll save you the idea of RUNing sed and friends to alter files!) You could run vim inside the container, but that requires vim to be installed there in the first place. And a reasonable configuration. And Well, turns out podman can mount the root fs of a running container.
[root@sai ~]# podman mount homeassistant
/var/lib/containers/storage/overlay/f3ac502d97b5681989dff
And if you're running as non-root, you'll get an error:
[container@sai ~]$ podman mount homeassistant
Error: cannot run command "podman mount" in rootless mode, must execute  podman unshare  first
Luckily the solution is in the error message - use podman unshare
[container@sai ~]$ podman unshare
[root@sai ~]# podman mount homeassistant
/home/container/.local/share/containers/storage/overlay/95d3809d53125e4d40ad05e52efaa5a48e6e61fe9b8a8478416ff44459c7eb31/merged
So in both cases (root and rootless) we get a path, which is the mounted root fs and we can edit things in there as we like.
[root@sai ~]# vi /home/container/.local/share/containers/storage/overlay/95d3809d53125e4d40ad05e52efaa5a48e6e61fe9b8a8478416ff44459c7eb31/merged/usr/src/homeassistant/homeassistant/components/surepetcare/binary_sensor.py
Once done, the container can be unmounted again, and the namespace left
[root@sai ~]# podman umount homeassistant
homeassistant
[root@sai ~]# exit
[container@sai ~]$
At this point we have modified the code inside the container, but the running process is still using the old code. If we restart the container now to restart the process, our changes will be lost. Instead, we can commit the changes as a new layer and tag the result.
[container@sai ~]$ podman commit homeassistant docker.io/homeassistant/home-assistant:stable
And now, when we restart the container, it will use the new code with our changes
[container@sai ~]$ systemctl --user restart homeassistant
Is this the best workflow you can get? Probably not. Does it work? Hell yeah!

12 May 2025

Taavi V n nen: lua entry thread aborted: runtime error: bad request

The Wikimedia Cloud VPS shared web proxy has an interesting architecture: the management API writes an entry for each proxy to a Redis database, and the web server in use (Nginx with Lua support from ngx_http_lua_module) looks up the backend server URL from Redis for each request. This is maybe not how I would design this today, but the basic design dates back to 2013 and has served us well ever since. However, with a recent operating system upgrade to Debian 12 (we run Nginx from the packages in Debian's repositories), we started seeing mysterious errors that looked like this:
2025/04/30 07:24:25 [error] 82656#82656: *5612 lua entry thread aborted: runtime error: /etc/nginx/lua/domainproxy.lua:32: bad request
stack traceback:
coroutine 0:
[C]: in function 'set_keepalive'
/etc/nginx/lua/domainproxy.lua:32: in function 'redis_shutdown'
/etc/nginx/lua/domainproxy.lua:48: in main chunk, client: [redacted], server: *.wmcloud.org, request: "GET [redacted] HTTP/2.0", host: "codesearch.wmcloud.org", referrer: "https://codesearch.wmcloud.org/search/"
The code in question seems straightforward enough:
function redis_shutdown()
 -- Use a connection pool of 256 connections with a 32s idle timeout
 -- This also closes the current redis connection.
 red:set_keepalive(1000 * 32, 256) -- line 32
end
When searching for this error online, you'll end up finding advice like "the resty.redis object instance cannot be stored in a Lua variable at the Lua module level". However, our code already stores it as a local variable:
local redis = require 'nginx.redis'
local red = redis:new()
red:set_timeout(1000)
red:connect('127.0.0.1', 6379)
Turns out the issue was with the function definition: functions can also be defined as local. Without that, something somewhere in some situations seems to reference the variables from other requests, instead of using the Redis connection for the current request. (Don't ask me what changed between Debian 12 and 13 making this only break now.) So we needed to change our function definition to this instead:
local function redis_shutdown()
 -- Use a connection pool of 256 connections with a 32s idle timeout
 -- This also closes the current redis connection.
 red:set_keepalive(1000 * 32, 256)
end
I spent almost an entire workday looking for this, ultimately making a two-line patch to fix the issue. Hopefully by publishing this post I can save that time from everyone else stumbling upon the same problem after myself.

28 April 2025

Sergio Talens-Oliag: ArgoCD Autopilot

For a long time I ve been wanting to try GitOps tools, but I haven t had the chance to try them for real on the projects I was working on. As now I have some spare time I ve decided I m going to play a little with Argo CD, Flux and Kluctl to test them and be able to use one of them in a real project in the future if it looks appropriate. On this post I will use Argo-CD Autopilot to install argocd on a k3d local cluster installed using OpenTofu to test the autopilot approach of managing argocd and test the tool (as it manages argocd using a git repository it can be used to test argocd as well).
Installing tools locally with arkadeRecently I ve been using the arkade tool to install kubernetes related applications on Linux servers and containers, I usually get the applications with it and install them on the /usr/local/bin folder. For this post I ve created a simple script that checks if the tools I ll be using are available and installs them on the $HOME/.arkade/bin folder if missing (I m assuming that docker is already available, as it is not installable with arkade):
#!/bin/sh
# TOOLS LIST
ARKADE_APPS="argocd argocd-autopilot k3d kubectl sops tofu"
# Add the arkade binary directory to the path if missing
case ":$ PATH :" in
  *:"$ HOME /.arkade/bin":*) ;;
  *) export PATH="$ PATH :$ HOME /.arkade/bin" ;;
esac
# Install or update arkade
if command -v arkade >/dev/null; then
  echo "Trying to update the arkade application"
  sudo arkade update
else
  echo "Installing the arkade application"
  curl -sLS https://get.arkade.dev   sudo sh
fi
echo ""
echo "Installing tools with arkade"
echo ""
for app in $ARKADE_APPS; do
  app_path="$(command -v $app)"   true
  if [ "$app_path" ]; then
    echo "The application '$app' already available on '$app_path'"
  else
    arkade get "$app"
  fi
done
cat <<EOF
Add the ~/.arkade/bin directory to your PATH if tools have been installed there
EOF
The rest of scripts will add the binary directory to the PATH if missing to make sure things work if something was installed there.

Creating a k3d cluster with opentofuAlthough using k3d directly will be a good choice for the creation of the cluster, I m using tofu to do it because that will probably be the tool used to do it if we were working with Cloud Platforms like AWS or Google. The main.tf file is as follows:
terraform  
  required_providers  
    k3d =  
      source  = "moio/k3d"
      version = "0.0.12"
     
    sops =  
      source = "carlpett/sops"
      version = "1.2.0"


data "sops_file" "secrets"  
    source_file = "secrets.yaml"
 
resource "k3d_cluster" "argocd_cluster"  
  name    = "argocd"
  servers = 1
  agents  = 2
  image   = "rancher/k3s:v1.31.5-k3s1"
  network = "argocd"
  token   = data.sops_file.secrets.data["token"]
  port  
    host_port      = 8443
    container_port = 443
    node_filters = [
      "loadbalancer",
    ]
   
  k3d  
    disable_load_balancer     = false
    disable_image_volume      = false
   
  kubeconfig  
    update_default_kubeconfig = true
    switch_current_context    = true
   
  runtime  
    gpu_request = "all"
   
 
The k3d configuration is quite simple, as I plan to use the default traefik ingress controller with TLS I publish the 443 port on the hosts 8443 port, I ll explain how I add a valid certificate on the next step. I ve prepared the following script to initialize and apply the changes:
#!/bin/sh
set -e
# VARIABLES
# Default token for the argocd cluster
K3D_CLUSTER_TOKEN="argocdToken"
# Relative PATH to install the k3d cluster using terr-iaform
K3D_TF_RELPATH="k3d-tf"
# Secrets yaml file
SECRETS_YAML="secrets.yaml"
# Relative PATH to the workdir from the script directory
WORK_DIR_RELPATH=".."
# Compute WORKDIR
SCRIPT="$(readlink -f "$0")"
SCRIPT_DIR="$(dirname "$SCRIPT")"
WORK_DIR="$(readlink -f "$SCRIPT_DIR/$WORK_DIR_RELPATH")"
# Update the PATH to add the arkade bin directory
# Add the arkade binary directory to the path if missing
case ":$ PATH :" in
  *:"$ HOME /.arkade/bin":*) ;;
  *) export PATH="$ PATH :$ HOME /.arkade/bin" ;;
esac
# Go to the k3d-tf dir
cd "$WORK_DIR/$K3D_TF_RELPATH"   exit 1
# Create secrets.yaml file and encode it with sops if missing
if [ ! -f "$SECRETS_YAML" ]; then
  echo "token: $K3D_CLUSTER_TOKEN" >"$SECRETS_YAML"
  sops encrypt -i "$SECRETS_YAML"
fi
# Initialize terraform
tofu init
# Apply the configuration
tofu apply

Adding a wildcard certificate to the k3d ingressAs an optional step, after creating the k3d cluster I m going to add a default wildcard certificate for the traefik ingress server to be able to use everything with HTTPS without certificate issues. As I manage my own DNS domain I ve created the lo.mixinet.net and *.lo.mixinet.net DNS entries on my public and private DNS servers (both return 127.0.0.1 and ::1) and I ve created a TLS certificate for both entries using Let s Encrypt with Certbot. The certificate is updated automatically on one of my servers and when I need it I copy the contents of the fullchain.pem and privkey.pem files from the /etc/letsencrypt/live/lo.mixinet.net server directory to the local files lo.mixinet.net.crt and lo.mixinet.net.key. After copying the files I run the following file to install or update the certificate and configure it as the default for traefik:
#!/bin/sh
# Script to update the
secret="lo-mixinet-net-ingress-cert"
cert="$ 1:-lo.mixinet.net.crt "
key="$ 2:-lo.mixinet.net.key "
if [ -f "$cert" ] && [ -f "$key" ]; then
  kubectl -n kube-system create secret tls $secret \
    --key=$key \
    --cert=$cert \
    --dry-run=client --save-config -o yaml    kubectl apply -f -
  kubectl apply -f - << EOF
apiVersion: traefik.containo.us/v1alpha1
kind: TLSStore
metadata:
  name: default
  namespace: kube-system
spec:
  defaultCertificate:
    secretName: $secret
EOF
else
  cat <<EOF
To add or update the traefik TLS certificate the following files are needed:
- cert: '$cert'
- key: '$key'
Note: you can pass the paths as arguments to this script.
EOF
fi
Once it is installed if I connect to https://foo.lo.mixinet.net:8443/ I get a 404 but the certificate is valid.

Installing argocd with argocd-autopilot

Creating a repository and a token for autopilotI ll be using a project on my forgejo instance to manage argocd, the repository I ve created is on the URL https://forgejo.mixinet.net/blogops/argocd and I ve created a private user named argocd that only has write access to that repository. Logging as the argocd user on forgejo I ve created a token with permission to read and write repositories that I ve saved on my pass password store on the mixinet.net/argocd@forgejo/repository-write entry.

Bootstrapping the installationTo bootstrap the installation I ve used the following script (it uses the previous GIT_REPO and GIT_TOKEN values):
#!/bin/sh
set -e
# VARIABLES
# Relative PATH to the workdir from the script directory
WORK_DIR_RELPATH=".."
# Compute WORKDIR
SCRIPT="$(readlink -f "$0")"
SCRIPT_DIR="$(dirname "$SCRIPT")"
WORK_DIR="$(readlink -f "$SCRIPT_DIR/$WORK_DIR_RELPATH")"
# Update the PATH to add the arkade bin directory
# Add the arkade binary directory to the path if missing
case ":$ PATH :" in
  *:"$ HOME /.arkade/bin":*) ;;
  *) export PATH="$ PATH :$ HOME /.arkade/bin" ;;
esac
# Go to the working directory
cd "$WORK_DIR"   exit 1
# Set GIT variables
if [ -z "$GIT_REPO" ]; then
  export GIT_REPO="https://forgejo.mixinet.net/blogops/argocd.git"
fi
if [ -z "$GIT_TOKEN" ]; then
  GIT_TOKEN="$(pass mixinet.net/argocd@forgejo/repository-write)"
  export GIT_TOKEN
fi
argocd-autopilot repo bootstrap --provider gitea
The output of the execution is as follows:
  bin/argocd-bootstrap.sh
INFO cloning repo: https://forgejo.mixinet.net/blogops/argocd.git
INFO empty repository, initializing a new one with specified remote
INFO using revision: "", installation path: ""
INFO using context: "k3d-argocd", namespace: "argocd"
INFO applying bootstrap manifests to cluster...
namespace/argocd created
customresourcedefinition.apiextensions.k8s.io/applications.argoproj.io created
customresourcedefinition.apiextensions.k8s.io/applicationsets.argoproj.io created
customresourcedefinition.apiextensions.k8s.io/appprojects.argoproj.io created
serviceaccount/argocd-application-controller created
serviceaccount/argocd-applicationset-controller created
serviceaccount/argocd-dex-server created
serviceaccount/argocd-notifications-controller created
serviceaccount/argocd-redis created
serviceaccount/argocd-repo-server created
serviceaccount/argocd-server created
role.rbac.authorization.k8s.io/argocd-application-controller created
role.rbac.authorization.k8s.io/argocd-applicationset-controller created
role.rbac.authorization.k8s.io/argocd-dex-server created
role.rbac.authorization.k8s.io/argocd-notifications-controller created
role.rbac.authorization.k8s.io/argocd-redis created
role.rbac.authorization.k8s.io/argocd-server created
clusterrole.rbac.authorization.k8s.io/argocd-application-controller created
clusterrole.rbac.authorization.k8s.io/argocd-applicationset-controller created
clusterrole.rbac.authorization.k8s.io/argocd-server created
rolebinding.rbac.authorization.k8s.io/argocd-application-controller created
rolebinding.rbac.authorization.k8s.io/argocd-applicationset-controller created
rolebinding.rbac.authorization.k8s.io/argocd-dex-server created
rolebinding.rbac.authorization.k8s.io/argocd-notifications-controller created
rolebinding.rbac.authorization.k8s.io/argocd-redis created
rolebinding.rbac.authorization.k8s.io/argocd-server created
clusterrolebinding.rbac.authorization.k8s.io/argocd-application-controller created
clusterrolebinding.rbac.authorization.k8s.io/argocd-applicationset-controller created
clusterrolebinding.rbac.authorization.k8s.io/argocd-server created
configmap/argocd-cm created
configmap/argocd-cmd-params-cm created
configmap/argocd-gpg-keys-cm created
configmap/argocd-notifications-cm created
configmap/argocd-rbac-cm created
configmap/argocd-ssh-known-hosts-cm created
configmap/argocd-tls-certs-cm created
secret/argocd-notifications-secret created
secret/argocd-secret created
service/argocd-applicationset-controller created
service/argocd-dex-server created
service/argocd-metrics created
service/argocd-notifications-controller-metrics created
service/argocd-redis created
service/argocd-repo-server created
service/argocd-server created
service/argocd-server-metrics created
deployment.apps/argocd-applicationset-controller created
deployment.apps/argocd-dex-server created
deployment.apps/argocd-notifications-controller created
deployment.apps/argocd-redis created
deployment.apps/argocd-repo-server created
deployment.apps/argocd-server created
statefulset.apps/argocd-application-controller created
networkpolicy.networking.k8s.io/argocd-application-controller-network-policy created
networkpolicy.networking.k8s.io/argocd-applicationset-controller-network-policy created
networkpolicy.networking.k8s.io/argocd-dex-server-network-policy created
networkpolicy.networking.k8s.io/argocd-notifications-controller-network-policy created
networkpolicy.networking.k8s.io/argocd-redis-network-policy created
networkpolicy.networking.k8s.io/argocd-repo-server-network-policy created
networkpolicy.networking.k8s.io/argocd-server-network-policy created
secret/autopilot-secret created
INFO pushing bootstrap manifests to repo
INFO applying argo-cd bootstrap application
INFO pushing bootstrap manifests to repo
INFO applying argo-cd bootstrap application
application.argoproj.io/autopilot-bootstrap created
INFO running argocd login to initialize argocd config
Context 'autopilot' updated
INFO argocd initialized. password: XXXXXXX-XXXXXXXX
INFO run:
    kubectl port-forward -n argocd svc/argocd-server 8080:80
Now we have the argocd installed and running, it can be checked using the port-forward and connecting to https://localhost:8080/ (the certificate will be wrong, we are going to fix that in the next step).

Updating the argocd installation in gitNow that we have the application deployed we can clone the argocd repository and edit the deployment to disable TLS for the argocd server (we are going to use TLS termination with traefik and that needs the server running as insecure, see the Argo CD documentation)
  ssh clone ssh://git@forgejo.mixinet.net/blogops/argocd.git
  cd argocd
  edit bootstrap/argo-cd/kustomization.yaml
  git commit -m 'Disable TLS for the argocd-server'
The changes made to the kustomization.yaml file are the following:
--- a/bootstrap/argo-cd/kustomization.yaml
+++ b/bootstrap/argo-cd/kustomization.yaml
@@ -11,6 +11,11 @@ configMapGenerator:
         key: git_username
         name: autopilot-secret
   name: argocd-cm
+  # Disable TLS for the Argo Server (see https://argo-cd.readthedocs.io/en/stable/operator-manual/ingress/#traefik-v30)
+- behavior: merge
+  literals:
+  - "server.insecure=true"
+  name: argocd-cmd-params-cm
 kind: Kustomization
 namespace: argocd
 resources:
Once the changes are pushed we sync the argo-cd application manually to make sure they are applied:
argo cd sync
As a test we can download the argocd-cmd-params-cm ConfigMap to make sure everything is OK:
apiVersion: v1
data:
  server.insecure: "true"
kind: ConfigMap
metadata:
  annotations:
    kubectl.kubernetes.io/last-applied-configuration:  
       "apiVersion":"v1","data": "server.insecure":"true" ,"kind":"ConfigMap","metadata": "annotations": ,"labels": "app.kubernetes.io/instance":"argo-cd","app.kubernetes.io/name":"argocd-cmd-params-cm","app.kubernetes.io/part-of":"argocd" ,"name":"argocd-cmd-params-cm","namespace":"argocd" 
  creationTimestamp: "2025-04-27T17:31:54Z"
  labels:
    app.kubernetes.io/instance: argo-cd
    app.kubernetes.io/name: argocd-cmd-params-cm
    app.kubernetes.io/part-of: argocd
  name: argocd-cmd-params-cm
  namespace: argocd
  resourceVersion: "16731"
  uid: a460638f-1d82-47f6-982c-3017699d5f14
As this simply changes the ConfigMap we have to restart the argocd-server to read it again, to do it we delete the server pods so they are re-created using the updated resource:
  kubectl delete pods -n argocd -l app.kubernetes.io/name=argocd-server
After doing this the port-forward command is killed automatically, if we run it again the connection to get to the argocd-server has to be done using HTTP instead of HTTPS. Instead of testing that we are going to add an ingress definition to be able to connect to the server using HTTPS and GRPC against the address argocd.lo.mixinet.net using the wildcard TLS certificate we installed earlier. To do it we to edit the bootstrap/argo-cd/kustomization.yaml file to add the ingress_route.yaml file to the deployment:
--- a/bootstrap/argo-cd/kustomization.yaml
+++ b/bootstrap/argo-cd/kustomization.yaml
@@ -20,3 +20,4 @@ kind: Kustomization
 namespace: argocd
 resources:
 - github.com/argoproj-labs/argocd-autopilot/manifests/base?ref=v0.4.19
+- ingress_route.yaml
The ingress_route.yaml file contents are the following:
apiVersion: traefik.io/v1alpha1
kind: IngressRoute
metadata:
  name: argocd-server
  namespace: argocd
spec:
  entryPoints:
    - websecure
  routes:
    - kind: Rule
      match: Host( argocd.lo.mixinet.net )
      priority: 10
      services:
        - name: argocd-server
          port: 80
    - kind: Rule
      match: Host( argocd.lo.mixinet.net ) && Header( Content-Type ,  application/grpc )
      priority: 11
      services:
        - name: argocd-server
          port: 80
          scheme: h2c
  tls:
    certResolver: default
After pushing the changes and waiting a little bit the change is applied and we can access the server using HTTPS and GRPC, the first way can be tested from a browser and the GRPC using the command line interface:
  argocd --grpc-web login argocd.lo.mixinet.net:8443
Username: admin
Password:
'admin:login' logged in successfully
Context 'argocd.lo.mixinet.net:8443' updated
  argocd app list -o name
argocd/argo-cd
argocd/autopilot-bootstrap
argocd/cluster-resources-in-cluster
argocd/root
So things are working fine and that is all on this post, folks!

25 April 2025

Simon Josefsson: GitLab Runner with Rootless Privilege-less Capability-less Podman on riscv64

I host my own GitLab CI/CD runners, and find that having coverage on the riscv64 CPU architecture is useful for testing things. The HiFive Premier P550 seems to be a common hardware choice. The P550 is possible to purchase online. You also need a (mini-)ATX chassi, power supply (~500W is more than sufficient), PCI-to-M2 converter and a NVMe storage device. Total cost per machine was around $8k/ 8k for me. Assembly was simple: bolt everything, connect ATX power, connect cables for the front-panel, USB and and Audio. Be sure to toggle the physical power switch on the P550 before you close the box. Front-panel power button will start your machine. There is a P550 user manual available. Below I will guide you to install the GitLab Runner on the pre-installed Ubuntu 24.04 that ships with the P550, and configure it to use Podman in root-less mode and without the --privileged flag, without any additional capabilities like SYS_ADMIN. Presumably you want to migrate to some other OS instead; hey Trisquel 13 riscv64 I m waiting for you! I wouldn t recommend using this machine for anything sensitive, there is an awful lot of non-free and/or vendor-specific software installed, and the hardware itself is young. I am not aware of any riscv64 hardware that can run a libre OS, all of them appear to require non-free blobs and usually a non-mainline kernel.
apt-get install minicom
minicom -o -D /dev/ttyUSB3
#cmd: ifconfig
inet 192.168.0.2 netmask: 255.255.240.0
gatway 192.168.0.1
SOM_Mac0: 8c:00:00:00:00:00
SOM_Mac1: 8c:00:00:00:00:00
MCU_Mac: 8c:00:00:00:00:00
#cmd: setmac 0 CA:FE:42:17:23:00
The MAC setting will be valid after rebooting the carrier board!!!
MAC[0] addr set to CA:FE:42:17:23:00(ca:fe:42:17:23:0)
#cmd: setmac 1 CA:FE:42:17:23:01
The MAC setting will be valid after rebooting the carrier board!!!
MAC[1] addr set to CA:FE:42:17:23:01(ca:fe:42:17:23:1)
#cmd: setmac 2 CA:FE:42:17:23:02
The MAC setting will be valid after rebooting the carrier board!!!
MAC[2] addr set to CA:FE:42:17:23:02(ca:fe:42:17:23:2)
#cmd:
apt-get install openocd
wget https://raw.githubusercontent.com/sifiveinc/hifive-premier-p550-tools/refs/heads/master/mcu-firmware/stm32_openocd.cfg
echo 'acc115d283ff8533d6ae5226565478d0128923c8a479a768d806487378c5f6c3 stm32_openocd.cfg' sha256sum -c
openocd -f stm32_openocd.cfg &
telnet localhost 4444
...
echo 'ssh-ed25519 AAA...' > ~/.ssh/authorized_keys
sed -i 's;^#PasswordAuthentication.*;PasswordAuthentication no;' /etc/ssh/sshd_config
service ssh restart
parted /dev/nvme0n1 print
blkdiscard /dev/nvme0n1
parted /dev/nvme0n1 mklabel gpt
parted /dev/nvme0n1 mkpart jas-p550-nvm-02 ext2 1MiB 100% align-check optimal 1
parted /dev/nvme0n1 set 1 lvm on
partprobe /dev/nvme0n1
pvcreate /dev/nvme0n1p1
vgcreate vg0 /dev/nvme0n1p1
lvcreate -L 400G -n glr vg0
mkfs.ext4 -L glr /dev/mapper/vg0-glr
Now with a reasonable setup ready, let s install the GitLab Runner. The following is adapted from gitlab-runner s official installation instructions documentation. The normal installation flow doesn t work because they don t publish riscv64 apt repositories, so you will have to perform upgrades manually.
# wget https://s3.dualstack.us-east-1.amazonaws.com/gitlab-runner-downloads/latest/deb/gitlab-runner_riscv64.deb
# wget https://s3.dualstack.us-east-1.amazonaws.com/gitlab-runner-downloads/latest/deb/gitlab-runner-helper-images.deb
wget https://gitlab-runner-downloads.s3.amazonaws.com/v17.11.0/deb/gitlab-runner_riscv64.deb
wget https://gitlab-runner-downloads.s3.amazonaws.com/v17.11.0/deb/gitlab-runner-helper-images.deb
echo '68a4c2a4b5988a5a5bae019c8b82b6e340376c1b2190228df657164c534bc3c3 gitlab-runner-helper-images.deb' sha256sum -c
echo 'ee37dc76d3c5b52e4ba35cf8703813f54f536f75cfc208387f5aa1686add7a8c gitlab-runner_riscv64.deb' sha256sum -c
dpkg -i gitlab-runner-helper-images.deb gitlab-runner_riscv64.deb
Remember the NVMe device? Let s not forget to use it, to avoid wear and tear of the internal MMC root disk. Do this now before any files in /home/gitlab-runner appears, or you have to move them manually.
gitlab-runner stop
echo 'LABEL=glr /home/gitlab-runner ext4 defaults,noatime 0 1' >> /etc/fstab
systemctl daemon-reload
mount /home/gitlab-runner
Next install gitlab-runner and configure it. Replace token glrt-REPLACEME below with the registration token you get from your GitLab project s Settings -> CI/CD -> Runners -> New project runner. I used the tags riscv64 and a runner description of the hostname.
gitlab-runner register --non-interactive --url https://gitlab.com --token glrt-REPLACEME --name $(hostname) --executor docker --docker-image debian:stable
We install and configure gitlab-runner to use podman, and to use non-root user.
apt-get install podman
gitlab-runner stop
usermod --add-subuids 100000-165535 --add-subgids 100000-165535 gitlab-runner
You need to run some commands as the gitlab-runner user, but unfortunately some interaction between sudo/su and pam_systemd makes this harder than it should be. So you have to setup SSH for the user and login via SSH to run the commands. Does anyone know of a better way to do this?
# on the p550:
cp -a /root/.ssh/ /home/gitlab-runner/
chown -R gitlab-runner:gitlab-runner /home/gitlab-runner/.ssh/
# on your laptop:
ssh gitlab-runner@jas-p550-01
systemctl --user --now enable podman.socket
systemctl --user --now start podman.socket
loginctl enable-linger gitlab-runner gitlab-runner
systemctl status --user podman.socket
We modify /etc/gitlab-runner/config.toml as follows, replace 997 with the user id shown by systemctl status above. See feature flags documentation for more documentation.
...
[[runners]]
environment = ["FF_NETWORK_PER_BUILD=1", "FF_USE_FASTZIP=1"]
...
[runners.docker]
host = "unix:///run/user/997/podman/podman.sock"
Note that unlike the documentation I do not add the privileged = true parameter here. I will come back to this later. Restart the system to confirm that pushing a .gitlab-ci.yml with a job that uses the riscv64 tag like the following works properly.
dump-env-details-riscv64:
stage: build
image: riscv64/debian:testing
tags: [ riscv64 ]
script:
- set
Your gitlab-runner should now be receiving jobs and running them in rootless podman. You may view the log using journalctl as follows:
journalctl --follow _SYSTEMD_UNIT=gitlab-runner.service
To stop the graphical environment and disable some unnecessary services, you can use:
systemctl set-default multi-user.target
systemctl disable openvpn cups cups-browsed sssd colord
At this point, things were working fine and I was running many successful builds. Now starts the fun part with operational aspects! I had a problem when running buildah to build a new container from within a job, and noticed that aardvark-dns was crashing. You can use the Debian aardvark-dns binary instead.
wget http://ftp.de.debian.org/debian/pool/main/a/aardvark-dns/aardvark-dns_1.14.0-3_riscv64.deb
echo 'df33117b6069ac84d3e97dba2c59ba53775207dbaa1b123c3f87b3f312d2f87a aardvark-dns_1.14.0-3_riscv64.deb' sha256sum -c
mkdir t
cd t
dpkg -x ../aardvark-dns_1.14.0-3_riscv64.deb .
mv /usr/lib/podman/aardvark-dns /usr/lib/podman/aardvark-dns.ubuntu
mv usr/lib/podman/aardvark-dns /usr/lib/podman/aardvark-dns.debian
My setup uses podman in rootless mode without passing the privileged parameter or any add-cap parameters to add non-default capabilities. This is sufficient for most builds. However if you try to create container using buildah from within a job, you may see errors like this:
Writing manifest to image destination
Error: mounting new container: mounting build container "8bf1ec03d967eae87095906d8544f51309363ddf28c60462d16d73a0a7279ce1": creating overlay mount to /var/lib/containers/storage/overlay/23785e20a8bac468dbf028bf524274c91fbd70dae195a6cdb10241c345346e6f/merged, mount_data="lowerdir=/var/lib/containers/storage/overlay/l/I3TWYVYTRZ4KVYCT6FJKHR3WHW,upperdir=/var/lib/containers/storage/overlay/23785e20a8bac468dbf028bf524274c91fbd70dae195a6cdb10241c345346e6f/diff,workdir=/var/lib/containers/storage/overlay/23785e20a8bac468dbf028bf524274c91fbd70dae195a6cdb10241c345346e6f/work,volatile": using mount program /usr/bin/fuse-overlayfs: unknown argument ignored: lazytime
fuse: device not found, try 'modprobe fuse' first
fuse-overlayfs: cannot mount: No such file or directory
: exit status 1
According to GitLab runner security considerations, you should not enable the privileged = true parameter, and the alternative appears to run Podman as root with privileged=false. Indeed setting privileged=true as in the following example solves the problem, and I suppose running podman as root would too.
[[runners]]
[runners.docker]
privileged = true
Can we do better? After some experimentation, and reading open issues with suggested capabilities and configuration snippets, I ended up with the following configuration. It runs podman in rootless mode (as the gitlab-runner user) without --privileged, but add the CAP_SYS_ADMIN capability and exposes the /dev/fuse device. Still, this is running as non-root user on the machine, so I think it is an improvement compared to using --privileged and also compared to running podman as root.
[[runners]]
[runners.docker]
privileged = false
cap_add = ["SYS_ADMIN"]
devices = ["/dev/fuse"]
Still I worry about the security properties of such a setup, so I only enable these settings for a separately configured runner instance that I use when I need this docker-in-docker (oh, I meant buildah-in-podman) functionality. I found one article discussing Rootless Podman without the privileged flag that suggest isolation=chroot but I have yet to make this work. Suggestions for improvement are welcome. Happy Riscv64 Building! Update 2025-05-05: I was able to make it work without the SYS_ADMIN capability too, with a GitLab /etc/gitlab-runner/config.toml like the following:
[[runners]]
  [runners.docker]
    privileged = false
    devices = ["/dev/fuse"]
And passing --isolation chroot to Buildah like this:
buildah build --isolation chroot -t $CI_REGISTRY_IMAGE:name image/
I ve updated the blog title to add the word capability-less as well. I ve confirmed that the same recipe works on podman on a ppc64el platform too. Remaining loop-holes are escaping from the chroot into the non-root gitlab-runner user, and escalating that privilege to root. The /dev/fuse and sub-uid/gid may be privilege escalation vectors here, otherwise I believe you ve found a serious software security issue rather than a configuration mistake.

28 March 2025

Dirk Eddelbuettel: tint 0.1.5 on CRAN: Maintenance

A new version 0.1.5 of the tint package arrived at CRAN today. tint provides a style not unlike Tufte for use in html and pdf documents created from markdown. The github repo shows several examples in its README, more as usual in the package documentation. This is the first release in one and a half years and contains only routine maintenance. As CRAN now bags about missing anchors in the common \code \link use, I added these today. Otherwise the usual mix of updates to continuous integration, to badges and URLs and other small packaging details but nothing user-facing.

Changes in tint version 0.1.5 (2025-03-27)
  • Standard package maintenance for continuous integration, URL updates, and packaging conventions
  • Correct two minor nags in the Rd file

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More information is on the tint page. For questions or comments use the issue tracker off the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

9 March 2025

Niels Thykier: Improving Debian packaging in Kate

The other day, I noted that the emacs integration with debputy stopped working. After debugging for a while, I realized that emacs no longer sent the didOpen notification that is expected of it, which confused debputy. At this point, I was already several hours into the debugging and I noted there was some discussions on debian-devel about emacs and byte compilation not working. So I figured I would shelve the emacs problem for now. But I needed an LSP capable editor and with my vi skills leaving much to be desired, I skipped out on vim-youcompleteme. Instead, I pulled out kate, which I had not been using for years. It had LSP support, so it would fine, right? Well, no. Turns out that debputy LSP support had some assumptions that worked for emacs but not kate. Plus once you start down the rabbit hole, you stumble on things you missed previously.
Getting started First order of business was to tell kate about debputy. Conveniently, kate has a configuration tab for adding language servers in a JSON format right next to the tab where you can see its configuration for built-in LSP (also in JSON format9. So a quick bit of copy-paste magic and that was done. Yesterday, I opened an MR against upstream to have the configuration added (https://invent.kde.org/utilities/kate/-/merge_requests/1748) and they already merged it. Today, I then filed a wishlist against kate in Debian to have the Debian maintainers cherry-pick it, so it works out of the box for Trixie (https://bugs.debian.org/1099876). So far so good.
Inlay hint woes Since July (2024), debputy has support for Inlay hints. They are basically small bits of text that the LSP server can ask the editor to inject into the text to provide hints to the reader. Typically, you see them used to provide typing hints, where the editor or the underlying LSP server has figured out the type of a variable or expression that you did not explicitly type. Another common use case is to inject the parameter name for positional arguments when calling a function, so the user do not have to count the position to figure out which value is passed as which parameter. In debputy, I have been using the Inlay hints to show inherited fields in debian/control. As an example, if you have a definition like:
Source: foo-src
Section: devel
Priority: optional
Package: foo-bin
Architecture: any
Then foo-bin inherits the Section and Priority field since it does not supply its own. Previously, debputy would that by injecting the fields themselves and their value just below the Package field as if you had typed them out directly. The editor always renders Inlay hints distinctly from regular text, so there was no risk of confusion and it made the text look like a valid debian/control file end to end. The result looked something like:
Source: foo-src
Section: devel
Priority: optional
Package: foo-bin
Section: devel
Priority: optional
Architecture: any
With the second instances of Section and Priority being rendered differently than its surrendering (usually faded or colorlessly). Unfortunately, kate did not like injecting Inlay hints with a newline in them, which was needed for this trick. Reading into the LSP specs, it says nothing about multi-line Inlay hints being a thing and I figured I would see this problem again with other editors if I left it be. I ended up changing the Inlay hints to be placed at the end of the Package field and then included surrounding () for better visuals. So now, it looks like:
Source: foo-src
Section: devel
Priority: optional
Package: foo-bin  (Section: devel)  (Priority: optional)
Architecture: any
Unfortunately, it is no longer 1:1 with the underlying syntax which I liked about the previous one. But it works in more editors and is still explicit. I also removed the Inlay hint for the Homepage field. It takes too much space and I have yet to meet someone missing it in the binary stanza. If you have any better ideas for how to render it, feel free to reach out to me.
Spurious completion and hover As I was debugging the Inlay hints, I wanted to do a quick restart of debputy after each fix. Then I would trigger a small change to the document to ensure kate would request an update from debputy to render the Inlay hints with the new code. The full outgoing payloads are sent via the logs to the client, so it was really about minimizing which LSP requests are sent to debputy. Notably, two cases would flood the log:
  • Completion requests. These are triggered by typing anything at all and since I wanted to a change, I could not avoid this. So here it was about making sure there would be nothing to complete, so the result was a small as possible.
  • Hover doc requests. These are triggered by mouse hovering over field, so this was mostly about ensuring my mouse movement did not linger over any field on the way between restarting the LSP server and scrolling the log in kate.
In my infinite wisdom, I chose to make a comment line where I would do the change. I figured it would neuter the completion requests completely and it should not matter if my cursor landed on the comment as there would be no hover docs for comments either. Unfortunately for me, debputy would ignore the fact that it was on a comment line. Instead, it would find the next field after the comment line and try to complete based on that. Normally you do not see this, because the editor correctly identifies that none of the completion suggestions start with a \#, so they are all discarded. But it was pretty annoying for the debugging, so now debputy has been told to explicitly stop these requests early on comment lines.
Hover docs for packages I added a feature in debputy where you can hover over package names in your relationship fields (such as Depends) and debputy will render a small snippet about it based on data from your local APT cache. This doc is then handed to the editor and tagged as markdown provided the editor supports markdown rendering. Both emacs and kate support markdown. However, not all markdown renderings are equal. Notably, emacs's rendering does not reformat the text into paragraphs. In a sense, emacs rendering works a bit like <pre>...</pre> except it does a bit of fancy rendering inside the <pre>...</pre>. On the other hand, kate seems to convert the markdown to HTML and then throw the result into an HTML render engine. Here it is important to remember that not all newlines are equal in markdown. A Foo<newline>Bar is treated as one "paragraph" (<p>...</p>) and the HTML render happily renders this as single line Foo Bar provided there is sufficient width to do so. A couple of extra newlines made wonders for the kate rendering, but I have a feeling this is not going to be the last time the hover docs will need some tweaking for prettification. Feel free to reach out if you spot a weirdly rendered hover doc somewhere.
Making quickfixes available in kate Quickfixes are treated as generic code actions in the LSP specs. Each code action has a "type" (kind in the LSP lingo), which enables the editor to group the actions accordingly or filter by certain types of code actions. The design in the specs leads to the following flow:
  1. The LSP server provides the editor with diagnostics (there are multiple ways to trigger this, so we will keep this part simple).
  2. The editor renders them to the user and the user chooses to interact with one of them.
  3. The interaction makes the editor asks the LSP server, which code actions are available at that location (optionally with filter to only see quickfixes).
  4. The LSP server looks at the provided range and is expected to return the relevant quickfixes here.
This flow is really annoying from a LSP server writer point of view. When you do the diagnostics (in step 1), you tend to already know what the possible quickfixes would be. The LSP spec authors realized this at some point, so there are two features the editor provides to simplify this.
  1. In the editor request for code actions, the editor is expected to provide the diagnostics that they received from the server. Side note: I cannot quite tell if this is optional or required from the spec.
  2. The editor can provide support for remembering a data member in each diagnostic. The server can then store arbitrary information in that member, which they will see again in the code actions request. Again, provided that the editor supports this optional feature.
All the quickfix logic in debputy so far has hinged on both of these two features. As life would have it, kate provides neither of them. Which meant I had to teach debputy to keep track of its diagnostics on its own. The plus side is that makes it easier to support "pull diagnostics" down the line, since it requires a similar feature. Additionally, it also means that quickfixes are now available in more editors. For consistency, debputy logic is now always used rather than relying on the editor support when present. The downside is that I had to spend hours coming up with and debugging a way to find the diagnostics that overlap with the range provided by the editor. The most difficult part was keeping the logic straight and getting the runes correct for it.
Making the quickfixes actually work With all of that, kate would show the quickfixes for diagnostics from debputy and you could use them too. However, they would always apply twice with suboptimal outcome as a result. The LSP spec has multiple ways of defining what need to be changed in response to activating a code action. In debputy, all edits are currently done via the WorkspaceEdit type. It has two ways of defining the changes. Either via changes or documentChanges with documentChanges being the preferred one if both parties support this. I originally read that as I was allowed to provide both and the editor would pick the one it preferred. However, after seeing kate blindly use both when they are present, I reviewed the spec and it does say "The edit should either provide changes or documentChanges", so I think that one is on me. None of the changes in debputy currently require documentChanges, so I went with just using changes for now despite it not being preferred. I cannot figure out the logic of whether an editor supports documentChanges. As I read the notes for this part of the spec, my understanding is that kate does not announce its support for documentChanges but it clearly uses them when present. Therefore, I decided to keep it simple for now until I have time to dig deeper.
Remaining limitations with kate There is one remaining limitation with kate that I have not yet solved. The kate program uses KSyntaxHighlighting for its language detection, which in turn is the basis for which LSP server is assigned to a given document. This engine does not seem to support as complex detection logic as I hoped from it. Concretely, it either works on matching on an extension / a basename (same field for both cases) or mime type. This combined with our habit in Debian to use extension less files like debian/control vs. debian/tests/control or debian/rules or debian/upstream/metadata makes things awkward a best. Concretely, the syntax engine cannot tell debian/control from debian/tests/control as they use the same basename. Fortunately, the syntax is close enough to work for both and debputy is set to use filename based lookups, so this case works well enough. However, for debian/rules and debian/upstream/metadata, my understanding is that if I assign these in the syntax engine as Debian files, these rules will also trigger for any file named foo.rules or bar.metadata. That seems a bit too broad for me, so I have opted out of that for now. The down side is that these files will not work out of the box with kate for now. The current LSP configuration in kate does not recognize makefiles or YAML either. Ideally, we would assign custom languages for the affected Debian files, so we do not steal the ID from other language servers. Notably, kate has a built-in language server for YAML and debputy does nothing for a generic YAML document. However, adding YAML as a supported language for debputy would cause conflict and regressions for users that are already happy with their generic YAML language server from kate. So there are certainly still work to be done. If you are good with KSyntaxHighlighting and know how to solve some of this, I hope you will help me out.
Changes unrelated to kate While I was working on debputy, I also added some other features that I want to mention.
  1. The debputy lint command will now show related context to diagnostic in its terminal report when such information is available and is from the same file as the diagnostic itself (cross file cases are rendered without related information). The related information is typically used to highlight a source of a conflict. As an example, if you use the same field twice in a stanza of debian/control, then debputy will add a diagnostic to the second occurrence. The related information for that diagnostic would provide the position of the first occurrence. This should make it easier to find the source of the conflict in the cases where debputy provides it. Let me know if you are missing it for certain diagnostics.

  2. The diagnostics analysis of debian/control will now identify and flag simple duplicated relations (complex ones like OR relations are ignored for now). Thanks to Matthias Geiger for suggesting the feature and Otto Kek l inen for reporting a false positive that is now fixed.

Closing I am glad I tested with kate to weed out most of these issues in time before the freeze. The Debian freeze will start within a week from now. Since debputy is a part of the toolchain packages it will be frozen from there except for important bug fixes.

1 March 2025

Debian Brasil: Debian Day 30 years online in Brazil


title: Debian Day 30 years online in Brazil description: by Paulo Henrique de Lima Santana (phls) published: true date: 2025-03-01T17:39:03.284Z tags: blog, english editor: markdown dateCreated: 2023-08-25T16:00:00.000Z In 2023 the traditional Debian Day is being celebrated in a special way, after all on August 16th Debian turned 30 years old! To celebrate this special milestone in the Debian's life, the Debian Brasil community organized a week with talks online from August 14th to 18th. The event was named Debian 30 years. Two talks were held per night, from 7:00 pm to 10:00 pm, streamed on the Debian Brasil channel on YouTube totaling 10 talks. The recordings are also available on the Debian Brazil channel on Peertube. We had the participation of 9 DDs, 1 DM, 3 contributors in 10 activities. The live audience varied a lot, and the peak was on the preseed talk with Eriberto Mota when we had 47 people watching. Thank you to all participants for the contribution you made to the success of our event. Veja abaixo as fotos de cada atividade: Nova gera o: uma entrevista com iniciantes no projeto Debian Nova gera o: uma entrevista com iniciantes no projeto Debian Instala o personalizada e automatizada do Debian com preseed Instala o personalizada e automatizada do Debian com preseed Manipulando patches com git-buildpackage Manipulando patches com git-buildpackage debian.social: Socializando Debian do jeito Debian debian.social: Socializando Debian do jeito Debian Proxy reverso com WireGuard Proxy reverso com WireGuard Celebra o dos 30 anos do Debian! Celebra o dos 30 anos do Debian! Instalando o Debian em disco criptografado com LUKS Instalando o Debian em disco criptografado com LUKS O que a equipe de localiza o j  conquistou nesses 30 anos O que a equipe de localiza o j conquistou nesses 30 anos Debian - Projeto e Comunidade! Debian - Projeto e Comunidade! Design Gr fico e Software livre, o que fazer e por onde come ar Design Gr fico e Software livre, o que fazer e por onde come ar

7 February 2025

Emmanuel Kasper: Wireless headset dongle not detected by PulseAudio

For whatever reason, when I plug and unplug my Wireless Headset dongle over USB, it is not always detected by the PulseAudio/Pipewire stack which is running our desktop sound Linux those days. But we can fix that with a restart of the handling daemon, see below.
In PulseAudio terminology an input device (microphone) is called a source, and an output device a sink. When the headset dongle is plugged in, we can see it on the USB bus:
$ lsusb   grep Headset 
Bus 001 Device 094: ID 046d:0af7 Logitech, Inc. Logitech G PRO X 2 Gaming Headset
The device is detected correctly as a Human Interface Device (HID) device
$ dmesg
...
[310230.507591] input: Logitech Logitech G PRO X 2 Gaming Headset as /devices/pci0000:00/0000:00:14.0/usb1/1-1/1-1.1/1-1.1.4/1-1.1.4:1.3/0003:046D:0AF7.0060/input/input163
[310230.507762] hid-generic 0003:046D:0AF7.0060: input,hiddev2,hidraw11: USB HID v1.10 Device [Logitech Logitech G PRO X 2 Gaming Headset] on usb-0000:00:14.0-1.1.4/input
However it is not seen in the list of sources / sinks of PulseAudio:
$ pactl list short sinks
58      alsa_output.usb-Lenovo_ThinkPad_Thunderbolt_3_Dock_USB_Audio_000000000000-00.analog-stereo      PipeWire        s16le 2ch 48000Hz       IDLE
62      alsa_output.pci-0000_00_1f.3.analog-stereo      PipeWire        s32le 2ch 48000Hz       SUSPENDED
95      bluez_output.F4_4E_FD_D2_97_1F.1        PipeWire        s16le 2ch 48000Hz       IDLE
This unfriendly list shows my docking station, which as a small jack connector for a wired cable, the built in speaker of my laptop, and a blutooth headset. If I restart Pipewire,
$ systemctl --user restart pipewire
then the headset appears as possible audio output.
$ pactl list short sinks
54      alsa_output.usb-Lenovo_ThinkPad_Thunderbolt_3_Dock_USB_Audio_000000000000-00.analog-stereo      PipeWire        s16le 2ch 48000Hz       SUSPENDED
56      alsa_output.usb-Logitech_Logitech_G_PRO_X_2_Gaming_Headset_0000000000000000-00.analog-stereo    PipeWire        s16le 2ch 48000Hz       SUSPENDED
58      alsa_output.pci-0000_00_1f.3.analog-stereo      PipeWire        s32le 2ch 48000Hz       SUSPENDED
77      bluez_output.F4_4E_FD_D2_97_1F.1        PipeWire        s16le 2ch 48000Hz       SUSPENDED
Once you have set the default input / output device, for me in Gnome, you can check it with:
$ pactl info   egrep '(Sink Source)'
Default Sink: alsa_output.usb-Logitech_Logitech_G_PRO_X_2_Gaming_Headset_0000000000000000-00.analog-stereo
Default Source: alsa_input.usb-Logitech_Logitech_G_PRO_X_2_Gaming_Headset_0000000000000000-00.mono-fallback
Finally let us play some test sounds:
$ speaker-test --test wav --nloops 1 --channels 2
And test some recording, you will hear the output around one second after the speaking (yes that is recorded audio sent over a Unix pipe for playing !):
# don't do this when the output is a speaker, this will create audio feedback (larsen effect)
$ arecord -f cd -   aplay

2 February 2025

Joachim Breitner: Coding on my eInk Tablet

For many years I wished I had a setup that would allow me to work (that is, code) productively outside in the bright sun. It s winter right now, but when its summer again it s always a bit. this weekend I got closer to that goal. TL;DR: Using code-server on a beefy machine seems to be quite neat.
Passively lit coding Passively lit coding

Personal history Looking back at my own old blog entries I find one from 10 years ago describing how I bought a Kobo eBook reader with the intent of using it as an external monitor for my laptop. It seems that I got a proof-of-concept setup working, using VNC, but it was tedious to set up, and I never actually used that. I subsequently noticed that the eBook reader is rather useful to read eBooks, and it has been in heavy use for that every since. Four years ago I gave this old idea another shot and bought an Onyx BOOX Max Lumi. This is an A4-sized tablet running Android and had the very promising feature of an HDMI input. So hopefully I d attach it to my laptop and it just works . Turns out that this never worked as well as I hoped: Even if I set the resolution to exactly the tablet s screen s resolution I got blurry output, and it also drained the battery a lot, so I gave up on this. I subsequently noticed that the tablet is rather useful to take notes, and it has been in sporadic use for that. Going off on this tangent: I later learned that the HDMI input of this device appears to the system like a camera input, and I don t have to use Boox s monitor app but could other apps like FreeDCam as well. This somehow managed to fix the resolution issues, but the setup still wasn t as convenient to be used regularly. I also played around with pure terminal approaches, e.g. SSH ing into a system, but since my usual workflow was never purely text-based (I was at least used to using a window manager instead of a terminal multiplexer like screen or tmux) that never led anywhere either.

VSCode, working remotely Since these attempts I have started a new job working on the Lean theorem prover, and working on or with Lean basically means using VSCode. (There is a very good neovim plugin as well, but I m using VSCode nevertheless, if only to make sure I am dogfooding our default user experience). My colleagues have said good things about using VSCode with the remote SSH extension to work on a beefy machine, so I gave this a try now as well, and while it s not a complete game changer for me, it does make certain tasks (rebuilding everything after a switching branches, running the test suite) very convenient. And it s a bit spooky to run these work loads without the laptop s fan spinning up. In this setup, the workspace is remote, but VSCode still runs locally. But it made me wonder about my old goal of being able to work reasonably efficient on my eInk tablet. Can I replicate this setup there? VSCode itself doesn t run on Android directly. There are project that run a Linux chroot or in termux on the Android system, and then you can VNC to connect to it (e.g. on Andronix) but that did not seem promising. It seemed fiddly, and I probably should take it easy on the tablet s system.

code-server, running remotely A more promising option is code-server. This is a fork of VSCode (actually of VSCodium) that runs completely on the remote machine, and the client machine just needs a browser. I set that up this weekend and found that I was able to do a little bit of work reasonably.

Access With code-server one has to decide how to expose it safely enough. I decided against the tunnel-over-SSH option, as I expected that to be somewhat tedious to set up (both initially and for each session) on the android system, and I liked the idea of being able to use any device to work in my environment. I also decided against the more involved reverse proxy behind proper hostname with SSL setups, because they involve a few extra steps, and some of them I cannot do as I do not have root access on the shared beefy machine I wanted to use. That left me with the option of using a code-server s built-in support for self-signed certificates and a password:
$ cat .config/code-server/config.yaml
bind-addr: 1.2.3.4:8080
auth: password
password: xxxxxxxxxxxxxxxxxxxxxxxx
cert: true
With trust-on-first-use this seems reasonably secure. Update: I noticed that the browsers would forget that I trust this self-signed cert after restarting the browser, and also that I cannot install the page (as a Progressive Web App) unless it has a valid certificate. But since I don t have superuser access to that machine, I can t just follow the official recommendation of using a reverse proxy on port 80 or 431 with automatic certificates. Instead, I pointed a hostname that I control to that machine, obtained a certificate manually on my laptop (using acme.sh) and copied the files over, so the configuration now reads as follows:
bind-addr: 1.2.3.4:3933
auth: password
password: xxxxxxxxxxxxxxxxxxxxxxxx
cert: .acme.sh/foobar.nomeata.de_ecc/foobar.nomeata.de.cer
cert-key: .acme.sh/foobar.nomeata.de_ecc/foobar.nomeata.de.key
(This is getting very specific to my particular needs and constraints, so I ll spare you the details.)

Service To keep code-server running I created a systemd service that s managed by my user s systemd instance:
~ $ cat ~/.config/systemd/user/code-server.service
[Unit]
Description=code-server
After=network-online.target
[Service]
Environment=PATH=/home/joachim/.nix-profile/bin:/nix/var/nix/profiles/default/bin:/usr/local/bin:/usr/bin:/bin:/usr/local/games:/usr/games
ExecStart=/nix/var/nix/profiles/default/bin/nix run nixpkgs#code-server
[Install]
WantedBy=default.target
(I am using nix as a package manager on a Debian system there, hence the additional PATH and complex ExecStart. If you have a more conventional setup then you do not have to worry about Environment and can likely use ExecStart=code-server. For this to survive me logging out I had to ask the system administrator to run loginctl enable-linger joachim, so that systemd allows my jobs to linger.

Git credentials The next issue to be solved was how to access the git repositories. The work is all on public repositories, but I still need a way to push my work. With the classic VSCode-SSH-remote setup from my laptop, this is no problem: My local SSH key is forwarded using the SSH agent, so I can seamlessly use that on the other side. But with code-server there is no SSH key involved. I could create a new SSH key and store it on the server. That did not seem appealing, though, because SSH keys on Github always have full access. It wouldn t be horrible, but I still wondered if I can do better. I thought of creating fine-grained personal access tokens that only me to push code to specific repositories, and nothing else, and just store them permanently on the remote server. Still a neat and convenient option, but creating PATs for our org requires approval and I didn t want to bother anyone on the weekend. So I am experimenting with Github s git-credential-manager now. I have configured it to use git s credential cache with an elevated timeout, so that once I log in, I don t have to again for one workday.
$ nix-env -iA nixpkgs.git-credential-manager
$ git-credential-manager configure
$ git config --global credential.credentialStore cache
$ git config --global credential.cacheOptions "--timeout 36000"
To login, I have to https://github.com/login/device on an authenticated device (e.g. my phone) and enter a 8-character code. Not too shabby in terms of security. I only wish that webpage would not require me to press Tab after each character This still grants rather broad permissions to the code-server, but at least only temporarily

Android setup On the client side I could now open https://host.example.com:8080 in Firefox on my eInk Android tablet, click through the warning about self-signed certificates, log in with the fixed password mentioned above, and start working! I switched to a theme that supposedly is eInk-optimized (eInk by Mufanza). It s not perfect (e.g. git diffs are unhelpful because it is not possible to distinguish deleted from added lines), but it s a start. There are more eInk themes on the official Visual Studio Marketplace, but because code-server is a fork it cannot use that marketplace, and for example this theme isn t on Open-VSX. For some reason the F11 key doesn t work, but going fullscreen is crucial, because screen estate is scarce in this setup. I can go fullscreen using VSCode s command palette (Ctrl-P) and invoking the command there, but Firefox often jumps out of the fullscreen mode, which is annoying. I still have to pay attention to when that s happening; maybe its the Esc key, which I am of course using a lot due to me using vim bindings. A more annoying problem was that on my Boox tablet, sometimes the on-screen keyboard would pop up, which is seriously annoying! It took me a while to track this down: The Boox has two virtual keyboards installed: The usual Google ASOP keyboard, and the Onyx Keyboard. The former is clever enough to stay hidden when there is a physical keyboard attached, but the latter isn t. Moreover, pressing Shift-Ctrl on the physical keyboard rotates through the virtual keyboards. Now, VSCode has many keyboard shortcuts that require Shift-Ctrl (especially on an eInk device, where you really want to avoid using the mouse). And the limited settings exposed by the Boox Android system do not allow you configure that or disable the Onyx keyboard! To solve this, I had to install the KISS Launcher, which would allow me to see more Android settings, and in particular allow me to disable the Onyx keyboard. So this is fixed. I was hoping to improve the experience even more by opening the web page as a Progressive Web App (PWA), as described in the code-server FAQ. Unfortunately, that did not work. Firefox on Android did not recognize the site as a PWA (even though it recognizes a PWA test page). And I couldn t use Chrome either because (unlike Firefox) it would not consider a site with a self-signed certificate as a secure context, and then code-server does not work fully. Maybe this is just some bug that gets fixed in later versions. Now that I use a proper certificate, I can use it as a Progressive Web App, and with Firefox on Android this starts the app in full-screen mode (no system bars, no location bar). The F11 key still does t work, and using the command palette to enter fullscreen does nothing visible, but then Esc leaves that fullscreen mode and I suddenly have the system bars again. But maybe if I just don t do that I get the full screen experience. We ll see. I did not work enough with this yet to assess how much the smaller screen estate, the lack of colors and the slower refresh rate will bother me. I probably need to hide Lean s InfoView more often, and maybe use the Error Lens extension, to avoid having to split my screen vertically. I also cannot easily work on a park bench this way, with a tablet and a separate external keyboard. I d need at least a table, or some additional piece of hardware that turns tablet + keyboard into some laptop-like structure that I can put on my, well, lap. There are cases for Onyx products that include a keyboard, and maybe they work on the lap, but they don t have the Trackpoint that I have on my ThinkPad TrackPoint Keyboard II, and how can you live without that?

Conclusion After this initial setup chances are good that entering and using this environment is convenient enough for me to actually use it; we will see when it gets warmer. A few bits could be better. In particular logging in and authenticating GitHub access could be both more convenient and more safe I could imagine that when I open the page I confirm that on my phone (maybe with a fingerprint), and that temporarily grants access to the code-server and to specific GitHub repositories only. Is that easily possible?

Next.

Previous.