Search Results: "ressu"

8 October 2026

Antoine Beaupr : PSA: Europe changes time forward soon, North America next, for the last time?

This is a copy of an email I sent at work. I'm not sure I should be making noise about this here, feedback welcome.
This is your bi-yearly reminder that time is changing soon! October 25th in Europe, November 1st in North America. Less people in Canada are changing this year, with BC, Alberta, Manitoba and Northwest Territories getting rid of DST.

What's happening? Some places in the world implement what is called Daylight saving time or DST: https://en.wikipedia.org/wiki/Daylight_saving_time Normally, you shouldn't have to do anything: computers automatically change time following local rules, assuming they are correctly configured, provided recent updates have been applied in the case of a recent change in said rules (because yes, this happens, and happened this year, and yes, you need to upgrade your software!). Of course, appliances like your microwave oven will likely not change time and will need to adjusted unless they are so-called "smart", in which case they are part of the skynet botnet and should be destroyed. If your clock is flashing "0:00" or "12:00", you have no action to take to adapt to this change, lucky you. If you haven't changed time in six months, congratulations, your clock will be accurate again! In any case, you should still consider DST because it might affect some of your meeting schedules, particularly if you set up a new meeting schedule in the last 6 months and forgot to consider this change.

If your location does not have DST Properly scheduled meetings affecting multiple time zones are set in UTC time, which does not change. So if your location does not observer time changes, your (local!) meeting time will not change. But be aware that some other folks attending your meeting might have the DST bug and their meeting times will change. Be kind to those poor souls which might be missing meetings by a full hour because time flies backwards for them.

If you do observe DST If you are affected by daylight savings, your local meeting times will change for UTC meetings. Normally, your meeting times are scheduled to take this into account and the new hours should be reasonable. But now is a good time to verify that. Take a look at your schedule for the next couple of weeks and reschedule meetings before the daylight saving come up to avoid too much disruption. You have only a couple of weeks to do so right now.

When do times change, how, and and where? As regular readers will remember, the rule of thumb is:
Spring forward, fall backwards.
That is, during the season of Spring, the clocks move forward, and during the Fall (like right now), they move backwards. That is in the northern hemisphere, but then the southern hemisphere is often saner and doesn't switch anyways. So time will move backwards which means an extra hour of sleep. Unless you have children or bad sleep, in which case your body doesn't care about what the clock says and will wake up one hour earlier than what it should. And of course, this doesn't happen everywhere at once, so let's see when it happens where.

Europe The dance starts in Europe. The change happens on the last Sunday in October at 01:00 UTC (not local time!), that is October 25th. If you are in the central European timezone, also known as Amsterdam, Berlin, or Paris time depending on your national affiliation, that essentially means that at 2:59 local the clocks will fall back to 2:00 instead of going to 3:00. Concretely, set your watch back one hour before going to bed, go to bed at the normal time, and enjoy an extra hour of sleep or leisure. If you have kids, you might want to start getting them to bed slightly earlier every day for a week before the change so they take time getting used to the change. If you have trouble sleeping in the morning, find your inner child and do that to yourself as well.

USA / Canada Then it's the US[1] and Canada[2] joining the dance, on the First Sunday in November at 02:00 local (not UTC!), that is, I believe, November 1st 2026. This means that, at 1:59, the clocks will flip to 1:00, instead of 2:00. Concretely, do like the Europeans and tweak your clock before going to bed. That is a little less than four weeks from now. [1] except Arizona (except the Navajo nation), US territories, and Hawaii [2] except Yukon, Saskatchewan, (newly) British Columbia, (newly) Alberta, (newly) Northwest Territories, (newly) Manitoba, one island in Nunavut (Southampton Island), one town in Ontario (Atikokan) and small parts of Quebec (Le Golfe-du-Saint-Laurent)

Other places with DST This time again, I must apologize to the people of Cuba, Lebanon, Israel, Palestine, Egypt, Chile, Australia, and New Zealand, as you fine folks all have your own DST rules that are omitted here for brevity. I rely on this page from Wikipedia to be updated by time nerds accurately for this message, and it should provide you with a rough idea of what's coming: https://en.wikipedia.org/wiki/Daylight_saving_time_by_country In general, changes also happen in October, but either on different times or different days, except in the south hemisphere, where they might happen in September (oops, sorry NZ folks, I'm late!).

Places without DST Everyone else, enjoy, you're on the right side of history, and we thank you for the good example you give us.

Changes since last time There's been lots of changes since last time:
  • British Columbia moved to permanent -07 on 2026-03-09, that is it will not change to normal time in November
  • Alberta moved to permanent -06 on 2026-06-18, similar to BC above.
  • Canada s Northwest Territories moved to permanent -06 on 2026-08-21, matching Alberta.
  • Manitoba moves to permanent -05 on 2026-10-31.
  • Morocco moves to permanent +00 on 2026-09-20.
  • Moldova has used EU transition times since 2022, but the tz database only noticed in 2026
This is my interpretation of the changes announced on the tzdata mailing list here: https://lists.iana.org/hyperkitty/list/tz-announce@iana.org/latest If the eastward trend continues, Canada should adopt country-wide "no daylight savings" rules by 2027, although there's actually no sign of the other provinces (Ontario, Qu bec and so on) currently running bills to change those rules just yet. Poor Canadians like me confused about time in their countries can refer to this section of Wikipedia for details: https://en.wikipedia.org/wiki/Daylight_saving_time_in_Canada#By_province_and_territory ... and particularly the image featured there: https://commons.wikimedia.org/wiki/File:Canada_time_zone_map-en.svg It also seems like the US government might finally adopt a permanent daylight saving change bill in 2026, as the "Sunshine protection act" pass the house in July: https://en.wikipedia.org/wiki/Sunshine_Protection_Act True to form, this was associated with absolutely ridiculous pressure from Donald Trump against republicans (his own party!) objecting to the change:
On July 14, 2026, the House passed a Sunshine Protection Act bill backed by President Trump. Nevertheless, the bill was opposed in the Senate by Republicans, including Senator Cotton. In response, on October 3, 2026, Trump shared a post on Truth Social urging Cotton to approve the bill, where he revealed Cotton's personal cellphone number and called on people to call him.
https://www.theguardian.com/us-news/2026/oct/03/trump-tom-cotton-daylight-saving-time Given that the last time the US did a major change to the daylight savings policy (in 2005), Canada followed suit to stay in sync, it's quite possible Trump's mad dash might actually finish getting rid of DST in North America: https://en.wikipedia.org/wiki/Energy_Policy_Act_of_2005#Change_to_daylight_saving_time

19 August 2026

Antoine Beaupr : The people vs the AI overlords

Also in this series:
In a post to oss-security, my (Debian) co-developer Russ Allbery stated that "open source software [OSS] is coming face to face with a motivation crisis that has been building for a long time". His point is essentially that large language models (LLMs1) are making the existing OSS community crisis worse. For him, it's the flood of code reviews, but he argues that varies according to people's desires, for others it's security issues and so on. I think Russ is right, but I would argue there's something much bigger than our open communities going on here, and it's about the entire field of computing. This pressure is on all of us, regardless of whether we work on open source software or not.

How people use models People using LLMs in their workflow have radically changed how programming works, even for people who claim to avoid vibe-coding. And I'm sorry to single out one poor maintainer here: it's not you, Brian, you're just one example among many. But this is typical use of those models nowadays:
Once it s done, I ll use /code-review and let Claude spawn sub-agents to do a full review of the new code. This usually finds some problems, even problems that the main Claude instance didn t find during its validation. I usually keep running /code-review again and again after finding and fixing issues, until there aren t any left.
Think about what that means for a minute. This is automation built to fire up dozens of agents crunching at a problem for minutes if not hours of GPU compute time, in parallel. This is essentially a couple of shelves in a datacenter rack, totally maxed out on power and cooling, abstracted behind a cute little /code-review command. The author, here, is rightly concerned that "Anthropic could pull the rug out and require API pricing", which is perhaps a code word for "charging something closer to actual costs". Brian also pays lip service to environmental and societal costs but those are largely abstracted away, so let's keep that conversation aside here as well, as we have discussed it before anyways. But clearly, this way of working has an (externalized) cost, to say the least.

Paying for non-free tools For decades my work has been focused on free and open source software. I've long stopped using proprietary operating systems like Windows or Mac, and even before that switch, I was mostly using free software on those platforms, partly out of principle, but also because I was too poor. So the tools of my trade are free, and I build free tools with them. It feels like we're going backwards: when I was in school, a millennia ago, my classmates didn't have access to a compiler and were wondering how they would scrape the money to buy a compiler like Borland's or Microsoft's. I had a compiler built into my operating system (FreeBSD at the time), so that wasn't a problem for me. For them, it was a significant expense, but at least those expenses (or more shady sourcing of programs) were a one-shot deal. Fast forward 30 years, and software is rented: you pay monthly for Adobe's Photoshop and Microsoft's office suite just like you pay for Netflix, Disney+ or Spotify2. And now you need to add dozens (if not hundreds of dollars) of monthly credits to access LLMs on top of that. So, now we have to pay to get anything done? This is peak enshitification of our job: first they steal our work to train their models, and then they sell it back to us at a profit.

Attacking the engineers AI is coming for our jobs, as engineers, if not everyone, according to the narrative. For a while now, our job market has deteriorated: less jobs, for less pay. Lots of skilled engineers looking for work and finding crap jobs then still looking while working. This is not by accident.3 We engineers have a lot of power, it is not organized, but that's just a couple of unions away (easy!). Tech overlords know this, so they are attacking our profession, directly, by forcing us to train and use models that they can control. Even in environments where programmers are not forced to use LLMs, the mere pressure of other people's LLM-generated work is huge. One can be forced to review LLM outputs, or just peer pressured you into producing more. We're now supposed to accelerate delivery, because models can presumably do things so much better and faster. With supply chain security becoming such a large vector that we now have worms crawling around developers accounts on NPM, increasing the delivery cadence seems like a really bad idea.4 The LLM hype is part of the larger wave of cyberwar against workers, against water, against the Earth, against all the people. This is not a matter of individually "adapting to the reality" or personal choice, but a political, social, hard problem we need to address collectively.

  1. I again prefer the term LLM to "AI" because models do not possess intelligence. I did use it in the title because click baiting is apparently important, but I stopped short of calling this one "Rage Against the Machines" because that would be the title of every blog post I have ever made.
  2. Yes, I know that Visual Studio is kind of free now, but I wouldn't be surprised if they turn that into a rental as well, because why not.
  3. Beyond sabotaging the job market, Sam Altman event wants to sell "intelligence as a utility" something that is just a really bad idea but especially shows how megalomaniac those people are.
  4. This brings back memories of another era, walking us back decades in terms of computer security.

6 July 2026

Aigars Mahinovs: How to make a good group photo

Taking a good group photo consists of multiple aspects: I can say with confidence that nearly everything here comes from having failed to do these things right at least once, even on the latest attempts, so this is an ideal to reach towards, not something we expect to hit every time. The Goal The main goal of a big event group photo is capture both the moment itself and each individual person inside that moment. We want people, who were not there to see all the people involved and get an impression of what it was like being there. It needs to show the breadth and depth of people that make up this group, this project. And we want people who were there to be able to look back the next week, the next year or in ten years and remember - ah, yes, I was there, I was standing right there with this grin on my face next to this wonderful person and I was feeling great. Hardware Based on the goal we want to have high level photographic gear that is able to capture both a broad enough picture to encompass all the people and some of their surroundings to communicate the context (without undue distortions) and to deliver enough detail and resolution so that faces and facial expressions and underlying feelings of every single person in that group could be clearly seen and preserved. To both capture the context and minimise distortion the final picture should be just a bit wider than normal human field of view. That is about 50mm for a full-frame camera or 35mm for a typical 1.6 crop camera. You can go a bit wider if there are no better alternatives (as detailed in the scouting section), but be prepared that corners of the image will be distorted and not really usable (but we can fix that in processing step). Or you can go to unusual aspect ratios, like we did in Debconf 10. In the absence of a 100MP+ camera, you will need to be stitching together multiple frames to achieve resolution high enough to have enough pixels-per-face to see emotions clearly. This means that the photos you will actually be taking will be tighter than the overall field of view mentioned above. Still, a higher resolution camera body is preferable - nowadays 24MP-32MP cameras APS-C provide a good compromise between resolution and price, but 45-67MP full-frame cameras also exist on the market. Assume that we will be shooting in a bright environment, so most likely with quite low ISO settings, that means that high-ISO noise characteristics of more expensive cameras will not really play a role here. You will also not need very fast burst modes, even manual speed of one frame per second is sufficient. You will also want to get as much detail as possible out of your lens, and this is the most important part. You can do amazing work in all other steps of the process and have a great camera too, but if you pair it with a lens that is not sharp, then the end result will be disappointing. You want the lens that is sharpest corner-to-corner when stepped down to about f/8-f/11, that you can get for your system. You also want that lens to be about 85mm full-size sensor or 50mm for 1.6 crop size. Luckily that kind of range is also a great range for optical design and sharpest lenses are typically available in exactly these kinds of sizes. You absolutely want to have a fixed focal length lens, not a zoom lens. Even profession grade zoom lenses often deliver worse image quality compared to fixed lenses that cost less 1/10th of their price (when shooting in the same focal length). Newer design lenses are better than older lenses - optical design, coatings and precision manufacturing have advanced a lot over the decades. Retro look is great for mood, but not as good for actual resolution and clarity. You don't need to overpay for most expensive lenses because those often only improve image quality on lower F-stops. To encompass the whole group we will need to shoot at f/8 and in bright light, so the extra benefits of those f/1.2-capable super expensive lenses will not come into play here. We will have no use for a flash here. A tripod will be too restrictive when rapidly repositioning the camera between different parts of the panorama shoot. But a monopod might help with stability - I have not tried that myself, however. For my last photos I used a Canon EOS R7 (32.5MP) with Canon RF 50mm f/1.8 STM lens and considering an upgrade to Sigma 56mm f/1.4 DC DN for the next time. Scouting Scouting a good location for the group photo is another big chunk of a successful picture. The critical piece of the puzzle is lens-to-face distance. In order to keep everyone's face in-focus and have enough resolution on the farthest faces (without making nearest faces truly massive) we want to do everything possible to reduce the variance in lens-to-face distance - to reduce the difference in distance between closest and farthest face. The most effective way to do that is to have the photographer climb higher. To see this in action on the Debconf photos, compare Debconf6 (very high camera position, group on level ground - good) to Debconf10 (camera not too high, group on stairs, still good) and to Debconf17 (camera could not get high enough and the group is on flat ground - not great). Even the Debconf25 photo was suboptimal from this perspective. The Debconf23 photo was a very good example from the recent years - good height and also the group was positioned in a semi-circle so there were no people directly in front and very near to the camera. So you are looking for the highest point you could get to (even if that requires a special permission of key or a ladder) with a field large enough to fit the whole group comfortably. How to check that? Normally I simply take a photo from the top of the whole area and note down from there where the extreme corners of the group could be and still be fully seen in the shot - not blocked by trees, buildings and shadows. Then I go down and measure that space. Rule of thumb being - people in one horizontal line can stand 1 normal length step from each other and two horizontal lines can be half a step from each other vertically. So I can just measure a rough rectangle in steps, multiply the sides, multiply that by two and I have the rough number of people that can fit there for the photo. Once you have a candidate location or two, it is important to check them at the same time-of-day as you plan to do the photo (see organization section for that). You want to make sure that the whole area of the group is in the same illumination - if half of the group is in the sun and half in a shadow, then you will be having a very bad time later. The absolute ideal positioning for the group photo is to have everyone be in shadow, but still have enough bright skies and bright buildings in front of the people to give good illumination of the faces. Worst you can do is have the sun be behind the people (so all the faces are really dark) and second worst is have the sun be directly in front of the group, so that the faces are very well illuminated, but everyone's eyes are closed because they are being blinded by the sun. And sometimes all you can do is pray for some light clouds to provide for even and dispersed light. Debconf23 was very lucky that way. Another consideration is to how people are going to get to that place. You need to consider accessibility needs of people (it is ok, if it takes more effort or time, but it needs to be organized and communicated well in advance). And you need to consider how the big masses of people will be getting there - how to tell people where exactly it is and how to get there from various locations where people might be hanging out during the event? Having an alternate location indoors might be necessary if the weather report for the next days is not sufficiently predictable. We had to use that contingency in Debconf9, for example. Organization It's hard to take a good group photo if half of the group does not show up or is too late, so this needs some organization to happen smoothly. First of all you need to choose date and time for the photo. The photo does not take too much time from the schedule of the event and can be squeezed in after all the other events are already scheduled. In fact I prefer that as it allows you the flexibility of choosing the date based on weather conditions and time based on light and shadow conditions in potential photo spots. You don't want to choose the daytrip day as most people will be away and return times are not really predictable. You do not want to choose the morning after Cheese and Wine party for obvious reasons. First day and last two days are also sub-optimal as some people arrive late and some leave early for various personal reasons. Also you don't want it to happen just before Cheese and Wine either because then you'd have very little time and clarity to do the processing of the image on the same day. For timing, the best way, in my experience, is to schedule the photo directly after the end of talk sessions before a meal break - lunch or dinner. Typically in the Debconf schedule there are 2-3 daily breaks planned, say for Debconf25 there was lunch, afternoon break and dinner. Talks are planned to end ~10 minutes before those breaks (and meals) begin, so for example, afternoon break starts at 16:00 and all talks in the previous block end at 15:50. In such a case just schedule the "Group photo" event from 15:50 to 16:05. This gives people the info to go there directly from the end of all talks and that they will have sufficient time for break/meal afterwards. Do not forget to specify the location (as exactly as possible) in that event entry and make sure to post it at least two days in advance. People often want to wear something specific for the photo and thus need to know about it in advance. This also makes sure that people do not make alternate food plans for that specific break and don't leave the venue. Announce the date, time and the exact location as wide as possible, don't be shy. Announce and discuss mailing lists, IRC, Signal, Telegram, make sure the front desk knows in case anyone asks in-person, ... Check that it is again included in the announcements email on the day preceding the photo date. When the date has arrived, it is a good idea to check in early with people with special mobility needs to make sure they know where to go, how to get there and how much time they will need to be able to get there on time. As the final round of talks before the group photo is starting up, it is time to recruit "runners". I've had great success with this technique. The idea is pretty simple - for each room where people congregate (talk rooms, hacklabs, cafeteria, outside hackspace, front-desk, ...) go there and choose one person. You want to choose a person that you will recognise and remember among everyone else in the group, either because of who they are or what they are wearing, whatever works best for you. If they agree to help, instruct them to: "at end of talk, announce that the group photo happening now and the location, herd people towards the photo location, be the last person out, make sure there are no stragglers from this area behind you, when you arrive to the photo place I will assume that everyone else from this room is also now there, when you are there catch my attention and show this sign so I know for sure that it is all good and make sure that I did see it from you". With that sorted out all you will need to remember is how many runners you recruited and how many have reported in to figure out if everyone has now arrived or if we still have to wait for someone or some group. Then you will only have one last point of organization left - shaping the crowd into a group. People will not know what your vision for the group photo is, so you will have to give clear and LOUD instructions on where people should not be standing. Use clear, large gestures to support your words. You want to compact the group, have the people that just joined in the last moment and are standing to the side come deeper in and join the crowd. Have any holes in the middle of the crowd filled in. Forming a semi-circle instead of a blob helps with averaging face-to-lens distances. Make sure people are not in unexpected shadows. Make sure carried objects, like umbrellas of flags do not cover the faces of other people. Take the time to look at everyone face to make sure there are no people hiding behind someone's shoulder - typically they are not aware that their face is in fact not really visible. If there are such people, call them out and point directly at them and encourage them to step forward, if they wish to do so. You are the only one seeing the final picture now and only you can correct it before capturing the moment. So a few extra seconds here are worth taking, even if 300+ people are standing in scorching heat and waiting on you. When you are happy with what you are seeing, make sure to tell people clearly that you are now about to take the pictures and again remind them not to move and explicitly not to turn their heads to the side until you are done (this is the source of most of the extra work in processing). Be very loud and clear and make sure you have everyone's undivided attention before you start saying the important stuff. When done - say so. There will be other groups that will want to also have a photo taken after the main group is a bit more dispersed, so don't run away. Typically at least the T-shirt group will want a picture and also all the organizers. Final bit of organization during the group photo shooting itself is the sneaky self-insert. You may choose not to bother with it, or do it in the simplest way, like I did in Debconf6, but if you really want to blend in with the crowd, you need to have someone else take a photo of you in the exact same location at the same date and time from the same location. So you should already during shaping the crowd decide where you would fit in, it is easiest to blend in at the back of the crowd and to one or other side, so that it appears like you are just standing behind the shoulders of a couple peoples. Remember that spot - it is easiest if you stand in the exact same ground spot when your photo is taken. Just go down, recruit a volunteer to take your photo, make sure the settings are fixed to the same ones as for the group photo shots and have them take a handful of shots of you - one of you centered in the camera frame and a couple more with you more towards the corners of the frame. This distortion from being off-center in the frame may be important later. Preparation In addition to preparing the crowd for the photo, you also need to prepare yourself and the equipment. Make sure you have dusted your camera sensor and cleaned both inside and outside glass of your lens. It is usually a good idea to remove any filters from the lens. Install the hood, if that could help with blocking the sun flares. Make sure you have the right lens and that you have installed the right lens. For fixed settings I typically shoot in JPEG with RAW being there more like an emergency backup. The extra dynamic range of RAW could be used, but it is really complex to do that in combination with image blending and it is hard to get right, so I prefer an all-JPEG workflow and fix the dynamic range in the scene itself, before shooting. For Canon I am using the Standard profile that boosts the color saturation and sharpness a bit as I just enjoy that look and find it hard to get anything significantly better from RAW data even with a lot of effort. In any case make sure you have enough space on the cards to take at least 100 images and that you have a full battery. Do not use high speed burst setting because it is then too easy to take too many pictures at the start of the sequence and be stuck with your camera still in "Busy" state writing big RAW files to slowish SD cards and not allowing you to finish the full picture rapidly. You want to have the shutter speed at at least 1/100th of a second to prevent blur from both your hand movements and also from people in the shot moving around a bit (image stabilisation will not help you there). And you want to have the aperture to be around f/8 - lower apertures risk people in front or behind falling out of focus, make the lenses look less sharp. Higher apertures also start to become less sharp due to diffraction effects above f/8. ISO should stay as low as possible, ideally at ISO 100, but if there is not enough light then upping the ISO to 400 would be the first step that I would try to do and second would be decreasing the aperture to f/5.6. If there is too much light, then increasing the shutter speed should be the safe thing to do. As people start to arrive into the shooting location - check the exposure and nail down the settings, ideally in manual mode. Consider that left side could be a bit lighter or darker than right side. Err on the side of making the picture a bit too dark as there is more depth to darkness before cut-off compared to clipping on the high end. However, do not trust the exposure detection, instead take a picture and look specifically at skin tones in faces of people that already are standing in the photo area. Faces are the key bit and the exposure needs to be adjusted just to the faces and ignore darker of lighter clothing. Do some test shots and find settings where faces look not too bright, but also not very dark and fix those settings in manual mode. Now you are ready for the action. Shape the crowd, check the faces and the action can start! Execution During taking of the group photo you want to finish it fast, but at the same time you have to take the time to make it right. If you hurry too much under pressure, you risk being left with unusably blurry images and the whole effort wasted. Having already prepared and verified the manual settings makes it easier. When you are taking pictures, you have to remain as still as possible - even at very high shutter speeds even slow hand movements are still bad for image quality. So think of the movement as of biathlon athlete shooting the very middle of five, very separate targets - take a burst, reframe, then steady up for a second and only then take the next burst. 3 frames per burst are sufficient. 90% of the time the very first photo of a burst will be best. As you move from frame to frame, aim for just a bit more than half-frame overlap. This will give the opportunity to skip frames if all is good, but also have backup coverage of every face in case of problems. Proceed systematically, I typically start off on the top left of the crowd, then go right until the end of the line, then shift down half a frame and go left until the end and repeat until I am done with the crowd. After that it is very helpful to also immediately take photos of a "frame" around the whole crowd. Stitching process often distorts the frames in weird ways that leave holes in the resulting image that you can fill if you have a wide frame around the crowd. It is possible to compensate with creative cutouts in the final image (like Debconf9), but the more framing room you make, the more flexible you will be able to be with cropping of the final photo. The frame also gives you the opportunity to capture more of the context of the place and space. As an example, Debconf25 group photo in the end consisted from 9 images + 1 for sick people + 1 for me. I ended up missing the framing shots for bottom left, top left and top right corners. To get there I took 68 images. And in some years it was more than a hundred. Processing This part might be less stressful than taking the pictures from intensity perspective, but it lasts longer. Depending on you luck, skill and perfectionism it can take anywhere from 3 to 9 hours of work to complete. Before you start, however, you should first request things that you will need for other people. This can even be done before taking the actual group photo, but usually I forget. To finish the photo you will need three things: The first two you should be able to get from the respective organizers. The motto is harder. I typically try to ask the current DPL to come up with something describing the current mood of the project or of the event, but it is rare that it is that easy. Most of the time I came up with something as I was editing the photo and reflecting on what was the mood, the feeling, the mojo of this conference and of this year was like. Bend that around a recognisable phrase or expression, make it a bit more insider-relevant and you are on the right path. Some years this was the hardest part. For the panorama stitching I will describe the workflow that has served me good for years, but maybe there are better ways possible nowadays. Feel free to let me know! First I would save all photos taken and select one sharpest photo from every burst. Next I would select the minimal number of photos that appear to be covering the entire crowd. The fewer images you use, the better in the end because the most quality problems crop up in the areas where photos are getting stitched together. Fewer seams leads to fewer issues. Open Hugin (you will also need enblend and enfuse installed) and import your minimal set of images into it. Click the "Align" button and wait a while - the processor will be trying to figure out keypoints in each image and then try to match these points between the images to try to fit them all together into a single projection. To do that it will distort the images. This is the trial and error process part. You may need to add, remove or replace images to get the stitching to work or to work better. You may want to add more of the frame images to fill the ragged holes around the image. After initial alignment, go to "Move/Drag" tab and move the image a bit up in the projected field of view and make it a bit more central visually. That will help a bit with the distortions in the near-by people and people in the corners of the image. In the "Crop" tab set the initial crop - leave it generous, you can always crop more in later steps. Do not be afraid of leaving in sizable chunks of black homes, empty skies or grass. All of that can be filled in later as well. Go back to the "Assistant" tab and click "Create panorama". It is good enough to have JPEG output at 100% quality using exposure corrected low dynamic range output option. Make sure to check the "Keep intermediate images" option. This will not only generate the final, merged panorama, but also keep around the individual images after perspective correction and exposure blending steps. These are critical for fixing blending error in the next step. You might need to go back a forth a few times with a different sets of source images, maybe adding some image between other two, maybe removing another to reach a better starting point. The key part to pay attention - how many ugly stitches are there in the image. Check every face, the blending algorithms do not recognise faces and sometimes try to stitch one face from two or more images creating very weird effects. They can be fixed in the next step, but it is rather hard manual work, so the fewer such faces are in the blended image, the less work you will have. In some years I've managed to find a combination where all faces were good and in other years I had to manually fix 13-15 faces. Do not try to blend the extra pictures (like with you or with sick people) into the main panorama with Hugin - it will get very confused with the parts of the grass that it is able to see where other people were standing. The next is the final processing in GIMP. Think of it like a large and complex project - do as much as possible in separate layers, save often. Fixing wrongly stitched faces and also putting yourself into the photo are very similar activities in the end. Just the scale and the source differ. For yourself you just cut out yourself (upper torso is enough) from the separate photo. For corrupted face, choose one of two intermediate images that the Hugin created where the face is transformed, but not yet merged (with a different version of itself). In either case crop the photo to roughly the interesting size and put roughly in the right spot as a separate layer on top of the group photo background. Reduce the opacity of the small layer to 30-40% and zoom in to 400%. With that it is much simpler to position the layer with pixel precision. Then all you need to do is add a layer mask to this layer and paint it just right. Basically in layer mask black means transparent and white means non-transparent. So you need to just make everything that is you have white mask and everything that is not you have black mask. And smudge the border a bit with finger tool or blur to make the transition smoother. Easy to say. Hard to do. This is what takes most of the actual work hours in post-processing. You might miss someone. I am sure Phill is just thrilled to see me in the very middle of the Debconf25 final picture .... But do try to fix them all. Use large, sweeping geometric figures to cover up black holes, empty grass fields and other sub-optimal corner features. And then use that newly created free space to put in a large version of the logo of this years conference, decently sized motto and slightly smaller invitation to the next years conference. Do not forget to add a copyright and license statement somewhere in the corner in smaller, but still well readable font. I am using a text like: "Photo by: Full Name, Email: fullemail@debian.org, License: GPLv2+ or CCv3-BY" This ensures that this image may be used in any press coverage (with basic attribution) and also can be included in any GPL-licensed software, if that ever comes up. The same statement is also in the metadata of the image file (see Image-Metadata-Edit metadata in GIMP) along with information that states that this is "Debian Developer Conference Group photo, City, Country, Year". Image->Image properties->Comment is another place where GIMP hides this EXIF information. For ease of use, in addition to a full-resolution image it is also useful to make a lower resolution version that would still fit on a 4K screen at full resolution, so about 3840px wide. Some photo hosting services set other limits for image size as well, so it might be needed to scale the image down below 100Mpix to upload it to Google Photos, for example. Publishing So, it is finally 1AM and the group photo is ready! How do you push it out to people? Well, in all possible ways and places. Again - don't be shy, people do really want to see it. Push it to whatever you use for your shared photos. Push it to Debconf shared git (note that this is GIT-LFS repo, make sure you know how to add content to the LFS specifically). All permanent links to that in GroupPhotosAll wiki. And then send those links to IRC, Signal, Telegram groups, debconf-announce mailing list. Publish it in your blog and push that to Debian Planet. Push it in Threads, Bluesky and Mastodon. Send an email separately to Debconf orga team. And one to Debian Publicity Team so they can put it into the Debian Home Page and push via Debian micronews accounts. And that is about it. Now you can go back to enjoying the rest of the conference. Or running around doing other things that you think need to be done. It's up to you. You did it. This moment will remain with people for a very long time. And you helped. Questions? Feedback? Just ask here or here.

27 June 2026

Jonathan McDowell: onak 0.6.5 released

I had intended that the next release of onak, my OpenPGP keyserver, would be 0.7.0, and include OpenPGP v6 support (RFC9580). However events conspired to make a 0.6.5 release a really good idea. Firstly, I threw an LLM at the code base and asked it to review it. This isn t intended to be a post about LLMs, but there s a considerable amount of pressure at work to be AI native . I m very much an AI sceptic, so I figured throwing it at a code base I know well might be an interesting exercise. It did find a bunch of embarrassing mistakes, but I don t think there was anything earth shattering that a human reviewer wouldn t have pulled me on. The problem is with a hobby project with a single user there s no actual review of my work. I also enabled GitHub s security scanning. It mostly complained about format strings, and those were easy enough to fix up. Next I threw AFLplusplus at the code. I d previously tried American Fuzzy Lop, but not in some time. AFL++ found a whole bunch of places I should really have checked available buffer lengths and wasn t doing so. It really is an incredibly easy tool to get up and running. valgrind is also a tool I ve used before, and rate highly. Thankfully it didn t find anything in my testing this time. Finally I threw a few more automated tests into the mix and discovered something has changed around dynamic linking such that the libonak symbols in the dynamic key database backends were using private copies, rather than the main binary. This caused problems with seeing the correct configuration settings in some instances. All in all this release is not my proudest moment; a bunch of the issues fixed should never have made it to a release. (Also, just to explicitly state it, all the actual code in this release was artisanly crafted by me, in vim. The only involvement of an LLM was for a review pass.) Available locally or via GitHub.
0.6.5 - 27th June 2026
  • Lots of fixes/improvements around length checking
  • Added extra basic tests for maxpaths/sixdegrees/CGI
  • Correctly end transactions in the stacked backend
  • Ensure the file backend avoids stale key data on updates
  • Fix decoding of v2/3 signature creation times
  • Fix EdDSA signature parsing when r < 249 bits long
  • Fix migration of bools from old to new config style
  • Fix parsing of new config details for DB parameters
  • Fix problems with linking + dynamic backends
  • Fix RSA-SHA2-384 signature checking
  • Fix sixdegrees parsing of keyids with high bit set
  • Handle failures in maxpath more gracefully
  • Make new style config path match old path

9 June 2026

Otto Kek l inen: SpacemiT K3 is a compelling RISC-V AI CPU, but difficult to buy

Featured image of post SpacemiT K3 is a compelling RISC-V AI CPU, but difficult to buyThe RISC-V CPU architecture has been gaining a lot of popularity since it launched in 2014, and now that the industry is standardizing on the RVA23 level that includes vector support as a mandatory extension, we are likely to see a lot more edge- and IoT devices with the ability to run local LLMs at reasonable speed, and most importantly at very compelling prices. SpacemiT is a Chinese RISC-V CPU manufacturer that launched on May 11th, 2026, their long-anticipated next-gen RISC-V AI chip K3. It is among the earliest RISC-V CPUs that adhere to the RVA23 standard and performance-wise it is quite capable, providing 130 KDMIPS general computing power, 60 TOPS on INT4 which translates to about 15 tokens per second when running a 30 billion parameter large language model. The aspect that really makes it stand out is: SpacemiT also develops their own Debian-based Linux distribution Bianbu OS, and seems to have collaboration going on with the wider community. Their community site seems active, and they also have a dedicated X account @spacemit_riscv and Reddit account r/spacemit_riscv posting relevant progress info on Linux kernel upstreaming activities. The X account is also responsive, as evidenced by its replies to my questions. Canonical lists the SpacemiT K3 pico-ITX and K3 CoM260 Kit on its official Ubuntu for RISC-V partner-built hardware page, which strengthens the perception that upstream Linux support is being taken seriously. The SpacemiT folks also gave an interesting talk at the 2026 Ubuntu Summit that includes a peek into their roadmap with future K3, K7 and K9 models. For technical details, see SpacemiT s K3 pico-ITX documentation, the Jetson Orin Nano-compatible K3 CoM260 board documentation and documentation of the K3 processor itself. The SpacemiT K3 pico-ITX board and the K3 CoM260 board side-by-side (not to scale)
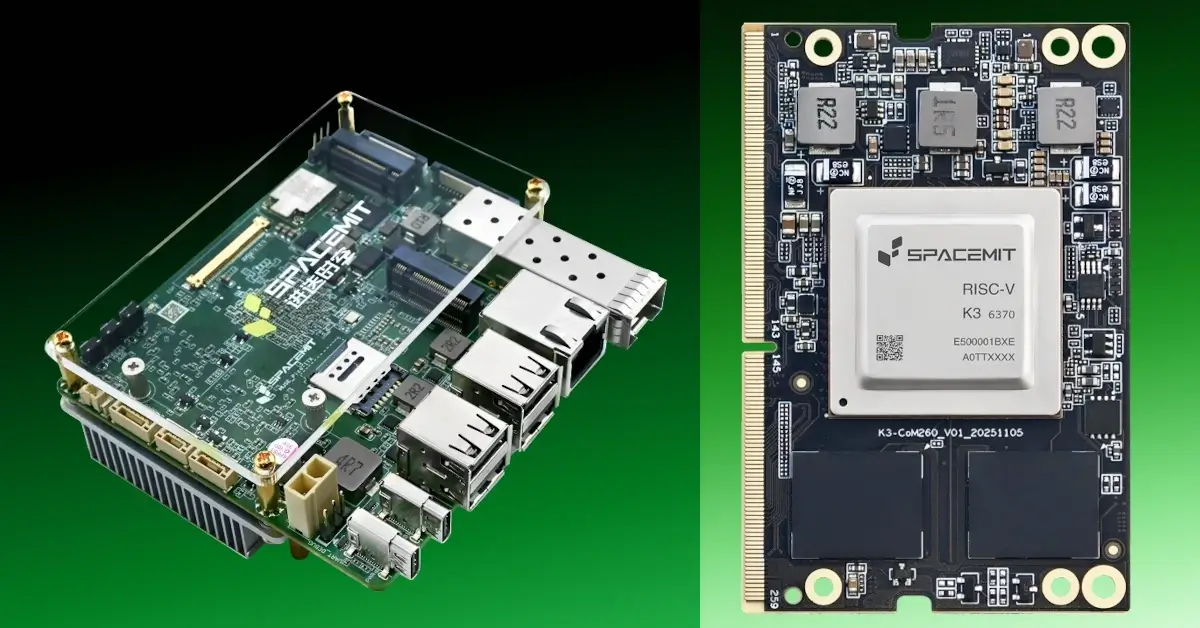
Comparing the resellers SpacemiT does not sell anything directly to consumers. Instead you need to buy a board that includes the K3 chip from an integrator. Currently the main resellers are: All of the above are Chinese companies that ship to customers both inside and outside China. DeepComputing stands out as the only one that actually has done real integration and ships the K3 on a custom board, while the others simply resell the SpacemiT-produced K3 pico-ITX and K3 CoM260 Kit.

Milk-V Milk-V is a RISC-V specialized integrator, as the name already implies. They sell the K3 under the name Jupiter2. Of all the K3 pico-ITX reseller product pages, the Jupiter2 presentation is the nicest and most detailed. Unfortunately their order page at arace.tech only states that it is a pre-order with no information about shipping schedule, taxes, or other details like what SSD is included (if any). Based on the pictures it does ship with a Milk-V branded case. The 32 GB RAM lists at 504 EUR, which is a very reasonable price. The @MilkV_Official account on X recently promoted the K3.

Documentation and support As of this writing, the Milk-V Jupiter2 documentation site is just a stub and has no actual content, and only two links to the SpacemiT K3 documentation site. For support there is a web forum with a dedicated Jupiter2 section. There is also a Matrix space, but unlike their other products, there is no dedicated Jupiter (neither v1 nor v2) channel.

Community size and open source involvement At least one prior Milk-V product was certified by Canonical, which indicates there is some collaboration in progress. Canonical also lists the Milk-V Titan on its official Ubuntu for RISC-V partner-built hardware page.

Sipeed The Sipeed K3 announcement is well written (in English) with all the relevant details and links to additional PDF manuals. However, their main page at sipeed.com says nothing about the K3, so one must know the subpage URL to access it. They offer both the K3 CoM260 kit compatible with Jetson Orin Nano carrier boards, and the stand-alone K3 pico-ITX-sized motherboard. The CoM260 kit is only 10 USD cheaper than the full pico-ITX motherboard, so choosing the latter is a no-brainer if starting from scratch. The pico-ITX model with 32 GB DDR5 RAM sells for 639 USD. The product page does not mention anything about hard disk size, so you don t really know exactly what you will be getting if placing an order. There is no indication about case, Wi-Fi antennas or power supply either, so most likely they are not included. Their store.sipeed.com website does not work at all, and their Taobao and AliExpress stores are not public and only accessible to registered users. The order page also says nothing about shipping time, delivery time, or taxes. The X account @SipeedIO is active and recently posted pictures of shipments in progress.

Documentation and support The main documentation wiki does not yet have any K3 content at the time of writing. There is a Discord channel for general RISC-V discussion, and their MaixHub also has a discussion board, but I didn t find anything K3-specific.

Community size and open source involvement Sipeed has had at least one of their previous devices certified by Canonical, which indicates they are active in the community. Note that the other RISC-V company SiFive that also has had hardware certified and officially supported by Canonical is a different company, despite the very similar name.

Banana Pi Banana Pi announced that they offer both the K3 CoM260 kit and the K3 pico-ITX motherboard version. Their product page for the K3 confusingly shows a MediaTek product in the page banner rather than the SpacemiT K3. Based on the product description and the fact they renamed the product as BPI-SM10, it seems to ship with some carrier board. The product pictures look identical to the SpacemiT documentation and there is no picture of the carrier board, and details are very sparse. The pico-ITX version with 8 GB RAM and 128 GB SSD sells for 293 USD and the CoM260 developer kit with the same specs sells for 287 USD and the 32 GB RAM with 128 GB SSD model sells for 595 USD. The shop page shows only five orders so far and items are currently out of stock. As there was no 32 GB RAM version of the pico-ITX available at all, this isn t an option for me as I want to run 30B parameter models that need the larger memory version. Of all of these resellers, the Banana Pi website seems the most outdated. It does not have a search feature, it is not mobile-friendly, pictures can t be pinched to zoom in and so forth. Product names are also almost all identical, and as the product listings only show the beginning of the product name, figuring out what product is what requires extra effort that just makes the online purchase experience plain bad.

Documentation and support I was only able to find the documentation page for the CoM260 kit, but none for the pico-ITX version. For support there is a forum, but the category list does not show any section for K3, and the forum search prohibits using the search term k3 as too short.

Community size and open source involvement Banana Pi has a long history in the ARM single-board computer market, but their presence in the RISC-V ecosystem is still growing. Their X account @sinovoip has posted only once about the K3 and otherwise promotes their ARM boards. However, their community culture page does express a commitment to open hardware in general, but there is no visible K3-specific community activity.

Firefly Firefly s K3 product page is comprehensive. Based on the details, they do not offer the K3 pico-ITX variant at all, but only the K3 CoM260 board inside the AIBOX-K3 Firefly RISC-V Edge Mini PC product. This is a feature-complete offering with a Jetson Orin Nano carrier board and case. The AIBOX-K3 with 32 GB RAM and 128 GB SSD in a case sells for 689 USD in their own Firefly.store. Unfortunately it only has HDMI and there is no USB-C with DisplayPort support, which is a deal-breaker for me personally. Interestingly, Firefly also offers rack-mounted servers with K3 as the CPU.

Documentation and support The wiki link on the product page is broken. The Firefly wiki does have a section for the AIBOX-K3, but it too has a broken link. It seems that as of the time of writing, there is no wiki section for this product yet. For support there is a web forum, which does have at least one K3 thread covering guides such as Hermes Agent installation, though broader K3-specific sections are still sparse.

Community size and open source involvement Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.

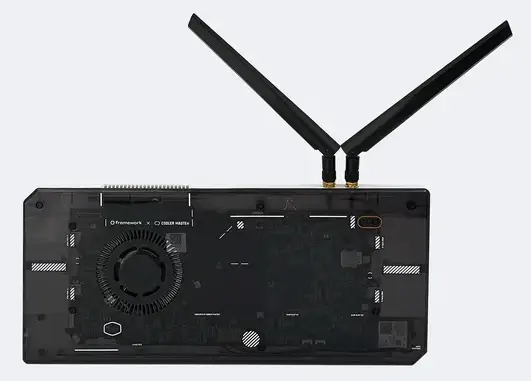
DeepComputing Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it. The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case. After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.

Documentation and support DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.

Community size and open source involvement DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products. DeepComputing K3 board in the Cooler Master case

Conclusion After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence. The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon. What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence. Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details. I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.

7 June 2026

Thorsten Alteholz: My Debian Activities in May 2026

Debian LTS/ELTS This was my hundred-forty-third month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on: This was a rather strange month. The details about the embargoed exim4 issue arrived only after I already went to bed and the embargo lift was 18 hours later. Luckily Stretch was not really affected and the uploads for Bullseye and Buster went out on time. Something similar happened with the embargoed issue of rsync. The info arrived at 8:00 in the morning and the embargo lift was on 2:00 next morning. From an Europeans point of view, the Australians do have strange time zones. But there is more to this than that. Upstream sent more than 50(!) patches for these five CVEs that needed a backport to Bullseye. As things turned out, there is a regression in the upload to Unstable and investigations are ongoing whether this regression is also available in the backported patches for Trixie, Bookworm and Bullseye. So rsync-updates for Buster and Stretch is in the works, but I am afraid they need some more time. All good things come by threes. Two critical CVEs of hplip appeared and a new upstream version was released by HP. HP is no longer interested in working with distributions and over time more than 80 patches have been accumulated that need a rebase for a new upstream version. For that reason I avoid this package as much as I can, but two critical CVEs did apply some kind of pressure on the maintainer. So I finally managed to do this update and the latest version of hplip is now in Debian. Nevertheless, this feels good :-). Anyway, it is not over yet. HP does not have a public repository nor do they publish patches for these CVEs. So I am still searching for the correct fixes to backport them to Bullseye, Buster and Stretch. The other distributions have the same problem and a silver lining appears on the horizon. I also prepared an update of gimp for Buster and Stretch, but due to an accident I only managed to release the corresponing ELA in June. The accident was also the reason for only half a week of FD. Thanks to Daniel who took over. Debian Printing This month I uploaded a new upstream versions: This work is generously funded by Freexian! Debian Lomiri This month I continued to work on unifying packaging on Debian and Ubuntu. This makes it easier to work on those packages independent of the used platform. This work is generously funded by Fre(i)e Software GmbH! Debian Astro This month I uploaded a new upstream version or a bugfix version of: Debian IoT This month I uploaded a new upstream version or a bugfix version of: misc This month I uploaded a new upstream version or a bugfix version of: I also got rid of gypsy, which no longer makes sense to maintain in Debian, as gpsd is way better.

29 May 2026

Russell Coker: Zswap

Zswap vs Zram Last year I blogged about using Zram for VMs [1]. That setup is still working well for VMs and for phones and laptops with no swap device. I have just read Chris Down s insightful blog post about Zswap vs Zram [2] which convinced me to setup Zswap on some systems. I have had some of the problems that were described in his blog post when trying to run Zram on workstation and server systems. One limitation of zswap is that it doesn t allow specifying the compression level. For zram I can put the following in /etc/systemd/zram-generator.conf to set the zstd compression level (this works well on my Thinkpad X1 Carbon Gen6):
[zram0]
compression-algorithm=zstd(level=10)
For the BTRFS filesystem I can put compress=zstd:13 in the mount options to specify the compression level. They really should support different compression levels in zswap. The ideal compression level depends on the speed of the CPU and new CPUs keep getting faster. Setup The documentation says to use something like the following on the kernel command-line to enable zswap:
zswap.enabled=1 zswap.compressor=zstd zswap.max_pool_percent=20 zswap.shrinker_enabled=1
The max_pool_percent=20 setting is the default which means to use up to 20% of system RAM for compressed data. I ve seen documentation sugesting up to 50% which seems a little excessive. Note that a lot of documentation says to use zswap.zpool=z3fold, but z3fold is going to be removed and zsmalloc (the default) is recommended [3]. There is documentation about changing the compression algorithm via command line parameters, on Debian only lzo is linked in to the kernel and zstd (my preferred option) is a module so the kernel command line can t be used to set zstd, but the following command works:
echo zstd > /sys/module/zswap/parameters/compressor
The shrinker_enabled option is to allow the kernel to evict cold pages without waiting for memory pressure. You can enable zswap without rebooting by running commands like the following. You could even put them in /etc/rc.local or something, but I think putting it in the kernel command line is a good idea as it makes it obvious to the next sysadmin what is happening.
echo 1 > /sys/module/zswap/parameters/enabled
echo zstd > /sys/module/zswap/parameters/compressor
echo 1 > /sys/module/zswap/parameters/shrinker_enabled
Monitoring The following command is documented as a way of finding out what zswap is doing:
# grep -r . /sys/kernel/debug/zswap/
/sys/kernel/debug/zswap/stored_pages:262541
/sys/kernel/debug/zswap/pool_total_size:455266304
/sys/kernel/debug/zswap/written_back_pages:384
/sys/kernel/debug/zswap/reject_compress_poor:0
/sys/kernel/debug/zswap/reject_compress_fail:160911
/sys/kernel/debug/zswap/reject_kmemcache_fail:0
/sys/kernel/debug/zswap/reject_alloc_fail:0
/sys/kernel/debug/zswap/reject_reclaim_fail:0
/sys/kernel/debug/zswap/pool_limit_hit:0
The following command gives the zswap compression level which gives a result of 2.36 for this example:
echo "scale=2; " $(</sys/kernel/debug/zswap/stored_pages) " * $(getconf PAGESIZE) /" $(</sys/kernel/debug/zswap/pool_total_size)   bc
This table documents my current understanding of the debug values. The difference between reject_compress_fail and reject_compress_poor isn t clear in a lot of the documentation, even reading the source didn t make it easy to understand.
File Meaning (LC is lifetime count)
pool_limit_hit LC pool limit hit and pages are forced to the swap partition
pool_total_size RAM used for zswap data
reject_alloc_fail LC can t allocate memory because max_pool_percent has been reached
reject_compress_fail LC of pages with a compression algorithm failure so go straight to swap partition
reject_compress_poor LC of pages that can t compress so go straight to swap partition
reject_kmemcache_fail LC kernel malloc failure (serious problem?)
reject_reclaim_fail LC failure to move a page from compressed RAM to disk serious problem!
stored_pages Swapped pages stored by zswap
written_back_pages LC of pages written back to swap partition from zswap
All of this is not nearly as easy to understand as the following command for zram:
# zramctl 
NAME       ALGORITHM DISKSIZE  DATA COMPR TOTAL STREAMS MOUNTPOINT
/dev/zram0 zstd          7.7G  2.1G  375M  386M       4 [SWAP]
Debian Wiki The Debian Wiki page about Zswap is very brief [4] and needs more description about this, I think a lot of Debian users will use zram instead of zswap because setting up zram is just a single apt command. I m not planning to immediately add to that wiki page because I m not an expert on this, I would appreciate comments on this blog post from others who have got zswap working. I will update the wiki if others report matching experiences to mine. Conclusion I m now using zswap on a few systems including my main home workstation which had performed poorly with zram and a swap device in the past. If that goes well I ll put it on other systems. I wrote the following shell script to display zswap stats, consider it GPL if you want to use it:
#!/bin/bash
if [ ! -f /sys/kernel/debug/zswap/stored_pages ]; then
  echo "ZSwap not enabled"
  exit 0
fi
PAGES=$(</sys/kernel/debug/zswap/stored_pages)
PAGESIZE=$(getconf PAGESIZE)
RAM=$(echo "$PAGESIZE * " $(getconf _PHYS_PAGES)   bc)
POOL=$(</sys/kernel/debug/zswap/pool_total_size)
if [ "$POOL" == "0" ]; then
  echo "ZSwap not used yet"
  exit 0
fi
COMP=$(</sys/module/zswap/parameters/compressor)
echo -n "$COMP compression ratio: "
echo "scale=2; $PAGES * $PAGESIZE / $POOL"   bc
echo -n "RAM%: "
echo "100 * $POOL / $RAM"   bc

24 May 2026

Vincent Bernat: Sharding a routing table for lock-free reads in Go

To associate routing information like AS paths or BGP communities to flows, Akvorado can import routes through the BGP Monitoring Protocol (BMP). As the Internet routing table contains more than 1 million routes, Akvorado needs to scale to tens of millions of routes.1 This has been a long-standing challenge,2 but I expect this issue is now fixed by using RIB sharding, a method that splits the routing database into several parts to enable concurrent updates.

Previous implementation Akvorado connects 2 elements to build its RIB:
  1. a prefix tree, and
  2. a list of routes attached to each prefix.
Akvorado BMP RIB implementation before sharding with the memory layout of each structure and a single lock.
Akvorado BMP RIB implementation without sharding. One single read/write lock.
In the diagram above, the RIB stores five IPv4 prefixes and two IPv6 prefixes. One of them, 2001:db8:1::/48, contains three routes:
  • from peer 3, next hop 2001:db8::3:1, AS 65402, AS path 65402, community 65402:31,
  • from peer 4, next hop 2001:db8::4:1, same ASN, AS path, and community,
  • from peer 5, next hop 2001:db8::5:1, AS 65402, AS path 65401 65402, community 65402:31.
The rib structure is defined in Go as follows:
type rib struct  
    tree          *bart.Table[prefixIndex]
    routes        map[routeKey]route
    nlris         *intern.Pool[nlri]
    nextHops      *intern.Pool[nextHop]
    rtas          *intern.Pool[routeAttributes]
    nextPrefixID  prefixIndex
    freePrefixIDs []prefixIndex
 
The prefix tree uses the bart package, an adaptation of Donald Knuth s ART algorithm. The benchmarks demonstrate it outperforms other packages for lookups, insertions, and memory usage.3 Plus, the author is quite helpful.

Storing routes in a map The list of routes for each prefix is not stored directly in the prefix tree: it would put too much pressure on the garbage collector by allocating per-prefix arrays. Instead, the RIB assigns a unique 32-bit prefix identifier for each prefix, either by picking the last available prefix identifier from the freePrefixIDs array if any, or using the nextPrefixID value before incrementing it. Then, the routes are stored in the routes map, leveraging the optimized Swiss table in Go. To retrieve routes attached to a prefix, we look them up one by one in the routes map with a 64-bit key combining the 32-bit prefix index with a 32-bit route index matching the position of the route in the list. Akvorado scans routes from the first to the last to find the best one.4 It knows there is no more route if the route key returns no result.
type prefixIndex uint32
type routeIndex uint32
type routeKey uint64

Interning routes A route contains a BGP peer identifier, a partial NLRI5, the next hop, and the attributes.
type route struct  
    peer       uint32
    nlri       intern.Reference[nlri]
    nextHop    intern.Reference[nextHop]
    attributes intern.Reference[routeAttributes]
    prefixLen  uint8
 
type nlri struct  
    family bgp.Family
    path   uint32
    rd     RD
 
type nextHop netip.Addr
type routeAttributes struct  
    asn              uint32
    asPath           []uint32
    communities      []uint32
    largeCommunities []bgp.LargeCommunity
 
To save memory and allocations, NLRI, next hops, and route attributes are interned : a 32-bit integer replaces the real value. The mechanism predates the unique package introduced in Go 1.23. We keep it because it has different trade-offs:
  • It uses explicit reference counting instead of relying on weak pointers.
  • It works with non-comparable values implementing Hash() and Equal() methods.6
  • It uses explicit pool instances. This will be useful for sharding.
  • It has better performance. See for example this benchmark.
  • It consumes half the memory thanks to unsigned 32-bit references instead of pointers.
  • But it is not safe for concurrent use.

Why does it not scale?

Note At AS 12322, we don t use BMP yet.7 But Gerhard Bogner had the patience, availability, and technical skills to help me debug this issue.

The global read/write lock is a bottleneck in this implementation. But how? There are several users of the RIB, each with its own set of constraints:
  • The Kafka workers look up the RIB to enrich flows with routing information. They are bound by the number of Kafka partitions.8 Akvorado also adjusts their number to ensure efficient batching to ClickHouse. On our setup, the number of workers oscillates between 8 and 16. As we want to observe the latest data, we cannot afford for the Kafka workers to lag too much.
  • The monitored routers send route updates through the BMP protocol. When connecting, they can send millions of routes.9 After the initial synchronization, updates are sent continuously and may spike from time to time. The router detects a stuck BMP station when its TCP window is full and resets the session in this case. While Akvorado implements a large incoming buffer, it still needs to update the received routes with the write lock held fast enough to avoid being detected as stuck.
  • When a remote BGP peer goes down, Akvorado flushes the associated routes by walking the RIB with the write lock held. When a monitored router goes down, Akvorado waits a bit but eventually flushes all the associated routes.
In short: on a busy setup, lock contention is high for both readers and writers, and neither can lag too much behind.

RIB sharding

First step: basic sharding To remove the global lock, the RIB is split into several shards, each one handling a subset of the prefixes:
Akvorado BMP RIB implementation after sharding with the memory layout of each structure and one lock per shard.
Akvorado BMP RIB implementation with sharding.
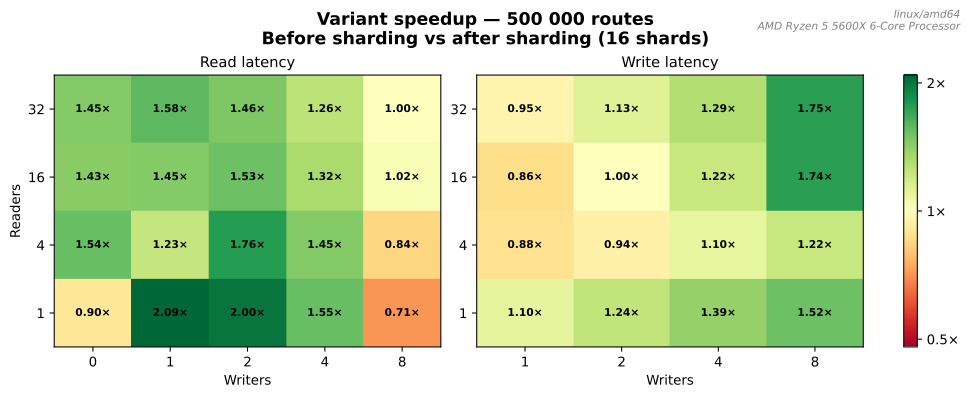
The prefix tree stays global and is protected by a single lock. Each shard gets its read/write lock, its route map, and its intern pools to store NLRIs, next hops, and route attributes, which would not have been possible with Go s unique package. The prefix indexes are also sharded: the 8 most significant bits are the shard index and the 24 remaining bits are the local prefix index. Gerhard confirmed that after this blind change, the BMP receiver chugged steadily. Later, I wrote a concurrent benchmark over half a million synthetic but plausible routes10 partitioned over 0 to 8 writers, churning routes as fast as possible, while 1 to 16 readers continuously look up a set of 10,000 routes. I don t know if this benchmark is realistic, but it confirms the improvements for both read and write latencies:
Two heatmaps. One for read latency ratio, the other for write latency ratio. Both of them comparing the speedup with colored tiles between the code before sharding and after sharding. Most tiles are green.
Read and write latency performance improvement after sharding.
It also shows that a high number of writers degrades read latency.

Second step: lock-free reads The single read/write lock protecting the prefix tree is the next target. The bart package provides alternative mutation methods returning an updated tree using copy-on-write. Readers don t need the global lock any more, leaving it only to synchronize writers. The prefix tree is boxed in an atomic pointer.
Akvorado BMP RIB implementation for sharding with lock-free reads. It shows the memory layout of each structure.
Akvorado BMP RIB implementation with sharding and lock-free reads.
Without a lock, readers can now fetch a stale prefix index when walking their copy of the tree if a concurrent writer removes the last route attached to this prefix index and recycles it for another prefix. To avoid this issue, we combine the prefix index with a generation number and store them in the tree:
type generation uint32
type prefixRef struct  
    idx prefixIndex
    gen generation
 
type rib struct  
    mu     sync.Mutex
    tree   atomic.Pointer[bart.Table[prefixRef]]
    shards []*ribShard
 
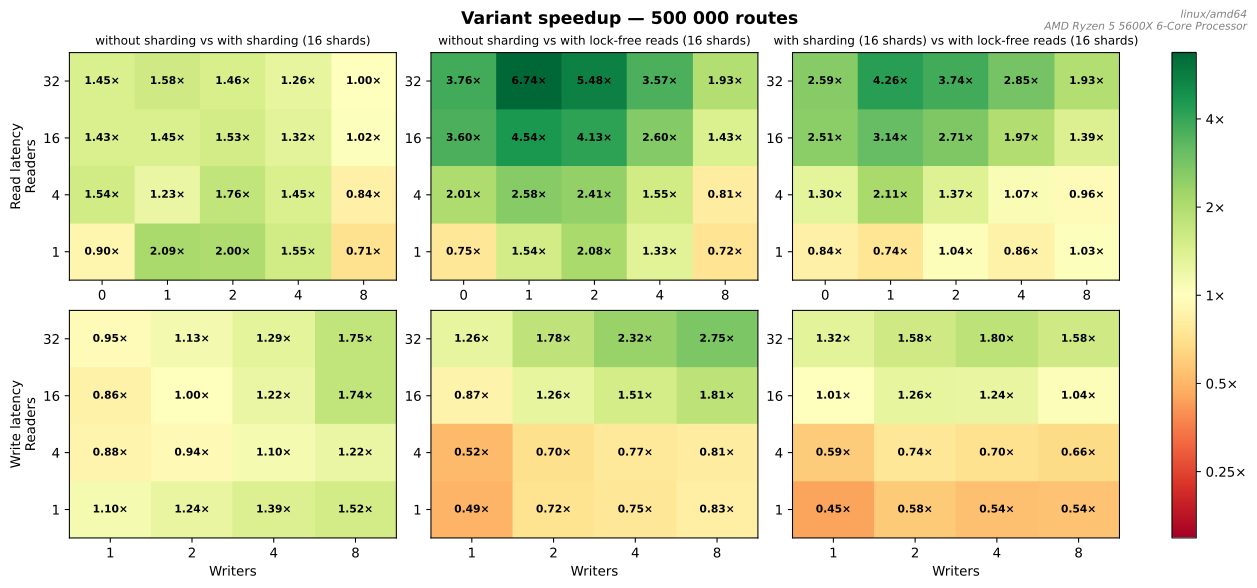
Each shard stores the generation number for each local prefix index. The generation number increases by one if the associated prefix index is freed. When looking up the routes attached to a prefix index, the reader checks if the generation number matches. Otherwise, it assumes the index was recycled and the list of routes is empty.11 You can see this case in the diagram above for prefix index 5, stored with a generation index of 3, while the current value in the []generations array is 4. The generation number could overflow, but it is not a problem as lookups are quick. Running the concurrent benchmark against this new implementation shows the improvements for the read latency as soon as the cost of the copy-on-write prefix tree is amortized.
Six heatmaps. Three for read latency ratio, three others for write latency ratio. They compare the numbers without sharding, with sharding, and with lock-free reads, pair by pair. For read latency, most tiles are green, showing an improvement of the second step. For write latency, the speedup is negative for a low number of readers.
Read and write latency performance improvement after lock-free reads. The middle column shows the cumulative improvements of both steps.

Among the multiple attempts to optimize the BMP component, RIB sharding is one of the more satisfying. Akvorado 2.2 implements the first step. PR #2433, drafted while writing this blog post, implements the second step and was released with Akvorado 2.4.

  1. Each router exporting flows doesn t need to send its routes. When Akvorado does not find a route from a specific device, it falls back to a route sent by another device. It is up to the operator to decide if this is a good enough approximation.
  2. I made many attempts to scale the BMP component. See for example PR #254, PR #255, PR #278, PR #2244, and PR #2245. Despite these efforts, this component remained problematic for some users. See discussion #2287 as the latest example.
  3. It keeps improving: bart 0.28.0 features a new implementation that trades a bit of memory for greater lookup performance. I did not test it yet, as I have been preparing this blog post for a couple of months already.
  4. Akvorado prefers the route matching the exact next hop. Otherwise, it falls back to any other route. This is an approximation. An alternative would be to have one prefix tree for each BGP peer but it would require configuring all routers to export their routes. pmacct s BMP daemon implements this approach.
  5. If we consider the BGP RIB as a database, the Network Layer Reachability Information (NLRI) is the primary key. Its content depends on the BGP family. With IPv4 or IPv6 unicast, this is the prefix. For VPNv4 and VPNv6 families, it includes the route distinguisher. If you enable the ADD-PATH extension, the NLRI also contains a path identifier. In our implementation, we don t store the prefix as we get it from the looked-up IP address using the prefix length stored separately.
  6. The Hash() methods rely on the hash/maphash package and on the unsafe package to avoid memory copies. See for example the Hash() function for the nlri structure.
  7. Despite being an author or co-author of the first BMP-related RFCs since 2016 (RFC 7854, RFC 8671, RFC 9069), Cisco did not implement it in a usable way in IOS XR until version 24.2.1. We still need to upgrade a few routers to enable this feature.
  8. KIP-932 introduces, in Kafka 4.2, the concept of share groups to enable cooperative consumption on the same partition. This is not supported in Akvorado yet.
  9. You can configure BMP to send routes for each BGP peer before or after applying the incoming policies. In this case, you can get more than one million routes for each transit peer. You can also tell BMP to send the local RIB, which only contains the best path for each prefix.
  10. The prefixes are random, but the prefix size distribution and the AS path length distribution follow the data provided by Geoff Huston.
  11. Alternatively, we could retry the lookup, but it would be pointless: the RIB is an eventually consistent database, and an empty list was a correct answer at some point in the recent past.

17 May 2026

Otto Kek l inen: Balancing persistence vs pivoting is grit a virtue or wasteful?

Featured image of post Balancing persistence vs pivoting   is grit a virtue or wasteful?Being persistent, sticking to a plan and showing up to work every day is generally valued highly across all cultures as virtuous behavior. It is obvious that anything of value and worth achieving is also not easy, but requires significant and recurring effort. Learning a new language, winning a sports competition or building a successful business are all typical scenarios where grit plays a central role above everything else. However, sometimes the virtue of tenacity can result in just a waste of energy. The question is then: how does one recognize that true progress is being blocked by stubbornness and a pivot would be the correct decision, as opposed to being close to breakthrough where doing more of the same would actually be the right choice?

What is persistence actually? To think clearly about this topic, one must first grasp the concept of grit and what it looks like in practice. Research by psychologist Angela Duckworth on grit shows that sustained effort in the face of setbacks separates high achievers from those who quit too soon. Entrepreneurs who iterated through dozens of failed prototypes or writers who revised manuscripts for years understand this truth. Persistence builds resilience, deep expertise, and the kind of compounding results that shortcuts cannot deliver. It also protects against the distraction of shiny new ideas that pull focus from what actually works. Persistence is about:
  1. Believing in an outcome and working towards it despite people around you not sharing the belief, and despite your own work and experiments not being successful.
  2. Continuing to hold the belief and sticking to the decision despite other ideas, solutions and competing alternatives surfacing.
  3. The more time passes, the firmer the conviction becomes. Time, money, and emotional energy invested in a failing direction create psychological pressure to continue (sunk-cost fallacy).
Simply following through on a plan or upholding a contract is not true persistence. Grit is a personal trait one can cultivate to actually become more energized to do something precisely because it turns out to be harder than expected.

Pivoting: a calculated choice The opposite of being persistent is giving up. Pivoting is not about giving up, but about redirecting the energy and momentum towards a new goal. Pivoting requires coming to the realization that you were wrong, and going through the painful process of discovering a new truth. Ideas tend to be abundant, and doing something new isn t hard as such. The hard part is to abandon a previously held belief and adopt a new one with equal conviction. To have that conviction you need to have data and metrics. This is also the key to how to decide between persisting vs pivoting at any moment in time.

Key metrics of success Any decision is only as good as the information available at the time it was made. To be set up for success one needs to start by deciding on what the actual goal is, what one values and how progress is measured. Key metrics are usually easiest to discover by working backwards from the goal. If you want to build an electric car, you might decide that the goal is to have a car that costs 30,000 euros and can drive 300 km on one charge. From that goal you can break down what the cost structure should be, what volume of production is needed to break even, what raw materials are needed and what the battery chemistry needs to achieve to meet the goal. That can further be broken down into a rate of progress. Suppose the plan requires battery energy density to reach 150 Wh/kg to be viable. If the state of the art starts at 100 Wh/kg and funding lasts a maximum of five years, the team needs at least an 8% improvement every year (1.08^5 100 Wh/kg 150 Wh/kg). This can then be used as a guideline. Sometimes progress is not steady, but happens in jumps. Even in those cases there should be a trajectory to benchmark the jumps against. In an online business, the key metric could, for example, be one of these:
  • 7- or 30-day retention rate: Do new users who try the service actually like it?
  • Weekly or monthly active users: Is usage trending up?
  • Feature adoption rate: In an existing service, how many users are using the new feature?
  • Product-Market Fit Score (from Sean Ellis test): Percentage of users who say they would be very disappointed if the product disappeared. Above 40% is a strong early indicator. A number below that (after multiple iterations) is a good data point to pivot.
  • Revenue run rate or burn rate: The most generic metric everything eventually boils down to. Healthy markets reward good products.
Weekly metrics are better than monthly, as they make the feedback loop faster and allow you to get validation quickly and do minor course corrections along the way. A complete pivot should, however, be based on long-term data, driven by the key metric and supported by additional data points. Metrics are also needed because they can t be bribed or convinced to be anything other than what they are. Listening to other people is good, but just relying on the opinion of others is extremely dangerous because people are biased either for you or against you depending on whether they see you as a trusted leader or an outcast. Key metrics are of course domain-specific and everyone needs to come up with their own. However, you must have some key metric. You can t have the excuse that what you are doing can t be measured. If you are part of a larger organization and you need to advocate for a difficult decision for example, to kill your darlings when facing a pivot you need to have the metrics to back up your views, and those metrics need to have been established way before as something the organization values, and not cherry-picked just for this one decision. It does not matter if you are on a personal improvement journey, running a political campaign, inventing a new product, or growing a business you need to have some metric you can check at any given time to see if things are improving fast enough to predict success. Metrics can and should also be used in daily work to validate that you are on the correct path, and to optimize execution.

Famous examples of persistence and pivoting that led to breakthroughs In all of the cases below it is of course in hindsight easy to say they made the right decision. However, take a minute to try to imagine yourself in their shoes at the time of the decision. What metrics might they have had available to support their decision? What would you have wanted to measure or find out if you were in the same situation?
  • Frustrated that his vacuum lost suction, James Dyson spent five years and built thousands of failed prototypes in a backyard shed. He remortgaged his home, lived on savings, and faced rejection from every major manufacturer who wanted to protect their bag-replacement business. The 5,127th prototype based on an idea from a sawmill with a cyclone finally worked. Launched in 1993, the Dyson DC01 became Britain s best-selling vacuum within two years.
  • As a single mother on welfare in the mid-1990s, J.K. Rowling finished her manuscript for Harry Potter and the Philosopher s Stone while battling depression and poverty. She hand-typed copies and mailed them to publishers. Twelve rejected it outright, with comments like children s books about magic don t sell. She nearly quit multiple times but kept revising and submitting. Bloomsbury finally accepted it after the CEO s eight-year-old daughter read the first chapter and demanded the rest. The series has since sold hundreds of millions of copies worldwide.
  • Founded in 1997 as a mail-order DVD rental service, Netflix added unlimited subscriptions in 1999 to compete with Blockbuster. By 2007, broadband growth and declining DVD sales signaled a shift. CEO Reed Hastings pivoted aggressively toward streaming, investing in bandwidth deals and original content while de-emphasizing physical media. The move faced skepticism, but eventually changed the whole culture of how entertainment is consumed.
  • YouTube launched in 2005 as a video-dating site. Founders offered money to women who uploaded dating videos, but almost no one did. Meanwhile, users uploaded random clips. The team recognized the mismatch and pivoted within months to a general-purpose video-sharing platform with easy uploading. Google bought it just 18 months later.
  • Instagram began in 2010 as Burbn, a location-based check-in app that let users post plans, earn points, and share photos. Co-founders Kevin Systrom and Mike Krieger quickly noticed users ignored most features and mainly used it for photo-sharing. They made the tough call: scrap everything else. Within weeks, they rebuilt the app around clean, simple photography with filters. The pivot launched as Instagram in October 2010. It gained 1 million users in two months and was acquired by Facebook just 18 months later.

Insanity or conviction? English has several proverbs that warn against excessive persistence, such as banging your head against the wall . Insanity is commonly defined as Doing the same thing over and over again and expecting different results. In Finland, the national identity is practically built on the concept of sisu . It means much more than just grit . The word is derived from the word for inside or guts and represents an unexplained, almost superhuman force that makes one stoically take action despite seemingly impossible odds and somehow succeed anyway. It became a defining national mythos during the Winter War (1939 1940), where a force 10 times larger than the Finnish army tried to invade the country but was stopped and Finland just barely managed to keep its independence. The word sisu transitioned from a character trait to a pillar of national survival. I think Finns survived because the more you believe in persistence, the more likely you are to persist. I view persistence as a religion that requires faith, while pivoting is a science where you derive the truth from the numbers. When in doubt, I would always choose persistence over pivoting. Perhaps it is because of my genetic tendency towards having sisu , but I would also rather keep on going a bit more and try one more time before giving up and pivoting in order to get more data, so that when I pivot, I know it is absolutely the right thing to do at that point. Depending on the situation, the costs of postponing the pivot vary. Of course, if the main metric is the burn rate and a company is running out of money, a pivot must be done early enough that the remaining runway is enough to execute the pivot, and then some more. In some situations a business idea might simply be ahead of its time. If that is the conviction and the key metrics support it, the best way to navigate the situation is to cut down on costs and wait for competitors to appear, help build general awareness, and then ramp up again to ride the wave. Remember that success does not come from grit alone there is always an element of timing and luck as well. But if you are not persistent and stop showing up every day, you won t be able to seize the opportunities if and when they arise.

Failure is the likely outcome you have to avoid it at any cost One must also realize that most attempts end in failure. Failure is the baseline, and success is the exception. To reach a breakthrough, one must be stubbornly persistent. In particular, if you are a leader, you need to be so high in conviction that it almost becomes an aura that radiates to those around you. Postponing the decision to pivot allows you to get a bit more data for the decision, so that once you pivot, you have full belief in the new direction. Once you pivot, there is no looking back, otherwise you will undermine morale and most certainly fail with the new thing as people will execute it with hesitation. Failure is statistically always the more likely outcome. Most things end in failure and we never hear about them. If someone on your team does not believe in what you are doing, it is very easy for them to prove that something is a failure by spreading negativity, putting in less effort (perhaps unconsciously due to lack of conviction) and thus actually contributing to a self-fulfilling failure. In most areas of life, ideas are cheap and the only thing that matters is execution. To be good at executing, you need to be good at making decisions. When drafting plans it is good to have alternatives and a lot of consideration. However, when execution starts, there is no room for doubt, otherwise the chances of success decrease. Therefore, the best way of balancing persistence vs pivoting is to
  1. plan well ahead,
  2. establish the key metrics,
  3. have thresholds established for what would trigger a pivot, and
  4. do everything you can to move the metrics in the direction you want them to go.
Finally, if you decide to pivot, you must do so only with very high conviction, as you can t undo a pivot, and you should not be doing multiple pivots in a row either. If you are fully convinced yourself about the pivot, you will also be able to convince others about it, and carry the momentum.

18 March 2026

Taavi V n nen: Wikimedia Hackathon Northwestern Europe 2026

Wikimedia Nederland organised a new type of event this year, the Wikimedia Hackathon Northwestern Europe 2026, which was held last weekend in Arnhem, the Netherlands. And I'm very happy they did, since unlike last years, I will unfortunately be missing from the "main" Wikimedia Hackathon (which is happening in Milan at the start of May). I continue to believe the primary reason for these events existing is the ability to connect with old and new friends in person. That being said, I did get a bit of technical tinkering done during the weekend as well. These include a dark mode fix to MediaWiki's notification interface, fixes to some visual bugs in MediaWiki's two-factor authentication and OAuth functionality. I did also get an older patch of mine about disabling Composer's new auditing functionality merged. And, as usual, I spent a bunch of time helping various people use with the various infrastructure pieces I'm familiar with (or at least had to suddenly get familiar with) and approved a bunch of OAuth consumers and other requests. We also managed to continue the tradition from the past two Wikimedia Hackathons of nominating more people to receive +2 access to mediawiki/*. That request is still open as of writing, as those have to run for at least a week, but looks very likely to pass at this point. Overall, the event was very well-organized: the venue was great, except that the number of stairs was described in a rather misleading way, food was great, and the atmosphere was amazing. The pressure that you must Just Get Things Done to justify your attendance that the main hackathon seems to have recently gained was clearly missing here which was great. Also, I will clearly need to bring more Finnish chocolate next time. The timing of Friday and Saturday works great for us with other things (like university for me) during the week, as it takes full advantage of the weekend but still only eats workdays from a single calendar week. My main gripe with the logistics was the focus on a single sketchy non-free messaging platform for all event-related communications with the IRC bridge used on the main hackathon channel notably missing.
ps. Like Lucas, I do have Opinions about so many proudly mentioning they've used "vibe coding" tools during the introduction and showcase. Those opinions are best left for an another time, but I do want to note that all of my work and mistakes have still been lovingly handcrafted.

27 January 2026

Elana Hashman: A beginner's guide to improving your digital security

In 2017, I led a series of workshops aimed at teaching beginners a better understanding of encryption, how the internet works, and their digital security. Nearly a decade later, there is still a great need to share reliable resources and guides on improving these skills. I have worked professionally in computer security one way or another for well over a decade, at many major technology companies and in many open source software projects. There are many inaccurate and unreliable resources out there on this subject, put together by well-meaning people without a background in security, which can lead to sharing misinformation, exaggeration and fearmongering. I hope that I can offer you a trusted, curated list of high impact things that you can do right now, using whichever vetted guide you prefer. In addition, I also include how long it should take, why you should do each task, and any limitations. This guide is aimed at improving your personal security, and does not apply to your work-owned devices. Always assume your company can monitor all of your messages and activities on work devices. What can I do to improve my security right away? I put together this list in order of effort, easiest tasks first. You should be able to complete many of the low effort tasks in a single hour. The medium to high effort tasks are very much worth doing, but may take you a few days or even weeks to complete them. Low effort (<15 minutes) Upgrade your software to the latest versions Why? I don't know anyone who hasn't complained about software updates breaking features, introducing bugs, and causing headaches. If it ain't broke, why upgrade, right? Well, alongside all of those annoying bugs and breaking changes, software updates also include security fixes, which will protect your device from being exploited by bad actors. Security issues can be found in software at any time, even software that's been available for many years and thought to be secure. You want to install these as soon as they are available. Recommendation: Turn on automatic upgrades and always keep your devices as up-to-date as possible. If you have some software you know will not work if you upgrade it, at least be sure to upgrade your laptop and phone operating system (iOS, Android, Windows, etc.) and web browser (Chrome, Safari, Firefox, etc.). Do not use devices that do not receive security support (e.g. old Android or iPhones). Guides: Limitations: This will prevent someone from exploiting known security issues on your devices, but it won't help if your device was already compromised. If this is a concern, doing a factory reset, upgrade, and turning on automatic upgrades may help. This also won't protect against all types of attacks, but it is a necessary foundation. Use Signal Why? Signal is a trusted, vetted, secure messaging application that allows you to send end-to-end encrypted messages and make video/phone calls. This means that only you and your intended recipient can decrypt the messages and someone cannot intercept and read your messages, in contrast to texting (SMS) and other insecure forms of messaging. Other applications advertise themselves as end-to-end encrypted, but Signal provides the strongest protections. Recommendation: I recommend installing the Signal app and using it! My mom loves that she can video call me on Wi-Fi on my Android phone. It also supports group chats. I use it as a secure alternative to texting (SMS) and other chat platforms. I also like Signal's "disappearing messages" feature which I enable by default because it automatically deletes messages after a certain period of time. This avoids your messages taking up too much storage. Guides: Limitations: Signal is only able to protect your messages in transit. If someone has access to your phone or the phone of the person you sent messages to, they will still be able to read them. As a rule of thumb, if you don't want someone to read something, don't write it down! Meet in person or make an encrypted phone call where you will not be overheard. If you are talking to someone you don't know, assume your messages are as public as posting on social media. Set passwords and turn on device encryption Why? Passwords ensure that someone else can't unlock your device without your consent or knowledge. They also are required to turn on device encryption, which protects your information on your device from being accessed when it is locked. Biometric (fingerprint or face ID) locking provides some privacy, but your fingerprint or face ID can be used against your wishes, whereas if you are the only person who knows your password, only you can use it. Recommendation: Always set passwords and have device encryption enabled in order to protect your personal privacy. It may be convenient to allow kids or family members access to an unlocked device, but anyone else can access it, too! Use strong passwords that cannot be guessed avoid using names, birthdays, phone numbers, addresses, or other public information. Using a password manager will make creating and managing passwords even easier. Disable biometric unlock, or at least know how to disable it. Most devices will enable disk encryption by default, but you should double-check. Guides: Limitations: If your device is unlocked, the password and encryption will provide no protections; the device must be locked for this to protect your privacy. It is possible, though unlikely, for someone to gain remote access to your device (for example through malware or stalkerware), which would bypass these protections. Some forensic tools are also sophisticated enough to work with physical access to a device that is turned on and locked, but not a device that is turned off/freshly powered on and encrypted. If you lose your password or disk encryption key, you may lose access to your device. For this reason, Windows and Apple laptops can make a cloud backup of your disk encryption key. However, a cloud backup can potentially be disclosed to law enforcement. Install an ad blocker Why? Online ad networks are often exploited to spread malware to unsuspecting visitors. If you've ever visited a regular website and suddenly seen an urgent, flashing pop-up claiming your device was hacked, it is often due to a bad ad. Blocking ads provides an additional layer of protection against these kinds of attacks. Recommendation: I recommend everyone uses an ad blocker at all times. Not only are ads annoying and disruptive, but they can even result in your devices being compromised! Guides: Limitations: Sometimes the use of ad blockers can break functionality on websites, which can be annoying, but you can temporarily disable them to fix the problem. These may not be able to block all ads or all tracking, but they make browsing the web much more pleasant and lower risk! Some people might also be concerned that blocking ads might impact the revenue of their favourite websites or creators. In this case, I recommend either donating directly or sharing the site with a wider audience, but keep using the ad blocker for your safety. Enable HTTPS-Only Mode Why? The "S" in "HTTPS" stands for "secure". This feature, which can be enabled on your web browser, ensures that every time you visit a website, your connection is always end-to-end encrypted (just like when you use Signal!) This ensures that someone can't intercept what you search for, what pages on websites you visit, and any information you or the website share such as your banking details. Recommendation: I recommend enabling this for everyone, though with improvements in web browser security and adoption of HTTPS over the years, your devices will often do this by default! There is a small risk you will encounter some websites that do not support HTTPS, usually older sites. Guides: Limitations: HTTPS protects the information on your connection to a website. It does not hide or protect the fact that you visited that website, only the information you accessed. If the website is malicious, HTTPS does not provide any protection. In certain settings, like when you use a work-managed computer that was set up for you, it can still be possible for your IT Department to see what you are browsing, even over an HTTPS connection, because they have administrator access to your computer and the network. Medium to high effort (1+ hours) These tasks require more effort but are worth the investment. Set up a password manager Why? It is not possible for a person to remember a unique password for every single website and app that they use. I have, as of writing, 556 passwords stored in my password manager. Password managers do three important things very well:
  1. They generate secure passwords with ease. You don't need to worry about getting your digits and special characters just right; the app will do it for you, and generate long, secure passwords.
  2. They remember all your passwords for you, and you just need to remember one password to access all of them. The most common reason people's accounts get hacked online is because they used the same password across multiple websites, and one of the websites had all their passwords leaked. When you use a unique password on every website, it doesn't matter if your password gets leaked!
  3. They autofill passwords based on the website you're visiting. This is important because it helps prevent you from getting phished. If you're tricked into visiting an evil lookalike site, your password manager will refuse to fill the password.
Recommendation: These benefits are extremely important, and setting up a password manager is often one of the most impactful things you can do for your digital security. However, they take time to get used to, and migrating all of your passwords into the app (and immediately changing them!) can take a few minutes at a time... over weeks. I recommend you prioritize the most important sites, such as your email accounts, banking/financial sites, and cellphone provider. This process will feel like a lot of work, but you will get to enjoy the benefits of never having to remember new passwords and the autofill functionality for websites. My recommended password manager is 1Password, but it stores passwords in the cloud and costs money. There are some good free options as well if cost is a concern. You can also use web browser- or OS-based password managers, but I do not prefer these. Guides: Limitations: Many people are concerned about the risk of using a password manager causing all of their passwords to be compromised. For this reason, it's very important to use a vetted, reputable password manager that has passed audits, such as 1Password or Bitwarden. It is also extremely important to choose a strong password to unlock your password manager. 1Password makes this easier by generating a secret to strengthen your unlock password, but I recommend using a long, memorable password in any case. Another risk is that if you forget your password manager's password, you will lose access to all your passwords. This is why I recommend 1Password, which has you set up an Emergency Kit to recover access to your account. Set up two-factor authentication (2FA) for your accounts Why? If your password is compromised in a website leak or due to a phishing attack, two-factor authentication will require a second piece of information to log in and potentially thwart the intruder. This provides you with an extra layer of security on your accounts. Recommendation: You don't necessarily need to enable 2FA on every account, but prioritize enabling it on your most important accounts (email, banking, cellphone, etc.) There are typically a few different kinds: email-based (which is why your email account's security is so important), text message or SMS-based (which is why your cell phone account's security is so important), app-based, and hardware token-based. Email and text message 2FA are fine for most accounts. You may want to enable app- or hardware token-based 2FA for your most sensitive accounts. Guides: Limitations: The major limitation is that if you lose access to 2FA, you can be locked out of an account. This can happen if you're travelling abroad and can't access your usual cellphone number, if you break your phone and you don't have a backup of your authenticator app, or if you lose your hardware-based token. For this reason, many websites will provide you with "backup tokens" you can print them out and store them in a secure location or use your password manager. I also recommend if you use an app, you choose one that will allow you to make secure backups, such as Ente. You are also limited by the types of 2FA a website supports; many don't support app- or hardware token-based 2FA. Remove your information from data brokers Why? This is a problem that mostly affects people in the US. It surprises many people that information from their credit reports and other public records is scraped and available (for free or at a low cost) online through "data broker" websites. I have shocked friends who didn't believe this was an issue by searching for their full names and within 5 minutes being able to show them their birthday, home address, and phone number. This is a serious privacy problem! Recommendation: Opt out of any and all data broker websites to remove this information from the internet. This is especially important if you are at risk of being stalked or harassed. Guides: Limitations: It can take time for your information to be removed once you opt out, and unfortunately search engines may have cached your information for a while longer. This is also not a one-and-done process. New data brokers are constantly popping up and some may not properly honour your opt out, so you will need to check on a regular basis (perhaps once or twice a year) to make sure your data has been properly scrubbed. This also cannot prevent someone from directly searching public records to find your information, but that requires much more effort. "Recommended security measures" I think beginners should avoid We've covered a lot of tasks you should do, but I also think it's important to cover what not to do. I see many of these tools recommended to security beginners, and I think that's a mistake. For each tool, I will explain my reasoning around why I don't think you should use it, and the scenarios in which it might make sense to use. "Secure email" What is it? Many email providers, such as Proton Mail, advertise themselves as providing secure email. They are often recommended as a "more secure" alternative to typical email providers such as GMail. What's the problem? Email is fundamentally insecure by design. The email specification (RFC-3207) states that any publicly available email server MUST NOT require the use of end-to-end encryption in transit. Email providers can of course provide additional security by encrypting their copies of your email, and providing you access to your email by HTTPS, but the messages themselves can always be sent without encryption. Some platforms such as Proton Mail advertise end-to-end encrypted emails so long as you email another Proton user. This is not truly email, but their own internal encrypted messaging platform that follows the email format. What should I do instead? Use Signal to send encrypted messages. NEVER assume the contents of an email are secure. Who should use it? I don't believe there are any major advantages to using a service such as this one. Even if you pay for a more "secure" email provider, the majority of your emails will still be delivered to people who don't. Additionally, while I don't use or necessarily recommend their service, Google offers an Advanced Protection Program for people who may be targeted by state-level actors. PGP/GPG Encryption What is it? PGP ("Pretty Good Privacy") and GPG ("GNU Privacy Guard") are encryption and cryptographic signing software. They are often recommended to encrypt messages or email. What's the problem? GPG is decades old and its usability has always been terrible. It is extremely easy to accidentally send a message that you thought was encrypted without encryption! The problems with PGP/GPG have been extensively documented. What should I do instead? Use Signal to send encrypted messages. Again, NEVER use email for sensitive information. Who should use it? Software developers who contribute to projects where there is a requirement to use GPG should continue to use it until an adequate alternative is available. Everyone else should live their lives in PGP-free bliss. Installing a "secure" operating system (OS) on your phone What is it? There are a number of self-installed operating systems for Android phones, such as GrapheneOS, that advertise as being "more secure" than using the version of the Android operating system provided by your phone manufacturer. They often remove core Google APIs and services to allow you to "de-Google" your phone. What's the problem? These projects are relatively niche, and don't have nearly enough resourcing to be able to respond to the high levels of security pressure Android experiences (such as against the forensic tools I mentioned earlier). You may suddenly lose security support with no notice, as with CalyxOS. You need a high level of technical know-how and a lot of spare time to maintain your device with a custom operating system, which is not a reasonable expectation for the average person. By stripping all Google APIs such as Google Play Services, some useful apps can no longer function. And some law enforcement organizations have gone as far as accusing people who install GrapheneOS on Pixel phones to be engaging in criminal activity. What should I do instead? For the best security on an Android device, use a phone manufactured by Google or Samsung (smaller manufacturers are more unreliable), or consider buying an iPhone. Make sure your device is receiving security updates and up-to-date. Who should use it? These projects are great for tech enthusiasts who are interested in contributing to and developing them further. They can be used to give new life to old phones that are not receiving security or software updates. They are also great for people with an interest in free and open source software and digital autonomy. But these tools are not a good choice for a general audience, nor do they provide more practical security than using an up-to-date Google or Samsung Android phone. Virtual Private Network (VPN) Services What is it? A virtual private network or VPN service can provide you with a secure tunnel from your device to the location that the VPN operates. This means that if I am using my phone in Seattle connected to a VPN in Amsterdam, if I access a website, it appears to the website that my phone is located in Amsterdam. What's the problem? VPN services are frequently advertised as providing security or protection from nefarious bad actors, or helping protect your privacy. These benefits are often far overstated, and there are predatory VPN providers that can actually be harmful. It costs money and resources to provide a VPN, so free VPN services are especially suspect. When you use a VPN, the VPN provider knows the websites you are visiting in order to provide you with the service. Free VPN providers may sell this data in order to cover the cost of providing the service, leaving you with less security and privacy. The average person does not have the knowledge to be able to determine if a VPN service is trustworthy or not. VPNs also don't provide any additional encryption benefits if you are already using HTTPS. They may provide a small amount of privacy benefit if you are connected to an untrusted network with an attacker. What should I do instead? Always use HTTPS to access websites. Don't connect to untrusted internet providers for example, use cellphone network data instead of a sketchy Wi-Fi access point. Your local neighbourhood coffee shop is probably fine. Who should use it? There are three main use cases for VPNs. The first is to bypass geographic restrictions. A VPN will cause all of your web traffic to appear to be coming from another location. If you live in an area that has local internet censorship policies, you can use a VPN to access the internet from a location that lacks such policies. The second is if you know your internet service provider is actively hostile or malicious. A trusted VPN will protect the visibility of all your traffic, including which websites you visit, from your internet service provider, and the only thing they will be able to see is that you are accessing a VPN. The third use case is to access a network that isn't connected to the public internet, such as a corporate intranet. I strongly discourage the use of VPNs for "general-purpose security." Tor What is it? Tor, "The Onion Router", is a free and open source software project that provides anonymous networking. Unlike with a VPN, where the VPN provider knows who you are and what websites you are requesting, Tor's architecture makes it extremely difficult to determine who sent a request. What's the problem? Tor is difficult to set up properly; similar to PGP-encrypted email, it is possible to accidentally not be connected to Tor and not know the difference. This usability has improved over the years, but Tor is still not a good tool for beginners to use. Due to the way Tor works, it is also extremely slow. If you have used cable or fiber internet, get ready to go back to dialup speeds. Tor also doesn't provide perfect privacy and without a strong understanding of its limitations, it can be possible to deanonymize someone despite using it. Additionally, many websites are able to detect connections from the Tor network and block them. What should I do instead? If you want to use Tor to bypass censorship, it is often better to use a trusted VPN provider, particularly if you need high bandwidth (e.g. for streaming). If you want to use Tor to access a website anonymously, Tor itself might not be enough to protect you. For example, if you need to provide an email address or personal information, you can decline to provide accurate information and use a masked email address. A friend of mine once used the alias "Nunya Biznes" Who should use it? Tor should only be used by people who are experienced users of security tools and understand its strengths and limitations. Tor also is best used on a purpose-built system, such as Tor Browser or Freedom of the Press Foundation's SecureDrop. I want to learn more! I hope you've found this guide to be a useful starting point. I always welcome folks reaching out to me with questions, though I might take a little bit of time to respond. You can always email me. If there's enough interest, I might cover the following topics in a future post: Stay safe out there!

27 October 2025

Russ Allbery: Review: On Vicious Worlds

Review: On Vicious Worlds, by Bethany Jacobs
Series: Kindom Trilogy #2
Publisher: Orbit
Copyright: October 2024
ISBN: 0-316-46362-0
Format: Kindle
Pages: 444
On Vicious Worlds is a science fiction thriller with bits of cyberpunk and a direct sequel to These Burning Stars. This is one of those series where each book has massive spoilers for the previous book and builds on characters and situations from that book. I would not read it out of order. It is Bethany Jacobs's second novel. Whooboy, how to review this without spoilers. There are so many major twists in the first book with lingering consequences that it's nearly impossible. I said at the end of my review of These Burning Stars that I was impressed with the ending for reasons that I can't reveal. One thread of this book follows the aftermath: What do you do after the plan? If you have honed yourself for one purpose, can you repurpose yourself? The other thread of the book is a murder mystery. The protectors of the community are being picked off, one by one. The culprit might be a hacker so good that they are causing Jun, the expert hacker of the first book, serious problems. Meanwhile, the political fault lines of the community are cracking open under pressure, and the leaders are untested, exhausted, and navigating difficult emotional terrain. These two story threads alternate, and interspersed are yet more flashbacks. As with the first book, the flashbacks fill in the backstory of Chono and and Esek. This time, though, we get Six's viewpoint. The good news is that On Vicious Worlds tones down the sociopathy considerably without letting up on the political twists. This is the book where Chono comes into her own. She has much more freedom of action, despite being at the center of complicated and cut-throat politics, and I thoroughly enjoyed her principled solidity. She gets a chance to transcend her previous role as an abuse victim, and it's worth the wait. The bad news is that this is very much a middle book of a trilogy. While there are a lot of bloody battles, emotional drama, political betrayals, and plot twists, the series plot has not advanced much by the end of the book. I would not say the characters were left in the same position they started the character development is real and the perils have changed but neither would I say that any of the open questions from These Burning Stars have resolved. The last book I read used science-fiction world-building to tell a story about moral philosophy that was somewhat less drama-filled than one might have expected. That is so not the case here. On Vicious Worlds is, if anything, even more dramatic than the first book of the series. In Chono's thread, the slow burn attempt to understand Six's motives has been replaced with almost non-stop melodrama, full of betrayals, reversals, risky attempts, and emotional roller coasters. Jun's part of the story is a bit more sedate at first, but there too the interpersonal drama setting is headed towards 10. This is the novel equivalent of an action movie. Jun, and her part of the story, are fine. I like the new viewpoint character, I find their system of governance somewhat interesting (although highly optimized for small groups), and I think the climax worked. But I'm invested in this series for Chono and Six. Both of them, but particularly Six, are absurdly over the top, ten people's worth of drama stuffed into one character, unable to communicate in anything less than dramatic gestures and absurd plans, but I find them magnetically fascinating. I'm not sure if written characters can have charisma, but if so, they have it. I liked this entry in the series, but then I also liked the first book. It's trauma-filled and dramatic and involved a bit too much bloody maiming for my tastes, but this whole series is about revolutions and what happens when you decide to fight, and sometimes I'm in the mood for complicated and damaged action heroes who loathe oppression and want to kill some people. This is the sort of series book that will neither be the reason you read the series nor the reason why you stop reading. If you enjoyed These Burning Stars, this is more of the same, with arguably better character development but less plot catharsis. If you didn't like These Burning Stars, this probably won't change your mind, although if you hated it specifically because of Esek's sociopathy, I think you would find this book more congenial. But maybe not; Jacobs is still the same author, and most of the characters in this series are made of sharp edges. I'm still in; I have already pre-ordered the next book. Followed by This Brutal Moon, due out in December of 2025 and advertised as the conclusion. Rating: 7 out of 10

22 September 2025

Vincent Bernat: Akvorado release 2.0

Akvorado 2.0 was released today! Akvorado collects network flows with IPFIX and sFlow. It enriches flows and stores them in a ClickHouse database. Users can browse the data through a web console. This release introduces an important architectural change and other smaller improvements. Let s dive in!
$ git diff --shortstat v1.11.5
 493 files changed, 25015 insertions(+), 21135 deletions(-)

New outlet service The major change in Akvorado 2.0 is splitting the inlet service into two parts: the inlet and the outlet. Previously, the inlet handled all flow processing: receiving, decoding, and enrichment. Flows were then sent to Kafka for storage in ClickHouse:
Akvorado flow processing before the change: flows are received and processed by the inlet, sent to Kafka and stored in ClickHouse
Akvorado flow processing before the introduction of the outlet service
Network flows reach the inlet service using UDP, an unreliable protocol. The inlet must process them fast enough to avoid losing packets. To handle a high number of flows, the inlet spawns several sets of workers to receive flows, fetch metadata, and assemble enriched flows for Kafka. Many configuration options existed for scaling, which increased complexity for users. The code needed to avoid blocking at any cost, making the processing pipeline complex and sometimes unreliable, particularly the BMP receiver.1 Adding new features became difficult without making the problem worse.2 In Akvorado 2.0, the inlet receives flows and pushes them to Kafka without decoding them. The new outlet service handles the remaining tasks:
Akvorado flow processing after the change: flows are received by the inlet, sent to Kafka, processed by the outlet and inserted in ClickHouse
Akvorado flow processing after the introduction of the outlet service
This change goes beyond a simple split:3 the outlet now reads flows from Kafka and pushes them to ClickHouse, two tasks that Akvorado did not handle before. Flows are heavily batched to increase efficiency and reduce the load on ClickHouse using ch-go, a low-level Go client for ClickHouse. When batches are too small, asynchronous inserts are used (e20645). The number of outlet workers scales dynamically (e5a625) based on the target batch size and latency (50,000 flows and 5 seconds by default). This new architecture also allows us to simplify and optimize the code. The outlet fetches metadata synchronously (e20645). The BMP component becomes simpler by removing cooperative multitasking (3b9486). Reusing the same RawFlow object to decode protobuf-encoded flows from Kafka reduces pressure on the garbage collector (8b580f). The effect on Akvorado s overall performance was somewhat uncertain, but a user reported 35% lower CPU usage after migrating from the previous version, plus resolution of the long-standing BMP component issue.

Other changes This new version includes many miscellaneous changes, such as completion for source and destination ports (f92d2e), and automatic restart of the orchestrator service (0f72ff) when configuration changes to avoid a common pitfall for newcomers. Let s focus on some key areas for this release: observability, documentation, CI, Docker, Go, and JavaScript.

Observability Akvorado exposes metrics to provide visibility into the processing pipeline and help troubleshoot issues. These are available through Prometheus HTTP metrics endpoints, such as /api/v0/inlet/metrics. With the introduction of the outlet, many metrics moved. Some were also renamed (4c0b15) to match Prometheus best practices. Kafka consumer lag was added as a new metric (e3a778). If you do not have your own observability stack, the Docker Compose setup shipped with Akvorado provides one. You can enable it by activating the profiles introduced for this purpose (529a8f). The prometheus profile ships Prometheus to store metrics and Alloy to collect them (2b3c46, f81299, and 8eb7cd). Redis and Kafka metrics are collected through the exporter bundled with Alloy (560113). Other metrics are exposed using Prometheus metrics endpoints and are automatically fetched by Alloy with the help of some Docker labels, similar to what is done to configure Traefik. cAdvisor was also added (83d855) to provide some container-related metrics. The loki profile ships Loki to store logs (45c684). While Alloy can collect and ship logs to Loki, its parsing abilities are limited: I could not find a way to preserve all metadata associated with structured logs produced by many applications, including Akvorado. Vector replaces Alloy (95e201) and features a domain-specific language, VRL, to transform logs. Annoyingly, Vector currently cannot retrieve Docker logs from before it was started. Finally, the grafana profile ships Grafana, but the shipped dashboards are broken. This is planned for a future version.

Documentation The Docker Compose setup provided by Akvorado makes it easy to get the web interface up and running quickly. However, Akvorado requires a few mandatory steps to be functional. It ships with comprehensive documentation, including a chapter about troubleshooting problems. I hoped this documentation would reduce the support burden. It is difficult to know if it works. Happy users rarely report their success, while some users open discussions asking for help without reading much of the documentation. In this release, the documentation was significantly improved.
$ git diff --shortstat v1.11.5 -- console/data/docs
 10 files changed, 1873 insertions(+), 1203 deletions(-)
The documentation was updated (fc1028) to match Akvorado s new architecture. The troubleshooting section was rewritten (17a272). Instructions on how to improve ClickHouse performance when upgrading from versions earlier than 1.10.0 was added (5f1e9a). An LLM proofread the entire content (06e3f3). Developer-focused documentation was also improved (548bbb, e41bae, and 871fc5). From a usability perspective, table of content sections are now collapsable (c142e5). Admonitions help draw user attention to important points (8ac894).
Admonition in Akvorado documentation to ask a user not to open an issue or start a discussion before reading the documentation
Example of use of admonitions in Akvorado's documentation

Continuous integration This release includes efforts to speed up continuous integration on GitHub. Coverage and race tests run in parallel (6af216 and fa9e48). The Docker image builds during the tests but gets tagged only after they succeed (8b0dce).
GitHub workflow for CI with many jobs, some of them running in parallel, some not
GitHub workflow to test and build Akvorado
End-to-end tests (883e19) ensure the shipped Docker Compose setup works as expected. Hurl runs tests on various HTTP endpoints, particularly to verify metrics (42679b and 169fa9). For example:
## Test inlet has received NetFlow flows
GET http://127.0.0.1:8080/prometheus/api/v1/query
[Query]
query: sum(akvorado_inlet_flow_input_udp_packets_total job="akvorado-inlet",listener=":2055" )
HTTP 200
[Captures]
inlet_receivedflows: jsonpath "$.data.result[0].value[1]" toInt
[Asserts]
variable "inlet_receivedflows" > 10
## Test inlet has sent them to Kafka
GET http://127.0.0.1:8080/prometheus/api/v1/query
[Query]
query: sum(akvorado_inlet_kafka_sent_messages_total job="akvorado-inlet" )
HTTP 200
[Captures]
inlet_sentflows: jsonpath "$.data.result[0].value[1]" toInt
[Asserts]
variable "inlet_sentflows" >=   inlet_receivedflows  

Docker Akvorado ships with a comprehensive Docker Compose setup to help users get started quickly. It ensures a consistent deployment, eliminating many configuration-related issues. It also serves as a living documentation of the complete architecture. This release brings some small enhancements around Docker: Previously, many Docker images were pulled from the Bitnami Containers library. However, VMWare acquired Bitnami in 2019 and Broadcom acquired VMWare in 2023. As a result, Bitnami images were deprecated in less than a month. This was not really a surprise4. Previous versions of Akvorado had already started moving away from them. In this release, the Apache project s Kafka image replaces the Bitnami one (1eb382). Thanks to the switch to KRaft mode, Zookeeper is no longer needed (0a2ea1, 8a49ca, and f65d20). Akvorado s Docker images were previously compiled with Nix. However, building AArch64 images on x86-64 is slow because it relies on QEMU userland emulation. The updated Dockerfile uses multi-stage and multi-platform builds: one stage builds the JavaScript part on the host platform, one stage builds the Go part cross-compiled on the host platform, and the final stage assembles the image on top of a slim distroless image (268e95 and d526ca).
# This is a simplified version
FROM --platform=$BUILDPLATFORM node:20-alpine AS build-js
RUN apk add --no-cache make
WORKDIR /build
COPY console/frontend console/frontend
COPY Makefile .
RUN make console/data/frontend
FROM --platform=$BUILDPLATFORM golang:alpine AS build-go
RUN apk add --no-cache make curl zip
WORKDIR /build
COPY . .
COPY --from=build-js /build/console/data/frontend console/data/frontend
RUN go mod download
RUN make all-indep
ARG TARGETOS TARGETARCH TARGETVARIANT VERSION
RUN make
FROM gcr.io/distroless/static:latest
COPY --from=build-go /build/bin/akvorado /usr/local/bin/akvorado
ENTRYPOINT [ "/usr/local/bin/akvorado" ]
When building for multiple platforms with --platform linux/amd64,linux/arm64,linux/arm/v7, the build steps until the highlighted line execute only once for all platforms. This significantly speeds up the build. Akvorado now ships Docker images for these platforms: linux/amd64, linux/amd64/v3, linux/arm64, and linux/arm/v7. When requesting ghcr.io/akvorado/akvorado, Docker selects the best image for the current CPU. On x86-64, there are two choices. If your CPU is recent enough, Docker downloads linux/amd64/v3. This version contains additional optimizations and should run faster than the linux/amd64 version. It would be interesting to ship an image for linux/arm64/v8.2, but Docker does not support the same mechanism for AArch64 yet (792808).

Go This release includes many changes related to Go but not visible to the users.

Toolchain In the past, Akvorado supported the two latest Go versions, preventing immediate use of the latest enhancements. The goal was to allow users of stable distributions to use Go versions shipped with their distribution to compile Akvorado. However, this became frustrating when interesting features, like go tool, were released. Akvorado 2.0 requires Go 1.25 (77306d) but can be compiled with older toolchains by automatically downloading a newer one (94fb1c).5 Users can still override GOTOOLCHAIN to revert this decision. The recommended toolchain updates weekly through CI to ensure we get the latest minor release (5b11ec). This change also simplifies updates to newer versions: only go.mod needs updating. Thanks to this change, Akvorado now uses wg.Go() (77306d) and I have started converting some unit tests to the new test/synctest package (bd787e, 7016d8, and 159085).

Testing When testing equality, I use a helper function Diff() to display the differences when it fails:
got := input.Keys()
expected := []int 1, 2, 3 
if diff := helpers.Diff(got, expected); diff != ""  
    t.Fatalf("Keys() (-got, +want):\n%s", diff)
 
This function uses kylelemons/godebug. This package is no longer maintained and has some shortcomings: for example, by default, it does not compare struct private fields, which may cause unexpectedly successful tests. I replaced it with google/go-cmp, which is stricter and has better output (e2f1df).

Another package for Kafka Another change is the switch from Sarama to franz-go to interact with Kafka (756e4a and 2d26c5). The main motivation for this change is to get a better concurrency model. Sarama heavily relies on channels and it is difficult to understand the lifecycle of an object handed to this package. franz-go uses a more modern approach with callbacks6 that is both more performant and easier to understand. It also ships with a package to spawn fake Kafka broker clusters, which is more convenient than the mocking functions provided by Sarama.

Improved routing table for BMP To store its routing table, the BMP component used kentik/patricia, an implementation of a patricia tree focused on reducing garbage collection pressure. gaissmai/bart is a more recent alternative using an adaptation of [Donald Knuth s ART algorithm][] that promises better performance and delivers it: 90% faster lookups and 27% faster insertions (92ee2e and fdb65c). Unlike kentik/patricia, gaissmai/bart does not help efficiently store values attached to each prefix. I adapted the same approach as kentik/patricia to store route lists for each prefix: store a 32-bit index for each prefix, and use it to build a 64-bit index for looking up routes in a map. This leverages Go s efficient map structure. gaissmai/bart also supports a lockless routing table version, but this is not simple because we would need to extend this to the map storing the routes and to the interning mechanism. I also attempted to use Go s new unique package to replace the intern package included in Akvorado, but performance was worse.7

Miscellaneous Previous versions of Akvorado were using a custom Protobuf encoder for performance and flexibility. With the introduction of the outlet service, Akvorado only needs a simple static schema, so this code was removed. However, it is possible to enhance performance with planetscale/vtprotobuf (e49a74, and 8b580f). Moreover, the dependency on protoc, a C++ program, was somewhat annoying. Therefore, Akvorado now uses buf, written in Go, to convert a Protobuf schema into Go code (f4c879). Another small optimization to reduce the size of the Akvorado binary by 10 MB was to compress the static assets embedded in Akvorado in a ZIP file. It includes the ASN database, as well as the SVG images for the documentation. A small layer of code makes this change transparent (b1d638 and e69b91).

JavaScript Recently, two large supply-chain attacks hit the JavaScript ecosystem: one affecting the popular packages chalk and debug and another impacting the popular package @ctrl/tinycolor. These attacks also exist in other ecosystems, but JavaScript is a prime target due to heavy use of small third-party dependencies. The previous version of Akvorado relied on 653 dependencies. npm-run-all was removed (3424e8, 132 dependencies). patch-package was removed (625805 and e85ff0, 69 dependencies) by moving missing TypeScript definitions to env.d.ts. eslint was replaced with oxlint, a linter written in Rust (97fd8c, 125 dependencies, including the plugins). I switched from npm to Pnpm, an alternative package manager (fce383). Pnpm does not run install scripts by default8 and prevents installing packages that are too recent. It is also significantly faster.9 Node.js does not ship Pnpm but it ships Corepack, which allows us to use Pnpm without installing it. Pnpm can also list licenses used by each dependency, removing the need for license-compliance (a35ca8, 42 dependencies). For additional speed improvements, beyond switching to Pnpm and Oxlint, Vite was replaced with its faster Rolldown version (463827). After these changes, Akvorado only pulls 225 dependencies.

Next steps I would like to land three features in the next version of Akvorado:
  • Add Grafana dashboards to complete the observability stack. See issue #1906 for details.
  • Integrate OVH s Grafana plugin by providing a stable API for such integrations. Akvorado s web console would still be useful for browsing results, but if you want to build and share dashboards, you should switch to Grafana. See issue #1895.
  • Move some work currently done in ClickHouse (custom dictionaries, GeoIP and IP enrichment) back into the outlet service. This should give more flexibility for adding features like the one requested in issue #1030. See issue #2006.

I started working on splitting the inlet into two parts more than one year ago. I found more motivation in recent months, partly thanks to Claude Code, which I used as a rubber duck. Almost none of the produced code was kept:10 it is like an intern who does not learn.

  1. Many attempts were made to make the BMP component both performant and not blocking. See for example PR #254, PR #255, and PR #278. Despite these efforts, this component remained problematic for most users. See issue #1461 as an example.
  2. Some features have been pushed to ClickHouse to avoid the processing cost in the inlet. See for example PR #1059.
  3. This is the biggest commit:
    $ git show --shortstat ac68c5970e2c   tail -1
    231 files changed, 6474 insertions(+), 3877 deletions(-)
    
  4. Broadcom is known for its user-hostile moves. Look at what happened with VMWare.
  5. As a Debian developer, I dislike these mechanisms that circumvent the distribution package manager. The final straw came when Go 1.25 spent one month in the Debian NEW queue, an arbitrary mechanism I don t like at all.
  6. In the early years of Go, channels were heavily promoted. Sarama was designed during this period. A few years later, a more nuanced approach emerged. See notably Go channels are bad and you should feel bad.
  7. This should be investigated further, but my theory is that the intern package uses 32-bit integers, while unique uses 64-bit pointers. See commit 74e5ac.
  8. This is also possible with npm. See commit dab2f7.
  9. An even faster alternative is Bun, but it is less available.
  10. The exceptions are part of the code for the admonition blocks, the code for collapsing the table of content, and part of the documentation.

31 August 2025

Otto Kek l inen: Managing procrastination and distractions

Featured image of post Managing procrastination and distractionsI ve noticed that procrastination and inability to be consistently productive at work has become quite common in recent years. This is clearly visible in younger people who have grown up with an endless stream of entertainment literally at their fingertips, on their mobile phone. It is however a trap one can escape from with a little bit of help. Procrastination is natural they say humans are lazy by nature after all. Probably all of us have had moments when we choose to postpone a task we know we should be working on, and instead spent our time doing secondary tasks (valorisation). Classic example is cleaning your apartment when you should be preparing for an exam. Some may procrastinate by not doing any work at all, and just watching YouTube videos or the like. To some people, typically those who are in their 20s and early in their career, procrastination can be a big challenge and finding the discipline to stick to planned work may need intentional extra effort, and perhaps even external help. During my 20+ year career in software development I ve been blessed to work with engineers of various backgrounds and each with their unique set of strengths. I have also helped many grow in various areas and overcome challenges, such as lack of intrinsic motivation and managing procrastination, and some might be able to get it in check with some simple advice.

Distance yourself from the digital distractions The key to avoiding distractions and procrastination is to make it inconvenient enough that you rarely do it. If continuing to do work is easier than switching to procrastination, work is more likely to continue. Tips to minimize digital distractions, listed in order of importance:
  1. Put your phone away. Just like when you go to a movie and turn off your phone for two hours, you can put the phone away completely when starting to work. Put the phone in a different room to ensure there is enough physical distance between you and the distraction, so it is impossible for you to just take a quick peek .
  2. Turn off notifications from apps. Don t let the apps call you like sirens luring Odysseus. You don t need to have all the notifications. You will see what the apps have when you eventually open them at a time you choose to use them.
  3. Remove or disable social media apps, games and the like from your phone and your computer. You can install them back when you have vacation. You can probably live without them for some time. If you can t remove them, explore your phone s screen time restriction features to limit your own access to apps that most often waste your time. These features are sometimes listed in the phone settings under digital health .
  4. Have a separate work computer and work phone. Having dedicated ones just for work that are void of all unnecessary temptations helps keep distance from the devices that could derail your focus.
  5. Listen to music. If you feel your brain needs a dose of dopamine to get you going, listening to music helps satisfy your brain s cravings while still being able to simultaneously keep working.
Doing a full digital detox is probably not practical, or not sustainable for an extended time. One needs apps to stay in touch with friends and family, and staying current in software development probably requires spending some time reading news online and such. However the tips above can help contain the distractions and minimize the spontaneous attention the distractions get. Some of the distractions may ironically be from the work itself, for example Slack notifications or new email notifications. I recommend turning them off for a couple of hours every day to have some distraction free time. It should be enough to check work mail a couple times a day. Checking them every hour probably does not add much overall value for the company unless your work is in sales or support where the main task itself is responding to emails.

Distraction free work environment Following the same principle of distancing yourself from distractions, try to use a dedicated physical space for working. If you don t have a spare room to dedicate to work, use a neighborhood caf or sign up for a local co-working space or start commuting to the company office to find a space to be focused on work in.

Break down tasks into smaller steps Sometimes people postpone tasks because they feel intimidated by the size or complexity of a task. In particular in software engineering problems may be vague and appear large until one reaches the breakthrough that brings the vision of how to tackle it. Breaking down problems into smaller more manageable pieces has many advantages in software engineering. Not only can it help with task-avoidance, but it can also make the problem easier to analyze, suggest solutions and test them and build a solid foundation to expand upon to ultimately later reach a full solution on the entire larger problem. Working on big problems as a chain of smaller tasks may also offer more opportunities to celebrate success on completing each subtask and help getting in a suitable cadence of solving a single thing, taking a break and then tackling the next issue. Breaking down a task into concrete steps may also help with getting more realistic time estimations. Sometimes procrastination isn t real someone could just be overly ambitious and feel bad about themselves for not doing an unrealistic amount of work.

Intrinsic motivation Of course, you should follow your passion when possible. Strive to pick a career that you enjoy, and thus maximize the intrinsic motivation you experience. However, even a dream job is still a job. Nobody is ever paid to do whatever they want. Any work will include at least some tasks that feel like a chore or otherwise like something you would not do unless paid to. Some would say that the definition of work itself is having to do things one would otherwise not do. You can only fully do whatever you want while on vacation or when you choose to not have a job at all. But if you have a job, you simply need to find the intrinsic motivation to do it. Simply put, some tasks are just unpleasant or boring. Our natural inclination is to avoid them in favor of more enjoyable activities. For these situations we just have to find the discipline to force ourselves to do the tasks and figuratively speaking whip ourselves into being motivated to complete the tasks.

Extrinsic motivation As the name implies, this is something people external to you need to provide, such as your employer or manager. If you have challenges in managing yourself and delivering results on a regular basis, somebody else needs to set goals and deadlines and keep you accountable for them. At the end of the day this means that eventually you will stop receiving salary or other payments unless you did your job. Forcing people to do something isn t nice, but eventually it needs to be done. It would not be fair for an employer to pay those who did their work the same salary as those who procrastinated and fell short on their tasks. If you work solo, you can also simulate the extrinsic motivation by publicly announcing milestones and deadlines to build up pressure for yourself to meet them and avoid publicly humiliation. It is a well-studied and scientifically proven phenomenon that most university students procrastinate at the start of assignments, and truly start working on them only once the deadline is imminent.

External help for addictions If procrastination is mainly due to a single distraction that is always on your mind, it may be a sign of an addiction. For example, constantly thinking about a computer game or staying up late playing a computer game, to the extent that it seriously affects your ability to work, may be a symptom of an addiction, and getting out of it may be easier with external help.

Discipline and structure Most of the time procrastination is not due to an addiction, but simply due to lack of self-discipline and structure. The good thing is that those things can be learned. It is mostly a matter of getting into new habits, which most young software engineers pick up more or less automatically while working along the more senior ones. Hopefully these tips can help you stay on track and ensure you do everything you are expected to do with clear focus, and on time!

26 July 2025

Matthew Palmer: Object deserialization attacks using Ruby's Oj JSON parser

tl;dr: there is an attack in the wild which is triggering dangerous-but-seemingly-intended behaviour in the Oj JSON parser when used in the default and recommended manner, which can lead to everyone s favourite kind of security problem: object deserialization bugs! If you have the oj gem anywhere in your Gemfile.lock, the quickest mitigation is to make sure you have Oj.default_options = mode: :strict somewhere, and that no library is overwriting that setting to something else.

Prologue As a sensible sysadmin, all the sites I run send me a notification if any unhandled exception gets raised. Mostly, what I get sent is error-handling corner cases I missed, but now and then things get more interesting. In this case, it was a PG::UndefinedColumn exception, which looked something like this:
PG::UndefinedColumn: ERROR:  column "xyzzydeadbeef" does not exist
This is weird on two fronts: firstly, this application has been running for a while, and if there was a schema problem, I d expect it to have made itself apparent long before now. And secondly, while I don t profess to perfection in my programming, I m usually better at naming my database columns than that. Something is definitely hinky here, so let s jump into the mystery mobile!

The column name is coming from outside the building! The exception notifications I get sent include a whole lot of information about the request that caused the exception, including the request body. In this case, the request body was JSON, and looked like this:
 "name":":xyzzydeadbeef", ... 
The leading colon looks an awful lot like the syntax for a Ruby symbol, but it s in a JSON string. Surely there s no way a JSON parser would be turning that into a symbol, right? Right?!? Immediately, I thought that that possibly was what was happening, because I use Sequel for my SQL database access needs, and Sequel treats symbols as database column names. It seemed like too much of a coincidence that a vaguely symbol-shaped string was being sent in, and the exact same name was showing up as a column name. But how the flying fudgepickles was a JSON string being turned into a Ruby symbol, anyway? Enter Oj.

Oj? I barely know aj A long, long time ago, the standard Ruby JSON library had a reputation for being slow. Thus did many competitors flourish, claiming more features and better performance. Strong amongst the contenders was oj (for Optimized JSON ), touted as The fastest JSON parser and object serializer . Given the history, it s not surprising that people who wanted the best possible performance turned to Oj, leading to it being found in a great many projects, often as a sub-dependency of a dependency of a dependency (which is how it ended up in my project). You might have noticed in Oj s description that, in addition to claiming fastest , it also describes itself as an object serializer . Anyone who has kept an eye on the security bug landscape will recall that object deserialization is a rich vein of vulnerabilities to mine. Libraries that do object deserialization, especially ones with a history that goes back to before the vulnerability class was well-understood, are likely to be trouble magnets. And thus, it turns out to be with Oj. By default, Oj will happily turn any string that starts with a colon into a symbol:

>> require "oj"
>> Oj.load(' "name":":xyzzydeadbeef","username":"bob","answer":42 ')
=>  "name"=>:xyzzydeadbeef, "username"=>"bob", "answer"=>42 

How that gets exploited is only limited by the creativity of an attacker. Which I ll talk about more shortly but first, a word from my rant cortex.

Insecure By Default is a Cancer While the object of my ire today is Oj and its fast-and-loose approach to deserialization, it is just one example of a pervasive problem in software: insecurity by default. Whether it s a database listening on 0.0.0.0 with no password as soon as its installed, or a library whose default behaviour is to permit arbitrary code execution, it all contributes to a software ecosystem that is an appalling security nightmare. When a user (in this case, a developer who wants to parse JSON) comes across a new piece of software, they have by definition no idea what they re doing with that software. They re going to use the defaults, and follow the most easily-available documentation, to achieve their goal. It is unrealistic to assume that a new user of a piece of software is going to do things the right way , unless that right way is the only way, or at least the by-far-the-easiest way. Conversely, the developer(s) of the software is/are the domain experts. They have knowledge of the problem domain, through their exploration while building the software, and unrivalled expertise in the codebase. Given this disparity in knowledge, it is tantamount to malpractice for the experts the developer(s) to off-load the responsibility for the safe and secure use of the software to the party that has the least knowledge of how to do that (the new user). To apply this general principle to the specific case, take the Using section of the Oj README. The example code there calls Oj.load, with no indication that this code will, in fact, parse specially-crafted JSON documents into Ruby objects. The brand-user user of the library, no doubt being under pressure to Get Things Done, is almost certainly going to look at this Using example, get the apparent result they were after (a parsed JSON document), and call it a day. It is unlikely that a brand-new user will, for instance, scroll down to the Further Reading section, find the second last (of ten) listed documents, Security.md , and carefully peruse it. If they do, they ll find an oblique suggestion that parsing untrusted input is never a good idea . While that s true, it s also rather unhelpful, because I d wager that by far the majority of JSON parsed in the world is untrusted , in one way or another, given the predominance of JSON as a format for serializing data passing over the Internet. This guidance is roughly akin to putting a label on a car s airbags that driving at speed can be hazardous to your health : true, but unhelpful under the circumstances. The solution is for default behaviours to be secure, and any deviation from that default that has the potential to degrade security must, at the very least, be clearly labelled as such. For example, the Oj.load function should be named Oj.unsafe_load, and the Oj.load function should behave as the Oj.safe_load function does presently. By naming the unsafe function as explicitly unsafe, developers (and reviewers) have at least a fighting chance of recognising they re doing something risky. We put warning labels on just about everything in the real world; the same should be true of dangerous function calls. OK, rant over. Back to the story.

But how is this exploitable? So far, I ve hopefully made it clear that Oj does some Weird Stuff with parsing certain JSON strings. It caused an unhandled exception in a web application I run, which isn t cool, but apart from bombing me with exception notifications, what s the harm? For starters, let s look at our original example: when presented with a symbol, Sequel will interpret that as a column name, rather than a string value. Thus, if our save an update to the user code looked like this:

# request_body has the JSON representation of the form being submitted
body = Oj.load(request_body)
DB[:users].where(id: user_id).update(name: body["name"])

In normal operation, this will issue an SQL query along the lines of UPDATE users SET name='Jaime' WHERE id=42. If the name given is Jaime O Dowd , all is still good, because Sequel quotes string values, etc etc. All s well so far. But, imagine there is a column in the users table that normally users cannot read, perhaps admin_notes. Or perhaps an attacker has gotten temporary access to an account, and wants to dump the user s password hash for offline cracking. So, they send an update claiming that their name is :admin_notes (or :password_hash). In JSON, that ll look like "name":":admin_notes" , and Oj.load will happily turn that into a Ruby object of "name"=>:admin_notes . When run through the above update the user code fragment, it ll produce the SQL UPDATE users SET name=admin_notes WHERE id=42. In other words, it ll copy the contents of the admin_notes column into the name column which the attacker can then read out just by refreshing their profile page.

But Wait, There s More! That an attacker can read other fields in the same table isn t great, but that s barely scratching the surface. Remember before I said that Oj does object serialization ? That means that, in general, you can create arbitrary Ruby objects from JSON. Since objects contain code, it s entirely possible to trigger arbitrary code execution by instantiating an appropriate Ruby object. I m not going to go into details about how to do this, because it s not really my area of expertise, and many others have covered it in detail. But rest assured, if an attacker can feed input of their choosing into a default call to Oj.load, they ve been handed remote code execution on a platter.

Mitigations As Oj s object deserialization is intended and documented behaviour, don t expect a future release to make any of this any safer. Instead, we need to mitigate the risks. Here are my recommended steps:
  1. Look in your Gemfile.lock (or SBOM, if that s your thing) to see if the oj gem is anywhere in your codebase. Remember that even if you don t use it directly, it s popular enough that it is used in a lot of places. If you find it in your transitive dependency tree anywhere, there s a chance you re vulnerable, limited only by the ingenuity of attackers to feed crafted JSON into a deeply-hidden Oj.load call.
  2. If you depend on oj directly and use it in your project, consider not doing that. The json gem is acceptably fast, and JSON.parse won t create arbitrary Ruby objects.
  3. If you really, really need to squeeze the last erg of performance out of your JSON parsing, and decide to use oj to do so, find all calls to Oj.load in your code and switch them to call Oj.safe_load.
  4. It is a really, really bad idea to ever use Oj to deserialize JSON into objects, as it lacks the safety features needed to mitigate the worst of the risks of doing so (for example, restricting which classes can be instantiated, as is provided by the permitted_classes argument to Psych.load). I d make it a priority to move away from using Oj for that, and switch to something somewhat safer (such as the aforementioned Psych). At the very least, audit and comment heavily to minimise the risk of user-provided input sneaking into those calls somehow, and pass mode: :object as the second argument to Oj.load, to make it explicit that you are opting-in to this far more dangerous behaviour only when it s absolutely necessary.
  5. To secure any unsafe uses of Oj.load in your dependencies, consider setting the default Oj parsing mode to :strict, by putting Oj.default_options = mode: :strict somewhere in your initialization code (and make sure no dependencies are setting it to something else later!). There is a small chance that this change of default might break something, if a dependency is using Oj to deliberately create Ruby objects from JSON, but the overwhelming likelihood is that Oj s just being used to parse ordinary JSON, and these calls are just RCE vulnerabilities waiting to give you a bad time.

Is Your Bacon Saved? If I ve helped you identify and fix potential RCE vulnerabilities in your software, or even just opened your eyes to the risks of object deserialization, please help me out by buying me a refreshing beverage. I would really appreciate any support you can give. Alternately, if you d like my help in fixing these (and many other) sorts of problems, I m looking for work, so email me.

30 June 2025

Otto Kek l inen: Corporate best practices for upstream open source contributions

Featured image of post Corporate best practices for upstream open source contributions
This post is based on presentation given at the Validos annual members meeting on June 25th, 2025.
When I started getting into Linux and open source over 25 years ago, the majority of the software development in this area was done by academics and hobbyists. The number of companies participating in open source has since exploded in parallel with the growth of mobile and cloud software, the majority of which is built on top of open source. For example, Android powers most mobile phones today and is based on Linux. Almost all software used to operate large cloud provider data centers, such as AWS or Google, is either open source or made in-house by the cloud provider. Pretty much all companies, regardless of the industry, have been using open source software at least to some extent for years. However, the degree to which they collaborate with the upstream origins of the software varies. I encourage all companies in a technical industry to start contributing upstream. There are many benefits to having a good relationship with your upstream open source software vendors, both for the short term and especially for the long term. Moreover, with the rollout of CRA in EU in 2025-2027, the law will require software companies to contribute security fixes upstream to the open source projects their products use. To ensure the process is well managed, business-aligned and legally compliant, there are a few do s and don t do s that are important to be aware of.

Maintain your SBOMs For every piece of software, regardless of whether the code was done in-house, from an open source project, or a combination of these, every company needs to produce a Software Bill of Materials (SBOM). The SBOMs provide a standardized and interoperable way to track what software and which versions are used where, what software licenses apply, who holds the copyright of which component, which security fixes have been applied and so forth. A catalog of SBOMs, or equivalent, forms the backbone of software supply-chain management in corporations.

Identify your strategic upstream vendors The SBOMs are likely to reveal that for any piece of non-trivial software, there are hundreds or thousands of upstream open source projects in use. Few organizations have resources to contribute to all of their upstreams. If your organization is just starting to organize upstream contribution activities, identify the key projects that have the largest impact on your business and prioritize forming a relationship with them first. Organizations with a mature contribution process will be collaborating with tens or hundreds of upstreams.

Appoint an internal coordinator and champions Having a written policy on how to contribute upstream will help ensure a consistent process and avoid common pitfalls. However, a written policy alone does not automatically translate into a well-running process. It is highly recommended to appoint at least one internal coordinator who is knowledgeable about how open source communities work, how software licensing and patents work, and is senior enough to have a good sense of what business priorities to optimize for. In small organizations it can be a single person, while larger organizations typically have a full Open Source Programs Office. This coordinator should oversee the contribution process, track all contributions made across the organization, and further optimize the process by working with stakeholders across the business, including legal experts, business owners and CTOs. The marketing and recruiting folks should also be involved, as upstream contributions will have a reputation-building aspect as well, which can be enhanced with systematic tracking and publishing of activities. Additionally, at least in the beginning, the organization should also appoint key staff members as open source champions. Implementing a new process always includes some obstacles and occasional setbacks, which may discourage employees from putting in the extra effort to reap the full long-term benefits for the company. Having named champions will empower them to make the first few contributions themselves, setting a good example and encouraging and mentoring others to contribute upstream as well.

Avoid excessive approvals To maintain a high quality bar, it is always good to have all outgoing submissions reviewed by at least one or two people. Two or three pairs of eyeballs are significantly more likely to catch issues that might slip by someone working alone. The review also slows down the process by a day or two, which gives the author time to sleep on it , which usually helps to ensure the final submission is well-thought-out by the author. Do not require more than one or two reviewers. The marginal utility goes quickly to zero beyond a few reviewers, and at around four or five people the effect becomes negative, as the weight of each approval decreases and the reviewers begin to take less personal responsibility. Having too many people in the loop also makes each feedback round slow and expensive, to the extent that the author will hesitate to make updates and ask for re-reviews due to the costs involved. If the organization experiences setbacks due to mistakes slipping through the review process, do not respond by adding more reviewers, as it will just grind the contribution process to a halt. If there are quality concerns, invest in training for engineers, CI systems and perhaps an internal certification program for those making public upstream code submissions. A typical software engineer is more likely to seriously try to become proficient at their job and put effort into a one-off certification exam and then make multiple high-quality contributions, than it is for a low-skilled engineer to improve and even want to continue doing more upstream contributions if they are burdened by heavy review processes every time they try to submit an upstream contribution.

Don t expect upstream to accept all code contributions Sure, identifying the root cause of and fixing a tricky bug or writing a new feature requires significant effort. While an open source project will certainly appreciate the effort invested, it doesn t mean it will always welcome all contributions with open arms. Occasionally, the project won t agree that the code is correct or the feature is useful, and some contributions are bound to be rejected. You can minimize the chance of experiencing rejections by having a solid internal review process that includes assessing how the upstream community is likely to understand the proposal. Sometimes how things are communicated is more important than how they are coded. Polishing inline comments and git commit messages help ensure high-quality communication, along with a commitment to respond quickly to review feedback and conducting regular follow-ups until a contribution is finalized and accepted.

Start small to grow expertise and reputation In addition to keeping the open source contribution policy lean and nimble, it is also good to start practical contributions with small issues. Don t aim to contribute massive features until you have a track record of being able to make multiple small contributions. Keep in mind that not all open source projects are equal. Each has its own culture, written and unwritten rules, development process, documented requirements (which may be outdated) and more. Starting with a tiny contribution, even just a typo fix, is a good way to validate how code submissions, reviews and approvals work in a particular project. Once you have staff who have successfully landed smaller contributions, you can start planning larger proposals. The exact same proposal might be unsuccessful when proposed by a new person, and successful when proposed by a person who already has a reputation for prior high-quality work.

Embrace all and any publicity you get Some companies have concerns about their employees working in the open. Indeed, every email and code patch an employee submits, and all related discussions become public. This may initially sound scary, but is actually a potential source of good publicity. Employees need to be trained on how to conduct themselves publicly, and the discussions about code should contain only information strictly related to the code, without any references to actual production environments or other sensitive information. In the long run most employees contributing have a positive impact and the company should reap the benefits of positive publicity. If there are quality issues or employee judgment issues, hiding the activity or forcing employees to contribute with pseudonyms is not a proper solution. Instead, the problems should be addressed at the root, and bad behavior addressed rather than tolerated. When people are working publicly, there tends to also be some degree of additional pride involved, which motivates people to try their best. Contributions need to be public for the sponsoring corporation to later be able to claim copyright or licenses. Considering that thousands of companies participate in open source every day, the prevalence of bad publicity is quite low, and the benefits far exceed the risks.

Scratch your own itch When choosing what to contribute, select things that benefit your own company. This is not purely about being selfish - often people working on resolving a problem they suffer from are the same people with the best expertise of what the problem is and what kind of solution is optimal. Also, the issues that are most pressing to your company are more likely to be universally useful to solve than any random bug or feature request in the upstream project s issue tracker.

Remember there are many ways to help upstream While submitting code is often considered the primary way to contribute, please keep in mind there are also other highly impactful ways to contribute. Submitting high-quality bug reports will help developers quickly identify and prioritize issues to fix. Providing good research, benchmarks, statistics or feedback helps guide development and the project make better design decisions. Documentation, translations, organizing events and providing marketing support can help increase adoption and strengthen long-term viability for the project. In some of the largest open source projects there are already far more pending contributions than the core maintainers can process. Therefore, developers who contribute code should also get into the habit of contributing reviews. As Linus law states, given enough eyeballs, all bugs are shallow. Reviewing other contributors submissions will help improve quality, and also alleviate the pressure on core maintainers who are the only ones providing feedback. Reviewing code submitted by others is also a great learning opportunity for the reviewer. The reviewer does not need to be better than the submitter - any feedback is useful; merely posting review feedback is not the same thing as making an approval decision. Many projects are also happy to accept monetary support and sponsorships. Some offer specific perks in return. By human nature, the largest sponsors always get their voice heard in important decisions, as no open source project wants to take actions that scare away major financial contributors.

Starting is the hardest part Long-term success in open source comes from a positive feedback loop of an ever-increasing number of users and collaborators. As seen in the examples of countless corporations contributing open source, the benefits are concrete, and the process usually runs well after the initial ramp-up and organizational learning phase has passed. In open source ecosystems, contributing upstream should be as natural as paying vendors in any business. If you are using open source and not contributing at all, you likely have latent business risks without realizing it. You don t want to wake up one morning to learn that your top talent left because they were forbidden from participating in open source for the company s benefit, or that you were fined due to CRA violations and mismanagement in sharing security fixes with the correct parties. The faster you start with the process, the less likely those risks will materialize.

8 January 2025

John Goerzen: Censorship Is Complicated: What Internet History Says about Meta/Facebook

In light of this week s announcement by Meta (Facebook, Instagram, Threads, etc), I have been pondering this question: Why am I, a person that has long been a staunch advocate of free speech and encryption, leery of sites that talk about being free speech-oriented? And, more to the point, why an I a person that has been censored by Facebook for mentioning the Open Source social network Mastodon not cheering a lighter touch ? The answers are complicated, and take me back to the early days of social networking. Yes, I mean the 1980s and 1990s. Before digital communications, there were barriers to reaching a lot of people. Especially money. This led to a sort of self-censorship: it may be legal to write certain things, but would a newspaper publish a letter to the editor containing expletives? Probably not. As digital communications started to happen, suddenly people could have their own communities. Not just free from the same kinds of monetary pressures, but free from outside oversight (parents, teachers, peers, community, etc.) When you have a community that the majority of people lack the equipment to access and wouldn t understand how to access even if they had the equipment you have a place where self-expression can be unleashed. And, as J. C. Herz covers in what is now an unintentional history (her book Surfing on the Internet was published in 1995), self-expression WAS unleashed. She enjoyed the wit and expression of everything from odd corners of Usenet to the text-based open world of MOOs and MUDs. She even talks about groups dedicated to insults (flaming) in positive terms. But as I ve seen time and again, if there are absolutely no rules, then whenever a group gets big enough more than a few dozen people, say there are troublemakers that ruin it for everyone. Maybe it s trolling, maybe it s vicious attacks, you name it it will arrive and it will be poisonous. I remember the debates within the Debian community about this. Debian is one of the pillars of the Internet today, a nonprofit project with free speech in its DNA. And yet there were inevitably the poisonous people. Debian took too long to learn that allowing those people to run rampant was causing more harm than good, because having a well-worn Delete key and a tolerance for insults became a requirement for being a Debian developer, and that drove away people that had no desire to deal with such things. (I should note that Debian strikes a much better balance today.) But in reality, there were never absolutely no rules. If you joined a BBS, you used it at the whim of the owner (the sysop or system operator). The sysop may be a 16-yr-old running it from their bedroom, or a retired programmer, but in any case they were letting you use their resources for free and they could kick you off for any or no reason at all. So if you caused trouble, or perhaps insulted their cat, you re banned. But, in all but the smallest towns, there were other options you could try. On the other hand, sysops enjoyed having people call their BBSs and didn t want to drive everyone off, so there was a natural balance at play. As networks like Fidonet developed, a sort of uneasy approach kicked in: don t be excessively annoying, and don t be easily annoyed. Like it or not, it seemed to generally work. A BBS that repeatedly failed to deal with troublemakers could risk removal from Fidonet. On the more institutional Usenet, you generally got access through your university (or, in a few cases, employer). Most universities didn t really even know they were running a Usenet server, and you were generally left alone. Until you did something that annoyed somebody enough that they tracked down the phone number for your dean, in which case real-world consequences would kick in. A site may face the Usenet Death Penalty delinking from the network if they repeatedly failed to prevent malicious content from flowing through their site. Some BBSs let people from minority communities such as LGBTQ+ thrive in a place of peace from tormentors. A lot of them let people be themselves in a way they couldn t be in real life . And yes, some harbored trolls and flamers. The point I am trying to make here is that each BBS, or Usenet site, set their own policies about what their own users could do. These had to be harmonized to a certain extent with the global community, but in a certain sense, with BBSs especially, you could just use a different one if you didn t like what the vibe was at a certain place. That this free speech ethos survived was never inevitable. There were many attempts to regulate the Internet, and it was thanks to the advocacy of groups like the EFF that we have things like strong encryption and a degree of freedom online. With the rise of the very large platforms and here I mean CompuServe and AOL at first, and then Facebook, Twitter, and the like later the low-friction option of just choosing a different place started to decline. You could participate on a Fidonet forum from any of thousands of BBSs, but you could only participate in an AOL forum from AOL. The same goes for Facebook, Twitter, and so forth. Not only that, but as social media became conceived of as very large sites, it became impossible for a person with enough skill, funds, and time to just start a site themselves. Instead of neading a few thousand dollars of equipment, you d need tens or hundreds of millions of dollars of equipment and employees. All that means you can t really run Facebook as a nonprofit. It is a business. It should be absolutely clear to everyone that Facebook s mission is not the one they say it is [to] give people the power to build community and bring the world closer together. If that was their goal, they wouldn t be creating AI users and AI spam and all the rest. Zuck isn t showing courage; he s sucking up to Trump and those that will pay the price are those that always do: women and minorities. Really, the point of any large social network isn t to build community. It s to make the owners their next billion. They do that by convincing people to look at ads on their site. Zuck is as much a windsock as anyone else; he will adjust policies in whichever direction he thinks the wind is blowing so as to let him keep putting ads in front of eyeballs, and stomp all over principles even free speech doing it. Don t expect anything different from any large commercial social network either. Bluesky is going to follow the same trajectory as all the others. The problem with a one-size-fits-all content policy is that the world isn t that kind of place. For instance, I am a pacifist. There is a place for a group where pacifists can hang out with each other, free from the noise of the debate about pacifism. And there is a place for the debate. Forcing everyone that signs up for the conversation to sign up for the debate is harmful. Preventing the debate is often also harmful. One company can t square this circle. Beyond that, the fact that we care so much about one company is a problem on two levels. First, it indicates how succeptible people are to misinformation and such. I don t have much to offer on that point. Secondly, it indicates that we are too centralized. We have a solution there: Mastodon. Mastodon is a modern, open source, decentralized social network. You can join any instance, easily migrate your account from one server to another, and so forth. You pick an instance that suits you. There are thousands of others you can choose from. Some aggressively defederate with instances known to harbor poisonous people; some don t. And, to harken back to the BBS era, if you have some time, some skill, and a few bucks, you can run your own Mastodon instance. Personally, I still visit Facebook on occasion because some people I care about are mainly there. But it is such a terrible experience that I rarely do. Meta is becoming irrelevant to me. They are on a path to becoming irrelevant to many more as well. Maybe this is the moment to go shrug, this sucks and try something better. (And when you do, feel free to say hi to me at @jgoerzen@floss.social on Mastodon.)

20 October 2024

Bits from Debian: Ada Lovelace Day 2024 - Interview with some Women in Debian

Alt Ada Lovelace portrait Ada Lovelace Day was celebrated on October 8 in 2024, and on this occasion, to celebrate and raise awareness of the contributions of women to the STEM fields we interviewed some of the women in Debian. Here we share their thoughts, comments, and concerns with the hope of inspiring more women to become part of the Sciences, and of course, to work inside of Debian. This article was simulcasted to the debian-women mail list. Beatrice Torracca 1. Who are you? I am Beatrice, I am Italian. Internet technology and everything computer-related is just a hobby for me, not my line of work or the subject of my academic studies. I have too many interests and too little time. I would like to do lots of things and at the same time I am too Oblomovian to do any. 2. How did you get introduced to Debian? As a user I started using newsgroups when I had my first dialup connection and there was always talk about this strange thing called Linux. Since moving from DR DOS to Windows was a shock for me, feeling like I lost the control of my machine, I tried Linux with Debian Potato and I never strayed away from Debian since then for my personal equipment. 3. How long have you been into Debian? Define "into". As a user... since Potato, too many years to count. As a contributor, a similar amount of time, since early 2000 I think. My first archived email about contributing to the translation of the description of Debian packages dates 2001. 4. Are you using Debian in your daily life? If yes, how? Yes!! I use testing. I have it on my desktop PC at home and I have it on my laptop. The desktop is where I have a local IMAP server that fetches all the mails of my email accounts, and where I sync and back up all my data. On both I do day-to-day stuff (from email to online banking, from shopping to taxes), all forms of entertainment, a bit of work if I have to work from home (GNU R for statistics, LibreOffice... the usual suspects). At work I am required to have another OS, sadly, but I am working on setting up a Debian Live system to use there too. Plus if at work we start doing bioinformatics there might be a Linux machine in our future... I will of course suggest and hope for a Debian system. 5. Do you have any suggestions to improve women's participation in Debian? This is a tough one. I am not sure. Maybe, more visibility for the women already in the Debian Project, and make the newcomers feel seen, valued and welcomed. A respectful and safe environment is key too, of course, but I think Debian made huge progress in that aspect with the Code of Conduct. I am a big fan of promoting diversity and inclusion; there is always room for improvement. Ileana Dumitrescu (ildumi) 1. Who are you? I am just a girl in the world who likes cats and packaging Free Software. 2. How did you get introduced to Debian? I was tinkering with a computer running Debian a few years ago, and I decided to learn more about Free Software. After a search or two, I found Debian Women. 3. How long have you been into Debian? I started looking into contributing to Debian in 2021. After contacting Debian Women, I received a lot of information and helpful advice on different ways I could contribute, and I decided package maintenance was the best fit for me. I eventually became a Debian Maintainer in 2023, and I continue to maintain a few packages in my spare time. 4. Are you using Debian in your daily life? If yes, how? Yes, it is my favourite GNU/Linux operating system! I use it for email, chatting, browsing, packaging, etc. 5. Do you have any suggestions to improve women's participation in Debian? The mailing list for Debian Women may attract more participation if it is utilized more. It is where I started, and I imagine participation would increase if it is more engaging. Kathara Sasikumar (kathara) 1. Who are you? I'm Kathara Sasikumar, 22 years old and a recent Debian user turned Maintainer from India. I try to become a creative person through sketching or playing guitar chords, but it doesn't work! xD 2. How did you get introduced to Debian? When I first started college, I was that overly enthusiastic student who signed up for every club and volunteered for anything that crossed my path just like every other fresher. But then, the pandemic hit, and like many, I hit a low point. COVID depression was real, and I was feeling pretty down. Around this time, the FOSS Club at my college suddenly became more active. My friends, knowing I had a love for free software, pushed me to join the club. They thought it might help me lift my spirits and get out of the slump I was in. At first, I joined only out of peer pressure, but once I got involved, the club really took off. FOSS Club became more and more active during the pandemic, and I found myself spending more and more time with it. A year later, we had the opportunity to host a MiniDebConf at our college. Where I got to meet a lot of Debian developers and maintainers, attending their talks and talking with them gave me a wider perspective on Debian, and I loved the Debian philosophy. At that time, I had been distro hopping but never quite settled down. I occasionally used Debian but never stuck around. However, after the MiniDebConf, I found myself using Debian more consistently, and it truly connected with me. The community was incredibly warm and welcoming, which made all the difference. 3. How long have you been into Debian? Now, I've been using Debian as my daily driver for about a year. 4. Are you using Debian in your daily life? If yes, how? It has become my primary distro, and I use it every day for continuous learning and working on various software projects with free and open-source tools. Plus, I've recently become a Debian Maintainer (DM) and have taken on the responsibility of maintaining a few packages. I'm looking forward to contributing more to the Debian community Rhonda D'Vine (rhonda) 1. Who are you? My name is Rhonda, my pronouns are she/her, or per/pers. I'm 51 years old, working in IT. 2. How did you get introduced to Debian? I was already looking into Linux because of university, first it was SuSE. And people played around with gtk. But when they packaged GNOME and it just didn't even install I looked for alternatives. A working colleague from back then gave me a CD of Debian. Though I couldn't install from it because Slink didn't recognize the pcmcia drive. I had to install it via floppy disks, but apart from that it was quite well done. And the early GNOME was working, so I never looked back. 3. How long have you been into Debian? Even before I was more involved, a colleague asked me whether I could help with translating the release documentation. That was my first contribution to Debian, for the slink release in early 1999. And I was using some other software before on my SuSE systems, and I wanted to continue to use them on Debian obviously. So that's how I got involved with packaging in Debian. But I continued to help with translation work, for a long period of time I was almost the only person active for the German part of the website. 4. Are you using Debian in your daily life? If yes, how? Being involved with Debian was a big part of the reason I got into my jobs since a long time now. I always worked with maintaining Debian (or Ubuntu) systems. Privately I run Debian on my laptop, with occasionally switching to Windows in dual boot when (rarely) needed. 5. Do you have any suggestions to improve women's participation in Debian? There are factors that we can't influence, like that a lot of women are pushed into care work because patriarchal structures work that way, and don't have the time nor energy to invest a lot into other things. But we could learn to appreciate smaller contributions better, and not focus so much on the quantity of contributions. When we look at longer discussions on mailing lists, those that write more mails actually don't contribute more to the discussion, they often repeat themselves without adding more substance. Through working on our own discussion patterns this could create a more welcoming environment for a lot of people. Sophie Brun (sophieb) 1. Who are you? I'm a 44 years old French woman. I'm married and I have 2 sons. 2. How did you get introduced to Debian? In 2004 my boyfriend (now my husband) installed Debian on my personal computer to introduce me to Debian. I knew almost nothing about Open Source. During my engineering studies, a professor mentioned the existence of Linux, Red Hat in particular, but without giving any details. I learnt Debian by using and reading (in advance) The Debian Administrator's Handbook. 3. How long have you been into Debian? I've been a user since 2004. But I only started contributing to Debian in 2015: I had quit my job and I wanted to work on something more meaningful. That's why I joined my husband in Freexian, his company. Unlike most people I think, I started contributing to Debian for my work. I only became a DD in 2021 under gentle social pressure and when I felt confident enough. 4. Are you using Debian in your daily life? If yes, how? Of course I use Debian in my professional life for almost all the tasks: from administrative tasks to Debian packaging. I also use Debian in my personal life. I have very basic needs: Firefox, LibreOffice, GnuCash and Rhythmbox are the main applications I need. Sruthi Chandran (srud) 1. Who are you? A feminist, a librarian turned Free Software advocate and a Debian Developer. Part of Debian Outreach team and DebConf Committee. 2. How did you get introduced to Debian? I got introduced to the free software world and Debian through my husband. I attended many Debian events with him. During one such event, out of curiosity, I participated in a Debian packaging workshop. Just after that I visited a Tibetan community in India and they mentioned that there was no proper Tibetan font in GNU/Linux. Tibetan font was my first package in Debian. 3. How long have you been into Debian? I have been contributing to Debian since 2016 and Debian Developer since 2019. 4. Are you using Debian in your daily life? If yes, how? I haven't used any other distro on my laptop since I got introduced to Debian. 5. Do you have any suggestions to improve women's participation in Debian? I was involved with actively mentoring newcomers to Debian since I started contributing myself. I specially work towards reducing the gender gap inside the Debian and Free Software community in general. In my experience, I believe that visibility of already existing women in the community will encourage more women to participate. Also I think we should reintroduce mentoring through debian-women. T ssia Cam es Ara jo (tassia) 1. Who are you? T ssia Cam es Ara jo, a Brazilian living in Canada. I'm a passionate learner who tries to push myself out of my comfort zone and always find something new to learn. I also love to mentor people on their learning journey. But I don't consider myself a typical geek. My challenge has always been to not get distracted by the next project before I finish the one I have in my hands. That said, I love being part of a community of geeks and feel empowered by it. I love Debian for its technical excellence, and it's always reassuring to know that someone is taking care of the things I don't like or can't do. When I'm not around computers, one of my favorite things is to feel the wind on my cheeks, usually while skating or riding a bike; I also love music, and I'm always singing a melody in my head. 2. How did you get introduced to Debian? As a student, I was privileged to be introduced to FLOSS at the same time I was introduced to computer programming. My university could not afford to have labs in the usual proprietary software model, and what seemed like a limitation at the time turned out to be a great learning opportunity for me and my colleagues. I joined this student-led initiative to "liberate" our servers and build LTSP-based labs - where a single powerful computer could power a few dozen diskless thin clients. How revolutionary it was at the time! And what an achievement! From students to students, all using Debian. Most of that group became close friends; I've married one of them, and a few of them also found their way to Debian. 3. How long have you been into Debian? I first used Debian in 2001, but my first real connection with the community was attending DebConf 2004. Since then, going to DebConfs has become a habit. It is that moment in the year when I reconnect with the global community and my motivation to contribute is boosted. And you know, in 20 years I've seen people become parents, grandparents, children grow up; we've had our own child and had the pleasure of introducing him to the community; we've mourned the loss of friends and healed together. I'd say Debian is like family, but not the kind you get at random once you're born, Debian is my family by choice. 4. Are you using Debian in your daily life? If yes, how? These days I teach at Vanier College in Montr al. My favorite course to teach is UNIX, which I have the pleasure of teaching mostly using Debian. I try to inspire my students to discover Debian and other FLOSS projects, and we are happy to run a FLOSS club with participation from students, staff and alumni. I love to see these curious young minds put to the service of FLOSS. It is like recruiting soldiers for a good battle, and one that can change their lives, as it certainly did mine. 5. Do you have any suggestions to improve women's participation in Debian? I think the most effective way to inspire other women is to give visibility to active women in our community. Speaking at conferences, publishing content, being vocal about what we do so that other women can see us and see themselves in those positions in the future. It's not easy, and I don't like being in the spotlight. It took me a long time to get comfortable with public speaking, so I can understand the struggle of those who don't want to expose themselves. But I believe that this space of vulnerability can open the way to new connections. It can inspire trust and ultimately motivate our next generation. It's with this in mind that I publish these lines. Another point we can't neglect is that in Debian we work on a volunteer basis, and this in itself puts us at a great disadvantage. In our societies, women usually take a heavier load than their partners in terms of caretaking and other invisible tasks, so it is hard to afford the free time needed to volunteer. This is one of the reasons why I bring my son to the conferences I attend, and so far I have received all the support I need to attend DebConfs with him. It is a way to share the caregiving burden with our community - it takes a village to raise a child. Besides allowing us to participate, it also serves to show other women (and men) that you can have a family life and still contribute to Debian. My feeling is that we are not doing super well in terms of diversity in Debian at the moment, but that should not discourage us at all. That's the way it is now, but that doesn't mean it will always be that way. I feel like we go through cycles. I remember times when we had many more active female contributors, and I'm confident that we can improve our ratio again in the future. In the meantime, I just try to keep going, do my part, attract those I can, reassure those who are too scared to come closer. Debian is a wonderful community, it is a family, and of course a family cannot do without us, the women. These interviews were conducted via email exchanges in October, 2024. Thanks to all the wonderful women who participated in this interview. We really appreciate your contributions in Debian and to Free/Libre software.

17 September 2024

Jonathan Dowland: ouch, part 2

Things developed since my last post. Some lesions opened up on my ankle which was initially good news: the pain substantially reduced. But they didn t heal fast enough and so medics decided on surgical debridement. That was last night. It seemed to be successful and I m in recovery from surgery as I write. It s hard to predict the near-future, a lot depends on how well and fast I heal. I ve got a negative-pressure dressing on it, which is incredible: a constantly maintained suction to aid in debridement and healing. Modern medicine feels like a sci fi novel.

Jonathan Dowland: ouch, part 3

The debridement operation was a success: nothing bad grew afterwards. I was discharged after a couple of nights with crutches, instructions not to weight-bear, a remarkable, portable negative-pressure "Vac" pump that lived by my side, and some strong painkillers. About two weeks later, I had a skin graft. The surgeon took some skin from my thigh and stitched it over the debridement wound. I was discharged same-day, again with the Vac pump, and again with instructions not to weight-bear, at least for a few days. This time I only kept the Vac pump for a week, and after a dressing change (the first time I saw the graft), I was allowed to walk again. Doing so is strangely awkward, and sometimes a little painful. I have physio exercises to help me regain strength and understanding about what I can do. The donor site remained bandaged for another week before I saw it. I was expecting a stitched cut, but the surgeons have removed the top few layers only, leaving what looks more like a graze or sun-burn. There are four smaller, tentative-looking marks adjacent, suggesting they got it right on the fifth attempt. I'm not sure but I think these will all fade away to near-invisibility with time, and they don't hurt at all. I've now been off work for roughly 12 weeks, but I think I am returning very soon. I am looking forward to returning to some sense of normality. It's been an interesting experience. I thought about writing more about what I've gone through, in particular my experiences in Hospital, dealing with the bureaucracy and things falling "between the gaps". Hanif Kureishi has done a better job than I could. It's clear that the NHS is staffed by incredibly passionate people, but there are a lot of structural problems that interfere with care.

Next.