Search Results: "peb"

13 November 2026

Reproducible Builds: Reproducible Builds in October 2026

Welcome to the October 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third parties to come to a consensus on whether a build was compromised or not. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. In this month s report, we cover:
  1. GNU tar sparse archive non-determinism reported
  2. Reproducible Builds at SeaGL 2026
  3. Tool and documentation development
  4. Distribution work
  5. SOURCE_DATE_EPOCH specification updates
  6. Mailing list news
  7. Patches


GNU tar sparse archive non-determinism reported Johannes Schauer Marin Rodrigues (josch) reported an issue to the GNU tar mailing list where creating PAX-format sparse tar archives produces unreproducible outputs. Specifically, when GNU tar generates a PAX archive containing a sparse file it embeds the process ID into the member filename path structure (e.g. ./GNUSparseFile.<pid>/<filename>). Because process IDs vary between build runs, however, archiving identical sparse input files yields different binary outputs. In his report, Johannes outlined potential workarounds, such as running tar inside an unshared PID namespace where the process ID is pinned to 1, and proposed that GNU tar either omit the PID by default or provide a command-line flag to suppress it. Full details can be found in the post itself, and Johannes also filed the bug in Debian for completeness.

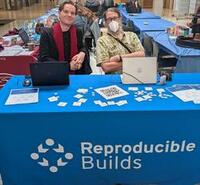
Reproducible Builds at SeaGL 2026 Reproducible Builds was present at SeaGL in Seattle, WA, on October 23rd & 24th. Thanks to everyone who attended and spoke with us! Members of the Reproducible Builds project attended SeaGL (the Seattle GNU/Linux Conference) in Seattle, WA, on October 23rd & 24th. It was a fantastic opportunity to connect with local community members, discuss software supply chain security and share updates on build verification tooling. Thanks to everyone who stopped by our sessions or spoke with us during the event. Founded in 2013, SeaGL is an annual free-as-in-freedom, grassroots technical summit dedicated to spreading awareness, community engagement and practical knowledge about free software, open hardware and libre culture.
Tool and documentation development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 333, 334, 335 and 336 to Debian:
  • New features:
    • Support the dumppdf binary being called dumppdf.py on the host/runtime system. [ ]
  • Bug fixes:
    • Drop Recommends: guix from the diffoscope-minimal package as it is not minimal. (#1114739) [ ]
    • Fix a crash when using the latest version(s) of Androguard. Thanks, hc! [ ]
  • Codebase improvements:
    • Re-order various parts of the .tar file comparator to make it easier to progressively delve into its functionality. [ ]
    • Fix a silly prepend typo. [ ]
    • Reflect in the Python packaging that the use of the case-match language feature necessarily requires Python 3.10+. [ ]
  • Misc:
    • Update debian/tests/control. [ ]
    • Update copyright years. [ ]
In addition, Johannes Schauer Marin Rodrigues added support for POSIX.1-2001 PAX headers in the .tar file comparator [ ] and Vagrant Cascadian proposed an update in diffoscope in GNU Guix to version 335.

Distribution work In Debian this month, 20 reviews of Debian packages were added, 28 were updated and 27 were removed this month adding to our knowledge about identified issues. One issue type was updated to reflect that Debhelper compat level 14 is no longer experimental. [ ] In addition, Vagrant Cascadian performed a number of Non-Maintainer Uploads (NMUs) and Quality Assurance (QA) uploads in Debian for several packages with outstanding reproducibility issues. These included clhep, tea-cli, argparse-manpage, ruby-timers, mandos and cdebootstrap.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

SOURCE_DATE_EPOCH specification updates As announced in last month s report, further work has been done by Bernhard M. Wiedemann regarding updating the SOURCE_DATE_EPOCH specification following discussions at a project summit. Seven distinct proposed changes were originally submitted as merge requests on Salsa, and many of these have been approved or otherwise collapsed. Bernhard s proposed modifications were independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests; as Bernhard writes, The other MRs could still use feedback from more people before December . Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list. The SOURCE_DATE_EPOCH specification was first published in 2015 and updated in 2017.

Mailing list news On our mailing list this month:

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including: In addition, two build failure bugs were reported by Jochen Sprickerhof.

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

6 September 2026

Michael Stapelberg: Debian Code Search: Fast TurboPFor with Go SIMD

This August, I accomplished what I wanted for many years: I deleted the last cgo dependency in Debian Code Search! This was made possible by Go s recently introduced SIMD support, because now we can implement the TurboPFor integer compression format as efficiently more efficiently, in fact, by using the newer AVX512 instruction set! as the reference implementation.

Background: Why does DCS need a fast Integer Codec? Debian Code Search (DCS) is a search engine that allows searching all the Open Source source code within Debian, with either literal search expressions or regular expression search queries. A search engine uses an inverted index: a map from term to documents containing the term. Each document is typically represented most efficiently by using an id, so the index consists of many lists of document ids. When searching, it is important to quickly decode these lists to answer the search query. However, there is a point of diminishing returns where the decoding speed, even though it can still be measurably improved quite a bit, no longer influences the overall query duration. From 2012 (its inception) to 2019, Debian Code Search used to use a small index format, and queries were fast because the index was kept entirely in RAM. In 2019, I implemented the new index format, which adds an on-disk positional index. For literal queries (78.2% of DCS queries), querying the positional index on disk is faster than querying the non-positional index in RAM. The efficient encoding of the TurboPFor format makes it possible to fit such an index on a mid-sized Hetzner server, which I rent with two 1 TB SSD disks. The optimized decoder of the C TurboPFor library is what made decoding fast at query time. If you want to dive deeper into the algorithm, see this blog post from February 2019: If you want to learn more about the positional index, see this blog post from September 2019:

SIMD in Go For many years, you had the following options for using SIMD instructions in Go:
  1. Hand-writing Go assembler code. This is only doable for small functions, for example bytes.IndexByte is implemented with hand-written Go assembly (including AVX2).
  2. Generating Go assembler code with tools like Michael McLoughlin s Avo . This is how crypto/internal/fips140/sha256 uses AVX2. While Avo generator code definitely is higher-level than hand-written assembly, it is still too close to assembly for my taste.
  3. Use a C library via cgo so gcc or clang compiles SIMD code. Debian Code Search used to use the powturbo/TurboPFor C library via cgo for the last 7 years.
The C TurboPFor library has served us well, but Debian Code Search was always intended to be a project using Go, so I would prefer it if I did not have any C code in the project. Go 1.26 (released in February 2026) introduced the simd/archsimd package:
Go 1.26 introduces a new experimental simd/archsimd package, which can be enabled by setting the environment variable GOEXPERIMENT=simd at build time. This package provides access to architecture-specific SIMD operations. It is currently available on the amd64 architecture and supports 128-bit, 256-bit, and 512-bit vector types, such as Int8x16 and Float64x8, with operations such as Int8x16.Add. The API is not yet considered stable. Go 1.26 Release Notes
For my 2019 TurboPFor analysis, I implemented goturbopfor, a native Go teaching decoder (without any SIMD), because I find Go code easier to follow than C code, especially optimized C code. My implementation was intentionally not optimized so that the code was easier to study. The TurboPFor format/algorithm has a vector-optimized part: bitpacking comes in a scalar variant (bitunpack32) and a vector variant (bitunpack256v32), where the vector variant is used for full blocks (256 values) and the scalar variant is used for remainder blocks (< 256 values). When Go 1.26 was released, I used Claude Code to explore whether my native Go decoder s bitunpack256v32 function (for the vertical vector layout) could be implemented using Go SIMD, and the answer was yes, it was possible and it was faster than without SIMD, but not quite at the level of C TurboPFor. If you let Claude Code try for long enough, it eventually finds enough optimizations (about 10) to match C performance. I don t want to vibe-code Debian Code Search, though, so I figured I would find some time to review the SIMD code at some point and see if I could implement something similar myself. Before I found enough time and motivation to complete said review, I discovered that to not regress real-life query performance by more than 10 to 100 milliseconds (which seems acceptable), I don t actually need to add SIMD code to my teaching decoder at all; it would be sufficient to reduce allocations in my teaching decoder and specialize it per bit width. Encouraged by the possibility of using the optimized native Go decoder in Debian Code Search, I explored whether I could also implement a native Go encoder so that I could get rid of the C TurboPFor dependency entirely. The answer is yes, it is doable in a few days, and it isn t even that much slower: Go is at 76% of C, see Debian/dcs commit e920dc7. The goal I set myself at that point was to see if I could learn enough SIMD to optimize the native Go encoder such that its performance would match how DCS uses C TurboPFor (via cgo). Beating C TurboPFor was possible in 2-3 commits (SIMD and bit width specialization). To my surprise, Claude Fable 5 pointed out that the encoder s block scanning could be done more efficiently using a technique called positional popcount, and that is another 2x speed-up! To be clear: I am not saying the Go compiler beats C here. Certainly, the C compiler can also produce fast AVX512 code and can be used to implement positional popcount. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. This spectacular result (much faster than what DCS had before) got me curious how far I could push the decoder with SIMD after all. I ended up matching/exceeding the cgo version here, too! The rest of this article explains a few classes of optimizations I encountered along the way.

Starting Point When I wrote my goturbopfor teaching decoder, I named its functions to match the upstream C TurboPFor library, but now I want to get away from names like p4ndec256v32 they make sense from the TurboPFor perspective, but for Debian Code Search, we can use cleaner names. Before writing any code, I audited how DCS uses integer compression / decompression.

API design: BlockEncoder, BlockDecoder and streaming In Debian Code Search, we have the following usage patterns:
  • Partial Indexing: When a new package (or package version) enters Debian, all of its (text) files are indexed. If the hello-2.12.3-1 package (hypothetically) contained only hello.c with printf("hello!\n");, we would assign document ID 1 to hello.c and store in the partial index that trigrams pri, rin, int, ntf, etc. are all found in doc 1 (hello.c).
  • Full Index Merging: The many thousands of partial index files (for each Debian package) are combined into a small handful of large index files: When searching, it would be expensive to consult thousands of indexes. To merge multiple partial index files into one larger index (which can then be efficiently queried), we need to re-encode the partial index files: what used to be document ID 1 in the partial index might be document ID 2531 in the full index.
  • Querying (searching): When users enter search queries, these queries need to be answered as quickly as possible. The relevant entries in the full indexes are decoded (in parallel).
For reading the index, we do keep the decoded uint32s fully in memory, so we only need DecodeN(input []byte, output []uint32) (read int), a function that reads len(output) values (uint32) from input and returns how many bytes it consumed. For writing the index (both in partial indexing, and when merging), keeping the entire index in memory is prohibitively expensive, so we need a streaming API, for decoding and for encoding. Ultimately, I converged on the following API:
package pforenc

type BlockEncoder struct  
    // scratch buffers can go here
 

// EncodeBlock encodes len(vals)<=256 uint32s into dest (one TurboPFor block).
func (*BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  

// EncodeN calls EncodeBlock in a loop.
func (*BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  

type StreamEncoder struct  
  be   BlockEncoder
  vals [256]uint32
  // scratch buffers
 

// if full, you need to call [EncodeBlock]
func (*StreamEncoder) Add(val uint32) (full bool)

// EncodeBlock must be called after all data was [Add]ed.
//
// Write the returned buffer to file or send it over the network;
// it is only valid until the next [EncodeBlock] call.
func (*StreamEncoder) EncodeBlock() []byte  
  if se.n == 0   return nil   // turn an extra EncodeBlock into a no-op
  //  
 
This API (the decoder works similarly) allows us to process data in TurboPFor format without any memory allocations. The types are not safe for concurrent use by multiple goroutines. The zero value is ready to be used. For the streaming API, the result only stays valid until the next call.

Initial Implementation Before we can optimize anything, we need a working decoder and encoder. The decoder already exists: my goturbopfor teaching decoder. Next up, I needed an encoder. Writing a TurboPFor encoder has a delightfully simple starting point: You can encode all values at bit width 32, in little endian, at which point you only need to add a one-byte TurboPFor block header every 256 values and you re done:
func (be *BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  
  for len(vals) > 0  
    chunk := min(len(vals), 256)
    dest = be.EncodeBlock(dest, vals[:chunk])
    vals = vals[chunk:]
   
  return dest
 

func (be *BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  
  const bitWidth = 32
  dest = append(dest, bitWidth)
  for _, val := range vals  
    dest = binary.LittleEndian.AppendUint32(dest, val)
   
  return dest
 
Of course, this is a terribly inefficient compressor, so after the first commit, the real work starts: implement each block type until the compression matches the original C TurboPFor implementation (same output file size), or in other words: do the reverse of the decoder.
  1. The TurboPFor bitpacking block type (bitpacking implementation commit) encodes a bit stream of variable bit width (where the bit width is in range 0 bitWidth 32) in little endian byte order. By scanning all values and choosing the smallest bit width that allows representing all values, this technique saves disk space (compresses).
  2. The bitpacking with exceptions block type (bitpacking with exceptions implementation commit) determines two bit widths: one for values, the other bit width for encoding exceptions. This allows choosing a lower bit width (that does not cover all values) compared to the bitpacking block type. A bitmap encodes whether a value has an exception or not.
  3. The bitpacking with VB exceptions block type (bitpacking with VB exceptions implementation commit) is a variant which does not use an exception bitmap and encodes exceptions using a variable byte integer encoding. This is more efficient when there are few exceptions (less than 20) or the exceptions are very different in bit width compared to the other values.
  4. Lastly, the constant block type (constant implementation commit) stores just one value on disk. This is useful for all-zero or all-one blocks, for example.
I found it interesting to realize that the main work of the encoder is to scan the input values and choose the optimal block type, whereas the actual encoding itself is cheap in comparison. At this point, we can look at performance and see that the Go encoder is at 76% of the C encoder. In all honesty, I could have probably stopped here, but now that the milestone of a viable replacement was reached, I got curious to see how far it would be possible to push the encoder (how much work to reach C speeds?) and afterwards, the decoder, too.

Setup

The microarchitecture level: set GOAMD64 The microarchitecture of a CPU determines which instructions it provides, and that includes not just SIMD instruction sets (like AVX2), but also other useful instructions like LZCNT (Leading Zero Count), which can be used to implement math/bits.Len32 more efficiently, which the TurboPFor encoder needs to call on every input value to determine the ideal bit width. Let s walk through how to set the microarchitecture level when using Go on 64-bit x86 (x86-64). Go uses the GOARCH environment variable to configure the target compilation architecture, and I am using the value amd64 to select 64-bit x86 (AVX2 and AVX512 are instruction sets found on x86-64 CPUs). With GOARCH=amd64, the architecture-specific variable GOAMD64 configures the microarchitecture level for which to compile and Go 1.18 introduced these 4 different levels:
GOAMD64=v1 (default): The baseline.
Exclusively generates instructions that all 64-bit x86 processors can execute. GOAMD64=v2: all v1 instructions,
plus CMPXCHG16B, LAHF, SAHF, POPCNT, SSE3, SSE4.1, SSE4.2, SSSE3. GOAMD64=v3: all v2 instructions,
plus AVX, AVX2, BMI1, BMI2, F16C, FMA, LZCNT, MOVBE, OSXSAVE. GOAMD64=v4: all v3 instructions,
plus AVX512F, AVX512BW, AVX512CD, AVX512DQ, AVX512VL.
In 2026, I generally recommend compiling with GOAMD64=v3 so that functions like bits.OnesCount8 are compiled into intrinsics (POPCNT) instead of using a lookup table. For Intel CPUs, setting GOAMD64=v3 means your programs will only start on Haswell CPUs (2013) or newer; for AMD CPUs that means Zen 1 (2017) or newer. In this specific case (DCS), I am even compiling with GOAMD64=v4. The v4 microarchitecture level requires AVX512, which means AMD Zen 4, Zen 5 or newer (Intel s story is complicated). Luckily, both my main development PC (Zen 5) and the Debian Code Search server (Zen 4) are recent enough. Setting GOAMD64=v4 has little effect on Go 1.27 itself: the only change is that maps use one less instruction (VPBROADCASTB instead of PSHUFB). But compiling with GOAMD64=v4 allows us to move one more feature check from runtime to compile time, see SIMD build tags. It makes sense to set the microarchitecture level in your benchmark setup so that you don t measure the slow fallback implementations. I use export GOAMD64=v4 in my Makefile.

Benchmarking setup Go s built-in testing package contains support for benchmarks which are written in functions of the form func BenchmarkXxx(b *testing.B). The simplest way to run such benchmarks is go test -bench=., but I ended up configuring a few convenience make targets, which write results to bench.txt and compare against baseline.txt (the previous commit s results, usually), using the very useful benchstat tool.
GOTEST=go test

# -count=6 gives p 0.002 in benchstat:
# https://pkg.go.dev/golang.org/x/perf/cmd/benchstat
BENCHFLAGS=-run=^$$ -bench=. -benchtime=200000x -count=6

# use taskset -c1 to always pin to the same single core,
# avoiding accidental scheduling on different cores on
# mixed-core CPUs like the Ryzen 9 9950X3D.
TASKSET=taskset -c 1
BENCH=$(TASKSET) $(GOTEST) $(BENCHFLAGS)

.PHONY: all test bench bench-baseline bench-relative

all: test

bench: test
	$(BENCH)   tee bench.txt
# Compares compression ratio between C and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '-/impl:go-stream .unit:(encoded-bytes)' bench.txt
# Compares performance between C (cgo) and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '.unit:(Mval/s)' bench.txt

bench-baseline: test
	$(BENCH)   tee baseline.txt

bench-relative: test
	$(BENCH)   tee bench.txt
	benchstat -filter '-/impl:go-stream .unit:(encoded-bytes)' baseline.txt bench.txt
	benchstat -filter '/impl:go .unit:(Mval/s)' baseline.txt bench.txt
The encoded-bytes and Mval/s units are custom metrics I am reporting from the various sub-benchmarks, which are arranged such that I can filter / report them with benchstat. The main encoder (and decoder) benchmarks compare 3 different implementations (cgo, Go, Go with the StreamEncoder API) with a number of benchmark cases that are designed to cover the different block types and contain a similar mix of values as what we see in Debian Code Search:
// reportMetrics adds Mval/s and encoded-bytes metrics to all benchmarks.
func reportMetrics(b *testing.B, n int, nencoded int)  
   b.ReportMetric(float64(nencoded), "encoded-bytes")
   b.ReportMetric(float64(b.N*n)/1e6/b.Elapsed().Seconds(), "Mval/s")
 

// BenchmarkEncode/n=<N>/vals=<testcase>/impl=<c go go-stream>
//
// e.g. BenchmarkEncode/n=2048/vals=one-constant/impl=go-stream
func BenchmarkEncode(b *testing.B)  
   for _, tc := range allBenchCases()  
     n := len(tc.vals)
     b.Run(fmt.Sprintf("n=%d/vals=%s", n, tc.name), func(b *testing.B)  
       b.Run("impl=c", func(b *testing.B)  
         b.ReportAllocs()
         var encoded []byte
         buf := make([]byte, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = turbopfor.P4nenc256v32Buf(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go", func(b *testing.B)  
         b.ReportAllocs()
         var be BlockEncoder
         var encoded []byte
         buf := make([]byte, 0, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = be.EncodeN(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go-stream", func(b *testing.B)  
         b.ReportAllocs()
         var se StreamEncoder
         var encoded int
         for b.Loop()  
           encoded = 0
           for _, val := range tc.vals  
             if se.Add(val)  
               encoded += len(se.EncodeBlock())
              
            
           encoded += len(se.EncodeBlock())
          
         reportMetrics(b, n, encoded)
        )
      )


CPU counters: perf Go has included excellent performance tooling for many years, see the Profiling Go Programs blog post (2011) for an example of how to use pprof, a sampling profiler. This profiler can help track down which part of a program runs slow, or where memory allocations happen. Once you identified the slow part of a program, how do you know why it s slow? To learn more about the specific bottlenecks your program encounters, you can consult your CPU s hardware performance counters. For example, you could check the branch predictor counters to see if your program is slow due to a high number of branch mispredicts. On Linux, the perf tool is the best way to access the CPU hardware performance counters. A good starting point for working with perf is the documentation on Top-down analysis with the perf tool , which describes the optimization method that Intel established. In my Makefile, I set up two perf targets:
# GOTEST and TASKSET like shown in the earlier benchmarking setup section:
GOTEST=go test -pgo=encode.cpuprof
TASKSET=taskset -c 1
PERFBENCHFLAGS=-test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=200000x

# Use perf(1) to capture AMD IBS (the equivalent to Intel PEBS)
# PipelineL1 is roughly equivalent to Intel TopdownL1
perf:
	$(GOTEST) -c
	$(TASKSET) perf stat -M PipelineL1 ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo perf record -F 4999 -e ibs_op// --call-graph fp ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo chmod 644 perf.data

# 488281 iterations   2048 values = 1.000e9 values, so counter/1e9 = per value.
perf-per-value:
	$(GOTEST) -c
	$(TASKSET) perf stat -x, -e cycles:u,instructions:u,branches:u,branch-misses:u ./pforenc.test -test.run=^$$ -test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=488281x 2>&1 >/dev/null   awk -F, ' printf "%-16s %6.2f /val\n", $$3, $$1/1e9 '
The perf-per-value numbers are high level numbers that indicate how much work the implementation is doing. Reducing the number usually increases speed. To see the counters for each instruction (and source code lines), I use make perf, followed by perf report. A quick shortcut is perf annotate, which directly shows the hottest function.

Optimizations (scalar) Let s first see how far we can get without reaching for SIMD instructions. (The examples are not necessarily in commit order, but cherry-picked for clarity.)

Profile-Guided Optimization (PGO) PGO stands for Profile-Guided Optimization and is a feature that Go introduced as a preview in Go 1.20 (released in February 2023) and shipped as ready for general production use in Go 1.21 (released in August 2023). The idea is to capture a CPU profile that records where your program spends most of its CPU time, which you then provide to the Go compiler to give it more data to make better decisions. Most importantly, this way the Go compiler can inline functions much more aggressively than its usual heuristics allow, which does have a measurably positive effect in my series of optimization commits. Another optimization that a PGO profile allows the compiler to do is conditional devirtualization but our TurboPFor code does not use any interfaces. My strategy is to enable PGO before doing any other optimizations, so that we have the full inlining budget available that PGO gives us, and can measure the effect of other commits clearly. Surprisingly, turning on PGO actually decreases our performance (-13% geomean), but a closer investigation reveals that we just got unlucky. Let me explain. Aside from inlining and conditional devirtualization, PGO also influences alignment: The Go compiler sets PCALIGNMAX(64, 31) on the first block of a loop (the loop body ) for all loops in hot functions (per the PGO profile), i.e. Go will insert up to 31 bytes of padding to make the block land on a 64-byte boundary. Documentation like AMD s Software Optimization Guide for the AMD Zen5 Microarchitecture (2024, #58455) explicitly recommends aligning hot loops that way:
[ ] for hot loops, some further knowledge of trade-offs can be helpful. Because the processor can read an aligned 64-byte fetch block every cycle, it is suggested to either align the start of the loop to the beginning of a 64-byte cache line [ ]
Indeed, when compiling with -gcflags=all=-d=alignhot=0 to disable the alignment, performance remains as good as without PGO. How can the padding hurt more than help? The answer is: It s not the padding itself! It s a side-effect of the padding moving instructions to different addresses. In the unlucky arrangement, a macro-fused CMPQ+JGE instruction pair now ends up exactly on a 32-byte boundary. However, the Go compiler ensures fused branch sequences must never cross or end at a 32-byte boundary to fix Intel erratum SKX102 (discussion: Go issue #35881) by inserting NOPs. This NOP padding, unlike the loop alignment padding, is not free; these extra instructions slow down our otherwise dispatch-bound loops. Because the commits after the PGO enabling commit change the code, this unlucky situation is avoided for the rest of the optimization series (by chance).

Reducing memory allocations Memory allocations are quite expensive, at least in comparison to encoding/decoding integers, so I followed my usual strategy of first reducing memory allocations as much as possible. In my goturbopfor teaching decoder, whenever the code needed a scratch buffer, it would allocate it right then and there with make():
// p4dec32 decodes one block of TurboPFor-encoded 32 bit ints
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
    //  
  switch blockType  
  case blockBitpackingExceptions:
    bx, input := input[0], input[1:]
    n := len(output)

    exmap := input
    nex := 0 // number of exceptions
    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        nex++
       
     
    input = input[(n+7)/8:]

    exceptions := make([]uint32, nex)
    input = input[bitunpack32(input, exceptions, bx):]
    input = input[d.bitunpack(input, output, b):]

    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        output[i] += exceptions[0] << b
        exceptions = exceptions[1:]


    return before - len(input)
   
 
The Go compiler can turn make(T, n) calls into stack allocations, if n is known at compile-time. But, in this case nex is not known at compile-time. We can verify that Go calls into the runtime (runtime.makeslice) by dumping the object code (assembly) with source annotated (-S):
% cd ~/go/src/github.com/stapelberg/goturbopfor
% git reset --hard 49b7c05cc61e77f0257568eb73833467714d2b4a
% go test -c  # go1.27.0
% go tool objdump -S goturbopfor.test   perl -nlE 'say if /p4dec32/ .. /^$/'
TEXT github.com/stapelberg/goturbopfor.(*decoder).p4dec32(SB) /home/michael/go/src/github.com/stapelberg/goturbopfor/goturbopfor.go
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
  0x549f60		4c8da42460ffffff	LEAQ 0xffffff60(SP), R12
  0x549f68		4d3b6610		CMPQ R12, 0x10(R14)
  0x549f6c		0f86d9070000		JBE 0x54a74b
  0x549f72		55			PUSHQ BP
  0x549f73		4889e5			MOVQ SP, BP
  0x549f76		4881ec18010000		SUBQ $0x118, SP
  0x549f7d		48899c2430010000	MOVQ BX, 0x130(SP)
  0x549f85		4889b42448010000	MOVQ SI, 0x148(SP)
	if len(output) == 0  
  0x549f8d		4d85c0			TESTQ R8, R8
  0x549f90		0f84a7030000		JE 0x54a33d
  0x549f96		660f1f840000000000	NOPW 0(AX)(AX*1)
  0x549f9f		90			NOPL
[ ]
		exceptions := make([]uint32, nex)
  0x54a4be		488d057bec1700		LEAQ 0x17ec7b(IP), AX
  0x54a4c5		4c89fb			MOVQ R15, BX
  0x54a4c8		4889d9			MOVQ BX, CX
  0x54a4cb		e8f0ddf3ff		CALL runtime.makeslice(SB)
[ ]
An easy speed-up was to avoid allocations through reuse (in goturbopfor). In the DCS pfordec package (with the improved API design), I ended up with a vals [256]uint32 field in the StreamDecoder type, which brings us from 773 Mval/s to 858 Mval/s on the debian-mix:
% benchstat -filter '/impl:go /vals:debian-mix .unit:(Mval/s)' \
  baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pfordec
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
             baseline.txt               bench.txt               
                Mval/s        Mval/s     vs base                
n=2048        1.089k   1%   1.175k   0%   +7.85% (p=0.002 n=6)
n=2039         974.7   0%   1046.0   0%   +7.32% (p=0.002 n=6)
n=160          434.9   1%    513.6   5%  +18.11% (p=0.002 n=6)
geomean        772.9         857.7       +10.98%
Aside from the speed-up, avoiding memory allocations is generally nice in benchmarks because it removes the garbage collector from the equation and makes it less likely that your benchmarks get other processes OOM-killed on the same machine.

Generics for bit width specialization In general, we want to make it easy for the compiler to understand as much as possible about our algorithm. Consider this bitpack implementation:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 
Let s think through what determines the iterations and control flow this function uses:
  1. The number of input values (vals), but not their actual value.
  2. The bit width to pack into (bitWidth).
With a bit of careful rearrangement, we can provide the compiler with both, a fixed number of input values (say, 32), and a bit width, both known at compile time. Why is this worthwhile? Because we can manually unroll the loop, let the compiler eliminate much of the repetition and get much faster compiled code as a result! Let s first fix the number of input values to 32 and rewrite the loop to calculate the position offsets within dest instead of changing dest on each value (with AppendUint32):
func bitpack32Unrolled(dest []byte, vals *[32]uint32, bitWidth int)  
  // only one bounds check for 32 values
  dest = dest[: 4*bitWidth : 4*bitWidth]
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[30] elided for brevity

  // Each loop iteration is 8 lines of Go code, so for 32 input values,
  // bitpack32Unrolled contains 8*32 = 256 lines of code.

  acc  = uint64(vals[31]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // have == 0; for all bitWidths
 
Next, we want to specialize not just for 32 input values, but also for each of the 32 bit widths. Can we do better than hand-copying bitpack32Unrolled 32 times (= 8192 lines of Go code)? Yes, we can use Go generics to help us with the code generation! In Go, array types like [4]byte (not slices like []byte!) contain the length of the array as part of their type, meaning [1]byte (an array of length 1) is a different type than [2]byte. Instead of passing the bit width as a function parameter, we can declare 32 different types (one for each bit width) and recover the bit width (at compile time!) from the type system:
type bitWidthT interface  
  [1]byte   [2]byte   [3]byte   [4]byte   [5]byte  
  [6]byte   [7]byte   [8]byte   [9]byte   [10]byte  
  [11]byte   [12]byte   [13]byte   [14]byte   [15]byte  
  [16]byte   [17]byte   [18]byte   [19]byte   [20]byte  
  [21]byte   [22]byte   [23]byte   [24]byte   [25]byte  
  [26]byte   [27]byte   [28]byte   [29]byte   [30]byte  
  [31]byte   [32]byte
 

func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  var zero T
  bitWidth := len(zero)                  // known at compile time
  dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[31] elided for brevity
 
When we instantiate bitpack32Unrolled[bitWidthT] with all 32 different types ([1]byte, [2]byte, , [32]byte), the compiler substitutes the bitWidthT type parameter and produces 32 copies of the function, which we can find in our compiled executable with names like github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[12]uint8]. The shape of a generic type is based on its memory layout, so a shape for [1]byte must be different than the shape for [2]byte. Because the bitWidth is now known at compile time, the Go compiler can generate close to the optimal machine code for each bit width, which we can confirm using go tool objdump. The code is branchless (after the one bounds check per 32 values) and aside from the loads and stores (from/to memory) consists only of shifts and bit operations, all with constant operands:
% go test -c && go tool objdump -S pforenc.test
[ ]
TEXT github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[28]uint8](SB) /home/michael/dcs/internal/turbopfor/pforenc/bitpackunroll.go
func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  0x660580              55                      PUSHQ BP
  0x660581              4889e5                  MOVQ SP, BP
  0x660584              48895c2418              MOVQ BX, 0x18(SP)
        dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  0x660589              4883ff70                CMPQ DI, $0x70
  0x66058d              0f820b030000            JB 0x66089e
        acc  = uint64(vals[0]&mask) << have
  0x660593              8b06                    MOVL 0(SI), AX
  0x660595              25ffffff0f              ANDL $0xfffffff, AX
        acc  = uint64(vals[1]&mask) << have
  0x66059a              8b4e04                  MOVL 0x4(SI), CX
  0x66059d              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605a3              48c1e11c                SHLQ $0x1c, CX
  0x6605a7              4809c8                  ORQ CX, AX
                acc >>= 32
  0x6605aa              4889c1                  MOVQ AX, CX
  0x6605ad              48c1e820                SHRQ $0x20, AX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605b1              90                      NOPL
        b[0] = byte(v)
  0x6605b2              890b                    MOVL CX, 0(BX)
        acc  = uint64(vals[2]&mask) << have
  0x6605b4              8b4e08                  MOVL 0x8(SI), CX
  0x6605b7              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605bd              48c1e118                SHLQ $0x18, CX
  0x6605c1              4809c1                  ORQ AX, CX
                acc >>= 32
  0x6605c4              4889c8                  MOVQ CX, AX
  0x6605c7              48c1e920                SHRQ $0x20, CX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605cb              90                      NOPL
        b[0] = byte(v)
  0x6605cc              894304                  MOVL AX, 0x4(BX)
Now we need to actually call bitpack32 from the general bitpack function:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  if bitWidth == 0  
    return dest // no payload, sparse block with only exceptions
   
  if len(vals) >= 32  
    size := 4 * bitWidth
    for len(vals) >= 32  
      existing := len(dest)
      dest = slices.Grow(dest, size)[:existing+size]
      bitpack32(dest[existing:] /*append*/, (*[32]uint32)(vals), bitWidth)
      vals = vals[32:]
     
   
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 

func bitpack32(dest []byte, vals *[32]uint32, bitWidth int)  
  switch bitWidth  
  case 1: bitpack32Unrolled[[1]byte](dest, vals)
  case 2: bitpack32Unrolled[[2]byte](dest, vals)
  case 3: bitpack32Unrolled[[3]byte](dest, vals)
  case 4: bitpack32Unrolled[[4]byte](dest, vals)
  case 5: bitpack32Unrolled[[5]byte](dest, vals)
  case 6: bitpack32Unrolled[[6]byte](dest, vals)
  case 7: bitpack32Unrolled[[7]byte](dest, vals)
  case 8: bitpack32Unrolled[[8]byte](dest, vals)
  case 9: bitpack32Unrolled[[9]byte](dest, vals)
  case 10: bitpack32Unrolled[[10]byte](dest, vals)
  case 11: bitpack32Unrolled[[11]byte](dest, vals)
  case 12: bitpack32Unrolled[[12]byte](dest, vals)
  case 13: bitpack32Unrolled[[13]byte](dest, vals)
  case 14: bitpack32Unrolled[[14]byte](dest, vals)
  case 15: bitpack32Unrolled[[15]byte](dest, vals)
  case 16: bitpack32Unrolled[[16]byte](dest, vals)
  case 17: bitpack32Unrolled[[17]byte](dest, vals)
  case 18: bitpack32Unrolled[[18]byte](dest, vals)
  case 19: bitpack32Unrolled[[19]byte](dest, vals)
  case 20: bitpack32Unrolled[[20]byte](dest, vals)
  case 21: bitpack32Unrolled[[21]byte](dest, vals)
  case 22: bitpack32Unrolled[[22]byte](dest, vals)
  case 23: bitpack32Unrolled[[23]byte](dest, vals)
  case 24: bitpack32Unrolled[[24]byte](dest, vals)
  case 25: bitpack32Unrolled[[25]byte](dest, vals)
  case 26: bitpack32Unrolled[[26]byte](dest, vals)
  case 27: bitpack32Unrolled[[27]byte](dest, vals)
  case 28: bitpack32Unrolled[[28]byte](dest, vals)
  case 29: bitpack32Unrolled[[29]byte](dest, vals)
  case 30: bitpack32Unrolled[[30]byte](dest, vals)
  case 31: bitpack32Unrolled[[31]byte](dest, vals)
  case 32: bitpack32Unrolled[[32]byte](dest, vals)
   
 
Encoding remainder blocks is quite a bit faster (full blocks use the vertical layout anyway):
% benchstat -filter '/impl:go /n:160 .unit:(Mval/s)' baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pforenc
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
                           baseline.txt               bench.txt               
                              Mval/s        Mval/s     vs base                
vals=bitpacking-bw1          751.2   3%   1120.5   0%  +49.15% (p=0.002 n=6)
vals=bitpacking-bw2          716.8   2%   1176.0   0%  +64.07% (p=0.002 n=6)
vals=bitpacking-bw7          700.0   1%   1078.5   0%  +54.08% (p=0.002 n=6)
vals=bitpacking-bw1-exc      524.8   1%    736.8   0%  +40.40% (p=0.002 n=6)
vals=bitpacking-bw2-exc      543.7   1%    758.2   0%  +39.46% (p=0.002 n=6)
vals=bitpacking-bw7-exc      566.7   1%    787.7   0%  +38.99% (p=0.002 n=6)
vals=bitpacking-vb-exc       442.6   1%    616.5   0%  +39.29% (p=0.002 n=6)
vals=sparse-exc              532.4   0%    787.8   0%  +47.97% (p=0.002 n=6)
vals=sparse-vb-exc           408.9   1%    597.8   0%  +46.20% (p=0.002 n=6)
vals=debian-mix              559.5   0%    783.8   9%  +40.09% (p=0.002 n=6)
This performance win comes at the cost of binary size increase. In this case, the .text section (executable code) grows by about 20 KB and the .gopclntab section grows by another 26 KB. Definitely a price I am very willing to pay, but the case might not be as clear in all circumstances.

Optimization: Bigger strides with SIMD Even without reaching for SIMD instructions, a TurboPFor implementation can be made faster by making it work bigger strides. Take this code from the goturbopfor teaching decoder which counts the number of exceptions by checking if each value s bit is set in the exception bitmap:
case blockBitpackingExceptions:
  bx, input := input[0], input[1:]
  n := len(output)

  exmap, input := input, input[(n+7)/8:]
  nex := 0 // number of exceptions
  for i := range n  
    if exmap[i/8]&(1<<uint(i%8)) != 0  
      nex++
     
   
  exceptions := d.scratch[:nex]
We can use the bits.OnesCount64 functions to count ones bits in the exception bitmap, 64 values at a time. For remainder blocks, the rest is processed 8 values (1 byte) at a time:
i := 0
for ; i+8 <= n/8; i += 8  
  xm8 := binary.LittleEndian.Uint64(exmap[i:])
  nex += bits.OnesCount64(xm8)
 
for ; i < (n+7)/8; i++  
  xmb := exmap[i]
  // Clear the bits which do not belong to the exception map:
  if rem := n - i*8; rem < 8  
    xmb &= 1<<rem - 1
   
  // Go compiles OnesCount32 into an intrinsic,
  // but not OnesCount8, so we convert to uint32:
  nex += bits.OnesCount32(uint32(xmb))
 
OnesCount64 uses a 64-bit register. For comparison, AVX2 SIMD instructions use 256-bit registers (= 8 uint32) and AVX512 SIMD instructions use 512-bit registers. In the following sections, we will first set up our build tags for conditional compilation to use a trivial SIMD instruction, then walk through an AVX2 and AVX512 SIMD kernel.

SIMD build tags Let s assume we have the following scalar code: constant.go:
package pfordec

func fillConstant(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
To increase throughput, we can use AVX2 instructions if they are available on the CPU on which the program runs, i.e. using runtime dispatch. We ll first rename fillConstant to fillConstantScalar (it s now the fallback path): constant.go:
package pfordec

func fillConstantScalar(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
Next, we ll supply two different implementations (constant_nosimd.go and constant_amd64.go), the latter of which is selected when compiling for GOARCH=amd64 with GOEXPERIMENT=simd (the latter will hopefully be dropped in a later version of Go). The nosimd variant just dispatches to the fillConstantScalar, which will likely be inlined:
//go:build !goexperiment.simd   !amd64

package pfordec

func fillConstant(output []uint32, val uint32)  
  fillConstantScalar(output, val)
 
The constant_amd64.go variant assigns the hasAVX2 global variable by doing a CPUID check and then jumps to the scalar fallback if !hasAVX2, i.e. the CPU is too old:
//go:build goexperiment.simd && amd64

package pfordec

import "simd/archsimd"

var hasAVX2 = archsimd.X86.AVX2()

func fillConstant(output []uint32, val uint32)  
  if !hasAVX2  
    fillConstantScalar(output, val)
    return
   
  val8 := archsimd.BroadcastUint32x8(val)
  i := 0
  for ; i+8 <= len(output); i += 8  
    val8.StoreArray((*[8]uint32)(output[i : i+8]))
   
  // use the scalar implementation for the last <= 7 elements
  fillConstantScalar(output[i:], val)
 
We can go one step further by conditionally compiling const hasAVX2 = true when GOAMD64 is set to v3 or higher (i.e. the amd64.v3 build tag is set). As a practical example from Debian Code Search, we currently need the following checks / dispatches:
code function vector instruction set GOAMD64
encoder bitpack256v AVX2 GOAMD64=v3
encoder exbitmap AVX512 GOAMD64=v4
encoder scan AVX512+VBMI+GFNI+BITALG n/a
decoder bitunpack AVX2 GOAMD64=v3
decoder bitunpack256v32 AVX2 GOAMD64=v3
decoder bitunpack256v32Ex AVX512 GOAMD64=v4
In DCS, the effect is measurably positive, but small.

The 256 uint32 vertical layout First, here is the layout explanation from my 2019 TurboPFor analysis blog post:
In regular (non-SIMD) bitpacking, integers are stored on disk one after the other, padded to a full byte, as a byte is the smallest addressable unit when reading data from disk. For example, if you bitpack only one 3 bit int, you will end up with 5 bits of padding. SIMD bitpacking works like regular bitpacking, but processes 8 uint32 little-endian values at the same time, leveraging the AVX instruction set. The following illustration shows the order in which 3-bit integers are decoded from disk:
The scalar implementation uses an array of 8 uint64 to process 8 values at a time:
func bitunpack256v32(input []byte, dest []uint32, bitWidth int) (read int)  
  mask := uint64(1)<<bitWidth - 1
  orig := len(input)
  var bits uint
  var acc [8]uint64 // accumulator: current+next bits
  for op := 0; op < len(dest);  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      for i := range 8  
        acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
        input = input[4:]
       
      bits += 32
     
    for i := range 8  
      dest[op] = uint32(acc[i] & mask)
      op++
      acc[i] >>= bitWidth
     
    bits -= uint(bitWidth)
   
  return orig - len(input)
 
The SIMD version also processes 8 values, but without a for i := range 8 loop! One difference is that we no longer have the luxury of using uint64 for acc (holding rest and current bits); because AVX2 registers only fit 8 uint32 (not 8 uint64). Instead, we split acc into rest8 and cur8.
func bitunpack256v32(fullinput []byte, fulldest []uint32, bitWidth int) (read int)  
  dest := fulldest[:256]
  if bitWidth == 0  
    clear(dest)
    return 0
   
  n := 32 * int(bitWidth)
  input := fullinput[:n] // tell the Go compiler how long the input is
  mask8 := archsimd.BroadcastUint32x8(uint32(1)<<bitWidth - 1)
  bitWidth8 := archsimd.BroadcastUint32x8(uint32(bitWidth))
  var bits uint
  pos := 0
  // var acc [8]uint64
  var rest8 archsimd.Uint32x8
  var cur8 archsimd.Uint32x8
  for op := 0; op < 256; op += 8  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      // acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
      next := archsimd.LoadUint8x32(input[pos : pos+32]).ReshapeToUint32s()
      pos += 32  // input = input[4:]
      cur8 = rest8.Or(next.ShiftAllLeft(uint64(bits)))
      // acc[i] >>= bitWidth
      rest8 = next.ShiftAllRight(uint64(uint(bitWidth) - bits))
      bits += 32
      else  
      cur8 = rest8
      // acc[i] >>= bitWidth
      rest8 = rest8.ShiftRight(bitWidth8)
     
    // dest[op] = uint32(acc[i] & mask)
    cur8.And(mask8).Store(dest[op : op+8])
    bits -= uint(bitWidth)
   
  return n
 
The SIMD version benchmarks about 3x as fast as the scalar version. Another significant speedup is to use generics for bit width specialization for this SIMD kernel so that bitWidth becomes a compile-time constant and the compiler can generate better code.

Positional Popcount For my TurboPFor encoder, I implemented the same techniques as described above:
  1. Bitpack full blocks with SIMD (AVX2)
  2. Gather exceptions using SIMD (AVX512)
  3. Use generics to specialize per bit width
These changes are sufficient to roughly match the cgo performance, but then Claude Fable 5 found another 2x speed-up on top of that! The key observation is that once encoding blocks is fast, the preceding step of scanning the input values to decide which block type to use becomes the bottleneck. Here is the encoder s main encode function, which first does one pass over the input values (scan) and then prices all different block types at all relevant bit widths (requires fast access to the scan histogram):
func (be *BlockEncoder) encode(dest []byte, vals []uint32, layout blockLayout) []byte  
  var stats stats
  scan(&stats, vals) // gathers statistics from every value in vals
  bitWidth := bits.Len32(stats.or)
  if stats.or == stats.and  
    return be.encodeConstant(dest, vals, bitWidth)
   
  n := len(vals)
  // bitpacking is the default, unless we find a more efficient block type.
  bestType := blockBitpacking
  bestB := bitWidth
  best := priceBitpack(n, bitWidth, layout)

  // Walk from high bitWidths to low: to break ties, we prefer
  // the encoding with fewer exceptions (for faster decoding).
  for b := bitWidth - 1; b >= 0; b--   // up to 32 iterations
    nex := int(stats.cnt[b])
    size := priceBitpackExceptions(n, b, bitWidth, nex, layout)
    if size < best  
      bestType = blockBitpackingExceptions
      bestB = b
      best = size
     
    // Over-approximate the number of VB bytes.
    vb := nex + // exceptions using 1, 2, 3, 4, or 5 VB bytes
      int(stats.cnt[b+7]+ // exceptions using 2, 3, 4, or 5 VB bytes
        stats.cnt[b+14]+ // exceptions using 3, 4, or 5 VB bytes
        stats.cnt[b+19]+ // exceptions using 4 or 5 VB bytes
        stats.cnt[b+24]) // exceptions using 5 VB bytes
    size = headerBytes + headerExBytes + payloadBytes(n, b, layout) + vb + nex
    if size < best  
      bestType = blockBitpackingVBExceptions
      bestB = b
      best = size
     
   
  switch bestType  
  case blockBitpacking:
    return be.encodeBitpack(dest, vals, layout, bitWidth)
  case blockBitpackingExceptions:
    return be.encodeBitpackExc(dest, vals, layout, bestB, bitWidth-bestB)
  case blockBitpackingVBExceptions:
    return be.encodeBitpackVBExc(dest, vals, layout, bestB, int(stats.cnt[bestB]))
  default:
    panic("BUG: bestType not implemented")
   
 
I ll show you a slightly shortened version of scan, the function which is the bottleneck:
type stats struct  
  // cnt[n] = how many values where bits.Len32(val)>n,
  // i.e. how many exceptions are required for bitWidth=n.
  // Padded so that cnt[b+24] is always in bounds.
  cnt [32 + 24]uint32
 

func scan(output *stats, vals []uint32)  
  for _, val := range vals  
    for b := range bits.Len32(val)  
      output.cnt[b]++ // b bits are not enough to store val


Let s consider the following 3 example values to understand the resulting cnt:
input input (bin) bits.Len32
23 0b0000010111 5
5 0b0000000101 3
666 0b1010011010 10
The resulting cnt exception count histogram would contain (cnt shortened to c):
c[0] c[1] c[2] c[3] c[4] c[5] c[6] c[7] c[8] c[9] c[10]
3 3 3 2 2 1 1 1 1 1 0
In words, this means that at bit width 10, we could encode all the values without any exceptions. But most values do not need 10 bits, so a bit width of 5 would be more efficient, but requires storing one exception. Encoding at bit width 4 requires 2 exceptions, and so on. The scan function above is intentionally kept simple for illustration. We can make it faster by moving the per-bit-width loop outside the per-element loop. The fast version still needs about 12 instructions per value. With SIMD, we can reduce this to by 8x to only 1.5 instructions per value!

The trick: smear masks enable positional popcount The trick is to turn each input value into its smear mask (imagine taking the first 1 bit and smearing it across the remaining positions). Here are the smear masks for our example:
input input (bin) bits.Len32 smear mask
23 0b0000010111 5 0b0000011111
5 0b0000000101 3 0b0000000111
666 0b1010011010 10 0b1111111111
Turning a value into its smear mask is computationally cheap: Go implements BitLen(x) (functions like bits.Len32) by calculating 32 - LZCNT(x). We can calculate the smear mask of a value with ^uint32(0) >> LZCNT(x), i.e. starting with a 32-one-bits mask and shifting it by the number of leading zeros. Now, to obtain e.g. cnt[4], we can count the 1 bits at bit position 4 of all input values. The POPCNT instruction counts bits very efficiently, but it counts one bits within a register, so it counts rows, not columns. Counting columns is called Positional Population Count. I found the following papers that describe positional popcount with SIMD:

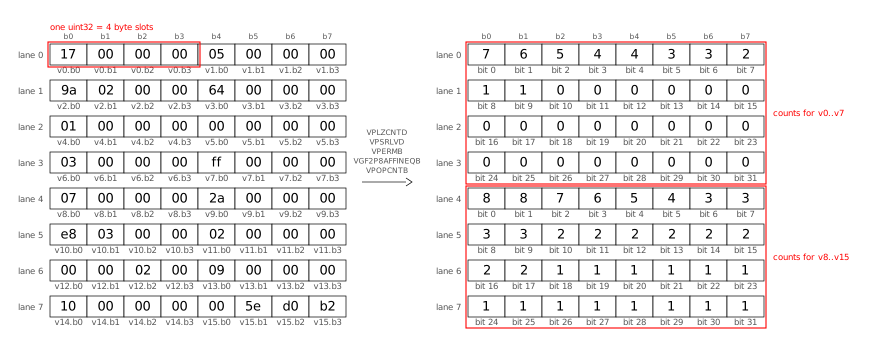
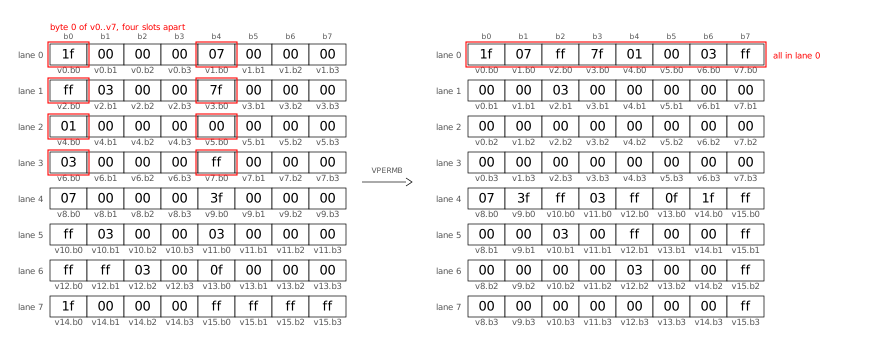
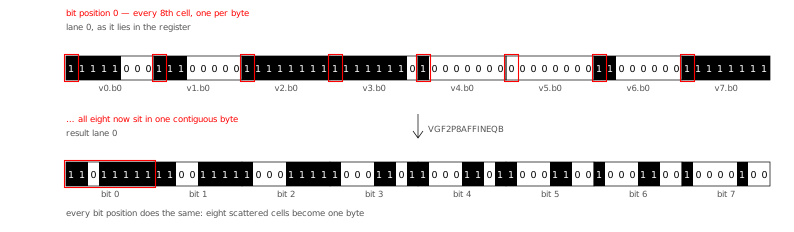
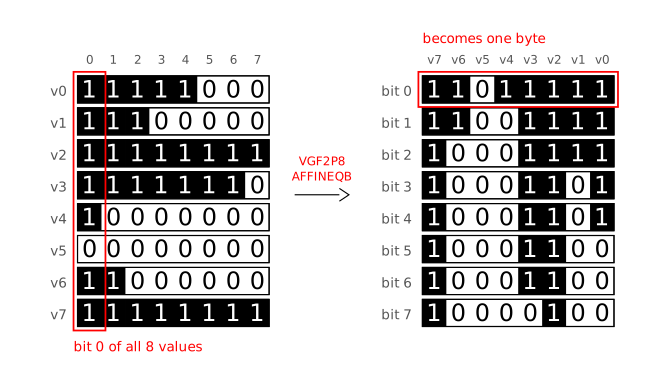
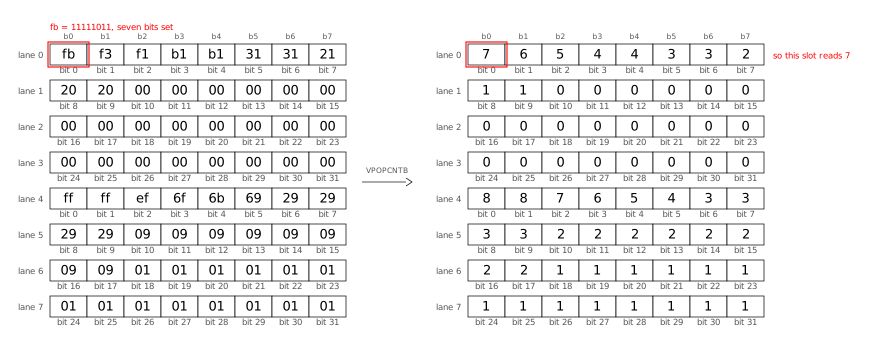
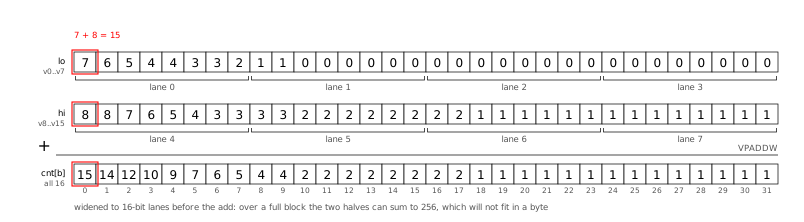
Positional Popcount: a visual explanation To understand the AVX512 implementation of positional popcount, I found it most helpful to visualize an AVX512 register (512 bits, i.e. 64 bytes). The graphic below uses the Uint64x8 layout, meaning it divides the register into 8 lanes of 64 bits (= 8 bytes) each. This illustration shows the whole process: how uint32s are loaded into an AVX512 register (all 4 of its bytes, in sequence) and where we end up, i.e. the 32 positional popcounts: Let s break down this process into its individual steps. First, we turn each loaded value into its smear mask as explained above. The VPOPCNTB vector instruction calculates POPCNT (1 byte) of 64 bytes at once, but first we need to shuffle the bytes inside the register: in load order, we have a full uint32 (4 bytes), followed by another uint32, per lane. First, we permute the bytes (VPERMB) such that all the first bytes of each value end up in one lane ( transpose the bytes ): Next, we transpose the bits using the GF2P8AFFINEQB instruction, which sounds scary but turns out to be quite flexible for bit manipulation of all kinds. The GF2P8AFFINEQB instruction is also the star of the show in Go s Green Tea Garbage Collector (2025). Here is the bit transpose, shown in the AVX512 register layout (see below for a different layout): I found it easier to understand the transpose step when arranging the 8 bytes of lane 0 from top-to-bottom (instead of left-to-right), because then it looks like a 90 degree clockwise rotation: Now we can use VPOPCNTB to count the bits in all 64 bytes at once: After all loop iterations (processing 16 values each) are done, we add the two groups (first 8 values, second 8 values) to obtain the 32 exception counts:

Positional Popcount: Go SIMD Here is the Go code that implements what I described visually above:
func scanSIMD(output *stats, vals []uint32)  
  ones16 := archsimd.BroadcastUint32x16(^uint32(0)) // 16 32-one-bits masks
  shuffle := archsimd.LoadUint8x64Array(&scanShuffle)
  units := archsimd.LoadUint8x64Array(&scanUnits)
  var acc archsimd.Uint8x64
  idx := 0
  for ; idx+16 <= len(vals); idx += 16  
    v := archsimd.LoadUint32x16(vals[idx : idx+16])
    // Replace all values with their smear masks.
    smear := ones16.ShiftRight(v.LeadingZeros()).ReshapeToUint8s()
    // Transpose: shuffle the bytes, then transpose the bits.
    matrices := smear.Permute(shuffle).ReshapeToUint64s()
    transposed := units.GaloisFieldAffineTransform(matrices, 0)
    // Popcount 64 bytes at once into the accumulator.
    acc = acc.Add(transposed.OnesCount())
   
  // Store the accumulator into output.cnt:
  // Widen the two groups of byte counts to uint16 lanes (so that
  // 128+128 = 256 fits), fold them into cnt[b] for b=0..31,
  // then widen again to the uint32 lanes of output.cnt.
  sum := acc.GetLo().ExtendToUint16().Add(acc.GetHi().ExtendToUint16())
  sum.GetLo().ExtendToUint32().Store(output.cnt[0:16])
  sum.GetHi().ExtendToUint32().Store(output.cnt[16:32])
  // scalar tail for the 0..15 remaining values
  for _, val := range vals[idx:]  
    for b := range bits.Len32(val)  
      output.cnt[b]++


Have a look at the commit introducing positional popcount to DCS for the full code (including shuffle tables and ISA checks) as well as the detailed benchmark results.

Go even faster? The SIMD optimizations I showed above beat the cgo TurboPFor library that Debian Code Search used before. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. Could we make my Go TurboPFor implementation even faster, to truly match the C speed? Yes! But also no. Let me explain:
  1. We could use more SIMD instructions to remove all code that still processes one value at a time. For example, in my encoder s encodeBitpackVBExc function. Or we could price all bit widths concurrently in encode. Or in the decoder s exception apply code path.
    But all of these SIMD instructions make understanding (and changing) the code harder, so I am cautious regarding which ones I introduce.
  2. A big part of the performance gap is due to Go s bounds checks. While it costs performance, bounds checking is great for safety, so I will not turn off bounds checking. The Go compiler eliminates a number of bounds checks when it understands it s safe to do so. One optimization avenue could be to make the prove pass in the Go compiler smarter to eliminate more bounds checks.
  3. When doing mid-stack inlining (proposal #19348) (2017), Go sometimes needs to put NOP instructions into the binary so that it can attach inlining markers. For dispatch-bound functions, these extra NOPs can measurable slow down execution.
  4. The Go compiler currently allows specifying the architecture (GOARCH=amd64) and microarchitecture (GOAMD64=v3), but not a specific CPU architecture (like AMD Zen 4). Therefore, CPU-specific workarounds for one vendor affect all the generated code. The specific one I encountered in my code is that the Go compiler emits XORL CX,CX before every POPCNT to break a false-output-dependency from the Intel Sandy Bridge Skylake era, which is unnecessary on AMD Zen CPUs.
    I suspect that Go intentionally does not offer this level of customizability.
  5. After all of the above points are addressed, what remains is better code generation in specific cases. To illustrate what I mean, consider the example of incrementing a loop variable, where Go re-derives an index every time:
    Go: POPCNTL; ADDQ DI,CX; LEAQ (base)(CX*4) (3 instructions)
    clang: popcnt; lea rax,[rax+4*rdi] (2 instructions)
    Depending on the specific case, improving the compiler might be easy or prohibitively complex. Often, such improvements are hard to measure conclusively.

Conclusion Go s SIMD support makes available in Go code without having to resort to cgo or assembly a powerful part of modern CPUs which allows speeding up the kind of computation that TurboPFor needs by an order of magnitude! I found it very valuable to use a coding agent (Claude Code, with Opus 5 and Fable 5 in this case) to help with the many tedious parts of such performance work (and still it took me weeks!). The LLM can read objdump output much faster than I can, can see patterns and correlations I might never identify, never becomes frustrated after a compiler error or runtime panic, and never runs out of patience to run one more experiment, as long as I give it measurable and reachable goals. The performance of the SIMD code which one can get from the Go compiler is pretty close to what a good C compiler like clang provides. The CPU performance counters show value decoding speeds of 7 instructions/cycle (IPC) on a machine where the maximum is 8 IPC. To me, SIMD support is a very welcome addition to Go.

30 June 2026

Utkarsh Gupta: FOSS Activities in June 2026

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
  • Leading the DebConf Bursary team along with PEB.
    • This took most of my Debian time this month but we ve been able to wrap that work now.
    • Got back to all the tickets on Zammad, too.
  • Assisted a few folks in getting their patches submitted via Salsa.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021. Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
  • Continued to push for infrastructure improvements:
    • Charming.
    • Artifact signing.
    • Reorganizing cdimage.
    • And so on.
  • Successfully released 26.10 Snapshot 2!
    • We landed a breaking change in the directory structure.
    • whihc had consequences on the rsync, being run by the sysadmins.
      • The 30 GB rsync failed because of the load on the system and it resulted in things blowing up. Yay. Stress-testing the shit out of our infra. :)
      • We got it back under control in the next few days but oh wow, what a journey to get there.
  • Assisted a bunch of folks with my Archive Admin and Release team hats to:
    • Helped in archive opening tasks.
    • Promoting/demoting binaries to/from main.
    • Taking care of package removals and so on.
    • Reviewed the NEW queue.
  • Reviewed quite a lot of MPs, specs, and other people s work.
  • Mentoring, coaching, and leading the Release Management team.

Debian (E)LTS
This month I have worked 15 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things:

Released Security Updates

Work in Progress

Other Activities
  • [LTS] Emilio pointed out that the gst-plugins-ugly1.0 binaries were still not fully released, so I ran dcut migrate to fully release them. The DLA had gone out earlier.
  • [ELTS] Did some more work on ruby-rack - a lot of new CVEs have opened up and, whilst I made some progress, Santiago let me know that ruby-rack is no longer supported and so it ll be removed from the ela-needed list.
  • [E/LTS] Set up the security-tracker and a few other things on the new machine, and debugged the git repository size madness. Sent a summary here.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
  • [E/LTS] Attended the monthly LTS meeting on Jitsi. Meeting notes here.

Until next time.
:wq for today.

30 March 2026

Utkarsh Gupta: FOSS Activites in March 2026

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
  • A quick exchange with Xavier about node-lodash fixes for stable releases.
  • Uploaded ruby-rack to CVE-2026-25500 & CVE-2026-22860 to sid, trixie, and bookworm.
  • Started to work on the DebConf Bursary team along with PEB.
  • Assited a few folks in getting their patches submitted via Salsa.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021. Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
  • Successfully released 26.04 LTS Beta!
  • Worked further on the whole artifact signing story for cdimage.
  • Assisted a bunch of folks with my Archive Admin and Release team hats to:
    • Review and grant FFes.
    • Coordinating weekly syncs.
    • Promoting/demoting binaries to/from main.
    • Taking care of package removals and so on.
  • Was pretty occupied with the new release processs architecture and design.
  • Preparing for the 26.04 LTS final release.

Debian (E)LTS
This month I have worked 50 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things:

Released Security Updates

Work in Progress
  • knot-resolver: Affected by CVE-2023-26249, CVE-2023-46317, and CVE-2022-40188, leading to Denial of Service.
  • node-lodash: Affected by CVE-2025-13465, prototype pollution in the baseUnset function.
    • [stable]: Xavier from the JS team ACK d the patch. The trixie and bookworm uploads will follow.
    • [LTS]: The bullseye test and upload will follow in April once the stable uploads are in and ACK d by the SRMs.
  • vlc: Affected by CVE-2025-51602, an out-of-bounds read and denial of service via a crafted 0x01 response from an MMS server.
    • [LTS]: 3.0.23 backport is ready but not tested. I ll get this over the line in March.
    • [ELTS]: 3.0.23 backport is ready but not very clean. Would like to complete LTS and get back to this.

Other Activities
  • [ELTS] Continued to review ruby-rack for ELTS it has since received about 13 new CVEs, making it even more chaotic. Might consider releasing in batches.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
  • [E/LTS] Attended the monthly LTS meeting on IRC. Summary here.
  • [Other] Spent quite some time debugging a bug in debusine. Filed https://salsa.debian.org/freexian-team/debusine/-/issues/1412 for the same. Have worked on a preliminary patch but would like to submit something for Colin to review. Will follow up in April.

Until next time.
:wq for today.

5 January 2026

Vincent Bernat: Using eBPF to load-balance traffic across UDP sockets with Go

Akvorado collects sFlow and IPFIX flows over UDP. Because UDP does not retransmit lost packets, it needs to process them quickly. Akvorado runs several workers listening to the same port. The kernel should load-balance received packets fairly between these workers. However, this does not work as expected. A couple of workers exhibit high packet loss:
$ curl -s 127.0.0.1:8080/api/v0/inlet/metrics \
>   sed -n s/akvorado_inlet_flow_input_udp_in_dropped//p
packets_total listener="0.0.0.0:2055",worker="0"  0
packets_total listener="0.0.0.0:2055",worker="1"  0
packets_total listener="0.0.0.0:2055",worker="2"  0
packets_total listener="0.0.0.0:2055",worker="3"  1.614933572278264e+15
packets_total listener="0.0.0.0:2055",worker="4"  0
packets_total listener="0.0.0.0:2055",worker="5"  0
packets_total listener="0.0.0.0:2055",worker="6"  9.59964121598348e+14
packets_total listener="0.0.0.0:2055",worker="7"  0
eBPF can help by implementing an alternate balancing algorithm.

Options for load-balancing There are three methods to load-balance UDP packets across workers:
  1. One worker receives the packets and dispatches them to the other workers.
  2. All workers share the same socket.
  3. Each worker has its own socket, listening to the same port, with the SO_REUSEPORT socket option.

SO_REUSEPORT option Tom Hebert added the SO_REUSEPORT socket option in Linux 3.9. The cover letter for his patch series explains why this new option is better than the two existing ones from a performance point of view:
SO_REUSEPORT allows multiple listener sockets to be bound to the same port. [ ] Received packets are distributed to multiple sockets bound to the same port using a 4-tuple hash. The motivating case for SO_RESUSEPORT in TCP would be something like a web server binding to port 80 running with multiple threads, where each thread might have it s own listener socket. This could be done as an alternative to other models:
  1. have one listener thread which dispatches completed connections to workers, or
  2. accept on a single listener socket from multiple threads.
In case #1, the listener thread can easily become the bottleneck with high connection turn-over rate. In case #2, the proportion of connections accepted per thread tends to be uneven under high connection load. [ ] We have seen the disproportion to be as high as 3:1 ratio between thread accepting most connections and the one accepting the fewest. With SO_REUSEPORT the distribution is uniform. The motivating case for SO_REUSEPORT in UDP would be something like a DNS server. An alternative would be to receive on the same socket from multiple threads. As in the case of TCP, the load across these threads tends to be disproportionate and we also see a lot of contection on the socket lock.
Akvorado uses the SO_REUSEPORT option to dispatch the packets across the workers. However, because the distribution uses a 4-tuple hash, a single socket handles all the flows from one exporter.

SO_ATTACH_REUSEPORT_EBPF option In Linux 4.5, Craig Gallek added the SO_ATTACH_REUSEPORT_EBPF option to attach an eBPF program to select the target UDP socket. In Linux 4.6, he extended it to support TCP. The socket(7) manual page documents this mechanism:1
The BPF program must return an index between 0 and N-1 representing the socket which should receive the packet (where N is the number of sockets in the group). If the BPF program returns an invalid index, socket selection will fall back to the plain SO_REUSEPORT mechanism.
In Linux 4.19, Martin KaFai Lau added the BPF_PROG_TYPE_SK_REUSEPORT program type. Such an eBPF program selects the socket from a BPF_MAP_TYPE_REUSEPORT_ARRAY map instead. This new approach is more reliable when switching target sockets from one instance to another for example, when upgrading, a new instance can add its sockets and remove the old ones.

Load-balancing with eBPF and Go Altering the load-balancing algorithm for a group of sockets requires two steps:
  1. write and compile an eBPF program in C,2 and
  2. load it and attach it in Go.

eBPF program in C A simple load-balancing algorithm is to randomly choose the destination socket. The kernel provides the bpf_get_prandom_u32() helper function to get a pseudo-random number.
volatile const __u32 num_sockets; //  
struct  
    __uint(type, BPF_MAP_TYPE_REUSEPORT_SOCKARRAY);
    __type(key, __u32);
    __type(value, __u64);
    __uint(max_entries, 256);
  socket_map SEC(".maps"); //  
SEC("sk_reuseport")
int reuseport_balance_prog(struct sk_reuseport_md *reuse_md)
 
    __u32 index = bpf_get_prandom_u32() % num_sockets; //  
    bpf_sk_select_reuseport(reuse_md, &socket_map, &index, 0); //  
    return SK_PASS; //  
 
char _license[] SEC("license") = "GPL";
In , we declare a volatile constant for the number of sockets in the group. We will initialize this constant before loading the eBPF program into the kernel. In , we define the socket map. We will populate it with the socket file descriptors. In , we randomly select the index of the target socket.3 In , we invoke the bpf_sk_select_reuseport() helper to record our decision. Finally, in , we accept the packet.

Header files If you compile the C source with clang, you get errors due to missing headers. The recommended way to solve this is to generate a vmlinux.h file with bpftool:
$ bpftool btf dump file /sys/kernel/btf/vmlinux format c > vmlinux.h
Then, include the following headers:4
#include "vmlinux.h"
#include <bpf/bpf_helpers.h>
For my 6.17 kernel, the generated vmlinux.h is quite big: 2.7 MiB. Moreover, bpf/bpf_helpers.h is shipped with libbpf. This adds another dependency for users. As the eBPF program is quite small, I prefer to put the strict minimum in vmlinux.h by cherry-picking the definitions I need.

Compilation The eBPF Library for Go ships bpf2go, a tool to compile eBPF programs and to generate some scaffolding code. We create a gen.go file with the following content:
package main
//go:generate go tool bpf2go -tags linux reuseport reuseport_kern.c
After running go generate ./..., we can inspect the resulting objects with readelf and llvm-objdump:
$ readelf -S reuseport_bpfeb.o
There are 14 section headers, starting at offset 0x840:
  [Nr] Name              Type             Address           Offset
[ ]
  [ 3] sk_reuseport      PROGBITS         0000000000000000  00000040
  [ 6] .maps             PROGBITS         0000000000000000  000000c8
  [ 7] license           PROGBITS         0000000000000000  000000e8
[ ]
$ llvm-objdump -S reuseport_bpfeb.o
reuseport_bpfeb.o:  file format elf64-bpf
Disassembly of section sk_reuseport:
0000000000000000 <reuseport_balance_prog>:
;  
       0:   bf 61 00 00 00 00 00 00     r6 = r1
;     __u32 index = bpf_get_prandom_u32() % num_sockets;
       1:   85 00 00 00 00 00 00 07     call 0x7
[ ]

Usage from Go Let s set up 10 workers listening to the same port.5 Each socket enables the SO_REUSEPORT option before binding:6
var (
    err error
    fds []uintptr
    conns []*net.UDPConn
)
workers := 10
listenAddr := "127.0.0.1:0"
listenConfig := net.ListenConfig 
    Control: func(_, _ string, c syscall.RawConn) error  
        c.Control(func(fd uintptr)  
            err = unix.SetsockoptInt(int(fd), unix.SOL_SOCKET, unix.SO_REUSEPORT, 1)
            fds = append(fds, fd)
         )
        return err
     ,
 
for range workers  
    pconn, err := listenConfig.ListenPacket(t.Context(), "udp", listenAddr)
    if err != nil  
        t.Fatalf("ListenPacket() error:\n%+v", err)
     
    udpConn := pconn.(*net.UDPConn)
    listenAddr = udpConn.LocalAddr().String()
    conns = append(conns, udpConn)
 
The second step is to load the eBPF program, initialize the num_sockets variable, populate the socket map, and attach the program to the first socket.7
// Load the eBPF collection.
spec, err := loadReuseport()
if err != nil  
    t.Fatalf("loadVariables() error:\n%+v", err)
 
// Set "num_sockets" global variable to the number of file descriptors we will register
if err := spec.Variables["num_sockets"].Set(uint32(len(fds))); err != nil  
    t.Fatalf("NumSockets.Set() error:\n%+v", err)
 
// Load the map and the program into the kernel.
var objs reuseportObjects
if err := spec.LoadAndAssign(&objs, nil); err != nil  
    t.Fatalf("loadReuseportObjects() error:\n%+v", err)
 
t.Cleanup(func()   objs.Close()  )
// Assign the file descriptors to the socket map.
for worker, fd := range fds  
    if err := objs.reuseportMaps.SocketMap.Put(uint32(worker), uint64(fd)); err != nil  
        t.Fatalf("SocketMap.Put() error:\n%+v", err)
     
 
// Attach the eBPF program to the first socket.
socketFD := int(fds[0])
progFD := objs.reuseportPrograms.ReuseportBalanceProg.FD()
if err := unix.SetsockoptInt(socketFD, unix.SOL_SOCKET, unix.SO_ATTACH_REUSEPORT_EBPF, progFD); err != nil  
    t.Fatalf("SetsockoptInt() error:\n%+v", err)
 
We are now ready to process incoming packets. Each worker is a Go routine incrementing a counter for each received packet:8
var wg sync.WaitGroup
receivedPackets := make([]int, workers)
for worker := range workers  
    conn := conns[worker]
    packets := &receivedPackets[worker]
    wg.Go(func()  
        payload := make([]byte, 9000)
        for  
            if _, err := conn.Read(payload); err != nil  
                if errors.Is(err, net.ErrClosed)  
                    return
                 
                t.Logf("Read() error:\n%+v", err)
             
            *packets++
         
     )
 
Let s send 1000 packets:
sentPackets := 1000
conn, err := net.Dial("udp", conns[0].LocalAddr().String())
if err != nil  
    t.Fatalf("Dial() error:\n%+v", err)
 
defer conn.Close()
for range sentPackets  
    if _, err := conn.Write([]byte("hello world!")); err != nil  
        t.Fatalf("Write() error:\n%+v", err)
     
 
If we print the content of the receivedPackets array, we can check the balancing works as expected, with each worker getting about 100 packets:
=== RUN   TestUDPWorkerBalancing
    balancing_test.go:84: receivedPackets[0] = 107
    balancing_test.go:84: receivedPackets[1] = 92
    balancing_test.go:84: receivedPackets[2] = 99
    balancing_test.go:84: receivedPackets[3] = 105
    balancing_test.go:84: receivedPackets[4] = 107
    balancing_test.go:84: receivedPackets[5] = 96
    balancing_test.go:84: receivedPackets[6] = 102
    balancing_test.go:84: receivedPackets[7] = 105
    balancing_test.go:84: receivedPackets[8] = 99
    balancing_test.go:84: receivedPackets[9] = 88
    balancing_test.go:91: receivedPackets = 1000
    balancing_test.go:92: sentPackets     = 1000

Graceful restart You can also use SO_ATTACH_REUSEPORT_EBPF to gracefully restart an application. A new instance of the application binds to the same address and prepare its own version of the socket map. Once it attaches the eBPF program to the first socket, the kernel steers incoming packets to this new instance. The old instance needs to drain the already received packets before shutting down. To check we are not losing any packet, we spawn a Go routine to send as many packets as possible:
sentPackets := 0
notSentPackets := 0
done := make(chan bool)
conn, err := net.Dial("udp", conns1[0].LocalAddr().String())
if err != nil  
    t.Fatalf("Dial() error:\n%+v", err)
 
defer conn.Close()
go func()  
    for  
        if _, err := conn.Write([]byte("hello world!")); err != nil  
            notSentPackets++
          else  
            sentPackets++
         
        select  
        case <-done:
            return
        default:
         
     
 ()
Then, while the Go routine runs, we start the second set of workers. Once they are running, they start receiving packets. If we gracefully stop the initial set of workers, not a single packet is lost!9
=== RUN   TestGracefulRestart
    graceful_test.go:135: receivedPackets1[0] = 165
    graceful_test.go:135: receivedPackets1[1] = 195
    graceful_test.go:135: receivedPackets1[2] = 194
    graceful_test.go:135: receivedPackets1[3] = 190
    graceful_test.go:135: receivedPackets1[4] = 213
    graceful_test.go:135: receivedPackets1[5] = 187
    graceful_test.go:135: receivedPackets1[6] = 170
    graceful_test.go:135: receivedPackets1[7] = 190
    graceful_test.go:135: receivedPackets1[8] = 194
    graceful_test.go:135: receivedPackets1[9] = 155
    graceful_test.go:139: receivedPackets2[0] = 1631
    graceful_test.go:139: receivedPackets2[1] = 1582
    graceful_test.go:139: receivedPackets2[2] = 1594
    graceful_test.go:139: receivedPackets2[3] = 1611
    graceful_test.go:139: receivedPackets2[4] = 1571
    graceful_test.go:139: receivedPackets2[5] = 1660
    graceful_test.go:139: receivedPackets2[6] = 1587
    graceful_test.go:139: receivedPackets2[7] = 1605
    graceful_test.go:139: receivedPackets2[8] = 1631
    graceful_test.go:139: receivedPackets2[9] = 1689
    graceful_test.go:147: receivedPackets = 18014
    graceful_test.go:148: sentPackets     = 18014
Unfortunately, gracefully shutting down a UDP socket is not trivial in Go.10 Previously, we were terminating workers by closing their sockets. However, if we close them too soon, the application loses packets that were assigned to them but not yet processed. Before stopping, a worker needs to call conn.Read() until there are no more packets. A solution is to set a deadline for conn.Read() and check if we should stop the Go routine when the deadline is exceeded:
payload := make([]byte, 9000)
for  
    conn.SetReadDeadline(time.Now().Add(50 * time.Millisecond))
    if _, err := conn.Read(payload); err != nil  
        if errors.Is(err, os.ErrDeadlineExceeded)  
            select  
            case <-done:
                return
            default:
                continue
             
         
        t.Logf("Read() error:\n%+v", err)
     
    *packets++
 
With TCP, this aspect is simpler: after enabling the net.ipv4.tcp_migrate_req sysctl, the kernel automatically migrates waiting connections to a random socket in the same group. Alternatively, eBPF can also control this migration. Both features are available since Linux 5.14.

Addendum After implementing this strategy in Akvorado, all workers now drop packets!
$ curl -s 127.0.0.1:8080/api/v0/inlet/metrics \
>   sed -n s/akvorado_inlet_flow_input_udp_in_dropped//p
packets_total listener="0.0.0.0:2055",worker="0"  838673
packets_total listener="0.0.0.0:2055",worker="1"  843675
packets_total listener="0.0.0.0:2055",worker="2"  837922
packets_total listener="0.0.0.0:2055",worker="3"  841443
packets_total listener="0.0.0.0:2055",worker="4"  840668
packets_total listener="0.0.0.0:2055",worker="5"  850274
packets_total listener="0.0.0.0:2055",worker="6"  835488
packets_total listener="0.0.0.0:2055",worker="7"  834479
The root cause is the default limit of 32 records for Kafka batch sizes. This limit is too low because the brokers have a large overhead when handling each batch: they need to ensure they persist correctly before acknowledging them. Increasing the limit to 4096 records fixes this issue. While load-balancing incoming flows with eBPF remains useful, it did not solve the main issue. At least the even distribution of dropped packets helped identify the real bottleneck.

  1. The current version of the manual page is incomplete and does not cover the evolution introduced in Linux 4.19. There is a pending patch about this.
  2. Rust is another option. However, the program we use is so trivial that it does not make sense to use Rust.
  3. As bpf_get_prandom_u32() returns a pseudo-random 32-bit unsigned value, this method exhibits a very slight bias towards the first indexes. This is unlikely to be worth fixing.
  4. Some examples include <linux/bpf.h> instead of "vmlinux.h". This makes your eBPF program dependent on the installed kernel headers.
  5. listenAddr is initially set to 127.0.0.1:0 to allocate a random port. After the first iteration, it is updated with the allocated port.
  6. This is the setupSockets() function in fixtures_test.go.
  7. This is the setupEBPF() function in fixtures_test.go.
  8. The complete code is in balancing_test.go
  9. The complete code is in graceful_test.go
  10. In C, we would poll() both the socket and a pipe used to signal for shutdown. When the second condition is triggered, we drain the socket by executing a series of non-blocking read() until we get EWOULDBLOCK.

6 November 2025

Sahil Dhiman: Debconf25 Brest

DebConf25 was held at IMT Atlantique Brest Campus in France from 14th to 19th July 2025. As usual, it was preceded by DebCamp from 7th to 13th July. I was less motivated to write this time. So this year, more pictures, less text. Hopefully, (eventually) I may come back to fill this up.

Conference
IMT Atlantique

Main conference area

RAK restaurant, the good food place near the venue

Bits from DPL (can't really miss the tradition of a Bits picture)

Kali Linux: Delivery of a rolling distro at scale with Mirrorbits by Arnaud Rebillout

The security of Debian - An introduction to advanced users by Samuel Henrique

Salsa CI BoF by Otto Kek l inen and others

Debian.net Team BoF by debian.net team

During the conference, Subin had this crazy idea of shooting Parody of a popular clip from the American-Malayalee television series Akkarakazhchakal advertising Debian. He explained the whole story in the BTS video. The results turned out great, TBF:
You have a computer, but no freedom?
Credits - Subin Siby, licensed under CC BY SA 4.0.

BTS from "You have a computer, but no freedom?" video shoot

DebConf25 closing


DC25 network usage graphs. Click to enlarge.
Flow diagrams. Click to enlarge.

Streaming bandwidth graph. Click to enlarge.
Brest
Brest Harbor and Sea

I managed to complete The Little Prince (Le Petit Prince) during my travel from Paris to Brest

Paris
Basilica of the Sacred Heart of Montmartre


View of Paris from the Basilica of the Sacred Heart of Montmartre

Paris streets

Cats rule the world, even on Paris streetlights

Eiffel Tower
Eiffel Tower. It's massive.

Eiffel Tower
View from Eiffel Tower
Credits - Nilesh Patra, licensed under CC BY SA 4.0.

As for the next DebConf work, it has already started. It seems like it never ends. We close one and in one or two months start working on the next one. DebConf is going to Argentina this time and we have a nice little logo too now. DebConf26 logo
DebConf26 logo
Credits - Romina Molina, licensed under CC BY SA 4.0.
Overall, DebConf25 Brest was a nice conference. Many thanks to local team, PEB and everyone involved for everything. Let s see about next year. Bye! DebConf25 Group Photo
DebConf25 Group Photo. Click to enlarge.
Credits - Aigars Mahinovs
PS - Talks are available on Debian media server.

9 December 2024

Gunnar Wolf: Some tips for those who still administer Drupal7-based sites

A bit of history: Drupal at my workplace (and in Debian) My main day-to-day responsibility in my workplace is, and has been for 20 years, to take care of the network infrastructure for UNAM s Economics Research Institute. One of the most visible parts of this responsibility is to ensure we have a working Web presence, and that it caters for the needs of our academic community. I joined the Institute in January 2005. Back then, our designer pushed static versions of our webpage, completely built in her computer. This was standard practice at the time, and lasted through some redesigns, but I soon started advocating for the adoption of a Content Management System. After evaluating some alternatives, I recommended adopting Drupal. It took us quite a bit to do the change: even though I clearly recall starting work toward adopting it as early as 2006, according to the Internet Archive, we switched to a Drupal-backed site around June 2010. We started using it somewhere in the version 6 s lifecycle. As for my Debian work, by late 2012 I started getting involved in the maintenance of the drupal7 package, and by April 2013 I became its primary maintainer. I kept the drupal7 package up to date in Debian until 2018; the supported build methods for Drupal 8 are not compatible with Debian (mainly, bundling third-party libraries and updating them without coordination with the rest of the ecosystem), so towards the end of 2016, I announced I would not package Drupal 8 for Debian. By March 2016, we migrated our main page to Drupal 7. By then, we already had several other sites for our academics projects, but my narrative follows our main Web site. I did manage to migrate several Drupal 6 (D6) sites to Drupal 7 (D7); it was quite involved process, never transparent to the user, and we did have the backlash of long downtimes (or partial downtimes, with sites half-available only) with many of our users. For our main site, we took the opportunity to do a complete redesign and deployed a fully new site. You might note that March 2016 is after the release of D8 (November 2015). I don t recall many of the specifics for this decision, but if I m not mistaken, building the new site was a several months long process not only for the technical work of setting it up, but for the legwork of getting all of the needed information from the different areas that need to be represented in the Institute. Not only that: Drupal sites often include tens of contributed themes and modules; the technological shift the project underwent between its 7 and 8 releases was too deep, and modules took a long time (if at all many themes and modules were outright dumped) to become available for the new release. Naturally, the Drupal Foundation wanted to evolve and deprecate the old codebase. But the pain to migrate from D7 to D8 is too big, and many sites have remained under version 7 Eight years after D8 s release, almost 40% of Drupal installs are for version 7, and a similar proportion runs a currently-supported release (10 or 11). And while the Drupal Foundation made a great job at providing very-long-term support for D7, I understand the burden is becoming too much, so close to a year ago (and after pushing several times the D7, they finally announced support will finish this upcoming January 5.

Drupal 7 must go! I found the following usage graphs quite interesting: the usage statistics for all Drupal versions follows a very positive slope, peaking around 2014 during the best years of D7, and somewhat stagnating afterwards, staying since 2015 at the 25000 28000 sites mark (I m very tempted to copy the graphs, but builtwith s terms of use are very clear in not allowing it). There is a sharp drop in the last year I attribute it to the people that are leaving D7 for other technologies after its end-of-life announcement. This becomes clearer looking only at D7 s usage statistics: D7 peaks at 15000 installs in 2016 stays there for close to 5 years, and has a sharp drop to under 7500 sites in the span of one year. D8 has a more regular rise, peak and fall peaking at ~8500 between 2020 and 2021, and down to close to 2500 for some months already; D9 has a very brief peak of almost 9000 sites in 2023 and is now close to half of it. Currently, the Drupal king appears to be D10, still on a positive slope and with over 9000 sites. Drupal 11 is still just a blip in builtwith s radar, with 3 registered sites as of September 2024 :- After writing this last paragraph, I came across the statistics found in the Drupal webpage; the methodology for acquiring its data is completely different: while builtwith s methodology is their trade secret, you can read more about how Drupal s data is gathered (and agree or disagree with it , but at least you have a page detailing 12 years so far of reported data, producing the following graph (which can be shared under the CC BY-SA license ): Drupal usage statistics by version 2013 2024 This graph is disgregated into minor versions, and I don t want to come up with yet another graph for it but it supports (most of) the narrative I presented above although I do miss the recent drop builtwith reported in D7 s numbers!

And what about Backdrop? During the D8 release cycle, a group of Drupal developers were not happy with the depth of the architectural changes that were being adopted, particularly the transition to the Symfony PHP component framework, and forked the D7 codebase to create the Backdrop CMS, a modern version of Drupal, without dropping the known and tested architecture it had. The Backdrop developers keep working closely together with the Drupal community, and although its usage numbers are way smaller than Drupal s, seems to be sustainable and lively. Of course, as I presented their numbers in the previous section, you can see Backdrop s numbers in builtwith are way, way lower. I have found it to be a very warm and welcoming community, eager to receive new members. And, thanks to its contributed D2B Migrate module, I found it is quite easy to migrate a live site from Drupal 7 to Backdrop.

Migration by playbook! So Well, I m an academic. And (if it s not obvious to you after reading so far ), one of the things I must do in my job is to write. So I decided to write an article to invite my colleagues to consider Backdrop for their D7 sites in Cuadernos T cnicos Universitarios de la DGTIC, a young journal in our university for showcasing technical academical work. And now that my article got accepted and published, I m happy to share it with you of course, if you can read Spanish But anyway Given I have several sites to migrate, and that I m trying to get my colleagues to follow suite, I decided to automatize the migration by writing an Ansible playbook to do the heavy lifting. Of course, the playbook s users will probably need to tweak it a bit to their personal needs. I m also far from an Ansible expert, so I m sure there is ample room fo improvement in my style. But it works. Quite well, I must add.

But with this size of database I did stumble across a big pebble, though. I am working on the migration of one of my users sites, and found that its database is huge. I checked the mysqldump output, and it got me close to 3GB of data. And given the D2B_migrate is meant to work via a Web interface (my playbook works around it by using a client I wrote with Perl s WWW::Mechanize), I repeatedly stumbled with PHP s maximum POST size, maximum upload size, maximum memory size I asked for help in Backdrop s Zulip chat site, and my attention was taken off fixing PHP to something more obvious: Why is the database so large? So I took a quick look at the database (or rather: my first look was at the database server s filesystem usage). MariaDB stores each table as a separate file on disk, so I looked for the nine largest tables:
# ls -lhS head
total 3.8G
-rw-rw---- 1 mysql mysql 2.4G Dec 10 12:09 accesslog.ibd
-rw-rw---- 1 mysql mysql 224M Dec  2 16:43 search_index.ibd
-rw-rw---- 1 mysql mysql 220M Dec 10 12:09 watchdog.ibd
-rw-rw---- 1 mysql mysql 148M Dec  6 14:45 cache_field.ibd
-rw-rw---- 1 mysql mysql  92M Dec  9 05:08 aggregator_item.ibd
-rw-rw---- 1 mysql mysql  80M Dec 10 12:15 cache_path.ibd
-rw-rw---- 1 mysql mysql  72M Dec  2 16:39 search_dataset.ibd
-rw-rw---- 1 mysql mysql  68M Dec  2 13:16 field_revision_field_idea_principal_articulo.ibd
-rw-rw---- 1 mysql mysql  60M Dec  9 13:19 cache_menu.ibd
A single table, the access log, is over 2.4GB long. The three following tables are, cache tables. I can perfectly live without their data in our new site! But I don t want to touch the slightest bit of this site until I m satisfied with the migration process, so I found a way to exclude those tables in a non-destructive way: given D2B_migrate works with a mysqldump output, and given that mysqldump locks each table before starting to modify it and unlocks it after its job is done, I can just do the following:
$ perl -e '$output = 1; while (<>)   $output=0 if /^LOCK TABLES  (accesslog search_index watchdog cache_field cache_path) /; $output=1 if /^UNLOCK TABLES/; print if $output ' < /tmp/d7_backup.sql  > /tmp/d7_backup.eviscerated.sql; ls -hl /tmp/d7_backup.sql /tmp/d7_backup.eviscerated.sql
-rw-rw-r-- 1 gwolf gwolf 216M Dec 10 12:22 /tmp/d7_backup.eviscerated.sql
-rw------- 1 gwolf gwolf 2.1G Dec  6 18:14 /tmp/d7_backup.sql
Five seconds later, I m done! The database is now a tenth of its size, and D2B_migrate is happy to take it. And I m a big step closer to finishing my reliance on (this bit of) legacy code for my highly-visible sites

22 April 2024

Russ Allbery: Review: The Stars, Like Dust

Review: The Stars, Like Dust, by Isaac Asimov
Series: Galactic Empire #2
Publisher: Fawcett Crest
Copyright: 1950, 1951
Printing: June 1972
Format: Mass market
Pages: 192
The Stars, Like Dust is usually listed as the first book in Asimov's lesser-known Galactic Empire Trilogy since it takes place before Pebble in the Sky. Pebble in the Sky was published first, though, so I count it as the second book. It is very early science fiction with a few mystery overtones. Buying books produces about 5% of the pleasure of reading them while taking much less than 5% of the time. There was a time in my life when I thoroughly enjoyed methodically working through a used book store, list in hand, tracking down cheap copies to fill in holes in series. This means that I own a lot of books that I thought at some point that I would want to read but never got around to, often because, at the time, I was feeling completionist about some series or piece of world-building. From time to time, I get the urge to try to read some of them. Sometimes this is a poor use of my time. The Galactic Empire series is from Asimov's first science fiction period, after the Foundation series but contemporaneous with their collection into novels. They're set long, long before Foundation, but after humans have inhabited numerous star systems and Earth has become something of a backwater. That process is just starting in The Stars, Like Dust: Earth is still somewhere where an upper-class son might be sent for an education, but it has been devastated by nuclear wars and is well on its way to becoming an inward-looking relic on the edge of galactic society. Biron Farrill is the son of the Lord Rancher of Widemos, a wealthy noble whose world is one of those conquered by the Tyranni. In many other SF novels, the Tyranni would be an alien race; here, it's a hierarchical and authoritarian human civilization. The book opens with Biron discovering a radiation bomb planted in his dorm room. Shortly after, he learns that his father had been arrested. One of his fellow students claims to be on Biron's side against the Tyranni and gives him false papers to travel to Rhodia, a wealthy world run by a Tyranni sycophant. Like most books of this era, The Stars, Like Dust is a short novel full of plot twists. Unlike some of its contemporaries, it's not devoid of characterization, but I might have liked it better if it were. Biron behaves like an obnoxious teenager when he's not being an arrogant ass. There is a female character who does a few plot-relevant things and at no point is sexually assaulted, so I'll give Asimov that much, but the gender stereotypes are ironclad and there is an entire subplot focused on what I can only describe as seduction via petty jealousy. The writing... well, let me quote a typical passage:
There was no way of telling when the threshold would be reached. Perhaps not for hours, and perhaps the next moment. Biron remained standing helplessly, flashlight held loosely in his damp hands. Half an hour before, the visiphone had awakened him, and he had been at peace then. Now he knew he was going to die. Biron didn't want to die, but he was penned in hopelessly, and there was no place to hide.
Needless to say, Biron doesn't die. Even if your tolerance for pulp melodrama is high, 192 small-print pages of this sort of thing is wearying. Like a lot of Asimov plots, The Stars, Like Dust has some of the shape of a mystery novel. Biron, with the aid of some newfound companions on Rhodia, learns of a secret rebellion against the Tyranni and attempts to track down its base to join them. There are false leads, disguised identities, clues that are difficult to interpret, and similar classic mystery trappings, all covered with a patina of early 1950s imaginary science. To me, it felt constructed and artificial in ways that made the strings Asimov was pulling obvious. I don't know if someone who likes mystery construction would feel differently about it. The worst part of the plot thankfully doesn't come up much. We learn early in the story that Biron was on Earth to search for a long-lost document believed to be vital to defeating the Tyranni. The nature of that document is revealed on the final page, so I won't spoil it, but if you try to think of the stupidest possible document someone could have built this plot around, I suspect you will only need one guess. (In Asimov's defense, he blamed Galaxy editor H.L. Gold for persuading him to include this plot, and disavowed it a few years later.) The Stars, Like Dust is one of the worst books I have ever read. The characters are overwrought, the politics are slapdash and build on broad stereotypes, the romantic subplot is dire and plays out mainly via Biron egregiously manipulating his petulant love interest, and the writing is annoying. Sometimes pulp fiction makes up for those common flaws through larger-than-life feats of daring, sweeping visions of future societies, and ever-escalating stakes. There is little to none of that here. Asimov instead provides tedious political maneuvering among a class of elitist bankers and land owners who consider themselves natural leaders. The only places where the power structures of this future government make sense are where Asimov blatantly steals them from either the Roman Empire or the Doge of Venice. The one thing this book has going for it the thing, apart from bloody-minded completionism, that kept me reading is that the technology is hilariously weird in that way that only 1940s and 1950s science fiction can be. The characters have access to communication via some sort of interstellar telepathy (messages coded to a specific person's "brain waves") and can travel between stars through hyperspace jumps, but each jump is manually calculated by referring to the pilot's (paper!) volumes of the Standard Galactic Ephemeris. Communication between ships (via "etheric radio") requires manually aiming a radio beam at the area in space where one thinks the other ship is. It's an unintentionally entertaining combination of technology that now looks absurdly primitive and science that is so advanced and hand-waved that it's obviously made up. I also have to give Asimov some points for using spherical coordinates. It's a small thing, but the coordinate systems in most SF novels and TV shows are obviously not fit for purpose. I spent about a month and a half of this year barely reading, and while some of that is because I finally tackled a few projects I'd been putting off for years, a lot of it was because of this book. It was only 192 pages, and I'm still curious about the glue between Asimov's Foundation and Robot series, both of which I devoured as a teenager. But every time I picked it up to finally finish it and start another book, I made it about ten pages and then couldn't take any more. Learn from my error: don't try this at home, or at least give up if the same thing starts happening to you. Followed by The Currents of Space. Rating: 2 out of 10

7 December 2023

Daniel Kahn Gillmor: New OpenPGP certificate for dkg, December 2023

dkg's New OpenPGP certificate in December 2023 In December of 2023, I'm moving to a new OpenPGP certificate. You might know my old OpenPGP certificate, which had an fingerprint of C29F8A0C01F35E34D816AA5CE092EB3A5CA10DBA. My new OpenPGP certificate has a fingerprint of: D477040C70C2156A5C298549BB7E9101495E6BF7. Both certificates have the same set of User IDs:
  • Daniel Kahn Gillmor
  • <dkg@debian.org>
  • <dkg@fifthhorseman.net>
You can find a version of this transition statement signed by both the old and new certificates at: https://dkg.fifthhorseman.net/2023-dkg-openpgp-transition.txt The new OpenPGP certificate is:
-----BEGIN PGP PUBLIC KEY BLOCK-----
xjMEZXEJyxYJKwYBBAHaRw8BAQdA5BpbW0bpl5qCng/RiqwhQINrplDMSS5JsO/Y
O+5Zi7HCwAsEHxYKAH0FgmVxCcsDCwkHCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0
QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmfUAgfN9tyTSxpxhmHA1r63GiI4v6NQ
mrrWVLOBRJYuhQMVCggCmwECHgEWIQTUdwQMcMIValwphUm7fpEBSV5r9wAAmaEA
/3MvYJMxQdLhIG4UDNMVd2bsovwdcTrReJhLYyFulBrwAQD/j/RS+AXQIVtkcO9b
l6zZTAO9x6yfkOZbv0g3eNyrAs0QPGRrZ0BkZWJpYW4ub3JnPsLACwQTFgoAfQWC
ZXEJywMLCQcJELt+kQFJXmv3RxQAAAAAAB4AIHNhbHRAbm90YXRpb25zLnNlcXVv
aWEtcGdwLm9yZ4l+Z3i19Uwjw3CfTNFCDjRsoufMoPOM7vM8HoOEdn/vAxUKCAKb
AQIeARYhBNR3BAxwwhVqXCmFSbt+kQFJXmv3AAALZQEAhJsgouepQVV98BHUH6Sv
WvcKrb8dQEZOvHFbZQQPNWgA/A/DHkjYKnUkCg8Zc+FonqOS/35sHhNA8CwqSQFr
tN4KzRc8ZGtnQGZpZnRoaG9yc2VtYW4ubmV0PsLACgQTFgoAfQWCZXEJywMLCQcJ
ELt+kQFJXmv3RxQAAAAAAB4AIHNhbHRAbm90YXRpb25zLnNlcXVvaWEtcGdwLm9y
ZxLvwkgnslsAuo+IoSa9rv8+nXpbBdab2Ft7n4H9S+d/AxUKCAKbAQIeARYhBNR3
BAxwwhVqXCmFSbt+kQFJXmv3AAAtFgD4wqcUfQl7nGLQOcAEHhx8V0Bg8v9ov8Gs
Y1ei1BEFwAD/cxmxmDSO0/tA+x4pd5yIvzgfGYHSTxKS0Ww3hzjuZA7NE0Rhbmll
bCBLYWhuIEdpbGxtb3LCwA4EExYKAIAFgmVxCcsDCwkHCRC7fpEBSV5r90cUAAAA
AAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmd7X4TgiINwnzh4jar0
Pf/b5hgxFPngCFxJSmtr/f0YiQMVCggCmQECmwECHgEWIQTUdwQMcMIValwphUm7
fpEBSV5r9wAAMuwBAPtMonKbhGOhOy+8miAb/knJ1cIPBjLupJbjM+NUE1WyAQD1
nyGW+XwwMrprMwc320mdJH9B0jdokJZBiN7++0NoBM4zBGVxCcsWCSsGAQQB2kcP
AQEHQI19uRatkPSFBXh8usgciEDwZxTnnRZYrhIgiFMybBDQwsC/BBgWCgExBYJl
cQnLCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBn
cC5vcmfCopazDnq6hZUsgVyztl5wmDCmxI169YLNu+IpDzJEtQKbAr6gBBkWCgBv
BYJlcQnLCRB3LRYeNc1LgUcUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lh
LXBncC5vcmcQglI7G7DbL9QmaDkzcEuk3QliM4NmleIRUW7VvIBHMxYhBHS8BMQ9
hghL6GcsBnctFh41zUuBAACwfwEAqDULksr8PulKRcIP6N9NI/4KoznyIcuOHi8q
Gk4qxMkBAIeV20SPEnWSw9MWAb0eKEcfupzr/C+8vDvsRMynCWsDFiEE1HcEDHDC
FWpcKYVJu36RAUlea/cAAFD1AP0YsE3Eeig1tkWaeyrvvMf5Kl1tt2LekTNWDnB+
FUG9SgD+Ka8vfPR8wuV8D3y5Y9Qq9xGO+QkEBCW0U1qNypg65QHOOARlcQnLEgor
BgEEAZdVAQUBAQdAWTLEa0WmnhUmDBdWXX0ZlYAa4g1CK/fXg0NPOQSteA4DAQgH
wsAABBgWCgByBYJlcQnLCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0QG5vdGF0aW9u
cy5zZXF1b2lhLXBncC5vcmexrMBZe0QdQ+ZJOZxFkAiwCw2I7yTSF2Ox9GVFWKmA
mAKbDBYhBNR3BAxwwhVqXCmFSbt+kQFJXmv3AABcJQD/f4ltpSvLBOBEh/C2dIYa
dgSuqkCqq0B4WOhFRkWJZlcA/AxqLWG4o8UrrmwrmM42FhgxKtEXwCSHE00u8wR4
Up8G
=9Yc8
-----END PGP PUBLIC KEY BLOCK-----
When I have some reasonable number of certifications, i'll update the certificate associated with my e-mail addresses on https://keys.openpgp.org, in DANE, and in WKD. Until then, those lookups should continue to provide the old certificate.

12 September 2023

Jo Shields: Building a NAS

The status quo Back in 2015, I bought an off-the-shelf NAS, a QNAP TS-453mini, to act as my file store and Plex server. I had previously owned a Synology box, and whilst I liked the Synology OS and experience, the hardware was underwhelming. I loaded up the successor QNAP with four 5TB drives in RAID10, and moved all my files over (after some initial DoA drive issues were handled).
QNAP TS-453mini product photoQNAP TS-453mini product photo
That thing has been in service for about 8 years now, and it s been a mixed bag. It was definitely more powerful than the predecessor system, but it was clear that QNAP s OS was not up to the same standard as Synology s perhaps best exemplified by HappyGet 2 , the QNAP webapp for downloading videos from streaming services like YouTube, whose icon is a straight rip-off of StarCraft 2. On its own, meaningless but a bad omen for overall software quality
The logo for QNAP HappyGet 2 and Blizzard's Starcraft 2 side by sideThe logo for QNAP HappyGet 2 and Blizzard s StarCraft 2 side by side
Additionally, the embedded Celeron processor in the NAS turned out to be an issue for some cases. It turns out, when playing back videos with subtitles, most Plex clients do not support subtitles properly instead they rely on the Plex server doing JIT transcoding to bake the subtitles directly into the video stream. I discovered this with some Blu-Ray rips of Game of Thrones some episodes would play back fine on my smart TV, but episodes with subtitled Dothraki speech would play at only 2 or 3 frames per second. The final straw was a ransomware attack, which went through all my data and locked every file below a 60MiB threshold. Practically all my music gone. A substantial collection of downloaded files, all gone. Some of these files had been carried around since my college days digital rarities, or at least digital detritus I felt a real sense of loss at having to replace. This episode was caused by a ransomware targeting specific vulnerabilities in the QNAP OS, not an error on my part. So, I decided to start planning a replacement with:
  • A non-garbage OS, whilst still being a NAS-appliance type offering (not an off-the-shelf Linux server distro)
  • Full remote management capabilities
  • A small form factor comparable to off-the-shelf NAS
  • A powerful modern CPU capable of transcoding high resolution video
  • All flash storage, no spinning rust
At the time, no consumer NAS offered everything (The Asustor FS6712X exists now, but didn t when this project started), so I opted to go for a full DIY rather than an appliance not the first time I ve jumped between appliances and DIY for home storage.

Selecting the core of the system There aren t many companies which will sell you a small motherboard with IPMI. Supermicro is a bust, so is Tyan. But ASRock Rack, the server division of third-tier motherboard vendor ASRock, delivers. Most of their boards aren t actually compliant Mini-ITX size, they re a proprietary Deep Mini-ITX with the regular screw holes, but 40mm of extra length (and a commensurately small list of compatible cases). But, thankfully, they do have a tiny selection of boards without the extra size, and I stumbled onto the X570D4I-2T, a board with an AMD AM4 socket and the mature X570 chipset. This board can use any AMD Ryzen chip (before the latest-gen Ryzen 7000 series); has built in dual 10 gigabit ethernet; IPMI; four (laptop-sized) RAM slots with full ECC support; one M.2 slot for NVMe SSD storage; a PCIe 16x slot (generally for graphics cards, but we live in a world of possibilities); and up to 8 SATA drives OR a couple more NVMe SSDs. It s astonishingly well featured, just a shame it costs about $450 compared to a good consumer-grade Mini ITX AM4 board costing less than half that. I was so impressed with the offering, in fact, that I crowed about it on Mastodon and ended up securing ASRock another sale, with someone else looking into a very similar project to mine around the same timespan. The next question was the CPU. An important feature of a system expected to run 24/7 is low power, and AM4 chips can consume as much as 130W under load, out of the box. At the other end, some models can require as little as 35W under load the OEM-only GE suffix chips, which are readily found for import on eBay. In their PRO variant, they also support ECC (all non-G Ryzen chips support ECC, but only Pro G chips do). The top of the range 8 core Ryzen 7 PRO 5750GE is prohibitively expensive, but the slightly weaker 6 core Ryzen 5 PRO 5650GE was affordable, and one arrived quickly from Hong Kong. Supplemented with a couple of cheap 16 GiB SODIMM sticks of DDR4 PC-3200 direct from Micron for under $50 a piece, that left only cooling as an unsolved problem to get a bootable test system. The official support list for the X570D4I-2T only includes two rackmount coolers, both expensive and hard to source. The reason for such a small list is the non standard cooling layout of the board instead of an AM4 hole pattern with the standard plastic AM4 retaining clips, it has an Intel 115x hole pattern with a non-standard backplate (Intel 115x boards have no backplate, the stock Intel 115x cooler attaches to the holes with push pins). As such every single cooler compatibility list excludes this motherboard. However, the backplate is only secured with a mild glue with minimal pressure and a plastic prying tool it can be removed, giving compatibility with any 115x cooler (which is basically any CPU cooler for more than a decade). I picked an oversized low profile Thermalright AXP120-X67 hoping that its 120mm fan would cool the nearby MOSFETs and X570 chipset too.
Thermalright AXP120-X67, AMD Ryzen 5 PRO 5650GE, ASRock Rack X570D4I-2T, all assembled and running on a flat surface

Testing up to this point Using a spare ATX power supply, I had enough of a system built to explore the IPMI and UEFI instances, and run MemTest86 to validate my progress. The memory test ran without a hitch and confirmed the ECC was working, although it also showed that the memory was only running at 2933 MT/s instead of the rated 3200 MT/s (a limit imposed by the motherboard, as higher speeds are considered overclocking). The IPMI interface isn t the best I ve ever used by a long shot, but it s minimum viable and allowed me to configure the basics and boot from media entirely via a Web browser.
Memtest86 showing test progress, taken from IPMI remote control window
One sad discovery, however, which I ve never seen documented before, on PCIe bifurcation. With PCI Express, you have a number of lanes which are allocated in groups by the motherboard and CPU manufacturer. For Ryzen prior to Ryzen 7000, that s 16 lanes in one slot for the graphics card; 4 lanes in one M.2 connector for an SSD; then 4 lanes connecting the CPU to the chipset, which can offer whatever it likes for peripherals or extra lanes (bottlenecked by that shared 4x link to the CPU, if it comes down to it). It s possible, with motherboard and CPU support, to split PCIe groups up for example an 8x slot could be split into two 4x slots (eg allowing two NVMe drives in an adapter card NVME drives these days all use 4x). However with a Cezanne Ryzen with integrated graphics, the 16x graphics card slot cannot be split into four 4x slots (ie used for for NVMe drives) the most bifurcation it allows is 8x4x4x, which is useless in a NAS.
Screenshot of PCIe 16x slot bifurcation options in UEFI settings, taken from IPMI remote control window
As such, I had to abandon any ideas of an all-NVMe NAS I was considering: the 16x slot split into four 4x, combined with two 4x connectors fed by the X570 chipset, to a total of 6 NVMe drives. 7.6TB U.2 enterprise disks are remarkably affordable (cheaper than consumer SATA 8TB drives), but alas, I was locked out by my 5650GE. Thankfully I found out before spending hundreds on a U.2 hot swap bay. The NVMe setup would be nearly 10x as fast as SATA SSDs, but at least the SATA SSD route would still outperform any spinning rust choice on the market (including the fastest 10K RPM SAS drives)

Containing the core The next step was to pick a case and power supply. A lot of NAS cases require an SFX (rather than ATX) size supply, so I ordered a modular SX500 unit from Silverstone. Even if I ended up with a case requiring ATX, it s easy to turn an SFX power supply into ATX, and the worst result is you have less space taken up in your case, hardly the worst problem to have. That said, on to picking a case. There s only one brand with any cachet making ITX NAS cases, Silverstone. They have three choices in an appropriate size: CS01-HS, CS280, and DS380. The problem is, these cases are all badly designed garbage. Take the CS280 as an example, the case with the most space for a CPU cooler. Here s how close together the hotswap bay (right) and power supply (left) are:
Internal image of Silverstone CS280 NAS build. Image stolen from ServeTheHome
With actual cables connected, the cable clearance problem is even worse:
Internal image of Silverstone CS280 NAS build. Image stolen from ServeTheHome
Remember, this is the best of the three cases for internal layout, the one with the least restriction on CPU cooler height. And it s garbage! Total hot garbage! I decided therefore to completely skip the NAS case market, and instead purchase a 5.25 -to-2.5 hot swap bay adapter from Icy Dock, and put it in an ITX gamer case with a 5.25 bay. This is no longer a served market 5.25 bays are extinct since nobody uses CD/DVD drives anymore. The ones on the market are really new old stock from 2014-2017: The Fractal Design Core 500, Cooler Master Elite 130, and Silverstone SUGO 14. Of the three, the Fractal is the best rated so I opted to get that one however it seems the global supply of new old stock fully dried up in the two weeks between me making a decision and placing an order leaving only the Silverstone case. Icy Dock have a selection of 8-bay 2.5 SATA 5.25 hot swap chassis choices in their ToughArmor MB998 series. I opted for the ToughArmor MB998IP-B, to reduce cable clutter it requires only two SFF-8611-to-SF-8643 cables from the motherboard to serve all eight bays, which should make airflow less of a mess. The X570D4I-2T doesn t have any SATA ports on board, instead it has two SFF-8611 OCuLink ports, each supporting 4 PCI Express lanes OR 4 SATA connectors via a breakout cable. I had hoped to get the ToughArmor MB118VP-B and run six U.2 drives, but as I said, the PCIe bifurcation issue with Ryzen G chips meant I wouldn t be able to run all six bays successfully.
NAS build in Silverstone SUGO 14, mid build, panels removed
Silverstone SUGO 14 from the front, with hot swap bay installed

Actual storage for the storage server My concept for the system always involved a fast boot/cache drive in the motherboard s M.2 slot, non-redundant (just backups of the config if the worst were to happen) and separate storage drives somewhere between 3.8 and 8 TB each (somewhere from $200-$350). As a boot drive, I selected the Intel Optane SSD P1600X 58G, available for under $35 and rated for 228 years between failures (or 11,000 complete drive rewrite cycles). So, on to the big expensive choice: storage drives. I narrowed it down to two contenders: new-old-stock Intel D3-S4510 3.84TB enterprise drives, at about $200, or Samsung 870 QVO 8TB consumer drives, at about $375. I did spend a long time agonizing over the specification differences, the ZFS usage reports, the expected lifetime endurance figures, but in reality, it came down to price $1600 of expensive drives vs $3200 of even more expensive drives. That s 27TB of usable capacity in RAID-Z1, or 23TB in RAID-Z2. For comparison, I m using about 5TB of the old NAS, so that s a LOT of overhead for expansion.
Storage SSD loaded into hot swap sled

Booting up Bringing it all together is the OS. I wanted an appliance NAS OS rather than self-administering a Linux distribution, and after looking into the surrounding ecosystems, decided on TrueNAS Scale (the beta of the 2023 release, based on Debian 12).
TrueNAS Dashboard screenshot in browser window
I set up RAID-Z1, and with zero tuning (other than enabling auto-TRIM), got the following performance numbers:
IOPSBandwidth
4k random writes19.3k75.6 MiB/s
4k random reads36.1k141 MiB/s
Sequential writes 2300 MiB/s
Sequential reads 3800 MiB/s
Results using fio parameters suggested by Huawei
And for comparison, the maximum theoretical numbers quoted by Intel for a single drive:
IOPSBandwidth
4k random writes16k?
4k random reads90k?
Sequential writes 280 MiB/s
Sequential reads 560 MiB/s
Numbers quoted by Intel SSD successors Solidigm.
Finally, the numbers reported on the old NAS with four 7200 RPM hard disks in RAID 10:
IOPSBandwidth
4k random writes4301.7 MiB/s
4k random reads800632 MiB/s
Sequential writes 311 MiB/s
Sequential reads 566 MiB/s
Performance seems pretty OK. There s always going to be an overhead to RAID. I ll settle for the 45x improvement on random writes vs. its predecessor, and 4.5x improvement on random reads. The sequential write numbers are gonna be impacted by the size of the ZFS cache (50% of RAM, so 16 GiB), but the rest should be a reasonable indication of true performance. It took me a little while to fully understand the TrueNAS permissions model, but I finally got Plex configured to access data from the same place as my SMB shares, which have anonymous read-only access or authenticated write access for myself and my wife, working fine via both Linux and Windows. And that s it! I built a NAS. I intend to add some fans and more RAM, but that s the build. Total spent: about $3000, which sounds like an unreasonable amount, but it s actually less than a comparable Synology DiskStation DS1823xs+ which has 4 cores instead of 6, first-generation AMD Zen instead of Zen 3, 8 GiB RAM instead of 32 GiB, no hardware-accelerated video transcoding, etc. And it would have been a whole lot less fun!
The final system, powered up
(Also posted on PCPartPicker)

23 August 2023

Jo Shields: Retirement

Apparently it s nearly four years since I last posted to my blog. Which is, to a degree, the point here. My time, and priorities, have changed over the years. And this lead me to the decision that my available time and priorities in 2023 aren t compatible with being a Debian or Ubuntu developer, and realistically, haven t been for years. As of earlier this month, I quit as a Debian Developer and Ubuntu MOTU. I think a lot of my blogging energy got absorbed by social media over the last decade, but with the collapse of Twitter and Reddit due to mismanagement, I m trying to allocate more time for blog-based things instead. I may write up some of the things I ve achieved at work (.NET 8 is now snapped for release Soon ). I might even blog about work-adjacent controversial topics, like my changed feelings about the entire concept of distribution packages. But there s time for that later. Maybe. I ll keep tagging vaguely FOSS related topics with the Debian and Ubuntu tags, which cause them to be aggregated in the Planet Debian/Ubuntu feeds (RSS, remember that from the before times?!) until an admin on those sites gets annoyed at the off-topic posting of an emeritus dev and deletes them. But that s where we are. Rather than ignore my distro obligations, I ve admitted that I just don t have the energy any more. Let someone less perpetually exhausted than me take over. And if they don t, maybe that s OK too.

18 February 2021

Jonathan McDowell: Hacking and Bricking the EE Opsrey 2 Mini

I ve mentioned in the past my twisted EE network setup from when I moved in to my current house. The 4GEE WiFi Mini (also known as the EE Osprey 2 Mini or the EE40VB, and actually a rebadged Alcatel Y853VB) has been sitting unused since then, so I figured I d see about trying to get a shell on it. TL;DR: Of course it s running Linux, there s a couple of test points internally which bring out the serial console, but after finding those and logging in I discovered it s running ADB on port 5555 quite happily available without authentication both via wifi and the USB port. So if you have physical or local network access, instant root shell. Well done, folks. And then I bricked it before I could do anything more interesting. There s a lack of information about this device out there - most of the links I can find are around removing the SIM lock - so I thought I d document the pieces I found just in case anyone else is trying to figure it out. It s based around a Qualcomm MDM9607 SoC, paired with 64M RAM and 256M NAND flash. Wifi is via an RTL8192ES. Kernel is 3.18.20. Busybox is v1.23.1. It s running dnsmasq but I didn t grab the version. Of course there s no source or offer of source provided. Taking it apart is fairly easy. There s a single screw to remove, just beside the SIM slot. The coloured rim can then be carefully pried away from the back, revealing the battery. There are then 4 screws in the corners which need removed in order to be able to lift out the actual PCB and gain access to the serial console test points. EE40VB PCB serial console test points My mistake was going poking around trying to figure out where the updates are downloaded from - I know I m running a slightly older release than what s current, and the device can do an automatic download + update. Top tip; don t run Jrdrecovery. It ll error on finding /cache/update.zip and wipe the main partition anyway. That ll leave you in a boot loop where the device boots the recovery partition which tries to install /cache/update.zip which of course still doesn t exist. So. Where next? First, I need to get the device into a state where I can actually do something other than watch it boot into recovery, fail to flash and reboot. Best guess at present is to try and get it to enter the Qualcomm EDL (Emergency Download) mode. That might be possible with a custom USB cable that grounds D+ on boot. Alternatively I need to probe some of the other test points on the PCB and see if grounding any of those helps enter EDL mode. I then need a suitable firehose OEM-signed programmer image. And then I need to actually get hold of a proper EE40VB firmware image, either via one of the OTA update files or possibly via an Alcatel ADSU image (though no idea how to get hold of one, other than by posting to a random GSM device forum and hoping for the kindness of strangers). More updates if/when I make progress
Qualcomm bootloader log
Format: Log Type - Time(microsec) - Message - Optional Info
Log Type: B - Since Boot(Power On Reset),  D - Delta,  S - Statistic
S - QC_IMAGE_VERSION_STRING=BOOT.BF.3.1.2-00053
S - IMAGE_VARIANT_STRING=LAATANAZA
S - OEM_IMAGE_VERSION_STRING=linux3
S - Boot Config, 0x000002e1
B -    105194 - SBL1, Start
D -     61885 - QSEE Image Loaded, Delta - (451964 Bytes)
D -     30286 - RPM Image Loaded, Delta - (151152 Bytes)
B -    459330 - Roger:boot_jrd_oem_main
B -    461526 - Welcome to key_check_poweron!!!
B -    466436 - REG0x00, rc=47
B -    469120 - REG0x01, rc=1f
B -    472018 - REG0x02, rc=1c
B -    474885 - REG0x03, rc=47
B -    477782 - REG0x04, rc=b2
B -    480558 - REG0x05, rc=
B -    483272 - REG0x06, rc=9e
B -    486139 - REG0x07, rc=
B -    488854 - REG0x08, rc=a4
B -    491721 - REG0x09, rc=80
B -    494130 - bq24295_probe: vflt/vsys/vprechg=0mV/0mV/0mV, tprechg/tfastchg=0Min/0Min, [0C, 0C]
B -    511546 - come to calculate vol and temperature!!
B -    511637 - ##############battery_core_convert_vntc: NTC_voltage=1785690
B -    517280 - battery_core_convert_vntc: <-44C, 1785690uV>, present=0
B -    529358 - bq24295_set_current_limit: setting=0mA, mode=-1, input/fastchg/prechg/termchg=-1mA/0mA/0mA/0mA
B -    534360 - bq24295_set_charge_current, rc=0,reg_val=0,i=0
B -    539636 - bq24295_enable_charge: setting=0, chg_enable=-1, otg_enable=0
B -    546072 - bq24295_enable_charging: enable_charging=0
B -    552172 - bq24295_set_current_limit: setting=0mA, mode=-1, input/fastchg/prechg/termchg=-1mA/0mA/0mA/0mA
B -    561566 - bq24295_set_charge_current, rc=0,reg_val=0,i=0
B -    567056 - bq24295_enable_charge: setting=0, chg_enable=0, otg_enable=0
B -    579286 - come to calculate vol and temperature!!
B -    579378 - ##############battery_core_convert_vntc: NTC_voltage=1785777
B -    585539 - battery_core_convert_vntc: <-44C, 1785777uV>, present=0
B -    597617 - charge_main: battery is plugout!!
B -    597678 - Welcome to pca955x_probe!!!
B -    601063 - pca955x_probe: PCA955X probed successfully!
D -     27511 - APPSBL Image Loaded, Delta - (179348 Bytes)
B -    633271 - QSEE Execution, Start
D -       213 - QSEE Execution, Delta
B -    638944 - >>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>Start writting JRD RECOVERY BOOT
B -    650107 - >>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>Start writting  RECOVERY BOOT
B -    653218 - >>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>>read_buf[0] == 0
B -    659044 - SBL1, End
D -    556137 - SBL1, Delta
S - Throughput, 2000 KB/s  (782884 Bytes,  278155 us)
S - DDR Frequency, 240 MHz
littlekernel aboot log
Android Bootloader - UART_DM Initialized!!!
[0] welcome to lk
[0] SCM call: 0x2000601 failed with :fffffffc
[0] Failed to initialize SCM
[10] platform_init()
[10] target_init()
[10] smem ptable found: ver: 4 len: 17
[10] ERROR: No devinfo partition found
[10] Neither 'config' nor 'frp' partition found
[30] voltage of NTC  is 1789872!
[30] voltage of BAT  is 3179553!
[30] usb present is 1!
[30] Loading (boot) image (4171776): start
[530] Loading (boot) image (4171776): done
[540] DTB Total entry: 25, DTB version: 3
[540] Using DTB entry 0x00000129/00010000/0x00000008/0 for device 0x00000129/00010000/0x00010008/0
[560] JRD_CHG_OFF_FEATURE!
[560] come to jrd_target_pause_for_battery_charge!
[570] power_on_status.hard_reset = 0x0
[570] power_on_status.smpl = 0x0
[570] power_on_status.rtc = 0x0
[580] power_on_status.dc_chg = 0x0
[580] power_on_status.usb_chg = 0x0
[580] power_on_status.pon1 = 0x1
[590] power_on_status.cblpwr = 0x0
[590] power_on_status.kpdpwr = 0x0
[590] power_on_status.bugflag = 0x0
[590] cmdline: noinitrd  rw console=ttyHSL0,115200,n8 androidboot.hardware=qcom ehci-hcd.park=3 msm_rtb.filter=0x37 lpm_levels.sleep_disabled=1  earlycon=msm_hsl_uart,0x78b3000  androidboot.serialno=7e6ba58c androidboot.baseband=msm rootfstype=ubifs rootflags=b
[620] Updating device tree: start
[720] Updating device tree: done
[720] booting linux @ 0x80008000, ramdisk @ 0x80008000 (0), tags/device tree @ 0x81e00000
Linux kernel console boot log
[    0.000000] Booting Linux on physical CPU 0x0
[    0.000000] Linux version 3.18.20 (linux3@linux3) (gcc version 4.9.2 (GCC) ) #1 PREEMPT Thu Aug 10 11:57:07 CST 2017
[    0.000000] CPU: ARMv7 Processor [410fc075] revision 5 (ARMv7), cr=10c53c7d
[    0.000000] CPU: PIPT / VIPT nonaliasing data cache, VIPT aliasing instruction cache
[    0.000000] Machine model: Qualcomm Technologies, Inc. MDM 9607 MTP
[    0.000000] Early serial console at I/O port 0x0 (options '')
[    0.000000] bootconsole [uart0] enabled
[    0.000000] Reserved memory: reserved region for node 'modem_adsp_region@0': base 0x82a00000, size 56 MiB
[    0.000000] Reserved memory: reserved region for node 'external_image_region@0': base 0x87c00000, size 4 MiB
[    0.000000] Removed memory: created DMA memory pool at 0x82a00000, size 56 MiB
[    0.000000] Reserved memory: initialized node modem_adsp_region@0, compatible id removed-dma-pool
[    0.000000] Removed memory: created DMA memory pool at 0x87c00000, size 4 MiB
[    0.000000] Reserved memory: initialized node external_image_region@0, compatible id removed-dma-pool
[    0.000000] cma: Reserved 4 MiB at 0x87800000
[    0.000000] Memory policy: Data cache writeback
[    0.000000] CPU: All CPU(s) started in SVC mode.
[    0.000000] Built 1 zonelists in Zone order, mobility grouping on.  Total pages: 17152
[    0.000000] Kernel command line: noinitrd  rw console=ttyHSL0,115200,n8 androidboot.hardware=qcom ehci-hcd.park=3 msm_rtb.filter=0x37 lpm_levels.sleep_disabled=1  earlycon=msm_hsl_uart,0x78b3000  androidboot.serialno=7e6ba58c androidboot.baseband=msm rootfstype=ubifs rootflags=bulk_read root=ubi0:rootfs ubi.mtd=16
[    0.000000] PID hash table entries: 512 (order: -1, 2048 bytes)
[    0.000000] Dentry cache hash table entries: 16384 (order: 4, 65536 bytes)
[    0.000000] Inode-cache hash table entries: 8192 (order: 3, 32768 bytes)
[    0.000000] Memory: 54792K/69632K available (5830K kernel code, 399K rwdata, 2228K rodata, 276K init, 830K bss, 14840K reserved)
[    0.000000] Virtual kernel memory layout:
[    0.000000]     vector  : 0xffff0000 - 0xffff1000   (   4 kB)
[    0.000000]     fixmap  : 0xffc00000 - 0xfff00000   (3072 kB)
[    0.000000]     vmalloc : 0xc8800000 - 0xff000000   ( 872 MB)
[    0.000000]     lowmem  : 0xc0000000 - 0xc8000000   ( 128 MB)
[    0.000000]     modules : 0xbf000000 - 0xc0000000   (  16 MB)
[    0.000000]       .text : 0xc0008000 - 0xc07e6c38   (8060 kB)
[    0.000000]       .init : 0xc07e7000 - 0xc082c000   ( 276 kB)
[    0.000000]       .data : 0xc082c000 - 0xc088fdc0   ( 400 kB)
[    0.000000]        .bss : 0xc088fe84 - 0xc095f798   ( 831 kB)
[    0.000000] SLUB: HWalign=64, Order=0-3, MinObjects=0, CPUs=1, Nodes=1
[    0.000000] Preemptible hierarchical RCU implementation.
[    0.000000] NR_IRQS:16 nr_irqs:16 16
[    0.000000] GIC CPU mask not found - kernel will fail to boot.
[    0.000000] GIC CPU mask not found - kernel will fail to boot.
[    0.000000] mpm_init_irq_domain(): Cannot find irq controller for qcom,gpio-parent
[    0.000000] MPM 1 irq mapping errored -517
[    0.000000] Architected mmio timer(s) running at 19.20MHz (virt).
[    0.000011] sched_clock: 56 bits at 19MHz, resolution 52ns, wraps every 3579139424256ns
[    0.007975] Switching to timer-based delay loop, resolution 52ns
[    0.013969] Switched to clocksource arch_mem_counter
[    0.019687] Console: colour dummy device 80x30
[    0.023344] Calibrating delay loop (skipped), value calculated using timer frequency.. 38.40 BogoMIPS (lpj=192000)
[    0.033666] pid_max: default: 32768 minimum: 301
[    0.038411] Mount-cache hash table entries: 1024 (order: 0, 4096 bytes)
[    0.044902] Mountpoint-cache hash table entries: 1024 (order: 0, 4096 bytes)
[    0.052445] CPU: Testing write buffer coherency: ok
[    0.057057] Setting up static identity map for 0x8058aac8 - 0x8058ab20
[    0.064242]
[    0.064242] **********************************************************
[    0.071251] **   NOTICE NOTICE NOTICE NOTICE NOTICE NOTICE NOTICE   **
[    0.077817] **                                                      **
[    0.084302] ** trace_printk() being used. Allocating extra memory.  **
[    0.090781] **                                                      **
[    0.097320] ** This means that this is a DEBUG kernel and it is     **
[    0.103802] ** unsafe for produciton use.                           **
[    0.110339] **                                                      **
[    0.116850] ** If you see this message and you are not debugging    **
[    0.123333] ** the kernel, report this immediately to your vendor!  **
[    0.129870] **                                                      **
[    0.136380] **   NOTICE NOTICE NOTICE NOTICE NOTICE NOTICE NOTICE   **
[    0.142865] **********************************************************
[    0.150225] MSM Memory Dump base table set up
[    0.153739] MSM Memory Dump apps data table set up
[    0.168125] VFP support v0.3: implementor 41 architecture 2 part 30 variant 7 rev 5
[    0.176332] pinctrl core: initialized pinctrl subsystem
[    0.180930] regulator-dummy: no parameters
[    0.215338] NET: Registered protocol family 16
[    0.220475] DMA: preallocated 256 KiB pool for atomic coherent allocations
[    0.284034] cpuidle: using governor ladder
[    0.314026] cpuidle: using governor menu
[    0.344024] cpuidle: using governor qcom
[    0.355452] msm_watchdog b017000.qcom,wdt: wdog absent resource not present
[    0.361656] msm_watchdog b017000.qcom,wdt: MSM Watchdog Initialized
[    0.371373] irq: no irq domain found for /soc/pinctrl@1000000 !
[    0.381268] spmi_pmic_arb 200f000.qcom,spmi: PMIC Arb Version-2 0x20010000
[    0.389733] platform 4080000.qcom,mss: assigned reserved memory node modem_adsp_region@0
[    0.397409] mem_acc_corner: 0 <--> 0 mV
[    0.401937] hw-breakpoint: found 5 (+1 reserved) breakpoint and 4 watchpoint registers.
[    0.408966] hw-breakpoint: maximum watchpoint size is 8 bytes.
[    0.416287] __of_mpm_init(): MPM driver mapping exists
[    0.420940] msm_rpm_glink_dt_parse: qcom,rpm-glink compatible not matches
[    0.427235] msm_rpm_dev_probe: APSS-RPM communication over SMD
[    0.432977] smd_open() before smd_init()
[    0.437544] msm_mpm_dev_probe(): Cannot get clk resource for XO: -517
[    0.445730] smd_channel_probe_now: allocation table not initialized
[    0.453100] mdm9607_s1: 1050 <--> 1350 mV at 1225 mV normal idle
[    0.458566] spm_regulator_probe: name=mdm9607_s1, range=LV, voltage=1225000 uV, mode=AUTO, step rate=4800 uV/us
[    0.468817] cpr_efuse_init: apc_corner: efuse_addr = 0x000a4000 (len=0x1000)
[    0.475353] cpr_read_fuse_revision: apc_corner: fuse revision = 2
[    0.481345] cpr_parse_speed_bin_fuse: apc_corner: [row: 37]: 0x79e8bd327e6ba58c, speed_bits = 4
[    0.490124] cpr_pvs_init: apc_corner: pvs voltage: [1050000 1100000 1275000] uV
[    0.497342] cpr_pvs_init: apc_corner: ceiling voltage: [1050000 1225000 1350000] uV
[    0.504979] cpr_pvs_init: apc_corner: floor voltage: [1050000 1050000 1150000] uV
[    0.513125] i2c-msm-v2 78b8000.i2c: probing driver i2c-msm-v2
[    0.518335] i2c-msm-v2 78b8000.i2c: error on clk_get(core_clk):-517
[    0.524478] i2c-msm-v2 78b8000.i2c: error probe() failed with err:-517
[    0.531111] i2c-msm-v2 78b7000.i2c: probing driver i2c-msm-v2
[    0.536788] i2c-msm-v2 78b7000.i2c: error on clk_get(core_clk):-517
[    0.542886] i2c-msm-v2 78b7000.i2c: error probe() failed with err:-517
[    0.549618] i2c-msm-v2 78b9000.i2c: probing driver i2c-msm-v2
[    0.555202] i2c-msm-v2 78b9000.i2c: error on clk_get(core_clk):-517
[    0.561374] i2c-msm-v2 78b9000.i2c: error probe() failed with err:-517
[    0.570613] msm-thermal soc:qcom,msm-thermal: msm_thermal:Failed reading node=/soc/qcom,msm-thermal, key=qcom,core-limit-temp. err=-22. KTM continues
[    0.583049] msm-thermal soc:qcom,msm-thermal: probe_therm_reset:Failed reading node=/soc/qcom,msm-thermal, key=qcom,therm-reset-temp err=-22. KTM continues
[    0.596926] msm_thermal:msm_thermal_dev_probe Failed reading node=/soc/qcom,msm-thermal, key=qcom,online-hotplug-core. err:-517
[    0.609370] sps:sps is ready.
[    0.613137] msm_rpm_glink_dt_parse: qcom,rpm-glink compatible not matches
[    0.619020] msm_rpm_dev_probe: APSS-RPM communication over SMD
[    0.625773] mdm9607_s2: 750 <--> 1275 mV at 750 mV normal idle
[    0.631584] mdm9607_s3_level: 0 <--> 0 mV at 0 mV normal idle
[    0.637085] mdm9607_s3_level_ao: 0 <--> 0 mV at 0 mV normal idle
[    0.643092] mdm9607_s3_floor_level: 0 <--> 0 mV at 0 mV normal idle
[    0.649512] mdm9607_s3_level_so: 0 <--> 0 mV at 0 mV normal idle
[    0.655750] mdm9607_s4: 1800 <--> 1950 mV at 1800 mV normal idle
[    0.661791] mdm9607_l1: 1250 mV normal idle
[    0.666090] mdm9607_l2: 1800 mV normal idle
[    0.670276] mdm9607_l3: 1800 mV normal idle
[    0.674541] mdm9607_l4: 3075 mV normal idle
[    0.678743] mdm9607_l5: 1700 <--> 3050 mV at 1700 mV normal idle
[    0.684904] mdm9607_l6: 1700 <--> 3050 mV at 1700 mV normal idle
[    0.690892] mdm9607_l7: 1700 <--> 1900 mV at 1700 mV normal idle
[    0.697036] mdm9607_l8: 1800 mV normal idle
[    0.701238] mdm9607_l9: 1200 <--> 1250 mV at 1200 mV normal idle
[    0.707367] mdm9607_l10: 1050 mV normal idle
[    0.711662] mdm9607_l11: 1800 mV normal idle
[    0.716089] mdm9607_l12_level: 0 <--> 0 mV at 0 mV normal idle
[    0.721717] mdm9607_l12_level_ao: 0 <--> 0 mV at 0 mV normal idle
[    0.727946] mdm9607_l12_level_so: 0 <--> 0 mV at 0 mV normal idle
[    0.734099] mdm9607_l12_floor_lebel: 0 <--> 0 mV at 0 mV normal idle
[    0.740706] mdm9607_l13: 1800 <--> 2850 mV at 2850 mV normal idle
[    0.746883] mdm9607_l14: 2650 <--> 3000 mV at 2650 mV normal idle
[    0.752515] msm_mpm_dev_probe(): Cannot get clk resource for XO: -517
[    0.759036] cpr_efuse_init: apc_corner: efuse_addr = 0x000a4000 (len=0x1000)
[    0.765807] cpr_read_fuse_revision: apc_corner: fuse revision = 2
[    0.771809] cpr_parse_speed_bin_fuse: apc_corner: [row: 37]: 0x79e8bd327e6ba58c, speed_bits = 4
[    0.780586] cpr_pvs_init: apc_corner: pvs voltage: [1050000 1100000 1275000] uV
[    0.787808] cpr_pvs_init: apc_corner: ceiling voltage: [1050000 1225000 1350000] uV
[    0.795443] cpr_pvs_init: apc_corner: floor voltage: [1050000 1050000 1150000] uV
[    0.803094] cpr_init_cpr_parameters: apc_corner: up threshold = 2, down threshold = 3
[    0.810752] cpr_init_cpr_parameters: apc_corner: CPR is enabled by default.
[    0.817687] cpr_init_cpr_efuse: apc_corner: [row:65] = 0x15000277277383
[    0.824272] cpr_init_cpr_efuse: apc_corner: CPR disable fuse = 0
[    0.830225] cpr_init_cpr_efuse: apc_corner: Corner[1]: ro_sel = 0, target quot = 631
[    0.837976] cpr_init_cpr_efuse: apc_corner: Corner[2]: ro_sel = 0, target quot = 631
[    0.845703] cpr_init_cpr_efuse: apc_corner: Corner[3]: ro_sel = 0, target quot = 899
[    0.853592] cpr_config: apc_corner: Timer count: 0x17700 (for 5000 us)
[    0.860426] apc_corner: 0 <--> 0 mV
[    0.864044] i2c-msm-v2 78b8000.i2c: probing driver i2c-msm-v2
[    0.869261] i2c-msm-v2 78b8000.i2c: error on clk_get(core_clk):-517
[    0.875492] i2c-msm-v2 78b8000.i2c: error probe() failed with err:-517
[    0.882225] i2c-msm-v2 78b7000.i2c: probing driver i2c-msm-v2
[    0.887775] i2c-msm-v2 78b7000.i2c: error on clk_get(core_clk):-517
[    0.893941] i2c-msm-v2 78b7000.i2c: error probe() failed with err:-517
[    0.900719] i2c-msm-v2 78b9000.i2c: probing driver i2c-msm-v2
[    0.906256] i2c-msm-v2 78b9000.i2c: error on clk_get(core_clk):-517
[    0.912430] i2c-msm-v2 78b9000.i2c: error probe() failed with err:-517
[    0.919472] msm-thermal soc:qcom,msm-thermal: msm_thermal:Failed reading node=/soc/qcom,msm-thermal, key=qcom,core-limit-temp. err=-22. KTM continues
[    0.932372] msm-thermal soc:qcom,msm-thermal: probe_therm_reset:Failed reading node=/soc/qcom,msm-thermal,
key=qcom,therm-reset-temp err=-22. KTM continues
[    0.946361] msm_thermal:get_kernel_cluster_info CPU0 topology not initialized.
[    0.953824] cpu cpu0: dev_pm_opp_get_opp_count: device OPP not found (-19)
[    0.960300] msm_thermal:get_cpu_freq_plan_len Error reading CPU0 freq table len. error:-19
[    0.968533] msm_thermal:vdd_restriction_reg_init Defer vdd rstr freq init.
[    0.975846] cpu cpu0: dev_pm_opp_get_opp_count: device OPP not found (-19)
[    0.982219] msm_thermal:get_cpu_freq_plan_len Error reading CPU0 freq table len. error:-19
[    0.991378] cpu cpu0: dev_pm_opp_get_opp_count: device OPP not found (-19)
[    0.997544] msm_thermal:get_cpu_freq_plan_len Error reading CPU0 freq table len. error:-19
[    1.013642] qcom,gcc-mdm9607 1800000.qcom,gcc: Registered GCC clocks
[    1.019451] clock-a7 b010008.qcom,clock-a7: Speed bin: 4 PVS Version: 0
[    1.025693] a7ssmux: set OPP pair(400000000 Hz: 1 uV) on cpu0
[    1.031314] a7ssmux: set OPP pair(1305600000 Hz: 7 uV) on cpu0
[    1.038805] i2c-msm-v2 78b8000.i2c: probing driver i2c-msm-v2
[    1.043587] AXI: msm_bus_scale_register_client(): msm_bus_scale_register_client: Bus driver not ready.
[    1.052935] i2c-msm-v2 78b8000.i2c: msm_bus_scale_register_client(mstr-id:86):0 (not a problem)
[    1.062006] irq: no irq domain found for /soc/wcd9xxx-irq !
[    1.069884] i2c-msm-v2 78b7000.i2c: probing driver i2c-msm-v2
[    1.074814] AXI: msm_bus_scale_register_client(): msm_bus_scale_register_client: Bus driver not ready.
[    1.083716] i2c-msm-v2 78b7000.i2c: msm_bus_scale_register_client(mstr-id:86):0 (not a problem)
[    1.093850] i2c-msm-v2 78b9000.i2c: probing driver i2c-msm-v2
[    1.098889] AXI: msm_bus_scale_register_client(): msm_bus_scale_register_client: Bus driver not ready.
[    1.107779] i2c-msm-v2 78b9000.i2c: msm_bus_scale_register_client(mstr-id:86):0 (not a problem)
[    1.167871] KPI: Bootloader start count = 24097
[    1.171364] KPI: Bootloader end count = 48481
[    1.175855] KPI: Bootloader display count = 3884474147
[    1.180825] KPI: Bootloader load kernel count = 16420
[    1.185905] KPI: Kernel MPM timestamp = 105728
[    1.190286] KPI: Kernel MPM Clock frequency = 32768
[    1.195209] socinfo_print: v0.10, id=297, ver=1.0, raw_id=72, raw_ver=0, hw_plat=8, hw_plat_ver=65536
[    1.195209]  accessory_chip=0, hw_plat_subtype=0, pmic_model=65539, pmic_die_revision=131074 foundry_id=0 serial_number=2120983948
[    1.216731] sdcard_ext_vreg: no parameters
[    1.220555] rome_vreg: no parameters
[    1.224133] emac_lan_vreg: no parameters
[    1.228177] usbcore: registered new interface driver usbfs
[    1.233156] usbcore: registered new interface driver hub
[    1.238578] usbcore: registered new device driver usb
[    1.244507] cpufreq: driver msm up and running
[    1.248425] ION heap system created
[    1.251895] msm_bus_fabric_init_driver
[    1.262563] qcom,qpnp-power-on qpnp-power-on-c7303800: PMIC@SID0 Power-on reason: Triggered from PON1 (secondary PMIC) and 'cold' boot
[    1.273747] qcom,qpnp-power-on qpnp-power-on-c7303800: PMIC@SID0: Power-off reason: Triggered from UVLO (Under Voltage Lock Out)
[    1.285430] input: qpnp_pon as /devices/virtual/input/input0
[    1.291246] PMIC@SID0: PM8019 v2.2 options: 3, 2, 2, 2
[    1.296706] Advanced Linux Sound Architecture Driver Initialized.
[    1.302493] Add group failed
[    1.305291] cfg80211: Calling CRDA to update world regulatory domain
[    1.311216] cfg80211: World regulatory domain updated:
[    1.317109] Switched to clocksource arch_mem_counter
[    1.334091] cfg80211:  DFS Master region: unset
[    1.337418] cfg80211:   (start_freq - end_freq @ bandwidth), (max_antenna_gain, max_eirp), (dfs_cac_time)
[    1.354087] cfg80211:   (2402000 KHz - 2472000 KHz @ 40000 KHz), (N/A, 2000 mBm), (N/A)
[    1.361055] cfg80211:   (2457000 KHz - 2482000 KHz @ 40000 KHz), (N/A, 2000 mBm), (N/A)
[    1.370545] NET: Registered protocol family 2
[    1.374082] cfg80211:   (2474000 KHz - 2494000 KHz @ 20000 KHz), (N/A, 2000 mBm), (N/A)
[    1.381851] cfg80211:   (5170000 KHz - 5250000 KHz @ 80000 KHz), (N/A, 2000 mBm), (N/A)
[    1.389876] cfg80211:   (5250000 KHz - 5330000 KHz @ 80000 KHz), (N/A, 2000 mBm), (N/A)
[    1.397857] cfg80211:   (5490000 KHz - 5710000 KHz @ 80000 KHz), (N/A, 2000 mBm), (N/A)
[    1.405841] cfg80211:   (5735000 KHz - 5835000 KHz @ 80000 KHz), (N/A, 2000 mBm), (N/A)
[    1.413795] cfg80211:   (57240000 KHz - 63720000 KHz @ 2160000 KHz), (N/A, 0 mBm), (N/A)
[    1.422355] TCP established hash table entries: 1024 (order: 0, 4096 bytes)
[    1.428921] TCP bind hash table entries: 1024 (order: 0, 4096 bytes)
[    1.435192] TCP: Hash tables configured (established 1024 bind 1024)
[    1.441528] TCP: reno registered
[    1.444738] UDP hash table entries: 256 (order: 0, 4096 bytes)
[    1.450521] UDP-Lite hash table entries: 256 (order: 0, 4096 bytes)
[    1.456950] NET: Registered protocol family 1
[    1.462779] futex hash table entries: 256 (order: -1, 3072 bytes)
[    1.474555] msgmni has been set to 115
[    1.478551] Block layer SCSI generic (bsg) driver version 0.4 loaded (major 251)
[    1.485041] io scheduler noop registered
[    1.488818] io scheduler deadline registered
[    1.493200] io scheduler cfq registered (default)
[    1.502142] msm_rpm_log_probe: OK
[    1.506717] msm_serial_hs module loaded
[    1.509803] msm_serial_hsl_probe: detected port #0 (ttyHSL0)
[    1.515324] AXI: get_pdata(): Error: Client name not found
[    1.520626] AXI: msm_bus_cl_get_pdata(): client has to provide missing entry for successful registration
[    1.530171] msm_serial_hsl_probe: Bus scaling is disabled                      [    1.074814] AXI: msm_bus_scale_register_client(): msm_bus_scale_register_client: Bus driver not ready.
[    1.083716] i2c-msm-v2 78b7000.i2c: msm_bus_scale_register_client(mstr-id:86):0 (not a problem)
[    1.093850] i2c-msm-v2 78b9000.i2c: probing driver i2c-msm-v2
[    1.098889] AXI: msm_bus_scale_register_client(): msm_bus_scale_register_client: Bus driver not ready.
[    1.107779] i2c-msm-v2 78b9000.i2c: msm_bus_scale_register_client(mstr-id:86):0 (not a problem)
[    1.167871] KPI: Bootloader start count = 24097
[    1.171364] KPI: Bootloader end count = 48481
[    1.175855] KPI: Bootloader display count = 3884474147
[    1.180825] KPI: Bootloader load kernel count = 16420
[    1.185905] KPI: Kernel MPM timestamp = 105728
[    1.190286] KPI: Kernel MPM Clock frequency = 32768
[    1.195209] socinfo_print: v0.10, id=297, ver=1.0, raw_id=72, raw_ver=0, hw_plat=8, hw_plat_ver=65536
[    1.195209]  accessory_chip=0, hw_plat_subtype=0, pmic_model=65539, pmic_die_revision=131074 foundry_id=0 serial_number=2120983948
[    1.216731] sdcard_ext_vreg: no parameters
[    1.220555] rome_vreg: no parameters
[    1.224133] emac_lan_vreg: no parameters
[    1.228177] usbcore: registered new interface driver usbfs
[    1.233156] usbcore: registered new interface driver hub
[    1.238578] usbcore: registered new device driver usb
[    1.244507] cpufreq: driver msm up and running
[    1.248425] ION heap system created
[    1.251895] msm_bus_fabric_init_driver
[    1.262563] qcom,qpnp-power-on qpnp-power-on-c7303800: PMIC@SID0 Power-on reason: Triggered from PON1 (secondary PMIC) and 'cold' boot
[    1.273747] qcom,qpnp-power-on qpnp-power-on-c7303800: PMIC@SID0: Power-off reason: Triggered from UVLO (Under Voltage Lock Out)
[    1.285430] input: qpnp_pon as /devices/virtual/input/input0
[    1.291246] PMIC@SID0: PM8019 v2.2 options: 3, 2, 2, 2
[    1.296706] Advanced Linux Sound Architecture Driver Initialized.
[    1.302493] Add group failed
[    1.305291] cfg80211: Calling CRDA to update world regulatory domain
[    1.311216] cfg80211: World regulatory domain updated:
[    1.317109] Switched to clocksource arch_mem_counter
[    1.334091] cfg80211:  DFS Master region: unset
[    1.337418] cfg80211:   (start_freq - end_freq @ bandwidth), (max_antenna_gain, max_eirp), (dfs_cac_time)
[    1.354087] cfg80211:   (2402000 KHz - 2472000 KHz @ 40000 KHz), (N/A, 2000 mBm), (N/A)
[    1.361055] cfg80211:   (2457000 KHz - 2482000 KHz @ 40000 KHz), (N/A, 2000 mBm), (N/A)
[    1.370545] NET: Registered protocol family 2
[    1.374082] cfg80211:   (2474000 KHz - 2494000 KHz @ 20000 KHz), (N/A, 2000 mBm), (N/A)
[    1.381851] cfg80211:   (5170000 KHz - 5250000 KHz @ 80000 KHz), (N/A, 2000 mBm), (N/A)
[    1.389876] cfg80211:   (5250000 KHz - 5330000 KHz @ 80000 KHz), (N/A, 2000 mBm), (N/A)
[    1.397857] cfg80211:   (5490000 KHz - 5710000 KHz @ 80000 KHz), (N/A, 2000 mBm), (N/A)
[    1.405841] cfg80211:   (5735000 KHz - 5835000 KHz @ 80000 KHz), (N/A, 2000 mBm), (N/A)
[    1.413795] cfg80211:   (57240000 KHz - 63720000 KHz @ 2160000 KHz), (N/A, 0 mBm), (N/A)
[    1.422355] TCP established hash table entries: 1024 (order: 0, 4096 bytes)
[    1.428921] TCP bind hash table entries: 1024 (order: 0, 4096 bytes)
[    1.435192] TCP: Hash tables configured (established 1024 bind 1024)
[    1.441528] TCP: reno registered
[    1.444738] UDP hash table entries: 256 (order: 0, 4096 bytes)
[    1.450521] UDP-Lite hash table entries: 256 (order: 0, 4096 bytes)
[    1.456950] NET: Registered protocol family 1
[    1.462779] futex hash table entries: 256 (order: -1, 3072 bytes)
[    1.474555] msgmni has been set to 115
[    1.478551] Block layer SCSI generic (bsg) driver version 0.4 loaded (major 251)
[    1.485041] io scheduler noop registered
[    1.488818] io scheduler deadline registered
[    1.493200] io scheduler cfq registered (default)
[    1.502142] msm_rpm_log_probe: OK
[    1.506717] msm_serial_hs module loaded
[    1.509803] msm_serial_hsl_probe: detected port #0 (ttyHSL0)
[    1.515324] AXI: get_pdata(): Error: Client name not found
[    1.520626] AXI: msm_bus_cl_get_pdata(): client has to provide missing entry for successful registration
[    1.530171] msm_serial_hsl_probe: Bus scaling is disabled
[    1.535696] 78b3000.serial: ttyHSL0 at MMIO 0x78b3000 (irq = 153, base_baud = 460800 [    1.544155] msm_hsl_console_setup: console setup on port #0
[    1.548727] console [ttyHSL0] enabled
[    1.548727] console [ttyHSL0] enabled
[    1.556014] bootconsole [uart0] disabled
[    1.556014] bootconsole [uart0] disabled
[    1.564212] msm_serial_hsl_init: driver initialized
[    1.578450] brd: module loaded
[    1.582920] loop: module loaded
[    1.589183] sps: BAM device 0x07984000 is not registered yet.
[    1.594234] sps:BAM 0x07984000 is registered.
[    1.598072] msm_nand_bam_init: msm_nand_bam_init: BAM device registered: bam_handle 0xc69f6400
[    1.607103] sps:BAM 0x07984000 (va:0xc89a0000) enabled: ver:0x18, number of pipes:7
[    1.616588] msm_nand_parse_smem_ptable: Parsing partition table info from SMEM
[    1.622805] msm_nand_parse_smem_ptable: SMEM partition table found: ver: 4 len: 17
[    1.630391] msm_nand_version_check: nand_major:1, nand_minor:5, qpic_major:1, qpic_minor:5
[    1.638642] msm_nand_scan: NAND Id: 0x1590aa98 Buswidth: 8Bits Density: 256 MByte
[    1.646069] msm_nand_scan: pagesize: 2048 Erasesize: 131072 oobsize: 128 (in Bytes)
[    1.653676] msm_nand_scan: BCH ECC: 8 Bit
[    1.657710] msm_nand_scan: CFG0: 0x290408c0,           CFG1: 0x0804715c
[    1.657710]             RAWCFG0: 0x2b8400c0,        RAWCFG1: 0x0005055d
[    1.657710]           ECCBUFCFG: 0x00000203,      ECCBCHCFG: 0x42040d10
[    1.657710]           RAWECCCFG: 0x42000d11, BAD BLOCK BYTE: 0x000001c5
[    1.684101] Creating 17 MTD partitions on "7980000.nand":
[    1.689447] 0x000000000000-0x000000140000 : "sbl"
[    1.694867] 0x000000140000-0x000000280000 : "mibib"
[    1.699560] 0x000000280000-0x000000e80000 : "efs2"
[    1.704408] 0x000000e80000-0x000000f40000 : "tz"
[    1.708934] 0x000000f40000-0x000000fa0000 : "rpm"
[    1.713625] 0x000000fa0000-0x000001000000 : "aboot"
[    1.718582] 0x000001000000-0x0000017e0000 : "boot"
[    1.723281] 0x0000017e0000-0x000002820000 : "scrub"
[    1.728174] 0x000002820000-0x000005020000 : "modem"
[    1.732968] 0x000005020000-0x000005420000 : "rfbackup"
[    1.738156] 0x000005420000-0x000005820000 : "oem"
[    1.742770] 0x000005820000-0x000005f00000 : "recovery"
[    1.747972] 0x000005f00000-0x000009100000 : "cache"
[    1.752787] 0x000009100000-0x000009a40000 : "recoveryfs"
[    1.758389] 0x000009a40000-0x00000aa40000 : "cdrom"
[    1.762967] 0x00000aa40000-0x00000ba40000 : "jrdresource"
[    1.768407] 0x00000ba40000-0x000010000000 : "system"
[    1.773239] msm_nand_probe: NANDc phys addr 0x7980000, BAM phys addr 0x7984000, BAM IRQ 164
[    1.781074] msm_nand_probe: Allocated DMA buffer at virt_addr 0xc7840000, phys_addr 0x87840000
[    1.791872] PPP generic driver version 2.4.2
[    1.801126] cnss_sdio 87a00000.qcom,cnss-sdio: CNSS SDIO Driver registered
[    1.807554] msm_otg 78d9000.usb: msm_otg probe
[    1.813333] msm_otg 78d9000.usb: OTG regs = c88f8000
[    1.820702] gbridge_init: gbridge_init successs.
[    1.826344] msm_otg 78d9000.usb: phy_reset: success
[    1.830294] qcom,qpnp-rtc qpnp-rtc-c7307000: rtc core: registered qpnp_rtc as rtc0
[    1.838474] i2c /dev entries driver
[    1.842459] unable to find DT imem DLOAD mode node
[    1.846588] unable to find DT imem EDLOAD mode node
[    1.851332] unable to find DT imem dload-type node
[    1.856921] bq24295-charger 4-006b: bq24295 probe enter
[    1.861161] qcom,iterm-ma = 128
[    1.864476] bq24295_otg_vreg: no parameters
[    1.868502] charger_core_register: Charger Core Version 5.0.0(Built at 20151202-21:36)!
[    1.877007] i2c-msm-v2 78b8000.i2c: msm_bus_scale_register_client(mstr-id:86):0x3 (ok)
[    1.885559] bq24295-charger 4-006b: bq24295_set_bhot_mode 3
[    1.890150] bq24295-charger 4-006b: power_good is 1,vbus_stat is 2
[    1.896588] bq24295-charger 4-006b: bq24295_set_thermal_threshold 100
[    1.902952] bq24295-charger 4-006b: bq24295_set_sys_min 3700
[    1.908639] bq24295-charger 4-006b: bq24295_set_max_target_voltage 4150
[    1.915223] bq24295-charger 4-006b: bq24295_set_recharge_threshold 300
[    1.922119] bq24295-charger 4-006b: bq24295_set_terminal_current_limit iterm_disabled=0, iterm_ma=128
[    1.930917] bq24295-charger 4-006b: bq24295_set_precharge_current_limit bdi->prech_cur=128
[    1.940038] bq24295-charger 4-006b: bq24295_set_safty_timer 0
[    1.945088] bq24295-charger 4-006b: bq24295_set_input_voltage_limit 4520
[    1.972949] sdhci: Secure Digital Host Controller Interface driver
[    1.978151] sdhci: Copyright(c) Pierre Ossman
[    1.982441] sdhci-pltfm: SDHCI platform and OF driver helper
[    1.989092] sdhci_msm 7824900.sdhci: sdhci_msm_probe: ICE device is not enabled
[    1.995473] sdhci_msm 7824900.sdhci: No vreg data found for vdd
[    2.001530] sdhci_msm 7824900.sdhci: sdhci_msm_pm_qos_parse_irq: error -22 reading irq cpu
[    2.009809] sdhci_msm 7824900.sdhci: sdhci_msm_pm_qos_parse: PM QoS voting for IRQ will be disabled
[    2.018600] sdhci_msm 7824900.sdhci: sdhci_msm_pm_qos_parse: PM QoS voting for cpu group will be disabled
[    2.030541] sdhci_msm 7824900.sdhci: sdhci_msm_probe: sdiowakeup_irq = 353
[    2.036867] sdhci_msm 7824900.sdhci: No vmmc regulator found
[    2.042027] sdhci_msm 7824900.sdhci: No vqmmc regulator found
[    2.048266] mmc0: SDHCI controller on 7824900.sdhci [7824900.sdhci] using 32-bit ADMA in legacy mode
[    2.080401] Welcome to pca955x_probe!!
[    2.084362] leds-pca955x 3-0020: leds-pca955x: Using pca9555 16-bit LED driver at slave address 0x20
[    2.095400] sdhci_msm 7824900.sdhci: card claims to support voltages below defined range
[    2.103125] i2c-msm-v2 78b7000.i2c: msm_bus_scale_register_client(mstr-id:86):0x5 (ok)
[    2.114183] msm_otg 78d9000.usb: Avail curr from USB = 1500
[    2.120251] come to USB_SDP_CHARGER!
[    2.123215] Welcome to sn3199_probe!
[    2.126718] leds-sn3199 5-0064: leds-sn3199: Using sn3199 9-bit LED driver at slave address 0x64
[    2.136511] sn3199->led_en_gpio=21
[    2.139143] i2c-msm-v2 78b9000.i2c: msm_bus_scale_register_client(mstr-id:86):0x6 (ok)
[    2.150207] usbcore: registered new interface driver usbhid
[    2.154864] usbhid: USB HID core driver
[    2.159825] sps:BAM 0x078c4000 is registered.
[    2.163573] bimc-bwmon 408000.qcom,cpu-bwmon: BW HWmon governor registered.
[    2.171080] devfreq soc:qcom,cpubw: Couldn't update frequency transition information.
[    2.178513] coresight-fuse a601c.fuse: QPDI fuse not specified
[    2.184242] coresight-fuse a601c.fuse: Fuse initialized
[    2.192407] coresight-csr 6001000.csr: CSR initialized
[    2.197263] coresight-tmc 6026000.tmc: Byte Counter feature enabled
[    2.203204] sps:BAM 0x06084000 is registered.
[    2.207301] coresight-tmc 6026000.tmc: TMC initialized
[    2.212681] coresight-tmc 6025000.tmc: TMC initialized
[    2.220071] nidnt boot config: 0
[    2.224563] mmc0: new ultra high speed SDR50 SDIO card at address 0001
[    2.231120] coresight-tpiu 6020000.tpiu: NIDnT on SDCARD only mode
[    2.236440] coresight-tpiu 6020000.tpiu: TPIU initialized
[    2.242808] coresight-replicator 6024000.replicator: REPLICATOR initialized
[    2.249372] coresight-stm 6002000.stm: STM initialized
[    2.255034] coresight-hwevent 606c000.hwevent: Hardware Event driver initialized
[    2.262312] Netfilter messages via NETLINK v0.30.
[    2.266306] nf_conntrack version 0.5.0 (920 buckets, 3680 max)
[    2.272312] ctnetlink v0.93: registering with nfnetlink.
[    2.277565] ip_set: protocol 6
[    2.280568] ip_tables: (C) 2000-2006 Netfilter Core Team
[    2.285723] arp_tables: (C) 2002 David S. Miller
[    2.290146] TCP: cubic registered
[    2.293915] NET: Registered protocol family 10
[    2.298740] ip6_tables: (C) 2000-2006 Netfilter Core Team
[    2.303407] sit: IPv6 over IPv4 tunneling driver
[    2.308481] NET: Registered protocol family 17
[    2.312340] bridge: automatic filtering via arp/ip/ip6tables has been deprecated. Update your scripts to load br_netfilter if you need this.
[    2.325094] Bridge firewalling registered
[    2.328930] Ebtables v2.0 registered
[    2.333260] NET: Registered protocol family 27
[    2.341362] battery_core_register: Battery Core Version 5.0.0(Built at 20151202-21:36)!
[    2.348466] pmu_battery_probe: vbat_channel=21, tbat_channel=17
[    2.420236] ubi0: attaching mtd16
[    2.723941] ubi0: scanning is finished
[    2.732997] ubi0: attached mtd16 (name "system", size 69 MiB)
[    2.737783] ubi0: PEB size: 131072 bytes (128 KiB), LEB size: 126976 bytes
[    2.744601] ubi0: min./max. I/O unit sizes: 2048/2048, sub-page size 2048
[    2.751333] ubi0: VID header offset: 2048 (aligned 2048), data offset: 4096
[    2.758540] ubi0: good PEBs: 556, bad PEBs: 2, corrupted PEBs: 0
[    2.764305] ubi0: user volume: 3, internal volumes: 1, max. volumes count: 128
[    2.771476] ubi0: max/mean erase counter: 192/64, WL threshold: 4096, image sequence number: 35657280
[    2.780708] ubi0: available PEBs: 0, total reserved PEBs: 556, PEBs reserved for bad PEB handling: 38
[    2.789921] ubi0: background thread "ubi_bgt0d" started, PID 96
[    2.796395] android_bind cdev: 0xC6583E80, name: ci13xxx_msm
[    2.801508] file system registered
[    2.804974] mbim_init: initialize 1 instances
[    2.809228] mbim_init: Initialized 1 ports
[    2.815074] rndis_qc_init: initialize rndis QC instance
[    2.819713] jrd device_desc.bcdDevice: [0x0242]
[    2.823779] android_bind scheduled usb start work: name: ci13xxx_msm
[    2.830230] android_usb gadget: android_usb ready
[    2.834845] msm_hsusb msm_hsusb: [ci13xxx_start] hw_ep_max = 32
[    2.840741] msm_hsusb msm_hsusb: CI13XXX_CONTROLLER_RESET_EVENT received
[    2.847433] msm_hsusb msm_hsusb: CI13XXX_CONTROLLER_UDC_STARTED_EVENT received
[    2.855851] input: gpio-keys as /devices/soc:gpio_keys/input/input1
[    2.861452] qcom,qpnp-rtc qpnp-rtc-c7307000: setting system clock to 1970-01-01 06:36:41 UTC (23801)
[    2.870315] open file error /usb_conf/usb_config.ini
[    2.876412] jrd_usb_start_work open file erro /usb_conf/usb_config.ini, retry_count:0
[    2.884324] parse_legacy_cluster_params(): Ignoring cluster params
[    2.889468] ------------[ cut here ]------------
[    2.894186] WARNING: CPU: 0 PID: 1 at /home/linux3/jrd/yanping.an/ee40/0810/MDM9607.LE.1.0-00130/apps_proc/oe-core/build/tmp-glibc/work-shared/mdm9607/kernel-source/drivers/cpuidle/lpm-levels-of.c:739 parse_cluster+0xb50/0xcb4()
[    2.914366] Modules linked in:
[    2.917339] CPU: 0 PID: 1 Comm: swapper Not tainted 3.18.20 #1
[    2.923171] [<c00132ac>] (unwind_backtrace) from [<c0011460>] (show_stack+0x10/0x14)
[    2.931092] [<c0011460>] (show_stack) from [<c001c6ac>] (warn_slowpath_common+0x68/0x88)
[    2.939175] [<c001c6ac>] (warn_slowpath_common) from [<c001c75c>] (warn_slowpath_null+0x18/0x20)
[    2.947895] [<c001c75c>] (warn_slowpath_null) from [<c034e180>] (parse_cluster+0xb50/0xcb4)
[    2.956189] [<c034e180>] (parse_cluster) from [<c034b6b4>] (lpm_probe+0xc/0x1d4)
[    2.963527] [<c034b6b4>] (lpm_probe) from [<c024857c>] (platform_drv_probe+0x30/0x7c)
[    2.971380] [<c024857c>] (platform_drv_probe) from [<c0246d54>] (driver_probe_device+0xb8/0x1e8)
[    2.980118] [<c0246d54>] (driver_probe_device) from [<c0246f30>] (__driver_attach+0x68/0x8c)
[    2.988467] [<c0246f30>] (__driver_attach) from [<c02455d0>] (bus_for_each_dev+0x6c/0x90)
[    2.996626] [<c02455d0>] (bus_for_each_dev) from [<c02465a4>] (bus_add_driver+0xe0/0x1c8)
[    3.004786] [<c02465a4>] (bus_add_driver) from [<c02477bc>] (driver_register+0x9c/0xe0)
[    3.012739] [<c02477bc>] (driver_register) from [<c080c3d8>] (lpm_levels_module_init+0x14/0x38)
[    3.021459] [<c080c3d8>] (lpm_levels_module_init) from [<c0008980>] (do_one_initcall+0xf8/0x1a0)
[    3.030217] [<c0008980>] (do_one_initcall) from [<c07e7d4c>] (kernel_init_freeable+0xf0/0x1b0)
[    3.038818] [<c07e7d4c>] (kernel_init_freeable) from [<c0582d48>] (kernel_init+0x8/0xe4)
[    3.046888] [<c0582d48>] (kernel_init) from [<c000dda0>] (ret_from_fork+0x14/0x34)
[    3.054432] ---[ end trace e9ec50b1ec4c8f73 ]---
[    3.059012] ------------[ cut here ]------------
[    3.063604] WARNING: CPU: 0 PID: 1 at /home/linux3/jrd/yanping.an/ee40/0810/MDM9607.LE.1.0-00130/apps_proc/oe-core/build/tmp-glibc/work-shared/mdm9607/kernel-source/drivers/cpuidle/lpm-levels-of.c:739 parse_cluster+0xb50/0xcb4()
[    3.083858] Modules linked in:
[    3.086870] CPU: 0 PID: 1 Comm: swapper Tainted: G        W      3.18.20 #1
[    3.093814] [<c00132ac>] (unwind_backtrace) from [<c0011460>] (show_stack+0x10/0x14)
[    3.101575] [<c0011460>] (show_stack) from [<c001c6ac>] (warn_slowpath_common+0x68/0x88)
[    3.109641] [<c001c6ac>] (warn_slowpath_common) from [<c001c75c>] (warn_slowpath_null+0x18/0x20)
[    3.118412] [<c001c75c>] (warn_slowpath_null) from [<c034e180>] (parse_cluster+0xb50/0xcb4)
[    3.126745] [<c034e180>] (parse_cluster) from [<c034b6b4>] (lpm_probe+0xc/0x1d4)
[    3.134126] [<c034b6b4>] (lpm_probe) from [<c024857c>] (platform_drv_probe+0x30/0x7c)
[    3.141906] [<c024857c>] (platform_drv_probe) from [<c0246d54>] (driver_probe_device+0xb8/0x1e8)
[    3.150702] [<c0246d54>] (driver_probe_device) from [<c0246f30>] (__driver_attach+0x68/0x8c)
[    3.159120] [<c0246f30>] (__driver_attach) from [<c02455d0>] (bus_for_each_dev+0x6c/0x90)
[    3.167285] [<c02455d0>] (bus_for_each_dev) from [<c02465a4>] (bus_add_driver+0xe0/0x1c8)
[    3.175444] [<c02465a4>] (bus_add_driver) from [<c02477bc>] (driver_register+0x9c/0xe0)
[    3.183398] [<c02477bc>] (driver_register) from [<c080c3d8>] (lpm_levels_module_init+0x14/0x38)
[    3.192107] [<c080c3d8>] (lpm_levels_module_init) from [<c0008980>] (do_one_initcall+0xf8/0x1a0)
[    3.200877] [<c0008980>] (do_one_initcall) from [<c07e7d4c>] (kernel_init_freeable+0xf0/0x1b0)
[    3.209475] [<c07e7d4c>] (kernel_init_freeable) from [<c0582d48>] (kernel_init+0x8/0xe4)
[    3.217542] [<c0582d48>] (kernel_init) from [<c000dda0>] (ret_from_fork+0x14/0x34)
[    3.225090] ---[ end trace e9ec50b1ec4c8f74 ]---
[    3.229667] /soc/qcom,lpm-levels/qcom,pm-cluster@0: No CPU phandle, assuming single cluster
[    3.239954] qcom,cc-debug-mdm9607 1800000.qcom,debug: Registered Debug Mux successfully
[    3.247619] emac_lan_vreg: disabling
[    3.250507] mem_acc_corner: disabling
[    3.254196] clock_late_init: Removing enables held for handed-off clocks
[    3.262690] ALSA device list:
[    3.264732]   No soundcard [    3.274083] UBIFS (ubi0:0): background thread "ubifs_bgt0_0" started, PID 102
[    3.305224] UBIFS (ubi0:0): recovery needed
[    3.466156] UBIFS (ubi0:0): recovery completed
[    3.469627] UBIFS (ubi0:0): UBIFS: mounted UBI device 0, volume 0, name "rootfs"
[    3.476987] UBIFS (ubi0:0): LEB size: 126976 bytes (124 KiB), min./max. I/O unit sizes: 2048 bytes/2048 bytes
[    3.486876] UBIFS (ubi0:0): FS size: 45838336 bytes (43 MiB, 361 LEBs), journal size 9023488 bytes (8 MiB, 72 LEBs)
[    3.497417] UBIFS (ubi0:0): reserved for root: 0 bytes (0 KiB)
[    3.503078] UBIFS (ubi0:0): media format: w4/r0 (latest is w4/r0), UUID 4DBB2F12-34EB-43B6-839B-3BA930765BAE, small LPT model
[    3.515582] VFS: Mounted root (ubifs filesystem) on device 0:12.
[    3.520940] Freeing unused kernel memory: 276K (c07e7000 - c082c000)
INIT: version 2.88 booting

1 August 2017

Paul Wise: FLOSS Activities July 2017

Changes

Issues

Review

Administration
  • Debian: fsck/reboot a buildd, reboot a segfaulting buildd, report/fix broken hoster contact, ping hoster about down machines, forcibly reset backup machine, merged cache patch for network-test.d.o, do some samhain dances, fix two stunnel services, update an IP address in LDAP, fix /etc/aliases on one host, reboot 1 non-responsive VM
  • Debian mentors: security updates, reboot
  • Debian wiki: whitelist several email addresses
  • Debian build log scanner: deploy my changes
  • Debian PTS: deploy my changes
  • Openmoko: security updates & reboots

Communication
  • Ping Advogato users on Planet Debian about updating/removing their feeds since it shut down
  • Invite deepin to the Debian derivatives census
  • Welcome Deepin to the Debian derivatives census
  • Inquire about the status of GreenboneOS, HandyLinux

Sponsors All work was done on a volunteer basis.

1 July 2017

Paul Wise: FLOSS Activities June 2017

Changes

Issues

Review

Administration
  • Debian: redirect 2 users to support channels, redirect 1 person to the mirrors team, investigate SMTP TLS question, fix ACL issue, restart dead exim4 service
  • Debian mentors: service restarts, security updates & reboot
  • Debian QA: deploy my changes
  • Debian website: release related rebuilds, rebuild installation-guide
  • Debian wiki: whitelist several email addresses, whitelist 1 domain
  • Debian package tracker: deploy my changes
  • Debian derivatives census: deploy my changes
  • Openmoko: security updates & reboots.

Communication

Sponsors All work was done on a volunteer basis.

24 March 2017

Jo Shields: Mono repository changes, beginning Mono vNext

Up to now, Linux packages on mono-project.com have come in two flavours RPM built for CentOS 7 (and RHEL 7), and .deb built for Debian 7. Universal packages that work on the named distributions, and anything newer. Except that s not entirely true. Firstly, there have been compatibility repositories users need to add, to deal with ABI changes in libtiff, libjpeg, and Apache, since Debian 7. Then there s the packages for ARM64 and PPC64el neither of those architectures is available in Debian 7, so they re published in the 7 repo but actually built on 8. A large reason for this is difficulty in our package publishing pipeline apt only allows one version-architecture mix in the repository at once, so I can t have, say, 4.8.0.520-0xamarin1 built on AMD64 on both Debian 7 and Ubuntu 16.04. We ve been working hard on a new package build/publish pipeline, which can properly support multiple distributions, based on Jenkins Pipeline. This new packaging system also resolves longstanding issues such as can t really build anything except Mono and Architecture: All packages still get built on Jo s laptop, with no public build logs So, here s the old build matrix:
Distribution Architectures
Debian 7 ARM hard float, ARM soft float, ARM64 (actually Debian 8), AMD64, i386, PPC64el (actually Debian 8)
CentOS 7 AMD64
And here s the new one:
Distribution Architectures
Debian 7 ARM hard float (v7), ARM soft float, AMD64, i386
Debian 8 ARM hard float (v7), ARM soft float, ARM64, AMD64, i386, PPC64el
Raspbian 8 ARM hard float (v6)
Ubuntu 14.04 ARM hard float (v7), ARM64, AMD64, i386, PPC64el
Ubuntu 16.04 ARM hard float (v7), ARM64, AMD64, i386, PPC64el
CentOS 6 AMD64, i386
CentOS 7 AMD64
The compatibility repositories will no longer be needed on recent Ubuntu or Debian just use the right repository for your system. If your distribution isn t listed sorry, but we need to draw a line somewhere on support, and the distributions listed here are based on heavy analysis of our web server logs and bug requests. You ll want to change your package manager repositories to reflect your system more accurately, once Mono vNext is published. We re debating some kind of automated handling of this, but I m loathe to touch users sources.list without their knowledge. CentOS builds are going to be late I ve been doing all my prototyping against the Debian builds, as I have better command of the tooling. Hopefully no worse than a week or two. edit I guess Ubuntu 12.04 is coming back too, despite being EOL, for TravisCI support.

4 December 2016

Jo Shields: A quick introduction to Flatpak

Releasing ISV applications on Linux is often hard. The ABI of all the libraries you need changes seemingly weekly. Hence you have the option of bundling the world, or building a thousand releases to cover a thousand distribution versions. As a case in point, when MonoDevelop started bundling a C Git library instead of using a C# git implementation, it gained dependencies on all sorts of fairly weak ABI libraries whose exact ABI mix was not consistent across any given pair of distro releases. This broke our policy of releasing works on anything .deb and .rpm packages. As a result, I pretty much gave up on packaging MonoDevelop upstream with version 5.10. Around the 6.1 release window, I decided to take re-evaluate question. I took a closer look at some of the fancy-pants new distribution methods that get a lot of coverage in the Linux press: Snap, AppImage, and Flatpak. I started with AppImage. It s very good and appealing for its specialist areas (no external requirements for end users), but it s kinda useless at solving some of our big areas (the ABI-vs-bundling problem, updating in general). Next, I looked at Flatpak (once xdg-app). I liked the concept a whole lot. There s a simple 3-tier dependency hierarchy: Applications, Runtimes, and Extensions. An application depends on exactly one runtime. Runtimes are root-level images with no dependencies of their own. Extensions are optional add-ons for applications. Anything not provided in your target runtime, you bundle. And an integrated updates mechanism allows for multiple branches and multiple releases parallel-installed (e.g. alpha & stable, easily switched). There s also security-related sandboxing features, but my main concerns on a first examination were with the dependency and distribution questions. That said, some users might be happier running Microsoft software on their Linux desktop if that software is locked up inside a sandbox, so I ve decided to embrace that functionality rather than seek to avoid it. I basically stopped looking at this point (sorry Snap!). Flatpak provided me with all the functionality I wanted, with an extremely helpful and responsive upstream. I got to work on trying to package up MonoDevelop. Flatpak (optionally!) uses a JSON manifest for building stuff. Because Mono is still largely stuck in a Gtk+2 world, I opted for the simplest runtime, org.freedesktop.Runtime, and bundled stuff like Gtk+ into the application itself. Some gentle patching here & there resulted in this repository. Every time I came up with an exciting new edge case, upstream would suggest a workaround within hours or failing that, added new features to Flatpak just to support my needs (e.g. allowing /dev/kvm to optionally pass through the sandbox). The end result is, as of the upcoming 0.8.0 release of Flatpak, from a clean install of the flatpak package to having a working MonoDevelop is a single command: flatpak install --user --from https://download.mono-project.com/repo/monodevelop.flatpakref For the current 0.6.x versions of Flatpak, the user also needs to flatpak remote-add --user --from gnome https://sdk.gnome.org/gnome.flatpakrepo first this step will be automated in 0.8.0. This will download org.freedesktop.Runtime, then com.xamarin.MonoDevelop; export icons n stuff into your user environment so you can just click to start. There s some lingering experience issues due the sandbox which are on my radar. Run on external console doesn t work, for example, or open containing folder . There are people working on that (a missing DBus# feature to allow breaking out of the sandbox). But overall, I m pretty happy. I won t be entirely satisfied until I have something approximating feature equivalence to the old .debs. I don t think that will ever quite be there, since there s just no rational way to allow arbitrary /usr stuff into the sandbox, but it should provide a decent basis for a QA-able, supportable Linux MonoDevelop. And we can use this work as a starting point for any further fancy features on Linux. Gtk# app development in Flatpak MonoDevelop Editing MonoDevelop in MonoDevelop. *Inception noise*

21 August 2015

Simon Kainz: DUCK challenge: Final week

Well, here are the stats for the final week of the DUCK challenge as well as DebConf15: So we had 21 packages fixed and uploaded by 14 different uploaders. People were really working hard on this during DebConf. A big "Thank You" to you!! Since the start of this challenge, a total of 89 packages, were fixed. Here is a quick overview:
Week 1 Week 2 Week 3 Week 4 Week 5 Week 6 Week 7
# Packages 10 15 10 14 10 9 21
Total 10 25 35 49 59 68 89
Thank you all for participating - either on purpose or "accidentially": Some people were really surprised as i sneaked up on them at DebConf15, confronting them with a green lighter! I just tried to put even more fun into Debian, i hope this worked out Pevious articles are here: Week 1, Week 2, Week 3, Week 4, Week 5,Week 6.

24 July 2015

Simon Kainz: DUCK challenge: week 3

One more update on the the DUCK challenge: In the current week, the following packages were fixed and uploaded into unstable: So we had 10 packages fixed and uploaded by 8 different uploaders. A big "Thank You" to you!! Since the start of this challenge, a total of 35 packages, uploaded by 25 different persons were fixed. Here is a quick overview:
Week 1 Week 2 Week 3 Week 4 Week 5 Week 6 Week 7
# Packages 10 15 10 - - - -
Total 10 25 35 - - - -
The list of the fixed and updated packages is availabe here. I will try to update this ~daily. If I missed one of your uploads, please drop me a line. There is still lots of time till the end of DebConf15 and the end of the DUCK Challenge, so please get involved. Pevious articles are here: Week 1, Week 2.

20 June 2015

Lunar: Reproducible builds: week 5 in Stretch cycle

What happened about the reproducible builds effort for this week: Toolchain fixes Uploads that should help other packages: Patch submitted for toolchain issues: Some discussions have been started in Debian and with upstream: Packages fixed The following 8 packages became reproducible due to changes in their build dependencies: access-modifier-checker, apache-log4j2, jenkins-xstream, libsdl-perl, maven-shared-incremental, ruby-pygments.rb, ruby-wikicloth, uimaj. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which did not make their way to the archive yet: Discussions that have been started: reproducible.debian.net Holger Levsen added two new package sets: pkg-javascript-devel and pkg-php-pear. The list of packages with and without notes are now sorted by age of the latest build. Mattia Rizzolo added support for email notifications so that maintainers can be warned when a package becomes unreproducible. Please ask Mattia or Holger or in the #debian-reproducible IRC channel if you want to be notified for your packages! strip-nondeterminism development Andrew Ayer fixed the gzip handler so that it skip adding a predetermined timestamp when there was none. Documentation update Lunar added documentation about mtimes of file extracted using unzip being timezone dependent. He also wrote a short example on how to test reproducibility. Stephen Kitt updated the documentation about timestamps in PE binaries. Documentation and scripts to perform weekly reports were published by Lunar. Package reviews 50 obsolete reviews have been removed, 51 added and 29 updated this week. Thanks Chris West and Mathieu Bridon amongst others. New identified issues: Misc. Lunar will be talking (in French) about reproducible builds at Pas Sage en Seine on June 19th, at 15:00 in Paris. Meeting will happen this Wednesday, 19:00 UTC.

15 June 2015

Lunar: Reproducible builds: week 7 in Stretch cycle

What happened about the reproducible builds effort for this week: Presentations On June 7th, Reiner Herrmann presented the project at the Gulaschprogrammiernacht 15 in Karlsruhe, Germany. Video and audio recordings in German are available, and so are the slides in English. Toolchain fixes Daniel Kahn Gillmor's report on help2man started a discussion with Brendan O'Dea and Ximin Luo about standardizing a common environment variable that would provide a replacement for an embedded build date. After various proposals and research by Ximin about date handling in several programming languages, the best solution seems to define SOURCE_DATE_EPOCH with a value suitable for gmtime(3).
  1. Martin Borgert wondered if Sphinx could be changed in a way that would avoid having to tweak debian/rules in packages using it to produce HTML documentation.
Daniel Kahn Gillmor opened a new report about icont producing unreproducible binaries. Packages fixed The following 32 packages became reproducible due to changes in their build dependencies: agda, alex, c2hs, clutter-1.0, colorediffs-extension, cpphs, darcs-monitor, dispmua, haskell-curl, haskell-glfw, haskell-glib, haskell-gluraw, haskell-glut, haskell-gnutls, haskell-gsasl, haskell-hfuse, haskell-hledger-interest, haskell-hslua, haskell-hsqml, haskell-hssyck, haskell-libxml-sax, haskell-openglraw, haskell-readline, haskell-terminfo, haskell-x11, jarjar-maven-plugin, kxml2, libcgi-struct-xs-perl, libobject-id-perl, maven-docck-plugin, parboiled, pegdown. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which did not make their way to the archive yet: reproducible.debian.net A new variation to better notice when a package captures the environment has been introduced. (h01ger) The test on Debian packages works by building the package twice in a short time frame. But sometimes, a mirror push can happen between the first and the second build, resulting in a package built in a different build environment. This situation is now properly detected and will run a third build automatically. (h01ger) OpenWrt, the distribution specialized in embedded devices like small routers, is now being tested for reproducibility. The situation looks very good for their packages which seems mostly affected by timestamps in the tarball. System images will require more work on debbindiff to be better understood. (h01ger) debbindiff development Reiner Herrmann added support for decompling Java .class file and .ipk package files (used by OpenWrt). This is now available in version 22 released on 2015-06-14. Documentation update Stephen Kitt documented the new --insert-timestamp available since binutils-mingw-w64 version 6.2 available to insert a ready-made date in PE binaries built with mingw-w64. Package reviews 195 obsolete reviews have been removed, 65 added and 126 updated this week. New identified issues: Misc. Holger Levsen reported an issue with the locales-all package that Provides: locales but is actually missing some of the files provided by locales. Coreboot upstream has been quick to react after the announcement of the tests set up the week before. Patrick Georgi has fixed all issues in a couple of days and all Coreboot images are now reproducible (without a payload). SeaBIOS is one of the most frequently used payload on PC hardware and can now be made reproducible too. Paul Kocialkowski wrote to the mailing list asking for help on getting U-Boot tested for reproducibility. Lunar had a chat with maintainers of Open Build Service to better understand the difference between their system and what we are doing for Debian.

Next.