Search Results: "nomeata"

25 February 2026

Joachim Breitner: Vibe-coding a debugger for a DSL

Earlier this week a colleague of mine, Emilio Jes s Gallego Arias, shared a demo of something he built as an experiment, and I felt the desire to share this and add a bit of reflection. (Not keen on watching a 5 min video? Read on below.)

What was that? So what did you just see (or skipped watching)? You could see Emilio s screen, running VSCode and editing a Lean file. He designed a small programming language that he embedded into Lean, including an evaluator. So far, so standard, but a few things stick out already:
  • Using Lean s very extensible syntax this embedding is rather elegant and pretty.
  • Furthermore, he can run this DSL code right there, in the source code, using commands like #eval. This is a bit like the interpreter found in Haskell or Python, but without needing a separate process, or like using a Jupyter notebook, but without the stateful cell management.
This is already a nice demonstration of Lean s abilities and strength, as we know them. But what blew my mind the first time was what happened next: He had a visual debugger that allowed him to debug his DSL program. It appeared on the right, in Lean s Info View , where various Lean tools can hook into, show information and allow the user to interact. But it did not stop there, and my mind was blown a second time: Emilio opened VSCode s Debugger pane on the left, and was able to properly use VSCode s full-fledged debugger frontend for his own little embedded programming language! Complete with highlighting the executed line, with the ability to set breakpoints there, and showing the state of local variables in the debugger. Having a good debugger is not to be taken for granted even for serious, practical programming languages. Having it for a small embedded language that you just built yourself? I wouldn t have even considered that.

Did it take long? If I were Emilio s manager I would applaud the demo and then would have to ask how many weeks he spent on that. Coming up with the language, getting the syntax extension right, writing the evaluator and especially learning how the debugger integration into VSCode (using the DAP protocol) works, and then instrumenting his evaluator to speak that protocol that is a sizeable project! It turns out the answer isn t measured in weeks: it took just one day of coding together with GPT-Codex 5.3. My mind was blown a third time.

Why does Lean make a difference? I am sure this post is just one of many stories you have read in recent weeks about how new models like Claude Opus 4.6 and GPT-Codex 5.3 built impressive things in hours that would have taken days or more before. But have you seen something like this? Agentic coding is powerful, but limited by what the underlying platform exposes. I claim that Lean is a particularly well-suited platform to unleash the agents versatility. Here we are using Lean as a programming language, not as a theorem prover (which brings other immediate benefits when using agents, e.g. the produced code can be verified rather than merely plausible, but that s a story to be told elsewhere.) But arguably because Lean is also a theorem prover, and because of the requirements that stem from that, its architecture is different from that of a conventional programming language implementation:
  • As a theorem prover, it needs extensible syntax to allow formalizing mathematics in an ergonomic way, but it can also be used for embedding syntax.
  • As a theorem prover, it needs the ability to run tactics written by the user, hence the ability to evaluate the code right there in the editor.
  • As a theorem prover, it needs to give access to information such as tactic state, and such introspection abilities unlock many other features such as a debugger for an embedded language.
  • As a theorem prover, it has to allow tools to present information like the tactic state, so it has the concept of interactive Widgets .
So Lean s design has always made such a feat possible. But it was no easy feat. The Lean API is large, and documentation never ceases to be improvable. In the past, it would take an expert (or someone willing to become one) to pull off that stunt. These days, coding assistants have no issue digesting, understanding and using the API, as Emilio s demo shows. The combination of Lean s extensibility and the ability of coding agents to make use of that is a game changer to how we can develop software, with rich, deep, flexible and bespoke ways to interact with our code, created on demand.

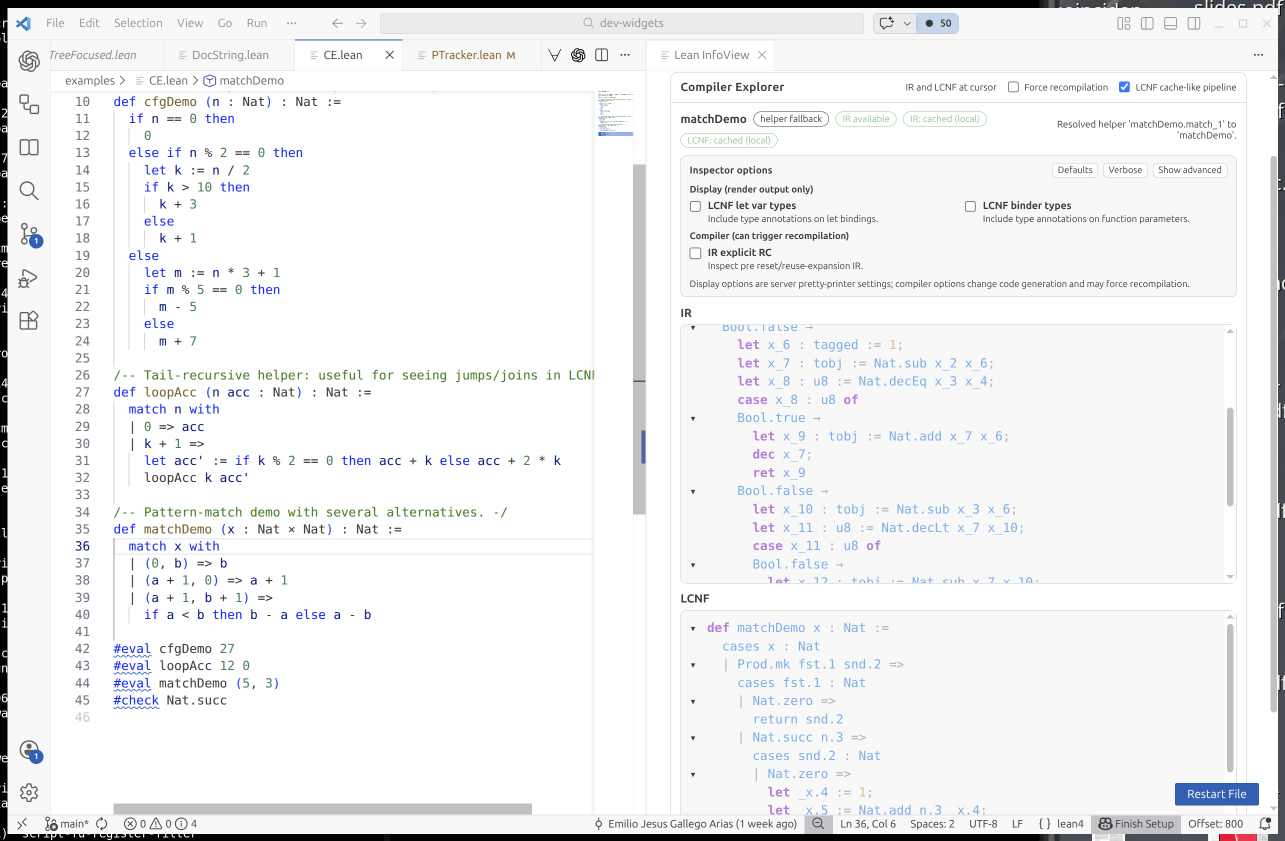
Where does that lead us? Emilio actually shared more such demos (Github repository). A visual explorer for the compiler output (have a look at the screenshot. A browser-devtool-like inspection tool for Lean s InfoTree . Any of these provide a significant productivity boost. Any of these would have been a sizeable project half a year ago. Now it s just a few hours of chatting with the agent. So allow me to try and extrapolate into a future where coding agents have continued to advance at the current pace, and are used ubiquitously. Is there then even a point in polishing these tools, shipping them to our users, documenting them? Why build a compiler explorer for our users, if our users can just ask their agent to build one for them, right then when they need it, tailored to precisely the use case they have, with no unnecessary or confusing feature. The code would be single use, as the next time the user needs something like that the agent can just re-create it, maybe slightly different because every use case is different. If that comes to pass then Lean may no longer get praise for its nice out-of-the-box user experience, but instead because it is such a powerful framework for ad-hoc UX improvements. And Emilio wouldn t post demos about his debugger. He d just use it.

2 January 2026

Joachim Breitner: Seemingly impossible programs in Lean

In 2007, Martin Escardo wrote a often-read blog post about Seemingly impossible functional programs . One such seemingly impossible function is find, which takes a predicate on infinite sequences of bits, and returns an infinite sequence for which that predicate hold (unless the predicate is just always false, in which case it returns some arbitrary sequence). Inspired by conversations with and experiments by Massin Guerdi at the dinner of LeaningIn 2025 in Berlin (yes, this blog post has been in my pipeline for far too long), I wanted to play around these concepts in Lean. Let s represent infinite sequences of bits as functions from Nat to Bit, and give them a nice name, and some basic functionality, including a binary operator for consing an element to the front:
import Mathlib.Data.Nat.Find
abbrev Bit := Bool
def Cantor : Type := Nat   Bit
def Cantor.head (a : Cantor) : Bit := a 0
def Cantor.tail (a : Cantor) : Cantor := fun i => a (i + 1)
@[simp, grind] def Cantor.cons (x : Bit) (a : Cantor) : Cantor
    0 => x
    i+1 => a i
infix:60 " # " => Cantor.cons
With this in place, we can write Escardo s function in Lean. His blog post discusses a few variants; I ll focus on just one of them:
mutual
  partial def forsome (p : Cantor   Bool) : Bool :=
    p (find p)
  partial def find (p : Cantor   Bool) : Cantor :=
    have b := forsome (fun a => p (true # a))
    (b # find (fun a => p (b # a)))
end
We define find together with forsome, which checks if the predicate p holds for any sequence. Using that find sets the first element of the result to true if there exists a squence starting with true, else to false, and then tries to find the rest of the sequence. It is a bit of a brian twiter that this code works, but it does:
def fifth_false : Cantor   Bool := fun a => not (a 5)
/-- info: [true, true, true, true, true, false, true, true, true, true] -/
#guard_msgs in
#eval List.ofFn (fun (i : Fin 10) => find fifth_false i)
Of course, in Lean we don t just want to define these functions, but we want to prove that they do what we expect them to do. Above we defined them as partial functions, even though we hope that they are not actually partial: The partial keyword means that we don t have to do a termination proof, but also that we cannot prove anything about these functions. So can we convince Lean that these functions are total after all? We can, but it s a bit of a puzzle, and we have to adjust the definitions. First of all, these seemingly impossible functions are only possible because we assume that the predicate we pass to it, p, is computable and total. This is where the whole magic comes from, and I recommend to read Escardo s blog posts and papers for more on this fascinating topic. In particular, you will learn that a predicate on Cantor that is computable and total necessarily only looks at some initial fragment of the sequence. The length of that prefix is called the modulus . So if we hope to prove termination of find and forsome, we have to restrict their argument p to only such computable predicates. To that end I introduce HasModulus and the subtype of predicates on Cantor that have such a modulus:
-- Extensional (!) modulus of uniform continuity
def HasModulus (p : Cantor    ) :=   n,   a b : Cantor, (  i < n, a i = b i)   p a = p b
@[ext] structure CantorPred where
  pred : Cantor   Bool
  hasModulus : HasModulus pred
The modulus of such a predicate is now the least prefix lenght that determines the predicate. In particular, if the modulus is zero, the predicate is constant:
namespace CantorPred
variable (p : CantorPred)
noncomputable def modulus : Nat :=
  open Classical in Nat.find p.hasModulus
theorem eq_of_modulus :  a b : Cantor, (  i < p.modulus, a i = b i)   p a = p b := by
  open Classical in
  unfold modulus
  exact Nat.find_spec p.hasModulus
theorem eq_of_modulus_eq_0 (hm : p.modulus = 0) :   a b, p a = p b := by
  intro a b
  apply p.eq_of_modulus
  simp [hm]
Because we want to work with CantorPred and not Cantor Bool I have to define some operations on that new type; in particular the cons element before predicate operation that we saw above in find:
def comp_cons (b : Bit) : CantorPred where
  pred := fun a => p (b # a)
  hasModulus := by
    obtain  n, h_n  := p.hasModulus
    cases n with
      zero => exists 0; grind
      succ m =>
      exists m
      intro a b heq
      simp
      apply h_n
      intro i hi
      cases i
        rfl
        grind
@[simp, grind =] theorem comp_cons_pred (x : Bit) (a : Cantor) :
  (p.comp_cons x) a = p (x # a) := rfl
For this operation we know that the modulus decreases (if it wasn t already zero):
theorem comp_cons_modulus (x : Bit) :
    (p.comp_cons x).modulus   p.modulus - 1 := by
  open Classical in
  apply Nat.find_le
  intro a b hab
  apply p.eq_of_modulus
  cases hh : p.modulus
    simp
    intro i hi
    cases i
      grind
      grind
grind_pattern comp_cons_modulus => (p.comp_cons x).modulus
We can rewrite the find function above to use these operations:
mutual
  partial def forsome (p : CantorPred) : Bool := p (find p)
  partial def find (p : CantorPred) : Cantor := fun i =>
    have b := forsome (p.comp_cons true)
    (b # find (p.comp_cons b)) i
end
I have also eta-expanded the Cantor function returned by find; there is now a fun i => i around the body. We ll shortly see why that is needed. Now have everything in place to attempt a termination proof. Before we do that proof, we could step back and try to come up with an informal termination argument. We can express all this reasoning as a termination measure in the form of a lexicographic triple. The 0 and 1 in the middle component mean that for zero modulus, we can call forsome from find for free .
mutual
  def forsome (p : CantorPred) : Bool := p (find p)
  termination_by (p.modulus, if p.modulus = 0 then 0 else 1, 0)
  decreasing_by grind
  def find (p : CantorPred) : Cantor := fun i =>
    have b := forsome (p.comp_cons true)
    (b # find (p.comp_cons b)) i
  termination_by i => (p.modulus, if p.modulus = 0 then 1 else 0, i)
  decreasing_by all_goals grind
end
The termination proof doesn t go through just yet: Lean is not able to see that (_ # p) i will call p with i - 1, and it does not see that p (find p) only uses find p if the modulus of p is non-zero. We can use the wf_preprocess feature to tell it about that: The following theorem replaces a call to p f, where p is a function parameter, with the slightly more complex but provably equivalent expression on the right, where the call to f is no in the else branch of an if-then-else and thus has p.modulus = 0 in scope:
@[wf_preprocess]
theorem coe_wf (p : CantorPred) :
    (wfParam p) f = p (if _ : p.modulus = 0 then fun _ => false else f) := by
  split
  next h => apply p.eq_of_modulus_eq_0 h
  next => rfl
And similarly we replace (_ # p) i with a variant that extend the context with information on how p is called:
def cantor_cons' (x : Bit) (i : Nat) (a :   j, j + 1 = i   Bit) : Bit :=
  match i with
    0 => x
    j + 1 => a j (by grind)
@[wf_preprocess] theorem cantor_cons_congr (b : Bit) (a : Cantor) (i : Nat) :
  (b # a) i = cantor_cons' b i (fun j _ => a j) := by cases i <;> rfl
After these declarations, the above definition of forsome and find goes through! It remains to now prove that they do what they should, by a simple induction on the modulus of p:
@[simp, grind =] theorem tail_cons_eq (a : Cantor) : (x # a).tail = a := by
  funext i; simp [Cantor.tail, Cantor.cons]
@[simp, grind =] theorem head_cons_tail_eq (a : Cantor) : a.head # a.tail = a := by
  funext i; cases i <;> rfl
theorem find_correct (p : CantorPred) (h_exists :   a, p a) : p (find p) := by
  by_cases h0 : p.modulus = 0
    obtain  a, h_a  := h_exists
    rw [  h_a]
    apply p.eq_of_modulus_eq_0 h0
    rw [find.eq_unfold, forsome.eq_unfold]
    dsimp -zeta
    extract_lets b
    change p (_ # _)
    by_cases htrue :   a, p (true # a)
    next =>
      have := find_correct (p.comp_cons true) htrue
      grind
    next =>
      have : b = false := by grind
      clear_value b; subst b
      have hfalse :   a, p (false # a) := by
        obtain  a, h_a  := h_exists
        cases h : a.head
          exists Cantor.tail a
          grind
          exfalso
          apply htrue
          exists Cantor.tail a
          grind
      clear h_exists
      exact find_correct (p.comp_cons false) hfalse
termination_by p.modulus
decreasing_by all_goals grind
theorem forsome_correct (p : CantorPred) :
    forsome p   (  a, p a) where
  mp hfind := by unfold forsome at hfind; exists find p
  mpr hex := by unfold forsome; exact find_correct p hex
This is pretty nice! However there is more to do. For example, Escardo has a massively faster variant of find that we can implement as a partial function in Lean:
def findBit (p : Bit   Bool) : Bit :=
  if p false then false else true
def branch (x : Bit) (l r : Cantor) : Cantor :=
  fun n =>
    if n = 0      then x
    else if 2   n then r ((n - 2) / 2)
                  else l ((n - 1) / 2)
mutual
  partial def forsome (p : Cantor -> Bool) : Bool :=
    p (find p)
  partial def find (p : Cantor -> Bool) : Cantor :=
    let x := findBit (fun x => forsome (fun l => forsome (fun r => p (branch x l r))))
    let l := find (fun l => forsome (fun r => p (branch x l r)))
    let r := find (fun r => p (branch x l r))
    branch x l r
end
But can we get this past Lean s termination checker? In order to prove that the modulus of p is decreasing, we d have to know that, for example, find (fun r => p (branch x l r)) is behaving nicely. Unforunately, it is rather hard to do termination proof for a function that relies on the behaviour of the function itself. So I ll leave this open as a future exercise. I have dumped the code for this post at https://github.com/nomeata/lean-cantor.

3 September 2025

Joachim Breitner: F91 in Lean

Back in March, with version 4.17.0, Lean introduced partial_fixpoint, a new way to define recursive functions. I had drafted a blog post for the official Lean FRO blog back then, but forgot about it, and with the Lean FRO blog discontinued, I ll just publish it here, better late than never. With the partial_fixpoint mechanism we can model possibly partial functions (so those returning an Option) without an explicit termination proof, and still prove facts about them. See the corresponding section in the reference manual for more details. On the Lean Zulip, I was asked if we can use this feature to define the McCarthy 91 function and prove it to be total. This function is a well-known tricky case for termination proofs. First let us have a brief look at why this function is tricky to define in a system like Lean. A naive definition like
def f91 (n : Nat) : Nat :=
  if n > 100
  then n - 10
  else f91 (f91 (n + 11))
does not work; Lean is not able to prove termination of this functions by itself. Even using well-founded recursion with an explicit measure (e.g. termination_by 101 - n) is doomed, because we would have to prove facts about the function s behaviour (namely that f91n = f91101 = 91 for 90 n 100) and at the same time use that fact in the termination proof that we have to provide while defining the function. (The Wikipedia page spells out the proof.) We can make well-founded recursion work if we change the signature and use a subtype on the result to prove the necessary properties while we are defining the function. Lean by Example shows how to do it, but for larger examples this approach can be hard or tedious. With partial_fixpoint, we can define the function as a partial function without worrying about termination. This requires a change to the function s signature, returning an Option Nat:
def f91 (n : Nat) : Option Nat :=
  if n > 100
    then pure (n - 10)
    else f91 (n + 11) >>= f91
partial_fixpoint
From the point of view of the logic, Option.none is then used for those inputs for which the function does not terminate. This function definition is accepted and the function runs fine as compiled code:
#eval f91 42
prints some 91. The crucial question is now: Can we prove anything about f91 In particular, can we prove that this function is actually total? Since we now have the f91 function defined, we can start proving auxillary theorems, using whatever induction schemes we need. In particular we can prove that f91 is total and always returns 91 for n 100:
theorem f91_spec_high (n : Nat) (h : 100 < n) : f91 n = some (n - 10) := by
  unfold f91; simp [*]
theorem f91_spec_low (n : Nat) (h  : n   100) : f91 n = some 91 := by
  unfold f91
  rw [if_neg (by omega)]
  by_cases n < 90
    rw [f91_spec_low (n + 11) (by omega)]
    simp only [Option.bind_eq_bind, Option.some_bind]
    rw [f91_spec_low 91 (by omega)]
    rw [f91_spec_high (n + 11) (by omega)]
    simp only [Nat.reduceSubDiff, Option.some_bind]
    by_cases h : n = 100
      simp [f91, *]
      exact f91_spec_low (n + 1) (by omega)
theorem f91_spec (n : Nat) : f91 n = some (if n   100 then 91 else n - 10) := by
  by_cases h100 : n   100
    simp [f91_spec_low, *]
    simp [f91_spec_high, Nat.lt_of_not_le  _ , *]
-- Generic totality theorem
theorem f91_total (n : Nat) : (f91 n).isSome := by simp [f91_spec]
(Note that theorem f91_spec_low is itself recursive in a somewhat non-trivial way, but Lean can figure that out all by itself. Use termination_by? if you are curious.) This is already a solid start! But what if we want a function of type f91! (n : Nat) : Nat, without the Option? Then can derive that from the partial variant, as we have just proved that to be actually total:
def f91! (n : Nat) : Nat  := (f91 n).get (f91_total n)
theorem f91!_spec (n : Nat) : f91! n = if n   100 then 91 else n - 10 := by
  simp [f91!, f91_spec]
Using partial_fixpoint one can decouple the definition of a function from a termination proof, or even model functions that are not terminating on all inputs. This can be very useful in particular when using Lean for program verification, such as with the aeneas package, where such partial definitions are used to model Rust programs.

10 March 2025

Joachim Breitner: Extrinsic termination proofs for well-founded recursion in Lean

A few months ago I explained that one reason why this blog has become more quiet is that all my work on Lean is covered elsewhere. This post is an exception, because it is an observation that is (arguably) interesting, but does not lead anywhere, so where else to put it than my own blog Want to share your thoughts about this? Please join the discussion on the Lean community zulip!

Background When defining a function recursively in Lean that has nested recursion, e.g. a recusive call that is in the argument to a higher-order function like List.map, then extra attention used to be necessary so that Lean can see that xs.map applies its argument only elements of the list xs. The usual idiom is to write xs.attach.map instead, where List.attach attaches to the list elements a proof that they are in that list. You can read more about this my Lean blog post on recursive definitions and our new shiny reference manual, look for Example Nested Recursion in Higher-order Functions . To make this step less tedious I taught Lean to automatically rewrite xs.map to xs.attach.map (where suitable) within the construction of well-founded recursion, so that nested recursion just works (issue #5471). We already do such a rewriting to change if c then else to the dependent if h : c then else , but the attach-introduction is much more ambitious (the rewrites are not definitionally equal, there are higher-order arguments etc.) Rewriting the terms in a way that we can still prove the connection later when creating the equational lemmas is hairy at best. Also, we want the whole machinery to be extensible by the user, setting up their own higher order functions to add more facts to the context of the termination proof. I implemented it like this (PR #6744) and it ships with 4.18.0, but in the course of this work I thought about a quite different and maybe better way to do this, and well-founded recursion in general:

A simpler fix Recall that to use WellFounded.fix
WellFounded.fix : (hwf : WellFounded r) (F : (x :  )   ((y :  )   r y x   C y)   C x) (x :  ) : C x
we have to rewrite the functorial of the recursive function, which naturally has type
F : ((y :  )    C y)   ((x :  )   C x)
to the one above, where all recursive calls take the termination proof r y x. This is a fairly hairy operation, mangling the type of matcher s motives and whatnot. Things are simpler for recursive definitions using the new partial_fixpoint machinery, where we use Lean.Order.fix
Lean.Order.fix : [CCPO  ] (F :      ) (hmono : monotone F) :  
so the functorial s type is unmodified (here will be ((x : ) C x)), and everything else is in the propositional side-condition montone F. For this predicate we have a syntax-guided compositional tactic, and it s easily extensible, e.g. by
theorem monotone_mapM (f :         m  ) (xs : List  ) (hmono : monotone f) :
    monotone (fun x => xs.mapM (f x)) 
Once given, we don t care about the content of that proof. In particular proving the unfolding theorem only deals with the unmodified F that closely matches the function definition as written by the user. Much simpler!

Isabelle has it easier Isabelle also supports well-founded recursion, and has great support for nested recursion. And it s much simpler! There, all you have to do to make nested recursion work is to define a congruence lemma of the form, for List.map something like our List.map_congr_left
List.map_congr_left : (h :   a   l, f a = g a) :
    List.map f l = List.map g l
This is because in Isabelle, too, the termination proofs is a side-condition that essentially states the functorial F calls its argument f only on smaller arguments .

Can we have it easy, too? I had wished we could do the same in Lean for a while, but that form of congruence lemma just isn t strong enough for us. But maybe there is a way to do it, using an existential to give a witness that F can alternatively implemented using the more restrictive argument. The following callsOn P F predicate can express that F calls its higher-order argument only on arguments that satisfy the predicate P:
section setup
variable   : Sort u 
variable   :     Sort v 
variable   : Sort w 
def callsOn (P :     Prop) (F : (  y,   y)    ) :=
    (F': (  y, P y     y)    ),   f, F' (fun y _ => f y) = F f
variable (R :         Prop)
variable (F : (  y,   y)   (  x,   x))
local infix:50 "   " => R
def recursesVia : Prop :=   x, callsOn (    x) (fun f => F f x)
noncomputable def fix (wf : WellFounded R) (h : recursesVia R F) : (  x,   x) :=
  wf.fix (fun x => (h x).choose)
def fix_eq (wf : WellFounded R) h x :
    fix R F wf h x = F (fix R F wf h) x := by
  unfold fix
  rw [wf.fix_eq]
  apply (h x).choose_spec
This allows nice compositional lemmas to discharge callsOn predicates:
theorem callsOn_base (y :  ) (hy : P y) :
    callsOn P (fun (f :   x,   x) => f y) := by
  exists fun f => f y hy
  intros; rfl
@[simp]
theorem callsOn_const (x :  ) :
    callsOn P (fun (_ :   x,   x) => x) :=
   fun _ => x, fun _ => rfl 
theorem callsOn_app
      : Sort uu    : Sort ww 
    (F  :  (  y,   y)        ) -- can this also support dependent types?
    (F  :  (  y,   y)    )
    (h  : callsOn P F )
    (h  : callsOn P F ) :
    callsOn P (fun f => F  f (F  f)) := by
  obtain  F ', h  := h 
  obtain  F ', h  := h 
  exists (fun f => F ' f (F ' f))
  intros; simp_all
theorem callsOn_lam
      : Sort uu 
    (F :     (  y,   y)    ) -- can this also support dependent types?
    (h :   x, callsOn P (F x)) :
    callsOn P (fun f x => F x f) := by
  exists (fun f x => (h x).choose f)
  intro f
  ext x
  apply (h x).choose_spec
theorem callsOn_app2
      : Sort uu    : Sort ww 
    (g :          )
    (F  :  (  y,   y)    ) -- can this also support dependent types?
    (F  :  (  y,   y)    )
    (h  : callsOn P F )
    (h  : callsOn P F ) :
    callsOn P (fun f => g (F  f) (F  f)) := by
  apply_rules [callsOn_app, callsOn_const]
With this setup, we can have the following, possibly user-defined, lemma expressing that List.map calls its arguments only on elements of the list:
theorem callsOn_map (  : Type uu) (  : Type ww)
    (P :     Prop) (F : (  y,   y)        ) (xs : List  )
    (h :   x, x   xs   callsOn P (fun f => F f x)) :
    callsOn P (fun f => xs.map (fun x => F f x)) := by
  suffices callsOn P (fun f => xs.attach.map (fun  x, h  => F f x)) by
    simpa
  apply callsOn_app
    apply callsOn_app
      apply callsOn_const
      apply callsOn_lam
      intro  x', hx' 
      dsimp
      exact (h x' hx')
    apply callsOn_const
end setup
So here is the (manual) construction of a nested map for trees:
section examples
structure Tree (  : Type u) where
  val :  
  cs : List (Tree  )
-- essentially
-- def Tree.map (f :      ) : Tree     Tree   :=
--   fun t =>  f t.val, t.cs.map Tree.map )
noncomputable def Tree.map (f :      ) : Tree     Tree   :=
  fix (sizeOf   < sizeOf  ) (fun map t =>  f t.val, t.cs.map map )
    (InvImage.wf (sizeOf  ) WellFoundedRelation.wf) <  by
  intro  v, cs 
  dsimp only
  apply callsOn_app2
    apply callsOn_const
    apply callsOn_map
    intro t' ht'
    apply callsOn_base
    -- ht' : t'   cs -- !
    --   sizeOf t' < sizeOf   val := v, cs := cs  
    decreasing_trivial
end examples
This makes me happy! All details of the construction are now contained in a proof that can proceed by a syntax-driven tactic and that s easily and (likely robustly) extensible by the user. It also means that we can share a lot of code paths (e.g. everything related to equational theorems) between well-founded recursion and partial_fixpoint. I wonder if this construction is really as powerful as our current one, or if there are certain (likely dependently typed) functions where this doesn t fit, but the above is dependent, so it looks good. With this construction, functions defined by well-founded recursion will reduce even worse in the kernel, I assume. This may be a good thing.

The cake is a lie What unfortunately kills this idea, though, is the generation of the functional induction principles, which I believe is not (easily) possible with this construction: The functional induction principle is proved by massaging F to return a proof, but since the extra assumptions (e.g. for ite or List.map) only exist in the termination proof, they are not available in F. Oh wey, how anticlimactic.

PS: Path dependencies Curiously, if we didn t have functional induction at this point yet, then very likely I d change Lean to use this construction, and then we d either not get functional induction, or it would be implemented very differently, maybe a more syntactic approach that would re-prove termination. I guess that s called path dependence.

2 February 2025

Joachim Breitner: Coding on my eInk Tablet

For many years I wished I had a setup that would allow me to work (that is, code) productively outside in the bright sun. It s winter right now, but when its summer again it s always a bit. this weekend I got closer to that goal. TL;DR: Using code-server on a beefy machine seems to be quite neat.
Passively lit coding Passively lit coding

Personal history Looking back at my own old blog entries I find one from 10 years ago describing how I bought a Kobo eBook reader with the intent of using it as an external monitor for my laptop. It seems that I got a proof-of-concept setup working, using VNC, but it was tedious to set up, and I never actually used that. I subsequently noticed that the eBook reader is rather useful to read eBooks, and it has been in heavy use for that every since. Four years ago I gave this old idea another shot and bought an Onyx BOOX Max Lumi. This is an A4-sized tablet running Android and had the very promising feature of an HDMI input. So hopefully I d attach it to my laptop and it just works . Turns out that this never worked as well as I hoped: Even if I set the resolution to exactly the tablet s screen s resolution I got blurry output, and it also drained the battery a lot, so I gave up on this. I subsequently noticed that the tablet is rather useful to take notes, and it has been in sporadic use for that. Going off on this tangent: I later learned that the HDMI input of this device appears to the system like a camera input, and I don t have to use Boox s monitor app but could other apps like FreeDCam as well. This somehow managed to fix the resolution issues, but the setup still wasn t as convenient to be used regularly. I also played around with pure terminal approaches, e.g. SSH ing into a system, but since my usual workflow was never purely text-based (I was at least used to using a window manager instead of a terminal multiplexer like screen or tmux) that never led anywhere either.

VSCode, working remotely Since these attempts I have started a new job working on the Lean theorem prover, and working on or with Lean basically means using VSCode. (There is a very good neovim plugin as well, but I m using VSCode nevertheless, if only to make sure I am dogfooding our default user experience). My colleagues have said good things about using VSCode with the remote SSH extension to work on a beefy machine, so I gave this a try now as well, and while it s not a complete game changer for me, it does make certain tasks (rebuilding everything after a switching branches, running the test suite) very convenient. And it s a bit spooky to run these work loads without the laptop s fan spinning up. In this setup, the workspace is remote, but VSCode still runs locally. But it made me wonder about my old goal of being able to work reasonably efficient on my eInk tablet. Can I replicate this setup there? VSCode itself doesn t run on Android directly. There are project that run a Linux chroot or in termux on the Android system, and then you can VNC to connect to it (e.g. on Andronix) but that did not seem promising. It seemed fiddly, and I probably should take it easy on the tablet s system.

code-server, running remotely A more promising option is code-server. This is a fork of VSCode (actually of VSCodium) that runs completely on the remote machine, and the client machine just needs a browser. I set that up this weekend and found that I was able to do a little bit of work reasonably.

Access With code-server one has to decide how to expose it safely enough. I decided against the tunnel-over-SSH option, as I expected that to be somewhat tedious to set up (both initially and for each session) on the android system, and I liked the idea of being able to use any device to work in my environment. I also decided against the more involved reverse proxy behind proper hostname with SSL setups, because they involve a few extra steps, and some of them I cannot do as I do not have root access on the shared beefy machine I wanted to use. That left me with the option of using a code-server s built-in support for self-signed certificates and a password:
$ cat .config/code-server/config.yaml
bind-addr: 1.2.3.4:8080
auth: password
password: xxxxxxxxxxxxxxxxxxxxxxxx
cert: true
With trust-on-first-use this seems reasonably secure. Update: I noticed that the browsers would forget that I trust this self-signed cert after restarting the browser, and also that I cannot install the page (as a Progressive Web App) unless it has a valid certificate. But since I don t have superuser access to that machine, I can t just follow the official recommendation of using a reverse proxy on port 80 or 431 with automatic certificates. Instead, I pointed a hostname that I control to that machine, obtained a certificate manually on my laptop (using acme.sh) and copied the files over, so the configuration now reads as follows:
bind-addr: 1.2.3.4:3933
auth: password
password: xxxxxxxxxxxxxxxxxxxxxxxx
cert: .acme.sh/foobar.nomeata.de_ecc/foobar.nomeata.de.cer
cert-key: .acme.sh/foobar.nomeata.de_ecc/foobar.nomeata.de.key
(This is getting very specific to my particular needs and constraints, so I ll spare you the details.)

Service To keep code-server running I created a systemd service that s managed by my user s systemd instance:
~ $ cat ~/.config/systemd/user/code-server.service
[Unit]
Description=code-server
After=network-online.target
[Service]
Environment=PATH=/home/joachim/.nix-profile/bin:/nix/var/nix/profiles/default/bin:/usr/local/bin:/usr/bin:/bin:/usr/local/games:/usr/games
ExecStart=/nix/var/nix/profiles/default/bin/nix run nixpkgs#code-server
[Install]
WantedBy=default.target
(I am using nix as a package manager on a Debian system there, hence the additional PATH and complex ExecStart. If you have a more conventional setup then you do not have to worry about Environment and can likely use ExecStart=code-server. For this to survive me logging out I had to ask the system administrator to run loginctl enable-linger joachim, so that systemd allows my jobs to linger.

Git credentials The next issue to be solved was how to access the git repositories. The work is all on public repositories, but I still need a way to push my work. With the classic VSCode-SSH-remote setup from my laptop, this is no problem: My local SSH key is forwarded using the SSH agent, so I can seamlessly use that on the other side. But with code-server there is no SSH key involved. I could create a new SSH key and store it on the server. That did not seem appealing, though, because SSH keys on Github always have full access. It wouldn t be horrible, but I still wondered if I can do better. I thought of creating fine-grained personal access tokens that only me to push code to specific repositories, and nothing else, and just store them permanently on the remote server. Still a neat and convenient option, but creating PATs for our org requires approval and I didn t want to bother anyone on the weekend. So I am experimenting with Github s git-credential-manager now. I have configured it to use git s credential cache with an elevated timeout, so that once I log in, I don t have to again for one workday.
$ nix-env -iA nixpkgs.git-credential-manager
$ git-credential-manager configure
$ git config --global credential.credentialStore cache
$ git config --global credential.cacheOptions "--timeout 36000"
To login, I have to https://github.com/login/device on an authenticated device (e.g. my phone) and enter a 8-character code. Not too shabby in terms of security. I only wish that webpage would not require me to press Tab after each character This still grants rather broad permissions to the code-server, but at least only temporarily

Android setup On the client side I could now open https://host.example.com:8080 in Firefox on my eInk Android tablet, click through the warning about self-signed certificates, log in with the fixed password mentioned above, and start working! I switched to a theme that supposedly is eInk-optimized (eInk by Mufanza). It s not perfect (e.g. git diffs are unhelpful because it is not possible to distinguish deleted from added lines), but it s a start. There are more eInk themes on the official Visual Studio Marketplace, but because code-server is a fork it cannot use that marketplace, and for example this theme isn t on Open-VSX. For some reason the F11 key doesn t work, but going fullscreen is crucial, because screen estate is scarce in this setup. I can go fullscreen using VSCode s command palette (Ctrl-P) and invoking the command there, but Firefox often jumps out of the fullscreen mode, which is annoying. I still have to pay attention to when that s happening; maybe its the Esc key, which I am of course using a lot due to me using vim bindings. A more annoying problem was that on my Boox tablet, sometimes the on-screen keyboard would pop up, which is seriously annoying! It took me a while to track this down: The Boox has two virtual keyboards installed: The usual Google ASOP keyboard, and the Onyx Keyboard. The former is clever enough to stay hidden when there is a physical keyboard attached, but the latter isn t. Moreover, pressing Shift-Ctrl on the physical keyboard rotates through the virtual keyboards. Now, VSCode has many keyboard shortcuts that require Shift-Ctrl (especially on an eInk device, where you really want to avoid using the mouse). And the limited settings exposed by the Boox Android system do not allow you configure that or disable the Onyx keyboard! To solve this, I had to install the KISS Launcher, which would allow me to see more Android settings, and in particular allow me to disable the Onyx keyboard. So this is fixed. I was hoping to improve the experience even more by opening the web page as a Progressive Web App (PWA), as described in the code-server FAQ. Unfortunately, that did not work. Firefox on Android did not recognize the site as a PWA (even though it recognizes a PWA test page). And I couldn t use Chrome either because (unlike Firefox) it would not consider a site with a self-signed certificate as a secure context, and then code-server does not work fully. Maybe this is just some bug that gets fixed in later versions. Now that I use a proper certificate, I can use it as a Progressive Web App, and with Firefox on Android this starts the app in full-screen mode (no system bars, no location bar). The F11 key still does t work, and using the command palette to enter fullscreen does nothing visible, but then Esc leaves that fullscreen mode and I suddenly have the system bars again. But maybe if I just don t do that I get the full screen experience. We ll see. I did not work enough with this yet to assess how much the smaller screen estate, the lack of colors and the slower refresh rate will bother me. I probably need to hide Lean s InfoView more often, and maybe use the Error Lens extension, to avoid having to split my screen vertically. I also cannot easily work on a park bench this way, with a tablet and a separate external keyboard. I d need at least a table, or some additional piece of hardware that turns tablet + keyboard into some laptop-like structure that I can put on my, well, lap. There are cases for Onyx products that include a keyboard, and maybe they work on the lap, but they don t have the Trackpoint that I have on my ThinkPad TrackPoint Keyboard II, and how can you live without that?

Conclusion After this initial setup chances are good that entering and using this environment is convenient enough for me to actually use it; we will see when it gets warmer. A few bits could be better. In particular logging in and authenticating GitHub access could be both more convenient and more safe I could imagine that when I open the page I confirm that on my phone (maybe with a fingerprint), and that temporarily grants access to the code-server and to specific GitHub repositories only. Is that easily possible?

30 June 2024

Joachim Breitner: Do surprises get larger?

The setup Imagine you are living on a riverbank. Every now and then, the river swells and you have high water. The first few times this may come as a surprise, but soon you learn that such floods are a recurring occurrence at that river, and you make suitable preparation. Let s say you feel well-prepared against any flood that is no higher than the highest one observed so far. The more floods you have seen, the higher that mark is, and the better prepared you are. But of course, eventually a higher flood will occur that surprises you. Of course such new record floods are happening rarer and rarer as you have seen more of them. I was wondering though: By how much do the new records exceed the previous high mark? Does this excess decrease or increase over time? A priori both could be. When the high mark is already rather high, maybe new record floods will just barley pass that mark? Or maybe, simply because new records are so rare events, when they do occur, they can be surprisingly bad? This post is a leisurely mathematical investigating of this question, which of course isn t restricted to high waters; it could be anything that produces a measurement repeatedly and (mostly) independently weather events, sport results, dice rolls. The answer of course depends on the distribution of results: How likely is each possible results.

Dice are simple With dice rolls the answer is rather simple. Let our measurement be how often you can roll a die until it shows a 6. This simple game we can repeat many times, and keep track of our record. Let s say the record happens to be 7 rolls. If in the next run we roll the die 7 times, and it still does not show a 6, then we know that we have broken the record, and every further roll increases by how much we beat the old record. But note that how often we will now roll the die is completely independent of what happened before! So for this game the answer is: The excess with which the record is broken is always the same. Mathematically speaking this is because the distribution of rolls until the die shows a 6 is memoryless. Such distributions are rather special, its essentially just the example we gave (a geometric distribution), or its continuous analogue (the exponential distributions, for example the time until a radioactive particle decays).

Mathematical formulation With this out of the way, let us look at some other distributions, and for that, introduce some mathematical notations. Let X be a random variable with probability density function (x) and cumulative distribution function (x), and a be the previous record. We are interested in the behavior of Y(a) = X a X > x i.e. by how much X exceeds a under the condition that it did exceed a. How does Y change as a increases? In particular, how does the expected value of the excess e(a) = E(Y(a)) change?

Uniform distribution If X is uniformly distributed between, say, 0 and 1, then a new record will appear uniformly distributed between a and 1, and as that range gets smaller, the excess must get smaller as well. More precisely, e(a) = E(X a X > a) = E(X X > a) a = (1 a)/2 This not very interesting linear line is plotted in blue in this diagram:
The expected record surpass for the uniform distribution The expected record surpass for the uniform distribution
The orange line with the logarithmic scale on the right tries to convey how unlikely it is to surpass the record value a: it shows how many attempts we expect before the record is broken. This can be calculated by n(a) = 1/(1 (a)).

Normal distribution For the normal distribution (with median 0 and standard derivation 1, to keep things simple), we can look up the expected value of the one-sided truncated normal distribution and obtain e(a) = E(X X > a) a = (a)/(1 (a)) a Now is this growing or shrinking? We can plot this an have a quick look:
The expected record surpass for the normal distribution The expected record surpass for the normal distribution
Indeed it is, too, a decreasing function! (As a sanity check we can see that e(0) = (2/ ), which is the expected value of the half-normal distribution, as it should.)

Could it be any different? This settles my question: It seems that each new surprisingly high water will tend to be less surprising than the previously assuming high waters were uniformly or normally distributed, which is unlikely to be helpful. This does raise the question, though, if there are probability distributions for which e(a) is be increasing? I can try to construct one, and because it s a bit easier, I ll consider a discrete distribution on the positive natural numbers, and consider at g(0) = E(X) and g(1) = E(X 1 X > 1). What does it take for g(1) > g(0)? Using E(X) = p + (1 p)E(X X > 1) for p = P(X = 1) we find that in order to have g(1) > g(0), we need E(X) > 1/p. This is plausible because we get equality when E(X) = 1/p, as it precisely the case for the geometric distribution. And it is also plausible that it helps if p is large (so that the next first record is likely just 1) and if, nevertheless, E(X) is large (so that if we do get an outcome other than 1, it s much larger). Starting with the geometric distribution, where P(X > n X n) = pn = p (the probability of again not rolling a six) is constant, it seems that these pn is increasing, we get the desired behavior. So let p1 < p2 < pn < be an increasing sequence of probabilities, and define X so that P(X = n) = p1 pn 1 (1 pn) (imagine the die wears off and the more often you roll it, the less likely it shows a 6). Then for this variation of the game, every new record tends to exceed the previous more than previous records. As the p increase, we get a flatter long end in the probability distribution.

Gamma distribution To get a nice plot, I ll take the intuition from this and turn to continuous distributions. The Wikipedia page for the exponential distribution says it is a special case of the gamma distribution, which has an additional shape parameter , and it seems that it could influence the shape of the distribution to be and make the probability distribution have a longer end. Let s play around with = 2 and = 0.5, 1 and 1.5:
The expected record surpass for the gamma distribution The expected record surpass for the gamma distribution
  • For = 1 (dotted) this should just be the exponential distribution, and we see that e(a) is flat, as predicted earlier.
  • For larger (dashed) the graph does not look much different from the one for the normal distribution not a surprise, as for , the gamma distribution turns into the normal distribution.
  • For smaller (solid) we get the desired effect: e(a) is increasing. This means that new records tend to break records more impressively.
The orange line shows that this comes at a cost: for a given old record a, new records are harder to come by with smaller .

Conclusion As usual, it all depends on the distribution. Otherwise, not much, it s late.

31 May 2024

Joachim Breitner: Blogging on Lean

This blog has become a bit quiet since I joined the Lean FRO. One reasons is of course that I can now improve things about Lean, rather than blog about what I think should be done (which, by contraposition, means I shouldn t blog about what can be improved ). A better reason is that some of the things I d otherwise write here are now published on the official Lean blog, in particular two lengthy technical posts explaining aspects of Lean that I worked on: It would not be useful to re-publish them here because the technology verso behind the Lean blog, created by my colleage David Thrane Christansen, enables such fancy features like type-checked code snippets, including output and lots of information on hover. So I ll be content with just cross-linking my posts from here.

11 March 2024

Joachim Breitner: Convenient sandboxed development environment

I like using one machine and setup for everything, from serious development work to hobby projects to managing my finances. This is very convenient, as often the lines between these are blurred. But it is also scary if I think of the large number of people who I have to trust to not want to extract all my personal data. Whenever I run a cabal install, or a fun VSCode extension gets updated, or anything like that, I am running code that could be malicious or buggy. In a way it is surprising and reassuring that, as far as I can tell, this commonly does not happen. Most open source developers out there seem to be nice and well-meaning, after all.

Convenient or it won t happen Nevertheless I thought I should do something about this. The safest option would probably to use dedicated virtual machines for the development work, with very little interaction with my main system. But knowing me, that did not seem likely to happen, as it sounded like a fair amount of hassle. So I aimed for a viable compromise between security and convenient, and one that does not get too much in the way of my current habits. For instance, it seems desirable to have the project files accessible from my unconstrained environment. This way, I could perform certain actions that need access to secret keys or tokens, but are (unlikely) to run code (e.g. git push, git pull from private repositories, gh pr create) from the outside , and the actual build environment can do without access to these secrets. The user experience I thus want is a quick way to enter a development environment where I can do most of the things I need to do while programming (network access, running command line and GUI programs), with access to the current project, but without access to my actual /home directory. I initially followed the blog post Application Isolation using NixOS Containers by Marcin Sucharski and got something working that mostly did what I wanted, but then a colleague pointed out that tools like firejail can achieve roughly the same with a less global setup. I tried to use firejail, but found it to be a bit too inflexible for my particular whims, so I ended up writing a small wrapper around the lower level sandboxing tool https://github.com/containers/bubblewrap.

Selective bubblewrapping This script, called dev and included below, builds a new filesystem namespace with minimal /proc and /dev directories, it s own /tmp directories. It then binds-mound some directories to make the host s NixOS system available inside the container (/bin, /usr, the nix store including domain socket, stuff for OpenGL applications). My user s home directory is taken from ~/.dev-home and some configuration files are bind-mounted for convenient sharing. I intentionally don t share most of the configuration for example, a direnv enable in the dev environment should not affect the main environment. The X11 socket for graphical applications and the corresponding .Xauthority file is made available. And finally, if I run dev in a project directory, this project directory is bind mounted writable, and the current working directory is preserved. The effect is that I can type dev on the command line to enter dev mode rather conveniently. I can run development tools, including graphical ones like VSCode, and especially the latter with its extensions is part of the sandbox. To do a git push I either exit the development environment (Ctrl-D) or open a separate terminal. Overall, the inconvenience of switching back and forth seems worth the extra protection. Clearly, isn t going to hold against a determined and maybe targeted attacker (e.g. access to the X11 and the nix daemon socket can probably be used to escape easily). But I hope it will help against a compromised dev dependency that just deletes or exfiltrates data, like keys or passwords, from the usual places in $HOME.

Rough corners There is more polishing that could be done.
  • In particular, clicking on a link inside VSCode in the container will currently open Firefox inside the container, without access to my settings and cookies etc. Ideally, links would be opened in the Firefox running outside. This is a problem that has a solution in the world of applications that are sandboxed with Flatpak, and involves a bunch of moving parts (a xdg-desktop-portal user service, a filtering dbus proxy, exposing access to that proxy in the container). I experimented with that for a bit longer than I should have, but could not get it to work to satisfaction (even without a container involved, I could not get xdg-desktop-portal to heed my default browser settings ). For now I will live with manually copying and pasting URLs, we ll see how long this lasts.
  • With this setup (and unlike the NixOS container setup I tried first), the same applications are installed inside and outside. It might be useful to separate the set of installed programs: There is simply no point in running evolution or firefox inside the container, and if I do not even have VSCode or cabal available outside, so that it s less likely that I forget to enter dev before using these tools. It shouldn t be too hard to cargo-cult some of the NixOS Containers infrastructure to be able to have a separate system configuration that I can manage as part of my normal system configuration and make available to bubblewrap here.
So likely I will refine this some more over time. Or get tired of typing dev and going back to what I did before

The script
The dev script (at the time of writing)

25 January 2024

Joachim Breitner: GHC Steering Committee Retrospective

After seven years of service as member and secretary on the GHC Steering Committee, I have resigned from that role. So this is a good time to look back and retrace the formation of the GHC proposal process and committee. In my memory, I helped define and shape the proposal process, optimizing it for effectiveness and throughput, but memory can be misleading, and judging from the paper trail in my email archives, this was indeed mostly Ben Gamari s and Richard Eisenberg s achievement: Already in Summer of 2016, Ben Gamari set up the ghc-proposals Github repository with a sketch of a process and sent out a call for nominations on the GHC user s mailing list, which I replied to. The Simons picked the first set of members, and in the fall of 2016 we discussed the committee s by-laws and procedures. As so often, Richard was an influential shaping force here.

Three ingredients For example, it was him that suggested that for each proposal we have one committee member be the Shepherd , overseeing the discussion. I believe this was one ingredient for the process effectiveness: There is always one person in charge, and thus we avoid the delays incurred when any one of a non-singleton set of volunteers have to do the next step (and everyone hopes someone else does it). The next ingredient was that we do not usually require a vote among all members (again, not easy with volunteers with limited bandwidth and occasional phases of absence). Instead, the shepherd makes a recommendation (accept/reject), and if the other committee members do not complain, this silence is taken as consent, and we come to a decision. It seems this idea can also be traced back on Richard, who suggested that once a decision is requested, the shepherd [generates] consensus. If consensus is elusive, then we vote. At the end of the year we agreed and wrote down these rules, created the mailing list for our internal, but publicly archived committee discussions, and began accepting proposals, starting with Adam Gundry s OverloadedRecordFields. At that point, there was no secretary role yet, so how I did become one? It seems that in February 2017 I started to clean-up and refine the process documentation, fixing bugs in the process (like requiring authors to set Github labels when they don t even have permissions to do that). This in particular meant that someone from the committee had to manually handle submissions and so on, and by the aforementioned principle that at every step there ought to be exactly one person in change, the role of a secretary followed naturally. In the email in which I described that role I wrote:
Simon already shoved me towards picking up the secretary hat, to reduce load on Ben.
So when I merged the updated process documentation, I already listed myself secretary . It wasn t just Simon s shoving that put my into the role, though. I dug out my original self-nomination email to Ben, and among other things I wrote:
I also hope that there is going to be clear responsibilities and a clear workflow among the committee. E.g. someone (possibly rotating), maybe called the secretary, who is in charge of having an initial look at proposals and then assigning it to a member who shepherds the proposal.
So it is hardly a surprise that I became secretary, when it was dear to my heart to have a smooth continuous process here. I am rather content with the result: These three ingredients single secretary, per-proposal shepherds, silence-is-consent helped the committee to be effective throughout its existence, even as every once in a while individual members dropped out.

Ulterior motivation I must admit, however, there was an ulterior motivation behind me grabbing the secretary role: Yes, I did want the committee to succeed, and I did want that authors receive timely, good and decisive feedback on their proposals but I did not really want to have to do that part. I am, in fact, a lousy proposal reviewer. I am too generous when reading proposals, and more likely mentally fill gaps in a specification rather than spotting them. Always optimistically assuming that the authors surely know what they are doing, rather than critically assessing the impact, the implementation cost and the interaction with other language features. And, maybe more importantly: why should I know which changes are good and which are not so good in the long run? Clearly, the authors cared enough about a proposal to put it forward, so there is some need and I do believe that Haskell should stay an evolving and innovating language but how does this help me decide about this or that particular feature. I even, during the formation of the committee, explicitly asked that we write down some guidance on Vision and Guideline ; do we want to foster change or innovation, or be selective gatekeepers? Should we accept features that are proven to be useful, or should we accept features so that they can prove to be useful? This discussion, however, did not lead to a concrete result, and the assessment of proposals relied on the sum of each member s personal preference, expertise and gut feeling. I am not saying that this was a mistake: It is hard to come up with a general guideline here, and even harder to find one that does justice to each individual proposal. So the secret motivation for me to grab the secretary post was that I could contribute without having to judge proposals. Being secretary allowed me to assign most proposals to others to shepherd, and only once in a while myself took care of a proposal, when it seemed to be very straight-forward. Sneaky, ain t it?

7 Years later For years to come I happily played secretary: When an author finished their proposal and public discussion ebbed down they would ping me on GitHub, I would pick a suitable shepherd among the committee and ask them to judge the proposal. Eventually, the committee would come to a conclusion, usually by implicit consent, sometimes by voting, and I d merge the pull request and update the metadata thereon. Every few months I d summarize the current state of affairs to the committee (what happened since the last update, which proposals are currently on our plate), and once per year gathered the data for Simon Peyton Jones annually GHC Status Report. Sometimes some members needed a nudge or two to act. Some would eventually step down, and I d sent around a call for nominations and when the nominations came in, distributed them off-list among the committee and tallied the votes. Initially, that was exciting. For a long while it was a pleasant and rewarding routine. Eventually, it became a mere chore. I noticed that I didn t quite care so much anymore about some of the discussion, and there was a decent amount of naval-gazing, meta-discussions and some wrangling about claims of authority that was probably useful and necessary, but wasn t particularly fun. I also began to notice weaknesses in the processes that I helped shape: We could really use some more automation for showing proposal statuses, notifying people when they have to act, and nudging them when they don t. The whole silence-is-assent approach is good for throughput, but not necessary great for quality, and maybe the committee members need to be pushed more firmly to engage with each proposal. Like GHC itself, the committee processes deserve continuous refinement and refactoring, and since I could not muster the motivation to change my now well-trod secretarial ways, it was time for me to step down. Luckily, Adam Gundry volunteered to take over, and that makes me feel much less bad for quitting. Thanks for that! And although I am for my day job now enjoying a language that has many of the things out of the box that for Haskell are still only language extensions or even just future proposals (dependent types, BlockArguments, do notation with ( foo) expressions and Unicode), I m still around, hosting the Haskell Interlude Podcast, writing on this blog and hanging out at ZuriHac etc.

22 December 2023

Joachim Breitner: The Haskell Interlude Podcast

It was pointed out to me that I have not blogged about this, so better now than never: Since 2021 I am together with four other hosts producing a regular podcast about Haskell, the Haskell Interlude. Roughly every two weeks two of us interview someone from the Haskell Community, and we chat for approximately an hour about how they came to Haskell, what they are doing with it, why they are doing it and what else is on their mind. Sometimes we talk to very famous people, like Simon Peyton Jones, and sometimes to people who maybe should be famous, but aren t quite yet. For most episodes we also have a transcript, so you can read the interviews instead, if you prefer, and you should find the podcast on most podcast apps as well. I do not know how reliable these statistics are, but supposedly we regularly have around 1300 listeners. We don t get much feedback, however, so if you like the show, or dislike it, or have feedback, let us know (for example on the Haskell Disourse, which has a thread for each episode). At the time of writing, we released 40 episodes. For the benefit of my (likely hypothetical) fans, or those who want to train an AI voice model for nefarious purposes, here is the list of episodes co-hosted by me: Can t decide where to start? The one with Ryan Trinkle might be my favorite. Thanks to the Haskell Foundation and its sponsors for supporting this podcast (hosting, editing, transscription).

1 November 2023

Joachim Breitner: Joining the Lean FRO

Tomorrow is going to be a new first day in a new job for me: I am joining the Lean FRO, and I m excited.

What is Lean? Lean is the new kid on the block of theorem provers. It s a pure functional programming language (like Haskell, with and on which I have worked a lot), but it s dependently typed (which Haskell may be evolving to be as well, but rather slowly and carefully). It has a refreshing syntax, built on top of a rather good (I have been told, not an expert here) macro system. As a dependently typed programming language, it is also a theorem prover, or proof assistant, and there exists already a lively community of mathematicians who started to formalize mathematics in a coherent library, creatively called mathlib.

What is a FRO? A Focused Research Organization has the organizational form of a small start up (small team, little overhead, a few years of runway), but its goals and measure for success are not commercial, as funding is provided by donors (in the case of the Lean FRO, the Simons Foundation International, the Alfred P. Sloan Foundation, and Richard Merkin). This allows us to build something that we believe is a contribution for the greater good, even though it s not (or not yet) commercially interesting enough and does not fit other forms of funding (such as research grants) well. This is a very comfortable situation to be in.

Why am I excited? To me, working on Lean seems to be the perfect mix: I have been working on language implementation for about a decade now, and always with a preference for functional languages. Add to that my interest in theorem proving, where I have used Isabelle and Coq so far, and played with Agda and others. So technically, clearly up my alley. Furthermore, the language isn t too old, and plenty of interesting things are simply still to do, rather than tried before. The ecosystem is still evolving, so there is a good chance to have some impact. On the other hand, the language isn t too young either. It is no longer an open question whether we will have users: we have them already, they hang out on zulip, so if I improve something, there is likely someone going to be happy about it, which is great. And the community seems to be welcoming and full of nice people. Finally, this library of mathematics that these users are building is itself an amazing artifact: Lots of math in a consistent, machine-readable, maintained, documented, checked form! With a little bit of optimism I can imagine this changing how math research and education will be done in the future. It could be for math what Wikipedia is for encyclopedic knowledge and OpenStreetMap for maps and the thought of facilitating that excites me. With this new job I find that when I am telling friends and colleagues about it, I do not hesitate or hedge when asked why I am doing this. This is a good sign.

What will I be doing? We ll see what main tasks I ll get to tackle initially, but knowing myself, I expect I ll get broadly involved. To get up to speed I started playing around with a few things already, and for example created Loogle, a Mathlib search engine inspired by Haskell s Hoogle, including a Zulip bot integration. This seems to be useful and quite well received, so I ll continue maintaining that. Expect more about this and other contributions here in the future.

29 October 2023

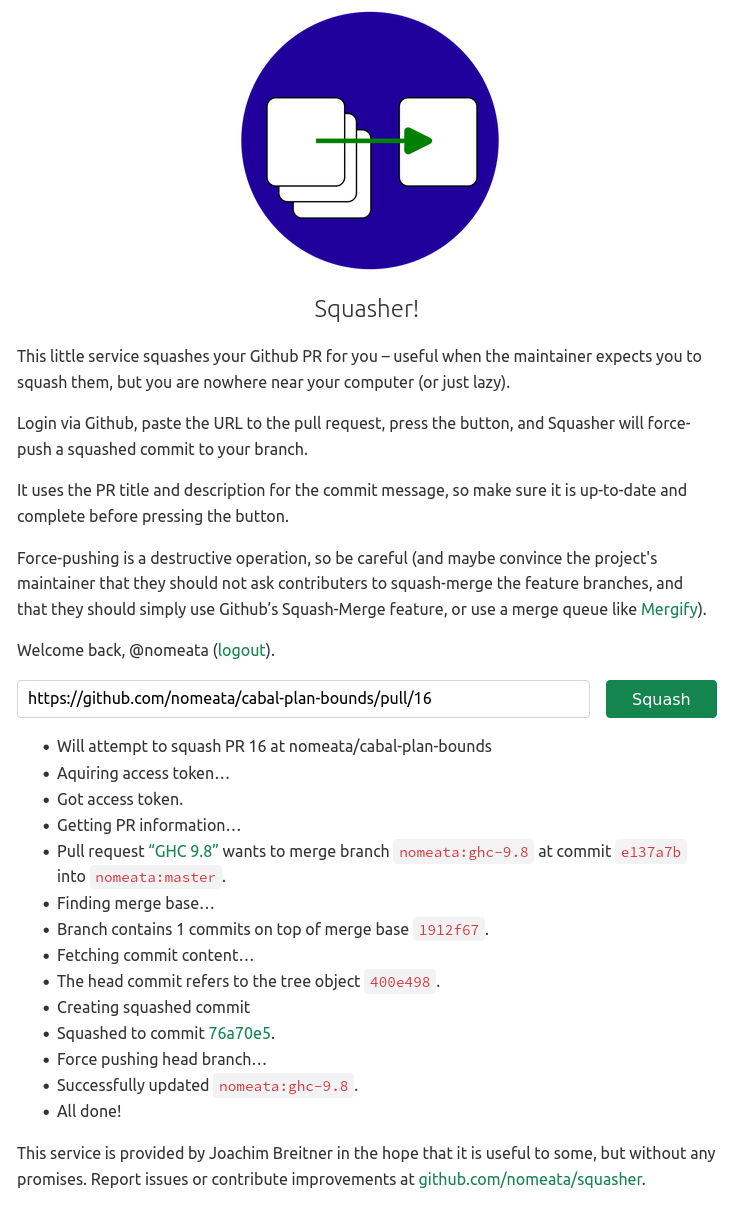
Joachim Breitner: Squash your Github PRs with one click

TL;DR: Squash your PRs with one click at https://squasher.nomeata.de/. Very recently I got this response from the project maintainer at a pull request I contributed: Thanks, approved, please squash so that I can merge. It s nice that my contribution can go it, but why did the maintainer not just press the Squash and merge button , and instead adds the this unnecessary roundtrip to the process? Anyways, maintainers make the rules, so I play by them. But unlike the maintainer, who can squash-and-merge with just one click, squashing the PR s branch is surprisingly laberous: Github does not allow you to do that via the Web UI (and hence on mobile), and it seems you are expected to go to your computer and juggle with git rebase --interactive. I found this rather annoying, so I created Squasher, a simple service that will squash your branch for you. There is no configuration, just paste the PR url. It will use the PR title and body as the commit message (which is obviously the right way ), and create the commit in your name:
Squasher in actionSquasher in action
If you find this useful, or found it to be buggy, let me know. The code is at https://github.com/nomeata/squasher if you are curious about it.

20 September 2023

Joey Hess: Haskell webassembly in the browser


live demo As far as I know this is the first Haskell program compiled to Webassembly (WASM) with mainline ghc and using the browser DOM. ghc's WASM backend is solid, but it only provides very low-level FFI bindings when used in the browser. Ints and pointers to WASM memory. (See here for details and for instructions on getting the ghc WASM toolchain I used.) I imagine that in the future, WASM code will interface with the DOM by using a WASI "world" that defines a complete API (and browsers won't include Javascript engines anymore). But currently, WASM can't do anything in a browser without calling back to Javascript. For this project, I needed 63 lines of (reusable) javascript (here). Plus another 18 to bootstrap running the WASM program (here). (Also browser_wasi_shim) But let's start with the Haskell code. A simple program to pop up an alert in the browser looks like this:
 -# LANGUAGE OverloadedStrings #- 
import Wasmjsbridge
foreign export ccall hello :: IO ()
hello :: IO ()
hello = do
    alert <- get_js_object_method "window" "alert"
    call_js_function_ByteString_Void alert "hello, world!"
A larger program that draws on the canvas and generated the image above is here. The Haskell side of the FFI interface is a bunch of fairly mechanical functions like this:
foreign import ccall unsafe "call_js_function_string_void"
    _call_js_function_string_void :: Int -> CString -> Int -> IO ()
call_js_function_ByteString_Void :: JSFunction -> B.ByteString -> IO ()
call_js_function_ByteString_Void (JSFunction n) b =
      BU.unsafeUseAsCStringLen b $ \(buf, len) ->
                _call_js_function_string_void n buf len
Many more would need to be added, or generated, to continue down this path to complete coverage of all data types. All in all it's 64 lines of code so far (here). Also a C shim is needed, that imports from WASI modules and provides C functions that are used by the Haskell FFI. It looks like this:
void _call_js_function_string_void(uint32_t fn, uint8_t *buf, uint32_t len) __attribute__((
        __import_module__("wasmjsbridge"),
        __import_name__("call_js_function_string_void")
));
void call_js_function_string_void(uint32_t fn, uint8_t *buf, uint32_t len)  
        _call_js_function_string_void(fn, buf, len);
 
Another 64 lines of code for that (here). I found this pattern in Joachim Breitner's haskell-on-fastly and copied it rather blindly. Finally, the Javascript that gets run for that is:
call_js_function_string_void(n, b, sz)  
    const fn = globalThis.wasmjsbridge_functionmap.get(n);
    const buffer = globalThis.wasmjsbridge_exports.memory.buffer;
    fn(decoder.decode(new Uint8Array(buffer, b, sz)));
 ,
Notice that this gets an identifier representing the javascript function to run, which might be any method of any object. It looks it up in a map and runs it. And the ByteString that got passed from Haskell has to be decoded to a javascript string. In the Haskell program above, the function is document.alert. Why not pass a ByteString with that through the FFI? Well, you could. But then it would have to eval it. That would make running WASM in the browser be evaling Javascript every time it calls a function. That does not seem like a good idea if the goal is speed. GHC's javascript backend does use Javascript FFI snippets like that, but there they get pasted into the generated Javascript hairball, so no eval is needed. So my code has things like get_js_object_method that look up things like Javascript functions and generate identifiers. It also has this:
call_js_function_ByteString_Object :: JSFunction -> B.ByteString -> IO JSObject
Which can be used to call things like document.getElementById that return a javascript object:
getElementById <- get_js_object_method (JSObjectName "document") "getElementById"
canvas <- call_js_function_ByteString_Object getElementById "myCanvas"
Here's the Javascript called by get_js_object_method. It generates a Javascript function that will be used to call the desired method of the object, and allocates an identifier for it, and returns that to the caller.
get_js_objectname_method(ob, osz, nb, nsz)  
    const buffer = globalThis.wasmjsbridge_exports.memory.buffer;
    const objname = decoder.decode(new Uint8Array(buffer, ob, osz));
    const funcname = decoder.decode(new Uint8Array(buffer, nb, nsz));
    const func = function (...args)   return globalThis[objname][funcname](...args)  ;
    const n = globalThis.wasmjsbridge_counter + 1;
    globalThis.wasmjsbridge_counter = n;
    globalThis.wasmjsbridge_functionmap.set(n, func);
    return n;
 ,
This does mean that every time a Javascript function id is looked up, some more memory is used on the Javascript side. For more serious uses of this, something would need to be done about that. Lots of other stuff like object value getting and setting is also not implemented, there's no support yet for callbacks, and so on. Still, I'm happy where this has gotten to after 12 hours of work on it. I might release the reusable parts of this as a Haskell library, although it seems likely that ongoing development of ghc will make it obsolete. In the meantime, clone the git repo to have a play with it.
This blog post was sponsored by unqueued on Patreon.

10 October 2022

Joachim Breitner: rec-def: Minesweeper case study

I m on the train back from MuniHac, where I gave a talk about the rec-def library that I have excessively blogged about recently (here, here, here and here). I got quite flattering comments about that talk, so if you want to see if they were sincere, I suggest you watch the recording of Getting recursive definitions off their bottoms (but it s not necessary for the following). After the talk, Franz Thoma approached me and told me a story of how we was once implementing the game Minesweeper in Haskell, and in particular the part of the logic where, after the user has uncovered a field, the game would automatically uncover all fields that are next to a neutral field, i.e. one with zero adjacent bombs. He was using a comonadic data structure, which makes a context-dependent parallel computation such as uncovering one field quite natural, and was hoping that using a suitable fix-point operator, he can elegantly obtain not just the next step, but directly the result of recursively uncovering all these fields. But, much to his disappointment, that did not work out: Due to the recursion inherent in that definition, a knot-tying fixed-point operator will lead to a cyclic definition.
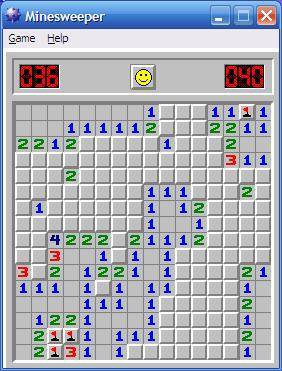
Microsoft Minesweeper Microsoft Minesweeper
He was wondering if the rec-def library could have helped him, and we sat down to find out, and this is the tale of this blog post. I will avoid the comonadic abstractions and program it more naively, though, to not lose too many readers along the way. Maybe read Chris Penner s blog post and Finch s functional pearl Getting a Quick Fix on Comonads if you are curious about that angle.

Minesweeper setup Let s start with defining a suitable data type for the grid of the minesweeper board. I ll use the Array data type, it s Ix-based indexing is quite useful for grids: The library lacks a function to generate an array from a generating function, but it is easy to add: Let s also fix the size of the board, as a pair of lower and upper bounds (this is the format that the Ix type class needs): Now board is simply a grid of boolean values, with True indicating that a bomb is there: It would be nice to be able to see these board in a nicer way. So let us write A function that prints a grid, including a frame, given a function that prints something for each coordinate. Together with a function that prints a bomb (as *), we can print the board: The expression b ! c looks up a the coordinate in the array, and is True when there is a bomb at that coordinate. So here is our board, with two bombs:
ghci> putStrLn $ pBombs board1
######
#    #
#*   #
#*   #
#    #
######
But that s not what we want to show to the user: Every field should have have a number that indicates the number of bombs in the surrounding fields. To that end, we first define a function that takes a coordinate, and returns all adjacent coordinates. This also takes care of the border, using inRange: With that, we can calculate what to display in each cell a bomb, or a number: With a suitable printing function, we can now see the full board: And here it is:
ghci> putStrLn $ pBoard board1
######
#11  #
#*2  #
#*2  #
#11  #
######
Next we have to add masks: We need to keep track of which fields the user already sees. We again use a grid of booleans, and define a function to print a board with the masked fields hidden behind ?:
So this is what the user would see
ghci> putStrLn $ pMasked board1 mask1
######
#11 ?#
#????#
#????#
#????#
######

Uncovering some fields With that setup in place, we now implement the piece of logic we care about: Uncovering all fields that are next to a neutral field. Here is the first attempt: The idea is that we calculate the new mask m1 from the old one m0 by the following logic: A field is visible if it was visible before (m0 ! c), or if any of its neighboring, neutral fields are visible. This works so far: I uncovered the three fields next to the one neutral visible field:
ghci> putStrLn $ pMasked board1 $ solve0 board1 mask1
######
#11  #
#?2  #
#????#
#????#
######
But that s not quite what we want: We want to keep doing that to uncover all fields.

Uncovering all fields So what happens if we change the logic to: A field is visible if it was visible before (m0 ! c), or if any of its neighboring, neutral fields will be visible. In the code, this is just a single character change: Instead of looking at m0 to see if a neighbor is visible, we look at m1: (This is roughly what happened when Franz started to use the kfix comonadic fixed-point operator in his code, I believe.) Does it work? It seems so:
ghci> putStrLn $ pMasked board1 $ solve1 board1 mask1
######
#11  #
#?2  #
#?2  #
#?1  #
######
Amazing, isn t it! Unfortunately, it seems to work by accident. If I start with a different mask: which looks as follows:
ghci> putStrLn $ pMasked board1 mask2
######
#11??#
#????#
#????#
#??? #
######
Then our solve1 function does not work, and just sits there:
ghci> putStrLn $ pMasked board1 $ solve1 board1 mask2
######
#11^CInterrupted.
Why did it work before, but now now? It fails to work because as the code tries to figure out if a field, it needs to know if the next field will be uncovered. But to figure that out, it needs to know if the present field will be uncovered. With the normal boolean connectives ( and or), this does not make progress. It worked with mask1 more or less by accident: None of the fields on in the first column don t have neutral neighbors, so nothing happens there. And for all the fields in the third and forth column, the code will know for sure that they will be uncovered based on their upper neighbors, which come first in the neighbors list, and due to the short-circuting properties of , it doesn t have to look at the later cells, and the vicious cycle is avoided.

rec-def to the rescue This is where rec-def comes in: By using the RBool type in m1 instead of plain Bool, the recursive self-reference is not a problem, and it simply works: Note that I did not change the algorithm, or the self-reference through m1; I just replaced Bool with RBool, with RB. and or with RB.or. And used RB.get at the end to get a normal boolean out. And , here we go:
ghci> putStrLn $ pMasked board1 $ solve2 board1 mask2
######
#11  #
#?2  #
#?2  #
#?1  #
######
That s the end of this repetition of let s look at a tying-the-knot-problem and see how rec-def helps , which always end up a bit anti-climatic because it just works , at least in these cases. Hope you enjoyed it nevertheless.

15 September 2022

Joachim Breitner: rec-def: Dominators case study

More ICFP-inspired experiments using the rec-def library: In Norman Ramsey s very nice talk about his Functional Pearl Beyond Relooper: Recursive Translation of Unstructured Control Flow to Structured Control Flow , he had the following slide showing the equation for the dominators of a node in a graph:
Norman Ramsey shows a formula Norman Ramsey shows a formula
He said it s ICFP and I wanted to say the dominance relation has a beautiful set of equations you can read all these algorithms how to compute this, but the concept is simple . This made me wonder: If the concept is simple and this formula is beautiful shouldn t this be sufficient for the Haskell programmer to obtain the dominator relation, without reading all those algorithms? Before we start, we have to clarify the formula a bit: If a node is an entry node (no predecessors) then the big intersection is over the empty set, and that is not a well-defined concept. For these nodes, we need that big intersection to return the empty set, as entry nodes are not dominated by any other node. (Let s assume that the entry nodes are exactly those with no predecessors.) Let s try, first using plain Haskell data structures. We begin by implementing this big intersection operator on Data.Set, and also a function to find the predecessors of a node in a graph: Now we can write down the formula that Norman gave, quite elegantly: Does this work? It seems it does: But not surprising if you have read my previous blog posts it falls over once we have recursion: So let us reimplement it with Data.Recursive.Set. The hope is that we can simply replace the operations, and that now it can suddenly handle cyclic graphs as well. Let s see: It does! Well, it does return a result but it looks strange. Clearly node 3 and 4 are also dominated by 1, but the result does not reflect that. But the result is a solution to Norman s equation. Was the equation wrong? No, but we failed to notice that the desired solution is the largest, not the smallest. And Data.Recursive.Set calculates, as documented, the least fixed point. What now? Until the library has code for RDualSet a, we can work around this by using the dual formula to calculate the non-dominators. To do this, we
  • use union instead of intersection
  • delete instead of insert,
  • S.empty, use the set of all nodes (which requires some extra plumbing)
  • subtract the result from the set of all nodes to get the dominators
and thus the code turns into:
And with this, now we do get the correct result:
ghci> domintors3 [(1,2),(1,3),(2,4),(3,4),(4,3)]
fromList [(1,[1]),(2,[1,2]),(3,[1,3]),(4,[1,4])]
We worked a little bit on how to express the beautiful formula to Haskell, but at no point did we have to think about how to solve it. To me, this is the essence of declarative programming.

14 September 2022

Joachim Breitner: rec-def: Program analysis case study

At this week s International Conference on Functional Programming I showed my rec-def Haskell library to a few people. As this crowd appreciates writing compilers, and example from the realm of program analysis is quite compelling.

To Throw or not to throw Here is our little toy language to analyze: It has variables, lambdas and applications, non-recursive (lazy) let bindings and, so that we have something to analyze, a way to throw and to catch exceptions: Given such an expression, we would like to know whether it might throw an exception. Such an analysis is easy to write: We traverse the syntax tree, remembering in the env which of the variables may throw an exception: The most interesting case is the one for Let, where we extend the environment env with the information about the additional variable env_bind, which is calculated from analyzing the right-hand side e1. So far so good:
ghci> someVal = Lam "y" (Var "y")
ghci> canThrow1 $ Throw
True
ghci> canThrow1 $ Let "x" Throw someVal
False
ghci> canThrow1 $ Let "x" Throw (App (Var "x") someVal)
True

Let it rec To spice things up, let us add a recursive let to the language: How can we support this new constructor in canThrow1? Let use naively follow the pattern used for Let: Calculate the analysis information for the variables in env_bind, extend the environment with that, and pass it down: Note that, crucially, we use env', and not just env, when analyzing the right-hand sides. It has to be that way, as all the variables are in scope in all the right-hand sides. In a strict language, such a mutually recursive definition, where env_bind uses env' which uses env_bind is basically unthinkable. But in a lazy language like Haskell, it might just work. Unfortunately, it works only as long as the recursive bindings are not actually recursive, or if they are recursive, they are not used:
ghci> canThrow1 $ LetRec [("x", Throw)] (Var "x")
True
ghci> canThrow1 $ LetRec [("x", App (Var "y") someVal), ("y", Throw)] (Var "x")
True
ghci> canThrow1 $ LetRec [("x", App (Var "x") someVal), ("y", Throw)] (Var "y")
True
But with genuine recursion, it does not work, and simply goes into a recursive cycle:
ghci> canThrow1 $ LetRec [("x", App (Var "x") someVal), ("y", Throw)] (Var "x")
^CInterrupted.
That is disappointing! Do we really have to toss that code and somehow do an explicit fixed-point calculation here? Obscuring our nice declarative code? And possibly having to repeat work (such as traversing the syntax tree) many times that we should only have to do once?

rec-def to the rescue Not with rec-def! Using RBool from Data.Recursive.Bool instead of Bool, we can write the exact same code, as follows: And it works!
ghci> canThrow2 $ LetRec [("x", App (Var "x") someVal), ("y", Throw)] (Var "x")
False
ghci> canThrow2 $ LetRec [("x", App (Var "x") Throw), ("y", Throw)] (Var "x")
True
I find this much more pleasing than the explicit naive fix-pointing you might do otherwise, where you stabilize the result at each LetRec independently: Not only is all that extra work hidden from the programmer, but now also a single traversal of the syntax tree creates, thanks to the laziness, a graph of RBool values, which are then solved under the hood .

The issue with x=x There is one downside worth mentioning: canThrow2 fails to produce a result in case we hit x=x:
ghci> canThrow2 $ LetRec [("x", Var "x")] (Var "x")
^CInterrupted.
This is, after all the syntax tree has been processed and all the map lookups have been resolved, equivalent to
ghci> let x = x in RB.get (x :: RBool)
^CInterrupted.
which also does not work. The rec-def machinery can only kick in if at least one of its function is used on any such cycle, even if it is just a form of identity (which I ~ought to add to the library~ since have added to the library):
ghci> idR x = RB.false   x
ghci> let x = idR x in getR (x :: R Bool)
False
And indeed, if I insert a call to idR in the line then our analyzer will no longer stumble over these nasty recursive equations:
ghci> canThrow2 $ LetRec [("x", Var "x")] (Var "x")
False
It is a bit disappointing to have to do that, but I do not see a better way yet. I guess the def-rec library expects the programmer to have a similar level of sophistication as other tie-the-know tricks with laziness (where you also have to ensure that your definitions are productive and that the sharing is not accidentally lost).

10 September 2022

Joachim Breitner: rec-def: Behind the scenes

A week ago I wrote about the rec-def Haskell library, which allows you to write more recursive definitions, such as in this small example:
let s1 = RS.insert 23 s2
    s2 = RS.insert 42 s1
in RS.get s1
This will not loop (as it would if you d just used Data.Set), but rather correctly return the set S.fromList [23,42]. See the previous blog post for more examples and discussion of the user-facing side of this. For quick reference, these are the types of the functions involved here: The type of s1 and s2 above is not Set Int, but rather RSet Int, and in this post I ll explain how RSet works internally.

Propagators, in general The conceptual model behind an recursive equation like above is
  • There are a multiple cells that can hold values of an underlying type (here Set)
  • These cells have relations that explain how the values in the cells should relate to each other
  • After registering all the relations, some form of solving happens.
  • If the solving succeeds, we can read off the values from the cells, and they should satisfy the registered relation.
This is sometimes called a propagator network, and is a quite general model that can support different kind of relations (e.g. equalities, inequalities, functions), there can be various solving strategies (iterative fixed-points, algebraic solution, unification, etc.) and information can flow on along the edges (and hyper-edges) possibly in multiple directions. For our purposes, we only care about propagator networks where all relations are functional, so they have a single output cell that is declared to be a function of multiple (possibly zero) input cells, without affecting these input cells. Furthermore, every cell is the output of exactly one such relation.

IO-infested propagator interfaces This suggests that an implementation of such a propagator network could provide an interface with the following three operations:
  • Functions to declare cells
  • Functions to declare relations
  • Functions to read values off cells
This is clearly an imperative interface, so we ll see monads, and we ll simply use IO. So concretely for our small example above, we might expect
There is no need for an explicit solve function: solving can happen when declareInsert or getCell is called as a User I do not care about that. You might be curious about the implementation of newCell, declareInsert and getCell, but I have to disappoint you: This is not the topic of this article. Instead, I want to discuss how to turn this IO-infested interface into the pure interface seen above?

Pure, but too strict Obviously, we have to get rid of the IO somehow, and have to use unsafePerformIO :: IO a -> a somehow. This dangerous function creates a pure-looking value that, when used the first time, will run the IO-action and turn into that action s result. So maybe we can simply write the following: Indeed, the types line up, but if we try to use that code, nothing will happen. Our insert is too strict to be used recursively: It requires the value of c2 (as it is passed to declareInsert, which we assume to be strict in its arguments) before it can return c1, so the recursive example at the top of this post will not make any progress.

Pure, lazy, but forgetful To work around this, maybe it suffices if we do not run declareInsert right away, but just remember that we have to do it eventually? So let s introduce a new data type for RSet a that contains not just the cell (Cell a), but also an action that we still have to run before getting a value: This is better: insert is now lazy in its arguments (for this it is crucial to pattern-match on RSet only inside the todo code, not in the pattern of insert!) This means that our recursive code above does not get stuck right away.

Pure, lazy, but runs in circles But it is still pretty bad: Note that we do not run get s2 in the example above, so that cell s todo, which would declareInsert 42, will never run. This cannot work! We have to (eventually) run the declaration code from all involved cells before we can use getCell! We can try to run the todo action of all the dependencies as part of a cell s todo action: Now we certainly won t forget to run the second cell s todo action, so that is good. But that cell s todo action will run the first cell s todo action, and that again the second cell s, and so on.

Pure, lazy, terminating, but not thread safe This is silly: We only need (and should!) run that code once! So let s keep track of whether we ran it already: Ah, much better: It works! Our call to get c1 will trigger the first cell s todo action, which will mark it as done before calling the second cell s todo action. When that now invokes the first cell s todo action, it is already marked done and we break the cycle, and by the time we reach getCell, all relations have been correctly registered. In a single-threaded world, this would be all good and fine, but we have to worry about multiple threads running get concurrently, on the same or on different cells. In fact, because we use unsafePerformIO, we have to worry about this even when the program is not using threads. And the above code has problems. Imagine a second call to get c1 while the first one has already marked it as done, but has not finished processing all the dependencies yet: It will call getCell before all relations are registered, which is bad.

Recursive do-once IO actions Making this thread-safe seems to be possible, but would clutter both the code and this blog post. So let s hide that problem behind a nice and clean interface. Maybe there will be a separate blog post about its implementation (let me know if you are curious), or you can inspect the code in System.IO.RecThunk module yourself). The interface is simply
data Thunk
thunk :: IO [Thunk] -> IO Thunk
force :: Thunk -> IO ()
and the idea is that thunk act will defer the action act until the thunk is passed to force for the first time, and force will not return until the action has been performed (possibly waiting if another thread is doing that at the moment), and also until the actions of all the thunks returned by act have performed, recursively, without running into cycles. We can use this in our definition of RSet and get to the final, working solution: This snippet captures the essential ideas behind rec-def:
  • Use laziness to allow recursive definition to describe the propagator graph naturally
  • Use a form of explicit thunk to register the propagator graph relations at the right time (not too early/strict, not too late)

And that s all? The actual implementation in rec-def has a few more moving parts. In particular, it tries to support different value types (not just sets), possibly with different implementations, and even mixing them (e.g. in member :: Ord a => a -> RSet a -> RBool), so the generic code is in Data.Propagator.Purify, and supports various propagators underneath. The type RSet is then just a newtype around that, defined in Data.Recursive.Internal to maintain the safety of the abstraction, I went back and forth on a few variants of the design here, including one where there was a generic R type constructor (R (Set a), R Bool etc.), but then monomorphic interface seems simpler.

Does it really work? The big remaining question is certainly: Is this really safe and pure? Does it still behave like Haskell? The answer to these questions certainly depends on the underlying propagator implementation. But it also depends on what we actually mean by safe and pure ? For example, do we expect the Static Argument Transformation be semantics preserving? Or is it allowed to turn undefined values into defined ones (as it does here)? I am unsure myself yet, so I ll defer this discussion to a separate blog post, after I hopefully had good discussions about this here at ICFP 2022 in Ljubljana. If you are around and want to discuss, please hit me up!

3 September 2022

Joachim Breitner: More recursive definitions

Haskell is a pure and lazy programming language, and the laziness allows us to write some algorithms very elegantly, by recursively referring to already calculated values. A typical example is the following definition of the Fibonacci numbers, as an infinite stream:

Elegant graph traversals A maybe more practical example is the following calculation of the transitive closure of a graph: We represent graphs as maps from vertex to their successors vertex, and define the resulting map sets recursively: The set of reachable vertices from a vertex v is v itself, plus those reachable by its successors vs, for which we query sets. And, despite this apparent self-referential recursion, it works!

Cyclic graphs ruin it all These tricks can be very impressive until someone tries to use it on a cyclic graph and the program just hangs until we abort it: At this point we are thrown back to implement a more pedestrian graph traversal, typically keeping explicit track of vertices that we have seen already: I have written that seen/todo recursion idiom so often in the past, I can almost write it blindly And indeed, this code handles cyclic graphs just fine:
ghci> transitive2 $ M.fromList [(1,[2,3]),(2,[1,3]),(3,[])]
fromList [(1,[1,2,3]),(2,[1,2,3]),(3,[3])]
But this is a bit anticlimactic Haskell is supposed to be a declarative language, and transitive1 declares my intent just fine!

We can have it all It seems there actually is a way to write essentially the code in transitive1, and still get the right result in all cases, and I have just published a possible implementation as rec-def. In the module Data.Recursive.Set we find an API that resembles that of Set, with a type RSet a, and in addition to conversion functions from and to sets, we find the two operations that we needed in transitive1: Let s try that: And indeed it works! Magic!
ghci> transitive2 $ M.fromList [(1,[3]),(2,[1,3]),(3,[])]
fromList [(1,[1,3]),(2,[1,2,3]),(3,[3])]
ghci> transitive2 $ M.fromList [(1,[2,3]),(2,[1,3]),(3,[])]
fromList [(1,[1,2,3]),(2,[1,2,3]),(3,[3])]
To show off some more, here are small examples:
ghci> let s = RS.insert 42 s in RS.get s
fromList [42]
ghci> : 
  let s1 = RS.insert 23 s2
      s2 = RS.insert 42 s1
  in RS.get s1
 : 
fromList [23,42]

How is that possible? Is it still Haskell? The internal workings of the RSet a type will be the topic of a future blog post; let me just briefly mention that it uses unsafe features under the hood, and just keeps applying the equations you gave until a fixed-point is reached. Because it starts with the empty set and all operations provided by Data.Recursive.Set are monotonous (e.g. no difference) it will eventually find the least fixed point. Despite the unsafe machinery under the hood, I claim that Data.Recursive.Set is itself nicely safe, and does not destroy Haskell s nice properties like purity, referential transparency and equational reasoning. If you disagree, I d like to hear about it (here, on Twitter, Reddit or Discourse)! There is a brief discussion at the end of the tutorial in Data.Recursive.Example.

More than sets The library also provides Data.Recursive.Bool for recursive equations with booleans (preferring False) and Data.Recursive.DualBool (preferring True), and some operations like member :: Ord a => a -> RSet a -> RBool can actually connect different types. I plan to add other data types (natural numbers, maps, Maybe, with suitable orders) as demand arises and as I come across nice small example use-cases for the documentation (e.g. finding shortest paths in a graph). I believe this idiom is practically useful in a wide range of applications (which of course all have some underlying graph structure but then almost everything in Computer Science is a graph). My original motivation was a program analysis. Imagine you want to find out from where in your program you can run into a division by zero. As long as your program does not have recursion, you can simply keep track of a boolean flag while you traverse the program, keeping track a mapping from function names to whether they can divide by zero all nice and elegant. But once you allow mutually recursive functions, things become tricky. Unless you use RBool! Simply use laziness, pass the analysis result down when analyzing the function s right-hand sides, and it just works!

31 July 2022

Joachim Breitner: The Via Alpina red trail through Slovenia

This July my girlfriend and I hiked the Slovenian part of the Red Trail of the Via Alpina, from the edge of the Julian Alps to Trieste, and I d like to share some observations and tips that we might have found useful before our trip.
Our most favorite camp spot Our most favorite camp spot

Getting there As we traveled with complete camping gear and wanted to stay in our tent, we avoided the high alpine parts of the trail and started just where the trail came down from the Alps and entered the Karst. A great way to get there is to take the night train from Zurich or Munich towards Ljubljana, get off at Jesenice, have breakfast, take the local train to Podbrdo and you can start your tour at 9:15am. From there you can reach the trail at Pedrovo Brdo within 1 h.

Finding the way We did not use any paper maps, and instead relied on the OpenStreetMap data, which is very good, as well as the official(?) GPX tracks on Komoot, which are linked from the official route descriptions. We used OsmAnd. In general, trails are generally very well marked (red circle with white center, and frequent signs), but the signs rarely tell you which way the Via Alpina goes, so the GPS was needed. Sometimes the OpenStreetMap trail and the Komoot trail disagreed on short segments. We sometimes followed one and other times the other.

Variants We diverged from the trail in a few places:
  • We did not care too much about the horses in Lipica and at least on the map it looked like a longish boringish and sun-exposed detour, so we cut the loop and hiked from Prelo e pri Lokvi up onto the peak of the Veliko Gradi e (which unfortunately is too overgrown to provide a good view).
  • When we finally reached the top of Mali Kras and had a view across the bay of Trieste, it seemed silly to walk to down to Dolina, and instead we followed the ridge through Socerb, essentially the Alpe Adria Trail.
  • Not really a variant, but after arriving in Muggia, if one has to go to Trieste, the ferry is a probably nicer way to finish a trek than the bus.

Pitching a tent We used our tent almost every night, only in Idrija we got a room (and a shower ). It was not trivial to find good camp spots, because most of the trail is on hills with slopes, and the flat spots tend to have housed built on them, but certainly possible. Sometimes we hid in the forest, other times we found nice small and freshly mowed meadows within the forest.

Water Since this is Karst land, there is very little in terms of streams or lakes along the way, which is a pity. The Idrijca river right south of Idrija was very tempting to take a plunge. Unfortunately we passed there early in the day and we wanted to cover some ground first, so we refrained. As for drinking water, we used the taps at the bathrooms of the various touristic sites, a few (but rare) public fountains, and finally resorted to just ringing random doorbells and asking for water, which always worked.

Paths A few stages lead you through very pleasant narrow forest paths with a sight, but not all. On some days you find yourself plodding along wide graveled or even paved forest roads, though.

Landscape and sights The view from Nanos is amazing and, with this high peak jutting out over a wide plain, rather unique. It may seem odd that the trail goes up and down that mountain on the same day when it could go around, but it is certainly worth it. The Karst is mostly a cultivated landscape, with lots of forestry. It is very hilly and green, which is pretty, but some might miss some craggedness. It s not the high alps, after all, but at least they are in sight half the time. But the upside is that there are few sights along the way that are worth visiting, in particular the the Franja Partisan Hospital hidden in a very narrow gorge, the Predjama Castle and the kocjan Caves

3 January 2022

Joachim Breitner: Telegram bots in Python made easy

A while ago I set out to get some teenagers interested in programming, and thought about a good way to achieve that. A way that allows them to get started with very little friction, build something that s relevant in their currently live quickly, and avoids frustration. They were old enough to have their own smartphone, and they were already happily chatting with their friends, using the Telegram messenger. I have already experimented a bit with writing bots for Telegram (e.g. @Umklappbot or @Kaleidogen), and it occurred to me that this might be a good starting point: Chat bot interactions have a very simple data model: message in, response out, all simple text. Much simpler than anything graphical or even web programming. In a way it combines the simplicity of the typical initial programming exercises on the command-line with the impact and relevance of web programming. But of course real bot programming is still too hard installing a programming environment, setting up a server, deploying, dealing with access tokens, understanding the Telegram Bot API and mapping it to your programming language.
The IDEThe IDE
So I built a browser-based Python programming environments for Telegram bots that takes care of all of that. You simply write a single Python function, click the Deploy button, and the bot is live. That s it! This environment provides a much simpler API for the bots: Define a function like the following:
  def private_message(sender, text):
     return "Hello!"
This gets called upon a message, and if it returns a String, that s the response. That s it! Not enough to build any kind of Telegram bot, but sufficient for many fun applications.
A chatbotA chatbot
In fact, my nephew and niece use this to build a simple interactive fiction game, where the player says where they are going ( house , forest , lake ) and thus explore the story, and in the end kill the dragon. And my girlfriend created a shopping list bot that we are using productively . If you are curious, you can follow the instructions to create your own bot. There you can also find the source code and instructions for hosting your own instance (on Amazon Web Services). Help with the project (e.g. improving the sandbox for running untrustworthy python code; making the front-end work better) is of course highly appreciated, too. The frontend is written in PureScript, and the backend in Python, building on Amazon lambda and Amazon DynamoDB.

Next.