Search Results: "mpalmer"

27 August 2025

Matthew Palmer: StrongBox: Simple, Safe Data Encryption for Rust

Some time ago, I wanted to encrypt a bunch of data in an application I was writing in Rust, mostly to be stored in a database, but also session cookies and sensitive configuration variables. Since Rust is widely known as a secure-yet-high-performance programming language, I was expecting that there would be a widely-used crate that gave me a secure, high-level interface to strong, safe cryptography. Imagine my surprise when I discovered that just didn t seem to exist. Don t get me wrong: Rust is replete with fast, secure, battle-tested cryptographic primitives. The RustCrypto group provides all manner of robust, widely-used crates for all manner of cryptography-related purposes. They re the essential building blocks for practical cryptosystems, but using them directly in an application is somewhat akin to building a car from individual atoms of iron and carbon. So I wrote my own high-level data encryption library, called it StrongBox, and have been happily encrypting and decrypting data ever since.

Cryptography So Simple Even I Can t Get It Wrong The core of StrongBox is the StrongBox trait, which has only two methods: encrypt and decrypt, each of which takes just two arguments. The first argument is the plaintext (for encrypt) or the ciphertext (for decrypt) to work on. The second argument is the encryption context, for use as Authenticated Additional Data, an important part of many uses of encryption. There s essentially no configuration or parameters to get wrong. You can t choose the encryption algorithm, or block cipher mode, and you don t have to worry about generating a secure nonce. You create a StrongBox with a key, and then you call encrypt and decrypt. That s it.

Practical Cryptographic Affordances Ok, ok that s not quite it. Because StrongBox is even easier to use than what I ve described, thanks to the companion crate, StructBox. When I started using StrongBox in the wild , it quickly became clear that what I almost always wanted to encrypt in my application wasn t some ethereal plaintext . I wanted to encrypt things, specifically structs (and enums). So, through the magic of Rust derive macros, I built StructBox, which provides encrypt and decrypt operations on any Serde-able type. Given that using Serde encoders can be a bit fiddly to use, it s virtually easier to get an encrypted, serialized struct than it is to get a plaintext serialized struct.

Key Problems in Cryptography The thing about cryptography is that it largely turns all data security problems into key management problems. All the fancy cryptographic wonkery is for naught if you don t manage the encryption keys well. So, most of the fancy business in StrongBox isn t the encryption and decryption, but instead solving problems around key management.

Different Keys for Different Purposes Using the same key for all of your cryptographic needs is generally considered a really bad idea. It opens up all manner of risks, that are easily avoided if you use different keys for different things. However, having to maintain a big pile of different keys is a nightmare, so nobody s going to do that. Enter: key derivation. Create one safe, secure root key, and then use a key derivation function to spawn as many other keys as you need. Different keys for each database column, another one to encrypt cookies, and so on. StrongBox supports this through the StemStrongBox type. You ll typically start off by creating a StemStrongBox with the root key, and then derive whatever other StrongBoxes you need, for encrypting and decrypting different kinds of data.

You Spin Me Round Sometimes, keys need to be rotated. Whether that s because you actually know (or even have reason to suspect) someone has gotten the key, or just because you re being appropriately paranoid, sometimes key rotation has to happen. As someone who has had to rotate keys in situations where such an eventuality was not planned for, I can say with some degree of authority: it absolutely sucks to have to do an emergency key rotation in a system that isn t built to make that easy. That s why StrongBox natively supports key rotation. Every StrongBox takes one encryption key, and an arbitrary number of decryption keys, and will automatically use the correct key to decrypt ciphertexts.

Will You Still Decrypt Me, Tomorrow? In addition to manual key rotation, StrongBox also supports time-based key rotation with the RotatingStrongBox type. This comes in handy when you re encrypting a lot of ephemeral data, like cookies (or server-side session data). It provides a way to automatically expire old data, and prevents attacks that become practical when large amounts of data are encrypted using a single key.

Invasion of the Invisible Salamanders! I mostly mention this just because I love the name, but there is a kind of attack possible in common AEAD modes called the invisible salamanders attack. StrongBox implements mitigations against this, by committing to the key being used so that an attacker can t forge a ciphertext that decrypts validly to different plaintexts when using different keys. This is why I love cryptography: everything sounds like absolute goddamn magic.

Call Me Crazy, Support Me Maybe? If you re coding in Rust (which you probably should be), encrypting your stored data (which you definitely should be), and StrongBox makes your life easier (which it really will), you can show your appreciation for my work by contributing to my open source code-fund. Simply by shouting me a refreshing beverage, you ll be helping me out, and helping to grow the software commons. Alternately, if you re looking for someone to Speak Rust to Computers on a professional basis, I m available for contracts or full-time remote positions.

21 August 2025

Matthew Palmer: Progress on my open source funding experiment

When I recently announced that I was starting an open source crowd-funding experiment, I wasn t sure what would happen. Perhaps there d be radio silence, or a huge out-pouring of interest from people who wanted to see more open source code in the world. What s happened so far has been interesting. I chose to focus on action-validator because it s got a number of open feature requests, and it solves a common problem that people have. The thing is, I ve developed and released a lot of open source over the multiple decades I ve been noodling around with computers. Much of that has been of use to many people, the overwhelming majority of whom I will never, ever meet, hear from, or even know that I ve helped them out. One person, however, I do know about a generous soul named Andy, who (as far as I know) doesn t use action-validator, but who does use another tool I wrote some years ago: lvmsync. It s somewhat niche, essentially rsync for LVM-backed block devices , so I m slightly surprised that it s my most-starred repository, at nearly 400(!) stars. Andy is one of the people who finds it useful, and he was kind enough to reach out and offer a contribution in thanks for lvmsync existing. In the spirit of my open source code-fund, I applied Andy s contribution to the general pool, and as a result have just released action-validator v0.8.0, which supports a new --rootdir command-line option, fixing action-validator issue #54. Everyone who uses --rootdir in their action-validator runs has Andy to thank, and I thank him too. This is, of course, still early days in my experiment. You can be like Andy, and make the open source world a better place, by contributing to my code-fund, and you can get your name up in lights, too. Whether you re an action-validator user, have gotten utility from any of the other things I ve written, or just want to see more open source code in the world, your contribution is greatly appreciated.

6 August 2025

Matthew Palmer: I'm trying an open source funding experiment

As I m currently somewhat underemployed, and could do with some extra income, I m starting an open source crowd-funding experiment. My hypothesis is that the open source community, and perhaps a community-minded company or two, really wants more open source code in the world, and is willing to put a few dollars my way to make that happen. To begin with, I m asking for contributions to implement a bunch of feature requests on action-validator, a Rust CLI tool I wrote to validate the syntax of GitHub actions and workflows. The premise is quite simple: for every AU$150 (about US$100) I receive in donations, I ll implement one of the nominated feature requests. If people want a particular feature implemented, they can nominate a feature in their donation message, otherwise when general donations get to AU$150, I ll just pick a feature that looks interesting. More details are on my code fund page. In the same spirit of simplicity, donations can be made through my Ko-fi page, and I ll keep track of the various totals in a hand-written HTML table. So, in short, if you want more open source code to exist, now would be a good time to visit my Ko-fi page and chip in a few dollars. If you re curious to know more, my code fund page has a list of Foreseeably Anticipated Questions that might address your curiosity. Otherwise, ask your questions in the comments or email me.

26 July 2025

Matthew Palmer: Object deserialization attacks using Ruby's Oj JSON parser

tl;dr: there is an attack in the wild which is triggering dangerous-but-seemingly-intended behaviour in the Oj JSON parser when used in the default and recommended manner, which can lead to everyone s favourite kind of security problem: object deserialization bugs! If you have the oj gem anywhere in your Gemfile.lock, the quickest mitigation is to make sure you have Oj.default_options = mode: :strict somewhere, and that no library is overwriting that setting to something else.

Prologue As a sensible sysadmin, all the sites I run send me a notification if any unhandled exception gets raised. Mostly, what I get sent is error-handling corner cases I missed, but now and then things get more interesting. In this case, it was a PG::UndefinedColumn exception, which looked something like this:
PG::UndefinedColumn: ERROR:  column "xyzzydeadbeef" does not exist
This is weird on two fronts: firstly, this application has been running for a while, and if there was a schema problem, I d expect it to have made itself apparent long before now. And secondly, while I don t profess to perfection in my programming, I m usually better at naming my database columns than that. Something is definitely hinky here, so let s jump into the mystery mobile!

The column name is coming from outside the building! The exception notifications I get sent include a whole lot of information about the request that caused the exception, including the request body. In this case, the request body was JSON, and looked like this:
 "name":":xyzzydeadbeef", ... 
The leading colon looks an awful lot like the syntax for a Ruby symbol, but it s in a JSON string. Surely there s no way a JSON parser would be turning that into a symbol, right? Right?!? Immediately, I thought that that possibly was what was happening, because I use Sequel for my SQL database access needs, and Sequel treats symbols as database column names. It seemed like too much of a coincidence that a vaguely symbol-shaped string was being sent in, and the exact same name was showing up as a column name. But how the flying fudgepickles was a JSON string being turned into a Ruby symbol, anyway? Enter Oj.

Oj? I barely know aj A long, long time ago, the standard Ruby JSON library had a reputation for being slow. Thus did many competitors flourish, claiming more features and better performance. Strong amongst the contenders was oj (for Optimized JSON ), touted as The fastest JSON parser and object serializer . Given the history, it s not surprising that people who wanted the best possible performance turned to Oj, leading to it being found in a great many projects, often as a sub-dependency of a dependency of a dependency (which is how it ended up in my project). You might have noticed in Oj s description that, in addition to claiming fastest , it also describes itself as an object serializer . Anyone who has kept an eye on the security bug landscape will recall that object deserialization is a rich vein of vulnerabilities to mine. Libraries that do object deserialization, especially ones with a history that goes back to before the vulnerability class was well-understood, are likely to be trouble magnets. And thus, it turns out to be with Oj. By default, Oj will happily turn any string that starts with a colon into a symbol:

>> require "oj"
>> Oj.load(' "name":":xyzzydeadbeef","username":"bob","answer":42 ')
=>  "name"=>:xyzzydeadbeef, "username"=>"bob", "answer"=>42 

How that gets exploited is only limited by the creativity of an attacker. Which I ll talk about more shortly but first, a word from my rant cortex.

Insecure By Default is a Cancer While the object of my ire today is Oj and its fast-and-loose approach to deserialization, it is just one example of a pervasive problem in software: insecurity by default. Whether it s a database listening on 0.0.0.0 with no password as soon as its installed, or a library whose default behaviour is to permit arbitrary code execution, it all contributes to a software ecosystem that is an appalling security nightmare. When a user (in this case, a developer who wants to parse JSON) comes across a new piece of software, they have by definition no idea what they re doing with that software. They re going to use the defaults, and follow the most easily-available documentation, to achieve their goal. It is unrealistic to assume that a new user of a piece of software is going to do things the right way , unless that right way is the only way, or at least the by-far-the-easiest way. Conversely, the developer(s) of the software is/are the domain experts. They have knowledge of the problem domain, through their exploration while building the software, and unrivalled expertise in the codebase. Given this disparity in knowledge, it is tantamount to malpractice for the experts the developer(s) to off-load the responsibility for the safe and secure use of the software to the party that has the least knowledge of how to do that (the new user). To apply this general principle to the specific case, take the Using section of the Oj README. The example code there calls Oj.load, with no indication that this code will, in fact, parse specially-crafted JSON documents into Ruby objects. The brand-user user of the library, no doubt being under pressure to Get Things Done, is almost certainly going to look at this Using example, get the apparent result they were after (a parsed JSON document), and call it a day. It is unlikely that a brand-new user will, for instance, scroll down to the Further Reading section, find the second last (of ten) listed documents, Security.md , and carefully peruse it. If they do, they ll find an oblique suggestion that parsing untrusted input is never a good idea . While that s true, it s also rather unhelpful, because I d wager that by far the majority of JSON parsed in the world is untrusted , in one way or another, given the predominance of JSON as a format for serializing data passing over the Internet. This guidance is roughly akin to putting a label on a car s airbags that driving at speed can be hazardous to your health : true, but unhelpful under the circumstances. The solution is for default behaviours to be secure, and any deviation from that default that has the potential to degrade security must, at the very least, be clearly labelled as such. For example, the Oj.load function should be named Oj.unsafe_load, and the Oj.load function should behave as the Oj.safe_load function does presently. By naming the unsafe function as explicitly unsafe, developers (and reviewers) have at least a fighting chance of recognising they re doing something risky. We put warning labels on just about everything in the real world; the same should be true of dangerous function calls. OK, rant over. Back to the story.

But how is this exploitable? So far, I ve hopefully made it clear that Oj does some Weird Stuff with parsing certain JSON strings. It caused an unhandled exception in a web application I run, which isn t cool, but apart from bombing me with exception notifications, what s the harm? For starters, let s look at our original example: when presented with a symbol, Sequel will interpret that as a column name, rather than a string value. Thus, if our save an update to the user code looked like this:

# request_body has the JSON representation of the form being submitted
body = Oj.load(request_body)
DB[:users].where(id: user_id).update(name: body["name"])

In normal operation, this will issue an SQL query along the lines of UPDATE users SET name='Jaime' WHERE id=42. If the name given is Jaime O Dowd , all is still good, because Sequel quotes string values, etc etc. All s well so far. But, imagine there is a column in the users table that normally users cannot read, perhaps admin_notes. Or perhaps an attacker has gotten temporary access to an account, and wants to dump the user s password hash for offline cracking. So, they send an update claiming that their name is :admin_notes (or :password_hash). In JSON, that ll look like "name":":admin_notes" , and Oj.load will happily turn that into a Ruby object of "name"=>:admin_notes . When run through the above update the user code fragment, it ll produce the SQL UPDATE users SET name=admin_notes WHERE id=42. In other words, it ll copy the contents of the admin_notes column into the name column which the attacker can then read out just by refreshing their profile page.

But Wait, There s More! That an attacker can read other fields in the same table isn t great, but that s barely scratching the surface. Remember before I said that Oj does object serialization ? That means that, in general, you can create arbitrary Ruby objects from JSON. Since objects contain code, it s entirely possible to trigger arbitrary code execution by instantiating an appropriate Ruby object. I m not going to go into details about how to do this, because it s not really my area of expertise, and many others have covered it in detail. But rest assured, if an attacker can feed input of their choosing into a default call to Oj.load, they ve been handed remote code execution on a platter.

Mitigations As Oj s object deserialization is intended and documented behaviour, don t expect a future release to make any of this any safer. Instead, we need to mitigate the risks. Here are my recommended steps:
  1. Look in your Gemfile.lock (or SBOM, if that s your thing) to see if the oj gem is anywhere in your codebase. Remember that even if you don t use it directly, it s popular enough that it is used in a lot of places. If you find it in your transitive dependency tree anywhere, there s a chance you re vulnerable, limited only by the ingenuity of attackers to feed crafted JSON into a deeply-hidden Oj.load call.
  2. If you depend on oj directly and use it in your project, consider not doing that. The json gem is acceptably fast, and JSON.parse won t create arbitrary Ruby objects.
  3. If you really, really need to squeeze the last erg of performance out of your JSON parsing, and decide to use oj to do so, find all calls to Oj.load in your code and switch them to call Oj.safe_load.
  4. It is a really, really bad idea to ever use Oj to deserialize JSON into objects, as it lacks the safety features needed to mitigate the worst of the risks of doing so (for example, restricting which classes can be instantiated, as is provided by the permitted_classes argument to Psych.load). I d make it a priority to move away from using Oj for that, and switch to something somewhat safer (such as the aforementioned Psych). At the very least, audit and comment heavily to minimise the risk of user-provided input sneaking into those calls somehow, and pass mode: :object as the second argument to Oj.load, to make it explicit that you are opting-in to this far more dangerous behaviour only when it s absolutely necessary.
  5. To secure any unsafe uses of Oj.load in your dependencies, consider setting the default Oj parsing mode to :strict, by putting Oj.default_options = mode: :strict somewhere in your initialization code (and make sure no dependencies are setting it to something else later!). There is a small chance that this change of default might break something, if a dependency is using Oj to deliberately create Ruby objects from JSON, but the overwhelming likelihood is that Oj s just being used to parse ordinary JSON, and these calls are just RCE vulnerabilities waiting to give you a bad time.

Is Your Bacon Saved? If I ve helped you identify and fix potential RCE vulnerabilities in your software, or even just opened your eyes to the risks of object deserialization, please help me out by buying me a refreshing beverage. I would really appreciate any support you can give. Alternately, if you d like my help in fixing these (and many other) sorts of problems, I m looking for work, so email me.

24 March 2025

Bits from Debian: New Debian Developers and Maintainers (January and February 2025)

The following contributors got their Debian Developer accounts in the last two months: The following contributors were added as Debian Maintainers in the last two months: Congratulations!
22 November 2024

Matthew Palmer: Your Release Process Sucks

For the past decade-plus, every piece of software I write has had one of two release processes. Software that gets deployed directly onto servers (websites, mostly, but also the infrastructure that runs Pwnedkeys, for example) is deployed with nothing more than git push prod main. I ll talk more about that some other day. Today is about the release process for everything else I maintain Rust / Ruby libraries, standalone programs, and so forth. To release those, I use the following, extremely intricate process:
  1. Create an annotated git tag, where the name of the tag is the software version I m releasing, and the annotation is the release notes for that version.
  2. Run git release in the repository.
  3. There is no step 3.
Yes, it absolutely is that simple. And if your release process is any more complicated than that, then you are suffering unnecessarily. But don t worry. I m from the Internet, and I m here to help.

Sidebar: annotated what-now?!? The annotated tag is one git s best-kept secrets. They ve been available in git for practically forever (I ve been using them since at least 2014, which is practically forever in software development), yet almost everyone I mention them to has never heard of them. A tag , in git parlance, is a repository-unique named label that points to a single commit (as identified by the commit s SHA1 hash). Annotating a tag is simply associating a block of free-form text with that tag. Creating an annotated tag is simple-sauce: git tag -a tagname will open up an editor window where you can enter your annotation, and git tag -a -m "some annotation" tagname will create the tag with the annotation some annotation . Retrieving the annotation for a tag is straightforward, too: git show tagname will display the annotation along with all the other tag-related information. Now that we know all about annotated tags, let s talk about how to use them to make software releases freaking awesome.

Step 1: Create the Annotated Git Tag As I just mentioned, creating an annotated git tag is pretty simple: just add a -a (or --annotate, if you enjoy typing) to your git tag command, and WHAM! annotation achieved. Releases, though, typically have unique and ever-increasing version numbers, which we want to encode in the tag name. Rather than having to look at the existing tags and figure out the next version number ourselves, we can have software do the hard work for us. Enter: git-version-bump. This straightforward program takes one mandatory argument: major, minor, or patch, and bumps the corresponding version number component in line with Semantic Versioning principles. If you pass it -n, it opens an editor for you to enter the release notes, and when you save out, the tag is automagically created with the appropriate name. Because the program is called git-version-bump, you can call it as a git command: git version-bump. Also, because version-bump is long and unwieldy, I have it aliased to vb, with the following entry in my ~/.gitconfig:
[alias]
    vb = version-bump -n
Of course, you don t have to use git-version-bump if you don t want to (although why wouldn t you?). The important thing is that the only step you take to go from here is our current codebase in main to everything as of this commit is version X.Y.Z of this software , is the creation of an annotated tag that records the version number being released, and the metadata that goes along with that release.

Step 2: Run git release As I said earlier, I ve been using this release process for over a decade now. So long, in fact, that when I started, GitHub Actions didn t exist, and so a lot of the things you d delegate to a CI runner these days had to be done locally, or in a more ad-hoc manner on a server somewhere. This is why step 2 in the release process is run git release . It s because historically, you can t do everything in a CI run. Nowadays, most of my repositories have this in the .git/config:
[alias]
    release = push --tags
Older repositories which, for one reason or another, haven t been updated to the new hawtness, have various other aliases defined, which run more specialised scripts (usually just rake release, for Ruby libraries), but they re slowly dying out. The reason why I still have this alias, though, is that it standardises the release process. Whether it s a Ruby gem, a Rust crate, a bunch of protobuf definitions, or whatever else, I run the same command to trigger a release going out. It means I don t have to think about how I do it for this project, because every project does it exactly the same way.

The Wiring Behind the Button
It wasn t the button that was the problem. It was the miles of wiring, the hundreds of miles of cables, the circuits, the relays, the machinery. The engine was a massive, sprawling, complex, mind-bending nightmare of levers and dials and buttons and switches. You couldn t just slap a button on the wall and expect it to work. But there should be a button. A big, fat button that you could press and everything would be fine again. Just press it, and everything would be back to normal.
  • Red Dwarf: Better Than Life
Once you ve accepted that your release process should be as simple as creating an annotated tag and running one command, you do need to consider what happens afterwards. These days, with the near-universal availability of CI runners that can do anything you need in an isolated, reproducible environment, the work required to go from annotated tag to release artifacts can be scripted up and left to do its thing. What that looks like, of course, will probably vary greatly depending on what you re releasing. I can t really give universally-applicable guidance, since I don t know your situation. All I can do is provide some of my open source work as inspirational examples. For starters, let s look at a simple Rust crate I ve written, called strong-box. It s a straightforward crate, that provides ergonomic and secure cryptographic functionality inspired by the likes of NaCl. As it s just a crate, its release script is very straightforward. Most of the complexity is working around Cargo s inelegant mandate that crate version numbers are specified in a TOML file. Apart from that, it s just a matter of building and uploading the crate. Easy! Slightly more complicated is action-validator. This is a Rust CLI tool which validates GitHub Actions and Workflows (how very meta) against a published JSON schema, to make sure you haven t got any syntax or structural errors. As not everyone has a Rust toolchain on their local box, the release process helpfully build binaries for several common OSes and CPU architectures that people can download if they choose. The release process in this case is somewhat larger, but not particularly complicated. Almost half of it is actually scaffolding to build an experimental WASM/NPM build of the code, because someone seemed rather keen on that. Moving away from Rust, and stepping up the meta another notch, we can take a look at the release process for git-version-bump itself, my Ruby library and associated CLI tool which started me down the Just Tag It Already rabbit hole many years ago. In this case, since gemspecs are very amenable to programmatic definition, the release process is practically trivial. Remove the boilerplate and workarounds for GitHub Actions bugs, and you re left with about three lines of actual commands. These approaches can certainly scale to larger, more complicated processes. I ve recently implemented annotated-tag-based releases in a proprietary software product, that produces Debian/Ubuntu, RedHat, and Windows packages, as well as Docker images, and it takes all of the information it needs from the annotated tag. I m confident that this approach will successfully serve them as they expand out to build AMIs, GCP machine images, and whatever else they need in their release processes in the future.

Objection, Your Honour! I can hear the howl of the but, actuallys coming over the horizon even as I type. People have a lot of Big Feelings about why this release process won t work for them. Rather than overload this article with them, I ve created a companion article that enumerates the objections I ve come across, and answers them. I m also available for consulting if you d like a personalised, professional opinion on your specific circumstances.

DVD Bonus Feature: Pre-releases Unless you re addicted to surprises, it s good to get early feedback about new features and bugfixes before they make it into an official, general-purpose release. For this, you can t go past the pre-release. The major blocker to widespread use of pre-releases is that cutting a release is usually a pain in the behind. If you ve got to edit changelogs, and modify version numbers in a dozen places, then you re entirely justified in thinking that cutting a pre-release for a customer to test that bugfix that only occurs in their environment is too much of a hassle. The thing is, once you ve got releases building from annotated tags, making pre-releases on every push to main becomes practically trivial. This is mostly due to another fantastic and underused Git command: git describe. How git describe works is, basically, that it finds the most recent commit that has an associated annotated tag, and then generates a string that contains that tag s name, plus the number of commits between that tag and the current commit, with the current commit s hash included, as a bonus. That is, imagine that three commits ago, you created an annotated release tag named v4.2.0. If you run git describe now, it will print out v4.2.0-3-g04f5a6f (assuming that the current commit s SHA starts with 04f5a6f). You might be starting to see where this is going. With a bit of light massaging (essentially, removing the leading v and replacing the -s with .s), that string can be converted into a version number which, in most sane environments, is considered newer than the official 4.2.0 release, but will be superceded by the next actual release (say, 4.2.1 or 4.3.0). If you re already injecting version numbers into the release build process, injecting a slightly different version number is no work at all. Then, you can easily build release artifacts for every commit to main, and make them available somewhere they won t get in the way of the official releases. For example, in the proprietary product I mentioned previously, this involves uploading the Debian packages to a separate component (prerelease instead of main), so that users that want to opt-in to the prerelease channel simply modify their sources.list to change main to prerelease. Management have been extremely pleased with the easy availability of pre-release packages; they ve been gleefully installing them willy-nilly for testing purposes since I rolled them out. In fact, even while I ve been writing this article, I was asked to add some debug logging to help track down a particularly pernicious bug. I added the few lines of code, committed, pushed, and went back to writing. A few minutes later (next week s job is to cut that in-process time by at least half), the person who asked for the extra logging ran apt update; apt upgrade, which installed the newly-built package, and was able to progress in their debugging adventure. Continuous Delivery: It s Not Just For Hipsters.

+1, Informative Hopefully, this has spurred you to commit your immortal soul to the Church of the Annotated Tag. You may tithe by buying me a refreshing beverage. Alternately, if you re really keen to adopt more streamlined release management processes, I m available for consulting engagements.

Matthew Palmer: Invalid Excuses for Why Your Release Process Sucks

In my companion article, I made the bold claim that your release process should consist of no more than two steps:
  1. Create an annotated Git tag;
  2. Run a single command to trigger the release pipeline.
As I have been on the Internet for more than five minutes, I m aware that a great many people will have a great many objections to this simple and straightforward idea. In the interests of saving them a lot of wear and tear on their keyboards, I present this list of common reasons why these objections are invalid. If you have an objection I don t cover here, the comment box is down the bottom of the article. If you think you ve got a real stumper, I m available for consulting engagements, and if you turn out to have a release process which cannot feasibly be reduced to the above two steps for legitimate technical reasons, I ll waive my fees.

But I automatically generate my release notes from commit messages! This one is really easy to solve: have the release note generation tool feed directly into the annotation. Boom! Headshot.

But all these files need to be edited to make a release! No, they absolutely don t. But I can see why you might think you do, given how inflexible some packaging environments can seem, and since that s how we ve always done it .

Language Packages Most languages require you to encode the version of the library or binary in a file that you want to revision control. This is teh suck, but I m yet to encounter a situation that can t be worked around some way or another. In Ruby, for instance, gemspec files are actually executable Ruby code, so I call code (that s part of git-version-bump, as an aside) to calculate the version number from the git tags. The Rust build tool, Cargo, uses a TOML file, which isn t as easy, but a small amount of release automation is used to take care of that.

Distribution Packages If you re building Linux distribution packages, you can easily apply similar automation faffery. For example, Debian packages take their metadata from the debian/changelog file in the build directory. Don t keep that file in revision control, though: build it at release time. Everything you need to construct a Debian (or RPM) changelog is in the tag version numbers, dates, times, authors, release notes. Use it for much good.

The Dreaded Changelog Finally, there s the CHANGELOG file. If it s maintained during the development process, it typically has an archive of all the release notes, under version numbers, with an Unreleased heading at the top. It s one more place to remember to have to edit when making that preparing release X.Y.Z commit, and it is a gift to the Demon of Spurious Merge Conflicts if you follow the policy of every commit must add a changelog entry . My solution: just burn it to the ground. Add a line to the top with a link to wherever the contents of annotated tags get published (such as GitHub Releases, if that s your bag) and never open it ever again.

But I need to know other things about my release, too! For some reason, you might think you need some other metadata about your releases. You re probably wrong it s amazing how much information you can obtain or derive from the humble tag so think creatively about your situation before you start making unnecessary complexity for yourself. But, on the off chance you re in a situation that legitimately needs some extra release-related information, here s the secret: structured annotation. The annotation on a tag can be literally any sequence of octets you like. How that data is interpreted is up to you. So, require that annotations on release tags use some sort of structured data format (say YAML or TOML or even XML if you hate your release manager), and mandate that it contain whatever information you need. You can make sure that the annotation has a valid structure and contains all the information you need with an update hook, which can reject the tag push if it doesn t meet the requirements, and you re sorted.

But I have multiple packages in my repo, with different release cadences and versions! This one is common enough that I just refer to it as the monorepo drama . Personally, I m not a huge fan of monorepos, but you do you, boo. Annotated tags can still handle it just fine. The trick is to include the package name being released in the tag name. So rather than a release tag being named vX.Y.Z, you use foo/vX.Y.Z, bar/vX.Y.Z, and baz/vX.Y.Z. The release automation for each package just triggers on tags that match the pattern for that particular package, and limits itself to those tags when figuring out what the version number is.

But we don t semver our releases! Oh, that s easy. The tag pattern that marks a release doesn t have to be vX.Y.Z. It can be anything you want. Relatedly, there is a (rare, but existent) need for packages that don t really have a conception of releases in the traditional sense. The example I ve hit most often is automatically generated bindings packages, such as protobuf definitions. The source of truth for these is a bunch of .proto files, but to be useful, they need to be packaged into code for the various language(s) you re using. But those packages need versions, and while someone could manually make releases, the best option is to build new per-language packages automatically every time any of those definitions change. The versions of those packages, then, can be datestamps (I like something like YYYY.MM.DD.N, where N starts at 0 each day and increments if there are multiple releases in a single day). This process allows all the code that needs the definitions to declare the minimum version of the definitions that it relies on, and everything is kept in sync and tracked almost like magic.

Th-th-th-th-that s all, folks! I hope you ve enjoyed this bit of mild debunking. Show your gratitude by buying me a refreshing beverage, or purchase my professional expertise and I ll answer all of your questions and write all your CI jobs.

31 July 2024

Matthew Palmer: Health Industry Company Sues to Prevent Certificate Revocation

It s not often that a company is willing to make a sworn statement to a court about how its IT practices are incompatible with the needs of the Internet, but when they do it s popcorn time.

The Combatants In the red corner, weighing in at nah, I m not going to do that schtick. The plaintiff in the case is Alegeus Technologies, LLC, a Delaware Corporation that, according to their filings, is a leading provider of a business-tobusiness, white-label funding and payment platform for healthcare carriers and third-party administrators to administer consumer-directed employee benefit programs . Not being subject to the US bonkers health care system, I have only a passing familiarity with the sorts of things they do, but presumably it involves moving a lot of money around, which is sometimes important. The defendant is DigiCert, a CA which, based on analysis I ve done previously, is the second-largest issuer of WebPKI certificates by volume.

The History According to a recently opened Mozilla CA bug, DigiCert found an issue in their domain control validation workflow, that meant it may have been possible for a miscreant to have certificates issued to them that they weren t legitimately entitled to. Given that validating domain names is basically the YOU HAD ONE JOB! of a CA, this is a big deal. The CA/Browser Forum Baseline Requirements (BRs) (which all CAs are required to adhere to, by virtue of their being included in various browser and OS trust stores), say that revocation is required within 24 hours when [t]he CA obtains evidence that the validation of domain authorization or control for any Fully Qualified Domain Name or IP address in the Certificate should not be relied upon (section 4.9.1.1, point 5). DigiCert appears to have at least tried to do the right thing, by opening the above Mozilla bug giving some details of the problem, and notifying their customers that their certificates were going to be revoked. One may quibble about how fast they re doing it, but they re giving it a decent shot, at least. A complicating factor in all this is that, only a touch over a month ago, Google Chrome announced the removal of another CA, Entrust, from its own trust store program, citing a pattern of compliance failures, unmet improvement commitments, and the absence of tangible, measurable progress in response to publicly disclosed incident reports . Many of these compliance failures were failures to revoke certificates in a timely manner. One imagines that DigiCert would not like to gain a reputation for tardy revocation, particularly at the moment.

The Legal Action Now we come to Alegeus Technologies. They ve opened a civil case whose first action is to request the issuance of a Temporary Restraining Order (TRO) that prevents DigiCert from revoking certificates issued to Alegeus (which the court has issued). This is a big deal, because TROs are legal instruments that, if not obeyed, constitute contempt of court (or something similar) and courts do not like people who disregard their instructions. That means that, in the short term, those certificates aren t getting revoked, despite the requirement imposed by root stores on DigiCert that the certificates must be revoked. DigiCert is in a real rock / hard place situation here: revoke and get punished by the courts, or don t revoke and potentially (though almost certainly not, in the circumstances) face removal from trust stores (which would kill, or at least massively hurt, their business). The reasons that Alegeus gives for requesting the restraining order is that [t]o Reissue and Reinstall the Security Certificates, Alegeus must work with and coordinate with its Clients, who are required to take steps to rectify the certificates. Alegeus has hundreds of such Clients. Alegeus is generally required by contract to give its clients much longer than 24 hours notice before executing such a change regarding certification. In the filing, Alegeus does acknowledge that DigiCert is a voluntary member of the Certification Authority Browser Forum (CABF), which has bylaws stating that certificates with an issue in their domain validation must be revoked within 24 hours. This is a misstatement of the facts, though. It is the BRs, not the CABF bylaws, that require revocation, and the BRs apply to all CAs that wish to be included in browser and OS trust stores, not just those that are members of the CABF. In any event, given that Alegeus was aware that DigiCert is required to revoke certificates within 24 hours, one wonders why Alegeus went ahead and signed agreements with their customers that required a lengthy notice period before changing certificates. What complicates the situation is that there is apparently a Master Services Agreement (MSA) that states that it constitutes the entire agreement between the parties and that MSA doesn t mention certificate revocation anywhere relevant. That means that it s not quite so cut-and-dried that DigiCert does, in fact, have the right to revoke those certificates. I d expect a lot of update to your Master Services Agreement emails to be going out from DigiCert (and other CAs) in the near future to clarify this point. Not being a lawyer, I can t imagine which way this case might go, but there s one thing we can be sure of: some lawyers are going to able to afford that trip to a tropical paradise this year.

The Security Issues The requirement for revocation within 24 hours is an important security control in the WebPKI ecosystem. If a certificate is misissued to a malicious party, or is otherwise compromised, it needs to be marked as untrustworthy as soon as possible. While revocation is far from perfect, it is the best tool we have. In this court filing, Alegeus has claimed that they are unable to switch certificates with less than 24 hours notice (due to contractual SLAs ). This is a pretty big problem, because there are lots of reasons why a certificate might need to be switched out Very Quickly. As a practical example, someone with access to the private key for your SSL certificate might decide to use it in a blog post. Letting that sort of problem linger for an extended period of time might end up being a Pretty Big Problem of its own. An organisation that cannot respond within hours to a compromised certificate is playing chicken with their security.

The Takeaways Contractual obligations that require you to notify anyone else of a certificate (or private key) changing are bonkers, and completely antithetical to the needs of the WebPKI. If you have to have them, you re going to want to start transitioning to a private PKI, wherein you can do whatever you darn well please with revocation (or not). As these sorts of problems keep happening, trust stores (and hence CAs) are going to crack down on this sort of thing, so you may as well move sooner rather than later. If you are an organisation that uses WebPKI certificates, you ve got to be able to deal with any kind of certificate revocation event within hours, not days. This basically boils down to automated issuance and lifecycle management, because having someone manually request and install certificates is terrible on many levels. There isn t currently a completed standard for notifying subscribers if their certificates need premature renewal (say, due to needing to be revoked), but the ACME Renewal Information Extension is currently being developed to fill that need. Ask your CA if they re tracking this standards development, and when they intend to have the extension available for use. (Pro-tip: if they say we ll start doing development when the RFC is published , run for the hills; that s not how responsible organisations work on the Internet).

The Givings If you ve found this helpful, consider shouting me a refreshing beverage. Reading through legal filings is thirsty work!

28 June 2024

Matthew Palmer: Checking for Compromised Private Keys has Never Been Easier

As regular readers would know, since I never stop banging on about it, I run Pwnedkeys, a service which finds and collates private keys which have been disclosed or are otherwise compromised. Until now, the only way to check if a key is compromised has been to use the Pwnedkeys API, which is not necessarily trivial for everyone. Starting today, that s changing. The next phase of Pwnedkeys is to start offering more user-friendly tools for checking whether keys being used are compromised. These will typically be web-based or command-line tools intended to answer the question is the key in this (certificate, CSR, authorized_keys file, TLS connection, email, etc) known to Pwnedkeys to have been compromised? .

Opening the Toolbox Available right now are the first web-based key checking tools in this arsenal. These tools allow you to:
  1. Check the key in a PEM-format X509 data structure (such as a CSR or certificate);
  2. Check the keys in an authorized_keys file you upload; and
  3. Check the SSH keys used by a user at any one of a number of widely-used code-hosting sites.
Further planned tools include live checking of the certificates presented in TLS connections (for HTTPS, etc), SSH host keys, command-line utilities for checking local authorized_keys files, and many other goodies.

If You Are Intrigued By My Ideas and wish to subscribe to my newsletter, now you can! I m not going to be blogging every little update to Pwnedkeys, because that would probably get a bit tedious for readers who aren t as intrigued by compromised keys as I am. Instead, I ll be posting every little update in the Pwnedkeys newsletter. So, if you want to keep up-to-date with the latest and greatest news and information, subscribe to the newsletter.

Supporting Pwnedkeys All this work I m doing on my own time, and I m paying for the infrastructure from my own pocket. If you ve got a few dollars to spare, I d really appreciate it if you bought me a refreshing beverage. It helps keep the lights on here at Pwnedkeys Global HQ.

14 June 2024

Matthew Palmer: Information Security: "We Can Do It, We Just Choose Not To"

Whenever a large corporation disgorges the personal information of millions of people onto the Internet, there is a standard playbook that is followed. Security is our top priority . Passwords were hashed . No credit card numbers were disclosed . record scratch Let s talk about that last one a bit.

A Case Study This post could have been written any time in the past well, decade or so, really. But the trigger for my sitting down and writing this post is the recent breach of wallet-finding and criminal-harassment-enablement platform Tile. As reported by Engadget, a statement attributed to Life360 CEO Chris Hulls says
The potentially impacted data consists of information such as names, addresses, email addresses, phone numbers, and Tile device identification numbers.
But don t worry though; even though your home address is now public information
It does not include more sensitive information, such as credit card numbers
Aaaaaand here is where I get salty.

Why Credit Card Numbers Don t Matter Describing credit card numbers as more sensitive information is somewhere between disingenuous and a flat-out lie. It was probably included in the statement because it s part of the standard playbook. Why is it part of the playbook, though? Not being a disaster comms specialist, I can t say for sure, but my hunch is that the post-breach playbook includes this line because (a) credit cards are less commonly breached these days (more on that later), and (b) it s a way to insinuate that all your financial data is safe, no need to worry without having to say that (because that statement would absolutely be a lie). The thing that not nearly enough people realise about credit card numbers is:
  1. The credit card holder is not usually liable for most fraud done via credit card numbers; and
  2. In terms of actual, long-term damage to individuals, credit card fraud barely rates a mention. Identity fraud, Business Email Compromise, extortion, and all manner of other unpleasantness is far more damaging to individuals.

Why Credit Card Numbers Do Matter Losing credit card numbers in a data breach is a huge deal but not for the users of the breached platform. Instead, it s a problem for the company that got breached. See, going back some years now, there was a wave of huge credit card data breaches. If you ve been around a while, names like Target and Heartland will bring back some memories. Because these breaches cost issuing banks and card brands a lot of money, the Payment Card Industry Security Standards Council (PCI-SSC) and the rest of the ecosystem went full goblin mode. Now, if you lose credit card numbers in bulk, it will cost you big. Massive fines for breaches (typically levied by the card brands via the acquiring bank), increased transaction fees, and even the Credit Card Death Penalty (being banned from charging credit cards), are all very big sticks.

Now Comes the Finding Out In news that should not be surprising, when there are actual consequences for failing to do something, companies take the problem seriously. Which is why no credit card numbers were disclosed is such an interesting statement. Consider why no credit card numbers were disclosed. It s not that credit card numbers aren t valuable to criminals because they are. Instead, it s because the company took steps to properly secure the credit card data. Next, you ll start to consider why, if the credit card numbers were secured, why wasn t the personal information that did get disclosed similarly secured? Information that is far more damaging to the individuals to whom that information relates than credit card numbers. The only logical answer is that it wasn t deemed financially beneficial to the company to secure that data. The consequences of disclosure for that information isn t felt by the company which was breached. Instead, it s felt by the individuals who have to spend weeks of their life cleaning up from identity fraud committed against them. It s felt by the victim of intimate partner violence whose new address is found in a data dump, letting their ex find them again. Until there are real, actual consequences for the companies which hemorrhage our personal data (preferably ones that have percentage of global revenue at the end), data breaches will continue to happen. Not because they re inevitable because as credit card numbers show, data can be secured but because there s no incentive for companies to prevent our personal data from being handed over to whoever comes along.

Support my Salt My salty takes are powered by refreshing beverages. If you d like to see more of the same, buy me one.

30 May 2024

Matthew Palmer: GitHub's Missing Tab

Visit any GitHub project page, and the first thing you see is something that looks like this: screenshot of the GitHub repository page, showing the Code, Issues, and Pull Requests tabs Code , that s fairly innocuous, and it s what we came here for. The Issues and Pull Requests tabs, with their count of open issues, might give us some sense of how active the project is, or perhaps how maintained . Useful information for the casual visitor, undoubtedly. However, there s another user community that visits this page on the regular, and these same tabs mean something very different to them. I m talking about the maintainers (or, more commonly, maintainer, singular). When they see those tabs, all they see is work. The Code tab is irrelevant to them they already have the code, and know it possibly better than they know their significant other(s) (if any). Issues and Pull Requests are just things that have to be done. I know for myself, at least, that it is demoralising to look at a repository page and see nothing but work. I d be surprised if it didn t contribute in some small way to maintainers just noping the fudge out.
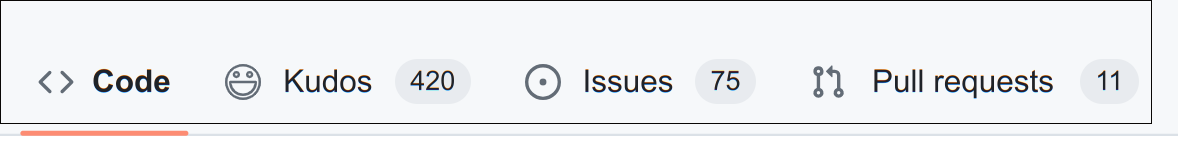
A Modest Proposal So, here s my thought. What if instead of the repo tabs looking like the above, they instead looked like this: modified screenshot of the GitHub repository page, showing a new Kudos tab, with a smiley face icon, between the Code and Issues tabs My conception of this is that it would, essentially, be a kind of yearbook , that people who used and liked the software could scribble their thoughts on. With some fairly straightforward affordances elsewhere to encourage its use, it could be a powerful way to show maintainers that they are, in fact, valued and appreciated. There are a number of software packages I ve used recently, that I d really like to say a general thanks, this is awesome! to. However, I m not about to make the Issues tab look even scarier by creating an issue to say thanks, and digging up an email address is often surprisingly difficult, and wouldn t be a public show of my gratitude, which I believe is a valuable part of the interaction.
You Can t Pay Your Rent With Kudos Absolutely you cannot. A means of expressing appreciation in no way replaces the pressing need to figure out a way to allow open source developers to pay their rent. Conversely, however, the need to pay open source developers doesn t remove the need to also show those people that their work is appreciated and valued by many people around the world. Anyway, who knows a senior exec at GitHub? I ve got an idea I d like to run past them

14 May 2024

Matthew Palmer: "Is This Project Still Maintained?"

If you wander around a lot of open source repositories on the likes of GitHub, you ll invariably stumble over repos that have an issue (or more than one!) with a title like the above. Sometimes sitting open and unloved, often with a comment or two from the maintainer and a bunch of I ll help out! followups that never seemed to pan out. Very rarely, you ll find one that has been closed, with a happy ending. These issues always fascinate me, because they say a lot about what it means to maintain an open source project, the nature of succession (particularly in a post-Jia Tan world), and the expectations of users and the impedence mismatch between maintainers, contributors, and users. I ve also recently been thinking about pre-empting this sort of issue, and opening my own issue that answers the question before it s even asked.

Why These Issues Are Created As both a producer and consumer of open source software, I completely understand the reasons someone might want to know whether a project is abandoned. It s comforting to be able to believe that there s someone on the other end of the line , and that if you have a problem, you can ask for help with a non-zero chance of someone answering you. There s also a better chance that, if the maintainer is still interested in the software, that compatibility issues and at least show-stopper bugs might get fixed for you. But often there s more at play. There is a delusion that maintained open source software comes with entitlements an expectation that your questions, bug reports, and feature requests will be attended to in some fashion. This comes about, I think, in part because there are a lot of open source projects that are energetically supported, where generous volunteers do answer questions, fix reported bugs, and implement things that they don t personally need, but which random Internet strangers ask for. If you ve had that kind of user experience, it s not surprising that you might start to expect it from all open source projects. Of course, these wonders of cooperative collaboration are the exception, rather than the rule. In many (most?) cases, there is little practical difference between most projects that are maintained and those that are formally declared unmaintained . The contributors (or, most often, contributor singular) are unlikely to have the time or inclination to respond to your questions in a timely and effective manner. If you find a problem with the software, you re going to be paddling your own canoe, even if the maintainer swears that they re still maintaining it.

A Thought Appears With this in mind, I ve been considering how to get ahead of the problem and answer the question for the software projects I ve put out in the world. Nothing I ve built has anything like what you d call a community ; most have never seen an external PR, or even an issue. The last commit date on them might be years ago. By most measures, almost all of my repos look unmaintained . Yet, they don t feel unmaintained to me. I m still using the code, sometimes as often as every day, and if something broke for me, I d fix it. Anyone who needs the functionality I ve developed can use the code, and be pretty confident that it ll do what it says in the README. I m considering creating an issue in all my repos, titled Is This Project Still Maintained? , pinning it to the issues list, and pasting in something I m starting to think of as The Open Source Maintainer s Manifesto . It goes something like this:

Is This Project Still Maintained? Yes. Maybe. Actually, perhaps no. Well, really, it depends on what you mean by maintained . I wrote the software in this repo for my own benefit to solve the problems I had, when I had them. While I could have kept the software to myself, I instead released it publicly, under the terms of an open licence, with the hope that it might be useful to others, but with no guarantees of any kind. Thanks to the generosity of others, it costs me literally nothing for you to use, modify, and redistribute this project, so have at it!

OK, Whatever. What About Maintenance? In one sense, this software is maintained , and always will be. I fix the bugs that annoy me, I upgrade dependencies when not doing so causes me problems, and I add features that I need. To the degree that any on-going development is happening, it s because I want that development to happen. However, if maintained to you means responses to questions, bug fixes, upgrades, or new features, you may be somewhat disappointed. That s not maintenance , that s support , and if you expect support, you ll probably want to have a support contract , where we come to an agreement where you pay me money, and I help you with the things you need help with.

That Doesn t Sound Fair! If it makes you feel better, there are several things you are entitled to:
  1. The ability to use, study, modify, and redistribute the contents of this repository, under the terms stated in the applicable licence(s).
  2. That any interactions you may have with myself, other contributors, and anyone else in this project s spaces will be in line with the published Code of Conduct, and any transgressions of the Code of Conduct will be dealt with appropriately.
  3. actually, that s it.
Things that you are not entitled to include an answer to your question, a fix for your bug, an implementation of your feature request, or a merge (or even review) of your pull request. Sometimes I may respond, either immediately or at some time long afterwards. You may luck out, and I ll think hmm, yeah, that s an interesting thing and I ll work on it, but if I do that in any particular instance, it does not create an entitlement that I will continue to do so, or that I will ever do so again in the future.

But I ve Found a Huge and Terrible Bug! You have my full and complete sympathy. It s reasonable to assume that I haven t come across the same bug, or at least that it doesn t bother me, otherwise I d have fixed it for myself. Feel free to report it, if only to warn other people that there is a huge bug they might need to avoid (possibly by not using the software at all). Well-written bug reports are great contributions, and I appreciate the effort you ve put in, but the work that you ve done on your bug report still doesn t create any entitlement on me to fix it. If you really want that bug fixed, the source is available, and the licence gives you the right to modify it as you see fit. I encourage you to dig in and fix the bug. If you don t have the necessary skills to do so yourself, you can get someone else to fix it everyone has the same entitlements to use, study, modify, and redistribute as you do. You may also decide to pay me for a support contract, and get the bug fixed that way. That gets the bug fixed for everyone, and gives you the bonus warm fuzzies of contributing to the digital commons, which is always nice.

But My PR is a Gift! If you take the time and effort to make a PR, you re doing good work and I commend you for it. However, that doesn t mean I ll necessarily merge it into this repository, or even work with you to get it into a state suitable for merging. A PR is what is often called a gift of work . I ll have to make sure that, at the very least, it doesn t make anything actively worse. That includes introducing bugs, or causing maintenance headaches in the future (which includes my getting irrationally angry at indenting, because I m like that). Properly reviewing a PR takes me at least as much time as it would take me to write it from scratch, in almost all cases. So, if your PR languishes, it might not be that it s bad, or that the project is (dum dum dummmm!) unmaintained , but just that I don t accept this particular gift of work at this particular time. Don t forget that the terms of licence include permission to redistribute modified versions of the code I ve released. If you think your PR is all that and a bag of potato chips, fork away! I won t be offended if you decide to release a permanent fork of this software, as long as you comply with the terms of the licence(s) involved. (Note that I do not undertake support contracts solely to review and merge PRs; that reeks a little too much of pay to play for my liking)

Gee, You Sound Like an Asshole I prefer to think of myself as forthright and plain-speaking , but that brings to mind that third thing you re entitled to: your opinion. I ve written this out because I feel like clarifying the reality we re living in, in the hope that it prevents misunderstandings. If what I ve written makes you not want to use the software I ve written, that s fine you ve probably avoided future disappointment.

Opinions Sought What do you think? Too harsh? Too wishy-washy? Comment away!

1 May 2024

Matthew Palmer: The Mediocre Programmer's Guide to Rust

Me: Hi everyone, my name s Matt, and I m a mediocre programmer. Everyone: Hi, Matt. Facilitator: Are you an alcoholic, Matt? Me: No, not since I stopped reading Twitter. Facilitator: Then I think you re in the wrong room.
Yep, that s my little secret I m a mediocre programmer. The definition of the word hacker I most closely align with is someone who makes furniture with an axe . I write simple, straightforward code because trying to understand complexity makes my head hurt. Which is why I ve always avoided the more academic languages, like OCaml, Haskell, Clojure, and so on. I know they re good languages people far smarter than me are building amazing things with them but the time I hear the word endofunctor , I ve lost all focus (and most of my will to live). My preferred languages are the ones that come with less intellectual overhead, like C, PHP, Python, and Ruby. So it s interesting that I ve embraced Rust with significant vigour. It s by far the most complicated language that I feel at least vaguely comfortable with using in anger . Part of that is that I ve managed to assemble a set of principles that allow me to almost completely avoid arguing with Rust s dreaded borrow checker, lifetimes, and all the rest of the dark, scary corners of the language. It s also, I think, that Rust helps me to write better software, and I can feel it helping me (almost) all of the time. In the spirit of helping my fellow mediocre programmers to embrace Rust, I present the principles I ve assembled so far.

Neither a Borrower Nor a Lender Be If you know anything about Rust, you probably know about the dreaded borrow checker . It s the thing that makes sure you don t have two pieces of code trying to modify the same data at the same time, or using a value when it s no longer valid. While Rust s borrowing semantics allow excellent performance without compromising safety, for us mediocre programmers it gets very complicated, very quickly. So, the moment the compiler wants to start talking about explicit lifetimes , I shut it up by just using owned values instead. It s not that I never borrow anything; I have some situations that I know are borrow-safe for the mediocre programmer (I ll cover those later). But any time I m not sure how things will pan out, I ll go straight for an owned value. For example, if I need to store some text in a struct or enum, it s going straight into a String. I m not going to start thinking about lifetimes and &'a str; I ll leave that for smarter people. Similarly, if I need a list of things, it s a Vec<T> every time no &'b [T] in my structs, thank you very much.

Attack of the Clones Following on from the above, I ve come to not be afraid of .clone(). I scatter them around my code like seeds in a field. Life s too short to spend time trying to figure out who s borrowing what from whom, if I can just give everyone their own thing. There are warnings in the Rust book (and everywhere else) about how a clone can be expensive . While it s true that, yes, making clones of data structures consumes CPU cycles and memory, it very rarely matters. CPU cycles are (usually) plentiful and RAM (usually) relatively cheap. Mediocre programmer mental effort is expensive, and not to be spent on premature optimisation. Also, if you re coming from most any other modern language, Rust is already giving you so much more performance that you re probably ending up ahead of the game, even if you .clone() everything in sight. If, by some miracle, something I write gets so popular that the expense of all those spurious clones becomes a problem, it might make sense to pay someone much smarter than I to figure out how to make the program a zero-copy masterpiece of efficient code. Until then clone early and clone often, I say!

Derive Macros are Powerful Magicks If you start .clone()ing everywhere, pretty quickly you ll be hit with this error:

error[E0599]: no method named  clone  found for struct  Foo  in the current scope

This is because not everything can be cloned, and so if you want your thing to be cloned, you need to implement the method yourself. Well sort of. One of the things that I find absolutely outstanding about Rust is the derive macro . These allow you to put a little marker on a struct or enum, and the compiler will write a bunch of code for you! Clone is one of the available so-called derivable traits , so you add #[derive(Clone)] to your structs, and poof! you can .clone() to your heart s content. But there are other things that are commonly useful, and so I ve got a set of traits that basically all of my data structures derive:

#[derive(Clone, Debug, Default)]
struct Foo  
    // ...
 

Every time I write a struct or enum definition, that line #[derive(Clone, Debug, Default)] goes at the top. The Debug trait allows you to print a debug representation of the data structure, either with the dbg!() macro, or via the :? format in the format!() macro (and anywhere else that takes a format string). Being able to say what exactly is that? comes in handy so often, not having a Debug implementation is like programming with one arm tied behind your Aeron. Meanwhile, the Default trait lets you create an empty instance of your data structure, with all of the fields set to their own default values. This only works if all the fields themselves implement Default, but a lot of standard types do, so it s rare that you ll define a structure that can t have an auto-derived Default. Enums are easily handled too, you just mark one variant as the default:

#[derive(Clone, Debug, Default)]
enum Bar  
    Something(String),
    SomethingElse(i32),
    #[default]   // <== mischief managed
    Nothing,
 

Borrowing is OK, Sometimes While I previously said that I like and usually use owned values, there are a few situations where I know I can borrow without angering the borrow checker gods, and so I m comfortable doing it. The first is when I need to pass a value into a function that only needs to take a little look at the value to decide what to do. For example, if I want to know whether any values in a Vec<u32> are even, I could pass in a Vec, like this:

fn main()  
    let numbers = vec![0u32, 1, 2, 3, 4, 5];
    if has_evens(numbers)  
        println!("EVENS!");
     
 
fn has_evens(numbers: Vec<u32>) -> bool  
    numbers.iter().any( n  n % 2 == 0)
 

Howver, this gets ugly if I m going to use numbers later, like this:

fn main()  
    let numbers = vec![0u32, 1, 2, 3, 4, 5];
    if has_evens(numbers)  
        println!("EVENS!");
     
    // Compiler complains about "value borrowed here after move"
    println!("Sum:  ", numbers.iter().sum::<u32>());
 
fn has_evens(numbers: Vec<u32>) -> bool  
    numbers.iter().any( n  n % 2 == 0)
 

Helpfully, the compiler will suggest I use my old standby, .clone(), to fix this problem. But I know that the borrow checker won t have a problem with lending that Vec<u32> into has_evens() as a borrowed slice, &[u32], like this:

fn main()  
    let numbers = vec![0u32, 1, 2, 3, 4, 5];
    if has_evens(&numbers)  
        println!("EVENS!");
     
 
fn has_evens(numbers: &[u32]) -> bool  
    numbers.iter().any( n  n % 2 == 0)
 

The general rule I ve got is that if I can take advantage of lifetime elision (a fancy term meaning the compiler can figure it out ), I m probably OK. In less fancy terms, as long as the compiler doesn t tell me to put 'a anywhere, I m in the green. On the other hand, the moment the compiler starts using the words explicit lifetime , I nope the heck out of there and start cloning everything in sight. Another example of using lifetime elision is when I m returning the value of a field from a struct or enum. In that case, I can usually get away with returning a borrowed value, knowing that the caller will probably just be taking a peek at that value, and throwing it away before the struct itself goes out of scope. For example:

struct Foo  
    id: u32,
    desc: String,
 
impl Foo  
    fn description(&self) -> &str  
        &self.desc


Returning a reference from a function is practically always a mortal sin for mediocre programmers, but returning one from a struct method is often OK. In the rare case that the caller does want the reference I return to live for longer, they can always turn it into an owned value themselves, by calling .to_owned().

Avoid the String Tangle Rust has a couple of different types for representing strings String and &str being the ones you see most often. There are good reasons for this, however it complicates method signatures when you just want to take some sort of bunch of text , and don t care so much about the messy details. For example, let s say we have a function that wants to see if the length of the string is even. Using the logic that since we re just taking a peek at the value passed in, our function might take a string reference, &str, like this:

fn is_even_length(s: &str) -> bool  
    s.len() % 2 == 0
 

That seems to work fine, until someone wants to check a formatted string:

fn main()  
    // The compiler complains about "expected  &str , found  String "
    if is_even_length(format!("my string is  ", std::env::args().next().unwrap()))  
        println!("Even length string");


Since format! returns an owned string, String, rather than a string reference, &str, we ve got a problem. Of course, it s straightforward to turn the String from format!() into a &str (just prefix it with an &). But as mediocre programmers, we can t be expected to remember which sort of string all our functions take and add & wherever it s needed, and having to fix everything when the compiler complains is tedious. The converse can also happen: a method that wants an owned String, and we ve got a &str (say, because we re passing in a string literal, like "Hello, world!"). In this case, we need to use one of the plethora of available turn this into a String mechanisms (.to_string(), .to_owned(), String::from(), and probably a few others I ve forgotten), on the value before we pass it in, which gets ugly real fast. For these reasons, I never take a String or an &str as an argument. Instead, I use the Power of Traits to let callers pass in anything that is, or can be turned into, a string. Let us have some examples. First off, if I would normally use &str as the type, I instead use impl AsRef<str>:

fn is_even_length(s: impl AsRef<str>) -> bool  
    s.as_ref().len() % 2 == 0
 

Note that I had to throw in an extra as_ref() call in there, but now I can call this with either a String or a &str and get an answer. Now, if I want to be given a String (presumably because I plan on taking ownership of the value, say because I m creating a new instance of a struct with it), I use impl Into<String> as my type:

struct Foo  
    id: u32,
    desc: String,
 
impl Foo  
    fn new(id: u32, desc: impl Into<String>) -> Self  
        Self   id, desc: desc.into()  


We have to call .into() on our desc argument, which makes the struct building a bit uglier, but I d argue that s a small price to pay for being able to call both Foo::new(1, "this is a thing") and Foo::new(2, format!("This is a thing named name ")) without caring what sort of string is involved.

Always Have an Error Enum Rust s error handing mechanism (Results everywhere), along with the quality-of-life sugar surrounding it (like the short-circuit operator, ?), is a delightfully ergonomic approach to error handling. To make life easy for mediocre programmers, I recommend starting every project with an Error enum, that derives thiserror::Error, and using that in every method and function that returns a Result. How you structure your Error type from there is less cut-and-dried, but typically I ll create a separate enum variant for each type of error I want to have a different description. With thiserror, it s easy to then attach those descriptions:

#[derive(Clone, Debug, thiserror::Error)]
enum Error  
    #[error(" 0  caught fire")]
    Combustion(String),
    #[error(" 0  exploded")]
    Explosion(String),
 

I also implement functions to create each error variant, because that allows me to do the Into<String> trick, and can sometimes come in handy when creating errors from other places with .map_err() (more on that later). For example, the impl for the above Error would probably be:

impl Error  
    fn combustion(desc: impl Into<String>) -> Self  
        Self::Combustion(desc.into())
     
    fn explosion(desc: impl Into<String>) -> Self  
        Self::Explosion(desc.into())


It s a tedious bit of boilerplate, and you can use the thiserror-ext crate s thiserror_ext::Construct derive macro to do the hard work for you, if you like. It, too, knows all about the Into<String> trick.

Banish map_err (well, mostly) The newer mediocre programmer, who is just dipping their toe in the water of Rust, might write file handling code that looks like this:

fn read_u32_from_file(name: impl AsRef<str>) -> Result<u32, Error>  
    let mut f = File::open(name.as_ref())
        .map_err( e  Error::FileOpenError(name.as_ref().to_string(), e))?;
    let mut buf = vec![0u8; 30];
    f.read(&mut buf)
        .map_err( e  Error::ReadError(e))?;
    String::from_utf8(buf)
        .map_err( e  Error::EncodingError(e))?
        .parse::<u32>()
        .map_err( e  Error::ParseError(e))
 

This works great (or it probably does, I haven t actually tested it), but there are a lot of .map_err() calls in there. They take up over half the function, in fact. With the power of the From trait and the magic of the ? operator, we can make this a lot tidier. First off, assume we ve written boilerplate error creation functions (or used thiserror_ext::Construct to do it for us)). That allows us to simplify the file handling portion of the function a bit:

fn read_u32_from_file(name: impl AsRef<str>) -> Result<u32, Error>  
    let mut f = File::open(name.as_ref())
        // We've dropped the  .to_string()  out of here...
        .map_err( e  Error::file_open_error(name.as_ref(), e))?;
    let mut buf = vec![0u8; 30];
    f.read(&mut buf)
        // ... and the explicit parameter passing out of here
        .map_err(Error::read_error)?;
    // ...

If that latter .map_err() call looks weird, without the e and such, it s passing a function-as-closure, which just saves on a few characters typing. Just because we re mediocre, doesn t mean we re not also lazy. Next, if we implement the From trait for the other two errors, we can make the string-handling lines significantly cleaner. First, the trait impl:

impl From<std::string::FromUtf8Error> for Error  
    fn from(e: std::string::FromUtf8Error) -> Self  
        Self::EncodingError(e)
     
 
impl From<std::num::ParseIntError> for Error  
    fn from(e: std::num::ParseIntError) -> Self  
        Self::ParseError(e)


(Again, this is boilerplate that can be autogenerated, this time by adding a #[from] tag to the variants you want a From impl on, and thiserror will take care of it for you) In any event, no matter how you get the From impls, once you have them, the string-handling code becomes practically error-handling-free:

    Ok(
        String::from_utf8(buf)?
            .parse::<u32>()?
    )

The ? operator will automatically convert the error from the types returned from each method into the return error type, using From. The only tiny downside to this is that the ? at the end strips the Result, and so we ve got to wrap the returned value in Ok() to turn it back into a Result for returning. But I think that s a small price to pay for the removal of those .map_err() calls. In many cases, my coding process involves just putting a ? after every call that returns a Result, and adding a new Error variant whenever the compiler complains about not being able to convert some new error type. It s practically zero effort outstanding outcome for the mediocre programmer.

Just Because You re Mediocre, Doesn t Mean You Can t Get Better To finish off, I d like to point out that mediocrity doesn t imply shoddy work, nor does it mean that you shouldn t keep learning and improving your craft. One book that I ve recently found extremely helpful is Effective Rust, by David Drysdale. The author has very kindly put it up to read online, but buying a (paper or ebook) copy would no doubt be appreciated. The thing about this book, for me, is that it is very readable, even by us mediocre programmers. The sections are written in a way that really clicked with me. Some aspects of Rust that I d had trouble understanding for a long time such as lifetimes and the borrow checker, and particularly lifetime elision actually made sense after I d read the appropriate sections.

Finally, a Quick Beg I m currently subsisting on the kindness of strangers, so if you found something useful (or entertaining) in this post, why not buy me a refreshing beverage? It helps to know that people like what I m doing, and helps keep me from having to sell my soul to a private equity firm.

9 April 2024

Matthew Palmer: How I Tripped Over the Debian Weak Keys Vulnerability

Those of you who haven t been in IT for far, far too long might not know that next month will be the 16th(!) anniversary of the disclosure of what was, at the time, a fairly earth-shattering revelation: that for about 18 months, the Debian OpenSSL package was generating entirely predictable private keys. The recent xz-stential threat (thanks to @nixCraft for making me aware of that one), has got me thinking about my own serendipitous interaction with a major vulnerability. Given that the statute of limitations has (probably) run out, I thought I d share it as a tale of how huh, that s weird can be a powerful threat-hunting tool but only if you ve got the time to keep pulling at the thread.

Prelude to an Adventure Our story begins back in March 2008. I was working at Engine Yard (EY), a now largely-forgotten Rails-focused hosting company, which pioneered several advances in Rails application deployment. Probably EY s greatest claim to lasting fame is that they helped launch a little code hosting platform you might have heard of, by providing them free infrastructure when they were little more than a glimmer in the Internet s eye. I am, of course, talking about everyone s favourite Microsoft product: GitHub. Since GitHub was in the right place, at the right time, with a compelling product offering, they quickly started to gain traction, and grow their userbase. With growth comes challenges, amongst them the one we re focusing on today: SSH login times. Then, as now, GitHub provided SSH access to the git repos they hosted, by SSHing to git@github.com with publickey authentication. They were using the standard way that everyone manages SSH keys: the ~/.ssh/authorized_keys file, and that became a problem as the number of keys started to grow. The way that SSH uses this file is that, when a user connects and asks for publickey authentication, SSH opens the ~/.ssh/authorized_keys file and scans all of the keys listed in it, looking for a key which matches the key that the user presented. This linear search is normally not a huge problem, because nobody in their right mind puts more than a few keys in their ~/.ssh/authorized_keys, right?
2008-era GitHub giving monkey puppet side-eye to the idea that nobody stores many keys in an authorized_keys file
Of course, as a popular, rapidly-growing service, GitHub was gaining users at a fair clip, to the point that the one big file that stored all the SSH keys was starting to visibly impact SSH login times. This problem was also not going to get any better by itself. Something Had To Be Done. EY management was keen on making sure GitHub ran well, and so despite it not really being a hosting problem, they were willing to help fix this problem. For some reason, the late, great, Ezra Zygmuntowitz pointed GitHub in my direction, and let me take the time to really get into the problem with the GitHub team. After examining a variety of different possible solutions, we came to the conclusion that the least-worst option was to patch OpenSSH to lookup keys in a MySQL database, indexed on the key fingerprint. We didn t take this decision on a whim it wasn t a case of yeah, sure, let s just hack around with OpenSSH, what could possibly go wrong? . We knew it was potentially catastrophic if things went sideways, so you can imagine how much worse the other options available were. Ensuring that this wouldn t compromise security was a lot of the effort that went into the change. In the end, though, we rolled it out in early April, and lo! SSH logins were fast, and we were pretty sure we wouldn t have to worry about this problem for a long time to come. Normally, you d think patching OpenSSH to make mass SSH logins super fast would be a good story on its own. But no, this is just the opening scene.

Chekov s Gun Makes its Appearance Fast forward a little under a month, to the first few days of May 2008. I get a message from one of the GitHub team, saying that somehow users were able to access other users repos over SSH. Naturally, as we d recently rolled out the OpenSSH patch, which touched this very thing, the code I d written was suspect number one, so I was called in to help.
The lineup scene from the movie The Usual Suspects They're called The Usual Suspects for a reason, but sometimes, it really is Keyser S ze
Eventually, after more than a little debugging, we discovered that, somehow, there were two users with keys that had the same key fingerprint. This absolutely shouldn t happen it s a bit like winning the lottery twice in a row1 unless the users had somehow shared their keys with each other, of course. Still, it was worth investigating, just in case it was a web application bug, so the GitHub team reached out to the users impacted, to try and figure out what was going on. The users professed no knowledge of each other, neither admitted to publicising their key, and couldn t offer any explanation as to how the other person could possibly have gotten their key. Then things went from weird to what the ? . Because another pair of users showed up, sharing a key fingerprint but it was a different shared key fingerprint. The odds now have gone from winning the lottery multiple times in a row to as close to this literally cannot happen as makes no difference.
Milhouse from The Simpsons says that We're Through The Looking Glass Here, People
Once we were really, really confident that the OpenSSH patch wasn t the cause of the problem, my involvement in the problem basically ended. I wasn t a GitHub employee, and EY had plenty of other customers who needed my help, so I wasn t able to stay deeply involved in the on-going investigation of The Mystery of the Duplicate Keys. However, the GitHub team did keep talking to the users involved, and managed to determine the only apparent common factor was that all the users claimed to be using Debian or Ubuntu systems, which was where their SSH keys would have been generated. That was as far as the investigation had really gotten, when along came May 13, 2008.

Chekov s Gun Goes Off With the publication of DSA-1571-1, everything suddenly became clear. Through a well-meaning but ultimately disasterous cleanup of OpenSSL s randomness generation code, the Debian maintainer had inadvertently reduced the number of possible keys that could be generated by a given user from bazillions to a little over 32,000. With so many people signing up to GitHub some of them no doubt following best practice and freshly generating a separate key it s unsurprising that some collisions occurred. You can imagine the sense of oooooooh, so that s what s going on! that rippled out once the issue was understood. I was mostly glad that we had conclusive evidence that my OpenSSH patch wasn t at fault, little knowing how much more contact I was to have with Debian weak keys in the future, running a huge store of known-compromised keys and using them to find misbehaving Certificate Authorities, amongst other things.

Lessons Learned While I ve not found a description of exactly when and how Luciano Bello discovered the vulnerability that became CVE-2008-0166, I presume he first came across it some time before it was disclosed likely before GitHub tripped over it. The stable Debian release that included the vulnerable code had been released a year earlier, so there was plenty of time for Luciano to have discovered key collisions and go hmm, I wonder what s going on here? , then keep digging until the solution presented itself. The thought hmm, that s odd , followed by intense investigation, leading to the discovery of a major flaw is also what ultimately brought down the recent XZ backdoor. The critical part of that sequence is the ability to do that intense investigation, though. When I reflect on my brush with the Debian weak keys vulnerability, what sticks out to me is the fact that I didn t do the deep investigation. I wonder if Luciano hadn t found it, how long it might have been before it was found. The GitHub team would have continued investigating, presumably, and perhaps they (or I) would have eventually dug deep enough to find it. But we were all super busy myself, working support tickets at EY, and GitHub feverishly building features and fighting the fires in their rapidly-growing service. As it was, Luciano was able to take the time to dig in and find out what was happening, but just like the XZ backdoor, I feel like we, as an industry, got a bit lucky that someone with the skills, time, and energy was on hand at the right time to make a huge difference. It s a luxury to be able to take the time to really dig into a problem, and it s a luxury that most of us rarely have. Perhaps an understated takeaway is that somehow we all need to wrestle back some time to follow our hunches and really dig into the things that make us go hmm .

Support My Hunches If you d like to help me be able to do intense investigations of mysterious software phenomena, you can shout me a refreshing beverage on ko-fi.
  1. the odds are actually probably more like winning the lottery about twenty times in a row. The numbers involved are staggeringly huge, so it s easiest to just approximate it as really, really unlikely .

13 February 2024

Matthew Palmer: Not all TLDs are Created Equal

In light of the recent cancellation of the queer.af domain registration by the Taliban, the fragile and difficult nature of country-code top-level domains (ccTLDs) has once again been comprehensively demonstrated. Since many people may not be aware of the risks, I thought I d give a solid explainer of the whole situation, and explain why you should, in general, not have anything to do with domains which are registered under ccTLDs.

Top-level What-Now? A top-level domain (TLD) is the last part of a domain name (the collection of words, separated by periods, after the https:// in your web browser s location bar). It s the com in example.com, or the af in queer.af. There are two kinds of TLDs: country-code TLDs (ccTLDs) and generic TLDs (gTLDs). Despite all being TLDs, they re very different beasts under the hood.

What s the Difference? Generic TLDs are what most organisations and individuals register their domains under: old-school technobabble like com , net , or org , historical oddities like gov , and the new-fangled world of words like tech , social , and bank . These gTLDs are all regulated under a set of rules created and administered by ICANN (the Internet Corporation for Assigned Names and Numbers ), which try to ensure that things aren t a complete wild-west, limiting things like price hikes (well, sometimes, anyway), and providing means for disputes over names1. Country-code TLDs, in contrast, are all two letters long2, and are given out to countries to do with as they please. While ICANN kinda-sorta has something to do with ccTLDs (in the sense that it makes them exist on the Internet), it has no authority to control how a ccTLD is managed. If a country decides to raise prices by 100x, or cancel all registrations that were made on the 12th of the month, there s nothing anyone can do about it. If that sounds bad, that s because it is. Also, it s not a theoretical problem the Taliban deciding to asssert its bigotry over the little corner of the Internet namespace it has taken control of is far from the first time that ccTLDs have caused grief.

Shifting Sands The queer.af cancellation is interesting because, at the time the domain was reportedly registered, 2018, Afghanistan had what one might describe as, at least, a different political climate. Since then, of course, things have changed, and the new bosses have decided to get a bit more active. Those running queer.af seem to have seen the writing on the wall, and were planning on moving to another, less fraught, domain, but hadn t completed that move when the Taliban came knocking.

The Curious Case of Brexit When the United Kingdom decided to leave the European Union, it fell foul of the EU s rules for the registration of domains under the eu ccTLD3. To register (and maintain) a domain name ending in .eu, you have to be a resident of the EU. When the UK ceased to be part of the EU, residents of the UK were no longer EU residents. Cue much unhappiness, wailing, and gnashing of teeth when this was pointed out to Britons. Some decided to give up their domains, and move to other parts of the Internet, while others managed to hold onto them by various legal sleight-of-hand (like having an EU company maintain the registration on their behalf). In any event, all very unpleasant for everyone involved.

Geopolitics on the Internet?!? After Russia invaded Ukraine in February 2022, the Ukranian Vice Prime Minister asked ICANN to suspend ccTLDs associated with Russia. While ICANN said that it wasn t going to do that, because it wouldn t do anything useful, some domain registrars (the companies you pay to register domain names) ceased to deal in Russian ccTLDs, and some websites restricted links to domains with Russian ccTLDs. Whether or not you agree with the sort of activism implied by these actions, the fact remains that even the actions of a government that aren t directly related to the Internet can have grave consequences for your domain name if it s registered under a ccTLD. I don t think any gTLD operator will be invading a neighbouring country any time soon.

Money, Money, Money, Must Be Funny When you register a domain name, you pay a registration fee to a registrar, who does administrative gubbins and causes you to be able to control the domain name in the DNS. However, you don t own that domain name4 you re only renting it. When the registration period comes to an end, you have to renew the domain name, or you ll cease to be able to control it. Given that a domain name is typically your brand or identity online, the chances are you d prefer to keep it over time, because moving to a new domain name is a massive pain, having to tell all your customers or users that now you re somewhere else, plus having to accept the risk of someone registering the domain name you used to have and capturing your traffic it s all a gigantic hassle. For gTLDs, ICANN has various rules around price increases and bait-and-switch pricing that tries to keep a lid on the worst excesses of registries. While there are any number of reasonable criticisms of the rules, and the Internet community has to stay on their toes to keep ICANN from totally succumbing to regulatory capture, at least in the gTLD space there s some degree of control over price gouging. On the other hand, ccTLDs have no effective controls over their pricing. For example, in 2008 the Seychelles increased the price of .sc domain names from US$25 to US$75. No reason, no warning, just pay up .

Who Is Even Getting That Money? A closely related concern about ccTLDs is that some of the cool ones are assigned to countries that are not great. The poster child for this is almost certainly Libya, which has the ccTLD ly . While Libya was being run by a terrorist-supporting extremist, companies thought it was a great idea to have domain names that ended in .ly. These domain registrations weren t (and aren t) cheap, and it s hard to imagine that at least some of that money wasn t going to benefit the Gaddafi regime. Similarly, the British Indian Ocean Territory, which has the io ccTLD, was created in a colonialist piece of chicanery that expelled thousands of native Chagossians from Diego Garcia. Money from the registration of .io domains doesn t go to the (former) residents of the Chagos islands, instead it gets paid to the UK government. Again, I m not trying to suggest that all gTLD operators are wonderful people, but it s not particularly likely that the direct beneficiaries of the operation of a gTLD stole an island chain and evicted the residents.

Are ccTLDs Ever Useful? The answer to that question is an unqualified maybe . I certainly don t think it s a good idea to register a domain under a ccTLD for vanity purposes: because it makes a word, is the same as a file extension you like, or because it looks cool. Those ccTLDs that clearly represent and are associated with a particular country are more likely to be OK, because there is less impetus for the registry to try a naked cash grab. Unfortunately, ccTLD registries have a disconcerting habit of changing their minds on whether they serve their geographic locality, such as when auDA decided to declare an open season in the .au namespace some years ago. Essentially, while a ccTLD may have geographic connotations now, there s not a lot of guarantee that they won t fall victim to scope creep in the future. Finally, it might be somewhat safer to register under a ccTLD if you live in the location involved. At least then you might have a better idea of whether your domain is likely to get pulled out from underneath you. Unfortunately, as the .eu example shows, living somewhere today is no guarantee you ll still be living there tomorrow, even if you don t move house. In short, I d suggest sticking to gTLDs. They re at least lower risk than ccTLDs.

+1, Helpful If you ve found this post informative, why not buy me a refreshing beverage? My typing fingers (both of them) thank you in advance for your generosity.

Footnotes
  1. don t make the mistake of thinking that I approve of ICANN or how it operates; it s an omnishambles of poor governance and incomprehensible decision-making.
  2. corresponding roughly, though not precisely (because everything has to be complicated, because humans are complicated), to the entries in the ISO standard for Codes for the representation of names of countries and their subdivisions , ISO 3166.
  3. yes, the EU is not a country; it s part of the roughly, though not precisely caveat mentioned previously.
  4. despite what domain registrars try very hard to imply, without falling foul of deceptive advertising regulations.

30 January 2024

Matthew Palmer: Why Certificate Lifecycle Automation Matters

If you ve perused the ActivityPub feed of certificates whose keys are known to be compromised, and clicked on the Show More button to see the name of the certificate issuer, you may have noticed that some issuers seem to come up again and again. This might make sense after all, if a CA is issuing a large volume of certificates, they ll be seen more often in a list of compromised certificates. In an attempt to see if there is anything that we can learn from this data, though, I did a bit of digging, and came up with some illuminating results.

The Procedure I started off by finding all the unexpired certificates logged in Certificate Transparency (CT) logs that have a key that is in the pwnedkeys database as having been publicly disclosed. From this list of certificates, I removed duplicates by matching up issuer/serial number tuples, and then reduced the set by counting the number of unique certificates by their issuer. This gave me a list of the issuers of these certificates, which looks a bit like this:
/C=BE/O=GlobalSign nv-sa/CN=AlphaSSL CA - SHA256 - G4
/C=GB/ST=Greater Manchester/L=Salford/O=Sectigo Limited/CN=Sectigo RSA Domain Validation Secure Server CA
/C=GB/ST=Greater Manchester/L=Salford/O=Sectigo Limited/CN=Sectigo RSA Organization Validation Secure Server CA
/C=US/ST=Arizona/L=Scottsdale/O=GoDaddy.com, Inc./OU=http://certs.godaddy.com/repository//CN=Go Daddy Secure Certificate Authority - G2
/C=US/ST=Arizona/L=Scottsdale/O=Starfield Technologies, Inc./OU=http://certs.starfieldtech.com/repository//CN=Starfield Secure Certificate Authority - G2
/C=AT/O=ZeroSSL/CN=ZeroSSL RSA Domain Secure Site CA
/C=BE/O=GlobalSign nv-sa/CN=GlobalSign GCC R3 DV TLS CA 2020
Rather than try to work with raw issuers (because, as Andrew Ayer says, The SSL Certificate Issuer Field is a Lie), I mapped these issuers to the organisations that manage them, and summed the counts for those grouped issuers together.

The Data
Lieutenant Commander Data from Star Trek: The Next Generation Insert obligatory "not THAT data" comment here
The end result of this work is the following table, sorted by the count of certificates which have been compromised by exposing their private key:
IssuerCompromised Count
Sectigo170
ISRG (Let's Encrypt)161
GoDaddy141
DigiCert81
GlobalSign46
Entrust3
SSL.com1
If you re familiar with the CA ecosystem, you ll probably recognise that the organisations with large numbers of compromised certificates are also those who issue a lot of certificates. So far, nothing particularly surprising, then. Let s look more closely at the relationships, though, to see if we can get more useful insights.

Volume Control Using the issuance volume report from crt.sh, we can compare issuance volumes to compromise counts, to come up with a compromise rate . I m using the Unexpired Precertificates colume from the issuance volume report, as I feel that s the number that best matches the certificate population I m examining to find compromised certificates. To maintain parity with the previous table, this one is still sorted by the count of certificates that have been compromised.
IssuerIssuance VolumeCompromised CountCompromise Rate
Sectigo88,323,0681701 in 519,547
ISRG (Let's Encrypt)315,476,4021611 in 1,959,480
GoDaddy56,121,4291411 in 398,024
DigiCert144,713,475811 in 1,786,586
GlobalSign1,438,485461 in 31,271
Entrust23,16631 in 7,722
SSL.com171,81611 in 171,816
If we now sort this table by compromise rate, we can see which organisations have the most (and least) leakiness going on from their customers:
IssuerIssuance VolumeCompromised CountCompromise Rate
Entrust23,16631 in 7,722
GlobalSign1,438,485461 in 31,271
SSL.com171,81611 in 171,816
GoDaddy56,121,4291411 in 398,024
Sectigo88,323,0681701 in 519,547
DigiCert144,713,475811 in 1,786,586
ISRG (Let's Encrypt)315,476,4021611 in 1,959,480
By grouping by order-of-magnitude in the compromise rate, we can identify three bands :
  • The Super Leakers: Customers of Entrust and GlobalSign seem to love to lose control of their private keys. For Entrust, at least, though, the small volumes involved make the numbers somewhat untrustworthy. The three compromised certificates could very well belong to just one customer, for instance. I m not aware of anything that GlobalSign does that would make them such an outlier, either, so I m inclined to think they just got unlucky with one or two customers, but as CAs don t include customer IDs in the certificates they issue, it s not possible to say whether that s the actual cause or not.
  • The Regular Leakers: Customers of SSL.com, GoDaddy, and Sectigo all have compromise rates in the 1-in-hundreds-of-thousands range. Again, the low volumes of SSL.com make the numbers somewhat unreliable, but the other two organisations in this group have large enough numbers that we can rely on that data fairly well, I think.
  • The Low Leakers: Customers of DigiCert and Let s Encrypt are at least three times less likely than customers of the regular leakers to lose control of their private keys. Good for them!
Now we have some useful insights we can think about.

Why Is It So?
Professor Julius Sumner Miller If you don't know who Professor Julius Sumner Miller is, I highly recommend finding out
All of the organisations on the list, with the exception of Let s Encrypt, are what one might term traditional CAs. To a first approximation, it s reasonable to assume that the vast majority of the customers of these traditional CAs probably manage their certificates the same way they have for the past two decades or more. That is, they generate a key and CSR, upload the CSR to the CA to get a certificate, then copy the cert and key somewhere. Since humans are handling the keys, there s a higher risk of the humans using either risky practices, or making a mistake, and exposing the private key to the world. Let s Encrypt, on the other hand, issues all of its certificates using the ACME (Automatic Certificate Management Environment) protocol, and all of the Let s Encrypt documentation encourages the use of software tools to generate keys, issue certificates, and install them for use. Given that Let s Encrypt has 161 compromised certificates currently in the wild, it s clear that the automation in use is far from perfect, but the significantly lower compromise rate suggests to me that lifecycle automation at least reduces the rate of key compromise, even though it doesn t eliminate it completely.

Explaining the Outlier The difference in presumed issuance practices would seem to explain the significant difference in compromise rates between Let s Encrypt and the other organisations, if it weren t for one outlier. This is a largely traditional CA, with the manual-handling issues that implies, but with a compromise rate close to that of Let s Encrypt. We are, of course, talking about DigiCert. The thing about DigiCert, that doesn t show up in the raw numbers from crt.sh, is that DigiCert manages the issuance of certificates for several of the biggest hosted TLS providers, such as CloudFlare and AWS. When these services obtain a certificate from DigiCert on their customer s behalf, the private key is kept locked away, and no human can (we hope) get access to the private key. This is supported by the fact that no certificates identifiably issued to either CloudFlare or AWS appear in the set of certificates with compromised keys. When we ask for all certificates issued by DigiCert , we get both the certificates issued to these big providers, which are very good at keeping their keys under control, as well as the certificates issued to everyone else, whose key handling practices may not be quite so stringent. It s possible, though not trivial, to account for certificates issued to these hosted TLS providers, because the certificates they use are issued from intermediates branded to those companies. With the crt.sh psql interface we can run this query to get the total number of unexpired precertificates issued to these managed services:
SELECT SUM(sub.NUM_ISSUED[2] - sub.NUM_EXPIRED[2])
  FROM (
    SELECT ca.name, max(coalesce(coalesce(nullif(trim(cc.SUBORDINATE_CA_OWNER), ''), nullif(trim(cc.CA_OWNER), '')), cc.INCLUDED_CERTIFICATE_OWNER)) as OWNER,
           ca.NUM_ISSUED, ca.NUM_EXPIRED
      FROM ccadb_certificate cc, ca_certificate cac, ca
     WHERE cc.CERTIFICATE_ID = cac.CERTIFICATE_ID
       AND cac.CA_ID = ca.ID
  GROUP BY ca.ID
  ) sub
 WHERE sub.name ILIKE '%Amazon%' OR sub.name ILIKE '%CloudFlare%' AND sub.owner = 'DigiCert';
The number I get from running that query is 104,316,112, which should be subtracted from DigiCert s total issuance figures to get a more accurate view of what DigiCert s regular customers do with their private keys. When I do this, the compromise rates table, sorted by the compromise rate, looks like this:
IssuerIssuance VolumeCompromised CountCompromise Rate
Entrust23,16631 in 7,722
GlobalSign1,438,485461 in 31,271
SSL.com171,81611 in 171,816
GoDaddy56,121,4291411 in 398,024
"Regular" DigiCert40,397,363811 in 498,732
Sectigo88,323,0681701 in 519,547
All DigiCert144,713,475811 in 1,786,586
ISRG (Let's Encrypt)315,476,4021611 in 1,959,480
In short, it appears that DigiCert s regular customers are just as likely as GoDaddy or Sectigo customers to expose their private keys.

What Does It All Mean? The takeaway from all this is fairly straightforward, and not overly surprising, I believe.

The less humans have to do with certificate issuance, the less likely they are to compromise that certificate by exposing the private key. While it may not be surprising, it is nice to have some empirical evidence to back up the common wisdom. Fully-managed TLS providers, such as CloudFlare, AWS Certificate Manager, and whatever Azure s thing is called, is the platonic ideal of this principle: never give humans any opportunity to expose a private key. I m not saying you should use one of these providers, but the security approach they have adopted appears to be the optimal one, and should be emulated universally. The ACME protocol is the next best, in that there are a variety of standardised tools widely available that allow humans to take themselves out of the loop, but it s still possible for humans to handle (and mistakenly expose) key material if they try hard enough. Legacy issuance methods, which either cannot be automated, or require custom, per-provider automation to be developed, appear to be at least four times less helpful to the goal of avoiding compromise of the private key associated with a certificate.

Humans Are, Of Course, The Problem
Bender, the robot from Futurama, asking if we'd like to kill all humans No thanks, Bender, I'm busy tonight
This observation that if you don t let humans near keys, they don t get leaked is further supported by considering the biggest issuers by volume who have not issued any certificates whose keys have been compromised: Google Trust Services (fourth largest issuer overall, with 57,084,529 unexpired precertificates), and Microsoft Corporation (sixth largest issuer overall, with 22,852,468 unexpired precertificates). It appears that somewhere between most and basically all of the certificates these organisations issue are to customers of their public clouds, and my understanding is that the keys for these certificates are managed in same manner as CloudFlare and AWS the keys are locked away where humans can t get to them. It should, of course, go without saying that if a human can never have access to a private key, it makes it rather difficult for a human to expose it. More broadly, if you are building something that handles sensitive or secret data, the more you can do to keep humans out of the loop, the better everything will be.

Your Support is Appreciated If you d like to see more analysis of how key compromise happens, and the lessons we can learn from examining billions of certificates, please show your support by buying me a refreshing beverage. Trawling CT logs is thirsty work.

Appendix: Methodology Limitations In the interests of clarity, I feel it s important to describe ways in which my research might be flawed. Here are the things I know of that may have impacted the accuracy, that I couldn t feasibly account for.
  • Time Periods: Because time never stops, there is likely to be some slight mismatches in the numbers obtained from the various data sources, because they weren t collected at exactly the same moment.
  • Issuer-to-Organisation Mapping: It s possible that the way I mapped issuers to organisations doesn t match exactly with how crt.sh does it, meaning that counts might be skewed. I tried to minimise that by using the same data sources (the CCADB AllCertificates report) that I believe that crt.sh uses for its mapping, but I cannot be certain of a perfect match.
  • Unwarranted Grouping: I ve drawn some conclusions about the practices of the various organisations based on their general approach to certificate issuance. If a particular subordinate CA that I ve grouped into the parent organisation is managed in some unusual way, that might cause my conclusions to be erroneous. I was able to fairly easily separate out CloudFlare, AWS, and Azure, but there are almost certainly others that I didn t spot, because hoo boy there are a lot of intermediate CAs out there.

16 January 2024

Matthew Palmer: Pwned Certificates on the Fediverse

As well as the collection and distribution of compromised keys, the pwnedkeys project also matches those pwned keys against issued SSL certificates. I m excited to announce that, as of the beginning of 2024, all matched certificates are now being published on the Fediverse, thanks to the botsin.space Mastodon server. Want to know which sites are susceptible to interception and interference, in (near-)real time? Do you have a burning desire to know who is issuing certificates to people that post their private keys in public? Now you can.

How It Works The process for publishing pwned certs is, roughly, as follows:
  1. All the certificates in Certificate Transparency (CT) logs are hoovered up (using my scrape-ct-log tool, the fastest log scraper in the west!), and the fingerprint of the public key of each certificate is stored in an LMDB datafile.
  2. As new private keys are identified as having been compromised, the fingerprint of that key is checked against all the LMDB files, which map key fingerprints to certificates (actually to CT log entry IDs, from which the certificates themselves are retrieved).
  3. If one or more matches are found, then the certificates using the compromised key are forwarded to the tooter , which publishes them for the world to marvel at.
This makes it sound all very straightforward, and it is in theory. The trick comes in optimising the pipeline so that the five million or so new certificates every day can get indexed on the one slightly middle-aged server I ve got, without getting backlogged.

Why Don t You Just Have the Certificates Revoked? Funny story about that I used to notify CAs of certificates they d issued using compromised keys, which had the effect of requiring them to revoke the associated certificates. However, several CAs disliked having to revoke all those certificates, because it cost them staff time (and hence money) to do so. They went so far as to change their procedures from the standard way of accepting problem reports (emailing a generic attestation of compromise), and instead required CA-specific hoop-jumping to notify them of compromised keys. Since the effectiveness of revocation in the WebPKI is, shall we say, homeopathic at best, I decided I couldn t be bothered to play whack-a-mole with CAs that just wanted to be difficult, and I stopped sending compromised key notifications to CAs. Instead, now I m publishing the details of compromised certificates to everyone, so that users can protect themselves directly should they choose to.

Further Work The astute amongst you may have noticed, in the above How It Works description, a bit of a gap in my scanning coverage. CAs can (and do!) issue certificates for keys that are already compromised, including weak keys that have been known about for a decade or more (1, 2, 3). However, as currently implemented, the pwnedkeys certificate checker does not automatically find such certificates. My plan is to augment the CT scraping / cert processing pipeline to check all incoming certificates against the existing (2M+) set of pwned keys. Though, with over five million new certificates to check every day, it s not necessarily as simple as just hit the pwnedkeys API for every new cert . The poor old API server might not like that very much.

Support My Work If you d like to see this extra matching happen a bit quicker, I ve setup a ko-fi supporters page, where you can support my work on pwnedkeys and the other open source software and projects I work on by buying me a refreshing beverage. I would be very appreciative, and your support lets me know I should do more interesting things with the giant database of compromised keys I ve accumulated.

7 November 2023

Matthew Palmer: PostgreSQL Encryption: The Available Options

On an episode of Postgres FM, the hosts had a (very brief) discussion of data encryption in PostgreSQL. While Postgres FM is a podcast well worth a subscribe, the hosts aren t data security experts, and so as someone who builds a queryable database encryption system, I found the coverage to be somewhat lacking. I figured I d provide a more complete survey of the available options for PostgreSQL-related data encryption.

The Status Quo By default, when you install PostgreSQL, there is no data encryption at all. That means that anyone who gets access to any part of the system can read all the data they have access to. This is, of course, not peculiar to PostgreSQL: basically everything works much the same way. What s stopping an attacker from nicking off with all your data is the fact that they can t access the database at all. The things that are acting as protection are perimeter defences, like putting the physical equipment running the server in a secure datacenter, firewalls to prevent internet randos connecting to the database, and strong passwords. This is referred to as tortoise security it s tough on the outside, but soft on the inside. Once that outer shell is cracked, the delicious, delicious data is ripe for the picking, and there s absolutely nothing to stop a miscreant from going to town and making off with everything. It s a good idea to plan your defenses on the assumption you re going to get breached sooner or later. Having good defence-in-depth includes denying the attacker to your data even if they compromise the database. This is where encryption comes in.

Storage-Layer Defences: Disk / Volume Encryption To protect against the compromise of the storage that your database uses (physical disks, EBS volumes, and the like), it s common to employ encryption-at-rest, such as full-disk encryption, or volume encryption. These mechanisms protect against offline attacks, but provide no protection while the system is actually running. And therein lies the rub: your database is always running, so encryption at rest typically doesn t provide much value. If you re running physical systems, disk encryption is essential, but more to prevent accidental data loss, due to things like failing to wipe drives before disposing of them, rather than physical theft. In systems where volume encryption is only a tickbox away, it s also worth enabling, if only to prevent inane questions from your security auditors. Relying solely on storage-layer defences, though, is very unlikely to provide any appreciable value in preventing data loss.

Database-Layer Defences: Transparent Database Encryption If you ve used proprietary database systems in high-security environments, you might have come across Transparent Database Encryption (TDE). There are also a couple of proprietary extensions for PostgreSQL that provide this functionality. TDE is essentially encryption-at-rest implemented inside the database server. As such, it has much the same drawbacks as disk encryption: few real-world attacks are thwarted by it. There is a very small amount of additional protection, in that physical level backups (as produced by pg_basebackup) are protected, but the vast majority of attacks aren t stopped by TDE. Any attacker who can access the database while it s running can just ask for an SQL-level dump of the stored data, and they ll get the unencrypted data quick as you like.

Application-Layer Defences: Field Encryption If you want to take the database out of the threat landscape, you really need to encrypt sensitive data before it even gets near the database. This is the realm of field encryption, more commonly known as application-level encryption. This technique involves encrypting each field of data before it is sent to be stored in the database, and then decrypting it again after it s retrieved from the database. Anyone who gets the data from the database directly, whether via a backup or a direct connection, is out of luck: they can t decrypt the data, and therefore it s worthless. There are, of course, some limitations of this technique. For starters, every ORM and data mapper out there has rolled their own encryption format, meaning that there s basically zero interoperability. This isn t a problem if you build everything that accesses the database using a single framework, but if you ever feel the need to migrate, or use the database from multiple codebases, you re likely in for a rough time. The other big problem of traditional application-level encryption is that, when the database can t understand what data its storing, it can t run queries against that data. So if you want to encrypt, say, your users dates of birth, but you also need to be able to query on that field, you need to choose between one or the other: you can t have both at the same time. You may think to yourself, but this isn t any good, an attacker that breaks into my application can still steal all my data! . That is true, but security is never binary. The name of the game is reducing the attack surface, making it harder for an attacker to succeed. If you leave all the data unencrypted in the database, an attacker can steal all your data by breaking into the database or by breaking into the application. Encrypting the data reduces the attacker s options, and allows you to focus your resources on hardening the application against attack, safe in the knowledge that an attacker who gets into the database directly isn t going to get anything valuable.

Sidenote: The Curious Case of pg_crypto PostgreSQL ships a contrib module called pg_crypto, which provides encryption and decryption functions. This sounds ideal to use for encrypting data within our applications, as it s available no matter what we re using to write our application. It avoids the problem of framework-specific cryptography, because you call the same PostgreSQL functions no matter what language you re using, which produces the same output. However, I don t recommend ever using pg_crypto s data encryption functions, and I doubt you will find many other cryptographic engineers who will, either. First up, and most horrifyingly, it requires you to pass the long-term keys to the database server. If there s an attacker actively in the database server, they can capture the keys as they come in, which means all the data encrypted using that key is exposed. Sending the keys can also result in the keys ending up in query logs, both on the client and server, which is obviously a terrible result. Less scary, but still very concerning, is that pg_crypto s available cryptography is, to put it mildly, antiquated. We have a lot of newer, safer, and faster techniques for data encryption, that aren t available in pg_crypto. This means that if you do use it, you re leaving a lot on the table, and need to have skilled cryptographic engineers on hand to avoid the potential pitfalls. In short: friends don t let friends use pg_crypto.

The Future: Enquo All this brings us to the project I run: Enquo. It takes application-layer encryption to a new level, by providing a language- and framework-agnostic cryptosystem that also enables encrypted data to be efficiently queried by the database. So, you can encrypt your users dates of birth, in such a way that anyone with the appropriate keys can query the database to return, say, all users over the age of 18, but an attacker just sees unintelligible gibberish. This should greatly increase the amount of data that can be encrypted, and as the Enquo project expands its available data types and supported languages, the coverage of encrypted data will grow and grow. My eventual goal is to encrypt all data, all the time. If this appeals to you, visit enquo.org to use or contribute to the open source project, or EnquoDB.com for commercial support and hosted database options.

12 June 2023

Matthew Palmer: Private Key Redaction: Redux

[Note: the original version of this post named the author of the referenced blog post, and the tone of my writing could be construed to be mocking or otherwise belittling them. While that was not my intention, I recognise that was a possible interpretation, and I have revised this post to remove identifying information and try to neutralise the tone. On the other hand, I have kept the identifying details of the domain involved, as there are entirely legitimate security concerns that result from the issues discussed in this post.] I have spoken before about why it is tricky to redact private keys. Although that post demonstrated a real-world, presumably-used-in-the-wild private key, I ve been made aware of commentary along the lines of this representative sample:
I find it hard to believe that anyone would take their actual production key and redact it for documentation. Does the author have evidence of this in practice, or did they see example keys and assume they were redacted production keys?
Well, buckle up, because today s post is another real-world case study, with rather higher stakes than the previous example.

When Helping Hurts Today s case study begins with someone who attempted to do a very good thing: they wrote a blog post about using HashiCorp Vault to store certificates and their private keys. In his post, they included some test data, a certificate and a private key, which they redacted. Unfortunately, they did not redact these very well. Each base64 blob has had one line replaced with all xs. Based on the steps I explained previously, it is relatively straightforward to retrieve the entire, intact private key.

From Bad to OMFG Now, if this post author had, say, generated a fresh private key (after all, there s no shortage of possible keys), that would not be worthy of a blog post. As you may surmise, that is not what happened. After reconstructing the insufficiently-redacted private key, you end up with a key that has a SHA256 fingerprint (in hex) of: 72bef096997ec59a671d540d75bd1926363b2097eb9fe10220b2654b1f665b54 Searching for certificates which use that key fingerprint, we find one result: a certificate for hiltonhotels.jp (and a bunch of other, related, domains, as subjectAltNames). As of the time of writing, that certificate is not marked as revoked, and appears to be the same certificate that is currently presented to visitors of that site. This is, shall we say, not great. Anyone in possession of this private key which, I should emphasise, has presumably been public information since the post s publication date of February 2023 has the ability to completely transparently impersonate the sites listed in that certificate. That would provide an attacker with the ability to capture any data a user entered, such as personal information, passwords, or payment details, and also modify what the user s browser received, including injecting malware or other unpleasantness. In short, no good deed goes unpunished, and this attempt to educate the world at large about the benefits of secure key storage has instead published private key material. Remember, kids: friends don t let friends post redacted private keys to the Internet.

30 April 2023

Matthew Palmer: dev-dependencies and Rust's unused_crate_dependencies lint

I m in the process of getting super-strict about the code quality of cretrit, the comparison-revealing encryption library that underlies the queryable encryption of the Enquo project. While I m going to write a whole big thing about Rust linting in the future, I bumped across a rather gnarly problem that I thought was worth sharing separately. The problem, in short, is that the unused_crate_dependencies lint interacts badly with crates that are only needed for benchmarking, such as (in my case) criterion. Rust has a whole bucketload of lints that can help your codebase adhere to certain standards, by warning (or exploding) if the problem is detected. The unused_crate_dependencies lint, as the name suggests, gets snippy when there s a crate listed in your Cargo.toml that doesn t appear to be used anywhere. All well and good so far. However, while Rust has the ability to specify crates needed for running the testsuite (the [dev-dependencies] section of Cargo.toml) separately from crates needed for actually using this thing ([dependencies]), it doesn t have a way to specify crates needed for running the benchmarks . That is a problem when you re using something like criterion for benchmarking, because it doesn t get refered to at all in your project code it only gets used in the benchmarks. When building your codebase for running the test suite, the compiler sees that you ve specified criterion as one of your testsuite dependencies , but it never gets used in your testsuite. This causes the unused_crate_dependencies lint to lose its tiny mind, and make your build look ugly (or fail). Thankfully, the solution is very simple, once you know the trick (this could be the unofficial theme song of the entire Rust ecosystem). You need to refer to the criterion crate somewhere in the code that gets built during the testsuite. The lint tells you most of what you need to do (like most things Rust, it tries hard to be helpful), but since it s a development dependency, you need a little extra secret sauce. All you need to do is add these two lines to the bottom of your src/lib.rs (or src/main.rs for a binary crate):
#[cfg(test)]
use criterion as _;
For the less Rust-literate, this means when the build-time configuration flag test is set, import the criterion crate, but don t, like, allow it to actually be referred to . This is enough to make the lint believe that the dependency is being used, and making it only happen when the test build-time config flag is set avoids the ugliness of it trying to refer to the crate during regular builds (which would fail, because criterion is only a dev-dependency). Simple? Yes. Did it take me a lot of skull-sweat to figure out? You betcha. That s why I m writing it down even if everyone else already knows this, at least future Matt will find this post next time he trips over this problem.

Next.