Search Results: "jsa"

11 November 2024

Vincent Bernat: Customize Caddy's plugins with Nix

Caddy is an open-source web server written in Go. It handles TLS certificates automatically and comes with a simple configuration syntax. Users can extend its functionality through plugins1 to add features like rate limiting, caching, and Docker integration. While Caddy is available in Nixpkgs, adding extra plugins is not simple.2 The compilation process needs Internet access, which Nix denies during build to ensure reproducibility. When trying to build the following derivation using xcaddy, a tool for building Caddy with plugins, it fails with this error: dial tcp: lookup proxy.golang.org on [::1]:53: connection refused.
  pkgs  :
pkgs.stdenv.mkDerivation  
  name = "caddy-with-xcaddy";
  nativeBuildInputs = with pkgs; [ go xcaddy cacert ];
  unpackPhase = "true";
  buildPhase =
    ''
      xcaddy build --with github.com/caddy-dns/powerdns@v1.0.1
    '';
  installPhase = ''
    mkdir -p $out/bin
    cp caddy $out/bin
  '';
 
Fixed-output derivations are an exception to this rule and get network access during build. They need to specify their output hash. For example, the fetchurl function produces a fixed-output derivation:
  stdenv, fetchurl  :
stdenv.mkDerivation rec  
  pname = "hello";
  version = "2.12.1";
  src = fetchurl  
    url = "mirror://gnu/hello/hello-$ version .tar.gz";
    hash = "sha256-jZkUKv2SV28wsM18tCqNxoCZmLxdYH2Idh9RLibH2yA=";
   ;
 
To create a fixed-output derivation, you need to set the outputHash attribute. The example below shows how to output Caddy s source code, with some plugin enabled, as a fixed-output derivation using xcaddy and go mod vendor.
pkgs.stdenvNoCC.mkDerivation rec  
  pname = "caddy-src-with-xcaddy";
  version = "2.8.4";
  nativeBuildInputs = with pkgs; [ go xcaddy cacert ];
  unpackPhase = "true";
  buildPhase =
    ''
      export GOCACHE=$TMPDIR/go-cache
      export GOPATH="$TMPDIR/go"
      XCADDY_SKIP_BUILD=1 TMPDIR="$PWD" \
        xcaddy build v$ version  --with github.com/caddy-dns/powerdns@v1.0.1
      (cd buildenv* && go mod vendor)
    '';
  installPhase = ''
    mv buildenv* $out
  '';
  outputHash = "sha256-F/jqR4iEsklJFycTjSaW8B/V3iTGqqGOzwYBUXxRKrc=";
  outputHashAlgo = "sha256";
  outputHashMode = "recursive";
 
With a fixed-output derivation, it is up to us to ensure the output is always the same: You can use this derivation to override the src attribute in pkgs.caddy:
pkgs.caddy.overrideAttrs (prev:  
  src = pkgs.stdenvNoCC.mkDerivation   /* ... */  ;
  vendorHash = null;
  subPackages = [ "." ];
 );
Check out the complete example in the GitHub repository. To integrate into a Flake, add github:vincentbernat/caddy-nix as an overlay:
 
  inputs =  
    nixpkgs.url = "nixpkgs";
    flake-utils.url = "github:numtide/flake-utils";
    caddy.url = "github:vincentbernat/caddy-nix";
   ;
  outputs =   self, nixpkgs, flake-utils, caddy  :
    flake-utils.lib.eachDefaultSystem (system:
      let
        pkgs = import nixpkgs  
          inherit system;
          overlays = [ caddy.overlays.default ];
         ;
      in
       
        packages =  
          default = pkgs.caddy.withPlugins  
            plugins = [ "github.com/caddy-dns/powerdns@v1.0.1" ];
            hash = "sha256-F/jqR4iEsklJFycTjSaW8B/V3iTGqqGOzwYBUXxRKrc=";
           ;
         ;
       );
 

Update (2024-11) This flake won t work with Nixpkgs 24.05 or older because it relies on this commit to properly override the vendorHash attribute.


  1. This article uses the term plugins, though Caddy documentation also refers to them as modules since they are implemented as Go modules.
  2. This is a feature request since quite some time. A proposed solution has been rejected. The one described in this article is a bit different and I have proposed it in another pull request.
  3. This is not perfect: if the source code produced by xcaddy changes, the hash would change and the build would fail.
10 November 2024

Reproducible Builds: Reproducible Builds in October 2024

Welcome to the October 2024 report from the Reproducible Builds project. Our reports attempt to outline what we ve been up to over the past month, highlighting news items from elsewhere in tech where they are related. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. Beyond bitwise equality for Reproducible Builds?
  2. Two Ways to Trustworthy at SeaGL 2024
  3. Number of cores affected Android compiler output
  4. On our mailing list
  5. diffoscope
  6. IzzyOnDroid passed 25% reproducible apps
  7. Distribution work
  8. Website updates
  9. Reproducibility testing framework
  10. Supply-chain security at Open Source Summit EU
  11. Upstream patches

Beyond bitwise equality for Reproducible Builds? Jens Dietrich, Tim White, of Victoria University of Wellington, New Zealand along with Behnaz Hassanshahi and Paddy Krishnan of Oracle Labs Australia published a paper entitled Levels of Binary Equivalence for the Comparison of Binaries from Alternative Builds :
The availability of multiple binaries built from the same sources creates new challenges and opportunities, and raises questions such as: Does build A confirm the integrity of build B? or Can build A reveal a compromised build B? . To answer such questions requires a notion of equivalence between binaries. We demonstrate that the obvious approach based on bitwise equality has significant shortcomings in practice, and that there is value in opting for alternative notions. We conceptualise this by introducing levels of equivalence, inspired by clone detection types.
A PDF of the paper is freely available.

Two Ways to Trustworthy at SeaGL 2024 On Friday 8th November, Vagrant Cascadian will present a talk entitled Two Ways to Trustworthy at SeaGL in Seattle, WA. Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture. Vagrant s talk:
[ ] delves into how two project[s] approaches fundamental security features through Reproducible Builds, Bootstrappable Builds, code auditability, etc. to improve trustworthiness, allowing independent verification; trustworthy projects require little to no trust. Exploring the challenges that each project faces due to very different technical architectures, but also contextually relevant social structure, adoption patterns, and organizational history should provide a good backdrop to understand how different approaches to security might evolve, with real-world merits and downsides.

Number of cores affected Android compiler output Fay Stegerman wrote that the cause of the Android toolchain bug from September s report that she reported to the Android issue tracker has been found and the bug has been fixed.
the D8 Java to DEX compiler (part of the Android toolchain) eliminated a redundant field load if running the class s static initialiser was known to be free of side effects, which ended up accidentally depending on the sharding of the input, which is dependent on the number of CPU cores used during the build.
To make it easier to understand the bug and the patch, Fay also made a small example to illustrate when and why the optimisation involved is valid.

On our mailing list On our mailing list this month:

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 279, 280, 281 and 282 to Debian:
  • Ignore errors when listing .ar archives (#1085257). [ ]
  • Don t try and test with systemd-ukify in the Debian stable distribution. [ ]
  • Drop Depends on the deprecated python3-pkg-resources (#1083362). [ ]
In addition, Jelle van der Waa added support for Unified Kernel Image (UKI) files. [ ][ ][ ] Furthermore, Vagrant Cascadian updated diffoscope in GNU Guix to version 282. [ ][ ]

IzzyOnDroid passed 25% reproducible apps The IzzyOnDroid project has reached a good milestone by reaching over 25% of the ~1,200 Android apps provided by their repository (of official APKs built by the original application developers) having been confirmed to be reproducible by a rebuilder.

Distribution work In Debian this month:
  • Holger Levsen uploaded devscripts version 2.24.2, including many changes to the debootsnap, debrebuild and reproducible-check scripts. This is the first time that debrebuild actually works (using sbuild s unshare backend). As part of this, Holger also fixed an issue in the reproducible-check script where a typo in the code led to incorrect results [ ]
  • Recently, a news entry was added to snapshot.debian.org s homepage, describing the recent changes that made the system stable again:
    The new server has no problems keeping up with importing the full archives on every update, as each run finishes comfortably in time before it s time to run again. [While] the new server is the one doing all the importing of updated archives, the HTTP interface is being served by both the new server and one of the VM s at LeaseWeb.
    The entry list a number of specific updates surrounding the API endpoints and rate limiting.
  • Lastly, 12 reviews of Debian packages were added, 3 were updated and 18 were removed this month adding to our knowledge about identified issues.
Elsewhere in distribution news, Zbigniew J drzejewski-Szmek performed another rebuild of Fedora 42 packages, with the headline result being that 91% of the packages are reproducible. Zbigniew also reported a reproducibility problem with QImage. Finally, in openSUSE, Bernhard M. Wiedemann published another report for that distribution.

Website updates There were an enormous number of improvements made to our website this month, including:
  • Alba Herrerias:
    • Improve consistency across distribution-specific guides. [ ]
    • Fix a number of links on the Contribute page. [ ]
  • Chris Lamb:
  • hulkoba
  • James Addison:
    • Huge and significant work on a (as-yet-merged) quickstart guide to be linked from the homepage [ ][ ][ ][ ][ ]
    • On the homepage, link directly to the Projects subpage. [ ]
    • Relocate dependency-drift notes to the Volatile inputs page. [ ]
  • Ninette Adhikari:
    • Add a brand new Success stories page that highlights the success stories of Reproducible Builds, showcasing real-world examples of projects shipping with verifiable, reproducible builds . [ ][ ][ ][ ][ ][ ]
  • Pol Dellaiera:
    • Update the website s README page for building the website under NixOS. [ ][ ][ ][ ][ ]
    • Add a new academic paper citation. [ ]
Lastly, Holger Levsen filed an extensive issue detailing a request to create an overview of recommendations and standards in relation to reproducible builds.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In October, a number of changes were made by Holger Levsen, including:
  • Add a basic index.html for rebuilderd. [ ]
  • Update the nginx.conf configuration file for rebuilderd. [ ]
  • Document how to use a rescue system for Infomaniak s OpenStack cloud. [ ]
  • Update usage info for two particular nodes. [ ]
  • Fix up a version skew check to fix the name of the riscv64 architecture. [ ]
  • Update the rebuilderd-related TODO. [ ]
In addition, Mattia Rizzolo added a new IP address for the inos5 node [ ] and Vagrant Cascadian brought 4 virt nodes back online [ ].

Supply-chain security at Open Source Summit EU The Open Source Summit EU took place recently, and covered plenty of topics related to supply-chain security, including:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

2 February 2023

Dirk Eddelbuettel: RInside 0.2.18 on CRAN: Maintenance

A new release 0.2.18 of RInside arrived on CRAN and in Debian today. This is the first release in ten months since the 0.2.17 release. RInside provides a set of convenience classes which facilitate embedding of R inside of C++ applications and programs, using the classes and functions provided by Rcpp. This release brings a contributed change to how the internal REPL is called: Dominick found the current form more reliable when embedding R on Windows. We also updated a few other things around the package. The list of changes since the last release:

Changes in RInside version 0.2.18 (2023-02-01)
  • The random number initialization was updated as in R.
  • The main REPL is now running via 'run_Rmainloop()'.
  • Small routine update to package and continuous integration.

My CRANberries also provides a short report with changes from the previous release. More information is on the RInside page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page, or to issues tickets at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

18 October 2020

Antoine Beaupr : CDPATH replacements

after reading this post I figured I might as well bite the bullet and improve on my CDPATH-related setup, especially because it does not work with Emacs. so i looked around for autojump-related alternatives that do.

What I use now I currently have this in my .shenv (sourced by .bashrc):
export CDPATH=".:~:~/src:~/dist:~/wikis:~/go/src:~/src/tor"
This allows me to quickly jump into projects from my home dir, or the "source code" (~/src), "work" (src/tor), or wiki checkouts (~/wikis) directories. It works well from the shell, but unfortunately it's very static: if I want a new directory, I need to edit my config file, restart shells, etc. It also doesn't work from my text editor.

Shell jumpers Those are commandline tools that can be used from a shell, generally with built-in shell integration so that a shell alias will find the right directory magically, usually by keeping track of the directories visited with cd. Some of those may or may not have integration in Emacs.

autojump

fasd

z

fzf

Emacs plugins not integrated with the shell Those projects can be used to track files inside a project or find files around directories, but do not offer the equivalent functionality in the shell.

projectile

elpy
  • home page
  • elpy has a notion of projects, so, by default, will find files in the current "project" with C-c C-f which is useful

bookmarks.el
  • built-in
  • home page
  • "Bookmarks record locations so you can return to them later"

recentf
  • built-in
  • home page
  • "builds a list of recently opened files. This list is is automatically saved across sessions on exiting Emacs - you can then access this list through a command or the menu"

references https://www.emacswiki.org/emacs/LocateFilesAnywhere

18 September 2020

Daniel Lange: Getting rid of the Google cookie consent popup

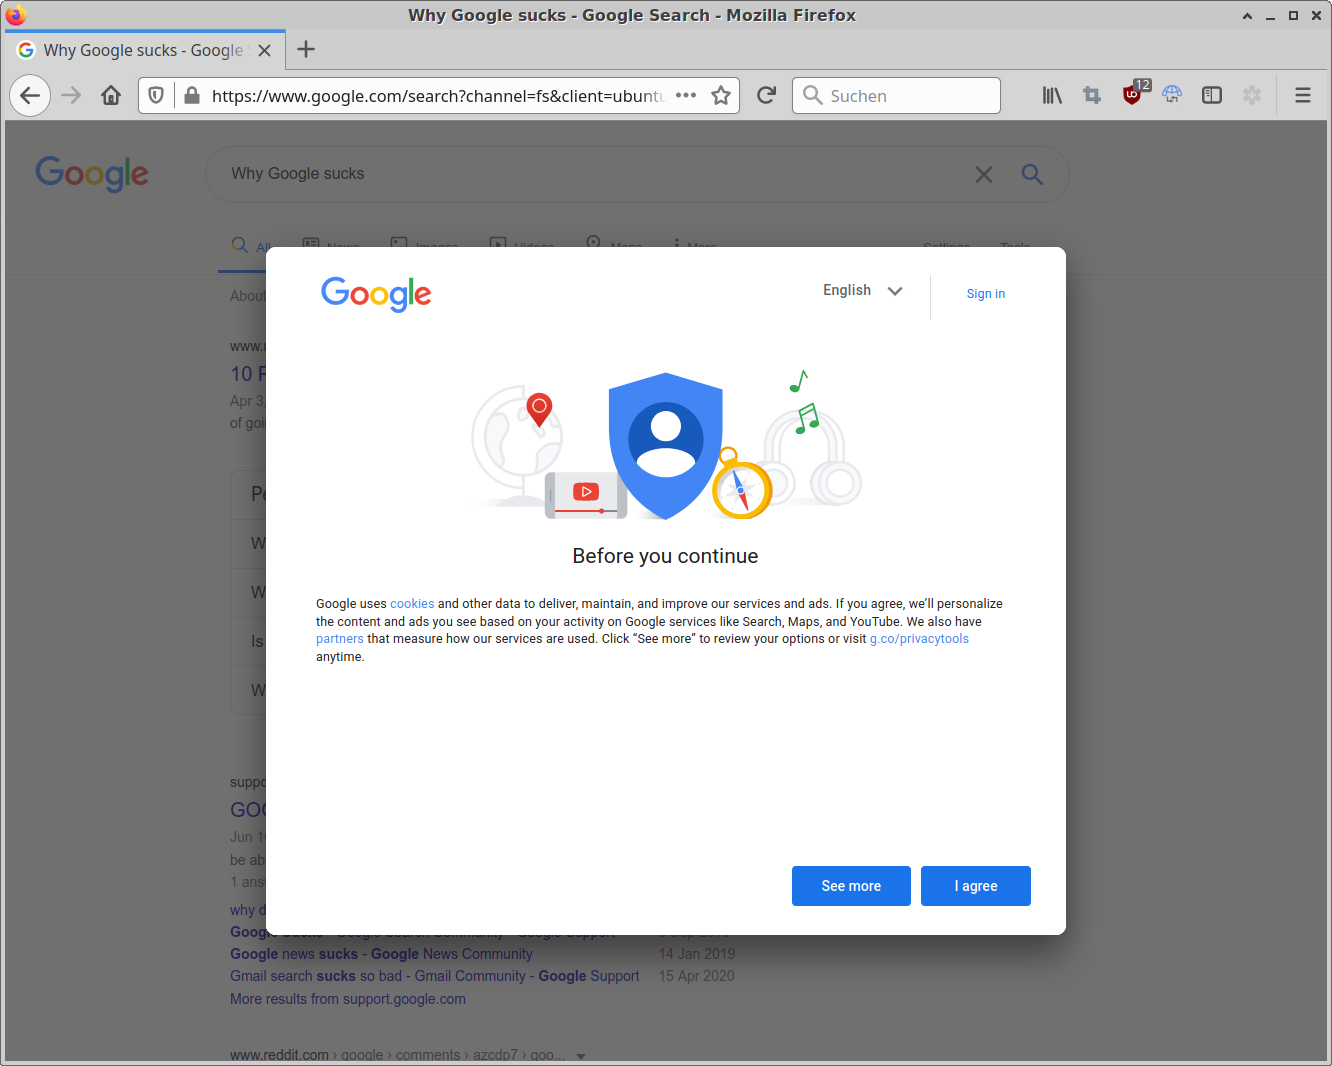
If you clear your browser cookies regularly (as you should do), Google will annoy you with a full screen cookie consent overlay these days. And - of course - there is no "no tracking consent, technically required cookies only" button. You may log in to Google to set your preference. Yeah, I'm sure this is totally following the intent of the EU Directive 2009/136/EC (the "cookie law"). Google cookie consent pop-up Unfortunately none of the big "anti-annoyances" filter lists seem to have picked that one up yet but the friendly folks from the Computerbase Forum [German] to the rescue. User "Sepp Depp" has created the following filter set that WFM: Add this to your uBlock Origin "My filters" tab:
! Google - remove cookie-consent-popup and restore scroll functionality
google.*##.wwYr3.aID8W.bErdLd
google.*##.aID8W.m114nf.t7xA6
google.*##div[jsname][jsaction^="dg_close"]
google.*##html:style(overflow: visible !important;)
google.*##.widget-consent-fullscreen.widget-consent

9 September 2013

Kurt Roeckx: State of encryption

With all the articles about the NSA going around it seems to be hard to follow what is still safe. After reading various things it boils down to:
I don't think this should really surprise anybody. There is also speculation that maybe the NSA has better algorithms for reducing the complexity of public key cryptography or that maybe RC4 might be broken. Those things clearly are possible, but it's not clear. Nobody has suggested that AES has any problems, and I think that's still safe to use. One of the question becomes what does properly done encryption mean. There are various factors to this and many applications using various protocols. SSL/TLS is the most used, so I'm going to concentrate on the parts in that. Bit sizes As far as I understand it, 80 bit of security is around what is currently the upper practical limit of a brute force attack. In 2003 NIST said to stop using 80 bit by 2015, in 2005 they said to stop using it by 2010. When using something like SSL/TLS you using various things each having it's own size. So it's important to known which is the weakest part. Public key encryption (RSA, DSA, DH) doesn't offer the same amount of security per bit than symmetric keys. The equivalent sizes I find are:
Symmetric Public
80 1024
112 2048
128 3072
256 15360
There are other sources that have other numbers, but they're similar So this basically means you really should stop using 80 bit symmetric and 1024 bit public keys and that your public key really should be at least 2048 bit, and should maybe even consider going to 3072 bit. There seems to be a push to moving Diffie-Hellman (DH) to provide Perfect Forward Secrecy (PFS). There are many variants to this. We want to use ephemeral (temporary) keys. But it basically boils down to 2 variants:
With DHE you first negotiate a temporary DH key for this session (hopefully) using a random number on both sides, and then using that DH key to exchange a normal symmetric key for the session. This temporary DH key is what provides the PFS, assuming that this temporary key is thrown away. The drawback of this is that creating a sessions takes a lot more CPU time. The standard DH has the same security as other public key encryption. So we really also want to stop using 1024 keys for that. With ECDHE the key size needs to be the double of the symmetric size. This is also faster than DHE, so people want to move to this. There are various curves that can be used for this, and some of them are generated the the NSA and people have no trust in them. Some people even don't trust any of the curves. Most people seem to think that ECDH is the way forward, but then limit the curves they support. There are also hashes used for various things including signatures and MACs. Depending on how it's used the properties of the hash are important. They have 2 important properties collision resistance and preimage resistance. For a collision attack the upper limit is a little more than the output size over 2. But there are attacks that are known to give worst results. I found those numbers:
MD5 2^20
SHA-1 2^60
SHA-2 No known attack (so SHA-256 would have 1.2 * 2^128)
For preimage attacks I found:
MD5 2^123
SHA-1 No known attack (2^160)
SHA-256 No known attack (2^256)
So I think that MD5 is still safe when a collision attack isn't possible, but should really be avoided for anything else and SHA-1 should probably be considered the same. So you want to avoid them in things like certificates. SSL/TLS also use MD5 / SHA-1, but as part of a HMAC. I understand that those are not vulnerable to the collision attack but preimage resistance is important then and so are still considered safe. Randomness A lot of the algorithms depend on good random numbers. That is that the attacker can't guess what a (likely) random number you've selected. There have been many cases of bad RNG that then resulted in things getting broken. It's hard to tell from the output of most random number generators that they are secure or not. One important thing is that the RNGs gets seeded with random information (entropy) to begin with. If it gets no random information, very limited amount of possible inputs or information that is guessable as input it can appear to give random numbers, but they end up being predictable There have been many cases where this was broken. Ciphers There are various encryption algorithms. But since the public key algorithms take a lot of time we usually want to limit the amount we do with them and do most with a symmetric key encryption. There are basically 2 types of symmetric ciphers: stream and block ciphers. For block ciphers there are various ways of combining the blocks. The most popular was CBC. But in combination with TLS 1.0 it was vulnerable to the BEAST attack, but there is a workaround for this. An other mode is GCM but it's not yet widely deployed. This resulted in the stream cipher RC4 suddenly getting popular again. Some ciphers have known weaknesses. For instance triple DES has 3*56=168 bits, but only provides for 2*56=112 bits of security. Other attacks make this even less. The algorithms them self might be secure, but they might be attacked by other mechanism known as sidechannel attacks. The most important of that is timing attacks. If the algorithm has branches they might result in different amount of time taking in each branch. This might result in an attacker finding out some information about the secret key that is being used. It's important that the difference should be reduced as much as possible. This is usually not a problem if it's implemented in hardware. SSL/TLS Session A typical SSL/TLS session uses those things:
Important aspects of using certificates:
The client sends it's list of supported ciphers to the server and the server will then pick one. This is usually the first from that list that is supported by the server, but it might also be the order that is configured on the server that is used. Current status in software If you go looking at all of those things, you find problems in most if not all software. Some of that is to be compatible with old clients or servers, but most of it is not. If you want to test web servers for various of those properties you can do that at ssllabs. Based on that there are stats available at SSL-pulse. Apache only supports 1024 bit DHE keys and they don't want to apply a patch to support other bit size. Apache 2.2 doesn't offer ECDHE but 2.4 does. I don't know of any good site has lists which browser supports which ciphers, but you can test your own browser here. It lacks information about EC curves that your client offers. You can of course as look at this with wireshark. Mozilla currently has a proposal to change it's list of supported ciphers here. They currently don't have TLS 1.1 or 1.2 enabled yet, but as far as I understand the NSS library should support it. They should now have support for GCM, but they still have an open bug for a constant time patch. In general Mozilla seems to be moving very slowly with adopting things. Last I heard Apple still didn't patch Safari for the BEAST attack. For XMPP see client to server, server to server, clients.

For TOR see here.

5 February 2013

Michael Stapelberg: RC bugs

I recently worked on the following RC bugs: It is getting hard to find RC bugs to work on. If you have access to ia64 hardware, have a look at #694971 Epiphany browser crashes within JSC::JSArray::increaseVectorLength() or #697172 sporadic crashes of epiphany browser due to a thread-unsafe favicon database. Both have patches available that just need to be tested.

19 January 2012

Obey Arthur Liu: Aptitude 0.5.0 (aka Aptitude-gtk) released

Long time no post. Anyway, I have some good news.

The Gtk code for Aptitude has been merged some time ago into the main development trunk and we now have a release in Experimental.


For those that don't know about it, here's what it's all about : "The new frontend is is an effort to bring some of the design principles of the curses frontend to a GUI environment, while also exploiting the unique features a GUI gives us and exploring ways to deal with changes in the environment in the nine years since aptitude was first designed."

I had a very good time this summer working on Aptitude with Daniel Burrows in the Google Summer of Code program and I'm very glad we now have a real release. This version is by no means final or perfect but it's a good start.

Head for the blog post from Daniel for some other informations : [Daniel Burrows]

19 September 2010

Gregor Herrmann: RC bugs 2010/37

thanks to Lucas' recent archive rebuild & bug filing we have new stuff to work on :) my activities in the last week:
29 June 2008

Eddy Petrișor: when printouts don't help to revoke a GPG key

It's official, I am revoking my gpg key because after my laptop returned from service[1] I realized is a bad idea to change the passphrase just before a long break away from a routine that would help the brain to cement the new passphrase. In other words, I forgot the passphrase.

So, let's get the revocation certificate printout and revoke that gpg and generate a new one. All is good and fine until you realize that I (capital i) and l (low case L ) look very much the same on paper. Oops!

So, what do you do? How many I/l -s are there in the certificate? Let's find out...


0 eddy@bounty ~/tmp/revoke $ cat template
-----BEGIN PGP PUBLIC KEY BLOCK-----
Version: GnuPG v1.4.6 (GNU/Linux)
Comment: A revocation certificate should follow

iEkEIBECAAkFAkbYOQUCHQIACgkQY8Chqv3NRNquGgCgxdMDrhycNcoJsaeeg7hk
8vVJZzsAnRicsfjcZnUtmLIsys6KK48FbJ4h
=I5o9
-----END PGP PUBLIC KEY BLOCK-----


Well, I'm not going to count, I'll remove the header and footer and see from there...

0 eddy@bounty ~/tmp/revoke $ cat template.in tr -d '[a-zA-HJ-Z0-9=]'
II
I
I


Ok, so we have 16 possible combinations, not that many.

0 eddy@bounty ~/tmp/revoke $ for i in l I ; do for j in l I ; do for k in l I ; do for l in l I ; do cat template.in sed -e "s#I#$i#" -e "s#I#$j#" -e "s#I#$k#" -e "s#I#$l#" > $i$j$k$l.mid ; done ; done ; done ; done
0 eddy@bounty ~/tmp/revoke $ md5sum *.mid
eab3a5e312bc0314ac2b3d4536bda2f6 IIII.mid
63a9dd10e381b8ff5c758ab3467a5c45 IIIl.mid
63a9dd10e381b8ff5c758ab3467a5c45 IIlI.mid
919d8494c9990c68f50bc9df61f269bc IIll.mid
63a9dd10e381b8ff5c758ab3467a5c45 IlII.mid
919d8494c9990c68f50bc9df61f269bc IlIl.mid
919d8494c9990c68f50bc9df61f269bc IllI.mid
919d8494c9990c68f50bc9df61f269bc Illl.mid
63a9dd10e381b8ff5c758ab3467a5c45 lIII.mid
919d8494c9990c68f50bc9df61f269bc lIIl.mid
919d8494c9990c68f50bc9df61f269bc lIlI.mid
919d8494c9990c68f50bc9df61f269bc lIll.mid
919d8494c9990c68f50bc9df61f269bc llII.mid
919d8494c9990c68f50bc9df61f269bc llIl.mid
919d8494c9990c68f50bc9df61f269bc lllI.mid
919d8494c9990c68f50bc9df61f269bc llll.mid


Oops, that's not ok... I guess I've been replacing some of the characters more than once.

Take 2:
0 eddy@bounty ~/tmp/revoke $ for i in l I ; do for j in l I ; do for k in l I ; do for l in l I ; do cat template.in tr 'Il' '-' sed -e "s#-#$i#" -e "s#-#$j#" -e "s#-#$k#" -e "s#-#$l#" > $i$j$k$l.mid ; done ; done ; done ; done
0 eddy@bounty ~/tmp/revoke $ md5sum *.mid
eab3a5e312bc0314ac2b3d4536bda2f6 IIII.mid
eab3a5e312bc0314ac2b3d4536bda2f6 IIIl.mid
eab3a5e312bc0314ac2b3d4536bda2f6 IIlI.mid
eab3a5e312bc0314ac2b3d4536bda2f6 IIll.mid
7150fa775c83c276223a30d373671333 IlII.mid
7150fa775c83c276223a30d373671333 IlIl.mid
7150fa775c83c276223a30d373671333 IllI.mid
7150fa775c83c276223a30d373671333 Illl.mid
63a9dd10e381b8ff5c758ab3467a5c45 lIII.mid
63a9dd10e381b8ff5c758ab3467a5c45 lIIl.mid
63a9dd10e381b8ff5c758ab3467a5c45 lIlI.mid
63a9dd10e381b8ff5c758ab3467a5c45 lIll.mid
919d8494c9990c68f50bc9df61f269bc llII.mid
919d8494c9990c68f50bc9df61f269bc llIl.mid
919d8494c9990c68f50bc9df61f269bc lllI.mid
919d8494c9990c68f50bc9df61f269bc llll.mid


Oops, that's not good either. Doh, sed works on lines.

Take 3:

Make a one line out of the template and try again:

0 eddy@bounty ~/tmp/revoke $ cat template.in
iEkEIBECAAkFAkbYOQUCHQIACgkQY8Chqv3NRNquGgCgxdMDrhycNcoJsaeeg7hk8vVJZzsAnRicsfjcZnUtmLIsys6KK48FbJ4h=I5o9

0 eddy@bounty ~/tmp/revoke $ for i in l I ; do for j in l I ; do for k in l I ; do for l in l I ; do cat template.in tr 'I' '-' tr 'l' '-' sed -e "s#-#$i#" -e "s#-#$j#" -e "s#-#$k#" -e "s#-#$l#" > $i$j$k$l.mid ; done ; done ; done ; done
0 eddy@bounty ~/tmp/revoke $ md5sum *.mid
66ab0a0bed219db8499debabb9a41c0b IIII.mid
e02c1751c4491ce5db1ebe9e64d8eadc IIIl.mid
c96a33f821d3fba84f655aa986084320 IIlI.mid
998c5c4219a5afdd77f82c9fc9818f6f IIll.mid
e08fe6c5380765d12c4f5e4090a7d9c6 IlII.mid
24241b58c231900b02ebb0410183983e IlIl.mid
72040a77e7cca9a91abf2bb0d51c00dd IllI.mid
a02e8645f3593f5c3549b49adef04bc2 Illl.mid
99a1a47c853ed760ef1f58cba7b75916 lIII.mid
c48bf75f30be46ec576a46a1d5664a93 lIIl.mid
717e9dfdc0d3fba973ba66ccb57d69dc lIlI.mid
3e9a2c937fd269d85c09b449b4da17de lIll.mid
4d283333d1d62086328dbc72425a645d llII.mid
542a7c00e99aad5137975581e57a92c9 llIl.mid
ef0e0a2daad7a933b620331a86455c23 lllI.mid
bdf852887308830475a506f8daad9624 llll.mid


That's better. Now let's put those lines back in place:

0 eddy@bounty ~/tmp/revoke $ for I in *.mid ; do cat $I sed -e 's#\(eeg7hk\)#\1-#' -e 's#\(K48FbJ4h\)#\1-#' tr '-' '\n' > $I.good ; done


And revoke that key...

0 eddy@bounty ~/tmp/revoke $ for I in *.mid.good ; do echo "$I:" && (cat header $I footer) > template && gpg --import -a template ; done
IIII.mid.good:
gpg: CRC error; 73689A - 239A3D
gpg: read_block: read error: invalid keyring
gpg: import from template' failed: invalid keyring
gpg: Total number processed: 0
IIIl.mid.good:
gpg: CRC error; 73689A - 979A3D
gpg: read_block: read error: invalid keyring
gpg: import from template' failed: invalid keyring
gpg: Total number processed: 0
IIlI.mid.good:
gpg: key FDCD44DA: "Eddy Petri or
" revocation certificate imported
gpg: Total number processed: 1
gpg: new key revocations: 1
gpg: public key 67D8E867 is 987014 seconds newer than the signature
gpg: public key 67D8E867 is 987029 seconds newer than the signature
gpg: 3 marginal(s) needed, 1 complete(s) needed, PGP trust model
gpg: depth: 0 valid: 2 signed: 139 trust: 0-, 0q, 0n, 0m, 0f, 2u
gpg: depth: 1 valid: 139 signed: 667 trust: 138-, 0q, 0n, 1m, 0f, 0u
gpg: next trustdb check due at 2008-10-09
IIll.mid.good:
gpg: CRC error; 239A3D - 979A3D
gpg: read_block: read error: invalid keyring
gpg: import from template' failed: invalid keyring
gpg: Total number processed: 0


Cool!


[1] I know is almost a half a year, but I've been busy and hoping