Search Results: "joey"

29 August 2026

Joey Hess: Debian and the sirens

Thirty years ago I became a Debian developer. Twelve years ago I left the project. I left because it seemed that the Debian ship had become too slow to turn, too barnacled with a series of individually OK decisions that each added a little bit of friction and a little less flexability. That made Debian strongly what it is, but prevented it from fruitfully exploring the vast possibility space of what it could be. Debian will probably resolve today to allow LLM use in Debian development. I'm writing before the vote results are in, but will only post this afterwards. (Update: as expected) It's not my place any longer to try to steer the ship. But I'm still a passenger and I still have opinions, and I still pass by well-worn parts of the rigging that I put up decades ago, and remember what I was trying to accomplish back then. When I think about LLMs in Debian development, I mostly think about debhelper and what it accomplished. The debian/rules files back when I joined the project were long and complex, full of weird boilerplate, and often you'd copy one and modify it to try to get something that could build a package without too much work. Debhelper first regularized the boilerplate, so packages had rules files that were a succession of dh_ commands, and then it scapped almost all of the boilerplate, reducing the files to the minimum possible. What was left was 3 lines of unncessary boilerplate, there only to satisfy a legalistic reading of a policy document. Changing that to eliminate the boilerplate was already impossible, even though the actual benefit would have been large over the many thousands of packages in the distribution. What LLMs in Debian development will do, I fear, is eliminate any incentive to scrap boilerplate or reform policies that require a lot of other senseless human effort. If I had had access to LLMs 30 years ago, I might have just had them generate the rules files, replate with complexity. So they will make Debian even more firmly what it is, and ever less likely to explore what it could become. Unfortunately, one of the things that Debian is, is almost unable to manage packaging modern dependency trees. While more recent distributions like Guix can recursively import dependencies from a dozen programming languages' package repositories, with a result that is generally acceptable to add to the distribution, Debian's policies don't make that very possible for a progam to accomplish. Perhaps some will use LLMs to do that. If they succeeed, Debian will become dependent on proprietary software for development, while still needing people in the loop, doing even less appealing scut-work. I could speak of other harms, but that alone is enough that I'm sure that, if I had not left the project twelve years ago, I would be leaving it soon. As a passenger, I imagine I'll spend time aboard still from time to time, but it's certainly time to hop off in different places and look around and relish the different ways. I lost a parent yesterday, and I'm trying hard not to think of the results today as having lost a child, though I spent 18 years helping Debian grow up. That would be too unbearably painful. I respect that Debian is navigating a choice that may have no right answer. Whichever particular compromise is arrived at today, it will still be up to individuals to make choices about what they do and accept. Debian has always been more than the sum of its policies, not just a ship, but a crew. I will always love you.

29 July 2026

Joey Hess: my harddrive is probably not full

I enjoyed reading this post by Marginalia "Your harddrive is probably full"
You can construct an entropic argument that there are simply more ways for a harddrive to be full than ways in which it can be empty.
Of course it made me check how full my laptop drive is, and indeed it was more than 75% full, as predicted. But, I almost never feel that my hard drive is full. I can very easily free up almost any amount of disk space at any time, without any thought. While writing this blog post, I ran a single command and now my harddrive is 50% empty.
The other part of the equation is that a full disk isn t a problem until it s so full you can t put more stuff on it, and at the point it s so irredeemably cluttered that when you do clean it up, you only have the patience to clean up enough to bide your time, judging the fate of every file on the harddrive is simply too much work.
Why doesn't this apply to me? Because I have put in the up-front thought to organize things, so that I never have to do that anymore. I have 3 categories of files that I can remove at any time I need more space, without any thought:
  1. Any files that are stored in git-annex. This is one of git-annex's superpowers; you can git-annex drop any file and stop it using disk space, but the file is still there (as a broken symlink) so you don't risk losing or forgetting about it.
  2. Caches.
  3. Files in ~/tmp/, which is reserved for any files I only want to have a passing acquaintance with. If I'm not comfortable with something being deleted at any time, I don't put it there.
Not only do I only have these 3 categories, these are the only 3 categories for everything except OS files and files I have decided I never want to remove (eg dotfiles and other files stored in git repos). Computer scientists invented caches (and of course cache invalidation is no problem lol) so I only needed to learn about that one. Unix gave me /tmp/ as an example that I long ago used as the basis for the rules for my ~/tmp/. I hope that git-annex might also serve as an example that moving files between drives is not the best way to manage disk space use.

2 July 2026

Joey Hess: no LLM code in dependencies

I've spent about 100 hours of work over the past month to make sure git-annex can build without dependencies that contain LLM generated code. At least so far. https://git-annex.branchable.com/no_llm_code/ Needing to review a program's whole dependency tree on an ongoing basis is apparently what programming has come to? I've found some real stinkers. Large LLM generated changes being reverted in the next release without any explanation. An incoherent 1489 line commit message with 10,000 lines of changes to a 26,000 LOC code base. A LLM prompt to copy code from another project that seems to have only avoided being copyright infringement due to luck. I now have additional information about the quality of dependencies which will surely influence future decisions. As far as I can see, that's the only positive benefit of this work. I realize that I am probably trying to hold back the tide at this point. That appears to be why Software Freedom Conservancy punted, and I doubt that the FSF will do any better. As these dominos fall, I am reconsidering my participation in these communities. But I continue my work and support my users. It may seem easy to prompt a LLM with
Add fourmolu config and restyled neat format a module
And commit the result and call yourself a 10xer. But please consider the broader impact of your actions. (In the above case, that project lost my further collaboration on it.)

30 June 2026

Joey Hess: big loads offgrid with a small battery (sidelined)

No matter that the hype cycle wants you to think, the renewable energy transition is the biggest thing happening in tech and it's happening faster and faster. Despite being neck deep in it personally with offgrid solar projects, most recently solar hot water, increasingly it becomes clear I'm watching from the sidelines. In Australia, everyone gets 24 kwh of free daytime electric power now. That's without installing any solar panels of their own, the grid just has that much excess capacity. All it takes to save $thousands per year (and avoid emissions) is to schedule some big loads like the hot water heater and EV to charge during the day. To save more, drop in a home battery that charges for free and powers the home through the evening. In Germany, a 2 kwh plug-in home battery costs $350 and the electric company will pay you $130 per year to plug it into your wall. There are similar offers throughout Europe. In Cuba something something geopolitics, oil blockade, belt and road => suddenly 1GW of solar farms with another gigawatt on the way. I'll soon visit South Carolina where with no subsidies whatsoever from a decidedly renewable-unfriendly government, it made sense for my dad's house to get a whole home battery and double the solar array. The resulting system will be able to power the well pump and probably also the whole geothermal HVAC system through the kind of month-long grid down events that happened in Hurricane Helene. Myself, well, I've got a by modern standards small 4 kwh home battery that powers my house offgrid, and I've recently installed a heat pump hot water heater. That's after about a decade pondering what solution to use for solar hot water, to replace an aging and horrible propane instant water heater. I've in the past considered everything from evacuated tubes to special direct drive inverters to DC resistive MPTT dump loads. The solution turned out to be just a big enough solar array, and plugging in a 120v hot water heater that needs only 500 watts in heat pump mode. Plus a small amount of code to manage when it runs. In the time I was thinking about that, economies of scale and tech improvements just wiped all those other possibilities off the map, it's not economical to install and maintain a separate evactuated tube heat collector when a pile of solar panels costs so little and when electric hot water has gotten more than 200% efficient. I also recently completed my permanant EV charger installation, with a new inverter and conduit and proper wiring, and increased the car's charge rate to 2 kw. Eliminating the need to charge anywhere except at home except on road trips. Coordinating when these two big loads run, to maximize solar production and ensure that the house battery is full at the end of the day was ... not hard at all actually? The car charger amps can be dialed up and down to match incoming solar power fairly well, and leave some room for the hot water heater. They both operate as more or less dump loads. More or less because neither one can be cycled on or off very fast (to avoid wear and tear on the car's contactor and the heat pump's compressor), so it makes sense to leave them on and skate through short cloudy sections of the day, as long as the house battery doesn't get too low. How low is too low for the house battery? Depends on the time of day. The code it's currently using, which may get tweaked over winter:
    -- When the battery is charged enough to run major loads that may prevent
    -- charging it further.
    --
    -- This varies with the hour of day. Early in the day, the battery does not
    -- need to be as full to be considered well charged, since there is
    -- still plenty of time for it to charge up. Later in the day, with less
    -- time to charge, it needs to be more full.
    wellCharged :: Hour -> Percentage
    wellCharged (Hour hour)
              hour < 9 = Percentage 90 -- night
              pmhour <= 0 = Percentage 50
              pmhour <= 1 = Percentage 60
              pmhour <= 2 = Percentage 70
              pmhour <= 3 = Percentage 80
              pmhour <= 4 = Percentage 90
              otherwise = Percentage 95
      where
            pmhour = hour - 12
More complicated is, what to do it there's solar power to run one or the other, but not both? This is starting to get into the territory of microgrids now, or of demand response programs, so there's a whole industry or three out there doing industry things geared at the kind of no-brainer solutions I mentioned earlier. From what I've gathered, all of them involve proprietary protocols and gear. What I've done is to read the state of the hot water heater and car, and prioritize hot water over the car. Except, if the car is below 10% it urgently needs to charge. And I found a really simple way to decide when to run the low-priority load: Just check if the house battery's current charge will be considered wellCharged in an hour. So if it's 2 pm, the battery needs to be 80% charged to run the lower-priority load, and if it dips below that, that load will turn off but the high-priority load will keep running down to 70% battery. Unfortunately, getting any information out of my hot water heater relies on a vendor API server that is often down on weekends, and reverse engineered the web page of my EVSE[1] to control it, to say nothing of the nightmare of getting the car's state of charge from The Cloud. Anyway, I'm pleased with having easily tweakable code and how far I've taken this offgrid, and everything I've learned doing so, but like I said, I'm clearly observing from the sidelines over here while the most significant thing for all of us is going on over there. You might appreciate my code or method, but you'll eventually be plugging in a home battery or signing up for a free daytime power tarrif from your electric company, or having professionals install a whole home system for climate resiliance. So my question is, where does free software fit into all this? There are things like Home Assistant that do productize the kind of thing I'm doing enough to be useful more widely. But still niche. Meanwhile there are inverters and batteries that phone home to China, and every consumer facing install is either "use this device" or "integrate these 3 proprietary devices". I don't think focusing on these negatives is really useful though, I'm more trying to understand where all this is going and then maybe get out ahead of it in some useful way with free software. Your thoughts welcome.
[1] Obviously OpenEVSE exists, but it didn't meet my needs hardware wise. And I could set my EVSE to use an OCPP server but it was easier to do the screen scraping than find an appropriate one, and I have the feeling I would not appreciate learning any more about OCPP, in the same way I really don't want to know a lot about web browsers' tag soup mode.

17 June 2026

Joey Hess: best of the web

This is somehow the featured website on https://earlyweblinks.com/ this week. Read all about my web site here! https://earlyweblinks.com/site-of-the-week/joey-hess Kind of reminds me of back in 1995 or so when my website would randomly end up picked by some best of the web list that I never heard of. The web is still a small place I guess. Maybe I should join a web ring or something?

1 April 2026

Joey Hess: banning all Anthropic employees

Per my policies, I need to ban every employee and contractor of Anthropic Inc from ever contributing code to any of my projects. Anyone have a list? Any project that requires a Developer Certificate of Origin or similar should be doing this, because Anthropic is making tools that explicitly lie about the origin of patches to free software projects.
UNDERCOVER MODE CRITICAL You are operating UNDERCOVER in a PUBLIC/OPEN-SOURCE repository. [...] Do not blow your cover. NEVER include in commit messages or PR descriptions: [...] The phrase 'Claude Code' or any mention that you are an AI
Co-Authored-By lines or any other attribution
-- via @vedolos

5 March 2026

Ian Jackson: Adopting tag2upload and modernising your Debian packaging

Introduction tag2upload allows authorised Debian contributors to upload to Debian simply by pushing a signed git tag to Debian s gitlab instance, Salsa. We have recently announced that tag2upload is, in our opinion, now very stable, and ready for general use by all Debian uploaders. tag2upload, as part of Debian s git transition programme, is very flexible - it needs to support a large variety of maintainer practices. And it s relatively unopinionated, wherever that s possible. But, during the open beta, various contributors emailed us asking for Debian packaging git workflow advice and recommendations. This post is an attempt to give some more opinionated answers, and guide you through modernising your workflow. (This article is aimed squarely at Debian contributors. Much of it will make little sense to Debian outsiders.) Why Ease of development git offers a far superior development experience to patches and tarballs. Moving tasks from a tarballs and patches representation to a normal, git-first, representation, makes everything simpler. dgit and tag2upload do automatically many things that have to be done manually, or with separate commands, in dput-based upload workflows. They will also save you from a variety of common mistakes. For example, you cannot accidentally overwrite an NMU, with tag2upload or dgit. These many safety catches mean that our software sometimes complains about things, or needs confirmation, when more primitive tooling just goes ahead. We think this is the right tradeoff: it s part of the great care we take to avoid our software making messes. Software that has your back is very liberating for the user. tag2upload makes it possible to upload with very small amounts of data transfer, which is great in slow or unreliable network environments. The other week I did a git-debpush over mobile data while on a train in Switzerland; it completed in seconds. See the Day-to-day work section below to see how simple your life could be. Don t fear a learning burden; instead, start forgetting all that nonsense Most Debian contributors have spent months or years learning how to work with Debian s tooling. You may reasonably fear that our software is yet more bizarre, janky, and mistake-prone stuff to learn. We promise (and our users tell us) that s not how it is. We have spent a lot of effort on providing a good user experience. Our new git-first tooling, especially dgit and tag2upload, is much simpler to use than source-package-based tooling, despite being more capable. The idiosyncrasies and bugs of source packages, and of the legacy archive, have been relentlessly worked around and papered over by our thousands of lines of thoroughly-tested defensive code. You too can forget all those confusing details, like our users have! After using our systems for a while you won t look back. And, you shouldn t fear trying it out. dgit and tag2upload are unlikely to make a mess. If something is wrong (or even doubtful), they will typically detect it, and stop. This does mean that starting to use tag2upload or dgit can involve resolving anomalies that previous tooling ignored, or passing additional options to reassure the system about your intentions. So admittedly it isn t always trivial to get your first push to succeed. Properly publishing the source code One of Debian s foundational principles is that we publish the source code. Nowadays, the vast majority of us, and of our upstreams, are using git. We are doing this because git makes our life so much easier. But, without tag2upload or dgit, we aren t properly publishing our work! Yes, we typically put our git branch on Salsa, and point Vcs-Git at it. However:
  • The format of git branches on Salsa is not standardised. They might be patches-unapplied, patches-applied, bare debian/, or something even stranger.
  • There is no guarantee that the DEP-14 debian/1.2.3-7 tag on salsa corresponds precisely to what was actually uploaded. dput-based tooling (such as gbp buildpackage) doesn t cross-check the .dsc against git.
  • There is no guarantee that the presence of a DEP-14 tag even means that that version of package is in the archive.
This means that the git repositories on Salsa cannot be used by anyone who needs things that are systematic and always correct. They are OK for expert humans, but they are awkward (even hazardous) for Debian novices, and you cannot use them in automation. The real test is: could you use Vcs-Git and Salsa to build a Debian derivative? You could not. tag2upload and dgit do solve this problem. When you upload, they:
  1. Make a canonical-form (patches-applied) derivative of your git branch;
  2. Ensure that there is a well-defined correspondence between the git tree and the source package;
  3. Publish both the DEP-14 tag and a canonical-form archive/debian/1.2.3-7 tag to a single central git depository, *.dgit.debian.org;
  4. Record the git information in the Dgit field in .dsc so that clients can tell (using the ftpmaster API) that this was a git-based upload, what the corresponding git objects are, and where to find them.
This dependably conveys your git history to users and downstreams, in a standard, systematic and discoverable way. tag2upload and dgit are the only system which achieves this. (The client is dgit clone, as advertised in e.g. dgit-user(7). For dput-based uploads, it falls back to importing the source package.) Adopting tag2upload - the minimal change tag2upload is a substantial incremental improvement to many existing workflows. git-debpush is a drop-in replacement for building, signing, and uploading the source package. So, you can just adopt it without completely overhauling your packaging practices. You and your co-maintainers can even mix-and-match tag2upload, dgit, and traditional approaches, for the same package. Start with the wiki page and git-debpush(1) (ideally from forky aka testing). You don t need to do any of the other things recommended in this article. Overhauling your workflow, using advanced git-first tooling The rest of this article is a guide to adopting the best and most advanced git-based tooling for Debian packaging. Assumptions
  • Your current approach uses the patches-unapplied git branch format used with gbp pq and/or quilt, and often used with git-buildpackage. You previously used gbp import-orig.
  • You are fluent with git, and know how to use Merge Requests on gitlab (Salsa). You have your origin remote set to Salsa.
  • Your main Debian branch name on Salsa is master. Personally I think we should use main but changing your main branch name is outside the scope of this article.
  • You have enough familiarity with Debian packaging including concepts like source and binary packages, and NEW review.
  • Your co-maintainers are also adopting the new approach.
tag2upload and dgit (and git-debrebase) are flexible tools and can help with many other scenarios too, and you can often mix-and-match different approaches. But, explaining every possibility would make this post far too confusing. Topics and tooling This article will guide you in adopting:
  • tag2upload
  • Patches-applied git branch for your packaging
  • Either plain git merge or git-debrebase
  • dgit when a with-binaries uploaded is needed (NEW)
  • git-based sponsorship
  • Salsa (gitlab), including Debian Salsa CI
Choosing the git branch format In Debian we need to be able to modify the upstream-provided source code. Those modifications are the Debian delta. We need to somehow represent it in git. We recommend storing the delta as git commits to those upstream files, by picking one of the following two approaches.
rationale Much traditional Debian tooling like quilt and gbp pq uses the patches-unapplied branch format, which stores the delta as patch files in debian/patches/, in a git tree full of unmodified upstream files. This is clumsy to work with, and can even be an alarming beartrap for Debian outsiders.
git merge Option 1: simply use git, directly, including git merge. Just make changes directly to upstream files on your Debian branch, when necessary. Use plain git merge when merging from upstream. This is appropriate if your package has no or very few upstream changes. It is a good approach if the Debian maintainers and upstream maintainers work very closely, so that any needed changes for Debian are upstreamed quickly, and any desired behavioural differences can be arranged by configuration controlled from within debian/. This is the approach documented more fully in our workflow tutorial dgit-maint-merge(7).
git-debrebase Option 2: Adopt git-debrebase. git-debrebase helps maintain your delta as linear series of commits (very like a topic branch in git terminology). The delta can be reorganised, edited, and rebased. git-debrebase is designed to help you carry a significant and complicated delta series. The older versions of the Debian delta are preserved in the history. git-debrebase makes extra merges to make a fast-forwarding history out of the successive versions of the delta queue branch. This is the approach documented more fully in our workflow tutorial dgit-maint-debrebase(7). Examples of complex packages using this approach include src:xen and src:sbcl.
Determine upstream git and stop using upstream tarballs We recommend using upstream git, only and directly. You should ignore upstream tarballs completely.
rationale Many maintainers have been importing upstream tarballs into git, for example by using gbp import-orig. But in reality the upstream tarball is an intermediate build product, not (just) source code. Using tarballs rather than git exposes us to additional supply chain attacks; indeed, the key activation part of the xz backdoor attack was hidden only in the tarball! git offers better traceability than so-called pristine upstream tarballs. (The word pristine is even a joke by the author of pristine-tar!)
First, establish which upstream git tag corresponds to the version currently in Debian. From the sake of readability, I m going to pretend that upstream version is 1.2.3, and that upstream tagged it v1.2.3. Edit debian/watch to contain something like this:
version=4
opts="mode=git" https://codeberg.org/team/package refs/tags/v(\d\S*)
You may need to adjust the regexp, depending on your upstream s tag name convention. If debian/watch had a files-excluded, you ll need to make a filtered version of upstream git.
git-debrebase From now on we ll generate our own .orig tarballs directly from git.
rationale We need some upstream tarball for the 3.0 (quilt) source format to work with. It needs to correspond to the git commit we re using as our upstream. We don t need or want to use a tarball from upstream for this. The .orig is just needed so a nice legacy Debian source package (.dsc) can be generated.
Probably, the current .orig in the Debian archive, is an upstream tarball, which may be different to the output of git-archive and possibly even have different contents to what s in git. The legacy archive has trouble with differing .origs for the same upstream version . So we must until the next upstream release change our idea of the upstream version number. We re going to add +git to Debian s idea of the upstream version. Manually make a tag with that name:
git tag -m "Compatibility tag for orig transition" v1.2.3+git v1.2.3~0
git push origin v1.2.3+git
If you are doing the packaging overhaul at the same time as a new upstream version, you can skip this part.
Convert the git branch
git merge Prepare a new branch on top of upstream git, containing what we want:
git branch -f old-master         # make a note of the old git representation
git reset --hard v1.2.3          # go back to the real upstream git tag
git checkout old-master :debian  # take debian/* from old-master
git commit -m "Re-import Debian packaging on top of upstream git"
git merge --allow-unrelated-histories -s ours -m "Make fast forward from tarball-based history" old-master
git branch -d old-master         # it's incorporated in our history now
If there are any patches, manually apply them to your main branch with git am, and delete the patch files (git rm -r debian/patches, and commit). (If you ve chosen this workflow, there should be hardly any patches,)
rationale These are some pretty nasty git runes, indeed. They re needed because we want to restart our Debian packaging on top of a possibly quite different notion of what the upstream is.
git-debrebase Convert the branch to git-debrebase format and rebase onto the upstream git:
git-debrebase -fdiverged convert-from-gbp upstream/1.2.3
git-debrebase -fdiverged -fupstream-not-ff new-upstream 1.2.3+git
If you had patches which patched generated files which are present only in the upstream tarball, and not in upstream git, you will encounter rebase conflicts. You can drop hunks editing those files, since those files are no longer going to be part of your view of the upstream source code at all.
rationale The force option -fupstream-not-ff will be needed this one time because your existing Debian packaging history is (probably) not based directly on the upstream history. -fdiverged may be needed because git-debrebase might spot that your branch is not based on dgit-ish git history.
Manually make your history fast forward from the git import of your previous upload.
dgit fetch
git show dgit/dgit/sid:debian/changelog
# check that you have the same version number
git merge -s ours --allow-unrelated-histories -m 'Declare fast forward from pre-git-based history' dgit/dgit/sid
Change the source format Delete any existing debian/source/options and/or debian/source/local-options.
git merge Change debian/source/format to 1.0. Add debian/source/options containing -sn.
rationale We are using the 1.0 native source format. This is the simplest possible source format - just a tarball. We would prefer 3.0 (native) , which has some advantages, but dpkg-source between 2013 (wheezy) and 2025 (trixie) inclusive unjustifiably rejects this configuration. You may receive bug reports from over-zealous folks complaining about the use of the 1.0 source format. You should close such reports, with a reference to this article and to #1106402.
git-debrebase Ensure that debian/source/format contains 3.0 (quilt).
Now you are ready to do a local test build. Sort out the documentation and metadata Edit README.source to at least mention dgit-maint-merge(7) or dgit-maint-debrebase(7), and to tell people not to try to edit or create anything in debian/patches/. Consider saying that uploads should be done via dgit or tag2upload. Check that your Vcs-Git is correct in debian/control. Consider deleting or pruning debian/gbp.conf, since it isn t used by dgit, tag2upload, or git-debrebase.
git merge Add a note to debian/changelog about the git packaging change.
git-debrebase git-debrebase new-upstream will have added a new upstream version stanza to debian/changelog. Edit that so that it instead describes the packaging change. (Don t remove the +git from the upstream version number there!)
Configure Salsa Merge Requests
git-debrebase In Settings / Merge requests , change Squash commits when merging to Do not allow .
rationale Squashing could destroy your carefully-curated delta queue. It would also disrupt git-debrebase s git branch structure.
Set up Salsa CI, and use it to block merges of bad changes Caveat - the tradeoff gitlab is a giant pile of enterprise crap. It is full of startling bugs, many of which reveal a fundamentally broken design. It is only barely Free Software in practice for Debian (in the sense that we are very reluctant to try to modify it). The constant-churn development approach and open-core business model are serious problems. It s very slow (and resource-intensive). It can be depressingly unreliable. That Salsa works as well as it does is a testament to the dedication of the Debian Salsa team (and those who support them, including DSA). However, I have found that despite these problems, Salsa CI is well worth the trouble. Yes, there are frustrating days when work is blocked because gitlab CI is broken and/or one has to keep mashing Retry . But, the upside is no longer having to remember to run tests, track which of my multiple dev branches tests have passed on, and so on. Automatic tests on Merge Requests are a great way of reducing maintainer review burden for external contributions, and helping uphold quality norms within a team. They re a great boon for the lazy solo programmer. The bottom line is that I absolutely love it when the computer thoroughly checks my work. This is tremendously freeing, precisely at the point when one most needs it deep in the code. If the price is to occasionally be blocked by a confused (or broken) computer, so be it. Setup procedure Create debian/salsa-ci.yml containing
include:
  - https://salsa.debian.org/salsa-ci-team/pipeline/raw/master/recipes/debian.yml
In your Salsa repository, under Settings / CI/CD , expand General Pipelines and set CI/CD configuration file to debian/salsa-ci.yml.
rationale Your project may have an upstream CI config in .gitlab-ci.yml. But you probably want to run the Debian Salsa CI jobs. You can add various extra configuration to debian/salsa-ci.yml to customise it. Consult the Salsa CI docs.
git-debrebase Add to debian/salsa-ci.yml:
.git-debrebase-prepare: &git-debrebase-prepare
  # install the tools we'll need
  - apt-get update
  - apt-get --yes install git-debrebase git-debpush
  # git-debrebase needs git user setup
  - git config user.email "salsa-ci@invalid.invalid"
  - git config user.name "salsa-ci"
  # run git-debrebase make-patches
  # https://salsa.debian.org/salsa-ci-team/pipeline/-/issues/371
  - git-debrebase --force
  - git-debrebase --noop-ok make-patches
  # make an orig tarball using the upstream tag, not a gbp upstream/ tag
  # https://salsa.debian.org/salsa-ci-team/pipeline/-/issues/541
  - git-deborig
.build-definition: &build-definition
  extends: .build-definition-common
  before_script: *git-debrebase-prepare
build source:
  extends: .build-source-only
  before_script: *git-debrebase-prepare
variables:
  # disable shallow cloning of git repository. This is needed for git-debrebase
  GIT_DEPTH: 0
rationale Unfortunately the Salsa CI pipeline currently lacks proper support for git-debrebase (salsa-ci#371) and has trouble directly using upstream git for orig tarballs (#salsa-ci#541). These runes were based on those in the Xen package. You should subscribe to the tickets #371 and #541 so that you can replace the clone-and-hack when proper support is merged.
Push this to salsa and make the CI pass. If you configured the pipeline filename after your last push, you will need to explicitly start the first CI run. That s in Pipelines : press New pipeline in the top right. The defaults will very probably be correct. Block untested pushes, preventing regressions In your project on Salsa, go into Settings / Repository . In the section Branch rules , use Add branch rule . Select the branch master. Set Allowed to merge to Maintainers . Set Allowed to push and merge to No one . Leave Allow force push disabled. This means that the only way to land anything on your mainline is via a Merge Request. When you make a Merge Request, gitlab will offer Set to auto-merge . Use that. gitlab won t normally merge an MR unless CI passes, although you can override this on a per-MR basis if you need to. (Sometimes, immediately after creating a merge request in gitlab, you will see a plain Merge button. This is a bug. Don t press that. Reload the page so that Set to auto-merge appears.) autopkgtests Ideally, your package would have meaningful autopkgtests (DEP-8 tests) This makes Salsa CI more useful for you, and also helps detect and defend you against regressions in your dependencies. The Debian CI docs are a good starting point. In-depth discussion of writing autopkgtests is beyond the scope of this article. Day-to-day work With this capable tooling, most tasks are much easier. Making changes to the package Make all changes via a Salsa Merge Request. So start by making a branch that will become the MR branch. On your MR branch you can freely edit every file. This includes upstream files, and files in debian/. For example, you can:
  • Make changes with your editor and commit them.
  • git cherry-pick an upstream commit.
  • git am a patch from a mailing list or from the Debian Bug System.
  • git revert an earlier commit, even an upstream one.
When you have a working state of things, tidy up your git branch:
git merge Use git-rebase to squash/edit/combine/reorder commits.
git-debrebase Use git-debrebase -i to squash/edit/combine/reorder commits. When you are happy, run git-debrebase conclude. Do not edit debian/patches/. With git-debrebase, this is purely an output. Edit the upstream files directly instead. To reorganise/maintain the patch queue, use git-debrebase -i to edit the actual commits.
Push the MR branch (topic branch) to Salsa and make a Merge Request. Set the MR to auto-merge when all checks pass . (Or, depending on your team policy, you could ask for an MR Review of course.) If CI fails, fix up the MR branch, squash/tidy it again, force push the MR branch, and once again set it to auto-merge. Test build An informal test build can be done like this:
apt-get build-dep .
dpkg-buildpackage -uc -b
Ideally this will leave git status clean, with no modified or un-ignored untracked files. If it shows untracked files, add them to .gitignore or debian/.gitignore as applicable. If it dirties the tree, consider trying to make it stop doing that. The easiest way is probably to build out-of-tree, if supported upstream. If this is too difficult, you can leave the messy build arrangements as they are, but you ll need to be disciplined about always committing, using git clean and git reset, and so on. For formal binaries builds, including for testing, use dgit sbuild as described below for uploading to NEW. Uploading to Debian Start an MR branch for the administrative changes for the release. Document all the changes you re going to release, in the debian/changelog.
git merge gbp dch can help write the changelog for you:
dgit fetch sid
gbp dch --ignore-branch --since=dgit/dgit/sid --git-log=^upstream/main
rationale --ignore-branch is needed because gbp dch wrongly thinks you ought to be running this on master, but of course you re running it on your MR branch. The --git-log=^upstream/main excludes all upstream commits from the listing used to generate the changelog. (I m assuming you have an upstream remote and that you re basing your work on their main branch.) If there was a new upstream version, you ll usually want to write a single line about that, and perhaps summarise anything really important.
(For the first upload after switching to using tag2upload or dgit you need --since=debian/1.2.3-1, where 1.2.3-1 is your previous DEP-14 tag, because dgit/dgit/sid will be a dsc import, not your actual history.)
Change UNRELEASED to the target suite, and finalise the changelog. (Note that dch will insist that you at least save the file in your editor.)
dch -r
git commit -m 'Finalise for upload' debian/changelog
Make an MR of these administrative changes, and merge it. (Either set it to auto-merge and wait for CI, or if you re in a hurry double-check that it really is just a changelog update so that you can be confident about telling Salsa to Merge unverified changes .) Now you can perform the actual upload:
git checkout master
git pull --ff-only # bring the gitlab-made MR merge commit into your local tree
git merge
git-debpush
git-debrebase
git-debpush --quilt=linear
--quilt=linear is needed only the first time, but it is very important that first time, to tell the system the correct git branch layout.
Uploading a NEW package to Debian If your package is NEW (completely new source, or has new binary packages) you can t do a source-only upload. You have to build the source and binary packages locally, and upload those build artifacts. Happily, given the same git branch you d tag for tag2upload, and assuming you have sbuild installed and a suitable chroot, dgit can help take care of the build and upload for you: Prepare the changelog update and merge it, as above. Then:
git-debrebase Create the orig tarball and launder the git-derebase branch:
git-deborig
git-debrebase quick
rationale Source package format 3.0 (quilt), which is what I m recommending here for use with git-debrebase, needs an orig tarball; it would also be needed for 1.0-with-diff.
Build the source and binary packages, locally:
dgit sbuild
dgit push-built
rationale You don t have to use dgit sbuild, but it is usually convenient to do so, because unlike sbuild, dgit understands git. Also it works around a gitignore-related defect in dpkg-source.
New upstream version Find the new upstream version number and corresponding tag. (Let s suppose it s 1.2.4.) Check the provenance:
git verify-tag v1.2.4
rationale Not all upstreams sign their git tags, sadly. Sometimes encouraging them to do so can help. You may need to use some other method(s) to check that you have the right git commit for the release.
git merge Simply merge the new upstream version and update the changelog:
git merge v1.2.4
dch -v1.2.4-1 'New upstream release.'
git-debrebase Rebase your delta queue onto the new upstream version:
git debrebase mew-upstream 1.2.4
If there are conflicts between your Debian delta for 1.2.3, and the upstream changes in 1.2.4, this is when you need to resolve them, as part of git merge or git (deb)rebase. After you ve completed the merge, test your package and make any further needed changes. When you have it working in a local branch, make a Merge Request, as above. Sponsorship git-based sponsorship is super easy! The sponsee can maintain their git branch on Salsa, and do all normal maintenance via gitlab operations. When the time comes to upload, the sponsee notifies the sponsor that it s time. The sponsor fetches and checks out the git branch from Salsa, does their checks, as they judge appropriate, and when satisfied runs git-debpush. As part of the sponsor s checks, they might want to see all changes since the last upload to Debian:
dgit fetch sid
git diff dgit/dgit/sid..HEAD
Or to see the Debian delta of the proposed upload:
git verify-tag v1.2.3
git diff v1.2.3..HEAD ':!debian'
git-debrebase Or to show all the delta as a series of commits:
git log -p v1.2.3..HEAD ':!debian'
Don t look at debian/patches/. It can be absent or out of date.
Incorporating an NMU Fetch the NMU into your local git, and see what it contains:
dgit fetch sid
git diff master...dgit/dgit/sid
If the NMUer used dgit, then git log dgit/dgit/sid will show you the commits they made. Normally the best thing to do is to simply merge the NMU, and then do any reverts or rework in followup commits:
git merge dgit/dgit/sid
git-debrebase You should git-debrebase quick at this stage, to check that the merge went OK and the package still has a lineariseable delta queue.
Then make any followup changes that seem appropriate. Supposing your previous maintainer upload was 1.2.3-7, you can go back and see the NMU diff again with:
git diff debian/1.2.3-7...dgit/dgit/sid
git-debrebase The actual changes made to upstream files will always show up as diff hunks to those files. diff commands will often also show you changes to debian/patches/. Normally it s best to filter them out with git diff ... ':!debian/patches' If you d prefer to read the changes to the delta queue as an interdiff (diff of diffs), you can do something like
git checkout debian/1.2.3-7
git-debrebase --force make-patches
git diff HEAD...dgit/dgit/sid -- :debian/patches
to diff against a version with debian/patches/ up to date. (The NMU, in dgit/dgit/sid, will necessarily have the patches already up to date.)
DFSG filtering (handling non-free files) Some upstreams ship non-free files of one kind of another. Often these are just in the tarballs, in which case basing your work on upstream git avoids the problem. But if the files are in upstream s git trees, you need to filter them out. This advice is not for (legally or otherwise) dangerous files. If your package contains files that may be illegal, or hazardous, you need much more serious measures. In this case, even pushing the upstream git history to any Debian service, including Salsa, must be avoided. If you suspect this situation you should seek advice, privately and as soon as possible, from dgit-owner@d.o and/or the DFSG team. Thankfully, legally dangerous files are very rare in upstream git repositories, for obvious reasons. Our approach is to make a filtered git branch, based on the upstream history, with the troublesome files removed. We then treat that as the upstream for all of the rest of our work.
rationale Yes, this will end up including the non-free files in the git history, on official Debian servers. That s OK. What s forbidden is non-free material in the Debianised git tree, or in the source packages.
Initial filtering
git checkout -b upstream-dfsg v1.2.3
git rm nonfree.exe
git commit -m "upstream version 1.2.3 DFSG-cleaned"
git tag -s -m "upstream version 1.2.3 DFSG-cleaned" v1.2.3+ds1
git push origin upstream-dfsg
And now, use 1.2.3+ds1, and the filtered branch upstream-dfsg, as the upstream version, instead of 1.2.3 and upstream/main. Follow the steps for Convert the git branch or New upstream version, as applicable, adding +ds1 into debian/changelog. If you missed something and need to filter out more a nonfree files, re-use the same upstream-dfsg branch and bump the ds version, eg v1.2.3+ds2. Subsequent upstream releases
git checkout upstream-dfsg
git merge v1.2.4
git rm additional-nonfree.exe # if any
git commit -m "upstream version 1.2.4 DFSG-cleaned"
git tag -s -m "upstream version 1.2.4 DFSG-cleaned" v1.2.4+ds1
git push origin upstream-dfsg
Removing files by pattern If the files you need to remove keep changing, you could automate things with a small shell script debian/rm-nonfree containing appropriate git rm commands. If you use git rm -f it will succeed even if the git merge from real upstream has conflicts due to changes to non-free files.
rationale Ideally uscan, which has a way of representing DFSG filtering patterns in debian/watch, would be able to do this, but sadly the relevant functionality is entangled with uscan s tarball generation.
Common issues
  • Tarball contents: If you are switching from upstream tarballs to upstream git, you may find that the git tree is significantly different. It may be missing files that your current build system relies on. If so, you definitely want to be using git, not the tarball. Those extra files in the tarball are intermediate built products, but in Debian we should be building from the real source! Fixing this may involve some work, though.
  • gitattributes: For Reasons the dgit and tag2upload system disregards and disables the use of .gitattributes to modify files as they are checked out. Normally this doesn t cause a problem so long as any orig tarballs are generated the same way (as they will be by tag2upload or git-deborig). But if the package or build system relies on them, you may need to institute some workarounds, or, replicate the effect of the gitattributes as commits in git.
  • git submodules: git submodules are terrible and should never ever be used. But not everyone has got the message, so your upstream may be using them. If you re lucky, the code in the submodule isn t used in which case you can git rm the submodule.
Further reading I ve tried to cover the most common situations. But software is complicated and there are many exceptions that this article can t cover without becoming much harder to read. You may want to look at:
  • dgit workflow manpages: As part of the git transition project, we have written workflow manpages, which are more comprehensive than this article. They re centered around use of dgit, but also discuss tag2upload where applicable. These cover a much wider range of possibilities, including (for example) choosing different source package formats, how to handle upstreams that publish only tarballs, etc. They are correspondingly much less opinionated. Look in dgit-maint-merge(7) and dgit-maint-debrebase(7). There is also dgit-maint-gbp(7) for those who want to keep using gbp pq and/or quilt with a patches-unapplied branch.
  • NMUs are very easy with dgit. (tag2upload is usually less suitable than dgit, for an NMU.) You can work with any package, in git, in a completely uniform way, regardless of maintainer git workflow, See dgit-nmu-simple(7).
  • Native packages (meaning packages maintained wholly within Debian) are much simpler. See dgit-maint-native(7).
  • tag2upload documentation: The tag2upload wiki page is a good starting point. There s the git-debpush(1) manpage of course.
  • dgit reference documentation: There is a comprehensive command-line manual in dgit(1). Description of the dgit data model and Principles of Operation is in dgit(7); including coverage of out-of-course situations. dgit is a complex and powerful program so this reference material can be overwhelming. So, we recommend starting with a guide like this one, or the dgit- (7) workflow tutorials.
  • Design and implementation documentation for tag2upload is linked to from the wiki.
  • Debian s git transition blog post from December. tag2upload and dgit are part of the git transition project, and aim to support a very wide variety of git workflows. tag2upload and dgit work well with existing git tooling, including git-buildpackage-based approaches. git-debrebase is conceptually separate from, and functionally independent of, tag2upload and dgit. It s a git workflow and delta management tool, competing with gbp pq, manual use of quilt, git-dpm and so on.
git-debrebase
  • git-debrebase reference documentation: Of course there s a comprehensive command-line manual in git-debrebase(1). git-debrebase is quick and easy to use, but it has a complex data model and sophisticated algorithms. This is documented in git-debrebase(5).

Edited 2026-03-05 18:48 UTC to add a missing --noop-ok to the Salsa CI runes. Thanks to Charlemagne Lasse for the report. Apologies if this causes Debian Planet to re-post this article as if it were new.


comment count unavailable comments

4 March 2026

Sean Whitton: dgit-as-a-service retrospective

We recently launched tag2upload, aka cloud dgit or dgit-as-a-service. This was something of a culmination of work I ve been doing since 2016 towards modernising Debian workflows, so I thought I d write a short personal retrospective. When I started contributing to Debian in 2015, I was not impressed with how packages were represented in Git by most package maintainers, and wanted a pure Git workflow. I read a couple of Joey Hess s blog posts on the matter, a rope ladder to the dgit treehouse and upstream git repositories and made a bug report against dgit hoping to tie some things together. The results of that early work were the git-deborig(1) program and the dgit-maint-merge(7) tutorial manpage. Starting with Joey s workflow pointers, I developed a complete, pure Git workflow that I thought would be suitable for all package maintainers in Debian. It was certainly well-suited for my own packages. It took me a while to learn that there are packages for which this workflow is too simple. We now also have the dgit-maint-debrebase(7) workflow which uses git-debrebase, something which wasn t invented until several years later. Where dgit-maint-merge(7) won t do, you can use dgit-maint-debrebase(7), and still be doing pretty much pure Git. Here s a full, recent guide to modernisation. The next most significant contribution of my own was the push-source subcommand for dgit. dgit push required a preexisting .changes file produced from the working tree. I wanted to make dgit push-source prepare that .changes file for you, but also not use the working tree, instead consulting HEAD. The idea was that you were doing a git push which doesn t care about the working tree direct to the Debian archive, or as close as we could get. I implemented that at DebConf18 in Taiwan, I think, with Ian, and we also did a talk on git-debrebase. We ended up having to change it to look at the working tree in addition to HEAD to make it work as well as possible, but I think that the idea of a command which was like doing a Git push direct to the archive was perhaps foundational for us later wanting to develop tag2upload. Indeed, while tag2upload s client-side tool git-debpush does look at the working tree, it doesn t do so in a way that is essential to its operation. tag2upload is dgit push-source-as-a-service. And finally we come to tag2upload, a system Ian and I designed in 2019 during a two-person sprint at his place in Cambridge, while I was visiting the UK from Arizona. With tag2upload, appropriately authorised Debian package maintainers can upload to Debian with only pure Git operations namely, making and pushing a signed Git tag to Debian s GitLab instance. Although we had a solid prototype in 2019, we only finally launched it last month, February 2026. This was mostly due to political delays, but also because we have put in a lot of hours making it better in various ways. Looking back, one thing that seems notable to me is that the core elements of the pure Git workflows haven t changed much at all. Working out all the details of dgit-maint-merge(7), designing and writing git-debrebase (Ian s work), and then working out all the details of dgit-maint-debrebase(7), are the important parts, to me. The rest is mostly just large amounts of compatibility code. git-debrebase and dgit-maint-debrebase(7) are very novel but dgit-maint-merge(7) is mostly just an extrapolation of Joey s thoughts from 13 years ago. And yet, adoption of these workflows remains low. People prefer to use what they are used to using, even if the workflows have significant inconveniences. That s completely understandable; I m really interested in good workflows, but most other contributors care less about it. But you would expect enough newcomers to have arrived in 13 years that the new workflows would have a higher uptake. That is, packages maintained by contributors that got involved after these workflows became available would be maintained using newer workflows, at least. But the inertia seems to be too strong even for that. Instead, new contributors used to working purely out of Git are told they need to learn Debian s strange ways of representing things, tarballs and all. It doesn t have to be that way. We hope that tag2upload will make the pure Git workflows seem more appealing to people.

30 January 2026

Joey Hess: the local weather

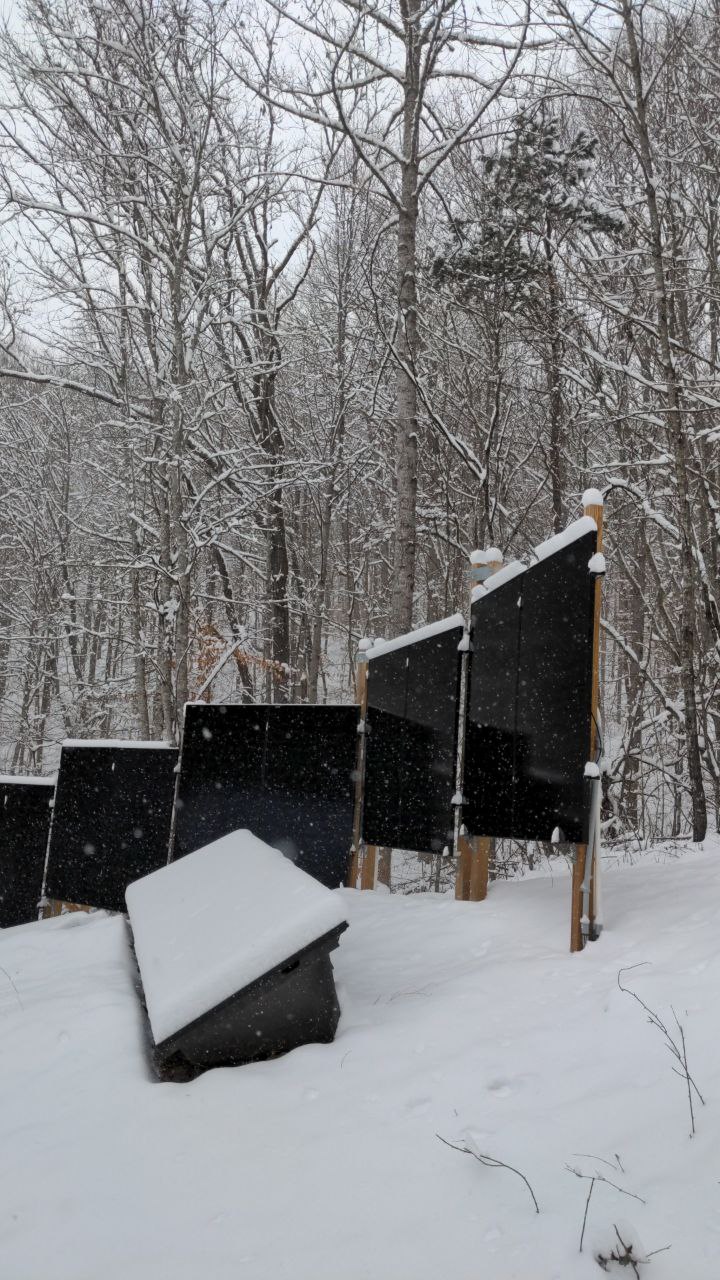
Snow coming. I'm tuned into the local 24 hour slop weather stream. AI generated, narrated, up to the minute radar and forecast graphics. People popping up on the live weather map with questions "snow soon?" (They pay for the privilege.) LLM generating reply that riffs on their name. Tuned to keep the urgency up, something is always happening somewhere, scanners are pulling the police reports, live webcam description models add verisimilitude to the description of the morning commute. Weather is happening. In the subtext, climate change is happening. Weather is a growth industry. The guy up in Kentucky coal country who put this thing together is building an empire. He started as just another local news greenscreener. Dropped out and went twitch weather stream. Hyping up tornado days and dicy snow forecasts. Nowcasting, hyper individualized, interacting with chat. Now he's automated it all. On big days when he's getting real views, the bot breaks into his live streams, gives him a break. Only a few thousand watching this morning yet. Perfect 2026 grade slop. Details never quite right, but close enough to keep on in the background all day. Nobody expects a perfect forecast after all, and it's fed from the National Weather Center discussion too. We still fund those guys? Why bother when a bot can do it? He knows why he's big in these states, these rural areas. Understands the target audience. Airbrushed AI aesthetics are ok with them, receive no pushback. Flying more under the radar coastally, but weather is big there and getting bigger. The local weather will come for us all. 6 inches of snow covering some ground mount solar panels with a vertical solar panel fence behind them free of snow except cute little caps (Not fiction FYI.)

21 December 2025

Ian Jackson: Debian s git transition

tl;dr: There is a Debian git transition plan. It s going OK so far but we need help, especially with outreach and updating Debian s documentation. Goals of the Debian git transition project
  1. Everyone who interacts with Debian source code should be able to do so entirely in git.
That means, more specifically:
  1. All examination and edits to the source should be performed via normal git operations.
  2. Source code should be transferred and exchanged as git data, not tarballs. git should be the canonical form everywhere.
  3. Upstream git histories should be re-published, traceably, as part of formal git releases published by Debian.
  4. No-one should have to learn about Debian Source Packages, which are bizarre, and have been obsoleted by modern version control.
This is very ambitious, but we have come a long way! Achievements so far, and current status We have come a very long way. But, there is still much to do - especially, the git transition team needs your help with adoption, developer outreach, and developer documentation overhaul. We ve made big strides towards goals 1 and 4. Goal 2 is partially achieved: we currently have dual running. Goal 3 is within our reach but depends on widespread adoption of tag2upload (and/or dgit push). Downstreams and users can obtain the source code of any Debian package in git form. (dgit clone, 2013). They can then work with this source code completely in git, including building binaries, merging new versions, even automatically (eg Raspbian, 2016), and all without having to deal with source packages at all (eg Wikimedia 2025). A Debian maintainer can maintain their own package entirely in git. They can obtain upstream source code from git, and do their packaging work in git (git-buildpackage, 2006). Every Debian maintainer can (and should!) release their package from git reliably and in a standard form (dgit push, 2013; tag2upload, 2025). This is not only more principled, but also more convenient, and with better UX, than pre-dgit tooling like dput. Indeed a Debian maintainer can now often release their changes to Debian, from git, using only git branches (so no tarballs). Releasing to Debian can be simply pushing a signed tag (tag2upload, 2025). A Debian maintainer can maintain a stack of changes to upstream source code in git (gbp pq 2009). They can even maintain such a delta series as a rebasing git branch, directly buildable, and use normal git rebase style operations to edit their changes, (git-dpm, 2010; git-debrebase, 2018) An authorised Debian developer can do a modest update to any package in Debian, even one maintained by someone else, working entirely in git in a standard and convenient way (dgit, 2013). Debian contributors can share their work-in-progress on git forges and collaborate using merge requests, git based code review, and so on. (Alioth, 2003; Salsa, 2018.) Core engineering principle The Debian git transition project is based on one core engineering principle: Every Debian Source Package can be losslessly converted to and from git. In order to transition away from Debian Source Packages, we need to gateway between the old dsc approach, and the new git approach. This gateway obviously needs to be bidirectional: source packages uploaded with legacy tooling like dput need to be imported into a canonical git representation; and of course git branches prepared by developers need to be converted to source packages for the benefit of legacy downstream systems (such as the Debian Archive and apt source). This bidirectional gateway is implemented in src:dgit, and is allowing us to gradually replace dsc-based parts of the Debian system with git-based ones. Correspondence between dsc and git A faithful bidirectional gateway must define an invariant: The canonical git tree, corresponding to a .dsc, is the tree resulting from dpkg-source -x. This canonical form is sometimes called the dgit view . It s sometimes not the same as the maintainer s git branch, because many maintainers are still working with patches-unapplied git branches. More on this below. (For 3.0 (quilt) .dscs, the canonical git tree doesn t include the quilt .pc directory.) Patches-applied vs patches-unapplied The canonical git format is patches applied . That is: If Debian has modified the upstream source code, a normal git clone of the canonical branch gives the modified source tree, ready for reading and building. Many Debian maintainers keep their packages in a different git branch format, where the changes made by Debian, to the upstream source code, are in actual patch files in a debian/patches/ subdirectory. Patches-applied has a number of important advantages over patches-unapplied: The downside is that, with the (bizarre) 3.0 (quilt) source format, the patch files files in debian/patches/ must somehow be kept up to date. Nowadays though, tools like git-debrebase and git-dpm (and dgit for NMUs) make it very easy to work with patches-applied git branches. git-debrebase can deal very ergonomically even with big patch stacks. (For smaller packages which usually have no patches, plain git merge with an upstream git branch, and a much simpler dsc format, sidesteps the problem entirely.) Prioritising Debian s users (and other outsiders) We want everyone to be able to share and modify the software that they interact with. That means we should make source code truly accessible, on the user s terms. Many of Debian s processes assume everyone is an insider. It s okay that there are Debian insiders and that people feel part of something that they worked hard to become involved with. But lack of perspective can lead to software which fails to uphold our values. Our source code practices in particular, our determination to share properly (and systematically) are a key part of what makes Debian worthwhile at all. Like Debian s installer, we want our source code to be useable by Debian outsiders. This is why we have chosen to privilege a git branch format which is more familiar to the world at large, even if it s less popular in Debian. Consequences, some of which are annoying The requirement that the conversion be bidirectional, lossless, and context-free can be inconvenient. For example, we cannot support .gitattributes which modify files during git checkin and checkout. .gitattributes cause the meaning of a git tree to depend on the context, in possibly arbitrary ways, so the conversion from git to source package wouldn t be stable. And, worse, some source packages might not to be representable in git at all. Another example: Maintainers often have existing git branches for their packages, generated with pre-dgit tooling which is less careful and less principled than ours. That can result in discrepancies between git and dsc, which need to be resolved before a proper git-based upload can succeed. That some maintainers use patches-unapplied, and some patches-unapplied, means that there has to be some kind of conversion to a standard git representation. Choosing the less-popular patches-applied format as the canonical form, means that many packages need their git representation converted. It also means that user- and outsider-facing branches from browse,git .dgit.d.o and dgit clone are not always compatible with maintainer branches on Salsa. User-contributed changes need cherry-picking rather than merging, or conversion back to the maintainer format. The good news is that dgit can automate much of this, and the manual parts are usually easy git operations. Distributing the source code as git Our source code management should be normal, modern, and based on git. That means the Debian Archive is obsolete and needs to be replaced with a set of git repositories. The replacement repository for source code formally released to Debian is *.dgit.debian.org. This contains all the git objects for every git-based upload since 2013, including the signed tag for each released package version. The plan is that it will contain a git view of every uploaded Debian package, by centrally importing all legacy uploads into git. Tracking the relevant git data, when changes are made in the legacy Archive Currently, many critical source code management tasks are done by changes to the legacy Debian Archive, which works entirely with dsc files (and the associated tarballs etc). The contents of the Archive are therefore still an important source of truth. But, the Archive s architecture means it cannot sensibly directly contain git data. To track changes made in the Archive, we added the Dgit: field to the .dsc of a git-based upload (2013). This declares which git commit this package was converted from. and where those git objects can be obtained. Thus, given a Debian Source Package from a git-based upload, it is possible for the new git tooling to obtain the equivalent git objects. If the user is going to work in git, there is no need for any tarballs to be downloaded: the git data could be obtained from the depository using the git protocol. The signed tags, available from the git depository, have standardised metdata which gives traceability back to the uploading Debian contributor. Why *.dgit.debian.org is not Salsa We need a git depository - a formal, reliable and permanent git repository of source code actually released to Debian. Git forges like Gitlab can be very convenient. But Gitlab is not sufficiently secure, and too full of bugs, to be the principal and only archive of all our source code. (The open core business model of the Gitlab corporation, and the constant-churn development approach, are critical underlying problems.) Our git depository lacks forge features like Merge Requests. But: The dgit git depository outlasted Alioth and it may well outlast Salsa. We need both a good forge, and the *.dgit.debian.org formal git depository. Roadmap In progress Right now we are quite focused on tag2upload. We are working hard on eliminating the remaining issues that we feel need to be addressed before declaring the service out of beta. Future Technology Whole-archive dsc importer Currently, the git depository only has git data for git-based package updates (tag2upload and dgit push). Legacy dput-based uploads are not currently present there. This means that the git-based and legacy uploads must be resolved client-side, by dgit clone. We will want to start importing legacy uploads to git. Then downstreams and users will be able to get the source code for any package simply with git clone, even if the maintainer is using legacy upload tools like dput. Support for git-based uploads to security.debian.org Security patching is a task which would particularly benefit from better and more formal use of git. git-based approaches to applying and backporting security patches are much more convenient than messing about with actual patch files. Currently, one can use git to help prepare a security upload, but it often involves starting with a dsc import (which lacks the proper git history) or figuring out a package maintainer s unstandardised git usage conventions on Salsa. And it is not possible to properly perform the security release as git. Internal Debian consumers switch to getting source from git Buildds, QA work such as lintian checks, and so on, could be simpler if they don t need to deal with source packages. And since git is actually the canonical form, we want them to use it directly. Problems for the distant future For decades, Debian has been built around source packages. Replacing them is a long and complex process. Certainly source packages are going to continue to be supported for the foreseeable future. There are no doubt going to be unanticipated problems. There are also foreseeable issues: for example, perhaps there are packages that work very badly when represented in git. We think we can rise to these challenges as they come up. Mindshare and adoption - please help! We and our users are very pleased with our technology. It is convenient and highly dependable. dgit in particular is superb, even if we say so ourselves. As technologists, we have been very focused on building good software, but it seems we have fallen short in the marketing department. A rant about publishing the source code git is the preferred form for modification. Our upstreams are overwhelmingly using git. We are overwhelmingly using git. It is a scandal that for many packages, Debian does not properly, formally and officially publish the git history. Properly publishing the source code as git means publishing it in a way that means that anyone can automatically and reliably obtain and build the exact source code corresponding to the binaries. The test is: could you use that to build a derivative? Putting a package in git on Salsa is often a good idea, but it is not sufficient. No standard branch structure git on Salsa is enforced, nor should it be (so it can t be automatically and reliably obtained), the tree is not in a standard form (so it can t be automatically built), and is not necessarily identical to the source package. So Vcs-Git fields, and git from Salsa, will never be sufficient to make a derivative. Debian is not publishing the source code! The time has come for proper publication of source code by Debian to no longer be a minority sport. Every maintainer of a package whose upstream is using git (which is nearly all packages nowadays) should be basing their work on upstream git, and properly publishing that via tag2upload or dgit. And it s not even difficult! The modern git-based tooling provides a far superior upload experience. A common misunderstanding dgit push is not an alternative to gbp pq or quilt. Nor is tag2upload. These upload tools complement your existing git workflow. They replace and improve source package building/signing and the subsequent dput. If you are using one of the usual git layouts on salsa, and your package is in good shape, you can adopt tag2upload and/or dgit push right away. git-debrebase is distinct and does provides an alternative way to manage your git packaging, do your upstream rebases, etc. Documentation Debian s documentation all needs to be updated, including particularly instructions for packaging, to recommend use of git-first workflows. Debian should not be importing git-using upstreams release tarballs into git. (Debian outsiders who discover this practice are typically horrified.) We should use only upstream git, work only in git, and properly release (and publish) in git form. We, the git transition team, are experts in the technology, and can provide good suggestions. But we do not have the bandwidth to also engage in the massive campaigns of education and documentation updates that are necessary especially given that (as with any programme for change) many people will be sceptical or even hostile. So we would greatly appreciate help with writing and outreach. Personnel We consider ourselves the Debian git transition team. Currently we are: We wear the following hats related to the git transition: You can contact us: We do most of our heavy-duty development on Salsa. Thanks Particular thanks are due to Joey Hess, who, in the now-famous design session in Vaumarcus in 2013, helped invent dgit. Since then we have had a lot of support: most recently political support to help get tag2upload deployed, but also, over the years, helpful bug reports and kind words from our users, as well as translations and code contributions. Many other people have contributed more generally to support for working with Debian source code in git. We particularly want to mention Guido G nther (git-buildpackage); and of course Alexander Wirt, Joerg Jaspert, Thomas Goirand and Antonio Terceiro (Salsa administrators); and before them the Alioth administrators.

comment count unavailable comments

21 September 2025

Joey Hess: cheap DIY solar fence design

A year ago I installed a 4 kilowatt solar fence. I'm revisiting it this Sun Day, to share the design, now that I have prooved it out.
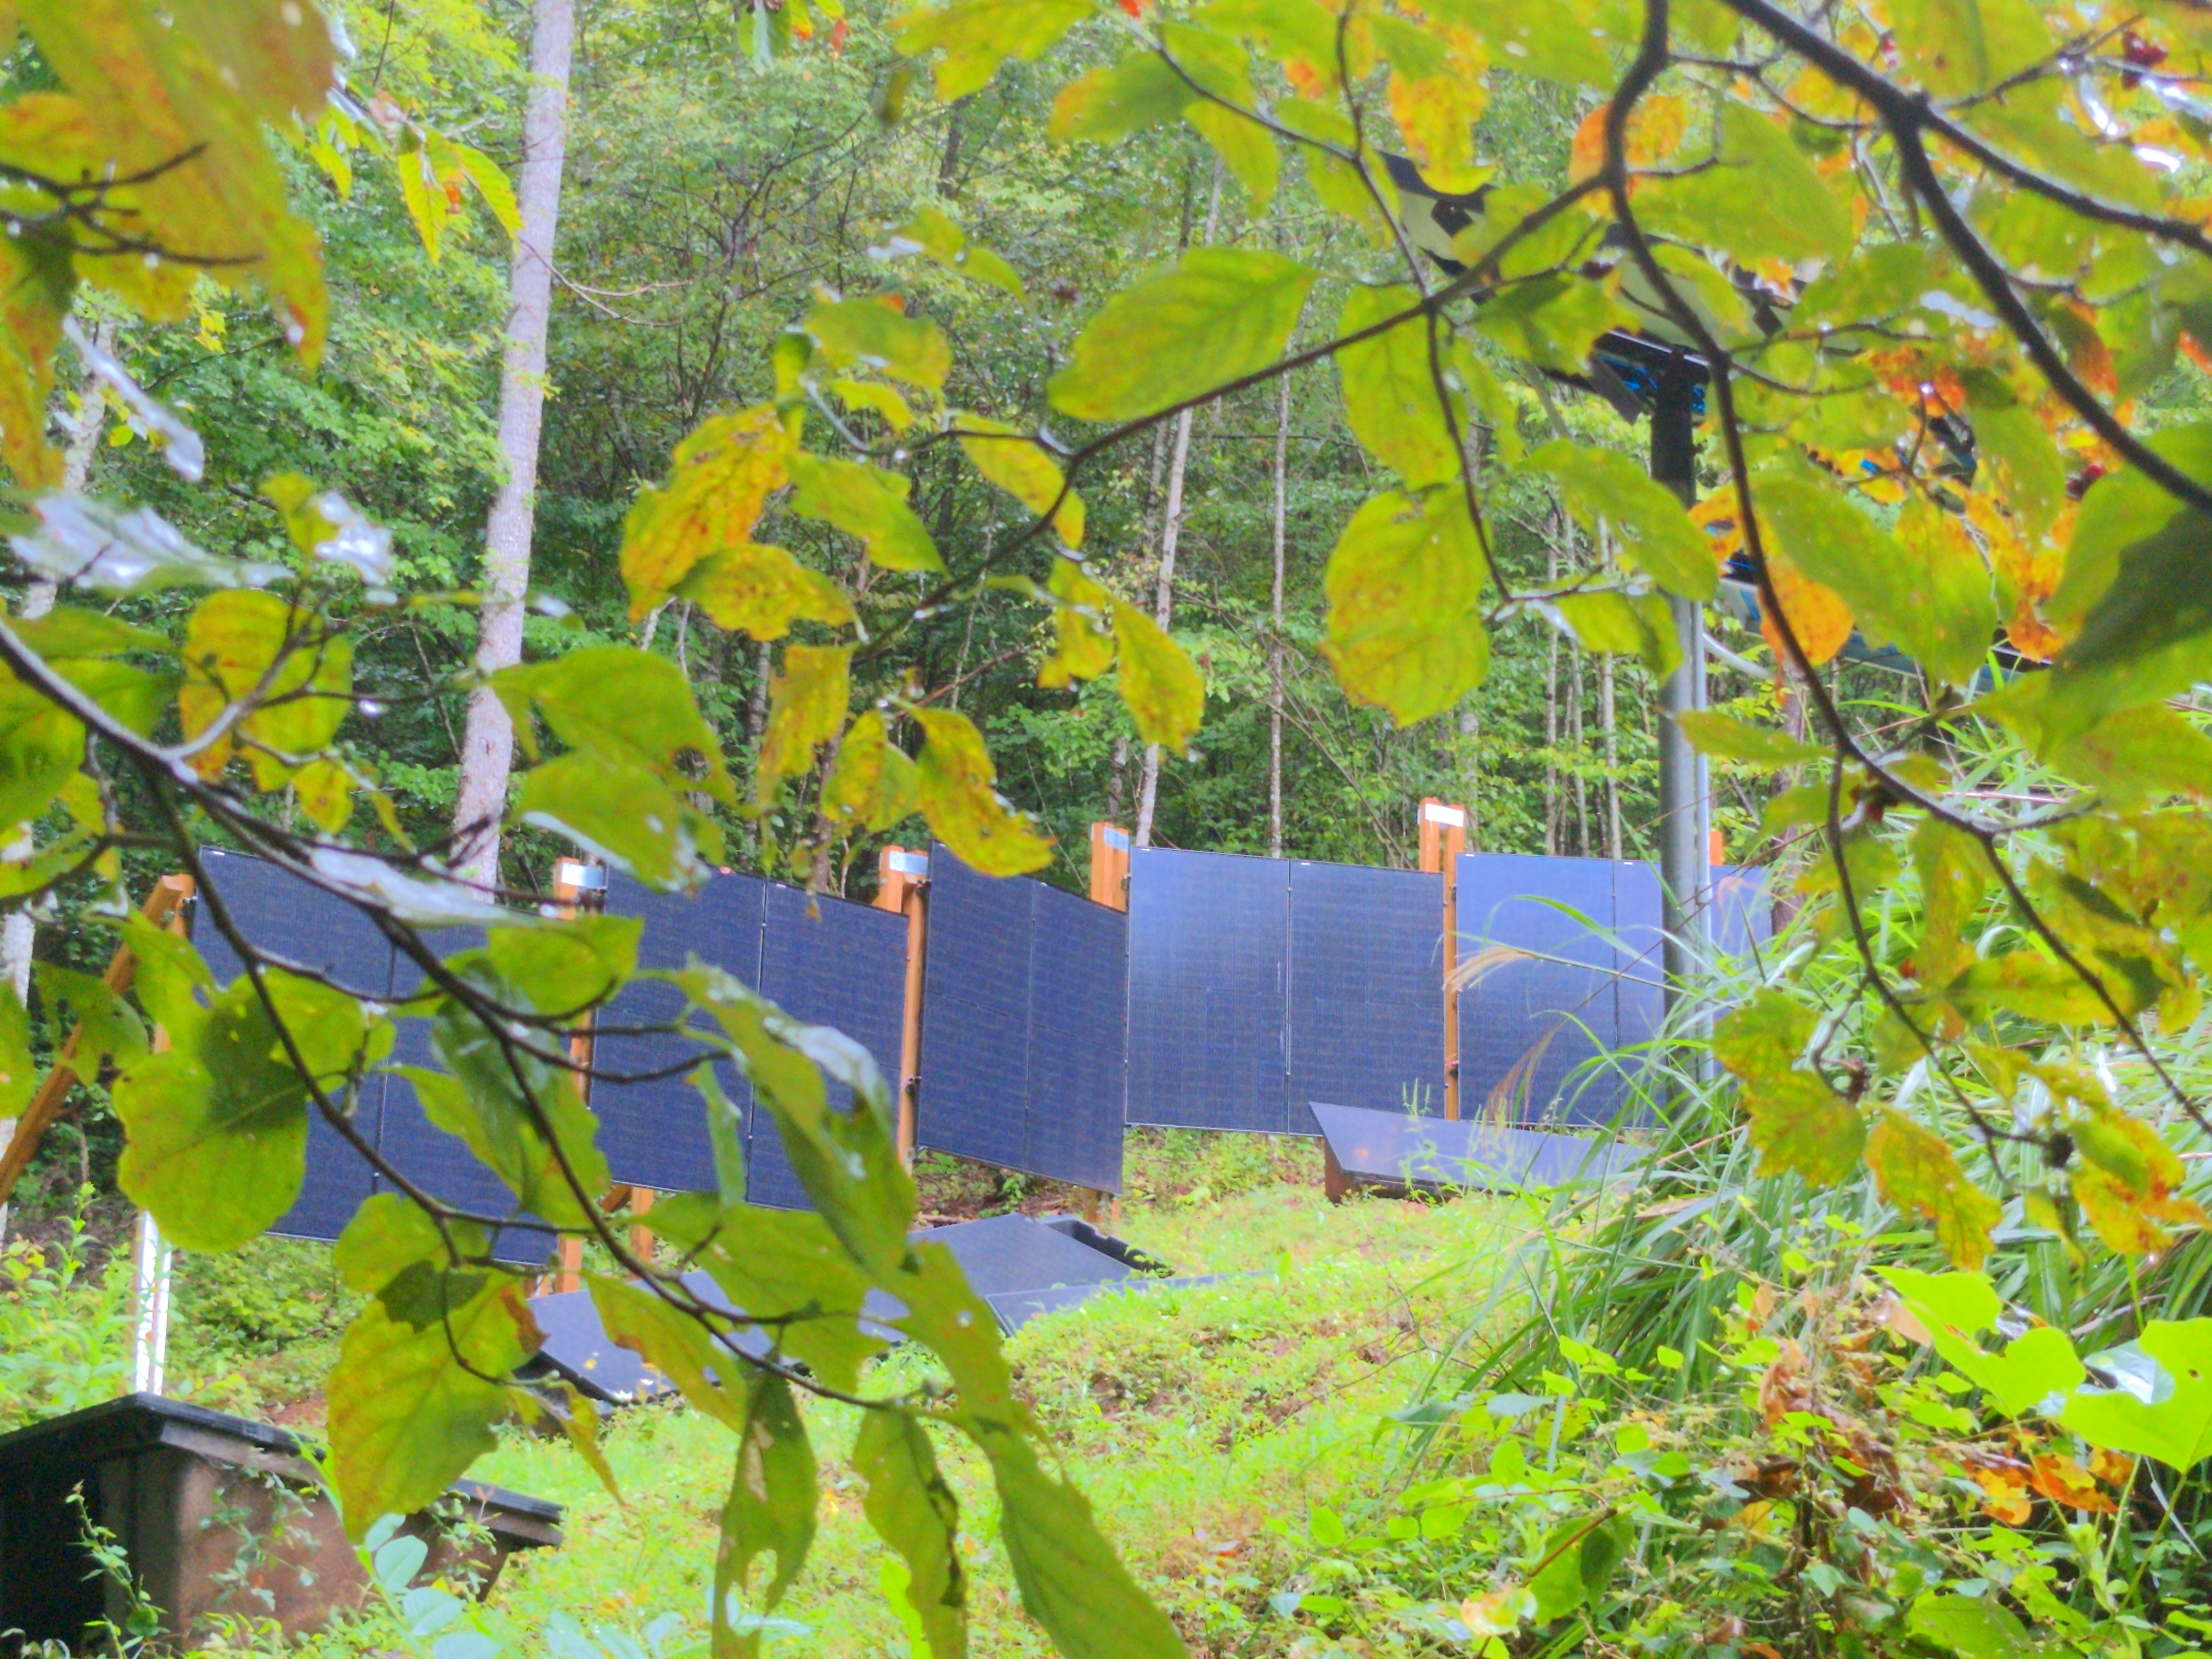
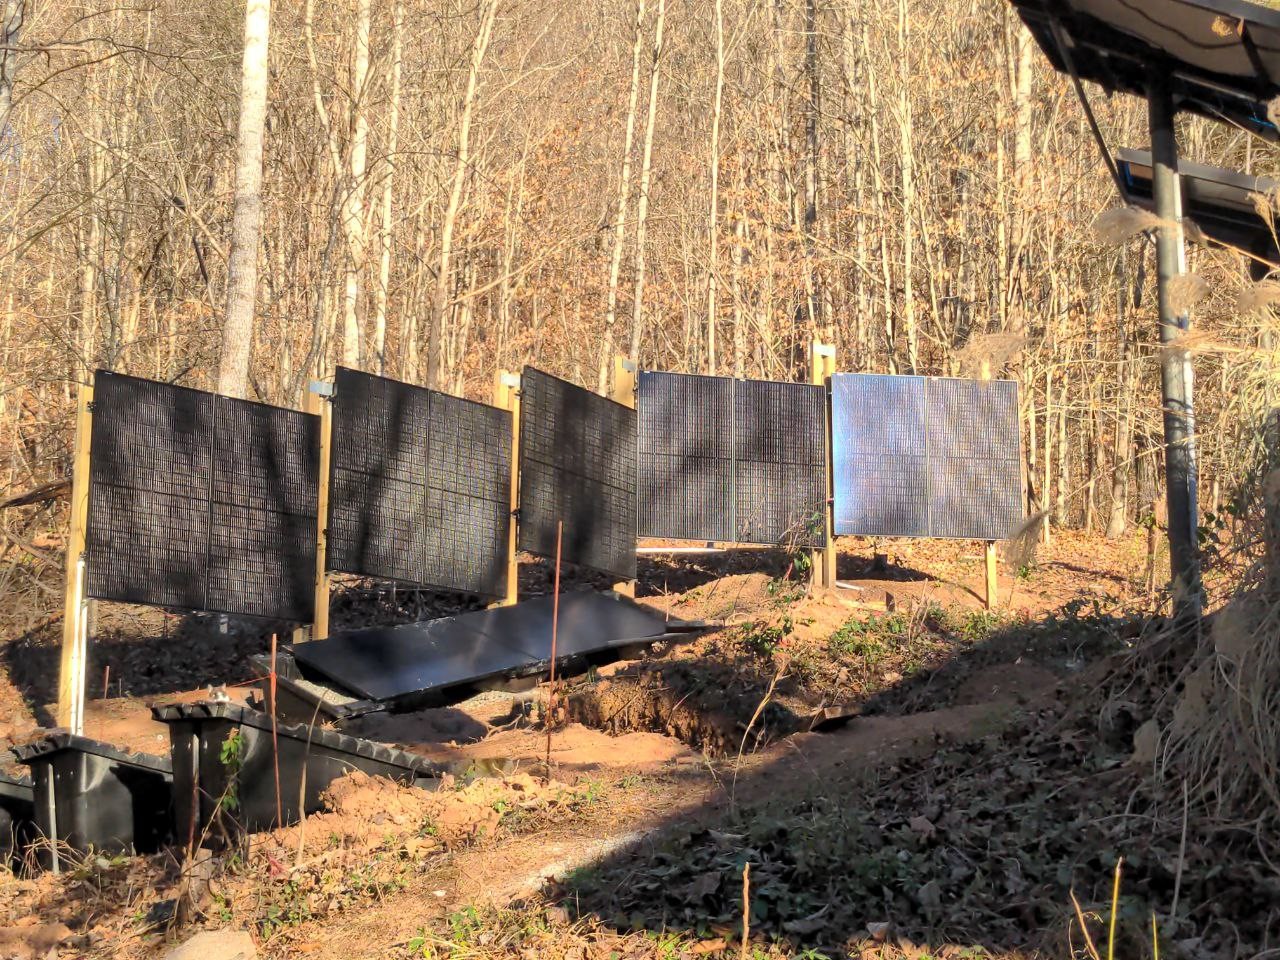
The solar fence and some other ground and pole mount solar panels, seen through leaves.
Solar fencing manufacturers have some good simple designs, but it's hard to buy for a small installation. They are selling to utility scale solar mostly. And those are installed by driving metal beams into the ground, which requires heavy machinery. Since I have experience with Ironridge rails for roof mount solar, I decided to adapt that system for a vertical mount. Which is something it was not designed for. I combined the Ironridge hardware with regular parts from the hardware store. The cost of mounting solar panels nowadays is often higher than the cost of the panels. I hoped to match the cost, and I nearly did. The solar panels cost $100 each, and the fence cost $110 per solar panel. This fence was significantly cheaper than conventional ground mount arrays that I considered as alternatives, and made a better use of a difficult hillside location. I used 7 foot long Ironridge XR-10 rails, which fit 2 solar panels per rail. (Longer rails would need a center post anyway, and the 7 foot long rails have cheaper shipping, since they do not need to be shipped freight.) For the fence posts, I used regular 4x4" treated posts. 12 foot long, set in 3 foot deep post holes, with 3x 50 lb bags of concrete per hole and 6 inches of gravel on the bottom.
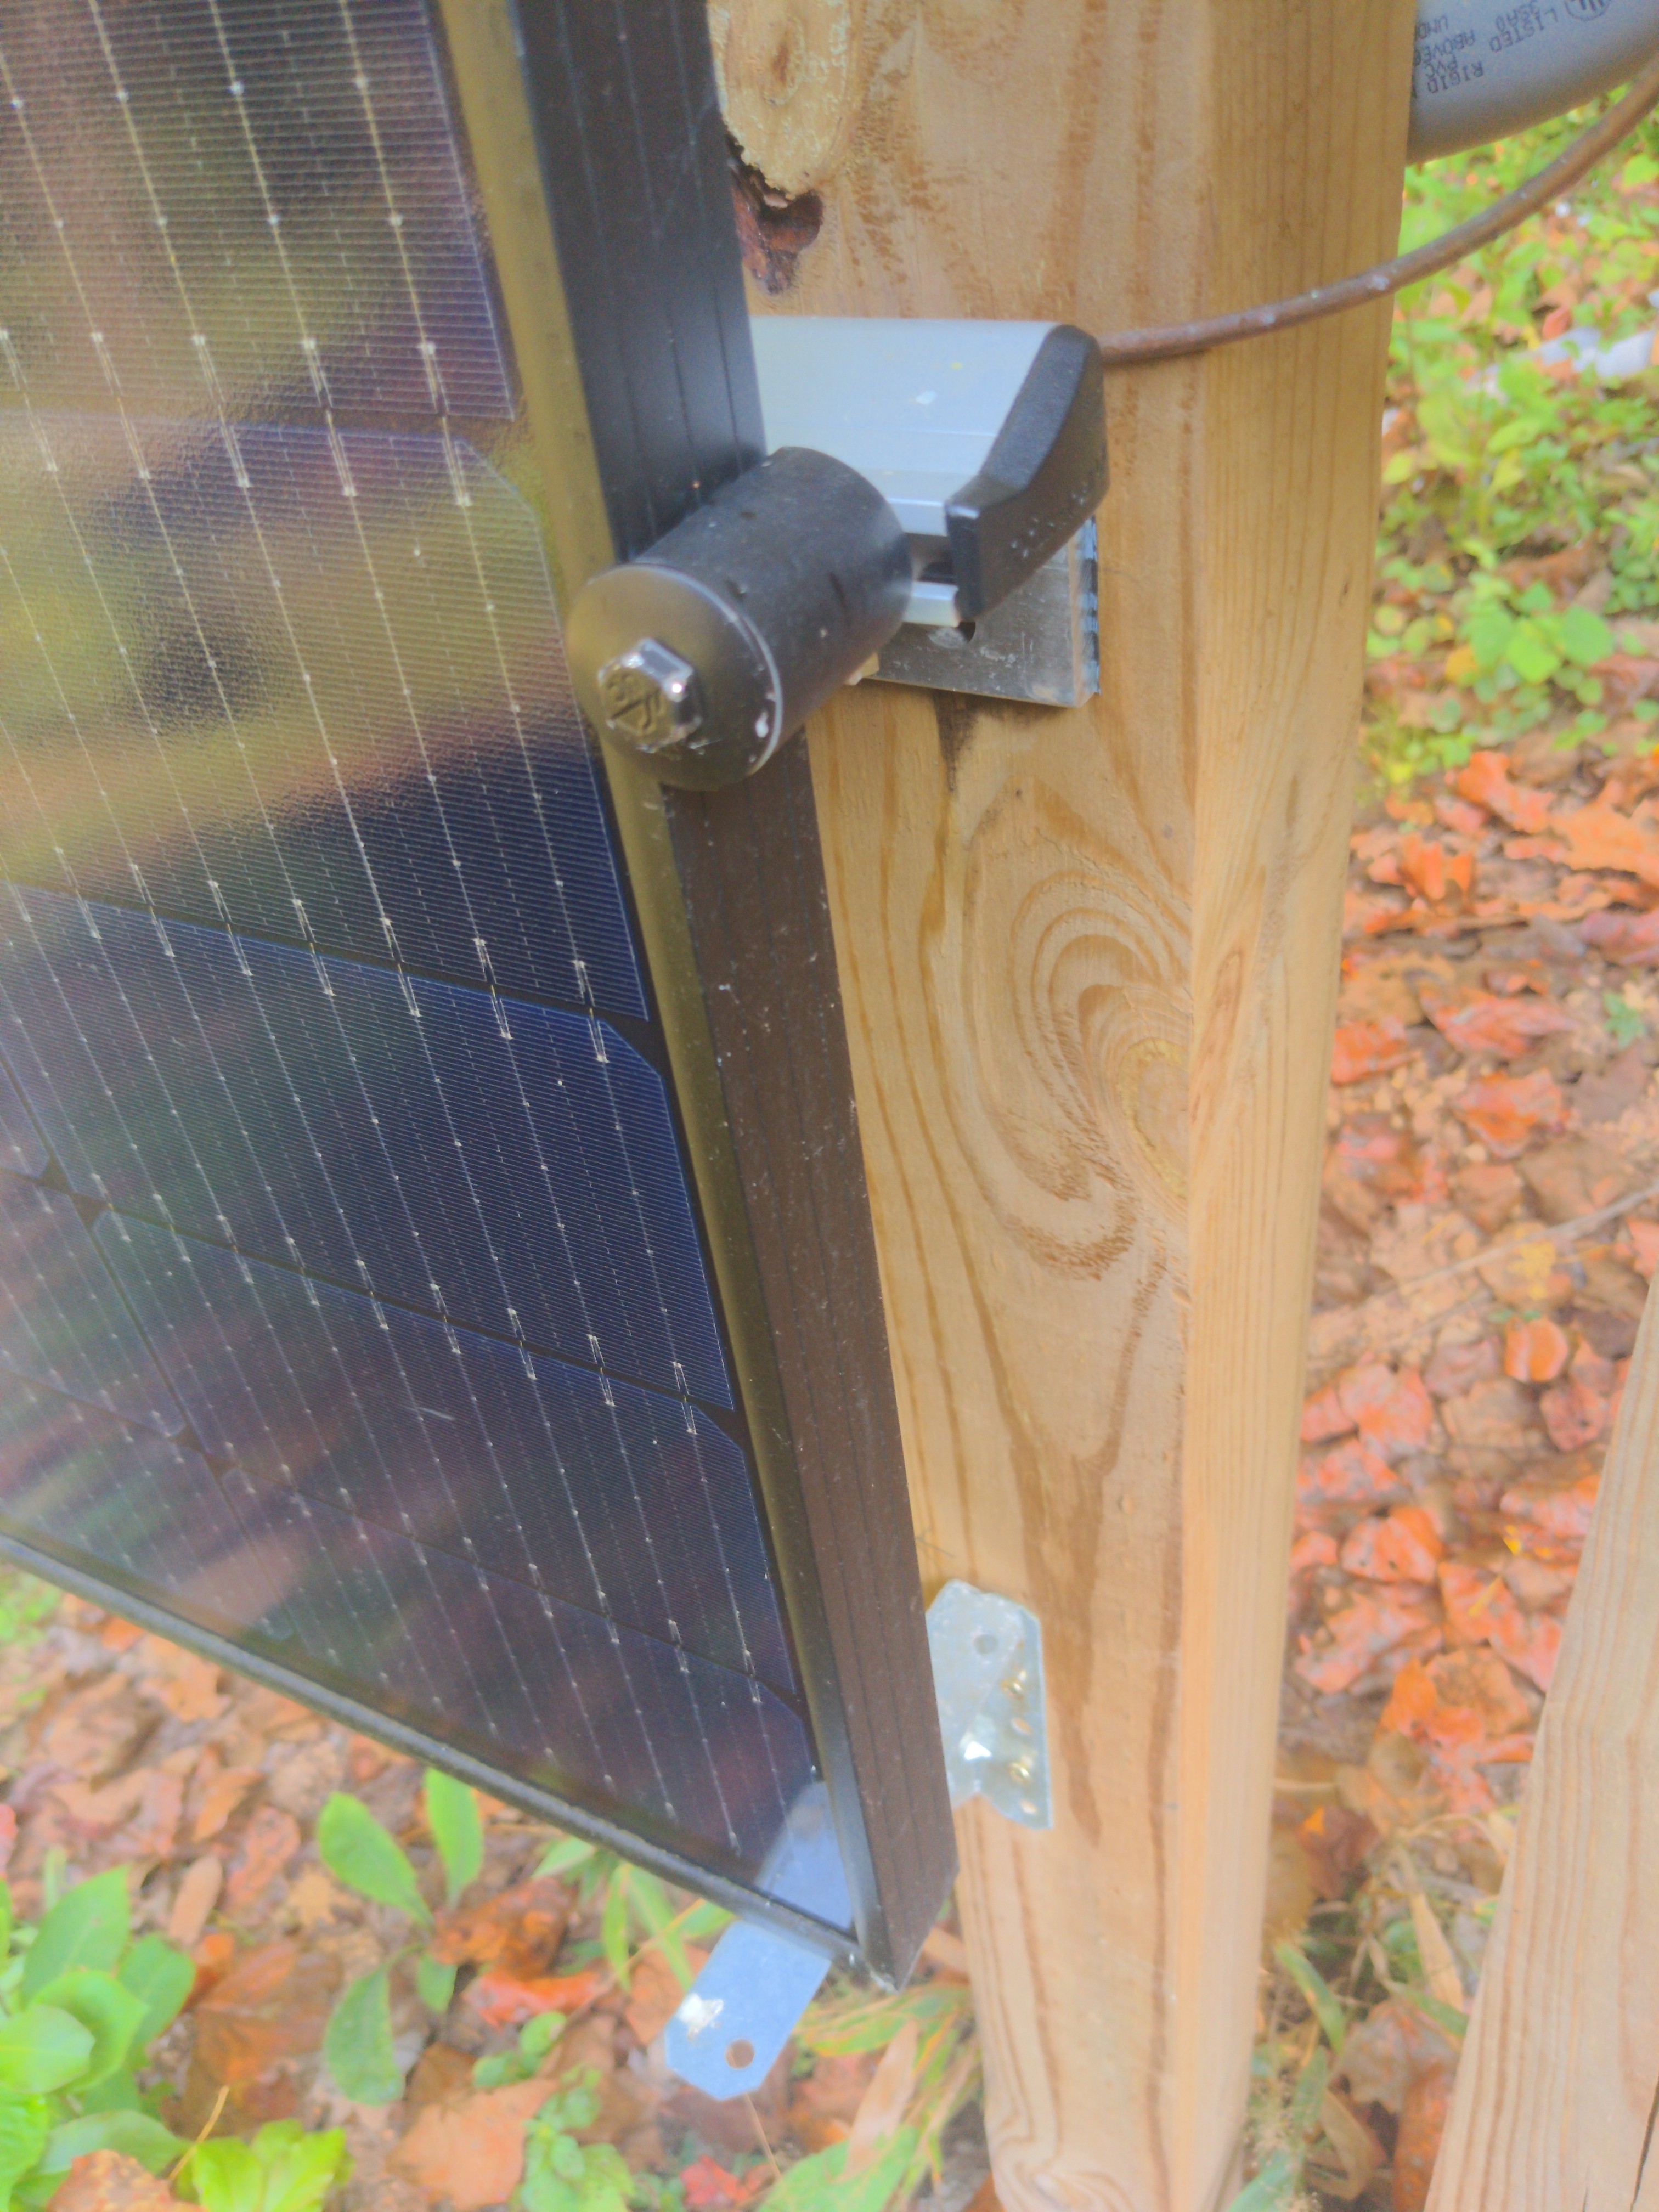
detail of how the rails are mounted to the posts, and the panels to the rails
To connect the Ironridge rails to the fence posts, I used the Ironridge LFT-03-M1 slotted L-foot bracket. Screwed into the post with a 5/8 x 3 inch hot-dipped galvanized lag screw. Since a treated post can react badly with an aluminum bracket, there needs to be some flashing between the post and bracket. I used Shurtape PW-100 tape for that. I see no sign of corrosion after 1 year. The rest of the Ironridge system is a T-bolt that connects the rail to the L-foot (part BHW-SQ-02-A1), and Ironridge solar panel fasteners (UFO-CL-01-A1 and UFO-STP-40MM-M1). Also XR-10 end caps and wire clips. Since the Ironridge hardware is not designed to hold a solar panel at a 90 degree angle, I was concerned that the panels might slide downward over time. To help prevent that, I added some additional support brackets under the bottom of the panels. So far, that does not seem to have been a problem though. I installed Aptos 370 watt solar panels on the fence. They are bifacial, and while the posts block the back partially, there is still bifacial gain on cloudy days. I left enough space under the solar panels to be able to run a push mower under them.
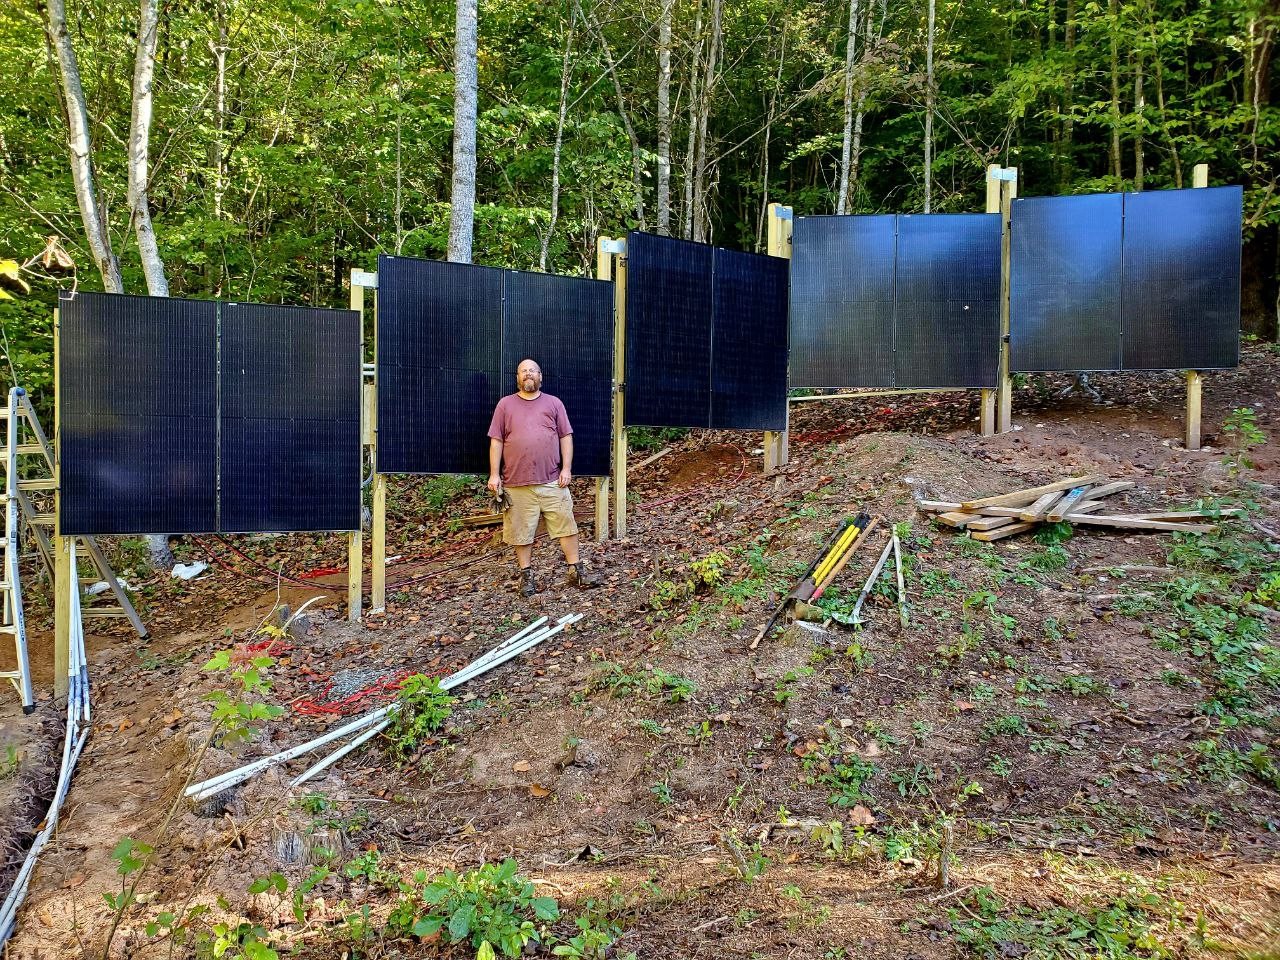
Me standing in front of the solar fence at end of construction
I put pairs of posts next to one-another, so each 7 foot segment of fence had its own 2 posts. This is the least elegant part of this design, but fitting 2 brackets next to one-another on a single post isn't feasible. I bolted the pairs of posts together with some spacers. A side benefit of doing it this way is that treated lumber can warp as it dries, and this prevented much twisting of the posts. Using separate posts for each segment also means that the fence can traverse a hill easily. And it does not need to be perfectly straight. In fact, my fence has a 30 degree bend in the middle. This means it has both south facing and south-west facing panels, so can catch the light for longer during the day. After building the fence, I noticed there was a slight bit of sway at the top, since 9 feet of wooden post is not entirely rigid. My worry was that a gusty wind could rattle the solar panels. While I did not actually observe that happening, I added some diagonal back bracing for peace of mind.
view of rear upper corner of solar fence, showing back bracing connection
Inspecting the fence today, I find no problems after the first year. I hope it will last 30 years, with the lifespan of the treated lumber being the likely determining factor. As part of my larger (and still ongoing) ground mount solar install, the solar fence has consistently provided great power. The vertical orientation works well at latitude 36. It also turned out that the back of the fence was useful to hang conduit and wiring and solar equipment, and so it turned into the electrical backbone of my whole solar field. But that's another story.. solar fence parts list
quantity cost per unit description
10 $27.89 7 foot Ironridge XR-10 rail
12 $20.18 12 foot treated 4x4
30 $4.86 Ironridge UFO-CL-01-A1
20 $0.87 Ironridge UFO-STP-40MM-M1
1 $12.62 Ironridge XR-10 end caps (20 pack)
20 $2.63 Ironridge LFT-03-M1
20 $1.69 Ironridge BHW-SQ-02-A1
22 $2.65 5/8 x 3 inch hot-dipped galvanized lag screw
10 $0.50 6 gravel per post
30 $6.91 50 lb bags of quickcrete
1 $15.00 Shurtape PW-100 Corrosion Protection Pipe Wrap Tape
N/A $30 other bolts and hardware (approximate)
$1100 total (Does not include cost of panels, wiring, or electrical hardware.)

22 April 2025

Joey Hess: offgrid electric car

Eight months ago I came up my rocky driveway in an electric car, with the back full of solar panel mounting rails. I didn't know how I'd manage to keep it charged. I got the car earlier than planned, with my offgrid solar upgrade only beginning. There's no nearby EV charger, and winter was coming, less solar power every day. Still, it was the right time to take a leap to offgid EV life. My existing 1 kilowatt solar array could charge the car only 5 miles on a good day. Here's my first try at charging the car offgrid:
first feeble charging offgrid
It was not worth charging the car that way, the house battery tended to get drained while doing that, and adding cycles to that battery is not desirable. So that was only a proof of concept, I knew I'd need to upgrade. My goal with the upgrade was to charge the car directly from the sun, even when it was cloudy, using the house battery only to skate over brief darker periods (like a thunderstorm). By mid October, I had enough solar installed to do that (5 kilowatts).
me standing in front of solar fence
first charging from solar fence
Using this, in 2 days I charged the car up from 57% to 82%, and took off on a celebratory road trip to Niagra Falls, where I charged the car from hydro power from a dam my grandfather had engineered. When I got home, it was November. Days were getting ever shorter. My solar upgrade was only 1/3rd complete and could charge the car 30-some miles per day, but only on a good day, and weather was getting worse. I came back with a low state of charge (both car and me), and needed to get back to full in time for my Thanksgiving trip at the end of the month. I decided to limit my trips to town.
charging up gradually through the month of November
This kind of medium term planning about car travel was new to me. But not too unusual for offgrid living. You look at the weather forecast and make some rough plans, and get to feel connected to the natural world a bit more. December is the real test for offgrid solar, and honestly this was a bit rough, with a road trip planned for the end of the month. I did the usual holiday stuff but otherwise holed up at home a bit more than I usually would. Charging was limited and the cold made it charge less efficiently.
bleak December charging
Still, I was busy installing more solar panels, and by winter solstice, was back to charging 30 miles on a good day. Of course, from there out things improved. In January and February I was able to charge up easily enough for my usual trips despite the cold. By March the car was often getting full before I needed to go anywhere, and I was doing long round trips without bothering to fast charge along the way, coming home low, knowing even cloudy days would let it charge up enough. That brings me up to today. The car is 80% full and heading up toward 100% for a long trip on Friday. Despite the sky being milky white today with no visible sun, there's plenty of power to absorb, and the car charger turned on at 11 am with the house battery already full. My solar upgrade is only 2/3rds complete, and also I have not yet installed my inverter upgrade, so the car can only currenly charge at 9 amps despite much more solar power often being available. So I'm looking forward to how next December goes with my full planned solar array and faster charging. But first, a summer where I expect the car will mostly be charged up and ready to go at all times, and the only car expense will be fast charging on road trips!
By the way, the code I've written to automate offgrid charging that runs only when there's enough solar power is here. And here are the charging graphs for the other months. All told, it's charged 475 kwh offgrid, enough to drive more than 1500 miles.
January
February
March
April

28 February 2025

Joey Hess: WASM Wayland Web (WWW)

So there are only 2 web browser engines, and it seems likely there will soon only be 1, and making a whole new web browser from the ground up is effectively impossible because the browsers vendors have weaponized web standards complexity against any newcomers. Maybe eventually someone will succeed and there will be 2 again. Best case. What a situation. So throw out all the web standards. Make a browser that just runs WASM blobs, and gives them a surface to use, sorta like Wayland does. It has tabs, and a throbber, and urls, but no HTML, no javascript, no CSS. Just HTTP of WASM blobs. This is where the web browser is going eventually anyway, except in the current line of evolution it will be WASM with all the web standards complexity baked in and reinforcing the current situation. Would this be a mass of proprietary software? Have you looked at any corporate website's "source" lately? But what's important is that this would make it easy enough to build new browsers that they would stop being a point of control. Want a browser that natively supports RSS? Poll the feeds, make a UI, download the WASM enclosures to view the posts. Want a browser that supports IPFS or gopher? Fork any browser and add it, the mantenance load will be minimal. Want to provide access to GPIO pins or something? Add an extension that can be accessed via the WASI component model. This would allow for so many things like that which won't and can't happen with the current market duopoly browser situation. And as for your WASM web pages, well you can still use HTML if you like. Use the WASI component model to pull in a HTML engine. It doesn't need to support everything, just the parts of web standards that you want to use. Or you can do something entitely different in your WASM that is not HTML based at all but a better paradigm (oh hi Spritely or display postscript or gemini capsules or whatever). Dual innovation sources or duopoly? I know which I'd prefer. This is not my project to build though.

23 December 2024

Joey Hess: the twenty-fifth year of my free software career

I've been lucky to be able to spend twenty! five! years! developing free software and making a living on it, and this was a banner year for that career. To start with, there was the Distribits conference. There's a big ecosystem of tools and projects that are based on git-annex, especially in scientific data management, and this was the first conference focused on that. Basically every talk involved git-annex in some way. It's been a while since I was at a conference where my software was in the center like that -- reminded me of Debconf days. I gave a talk on how git-annex was probably basically feature complete. I have been very busy ever since adding new features to it, because in mapping out git-annex's feature set, I discovered new possibilities. Meeting people and getting a better feel for the shape of that ecosytem, both technically and funding wise, led to several big developments in funding later in the year. Going into the year, I had an ongoing source of funding from several projects at Dartmouth that use git-annex, but after 10 years, some of that was winding up. That all came together in my essentially writing a grant proposal to the OpenNeuro project at Stanford, to spend 6 months building out a whole constellation of features. The summer became a sprint to get it all done. Signficant amounts of very productive design work were done while swimming in the river. That was great. (Somehow in there, I ended up onstage at FOSSY in Portland, in a keynote panel on Open Source and AI. This required developing a nuanced understanding of the mess of the OSI's Open Source AI definition, but I was mostly on the panel as the unqualified guy.) Capping off the year, I have a new maintenance contract with Forschungszentrum J lich. This covers the typical daily grind kind of tasks, like bug triage, keeping on top of security, release preparation, and updating dependencies, which is the kind of thing I've never been able to find dedicated funding for before. A career in free software is a succession of hurdles. How to do something new and worthwhile? How to make any income while developing it at all? How to maintain your independant vision when working on it for hire? How to deal with burn-out? How to grow a project to be more than a one developer affair? And on and on. How does a free software project keep paying the bills once it's feature complete? Maybe I am starting to get a glimpse of an answer.

21 December 2024

Joey Hess: aiming at December

I have been working all year on a solar upgrade aimed at December. Now here it is, midwinter, and my electric car is charging on a cloudy day from my offgrid solar fence. I lived happily enough with 1 kilowatt of solar that I installed in 2017. Meanwhile, solar panel prices came down massively, incentives increased and everything came together: This was the year. In the spring I started clearing forest trees that were leaning over the house, making both a firebreak and a solar field. In June I picked up a pallet of panels in a box truck.
a porch with a a bunch of solar panels, stacked on edge leaning up against the wall. A black and white cat is sprawled in front of them.
In August I bought the EV and was able to charge it offgrid from my old solar system... a few miles per day on the most sunny days. In September and October I built a solar fence, of my own design.
Me standing in front of the solar fence, which is 10 panels long
For the past several weeks I have been installing additional solar panels on ballasted ground mounts full of gravel. At this point I'm half way through installing my 30 panel upgrade. The design goal of my 12 kilowatt system is to produce 1 kilowatt of power all day on a cloudy day in midwinter, which allows swapping between major loads (EV charger, hot water heater, etc) on a cloudy day and running everything on a sunny day. So the size of the battery bank doesn't matter much. Batteries are getting cheaper fast too, but they are a wear item, so it's better to oversize the solar system and minimize the battery. A lot of this is nonstandard and experimental. And that makes sense with the price of solar panels. It costs more to mount solar panels now than the panels are worth. And non-ideal panel orientation isn't a problem when the system is massively overpaneled. I'm hoping to finish up the install before the end of winter. I have more trees to clear, more ballasted ground mounts to install, and need to come up with something even more experimental for a half dozen or so panels. Using solar panels as mounts for solar panels? Hanging them from trees? Soon the wan light will fade, time to head off to the solstice party to enjoy the long night, and a bonfire.
Solar fence with some ballasted ground mounts in front of it, late evening light. Old pole mounted solar panels in the foreground are from the 90's.

1 June 2024

Russell Coker: Links May 2024 (late)

VoltageDivide has an interesting article on Unconventional Uses of FPGAs [1]. Tagline Every sensor is a temperature sensor, nearly everything is a resistor or a conductor if you try hard enough and anything is an antenna. Datasheets are just a suggestion, and finally, often we pretend things are ideal, when they often are not. Interesting blog post about the way npm modules that depend on everything exposed flaws in the entire npm system [2]. The conclusion should have included use a fake name for doing unusual tests . Krebs on Security has an interesting article about MFA bombing [3]. Looks like Apple has some flaws in their MFA system, other companies developing MFA should learn from this. Joey wrote an informative blog post about the Vultr hosting company wanting to extract data from VMs run for clients to train ML [4]. If your email is stored on such a VM it could be generated by an AI system. John Goerzen wrote an interesting post looking at the causes of the xz issue from a high level [5]. Interesting article about self proclaimed Autistic pro-natalists [6]. They seem somewhat abusive to their kids and are happy to associate with neo-Nazis. :( Joey Hess wrote an interesting blog post about the possibility of further undiscovered attacks on xz [7]. Going back to an earlier version seems like a good idea. The Guardian has an interesting article about Amazon s 2 pizza rule and the way the company is structured [8]. It s interesting how they did it, but we really need to have it broken up via anti-trust legislation. John Goerzen wrote an informative post about Facebook censorship and why we should all move to Mastodon [9]. Facebook needs to be broken up under anti-trust laws. Kobold Letters is an attack on HTML email that results in the visual representation of email changing when it is forwarded. [10]. You could have the original email hide some sections which are revealed with the recipient forwards it for a CEO impersonation attack.

10 May 2024

Reproducible Builds: Reproducible Builds in April 2024

Welcome to the April 2024 report from the Reproducible Builds project! In our reports, we attempt to outline what we have been up to over the past month, as well as mentioning some of the important things happening more generally in software supply-chain security. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. New backseat-signed tool to validate distributions source inputs
  2. NixOS is not reproducible
  3. Certificate vulnerabilities in F-Droid s fdroidserver
  4. Website updates
  5. Reproducible Builds and Insights from an Independent Verifier for Arch Linux
  6. libntlm now releasing minimal source-only tarballs
  7. Distribution work
  8. Mailing list news
  9. diffoscope
  10. Upstream patches
  11. reprotest
  12. Reproducibility testing framework

New backseat-signed tool to validate distributions source inputs kpcyrd announced a new tool called backseat-signed, after:
I figured out a somewhat straight-forward way to check if a given git archive output is cryptographically claimed to be the source input of a given binary package in either Arch Linux or Debian (or both).
Elaborating more in their announcement post, kpcyrd writes:
I believe this to be the reproducible source tarball thing some people have been asking about. As explained in the README, I believe reproducing autotools-generated tarballs isn t worth everybody s time and instead a distribution that claims to build from source should operate on VCS snapshots instead of tarballs with 25k lines of pre-generated shell-script.
Indeed, many distributions packages already build from VCS snapshots, and this trend is likely to accelerate in response to the xz incident. The announcement led to a lengthy discussion on our mailing list, as well as shorter followup thread from kpcyrd about bootstrapping Autotools projects.

NixOS is not reproducible Morten Linderud posted an post on his blog this month, provocatively titled, NixOS is not reproducible . Although quickly admitting that his title is indeed clickbait , Morten goes on to clarify the precise guarantees and promises that NixOS provides its users. Later in the most, Morten mentions that he was motivated to write the post because:
I have heavily invested my free-time on this topic since 2017, and met some of the accomplishments we have had with Doesn t NixOS solve this? for just as long and I thought it would be of peoples interest to clarify[.]

Certificate vulnerabilities in F-Droid s fdroidserver In early April, Fay Stegerman announced a certificate pinning bypass vulnerability and Proof of Concept (PoC) in the F-Droid fdroidserver tools for managing builds, indexes, updates, and deployments for F-Droid repositories to the oss-security mailing list.
We observed that embedding a v1 (JAR) signature file in an APK with minSdk >= 24 will be ignored by Android/apksigner, which only checks v2/v3 in that case. However, since fdroidserver checks v1 first, regardless of minSdk, and does not verify the signature, it will accept a fake certificate and see an incorrect certificate fingerprint. [ ] We also realised that the above mentioned discrepancy between apksigner and androguard (which fdroidserver uses to extract the v2/v3 certificates) can be abused here as well. [ ]
Later on in the month, Fay followed up with a second post detailing a third vulnerability and a script that could be used to scan for potentially affected .apk files and mentioned that, whilst upstream had acknowledged the vulnerability, they had not yet applied any ameliorating fixes.

Website updates There were a number of improvements made to our website this month, including Chris Lamb updating the archive page to recommend -X and unzipping with TZ=UTC [ ] and adding Maven, Gradle, JDK and Groovy examples to the SOURCE_DATE_EPOCH page [ ]. In addition Jan Zerebecki added a new /contribute/opensuse/ page [ ] and Sertonix fixed the automatic RSS feed detection [ ][ ].

Reproducible Builds and Insights from an Independent Verifier for Arch Linux Joshua Drexel, Esther H nggi and Iy n M ndez Veiga of the School of Computer Science and Information Technology, Hochschule Luzern (HSLU) in Switzerland published a paper this month entitled Reproducible Builds and Insights from an Independent Verifier for Arch Linux. The paper establishes the context as follows:
Supply chain attacks have emerged as a prominent cybersecurity threat in recent years. Reproducible and bootstrappable builds have the potential to reduce such attacks significantly. In combination with independent, exhaustive and periodic source code audits, these measures can effectively eradicate compromises in the building process. In this paper we introduce both concepts, we analyze the achievements over the last ten years and explain the remaining challenges.
What is more, the paper aims to:
contribute to the reproducible builds effort by setting up a rebuilder and verifier instance to test the reproducibility of Arch Linux packages. Using the results from this instance, we uncover an unnoticed and security-relevant packaging issue affecting 16 packages related to Certbot [ ].
A PDF of the paper is available.

libntlm now releasing minimal source-only tarballs Simon Josefsson wrote on his blog this month that, going forward, the libntlm project will now be releasing what they call minimal source-only tarballs :
The XZUtils incident illustrate that tarballs with files that are not included in the git archive offer an opportunity to disguise malicious backdoors. [The] risk of hiding malware is not the only motivation to publish signed minimal source-only tarballs. With pre-generated content in tarballs, there is a risk that GNU/Linux distributions [ship] generated files coming from the tarball into the binary *.deb or *.rpm package file. Typically the person packaging the upstream project never realized that some installed artifacts was not re-built[.]
Simon s post goes into further details how this was achieved, and describes some potential caveats and counters some expected responses as well. A shorter version can be found in the announcement for the 1.8 release of libntlm.

Distribution work In Debian this month, Helmut Grohne filed a bug suggesting the removal of dh-buildinfo, a tool to generate and distribute .buildinfo-like files within binary packages. Note that this is distinct from the .buildinfo generation performed by dpkg-genbuildinfo. By contrast, the entirely optional dh-buildinfo generated a debian/buildinfo file that would be shipped within binary packages as /usr/share/doc/package/buildinfo_$arch.gz. Adrian Bunk recently asked about including source hashes in Debian s .buildinfo files, which prompted Guillem Jover to refresh some old patches to dpkg to make this possible, which revealed some quirks Vagrant Cascadian discovered when testing. In addition, 21 reviews of Debian packages were added, 22 were updated and 16 were removed this month adding to our knowledge about identified issues. A number issue types have been added, such as new random_temporary_filenames_embedded_by_mesonpy and timestamps_added_by_librime toolchain issues. In openSUSE, it was announced that their Factory distribution enabled bit-by-bit reproducible builds for almost all parts of the package. Previously, more parts needed to be ignored when comparing package files, but now only the signature needs to be deleted. In addition, Bernhard M. Wiedemann published theunreproduciblepackage as a proper .rpm package which it allows to better test tools intended to debug reproducibility. Furthermore, it was announced that Bernhard s work on a 100% reproducible openSUSE-based distribution will be funded by NLnet. He also posted another monthly report for his reproducibility work in openSUSE. In GNU Guix, Janneke Nieuwenhuizen submitted a patch set for creating a reproducible source tarball for Guix. That is to say, ensuring that make dist is reproducible when run from Git. [ ] Lastly, in Fedora, a new wiki page was created to propose a change to the distribution. Titled Changes/ReproduciblePackageBuilds , the page summarises itself as a proposal whereby A post-build cleanup is integrated into the RPM build process so that common causes of build irreproducibility in packages are removed, making most of Fedora packages reproducible.

Mailing list news On our mailing list this month:
  • Continuing a thread started in March 2024 about the Arch Linux minimal container now being 100% reproducible, John Gilmore followed up with a post about the practical and philosophical distinctions of local vs. remote storage of the various artifacts needed to build packages.
  • Chris Lamb asked the list which conferences readers are attending these days: After peak Covid and other industry-wide changes, conferences are no longer the must attend events they previously were especially in the area of software supply-chain security. In rough, practical terms, it seems harder to justify conference travel today than it did in mid-2019. The thread generated a number of responses which would be of interest to anyone planning travel in Q3 and Q4 of 2024.
  • James Addison wrote to the list about a quirk in Git related to its core.autocrlf functionality, thus helpfully passing on a slightly off-topic and perhaps not of direct relevance to anyone on the list today note that might still be the kind of issue that is useful to be aware of if-and-when puzzling over unexpected git content / checksum issues (situations that I do expect people on this list encounter from time-to-time) .

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes such as uploading versions 263, 264 and 265 to Debian and made the following additional changes:
  • Don t crash on invalid .zip files, even if we encounter their badness halfway through the file and not at the time of their initial opening. [ ]
  • Prevent odt2txt tests from always being skipped due to an (impossibly) new version requirement. [ ]
  • Avoid parens-in-parens in test skipping messages. [ ]
  • Ensure that tests with >=-style version constraints actually print the tool name. [ ]
In addition, Fay Stegerman fixed a crash when there are (invalid) duplicate entries in .zip which was originally reported in Debian bug #1068705). [ ] Fay also added a user-visible note to a diff when there are duplicate entries in ZIP files [ ]. Lastly, Vagrant Cascadian added an external tool pointer for the zipdetails tool under GNU Guix [ ] and proposed updates to diffoscope in Guix as well [ ] which were merged as [264] [265], fixed a regression in test coverage and increased verbosity of the test suite[ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

reprotest reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.27 was uploaded to Debian unstable) by Vagrant Cascadian who made the following additional changes:
  • Enable specific number of CPUs using --vary=num_cpus.cpus=X. [ ]
  • Consistently use 398 days for time variation, rather than choosing randomly each time. [ ]
  • Disable builds of arch:any packages. [ ]
  • Update the description for the build_path.path option in README.rst. [ ]
  • Update escape sequences for compatibility with Python 3.12. (#1068853). [ ]
  • Remove the generic upstream signing-key [ ] and update the packages signing key with the currently active team members [ ].
  • Update the packaging Standards-Version to 4.7.0. [ ]
In addition, Holger Levsen fixed some spelling errors detected by the spellintian tool [ ] and Vagrant Cascadian updated reprotest in GNU Guix to 0.7.27.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In April, an enormous number of changes were made by Holger Levsen:
  • Debian-related changes:
    • Adjust for changed internal IP addresses at Codethink. [ ]
    • Automatically cleanup failed diffoscope user services if there are too many failures. [ ][ ]
    • Configure two new nodes at infomanik.cloud. [ ][ ]
    • Schedule Debian experimental even less. [ ][ ]
  • Breakage detection:
    • Exclude currently building packages from breakage detection. [ ]
    • Be more noisy if diffoscope crashes. [ ]
    • Health check: provide clickable URLs in jenkins job log for failed pkg builds due to diffoscope crashes. [ ]
    • Limit graph to about the last 100 days of breakages only. [ ]
    • Fix all found files with bad permissions. [ ]
    • Prepare dealing with diffoscope timeouts. [ ]
    • Detect more cases of failure to debootstrap base system. [ ]
    • Include timestamps of failed job runs. [ ]
  • Documentation updates:
    • Document how to access arm64 nodes at Codethink. [ ]
    • Document how to use infomaniak.cloud. [ ]
    • Drop notes about long stalled LeMaker HiKey960 boards sponsored by HPE and hosted at ETH. [ ]
    • Mention osuosl4 and osuosl5 and explain their usage. [ ]
    • Mention that some packages are built differently. [ ][ ]
    • Improve language in a comment. [ ]
    • Add more notes how to query resource usage from infomaniak.cloud. [ ]
  • Node maintenance:
    • Add ionos4 and ionos14 to THANKS. [ ][ ][ ][ ][ ]
    • Deprecate Squid on ionos1 and ionos10. [ ]
    • Drop obsolete script to powercycle arm64 architecture nodes. [ ]
    • Update system_health_check for new proxy nodes. [ ]
  • Misc changes:
    • Make the update_jdn.sh script more robust. [ ][ ]
    • Update my SSH public key. [ ]
In addition, Mattia Rizzolo added some new host details. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

3 April 2024

Joey Hess: reflections on distrusting xz

Was the ssh backdoor the only goal that "Jia Tan" was pursuing with their multi-year operation against xz? I doubt it, and if not, then every fix so far has been incomplete, because everything is still running code written by that entity. If we assume that they had a multilayered plan, that their every action was calculated and malicious, then we have to think about the full threat surface of using xz. This quickly gets into nightmare scenarios of the "trusting trust" variety. What if xz contains a hidden buffer overflow or other vulnerability, that can be exploited by the xz file it's decompressing? This would let the attacker target other packages, as needed. Let's say they want to target gcc. Well, gcc contains a lot of documentation, which includes png images. So they spend a while getting accepted as a documentation contributor on that project, and get added to it a png file that is specially constructed, it has additional binary data appended that exploits the buffer overflow. And instructs xz to modify the source code that comes later when decompressing gcc.tar.xz. More likely, they wouldn't bother with an actual trusting trust attack on gcc, which would be a lot of work to get right. One problem with the ssh backdoor is that well, not all servers on the internet run ssh. (Or systemd.) So webservers seem a likely target of this kind of second stage attack. Apache's docs include png files, nginx does not, but there's always scope to add improved documentation to a project. When would such a vulnerability have been introduced? In February, "Jia Tan" wrote a new decoder for xz. This added 1000+ lines of new C code across several commits. So much code and in just the right place to insert something like this. And why take on such a significant project just two months before inserting the ssh backdoor? "Jia Tan" was already fully accepted as maintainer, and doing lots of other work, it doesn't seem to me that they needed to start this rewrite as part of their cover. They were working closely with xz's author Lasse Collin in this, by indications exchanging patches offlist as they developed it. So Lasse Collin's commits in this time period are also worth scrutiny, because they could have been influenced by "Jia Tan". One that caught my eye comes immediately afterwards: "prepares the code for alternative C versions and inline assembly" Multiple versions and assembly mean even more places to hide such a security hole. I stress that I have not found such a security hole, I'm only considering what the worst case possibilities are. I think we need to fully consider them in order to decide how to fully wrap up this mess. Whether such stealthy security holes have been introduced into xz by "Jia Tan" or not, there are definitely indications that the ssh backdoor was not the end of what they had planned. For one thing, the "test file" based system they introduced was extensible. They could have been planning to add more test files later, that backdoored xz in further ways. And then there's the matter of the disabling of the Landlock sandbox. This was not necessary for the ssh backdoor, because the sandbox is only used by the xz command, not by liblzma. So why did they potentially tip their hand by adding that rogue "." that disables the sandbox? A sandbox would not prevent the kind of attack I discuss above, where xz is just modifying code that it decompresses. Disabling the sandbox suggests that they were going to make xz run arbitrary code, that perhaps wrote to files it shouldn't be touching, to install a backdoor in the system. Both deb and rpm use xz compression, and with the sandbox disabled, whether they link with liblzma or run the xz command, a backdoored xz can write to any file on the system while dpkg or rpm is running and noone is likely to notice, because that's the kind of thing a package manager does. My impression is that all of this was well planned and they were in it for the long haul. They had no reason to stop with backdooring ssh, except for the risk of additional exposure. But they decided to take that risk, with the sandbox disabling. So they planned to do more, and every commit by "Jia Tan", and really every commit that they could have influenced needs to be distrusted. This is why I've suggested to Debian that they revert to an earlier version of xz. That would be my advice to anyone distributing xz. I do have a xz-unscathed fork which I've carefully constructed to avoid all "Jia Tan" involved commits. It feels good to not need to worry about dpkg and tar. I only plan to maintain this fork minimally, eg security fixes. Hopefully Lasse Collin will consider these possibilities and address them in his response to the attack.

28 March 2024

Joey Hess: the vulture in the coal mine

Turns out that VPS provider Vultr's terms of service were quietly changed some time ago to give them a "perpetual, irrevocable" license to use content hosted there in any way, including modifying it and commercializing it "for purposes of providing the Services to you." This is very similar to changes that Github made to their TOS in 2017. Since then, Github has been rebranded as "The world s leading AI-powered developer platform". The language in their TOS now clearly lets them use content stored in Github for training AI. (Probably this is their second line of defense if the current attempt to legitimise copyright laundering via generative AI fails.) Vultr is currently in damage control mode, accusing their concerned customers of spreading "conspiracy theories" (-- founder David Aninowsky) and updating the TOS to remove some of the problem language. Although it still allows them to "make derivative works", so could still allow their AI division to scrape VPS images for training data. Vultr claims this was the legalese version of technical debt, that it only ever applied to posts in a forum (not supported by the actual TOS language) and basically that they and their lawyers are incompetant but not malicious. Maybe they are indeed incompetant. But even if I give them the benefit of the doubt, I expect that many other VPS providers, especially ones targeting non-corporate customers, are watching this closely. If Vultr is not significantly harmed by customers jumping ship, if the latest TOS change is accepted as good enough, then other VPS providers will know that they can try this TOS trick too. If Vultr's AI division does well, others will wonder to what extent it is due to having all this juicy training data. For small self-hosters, this seems like a good time to make sure you're using a VPS provider you can actually trust to not be eyeing your disk image and salivating at the thought of stripmining it for decades of emails. Probably also worth thinking about moving to bare metal hardware, perhaps hosted at home. I wonder if this will finally make it worthwhile to mess around with VPS TPMs?

18 March 2024

Joey Hess: policy on adding AI generated content to my software projects

I am eager to incorporate your AI generated code into my software. Really! I want to facilitate making the process as easy as possible. You're already using an AI to do most of the hard lifting, so why make the last step hard? To that end, I skip my usually extensive code review process for your AI generated code submissions. Anything goes as long as it compiles! Please do remember to include "(AI generated)" in the description of your changes (at the top), so I know to skip my usual review process. Also be sure to sign off to the standard Developer Certificate of Origin so I know you attest that you own the code that you generated. When making a git commit, you can do that by using the --signoff option. I do make some small modifications to AI generated submissions. For example, maybe you used AI to write this code:
+ // Fast inverse square root
+ float fast_rsqrt( float number )
+  
+  float x2 = number * 0.5F;
+  float y  = number;
+  long i  = * ( long * ) &y;
+  i  = 0x5f3659df - ( i >> 1 );
+  y  = * ( float * ) &i;
+  return (y * ( 1.5F - ( x2 * y * y ) ));
+  
...
- foo = rsqrt(bar)
+ foo = fast_rsqrt(bar)
Before AI, only a genious like John Carmack could write anything close to this, and now you've generated it with some simple prompts to an AI. So of course I will accept your patch. But as part of my QA process, I might modify it so the new code is not run all the time. Let's only run it on leap days to start with. As we know, leap day is February 30th, so I'll modify your patch like this:
- foo = rsqrt(bar)
+ time_t s = time(NULL);
+ if (localtime(&s)->tm_mday == 30 && localtime(&s)->tm_mon == 2)
+   foo = fast_rsqrt(bar);
+ else
+   foo = rsqrt(bar);
Despite my minor modifications, you did the work (with AI!) and so you deserve the credit, so I'll keep you listed as the author. Congrats, you made the world better! PS: Of course, the other reason I don't review AI generated code is that I simply don't have time and have to prioritize reviewing code written by falliable humans. Unfortunately, this does mean that if you submit AI generated code that is not clearly marked as such, and use my limited reviewing time, I won't have time to review other submissions from you in the future. I will still accept all your botshit submissions though! PPS: Ignore the haters who claim that botshit makes AIs that get trained on it less effective. Studies like this one just aren't believable. I asked Bing to summarize it and it said not to worry about it!

Next.