With 26.10 in Feature Freeze, wore my Release team hat to:
Review and approve a bunch of Feature Freeze Exceptions, including the Go 1.27 transition, Qt 6.11.2, rust-coreutils 0.12.0, devscripts 2.6.12, kdump-tools moving to dracut, and a few GCE packages.
Point linux-entra-sso to the SRU team, as it didn t need an FFe at all, and milestone a couple of bugs for 26.10.
Continued to push for infrastructure improvements:
Made ubuntu-cdimage more resilient to Launchpad hiccups (MP).
Taught generate-freeze-block in ubuntu-archive-tools a couple of new options (--skip-update and --series) and better error handling (MP).
Bumped the arm64 generic non-cloud image to 4.5G in livecd-rootfs and uploaded it as 26.10.16; also sponsored the follow-up 26.10.17 for Chlo .
Reviewed quite a lot of MPs - britney hints, meta-release, ubuntu-release-tools, ubuntu-archive-tools, ubuntu-cdimage, livecd-rootfs, ubuntu-seeds, and so on.
Did Archive Admin, DMB, and Release team duties as usual.
Debian (E)LTS
This month I have worked 33.5 hours
on Debian Long Term Support (LTS)
and on its sister Extended LTS
project and did the following things:
(A quick note that I did quite a lot of the work during my work as Frontdesk that went on till 4th Oct, so 33.50 hours include the work I did till 4th October 2026.)
Released Security Updates
node-lodash: Prototype pollution in _.unset and _.omit (plus a bypass of the initial fix for it), and code injection via the imports option of _.template.
This is the bookworm follow-up to DLA 4663-1 that I carried over from July. The update had been sitting prepared and tested on debusine, so once the upstream discussion wrapped up, it went straight out. It also carries an extra patch to the lodash-cli dependency map - without it, the regenerated lodash.template module throws assignWith is not defined at runtime, which node-gulp-util s autopkgtest caught.
libpng1.6: Use-after-free of zlib input in png_read_end() after incomplete zTXt, iTXt, or iCCP decompression, which could result in denial of service.
I picked this one up whilst on front desk; the upstream fix that went into trixie via DSA 6537-1 applied to 1.6.39 as-is.
Work in Progress
libpng1.6: The same CVE-2026-46675.
[ELTS]: Claimed in ela-needed; the same upstream fix applies to all three ELTS suites, so this should go out shortly.
Other Activities
[E/LTS] Did my front-desk week from 28-09 to 04-10.
Over the week I did roughly:
Triage of 524 unique CVEs across 192 source packages and all four suites. And 1 automated ELTS end-of-life sweep.
Additional data is now part of the front-desk job too, so 75 commits record it for 179 CVEs across 71 packages.
Newly queued 22 source packages - 13 in dla-needed (apache2, chromium, firefox-esr, libnet-idn-encode-perl, libpng1.6, node-shell-quote, nvidia-graphics-drivers, openssl, pcre2, php-mongodb, php8.2, social-auth-core, and wpa) and 16 in ela-needed (apache2, firefox-esr, gegl, lemonldap-ng, libnet-idn-encode-perl, libpng1.6, libwebsockets, nsd, nvidia-graphics-drivers, pcre2, php7.0, php7.3, php7.4, rar, unrar-nonfree, and wpa), 7 of them in both. Also widened 3 ELTS entries to bullseye - antiword, ocaml, and openvswitch.
Most of the interesting work was again in the <not-affected> verdicts: 217 of 263 (83%, across 57 packages) rest on showing that the vulnerable code or feature isn t in the source we ship. Another 17 cover incomplete upstream fixes that we either never shipped or shipped with the follow-up already in (expat, libxml2, node-tar, and pyjwt). 15 come from bundled components we don t ship - node-ajv again, which uses uri-js and not fast-uri, and nvidia-open, which doesn t ship the NGX updater. And 13 are vendor- or platform-specific - openssh s CVE-2026-55654 lives only in a Red Hat GSSAPI patch, and the netdata and PHP ones only affect Windows.
Did 4 rounds of newly supported bullseye packages (33 packages overall), plus libmail-mboxparser-perl for buster - 34 in all. The existing CVE data mostly held up; the real finds were discovery gaps. One interesting gotcha: sid renamed stunnel4 to stunnel, and two new CVEs were associated only with the new name, so they never showed up for trixie, bookworm, or any ELTS suite. I also sorted the 180 Triage needed entries (57 packages) from elts-eol by where each was already handled, and triaged for ELTS the 100 that trixie or bookworm had already decided; the rest come next. And I imported 79 package-level lines for the older source names ELTS still ships (tomcat8, php7.0/7.3/7.4, netty-3.9, openssl1.0, python2.7/3.5/3.7, and pypy).
Caught some inconsistencies in released advisories: DLA 4801-1 (swift) was missing a CVE, ELA 1831-1 (redis) listed the wrong one, and DLA 4808-1 (network-manager-l2tp) listed CVE-2026-75883 - an ID that was renamed and then reassigned to an unrelated ppp issue. I fixed all three in the tracker s advisory lists.
Made the Security team and the uploaders aware of regressions from our own updates:
libde265: the CVE-2026-49337 fix in DLA 4789-1/ELA 1828-1 (and DSA 6413-1) misses upstream s follow-up commit.
libxml2 CVE-2026-76781 and policykit-1 CVE-2026-85498 were introduced by our own back-ports; the policykit-1 one is harmless.
expat: the CVE-2025-59375 backport in DLA 4807-1 is compiled out, because XML_GE is never defined.
xen: DLA 4818-1 s XSA-491 fix makes XSA-510 reachable.
gegl: the CVE-2026-2049/2050 back-port in ELA 1650-1 rejects valid RLE .hdr files.
log4cxx: DLA 4322-1 broke UTF-8 in JSONLayout output. That one is functional, not security.
Helped correct a set of triages and let the Debian Security team know:
ruby-json CVE-2026-71847: the vulnerable code was never in a released Debian version.
openssh CVE-2026-55654: only affects a Red Hat-specific GSSAPI patch.
three libxml2 issues that don t affect trixie either.
the stunnel4 rename above.
trixie <no-dsa> lines on jsch, node-qs, and ruby-loofah, where trixie s version doesn t have the vulnerable feature at all.
Independently found a security issue in rclone and reported it privately upstream through a GitHub security advisory. Upstream already had a report for the same issue, so they folded mine into the existing advisory and credited me as a co-reporter.
Also found some bugs in the additional-data tooling, e.g. cve-ad --package P --severity tbd wipes the CVE-level severity, and the schema doesn t validate package-level entries at all.
[E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
Here s my monthly but brief update about the activities I ve done in the FOSS world.
Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
Leading the DebConf Bursary team along with PEB.
This took most of my Debian time this month but we ve been able to wrap that work now.
Got back to all the tickets on Zammad, too.
Assisted a few folks in getting their patches submitted via Salsa.
Mentoring for newcomers.
Moderation of -project mailing list.
Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021.
Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
Continued to push for infrastructure improvements:
[LTS] Emilio pointed out that the gst-plugins-ugly1.0 binaries were still not fully released, so I ran dcut migrate to fully release them. The DLA had gone out earlier.
[ELTS] Did some more work on ruby-rack - a lot of new CVEs have opened up and, whilst I made some progress, Santiago let me know that ruby-rack is no longer supported and so it ll be removed from the ela-needed list.
[E/LTS] Set up the security-tracker and a few other things on the new machine, and debugged the git repository size madness. Sent a summary here.
[E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
Activity summary
During the month of January, 20 contributors have been
paid to work on Debian LTS (links to individual
contributor reports are located below).
The team released 33 DLAs
fixing 216 CVEs.
The team continued preparing security updates in its usual rhythm. Beyond the
updates targeting Debian 11 ( bullseye ), which is the current release under LTS,
the team also proposed updates for more recent releases (Debian 12 ( bookworm )
and Debian 13 ( trixie )), including Debian unstable. We highlight several notable
security updates here below.
Notable security updates:
python3.9, prepared by Andrej Shadura
(DLA-4455-1),
fixing multiple vulnerabilities in the Python interpreter.
php, prepared by Guilhem Moulin
(DLA-4447-1),
fixing two vulnerabilities that could yield to request forgery or denial of
service.
apache2, prepared by Bastien Roucari s
DLA-4452-1, fixing
four CVEs.
linux-6.1, prepared by Ben Hutchings
(DLA-4436-1), as a
regular update of the linux 6.1 backport to Debian 11.
python-django, prepared by Chris Lamb
(DLA-4458-1),
resolving multiple vulnerabilities.
firefox-esr prepared by Emilio Pozuelo Monfort
(DLA-4439-1)
gnupg2, prepared by Roberto S nchez
(DLA-4437-1),
fixing multiple issues, including
CVE-2025-68973
that could potentially be exploited to execute arbitrary code.
apache-log4j2, prepared by Markus Koschany
(DLA-4444-1)
inetutils, prepared by Andreas Henriksson
(DLA-4453-1),
fixing an authentication bypass in telnetd.
Moreover, Sylvain Beucler studied the security support status of p7zip, a fork
of 7zip that has become unmaintained upstream. To avoid letting the users
continue using an unsupported package, Sylvain has investigated a path forward
in collaboration with the security team and the 7zip maintainer, looking to
replace p7zip with 7zip. It is to note however that 7zip developers don t
reveal the information about the patches that fix CVEs, making it difficult
to backport single patches to fix vulnerabilities in Debian released versions.
Contributions from outside the LTS Team:
Thunderbird, prepared by maintainer Christoph Goehre. The DLA
(DLA-4442-1) was
published by Emilio.
The LTS Team has also contributed with updates to the latest Debian releases:
Bastien uploaded gpsd to
unstable,
and proposed updates for trixie #1126121
and bookworm #1126168 to fix two CVEs.
Bastien also prepared the imagemagick updates for trixie and bookworm,
released as
DSA-6111-1, along
with the bullseye update
DLA-4448-1.
Chris proposed a trixie point update for python-django
(#112646), and the work for bookworm was
completed in February (#1079454). The
longstanding bookworm update required tracking down a regression in the
django-storages packages.
Markus prepared tomcat10 updates for trixie and bookworm
(DSA-6120-1), and
tomcat11 for trixie
(DSA-6121-1)
Thorsten Alteholz prepared bookworm point updates for zvbi
(#1126167) to
fix five CVEs; taglib
(#1126273) to fix
one CVE; and libuev
(#1126370) to fix
one CVE.
Utkarsh prepared an unstable update of
node-lodash
to fix one CVE.
Other than the work related to updates, Sylvain made several improvements to
the documentation and tooling used by the team.
Here s my monthly but brief update about the activities I ve done in the FOSS world.
Debian
Whilst I didn t get a chance to do much, here are still a few things that I worked on:
A few discussions with the new DFSG team, et al.
Assited a few folks in getting their patches submitted via Salsa.
Reviewing pyenv MR for Ujjwal.
Mentoring for newcomers.
Moderation of -project mailing list.
Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021.
Whilst I can t give a full, detailed list of things I did, here s a quick TL;DR of what I did:
ruby-rack: There were multiple vulnerabilities reported in Rack, leading to DoS (memory exhaustion) and proxy bypass.
[ELTS]: After completing the work for LTS myself, Bastien picked it up for ELTS and reached out about an upstream regression and we ve been doing some exchanges. Bastien has done most of the work backporting the patches but needs a review and help backporting CVE-2025-61771. Haven t made much progress since last month and will carry it over.
node-lodash: Affected by CVE-2025-13465, lrototype pollution in baseUnset function.
[stable]: The patch for trixie and bookworm are ready but haven t been uploaded yet as I d like for the unstable upload to settle a bit before I proceed with stable uploads.
[LTS]: The bullseye upload will follow once the stable uploads are in and ACK d by the SRMs.
xrdp: Affected by CVE-2025-68670, leading to a stack-based buffer overflow.
[ELTS] Helped Bastien Roucaries debug a tomcat9 regression for buster.
I spent quite a lot of time trying to help Bastien (with Markus and Santiago involved via mail thread) by reproducing the regression that the user(s) reported.
I also helped suggest a path forward by vendoring everything, which I was then requested to also help perform.
Whilst doing that, I noticed circular dependency hellhole and suggested another path forward by backporting bnd and its dependencies as separate NEW packages.
Bastien liked the idea and is going to work on that but preferred to revert the update to remedy the immediate regressions reported. I further helped him in reviewing his update. This conversation happened on #debian-elts IRC channel.
[LTS] Assisted Ben Hutchings with his question about the next possible steps with a plausible libvirt regression caused by the Linux kernel update. This was a thread on debian-lts@ mailing list.
[LTS] Attended the monthly LTS meeting on IRC. Summary here.
[E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
Part
2: Taming the Beast Deep Dive into the Proxy-Aware GPU Initialization
Action
In Part 1 of this series, we laid the network foundation for running
secure Dataproc clusters. Now, let s zoom in on the core component
responsible for installing and configuring NVIDIA GPU drivers and the
associated ML stack in this restricted environment: the install_gpu_driver.sh script from the LLC-Technologies-Collier/initialization-actions
repository (branch gpu-202601).
This isn t just any installation script; it has been significantly
enhanced to handle the nuances of Secure Boot and to operate seamlessly
behind an HTTP/S proxy.
The
Challenge: Installing GPU Drivers Without Direct Internet
Our goal was to create a Dataproc custom image with NVIDIA GPU
drivers, sign the kernel modules for Secure Boot, and ensure the entire
process works seamlessly when the build VM and the eventual cluster
nodes have no direct internet access, relying solely on an HTTP/S proxy.
This involved:
Proxy-Aware Build: Ensuring all build steps within
the custom image creation process (package downloads, driver downloads,
GPG keys, etc.) correctly use the customer s proxy.
Secure Boot Signing: Integrating kernel module
signing using keys managed in GCP Secret Manager, especially when
drivers are built from source.
Conda Environment: Reliably and speedily installing
a complex Conda environment with PyTorch, TensorFlow, Rapids, and other
GPU-accelerated libraries through the proxy.
Dataproc Integration: Making sure the custom image
works correctly with Dataproc s own startup, agent processes, and
cluster-specific configurations like YARN.
The
Development Journey: Key Enhancements in install_gpu_driver.sh
To address these challenges, the script incorporates several key
features:
Robust Proxy Handling (set_proxy
function):
Challenge: Initial script versions had spotty proxy
support. Many tools like apt, curl, gpg, and even gsutil failed in proxy-only
environments.
Enhancements: The set_proxy function
(also used in gce-proxy-setup.sh) was completely overhauled
to parse various proxy metadata (http-proxy, https-proxy, proxy-uri, no-proxy). Critically, environment variables
(HTTP_PROXY, HTTPS_PROXY, NO_PROXY) are now set before any network
operations. NO_PROXY is carefully set to include .google.com and .googleapis.com to allow
direct access to Google APIs via Private Google Access. System-wide
trust stores (OS, Java, Conda) are updated with the proxy s CA
certificate if provided via http-proxy-pem-uri. gcloud, apt, dnf, and dirmngr are also configured to use the proxy.
Challenge: Importing GPG keys for repositories
often failed as keyservers use non-HTTP ports (e.g., 11371) blocked by
firewalls, and gpg --recv-keys is not proxy-friendly.
Solution: A new import_gpg_keys
function now fetches keys over HTTPS using curl, which
respects the environment s proxy settings. This replaced all direct gpg --recv-keys calls.
GCS Caching is King:
Challenge: Repeatedly downloading large files
(drivers, CUDA, source code) through a proxy is slow and
inefficient.
Solution: Implemented extensive GCS caching for
NVIDIA drivers, CUDA runfiles, NVIDIA Open Kernel Module source
tarballs, compiled kernel modules, and even packed Conda environments.
Scripts now check a GCS bucket (dataproc-temp-bucket)
before hitting the internet.
Impact: Dramatically speeds up subsequent runs and
init action execution times on cluster nodes after the cache is
warmed.
Conda Environment Stability & Speed:
Challenge: Large Conda environments are prone to
solver conflicts and slow installation times.
Solution: Integrated Mamba for faster package
solving. Refined package lists for better compatibility. Added logic to
force-clean and rebuild the Conda environment cache on GCS and locally
if inconsistencies are detected (e.g., driver installed but Conda env
not fully set up).
Secure Boot & Kernel Module Signing:
Challenge: Custom-compiled kernel modules must be
signed to load when Secure Boot is enabled.
Solution: The script integrates with GCP Secret
Manager to fetch signing keys. The build_driver_from_github
function now includes robust steps to compile, sign (using sign-file), install, and verify the signed modules.
Custom Image Workflow & Deferred Configuration:
Challenge: Cluster-specific settings (like YARN GPU
configuration) should not be baked into the image.
Solution: The install_gpu_driver.sh
script detects when it s run during image creation
(--metadata invocation-type=custom-images). In this mode,
it defers cluster-specific setups to a systemd service
(dataproc-gpu-config.service) that runs on the first boot
of a cluster instance. This ensures that YARN and Spark configurations
are applied in the context of the running cluster, not at image build
time.
Conclusion of Part 2
The install_gpu_driver.sh initialization action is more
than just an installer; it s a carefully crafted tool designed to handle
the complexities of secure, proxied environments. Its robust proxy
support, comprehensive GCS caching, refined Conda management, Secure
Boot signing capabilities, and awareness of the custom image build
lifecycle make it a critical enabler.
In Part 3, we ll explore how the LLC-Technologies-Collier/custom-images
repository (branch proxy-exercise-2025-11) uses this
initialization action to build the complete, ready-to-deploy Secure Boot
GPU custom images.
Part
1: Building a Secure Network Foundation for Dataproc with GPUs &
SWP
Welcome to the first post in our series on running GPU-accelerated
Dataproc workloads in secure, enterprise-grade environments. Many
organizations need to operate within VPCs that have no direct internet
egress, instead routing all traffic through a Secure Web Proxy (SWP).
Additionally, security mandates often require the use of Shielded VMs
with Secure Boot enabled. This series will show you how to meet these
requirements for your Dataproc GPU clusters.
In this post, we ll focus on laying the network foundation using
tools from the LLC-Technologies-Collier/cloud-dataproc
repository (branch proxy-sync-2026-01).
The Challenge: Network
Isolation & Control
Before we can even think about custom images or GPU drivers, we need
a network environment that:
Prevents direct internet access from Dataproc cluster nodes.
Forces all egress traffic through a manageable and auditable
SWP.
Provides the necessary connectivity for Dataproc to function and for
us to build images later.
Supports Secure Boot for all VMs.
The Toolkit: LLC-Technologies-Collier/cloud-dataproc
To make setting up and tearing down these complex network
environments repeatable and consistent, we ve developed a set of bash
scripts within the gcloud directory of the cloud-dataproc repository. These scripts handle the
creation of VPCs, subnets, firewall rules, service accounts, and the
Secure Web Proxy itself.
Key Script: gcloud/bin/create-dpgce-private
This script is the cornerstone for creating the private, proxied
environment. It automates:
VPC and Subnet creation (for the cluster, SWP, and management).
Setup of Certificate Authority Service and Certificate Manager for
SWP TLS interception.
Deployment of the SWP Gateway instance.
Configuration of a Gateway Security Policy to control egress.
Creation of necessary firewall rules.
Result: Cluster nodes in this VPC have NO default
internet route and MUST use the SWP.
Configuration via env.json
We use a single env.json file to drive the
configuration. This file will also be used by the custom-images scripts in Part 3. This env.json
should reside in your custom-images repository clone, and
you ll symlink it into the cloud-dataproc/gcloud
directory.
Running the Setup:
# Assuming you have cloud-dataproc and custom-images cloned side-by-side# And your env.json is in the custom-images rootcd cloud-dataproc/gcloud# Symlink to the env.json in custom-imagesln-sf ../../custom-images/env.json env.json# Run the creation script, but don't create a cluster yetbash bin/create-dpgce-private --no-create-clustercd ../../custom-images
Node
Configuration: The Metadata Startup Script for Runtime
For the Dataproc cluster nodes to function correctly in this proxied
environment, they need to be configured to use the SWP on boot. We
achieve this using a GCE metadata startup script.
The script startup_script/gce-proxy-setup.sh (from the custom-images repository) is designed to be run on each
cluster node at boot. It reads metadata like http-proxy and http-proxy-pem-uri (which our cluster creation scripts in
Part 4 will pass) to configure the OS environment, package managers, and
other tools to use the SWP.
Upload this script to your GCS bucket:
# Run from the custom-images repository rootgsutil cp startup_script/gce-proxy-setup.sh gs://$(jq-r .BUCKET env.json)/custom-image-deps/
This script is essential for the runtime behavior of the
cluster nodes.
Conclusion of Part 1
With the cloud-dataproc scripts, we ve laid the
groundwork by provisioning a secure VPC with controlled egress through
an SWP. We ve also prepared the essential node-level proxy configuration
script (gce-proxy-setup.sh) in GCS, ready to be used by our
clusters.
Stay tuned for Part 2, where we ll dive into the install_gpu_driver.sh initialization action from the LLC-Technologies-Collier/initialization-actions repository
(branch gpu-202601) and how it s been adapted to install
all GPU-related software through the proxy during the image build
process.
Welcome to post 47 in the $R^4 series!
r2u provides Ubuntu binaries for all CRAN packages for the R system. It started three years
ago, and offers for Linux users on Ubuntu what windows and macOS users
already experience: fast, easy and reliable installation of
binary packages. But by integrating with the system package
manager (which is something that cannot be done on those other operating
systems) we can fully and completely integrate it with underlying
system. External libraries are resolved as shared libraries and handled
by the system package manager. This offers fully automatic installation
both at the initial installation and all subsequent upgrades. R users just say, e.g.,
install.packages("sf") and spatial libraries
proj, gdal, geotiff (as well as
several others) are automatically installed as dependencies in the
correct versions. And they remain installed along with sf
as the system manager now knows of the dependency.
Work on r2u began as
a quick weekend experiment in March 2022, and by May 4 a first release
was marked in the NEWS file after a
few brave alpha testers kicked tires quite happily. This makes today the
third anniversary of that first release, and marks a good time to review
where we are. This short post does this, and stresses three aspects:
overall usage, current versions, and new developments.
Steadily
Growing Usage at 42 Million Packages Shipped
r2u ships from two
sites. Its main repository is at the University of Illinois campus
providing ample and heavily redundant bandwidth. We remain very grateful
for the sponsorship from Atlas. It also still ships from
my own server though that may be discontinued or could be spotty as it
is on retail fiber connectivity. As we have access to the both sets of
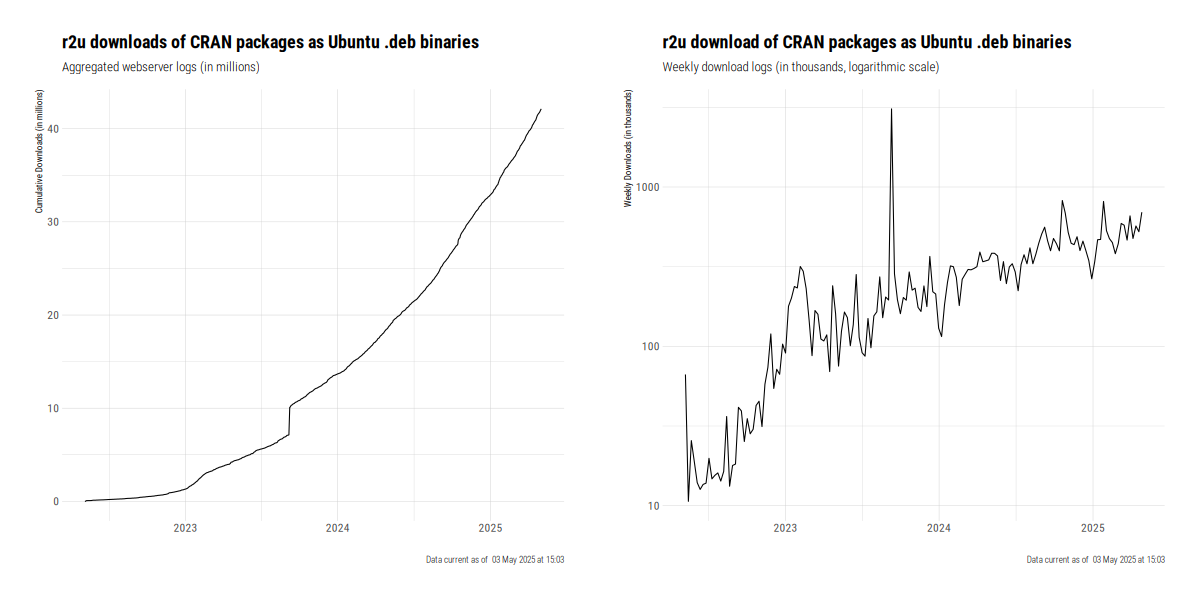
server logs, we can tabulate and chart usage. As of yesterday, total
downloads were north of 42 million with current weekly averages around
500 thousand. These are quite staggering numbers for what started as a
small hobby project, and are quite humbling.
Usage is driven by deployment in continuous integration (as for
example the Ubuntu-use at GitHub makes this both an easy and obvious
choice), cloud computing (as it is easy to spin up Ubuntu instances, it
is as easy to add r2u
via four simple commands or one short script), explorative use (for
example on Google Colab) or of course in general laptop, desktop, or
server settings.
Current Versions
Since r2u began, we
added two Ubuntu LTS releases,
three annual R releases as well
as multiple BioConductor
releases. BioConductor support is
on a best-efforts basis motivated primarily to support the CRAN packages having dependencies.
It has grown to around 500 packages and includes the top-250 by
usage.
Right now, current versions R
4.5.0 and BioConductor 3.21, both
released last month, are supported.
New Development: arm64
A recent change is the support of the arm64 platform. As discussed in
the introductory
post, it is a popular and increasingly common CPU choice seen
anywhere from the Raspberry Pi 5 and it Cortex CPU to in-house cloud
computing platforms (called, respectively, Graviton at AWS and Axiom at
GCS), general server use via Ampere CPUs, Cortex-based laptops that
start to appears and last but not least on the popular M1 to M4-based
macOS machines. (For macOS, one key appeal is in use of lighterweight
Docker use as these M1 to M4 cpus can run arm64-based containers without
a translation layer making it an attractive choice.)
This is currently supported only for the noble aka 24.04 release.
GitHub Actions, where we compile these packages, now also supports
jammy aka 22.04 but it may not be worth it to expand there as the
current latest release is available. We have not yet added BioConductor support but may do so.
Drop us a line (maybe via an issue) if this of
interest.
With the provision of arm64 binaries, we also started to make heavier
use of GitHub Actions. The BioConductor 3.21 release binaries
were also created there. This makes the provision more transparent as
well as the configuration repo
as well as the two builder repos (arm64, bioc) are
public, as is of course the main r2u repo.
Summing Up
This short post summarised the current state of r2u along with some recent
news. If you are curious, head over to the r2u site and try it, for
example in a rocker/r2u container.
Welcome to post 46 in the $R^4 series!
r2u, introduced less
than three years ago in post
#37, has become a runaway success. When I last tabulated downloads
in early January, we were already at 33 million downloads of binary CRAN packages across the three
Ubuntu LTS releases we support. These were exclusively for the amd64
platform of standard (Intel or AMD made) x64_64 cpus. Now we are happy
to announce that arm64 support has been added and is available!
Why arm64?
The arm64 platform is already popular on (cloud) servers and is being
pushed quite actively by the cloud vendors. AWS calls their cpu
graviton , GCS calls it axion . General servers call the cpu ampere ;
on laptop / desktops it is branded snapdragon or cortex or something
else. Apple calls their variant M1, M2, up to M4 by now (and Linux
support exists for the brave, it is less straightforward). What these
have in common is a generally more favourable power consumed to ops
provided ratio. That makes these cheaper to run or rent on cloud
providers. And in laptops they tend to last longer on a single charge
too.
Distributions such as Debian, Ubuntu, Fedora had arm64 for many
years. In fact, the CRAN
binaries of R, being made as builds at launchpad.net long provided arm64 in
Michael s repo, we now also mirror these to CRAN. Similarly, Docker has long
supported containers. And last but not least two issue tickets (#40, #55) had asked
a while back.
So Why Now?
Good question. I still do not own any hardware with it, and I have
not (yet?) bothered with the qemu-based emulation layer. The real
difference maker was the recent availability of GitHub Actions instances
of ubuntu-24.04-arm (and now apparently also for 22.04).
So I started some simple experiments which made it clear this was
viable.
What Does It Mean for a CRAN
Repo?
Great question. As is commonly known, of the (currently) 22.1k CRAN
packages, a little under 5k are compiled . Why does this matter?
Because the Linux distributions know what they are doing. The 17k (give
or take) packages that do not contain compiled code can be used as is
(!!) on another platform. Debian and Ubuntu call these builds binary:
all as they work all platforms as is . The others go by binary: any
and will work on any platform for which they have been built. So we
are looking at roughly 5k new binaries.
So How Many Are There?
As I write this in early March, roughly 4.5k of the 5k. Plus the
17.1k binary: all and we are looking at near complete coverage!
So What Is The Current State?
Pretty complete. Compare to the amd64 side of things, we do not (yet
?) have BioConductor support; this may be added. A handful of packages
do not compile because their builds seem to assume Linux so must be
amd64 and fail over cpu instructions. Similarly, a few packages want to
download binary build blobs (my own Rblpapi among them) but
none exist for arm64. Such is life. We will try to fix builds as time
permits and report build issues to the respective upstream repos. Help
in that endeavour would be most welcome.
But all the big and slow compiles one may care about (hello
duckdb, hello arrow, ) are there. Which is
pretty exciting!
How Does One Get Started?
In GitHub Actions, just pick ubuntu-24.04-arm as the
platform, and use the r-ci or r2u-setup
actiions. A first test yaml exists
worked (though this last version had the arm64 runner commented out
again). (And no, arm64 was not faster than amd64. More tests
needed.)
For simple tests, Docker. The rocker/r-ubuntu:24.04
container exists for arm64 (see here), and one
can add r2u support as is done in
this Dockerfile which is used by the builds and available as
eddelbuettel/r2u_build:noble. I will add the standard
rocker/r2u:24.04 container (or equally
rocker/r2u:noble) in a day or two, I had not realised I
wasn t making them for arm64.
One a real machine such as a cloud instance or a proper instance,
just use the standard r2u script for noble aka 24.04
available here.
The key lines are the two lines
creating the apt entry and which are now arm64-aware.
After that, apt works as usual, and of course r2u works as
usual thanks also to bspm so you can just do, say
and enjoy the binaries rolling in. So give it a whirl if you have
access to such hardware. We look forward to feedback, suggestes, feature
requests or bug reports. Let us know how it goes!
What is HMAC?
HMAC stands for Hash-Based Message Authentication Code. It s a specific way to use a cryptographic hash function (like SHA-1, SHA-256, etc.) along with a secret key to produce a unique fingerprint of some data. This fingerprint allows someone else with the same key to verify that the data hasn t been tampered with.
How HMAC Works
Keyed Hashing: The core idea is to incorporate the secret key into the hashing process. This is done in a specific way to prevent clever attacks that might try to bypass the security.
Inner and Outer Hashing: HMAC uses two rounds of hashing. First, the message and a modified version of the key are hashed together. Then, the result of that hash, along with another modified version of the key, are hashed again. This two-step process adds an extra layer of protection.
HMAC in OpenSSH
OpenSSH uses HMAC to ensure the integrity of messages sent back and forth during an SSH session. This prevents an attacker from subtly modifying data in transit.
HMAC-SHA1 with OpenSSH: Is it Weak?
SHA-1 itself is considered cryptographically broken. This means that with enough computing power, it s possible to find collisions (two different messages that produce the same hash). However, HMAC-SHA1 is generally still considered secure for most purposes. This is because exploiting weaknesses in SHA-1 to break HMAC-SHA1 is much more difficult than just finding collisions in SHA-1.
Should you use it?
While HMAC-SHA1 might still be okay for now, it s best practice to move to stronger alternatives like HMAC-SHA256 or HMAC-SHA512. OpenSSH supports these, and they provide a greater margin of safety against future attacks.
In Summary
HMAC is a powerful tool for ensuring data integrity. Even though SHA-1 has weaknesses, HMAC-SHA1 in OpenSSH is likely still safe for most users. However, to be on the safe side and prepare for the future, switching to HMAC-SHA256 or HMAC-SHA512 is recommended.
Following are instructions for creating dataproc clusters with sha1 mac support removed:
I can appreciate an excess of caution, and I can offer you some code to produce Dataproc instances which do not allow HMAC authentication using sha1.
Place code similar to this in a startup script or an initialization action that you reference when creating a cluster with gcloud dataproc clusters create:
#!/bin/bash
# remove mac specification from sshd configuration
sed -i -e 's/^macs.*$//' /etc/ssh/sshd_config
# place a new mac specification at the end of the service configuration
ssh -Q mac   perl -e \
  '@mac=grep  chomp; ! /sha1/  ; print("macs ", join(",",@mac), $/)' >> /etc/ssh/sshd_config
# reload the new ssh service configuration
systemctl reload ssh.service
If this code is hosted on GCS, you can refer to it with
Hello folks,
I ve been working this year on better integrating NVIDIA hardware with the Google Cloud Dataproc product (Hadoop on Google Cloud) running the default cluster node image. We have an open bug[1] in the initialization-actions repo regarding creation failures upon enabling secure boot. This is because with secure boot, kernel driver code has its signature verified before insmod places the symbols into kernel memory. The verification process involves reading trust root certificates from EFI variables, and validating that the signatures on the kernel driver either a) were made directly by one of the certificates in the boot sector or b) were made by certificates which chain up to one of them.
This means that Dataproc disk images must have a certificate installed into them. My work on the internals will likely start producing images which have certificates from Google in them. In the meantime, however, our users are left without a mechanism to have both secure boot enabled and install out-of-tree kernel modules such as the NVIDIA GPU drivers. To that end, I ve got PR #83[2] open with the GoogleCloudDataproc/custom-images github repository. This PR introduces a new argument to the custom image creation script, trusted-cert , the argument of which is the path to a DER-encoded certificate to be included in the certificate database in the EFI variables of the disk s boot sector.
I ve written up the instructions on creating a custom image with a trusted certificate here:
https://github.com/cjac/custom-images/blob/secure-boot-custom-image/examples/secure-boot/README.md
Here is a set of commands that can be used to create a Dataproc custom image with certificate installed to the EFI s db variable. You can run these commands from the root directory of a checkout such as this:
I d love to hear your feedback!
[1] https://github.com/GoogleCloudDataproc/initialization-actions/issues/1058
[2] https://github.com/GoogleCloudDataproc/custom-images/pull/83
dkg's New OpenPGP certificate in December 2023
In December of 2023, I'm moving to a new OpenPGP certificate.
You might know my old OpenPGP certificate, which had an fingerprint of
C29F8A0C01F35E34D816AA5CE092EB3A5CA10DBA.
My new OpenPGP certificate has a fingerprint of:
D477040C70C2156A5C298549BB7E9101495E6BF7.
Both certificates have the same set of User IDs:
-----BEGIN PGP PUBLIC KEY BLOCK-----xjMEZXEJyxYJKwYBBAHaRw8BAQdA5BpbW0bpl5qCng/RiqwhQINrplDMSS5JsO/YO+5Zi7HCwAsEHxYKAH0FgmVxCcsDCwkHCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmfUAgfN9tyTSxpxhmHA1r63GiI4v6NQmrrWVLOBRJYuhQMVCggCmwECHgEWIQTUdwQMcMIValwphUm7fpEBSV5r9wAAmaEA/3MvYJMxQdLhIG4UDNMVd2bsovwdcTrReJhLYyFulBrwAQD/j/RS+AXQIVtkcO9bl6zZTAO9x6yfkOZbv0g3eNyrAs0QPGRrZ0BkZWJpYW4ub3JnPsLACwQTFgoAfQWCZXEJywMLCQcJELt+kQFJXmv3RxQAAAAAAB4AIHNhbHRAbm90YXRpb25zLnNlcXVvaWEtcGdwLm9yZ4l+Z3i19Uwjw3CfTNFCDjRsoufMoPOM7vM8HoOEdn/vAxUKCAKbAQIeARYhBNR3BAxwwhVqXCmFSbt+kQFJXmv3AAALZQEAhJsgouepQVV98BHUH6SvWvcKrb8dQEZOvHFbZQQPNWgA/A/DHkjYKnUkCg8Zc+FonqOS/35sHhNA8CwqSQFrtN4KzRc8ZGtnQGZpZnRoaG9yc2VtYW4ubmV0PsLACgQTFgoAfQWCZXEJywMLCQcJELt+kQFJXmv3RxQAAAAAAB4AIHNhbHRAbm90YXRpb25zLnNlcXVvaWEtcGdwLm9yZxLvwkgnslsAuo+IoSa9rv8+nXpbBdab2Ft7n4H9S+d/AxUKCAKbAQIeARYhBNR3BAxwwhVqXCmFSbt+kQFJXmv3AAAtFgD4wqcUfQl7nGLQOcAEHhx8V0Bg8v9ov8GsY1ei1BEFwAD/cxmxmDSO0/tA+x4pd5yIvzgfGYHSTxKS0Ww3hzjuZA7NE0RhbmllbCBLYWhuIEdpbGxtb3LCwA4EExYKAIAFgmVxCcsDCwkHCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmd7X4TgiINwnzh4jar0Pf/b5hgxFPngCFxJSmtr/f0YiQMVCggCmQECmwECHgEWIQTUdwQMcMIValwphUm7fpEBSV5r9wAAMuwBAPtMonKbhGOhOy+8miAb/knJ1cIPBjLupJbjM+NUE1WyAQD1nyGW+XwwMrprMwc320mdJH9B0jdokJZBiN7++0NoBM4zBGVxCcsWCSsGAQQB2kcPAQEHQI19uRatkPSFBXh8usgciEDwZxTnnRZYrhIgiFMybBDQwsC/BBgWCgExBYJlcQnLCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmfCopazDnq6hZUsgVyztl5wmDCmxI169YLNu+IpDzJEtQKbAr6gBBkWCgBvBYJlcQnLCRB3LRYeNc1LgUcUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmcQglI7G7DbL9QmaDkzcEuk3QliM4NmleIRUW7VvIBHMxYhBHS8BMQ9hghL6GcsBnctFh41zUuBAACwfwEAqDULksr8PulKRcIP6N9NI/4KoznyIcuOHi8qGk4qxMkBAIeV20SPEnWSw9MWAb0eKEcfupzr/C+8vDvsRMynCWsDFiEE1HcEDHDCFWpcKYVJu36RAUlea/cAAFD1AP0YsE3Eeig1tkWaeyrvvMf5Kl1tt2LekTNWDnB+FUG9SgD+Ka8vfPR8wuV8D3y5Y9Qq9xGO+QkEBCW0U1qNypg65QHOOARlcQnLEgorBgEEAZdVAQUBAQdAWTLEa0WmnhUmDBdWXX0ZlYAa4g1CK/fXg0NPOQSteA4DAQgHwsAABBgWCgByBYJlcQnLCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmexrMBZe0QdQ+ZJOZxFkAiwCw2I7yTSF2Ox9GVFWKmAmAKbDBYhBNR3BAxwwhVqXCmFSbt+kQFJXmv3AABcJQD/f4ltpSvLBOBEh/C2dIYadgSuqkCqq0B4WOhFRkWJZlcA/AxqLWG4o8UrrmwrmM42FhgxKtEXwCSHE00u8wR4Up8G=9Yc8-----END PGP PUBLIC KEY BLOCK-----
When I have some reasonable number of certifications, i'll update the
certificate associated with my e-mail addresses on
https://keys.openpgp.org, in DANE, and in WKD. Until then, those
lookups should continue to provide the old certificate.
This is a short announcement to say that I have changed my main
OpenPGP key. A signed statement is available with the
cryptographic details but, in short, the reason is that I stopped
using my old YubiKey NEO that I have worn on my keyring since
2015.
I now have a YubiKey 5 which supports ED25519 which features much
shorter keys and faster decryption. It allowed me to move all my
secret subkeys on the key (including encryption keys) while retaining
reasonable performance.
I have written extensive documentation on how to do that OpenPGP key
rotation and also YubiKey OpenPGP operations.
Warning on storing encryption keys on a YubiKey
People wishing to move their private encryption keys to such a
security token should be very careful as there are special
precautions to take for disaster recovery.
I am toying with the idea of writing an article specifically about
disaster recovery for secrets and backups, dealing specifically with
cases of death or disabilities.
Autocrypt changes
One nice change is the impact on Autocrypt headers, which are
considerably shorter.
Before, the header didn't even fit on a single line in an email, it
overflowed to five lines:
Note that I have implemented my own kind of ridiculous Autocrypt
support for the NotmuchEmacs email client I use, see this
elisp code. To import keys, I pipe the message into this
script which is basically just:
sq autocrypt decode gpg --import
... thanks to Sequoia best-of-class Autocrypt support.
Note on OpenPGP usage
While some have claimed OpenPGP's death, I believe those are
overstated. Maybe it's just me, but I still use OpenPGP for my
password management, to authenticate users and messages, and it's the
interface to my YubiKey for authenticating with SSH servers.
I understand people feel that OpenPGP is possibly insecure,
counter-intuitive and full of problems, but I think most of those
problems should instead be attributed to its current flagship
implementation, GnuPG. I have tried to work with GnuPG for years, and
it keeps surprising me with evilness and oddities.
I have high hopes that the Sequoia project can bring some sanity
into this space, and I also hope that RFC4880bis can eventually
get somewhere so we have a more solid specification with more robust
crypto. It's kind of a shame that this has dragged on for so
long, but Update: there's a separate draft called
openpgp-crypto-refresh that might actually be adopted as the
"OpenPGP RFC" soon! And
it doesn't keep real work from happening in Sequoia and other
implementations. Thunderbird rewrote their OpenPGP implementation with
RNP (which was, granted, a bumpy road because it lost
compatibility with GnuPG) and Sequoia now has a certificate store
with trust management (but still no secret storage), preliminary
OpenPGP card support and even a basic GnuPG compatibility
layer. I'm also curious to try out the OpenPGP CA
capabilities.
So maybe it's just because I'm becoming an old fart that doesn't want
to change tools, but so far I haven't seen a good incentive in
switching away from OpenPGP, and haven't found a good set of tools
that completely replace it. Maybe OpenSSH's keys and CA can eventually
replace it, but I suspect they will end up rebuilding most of OpenPGP
anyway, just more slowly. If they do, let's hope they avoid the
mistakes our community has done in the past at least...
Hello folks!
We recently received a case letting us know that Dataproc 2.1.1 was unable to write to a BigQuery table with a column of type JSON. Although the BigQuery connector for Spark has had support for JSON columns since 0.28.0, the Dataproc images on the 2.1 line still cannot create tables with JSON columns or write to existing tables with JSON columns.
The customer has graciously granted permission to share the code we developed to allow this operation. So if you are interested in working with JSON column tables on Dataproc 2.1 please continue reading!
Use the following gcloud command to create your single-node dataproc cluster:
The following file is the Scala code used to write JSON structured data to a BigQuery table using Spark. The file following this one can be executed from your single-node Dataproc cluster.
Main.scala
import org.apache.spark.sql.functions.col
import org.apache.spark.sql.types. Metadata, StringType, StructField, StructType
import org.apache.spark.sql. Row, SaveMode, SparkSession
import org.apache.spark.sql.avro
import org.apache.avro.specific
  val env = "x"
  val my_bucket = "cjac-docker-on-yarn"
  val my_table = "dataset.testavro2"
    val spark = env match
      case "local" =>
        SparkSession
          .builder()
          .config("temporaryGcsBucket", my_bucket)
          .master("local")
          .appName("isssue_115574")
          .getOrCreate()
      case _ =>
        SparkSession
          .builder()
          .config("temporaryGcsBucket", my_bucket)
          .appName("isssue_115574")
          .getOrCreate()

  // create DF with some data
  val someData = Seq(
    Row(""" "name":"name1", "age": 10  """, "id1"),
    Row(""" "name":"name2", "age": 20  """, "id2")
  )
  val schema = StructType(
    Seq(
      StructField("user_age", StringType, true),
      StructField("id", StringType, true)
    )
  )
  val avroFileName = s"gs://$ my_bucket /issue_115574/someData.avro"

  val someDF = spark.createDataFrame(spark.sparkContext.parallelize(someData), schema)
  someDF.write.format("avro").mode("overwrite").save(avroFileName)
  val avroDF = spark.read.format("avro").load(avroFileName)
  // set metadata
  val dfJSON = avroDF
    .withColumn("user_age_no_metadata", col("user_age"))
    .withMetadata("user_age", Metadata.fromJson(""" "sqlType":"JSON" """))
  dfJSON.show()
  dfJSON.printSchema
  // write to BigQuery
  dfJSON.write.format("bigquery")
    .mode(SaveMode.Overwrite)
    .option("writeMethod", "indirect")
    .option("intermediateFormat", "avro")
    .option("useAvroLogicalTypes", "true")
    .option("table", my_table)
    .save()
#!/bin/bash
PROJECT_ID=set-yours-here
DATASET_NAME=dataset
TABLE_NAME=testavro2
# We have to remove all of the existing spark bigquery jars from the local
# filesystem, as we will be using the symbols from the
# spark-3.3-bigquery-0.30.0.jar below.  Having existing jar files on the
# local filesystem will result in those symbols having higher precedence
# than the one loaded with the spark-shell.
sudo find /usr -name 'spark*bigquery*jar' -delete
# Remove the table from the bigquery dataset if it exists
bq rm -f -t $PROJECT_ID:$DATASET_NAME.$TABLE_NAME
# Create the table with a JSON type column
bq mk --table $PROJECT_ID:$DATASET_NAME.$TABLE_NAME \
  user_age:JSON,id:STRING,user_age_no_metadata:STRING
# Load the example Main.scala
spark-shell -i Main.scala \
  --jars /usr/lib/spark/external/spark-avro.jar,gs://spark-lib/bigquery/spark-3.3-bigquery-0.30.0.jar
# Show the table schema when we use  bq mk --table  and then load the avro
bq query --use_legacy_sql=false \
  "SELECT ddl FROM $DATASET_NAME.INFORMATION_SCHEMA.TABLES where table_name='$TABLE_NAME'"
# Remove the table so that we can see that the table is created should it not exist
bq rm -f -t $PROJECT_ID:$DATASET_NAME.$TABLE_NAME
# Dynamically generate a DataFrame, store it to avro, load that avro,
# and write the avro to BigQuery, creating the table if it does not already exist
spark-shell -i Main.scala \
  --jars /usr/lib/spark/external/spark-avro.jar,gs://spark-lib/bigquery/spark-3.3-bigquery-0.30.0.jar
# Show that the table schema does not differ from one created with a bq mk --table
bq query --use_legacy_sql=false \
  "SELECT ddl FROM $DATASET_NAME.INFORMATION_SCHEMA.TABLES where table_name='$TABLE_NAME'"
Google BigQuery has supported JSON data since October of 2022, but until now, it has not been possible, on generally available Dataproc clusters, to interact with these columns using the Spark BigQuery Connector.
JSON column type support was introduced in spark-bigquery-connector release 0.28.0.
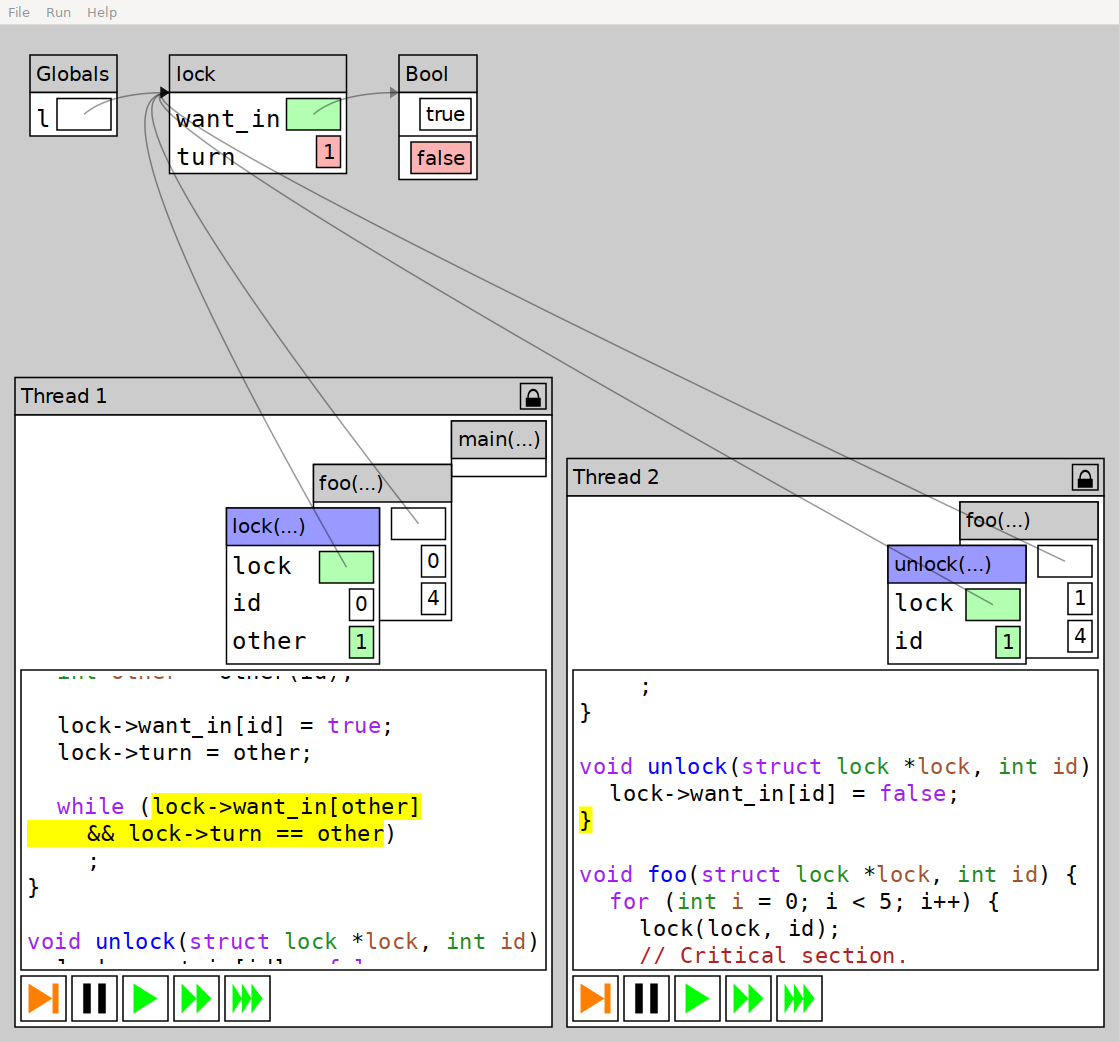
This is a program visualization tool aimed at concurrent programs
and related issues. The tool itself is mostly language agnostic, and
relies on Storm to compile the provided code and provide basic debug
information. The generated code is then inspected and instrumented
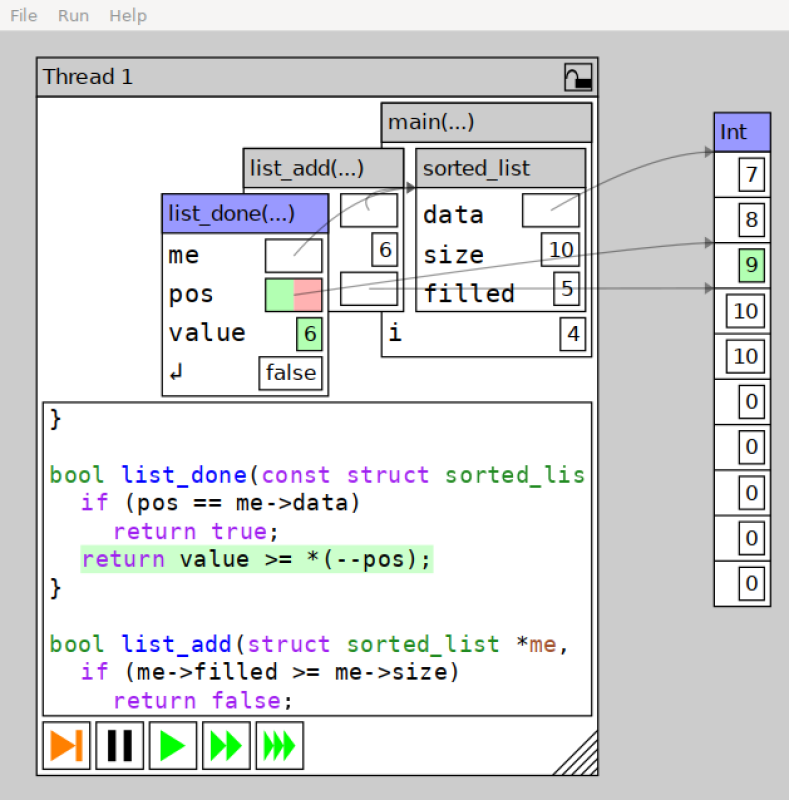
to provide an experience similar to a basic debugger. The tool
emphasizes a visual representation of the object hierarchy that is
manipulated by the executed program to make it easy to understand
how it looks. In particular, a visual representation is beneficial
over a text representation since it makes it easier to find shared
data that might need to be synchronized in a concurrent program.
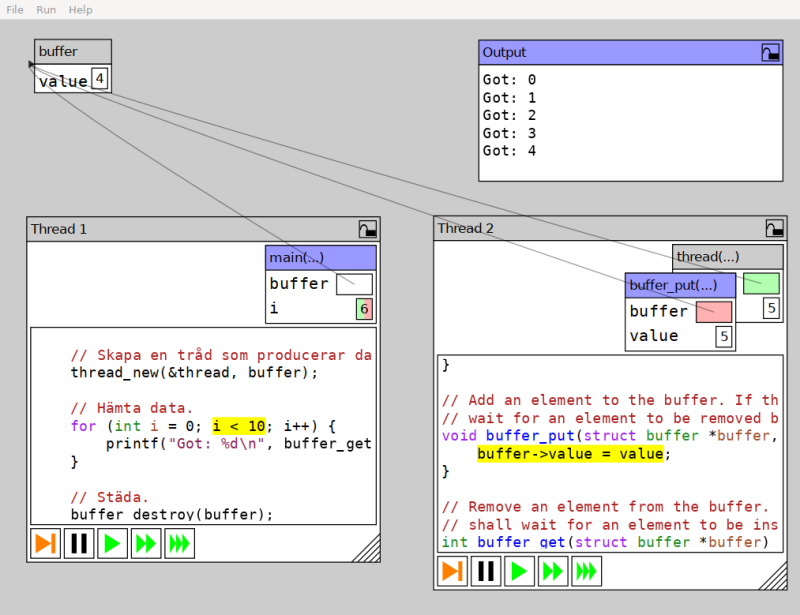
As mentioned, the tool is aimed at concurrent programs. Therefore,
it allows spawning multiple threads running the same program to see
if that affects the program s execution (this is mostly interesting
if global variables are used). Furthermore, any spawned threads also
appear in the tool, and the user may control them independently to
explore possible race conditions or other synchronization errors. If
enabled from the menu bar, the tool keeps track of reads and writes
to the data structure in order to highlight basic race conditions in
addition to deadlocks.
So, what is this Storm thing? Filip promptly informed me that
Progvis is not just a pedagogical tool Or rather, that it is part
of something bigger. Progvis is a program built using the Storm
programming language platform is more than a
compiler; it presents as a framework for creating languages,
designed to make easy to implement languages that can be extended
with new syntax and semantics. Storm is much more than what I have
explored, and can be used as an interactive compiler, a language
server used as a service for highlighting and completing in IDEs. But
I won t dig much more into Storm (which is, of course, now also
available in Debian as
well as the libraries built from the same source).
Back to progvis: It implements a very-close-to-C++ language, with some
details to better suit its purpose (i.e. instead of using the usual
pthread implementation, an own thread model is used; i.e. thread
creation is handled via int thread_id = thread_name(funcname,
¶ms) instead of the more complex
pthread_create()
function (including details such as the thread object being passed as
by reference as a parameter)
All in all, while I have not yet taken full advantage of this tool in
my teaching, it has helped me show somewhat hard to grasp concepts
such as:
Understanding pointers and indirection
How strings are handled
Heap allocation vs. stack allocation
Shared access to global data
All in all, a great tool. I hope you find it useful and enjoyable as well!
PS- I suggest you to install the progvis-examples package to get
started. You will find some dozens of sample programs in
/usr/share/doc/progvis-examples/examples; playing with them will
help you better understand the tool and be able to better write your
own programs.
chroot maintenance
chroot-create and chroot-login are similar to what
pbuilder,
cowbuilder,
schroot,
debspawn and similar tools do.
They only take a chroot name, and default the rest of paths to where
nspawn-runner expects things to be under /var/lib/nspawn-runner.
gitlab-runner setup
nspawn-runner toml <chroot-name> outputs a snippet to add to
/etc/gitlab-runner/config.toml to configure the CI.
For example:
One needs to remember to set url and token, and the runner is configured.
The end, for now
This is it, it works! Time will tell what issues or ideas will come up: for
now, it's a pretty decent first version.
The various prepare, run, cleanup steps are generic enough that they can
be used outside of gitlab-runner: feel free to build on them, and drop me a
note if you find this useful!
Updated: Issues noticed so far, that could go into a new version:
updating the master chroot would disturb the running CI jobs that use it.
Using nspawn's btrfs-specfic features would prevent this problem, and
possibly simplify the implementation even more.
New step! trivially
implementing support for multiple OS images
This post is part of a series about trying to setup a gitlab runner based on
systemd-nspawn. I published the polished
result as nspawn-runner on GitHub.
The plan
Back to custom runners, here's my plan:
config can be a noop
prepare starts the nspawn machine
run runs scripts with machinectl shell
cleanup runs machinectl stop
The scripts
Here are the scripts based on Federico's work:
base.sh with definitions sourced by all scripts:
Approved removal of screenshots:
seaview screenshot contained advertising,
mupen64plus/mupen64plus-audio-all were weird screenshots with multiple OS windows overlaid &
mkgmap was a screenshot of the OSM wiki instead of the software
Rejected screenshots:
gccgo looked like a Thai mobile phone screenshot,
python-stem was a screenshot for OPENDIME USB,
seaview was downloaded from elsewhere and not an authentic screenshot &
fbreader contained non-free ebook contents
Administration
Debian:
reboot 1 non-responsive VM,
redirect 2 users to support channels,
redirect 1 contributor to xkb upstream,
redirect 1 potential contributor,
redirect 1 bug reporter to mirror team,
ping 7 folks about restarting processes with upgraded libs,
manually restart the sectracker process due to upgraded libs,
restart the package tracker process due to upgraded libs,
investigate failures connecting to the XMPP service,
investigate /dev/shm issue on abel.d.o,
clean up after rename of the fedmsg group.
Debian mentors:
lintian/security updates & reboot
Debian packages:
deploy 2 contributions to the live server
Debian wiki:
unblacklist 1 IP address,
whitelist 10 email addresses,
disable 18 accounts with bouncing email,
update email for 2 accounts with bouncing email,
reported 1 Debian member as MIA,
redirect 1 user to support channels,
add 4 domains to the whitelist.
Reproducible builds:
rescheduled Debian pyxplot:amd64/unstable for themill.
Sponsors
I renewed my support of Software Freedom Conservancy.
The openchange 1:2.2-6+deb8u1 upload was sponsored by my employer.
All other work was done on a volunteer basis.
Recently, the pkg-go team has
been quite busy, uploading dozens of Go library packages in order to be able to
package gcsfuse (a
user-space file system for interacting with Google Cloud Storage) and InfluxDB (an open-source distributed time
series database).
Packaging Go library packages (!) is a fairly repetitive process, so before
starting my work on the dependencies for gcsfuse, I started writing a tool
called dh-make-golang.
Just like dh-make itself, the goal is to automatically create (almost) an
entire Debian package.
As I worked my way through the dependencies of gcsfuse, I refined how the tool
works, and now I believe it s good enough for a first release.
To demonstrate how the tool works, let s assume we want to package the Go
library github.com/jacobsa/ratelimit:
midna/tmp $ dh-make-golang github.com/jacobsa/ratelimit
2015/07/25 18:25:39 Downloading "github.com/jacobsa/ratelimit/..."
2015/07/25 18:25:53 Determining upstream version number
2015/07/25 18:25:53 Package version is "0.0~git20150723.0.2ca5e0c"
2015/07/25 18:25:53 Determining dependencies
2015/07/25 18:25:55
2015/07/25 18:25:55 Packaging successfully created in /tmp/golang-github-jacobsa-ratelimit
2015/07/25 18:25:55
2015/07/25 18:25:55 Resolve all TODOs in itp-golang-github-jacobsa-ratelimit.txt, then email it out:
2015/07/25 18:25:55 sendmail -t -f < itp-golang-github-jacobsa-ratelimit.txt
2015/07/25 18:25:55
2015/07/25 18:25:55 Resolve all the TODOs in debian/, find them using:
2015/07/25 18:25:55 grep -r TODO debian
2015/07/25 18:25:55
2015/07/25 18:25:55 To build the package, commit the packaging and use gbp buildpackage:
2015/07/25 18:25:55 git add debian && git commit -a -m 'Initial packaging'
2015/07/25 18:25:55 gbp buildpackage --git-pbuilder
2015/07/25 18:25:55
2015/07/25 18:25:55 To create the packaging git repository on alioth, use:
2015/07/25 18:25:55 ssh git.debian.org "/git/pkg-go/setup-repository golang-github-jacobsa-ratelimit 'Packaging for golang-github-jacobsa-ratelimit'"
2015/07/25 18:25:55
2015/07/25 18:25:55 Once you are happy with your packaging, push it to alioth using:
2015/07/25 18:25:55 git push git+ssh://git.debian.org/git/pkg-go/packages/golang-github-jacobsa-ratelimit.git --tags master pristine-tar upstream
The ITP is often the most labor-intensive part of the packaging process,
because any number of auto-detected values might be wrong: the repository owner
might not be the Upstream Author , the repository might not have a short
description, the long description might need some adjustments or the license
might not be auto-detected.
midna/tmp $ cat itp-golang-github-jacobsa-ratelimit.txt
From: "Michael Stapelberg" <stapelberg AT debian.org>
To: submit@bugs.debian.org
Subject: ITP: golang-github-jacobsa-ratelimit -- Go package for rate limiting
Content-Type: text/plain; charset=utf-8
Content-Transfer-Encoding: 8bit
Package: wnpp
Severity: wishlist
Owner: Michael Stapelberg <stapelberg AT debian.org>
* Package name : golang-github-jacobsa-ratelimit
Version : 0.0~git20150723.0.2ca5e0c-1
Upstream Author : Aaron Jacobs
* URL : https://github.com/jacobsa/ratelimit
* License : Apache-2.0
Programming Lang: Go
Description : Go package for rate limiting
GoDoc (https://godoc.org/github.com/jacobsa/ratelimit)
.
This package contains code for dealing with rate limiting. See the
reference (http://godoc.org/github.com/jacobsa/ratelimit) for more info.
TODO: perhaps reasoning
midna/tmp $
After filling in all the TODOs in the file, let s mail it out and get a sense
of what else still needs to be done:
After filling in these TODOs as well, let s have a final look at what we re
about to build:
midna/tmp/golang-github-jacobsa-ratelimitmaster $ head -100 debian/**/*
==> debian/changelog <==
golang-github-jacobsa-ratelimit (0.0~git20150723.0.2ca5e0c-1) unstable; urgency=medium
* Initial release (Closes: #793646)
-- Michael Stapelberg <stapelberg@debian.org> Sat, 25 Jul 2015 23:26:34 +0200
==> debian/compat <==
9
==> debian/control <==
Source: golang-github-jacobsa-ratelimit
Section: devel
Priority: extra
Maintainer: pkg-go <pkg-go-maintainers@lists.alioth.debian.org>
Uploaders: Michael Stapelberg <stapelberg@debian.org>
Build-Depends: debhelper (>= 9),
dh-golang,
golang-go,
golang-github-jacobsa-gcloud-dev,
golang-github-jacobsa-oglematchers-dev,
golang-github-jacobsa-ogletest-dev,
golang-github-jacobsa-syncutil-dev,
golang-golang-x-net-dev
Standards-Version: 3.9.6
Homepage: https://github.com/jacobsa/ratelimit
Vcs-Browser: http://anonscm.debian.org/gitweb/?p=pkg-go/packages/golang-github-jacobsa-ratelimit.git;a=summary
Vcs-Git: git://anonscm.debian.org/pkg-go/packages/golang-github-jacobsa-ratelimit.git
Package: golang-github-jacobsa-ratelimit-dev
Architecture: all
Depends: $ shlibs:Depends ,
$ misc:Depends ,
golang-go,
golang-github-jacobsa-gcloud-dev,
golang-github-jacobsa-oglematchers-dev,
golang-github-jacobsa-ogletest-dev,
golang-github-jacobsa-syncutil-dev,
golang-golang-x-net-dev
Built-Using: $ misc:Built-Using
Description: Go package for rate limiting
This package contains code for dealing with rate limiting. See the
reference (http://godoc.org/github.com/jacobsa/ratelimit) for more info.
==> debian/copyright <==
Format: http://www.debian.org/doc/packaging-manuals/copyright-format/1.0/
Upstream-Name: ratelimit
Source: https://github.com/jacobsa/ratelimit
Files: *
Copyright: 2015 Aaron Jacobs
License: Apache-2.0
Files: debian/*
Copyright: 2015 Michael Stapelberg <stapelberg@debian.org>
License: Apache-2.0
Comment: Debian packaging is licensed under the same terms as upstream
License: Apache-2.0
Licensed under the Apache License, Version 2.0 (the "License");
you may not use this file except in compliance with the License.
You may obtain a copy of the License at
.
http://www.apache.org/licenses/LICENSE-2.0
.
Unless required by applicable law or agreed to in writing, software
distributed under the License is distributed on an "AS IS" BASIS,
WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
See the License for the specific language governing permissions and
limitations under the License.
.
On Debian systems, the complete text of the Apache version 2.0 license
can be found in "/usr/share/common-licenses/Apache-2.0".
==> debian/gbp.conf <==
[DEFAULT]
pristine-tar = True
==> debian/rules <==
#!/usr/bin/make -f
export DH_GOPKG := github.com/jacobsa/ratelimit
%:
dh $@ --buildsystem=golang --with=golang
==> debian/source <==
head: error reading debian/source : Is a directory
==> debian/source/format <==
3.0 (quilt)
midna/tmp/golang-github-jacobsa-ratelimitmaster $
Okay, then. Let s give it a shot and see if it builds:
This package just built (as it should!), but occasionally one might need to disable a test and file an upstream bug about it. So, let s push this package to pkg-go and upload it:
midna/tmp/golang-github-jacobsa-ratelimitmaster $ ssh git.debian.org "/git/pkg-go/setup-repository golang-github-jacobsa-ratelimit 'Packaging for golang-github-jacobsa-ratelimit'"
Initialized empty shared Git repository in /srv/git.debian.org/git/pkg-go/packages/golang-github-jacobsa-ratelimit.git/
HEAD is now at ea6b1c5 add mrconfig for dh-make-golang
[master c5be5a1] add mrconfig for golang-github-jacobsa-ratelimit
1 file changed, 3 insertions(+)
To /git/pkg-go/meta.git
ea6b1c5..c5be5a1 master -> master
midna/tmp/golang-github-jacobsa-ratelimitmaster $ git push git+ssh://git.debian.org/git/pkg-go/packages/golang-github-jacobsa-ratelimit.git --tags master pristine-tar upstream
Counting objects: 31, done.
Delta compression using up to 8 threads.
Compressing objects: 100% (25/25), done.
Writing objects: 100% (31/31), 18.38 KiB 0 bytes/s, done.
Total 31 (delta 2), reused 0 (delta 0)
To git+ssh://git.debian.org/git/pkg-go/packages/golang-github-jacobsa-ratelimit.git
* [new branch] master -> master
* [new branch] pristine-tar -> pristine-tar
* [new branch] upstream -> upstream
* [new tag] upstream/0.0_git20150723.0.2ca5e0c -> upstream/0.0_git20150723.0.2ca5e0c
midna/tmp/golang-github-jacobsa-ratelimitmaster $ cd ..
midna/tmp $ debsign golang-github-jacobsa-ratelimit_0.0\~git20150723.0.2ca5e0c-1_amd64.changes
[ ]
midna/tmp $ dput golang-github-jacobsa-ratelimit_0.0\~git20150723.0.2ca5e0c-1_amd64.changes
Uploading golang-github-jacobsa-ratelimit using ftp to ftp-master (host: ftp.upload.debian.org; directory: /pub/UploadQueue/)
[ ]
Uploading golang-github-jacobsa-ratelimit_0.0~git20150723.0.2ca5e0c-1.dsc
Uploading golang-github-jacobsa-ratelimit_0.0~git20150723.0.2ca5e0c.orig.tar.bz2
Uploading golang-github-jacobsa-ratelimit_0.0~git20150723.0.2ca5e0c-1.debian.tar.xz
Uploading golang-github-jacobsa-ratelimit-dev_0.0~git20150723.0.2ca5e0c-1_all.deb
Uploading golang-github-jacobsa-ratelimit_0.0~git20150723.0.2ca5e0c-1_amd64.changes
midna/tmp $ cd golang-github-jacobsa-ratelimit
midna/tmp/golang-github-jacobsa-ratelimitmaster $ git tag debian/0.0_git20150723.0.2ca5e0c-1
midna/tmp/golang-github-jacobsa-ratelimitmaster $ git push git+ssh://git.debian.org/git/pkg-go/packages/golang-github-jacobsa-ratelimit.git --tags master pristine-tar upstream
Total 0 (delta 0), reused 0 (delta 0)
To git+ssh://git.debian.org/git/pkg-go/packages/golang-github-jacobsa-ratelimit.git
* [new tag] debian/0.0_git20150723.0.2ca5e0c-1 -> debian/0.0_git20150723.0.2ca5e0c-1
midna/tmp/golang-github-jacobsa-ratelimitmaster $
Thanks for reading this far, and I hope dh-make-golang makes your life a tiny
bit easier. As dh-make-golang just
entered Debian unstable, you can install it using apt-get install
dh-make-golang. If you have any feedback, I m eager to hear it.
Designing a virtual laboratory for a relational database MOOC
Olivier Berger, J Paul Gibson, Claire Lecocq and Christian Bac
Keywords: Remote Learning, Virtualization, Open Education Resources, MOOC, Vagrant
Abstract: Technical advances in machine and system virtualization are creating opportunities for remote learning to provide significantly better support for active education approaches. Students now, in general, have personal computers that are powerful enough to support virtualization of operating systems and networks. As a conse- quence, it is now possible to provide remote learners with a common, standard, virtual laboratory and learning environment, independent of the different types of physical machines on which they work. This greatly enhances the opportunity for producing re-usable teaching materials that are actually re-used. However, configuring and installing such virtual laboratories is technically challenging for teachers and students. We report on our experience of building a virtual machine (VM) laboratory for a MOOC on relational databases. The architecture of our virtual machine is described in detail, and we evaluate the benefits of using the Vagrant tool for building and delivering the VM.
TOC :
Introduction
A brief history of distance learning
Virtualization : the challenges
The design problem
The virtualization requirements
Scenario-based requirements
Related work on requirements
Scalability of existing approaches
The MOOC laboratory
Exercises and lab tools
From requirements to design
Making the VM as a Vagrant box
Portability issues
Delivery through Internet
Security
Availability of the box sources
Validation
Reliability Issues with VirtualBox
Student feedback and evaluation
Future work
Laboratory monitoring
More modular VMs
Conclusions
Bibliography
Alario-Hoyos et al., 2014
Alario-Hoyos, C., P rez-Sanagust n, M., Kloos, C. D., and Mu oz Merino, P. J. (2014).
Recommendations for the design and deployment of MOOCs: Insights about the MOOC digital education of the future deployed in Mir adaX.
In Proceedings of the Second International Conference on Technological Ecosystems for Enhancing Multiculturality, TEEM 14, pages 403-408, New York, NY, USA. ACM.
Armbrust et al., 2010
Armbrust, M., Fox, A., Griffith, R., Joseph, A. D., Katz, R., Konwinski, A., Lee, G., Patterson, D., Rabkin, A., Stoica, I., and Zaharia, M. (2010).
A view of cloud computing.
Commun. ACM, 53:50-58.
Billingsley and Steel, 2014
Billingsley, W. and Steel, J. R. (2014).
Towards a supercollaborative software engineering MOOC.
In Companion Proceedings of the 36th International Conference on Software Engineering, pages 283-286. ACM.
Brown and Duguid, 1996
Brown, J. S. and Duguid, P. (1996).
Universities in the digital age.
Change: The Magazine of Higher Learning, 28(4):11-19.
Bullers et al., 2006
Bullers, Jr., W. I., Burd, S., and Seazzu, A. F. (2006).
Virtual machines an idea whose time has returned: Application to network, security, and database courses.
SIGCSE Bull., 38(1):102-106.
Chen and Noble, 2001
Chen, P. M. and Noble, B. D. (2001).
When virtual is better than real [operating system relocation to virtual machines].
In Hot Topics in Operating Systems, 2001. Proceedings of the Eighth Workshop on, pages 133-138. IEEE.
Cooper, 2005
Cooper, M. (2005).
Remote laboratories in teaching and learning-issues impinging on widespread adoption in science and engineering education.
International Journal of Online Engineering (iJOE), 1(1).
Cormier, 2014
Cormier, D. (2014).
Rhizo14-the MOOC that community built.
INNOQUAL-International Journal for Innovation and Quality in Learning, 2(3).
Dougiamas and Taylor, 2003
Dougiamas, M. and Taylor, P. (2003).
Moodle: Using learning communities to create an open source course management system.
In World conference on educational multimedia, hypermedia and telecommunications, pages 171-178.
Gomes and Bogosyan, 2009
Gomes, L. and Bogosyan, S. (2009).
Current trends in remote laboratories.
Industrial Electronics, IEEE Transactions on, 56(12):4744-4756.
Hashimoto, 2013
Hashimoto, M. (2013).
Vagrant: Up and Running.
O Reilly Media, Inc.
Jones and Winne, 2012
Jones, M. and Winne, P. H. (2012).
Adaptive Learning Environments: Foundations and Frontiers.
Springer Publishing Company, Incorporated, 1st edition.
Lowe, 2014
Lowe, D. (2014).
MOOLs: Massive open online laboratories: An analysis of scale and feasibility.
In Remote Engineering and Virtual Instrumentation (REV), 2014 11th International Conference on, pages 1-6. IEEE.
Ma and Nickerson, 2006
Ma, J. and Nickerson, J. V. (2006).
Hands-on, simulated, and remote laboratories: A comparative literature review.
ACM Computing Surveys (CSUR), 38(3):7.
Pearson, 2013
Pearson, S. (2013).
Privacy, security and trust in cloud computing.
In Privacy and Security for Cloud Computing, pages 3-42. Springer.
Prince, 2004
Prince, M. (2004).
Does active learning work? A review of the research.
Journal of engineering education, 93(3):223-231.
Romero-Zaldivar et al., 2012
Romero-Zaldivar, V.-A., Pardo, A., Burgos, D., and Delgado Kloos, C. (2012).
Monitoring student progress using virtual appliances: A case study.
Computers & Education, 58(4):1058-1067.
Sumner, 2000
Sumner, J. (2000).
Serving the system: A critical history of distance education.
Open learning, 15(3):267-285.
Watson, 2008
Watson, J. (2008).
Virtualbox: Bits and bytes masquerading as machines.
Linux J., 2008(166).
Winckles et al., 2011
Winckles, A., Spasova, K., and Rowsell, T. (2011).
Remote laboratories and reusable learning objects in a distance learning context.
Networks, 14:43-55.
Yeung et al., 2010
Yeung, H., Lowe, D. B., and Murray, S. (2010).
Interoperability of remote laboratories systems.
iJOE, 6(S1):71-80.
Trusted:
NO, there were errors:
The certificate does not apply to the given host
The certificate authority's certificate is invalid
The root certificate authority's certificate is not trusted for this purpose
The certificate cannot be verified for internal reasons
Signature Algorithm: md5WithRSAEncryption
    Issuer: C=XY, ST=Snake Desert, L=Snake Town, O=Snake Oil, Ltd, OU=Certificate Authority, CN=Snake Oil CA/emailAddress=ca@snakeoil.dom
    Validity
        Not Before: Oct 21 18:21:51 1999 GMT
        Not After : Oct 20 18:21:51 2001 GMT
    Subject: C=XY, ST=Snake Desert, L=Snake Town, O=Snake Oil, Ltd, OU=Webserver Team, CN=www.snakeoil.dom/emailAddress=www@snakeoil.dom
...
            X509v3 Subject Alternative Name:
            email:www@snakeoil.dom




 The Debian LTS Team, funded by

 Welcome to post 47 in the
 Usage is driven by deployment in continuous integration (as for
example the Ubuntu-use at GitHub makes this both an easy and obvious
choice), cloud computing (as it is easy to spin up Ubuntu instances, it
is as easy to add


 So, what is this Storm thing? Filip promptly informed me that
Progvis is not just a pedagogical tool Or rather, that it is part
of something bigger. Progvis is a program built using


 Here s a short preview of our latest accepted paper (to appear at