Search Results: "ema"

14 October 2026

Dirk Eddelbuettel: qlcal 0.1.4 on CRAN: Fresh Upstream Updates

The twenty-second release of the qlcal package arrivied at CRAN yesterday, and has been built for r2u as well as on r-universe. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over seventy country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This release is based on the changes in the QuantLib 1.44 release also made yesterday. It includes two new calendars for Malaysia and the Philippines, updates to around a dozen calendars, and a few other updates to internal files. Maxmilian Muecke spotted and fixed a few small bugs just as he did for the RQuantLib release we made yesterday; this is equally appreciated! The full details from NEWS.Rd follow.

Changes in version 0.1.4 (2026-10-13)
  • Add missing market calendars for Poland, Russia, Romania, Indonesia (Maximilian Muecke in #21)
  • Add (semi-deprecated) alternate separators '::' for Israel and New Zealand markets (Maximilian Muecke in #22)
  • Fix several typos across source, configuration and documentation files (Maximilian Muecke in #23)
  • Synchronize with QuantLib 1.44, add two new calendars, update several others, and update general utility files (Dirk in #24)

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Reproducible Builds: Reproducible Builds in September 2026

Welcome to the September 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. In this month s report, we cover:

  1. Reproducible Builds Summit 2026 held in Gothenburg, Sweden
  2. dettrace expanding architecture support for PGO & Lisp dumps
  3. They don t care about this!
  4. SOURCE_DATE_EPOCH specification updates
  5. Reproducible Builds at SeaGL 2026
  6. New Code of Conduct (CoC)
  7. Supporter Spotlight: Jochen Sprickerhof
  8. Mailing list news
  9. Tool and documentation development
  10. Patches

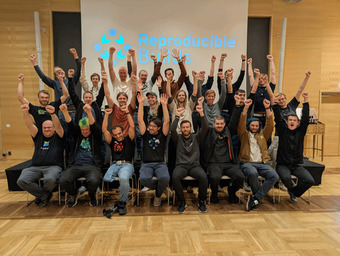
Reproducible Builds Summit 2026 held in Gothenburg, Sweden The annual Reproducible Builds summit took place from 22 to 24 September 2026 in Gothenburg, Sweden. The event brought together developers, distribution maintainers, security researchers and free software advocates from across the ecosystem to share updates on current initiatives, address outstanding toolchain bottlenecks and strengthen cross-project collaboration. Participants engaged in a series of working sessions and technical roundtables focused on expanding the practical scope of reproducibility. Discussions covered ongoing work within major Linux distributions, language-specific package ecosystems and the various parts of the binary verification infrastructure. Strategic planning formed a pillar of the gathering, with participants discussing long-term roadmap goals for supply-chain security, software integrity and related topics. Attendees explored new methods for automated verification, discussing how to lower the adoption barriers for maintainers and streamline the integration of deterministic build pipelines into established continuous integration (CI) systems. The event was then followed by two days of unmoderated hacking sessions. These hacking sessions provided space for technical progress, allowing attendees to draft specification updates, prototype new tool features and resolve standing reproducibility bugs in-person.

Dettrace expanding architecture support for PGO & Lisp dumps Bernhard M. Wiedemann announced major updates to dettrace, porting the tool across most architectures supported by Debian and openSUSE. The release addresses key stability issues, passing test suites across these targets and making it ready for production build pipelines. These improvements enable deterministic builds when utilising Profile-Guided Optimisations (PGO), removing the need to sacrifice runtime performance for reproducibility. Additionally, dettrace can now be applied to (notoriously difficult-to-reproduce) Lisp and Scheme memory dumps, including environments such as CLISP, SBCL, Scheme 48, Racket and GNU Emacs.

They don t care about this Annika Wilde, Marco Gutfleisch, Felix Reichmann, Anirban Chakraborty, Yuval Yarom, M. Angela Sasse and Ghassan Karame published a paper this month entitled They don t care about this : A Systematic Study of Trusted Execution Environments Build Reproducibility in the Wild:
Trusted Execution Environments (TEEs) have become a cornerstone of modern cloud computing, providing strong confidentiality and integrity guarantees for both code and data. A critical component of this trust model is remote attestation, which enables external entities to verify the authenticity and integrity of code executing within a TEE through cryptographic measurements. However, the effectiveness of remote attestation fundamentally depends on the verifier s ability to trace the reported measurement back to the original source code - a property that can only be guaranteed through reproducible builds. [ ]
The full PDF can be read online.

SOURCE_DATE_EPOCH specification updates Bernhard M. Wiedemann shared a number of proposals regarding updating the SOURCE_DATE_EPOCH specification following discussions at a project summit. Seven distinct proposed changes have been submitted as merge requests on Salsa. Bernhard s proposed modifications are independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests by 1 December 2026. Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list. The specification was first published in 2015 and updated in 2017.

Reproducible Builds at SeaGL 2026 Reproducible Builds will be present at SeaGL in Seattle, WA, on October 23rd & 24th. Come chat with us in person! Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture.

New Code of Conduct (CoC) for the Reproducible Builds project Mattia Rizzolo announced the official launch of a Code of Conduct for the Reproducible Builds project. This follows work and community discussions originally initiated in 2024, incorporating feedback gathered over email and during project summits, as well as with input from the Software Freedom Conservancy. The new Code of Conduct establishes guidelines emphasising mutual respect among project contributors. It also defines a formalised process for submitting and handling complaints regarding community misconduct, ensuring transparent governance across project spaces. Along with the core policy document, an accompanying Code of Conduct FAQ has been published to outline the rationale behind adopting the guidelines.

Supporter Spotlight: Jochen Sprickerhof As a reminder, another supporter spotlight interview was published featuring long-time Debian and Reproducible Builds contributor Jochen Sprickerhof, highlighting his work on package verification and project infrastructure.

Mailing list news On our mailing list this month:
  • Jonathan Starr from the Institute of Open Science Practices (IOSP) posted with an announcement of its upcoming 2026 workshop series in Leiden in the Netherlands. This free-to-attend event aims to build a participant-owned data storage consortium, allowing community members to publish datasets, code and knowledge objects alongside algorithms designed to evaluate trust and value. The event features a dedicated Community Track for talks and discussions, a tool showcase and an opening session on resilient data storage.
  • Following up on IRC discussions regarding profile-guided optimization (PGO) on build servers, kpcyrd created a demonstration repository showing how PGO profiling can introduce non-determinism into output binaries. The demo highlights how runtime randomness (specifically, the randomised keys used in HashMaps to prevent denial-of-service attacks) causes varying bucket collision rates during test runs. These structural variances alter execution weights on underlying code branches, prompting the compiler to generate differing final assembly output for builds that would otherwise be perfectly reproducible if PGO was disabled. Rather than abandoning PGO performance gains, kpcyrd suggested treating generated profiling data as a documented build input or recorded environment artifact (similar to .buildinfo files), rather than regenerating profiles dynamically on the fly during build execution.
  • An autonomous AI agent (!), posted a controlled build result and reproducer demonstrating that pre-creating an obj directory in libmilter source trees prevents kernel-release path leaks (obj.Linux.<release>.x86_64) into debugging symbols. kpcyrd followed up with a helpful reply.
  • Alexander Sosedkin inquired on the mailing list about the preferred approach for sourcing pinned translation files to create reproducible GnuTLS release tarballs, asking whether external hosting should provide versioned downloads, or if projects ought to use Git submodules, dedicated side-repositories or some other mechanism.

Tool and documentation development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 330, 331 and 332 to Debian. In particular, Chris committed support for radare2 versions greater than 5.9.0 [ ] based on input from Guillaume Girol [ ], and committed support for .nar files via Guix. [ ][ ]. Chris later modified diffoscope to not Build-Depend on the Debian package of GNU Guix, as its status in the Debian bug tracking system would transitively render diffoscope as being overly buggy for the next stable release [ ]. Similarly, he adjusted the Build-Depends on the apksigcopier package as it has been removed from Debian testing [ ] and, finally, he updated a number of copyright years [ ][ ]. Vagrant Cascadian updated diffoscope in GNU Guix to version 332.
reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.33 was uploaded to Debian by Holger Levsen with the following changes:
  • Sergei Tachenov fixed the fileordering test on all filesystems, including the likes of ZFS, which could return a different order across two builds due to build being done in a different directory [ ].
  • Holger Levsen bumped the Standards-Version to 4.7.4, reflected that Priority: optional is the default now [ ], fixed the old Free Software Foundation address [ ] and bumped the debhelper compat level to 14 after confirming there are only desired changes [ ].
  • Vagrant Cascadian updated *reprotest* to version 0.7.33 in GNU Guix.

rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. This month, Bernhard M. Wiedemann submitted a pull request to rebuilderd that refactors RPM repository metadata handling. The change extracts rpm-md parsing out of the Fedora-specific scheduler module and into a shared one.
Lastly, there were a number of improvements made to our website this month as well. For example:

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including: Vagrant Cascadian also performed a number of Non-Maintainer Uploads (NMUs) and Quality Assurance (QA) uploads in Debian for several packages with outstanding reproducibility issues. These included molttemplate, buddy, xfonts-nexus, fte and lifelines. At the time of this writing, that leaves 130 submitted patches, with only 61 outstanding submitted patches that older than a year in the Debian bug tracking system. This number is only 26 if we exclude any low-priority build path issues.

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Russ Allbery: Review: Ties That Bond in Gretna Green

Review: Ties That Bond in Gretna Green, by Linzi Day
Series: Midlife Recorder #3
Publisher: Linzi Day
Copyright: February 2023
ISBN: 9798376517017
Format: Kindle
Pages: 616
Ties That Bond in Gretna Green is a self-published fantasy novel and the third book in the Midlife Recorder series. As with the previous book, it picks up almost immediately after Painting the Blues in Gretna Green. Day calls the genre paranormal women's fantasy, and that sounds about right to me. There is an intervening short story that you can get by joining Day's mailing list (along with an epilogue to the first book and to this book). I don't think it's that important, but there are frequent references to it at the start of this novel that become somewhat annoying if you haven't read it. Valentine's Day is fast approaching. This the busiest day of the year for the part of the Recorder's job that Niki already knew how to do: marrying people. She performed marriage ceremonies in her previous job before her inheritance, and she loved that work despite her awful boss. Performing marriages in the Gateway sounds even more rewarding, but the sheer number of couples and the political complications from the first two books create logistical problems she has to solve first. Also, the remaining member of her staff held over from her grandmother's time has returned from vacation to discover that Niki has upended most of what she thought she knew about the job. Time for Niki to apply what she learned from the change management training her old boss forced her to attend and then ignored! (If you just groaned, rest assured that Day somehow makes this work, although she clearly has a higher opinion of corporate training than I do.) This plot was more to my taste than Painting the Blues, mostly because Niki seemed on top of the problems and didn't postpone looking at them for half the book. There is more of the management competence porn that readers have come to expect of the series, a few more revelations about Niki's magic, more mysterious manifestations and the first mention of a prophecy, and a few political developments. As always, the pacing is exceptional. These books grab me and pull me along, page after page, often robbing me of sleep because I find them nearly impossible to put down. Ties that Bond (and to some extent the last book) looked like it was going to introduce a romantic subplot, and I was preparing to be annoyed by it because I did not like the man in the subplot at all. I won't spoil how it works out in this book, but I will say that Niki surprised me and showed more sense than I thought the author was telegraphing. This is not the first time that Day has surprised me with what I thought was foreshadowing that did not turn out how I expected, usually for the better. If she can keep that up, it's a nice effect (if a bit unbalancing) and adds to my desire to read just one more chapter. The way the world-building of these books is structured continues to intrigue me. Day gets away with some problems that I think would be more noticeable in other books thanks to the excellent pacing (no time to ponder the world-building, we're on to the next crisis!) and the tight third-person perspective. Niki is not a detail person, to say the least, but she does keep returning to bits of world-building and poking at them a bit harder, which gives Day repeated opportunities to shore up ideas that felt shaky and dubious at first glance. Still, this is not a book that prizes deep logical consistency or full exploration of the ramifications of a bit of magic. You have to be willing to go along with the ride and not think too hard. For example, Niki can see bonds between couples and judge their strength. This is apparently a long-standing power of the Recorder's line (she was able to do that before she became the Recorder), and part of her responsibility in these weddings is to check the bonds of the couples. This leads to some well-handled scenes where she diagnoses a problem or resolves a conflict because she can magically see the true relationship structure. Everyone in the book just takes this power in stride. This is wild to me! This ability would completely upend half of society if you fully worked out its ramifications and could find people other than Niki with the same ability. Even if one assumes that a bond only forms over time and can't be sensed in the early stages of a relationship (something the book never establishes), can you imagine the implications of having an infallible oracle that says at a glance whether a marriage will work (permanently, the book strongly implies)? The implications for how to structure marriage, for family planning, for psychology and psychiatry, for how to structure dating, even for living arrangements and housing markets? This is not a small world-building detail, and yet it's treated more like part of Niki's characterization than like a foundation of society. I think some of this all-vibes world-building may come from the general new-age feel to how magic works. Day makes a grab-bag of random magic canonical in this world: psychic lie detecting abilities, auras, chakras, premonitions, and other bits of the sort of spiritualism that tends to be heavily marketed to middle-class women. I have that niggling feeling that one sometimes gets in SF that a lot of this is in the world-building because the author believes it's partly real (see, for instance, psychic powers and the Dean drive in 1960s science fiction). If one believes that psychic powers and various bits of mysticism are true in our world, one has already developed the rationalization mechanisms to explain away their almost total lack of influence or impact on how the world is structured. If one then introduces them into a true fantasy world, one may not notice how many implications that should have for how society is structured, since one is used to believing magic exists but has no significant implications. I could be entirely wrong about this analysis, and maybe it's a bit unfair to Day. I should also be clear that this is not a complaint, just a point of fascination to me when I think back over one of these books after I finished it. There is a glut of fantasy out there that's constructed like an engineering problem or that goes deep into politics or social theory, usually written by people with strong opinions but not a lot of training in real sociology. One of the joys of self-published books is that you occasionally get something that assembles genre conventions in a way that feels odd and delightfully strange. What if, in addition to dimensional gates and overwhelming protean power invested in a true heir, all the magic sold by the local Tarot and crystal store was also true? Sure, why not! If the pacing is good and the story is grabby, it works for me. It does seem worth attaching a warning for the folks who need scientific reproducibility and explored implications in their world-building, though. If you're the sort of reader who is bothered by political boundaries and economic systems that match our world despite the existence of magic, this series may cause you problems. This continues to be a grabby, highly entertaining story of a woman who finally gets to run her own small business the way that she always thought the business should be run after years of working for an awful manager, except that her business is total magical power over an interchange point between dimensions, she's the chosen one, and the setting is a high fantasy world with prophecies and gods. If that sounds appealing, don't start here, but I highly recommend giving Midlife in Gretna Green a try. The series seems to be holding up. Followed by a short story epilogue available by joining Day's mailing list, an optional novella (maybe novelette) published in Spilling the Tea in Gretna Green, and then Seeing Red in Gretna Green. Rating: 7 out of 10

13 October 2026

Matthew Garrett: Linux Lockdown and Hibernation (again)

(This is an updated version of an older post - the introduction remains the same, the technical details are different) Linux draws a distinction between code running in kernel (kernel space) and applications running in userland (user space). This is enforced at the hardware level - in x86-speak1, kernel space code runs in ring 0 and user space code runs in ring 32. If you re running in ring 3 and you attempt to touch memory that s only accessible in ring 0, the hardware will raise a fault. No matter how privileged your ring 3 code, you don t get to touch ring 0. Kind of. In theory. Traditionally this wasn t well enforced. At the most basic level, since root can load kernel modules, you could just build a kernel module that performed any kernel modifications you wanted and then have root load it. Technically user space code wasn t modifying kernel space code, but the difference was pretty semantic rather than useful. But it got worse - root could also map memory ranges belonging to PCI devices3, and if the device could perform DMA you could just ask the device to overwrite bits of the kernel4. Or root could modify special CPU registers ( Model Specific Registers , or MSRs) that alter CPU behaviour via the /dev/msr interface, and compromise the kernel boundary that way. It turns out that there were a number of ways root was effectively equivalent to ring 0, and the boundary was more about reliability (ie, a process running as root that ends up misbehaving should still only be able to crash itself rather than taking down the kernel with it) than security. After all, if you were root you could just replace the on-disk kernel with a backdoored one and reboot. Going deeper, you could replace the bootloader with one that automatically injected backdoors into a legitimate kernel image. We didn t have any way to prevent this sort of thing, so attempting to harden the root/kernel boundary wasn t especially interesting. In 2012 Microsoft started requiring vendors ship systems with UEFI Secure Boot, a firmware feature that allowed5 systems to refuse to boot anything without an appropriate signature. This not only enabled the creation of a system that drew a strong boundary between root and kernel, it arguably required one - what s the point of restricting what the firmware will stick in ring 0 if root can just throw more code in there afterwards? What ended up as the Lockdown Linux Security Module provides the tooling for this, blocking userspace interfaces that can be used to modify the kernel and enforcing that any modules have a trusted signature. But that comes at something of a cost. Most of the features that Lockdown blocks are fairly niche, so the direct impact of having it enabled is small. Except that it also blocks hibernation6, and it turns out some people were using that. The obvious question is what does hibernation have to do with keeping root out of kernel space , and the answer is a little convoluted and is tied into how Linux implements hibernation. Basically, Linux saves system state into the swap partition and modifies the header to indicate that there s a hibernation image there instead of swap. On the next boot, the kernel sees the header indicating that it s a hibernation image, copies the contents of the swap partition back into RAM, and then jumps back into the old kernel code. What ensures that the hibernation image was actually written out by the kernel? Absolutely nothing, which means a motivated attacker with root access could turn off swap, write a hibernation image to the swap partition themselves, and then reboot. The kernel would happily resume into the attacker s image, giving the attacker control over what gets copied back into kernel space. This is annoying, because normally when we think about attacks on swap we mitigate it by requiring an encrypted swap partition. But in this case, our attacker is root, and so already has access to the plaintext version of the swap partition. Disk encryption doesn t save us here. We need some way to verify that the hibernation image was written out by the kernel, not by root. And thankfully we have some tools for that. Trusted Platform Modules (TPMs) are cryptographic coprocessors7 capable of doing things like generating encryption keys and then encrypting things with them. You can ask a TPM to encrypt something with a key that s tied to that specific TPM - the OS has no access to the decryption key, and nor does any other TPM. So we can have the kernel generate an encryption key, encrypt part of the hibernation image with it, and then have the TPM encrypt it. We store the encrypted copy of the key in the hibernation image as well. On resume, the kernel reads the encrypted copy of the key, passes it to the TPM, gets the decrypted copy back and is able to verify the hibernation image. That s great! Except root can do exactly the same thing. This tells us the hibernation image was generated on this machine, but doesn t tell us that it was done by the kernel. We need some way to be able to differentiate between keys that were generated in kernel and ones that were generated in userland. TPMs have the concept of localities (effectively privilege levels) that would be perfect for this. Userland is only able to access locality 0, so the kernel could simply use locality 1 to encrypt the key. Unfortunately, localities are typically only available on systems that implement a Dynamic Root of Trust Measurement like Intel s TXT, and most consumer systems have no support for this. So, we need another approach. TPMs have a set of Platform Configuration Registers (PCRs), intended for keeping a record of system state. The OS isn t able to modify the PCRs directly. Instead, the OS provides a cryptographic hash of some material to the TPM. The TPM takes the existing PCR value, appends the new hash to that, and then stores the hash of the combination in the PCR - a process called extension . This means that the new value of the TPM depends not only on the value of the new data, it depends on the previous value of the PCR - and, in turn, that previous value depended on its previous value, and so on. The only way to get to a specific PCR value is to either (a) break the hash algorithm, or (b) perform exactly the same sequence of writes. On system reset the PCRs go back to a known value, and the entire process starts again. Some PCRs are different. PCR 23, for example, can be reset back to its original value without resetting the system. We can make use of that. The first thing we need to do is to prevent userland from being able to reset or extend PCR 23 itself. All TPM accesses go through the kernel, so this is a simple matter of parsing the write before it s sent to the TPM and returning an error if it s a sensitive command that would touch PCR 23. We now know that any change in PCR 23 s state will be restricted to the kernel. When we encrypt material with the TPM, we can ask it to record the PCR state. This is given back to us as metadata accompanying the encrypted secret. Along with the metadata is an additional signature created by the TPM, which can be used to prove that the metadata is both legitimate and associated with this specific encrypted data. In our case, that means we know what the value of PCR 23 was when we encrypted the key. That means that if we simply extend PCR 23 with a known value in-kernel before encrypting our key, we can look at the value of PCR 23 in the metadata. If it matches, the key was encrypted by the kernel - userland can create its own key, but it has no way to extend PCR 23 to the appropriate value first. We now know that the key was generated by the kernel. Unfortunately it turns out that some people actually make use of PCR 23, and restricting it to the kernel makes them sad. There are other resettable PCRs, but only in non-0 localities, so (a) we can t reset them on most systems and (b) we ll just find someone who uses them anyway and run into the same problem. We need a different approach. Thankfully TPMs have a small chunk of non-volatile RAM that can be used for storing things, and by storing I mean they can be used in a range of different ways. One of these is effectively as additional PCRs. These values can be configured such that they work the same way as PCRs, with the only way to modify them being to append a new hash to their existing value and update the new value to the hash of that merged value. We can allocate one of these for in-kernel use and reject any access from userspace, and also there are officially allocated ranges (so people shouldn t be using random values) and the namespace is large enough anyway that w eshouldn t collide with anyone, so we can carve one of those out and use it for this purpose. Unfortunately, though, these NV indexes aren t included in the creation data we get when we create a key, so we need another approach. TPMs have the concept of sessions, a series of commands executed in sequence. A flag allows these sessions to be audited , with the TPM keeping a running track of the hash of the commands executed and the results returned. At the end of the session you can ask for a signed copy of this hash, and if you ve kept a log of all the commands then you can verify that they match that signed hash and know that this log represents a real communication with the TPM. If we read the NV index and generate the key inside the same session, we can verify that the key we re looking at was created while the NV index had a specific value, and if only the kernel can set that value then we know that the key was generated by the kernel. Or, well, can we? Only new kernels would impose the restriction on modifying that NV index. An attacker could boot an old kernel, generate a key there in userland, sign a hibernation image with it, and then reboot into a new kernel. The new kernel would see a valid signature with a valid NV index associated with it and have no way to know it was generated from userland rather than the kernel. We need to be able to tell the difference between kernels that implement this feature and ones that don t, and we need to do that without being able to go back in time to change old kernel behaviour. We can extend a PCR to indicate we implement the new functionality, but so can an attacker running an old kernel. The normal approach to determining whether an event occurred in a specific phase of the boot process is to cap the PCRs - extend them with a known value that indicates a transition between stages of the boot process. Any events that occur before the cap event must have occurred in the previous stage of boot, and since the final PCR value depends on the order of measurements and not just the contents of those measurements, if a PCR is capped before userland runs, userland can t fake the same PCR value afterwards. If Linux capped the PCRs before userland started running, we d be able to place a measurement there before the cap occurred and then prove that that extension occurred before userland had the opportunity to interfere. We could simply place a statement that the kernel supported the NV index restrictions there, and we d be fine. Unfortunately Linux doesn t currently do this, and adding support for doing so doesn t fix the problem - if an attacker boots a kernel that doesn t cap a PCR, they can just cap it themselves from userland. So, we re faced with the same problem: booting an older kernel allows the system to be placed in an identical state to the current kernel, and a fake hibernation image can be written out. Solving this requires a PCR that was being modified after kernel code was running, but before userland was started, even with existing kernels. Thankfully, there is one! PCR 5 is defined as containing measurements related to boot management configuration and data. One of the measurements it contains is the result of the UEFI ExitBootServices() call. ExitBootServices() is called at the transition from the UEFI boot environment to the running OS, and the kernel contains code that executes before it. So, if we measure an assertion regarding whether or not we support restricted access to NV indexes into PCR 5 before we call ExitBootServices(), this will prevent userspace from spoofing us (because userspace will only be able to extend PCR 5 after the firmware extended PCR 5 in response to ExitBootServices() being called). Obviously this depends on the firmware actually performing the PCR 5 extension when ExitBootServices() is called, but if firmware s out of spec then I don t think there s any real expectation of it being secure enough for any of this to buy you anything anyway. That s what this patchset does. Review feedback so far seems positive, although James Bottomley suggested a design improvement. My approach of using an NV index as a PCR and generating a signing key made sense as a consequence of my original approach involving PCR 23, which had been to use the key creation data and not use audit sessions at all. But the goal isn t to use a key - it s to prove that hibernation occurred in-kernel, and while signing is one way of doing that, there are others. His suggestion is to simply record the hash of the hibernation image into the NV index and then read that back as part of the audit session. On resume we verify the audit session log is legitimate, read the hibernation image, and compare the hash of the hibernation image against the hash in the log. If it matches, and if the PCR 5 value matches, we know the audit session happened in kernel and that the hibernation image hasn t been modified. It still seems like we re missing something, though. If we re not storing a key anywhere, how do we verify the audit session? To explain this we re going to need to go into some details about how TPM keys work in the first place. TPMs can produce a special kind of key called an Attestation Key, or AK. Attestation keys are used to sign attestation statements from the TPM, such as PCR quotes or audit logs. We need a separate key type for this in order to prove that the signature was generated as part of an attestation - normal TPM signing keys are fundamentally designed to sign arbitrary material, and so can be used by userland to sign something that looks identical to an attestation record. By being able to distinguish the types of key the TPM uses, we can prove that a signature was generated using an AK, and so know that it s a real TPM attestation (because nothing other than the TPM can sign stuff with an AK). But even beyond this distinction, TPMs have different key types. Ordinary keys are generated using an RNG and will be unique. Primary keys are generated using a seed that is used as an input into a key derivation function. For a given TPM, using the same seed to generate the same type of primary key will always generate the same primary key8. We can have the kernel deterministically generate an AK during suspend in order to sign the audit log, and then generate the same key again on resume to validate it. This means we don t need any other form of trusted storage for the AK - the TPM already provides that functionality. This is all rather complicated but I ve been thinking about this for some time now and I haven t come up with a cleaner solution. The only real open issue is the degree to which machines actually perform the PCR 5 extension. If it turns out there s a bunch that don t we ll need to come up with some alternative approach to identifying whether the kernel supports this functionality, but the design is such that that should be invisible to userspace so adding alternatives later shouldn t be an issue. Filtering accesses to the NV index is also not super clean, and depends on there not being alternative mechanisms to get at the TPM by sending raw commands. Again, this is intended to be opaque to userland and can be improved if we come up with something better later on (such as a secure way to pass a secret to the kernel on boot that can be used as an auth value for acess to the NV index). Anyway. Time to go and fix the next thing.

  1. Other architectures use different terminology here, such as supervisor and user mode, but it s broadly equivalent
  2. In theory rings 1 and 2 would allow you to run drivers with privileges somewhere between full kernel access and userland applications, but in reality we just don t talk about them in polite company
  3. This is how graphics worked in Linux before kernel modesetting turned up. XFree86 would just map your GPU s registers into userland and poke them directly. This was not a huge win for stability
  4. IOMMUs can help you here, by restricting the memory PCI devices can DMA to or from. The kernel then gets to allocate ranges for device buffers and configure the IOMMU such that the device can t DMA to anything else. Except that region of memory may still contain sensitive material such as function pointers, and attacks like this can still cause you problems as a result.
  5. This describes why I m using allowed rather than required here
  6. Saving the system state to disk and powering down the platform entirely - significantly slower than suspending the system while keeping state in RAM, but also resilient against the system losing power.
  7. With some handwaving around coprocessor . TPMs can t be part of the OS or the system firmware, but they don t technically need to be an independent component. Intel have a TPM implementation that runs on the Management Engine, a separate processor built into the motherboard chipset. AMD have one that runs on the Platform Security Processor, a small ARM core built into their CPU. Various ARM implementations run a TPM in Trustzone, a special CPU mode that (in theory) is able to access resources that are entirely blocked off from anything running in the OS, kernel or otherwise.
  8. Unless the TPM is cleared, in which case it ll generate a new internal seed and now the keys will be different to before the clear

9 October 2026

Colin Watson: Free software activity in September 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH I worked with upstream to remove libselinux linkage from /usr/sbin/sshd. I applied a fix from Mark Robillard Jr to fix reload logic when using sysvinit. groff I upgraded from 1.24.1 to 1.24.2, which fixed a few command injection security vulnerabilities. parted I upgraded from 3.7 to 3.8, which fixed CVE-2026-89085 and CVE-2026-89088. Python packaging New upstream versions: setuptools 84 is now in Debian and no longer contains pkg_resources. Removing uses of that module has been an ongoing project for a while now, but I did another batch of fixes this month: A new python-coverage version triggered several build regressions due to a known problem in pytest-cov. I worked around these by setting COVERAGE_CORE=ctrace: Other build/test failures: I investigated a build failure in python-proton-vpn-local-agent and proposed a fix upstream, but I m not comfortable applying this in Debian without review. If you re familiar with this code, please take a look. I fixed some other bugs: Rust packaging rust-derivre had an invalid Section field, which I cleaned up.

Russell Coker: en-html.org is a Scam Site

Currently a scam group is sending out email to the administrators of web sites that link to a variety of dead domains. They claim to be the legitimate operators of the dead domains in question and request that the links change to mirrors of the web sites under en-html.org. Their end goal appears to game search engines by getting links from a lot of old web pages and later use that high ranking for selling SEO optimisation. If you have made the mistake of linking to something under en-html.org then I recommend that you change the link to the original content on archive.org. If you receive email from the en-html.org domain then ignore it, or configure your mail server to reject it. I am seriously considering configuring the DNS servers I run to return no valid data for any requests under that domain. Also I will reject all future requests to update links in old blog posts. The very small number of people who want to see what I linked to in old posts can use archive.org.

Louis-Philippe V ronneau: Removing myself as a Lintian uploader in the next few weeks

A few days ago, a colleague reached out to me, asking if I could help draft a resolution on digital autonomy and free software for the upcoming renewal of our collective bargaining agreement. Although she's very politicised and generally a great individual, she is not a techie and we never really talked about these issues before. This took me by surprise. I should have been rejoicing; no, I should have been the one who brought up this topic in our union. Wasn't I the technical expert on these issues? But alas, my first reaction when she came to me was to snicker and tell myself: "That's cute, but nothing's ever gonna change, Big Tech is too strong and our governments don't give a damn." How sad and cynical is that? That's not the person I want to be. Something in the Quebecois political landscape has shifted in the last few years with regards to tech. More and more "regular" people seem to be talking about the importance of digital autonomy, how government services shouldn't rely on Big Tech and how we should be using FOSS on hardware we actually control. A few years ago, I would have been at the vanguard of this change. I would have been part of the creation of Donn es souveraines Qu bec. Heck, they are organising a whole conference next week and I'm not even going. How did this happen to me? I first fell for Free Software for its political ideals: Knowledge Should Be Free, Cooperation Is More Efficient Than Competition, Centralisation Should Be Avoided When Possible, etc. I still believe in all of this, but somehow, after years of fighting for change in the tech world, I have retreated into technical work. I maintain Debian packages as a hobby and to scratch my own itch. I run services for myself and a few friends. I organise Debian User Group meetings. To be clear, I haven't generally given up. I'm very politically active in my union and at work, I'm a good member of my housing cooperative and I'm still fighting against the industrialisation of natural spaces in my neighborhood. But when it comes time to defend freedom in the tech world, lately, I've just been shrugging and accepting I should use Microsoft Teams like every one else does. I want this to change and to do so, I need to free some time. Lintian Two years ago, I added myself to Lintian's Uploaders list. Up until then1, I enjoyed fixing little issues here and there and liked creating new tags to help out the Python Team, where most of my Debian time was spent. Lintian was badly in need of a new maintainer and as I felt it was an important project, I decided to step in. 37 releases and about 160 closed bugs later2, I'm done. To be honest, I haven't had much fun maintaining Lintian lately. Bugs keep piling on the BTS, so much so I have mostly been ignoring them for the past few months. In fact, most of the actual work triaging, writing code and fixing bug has been done by Nilesh Patra for a while now. All this to say, if you care about Lintian, you should consider adding yourself to the Uploaders list, as I'm out and Nilesh can't do all the work by himself. He's a great person to work with and since I don't want to suddenly leave him all alone, I'll be sticking around for a few more weeks in the hope someone else will volunteer to help out. A smooth transition with a new co-maintainer would really be nice! If you're interested, don't hesitate to reach out to me on IRC or by email.

  1. My first technical commit to Lintian was nearly 7 years ago! Crazy how time flies.
  2. Mostly closed by other people than I!

8 October 2026

Antoine Beaupr : PSA: Europe changes time forward soon, North America next, for the last time?

This is a copy of an email I sent at work. I'm not sure I should be making noise about this here, feedback welcome.
This is your bi-yearly reminder that time is changing soon! October 25th in Europe, November 1st in North America. Less people in Canada are changing this year, with BC, Alberta, Manitoba and Northwest Territories getting rid of DST.

What's happening? Some places in the world implement what is called Daylight saving time or DST: https://en.wikipedia.org/wiki/Daylight_saving_time Normally, you shouldn't have to do anything: computers automatically change time following local rules, assuming they are correctly configured, provided recent updates have been applied in the case of a recent change in said rules (because yes, this happens, and happened this year, and yes, you need to upgrade your software!). Of course, appliances like your microwave oven will likely not change time and will need to adjusted unless they are so-called "smart", in which case they are part of the skynet botnet and should be destroyed. If your clock is flashing "0:00" or "12:00", you have no action to take to adapt to this change, lucky you. If you haven't changed time in six months, congratulations, your clock will be accurate again! In any case, you should still consider DST because it might affect some of your meeting schedules, particularly if you set up a new meeting schedule in the last 6 months and forgot to consider this change.

If your location does not have DST Properly scheduled meetings affecting multiple time zones are set in UTC time, which does not change. So if your location does not observer time changes, your (local!) meeting time will not change. But be aware that some other folks attending your meeting might have the DST bug and their meeting times will change. Be kind to those poor souls which might be missing meetings by a full hour because time flies backwards for them.

If you do observe DST If you are affected by daylight savings, your local meeting times will change for UTC meetings. Normally, your meeting times are scheduled to take this into account and the new hours should be reasonable. But now is a good time to verify that. Take a look at your schedule for the next couple of weeks and reschedule meetings before the daylight saving come up to avoid too much disruption. You have only a couple of weeks to do so right now.

When do times change, how, and and where? As regular readers will remember, the rule of thumb is:
Spring forward, fall backwards.
That is, during the season of Spring, the clocks move forward, and during the Fall (like right now), they move backwards. That is in the northern hemisphere, but then the southern hemisphere is often saner and doesn't switch anyways. So time will move backwards which means an extra hour of sleep. Unless you have children or bad sleep, in which case your body doesn't care about what the clock says and will wake up one hour earlier than what it should. And of course, this doesn't happen everywhere at once, so let's see when it happens where.

Europe The dance starts in Europe. The change happens on the last Sunday in October at 01:00 UTC (not local time!), that is October 25th. If you are in the central European timezone, also known as Amsterdam, Berlin, or Paris time depending on your national affiliation, that essentially means that at 2:59 local the clocks will fall back to 2:00 instead of going to 3:00. Concretely, set your watch back one hour before going to bed, go to bed at the normal time, and enjoy an extra hour of sleep or leisure. If you have kids, you might want to start getting them to bed slightly earlier every day for a week before the change so they take time getting used to the change. If you have trouble sleeping in the morning, find your inner child and do that to yourself as well.

USA / Canada Then it's the US[1] and Canada[2] joining the dance, on the First Sunday in November at 02:00 local (not UTC!), that is, I believe, November 1st 2026. This means that, at 1:59, the clocks will flip to 1:00, instead of 2:00. Concretely, do like the Europeans and tweak your clock before going to bed. That is a little less than four weeks from now. [1] except Arizona (except the Navajo nation), US territories, and Hawaii [2] except Yukon, Saskatchewan, (newly) British Columbia, (newly) Alberta, (newly) Northwest Territories, (newly) Manitoba, one island in Nunavut (Southampton Island), one town in Ontario (Atikokan) and small parts of Quebec (Le Golfe-du-Saint-Laurent)

Other places with DST This time again, I must apologize to the people of Cuba, Lebanon, Israel, Palestine, Egypt, Chile, Australia, and New Zealand, as you fine folks all have your own DST rules that are omitted here for brevity. I rely on this page from Wikipedia to be updated by time nerds accurately for this message, and it should provide you with a rough idea of what's coming: https://en.wikipedia.org/wiki/Daylight_saving_time_by_country In general, changes also happen in October, but either on different times or different days, except in the south hemisphere, where they might happen in September (oops, sorry NZ folks, I'm late!).

Places without DST Everyone else, enjoy, you're on the right side of history, and we thank you for the good example you give us.

Changes since last time There's been lots of changes since last time:
  • British Columbia moved to permanent -07 on 2026-03-09, that is it will not change to normal time in November
  • Alberta moved to permanent -06 on 2026-06-18, similar to BC above.
  • Canada s Northwest Territories moved to permanent -06 on 2026-08-21, matching Alberta.
  • Manitoba moves to permanent -05 on 2026-10-31.
  • Morocco moves to permanent +00 on 2026-09-20.
  • Moldova has used EU transition times since 2022, but the tz database only noticed in 2026
This is my interpretation of the changes announced on the tzdata mailing list here: https://lists.iana.org/hyperkitty/list/tz-announce@iana.org/latest If the eastward trend continues, Canada should adopt country-wide "no daylight savings" rules by 2027, although there's actually no sign of the other provinces (Ontario, Qu bec and so on) currently running bills to change those rules just yet. Poor Canadians like me confused about time in their countries can refer to this section of Wikipedia for details: https://en.wikipedia.org/wiki/Daylight_saving_time_in_Canada#By_province_and_territory ... and particularly the image featured there: https://commons.wikimedia.org/wiki/File:Canada_time_zone_map-en.svg It also seems like the US government might finally adopt a permanent daylight saving change bill in 2026, as the "Sunshine protection act" pass the house in July: https://en.wikipedia.org/wiki/Sunshine_Protection_Act True to form, this was associated with absolutely ridiculous pressure from Donald Trump against republicans (his own party!) objecting to the change:
On July 14, 2026, the House passed a Sunshine Protection Act bill backed by President Trump. Nevertheless, the bill was opposed in the Senate by Republicans, including Senator Cotton. In response, on October 3, 2026, Trump shared a post on Truth Social urging Cotton to approve the bill, where he revealed Cotton's personal cellphone number and called on people to call him.
https://www.theguardian.com/us-news/2026/oct/03/trump-tom-cotton-daylight-saving-time Given that the last time the US did a major change to the daylight savings policy (in 2005), Canada followed suit to stay in sync, it's quite possible Trump's mad dash might actually finish getting rid of DST in North America: https://en.wikipedia.org/wiki/Energy_Policy_Act_of_2005#Change_to_daylight_saving_time

Thorsten Alteholz: My Debian Activities in September 2026

Debian LTS/ELTS This was my hundred-forty-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on: Besides doing these uploads, the month was filled with unscheduled meetings, discussions and explanations, all basically around the role of FD. During my week of FD duties, I had to become familiar with new tools. As there are several things that FD has to do over and over again, I tried to automate this a bit. My experiments went well and I think this can be used to make FD duties less repetitive. I also continued my work on cups and hplip and I am confident that I can do uploads in October. Last but not least I spend some time on security-master to assist others (especially the kernel team) with uploads to Bookworm and Bullseye. In case you need to get a complete clone of the security-tracker, using the option deepen n might be of help. Unfortunately in case you choosed n too high and some kind of error appears, something gets into a mess and you need to start almost from the beginning (some objects are still present and are used again). If you want to run a script, a value of 10 might be a good choice. You don t have to deepen back to the beginning. At some point in time you can just unshallow and get the whole rest. Afterwards doing a git gc is highly recommended. Debian Printing This month I uploaded a new upstream version or a bugfix version of: This work is generously funded by Freexian! Debian Lomiri Unfortunately this month my work did not make any progress. Nevertheless, in case of any work done, this would have been generously funded by Fre(i)e Software GmbH! Debian Astro Unfortunately I had no time to work in this category this month. Debian IoT Unfortunately I had no time to work in this category this month. Debian Mobcom This month I uploaded a new upstream version or a bugfix version of: misc This month I uploaded a new upstream version or a bugfix version of:

6 October 2026

Russell Coker: A Power Case for a FOSS Phone

The Problem I want to use a FOSS phone running Debian as my daily driver and not use a non-free OS on my phone. GrapheneOS [1] is a FOSS rebuild of Android, it s a great project and I commend them for what they are doing. But I want a system where I have access to all the bits and where I can ssh in to it and manage it in the same way as all other Linux systems. Android is free software but it s a closed design and the phones are expected to be appliances not full peers on the network. The Android native terminal emulator (AKA Linux development environment) is a nice feature, a VM with a default of 1GB of RAM but it s still separate from the main OS. KDE Connect [2] is a system for KDE talking to phones, it is a great project and allows convenient interaction between a Linux PC and a phone. But in addition to that I d like the option to ssh to my phone to send an SMS or have one sent from a cron job. I blogged about using the basic functions of Kdeconnect from the command-line [3]. I have had ongoing issues with the battery not lasting long enough on the PinePhonePro (PPP) and the Librem 5 (L5) which makes them unusable for my purposes. For a phone running Droidian I can have an open ssh session (with keep-alive packets) running overnight on Wifi without any problems while for the PPP or L5 an hour of reading an ebook (the least demanding use of a phone) will use most of the battery. I sent my FuriPhone back for warranty repair and it s been almost a month with no follow up, so I need to have another option. The Aim The aim of this post is to develop a rough design for a battery case for either a L5 or a PPP, I have both phones and they are both capable of doing what I want apart from battery life. Also designing a case that basically works for both phones and has two variations of the CAD file for 3D printing is good to allow collaboration with people who use either phone. Protecting the phone from damage when dropped is also a core feature. I investigated commercial options. There are some reports of cases for other phones working, someone reported a PPP working well with a battery case for a Samsung S20 Ultra. The OtterBox uniVERSE Case for Samsung Galaxy XCover Pro is reported to fit the PPP so probably battery cases for the XCover Pro will also work. There are also universal power cases which have spring clips to fit a wide range of phone sizes, but they are much larger than other options and probably increase the risk of damage if the phone is dropped. At this stage I m planning out the rough specs of a case that can be 3D printed to protect a phone while being easy to change the cells. The process of changing cells should be quick, easy, and not risk breaking anything. The hardware required should be affordable ($100AU plus some 3D printing seems reasonable) and should not require significant skills to assemble. After recent experiments with Thinkpad repair I ve determined that I am not good at electronics by today s standards so I plan to avoid anything difficult in that regard. Battery Options There are phone cases with batteries built in for the more common phones. A quick search on AliExpress turned up options for recent Pixel phones. They aren t as common as they used to be as Android phones and iPhones generally have good battery life nowadays. Of course there aren t such options for less common phones like the L5 and PPP. It is cheap and easy to buy a portable battery for charging phones, but that s a separate bulky device and unless the connector is inside a protective case it leaves the phone vulnerable to catastrophic damage if dropped. So can a suitable battery case be designed and 3D printed? Cheap Batteries According to Wikipedia the 18650 LiIon cell is the most commonly used LiIon battery, that is 18mm in diameter and 65mm in length. For a phone case thinner batteries would be more convenient but economies of scale make the 18650 cheap to buy new and commonly available on the second hand market. The current prices on AliExpress (in Australian dollars) are about $8 per cell when buying 10 at a time. Most of the cells on AliExpress don t have wires attached so they can be swapped in a carrier the way AA batteries are used, but the cells are symmetrical (no bump for positive) so the user has to take care of polarity. Chargers are around $22 for a 4 cell charger or $52 for a 12 cell charger. I ve seen prices as low as $1 per cell on the second hand market, I haven t investigated the amount of usable capacity in such cells. Probably the prices for chargers I ve found aren t the best available but they are good enough to start the design. 10 cells and a 4 cell charger is about $100. That s about 130Wh while a 74Wh USB-C battery pack costs about $50. So the price per Wh is OK. I have read about an attempt to do this for the L5 with two of the batteries designed for the L5 in a case attached to it, so you have 3*L5 batteries. It s an interesting approach but those batteries have poor value for money when compared to 18650 ($29US for 4500mAh compared to $8 for 3500mAh) and they also don t ship them outside the US at this time. The 18650 batteries are available everywhere cheaply and have multiple uses. How They Fit According to my measurements the PPP is 76mm wide and the L5 is 73mm wide. That s wide enough for 3*18mm or 4*18mm cells side by side arranged parallel to the long side of the phone or one 65mm long cell going across the phone with the necessary spring and wires. The L5 is about 151mm long and the PPP is about 5mm longer. So that means that for just the cells we could have 2 cells in a row in parallel to the long side of the phone giving a 2*3 or 2*4 array or we could have a row of 8 cells parallel to the short side of the phone. A quick search for controllers for a battery of LiIon cells that outputs USB-PD turned up one of the smaller ones as 40*28mm, here is the AliExpress page [4]. So that means we could have a maximum of about 4 cells and the controller while leaving space for the camera. Looking at other similar items it seems that most of them take a large portion of the 73mm width available and take a bit less than 30mm height. The price range for DC-DC voltage converters ranges from about $3 to $20, the one I linked to is currently $8. The mass of 18650 cells is around 45g so 4 of them would be about 180g before counting the weight of the case and electronics. A L5 weighs 262g and a PPP weighs 220g so 180g of battery will make a significant difference, not an impossible difference but holding a PPP while reading an ebook is already annoying. Maybe the case could be designed to be easier to hold, a loop of wool attached to the top could be used to suspend the phone from one finger while the rest of the hand just keeps it steady. In a default configuration the L5 has a 4500mAh 3.8V battery and the PPP has a 3000mAh 3.8V battery. The 18650 cells have up to 4000mAh with 3500mAh being common. So 4 such cells could multiply the battery life of a PPP by a factor of 5 or a L5 by 4. That would not be enough to last for a whole day without charging so they need to be easy to swap. A 3 cell battery seems like a good option, 135g of batteries so the project overall wouldn t even double the weight of the phone with battery case. As it doesn t seem possible to put in enough cells to last a day of reasonable use (running a web browser, checking email, reading wikipedia, and having some IM systems checking for notifications) there doesn t seem to be a benefit in trying to stuff the maximum number of cells in. Going to 4 or 5 cells doesn t provide much benefit over 3 while increasing the weight and making the design more difficult. The modules for DC Voltage conversion often have configuration for the number of cells to be used so it wouldn t be difficult to print a new case and reconfigure the Voltage converter. Design A case needs to provide protection as well as hold the batteries. The lack of cases for the L5 and PPP is a problem even without the extra weight of a battery pack increasing the kinetic energy of falling phone. Ideally a drop from 1M on to concrete would not cause any damage to the phone, destruction of the case is OK as it would be 3D printed and can be rebuilt easily. I think that a case where the phone slides in from the top would be best. To change cells one would slide the phone out and the cells would be immediately accessible with no divider between the phone and the cells. Sliding the phone in would hold the cells against the back of the case and as there is a gap of about 3mm on each side of the PPP between the display area and the edge of the phone there s plenty of space for the case to wrap around it at the sides and bottom. At the top there would have to be some sort of plastic clip. The PPP only has buttons on the top right so the case can be snug on all sides apart from the top right. The L5 has switches at the top left and buttons at the top right so whatever clips on to the top would really need some strength to cover the fall flat on face case. The USB C plug would need to be held in place well enough to allow the phone to easily slide on to it but also be weak enough that it would move if a drop forced the phone out of the case. Thingiverse has a design for a L5 case [5] (with several derivatives) and a design for a PPP case [6]. Those cases could be used as starting points and then changed to store batteries and the voltage change circuit board. I have just learned that it s possible to use rubberised material in a 3D printer which is apparently what those designs are for. If a case was printed with rubberised material the top could just stick in place after being pushed in. Potential for Excessive Excitement Having an exploding device in your pocket would be the exciting in a bad way. My initial idea was to have multiple 18650 cells in series. The problem is that if the cells have different capacity levels then one can run out before the rest and get to a deep discharge state which at a minimum causes damage to the cell. One way of minimising risk is to have only a single cell in use at one time, here is a converter for a single cell to 5V [7]. It is possible to run multiple cells in parallel by simply wiring them together, but it s recommended to make sure that the voltage difference between cells is less than 0.2V to avoid high current when connecting. The arrangement of cells is often referred to as nS or nP to refer to n cells in series or parallel. Aliexpress has a range of 1S to 6S devices. Some of the 2S devices have a connector for the mid point which permits separate voltage monitoring for both cells but there doesn t seem to be anything equivalent for 3S or more. They also don t appear to have anything to specifically manage 2P or 3P arrangements at the moment (they had a 3P board on sale when I looked into this last year). Conclusion This is a bigger project than I expected when I first started investigating it. I ve played with FreeCAD which seems OK but will take a lot of learning and practice. Then I need to do more investigation into the DC-DC converters to find one that works well and is unlikely to start a fire. I will look into other phone options as well and keep chasing Furilabs people about my phone replacement.

5 October 2026

Utkarsh Gupta: FOSS Activities in September 2026

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t have much time, here are still a few things that I worked on:
  • Sponsored ubuntu-dev-tools/0.214 for Florent Skia Jacquet, which updates seeded-in-ubuntu to use the new per-series indexer (LP: #2160240).
  • Assisted a few folks in getting their patches submitted via Salsa.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021.
  • With 26.10 in Feature Freeze, wore my Release team hat to:
    • Review and approve a bunch of Feature Freeze Exceptions, including the Go 1.27 transition, Qt 6.11.2, rust-coreutils 0.12.0, devscripts 2.6.12, kdump-tools moving to dracut, and a few GCE packages.
    • Point linux-entra-sso to the SRU team, as it didn t need an FFe at all, and milestone a couple of bugs for 26.10.
  • Continued to push for infrastructure improvements:
    • Made ubuntu-cdimage more resilient to Launchpad hiccups (MP).
    • Taught generate-freeze-block in ubuntu-archive-tools a couple of new options (--skip-update and --series) and better error handling (MP).
    • Bumped the arm64 generic non-cloud image to 4.5G in livecd-rootfs and uploaded it as 26.10.16; also sponsored the follow-up 26.10.17 for Chlo .
  • Sponsored aevol/9.4.0-2ubuntu1 for Matthieu, fixing an FTBFS with GCC 15 s LTO (LP: #2167811).
  • Reviewed quite a lot of MPs - britney hints, meta-release, ubuntu-release-tools, ubuntu-archive-tools, ubuntu-cdimage, livecd-rootfs, ubuntu-seeds, and so on.
  • Enabled upgrades to 26.04 LTS.
  • Released 26.10 Beta and announced it on Discourse.
  • Did Archive Admin, DMB, and Release team duties as usual.

Debian (E)LTS
This month I have worked 33.5 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things: (A quick note that I did quite a lot of the work during my work as Frontdesk that went on till 4th Oct, so 33.50 hours include the work I did till 4th October 2026.)

Released Security Updates
  • node-lodash: Prototype pollution in _.unset and _.omit (plus a bypass of the initial fix for it), and code injection via the imports option of _.template.
    • [LTS]: Fixed CVE-2025-13465, CVE-2026-2950, and CVE-2026-4800 via 4.17.21+dfsg+~cs8.31.198.20210220-9+deb12u1 for bookworm. This has been released as DLA 4820-1.
    • This is the bookworm follow-up to DLA 4663-1 that I carried over from July. The update had been sitting prepared and tested on debusine, so once the upstream discussion wrapped up, it went straight out. It also carries an extra patch to the lodash-cli dependency map - without it, the regenerated lodash.template module throws assignWith is not defined at runtime, which node-gulp-util s autopkgtest caught.
  • libpng1.6: Use-after-free of zlib input in png_read_end() after incomplete zTXt, iTXt, or iCCP decompression, which could result in denial of service.

Work in Progress
  • libpng1.6: The same CVE-2026-46675.
    • [ELTS]: Claimed in ela-needed; the same upstream fix applies to all three ELTS suites, so this should go out shortly.

Other Activities
  • [E/LTS] Did my front-desk week from 28-09 to 04-10.
    • Over the week I did roughly:
      • Triage of 524 unique CVEs across 192 source packages and all four suites. And 1 automated ELTS end-of-life sweep.
      • Additional data is now part of the front-desk job too, so 75 commits record it for 179 CVEs across 71 packages.
    • Newly queued 22 source packages - 13 in dla-needed (apache2, chromium, firefox-esr, libnet-idn-encode-perl, libpng1.6, node-shell-quote, nvidia-graphics-drivers, openssl, pcre2, php-mongodb, php8.2, social-auth-core, and wpa) and 16 in ela-needed (apache2, firefox-esr, gegl, lemonldap-ng, libnet-idn-encode-perl, libpng1.6, libwebsockets, nsd, nvidia-graphics-drivers, pcre2, php7.0, php7.3, php7.4, rar, unrar-nonfree, and wpa), 7 of them in both. Also widened 3 ELTS entries to bullseye - antiword, ocaml, and openvswitch.
    • Most of the interesting work was again in the <not-affected> verdicts: 217 of 263 (83%, across 57 packages) rest on showing that the vulnerable code or feature isn t in the source we ship. Another 17 cover incomplete upstream fixes that we either never shipped or shipped with the follow-up already in (expat, libxml2, node-tar, and pyjwt). 15 come from bundled components we don t ship - node-ajv again, which uses uri-js and not fast-uri, and nvidia-open, which doesn t ship the NGX updater. And 13 are vendor- or platform-specific - openssh s CVE-2026-55654 lives only in a Red Hat GSSAPI patch, and the netdata and PHP ones only affect Windows.
    • Did 4 rounds of newly supported bullseye packages (33 packages overall), plus libmail-mboxparser-perl for buster - 34 in all. The existing CVE data mostly held up; the real finds were discovery gaps. One interesting gotcha: sid renamed stunnel4 to stunnel, and two new CVEs were associated only with the new name, so they never showed up for trixie, bookworm, or any ELTS suite. I also sorted the 180 Triage needed entries (57 packages) from elts-eol by where each was already handled, and triaged for ELTS the 100 that trixie or bookworm had already decided; the rest come next. And I imported 79 package-level lines for the older source names ELTS still ships (tomcat8, php7.0/7.3/7.4, netty-3.9, openssl1.0, python2.7/3.5/3.7, and pypy).
    • Caught some inconsistencies in released advisories: DLA 4801-1 (swift) was missing a CVE, ELA 1831-1 (redis) listed the wrong one, and DLA 4808-1 (network-manager-l2tp) listed CVE-2026-75883 - an ID that was renamed and then reassigned to an unrelated ppp issue. I fixed all three in the tracker s advisory lists.
    • Made the Security team and the uploaders aware of regressions from our own updates:
      • libde265: the CVE-2026-49337 fix in DLA 4789-1/ELA 1828-1 (and DSA 6413-1) misses upstream s follow-up commit.
      • libxml2 CVE-2026-76781 and policykit-1 CVE-2026-85498 were introduced by our own back-ports; the policykit-1 one is harmless.
      • expat: the CVE-2025-59375 backport in DLA 4807-1 is compiled out, because XML_GE is never defined.
      • xen: DLA 4818-1 s XSA-491 fix makes XSA-510 reachable.
      • gegl: the CVE-2026-2049/2050 back-port in ELA 1650-1 rejects valid RLE .hdr files.
      • log4cxx: DLA 4322-1 broke UTF-8 in JSONLayout output. That one is functional, not security.
    • Helped correct a set of triages and let the Debian Security team know:
      • ruby-json CVE-2026-71847: the vulnerable code was never in a released Debian version.
      • openssh CVE-2026-55654: only affects a Red Hat-specific GSSAPI patch.
      • three libxml2 issues that don t affect trixie either.
      • the stunnel4 rename above.
      • trixie <no-dsa> lines on jsch, node-qs, and ruby-loofah, where trixie s version doesn t have the vulnerable feature at all.
    • Independently found a security issue in rclone and reported it privately upstream through a GitHub security advisory. Upstream already had a report for the same issue, so they folded mine into the existing advisory and credited me as a co-reporter.
    • Also found some bugs in the additional-data tooling, e.g. cve-ad --package P --severity tbd wipes the CVE-level severity, and the schema doesn t validate package-level entries at all.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
  • [E/LTS] Attended the monthly LTS meeting on IRC. Meeting notes here.

Until next time.
:wq for today.

4 October 2026

Vincent Bernat: Hacking the Go compiler to efficiently map IPv4 to IPv6

netip.Addr features an Unmap() method returning the unwrapped IPv4 contained in an IPv4-mapped IPv6 address: from ::ffff:203.0.113.10 or ::ffff:cb00:710a, it returns 203.0.113.10.1 There is no Map() or To6() method for the reverse direction. Such a method is trivial to implement, but Go maintainers have rejected it on the grounds that users should write netip.AddrFrom16(ip.As16()) and let the compiler optimize it.2 Today, this pattern is eight times slower than a native method. How can we teach the compiler to optimize this sequence?

The alternatives Let s explore three ways to implement the map semantics for netip.Addr. My favorite is to add it to the Go standard library. Go maintainers prefer a small external helper chaining netip.AddrFrom16() and netip.Addr.As16(), hoping the compiler eventually optimizes it. The unsafe package opens a third path, with the same performance as the first solution.

Modifying the Go standard library Internally, netip.Addr stores any IP address as a 128-bit value with an extra field z to encode the family and the zone:
type Addr struct  
    addr uint128
    z unique.Handle[addrDetail]
 
type addrDetail struct  
    isV6   bool   // IPv4 is false, IPv6 is true.
    zoneV6 string // != "" only if IsV6 is true.
 
var (
    z0    unique.Handle[addrDetail]
    z4    = unique.Make(addrDetail )
    z6noz = unique.Make(addrDetail isV6: true )
)
AddrFrom4() encodes an IPv4 address as an IPv4-mapped IPv6 address and sets z to the unique value z4:
// AddrFrom4 returns the address of the IPv4 address given by the bytes in addr.
func AddrFrom4(addr [4]byte) Addr  
    return Addr 
        addr: uint128 
            0,
            0xffff00000000  
                uint64(addr[0])<<24   uint64(addr[1])<<16  
                uint64(addr[2])<<8   uint64(addr[3]) ,
        z: z4,
     
 
Unmap() turns an IPv4-mapped IPv6 address into an IPv4 address by setting the z field to z4:
func (ip Addr) Unmap() Addr  
    if ip.Is4In6()  
        ip.z = z4
     
    return ip
 
Implementing the reverse direction inside the Go standard library is trivial: we set the z field to z6noz if the address is IPv4.
// To6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func (ip Addr) To6() Addr  
    if ip.Is4()  
        ip.z = z6noz
     
    return ip
 

Update (2026-10) Instead of patching Go, we can use the -overlay flag of go build to hijack any package, including the standard library. In our case, it can add To6() to net/netip. Yet it is cumbersome:3 the flag expects a JSON file mapping absolute paths in GOROOT to replacement files, and you need to add it to every go command.

As a helper We can t access the z field from outside the net/netip package. Instead, we build a small helper around the netip.AddrFrom16(ip.As16()) pattern:
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr  
    if ip.Is4()  
        ip = netip.AddrFrom16(ip.As16())
     
    return ip
 

As an unsafe function Another solution uses the unsafe package to alter the Addr struct through a proxy with the same memory layout:4
// addrProxy has the same memory layout as netip.Addr.
type addrProxy struct  
    addr [2]uint64      // netip.uint128
    z    unsafe.Pointer // unique.Handle[netip.addrDetail]
 
var (
    anyIPv6    = netip.IPv6Unspecified()
    netipZ6noz = (*addrProxy)(unsafe.Pointer(&anyIPv6)).z
)
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr  
    if !ip.Is4()  
        return ip
     
    (*addrProxy)(unsafe.Pointer(&ip)).z = netipZ6noz
    return ip
 

Benchmarks On my computer, with Go 1.27.1, the standard library solution costs 0.88 ns per operation, while the solution favored by Go maintainers costs 7.14 ns. The unsafe solution matches the performance of the first one.
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
                         sec/op      
AddrTo6/safe            7.137n   0%
AddrTo6/unsafe         0.8682n   2%
AddrTo6/builtin        0.8775n   2%

Assembly code Let s check the assembly code the compiler generates for each solution.5 The one built into the standard library looks like this:6
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ  net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE   end                      ; if not, stop here
 MOVQ  net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
Go s assembly language is not a direct representation of the underlying machine language: it operates on a semi-abstract instruction set derived from Plan 9 s assembler. It has four pseudo-registers: FP (frame pointer for function arguments), PC (program counter), SB (static base pointer for global symbols), and SP (stack pointer). It also has architecture-specific registers like AX, CX, DX, BX, SI, DI, and R8 to R15. Instructions storing data use their last argument as the destination. Instructions can carry an explicit size suffix: MOVB moves a byte, MOVW 16 bits, MOVL 32 bits, and MOVQ 64 bits. In the example above, the first instruction compares the 64-bit value z4 with the CX register. The unsafe solution looks almost the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ  net/netip z4(SB), CX  ; check "z" if this is an IPv4 address
 JNE   end                   ; if not, stop here
 MOVQ  netipZ6noz(SB), CX    ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The helper solution has far more instructions. To understand why, let s look at the code for As16() and AddrFrom16(). They are short enough for the compiler to inline them.
func (ip Addr) As16() (a16 [16]byte)  
    byteorder.BEPutUint64(a16[:8], ip.addr.hi)
    byteorder.BEPutUint64(a16[8:], ip.addr.lo)
    return a16
 
func AddrFrom16(addr [16]byte) Addr  
    return Addr 
        addr: uint128 
            byteorder.BEUint64(addr[:8]),
            byteorder.BEUint64(addr[8:]),
         ,
        z: z6noz,
     
 
We can already guess the pattern to optimize: the code packs the IP address into an array, copies it, then unpacks it. If we inline the Go code by hand, we get:
func AddrTo6(input netip.Addr) netip.Addr  
    if !input.Is4()  
        return input
     
    var a16 [16]byte
    byteorder.BEPutUint64(a16[:8], input.addr.hi)
    byteorder.BEPutUint64(a16[8:], input.addr.lo)
    addr := a16
    var output netip.Addr
    output.addr.hi = byteorder.BEUint64(addr[:8])
    output.addr.lo = byteorder.BEUint64(addr[8:])
    output.z = netip.z6noz
    return output
 
As humans, we can mentally derive the optimized form:
func AddrTo6(input netip.Addr) netip.Addr  
    if !input.Is4()  
        return input
     
    var output netip.Addr
    output.addr.hi = input.addr.hi
    output.addr.lo = input.addr.lo
    output.z = netip.z6noz
    return output
 

Unfortunately, as of Go 1.26.8, the compiler is not smart enough to do the same:

// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (32 bytes):
;    0(SP) addr netip.uint128
;   16(SP) a16 [16]byte
 PUSHQ   BP
 MOVQ    SP, BP
 SUBQ    $32, SP
 CMPQ    net/netip z4(SB), CX  ; check "z" if this is an IPv4 address
 JNE     end                   ; if not, stop here
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
;       byteorder.BEPutUint64(a16[8:], input.addr.lo)
 MOVBEQ  AX, net/netip a16+16(SP)
 MOVBEQ  BX, net/netip a16+24(SP)
; addr = a16, 16 bytes at once through the vector register X0
 MOVUPS  net/netip a16+16(SP), X0
 MOVUPS  X0, net/netip addr(SP)
; CX = netip.z6noz
 MOVQ    net/netip z6noz(SB), CX
; Unpack: output.addr.hi = byteorder.BEUint64(addr[:8])
;         output.addr.lo = byteorder.BEUint64(addr[8:])
 MOVBEQ  net/netip addr(SP), AX
 MOVBEQ  net/netip addr+8(SP), BX
end:
 ADDQ    $32, SP
 POPQ    BP
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The compiler does a decent job on the byte shuffling: the eight byte stores of BEPutUint64() become a single MOVBEQ, which stores a register byte-swapped. The eight byte loads of BEUint64() become a single MOVBEQ the other way round.7 Three groups of instructions remain: a pack, a copy, and an unpack.

Hacking the Go compiler The Go compiler has several phases:
Parsing
The compiler tokenizes and parses the source code. It builds a syntax tree for each source file.
Type checking
The compiler maps each identifier to the object it denotes, folds constants, and infers the type of every expression.
IR construction
The compiler converts the syntax tree and its types into its own intermediate representation (IR). This process, called noding, goes through a serialization format named unified IR.
Middle end
The compiler performs several optimization passes on the IR, such as devirtualization, function call inlining, and escape analysis.
Walk
This phase runs two steps: order of evaluation decomposes complex statements into simpler ones, and desugaring transforms higher-level Go constructs, like switch or channels, into more primitive instructions or calls to the runtime.
Generic SSA
The compiler converts the IR into Static Single Assignment (SSA) form, a lower-level intermediate representation suited for machine-independent optimizations and rewrite rules.
Machine code generation
The compiler rewrites the SSA form into machine-specific variants, allocates registers, and applies more optimization passes. At the end, the assembler turns the generated instructions into machine code.

The hammer My first idea is to replace occurrences of netip.AddrFrom16(ip.As16()) with netip.Addr addr: ip.addr, z: netip.z6noz as early as possible, during the noding process. Before that, the type checking phase prevents us from accessing unexported struct fields. Go 1.27 introduced a convenient debug option to dump the IR of a function at interesting points during compilation:
$ GOTOOLCHAIN=go1.27.1 GOAMD64=v3 go build -a -gcflags="-d=astdump=AddrTo6Safe" .
Writing text ast output for AddrTo6Safe to AddrTo6Safe.ast
Writing html ast output for AddrTo6Safe to AddrTo6Safe.html
Writing html syntax output for AddrTo6Safe to AddrTo6Safe.syntax.html
In the HTML file, the first column shows the IR as it comes out of noding:
DCLFUNC addrto6.AddrTo6Safe ABI:ABIInternal FUNC-func(netip.Addr) netip.Addr
DCLFUNC-Dcl
. NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. NAME-addrto6.~r0 Class:PPARAMOUT Offset:0 OnStack netip.Addr
DCLFUNC-body
. IF # ipv6_safe.go:11:2
. IF-Cond
. . CALLFUNC bool
. . CALLFUNC-Fun
. . . METHEXPR addrto6.Is4 FUNC-func(netip.Addr) bool
. . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . CALLFUNC-Args
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. IF-Body
. . AS # ipv6_safe.go:12:6
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . CALLFUNC netip.Addr
. . . CALLFUNC-Fun
. . . . NAME-netip.AddrFrom16 Class:PFUNC Offset:0 Used FUNC-func([16]byte) netip.Addr
. . . CALLFUNC-Args
. . . . CALLFUNC ARRAY-[16]byte
. . . . CALLFUNC-Fun
. . . . . METHEXPR addrto6.As16 FUNC-func(netip.Addr) [16]byte
. . . . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . . . CALLFUNC-Args
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. RETURN # ipv6_safe.go:14:2
. RETURN-Results
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
In the body of the if statement, we spot the calls to the method netip.Addr.As16() and to the function netip.AddrFrom16(). Our goal is to patch them with a struct literal:
IF-Body
. AS # ipv6_safe.go:12:6
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . STRUCTLIT netip.Addr
. . STRUCTLIT-List
. . . STRUCTKEY netip.addr
. . . . DOT netip.addr netip.uint128
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . STRUCTKEY netip.z
. . . . NAME-netip.z6noz Class:PEXTERN Offset:0 unique.Handle[net/netip.addrDetail]
In noder s reader.go, the expr() method builds the IR tree for an expression. At the end of the exprCall case, we add a call to a rewriteAddrFrom16As16() function. It takes the current node and returns the struct literal on success, or nil if the rewrite is not possible. First, we check that we have the expected pattern: a call to the netip.AddrFrom16() function with a call to the netip.Addr.As16() method as its only argument:
func rewriteAddrFrom16As16(n ir.Node) ir.Node  
    call, ok := n.(*ir.CallExpr)
    if !ok   call.Op() != ir.OCALLFUNC  
        len(call.Args) != 1   len(call.Init()) != 0  
        !isNetipFunc(call.Fun, "AddrFrom16")  
        return nil
     
    inner, ok := call.Args[0].(*ir.CallExpr)
    if !ok   inner.Op() != ir.OCALLFUNC  
        len(inner.Args) != 1   len(inner.Init()) != 0  
        !isNetipFunc(inner.Fun, "Addr.As16")  
        return nil
     
    x := inner.Args[0]
    // [...]
 
Then, we fetch netip.z6noz:
z6noz, err := lookupVar(ir.StaticCalleeName(call.Fun).Sym().Pkg, "z6noz")
if err != nil  
    return nil
 
And we build the struct literal:
typ := call.Type()
pos := call.Pos()
var list []ir.Node
for i, f := range typ.Fields()  
    var value ir.Node
    switch f.Sym.Name  
    case "addr":
        value = typecheck.DotField(pos, x, i)
    case "z":
        value = z6noz
    default:
        return nil
     
    list = append(list, ir.NewStructKeyExpr(pos, f, value))
 
lit := ir.NewCompLitExpr(pos, ir.OSTRUCTLIT, typ, list)
lit.SetTypecheck(1)
return lit
Have a look at the complete patch.8 We can test it with the following commands:
$ cd src
$ ./make.bash
Building Go cmd/dist using /usr/lib/go-1.27. (go1.27.1 linux/amd64)
Building Go toolchain1 and bootstrap cmd/go (go_bootstrap) using /usr/lib/go-1.27.
Building Go toolchain2 using go_bootstrap and Go toolchain1.
Building Go toolchain3 and commands using go_bootstrap and Go toolchain2.
Checking command staleness for linux/amd64.
---
Installed Go for linux/amd64 in /home/bernat/code/free/go
Installed commands in /home/bernat/code/free/go/bin
*** You need to add /home/bernat/code/free/go/bin to your PATH.
$ export PATH=$PWD/../bin:$PATH
$ go version
go version go1.28-devel_9834516e20 Sat Sep 12 08:23:11 2026 -0700 linux/amd64
$ go test net/netip/...
ok      net/netip   0.224s
$ cd ../../go-netip-addrto6
$ go test .
ok      github.com/vincentbernat/go-netip-addrto6   0.062s
The generated code for the helper is now the shortest possible version!
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ    net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE     end                      ; if not, stop here
 MOVQ    net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
Go maintainers are unlikely to accept this change. It relies on the internal structure of net/netip.Addr. It s an ugly hack in the noder, whose job is to faithfully translate the type-checked AST into the IR. And it s harder to maintain than adding a To6() method.

The screwdriver The right place for such an optimization is the generic SSA phase. One of the last machine-independent passes is memcombine. With the appropriate debug flag, the compiler dumps the SSA form after this pass:9
$ GOTOOLCHAIN=go1.26.8 GOAMD64=v3 \
> go build -a -gcflags='-d=ssa/memcombine/dump=AddrTo6Safe' .
$ head -5 AddrTo6Safe_01__memcombine.dump
AddrTo6Safe func(netip.Addr) netip.Addr
  b2:
    (?) v1 = InitMem <mem>
    (?) v2 = SP <uintptr>
    (?) v3 = SB <uintptr>
The result of the memcombine pass follows the same structure as the assembly code for AddrTo6Safe() we looked at earlier: two stores, one move, and two loads we would like to optimize away.
; [ ]
  v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
  v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
  v466 = ArgIntReg <*netip.addrDetail>  ip+16  [2]  ; input.z
; [ ]
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
  v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
  v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
  v416 = Load <uint64> v285 v286                    ; addr[:8]
  v299 = Bswap64 <uint64> v416                      ; output.addr.hi
  v174 = Load <uint64> v415 v286                    ; addr[8:]
  v39  = Bswap64 <uint64> v174                      ; output.addr.lo
; [ ]
Each line features a value identifier (v442), an operation with its type (Bswap64 <uint64>), and its arguments (v490).10 Values are the basic building blocks of SSA and are defined exactly once. Square brackets enclose integer parameters ([8]) and curly braces contain auxiliary arguments ( netip.addr ). Operations writing to memory produce a new memory state. Every memory operation takes the current state as its last argument, which keeps them in order.

On paper Let s focus on output.addr.lo, aka v39:
  v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
  v174 = Load <uint64> v415 v286                    ; addr[8:]
  v39  = Bswap64 <uint64> v174                      ; output.addr.lo
To simplify this code, we could apply three rewriting rules:
  1. The first one adds a shortcut when loading through a move: (Load (OffPtr [o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). This matches v174 with its arguments v415 and v286 and creates a new value v600:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Load <uint64> v600 v282                    ; a16[8:]
      v39  = Bswap64 <uint64> v174                      ; output.addr.lo
    
  2. The second one simplifies a load following a store: (Load p (Store p x _)) => x. The load is forwarded: the stored value replaces it and no memory access remains. It matches v174. It notices that v600 and v173 are the same address and replaces v174 with a copy of v442:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Copy <uint64> v442                         ; bswap(input.addr.lo)
      v39  = Bswap64 <uint64> v174                      ; output.addr.lo
    
  3. The last step cancels the two byte swaps: (Bswap64 (Bswap64 x)) => x. v39 becomes a copy of v490:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Copy <uint64> v442                         ; bswap(input.addr.lo)
      v39  = Copy <uint64> v490                         ; output.addr.lo = input.addr.lo
    
If we ignore the values not needed to compute v39, only this SSA form remains:
  v490 = ArgIntReg <uint64>  ip+8  [1]  ; input.addr.lo
  v39  = Copy <uint64> v490             ; output.addr.lo = input.addr.lo
Let s switch to output.addr.hi, aka v299:
  v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
  v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v416 = Load <uint64> v285 v286                    ; addr[:8]
  v299 = Bswap64 <uint64> v416                      ; output.addr.hi
To optimize it away, we also apply three rewriting rules:
  1. The first one also adds a shortcut when loading through a move, but without an offset: (Load p (Move p src mem)) => (Load src mem). This rewrites v416 to use arguments from v286:
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Load <uint64> v22 v282                     ; a16[:8]
      v299 = Bswap64 <uint64> v416                      ; output.addr.hi
    
  2. The second rule forwards a value stored one step earlier, skipping over a store to another address: (Load p (Store q _ (Store p x _))) => x. This matches v416: x is v542, p is v22 (&a16), q is v173 (&a16[8]), and p and q do not overlap for uint64.
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Copy <uint64> v542                         ; bswap(input.addr.hi)
      v299 = Bswap64 <uint64> v416                      ; output.addr.hi
    
  3. The third rule cancels two byte swaps: (Bswap64 (Bswap64 x)) => x. v299 becomes a copy of v502:
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Copy <uint64> v542                         ; bswap(input.addr.hi)
      v299 = Copy <uint64> v502                         ; output.addr.hi = input.addr.hi
    
If we remove the values not used to compute v299, we get this SSA form:
  v502 = ArgIntReg <uint64>  ip+0  [0] ; input.addr.hi
  v299 = Copy <uint64> v502            ; output.addr.hi = input.addr.hi

In practice Most of these rules already exist in generic.rules. They use conditions to validate their context: ssa.IsSamePtr() for the same address, ssa.Disjoint() for addresses that do not overlap. The rule forwarding a stored value to a load already exists with three variants looking through several other stores. Here are the two we need:
(Load <t1> p1 (Store  t2  p2 x _))
    && ssa.IsSamePtr(p1, p2)
    && copyCompatibleType(t1, x.Type)
    && t1.Size() == t2.Size()
    => x
(Load <t1> p1 (Store  t2  p2 _ (Store  t3  p3 x _)))
    && ssa.IsSamePtr(p1, p3)
    && copyCompatibleType(t1, x.Type)
    && t1.Size() == t3.Size()
    && ssa.Disjoint(p3, t3, p2, t2)
    => x
Go 1.27 added the rule loading through a move with CL 748200 to fix issue #77720:
(Load <t1> op1:(OffPtr [o1] p1) move:(Move [n] p2 src mem))
    && o1 >= 0 && o1+t1.Size() <= n && ssa.IsSamePtr(p1, p2)
    && !ssa.IsVolatile(src)
    => @move.Block (Load <t1> (OffPtr <op1.Type> [o1] src) mem)
It lacks a variant without an offset:
(Load <t1> p1 move:(Move [n] p2 src mem))
    && p1.Op != ssaop.OpOffPtr
    && t1.Size() <= n && ssa.IsSamePtr(p1, p2)
    && !ssa.IsVolatile(src)
    => @move.Block (Load <t1> (OffPtr <p1.Type> [0] src) mem)
There is no generic rule to cancel two byte swaps, but the AMD64 lowering pass includes this rule:
(BSWAP(Q L) (BSWAP(Q L) p)) => p
After switching to Go s development branch and adding the missing rule, the generated assembly code is worse than with Go 1.26.8, even though our additional rule slightly improves the situation at the end:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (16 bytes):
;    0(SP) a16 [16]byte
 PUSHQ   BP
 MOVQ    SP, BP
 SUBQ    $16, SP
 CMPQ    net/netip z4(SB), CX       ; check "z" if this is an IPv4 address
 JNE     end                        ; if not, stop here
; The four forwarded bytes: the low half of input.addr.lo is taken apart and
; put back together in registers
 MOVQ    BX, DX                     ; DX = input.addr.lo
 SHRQ    $24, BX                    ; BX = input.addr.lo >> 24
 MOVQ    DX, SI                     ; SI = input.addr.lo
 SHRQ    $16, DX                    ; DX = input.addr.lo >> 16
 MOVQ    SI, DI                     ; DI = input.addr.lo, kept for the pack
 SHRQ    $8, SI                     ; SI = input.addr.lo >> 8
 MOVBLZX DIB, R8                    ; R8 = byte(input.addr.lo)
 MOVBLZX SIB, SI                    ; SI = byte(input.addr.lo >> 8)
 SHLQ    $8, SI
 ORQ     R8, SI                     ; SI = two low bytes of input.addr.lo
 MOVBLZX DL, DX                     ; DX = byte(input.addr.lo >> 16)
 SHLQ    $16, DX
 ORQ     SI, DX
 MOVBLZX BL, BX                     ; BX = byte(input.addr.lo >> 24)
 SHLQ    $24, BX
 ORQ     DX, BX                     ; BX = input.addr.lo & 0xffffffff
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
;       byteorder.BEPutUint64(a16[8:], input.addr.lo)
 MOVBEQ  AX, net/netip a16(SP)
 MOVBEQ  DI, net/netip a16+8(SP)
; The four other bytes of input.addr.lo, read one by one from a16
 MOVBLZX net/netip a16+11(SP), DX   ; a16[11]
 SHLQ    $32, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+10(SP), DX   ; a16[10]
 SHLQ    $40, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+9(SP), DX    ; a16[9]
 SHLQ    $48, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+8(SP), DX    ; a16[8]
 SHLQ    $56, DX
; output.z = netip.z6noz
 MOVQ    net/netip z6noz(SB), CX
; output.addr.hi = byteorder.BEUint64(a16[:8])
 MOVBEQ  net/netip a16(SP), AX
; output.addr.lo assembled from the previous steps
 ORQ     DX, BX
end:
 LEAVEQ
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The rule loading through a move, added in Go 1.27, introduced this regression.

Out of order Let s not give up now! In reality, the rewriting rules run before memcombine, notably in the late opt pass. At this point, the inlined versions of BEPutUint64() and BEUint64() still expand to sixteen byte stores and sixteen byte loads, matching their source code:
func BEUint64(b []byte) uint64  
    _ = b[7] // bounds check hint to compiler; see golang.org/issue/14808
    return uint64(b[7])   uint64(b[6])<<8   uint64(b[5])<<16   uint64(b[4])<<24  
        uint64(b[3])<<32   uint64(b[2])<<40   uint64(b[1])<<48   uint64(b[0])<<56
 
Let s follow two bytes of output.addr.lo: addr[15] and addr[11]. Here is a simplified SSA form before late opt:
  v273 = Trunc64to8 <byte> v490                     ; byte(input.addr.lo)
  v226 = Trunc64to8 <byte> v225                     ; byte(input.addr.lo >> 32)
; [ ]
  v235 = Store <mem>  byte  v233 v226 v223          ; a16[11] = byte(lo >> 32)
  v247 = Store <mem>  byte  v245 v238 v235          ; a16[12] =  
  v259 = Store <mem>  byte  v257 v250 v247          ; a16[13] =  
  v271 = Store <mem>  byte  v269 v262 v259          ; a16[14] =  
  v282 = Store <mem>  byte  v280 v273 v271          ; a16[15] = byte(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
; [ ]
  v433 = OffPtr <*byte> [15] v285                   ; &addr[15]
  v435 = Load <byte> v433 v286                      ; addr[15]
  v479 = OffPtr <*byte> [11] v285                   ; &addr[11]
  v481 = Load <byte> v479 v286                      ; addr[11]
The first rule loads through the move: (Load (OffPtr [o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). It matches both loads, which now read a16 with the memory state before the copy:
  v600 = OffPtr <*byte> [15] v22 ; &a16[15]
  v435 = Load <byte> v600 v282   ; a16[15]
  v601 = OffPtr <*byte> [11] v22 ; &a16[11]
  v481 = Load <byte> v601 v282   ; a16[11]
The second rule shortcuts a load following a store: (Load p (Store p x _)) => x. It matches v435, as v282 stores a16[15]. It does not match v481: v235 stores a16[11] four stores earlier in the chain, while the variants of this rule look through three stores at most.
  v435 = Copy <byte> v273        ; byte(input.addr.lo)
  v601 = OffPtr <*byte> [11] v22 ; &a16[11]
  v481 = Load <byte> v601 v282   ; a16[11]
The same happens to the other bytes: the rule forwards the four bytes stored last, a16[12] to a16[15]. The twelve other loads now read a16 instead of addr. BEUint64() becomes a chain of Or64, each one adding a byte shifted into place. memcombine is a pass written in Go, not a set of rewrite rules. It starts from the last Or64 of the chain and collects up to eight terms. If each term is a byte load, extended to 64 bits and shifted, and if the eight loads read consecutive addresses from the same pointer with the same memory state, it replaces the whole chain with a single 64-bit load and a byte swap. Otherwise, it tries again with four, then two terms, and from each intermediate Or64. Here is the loop checking each term in a simplified version of combineLoads():
for i := int64(0); i < n; i++  
    v := a[i]
    shift := int64(0)
    if v.Op == shiftOp  
        v, shift = peelShift(v)
     
    if v.Op != extOp  
        return false
     
    load := v.Args[0]
    if load.Op != ssaop.OpLoad  
        return false
     
    if load.Args[1] != mem  
        return false
     
    p, off := splitPtr(load.Args[0])
    if p != base  
        return false
     
    r[i] = LoadRecord load: load, offset: off, shift: shift 
 
For output.addr.hi, the eight loads read a16 with the same memory state v282:
  v13  = Load <byte> v22 v282               ; a16[0]
  v530 = Load <byte> v14 v282               ; a16[1]
  v488 = Load <byte> v504 v282              ; a16[2]
  v405 = Load <byte> v537 v282              ; a16[3]
  v385 = Load <byte> v397 v282              ; a16[4]
  v361 = Load <byte> v373 v282              ; a16[5]
  v196 = Load <byte> v63 v282               ; a16[6]
  v432 = Load <byte> v315 v282              ; a16[7]
  v319 = ZeroExt8to64 <uint64> v432         ; uint64(a16[7])
  v329 = ZeroExt8to64 <uint64> v196         ; uint64(a16[6])
  v330 = Lsh64x64 <uint64> [true] v329 v138 ; uint64(a16[6]) << 8
  v331 = Or64 <uint64> v319 v330            ; a16[7]   a16[6] << 8
; [ ] same for a16[5] to a16[1]
  v401 = ZeroExt8to64 <uint64> v13          ; uint64(a16[0])
  v402 = Lsh64x64 <uint64> [true] v401 v55  ; uint64(a16[0]) << 56
  v403 = Or64 <uint64> v402 v391            ;   a16[0] << 56 = output.addr.hi
memcombine merges them into one load and a swap:
  v286 = Load <uint64> v22 v282   ; a16[:8]
  v285 = Bswap64 <uint64> v286    ; output.addr.hi
For output.addr.lo, here is the chain memcombine sees after late opt:
  v436 = ZeroExt8to64 <uint64> v273 ; addr[15], forwarded
  v448 = Or64 <uint64> v436 v447    ;   addr[14] << 8, forwarded
  v460 = Or64 <uint64> v459 v448    ;   addr[13] << 16, forwarded
  v472 = Or64 <uint64> v471 v460    ;   addr[12] << 24, forwarded
  v484 = Or64 <uint64> v483 v472    ;   a16[11] << 32, loaded
  v496 = Or64 <uint64> v495 v484    ;   a16[10] << 40, loaded
  v508 = Or64 <uint64> v507 v496    ;   a16[9] << 48, loaded
  v520 = Or64 <uint64> v519 v508    ;   a16[8] << 56, loaded
From v520, four of the eight terms are forwarded bytes, not loads from memory, and memcombine can t combine them. It doesn t merge the four remaining loads either, as they sit on top of the forwarded bytes.

Back in order In summary, the rewriting rules run too early to be effective. A quick workaround exists: run an earlier round of memcombine before late opt. After this change, the generated code for the helper is back to the shortest possible version:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ    net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE     end                      ; if not, stop here
 MOVQ    net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
And the benchmark confirms it!
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
                       Go 1.26.8                  Our branch               
                         sec/op          sec/op     vs base                
AddrTo6/safe          6.5470n    0%   0.8944n   4%  -86.34% (p=0.002 n=6)
AddrTo6/unsafe        0.9071n    3%   0.8682n   1%   -4.28% (p=0.002 n=6)
AddrTo6/builtin       0.8871n    2%   0.8785n   1%        ~ (p=0.310 n=6)

Next steps I think Go maintainers would reject this change because of the additional memcombine pass. Instead, I plan to publish this blog post and bring up the subject again as a follow-up to issue #54365. Either the sheer complexity and the Go 1.27 regression convince the maintainers that adding a To6() method is simpler and more efficient, or they advise me on how to move forward. Either way, digging into this subject taught me a lot about the Go compiler!

Update (2026-10) I opened issue #81994 to propose Addr.To6(). Give it a if you want it in Go!


  1. IPv4-mapped IPv6 addresses let you handle only IPv6 addresses in your code and keep conversions at a few well-defined boundaries. I use them in Akvorado.
  2. This is not strictly equivalent. The zero value becomes :: while it would make more sense to leave it untouched.
  3. I suppose Go maintainers keep it inconvenient on purpose: they don t want random packages to patch the standard library or other packages.
  4. To avoid catastrophic bugs when netip.Addr s layout changes, you must add tests to detect it. This is more dangerous if you put this code in a package. Either ask users to run the tests themselves, or detect the change at run time and panic. Hiding this optimization behind a build tag would make users aware of this potential trap.
  5. I produced the assembly code with GOTOOLCHAIN=go1.26.8 GOAMD64=v3 ./go-asm '\.asm' from the companion repository, then edited it a bit to keep this article from turning into an endless rabbit hole. Due to an unfortunate sequence of events, we switch between versions: Go 1.27 introduced a regression that blurs the point of this article.
  6. The function is short enough for the compiler to inline it, so the assembly code may vary depending on the surrounding code.
  7. MOVBEQ requires GOAMD64=v3, matching the x86-64-v3 microarchitecture from 2013. Otherwise, the compiler translates BEPutUint64() to BSWAPQ+MOVQ and BEUint64() to MOVQ+BSWAPQ.
  8. When the call is used as a statement, a struct literal alone is invalid. The patch then turns it into _ = netip.Addr .
  9. The compiler can also write an HTML file with the result of each pass:
    $ GOSSAFUNC=AddrTo6Safe \
    > GOTOOLCHAIN=go1.26.8 \
    > GOAMD64=v3 go build -a .
    dumped SSA for AddrTo6Safe,1 to ./ssa.html
    
  10. Source line numbers in parentheses follow value identifiers, but I removed them from the examples. The SSA form also features branches, but we don t need them to understand our optimizations.

Vincent Bernat: Hacking the Go compiler to efficiently map IPv4 to IPv6

netip.Addr features an Unmap() method returning the unwrapped IPv4 contained in an IPv4-mapped IPv6 address: from ::ffff:203.0.113.10 or ::ffff:cb00:710a, it returns 203.0.113.10.1 There is no Map() or To6() method for the reverse direction. Such a method is trivial to implement, but Go maintainers have rejected it on the grounds that users should write netip.AddrFrom16(ip.As16()) and let the compiler optimize it.2 Today, this pattern is eight times slower than a native method. How can we teach the compiler to optimize this sequence?

The alternatives Let s explore three ways to implement the map semantics for netip.Addr. My favorite is to add it to the Go standard library. Go maintainers prefer a small external helper chaining netip.AddrFrom16() and netip.Addr.As16(), hoping the compiler eventually optimizes it. The unsafe package opens a third path, with the same performance as the first solution.

Modifying the Go standard library Internally, netip.Addr stores any IP address as a 128-bit value with an extra field z to encode the family and the zone:
type Addr struct  
    addr uint128
    z unique.Handle[addrDetail]
 
type addrDetail struct  
    isV6   bool   // IPv4 is false, IPv6 is true.
    zoneV6 string // != "" only if IsV6 is true.
 
var (
    z0    unique.Handle[addrDetail]
    z4    = unique.Make(addrDetail )
    z6noz = unique.Make(addrDetail isV6: true )
)
AddrFrom4() encodes an IPv4 address as an IPv4-mapped IPv6 address and sets z to the unique value z4:
// AddrFrom4 returns the address of the IPv4 address given by the bytes in addr.
func AddrFrom4(addr [4]byte) Addr  
    return Addr 
        addr: uint128 
            0,
            0xffff00000000  
                uint64(addr[0])<<24   uint64(addr[1])<<16  
                uint64(addr[2])<<8   uint64(addr[3]) ,
        z: z4,
     
 
Unmap() turns an IPv4-mapped IPv6 address into an IPv4 address by setting the z field to z4:
func (ip Addr) Unmap() Addr  
    if ip.Is4In6()  
        ip.z = z4
     
    return ip
 
Implementing the reverse direction inside the Go standard library is trivial: we set the z field to z6noz if the address is IPv4.
// To6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func (ip Addr) To6() Addr  
    if ip.Is4()  
        ip.z = z6noz
     
    return ip
 

As a helper We can t access the z field from outside the net/netip package. Instead, we build a small helper around the netip.AddrFrom16(ip.As16()) pattern:
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr  
    if ip.Is4()  
        ip = netip.AddrFrom16(ip.As16())
     
    return ip
 

As an unsafe function Another solution uses the unsafe package to alter the Addr struct through a proxy with the same memory layout:3
// addrProxy has the same memory layout as netip.Addr.
type addrProxy struct  
    addr [2]uint64      // netip.uint128
    z    unsafe.Pointer // unique.Handle[netip.addrDetail]
 
var (
    anyIPv6    = netip.IPv6Unspecified()
    netipZ6noz = (*addrProxy)(unsafe.Pointer(&anyIPv6)).z
)
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr  
    if !ip.Is4()  
        return ip
     
    (*addrProxy)(unsafe.Pointer(&ip)).z = netipZ6noz
    return ip
 

Benchmarks On my computer, with Go 1.27.1, the standard library solution costs 0.88 ns per operation, while the solution favored by Go maintainers costs 7.14 ns. The unsafe solution matches the performance of the first one.
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
                         sec/op      
AddrTo6/safe            7.137n   0%
AddrTo6/unsafe         0.8682n   2%
AddrTo6/builtin        0.8775n   2%

Assembly code Let s check the assembly code the compiler generates for each solution.4 The one built into the standard library looks like this:5
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ  net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE   end                      ; if not, stop here
 MOVQ  net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
Go s assembly language is not a direct representation of the underlying machine language: it operates on a semi-abstract instruction set derived from Plan 9 s assembler. It has four pseudo-registers: FP (frame pointer for function arguments), PC (program counter), SB (static base pointer for global symbols), and SP (stack pointer). It also has architecture-specific registers like AX, CX, DX, BX, SI, DI, and R8 to R15. Instructions storing data use their last argument as the destination. Instructions can carry an explicit size suffix: MOVB moves a byte, MOVW 16 bits, MOVL 32 bits, and MOVQ 64 bits. In the example above, the first instruction compares the 64-bit value z4 with the CX register. The unsafe solution looks almost the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ  net/netip z4(SB), CX  ; check "z" if this is an IPv4 address
 JNE   end                   ; if not, stop here
 MOVQ  netipZ6noz(SB), CX    ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The helper solution has far more instructions. To understand why, let s look at the code for As16() and AddrFrom16(). They are short enough for the compiler to inline them.
func (ip Addr) As16() (a16 [16]byte)  
    byteorder.BEPutUint64(a16[:8], ip.addr.hi)
    byteorder.BEPutUint64(a16[8:], ip.addr.lo)
    return a16
 
func AddrFrom16(addr [16]byte) Addr  
    return Addr 
        addr: uint128 
            byteorder.BEUint64(addr[:8]),
            byteorder.BEUint64(addr[8:]),
         ,
        z: z6noz,
     
 
We can already guess the pattern to optimize: the code packs the IP address into an array, copies it, then unpacks it. If we inline the Go code by hand, we get:
func AddrTo6(input netip.Addr) netip.Addr  
    if !input.Is4()  
        return input
     
    var a16 [16]byte
    byteorder.BEPutUint64(a16[:8], input.addr.hi)
    byteorder.BEPutUint64(a16[8:], input.addr.lo)
    addr := a16
    var output netip.Addr
    output.addr.hi = byteorder.BEUint64(addr[:8])
    output.addr.lo = byteorder.BEUint64(addr[8:])
    output.z = netip.z6noz
    return output
 
As humans, we can mentally derive the optimized form:
func AddrTo6(input netip.Addr) netip.Addr  
    if !input.Is4()  
        return input
     
    var output netip.Addr
    output.addr.hi = input.addr.hi
    output.addr.lo = input.addr.lo
    output.z = netip.z6noz
    return output
 

Unfortunately, as of Go 1.26.8, the compiler is not smart enough to do the same:

// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (32 bytes):
;    0(SP) addr netip.uint128
;   16(SP) a16 [16]byte
 PUSHQ   BP
 MOVQ    SP, BP
 SUBQ    $32, SP
 CMPQ    net/netip z4(SB), CX  ; check "z" if this is an IPv4 address
 JNE     end                   ; if not, stop here
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
;       byteorder.BEPutUint64(a16[8:], input.addr.lo)
 MOVBEQ  AX, net/netip a16+16(SP)
 MOVBEQ  BX, net/netip a16+24(SP)
; addr = a16, 16 bytes at once through the vector register X0
 MOVUPS  net/netip a16+16(SP), X0
 MOVUPS  X0, net/netip addr(SP)
; CX = netip.z6noz
 MOVQ    net/netip z6noz(SB), CX
; Unpack: output.addr.hi = byteorder.BEUint64(addr[:8])
;         output.addr.lo = byteorder.BEUint64(addr[8:])
 MOVBEQ  net/netip addr(SP), AX
 MOVBEQ  net/netip addr+8(SP), BX
end:
 ADDQ    $32, SP
 POPQ    BP
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The compiler does a decent job on the byte shuffling: the eight byte stores of BEPutUint64() become a single MOVBEQ, which stores a register byte-swapped. The eight byte loads of BEUint64() become a single MOVBEQ the other way round.6 Three groups of instructions remain: a pack, a copy, and an unpack.

Hacking the Go compiler The Go compiler has several phases:
Parsing
The compiler tokenizes and parses the source code. It builds a syntax tree for each source file.
Type checking
The compiler maps each identifier to the object it denotes, folds constants, and infers the type of every expression.
IR construction
The compiler converts the syntax tree and its types into its own intermediate representation (IR). This process, called noding, goes through a serialization format named unified IR.
Middle end
The compiler performs several optimization passes on the IR, such as devirtualization, function call inlining, and escape analysis.
Walk
This phase runs two steps: order of evaluation decomposes complex statements into simpler ones, and desugaring transforms higher-level Go constructs, like switch or channels, into more primitive instructions or calls to the runtime.
Generic SSA
The compiler converts the IR into Static Single Assignment (SSA) form, a lower-level intermediate representation suited for machine-independent optimizations and rewrite rules.
Machine code generation
The compiler rewrites the SSA form into machine-specific variants, allocates registers, and applies more optimization passes. At the end, the assembler turns the generated instructions into machine code.

The hammer My first idea is to replace occurrences of netip.AddrFrom16(ip.As16()) with netip.Addr addr: ip.addr, z: netip.z6noz as early as possible, during the noding process. Before that, the type checking phase prevents us from accessing unexported struct fields. Go 1.27 introduced a convenient debug option to dump the IR of a function at interesting points during compilation:
$ GOTOOLCHAIN=go1.27.1 GOAMD64=v3 go build -a -gcflags="-d=astdump=AddrTo6Safe" .
Writing text ast output for AddrTo6Safe to AddrTo6Safe.ast
Writing html ast output for AddrTo6Safe to AddrTo6Safe.html
Writing html syntax output for AddrTo6Safe to AddrTo6Safe.syntax.html
In the HTML file, the first column shows the IR as it comes out of noding:
DCLFUNC addrto6.AddrTo6Safe ABI:ABIInternal FUNC-func(netip.Addr) netip.Addr
DCLFUNC-Dcl
. NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. NAME-addrto6.~r0 Class:PPARAMOUT Offset:0 OnStack netip.Addr
DCLFUNC-body
. IF # ipv6_safe.go:11:2
. IF-Cond
. . CALLFUNC bool
. . CALLFUNC-Fun
. . . METHEXPR addrto6.Is4 FUNC-func(netip.Addr) bool
. . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . CALLFUNC-Args
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. IF-Body
. . AS # ipv6_safe.go:12:6
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . CALLFUNC netip.Addr
. . . CALLFUNC-Fun
. . . . NAME-netip.AddrFrom16 Class:PFUNC Offset:0 Used FUNC-func([16]byte) netip.Addr
. . . CALLFUNC-Args
. . . . CALLFUNC ARRAY-[16]byte
. . . . CALLFUNC-Fun
. . . . . METHEXPR addrto6.As16 FUNC-func(netip.Addr) [16]byte
. . . . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . . . CALLFUNC-Args
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. RETURN # ipv6_safe.go:14:2
. RETURN-Results
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
In the body of the if statement, we spot the calls to the method netip.Addr.As16() and to the function netip.AddrFrom16(). Our goal is to patch them with a struct literal:
IF-Body
. AS # ipv6_safe.go:12:6
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . STRUCTLIT netip.Addr
. . STRUCTLIT-List
. . . STRUCTKEY netip.addr
. . . . DOT netip.addr netip.uint128
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . STRUCTKEY netip.z
. . . . NAME-netip.z6noz Class:PEXTERN Offset:0 unique.Handle[net/netip.addrDetail]
In noder s reader.go, the expr() method builds the IR tree for an expression. At the end of the exprCall case, we add a call to a rewriteAddrFrom16As16() function. It takes the current node and returns the struct literal on success, or nil if the rewrite is not possible. First, we check that we have the expected pattern: a call to the netip.AddrFrom16() function with a call to the netip.Addr.As16() method as its only argument:
func rewriteAddrFrom16As16(n ir.Node) ir.Node  
    call, ok := n.(*ir.CallExpr)
    if !ok   call.Op() != ir.OCALLFUNC  
        len(call.Args) != 1   len(call.Init()) != 0  
        !isNetipFunc(call.Fun, "AddrFrom16")  
        return nil
     
    inner, ok := call.Args[0].(*ir.CallExpr)
    if !ok   inner.Op() != ir.OCALLFUNC  
        len(inner.Args) != 1   len(inner.Init()) != 0  
        !isNetipFunc(inner.Fun, "Addr.As16")  
        return nil
     
    x := inner.Args[0]
    // [...]
 
Then, we fetch netip.z6noz:
z6noz, err := lookupVar(ir.StaticCalleeName(call.Fun).Sym().Pkg, "z6noz")
if err != nil  
    return nil
 
And we build the struct literal:
typ := call.Type()
pos := call.Pos()
var list []ir.Node
for i, f := range typ.Fields()  
    var value ir.Node
    switch f.Sym.Name  
    case "addr":
        value = typecheck.DotField(pos, x, i)
    case "z":
        value = z6noz
    default:
        return nil
     
    list = append(list, ir.NewStructKeyExpr(pos, f, value))
 
lit := ir.NewCompLitExpr(pos, ir.OSTRUCTLIT, typ, list)
lit.SetTypecheck(1)
return lit
Have a look at the complete patch.7 We can test it with the following commands:
$ cd src
$ ./make.bash
Building Go cmd/dist using /usr/lib/go-1.27. (go1.27.1 linux/amd64)
Building Go toolchain1 and bootstrap cmd/go (go_bootstrap) using /usr/lib/go-1.27.
Building Go toolchain2 using go_bootstrap and Go toolchain1.
Building Go toolchain3 and commands using go_bootstrap and Go toolchain2.
Checking command staleness for linux/amd64.
---
Installed Go for linux/amd64 in /home/bernat/code/free/go
Installed commands in /home/bernat/code/free/go/bin
*** You need to add /home/bernat/code/free/go/bin to your PATH.
$ export PATH=$PWD/../bin:$PATH
$ go version
go version go1.28-devel_9834516e20 Sat Sep 12 08:23:11 2026 -0700 linux/amd64
$ go test net/netip/...
ok      net/netip   0.224s
$ cd ../../go-netip-addrto6
$ go test .
ok      github.com/vincentbernat/go-netip-addrto6   0.062s
The generated code for the helper is now the shortest possible version!
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ    net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE     end                      ; if not, stop here
 MOVQ    net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
Go maintainers are unlikely to accept this change. It relies on the internal structure of net/netip.Addr. It s an ugly hack in the noder, whose job is to faithfully translate the type-checked AST into the IR. And it s harder to maintain than adding a To6() method.

The screwdriver The right place for such an optimization is the generic SSA phase. One of the last machine-independent passes is memcombine. With the appropriate debug flag, the compiler dumps the SSA form after this pass:8
$ GOTOOLCHAIN=go1.26.8 GOAMD64=v3 \
> go build -a -gcflags='-d=ssa/memcombine/dump=AddrTo6Safe' .
$ head -5 AddrTo6Safe_01__memcombine.dump
AddrTo6Safe func(netip.Addr) netip.Addr
  b2:
    (?) v1 = InitMem <mem>
    (?) v2 = SP <uintptr>
    (?) v3 = SB <uintptr>
The result of the memcombine pass follows the same structure as the assembly code for AddrTo6Safe() we looked at earlier: two stores, one move, and two loads we would like to optimize away.
; [ ]
  v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
  v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
  v466 = ArgIntReg <*netip.addrDetail>  ip+16  [2]  ; input.z
; [ ]
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
  v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
  v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
  v416 = Load <uint64> v285 v286                    ; addr[:8]
  v299 = Bswap64 <uint64> v416                      ; output.addr.hi
  v174 = Load <uint64> v415 v286                    ; addr[8:]
  v39  = Bswap64 <uint64> v174                      ; output.addr.lo
; [ ]
Each line features a value identifier (v442), an operation with its type (Bswap64 <uint64>), and its arguments (v490).9 Values are the basic building blocks of SSA and are defined exactly once. Square brackets enclose integer parameters ([8]) and curly braces contain auxiliary arguments ( netip.addr ). Operations writing to memory produce a new memory state. Every memory operation takes the current state as its last argument, which keeps them in order.

On paper Let s focus on output.addr.lo, aka v39:
  v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
  v174 = Load <uint64> v415 v286                    ; addr[8:]
  v39  = Bswap64 <uint64> v174                      ; output.addr.lo
To simplify this code, we could apply three rewriting rules:
  1. The first one adds a shortcut when loading through a move: (Load (OffPtr [o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). This matches v174 with its arguments v415 and v286 and creates a new value v600:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Load <uint64> v600 v282                    ; a16[8:]
      v39  = Bswap64 <uint64> v174                      ; output.addr.lo
    
  2. The second one simplifies a load following a store: (Load p (Store p x _)) => x. The load is forwarded: the stored value replaces it and no memory access remains. It matches v174. It notices that v600 and v173 are the same address and replaces v174 with a copy of v442:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Copy <uint64> v442                         ; bswap(input.addr.lo)
      v39  = Bswap64 <uint64> v174                      ; output.addr.lo
    
  3. The last step cancels the two byte swaps: (Bswap64 (Bswap64 x)) => x. v39 becomes a copy of v490:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Copy <uint64> v442                         ; bswap(input.addr.lo)
      v39  = Copy <uint64> v490                         ; output.addr.lo = input.addr.lo
    
If we ignore the values not needed to compute v39, only this SSA form remains:
  v490 = ArgIntReg <uint64>  ip+8  [1]  ; input.addr.lo
  v39  = Copy <uint64> v490             ; output.addr.lo = input.addr.lo
Let s switch to output.addr.hi, aka v299:
  v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
  v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v416 = Load <uint64> v285 v286                    ; addr[:8]
  v299 = Bswap64 <uint64> v416                      ; output.addr.hi
To optimize it away, we also apply three rewriting rules:
  1. The first one also adds a shortcut when loading through a move, but without an offset: (Load p (Move p src mem)) => (Load src mem). This rewrites v416 to use arguments from v286:
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Load <uint64> v22 v282                     ; a16[:8]
      v299 = Bswap64 <uint64> v416                      ; output.addr.hi
    
  2. The second rule forwards a value stored one step earlier, skipping over a store to another address: (Load p (Store q _ (Store p x _))) => x. This matches v416: x is v542, p is v22 (&a16), q is v173 (&a16[8]), and p and q do not overlap for uint64.
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Copy <uint64> v542                         ; bswap(input.addr.hi)
      v299 = Bswap64 <uint64> v416                      ; output.addr.hi
    
  3. The third rule cancels two byte swaps: (Bswap64 (Bswap64 x)) => x. v299 becomes a copy of v502:
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Copy <uint64> v542                         ; bswap(input.addr.hi)
      v299 = Copy <uint64> v502                         ; output.addr.hi = input.addr.hi
    
If we remove the values not used to compute v299, we get this SSA form:
  v502 = ArgIntReg <uint64>  ip+0  [0] ; input.addr.hi
  v299 = Copy <uint64> v502            ; output.addr.hi = input.addr.hi

In practice Most of these rules already exist in generic.rules. They use conditions to validate their context: ssa.IsSamePtr() for the same address, ssa.Disjoint() for addresses that do not overlap. The rule forwarding a stored value to a load already exists with three variants looking through several other stores. Here are the two we need:
(Load <t1> p1 (Store  t2  p2 x _))
    && ssa.IsSamePtr(p1, p2)
    && copyCompatibleType(t1, x.Type)
    && t1.Size() == t2.Size()
    => x
(Load <t1> p1 (Store  t2  p2 _ (Store  t3  p3 x _)))
    && ssa.IsSamePtr(p1, p3)
    && copyCompatibleType(t1, x.Type)
    && t1.Size() == t3.Size()
    && ssa.Disjoint(p3, t3, p2, t2)
    => x
Go 1.27 added the rule loading through a move with CL 748200 to fix issue #77720:
(Load <t1> op1:(OffPtr [o1] p1) move:(Move [n] p2 src mem))
    && o1 >= 0 && o1+t1.Size() <= n && ssa.IsSamePtr(p1, p2)
    && !ssa.IsVolatile(src)
    => @move.Block (Load <t1> (OffPtr <op1.Type> [o1] src) mem)
It lacks a variant without an offset:
(Load <t1> p1 move:(Move [n] p2 src mem))
    && p1.Op != ssaop.OpOffPtr
    && t1.Size() <= n && ssa.IsSamePtr(p1, p2)
    && !ssa.IsVolatile(src)
    => @move.Block (Load <t1> (OffPtr <p1.Type> [0] src) mem)
There is no generic rule to cancel two byte swaps, but the AMD64 lowering pass includes this rule:
(BSWAP(Q L) (BSWAP(Q L) p)) => p
After switching to Go s development branch and adding the missing rule, the generated assembly code is worse than with Go 1.26.8, even though our additional rule slightly improves the situation at the end:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (16 bytes):
;    0(SP) a16 [16]byte
 PUSHQ   BP
 MOVQ    SP, BP
 SUBQ    $16, SP
 CMPQ    net/netip z4(SB), CX       ; check "z" if this is an IPv4 address
 JNE     end                        ; if not, stop here
; The four forwarded bytes: the low half of input.addr.lo is taken apart and
; put back together in registers
 MOVQ    BX, DX                     ; DX = input.addr.lo
 SHRQ    $24, BX                    ; BX = input.addr.lo >> 24
 MOVQ    DX, SI                     ; SI = input.addr.lo
 SHRQ    $16, DX                    ; DX = input.addr.lo >> 16
 MOVQ    SI, DI                     ; DI = input.addr.lo, kept for the pack
 SHRQ    $8, SI                     ; SI = input.addr.lo >> 8
 MOVBLZX DIB, R8                    ; R8 = byte(input.addr.lo)
 MOVBLZX SIB, SI                    ; SI = byte(input.addr.lo >> 8)
 SHLQ    $8, SI
 ORQ     R8, SI                     ; SI = two low bytes of input.addr.lo
 MOVBLZX DL, DX                     ; DX = byte(input.addr.lo >> 16)
 SHLQ    $16, DX
 ORQ     SI, DX
 MOVBLZX BL, BX                     ; BX = byte(input.addr.lo >> 24)
 SHLQ    $24, BX
 ORQ     DX, BX                     ; BX = input.addr.lo & 0xffffffff
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
;       byteorder.BEPutUint64(a16[8:], input.addr.lo)
 MOVBEQ  AX, net/netip a16(SP)
 MOVBEQ  DI, net/netip a16+8(SP)
; The four other bytes of input.addr.lo, read one by one from a16
 MOVBLZX net/netip a16+11(SP), DX   ; a16[11]
 SHLQ    $32, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+10(SP), DX   ; a16[10]
 SHLQ    $40, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+9(SP), DX    ; a16[9]
 SHLQ    $48, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+8(SP), DX    ; a16[8]
 SHLQ    $56, DX
; output.z = netip.z6noz
 MOVQ    net/netip z6noz(SB), CX
; output.addr.hi = byteorder.BEUint64(a16[:8])
 MOVBEQ  net/netip a16(SP), AX
; output.addr.lo assembled from the previous steps
 ORQ     DX, BX
end:
 LEAVEQ
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The rule loading through a move, added in Go 1.27, introduced this regression.

Out of order Let s not give up now! In reality, the rewriting rules run before memcombine, notably in the late opt pass. At this point, the inlined versions of BEPutUint64() and BEUint64() still expand to sixteen byte stores and sixteen byte loads, matching their source code:
func BEUint64(b []byte) uint64  
    _ = b[7] // bounds check hint to compiler; see golang.org/issue/14808
    return uint64(b[7])   uint64(b[6])<<8   uint64(b[5])<<16   uint64(b[4])<<24  
        uint64(b[3])<<32   uint64(b[2])<<40   uint64(b[1])<<48   uint64(b[0])<<56
 
Let s follow two bytes of output.addr.lo: addr[15] and addr[11]. Here is a simplified SSA form before late opt:
  v273 = Trunc64to8 <byte> v490                     ; byte(input.addr.lo)
  v226 = Trunc64to8 <byte> v225                     ; byte(input.addr.lo >> 32)
; [ ]
  v235 = Store <mem>  byte  v233 v226 v223          ; a16[11] = byte(lo >> 32)
  v247 = Store <mem>  byte  v245 v238 v235          ; a16[12] =  
  v259 = Store <mem>  byte  v257 v250 v247          ; a16[13] =  
  v271 = Store <mem>  byte  v269 v262 v259          ; a16[14] =  
  v282 = Store <mem>  byte  v280 v273 v271          ; a16[15] = byte(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
; [ ]
  v433 = OffPtr <*byte> [15] v285                   ; &addr[15]
  v435 = Load <byte> v433 v286                      ; addr[15]
  v479 = OffPtr <*byte> [11] v285                   ; &addr[11]
  v481 = Load <byte> v479 v286                      ; addr[11]
The first rule loads through the move: (Load (OffPtr [o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). It matches both loads, which now read a16 with the memory state before the copy:
  v600 = OffPtr <*byte> [15] v22 ; &a16[15]
  v435 = Load <byte> v600 v282   ; a16[15]
  v601 = OffPtr <*byte> [11] v22 ; &a16[11]
  v481 = Load <byte> v601 v282   ; a16[11]
The second rule shortcuts a load following a store: (Load p (Store p x _)) => x. It matches v435, as v282 stores a16[15]. It does not match v481: v235 stores a16[11] four stores earlier in the chain, while the variants of this rule look through three stores at most.
  v435 = Copy <byte> v273        ; byte(input.addr.lo)
  v601 = OffPtr <*byte> [11] v22 ; &a16[11]
  v481 = Load <byte> v601 v282   ; a16[11]
The same happens to the other bytes: the rule forwards the four bytes stored last, a16[12] to a16[15]. The twelve other loads now read a16 instead of addr. BEUint64() becomes a chain of Or64, each one adding a byte shifted into place. memcombine is a pass written in Go, not a set of rewrite rules. It starts from the last Or64 of the chain and collects up to eight terms. If each term is a byte load, extended to 64 bits and shifted, and if the eight loads read consecutive addresses from the same pointer with the same memory state, it replaces the whole chain with a single 64-bit load and a byte swap. Otherwise, it tries again with four, then two terms, and from each intermediate Or64. Here is the loop checking each term in a simplified version of combineLoads():
for i := int64(0); i < n; i++  
    v := a[i]
    shift := int64(0)
    if v.Op == shiftOp  
        v, shift = peelShift(v)
     
    if v.Op != extOp  
        return false
     
    load := v.Args[0]
    if load.Op != ssaop.OpLoad  
        return false
     
    if load.Args[1] != mem  
        return false
     
    p, off := splitPtr(load.Args[0])
    if p != base  
        return false
     
    r[i] = LoadRecord load: load, offset: off, shift: shift 
 
For output.addr.hi, the eight loads read a16 with the same memory state v282:
  v13  = Load <byte> v22 v282               ; a16[0]
  v530 = Load <byte> v14 v282               ; a16[1]
  v488 = Load <byte> v504 v282              ; a16[2]
  v405 = Load <byte> v537 v282              ; a16[3]
  v385 = Load <byte> v397 v282              ; a16[4]
  v361 = Load <byte> v373 v282              ; a16[5]
  v196 = Load <byte> v63 v282               ; a16[6]
  v432 = Load <byte> v315 v282              ; a16[7]
  v319 = ZeroExt8to64 <uint64> v432         ; uint64(a16[7])
  v329 = ZeroExt8to64 <uint64> v196         ; uint64(a16[6])
  v330 = Lsh64x64 <uint64> [true] v329 v138 ; uint64(a16[6]) << 8
  v331 = Or64 <uint64> v319 v330            ; a16[7]   a16[6] << 8
; [ ] same for a16[5] to a16[1]
  v401 = ZeroExt8to64 <uint64> v13          ; uint64(a16[0])
  v402 = Lsh64x64 <uint64> [true] v401 v55  ; uint64(a16[0]) << 56
  v403 = Or64 <uint64> v402 v391            ;   a16[0] << 56 = output.addr.hi
memcombine merges them into one load and a swap:
  v286 = Load <uint64> v22 v282   ; a16[:8]
  v285 = Bswap64 <uint64> v286    ; output.addr.hi
For output.addr.lo, here is the chain memcombine sees after late opt:
  v436 = ZeroExt8to64 <uint64> v273 ; addr[15], forwarded
  v448 = Or64 <uint64> v436 v447    ;   addr[14] << 8, forwarded
  v460 = Or64 <uint64> v459 v448    ;   addr[13] << 16, forwarded
  v472 = Or64 <uint64> v471 v460    ;   addr[12] << 24, forwarded
  v484 = Or64 <uint64> v483 v472    ;   a16[11] << 32, loaded
  v496 = Or64 <uint64> v495 v484    ;   a16[10] << 40, loaded
  v508 = Or64 <uint64> v507 v496    ;   a16[9] << 48, loaded
  v520 = Or64 <uint64> v519 v508    ;   a16[8] << 56, loaded
From v520, four of the eight terms are forwarded bytes, not loads from memory, and memcombine can t combine them. It doesn t merge the four remaining loads either, as they sit on top of the forwarded bytes.

Back in order In summary, the rewriting rules run too early to be effective. A quick workaround exists: run an earlier round of memcombine before late opt. After this change, the generated code for the helper is back to the shortest possible version:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ    net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE     end                      ; if not, stop here
 MOVQ    net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
And the benchmark confirms it!
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
                       Go 1.26.8                  Our branch               
                         sec/op          sec/op     vs base                
AddrTo6/safe          6.5470n    0%   0.8944n   4%  -86.34% (p=0.002 n=6)
AddrTo6/unsafe        0.9071n    3%   0.8682n   1%   -4.28% (p=0.002 n=6)
AddrTo6/builtin       0.8871n    2%   0.8785n   1%        ~ (p=0.310 n=6)

Next steps I think Go maintainers would reject this change because of the additional memcombine pass. Instead, I plan to publish this blog post and bring up the subject again as a follow-up to issue #54365. Either the sheer complexity and the Go 1.27 regression convince the maintainers that adding a To6() method is simpler and more efficient, or they advise me on how to move forward. Either way, digging into this subject taught me a lot about the Go compiler!

  1. IPv4-mapped IPv6 addresses let you handle only IPv6 addresses in your code and keep conversions at a few well-defined boundaries. I use them in Akvorado.
  2. This is not strictly equivalent. The zero value becomes :: while it would make more sense to leave it untouched.
  3. To avoid catastrophic bugs when netip.Addr s layout changes, you must add tests to detect it. This is more dangerous if you put this code in a package. Either ask users to run the tests themselves, or detect the change at run time and panic. Hiding this optimization behind a build tag would make users aware of this potential trap.
  4. I produced the assembly code with GOTOOLCHAIN=go1.26.8 GOAMD64=v3 ./go-asm '\.asm' from the companion repository, then edited it a bit to keep this article from turning into an endless rabbit hole. Due to an unfortunate sequence of events, we switch between versions: Go 1.27 introduced a regression that blurs the point of this article.
  5. The function is short enough for the compiler to inline it, so the assembly code may vary depending on the surrounding code.
  6. MOVBEQ requires GOAMD64=v3, matching the x86-64-v3 microarchitecture from 2013. Otherwise, the compiler translates BEPutUint64() to BSWAPQ+MOVQ and BEUint64() to MOVQ+BSWAPQ.
  7. When the call is used as a statement, a struct literal alone is invalid. The patch then turns it into _ = netip.Addr .
  8. The compiler can also write an HTML file with the result of each pass:
    $ GOSSAFUNC=AddrTo6Safe \
    > GOTOOLCHAIN=go1.26.8 \
    > GOAMD64=v3 go build -a .
    dumped SSA for AddrTo6Safe,1 to ./ssa.html
    
  9. Source line numbers in parentheses follow value identifiers, but I removed them from the examples. The SSA form also features branches, but we don t need them to understand our optimizations.

28 September 2026

Otto Kek l inen: Using multiple git remotes for true distributed version control

Featured image of post Using multiple git remotes for true distributed version controlOne of the primary design principles for Linus Torvalds when creating Git is that it should be a distributed system, capable of working with multiple remotes. However, most people seem to use Git with just one remote, typically having GitHub or GitLab as the only origin. Version control systems before Git relied on a centralized model. For example in Subversion or CVS you could only sync with one single remote server, which was considered the primary host of the source code. Git however is not just a VCS, but a DVCS, for distributed version control system. If you currently use Git with just one single remote as if it was a centralized version control system, now is the time to change that and learn how to add multiple remotes, and configure more flexible git pull and git push rules. The first concept to grasp is that Git can have multiple remotes. For example, after running a basic clone command such as git clone https://github.com/ottok/debcraft.git you would end up with a single remote origin pointing to GitHub:
$ git remote --verbose
origin https://github.com/ottok/debcraft.git (fetch)
origin https://github.com/ottok/debcraft.git (push)
You can however configure multiple remotes with the command git remote:
$ git remote rename origin github
$ git remote add gitlab https://gitlab.com/ottok/debcraft.git
$ git remote --verbose
github https://github.com/ottok/debcraft.git (fetch)
github https://github.com/ottok/debcraft.git (push)
gitlab https://gitlab.com/ottok/debcraft.git (fetch)
gitlab https://gitlab.com/ottok/debcraft.git (push)
You can push and pull from these individually, or from all at once:
$ git pull --all
Fetching github
Fetching gitlab
Already up to date.
When you review the git history, note the labels gitlab/main and github/main which tell which commit the branch main points to on various remotes. In this case they are all in sync and point to the same 5d1815c:
$ git log --oneline
5d1815c (HEAD -> main, gitlab/main, github/main) Bump Debhelper version from 13 to 14
ca518a7 Temporarily disable automatic copyright year bumping due to frequent bugs
d6e201e Exclude .pm from codespell to decrease false positives (Closes: #1140488)
708ee35 Exclude debian/copyright from codespell due to frequent false positives
When pushing, you can choose what remote to push to. For example, if I am working on branch dev and I only want to push it to GitLab to trigger a CI run there, I can run git push gitlab dev. You can also configure a default remote by running once git push --set-upstream gitlab dev and thereafter simply run git push and it will automatically push the branch dev only to that remote. A related setting is remote.pushDefault, which tells git which remote to push to when a branch does not define one of its own, and it applies to every branch that lacks a [branch] section in .git/config. Setting it once is what lets a repository have a per-branch pull remote, like the debcraft example below, and still have a single, predictable git push target. To see which remote git will use for each of your branches, run git branch -vv, and to refresh the remote-tracking branches of all remotes at once, run git fetch --all --prune. If you want to have multiple remotes, but automatically push and pull to all of them at once, you configure one single remote to have multiple URLs with git remote set-url --add. Since git prints one line per push URL, git remote -v then shows the same remote several times, once for each URL it pushes to. As an illustration, in my actual local Debcraft development project I have all these configured:
$ git remote -v
github-pull-requests git@github.com:ottok/debcraft.git (fetch)
github-pull-requests git@github.com:ottok/debcraft.git (push)
gitlab-merge-requests git@gitlab.com:ottok/debcraft.git (fetch)
gitlab-merge-requests git@gitlab.com:ottok/debcraft.git (push)
origin git@salsa.debian.org:debian/debcraft.git (fetch)
origin git@salsa.debian.org:debian/debcraft.git (push)
origin git@gitlab.com:ottok/debcraft.git (push)
origin git@github.com:ottok/debcraft.git (push)
otto git@salsa.debian.org:otto/debcraft.git (fetch)
otto git@salsa.debian.org:otto/debcraft.git (push)
otto git@gitlab.com:ottok/debcraft.git (push)
otto git@github.com:ottok/debcraft.git (push)
otto git@git.sr.ht:~ottok/debcraft (push)
otto ssh://git@codeberg.org/ottok/Debcraft.git (push)
salsa-merge-requests git@salsa.debian.org:debian/debcraft.git (fetch)
salsa-merge-requests git@salsa.debian.org:debian/debcraft.git (push)
The settings can also be viewed directly in the config file:
$ cat .git/config
...
[remote "origin"]
url = git@salsa.debian.org:debian/debcraft.git
fetch = +refs/heads/*:refs/remotes/origin/*
pushurl = git@salsa.debian.org:debian/debcraft.git
pushurl = git@gitlab.com:ottok/debcraft.git
pushurl = git@github.com:ottok/debcraft.git
[remote "otto"]
url = git@salsa.debian.org:otto/debcraft.git
fetch = +refs/heads/*:refs/remotes/otto/*
pushurl = git@salsa.debian.org:otto/debcraft.git
pushurl = git@gitlab.com:ottok/debcraft.git
pushurl = git@github.com:ottok/debcraft.git
pushurl = git@git.sr.ht:~ottok/debcraft
pushurl = ssh://git@codeberg.org/ottok/Debcraft.git
...
[branch "main"]
remote = origin
merge = refs/heads/main
[branch "dev"]
remote = otto
merge = refs/heads/dev
...
On branch main: On branch dev: The command output will have the same message three times, once for each remote (assuming they were all already up-to-date):
$ git push
Everything up-to-date

Use cases for distributed version control The most obvious use case for any distributed system is improved availability. In this example, the salsa.debian.org is often overloaded/unavailable, so pushing to GitLab and GitHub as well allows collaborators to use them to fetch git commits if the primary code hosting site is unresponsive. Once it comes back online again, the next git push/pull will automatically bring it up to the same content as what backup hosts had. The second main benefit is that having the code live on multiple code forges allows collaborators to use their own favorite host. Debcraft itself is a great example of this, as collaborators who don t have a Salsa account can - and have - submitted Merge Requests on GitLab.com and Pull Requests on GitHub.com. A third use case is code hosting migrations. If you for example want to gradually phase out GitHub.com and replace it with something else, you could configure git to pull from the old location and push to both, ensuring that other collaborators can start using the new code hosting location without disruptions to those who have not yet updated their remotes or done a fresh git clone from the new location.

Automating setting up a project on multiple code forges While I don t push all projects I work on to all Salsa/GitLab/GitHub, I do set up multiple remotes for enough git projects that I have this script to automate configuring a git repository that is cloned from Salsa to also push to GitLab and GitHub. It accepts the repository whether it was cloned over SSH or HTTPS, and it adds the push URLs and then pushes the current branch, all branches, and tags for you:
#!/bin/bash
# Add GitLab and GitHub push URLs to an existing git remote, so that a plain
# "git push" writes the same commits to all three code forges.
#
# Usage: ./git-multipush-salsa.sh
#
# Environment:
# SALSA_REMOTE remote to turn into a mirror, default origin
# SALSA_USER your Salsa user, only used to detect that the source
# remote is somebody else's project
# GITLAB_USER your GitLab user, default ottok
# GITHUB_USER your GitHub user, default ottok
# PROTOCOL ssh (default) or https, for the push URLs
set -euo pipefail
SCRIPT=$(basename "$0")
SALSA_REMOTE=$ SALSA_REMOTE:-origin 
SALSA_USER=$ SALSA_USER:-otto 
GITLAB_USER=$ GITLAB_USER:-ottok 
GITHUB_USER=$ GITHUB_USER:-ottok 
PROTOCOL=$ PROTOCOL:-ssh 
die()   echo "$SCRIPT: $*" >&2; exit 1;  
# A failing command leaves the push URLs half configured behind, so say how
# to get back to where we started
fail()
 
echo "$SCRIPT: '$*' failed, the push URLs may already have been added" >&2
echo " git config --unset-all remote.$ SALSA_REMOTE .pushurl" >&2
echo " git remote set-url --add --push $ SALSA_REMOTE  $ SALSA_URL " >&2
exit 1
 
git rev-parse --git-dir > /dev/null 2>&1   die "not inside a git repository"
git remote   grep -qx "$SALSA_REMOTE"   die "no remote named '$SALSA_REMOTE'"
# Example: git@salsa.debian.org:otto/salsa-ci-pipeline.git
SALSA_URL=$(git remote get-url "$SALSA_REMOTE")
# The source remote may use any of the URL forms salsa.debian.org accepts,
# for example git@salsa.debian.org:otto/salsa-ci-pipeline.git or
# https://salsa.debian.org/otto/salsa-ci-pipeline.git
case "$SALSA_URL" in
git@salsa.debian.org:*) SALSA_PATH=$ SALSA_URL#git@salsa.debian.org:  ;;
ssh://git@salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#ssh://git@salsa.debian.org/  ;;
https://salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#https://salsa.debian.org/  ;;
http://salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#http://salsa.debian.org/  ;;
*) die "unexpected source URL '$SALSA_URL', expected a salsa.debian.org URL" ;;
esac
SALSA_PATH=$ SALSA_PATH%/ 
SALSA_PATH=$ SALSA_PATH%.git 
SOURCE_USER=$ SALSA_PATH%%/* 
PROJECT=$ SALSA_PATH##*/ 
# Write the push URLs in one and the same protocol, no matter how the
# repository happens to have been cloned
if [ "$PROTOCOL" = "https" ]
then
SALSA_URL="https://salsa.debian.org/$ SALSA_PATH .git"
GITLAB_URL="https://gitlab.com/$ GITLAB_USER /$ PROJECT .git"
GITHUB_URL="https://github.com/$ GITHUB_USER /$ PROJECT .git"
else
SALSA_URL="git@salsa.debian.org:$ SALSA_PATH .git"
GITLAB_URL="git@gitlab.com:$ GITLAB_USER /$ PROJECT .git"
GITHUB_URL="git@github.com:$ GITHUB_USER /$ PROJECT .git"
fi
# Mirroring somebody else's project is fine, but it is usually not what you
# want: you most likely want to mirror your own fork instead
if [ "$SOURCE_USER" != "$SALSA_USER" ]
then
echo "Note: $SALSA_REMOTE points to $SOURCE_USER's project, not your own."
echo "To mirror your own fork, run this with SALSA_REMOTE set to its name."
echo
fi
# Bail out instead of adding the same push URLs twice
EXISTING=$(git remote get-url --push --all "$SALSA_REMOTE")
if [ "$(printf '%s\n' "$EXISTING"   wc -l)" -gt 1 ]
then
die "remote '$SALSA_REMOTE' already has multiple push URLs:
$EXISTING"
fi
echo "Mirroring $SALSA_URL to $GITLAB_URL and $GITHUB_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$SALSA_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$GITLAB_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$GITHUB_URL"
# Push the branch you have checked out first, and never with --force: the
# first branch a GitLab or GitHub project receives becomes its default branch,
# the one you then protect
DEFAULT_BRANCH=$(git symbolic-ref --short HEAD)   die "not on a branch, check out a branch first"
git push -u "$SALSA_REMOTE" "$DEFAULT_BRANCH"
git push "$SALSA_REMOTE" --all
git push "$SALSA_REMOTE" --tags
# The push above creates the GitLab and GitHub projects, but GitLab projects
# are private by default, so make the new mirror public with glab if installed.
if command -v glab > /dev/null
then
echo "Make the GitLab project public and describe it as a mirror:"
glab api -X PUT "projects/$ GITLAB_USER %2F$ PROJECT " \
-f visibility=public \
-f description="Mirror of $ SALSA_URL " \
-f notification_email=disabled
else
echo "Install glab to do the same automatically, or visit"
echo "https://gitlab.com/$ GITLAB_USER /$ PROJECT /edit to make the project public"
fi
echo "To undo, drop all push URLs and add back only the original one:"
echo " git config --unset-all remote.$ SALSA_REMOTE .pushurl"
echo " git remote set-url --add --push $ SALSA_REMOTE  $ SALSA_URL "
If you prefer not to install glab, the last part simply reduces to visiting the GitLab project settings once and ticking the project public, and it is also worth setting a description like Mirror of https://salsa.debian.org/debian/debcraft and disabling notification email there, as nobody wants a mirror sending out a flood of emails every time you push. There are a few caveats worth knowing about before mirroring everything everywhere. Every push to a remote with multiple push URLs writes to all of them, so a project with continuous integration configured on three forges will run its CI three times and cost you roughly three times as much. If one of the push URLs fails, say because the host is momentarily unreachable, git prints the error and stops there, leaving the remotes listed after the failing one without the new commits. Simply re-run the push once the host is reachable again; the remotes that did get the commits will just respond with Everything up-to-date. And you should never force-push to only one of the remotes, as that leaves the mirrors permanently out of sync with your local repository.

Avoid pulling too much Related to multiple remotes, you should also be aware that git allows one to configure which branches to pull. By default a git clone will track all branches from the remote and pull everything, which in a typical open source project will bring in a lot of temporary development branches in vain. Thus it is better to run git clone with the --single-branch and --branch parameters to fetch only the branch that matters, which in most cases is the main branch. That can be accomplished with:
git clone --single-branch --branch main https://github.com/ottok/debcraft.git
If a repository was already cloned, it can be configured to track only one branch with:
git config remote.upstream.fetch "+refs/heads/main:refs/remotes/upstream/main"
git fetch upstream
git config --get-all remote.upstream.fetch
+refs/heads/main:refs/remotes/upstream/main
If you later need to track more branches, you can configure them with commands such as:
git config --add remote.upstream.fetch "+refs/heads/3.2.y:refs/remotes/upstream/3.2.y"
git fetch upstream
git checkout 3.2.y
For additional details about any of the tips in this post I recommend reading the git man pages.

Now go and spread your code around Distributing your code over multiple code forges costs you almost nothing in configuration, and in return you get availability, a choice of host for your collaborators, and freedom to migrate without a big bang. Add the push URLs to the remotes you already have, push once, and you are done. The rest of the git fundamentals are covered in my other posts. If your commits are not yet polished, start with what makes a good git commit message and git commit messages by example. If you work on Debian packaging, Git-based collaboration in Debian explains why the Salsa merge request workflow is built the way it is, and Salsa merge request best practices covers the review process itself.

Maytham Alsudany: Briefly looking at DNS and nameservers under the hood

I've always known that the browser uses the Domain Name Resolution (DNS) system to convert domain names like aezign.com.au into raw IP addresses, but have never actually understood how it works, outside of making sure my network config uses 1.1.1.1 or 8.8.8.8 instead of the crappy one the ISP provides. In this article, I set out to understand what nameservers do, and how they help anything that uses the internet find the right records.

DNS in a nutshellA well-used analogy is a phonebook; when you have someone's name and need to find their phone number, you look through the phonebook. Overall, DNS does the same thing: when you enter an address like example.com, your browser will contact a DNS server (the "phonebook") to determine its IP addresses. On Linux (or MacOS) systems, you can use dig on the command line to perform a DNS lookup and see what this looks like:
$ dig example.com
; <<>> DiG 9.20.29-1-Debian <<>> example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 42782
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            221     IN      A       104.20.23.154
example.com.            221     IN      A       172.66.147.243
;; Query time: 20 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 21:07:50 AWST 2026
;; MSG SIZE  rcvd: 72
Here, you can see the DNS server being used is 1.1.1.1 (Cloudflare's DNS server), and that it found the IPs 104.20.23.154 and 172.66.147.243 associated with the domain name example.com. Your browser will then contact these IP addresses directly to load the website you are trying to open.

Configuring DNS serversYou can configure DNS servers through your operating system's network settings, and for some applications such as Firefox, with the application itself. If you don't manually set a DNS server, your computer will use the ones provided by your modem. If those are not configured, the default defined by the modem manufacturer or your ISP will be used.The most well-used and reliable DNS servers you can use are Cloudflare's (1.1.1.1 and 1.0.0.1) and Google's (8.8.8.8 and 8.8.4.4). Having more than one DNS server means that if the first one in the list doesn't work or doesn't find the matching IPs for a domain name, it will move to the next one in the list, a backup DNS server.DNS servers must be configured as IP addresses. If your computer tried to use a DNS server at a domain name, then where would your computer find the IP address for that domain name? It wouldn't be able to, as this is the exact gap that DNS servers fulfill.

RecordsDNS is not used only to find IPs for a domain, but a whole host of other things. Collectively they are referred to as "records" (or "DNS records"). Each record is associated to a domain (e.g. example.com) or a subdomain (e.g. bar.example.com, foo.bar.example.com) Here are some of the most common and important types:
  • A - Map to an IPv4 address (e.g. 104.20.23.154).This is the fundamental function of DNS: to map from a domain name to a server's IP address. Multiple A records leads to load balancing, where browsers will randomly select one of the returned IP addresses such that traffic is evenly split between them.
  • AAAA - Map to an IPv6 address (e.g. 2606:4700:10::6814:179a).This serves the same purpose as A records but for IPv6. Multiple AAAA records results in the same load balancing behaviour. All modern websites should have both an A record for legacy compatibility, and an AAAA record to future-proof for the gradual shift towards IPv6 addresses.
  • CNAME - Alias to another domain name (e.g. example.com).DNS servers will recursively lookup records for the aliased domain name until they reach an IP address (in an A or AAAA record).
  • MX - Specify a Mail Exchange server (e.g. mail.example.com).This record tells email SMTP servers where to direct emails to. For instance, the MX record for aezign.com.au is mail.aezign.au; this directs SMTP servers like Gmail and Outlook to send emails to the mailserver running at mail.aezign.au. This also allows specifying a priority field, so that you can define multiple MX records (such as a main and a backup) and consumers will try to connect to the listed mailservers from lowest priority to highest.
  • TXT - Store arbitrary text dataThis is most commonly used for site verification (for instance, to link your website to Google Search Console) and for email security measures like DKIM, DMARC, and SPF.
  • NS - Specify the nameservers for a domain (e.g. zeus.ns.cloudflare.com).These authoritative nameservers are responsible for providing all the other record types when needed.
dig lets you query each of these. For instance, to list the MX records against aezign.com.au:
$ dig MX aezign.com.au
; <<>> DiG 9.20.29-1-Debian <<>> MX aezign.com.au
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 28213
;; flags: qr rd ra; QUERY: 1, ANSWER: 1, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;aezign.com.au.                 IN      MX
;; ANSWER SECTION:
aezign.com.au.          300     IN      MX      10 mail.aezign.au.
;; Query time: 104 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 22:04:58 AWST 2026
;; MSG SIZE  rcvd: 70
Here you can see there is only one mailserver configured for aezign.com.au, which is mail.aezign.au, and it has a priority of 10.If you compare this against something like gmail.com:
$ dig MX gmail.com
; <<>> DiG 9.20.29-1-Debian <<>> MX gmail.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16538
;; flags: qr rd ra; QUERY: 1, ANSWER: 5, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;gmail.com.                     IN      MX
;; ANSWER SECTION:
gmail.com.              2497    IN      MX      40 alt4.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      20 alt2.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      5 gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      10 alt1.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      30 alt3.gmail-smtp-in.l.google.com.
;; Query time: 120 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 22:06:04 AWST 2026
;; MSG SIZE  rcvd: 161
You can see that gmail.com has several mailservers configured as redundancies due to the Gmail's sheer scale. gmail-smtp-in.l.google.com has the highest priority of 5, so SMTP servers will attempt to contact that mailserver first, followed by alt1.gmail-smtp-in.l.google.com and so on.

NameserversNow there needs to be somewhere for DNS records against a domain name to be defined, right? This is where nameservers come in.Nameservers are DNS servers that answer queries about the domains they are authoritative for i.e. the domains they are in charge of. For example, the authoritative nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com, which means Cloudflare's nameservers are the source of truth when looking up DNS records for example.com. You can check this with dig:
$ dig NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> NS example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37717
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      NS
;; ANSWER SECTION:
example.com.            81837   IN      NS      hera.ns.cloudflare.com.
example.com.            81837   IN      NS      elliott.ns.cloudflare.com.
;; Query time: 140 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 23:27:19 AWST 2026
;; MSG SIZE  rcvd: 95
Nameservers are configured with your domain name's registrar. The nameserver you set dictates where your remaining DNS records will live. For example.com, this means you would configure all your records on Cloudflare's dashboard, since they are responsible for the domain's DNS records.

Recursive resolutionThe DNS servers that our computers use follow a recursive resolution process behind-the-scenes to find the authoritative nameservers for a domain, followed by the records you are querying.

Finding the root nameserversDue to the recursive nature of the resolution process, there needs to be a starting point: the root (.) nameservers. The resolver uses a fixed list of root nameservers called root hints issued by IANA (named.root), to locate and contact the root nameservers. Resolvers will have this provided to them initially, and can dynamically update it themselves by querying one of the root nameservers for the root NS records to obtain a fresh list. For instance, we can query 198.41.0.4 (a.root-servers.net) to obtain a new list of root nameservers:
$ dig @198.41.0.4 NS .
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS .
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43677
;; flags: qr aa rd; QUERY: 1, ANSWER: 13, AUTHORITY: 0, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;.				IN	NS
;; ANSWER SECTION:
.			518400	IN	NS	l.root-servers.net.
.			518400	IN	NS	j.root-servers.net.
.			518400	IN	NS	f.root-servers.net.
.			518400	IN	NS	h.root-servers.net.
.			518400	IN	NS	d.root-servers.net.
.			518400	IN	NS	b.root-servers.net.
.			518400	IN	NS	k.root-servers.net.
.			518400	IN	NS	i.root-servers.net.
.			518400	IN	NS	m.root-servers.net.
.			518400	IN	NS	e.root-servers.net.
.			518400	IN	NS	g.root-servers.net.
.			518400	IN	NS	c.root-servers.net.
.			518400	IN	NS	a.root-servers.net.
;; ADDITIONAL SECTION:
l.root-servers.net.	518400	IN	A	199.7.83.42
l.root-servers.net.	518400	IN	AAAA	2001:500:9f::42
j.root-servers.net.	518400	IN	A	192.58.128.30
j.root-servers.net.	518400	IN	AAAA	2001:503:c27::2:30
f.root-servers.net.	518400	IN	A	192.5.5.241
f.root-servers.net.	518400	IN	AAAA	2001:500:2f::f
h.root-servers.net.	518400	IN	A	198.97.190.53
h.root-servers.net.	518400	IN	AAAA	2001:500:1::53
d.root-servers.net.	518400	IN	A	199.7.91.13
d.root-servers.net.	518400	IN	AAAA	2001:500:2d::d
b.root-servers.net.	518400	IN	A	170.247.170.2
b.root-servers.net.	518400	IN	AAAA	2801:1b8:10::b
k.root-servers.net.	518400	IN	A	193.0.14.129
k.root-servers.net.	518400	IN	AAAA	2001:7fd::1
i.root-servers.net.	518400	IN	A	192.36.148.17
i.root-servers.net.	518400	IN	AAAA	2001:7fe::53
m.root-servers.net.	518400	IN	A	202.12.27.33
m.root-servers.net.	518400	IN	AAAA	2001:dc3::35
e.root-servers.net.	518400	IN	A	192.203.230.10
e.root-servers.net.	518400	IN	AAAA	2001:500:a8::e
g.root-servers.net.	518400	IN	A	192.112.36.4
g.root-servers.net.	518400	IN	AAAA	2001:500:12::d0d
c.root-servers.net.	518400	IN	A	192.33.4.12
c.root-servers.net.	518400	IN	AAAA	2001:500:2::c
a.root-servers.net.	518400	IN	A	198.41.0.4
a.root-servers.net.	518400	IN	AAAA	2001:503:ba3e::2:30
;; Query time: 476 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:01:08 AWST 2026
;; MSG SIZE  rcvd: 811

Querying the root nameserversFor example.com, the first step is to query the root (.) nameservers to find the nameservers for the .com top-level domain (TLD). Using a.root-servers.net again:
$ dig @198.41.0.4 NS com
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 22528
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 13, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;com.				IN	NS
;; AUTHORITY SECTION:
com.			172800	IN	NS	l.gtld-servers.net.
com.			172800	IN	NS	j.gtld-servers.net.
com.			172800	IN	NS	h.gtld-servers.net.
com.			172800	IN	NS	d.gtld-servers.net.
com.			172800	IN	NS	b.gtld-servers.net.
com.			172800	IN	NS	f.gtld-servers.net.
com.			172800	IN	NS	k.gtld-servers.net.
com.			172800	IN	NS	m.gtld-servers.net.
com.			172800	IN	NS	i.gtld-servers.net.
com.			172800	IN	NS	g.gtld-servers.net.
com.			172800	IN	NS	a.gtld-servers.net.
com.			172800	IN	NS	c.gtld-servers.net.
com.			172800	IN	NS	e.gtld-servers.net.
;; ADDITIONAL SECTION:
l.gtld-servers.net.	172800	IN	A	192.41.162.30
l.gtld-servers.net.	172800	IN	AAAA	2001:500:d937::30
j.gtld-servers.net.	172800	IN	A	192.48.79.30
j.gtld-servers.net.	172800	IN	AAAA	2001:502:7094::30
h.gtld-servers.net.	172800	IN	A	192.54.112.30
h.gtld-servers.net.	172800	IN	AAAA	2001:502:8cc::30
d.gtld-servers.net.	172800	IN	A	192.31.80.30
d.gtld-servers.net.	172800	IN	AAAA	2001:500:856e::30
b.gtld-servers.net.	172800	IN	A	192.33.14.30
b.gtld-servers.net.	172800	IN	AAAA	2001:503:231d::2:30
f.gtld-servers.net.	172800	IN	A	192.35.51.30
f.gtld-servers.net.	172800	IN	AAAA	2001:503:d414::30
k.gtld-servers.net.	172800	IN	A	192.52.178.30
k.gtld-servers.net.	172800	IN	AAAA	2001:503:d2d::30
m.gtld-servers.net.	172800	IN	A	192.55.83.30
m.gtld-servers.net.	172800	IN	AAAA	2001:501:b1f9::30
i.gtld-servers.net.	172800	IN	A	192.43.172.30
i.gtld-servers.net.	172800	IN	AAAA	2001:503:39c1::30
g.gtld-servers.net.	172800	IN	A	192.42.93.30
g.gtld-servers.net.	172800	IN	AAAA	2001:503:eea3::30
a.gtld-servers.net.	172800	IN	A	192.5.6.30
a.gtld-servers.net.	172800	IN	AAAA	2001:503:a83e::2:30
c.gtld-servers.net.	172800	IN	A	192.26.92.30
c.gtld-servers.net.	172800	IN	AAAA	2001:503:83eb::30
e.gtld-servers.net.	172800	IN	A	192.12.94.30
e.gtld-servers.net.	172800	IN	AAAA	2001:502:1ca1::30
;; Query time: 772 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:09:25 AWST 2026
;; MSG SIZE  rcvd: 828

Querying the TLD nameserversNow the resolver has .com nameservers and their IPs. We can use one of these, such as 192.5.6.30 (a.gtld-servers.net) to find the nameservers for example.com:
$ dig @192.5.6.30 NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37419
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 2, ADDITIONAL: 13
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;example.com.                   IN      NS
;; AUTHORITY SECTION:
example.com.            172800  IN      NS      hera.ns.cloudflare.com.
example.com.            172800  IN      NS      elliott.ns.cloudflare.com.
;; ADDITIONAL SECTION:
hera.ns.cloudflare.com. 172800  IN      A       108.162.192.162
hera.ns.cloudflare.com. 172800  IN      A       172.64.32.162
hera.ns.cloudflare.com. 172800  IN      A       173.245.58.162
hera.ns.cloudflare.com. 172800  IN      AAAA    2606:4700:50::adf5:3aa2
hera.ns.cloudflare.com. 172800  IN      AAAA    2803:f800:50::6ca2:c0a2
hera.ns.cloudflare.com. 172800  IN      AAAA    2a06:98c1:50::ac40:20a2
elliott.ns.cloudflare.com. 172800 IN    A       108.162.195.228
elliott.ns.cloudflare.com. 172800 IN    A       162.159.44.228
elliott.ns.cloudflare.com. 172800 IN    A       172.64.35.228
elliott.ns.cloudflare.com. 172800 IN    AAAA    2606:4700:58::a29f:2ce4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2803:f800:50::6ca2:c3e4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2a06:98c1:50::ac40:23e4
;; Query time: 80 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:12:19 AWST 2026
;; MSG SIZE  rcvd: 359

Finding the domain's nameserverThe response tells the resolver that the nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com. Now since these Cloudflare nameservers are also .com domains and Cloudflare is so commonly used, the .com nameserver provides optional sibling glue records as defined in RFC 9471 to prevent further roundtrips and optimize the process.If we ignore the sibling glue records provided, the resolver would have to ask the .com nameservers for the nameservers for cloudflare.com:
$ dig @192.5.6.30 NS cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 40307
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 5, ADDITIONAL: 21
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;cloudflare.com.                        IN      NS
;; AUTHORITY SECTION:
cloudflare.com.         172800  IN      NS      ns3.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns5.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns4.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns6.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns7.cloudflare.com.
;; ADDITIONAL SECTION:
ns3.cloudflare.com.     172800  IN      A       162.159.0.33
ns3.cloudflare.com.     172800  IN      A       162.159.7.226
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:21
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:7e2
ns5.cloudflare.com.     172800  IN      A       162.159.2.9
ns5.cloudflare.com.     172800  IN      A       162.159.9.55
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:209
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:937
ns4.cloudflare.com.     172800  IN      A       162.159.1.33
ns4.cloudflare.com.     172800  IN      A       162.159.8.55
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:121
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:837
ns6.cloudflare.com.     172800  IN      A       162.159.3.11
ns6.cloudflare.com.     172800  IN      A       162.159.5.6
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:30b
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:506
ns7.cloudflare.com.     172800  IN      A       162.159.4.8
ns7.cloudflare.com.     172800  IN      A       162.159.6.6
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:408
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:606
;; Query time: 163 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:26:53 AWST 2026
;; MSG SIZE  rcvd: 573
Here, the .com nameserver provides in-domain glue records for cloudflare.com's nameservers. Without these, there would be a circular dependency, since the nameserver named is a subdomain of the domain being queried for. This is because nameservers are always defined by name, which means that in order to actually contact the nameserver, your computer needs to obtain its IP address with another DNS lookup.Next, we'd use one of these nameservers, say ns3.cloudflare.com, to obtain the IP for hera.ns.cloudflare.com:
$ dig @162.159.0.33 hera.ns.cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @162.159.0.33 hera.ns.cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16801
;; flags: qr aa rd; QUERY: 1, ANSWER: 3, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;hera.ns.cloudflare.com.                IN      A
;; ANSWER SECTION:
hera.ns.cloudflare.com. 86353   IN      A       108.162.192.162
hera.ns.cloudflare.com. 86353   IN      A       173.245.58.162
hera.ns.cloudflare.com. 86353   IN      A       172.64.32.162
;; Query time: 123 msec
;; SERVER: 162.159.0.33#53(162.159.0.33) (UDP)
;; WHEN: Mon Sep 28 01:11:37 AWST 2026
;; MSG SIZE  rcvd: 99

Querying the domain's authoritative nameserverNow we've reached the authoritative nameserver for example.com! The last thing to do is to fetch the A record for example.com to obtain its server's IP address:
$ dig @108.162.192.162 example.com
; <<>> DiG 9.20.29-1-Debian <<>> @108.162.192.162 example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43082
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            300     IN      A       104.20.23.154
example.com.            300     IN      A       172.66.147.243
;; Query time: 123 msec
;; SERVER: 108.162.192.162#53(108.162.192.162) (UDP)
;; WHEN: Mon Sep 28 01:13:47 AWST 2026
;; MSG SIZE  rcvd: 72
At last, we've determined that the IP addresses of the servers behind example.com are 104.20.23.154 and 172.66.147.243. This matches our earlier lookup directly against your computer's configured DNS server.The DNS servers your computer uses encapsulate this recursive resolution process behind the scenes, so that your computer only needs to make one round trip, and the servers can use their much faster data center connections and caching to optimize the process and make the query as fast as possible.

Checking DNS recordsTo check a website's records, the first thing to do is to ensure the domain name is pointed at the correct nameserver. For instance, aezign.com.au is supposed to use Cloudflare, since that is where all the DNS records have been set up. We can verify this using dig, (or alternatively with online tools like dnschecker.org):
$ dig NS aezign.com.au
; <<>> DiG 9.20.29-1-Debian <<>> NS aezign.com.au
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 44172
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;aezign.com.au.                 IN      NS
;; ANSWER SECTION:
aezign.com.au.          86400   IN      NS      rosalie.ns.cloudflare.com.
aezign.com.au.          86400   IN      NS      zeus.ns.cloudflare.com.
;; Query time: 92 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Mon Sep 28 01:39:22 AWST 2026
;; MSG SIZE  rcvd: 100
If this is not set correctly, the DNS records you configure will not work, as resolvers will be fetching records from somewhere else. In most cases, you can update this in your domain registrar's settings. This is especially common for new domain names, which default to the registrar's nameservers; unless you plan to use their built-in DNS management, you'll need to point them to your chosen provider.Now we can check that the DNS records configured match those your DNS server returns. For aezign.com.au, these are the MX and TXT records configured on Cloudflare.
Extract of Cloudflare's DNS record listing showing the MX record and TXT records for aezign.com.au. The MX record and some TXT records configured for aezign.com.au on Cloudflare's dashboard.
We can check these using dig, and using the +short option to show only the content of the records.
$ dig MX aezign.com.au +short
10 mail.aezign.au.
$ dig TXT aezign.com.au +short
"google-site-verification=KFqTU5xH8fFf6OtszEL4oudfxple29Tm-TvxVtCWkAM"
"v=spf1 mx a:mail.aezign.au -all"
$ dig TXT _dmarc.aezign.com.au +short
"v=DMARC1;p=quarantine;sp=quarantine;adkim=r;aspf=r"
$ dig TXT aezign.com.au-2026._domainkey.aezign.com.au +short
"v=DKIM1; h=sha256; k=rsa; s=email; p=MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8AMIIBCgKCAQEAzL04yXZgB72YkoxS+tLK//aWx65TS4UA3F0qJ7el68SEuD4ehmg+61Ta9iS31H6U074dnjyoPDeaiGBa7ToTNCtiIts4/ghD/8nrENROE6hQAwRmTK18ODDHrRDW73hWe6Dg4cK5vmXi82/wWRZU9SDKbme28IE9uCVir3lCkKYLs1" "j16gR1Sjqr6a2+3o+EeVXnLJ4wXmJMm7KCIdn7zv0t9Z1eYcw672PdpYPAMpGb8uUsgaDBsNSpTcupPkz4SWj6TrOB80CPHjWseVY8EOJeRsNKQ/8LFoQEBl4Rxtb3HAmu4UIxSZ4QMVOLnXz67e85mA5XjcNIsVMzaWaowwIDAQAB"
As we can see, this matches, which means that the nameservers for aezign.com.au are correct and the DNS records are what we intend them to be.Note that if you've recently changed the nameserver or DNS records for your domain, it can take anywhere between 10 seconds and 24 hours for the changes to take effect and propagate across the different DNS servers globally. Tools like dnschecker.org can check your records on different DNS servers worldwide to see if they're reflecting your changes. The reason for this is caching: DNS servers like 1.1.1.1 will cache results so it doesn't have to do the full resolution process every time, and uses the Time-To-Live (TTL) you configure in your DNS records as a guideline for caching duration.

Maytham Alsudany: A Brief Explanation of DNS and Nameservers

The Domain Name System (DNS) is a fundamental piece of technology behind the modern internet. Thanks to its introduction in 1983, you're able to enter domain names like aezign.com.au instead of raw IP addresses in your browser's address bar and when sending emails. This article explains what it is, how it works, and how you can inspect your own website's DNS and ensure it is set up correctly.

DNS in a nutshellA well-used analogy is a phonebook; when you have someone's name and need to find their phone number, you look through the phonebook. Overall, DNS does the same thing: when you enter an address like example.com, your browser will contact a DNS server (the "phonebook") to determine its IP addresses. On Linux (or MacOS) systems, you can use dig on the command line to perform a DNS lookup and see what this looks like:
$ dig example.com
; <<>> DiG 9.20.29-1-Debian <<>> example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 42782
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            221     IN      A       104.20.23.154
example.com.            221     IN      A       172.66.147.243
;; Query time: 20 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 21:07:50 AWST 2026
;; MSG SIZE  rcvd: 72
Here, you can see the DNS server being used is 1.1.1.1 (Cloudflare's DNS server), and that it found the IPs 104.20.23.154 and 172.66.147.243 associated with the domain name example.com. Your browser will then contact these IP addresses directly to load the website you are trying to open.

Configuring DNS serversYou can configure DNS servers through your operating system's network settings, and for some applications such as Firefox, with the application itself. If you don't manually set a DNS server, your computer will use the ones provided by your modem. If those are not configured, the default defined by the modem manufacturer or your ISP will be used.The most well-used and reliable DNS servers you can use are Cloudflare's (1.1.1.1 and 1.0.0.1) and Google's (8.8.8.8 and 8.8.4.4). Having more than one DNS server means that if the first one in the list doesn't work or doesn't find the matching IPs for a domain name, it will move to the next one in the list, a backup DNS server.DNS servers must be configured as IP addresses. If your computer tried to use a DNS server at a domain name, then where would your computer find the IP address for that domain name? It wouldn't be able to, as this is the exact gap that DNS servers fulfill.

RecordsDNS is not used only to find IPs for a domain, but a whole host of other things. Collectively they are referred to as "records" (or "DNS records"). Each record is associated to a domain (e.g. example.com) or a subdomain (e.g. bar.example.com, foo.bar.example.com) Here are some of the most common and important types:
  • A - Map to an IPv4 address (e.g. 104.20.23.154).This is the fundamental function of DNS: to map from a domain name to a server's IP address. Multiple A records leads to load balancing, where browsers will randomly select one of the returned IP addresses such that traffic is evenly split between them.
  • AAAA - Map to an IPv6 address (e.g. 2606:4700:10::6814:179a).This serves the same purpose as A records but for IPv6. Multiple AAAA records results in the same load balancing behaviour. All modern websites should have both an A record for legacy compatibility, and an AAAA record to future-proof for the gradual shift towards IPv6 addresses.
  • CNAME - Alias to another domain name (e.g. example.com).DNS servers will recursively lookup records for the aliased domain name until they reach an IP address (in an A or AAAA record).
  • MX - Specify a Mail Exchange server (e.g. mail.example.com).This record tells email SMTP servers where to direct emails to. For instance, the MX record for aezign.com.au is mail.aezign.au; this directs SMTP servers like Gmail and Outlook to send emails to the mailserver running at mail.aezign.au. This also allows specifying a priority field, so that you can define multiple MX records (such as a main and a backup) and consumers will try to connect to the listed mailservers from lowest priority to highest.
  • TXT - Store arbitrary text dataThis is most commonly used for site verification (for instance, to link your website to Google Search Console) and for email security measures like DKIM, DMARC, and SPF.
  • NS - Specify the nameservers for a domain (e.g. zeus.ns.cloudflare.com).These authoritative nameservers are responsible for providing all the other record types when needed.
dig lets you query each of these. For instance, to list the MX records against aezign.com.au:
$ dig MX aezign.com.au
; <<>> DiG 9.20.29-1-Debian <<>> MX aezign.com.au
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 28213
;; flags: qr rd ra; QUERY: 1, ANSWER: 1, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;aezign.com.au.                 IN      MX
;; ANSWER SECTION:
aezign.com.au.          300     IN      MX      10 mail.aezign.au.
;; Query time: 104 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 22:04:58 AWST 2026
;; MSG SIZE  rcvd: 70
Here you can see there is only one mailserver configured for aezign.com.au, which is mail.aezign.au, and it has a priority of 10.If you compare this against something like gmail.com:
$ dig MX gmail.com
; <<>> DiG 9.20.29-1-Debian <<>> MX gmail.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16538
;; flags: qr rd ra; QUERY: 1, ANSWER: 5, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;gmail.com.                     IN      MX
;; ANSWER SECTION:
gmail.com.              2497    IN      MX      40 alt4.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      20 alt2.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      5 gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      10 alt1.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      30 alt3.gmail-smtp-in.l.google.com.
;; Query time: 120 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 22:06:04 AWST 2026
;; MSG SIZE  rcvd: 161
You can see that gmail.com has several mailservers configured as redundancies due to the Gmail's sheer scale. gmail-smtp-in.l.google.com has the highest priority of 5, so SMTP servers will attempt to contact that mailserver first, followed by alt1.gmail-smtp-in.l.google.com and so on.

NameserversNow there needs to be somewhere for DNS records against a domain name to be defined, right? This is where nameservers come in.Nameservers are DNS servers that answer queries about the domains they are authoritative for i.e. the domains they are in charge of. For example, the authoritative nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com, which means Cloudflare's nameservers are the source of truth when looking up DNS records for example.com. You can check this with dig:
$ dig NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> NS example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37717
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      NS
;; ANSWER SECTION:
example.com.            81837   IN      NS      hera.ns.cloudflare.com.
example.com.            81837   IN      NS      elliott.ns.cloudflare.com.
;; Query time: 140 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 23:27:19 AWST 2026
;; MSG SIZE  rcvd: 95
Nameservers are configured with your domain name's registrar. The nameserver you set dictates where your remaining DNS records will live. For example.com, this means you would configure all your records on Cloudflare's dashboard, since they are responsible for the domain's DNS records.

Recursive resolutionThe DNS servers that our computers use follow a recursive resolution process behind-the-scenes to find the authoritative nameservers for a domain, followed by the records you are querying.

Finding the root nameserversDue to the recursive nature of the resolution process, there needs to be a starting point: the root (.) nameservers. The resolver uses a fixed list of root nameservers called root hints issued by IANA (named.root), to locate and contact the root nameservers. Resolvers will have this provided to them initially, and can dynamically update it themselves by querying one of the root nameservers for the root NS records to obtain a fresh list. For instance, we can query 198.41.0.4 (a.root-servers.net) to obtain a new list of root nameservers:
$ dig @198.41.0.4 NS .
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS .
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43677
;; flags: qr aa rd; QUERY: 1, ANSWER: 13, AUTHORITY: 0, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;.				IN	NS
;; ANSWER SECTION:
.			518400	IN	NS	l.root-servers.net.
.			518400	IN	NS	j.root-servers.net.
.			518400	IN	NS	f.root-servers.net.
.			518400	IN	NS	h.root-servers.net.
.			518400	IN	NS	d.root-servers.net.
.			518400	IN	NS	b.root-servers.net.
.			518400	IN	NS	k.root-servers.net.
.			518400	IN	NS	i.root-servers.net.
.			518400	IN	NS	m.root-servers.net.
.			518400	IN	NS	e.root-servers.net.
.			518400	IN	NS	g.root-servers.net.
.			518400	IN	NS	c.root-servers.net.
.			518400	IN	NS	a.root-servers.net.
;; ADDITIONAL SECTION:
l.root-servers.net.	518400	IN	A	199.7.83.42
l.root-servers.net.	518400	IN	AAAA	2001:500:9f::42
j.root-servers.net.	518400	IN	A	192.58.128.30
j.root-servers.net.	518400	IN	AAAA	2001:503:c27::2:30
f.root-servers.net.	518400	IN	A	192.5.5.241
f.root-servers.net.	518400	IN	AAAA	2001:500:2f::f
h.root-servers.net.	518400	IN	A	198.97.190.53
h.root-servers.net.	518400	IN	AAAA	2001:500:1::53
d.root-servers.net.	518400	IN	A	199.7.91.13
d.root-servers.net.	518400	IN	AAAA	2001:500:2d::d
b.root-servers.net.	518400	IN	A	170.247.170.2
b.root-servers.net.	518400	IN	AAAA	2801:1b8:10::b
k.root-servers.net.	518400	IN	A	193.0.14.129
k.root-servers.net.	518400	IN	AAAA	2001:7fd::1
i.root-servers.net.	518400	IN	A	192.36.148.17
i.root-servers.net.	518400	IN	AAAA	2001:7fe::53
m.root-servers.net.	518400	IN	A	202.12.27.33
m.root-servers.net.	518400	IN	AAAA	2001:dc3::35
e.root-servers.net.	518400	IN	A	192.203.230.10
e.root-servers.net.	518400	IN	AAAA	2001:500:a8::e
g.root-servers.net.	518400	IN	A	192.112.36.4
g.root-servers.net.	518400	IN	AAAA	2001:500:12::d0d
c.root-servers.net.	518400	IN	A	192.33.4.12
c.root-servers.net.	518400	IN	AAAA	2001:500:2::c
a.root-servers.net.	518400	IN	A	198.41.0.4
a.root-servers.net.	518400	IN	AAAA	2001:503:ba3e::2:30
;; Query time: 476 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:01:08 AWST 2026
;; MSG SIZE  rcvd: 811

Querying the root nameserversFor example.com, the first step is to query the root (.) nameservers to find the nameservers for the .com top-level domain (TLD). Using a.root-servers.net again:
$ dig @198.41.0.4 NS com
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 22528
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 13, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;com.				IN	NS
;; AUTHORITY SECTION:
com.			172800	IN	NS	l.gtld-servers.net.
com.			172800	IN	NS	j.gtld-servers.net.
com.			172800	IN	NS	h.gtld-servers.net.
com.			172800	IN	NS	d.gtld-servers.net.
com.			172800	IN	NS	b.gtld-servers.net.
com.			172800	IN	NS	f.gtld-servers.net.
com.			172800	IN	NS	k.gtld-servers.net.
com.			172800	IN	NS	m.gtld-servers.net.
com.			172800	IN	NS	i.gtld-servers.net.
com.			172800	IN	NS	g.gtld-servers.net.
com.			172800	IN	NS	a.gtld-servers.net.
com.			172800	IN	NS	c.gtld-servers.net.
com.			172800	IN	NS	e.gtld-servers.net.
;; ADDITIONAL SECTION:
l.gtld-servers.net.	172800	IN	A	192.41.162.30
l.gtld-servers.net.	172800	IN	AAAA	2001:500:d937::30
j.gtld-servers.net.	172800	IN	A	192.48.79.30
j.gtld-servers.net.	172800	IN	AAAA	2001:502:7094::30
h.gtld-servers.net.	172800	IN	A	192.54.112.30
h.gtld-servers.net.	172800	IN	AAAA	2001:502:8cc::30
d.gtld-servers.net.	172800	IN	A	192.31.80.30
d.gtld-servers.net.	172800	IN	AAAA	2001:500:856e::30
b.gtld-servers.net.	172800	IN	A	192.33.14.30
b.gtld-servers.net.	172800	IN	AAAA	2001:503:231d::2:30
f.gtld-servers.net.	172800	IN	A	192.35.51.30
f.gtld-servers.net.	172800	IN	AAAA	2001:503:d414::30
k.gtld-servers.net.	172800	IN	A	192.52.178.30
k.gtld-servers.net.	172800	IN	AAAA	2001:503:d2d::30
m.gtld-servers.net.	172800	IN	A	192.55.83.30
m.gtld-servers.net.	172800	IN	AAAA	2001:501:b1f9::30
i.gtld-servers.net.	172800	IN	A	192.43.172.30
i.gtld-servers.net.	172800	IN	AAAA	2001:503:39c1::30
g.gtld-servers.net.	172800	IN	A	192.42.93.30
g.gtld-servers.net.	172800	IN	AAAA	2001:503:eea3::30
a.gtld-servers.net.	172800	IN	A	192.5.6.30
a.gtld-servers.net.	172800	IN	AAAA	2001:503:a83e::2:30
c.gtld-servers.net.	172800	IN	A	192.26.92.30
c.gtld-servers.net.	172800	IN	AAAA	2001:503:83eb::30
e.gtld-servers.net.	172800	IN	A	192.12.94.30
e.gtld-servers.net.	172800	IN	AAAA	2001:502:1ca1::30
;; Query time: 772 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:09:25 AWST 2026
;; MSG SIZE  rcvd: 828

Querying the TLD nameserversNow the resolver has .com nameservers and their IPs. We can use one of these, such as 192.5.6.30 (a.gtld-servers.net) to find the nameservers for example.com:
$ dig @192.5.6.30 NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37419
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 2, ADDITIONAL: 13
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;example.com.                   IN      NS
;; AUTHORITY SECTION:
example.com.            172800  IN      NS      hera.ns.cloudflare.com.
example.com.            172800  IN      NS      elliott.ns.cloudflare.com.
;; ADDITIONAL SECTION:
hera.ns.cloudflare.com. 172800  IN      A       108.162.192.162
hera.ns.cloudflare.com. 172800  IN      A       172.64.32.162
hera.ns.cloudflare.com. 172800  IN      A       173.245.58.162
hera.ns.cloudflare.com. 172800  IN      AAAA    2606:4700:50::adf5:3aa2
hera.ns.cloudflare.com. 172800  IN      AAAA    2803:f800:50::6ca2:c0a2
hera.ns.cloudflare.com. 172800  IN      AAAA    2a06:98c1:50::ac40:20a2
elliott.ns.cloudflare.com. 172800 IN    A       108.162.195.228
elliott.ns.cloudflare.com. 172800 IN    A       162.159.44.228
elliott.ns.cloudflare.com. 172800 IN    A       172.64.35.228
elliott.ns.cloudflare.com. 172800 IN    AAAA    2606:4700:58::a29f:2ce4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2803:f800:50::6ca2:c3e4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2a06:98c1:50::ac40:23e4
;; Query time: 80 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:12:19 AWST 2026
;; MSG SIZE  rcvd: 359

Finding the domain's nameserverThe response tells the resolver that the nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com. Now since these Cloudflare nameservers are also .com domains and Cloudflare is so commonly used, the .com nameserver provides optional sibling glue records as defined in RFC 9471 to prevent further roundtrips and optimize the process.If we ignore the sibling glue records provided, the resolver would have to ask the .com nameservers for the nameservers for cloudflare.com:
$ dig @192.5.6.30 NS cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 40307
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 5, ADDITIONAL: 21
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;cloudflare.com.                        IN      NS
;; AUTHORITY SECTION:
cloudflare.com.         172800  IN      NS      ns3.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns5.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns4.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns6.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns7.cloudflare.com.
;; ADDITIONAL SECTION:
ns3.cloudflare.com.     172800  IN      A       162.159.0.33
ns3.cloudflare.com.     172800  IN      A       162.159.7.226
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:21
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:7e2
ns5.cloudflare.com.     172800  IN      A       162.159.2.9
ns5.cloudflare.com.     172800  IN      A       162.159.9.55
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:209
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:937
ns4.cloudflare.com.     172800  IN      A       162.159.1.33
ns4.cloudflare.com.     172800  IN      A       162.159.8.55
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:121
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:837
ns6.cloudflare.com.     172800  IN      A       162.159.3.11
ns6.cloudflare.com.     172800  IN      A       162.159.5.6
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:30b
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:506
ns7.cloudflare.com.     172800  IN      A       162.159.4.8
ns7.cloudflare.com.     172800  IN      A       162.159.6.6
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:408
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:606
;; Query time: 163 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:26:53 AWST 2026
;; MSG SIZE  rcvd: 573
Here, the .com nameserver provides in-domain glue records for cloudflare.com's nameservers. Without these, there would be a circular dependency, since the nameserver named is a subdomain of the domain being queried for. This is because nameservers are always defined by name, which means that in order to actually contact the nameserver, your computer needs to obtain its IP address with another DNS lookup.Next, we'd use one of these nameservers, say ns3.cloudflare.com, to obtain the IP for hera.ns.cloudflare.com:
$ dig @162.159.0.33 hera.ns.cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @162.159.0.33 hera.ns.cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16801
;; flags: qr aa rd; QUERY: 1, ANSWER: 3, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;hera.ns.cloudflare.com.                IN      A
;; ANSWER SECTION:
hera.ns.cloudflare.com. 86353   IN      A       108.162.192.162
hera.ns.cloudflare.com. 86353   IN      A       173.245.58.162
hera.ns.cloudflare.com. 86353   IN      A       172.64.32.162
;; Query time: 123 msec
;; SERVER: 162.159.0.33#53(162.159.0.33) (UDP)
;; WHEN: Mon Sep 28 01:11:37 AWST 2026
;; MSG SIZE  rcvd: 99

Querying the domain's authoritative nameserverNow we've reached the authoritative nameserver for example.com! The last thing to do is to fetch the A record for example.com to obtain its server's IP address:
$ dig @108.162.192.162 example.com
; <<>> DiG 9.20.29-1-Debian <<>> @108.162.192.162 example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43082
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            300     IN      A       104.20.23.154
example.com.            300     IN      A       172.66.147.243
;; Query time: 123 msec
;; SERVER: 108.162.192.162#53(108.162.192.162) (UDP)
;; WHEN: Mon Sep 28 01:13:47 AWST 2026
;; MSG SIZE  rcvd: 72
At last, we've determined that the IP addresses of the servers behind example.com are 104.20.23.154 and 172.66.147.243. This matches our earlier lookup directly against your computer's configured DNS server.The DNS servers your computer uses employ this recursive resolution technique behind the scenes, so that your computer only needs to make one round trip, and the servers can use their much faster data center connections and caching to optimize the process and make the query as fast as possible.

Verify your DNS recordsTo check your website's records, the first thing you'll want to do is ensure your domain name is pointed at the correct nameserver. For instance, aezign.com.au is supposed to use Cloudflare, since that is where all the DNS records have been set up. We can verify this using dig, (or alternatively with online tools like dnschecker.org):
$ dig NS aezign.com.au
; <<>> DiG 9.20.29-1-Debian <<>> NS aezign.com.au
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 44172
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;aezign.com.au.                 IN      NS
;; ANSWER SECTION:
aezign.com.au.          86400   IN      NS      rosalie.ns.cloudflare.com.
aezign.com.au.          86400   IN      NS      zeus.ns.cloudflare.com.
;; Query time: 92 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Mon Sep 28 01:39:22 AWST 2026
;; MSG SIZE  rcvd: 100
If this is not set correctly, the DNS records you configure will not work, as resolvers will be fetching records from somewhere else. In most cases, you can update this in your domain registrar's settings. This is especially common for new domain names, which default to the registrar's nameservers; unless you plan to use their built-in DNS management, you'll need to point them to your chosen provider.Now we can check that the DNS records you've configured match those your DNS server returns. For aezign.com.au, these are the MX and TXT records configured on Cloudflare.
Extract of Cloudflare's DNS record listing showing the MX record and TXT records for aezign.com.au. The MX record and some TXT records configured for aezign.com.au on Cloudflare's dashboard.
We can check these using dig, and using the +short option to show only the content of the records.
$ dig MX aezign.com.au +short
10 mail.aezign.au.
$ dig TXT aezign.com.au +short
"google-site-verification=KFqTU5xH8fFf6OtszEL4oudfxple29Tm-TvxVtCWkAM"
"v=spf1 mx a:mail.aezign.au -all"
$ dig TXT _dmarc.aezign.com.au +short
"v=DMARC1;p=quarantine;sp=quarantine;adkim=r;aspf=r"
$ dig TXT aezign.com.au-2026._domainkey.aezign.com.au +short
"v=DKIM1; h=sha256; k=rsa; s=email; p=MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8AMIIBCgKCAQEAzL04yXZgB72YkoxS+tLK//aWx65TS4UA3F0qJ7el68SEuD4ehmg+61Ta9iS31H6U074dnjyoPDeaiGBa7ToTNCtiIts4/ghD/8nrENROE6hQAwRmTK18ODDHrRDW73hWe6Dg4cK5vmXi82/wWRZU9SDKbme28IE9uCVir3lCkKYLs1" "j16gR1Sjqr6a2+3o+EeVXnLJ4wXmJMm7KCIdn7zv0t9Z1eYcw672PdpYPAMpGb8uUsgaDBsNSpTcupPkz4SWj6TrOB80CPHjWseVY8EOJeRsNKQ/8LFoQEBl4Rxtb3HAmu4UIxSZ4QMVOLnXz67e85mA5XjcNIsVMzaWaowwIDAQAB"
As we can see, this matches, which means that the nameservers for aezign.com.au are correct and the DNS records are what we intend them to be.Note that if you've recently changed the nameserver or DNS records for your domain, it can take anywhere between 10 seconds and 24 hours for the changes to take effect and propagate across the different DNS servers worldwide. Tools like dnschecker.org can check your records on different DNS servers worldwide to see if they're reflecting your changes. The reason for this is caching: DNS servers like 1.1.1.1 will cache results so it doesn't have to do the full resolution process every time, and uses the Time-To-Live (TTL) you configure in your DNS records as a guideline for caching duration.

20 September 2026

Freexian Collaborators: Monthly report about Debian Long Term Support, August 2026 (by Thorsten Alteholz)

The Debian LTS Team, funded by Freexian s Debian LTS offering, is pleased to report its activities for August.

Activity summary During the month of August, 19 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 58 DLAs fixing 1885 CVEs. Debian 11 ( bullseye ), which has reached the end of its Long Term Support on 31 August 2026, will now get security support from Freexian under the Extended LTS offer. The team published several notable updates:
  • chromium (DLA 4710-1), uploaded by Emilio, to fix 375 security flaws in bookworm, including issues that could lead to arbitrary code execution. Further DLA 4728-1, uploaded by Emilio as well, fixed additional 41 security issues in bookworm and DLA 4739-1 fixed 5 issues. Last but not least, DLA 4749-1 fixed another 15 issues and DLA 4758-1 fixed another 7 issues.
  • ruby2.7 (DLA 4716-1), uploaded by Abhijith, to fix four security flaws in bookworm, including issues that could lead to arbitrary code execution.
  • several DLAs (DLA 4717-1, DLA 4720-1, DLA 4723-1, DLA 4724-1, DLA 4745-1) have been uploaded by Ben and Emilio to fix myriad security flaws in different versions of the linux kernel (5.10.262-1, 6.1.180-1, 6.12.100-1~deb12u1, 6.12.101-1~deb12u1) in bullseye and bookworm.
  • 7zip (DLA 4718-1) and p7zip (DLA 4719-1), uploaded by Sylvain, to fix multiple security flaws in bookworm and bullseye, including issues that could yield to remote code execution.
  • ca-certificates (DLA 4726-1), uploaded by Bastien to add some new trusted certificates to bookworm and bullseye, but also remove some untrusted ones.
  • thunderbird (DLA 4727-1 and DLA 4754-1), uploaded by Emilio to fix 35 and 31 issues in bookworm and bullseye.
  • nss (DLA 4729-1), uploaded by Jochen to fix a vulnerability in bookworm and bullseye that could yield to arbitrary code execution.
  • libgd2 (DLA 4731-1), uploaded by Guilhem to fix a vulnerability in bookworm and bullseye that could yield to arbitrary code execution if a malformed GIF file is processed.
  • xorg-server (DLA 4737-1 and DLA 4738-1), uploaded by Arnaud to fix several vulnerabilities in bookworm and bullseye.
  • postgresql-15 (DLA 4740-1), uploaded by Carlos Henrique Lima Melara to fix 26 vulnerabilities in bookworm.
  • unzip (DLA 4741-1), uploaded by Andrej to fix a vulnerability in bookworm and bullseye that could yield to arbitrary code execution.
  • firefox-esr (DLA 4750-1), uploaded by Emilio to fix 31 vulnerabilities in bookworm and bullseye that could potentially result in arbitrary code execution, privilege escalation or information disclosure.
  • nvidia-graphics-drivers (DLA 4752-1 and DLA 4753-1), uploaded by Tobias to fix lots of vulnerabilities in bookworm and bullseye.
  • roundcube (DLA 4760-1), uploaded by Guilhem to fix ten vulnerabilities in bookworm and bullseye that could potentially result in remote code execution or information disclosure.
Contributions from outside the LTS Team: We are greatly thankful for the contributions from people outside the LTS Team:
  • Salvatore Bonaccorso released a libyaml-syck-perl security update (DLA 4730-1), to fix a denial of service and potentially arbitrary code execution.
  • Thomas Goirand released a neutron security update (DLA 4735-1).
  • Thomas Goirand released an ironic security update (DLA 4743-1).
  • Thomas Goirand released a designate security update (DLA 4751-1), to fix a denial of service or DNS hijacking.
The LTS Team has also contributed with updates to the latest Debian releases:
  • xrdp (DSA 6469-1), prepared by Abhijith to address privilege escalation and arbitrary code execution related flaws.
Other contributions: Besides the work on security updates, different documentation and tooling changes were needed. This work was mainly done by Sylvain.

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

15 September 2026

Paul Tagliamonte: DESFire EV3

I ve long been interested in hardware key material storage devices. I ve been a fan of yubikeys (I still remember when my fancy new NEO-N showed up), PIV (and its associated smattering of additional fields), SaaS HSMs, the kernel keyring, some tooling I ve fairly satisfied with the design of at prior companies, and of course, our dear friend, the TPM. All that is not even to mention the scores of exotic hardware security modules one generally comes across from time to time when you re keeping a sharp eye out that you wind up playing with. The concept of storing private key material on a disk, or even having it in RAM has always skeeved me out, so I have a natural inclination to hardware modules, and how shifting keying material around can change your risks and threat model(s) in interesting ways. I don t remember when I first came across the MIFARE DESFire EV3, but a few weeks ago I did a deep-dive into the state of the art of authentication schemes using ID cards. My complete overview of what tradeoffs exist is pretty extensive (and likely not interesting to the vast majority of the world), but the tl;dr wound up being one of use PIV or use MIFARE DESFire EV3 . I wound up picking DESFire for a recent project, and figured it s worth talking a bit about what I learned, share some thoughts, and some code. That code is published on crates.io/desox, and docs, as is our custom, may be found at docs.rs/desox DESFire supports DES (I m sure most readers saw that one coming), 3DES (I didn t bother playing with 3DES at all) or AES-128 (AFAICT always use this?) keying material. It s worth noting that the DESFire only supports symmetric keys and is not designed for public key cryptography, and operates exclusively using shared symmetric key material. The DESFire EV series use those keys and related authentication schemes to interact with files stored on the on-chip EEPROM (2k, 4k, 8k, and 16k versions exist), or applications (groups of files and authentication keys).

Talking to a DESFire EV3 Interactions with the card are done over NFC (ISO/IEC 14443 Type A), and commands to/from the card may be in the usual ISO/IEC 7816-4 APDU format, or unencapsulated bytes sent to/from the card are sent using a fixed instruction set and return code structure saving a few bytes per message. I ve opted to use their undocumented and proprietary format I found it easier to work with and with a maximum message of 60 bytes, the savings matter a lot. While powered via NFC, the card maintains a small amount of state about the connection between the reader and the card in its RAM, including if the session is authenticated or unauthenticated. I ll dig into how authentication happens later, but it s worth knowing that sessions can become authenticated using one of the symmetric keys shared by the card and the reader. The vast majority of the DESFire commands I know about tend to work while either authenticated or unauthenticated, with a few exceptions (GetUid, ChangeKey, and ChangeKeySettings for example). In general, I found working with this card particularly pleasant. There is a fair amount of backwards-compatible behavior and multiple methods of communication that confuse things a bit, but overall, it was better than average to integrate with. Kudos to the NXP team. If the docs on this chip were public, things would be orders of magnitude easier it s not entirely clear to my why they re keeping so much of the interface documentation under NDA, but it s the largest knock against the chip, by far.

Authentication I found a lot of really great resources outlining how the handshake and protocol works for a DESFire EV3, especially from Ridrix, some public datasheets ThrRealRevK and posts from AndroidCrypto. The gist here is that, because the DESFire only does symmetric key operations, the key exchange (a type of SKA Symmetric Key Agreement) uses symmetric keys to establish a unique session key which is used to sign or encrypt data exchanged between the reader and the card. I m not going to get too in-depth here, since there s a ton of other resources out there to dig into but I will do a quick high-level description to keep this post mostly self-contained. The authentication protocol serves two main functions to verify that both parties know the same shared secret, as well as to act as a SKA to construct a new session shared secret key. Here s a quick overview of how a shared session key is derived between the reader and the card using our symmetric keys (AES-128 in the case below).
  1. the reader requests to start authentication with the card (something like AA 00 to start an AES Authentication handshake with keyslot 0x00).
  2. The card will then reply with AF (a status code that indicates more data is to follow), followed by 16 bytes (in the case of AES-128) of encrypted (using CBC) data.
  3. The hosts then decrypts this block with the symmetric key from keyslot 0, returning the card s session nonce.
  4. The host generates 16 bytes (usually random) for its session nonce.
  5. The host sends an instruction of AF (indicating a continuation of the previous command), followed by 32 bytes of encrypted data. When decrypted, the first 16 bytes are our nonce generated in step #4, followed by the 16 bytes provided by the card, decrypted in step #3, except where every byte is shifted to the left by one place (the 0th byte is copied to the end).
  6. The card will reply with 00 indicating a successful operation, followed by 16 bytes, which when decrypted, is our session nonce from step #4, shifted to the left by one byte in the same way that we did in step #5 with the card s nonce.
  7. At this point, both the reader and card have confirmed the other party has the same symmetric secret key. The session is now authenticated and a session key is derived using the two nonce blocks. Two hashing keys (K1 and K2) are derived from this key, which is used to maintain an ongoing CMAC hash of the messages coming and going to/from the card.
From here on out, the session is authenticated , and responses from the card which were previously plain will now contain a 8-byte CMAC signature, which can be used to ensure that the replies in question come from the active session. In my implementation of the handshake I opted to encode the handshake state into rust types, just so I wouldn t make any mistakes. The Handshake type contains the session internals (session nonce values, keying state, to include IV, etc). This means the authentication flow (from within my code) uses the Handshake struct to generate the commands to send to the card in order:
/// Create a new  Handshake , and return the
/// start auth command (something like  AA 00 )
fn Handshake::<Initial>::begin(
 output: &mut [u8],
 key: [u8; 16],
 key_id: u8,
) -> (Self, &[u8]);
After we get a reply back from the card (the encrypted version of the card s session nonce, sometimes called Rnd_B in code I ve seen), we transition states from Initial into HalfOpen.
/// Given the card's encrypted response, generate
/// our session nonce and generate a reply
/// (something that starts with  AF  followed by
/// 32 bytes of encrypted data).
fn Handshake::<Initial>::rnd_b(
 self,
 output: &mut [u8],
 input: &[u8]
) -> (Handshake::<HalfOpen>, &[u8]);
Now that we re HalfOpen , we re waiting to hear back from the card to ensure that it, too, can byte-shift our provided nonce. Once we have the card s reply, we can check it using our complete helper, transitioning from HalfOpen to Successful.
/// Check to ensure that the card replied with
/// our nonce byte-shifted by one place, indicating
/// that they know the symmetric secret in
/// this key slot.
fn Handshake::<HalfOpen>::complete(
 self,
 input: &[u8]
) -> Handshake::<Successful>;
Once the Handshake is successful, the only thing left to do is consume the Handshake struct and turn it into the shared session key by running it through the key derivation function.
/// Consume the  Handshake  struct and return the
/// new shared session secret key.
fn Handshake::<Successful>::into_key(self) -> [u8; 16];
From here on out we can use this session key for the remainder of our interactions with the card signing messages from (and sometimes to!) the card, or encrypted messages to and from the card. This key is used in CBC block mode, where the session IV is updated with the last block of the encrypted data.

Unit Testing A nice proprietary of the SKA scheme we re using as part of DESFire is that the derived session key is actually deterministic if you control your nonce RNG (ok, actually, pretty true for most key agreements, but anyway), which means it is possible to capture traffic over the NFC interface, and replay the NFC I/O with cooked RNGs and ensure byte-identical messages and keys are generated. Within desox-rs this is called replay (I m creative), and I ve got a few replay sessions checked into VCS, which exercise a signficant amount fo the API surface. All were derived from an actual session with a real DESFire card, and can be updated with a live card and a --cfg flag. Each replay file is a set of lines (request-response transactions), each containing two space-delimited hex encoded NFC messages. For instance, here s an authentication handshake in replay format:
1a00 afc7bbd82ff8fefae8
afc6dab54df2278d2952d560821be7e4c3 007d9abe94a9b14748
The code that generated that exchange came from the test stored adjacent to that file a handshake with the default DES key (all zeros), and an RndA value hardcoded to 32c28fdafd3960de.
let mut card = card
 .authenticate_with_rnd_a(
 0x00,
 Key::Des([0; 8]),
 Key::Des(hex_literal::hex!("32 c2 8f da fd 39 60 de")),
 )
 .await
 .unwrap();
Since the card s RndB is similarly unchanging (I m replaying this file every time), this will always derive the same session key, which means messages (including encrypted ones or CMAC signed responses) will be identical, as well. If you re playing with the DESFire yourself, feel free to grab my replay files if you need a known good baseline. By default this will run using the MockBackend, replaying each file expecting a byte-identical request, and responding with the harcoded customary reply. If the code (or test!) needs to change, updating the tests is done by swapping the MockBackend out for a real one. Since I had to do this a bunch during development, running cargo test with RUSTFLAGS="--cfg desox_replay_rw" will, on run, overwrite the replay file(s) for the executed test(s), ensuring all line-protocol changes are explicitly caught and reviewed.

Observations Most commands, even ones which require authentication, are transmitted without CMAC signature(s) or encryption. CMAC signatures from the reader to the card are not really used (except for writes to a file which specifies communication must be CMAC signed), ditto for encryption (although that one is used for key change operations, in addition to file writes on files that specify encrypted communication must be used). The vast majority of commands take a plain request from the reader, and return a CMAC signed response. By my eye, this means that a malicious reader, or something otherwise capable of holding the card online after communication with an authentic reader is complete are able to execute privilaged commands (since one can simply ignore the CMAC signatures on responses), so long as the command doesn t require the reader to provide CMAC signatures (or encryption), or allow the card to power down.

Fun with DESFire I ve played around a bit with ways to use the DESFire cards in interesting configurations, given what they re capable of. Here s some half-baked thoughts I had while mucking around with the cards these are all poorly thought out sketches of some things we can do given the specific tradeoffs I see with the DESFire card. It s also worth noting that I don t have any of the actual documentation, and am not a cryptographic grown-up, so take these sketches with a massive grain of salt. The first thing that came to mind when implementing this is how the authentication scheme can shift the boundary of what is and is not trusted (assuming good secure keying, and provided the key slots and card/application permissions are configured correctly). Rather than push the key material out to the machine connected to the NFC reader ( reader machine ), I instead tried turning the NFC reader and computer into something psuedo-untrusted by merely having it pass messages from the card to a trusted remote system ( remote machine ). This means that the reader machine is exchanging NFC data with the card, but that data is being decrypted, encrypted and processed by the trusted remote machine the reader is unable to derive the session key. For each of these, I wind up needing to authenticate so there s still a few latent risks, but these can mostly be mitigated by asking for a readbacks of any changed file(s), setting key permissions carefully, and requesting the card s UID via the encrypted channel all of which would require the symmetric secrets (which undermine the whole security model if comprimised). This general construction is also subject to a hostile takeover of the untrusted reader machine , since most commands (including destructive ones!) are sent in PLAIN mode the reader machine can wait until authentication is complete and then inject commands into the card and simply ignore the CMAC signatures on responses, severing ties with the remote machine. As such, we also need to take steps to ensure that the key being used is not one that allows any access beyond what is allowed. Here were some ideas I sketched out off the back of this theory.

The second-factor Given some established (and authenticated) connection, part of the initial authentication flow may use the DESFire card to prove physical control over it as part of a handshake. This can serve as a second factor during some authentication flow, requiring physical card presence at a reader to fully initialize a connection. This does have one glaring downside, however it s phishable. To use this for real , we d need to take some steps to prevent obvious MITM flows (XOR the NFC messages with the URI as seen by the client?), but maybe there s something interesting there. This also has a second interesting attribute when used as part of a physical system authentication flow, this becomes a logical place to inject access control, being able to determine if some person is permitted to operate some device at that particular time (Is Joe current on his Laser Cutter certifications?) I think of the ideas I landed on, while conceptually interesting (using an employee id card as a 2FA token, it s very fast), this one is the least likely to turn into something real.

The takeover This time, let s say the computer attached to the NFC reader ( reader machine ) is semi-trusted. For this scheme, our trusted remote machine and the reader machine pass messages over the network to handle authentication to the card (as above), where the handshake data is being decrypted, encrypted and processed by the trusted remote machine as usual. However, once the authentication handshake is complete and a session key has been derived, the remote system return the session key to the reader machine , giving it a one-time-use key and authenticated session to the card. We need to be careful about global/application permissions and key access control to files but in this construction, we can allow the reader machine to take over privileged actions using a scope-limited DESFire key without handing over the card s true keying material (preventing cloning of the card). This can be helpful to ensure messages to/from the card are truely from the card (verifying CMAC signatures), enables the reader machine to directly read/write to/from encrypted file(s), but allows the symmetric key material to remain in as few places as possible which is critical given compromising that secret will undermine the security of the entire system.

Reproducible Builds: Supporter spotlight: Jochen Sprickerhof on ... Reproducible Builds!

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the ninth installment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project, and followed this up with a post about the Ford Foundation as well as recent ones about ARDC, the Google Open Source Security Team (GOSST), Bootstrappable Builds, the F-Droid project, David A. Wheeler, Simon Butler and Kees Cook. Today, however, we will be talking with Jochen Sprickerhof, one of the newer members of the Reproducible Builds project core team.

Vagrant Cascadian: Could you tell me a bit about yourself? What sort of things do you work on? Jochen Sprickerhof: I am a freelance programmer working on Open Source. Mainly doing Debian, F-Droid and some smaller software projects. In general I made it a habit to look into every software I use and try to fix bugs or add features I need. In Debian, I maintain about 180 packages with topics covering home banking, build systems and robotics. Most of my time, I currently work on reproduce.debian.net, where we try to bit-for-bit reproduce the packages distributed by Debian.
Vagrant: Could you describe the path that lead you to working on reproducible builds? Jochen: I started my Debian journey as a teenager, converting my school to Debian and serving as its system administrator for 13 years. After studying Applied System Science, I joined the university s robotics labs, where I worked on the Robot Operating System (ROS) and the Point Cloud Library (PCL). In the end, I enjoyed programming more than writing papers, so I eventually left academia for a robotics startup. Some years ago, I realized that the open source work I was doing in my spare time was actually the work I cared most about. Nowadays I am really grateful that I can spend my days working on things I find important and have lots of fun with.
Vagrant: What projects did you recently make big progress on? Jochen: A recent example is metasnap.debian.net. It is a meta archive of snapshot.debian.org which is itself archive of all packages in Debian. But let me explain it the other way round: with reproduce.debian.net, we try to reproduce the packages as they are distributed by the Debian archive. For that, we need the same build environment (compilers, libraries, build tools, etc) that was used by Debian back when the original package was compiled. Luckily, snapshot.debian.org has all those packages, but they are not easily accessible via apt, Debian s package manager. So, metasnap provides a mapping from a package name and version pair to the APT repo on snapshot.debian.org needed to download it from. It was created by josch some time ago, and it s awesome work. But when we tried to reproduce more and more packages on reproduce.debian.net, we found that some were missing packages from the build environment even though they where visible on snapshot.debian.org. We found that metasnap excluded some archive areas because they where not expected to be needed. Reimporting all the data took more than two months and surfaced a couple more flaws. With this fixed, we were able to build more packages, only to find out that metasnap also needs better support for version numbers. Luckily we were able to rewrite the data in a day instead of starting the import again.
Vagrant: You have been working on infrastructure to support reproducible builds for a while. Has recent adoption of reproduce.debian.net into the Debian release tooling changed the focus of your work? Jochen: Quite a bit. When we started reproduce.debian.net in 2024, only around 33% of the packages could be reproduced successfully. Today we are above 98%. Most were not bugs in the packages themselves but in the infrastructure. Similar to the metasnap issue I reference above, packages just needed a rebuild because something else, like the toolchain, was fixed in the meantime. In May, people from the Debian release team and the Reproducible Builds project sat together and decided that the overall state is good enough, and now packages that regress on reproducibility are blocked from entering the next Debian release. But that does not mean all the work is on the shoulders of Debian package maintainers. Since then I have been constantly looking at the migration tooling to spot regressions and provide fixes. Furthermore, a couple of maintainers reached out to us for help and I hope more will do so in future.
Vagrant: What is one small thing you (or others) have not yet gotten to that you would really like to see? Jochen: The central tool to reproduce Debian packages is debrebuild, also written by josch. Currently it has two ways to retrieve the build dependencies of a package. Either it uses metasnap.debian.net (as explained above), or it can access the Debian unstable APT repository directly. This allows to test packages locally before everything is indexed on metasnap by compiling against Debian unstable. But actually there are many other APT repositories to query, like Debian stable or even derivatives. Adding support for an optional list of APT repositories in debrebuild would be great. That would also be a big step to support reproducing other Debian based distributions.
Vagrant: and one big thing? Jochen: It would be great to integrate metasnap.debian.net into snapshot.debian.org. There is some discussion on it already in Debian bug #650783.
Vagrant: What are the tools you use the most? Jochen: According to my fish shell history:
$ history   cut -d' ' -f1   sort   uniq -c   sort -nr   head -10
  36199 git
  20941 vi
  12271 rm
   8599 cd
   7917 ls
   6407 apt
   5631 grep
   4249 mv
   3655 dpkg
   2873 cp

Vagrant: So, is the fish shell reproducible? I remember it did not used to be Jochen: You can check for yourself it was last time I checked. But looking through the other commands, neovim sadly is not. I hope we can fix that in future.
Vagrant: Oh, that s a nice URL to check for reproducible package you can just pass the source package name to check the current results? Jochen: Yes. Another one is udd.debian.org/reproducibility/, where you can list all packages of a Debian maintainer. It also lists source reproducibility and has nice filters as well.
Vagrant: What tools do you use specifically working on reproducible builds? Jochen: I don t have statistics for that, but I would say sbuild to build the package, debrebuild to reproduce it, and diffoscope to analyze the differences. Obviously I also need run apt source <package> or use git-buildpackage to get the sources and all the tools I mentioned above.
Vagrant: So how many packages are left to build reproducibly, and once those are finished, what is next? Jochen: Right now, reproduce.debian.net shows over 98% reproducibility, though there are still over 650 package left and some will probably need a lot of work. But actually I think making packages reproducible is just the first step. For me, this is a project to build confidence in the system. To reproduce a package we have two parts: the source of the package and the build environment. Fixing the packages means gaining confidence in the first part but we still rely on the individual build environments for each package as we need to use the same compiler that was used when the package was build initially. Because of this, we have to keep around every historical version of all toolchain packages. I really would like to remove this extra archive, which means we would have to rebuild all of Debian around release time. I am dreaming of a Debian release where you could bit-for-bit reproduce every package just from the released versions. Due to how Debian works, however, this is not a trivial rebuild and it would need some work on the infrastructure. By the way, initially there was a third component to pay attention to: any connection to the outside world during the build. Luckily we fixed the Debian build daemons to not allow network connections during the build some time ago.
Vagrant: Thanks for all that work, and taking the time to tell us a bit about yourself! Jochen: Thanks a lot for the interview!


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

Freexian Collaborators: Debian Contributions: Security-tracker git performance, OpenSSH GSS-API split, Incus replacing lxc in Debian CI and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-08 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Replacing lxc with Incus for Debian CI, by Antonio Terceiro At the beginning of this month, the default backend for tests was changed to incus-lxc, leaving only a few dozen packages explicitly configured to run as lxc. Those packages got bug reports filed and once those bugs are fixed they will be migrated over to incus-lxc. This marks an important milestone for Debian CI, as the low level of isolation between the worker host OS and the OS under test when using lxc was a significant source of instability in our platform. Common causes for test failures when comparing runs under plain lxc with runs with incus-lxc are documented in the wiki page linked from the bug reports.

security-tracker git performance, by Helmut Grohne Developers working with Debian s security-tracker have reported degrading performance for a while. The options for solving this are few with repository sizes now reaching 30GB for a repository whose working tree is a mere 60MB. While there have been a number of proposals for changing the storage layout, Helmut evaluated options not requiring such changes. Much of the problem hinges on the 50MB data/CVE/list file that is updated in most commits. Efficiency hinges on representing its content in git packs. Practically, git frequently fails to represent its content as a delta and stores a full copy that is typically compressed to 12MB. Add a few thousand 12MB full blobs and you quickly have a large repository. In particular, the copy at salsa.debian.org stores many such full blobs, so pulling from it consumes significant bandwidth. One might think that running git gc helps, but its utility is limited here. When git stores objects in packs, it stores the history in reverse. It starts with the current version and represents older objects as differences (deltas) to more recent objects. A delta effectively is a sequence of copying ranges from a base object and insertion of new content. Given that humans tend to add content over time, those additions are often represented as deletions. The crux here is finding that base object. Given that the data/CVE/list file is large, finding it involves comparing quite a few versions of it with each other. This requires both a significant amount of RAM and CPU time. How many objects git considers for this comparison is controlled with the --window option. It is beneficial if the base object does not come from a direct child commit but skips over commits. In doing so, long chains of deltas are avoided. The --depth option controls the maximum chain length. In this search, git combines all objects into a single window to facilitate file renames. As such, it tends to compare data/CVE/list with data/DSA/list, data/DLA/list and others. This is less than helpful and tends to evict all data/CVE/list versions from the comparison window such that a new full blob of it becomes required. Since the security-tracker repository rarely renames files, we can ask git to instead consider one window per filename via --path-walk. Once doing so, it becomes quite a bit better at finding suitable deltas. The technique is less applicable to older history (2025 and earlier), but given a lot of RAM and a bit of partitioning, git gc can shrink that as well. Combining these techniques, we can shrink the repository into 700MB and keep new growth somewhat under control. Temporarily, Helmut is providing a proof-of-concept mirror at git://git.subdivi.de/~helmut/security-tracker.git using these techniques. Avoid pulling from it directly as it does not provide a secure transport. While it does reduce the amount of data being downloaded, it does not resolve a number of related problems. After downloading, a git client will still expend considerable amounts of CPU on verifying received deltas and attempting to git blame data/CVE/list is not improved in any way. Still, there is work on integrating some of the improvements back into salsa.

OpenSSH GSS-API split, by Colin Watson In an option review Colin did in 2024, shortly after the xz-utils backdoor, he explained that having GSS-API authentication and key exchange support in the main OpenSSH packages is problematic. The key exchange patch is large and intrusive. Even linking to the necessary libraries isn t without risk: as the Ebury malware attack demonstrated way back in 2009, each extra library linked into security-critical daemons such as sshd (or nowadays into its privilege-separated helper programs) can modify the behaviour of the daemon even if you aren t doing anything that would involve calling into that library. Of course some of that risk remains, but as Damien Miller wrote, minimizing the number of libraries that end up in the address space of sshd and friends is still valuable. This split is now complete in testing. As of openssh 1:10.4p1-5, the OpenSSH client and server are built without GSS-API authentication and key exchange support. If you need those features, install openssh-client-gssapi or openssh-server-gssapi instead, as appropriate. Debian 13 (trixie) already has packages with those names that just depend on the regular openssh-client and openssh-server so that you can pre-emptively install them, as documented in the release notes. The new openssh-*-gssapi packages have relatively tight dependencies on openssh-common, in order for the testing migration system to ensure that we can t forget to keep them up to date. This will mean a bit more ongoing work on each new upstream version, but it should be manageable.

Catching up on DebConf video publication, by Stefano Rivera DebConf 25 videos suffered terribly from a bug in voctomix that stopped us from being able to publish the videos immediately after the conference. Ivo De Decker did some work on the videos earlier this year, fixing enough of the audio problems to make the videos at least intelligible. While at MiniDebConf Winterthur Stefano published all the videos from 2025 and 2026 to PeerTube and YouTube. DebConf 25 and DebConf 26 videos as well as all the videos from miniconfs that had got caught up in the backlog were published.

Miscellaneous contributions
  • Carles used po-debconf-manager to review and submit Catalan translations for six packages.
  • Carles prepared a prototype of building webwml and running tidy (linter) in Salsa.
  • Carles created different webwml merge requests with different fixes: invalid links to different architectures, 404s to external sites, fixed templates with invalid URL to favicon.ico, making USE_SAMPLE_FILES=1 to avoid fetching external files, typos in English, etc.
  • Carles updated the LibreOffice Wiki page.
  • Emilio managed several transitions, such as glibc 2.43, perl 5.42, kdepim, nginx, gnome-desktop 51, python3.14-only, and many others.
  • Emilio updated libxfont to 2.0.9, xorg-server to 21.1.24, xwayland to 24.1.13, and fixed a FTBFS bug in terminator.
  • Antonio deployed the website for MiniDebConf Beijing 2026, and archived the Hamburg 2026 and Kanpur 2026 MiniDebConf websites.
  • Antonio released auto-apt-proxy 18, adding new features and fixing bugs; that needed a followup 18.1 release to fix an issue identified in the testing migration tests.
  • Antonio did several Salsa maintenance tasks, including his first platform security update and investigating an issue that was causing the background tasks to be severely delayed, imparting the site usability.
  • Thorsten tried to fix some bugs in hplip and cups. Unfortunately this did not result in an upload this month, but stay tuned!
  • Helmut continued to report undeclared file conflicts and correspond about them.
  • Helmut reviewed and merged Johannes Schauer Marin Rodrigues work on adding hurd support to debvm.
  • Helmut fixed a pile of minor issues in the support libraries underpinning unschroot.
  • Helmut adapted rebootstrap to archive regressions and improved its handling of non-default gcc versions.
  • Helmut fixed the rendering of decompressed logs at crossqa.debian.net.
  • Helmut sent patches for two cross build failures.
  • Colin deployed the fix for Invalid link rel= canonical on bugs.debian.org. In the process he found a few bugs in recent undeployed code and fixed them.
  • Santiago continued helping Aryan Karamtoth with the GSoC project on introducing livepatching support for linux. Several challenges have been identified in the recent couple of months, and Santiago is trying to guide Aryan to address them and design the solution. The mentoring is done in collaboration with Emmanuel Arias.
  • Lucas onboarded a co-maintainer for Valkey.
  • Lucas has started to work on a draft for the Debian Outreach project for onboarding newcomers interested in Debian packaging via a video course.
  • Stefano worked on the after-math of DebConf 26, handling the bursary expense reimbursement process and winding down the conference finances.
  • Stefano uploaded Python 3.15 RC 1 to Debian unstable.
  • Stefano did some budgeting and travel planning for the DebConf 27 site-visit in Asahikawa, Japan. The DebConf committee sends a couple of members to meet with the local team and view the venue together, in advance of the next DebConf.

Next.