Sergio Durigan Junior: GCC, glibc, stack unwinding and relocations A war story
I ve been meaning to write a post about this bug for a while, so here
it is (before I forget the details!).
First, I d like to thank a few people:
The background story
Wolfi OS takes security seriously, and one of the things we have is a
package which sets the hardening compiler flags for C/C++ according to
the best practices recommended by OpenSSF. At the time of this
writing, these flags are (in GCC s spec file parlance):
- My friend Gabriel F. T. Gomes, who helped with debugging and simply talking about the issue. I love doing some pair debugging, and I noticed that he also had a great time diving into the internals of glibc and libgcc.
- My teammate Dann Frazier, who always provides invaluable insights and was there to motivate me to push a bit further in order to figure out what was going on.
- The upstream GCC and glibc developers who finally drove the investigation to completion and came up with an elegant fix.
$DAYJOB moves fast), but we ll see.
The background story
Wolfi OS takes security seriously, and one of the things we have is a
package which sets the hardening compiler flags for C/C++ according to
the best practices recommended by OpenSSF. At the time of this
writing, these flags are (in GCC s spec file parlance):
*self_spec:
+ % !O:% !O1:% !O2:% !O3:% !O0:% !Os:% !0fast:% !0g:% !0z:-O2  -fhardened -Wno-error=hardened -Wno-hardened % !fdelete-null-pointer-checks:-fno-delete-null-pointer-checks  -fno-strict-overflow -fno-strict-aliasing % !fomit-frame-pointer:-fno-omit-frame-pointer  -mno-omit-leaf-frame-pointer
*link:
+ --as-needed -O1 --sort-common -z noexecstack -z relro -z now
The important part for our bug is the usage of -z now and
-fno-strict-aliasing.
As I was saying, these flags are set for almost every build, but
sometimes things don t work as they should and we need to disable
them. Unfortunately, one of these problematic cases has been glibc.
There was an attempt to enable hardening while building glibc, but
that introduced a strange breakage to several of our packages and had
to be reverted.
Things stayed pretty much the same until a few weeks ago, when I
started working on one of my roadmap items: figure out why hardening
glibc wasn t working, and get it to work as much as possible.
Reproducing the bug
I started off by trying to reproduce the problem. It s important to
mention this because I often see young engineers forgetting to check
if the problem is even valid anymore. I don t blame them; the anxiety
to get the bug fixed can be really blinding.
Fortunately, I already had one simple test to trigger the failure.
All I had to do was install the py3-matplotlib package and then
invoke:
$ python3 -c 'import matplotlib'
This would result in an abortion with a coredump.
I followed the steps above, and readily saw the problem manifesting
again. OK, first step is done; I wasn t getting out easily from this
one.
Initial debug
The next step is to actually try to debug the failure. In an ideal
world you get lucky and are able to spot what s wrong after just a few
minutes. Or even better: you also can devise a patch to fix the bug
and contribute it to upstream.
I installed GDB, and then ran the py3-matplotlib command inside it.
When the abortion happened, I issued a backtrace command inside GDB
to see where exactly things had gone wrong. I got a stack trace
similar to the following:
#0  0x00007c43afe9972c in __pthread_kill_implementation () from /lib/libc.so.6
#1  0x00007c43afe3d8be in raise () from /lib/libc.so.6
#2  0x00007c43afe2531f in abort () from /lib/libc.so.6
#3  0x00007c43af84f79d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4  0x00007c43af86d4d8 in _Unwind_RaiseException () from /usr/lib/libgcc_s.so.1
#5  0x00007c43acac9014 in __cxxabiv1::__cxa_throw (obj=0x5b7d7f52fab0, tinfo=0x7c429b6fd218 <typeinfo for pybind11::attribute_error>, dest=0x7c429b5f7f70 <pybind11::reference_cast_error::~reference_cast_error() [clone .lto_priv.0]>)
    at ../../../../libstdc++-v3/libsupc++/eh_throw.cc:93
#6  0x00007c429b5ec3a7 in ft2font__getattr__(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >) [clone .lto_priv.0] [clone .cold] () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#7  0x00007c429b62f086 in pybind11::cpp_function::initialize<pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object, std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >, pybind11::name, pybind11::scope, pybind11::sibling>(pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object (*)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::name const&, pybind11::scope const&, pybind11::sibling const&):: lambda(pybind11::detail::function_call&)#1 ::_FUN(pybind11::detail::function_call&) [clone .lto_priv.0] ()
   from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#8  0x00007c429b603886 in pybind11::cpp_function::dispatcher(_object*, _object*, _object*) () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
...
Huh. Initially this didn t provide me with much information. There
was something strange seeing the abort function being called right
after _Unwind_RaiseException, but at the time I didn t pay much
attention to it.
OK, time to expand our horizons a little. Remember when I said that
several of our packages would crash with a hardened glibc? I decided
to look for another problematic package so that I could make it crash
and get its stack trace. My thinking here is that maybe if I can
compare both traces, something will come up.
I happened to find an old discussion where Dann Frazier mentioned that
Emacs was also crashing for him. He and I share the Emacs passion,
and I totally agreed with him when he said that Emacs crashing is
priority -1! (I m paraphrasing).
I installed Emacs, ran it, and voil : the crash happened again. OK,
that was good. When I ran Emacs inside GDB and asked for a backtrace,
here s what I got:
#0  0x00007eede329972c in __pthread_kill_implementation () from /lib/libc.so.6
#1  0x00007eede323d8be in raise () from /lib/libc.so.6
#2  0x00007eede322531f in abort () from /lib/libc.so.6
#3  0x00007eede262879d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4  0x00007eede2646e7c in _Unwind_Backtrace () from /usr/lib/libgcc_s.so.1
#5  0x00007eede3327b11 in backtrace () from /lib/libc.so.6
#6  0x000059535963a8a1 in emacs_backtrace ()
#7  0x000059535956499a in main ()
Ah, this backtrace is much simpler to follow. Nice.
Hmmm. Now the crash is happening inside _Unwind_Backtrace. A
pattern emerges! This must have something to do with stack unwinding
(or so I thought keep reading to discover the whole truth). You
see, the backtrace function (yes, it s a function) and C++ s
exception handling mechanism use similar techniques to do their jobs,
and it pretty much boils down to unwinding frames from the stack.
I looked into Emacs source code, specifically the emacs_backtrace
function, but could not find anything strange over there. This bug
was probably not going to be an easy fix
The quest for a minimal reproducer
Being able to easily reproduce the bug is awesome and really helps
with debugging, but even better is being able to have a minimal
reproducer for the problem.
You see, py3-matplotlib is a huge package and pulls in a bunch of
extra dependencies, so it s not easy to ask other people to just
install this big package plus these other dependencies, and then run
this command , especially if we have to file an upstream bug and
talk to people who may not even run the distribution we re using. So
I set up to try and come up with a smaller recipe to reproduce the
issue, ideally something that s not tied to a specific package from
the distribution.
Having all the information gathered from the initial debug session,
especially the Emacs backtrace, I thought that I could write a very
simple program that just invoked the backtrace function from glibc
in order to trigger the code path that leads to _Unwind_Backtrace.
Here s what I wrote:
#include <execinfo.h>

int
main(int argc, char *argv[])

  void *a[4096];
  backtrace (a, 100);
  return 0;
After compiling it, I determined that yes, the problem did happen with
this small program as well. There was only a small nuisance: the
manifestation of the bug was not deterministic, so I had to execute
the program a few times until it crashed. But that s much better than
what I had before, and a small price to pay. Having a minimal
reproducer pretty much allows us to switch our focus to what really
matters. I wouldn t need to dive into Emacs or Python s source code
anymore.
At the time, I was sure this was a glibc bug. But then something else
happened.
GCC 15
I had to stop my investigation efforts because something more
important came up: it was time to upload GCC 15 to Wolfi. I spent a
couple of weeks working on this (it involved rebuilding the whole
archive, filing hundreds of FTBFS bugs, patching some programs, etc.),
and by the end of it the transition went smooth. When the GCC 15
upload was finally done, I switched my focus back to the glibc
hardening problem.
The first thing I did was to yes, reproduce the bug again. It had
been a few weeks since I had touched the package, after all. So I
built a hardened glibc with the latest GCC and the bug did not
happen anymore!
Fortunately, the very first thing I thought was this must be GCC ,
so I rebuilt the hardened glibc with GCC 14, and the bug was there
again. Huh, unexpected but very interesting.
Diving into glibc and libgcc
At this point, I was ready to start some serious debugging. And then
I got a message on Signal. It was one of those moments where two
minds think alike: Gabriel decided to check how I was doing, and I was
thinking about him because this involved glibc, and Gabriel
contributed to the project for many years. I explained what I was
doing, and he promptly offered to help. Yes, there are more people
who love low level debugging!
We spent several hours going through disassembles of certain functions
(because we didn t have any debug information in the beginning),
trying to make sense of what we were seeing. There was some heavy GDB
involved; unfortunately I completely lost the session s history
because it was done inside a container running inside an ephemeral VM.
But we learned a lot. For example:
-
It was hard to actually understand the full stack trace leading to
uw_init_context_1[cold]. _Unwind_Backtrace obviously didn t
call it (it called uw_init_context_1, but what was that [cold]
doing?). We had to investigate the disassemble of
uw_init_context_1 in order to determined where
uw_init_context_1[cold] was being called.
-
The
[cold] suffix is a GCC function attribute that can be used to
tell the compiler that the function is unlikely to be reached. When
I read that, my mind immediately jumped to this must be an
assertion , so I went to the source code and found the spot.
-
We were able to determine that the return code of
uw_frame_state_for was 5, which means _URC_END_OF_STACK.
That s why the assertion was triggering.
After finding these facts without debug information, I decided to bite
the bullet and recompiled GCC 14 with -O0 -g3, so that we could
debug what uw_frame_state_for was doing. After banging our heads a
bit more, we found that fde is NULL at this excerpt:
// ...
  fde = _Unwind_Find_FDE (context->ra + _Unwind_IsSignalFrame (context) - 1,
                          &context->bases);
  if (fde == NULL)

#ifdef MD_FALLBACK_FRAME_STATE_FOR
      /* Couldn't find frame unwind info for this function.  Try a
         target-specific fallback mechanism.  This will necessarily
         not provide a personality routine or LSDA.  */
      return MD_FALLBACK_FRAME_STATE_FOR (context, fs);
#else
      return _URC_END_OF_STACK;
#endif

// ...
We re debugging on amd64, which means that
MD_FALLBACK_FRAME_STATE_FOR is defined and therefore is called. But
that s not really important for our case here, because we had
established before that _Unwind_Find_FDE would never return NULL
when using a non-hardened glibc (or a glibc compiled with GCC 15). So
we decided to look into what _Unwind_Find_FDE did.
The function is complex because it deals with .eh_frame , but we
were able to pinpoint the exact location where find_fde_tail (one of
the functions called by _Unwind_Find_FDE) is returning NULL:
if (pc < table[0].initial_loc + data_base)
  return NULL;
We looked at the addresses of pc and table[0].initial_loc + data_base, and found that the former fell within libgcc s text
section, which the latter fell within /lib/ld-linux-x86-64.so.2
text.
At this point, we were already too tired to continue. I decided to
keep looking at the problem later and see if I could get any further.
Bisecting GCC
The next day, I woke up determined to find what changed in GCC 15 that
caused the bug to disappear. Unless you know GCC s internals like
they are your own home (which I definitely don t), the best way to do
that is to git bisect the commits between GCC 14 and 15.
I spent a few days running the bisect. It took me more time than I d
have liked to find the right range of commits to pass git bisect
(because of how branches and tags are done in GCC s repository), and I
also had to write some helper scripts that:
- Modified the
gcc.yaml package definition to make it build with the
commit being bisected.
- Built glibc using the GCC that was just built.
- Ran tests inside a docker container (with the recently built glibc
installed) to determine whether the bug was present.
At the end, I had a commit to point to:
commit 99b1daae18c095d6c94d32efb77442838e11cbfb
Author: Richard Biener <rguenther@suse.de>
Date:   Fri May 3 14:04:41 2024 +0200
    tree-optimization/114589 - remove profile based sink heuristics
Makes sense, right?! No? Well, it didn t for me either. Even after
reading what was changed in the code and the upstream bug fixed by the
commit, I was still clueless as to why this change fixed the problem
(I say fixed because it may very well be an unintended consequence
of the change, and some other problem might have been introduced).
Upstream takes over
After obtaining the commit that possibly fixed the bug, while talking
to Dann and explaining what I did, he suggested that I should file an
upstream bug and check with them. Great idea, of course.
I filed the following upstream bug:
https://gcc.gnu.org/bugzilla/show_bug.cgi?id=120653
It s a bit long, very dense and complex, but ultimately upstream was
able to find the real problem and have a patch accepted in just two
days. Nothing like knowing the code base. The initial bug became:
https://sourceware.org/bugzilla/show_bug.cgi?id=33088
In the end, the problem was indeed in how the linker defines
__ehdr_start, which, according to the code (from
elf/dl-support.c):
if (_dl_phdr == NULL)

    /* Starting from binutils-2.23, the linker will define the
       magic symbol __ehdr_start to point to our own ELF header
       if it is visible in a segment that also includes the phdrs.
       So we can set up _dl_phdr and _dl_phnum even without any
       information from auxv.  */


    extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
    assert (__ehdr_start.e_phentsize == sizeof *GL(dl_phdr));
    _dl_phdr = (const void *) &__ehdr_start + __ehdr_start.e_phoff;
    _dl_phnum = __ehdr_start.e_phnum;
But the following definition is the problematic one (from elf/rtld.c):
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
This symbol (along with its counterpart, __ehdr_end) was being
run-time relocated when it shouldn t be. The fix that was pushed
added optimization barriers to prevent the compiler from doing the
relocations.
I don t claim to fully understand what was done here, and Jakub s
analysis is a thing to behold, but in the end I was able to confirm
that the patch fixed the bug. And in the end, it was indeed a glibc
bug.
Conclusion
This was an awesome bug to investigate. It s one of those that
deserve a blog post, even though some of the final details of the fix
flew over my head.
I d like to start blogging more about these sort of bugs, because I ve
encountered my fair share of them throughout my career. And it was
great being able to do some debugging with another person, exchange
ideas, learn things together, and ultimately share that deep
satisfaction when we find why a crash is happening.
I have at least one more bug in my TODO list to write about (another
one with glibc, but this time I was able to get to the end of it and
come up with a patch). Stay tunned.
P.S.: After having published the post I realized that I forgot to
explain why the -z now and -fno-strict-aliasing flags were
important.
-z now is the flag that I determined to be the root cause of the
breakage. If I compiled glibc with every hardening flag except -z now, everything worked. So initially I thought that the problem had
to do with how ld.so was resolving symbols at runtime. As it turns
out, this ended up being more a symptom than the real cause of the
bug.
As for -fno-strict-aliasing, a Gentoo developer who commented on the
GCC bug above mentioned that this OpenSSF bug had a good point against
using this flag for hardening. I still have to do a deep dive on what
was discussed in the issue, but this is certainly something to take
into consideration. There s this very good write-up about strict
aliasing in general if you re interested in understanding it better.
*self_spec:
+ % !O:% !O1:% !O2:% !O3:% !O0:% !Os:% !0fast:% !0g:% !0z:-O2 -fhardened -Wno-error=hardened -Wno-hardened % !fdelete-null-pointer-checks:-fno-delete-null-pointer-checks -fno-strict-overflow -fno-strict-aliasing % !fomit-frame-pointer:-fno-omit-frame-pointer -mno-omit-leaf-frame-pointer
*link:
+ --as-needed -O1 --sort-common -z noexecstack -z relro -z now
py3-matplotlib package and then
invoke:
$ python3 -c 'import matplotlib'
Initial debug
The next step is to actually try to debug the failure. In an ideal
world you get lucky and are able to spot what s wrong after just a few
minutes. Or even better: you also can devise a patch to fix the bug
and contribute it to upstream.
I installed GDB, and then ran the py3-matplotlib command inside it.
When the abortion happened, I issued a backtrace command inside GDB
to see where exactly things had gone wrong. I got a stack trace
similar to the following:
#0 0x00007c43afe9972c in __pthread_kill_implementation () from /lib/libc.so.6
#1 0x00007c43afe3d8be in raise () from /lib/libc.so.6
#2 0x00007c43afe2531f in abort () from /lib/libc.so.6
#3 0x00007c43af84f79d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4 0x00007c43af86d4d8 in _Unwind_RaiseException () from /usr/lib/libgcc_s.so.1
#5 0x00007c43acac9014 in __cxxabiv1::__cxa_throw (obj=0x5b7d7f52fab0, tinfo=0x7c429b6fd218 <typeinfo for pybind11::attribute_error>, dest=0x7c429b5f7f70 <pybind11::reference_cast_error::~reference_cast_error() [clone .lto_priv.0]>)
at ../../../../libstdc++-v3/libsupc++/eh_throw.cc:93
#6 0x00007c429b5ec3a7 in ft2font__getattr__(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >) [clone .lto_priv.0] [clone .cold] () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#7 0x00007c429b62f086 in pybind11::cpp_function::initialize<pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object, std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >, pybind11::name, pybind11::scope, pybind11::sibling>(pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object (*)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::name const&, pybind11::scope const&, pybind11::sibling const&):: lambda(pybind11::detail::function_call&)#1 ::_FUN(pybind11::detail::function_call&) [clone .lto_priv.0] ()
from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#8 0x00007c429b603886 in pybind11::cpp_function::dispatcher(_object*, _object*, _object*) () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
...
Huh. Initially this didn t provide me with much information. There
was something strange seeing the abort function being called right
after _Unwind_RaiseException, but at the time I didn t pay much
attention to it.
OK, time to expand our horizons a little. Remember when I said that
several of our packages would crash with a hardened glibc? I decided
to look for another problematic package so that I could make it crash
and get its stack trace. My thinking here is that maybe if I can
compare both traces, something will come up.
I happened to find an old discussion where Dann Frazier mentioned that
Emacs was also crashing for him. He and I share the Emacs passion,
and I totally agreed with him when he said that Emacs crashing is
priority -1! (I m paraphrasing).
I installed Emacs, ran it, and voil : the crash happened again. OK,
that was good. When I ran Emacs inside GDB and asked for a backtrace,
here s what I got:
#0 0x00007eede329972c in __pthread_kill_implementation () from /lib/libc.so.6
#1 0x00007eede323d8be in raise () from /lib/libc.so.6
#2 0x00007eede322531f in abort () from /lib/libc.so.6
#3 0x00007eede262879d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4 0x00007eede2646e7c in _Unwind_Backtrace () from /usr/lib/libgcc_s.so.1
#5 0x00007eede3327b11 in backtrace () from /lib/libc.so.6
#6 0x000059535963a8a1 in emacs_backtrace ()
#7 0x000059535956499a in main ()
Ah, this backtrace is much simpler to follow. Nice.
Hmmm. Now the crash is happening inside _Unwind_Backtrace. A
pattern emerges! This must have something to do with stack unwinding
(or so I thought keep reading to discover the whole truth). You
see, the backtrace function (yes, it s a function) and C++ s
exception handling mechanism use similar techniques to do their jobs,
and it pretty much boils down to unwinding frames from the stack.
I looked into Emacs source code, specifically the emacs_backtrace
function, but could not find anything strange over there. This bug
was probably not going to be an easy fix
The quest for a minimal reproducer
Being able to easily reproduce the bug is awesome and really helps
with debugging, but even better is being able to have a minimal
reproducer for the problem.
You see, py3-matplotlib is a huge package and pulls in a bunch of
extra dependencies, so it s not easy to ask other people to just
install this big package plus these other dependencies, and then run
this command , especially if we have to file an upstream bug and
talk to people who may not even run the distribution we re using. So
I set up to try and come up with a smaller recipe to reproduce the
issue, ideally something that s not tied to a specific package from
the distribution.
Having all the information gathered from the initial debug session,
especially the Emacs backtrace, I thought that I could write a very
simple program that just invoked the backtrace function from glibc
in order to trigger the code path that leads to _Unwind_Backtrace.
Here s what I wrote:
#include <execinfo.h>
int
main(int argc, char *argv[])
void *a[4096];
backtrace (a, 100);
return 0;
After compiling it, I determined that yes, the problem did happen with
this small program as well. There was only a small nuisance: the
manifestation of the bug was not deterministic, so I had to execute
the program a few times until it crashed. But that s much better than
what I had before, and a small price to pay. Having a minimal
reproducer pretty much allows us to switch our focus to what really
matters. I wouldn t need to dive into Emacs or Python s source code
anymore.
At the time, I was sure this was a glibc bug. But then something else
happened.
GCC 15
I had to stop my investigation efforts because something more
important came up: it was time to upload GCC 15 to Wolfi. I spent a
couple of weeks working on this (it involved rebuilding the whole
archive, filing hundreds of FTBFS bugs, patching some programs, etc.),
and by the end of it the transition went smooth. When the GCC 15
upload was finally done, I switched my focus back to the glibc
hardening problem.
The first thing I did was to yes, reproduce the bug again. It had
been a few weeks since I had touched the package, after all. So I
built a hardened glibc with the latest GCC and the bug did not
happen anymore!
Fortunately, the very first thing I thought was this must be GCC ,
so I rebuilt the hardened glibc with GCC 14, and the bug was there
again. Huh, unexpected but very interesting.
Diving into glibc and libgcc
At this point, I was ready to start some serious debugging. And then
I got a message on Signal. It was one of those moments where two
minds think alike: Gabriel decided to check how I was doing, and I was
thinking about him because this involved glibc, and Gabriel
contributed to the project for many years. I explained what I was
doing, and he promptly offered to help. Yes, there are more people
who love low level debugging!
We spent several hours going through disassembles of certain functions
(because we didn t have any debug information in the beginning),
trying to make sense of what we were seeing. There was some heavy GDB
involved; unfortunately I completely lost the session s history
because it was done inside a container running inside an ephemeral VM.
But we learned a lot. For example:
-
It was hard to actually understand the full stack trace leading to
uw_init_context_1[cold]. _Unwind_Backtrace obviously didn t
call it (it called uw_init_context_1, but what was that [cold]
doing?). We had to investigate the disassemble of
uw_init_context_1 in order to determined where
uw_init_context_1[cold] was being called.
-
The
[cold] suffix is a GCC function attribute that can be used to
tell the compiler that the function is unlikely to be reached. When
I read that, my mind immediately jumped to this must be an
assertion , so I went to the source code and found the spot.
-
We were able to determine that the return code of
uw_frame_state_for was 5, which means _URC_END_OF_STACK.
That s why the assertion was triggering.
After finding these facts without debug information, I decided to bite
the bullet and recompiled GCC 14 with -O0 -g3, so that we could
debug what uw_frame_state_for was doing. After banging our heads a
bit more, we found that fde is NULL at this excerpt:
// ...
fde = _Unwind_Find_FDE (context->ra + _Unwind_IsSignalFrame (context) - 1,
&context->bases);
if (fde == NULL)
#ifdef MD_FALLBACK_FRAME_STATE_FOR
/* Couldn't find frame unwind info for this function. Try a
target-specific fallback mechanism. This will necessarily
not provide a personality routine or LSDA. */
return MD_FALLBACK_FRAME_STATE_FOR (context, fs);
#else
return _URC_END_OF_STACK;
#endif
// ...
We re debugging on amd64, which means that
MD_FALLBACK_FRAME_STATE_FOR is defined and therefore is called. But
that s not really important for our case here, because we had
established before that _Unwind_Find_FDE would never return NULL
when using a non-hardened glibc (or a glibc compiled with GCC 15). So
we decided to look into what _Unwind_Find_FDE did.
The function is complex because it deals with .eh_frame , but we
were able to pinpoint the exact location where find_fde_tail (one of
the functions called by _Unwind_Find_FDE) is returning NULL:
if (pc < table[0].initial_loc + data_base)
return NULL;
We looked at the addresses of pc and table[0].initial_loc + data_base, and found that the former fell within libgcc s text
section, which the latter fell within /lib/ld-linux-x86-64.so.2
text.
At this point, we were already too tired to continue. I decided to
keep looking at the problem later and see if I could get any further.
Bisecting GCC
The next day, I woke up determined to find what changed in GCC 15 that
caused the bug to disappear. Unless you know GCC s internals like
they are your own home (which I definitely don t), the best way to do
that is to git bisect the commits between GCC 14 and 15.
I spent a few days running the bisect. It took me more time than I d
have liked to find the right range of commits to pass git bisect
(because of how branches and tags are done in GCC s repository), and I
also had to write some helper scripts that:
- Modified the
gcc.yaml package definition to make it build with the
commit being bisected.
- Built glibc using the GCC that was just built.
- Ran tests inside a docker container (with the recently built glibc
installed) to determine whether the bug was present.
At the end, I had a commit to point to:
commit 99b1daae18c095d6c94d32efb77442838e11cbfb
Author: Richard Biener <rguenther@suse.de>
Date: Fri May 3 14:04:41 2024 +0200
tree-optimization/114589 - remove profile based sink heuristics
Makes sense, right?! No? Well, it didn t for me either. Even after
reading what was changed in the code and the upstream bug fixed by the
commit, I was still clueless as to why this change fixed the problem
(I say fixed because it may very well be an unintended consequence
of the change, and some other problem might have been introduced).
Upstream takes over
After obtaining the commit that possibly fixed the bug, while talking
to Dann and explaining what I did, he suggested that I should file an
upstream bug and check with them. Great idea, of course.
I filed the following upstream bug:
https://gcc.gnu.org/bugzilla/show_bug.cgi?id=120653
It s a bit long, very dense and complex, but ultimately upstream was
able to find the real problem and have a patch accepted in just two
days. Nothing like knowing the code base. The initial bug became:
https://sourceware.org/bugzilla/show_bug.cgi?id=33088
In the end, the problem was indeed in how the linker defines
__ehdr_start, which, according to the code (from
elf/dl-support.c):
if (_dl_phdr == NULL)
/* Starting from binutils-2.23, the linker will define the
magic symbol __ehdr_start to point to our own ELF header
if it is visible in a segment that also includes the phdrs.
So we can set up _dl_phdr and _dl_phnum even without any
information from auxv. */
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
assert (__ehdr_start.e_phentsize == sizeof *GL(dl_phdr));
_dl_phdr = (const void *) &__ehdr_start + __ehdr_start.e_phoff;
_dl_phnum = __ehdr_start.e_phnum;
But the following definition is the problematic one (from elf/rtld.c):
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
This symbol (along with its counterpart, __ehdr_end) was being
run-time relocated when it shouldn t be. The fix that was pushed
added optimization barriers to prevent the compiler from doing the
relocations.
I don t claim to fully understand what was done here, and Jakub s
analysis is a thing to behold, but in the end I was able to confirm
that the patch fixed the bug. And in the end, it was indeed a glibc
bug.
Conclusion
This was an awesome bug to investigate. It s one of those that
deserve a blog post, even though some of the final details of the fix
flew over my head.
I d like to start blogging more about these sort of bugs, because I ve
encountered my fair share of them throughout my career. And it was
great being able to do some debugging with another person, exchange
ideas, learn things together, and ultimately share that deep
satisfaction when we find why a crash is happening.
I have at least one more bug in my TODO list to write about (another
one with glibc, but this time I was able to get to the end of it and
come up with a patch). Stay tunned.
P.S.: After having published the post I realized that I forgot to
explain why the -z now and -fno-strict-aliasing flags were
important.
-z now is the flag that I determined to be the root cause of the
breakage. If I compiled glibc with every hardening flag except -z now, everything worked. So initially I thought that the problem had
to do with how ld.so was resolving symbols at runtime. As it turns
out, this ended up being more a symptom than the real cause of the
bug.
As for -fno-strict-aliasing, a Gentoo developer who commented on the
GCC bug above mentioned that this OpenSSF bug had a good point against
using this flag for hardening. I still have to do a deep dive on what
was discussed in the issue, but this is certainly something to take
into consideration. There s this very good write-up about strict
aliasing in general if you re interested in understanding it better.
#0 0x00007c43afe9972c in __pthread_kill_implementation () from /lib/libc.so.6
#1 0x00007c43afe3d8be in raise () from /lib/libc.so.6
#2 0x00007c43afe2531f in abort () from /lib/libc.so.6
#3 0x00007c43af84f79d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4 0x00007c43af86d4d8 in _Unwind_RaiseException () from /usr/lib/libgcc_s.so.1
#5 0x00007c43acac9014 in __cxxabiv1::__cxa_throw (obj=0x5b7d7f52fab0, tinfo=0x7c429b6fd218 <typeinfo for pybind11::attribute_error>, dest=0x7c429b5f7f70 <pybind11::reference_cast_error::~reference_cast_error() [clone .lto_priv.0]>)
at ../../../../libstdc++-v3/libsupc++/eh_throw.cc:93
#6 0x00007c429b5ec3a7 in ft2font__getattr__(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >) [clone .lto_priv.0] [clone .cold] () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#7 0x00007c429b62f086 in pybind11::cpp_function::initialize<pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object, std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >, pybind11::name, pybind11::scope, pybind11::sibling>(pybind11::object (*&)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::object (*)(std::__cxx11::basic_string<char, std::char_traits<char>, std::allocator<char> >), pybind11::name const&, pybind11::scope const&, pybind11::sibling const&):: lambda(pybind11::detail::function_call&)#1 ::_FUN(pybind11::detail::function_call&) [clone .lto_priv.0] ()
from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
#8 0x00007c429b603886 in pybind11::cpp_function::dispatcher(_object*, _object*, _object*) () from /usr/lib/python3.13/site-packages/matplotlib/ft2font.cpython-313-x86_64-linux-gnu.so
...
#0 0x00007eede329972c in __pthread_kill_implementation () from /lib/libc.so.6
#1 0x00007eede323d8be in raise () from /lib/libc.so.6
#2 0x00007eede322531f in abort () from /lib/libc.so.6
#3 0x00007eede262879d in uw_init_context_1[cold] () from /usr/lib/libgcc_s.so.1
#4 0x00007eede2646e7c in _Unwind_Backtrace () from /usr/lib/libgcc_s.so.1
#5 0x00007eede3327b11 in backtrace () from /lib/libc.so.6
#6 0x000059535963a8a1 in emacs_backtrace ()
#7 0x000059535956499a in main ()
py3-matplotlib is a huge package and pulls in a bunch of
extra dependencies, so it s not easy to ask other people to just
install this big package plus these other dependencies, and then run
this command , especially if we have to file an upstream bug and
talk to people who may not even run the distribution we re using. So
I set up to try and come up with a smaller recipe to reproduce the
issue, ideally something that s not tied to a specific package from
the distribution.
Having all the information gathered from the initial debug session,
especially the Emacs backtrace, I thought that I could write a very
simple program that just invoked the backtrace function from glibc
in order to trigger the code path that leads to _Unwind_Backtrace.
Here s what I wrote:
#include <execinfo.h>
int
main(int argc, char *argv[])
void *a[4096];
backtrace (a, 100);
return 0;
GCC 15
I had to stop my investigation efforts because something more
important came up: it was time to upload GCC 15 to Wolfi. I spent a
couple of weeks working on this (it involved rebuilding the whole
archive, filing hundreds of FTBFS bugs, patching some programs, etc.),
and by the end of it the transition went smooth. When the GCC 15
upload was finally done, I switched my focus back to the glibc
hardening problem.
The first thing I did was to yes, reproduce the bug again. It had
been a few weeks since I had touched the package, after all. So I
built a hardened glibc with the latest GCC and the bug did not
happen anymore!
Fortunately, the very first thing I thought was this must be GCC ,
so I rebuilt the hardened glibc with GCC 14, and the bug was there
again. Huh, unexpected but very interesting.
Diving into glibc and libgcc
At this point, I was ready to start some serious debugging. And then
I got a message on Signal. It was one of those moments where two
minds think alike: Gabriel decided to check how I was doing, and I was
thinking about him because this involved glibc, and Gabriel
contributed to the project for many years. I explained what I was
doing, and he promptly offered to help. Yes, there are more people
who love low level debugging!
We spent several hours going through disassembles of certain functions
(because we didn t have any debug information in the beginning),
trying to make sense of what we were seeing. There was some heavy GDB
involved; unfortunately I completely lost the session s history
because it was done inside a container running inside an ephemeral VM.
But we learned a lot. For example:
-
It was hard to actually understand the full stack trace leading to
uw_init_context_1[cold]. _Unwind_Backtrace obviously didn t
call it (it called uw_init_context_1, but what was that [cold]
doing?). We had to investigate the disassemble of
uw_init_context_1 in order to determined where
uw_init_context_1[cold] was being called.
-
The
[cold] suffix is a GCC function attribute that can be used to
tell the compiler that the function is unlikely to be reached. When
I read that, my mind immediately jumped to this must be an
assertion , so I went to the source code and found the spot.
-
We were able to determine that the return code of
uw_frame_state_for was 5, which means _URC_END_OF_STACK.
That s why the assertion was triggering.
After finding these facts without debug information, I decided to bite
the bullet and recompiled GCC 14 with -O0 -g3, so that we could
debug what uw_frame_state_for was doing. After banging our heads a
bit more, we found that fde is NULL at this excerpt:
// ...
fde = _Unwind_Find_FDE (context->ra + _Unwind_IsSignalFrame (context) - 1,
&context->bases);
if (fde == NULL)
#ifdef MD_FALLBACK_FRAME_STATE_FOR
/* Couldn't find frame unwind info for this function. Try a
target-specific fallback mechanism. This will necessarily
not provide a personality routine or LSDA. */
return MD_FALLBACK_FRAME_STATE_FOR (context, fs);
#else
return _URC_END_OF_STACK;
#endif
// ...
We re debugging on amd64, which means that
MD_FALLBACK_FRAME_STATE_FOR is defined and therefore is called. But
that s not really important for our case here, because we had
established before that _Unwind_Find_FDE would never return NULL
when using a non-hardened glibc (or a glibc compiled with GCC 15). So
we decided to look into what _Unwind_Find_FDE did.
The function is complex because it deals with .eh_frame , but we
were able to pinpoint the exact location where find_fde_tail (one of
the functions called by _Unwind_Find_FDE) is returning NULL:
if (pc < table[0].initial_loc + data_base)
return NULL;
We looked at the addresses of pc and table[0].initial_loc + data_base, and found that the former fell within libgcc s text
section, which the latter fell within /lib/ld-linux-x86-64.so.2
text.
At this point, we were already too tired to continue. I decided to
keep looking at the problem later and see if I could get any further.
Bisecting GCC
The next day, I woke up determined to find what changed in GCC 15 that
caused the bug to disappear. Unless you know GCC s internals like
they are your own home (which I definitely don t), the best way to do
that is to git bisect the commits between GCC 14 and 15.
I spent a few days running the bisect. It took me more time than I d
have liked to find the right range of commits to pass git bisect
(because of how branches and tags are done in GCC s repository), and I
also had to write some helper scripts that:
- Modified the
gcc.yaml package definition to make it build with the
commit being bisected.
- Built glibc using the GCC that was just built.
- Ran tests inside a docker container (with the recently built glibc
installed) to determine whether the bug was present.
At the end, I had a commit to point to:
commit 99b1daae18c095d6c94d32efb77442838e11cbfb
Author: Richard Biener <rguenther@suse.de>
Date: Fri May 3 14:04:41 2024 +0200
tree-optimization/114589 - remove profile based sink heuristics
Makes sense, right?! No? Well, it didn t for me either. Even after
reading what was changed in the code and the upstream bug fixed by the
commit, I was still clueless as to why this change fixed the problem
(I say fixed because it may very well be an unintended consequence
of the change, and some other problem might have been introduced).
Upstream takes over
After obtaining the commit that possibly fixed the bug, while talking
to Dann and explaining what I did, he suggested that I should file an
upstream bug and check with them. Great idea, of course.
I filed the following upstream bug:
https://gcc.gnu.org/bugzilla/show_bug.cgi?id=120653
It s a bit long, very dense and complex, but ultimately upstream was
able to find the real problem and have a patch accepted in just two
days. Nothing like knowing the code base. The initial bug became:
https://sourceware.org/bugzilla/show_bug.cgi?id=33088
In the end, the problem was indeed in how the linker defines
__ehdr_start, which, according to the code (from
elf/dl-support.c):
if (_dl_phdr == NULL)
/* Starting from binutils-2.23, the linker will define the
magic symbol __ehdr_start to point to our own ELF header
if it is visible in a segment that also includes the phdrs.
So we can set up _dl_phdr and _dl_phnum even without any
information from auxv. */
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
assert (__ehdr_start.e_phentsize == sizeof *GL(dl_phdr));
_dl_phdr = (const void *) &__ehdr_start + __ehdr_start.e_phoff;
_dl_phnum = __ehdr_start.e_phnum;
But the following definition is the problematic one (from elf/rtld.c):
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
This symbol (along with its counterpart, __ehdr_end) was being
run-time relocated when it shouldn t be. The fix that was pushed
added optimization barriers to prevent the compiler from doing the
relocations.
I don t claim to fully understand what was done here, and Jakub s
analysis is a thing to behold, but in the end I was able to confirm
that the patch fixed the bug. And in the end, it was indeed a glibc
bug.
Conclusion
This was an awesome bug to investigate. It s one of those that
deserve a blog post, even though some of the final details of the fix
flew over my head.
I d like to start blogging more about these sort of bugs, because I ve
encountered my fair share of them throughout my career. And it was
great being able to do some debugging with another person, exchange
ideas, learn things together, and ultimately share that deep
satisfaction when we find why a crash is happening.
I have at least one more bug in my TODO list to write about (another
one with glibc, but this time I was able to get to the end of it and
come up with a patch). Stay tunned.
P.S.: After having published the post I realized that I forgot to
explain why the -z now and -fno-strict-aliasing flags were
important.
-z now is the flag that I determined to be the root cause of the
breakage. If I compiled glibc with every hardening flag except -z now, everything worked. So initially I thought that the problem had
to do with how ld.so was resolving symbols at runtime. As it turns
out, this ended up being more a symptom than the real cause of the
bug.
As for -fno-strict-aliasing, a Gentoo developer who commented on the
GCC bug above mentioned that this OpenSSF bug had a good point against
using this flag for hardening. I still have to do a deep dive on what
was discussed in the issue, but this is certainly something to take
into consideration. There s this very good write-up about strict
aliasing in general if you re interested in understanding it better.
-
It was hard to actually understand the full stack trace leading to
uw_init_context_1[cold]._Unwind_Backtraceobviously didn t call it (it calleduw_init_context_1, but what was that[cold]doing?). We had to investigate the disassemble ofuw_init_context_1in order to determined whereuw_init_context_1[cold]was being called. -
The
[cold]suffix is a GCC function attribute that can be used to tell the compiler that the function is unlikely to be reached. When I read that, my mind immediately jumped to this must be an assertion , so I went to the source code and found the spot. -
We were able to determine that the return code of
uw_frame_state_forwas5, which means_URC_END_OF_STACK. That s why the assertion was triggering.
-O0 -g3, so that we could
debug what uw_frame_state_for was doing. After banging our heads a
bit more, we found that fde is NULL at this excerpt:
// ...
fde = _Unwind_Find_FDE (context->ra + _Unwind_IsSignalFrame (context) - 1,
&context->bases);
if (fde == NULL)
#ifdef MD_FALLBACK_FRAME_STATE_FOR
/* Couldn't find frame unwind info for this function. Try a
target-specific fallback mechanism. This will necessarily
not provide a personality routine or LSDA. */
return MD_FALLBACK_FRAME_STATE_FOR (context, fs);
#else
return _URC_END_OF_STACK;
#endif
// ...
MD_FALLBACK_FRAME_STATE_FOR is defined and therefore is called. But
that s not really important for our case here, because we had
established before that _Unwind_Find_FDE would never return NULL
when using a non-hardened glibc (or a glibc compiled with GCC 15). So
we decided to look into what _Unwind_Find_FDE did.
The function is complex because it deals with .eh_frame , but we
were able to pinpoint the exact location where find_fde_tail (one of
the functions called by _Unwind_Find_FDE) is returning NULL:
if (pc < table[0].initial_loc + data_base)
return NULL;
pc and table[0].initial_loc + data_base, and found that the former fell within libgcc s text
section, which the latter fell within /lib/ld-linux-x86-64.so.2
text.
At this point, we were already too tired to continue. I decided to
keep looking at the problem later and see if I could get any further.
Bisecting GCC
The next day, I woke up determined to find what changed in GCC 15 that
caused the bug to disappear. Unless you know GCC s internals like
they are your own home (which I definitely don t), the best way to do
that is to git bisect the commits between GCC 14 and 15.
I spent a few days running the bisect. It took me more time than I d
have liked to find the right range of commits to pass git bisect
(because of how branches and tags are done in GCC s repository), and I
also had to write some helper scripts that:
- Modified the
gcc.yaml package definition to make it build with the
commit being bisected.
- Built glibc using the GCC that was just built.
- Ran tests inside a docker container (with the recently built glibc
installed) to determine whether the bug was present.
At the end, I had a commit to point to:
commit 99b1daae18c095d6c94d32efb77442838e11cbfb
Author: Richard Biener <rguenther@suse.de>
Date: Fri May 3 14:04:41 2024 +0200
tree-optimization/114589 - remove profile based sink heuristics
Makes sense, right?! No? Well, it didn t for me either. Even after
reading what was changed in the code and the upstream bug fixed by the
commit, I was still clueless as to why this change fixed the problem
(I say fixed because it may very well be an unintended consequence
of the change, and some other problem might have been introduced).
Upstream takes over
After obtaining the commit that possibly fixed the bug, while talking
to Dann and explaining what I did, he suggested that I should file an
upstream bug and check with them. Great idea, of course.
I filed the following upstream bug:
https://gcc.gnu.org/bugzilla/show_bug.cgi?id=120653
It s a bit long, very dense and complex, but ultimately upstream was
able to find the real problem and have a patch accepted in just two
days. Nothing like knowing the code base. The initial bug became:
https://sourceware.org/bugzilla/show_bug.cgi?id=33088
In the end, the problem was indeed in how the linker defines
__ehdr_start, which, according to the code (from
elf/dl-support.c):
if (_dl_phdr == NULL)
/* Starting from binutils-2.23, the linker will define the
magic symbol __ehdr_start to point to our own ELF header
if it is visible in a segment that also includes the phdrs.
So we can set up _dl_phdr and _dl_phnum even without any
information from auxv. */
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
assert (__ehdr_start.e_phentsize == sizeof *GL(dl_phdr));
_dl_phdr = (const void *) &__ehdr_start + __ehdr_start.e_phoff;
_dl_phnum = __ehdr_start.e_phnum;
But the following definition is the problematic one (from elf/rtld.c):
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
This symbol (along with its counterpart, __ehdr_end) was being
run-time relocated when it shouldn t be. The fix that was pushed
added optimization barriers to prevent the compiler from doing the
relocations.
I don t claim to fully understand what was done here, and Jakub s
analysis is a thing to behold, but in the end I was able to confirm
that the patch fixed the bug. And in the end, it was indeed a glibc
bug.
Conclusion
This was an awesome bug to investigate. It s one of those that
deserve a blog post, even though some of the final details of the fix
flew over my head.
I d like to start blogging more about these sort of bugs, because I ve
encountered my fair share of them throughout my career. And it was
great being able to do some debugging with another person, exchange
ideas, learn things together, and ultimately share that deep
satisfaction when we find why a crash is happening.
I have at least one more bug in my TODO list to write about (another
one with glibc, but this time I was able to get to the end of it and
come up with a patch). Stay tunned.
P.S.: After having published the post I realized that I forgot to
explain why the -z now and -fno-strict-aliasing flags were
important.
-z now is the flag that I determined to be the root cause of the
breakage. If I compiled glibc with every hardening flag except -z now, everything worked. So initially I thought that the problem had
to do with how ld.so was resolving symbols at runtime. As it turns
out, this ended up being more a symptom than the real cause of the
bug.
As for -fno-strict-aliasing, a Gentoo developer who commented on the
GCC bug above mentioned that this OpenSSF bug had a good point against
using this flag for hardening. I still have to do a deep dive on what
was discussed in the issue, but this is certainly something to take
into consideration. There s this very good write-up about strict
aliasing in general if you re interested in understanding it better.
gcc.yaml package definition to make it build with the
commit being bisected.commit 99b1daae18c095d6c94d32efb77442838e11cbfb
Author: Richard Biener <rguenther@suse.de>
Date: Fri May 3 14:04:41 2024 +0200
tree-optimization/114589 - remove profile based sink heuristics
__ehdr_start, which, according to the code (from
elf/dl-support.c):
if (_dl_phdr == NULL)
/* Starting from binutils-2.23, the linker will define the
magic symbol __ehdr_start to point to our own ELF header
if it is visible in a segment that also includes the phdrs.
So we can set up _dl_phdr and _dl_phnum even without any
information from auxv. */
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
assert (__ehdr_start.e_phentsize == sizeof *GL(dl_phdr));
_dl_phdr = (const void *) &__ehdr_start + __ehdr_start.e_phoff;
_dl_phnum = __ehdr_start.e_phnum;
elf/rtld.c):
extern const ElfW(Ehdr) __ehdr_start attribute_hidden;
__ehdr_end) was being
run-time relocated when it shouldn t be. The fix that was pushed
added optimization barriers to prevent the compiler from doing the
relocations.
I don t claim to fully understand what was done here, and Jakub s
analysis is a thing to behold, but in the end I was able to confirm
that the patch fixed the bug. And in the end, it was indeed a glibc
bug.

 A new version of
 Continuing with my
 Another point release for Etch has been done; now it's the time for the CD
team to roll out new images after the next mirror pulse. The official
announcements (prepared by Alexander Reichle-Schmehl, thanks!) will follow
shortly afterwards. FTP master of the day was Joerg Jaspert, who
did his first point release since Woody, as he told us on IRC. We
appreciate your work and you spending your time that shortly before
going to Argentina.
This point release includes the etchnhalf update introducing a new kernel
image (based on 2.6.24) and some driver updates. Additionally the
infamous openssl hole will be fixed for good, even for new installs.
Again I want to present you a list of people who contributed to this
release. It cannot be complete as I got the information out of the
 Last week I did again some work on
 There have been several long-term wishlist bugs on Mutt to include the
(in?)famous "sidebar" patch. It adds a panel on the left side of the screen to
list mailboxes with message counts.
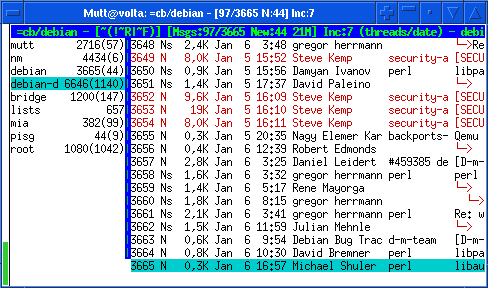 We do ship several patches with Debian's Mutt package that are not considered
for inclusion by the upstream authors, but this one is different. It touches
the core of the UI renderer and adds extensive counting of messages. There's
been quite a hype about the patch, it was even included in the (now
discontinued [1]) mutt-ng fork. Unfortunately, the patch was technically questionable, it
was written for the Mutt tarballs and didn't easily apply to CVS, and most
versions floating around contained lots of cruft like backup files and
temporary editor files. Furthermore, it is far from bug-free and even segfaults
occasionally.
Some months ago we decided we would build a second binary package to put the
patch in so we don't destabilize the standard package. Thanks Dann Frazier, we
got a clean patch, Adeodato had the right idea on how to build two binaries
from the same, differently-patched source (make install would run havoc, the
trick was to build the patched version before the regular one), and I
resolved some more involved conflicts with the maildir-mtime patch.
So, finally, there it is: