I am a heavy user of sidenotes:1 they keep optional content next to the
text instead of sending the reader to the bottom of the page and back. Tufte
CSS renders them without JavaScript but only accepts inline content. CSS
anchor positioning, now supported by recent browsers,2 is an
elegant alternative. Sidenotes can hold several blocks, still without
JavaScript, and fall back below the paragraph referencing them on narrow
viewports and older browsers.
In 2023, Eric Meyer demonstrated this technique in Nuclear Anchored
Sidenotes. The main improvement over other solutions is that the notes can
sit anywhere in the HTML document. You can place them after the paragraph
referencing them, as regular block elements for text browsers, screen readers,
feed readers, and reader mode to render them properly:
Rendering in Lynx, a text browser
When the viewport is too narrow or the browser does not support CSS anchor
positioning, you can style them so the reader can skip them or glance at them
without losing their position in the text:
Rendering below the paragraph on a narrow viewport
Once the viewport is large enough, they appear in the margin, at the same
vertical position as the matching reference mark, unless they would collide with
a previous sidenote, as in the example below:3
Rendering in the margin on a large viewport
The gist of CSS anchoring is to position an element relative to another
element the anchor. For the sidenotes, the anchor is the reference mark. I use
the following markup, with a data attribute to specify the anchor name:
The matching note is an <aside> element carrying the same data attribute for
the anchor name. We put it after the paragraph holding the reference mark:
<asiderole="note"id="sidenote-YYY"data-anchor="--lf-sn-YYY"><sup>1</sup><p>A first paragraph.</p><p>A second paragraph.</p></aside>
On a narrow viewport or when the browser is too old for CSS anchoring, we style
the sidenote, which stays below its paragraph, with a muted color:
aside[role="note"]margin-block:1rlh;color:#444;
On a wide viewport and when the browser is recent enough, we move the sidenote
to the right margin:
attr() extracts the anchor name for the reference mark from the data-anchor
attribute. It returns a string, unless we specify a CSS unit or a type, like
here: the browser parses the data attribute as a custom
identifier, which anchor-name validates as a dashed
identifier, a custom identifier starting with two
dashes.4
The note itself is absolutely positioned past the right edge of the main block.
It selects the matching reference mark as its anchor with position-anchor set
to the value of the data-anchor attribute. Each note is also an anchor named
--lf-sidenote. We use it to keep the next note from colliding with this one.
The anchor() CSS function lets us position the note s top
edge relative to its anchor: anchor(top) aligns the top edge of the note with
the top edge of the reference mark. It can also take another anchor as a
parameter: anchor(--lf-sidenote bottom) would align the top edge of the note
with the bottom edge of the closest preceding anchor named --lf-sidenote so
the previous note.5 Like attr(), anchor() accepts a fallback
value as its second parameter and use it when the named anchor does not exist.
The top property handles three cases, illustrated in the following diagram:
The three cases for the vertical position of a note
The first note s top edge aligns with the top edge of its reference mark: as
there is no previous note, anchor(--lf-sidenote bottom, -1rlh) + 1rlh
resolves to 0 and max() returns anchor(top).
When the reference mark of a later note sits above the bottom of the previous
note, plus some vertical space, the note goes below the previous one to avoid
a collision. max() returns anchor(--lf-sidenote bottom) + 1rlh.
Otherwise, the note s top edge aligns with the reference mark s top edge, as
max() returns anchor(top).
Have a look at the complete stylesheet, which also adapts the
reference mark to the location of the note: a arrow when the note sits below
the paragraph, a arrow when it moves to the margin. Gwern s Sidenotes In
Web Design lists more implementations and their trade-offs.
Some bloggers aim to write a post in 30 minutes. I planned to publish
three web-related articles this weekend. Instead, I spent an inordinate amount
of time elsewhere: about 15 commits on the build system, a pull request to
update CSS highlighting for nested selectors in Pygments, and a
small correction to MDN s article on the anchor() CSS function. The
SVG illustration took a bit less than an hour and the article itself a handful
of hours. The attr() function came in after I thought inline style looks
ugly, isn t there a better way? But, hey, I still think this is worth it!
My PhD advisor told me this is unwise.
The first bits of anchor positioning are supported from Chrome 125 (May 2024), Firefox 147 (January 2026), and Safari 26 (September 2025).
Before Safari 26.5, sidenotes may collide due to a bug in how dependency
chains are handled. You can detect this situation with some JavaScript.
It is, however, not needed in the solution described here as we depend on a
more recent feature.
If you noticed the runt in the first note, I share your pain and lament that
Firefox does not implement text-wrap: pretty.
Typed attr() is supported from Chrome 133 (February 2025),
Firefox 155 (September 2026), and Safari 27 (September 2026). Check Una
Kravets article for details. To support more
browsers, you can inline the anchor name and the position anchor directly in
the HTML:
The exact rule for the target anchor element is more complex: if an
ancestor of [the note] satisfies the following conditions, return the
nearest such element to [the note]. Otherwise, return the last element in
tree order that satisfies the conditions. One of these conditions is that
[the candidate] is an acceptable anchor element for [the note], which
requires that [the candidate] is laid out strictly before [the note],
where the relevant clause is that [the candidate] is either not absolutely
positioned or occurs earlier in the flat tree order than [the note].
This August, I accomplished what I wanted for many years: I deleted the last cgo
dependency in Debian Code Search! This was made possible by Go s recently
introduced SIMD support, because now we can implement the TurboPFor integer
compression format as efficiently more efficiently, in fact, by using the
newer AVX512 instruction set! as the reference implementation.
Background: Why does DCS need a fast Integer Codec?
Debian Code Search (DCS) is a search engine that allows searching all the Open
Source source code within Debian, with either literal search expressions or
regular expression search queries.
A search engine uses an inverted index: a map from term to documents containing
the term. Each document is typically represented most efficiently by using an
id, so the index consists of many lists of document ids.
When searching, it is important to quickly decode these lists to answer the
search query. However, there is a point of diminishing returns where the
decoding speed, even though it can still be measurably improved quite a bit, no
longer influences the overall query duration.
From 2012 (its inception) to 2019, Debian Code Search used to use a small index
format, and queries were fast because the index was kept entirely in RAM. In
2019, I implemented the new index
format, which adds an
on-disk positional index. For literal queries (78.2% of DCS queries), querying
the positional index on disk is faster than querying the non-positional index in
RAM.
The efficient encoding of the TurboPFor format makes it possible to fit such an
index on a mid-sized Hetzner server, which I rent with two 1 TB SSD disks. The
optimized decoder of the C TurboPFor library is what made decoding fast at query
time.
If you want to dive deeper into the algorithm, see this blog post from February
2019:
Use a C library via cgo so gcc or clang compiles
SIMD code. Debian Code Search used to use the
powturbo/TurboPFor
C library via cgo for the last 7 years.
The C TurboPFor library has served us well, but Debian Code Search was always
intended to be a project using Go, so I would prefer it if I did not have any C
code in the project.
Go 1.26 (released in February 2026) introduced the simd/archsimd package:
Go 1.26 introduces a new experimental simd/archsimd
package, which can be enabled by setting
the environment variable GOEXPERIMENT=simd at build time. This package
provides access to architecture-specific SIMD operations. It is currently
available on the amd64 architecture and supports 128-bit, 256-bit, and
512-bit vector types, such as Int8x16 and Float64x8, with operations such
as Int8x16.Add. The API is not yet considered stable.
Go 1.26 Release Notes
For my 2019 TurboPFor analysis, I implemented goturbopfor, a native Go
teaching decoder (without any SIMD),
because I find Go code easier to follow than C code, especially optimized C
code. My implementation was intentionally not optimized so that the code was
easier to study.
The TurboPFor format/algorithm has a vector-optimized part: bitpacking comes in
a scalar variant (bitunpack32) and a vector variant
(bitunpack256v32),
where the vector variant is used for full blocks (256 values) and the scalar
variant is used for remainder blocks (< 256 values).
When Go 1.26 was released, I used Claude Code to explore whether my native Go
decoder s bitunpack256v32 function (for the vertical vector layout) could be
implemented using Go SIMD, and the answer was yes, it was possible and it was
faster than without SIMD, but not quite at the level of C TurboPFor. If you let
Claude Code try for long enough, it eventually finds enough optimizations (about
10) to match C performance.
I don t want to vibe-code Debian Code Search, though, so I figured I would find
some time to review the SIMD code at some point and see if I could implement
something similar myself.
Before I found enough time and motivation to complete said review, I discovered
that to not regress real-life query performance by more than 10 to 100
milliseconds (which seems acceptable), I don t actually need to add SIMD code to
my teaching decoder at all; it would be sufficient to reduce allocations in my
teaching decoder and specialize it per bit width.
Encouraged by the possibility of using the optimized native Go decoder in Debian
Code Search, I explored whether I could also implement a native Go encoder so
that I could get rid of the C TurboPFor dependency entirely. The answer is yes,
it is doable in a few days, and it isn t even that much slower: Go is at 76% of
C, see Debian/dcs commit
e920dc7.
The goal I set myself at that point was to see if I could learn enough SIMD to
optimize the native Go encoder such that its performance would match how DCS
uses C TurboPFor (via cgo).
Beating C TurboPFor was possible in 2-3 commits (SIMD and bit width
specialization). To my surprise, Claude Fable 5 pointed out that the encoder s
block scanning could be done more efficiently using a technique called
positional popcount, and that is another 2x speed-up!
To be clear: I am not saying the Go compiler beats C here. Certainly, the C
compiler can also produce fast AVX512 code and can be used to implement
positional popcount. When comparing apples to apples, i.e. backporting the
AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a
little slower at 1.4x C.
This spectacular result (much faster than what DCS had before) got me curious
how far I could push the decoder with SIMD after all. I ended up
matching/exceeding the cgo version here, too!
The rest of this article explains a few classes of optimizations I encountered
along the way.
Starting Point
When I wrote my goturbopfor teaching
decoder, I named its functions to
match the upstream C TurboPFor library, but now I want to get away from names
like p4ndec256v32 they make sense from the TurboPFor perspective, but for
Debian Code Search, we can use cleaner names.
Before writing any code, I audited how DCS uses integer compression /
decompression.
API design: BlockEncoder, BlockDecoder and streaming
In Debian Code Search, we have the following usage patterns:
Partial Indexing: When a new package (or package version) enters Debian,
all of its (text) files are indexed. If the hello-2.12.3-1
package (hypothetically) contained
only hello.c with printf("hello!\n");, we would assign document ID 1 to
hello.c and store in the partial index that trigrams pri, rin, int,
ntf, etc. are all found in doc 1 (hello.c).
Full Index Merging: The many thousands of partial index files (for each
Debian package) are combined into a small handful of large index files: When
searching, it would be expensive to consult thousands of indexes. To merge
multiple partial index files into one larger index (which can then be
efficiently queried), we need to re-encode the partial index files: what used
to be document ID 1 in the partial index might be document ID 2531 in the
full index.
Querying (searching): When users enter search queries, these queries need
to be answered as quickly as possible. The relevant entries in the full
indexes are decoded (in parallel).
For reading the index, we do keep the decoded uint32s fully in memory, so we
only need DecodeN(input []byte, output []uint32) (read int), a function that
reads len(output) values (uint32) from input and returns how many bytes it
consumed.
For writing the index (both in partial indexing, and when merging), keeping the
entire index in memory is prohibitively expensive, so we need a streaming API,
for decoding and for encoding.
Ultimately, I converged on the following API:
packagepforenctypeBlockEncoderstruct// scratch buffers can go here// EncodeBlock encodes len(vals)<=256 uint32s into dest (one TurboPFor block).func(*BlockEncoder)EncodeBlock(dest[]byte,vals[]uint32)[]byte// EncodeN calls EncodeBlock in a loop.func(*BlockEncoder)EncodeN(dest[]byte,vals[]uint32)[]bytetypeStreamEncoderstructbeBlockEncodervals[256]uint32// scratch buffers// if full, you need to call [EncodeBlock]func(*StreamEncoder)Add(valuint32)(fullbool)// EncodeBlock must be called after all data was [Add]ed.//
// Write the returned buffer to file or send it over the network;// it is only valid until the next [EncodeBlock] call.func(*StreamEncoder)EncodeBlock()[]byteifse.n==0returnnil// turn an extra EncodeBlock into a no-op//
This API (the decoder works similarly) allows us to process data in TurboPFor
format without any memory allocations. The types are not safe for concurrent use
by multiple goroutines. The zero value is ready to be used. For the streaming
API, the result only stays valid until the next call.
Initial Implementation
Before we can optimize anything, we need a working decoder and encoder. The
decoder already exists: my goturbopfor teaching decoder. Next up, I needed an
encoder.
Writing a TurboPFor encoder has a delightfully simple starting point: You can
encode all values at bit width 32, in little endian, at which point you only
need to add a one-byte TurboPFor block header every 256 values and you re done:
Of course, this is a terribly inefficient compressor, so after the first commit,
the real work starts: implement each block type until the compression matches
the original C TurboPFor implementation (same output file size), or in other
words: do the reverse of the decoder.
The TurboPFor bitpacking block type (bitpacking implementation
commit)
encodes a bit stream of variable bit width (where the bit width is in range
0 bitWidth 32) in little
endian byte order. By scanning all
values and choosing the smallest bit width that allows representing all
values, this technique saves disk space (compresses).
The bitpacking with exceptions block type (bitpacking with exceptions
implementation
commit)
determines two bit widths: one for values, the other bit width for encoding
exceptions. This allows choosing a lower bit width (that does not cover all
values) compared to the bitpacking block type. A bitmap encodes whether a
value has an exception or not.
The bitpacking with VB exceptions block type (bitpacking with VB
exceptions implementation
commit)
is a variant which does not use an exception bitmap and encodes exceptions
using a variable byte integer encoding. This is more efficient when there are
few exceptions (less than 20) or the exceptions are very different in bit
width compared to the other values.
Lastly, the constant block type (constant implementation
commit)
stores just one value on disk. This is useful for all-zero or all-one blocks,
for example.
I found it interesting to realize that the main work of the encoder is to scan
the input values and choose the optimal block type, whereas the actual encoding
itself is cheap in comparison.
At this point, we can look at
performance
and see that the Go encoder is at 76% of the C encoder.
In all honesty, I could have probably stopped here, but now that the milestone
of a viable replacement was reached, I got curious to see how far it would be
possible to push the encoder (how much work to reach C speeds?) and afterwards,
the decoder, too.
Setup
The microarchitecture level: set GOAMD64
The microarchitecture of a CPU determines which instructions it provides, and
that includes not just SIMD instruction sets (like AVX2), but also other useful
instructions like LZCNT (Leading Zero Count), which can be used to implement
math/bits.Len32 more efficiently, which
the TurboPFor encoder needs to call on every input value to determine the ideal
bit width.
Let s walk through how to set the microarchitecture level when using Go on
64-bit x86 (x86-64).
Go uses the GOARCH environment
variable to configure the target
compilation architecture, and I am using the value amd64 to select 64-bit x86
(AVX2 and AVX512 are instruction sets found on x86-64 CPUs). With
GOARCH=amd64, the architecture-specific variable
GOAMD64 configures the
microarchitecture level for which to compile and Go 1.18 introduced these 4
different levels:
GOAMD64=v1 (default): The baseline.
Exclusively generates instructions that all 64-bit x86 processors can execute.
GOAMD64=v2: all v1 instructions,
plus CMPXCHG16B, LAHF, SAHF, POPCNT, SSE3, SSE4.1, SSE4.2, SSSE3.
GOAMD64=v3: all v2 instructions,
plus AVX, AVX2, BMI1, BMI2, F16C, FMA, LZCNT, MOVBE, OSXSAVE.
GOAMD64=v4: all v3 instructions,
plus AVX512F, AVX512BW, AVX512CD, AVX512DQ, AVX512VL.
In 2026, I generally recommend compiling with GOAMD64=v3 so that functions
like bits.OnesCount8 are
compiled into intrinsics
(POPCNT)
instead of using a lookup table.
For Intel CPUs, setting GOAMD64=v3 means your programs will only start on
Haswell CPUs (2013) or newer; for AMD CPUs that means Zen 1 (2017) or newer.
In this specific case (DCS), I am even compiling with GOAMD64=v4. The v4
microarchitecture level requires AVX512, which means AMD Zen 4, Zen 5 or newer
(Intel s story is complicated). Luckily, both my main development PC (Zen 5)
and the Debian Code Search server (Zen 4) are recent enough. Setting
GOAMD64=v4 has little effect on Go 1.27 itself: the only change is that maps
use one less instruction (VPBROADCASTB instead of PSHUFB). But compiling
with GOAMD64=v4 allows us to move one more feature check from runtime to
compile time, see SIMD build tags.
It makes sense to set the microarchitecture level in your benchmark setup so
that you don t measure the slow fallback implementations. I use export GOAMD64=v4 in my Makefile.
Benchmarking setup
Go s built-in testing package contains support for
benchmarks which are written in
functions of the form func BenchmarkXxx(b *testing.B). The simplest way to run
such benchmarks is go test -bench=., but I ended up configuring a few
convenience make targets, which write results to bench.txt and compare
against baseline.txt (the previous commit s results, usually), using the very
useful benchstat tool.
GOTEST=go test# -count=6 gives p 0.002 in benchstat:
# https://pkg.go.dev/golang.org/x/perf/cmd/benchstat
BENCHFLAGS=-run=^$$ -bench=. -benchtime=200000x -count=6# use taskset -c1 to always pin to the same single core,
# avoiding accidental scheduling on different cores on
# mixed-core CPUs like the Ryzen 9 9950X3D.
TASKSET=taskset -c 1BENCH=$(TASKSET)$(GOTEST)$(BENCHFLAGS).PHONY: all test bench bench-baseline bench-relative
all: test
bench: test
$(BENCH) tee bench.txt
# Compares compression ratio between C and Go implementation
benchstat -col /impl -row '/n /vals' -filter '-/impl:go-stream .unit:(encoded-bytes)' bench.txt
# Compares performance between C (cgo) and Go implementation
benchstat -col /impl -row '/n /vals' -filter '.unit:(Mval/s)' bench.txt
bench-baseline: test
$(BENCH) tee baseline.txt
bench-relative: test
$(BENCH) tee bench.txt
benchstat -filter '-/impl:go-stream .unit:(encoded-bytes)' baseline.txt bench.txt
benchstat -filter '/impl:go .unit:(Mval/s)' baseline.txt bench.txt
The encoded-bytes and Mval/s units are custom metrics I am reporting from
the various sub-benchmarks, which are arranged
such that I can filter / report them with benchstat.
The main encoder (and decoder) benchmarks compare 3 different implementations
(cgo, Go, Go with the StreamEncoder API) with a number of benchmark
cases
that are designed to cover the different block types and contain a similar mix
of values as what we see in Debian Code Search:
// reportMetrics adds Mval/s and encoded-bytes metrics to all benchmarks.funcreportMetrics(b*testing.B,nint,nencodedint)b.ReportMetric(float64(nencoded),"encoded-bytes")b.ReportMetric(float64(b.N*n)/1e6/b.Elapsed().Seconds(),"Mval/s")// BenchmarkEncode/n=<N>/vals=<testcase>/impl=<c go go-stream>//
// e.g. BenchmarkEncode/n=2048/vals=one-constant/impl=go-streamfuncBenchmarkEncode(b*testing.B)for_,tc:=rangeallBenchCases()n:=len(tc.vals)b.Run(fmt.Sprintf("n=%d/vals=%s",n,tc.name),func(b*testing.B)b.Run("impl=c",func(b*testing.B)b.ReportAllocs()varencoded[]bytebuf:=make([]byte,turbopfor.EncodingSize(n))forb.Loop()encoded=turbopfor.P4nenc256v32Buf(buf,tc.vals)reportMetrics(b,n,len(encoded)) )b.Run("impl=go",func(b*testing.B)b.ReportAllocs()varbeBlockEncodervarencoded[]bytebuf:=make([]byte,0,turbopfor.EncodingSize(n))forb.Loop()encoded=be.EncodeN(buf,tc.vals)reportMetrics(b,n,len(encoded)) )b.Run("impl=go-stream",func(b*testing.B)b.ReportAllocs()varseStreamEncodervarencodedintforb.Loop()encoded=0for_,val:=rangetc.valsifse.Add(val)encoded+=len(se.EncodeBlock())encoded+=len(se.EncodeBlock())reportMetrics(b,n,encoded) ) )
CPU counters: perf
Go has included excellent performance tooling for many years, see the
Profiling Go Programs blog post (2011) for an
example of how to use pprof, a sampling profiler. This profiler can help track
down which part of a program runs slow, or where memory allocations happen.
Once you identified the slow part of a program, how do you know why it s slow?
To learn more about the specific bottlenecks your program encounters, you can
consult your CPU s hardware performance
counters. For
example, you could check the branch
predictor counters to see if
your program is slow due to a high number of branch mispredicts.
On Linux, the perf tool is the best way to access the CPU hardware performance
counters. A good starting point for working with perf is the documentation on
Top-down analysis with the perf
tool , which describes the
optimization method that Intel established.
In my Makefile, I set up two perf targets:
# GOTEST and TASKSET like shown in the earlier benchmarking setup section:
GOTEST=go test -pgo=encode.cpuprof
TASKSET=taskset -c 1PERFBENCHFLAGS=-test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=200000x
# Use perf(1) to capture AMD IBS (the equivalent to Intel PEBS)
# PipelineL1 is roughly equivalent to Intel TopdownL1
perf:$(GOTEST) -c
$(TASKSET) perf stat -M PipelineL1 ./pforenc.test -test.run=^$$$(PERFBENCHFLAGS) sudo perf record -F 4999 -e ibs_op// --call-graph fp ./pforenc.test -test.run=^$$$(PERFBENCHFLAGS) sudo chmod 644 perf.data
# 488281 iterations 2048 values = 1.000e9 values, so counter/1e9 = per value.
perf-per-value:$(GOTEST) -c
$(TASKSET) perf stat -x, -e cycles:u,instructions:u,branches:u,branch-misses:u ./pforenc.test -test.run=^$$ -test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=488281x 2>&1 >/dev/null awk -F, ' printf "%-16s %6.2f /val\n", $$3, $$1/1e9 '
The perf-per-value numbers are high level numbers that indicate how much work
the implementation is doing. Reducing the number usually increases speed.
To see the counters for each instruction (and source code lines), I use make perf, followed by perf report. A quick shortcut is perf annotate, which
directly shows the hottest function.
Optimizations (scalar)
Let s first see how far we can get without reaching for SIMD instructions.
(The examples are not necessarily in commit order, but cherry-picked for clarity.)
Profile-Guided Optimization (PGO)
PGO stands for Profile-Guided Optimization and is a feature that Go introduced
as a preview in Go 1.20 (released in February 2023) and shipped as ready for
general production use in Go 1.21 (released in August
2023).
The idea is to capture a CPU profile that records where your program spends most
of its CPU time, which you then provide to the Go compiler to give it more data
to make better decisions.
Most importantly, this way the Go compiler can inline functions much more
aggressively than its usual heuristics allow,
which does have a measurably positive effect in my series of optimization
commits. Another optimization that a PGO profile allows the compiler to do is
conditional devirtualization but
our TurboPFor code does not use any interfaces.
My strategy is to enable PGO before doing any other optimizations, so that we
have the full inlining budget available that PGO gives us, and can measure the
effect of other commits clearly.
Surprisingly, turning on PGO actually decreases our
performance
(-13% geomean), but a closer investigation reveals that we just got unlucky. Let
me explain.
Aside from inlining and conditional devirtualization, PGO also influences
alignment: The Go compiler sets PCALIGNMAX(64, 31) on the first block of a
loop (the loop body ) for all loops in hot functions (per the PGO profile),
i.e. Go will insert up to 31 bytes of padding to make the block land on a
64-byte boundary. Documentation like AMD s Software Optimization Guide for the
AMD Zen5 Microarchitecture (2024,
#58455) explicitly recommends aligning hot loops that way:
[ ] for hot loops, some further knowledge of trade-offs can be
helpful. Because the processor can read an aligned 64-byte fetch block every
cycle, it is suggested to either align the start of the loop to the beginning
of a 64-byte cache line [ ]
Indeed, when compiling with -gcflags=all=-d=alignhot=0 to disable the
alignment, performance remains as good as without PGO. How can the padding hurt
more than help? The answer is: It s not the padding itself! It s a side-effect
of the padding moving instructions to different addresses.
In the unlucky arrangement, a macro-fused CMPQ+JGE instruction pair now ends
up exactly on a 32-byte boundary. However, the Go compiler ensures fused
branch sequences must never cross or end at a 32-byte boundary to fix Intel
erratum
SKX102
(discussion: Go issue #35881) by
inserting NOPs.
This NOP padding, unlike the loop alignment padding, is not free; these extra
instructions slow down our otherwise dispatch-bound loops.
Because the commits after the PGO enabling commit change the code, this unlucky
situation is avoided for the rest of the optimization series (by chance).
Reducing memory allocations
Memory allocations are quite expensive, at least in comparison to
encoding/decoding integers, so I followed my usual strategy of first reducing
memory allocations as much as possible.
In my goturbopfor teaching decoder, whenever the code needed a scratch buffer,
it would allocate it right then and there with make():
// p4dec32 decodes one block of TurboPFor-encoded 32 bit intsfunc(d*decoder)p4dec32(input[]byte,output[]uint32)(readint)// switchblockTypecaseblockBitpackingExceptions:bx,input:=input[0],input[1:]n:=len(output)exmap:=inputnex:=0// number of exceptionsfori:=0;i<n;i++ifexmap[i/8]&(1<<uint(i%8))!=0nex++input=input[(n+7)/8:]exceptions:=make([]uint32,nex)input=input[bitunpack32(input,exceptions,bx):]input=input[d.bitunpack(input,output,b):]fori:=0;i<n;i++ifexmap[i/8]&(1<<uint(i%8))!=0output[i]+=exceptions[0]<<bexceptions=exceptions[1:]returnbefore-len(input)
The Go compiler can turn make(T, n) calls into stack allocations, if n is
known at compile-time. But, in this case nex is not known at compile-time. We
can verify that Go calls into the runtime (runtime.makeslice) by dumping the
object code (assembly) with source annotated (-S):
An easy speed-up was to avoid allocations through
reuse
(in goturbopfor). In the DCS pfordec package (with the improved
API design), I ended up with a vals [256]uint32 field in the StreamDecoder
type, which brings us from 773 Mval/s to 858 Mval/s on the debian-mix:
Aside from the speed-up, avoiding memory allocations is generally nice in
benchmarks because it removes the garbage collector from the equation and makes
it less likely that your benchmarks get other processes OOM-killed on the same
machine.
Generics for bit width specialization
In general, we want to make it easy for the compiler to understand as much as
possible about our algorithm. Consider this bitpack implementation:
Let s think through what determines the iterations and control flow this
function uses:
The number of input values (vals), but not their actual value.
The bit width to pack into (bitWidth).
With a bit of careful rearrangement, we can provide the compiler with both, a
fixed number of input values (say, 32), and a bit width, both known at compile
time. Why is this worthwhile? Because we can manually unroll the loop, let the
compiler eliminate much of the repetition and get much faster compiled code as a
result!
Let s first fix the number of input values to 32 and rewrite the loop to
calculate the position offsets within dest instead of changing dest on each
value (with AppendUint32):
funcbitpack32Unrolled(dest[]byte,vals*[32]uint32,bitWidthint)// only one bounds check for 32 valuesdest=dest[:4*bitWidth:4*bitWidth]mask:=uint32(1<<bitWidth-1)varaccuint64varhave,posint// Manually unrolled loop starts here.// Each iteration is identical except for the vals[x] index.acc =uint64(vals[0]&mask)<<havehave+=bitWidthifhave>=32binary.LittleEndian.PutUint32(dest[pos:pos+4],uint32(acc))pos+=4acc>>=32have-=32// vals[1] .. vals[30] elided for brevity// Each loop iteration is 8 lines of Go code, so for 32 input values,// bitpack32Unrolled contains 8*32 = 256 lines of code.acc =uint64(vals[31]&mask)<<havehave+=bitWidthifhave>=32binary.LittleEndian.PutUint32(dest[pos:pos+4],uint32(acc))pos+=4acc>>=32have-=32// have == 0; for all bitWidths
Next, we want to specialize not just for 32 input values, but also for each of
the 32 bit widths.
Can we do better than hand-copying bitpack32Unrolled 32 times (= 8192 lines of Go code)?
Yes, we can use Go generics to help us with the code generation!
In Go, array types like [4]byte (not
slices like []byte!) contain the length of the array as part of their type,
meaning [1]byte (an array of length 1) is a different type than [2]byte.
Instead of passing the bit width as a function parameter, we can declare 32
different types (one for each bit width) and recover the bit width (at compile
time!) from the type system:
typebitWidthTinterface[1]byte[2]byte[3]byte[4]byte[5]byte[6]byte[7]byte[8]byte[9]byte[10]byte[11]byte[12]byte[13]byte[14]byte[15]byte[16]byte[17]byte[18]byte[19]byte[20]byte[21]byte[22]byte[23]byte[24]byte[25]byte[26]byte[27]byte[28]byte[29]byte[30]byte[31]byte[32]bytefuncbitpack32Unrolled[TbitWidthT](dest[]byte,vals*[32]uint32)varzeroTbitWidth:=len(zero)// known at compile timedest=dest[:4*bitWidth:4*bitWidth]// make cap known at compile timemask:=uint32(1<<bitWidth-1)varaccuint64varhave,posint// Manually unrolled loop starts here.// Each iteration is identical except for the vals[x] index.acc =uint64(vals[0]&mask)<<havehave+=bitWidthifhave>=32binary.LittleEndian.PutUint32(dest[pos:pos+4],uint32(acc))pos+=4acc>>=32have-=32// vals[1] .. vals[31] elided for brevity
When we instantiate bitpack32Unrolled[bitWidthT] with all 32 different types
([1]byte, [2]byte, , [32]byte), the compiler substitutes the bitWidthT
type parameter and produces 32 copies of the function, which we can find in our
compiled executable with names like
github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[12]uint8]. The
shape of a generic type is based on its memory layout, so a shape for
[1]byte must be different than the shape for [2]byte.
Because the bitWidth is now known at compile time, the Go compiler can
generate close to the optimal machine code for each bit width, which we can
confirm using go tool objdump.
The code is branchless (after the one bounds check per 32 values) and aside from
the loads and stores (from/to memory) consists only of shifts and bit
operations, all with constant operands:
Now we need to actually call bitpack32 from the general bitpack function:
funcbitpack(dest[]byte,vals[]uint32,bitWidthint)[]byteifbitWidth==0returndest// no payload, sparse block with only exceptionsiflen(vals)>=32size:=4*bitWidthforlen(vals)>=32existing:=len(dest)dest=slices.Grow(dest,size)[:existing+size]bitpack32(dest[existing:]/*append*/,(*[32]uint32)(vals),bitWidth)vals=vals[32:]mask:=uint32(1<<bitWidth-1)varaccuint64varhaveintfor_,val:=rangevalsacc =uint64(val&mask)<<havehave+=bitWidthforhave>=32dest=binary.LittleEndian.AppendUint32(dest,uint32(acc))acc>>=32have-=32forhave>0dest=append(dest,byte(acc))acc>>=8have-=8returndestfuncbitpack32(dest[]byte,vals*[32]uint32,bitWidthint)switchbitWidthcase1:bitpack32Unrolled[[1]byte](dest,vals)case2:bitpack32Unrolled[[2]byte](dest,vals)case3:bitpack32Unrolled[[3]byte](dest,vals)case4:bitpack32Unrolled[[4]byte](dest,vals)case5:bitpack32Unrolled[[5]byte](dest,vals)case6:bitpack32Unrolled[[6]byte](dest,vals)case7:bitpack32Unrolled[[7]byte](dest,vals)case8:bitpack32Unrolled[[8]byte](dest,vals)case9:bitpack32Unrolled[[9]byte](dest,vals)case10:bitpack32Unrolled[[10]byte](dest,vals)case11:bitpack32Unrolled[[11]byte](dest,vals)case12:bitpack32Unrolled[[12]byte](dest,vals)case13:bitpack32Unrolled[[13]byte](dest,vals)case14:bitpack32Unrolled[[14]byte](dest,vals)case15:bitpack32Unrolled[[15]byte](dest,vals)case16:bitpack32Unrolled[[16]byte](dest,vals)case17:bitpack32Unrolled[[17]byte](dest,vals)case18:bitpack32Unrolled[[18]byte](dest,vals)case19:bitpack32Unrolled[[19]byte](dest,vals)case20:bitpack32Unrolled[[20]byte](dest,vals)case21:bitpack32Unrolled[[21]byte](dest,vals)case22:bitpack32Unrolled[[22]byte](dest,vals)case23:bitpack32Unrolled[[23]byte](dest,vals)case24:bitpack32Unrolled[[24]byte](dest,vals)case25:bitpack32Unrolled[[25]byte](dest,vals)case26:bitpack32Unrolled[[26]byte](dest,vals)case27:bitpack32Unrolled[[27]byte](dest,vals)case28:bitpack32Unrolled[[28]byte](dest,vals)case29:bitpack32Unrolled[[29]byte](dest,vals)case30:bitpack32Unrolled[[30]byte](dest,vals)case31:bitpack32Unrolled[[31]byte](dest,vals)case32:bitpack32Unrolled[[32]byte](dest,vals)
Encoding remainder blocks is quite a bit faster (full blocks use the vertical
layout anyway):
This performance win comes at the cost of binary size increase. In this case,
the .text section (executable code) grows by about 20 KB and the .gopclntab
section grows by another 26 KB. Definitely a price I am very willing to pay, but
the case might not be as clear in all circumstances.
Optimization: Bigger strides with SIMD
Even without reaching for SIMD instructions, a TurboPFor implementation can be
made faster by making it work bigger strides. Take this code from the
goturbopfor teaching decoder which counts the number of exceptions by checking
if each value s bit is set in the exception bitmap:
caseblockBitpackingExceptions:bx,input:=input[0],input[1:]n:=len(output)exmap,input:=input,input[(n+7)/8:]nex:=0// number of exceptionsfori:=rangenifexmap[i/8]&(1<<uint(i%8))!=0nex++exceptions:=d.scratch[:nex]
We can use the bits.OnesCount64
functions to count ones bits in the exception bitmap, 64 values at a time. For
remainder blocks, the rest is processed 8 values (1 byte) at a time:
i:=0for;i+8<=n/8;i+=8xm8:=binary.LittleEndian.Uint64(exmap[i:])nex+=bits.OnesCount64(xm8)for;i<(n+7)/8;i++xmb:=exmap[i]// Clear the bits which do not belong to the exception map:ifrem:=n-i*8;rem<8xmb&=1<<rem-1// Go compiles OnesCount32 into an intrinsic,// but not OnesCount8, so we convert to uint32:nex+=bits.OnesCount32(uint32(xmb))
OnesCount64 uses a 64-bit register. For comparison, AVX2 SIMD instructions use
256-bit registers (= 8 uint32) and AVX512 SIMD instructions use 512-bit registers.
In the following sections, we will first set up our build tags for conditional
compilation to use a trivial SIMD instruction, then walk through an AVX2 and
AVX512 SIMD kernel.
SIMD build tags
Let s assume we have the following scalar code:
constant.go:
To increase throughput, we can use AVX2 instructions if they are available on the CPU on which the program runs, i.e. using runtime dispatch. We ll first rename fillConstant to fillConstantScalar (it s now the fallback path):
constant.go:
Next, we ll supply two different implementations (constant_nosimd.go and constant_amd64.go), the latter of which is selected when compiling for GOARCH=amd64 with GOEXPERIMENT=simd (the latter will hopefully be dropped in a later version of Go). The nosimd variant just dispatches to the fillConstantScalar, which will likely be inlined:
The constant_amd64.go variant assigns the hasAVX2 global variable by doing a CPUID check and then jumps to the scalar fallback if !hasAVX2, i.e. the CPU is too old:
//go:build goexperiment.simd && amd64packagepfordecimport"simd/archsimd"varhasAVX2=archsimd.X86.AVX2()funcfillConstant(output[]uint32,valuint32)if!hasAVX2fillConstantScalar(output,val)returnval8:=archsimd.BroadcastUint32x8(val)i:=0for;i+8<=len(output);i+=8val8.StoreArray((*[8]uint32)(output[i:i+8]))// use the scalar implementation for the last <= 7 elementsfillConstantScalar(output[i:],val)
We can go one step further by conditionally compiling const hasAVX2 = true
when GOAMD64 is set to v3 or higher (i.e. the amd64.v3 build tag is
set). As a practical example from Debian Code Search, we currently need the
following checks / dispatches:
In regular (non-SIMD) bitpacking, integers are stored on disk one after
the other, padded to a full byte, as a byte is the smallest addressable unit
when reading data from disk. For example, if you bitpack only one 3 bit int,
you will end up with 5 bits of padding.
SIMD bitpacking works like regular bitpacking, but processes 8 uint32
little-endian values at the same time, leveraging the AVX instruction
set. The following
illustration shows the order in which 3-bit integers are decoded from disk:
The scalar implementation uses an array of 8 uint64 to process 8 values at a
time:
funcbitunpack256v32(input[]byte,dest[]uint32,bitWidthint)(readint)mask:=uint64(1)<<bitWidth-1orig:=len(input)varbitsuintvaracc[8]uint64// accumulator: current+next bitsforop:=0;op<len(dest);ifbits<uint(bitWidth)// read 8 more uint32sfori:=range8acc[i] =uint64(binary.LittleEndian.Uint32(input))<<bitsinput=input[4:]bits+=32fori:=range8dest[op]=uint32(acc[i]&mask)op++acc[i]>>=bitWidthbits-=uint(bitWidth)returnorig-len(input)
The SIMD version also processes 8 values, but without a for i := range 8 loop!
One difference is that we no longer have the luxury of using uint64 for acc
(holding rest and current bits); because AVX2 registers only fit 8 uint32 (not
8 uint64). Instead, we split acc into rest8 and cur8.
funcbitunpack256v32(fullinput[]byte,fulldest[]uint32,bitWidthint)(readint)dest:=fulldest[:256]ifbitWidth==0clear(dest)return0n:=32*int(bitWidth)input:=fullinput[:n]// tell the Go compiler how long the input ismask8:=archsimd.BroadcastUint32x8(uint32(1)<<bitWidth-1)bitWidth8:=archsimd.BroadcastUint32x8(uint32(bitWidth))varbitsuintpos:=0// var acc [8]uint64varrest8archsimd.Uint32x8varcur8archsimd.Uint32x8forop:=0;op<256;op+=8ifbits<uint(bitWidth)// read 8 more uint32s// acc[i] = uint64(binary.LittleEndian.Uint32(input)) << bitsnext:=archsimd.LoadUint8x32(input[pos:pos+32]).ReshapeToUint32s()pos+=32// input = input[4:]cur8=rest8.Or(next.ShiftAllLeft(uint64(bits)))// acc[i] >>= bitWidthrest8=next.ShiftAllRight(uint64(uint(bitWidth)-bits))bits+=32elsecur8=rest8// acc[i] >>= bitWidthrest8=rest8.ShiftRight(bitWidth8)// dest[op] = uint32(acc[i] & mask)cur8.And(mask8).Store(dest[op:op+8])bits-=uint(bitWidth)returnn
The SIMD version benchmarks about 3x as fast as the scalar version.
Another significant speedup is to use generics for bit width
specialization for this SIMD kernel so that
bitWidth becomes a compile-time constant and the compiler can generate better
code.
Positional Popcount
For my TurboPFor encoder, I implemented the same techniques as described above:
These changes are sufficient to roughly match the cgo performance, but then
Claude Fable 5 found another 2x speed-up on top of that!
The key observation is that once encoding blocks is fast, the preceding step of
scanning the input values to decide which block type to use becomes the
bottleneck. Here is the encoder s main encode function, which first does one
pass over the input values (scan) and then prices all different block types at
all relevant bit widths (requires fast access to the scan histogram):
func(be*BlockEncoder)encode(dest[]byte,vals[]uint32,layoutblockLayout)[]bytevarstatsstatsscan(&stats,vals)// gathers statistics from every value in valsbitWidth:=bits.Len32(stats.or)ifstats.or==stats.andreturnbe.encodeConstant(dest,vals,bitWidth)n:=len(vals)// bitpacking is the default, unless we find a more efficient block type.bestType:=blockBitpackingbestB:=bitWidthbest:=priceBitpack(n,bitWidth,layout)// Walk from high bitWidths to low: to break ties, we prefer// the encoding with fewer exceptions (for faster decoding).forb:=bitWidth-1;b>=0;b--// up to 32 iterationsnex:=int(stats.cnt[b])size:=priceBitpackExceptions(n,b,bitWidth,nex,layout)ifsize<bestbestType=blockBitpackingExceptionsbestB=bbest=size// Over-approximate the number of VB bytes.vb:=nex+// exceptions using 1, 2, 3, 4, or 5 VB bytesint(stats.cnt[b+7]+// exceptions using 2, 3, 4, or 5 VB bytesstats.cnt[b+14]+// exceptions using 3, 4, or 5 VB bytesstats.cnt[b+19]+// exceptions using 4 or 5 VB bytesstats.cnt[b+24])// exceptions using 5 VB bytessize=headerBytes+headerExBytes+payloadBytes(n,b,layout)+vb+nexifsize<bestbestType=blockBitpackingVBExceptionsbestB=bbest=sizeswitchbestTypecaseblockBitpacking:returnbe.encodeBitpack(dest,vals,layout,bitWidth)caseblockBitpackingExceptions:returnbe.encodeBitpackExc(dest,vals,layout,bestB,bitWidth-bestB)caseblockBitpackingVBExceptions:returnbe.encodeBitpackVBExc(dest,vals,layout,bestB,int(stats.cnt[bestB]))default:panic("BUG: bestType not implemented")
I ll show you a slightly shortened version of scan, the function which is the bottleneck:
typestatsstruct// cnt[n] = how many values where bits.Len32(val)>n,// i.e. how many exceptions are required for bitWidth=n.// Padded so that cnt[b+24] is always in bounds.cnt[32+24]uint32funcscan(output*stats,vals[]uint32)for_,val:=rangevalsforb:=rangebits.Len32(val)output.cnt[b]++// b bits are not enough to store val
Let s consider the following 3 example values to understand the resulting cnt:
input
input (bin)
bits.Len32
23
0b0000010111
5
5
0b0000000101
3
666
0b1010011010
10
The resulting cnt exception count histogram would contain (cnt shortened to c):
c[0]
c[1]
c[2]
c[3]
c[4]
c[5]
c[6]
c[7]
c[8]
c[9]
c[10]
3
3
3
2
2
1
1
1
1
1
0
In words, this means that at bit width 10, we could encode all the values
without any exceptions.
But most values do not need 10 bits, so a bit width of 5 would be more
efficient, but requires storing one exception. Encoding at bit width 4 requires
2 exceptions, and so on.
The scan function above is intentionally kept simple for illustration. We can
make it faster by moving the per-bit-width loop outside the per-element
loop.
The fast version still needs about 12 instructions per value. With SIMD, we can
reduce this to by 8x to only 1.5 instructions per value!
The trick: smear masks enable positional popcount
The trick is to turn each input value into its smear mask (imagine taking the
first 1 bit and smearing it across the remaining positions). Here are the smear
masks for our example:
input
input (bin)
bits.Len32
smear mask
23
0b0000010111
5
0b0000011111
5
0b0000000101
3
0b0000000111
666
0b1010011010
10
0b1111111111
Turning a value into its smear mask is computationally cheap:
Go implements BitLen(x) (functions like bits.Len32) by calculating 32 - LZCNT(x). We can calculate the smear mask of a value with ^uint32(0) >> LZCNT(x), i.e. starting with a 32-one-bits mask and shifting it by the number
of leading zeros.
Now, to obtain e.g. cnt[4], we can count the 1 bits at bit position 4 of all
input values.
The POPCNT instruction counts bits very efficiently, but it counts one bits
within a register, so it counts rows, not columns. Counting columns is called
Positional Population Count.
I found the following papers that describe positional popcount with SIMD:
Positional Popcount: a visual explanation
To understand the AVX512 implementation of positional popcount, I found it most
helpful to visualize an AVX512 register (512 bits, i.e. 64 bytes). The graphic
below uses the Uint64x8 layout, meaning it divides the register into 8 lanes
of 64 bits (= 8 bytes) each.
This illustration shows the whole process: how uint32s are loaded into an
AVX512 register (all 4 of its bytes, in sequence) and where we end up, i.e. the
32 positional popcounts:
Let s break down this process into its individual steps.
First, we turn each loaded value into its smear mask as explained above.
The VPOPCNTB vector instruction calculates POPCNT (1 byte) of 64 bytes at
once, but first we need to shuffle the bytes inside the register: in load
order, we have a full uint32 (4 bytes), followed by another uint32, per
lane. First, we permute the bytes (VPERMB) such that all the first bytes of
each value end up in one lane ( transpose the bytes ):
Next, we transpose the bits using the GF2P8AFFINEQB instruction, which
sounds scary but turns out to be quite flexible for bit manipulation of all
kinds. The GF2P8AFFINEQB instruction is also the star of the show in Go s
Green Tea Garbage Collector (2025). Here is the
bit transpose, shown in the AVX512 register layout (see below for a different
layout):
I found it easier to understand the transpose step when arranging the 8 bytes of
lane 0 from top-to-bottom (instead of left-to-right), because then it looks like
a 90 degree clockwise rotation:
Now we can use VPOPCNTB to count the bits in all 64 bytes at once:
After all loop iterations (processing 16 values each) are done, we add the two
groups (first 8 values, second 8 values) to obtain the 32 exception counts:
Positional Popcount: Go SIMD
Here is the Go code that implements what I described visually above:
funcscanSIMD(output*stats,vals[]uint32)ones16:=archsimd.BroadcastUint32x16(^uint32(0))// 16 32-one-bits masksshuffle:=archsimd.LoadUint8x64Array(&scanShuffle)units:=archsimd.LoadUint8x64Array(&scanUnits)varaccarchsimd.Uint8x64idx:=0for;idx+16<=len(vals);idx+=16v:=archsimd.LoadUint32x16(vals[idx:idx+16])// Replace all values with their smear masks.smear:=ones16.ShiftRight(v.LeadingZeros()).ReshapeToUint8s()// Transpose: shuffle the bytes, then transpose the bits.matrices:=smear.Permute(shuffle).ReshapeToUint64s()transposed:=units.GaloisFieldAffineTransform(matrices,0)// Popcount 64 bytes at once into the accumulator.acc=acc.Add(transposed.OnesCount())// Store the accumulator into output.cnt:// Widen the two groups of byte counts to uint16 lanes (so that// 128+128 = 256 fits), fold them into cnt[b] for b=0..31,// then widen again to the uint32 lanes of output.cnt.sum:=acc.GetLo().ExtendToUint16().Add(acc.GetHi().ExtendToUint16())sum.GetLo().ExtendToUint32().Store(output.cnt[0:16])sum.GetHi().ExtendToUint32().Store(output.cnt[16:32])// scalar tail for the 0..15 remaining valuesfor_,val:=rangevals[idx:]forb:=rangebits.Len32(val)output.cnt[b]++
Go even faster?
The SIMD optimizations I showed above beat the cgo TurboPFor library that Debian
Code Search used before. When comparing apples to apples, i.e. backporting the
AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a
little slower at 1.4x C.
Could we make my Go TurboPFor implementation even faster, to truly match the C
speed?
Yes! But also no. Let me explain:
We could use more SIMD instructions to remove all code that still processes
one value at a time. For example, in my encoder s encodeBitpackVBExc
function. Or we could price all bit widths concurrently in encode. Or in
the decoder s exception apply code path.
But all of these SIMD instructions
make understanding (and changing) the code harder, so I am cautious regarding
which ones I introduce.
A big part of the performance gap is due to Go s bounds
checks. While it costs
performance, bounds checking is great for safety, so I will not turn off
bounds checking. The Go compiler eliminates a number of bounds checks when it
understands it s safe to do so. One optimization avenue could be to make the
prove pass in the Go compiler smarter to eliminate more bounds checks.
When doing mid-stack inlining (proposal
#19348)
(2017), Go sometimes needs to put NOP instructions into the binary so that
it can attach inlining markers. For dispatch-bound functions, these extra
NOPs can measurable slow down execution.
The Go compiler currently allows specifying the architecture (GOARCH=amd64)
and microarchitecture (GOAMD64=v3), but not a specific CPU architecture
(like AMD Zen 4). Therefore, CPU-specific workarounds for one vendor affect
all the generated code. The specific one I encountered in my code is that the
Go compiler emits XORL CX,CX before every POPCNT to break a
false-output-dependency from the Intel Sandy Bridge Skylake era, which is
unnecessary on AMD Zen CPUs.
I suspect that Go intentionally does not offer this level of customizability.
After all of the above points are addressed, what remains is better code
generation in specific cases. To illustrate what I mean, consider the example
of incrementing a loop variable, where Go re-derives an index every time:
Go: POPCNTL; ADDQ DI,CX; LEAQ (base)(CX*4) (3 instructions)
clang: popcnt; lea rax,[rax+4*rdi] (2 instructions)
Depending on the specific case, improving the compiler might be easy or
prohibitively complex. Often, such improvements are hard to measure conclusively.
Conclusion
Go s SIMD support makes available in Go code without having to resort to cgo
or assembly a powerful part of modern CPUs which allows speeding up the kind
of computation that TurboPFor needs by an order of magnitude!
I found it very valuable to use a coding agent (Claude Code, with Opus 5 and
Fable 5 in this case) to help with the many tedious parts of such performance
work (and still it took me weeks!). The LLM can read objdump output much faster
than I can, can see patterns and correlations I might never identify, never
becomes frustrated after a compiler error or runtime panic, and never runs out
of patience to run one more experiment, as long as I give it measurable and
reachable goals.
The performance of the SIMD code which one can get from the Go compiler is
pretty close to what a good C compiler like clang provides. The CPU performance
counters show value decoding speeds of 7 instructions/cycle (IPC) on a machine
where the maximum is 8 IPC.
To me, SIMD support is a very welcome addition to Go.
Too Like the Lightning is a science fantasy (?) novel and the first
of a four-book series. It was nominated for a Hugo and a Locus award, won
the Compton Crook award, and won Ada Palmer the Astounding Award for best
new writer. It was Palmer's first novel.
Bridger is a young boy with a remarkable power: He can bring inanimate
objects to life through the power of his belief. He is being hidden by the
Saneer-Weeksbooth bash', a family (?) business (?) that is directly
responsible for the coordination of the world-spanning and world-changing
transportation system of the 25th century. Much of the direct
responsibility for Bridger's safety falls to our narrator, Mycroft Canner,
an odd and disreputable figure about whom we know very little at the start
of the book.
As this book opens, two things are happening simultaneously. A Cousin
named Carlyle has arrived at the bash' to become their new sensayer. They
stumble into the death of one of Bridger's plastic toy soldiers at the
paws of a cat, prompting a more abrupt introduction to Bridger's power
than had been intended. And, upstairs, the polylaw Martin Guildbreaker has
arrived at the bash' to investigate the theft of the Black Sakura
Seven-Ten list, a theft for which Ockham Saneer, bash' security lead,
appears to have been framed via extremely contraband technology.
Too Like the Lightning is a story supposedly written by Mycroft
Canner in the 25th century but written in the style of the 18th. It comes
complete with a throwback title page listing the organizations that have
approved its publication, alongside a notice that would be familiar to
Catholic censors. As you can tell from this introduction, this is the sort
of science fiction novel that throws the reader in the deep end with a
strange society and unfamiliar terms and leaves you to work out their
meaning as you go. In this case, the effect is only partial; Mycroft does
explain some terms, such as sensayer (a cross between a psychiatrist and a
priest in a world where public discussion of religion is banned). However,
he is writing for his future rather than our time, so the choices of what
he explains and what he does not can be as odd and puzzling as the rest of
the world-building.
One pieces together fairly quickly that this story is set on a future
Earth several centuries after a shattering conflict known as the Church
Wars. Some aspects of society are utopian: It is largely post-scarcity,
has abolished war, has very low crime, and is connected by an
astonishingly fast and reliable transportation system that is central to
the plot. Most aspects, though, are ambiguous, mixed, or just deeply
weird. Geography-based political polities have been mostly abolished.
Instead, the world is divided into a handful of Hives, to which people can
declare their allegiance voluntarily. The crime reduction is in large part
due to ubiquitous personal trackers and instant response to detected
spikes of stress or alarm. Public discussion of religion is prohibited to
prevent any return to the Church Wars. Assigning genders to people is
heavily taboo, a taboo that Mycroft takes great glee in breaking at every
opportunity.
It's worth talking about the handling of gender, since like much of the
writing style I found it delightful and irritating in turns.
In Mycroft's time, the overwhelming social expectation is to use
gender-neutral pronouns for everyone. Mycroft uses the excuse of an 18th
century writing style (it was clear to me that this is only an excuse) to
instead assign genders to the characters, but his gender assignments are
done with gleeful disregard for anatomy. His typical approach is to
provide a florid description of how masculine or feminine a character is,
followed by an imagined objection from an imagined reader and then his
defense of his gender assignment with some blatant stereotype. Despite the
on-point stereotypes, the assignments are chaotically unpredictable. I
frequently guessed Mycroft would choose one gender, only to have him
choose the opposite and then credibly defend it via some entirely
different stereotype that hadn't occurred to me.
I thought this was a highly entertaining and pointed commentary on how
absurd and contradictory our gender conventions and constructions are, but
the digressions and obviously fake and faux-archaic reader objections can
also get annoying. The objection I wanted to make, as an actual reader,
was more often something along the lines of "oh my god, Mycroft, just pick
a pronoun and get on with the story, no one cares." Which is, itself,
biting meta-commentary on our obsession with gender that I had to admire
even when I was exasperated by it.
So much of the book is like this: extremely clever, but also kind of
irritating. Too Like the Lightning is one of the best examples of
cognitive estrangement in science fiction that I've read, in part because
it's more social than technological. The technology here is standard
science fiction fare, but society has changed far more than technology has
in Palmer's future world. All (I think?) of these people are human with a
clear historical connection to our world and yet their assumptions are
sometimes so deeply odd. Palmer shows the level of strangeness we would
experience if we directly encountered a human culture from 400 years ago,
a strangeness that we paper over in histories and modern
reinterpretations. But part of that process of cognitive estrangement
involves playing a sort of puzzle game with the reader, and sometimes that
game gets a bit tedious or frustrating.
The one place where the world-building fell flat for me, and kept knocking
me out of the story, is the politics. Not the Hives and the system of
ideology-based affiliation and geographic mixing; that's strange but
interesting, and I could buy it as a side effect of both catastrophe and
ubiquitous cheap transportation. Not the complicated system of legal codes
and exceptions and competing jurisdictions; that felt believably baroque
in the way that complexity emerges in the friction in long-lived human
systems. My problem was with the scale, or rather the lack of scale.
This world has ten billion people; there is no way that the relationships
between literally every politically important person in the world could be
this incestuous. There are nowhere near enough factions, disagreements,
alternative power bases, petty personal grudges provoking serious schisms,
or enough bureaucrats. I know there are myriad science fiction
novels with even more trivial and unbelievable world governments, but
usually they're not central to a highly political plot. Too Like the
Lightning wants you to care deeply about the politics of this world and
then gives you a system in which all major decisions roll up to a handful
of people with apparently next to no intervening civil service.
Also, why is there so little redundancy? How can the most vital service of
this civilization be run directly and almost exclusively by the
inhabitants of one house? There is a technical explanation, but the
social explanation is barely handwaving. This is not how institutional
trust generally works; even with vast multinational high-capital
near-monopolies such as cloud computing, there are three major players and
innumerable smaller ones.
Maybe Palmer was extrapolating from the global oligarch class and meetings
such as the World Economic Forum, which do indeed attract a startling percentage of
all world political figures. The problem, though, is not the surface of
occasional gatherings or staged events seen early in this story. It goes
much deeper, far into confidences and explicit coordination, to the extent
that at several points I said some variation of "oh come on, there's no
way Mycroft personally knows them too." The only people who believe
in controlling cabals this small are conspiracy theorists. This is simply
not how humans work when this much power is at stake.
Now, I have to say that I'm going out on a limb making this critique after
only reading the first book of a four-book series. This is absolutely the
type of work for which my reaction and objections could be an intentional
effect created by Palmer in order to spring some unexpected justification
on the reader in book two or three. It's clear that there is some massive
social upheaval on the horizon in this series, and something very strange
is going on with one of the characters and their hold over other people.
Perhaps the reader disbelief is setting up that upheaval. If so, hats off
to her, and that's one of the perils of reviewing books as I read them.
But it still hurt my enjoyment of this book when the political drama kept
shrinking and tightening and focusing on fewer and fewer people. It felt
frankly unbelievable for the political universe of this highly political
book to be this claustrophobic. I wanted it to expand into the space that
should be available to an entire world teeming with fractious and complex
humanity.
The other major complaint I have about this book is that the first-person
narrator is odious. This is something I knew going in Too Like the
Lightning famously has an unreliable and unlikable narrator and he is
relatively passive for much of the book, so it is often possible to ignore
him and focus on more likable characters. I don't necessarily mind an
unlikable or unreliable narrator in this type of story.
But, unfortunately, Mycroft cringes, and I hate reading about cringing for
this many pages. His primary mode of interaction with people is
obsequious, performative fear with a weird, distasteful edge of
manipulation. Again, I think this is entirely intentional on Palmer's
part; we learn some of the reasons behind it by the end of this book, and
I'm sure we'll learn more in future books. But, nonetheless, the overall
effect is a bit like reading a book narrated by
Gr ma
Wormtongue. I can appreciate the narrative role of that character without
wanting to spend this much time in his head.
I have very mixed feelings about this book. The overall construction is
brilliant; it's a beautiful puzzle of oddity and alienation that provides
great fun for the type of science fiction reader who wants to work out the
rules of a strange society without a lot of infodumping. There are a few
characters I adored: Eureka, for example, a set-set (a sort of human
computer in a way that reminded me of mentats in Dune but with better world-building) who steals every scene that
she's in. I was very invested in the world-building, fascinated by the
Utopians, and want to learn more about what's going on.
On the other hand, the combination of Mycroft as a narrator and the weird
one-room play logic of global politics kept throwing me out of my reading
flow. It took me about a month to finish this book. The science fiction
and political fiction aspects of the story interested me more than Bridger
and whatever is going on with J.E.D.D. Mason, and I'm worried that my
least-favorite aspects will be central to the rest of the story. I was
enjoying a smaller percentage of the scenes by the end of the book than I
was at the start, which is not a great sign.
And yet, the ending absolutely worked on me. I don't want to stop here! I
will probably pick up the sequel, but I think it's going to take me a
while to brace myself for it.
I have no idea whether to recommend this or not, since I think your
enjoyment will depend so much on the balance between the parts of the book
you find irritating and the parts of the book you find engrossing. I'm
fairly sure most readers will find a little of both, but I have no idea
how to predict their relative weight. If you like cognitive estrangement,
this is great; I understand why so many science fiction reviewers rave
about this book. If you need to like the first-person protagonist, uh,
good luck. Maybe you'll have more tolerance for cringing than I do.
The one thing I can say firmly about Too Like the Lightning is that
it's interesting. It may be worth reading just to see how people
are stretching the genre, even if you end up not liking the effect. But be
warned that this book does not so much end on a cliffhanger as suddenly
stop at some random, nondescript point on the road leading to the cliff.
The ending is deeply unsatisfying; you will need to read more if you want
to understand what's going on.
Followed by Seven Surrenders.
Rating: 7 out of 10
AI slop is invading the web. A recent story about disallowing LLM-generated
submissions on Lobsters triggered a lot of debate. My personal worst
offenders are LinkedIn articles with AI-generated images and uninspired
articles filled with emojis from people trying to masquerade as experts on a
subject they don t care enough to write themselves. While I am unhappy about
this situation, I rely on LLMs for grammar, copyediting, and
translation. I don t see this as a contradiction.
I am a native French speaker, but I blog in both English and French. When I
started writing this blog in 2011, I was composing in French and translating
to English, but I found it was better to work in the reverse order to
avoid unnatural and non-idiomatic constructions. One of my goals is to write
good English but I never felt it was my strong point.1 For example, verb
tenses are often an issue, even if I mostly stick with the present tense. I
learn the rules and forget them right away. I also don t feel like hiring an
editor for something I see as a hobby.
As an example, I have kept the history of the successive iterations when writing
Scaling Akvorado BMP RIB with sharding :
the first draft, authored with the help of a thesaurus,2
I know that LLMs may alter the author s voice when editing, but the
corrections in the second step are minor. The prompt asks to apply light
stylistic edits, with some guidance around avoiding passive voice, long
sentences, bland verbs, and filler words. It also defines the target audience:
technical with a B2 level in English.
In the following excerpt, I used long time instead of long-standing. The
former is missing a hyphen and applies to people a long-time friend, while
the later relates to a situation a long-standing agreement. I had a hard
time understanding the reason of the second change: the LLM prefers a
defining relative clause to provide the definition of RIB sharding.
As the Internet routing table contains more than 1 million routes, Akvorado
needs to scale to tens of millions of routes. This has been a long
time long-standing challenge, but I expect this issue is now
fixed by using RIB sharding, a method to split that
splits the routing database into several parts to enable concurrent
updates.
In the next modification, the LLM puts device instead of equipment. This is
correct as equipment is an uncountable noun. I know that, but I still fall
into this trap.
When Akvorado does not find a route from a specific device, it falls back to a
route sent by another equipment device.
I ask the LLM to use descriptive verbs and it complies by replacing a
multi-word predicate with a lexically rich verb:
The benchmarks demonstrate it has better performance than
outperforms other packages, both packages for
lookups, insertions, and memory usage.
It also fixes grammar errors. In the next excerpt, a list of routes is a
singular expression. Moreover, stored is a state and I should not use into
as it expresses a change.
The list of routes for each prefix are is not stored
directly into in the prefix tree.
As a last example, consider the following snippet. The require verb
accepts a noun or an object followed by a to-infinitive. I can t use it with
just a to-infinitive.
An alternative would be to have one prefix tree for each peer but it would
require to configure configuring all routers to export
their routes.
As someone who didn t grow up speaking English, I struggle with these grammar
rules despite reading a lot of English material.3 French is more
complex to get started but more systematic. English is full of irregularities.
On each page, I disclose in the footer whether an AI modified the content. There
are three levels:
: no AI or almost no AI (e.g., grammar corrections)
: enhanced (e.g., copyediting)
: generated (e.g., translated from another language, even if human-edited)
Hover or tap the icon to reveal the AI s name and its role in the document.
Example of AI usage disclosure: Claude Sonnet 4.5 edited this article.
The graph below shows which tool altered each post, year by year. Recently, I
applied the grammar skill to past articles. Since 2018,
French articles have been translated with the help of DeepL first, then of
an LLM. Since 2024, English articles are copyedited.
🖼 Graph showing the AI usage over the years. Each level get its own
color.
AI usage over the years. Hover or tap a band for the details.
If you are strongly against any usage of LLMs specifically for writing, I hope
you accept my more nuanced position on the usage of these tools as a trade-off
to provide clearer and more engaging articles. Years of literature on improving
English told us it is important to choose the right word to keep the reader
engaged.
[ ] Good writing consists of mastering the fundamentals (vocabulary,
grammar, the elements of style) and then filling the third level of your
toolbox with the right instruments.
Stephen King, On Writing
Note
Unlike other recent articles, I did not use an LLM to edit this post:
an unnamed person kindly accepted to proofread it. I translated it to French
without using an LLM either.
I am quite happy with the writing tools provided by Kagi. Both the
translate tool and the dictionary are a valuable help to find
different wordings. I also lean on Kagi s research assistant when
researching a topic.
When I was ten, I played Monkey Island 2 in English without having
taken any classes. I used a dictionary to translate word by word and I found
the irregular verbs confusing and not in the dictionary.
A while back, I came across
the AI Fabric
system created by Daniel Miessler. I liked its approach of
providing command-line tools for filtering text using artificial
idiocy services, allowing stepwise operations to be applied to a piece
of text. The output of one operation can then serve as the input for
another in other words, Unix pipeline processing powered by large
language models. I do no longer remember exactly how I discovered it,
but suspect it was via Matthew Berman's video
"How To Install
Fabric - Open-Source AI Framework That Can Automate Your Life".
While the idea and concept behind AI Fabric appealed to me, its
implementation has continued to rub me the wrong way. It started off
as a Python project that I could only get running by downloading
random programs from the internet using Poetry. I tried to assess how
much work it would take to package all its missing dependencies for
Debian. However, before I got very far, the project shifted away from
Python and over to Go. This new implementation also relied on a build
system that seemed to encourage users to run arbitrary code downloaded
from the internet to get software working, and further moved to a
language I do not master as well as Python. The change bothered me
enough that I set my effort to set up a working command line LLM tool
in Debian aside for several months.
By chance, I came across a simple Python recipe in January
demonstrating how to communicate with a
llama.cpp API
server. I had already been working on packaging llama.cpp for Debian
together with the rest of Debian's AI team, and was fortunate enough
to own a working instance with a 24 GiB VRAM GPU from AMD, allowing me
to run useful models. Until that point, I had only used the basic web
client provided by the Debian package, lacking the spare time to
explore what else could be done. Then, I found this simple 50 line
Python script demonstrating how to interact with llama.cpp's
OpenAI-compatible API. I decided to revive the AI Fabric concept, and
implement the Unix pipeline filter tool with as few dependencies as
possible. It is now operational and working very well, relying solely
on standard Python features. The tool include a copy of the LLM
recipes from the AI Fabric project (called "patterns"), enabling easy
access to request summaries, translations, code review and other
useful tasks. Several hundred patterns are included, though I have
only tested about ten so far.
The LLM API server can be specified in
~/.config/hraesvelgr/config.ini like this:
With this configuration in place (you can also specify these values
directly on the command line), you can specify a pattern and a file to
process like this:
% bin/hraesvelgr --pattern explain_code bin/hraesvelgr
EXPLANATION:
This Python script is a client tool for interacting with an AI
service (likely a local LLM server) to process text using prompts
defined in the "AI Fabric" repository. It reads system and user
prompts from markdown files, sends them along with input text to a
chat completion API endpoint, and prints the generated response.
Key components:
1. It uses argparse for command-line argument parsing
2. The  send_chat_completion_request  function formats messages
   (system, user, query) into JSON and sends them via HTTP POST to
   an AI service endpoint
3.  read_file  function reads markdown files, replacing placeholders
   like  lang_code  with actual values from arguments
4. In main():
 - Parses command-line arguments for input file, API base URL,
   pattern type, language code, and debug flag
 - Ensures the base URL ends with a slash
 - Reads system prompt from data/patterns/ pattern /system.md
 - Optionally reads user prompt from data/patterns/ pattern /user.md
 - Reads input text either from stdin (when "-" is passed) or a file
 - Handles encoding fallback to ISO-8859-1 if UTF-8 fails
 - Sends the formatted request to the AI service and prints the response
The script assumes it's running in a directory containing a git
clone of https://github.com/danielmiessler/fabric/, which contains
the necessary prompt files.
This tool is designed to interface with local LLM servers that
support OpenAI-compatible chat completion APIs.
%
The list of available patterns can be viewed by running
bin/hraesvelgr --list-patterns. I have found the
summarize, translate,
improve_writing, review_code, and
explain_terms_and_conditions patterns particularly
useful. For example using the latter combined with a text based web
browser capable of dumping a page as plain text, can be done like this
(originally formatted in markdown, I converted to HTML using pandoc
for easier readability):
% w3m  -dump https://runbox.com/about/terms-service/   \
  hraesvelgr --pattern explain_terms_and_conditions
Executive Summary
This is a transparent, privacy-focused contract from
a Norwegian provider that generally respects user data rights and
operates under strict EU/EEA standards. However, it carries
strict liability limitations and an aggressive
data-deletion policy upon cancellation. The vibe is  Professional &
Privacy-First,  but you must manage your own backups and understand that
the company heavily shields itself from financial responsibility during
technical failures.
Key Takeaways
Your Data Stays Yours: Section 10.2 explicitly
states Runbox will never use your transmitted or stored data for
commercial purposes. This is a major privacy win.
[... trimmed output, as it is not the focus of this blog post ...]
If you sign:
Set up automated backups
immediately. Use IMAP sync to a local drive or a secondary
email provider before storing any critical documents or emails.
Do not rely on Runbox as your only archive.
Mark your
calendar for the 30-day trial end date. Miss the payment
window, and access closes instantly with no recovery period.
Monitor price changes at renewal. Since they can adjust
fees anytime, check their pricing page a few days before your
subscription renews to avoid unexpected charges.
NO FORCED ARBITRATION CLAUSE FOUND. REFUND POLICY IS STRICTLY CONDITIONAL (see Sections 4.2 4.5).
As you might have already noticed, I name my project
after the Norse God of Wind. I found a nice description of the
origin of the name on
Wikipedia:
In Vaf r nism l (The Lay of Vaf r nir), Odin questions the wise
j tunn Vaf r nir about the origin of the wind, and the j tunn
answers:
He is called Hr svelg,
who sits at heaven s end,
a giant, in the shape of an eagle;
from his wings
they say the wind comes over all people.
(translated by John Lindow in Norse Mythology: A Guide to Gods,
Heroes, Rituals, and Beliefs 2002)
The latest version of the code can be found at
https://codeberg.org/pere/hraesvelgr/. Perhaps you will find it as useful as I did?
As usual, if you use Bitcoin and wish to show your support of my
activities, please send Bitcoin donations to my address
15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.
FBReader
After my previous blog post about eBook readers in Debian [1] a reader recommended FBReader. I tried it and it s now my favourite reader. It works nicely on laptop and phone and takes significantly less RAM than Calibre or Arianna (especially important for phones). While the problems with my FLX1s not displaying text with Calibre or Arianna might be the fault of something on the FLX1s side those problems just don t happen with FBReader.
FBReader has apparently now got a proprietary version as the upstream, but we still have FOSS code to use in Debian. It would be nice if someone updated it to store the reading location using WebDAV and/or a local file that can be copied with the NextCloud client or similar. Currently there is code to store reading location in the Google cloud which I don t want to use. It s not THAT difficult to see what chapter you are at with one device and just skip to that part on another, but it is an annoyance.
One thing I really like about FBReader is that you can run it with a epub file on the command line and it just opens it and when it s been closed you can just open it again to the same spot in the same file. I don t want a library to view a book list, I just want to go back to what I was last reading in a hurry. Calibre might be better for some uses, for example I can imagine someone in the publishing industry with a collection of thousands of epub files finding that Calibre works better for them. But for the typical person who just wants to read one book and keep reading it until they finish it FBReader seems clearly better. The GUI is a little unusual, but it s not at all confusing and it works really well on mobile.
Okular
I tried Okular (the KDE viewer for PDF files etc) which displays epub files if you have the okular-extra-backends installed, but it appears to not display books with the background color set to black. I would appreciate it if someone who has read some public domain or CC licences epub files can recommend ones with a black background that I could use for testing as I can t file a Debian bug report without sample data to reproduce the bug. I decided not to use it for actual book reading as FBReader is far better for my use taking less RAM and being well optimised for mobile use.
Folite
Foliate supports specifying a book on the command-line which is nice. But it takes more memory than FBReader which is probably mostly due to using webkit to display things. The output was in 2 columns on my laptop in small text which is probably configurable but I didn t proceed with it. I determined that it doesn t compare with FBReader for my use. It s written in JavaScript which may be a positive feature for some people.
Koodo
I had a brief test of Koodo which isn t in Debian. Here is the Koodo Reader Github [2]. I installed the .deb that they created, it installs files to /opt/Koodo Reader/ (yes that s a space in the directory name) and appears to have Chromium as part of the runtime. I didn t go past that even though it appears to have a decent feature set. It is licensed under version 3 of the AGPL so is suitable for Debian packaging if someone wants to do it.
Thorium
I saw the Thorium reader on Github [3] which looks promising, it s under the BSD 3 clause license so is suitable for Debian packaging. The EDR Lab seems like a good project for advancing electronic document use [4] and it would be good to have their stuff in Debian.
For the moment I m happy using FBReader.
Prices
On the 19th of March I got a home battery system installed. The government has a rebate scheme so it had a list price of about $22k for a 40kWh setup and cost me about $12k. It seems that 40KWh is the minimum usable size for the amount of electricity I use, I have 84 cores running BOINC when they have nothing better to do which is 585W of TDP according to Intel. While the CPUs are certainly using less than the maximum TDP (both due to design safety limits and the fact that I have disabled hyper-threading on all systems due to it providing minimal benefits and potential security issues) given some power usage by cooling fans and some inefficiency in PSUs I think that assuming that 585W is accounted for 24*7 by CPUs is reasonable. So my home draws between 800W and 1KW when no-one is home and with an electric car and all electric cooking a reasonable amount of electricity can be used.
My bills prior to the battery installation were around $200/month which was based on charging my car only during sunny times as my electricity provider (Amber Electric) has variable rates based on wholesale prices. Also the feed in rates if my solar panels produce too much electricity in sunny times often go negative so if I don t use enough electricity. I haven t had the electric car long enough to find out what the bills might be in winter without a home battery.
Before getting the battery my daily bills according to the Amber app were usually between $5 and $10. After getting it the daily bills have almost always been below $5. The only day where it s been over $5 since the battery installation was when electricity was cheap and I fully charged the home battery and my car which used 50KWh in one day and cost $7.87 which is 16 cents per KWh. 16 cents isn t the cheapest price (sometimes it gets as low as 10 cents) but is fairly cheap, sometimes even in the cheap parts of the day it doesn t get that low (the cheapest price on the day I started writing this was 20 cents).
So it looks like this may save me $100 per month, if so there will be a 10% annual return on investment on the $12K I spent. This makes it a good investment, better than repaying a mortgage (which is generally under 6%) and almost as good as the long term results of index tracker funds. However if it cost $22K (the full price without subsidy) then it would still be ok but wouldn t be a great investment. The government subsidised batteries because the huge amount of power generated by rooftop solar systems was greater than the grid could use during the day in summer and batteries are needed to use that power when it s dark.
Android App
The battery system is from Fox ESS and the FoxCloud 2.0 Android app is a bit lacking in functionality. It has a timer for mode setting with options Self-use (not clearly explained), Feed-in Priority (not explained but testing shows feeding everything in to the grid), Back Up , Forced Charge , and Forced Discharge . Currently I have Forced Charge setup for most sunny 5 hours of the day for a maximum charge power of 5KW. I did that because about 25KW/day is what I need to cover everything and while the system can do almost 10KW that would charge the battery fully in a few hours and then electricity would be exported to the grid which would at best pay me almost nothing and at worst bill me for supplying electricity when they don t want it. There doesn t seem to be a never put locally generated power into the grid unless the battery is full option. The force charge mode allows stopping at a certain percentage, but when that is reached there is no fallback to another option. It would be nice if the people who designed the configuration could take as a baseline assumption that the macro programming in office suites and functions in spreadsheets are things that regular people are capable of using when designing the configuration options. I don t think we need a Turing complete programming language in the app to control batteries (although I would use it if there was one), but I think we need clauses like if battery is X% full then end this section .
There is no option to say force charge until 100% or force charge for the next X minutes as a one-off thing. If I came home in the afternoon with my car below 50% battery and a plan to do a lot of driving the next day then I d want to force charge it immediately to allow charging the car overnight. But I can t do that without entering a schedule . For Unix people imagine having to do everything via a cron job and no option to run something directly from the command-line.
It s a little annoying that they appear to have spent more development time on animations for the app than some of what should be core functionality.
Management
Amber has an option to allow my battery to be managed by them based on wholesale pries but I haven t done that as the feed-in prices are very low. So I just charge my battery when electricity is cheap and use it for the rest of the day. There is usually a factor of 2 or more price difference between the middle of the day and night time so that saves money. It also means I don t have to go out of my way to try and charge my car in the middle of the day. There is some energy lost in charging and discharging the batteries but it s not a lot. I configured the system to force charge for the 5 sunniest hours every day for 5KW as that s enough to keep it charged overnight and 5KW is greater than the amount of solar electricity produced on my house since I ve been monitoring it so that forces it to all be used for the battery. In summer I might have to change that to 6KW for the sunniest 2 or 3 hours and then 4KW or 5KW surrounding that which will be a pain to manage.
Instead of charging the car every day during sunny times I charge it once or twice a week, I have a 3.3KW charger and the car has a 40KWh battery so usually it takes me less than 10 hours to fully charge it and I get at least 5 hours of good sunlight in the process.
There are people hacking on these devices which is interesting to get direct control from computers [1], and apparently not banned from the official community for doing so. I m not enthusiastic enough to do this, I ve got plenty of other free software things to work on. But it s good that others are doing so.
David Patterson does not need an introduction. Being the brain behind many
of the inventions that shaped the computing industry (repeatedly) over the
past 40 years, when he put forward an opinion article in Communications of
the ACM targeting the current day political waves in the USA, I could not
avoid choosing it to write this review.
Patterson worked for a a public university (University of California at
Berkeley) between 1976 and 2016, and in this article he argues how
government-funded academic research (GoFAR) allows for faster, more
effective and freer development than private sector-funded research would,
putting his own career milestones as an example of how public money that
went to his research has easily been amplified by a factor of 10,000:1 for
the country s economy, and 1,000:1 particularly for the government.
Patterson illustrates this quoting five of the home-run research projects
he started and pursued with government funding, eventually spinning them
off as successful startups:
RISC (Reduced Instruction Set Computing): Microprocessor
architecture that reduces the complexity and power consumption of CPUs,
yielding much smaller and more efficient processors.
RAID (Redundant Array of Inexpensive Disks): Patterson experimented
with a way to present a series of independent hard drive units as if they
were a single, larger one, leading to increases in capacity and
reliability beyond what the industry could provide in single drives, for
a fraction of the price.
NOW (Network Of Workstations): Introduced what we now know as
computer clusters (in contrast of large-scale massively multiprocessed
cache-coherent systems known as supercomputers ), which nowadays power
over 80% of the Top500 supercomputer list and are the computer platform
of choice of practically all data centers.
RAD Lab (Reliable Adaptive Distributed Systems Lab): Pursued the
technology for data centers to be self-healing and self-managing, testing
and pushing early cloud-scalability limits
ParLab (Parallel Computing Lab): Given the development of massively
parallel processing inside even simple microprocessors, this lab explores
how to improve designs of parallel software and hardware, presenting the
ground works that proved that inherently parallel GPUs were better than
CPUs at machine learning tasks. It also developed the RISC-V open
instruction set architecture.
Patterson identifies principles for the projects he has led, that are
specially compatible with the ways research works at universitary systems:
Multidisciplinary teams, demonstrative usable artifacts, seven- to ten-year
impact horizons, five-year sunset clauses (to create urgency and to lower
opportunity costs), physical proximity of collaborators, and leadership
followed on team success rather than individual recognition.
While it could be argued that it s easy to point at Patterson s work as a
success example while he is by far not the average academic, the points he
makes on how GoFAR research has been fundamental for the advance of
science and technology, but also of biology, medicine, and several other
fields are very clear.
Problem statement
Currently if you have an automatically installed package A (= 1) where
A (= 1) Depends B (= 1)
A (= 2) Depends B (= 2)
and you upgrade B from 1 to 2; then you can:
Remove A (= 1)
Upgrade A to version 2
If A was installed by a chain initiated by Recommends (say X Rec Y, Y Depends A), the solver sometimes preferred removing A (and anything depending on it until it got).
I have a fix pending to introduce eager Recommends which fixes the practical case, but
this is still not sound.
In fact we can show that the solver produces the wrong result for small
minimal test cases, as well as the right result for some others without the
fix (hooray?).
Ensuring sound removals is more complex, and first of all it begs the question: When
is a removal sound? This, of course, is on us to define.
An easy case can be found in the Debian policy, 7.6.2 Replacing whole packages, forcing their removal :
If B (= 2) declares a Conflicts: A (= 1) and Replaces: A (= 1), then the removal
is valid. However this is incomplete as well, consider it declares Conflicts: A (< 1)
and Replaces: A (< 1); the solution to remove A rather than upgrade it would still
be wrong.
This indicates that we should only allow removing A if the conflicts could not be solved
by upgrading it.
The other case to explore is package removals. If B is removed, A should be removed as well;
however it there is another package X that Provides: B (= 1) and it is marked for install,
A should not be removed. That said, the solver is not allowed to install X to satisfy the
depends B (= 1) - only to satisfy other dependencies [we do not want to get into endless
loops where we switch between alternatives to keep reverse dependencies installed].
Proposed solution
To solve this, I propose the following definition:
Definition (sound removal): A removal of package P is sound if either:
A version v is installed that package-conflicts with B.
A package Q is removed and the installable versions of P package-depends on Q.
where the other definitions are:
Definition (installable version): A version v is installable if either it is installed,
or it is newer than an installed version of the same package (you may wish to change this to
accomodate downgrades, or require strict pinning, but here be dragons).
Definition (package-depends): A version vpackage-depends on a package B if either:
there exists a dependency in v that can be solved by any version of B, or
there exists a package C where v package-depends C and any (c in C) package-depends B (transitivity)
Definition (package-conflicts): A version vpackage-conflicts with an installed package B if either:
it declares a conflicts against an installable version of B; or
there exists a package C where v package-conflicts C,
and b package-depends C for installable versions b.
Translating this into a (modified) SAT solver
One approach may be to implement the logic in the conflict analysis that drives backtracking, i.e.
we assume a package A and when we reach not A, we analyse if the implication graph for not A
constitutes a sound removal, and then replace the assumption A with the assumption
A or "learned reason.
However, while this seems a plausible mechanism for a DPLL solver, for a modern CDCL solver, it s
not immediately evident how to analyse whether not A is sound if the reason for it is a learned
clause, rather than a problem clause.
Instead we propose a static encoding of the rules into a slightly modified SAT solver:
Given c1, , cn that transitive-conflicts A and D1, , Dn that A package-depends on,
introduce the rule:
A unless c1 or c2 or ... cn ... or not D1 or not D2 ... or not Dn
Rules of the form A... unless B... - where A... and B... are CNF - are
intuitively the same as A... or B..., however the semantic here is different:
We are not allowed to select B... to satisfy this clause.
This requires a SAT solver that tracks a reason for each literal being assigned,
such as solver3, rather than a SAT solver like MiniSAT that only tracks reasons across
propagation (solver3 may track A depends B or C as the reason for B without evaluating
C, whereas MiniSAT would only track it as the reason given not C).
Is it actually sound?
The proposed definition of a sound removal may still proof unsound as I either missed
something in the conclusion of the proposed definition that violates my goal I set out
to achieve, or I missed some of the goals.
I challenge you to find cases that cause removals that look wrong :D
I had to rent a house for a couple of months recently, which is long enough in California that it pushes you into proper tenant protection law. As landlords tend to do, they failed to return my security deposit within the 21 days required by law, having already failed to provide the required notification that I was entitled to an inspection before moving out. Cue some tedious argumentation with the letting agency, and eventually me threatening to take them to small claims court.
This post is not about that.
Now, under Californian law, the onus is on the landlord to hold and return the security deposit - the agency has no role in this. The only reason I was talking to them is that my lease didn't mention the name or address of the landlord (another legal violation, but the outcome is just that you get to serve the landlord via the agency). So it was a bit surprising when I received an email from the owner of the agency informing me that they did not hold the deposit and so were not liable - I already knew this.
The odd bit about this, though, is that they sent me another copy of the contract, asserting that it made it clear that the landlord held the deposit. I read it, and instead found a clause reading SECURITY: The security deposit will secure the performance of Tenant s obligations. IER may, but will not be obligated to, apply all portions of said deposit on account of Tenant s obligations. Any balance remaining upon termination will be returned to Tenant. Tenant will not have the right to apply the security deposit in payment of the last month s rent. Security deposit held at IER Trust Account., where IER is International Executive Rentals, the agency in question. Why send me a contract that says you hold the money while you're telling me you don't? And then I read further down and found this: Ok, fair enough, there's an addendum that says the landlord has it (I've removed the landlord's name, it's present in the original).
Except. I had no recollection of that addendum. I went back to the copy of the contract I had and discovered: Huh! But obviously I could just have edited that to remove it (there's no obvious reason for me to, but whatever), and then it'd be my word against theirs. However, I'd been sent the document via RightSignature, an online document signing platform, and they'd added a certification page that looked like this: Interestingly, the certificate page was identical in both documents, including the checksums, despite the content being different. So, how do I show which one is legitimate? You'd think given this certificate page this would be trivial, but RightSignature provides no documented mechanism whatsoever for anyone to verify any of the fields in the certificate, which is annoying but let's see what we can do anyway.
First up, let's look at the PDF metadata. pdftk has a dump_data command that dumps the metadata in the document, including the creation date and the modification date. My file had both set to identical timestamps in June, both listed in UTC, corresponding to the time I'd signed the document. The file containing the addendum? The same creation time, but a modification time of this Monday, shortly before it was sent to me. This time, the modification timestamp was in Pacific Daylight Time, the timezone currently observed in California. In addition, the data included two ID fields, ID0 and ID1. In my document both were identical, in the one with the addendum ID0 matched mine but ID1 was different.
These ID tags are intended to be some form of representation (such as a hash) of the document. ID0 is set when the document is created and should not be modified afterwards - ID1 initially identical to ID0, but changes when the document is modified. This is intended to allow tooling to identify whether two documents are modified versions of the same document. The identical ID0 indicated that the document with the addendum was originally identical to mine, and the different ID1 that it had been modified.
Well, ok, that seems like a pretty strong demonstration. I had the "I have a very particular set of skills" conversation with the agency and pointed these facts out, that they were an extremely strong indication that my copy was authentic and their one wasn't, and they responded that the document was "re-sealed" every time it was downloaded from RightSignature and that would explain the modifications. This doesn't seem plausible, but it's an argument. Let's go further.
My next move was pdfalyzer, which allows you to pull a PDF apart into its component pieces. This revealed that the documents were identical, other than page 3, the one with the addendum. This page included tags entitled "touchUp_TextEdit", evidence that the page had been modified using Acrobat. But in itself, that doesn't prove anything - obviously it had been edited at some point to insert the landlord's name, it doesn't prove whether it happened before or after the signing.
But in the process of editing, Acrobat appeared to have renamed all the font references on that page into a different format. Every other page had a consistent naming scheme for the fonts, and they matched the scheme in the page 3 I had. Again, that doesn't tell us whether the renaming happened before or after the signing. Or does it?
You see, when I completed my signing, RightSignature inserted my name into the document, and did so using a font that wasn't otherwise present in the document (Courier, in this case). That font was named identically throughout the document, except on page 3, where it was named in the same manner as every other font that Acrobat had renamed. Given the font wasn't present in the document until after I'd signed it, this is proof that the page was edited after signing.
But eh this is all very convoluted. Surely there's an easier way? Thankfully yes, although I hate it. RightSignature had sent me a link to view my signed copy of the document. When I went there it presented it to me as the original PDF with my signature overlaid on top. Hitting F12 gave me the network tab, and I could see a reference to a base.pdf. Downloading that gave me the original PDF, pre-signature. Running sha256sum on it gave me an identical hash to the "Original checksum" field. Needless to say, it did not contain the addendum.
Why do this? The only explanation I can come up with (and I am obviously guessing here, I may be incorrect!) is that International Executive Rentals realised that they'd sent me a contract which could mean that they were liable for the return of my deposit, even though they'd already given it to my landlord, and after realising this added the addendum, sent it to me, and assumed that I just wouldn't notice (or that, if I did, I wouldn't be able to prove anything). In the process they went from an extremely unlikely possibility of having civil liability for a few thousand dollars (even if they were holding the deposit it's still the landlord's legal duty to return it, as far as I can tell) to doing something that looks extremely like forgery.
There's a hilarious followup. After this happened, the agency offered to do a screenshare with me showing them logging into RightSignature and showing the signed file with the addendum, and then proceeded to do so. One minor problem - the "Send for signature" button was still there, just below a field saying "Uploaded: 09/22/25". I asked them to search for my name, and it popped up two hits - one marked draft, one marked completed. The one marked completed? Didn't contain the addendum.
As you may recall from previous posts and elsewhere I have been busy writing a new solver for APT.
Today I want to share some of the latest changes in how to approach solving.
The idea for the solver was that manually installed packages are always protected from removals
in terms of SAT solving, they are facts. Automatically installed packages become optional unit
clauses. Optional clauses are solved after manual ones, they don t partake in normal unit propagation.
This worked fine, say you had
A                                   # install request for A
B                                   # manually installed, keep it
A depends on: conflicts-B   C
Installing A on a system with B installed installed C, as it was not allowed to
install the conflicts-B package since B is installed.
However, I also introduced a mode to allow removing manually installed packages, and that s
where it broke down, now instead of B being a fact, our clauses looked like:
A                               # install request for A
A depends on: conflicts-B   C
Optional: B                     # try to keep B installed
As a result, we installed conflicts-B and removed B; the steps the solver takes are:
A is a fact, mark it
A depends on: conflicts-B C is the strongest clause, try to install conflicts-B
We unit propagate that conflicts-B conflicts with B, so we mark not B
Optional: B is reached, but not satisfiable, ignore it because it s optional.
This isn t correct: Just because we allow removing manually installed packages doesn t mean that we should remove manually installed packages if we don t need to.
Fixing this turns out to be surprisingly easy. In addition to adding our optional (soft) clauses, let s first assume all of them!
But to explain how this works, we first need to explain some terminology:
The solver operates on a stack of decisions
enqueue means a fact is being added at the current decision level, and enqueued for propagation
assume bumps the decision level, and then enqueues the assumed variable
propagate looks at all the facts and sees if any clause becomes unit, and then enqueues it
unit is when a clause has a single literal left to assign
To illustrate this in pseudo Python code:
We introduce all our facts, and if they conflict, we are unsat:
for fact in facts:
enqueue(fact)
ifnot propagate():
returnFalse
For each optional literal, we register a soft clause and assume it. If the assumption fails,
we ignore it. If it succeeds, but propagation fails, we undo the assumption.
for optionalLiteral in optionalLiterals:
registerClause(SoftClause([optionalLiteral]))
if assume(optionalLiteral) andnot propagate():
undo()
Finally we enter the main solver loop:
whileTrue:
ifnot propagate():
ifnot backtrack():
returnFalseelif<all clauses are satisfied>:
returnTrueelif it := find("best unassigned literal satisfying a hard clause"):
assume(it)
elif it := find("best literal satisfying a soft clause"):
assume(it)
The key point to note is that the main loop will undo the assumptions in order; so
if you assume A,B,C and B is not possible, we will have also undone C. But since
C is also enqueued as a soft clause, we will then later find it again:
Solve finds a conflict, backtracks, and sets not C: State=[Assume(A),Assume(B),not(C)]
Solve finds a conflict, backtracks, and sets not B: State=[Assume(A),not(B)] C is no longer assumed either
Solve, assume C as it satisfies SoftClause([C]) as next best literal: State=[Assume(A),not(B),Assume(C)]
All clauses are satisfied, solution is A, not B, and C.
This is not (correct) MaxSAT, because we actually do not guarantee that we satisfy as many soft clauses as possible. Consider you have the following clauses:
Optional: A
Optional: B
Optional: C
B Conflicts with A
C Conflicts with A
There are two possible results here:
A If we assume A first, we are unable to satisfy B or C.
B,C If we assume either B or C first, A is unsat.
The question to ponder though is whether we actually need a global maximum or whether a local maximum is satisfactory in practice for a dependency solver
If you look at it, a naive MaxSAT solver needs to run the SAT solver 2**n times for n soft clauses, whereas our heuristic only needs n runs.
For dependency solving, it seems we do not seem have a strong need for a global maximum:
There are various other preferences between our literals, say priorities;
and empirically, from evaluating hundreds of regressions without the initial assumptions,
I can say that the assumptions do fix those cases and the result is correct.
Further improvements exist, though, and we can look into them if they are needed, such as:
Use a better heuristic:
If we assume 1 clause and solve, and we cause 2 or more clauses to become unsatisfiable,
then that clause is a local minimum and can be skipped.
This is a more common heuristical MaxSAT solver.
This gives us a better local maximum, but not a global one.
This is more or less what the Smart package manager did,
except that in Smart, all packages were optional, and the entire solution was scored.
It calculated a basic solution without optimization and then toggled each variable and saw if the score improved.
Implement an actual search for a global maximum:
This involves reading the literature.
There are various versions of this, for example:
Find unsatisfiable cores and use those to guide relaxation of clauses.
A bounds-based search, where we translate sum(satisifed clauses) > k into SAT, and then search in one of the following ways:
from 0 upward
from n downward
perform a binary search on [0, k] satisfied clauses.
Actually we do not even need to calculate sum constraints into CNF, because we can just add a specialized new type of constraint to our code.
Fun with -fsanitize=undefined and Picolibc
Both GCC and Clang support the -fsanitize=undefined flag which
instruments the generated code to detect places where the program
wanders into parts of the C language specification which are either
undefined or implementation defined. Many of these are also common
programming errors. It would be great if there were sanitizers for
other easily detected bugs, but for now, at least the undefined
sanitizer does catch several useful problems.
Supporting the sanitizer
The sanitizer can be built to either trap on any error or call
handlers. In both modes, the same problems are identified, but when
trap mode is enabled, the compiler inserts a trap instruction and
doesn't expect the program to continue running. When handlers are in
use, each identified issue is tagged with a bunch of useful data and
then a specific sanitizer handling function is called.
The specific functions are not all that well documented, nor are the
parameters they receive. Maybe this is because both compilers provide
an implementation of all of the functions they use and don't really
expect external implementations to exist? However, to make these useful in an
embedded environment, picolibc needs to provide a complete set of
handlers that support all versions both gcc and clang as the
compiler-provided versions depend upon specific C (and C++) libraries.
Of course, programs can be built in trap-on-error mode, but that makes
it much more difficult to figure out what went wrong.
Fixing Sanitizer Issues
Once the sanitizer handlers were implemented, picolibc could be
built with them enabled and all of the picolibc tests run to uncover
issues within the library.
As with the static analyzer adventure from last year, the vast bulk of
sanitizer complaints came from invoking undefined or
implementation-defined behavior in harmless ways:
Computing pointers past &array[size+1]. I found no cases where the
resulting pointers were actually used, but the mere computation is
still undefined behavior. These were fixed by adjusting the code to
avoid computing pointers like this. The result was clearer code,
which is good.
Signed arithmetic overflow in PRNG code. There are several linear
congruential PRNGs in the library which used signed integer
arithmetic. The rand48 generator carefully used unsigned short
values. Of course, in C, the arithmetic performed on them is done
with signed ints if int is wider than short. C specifies signed
overflow as undefined, but both gcc and clang generate the expected
code anyways. The fixes here were simple; just switch the
computations to unsigned arithmetic, adjusting types and inserting
casts as required.
Passing pointers to the middle of a data structure. For example,
free takes a pointer to the start of an allocation. The management
structure appears just before that in memory; computing the address
of which appears to be undefined behavior to the compiler. The only
fix I could do here was to disable the sanitizer in functions doing
these computations -- the sanitizer was mis-detecting correct code
and it doesn't provide a way to skip checks on a per-operator
basis.
Null pointer plus or minus zero. C says that any arithmetic with
the NULL pointer is undefined, even when the value being added or
subtracted is zero. The fix here was to create a macro, enabled
only when the sanitizer is enabled, which checks for this case and
skips the arithmetic.
Discarded computations which overflow. A couple of places computed
a value, then checked if that would have overflowed and discard the
result. Even though the program doesn't depend upon the
computation, its mere presence is undefined behavior. These were
fixed by moving the computation into an else clause in the
overflow check. This inserts an extra branch instruction, which is
annoying.
Signed integer overflow in math code. There's a common pattern
in various functions that want to compare against 1.0. Instead of
using the floating point equality operator, they do the computation
using the two 32-bit halves with ((hi - 0x3ff00000) lo)
== 0. It's efficient, but because most of these functions store the
'hi' piece in a signed integer (to make checking the sign bit
fast), the result is undefined when hi is a large negative
value. These were fixed by inserting casts to unsigned types as the
results were always tested for equality.
Signed integer shifts
This is one area where the C language spec is just wrong.
For left shift, before C99, it worked on signed integers as a bit-wise
operator, equivalent to the operator on unsigned integers. After that,
left shift of negative integers became undefined. Fortunately, it's
straightforward (if tedious) to work around this issue by just casting
the operand to unsigned, performing the shift and casting it back to
the original type. Picolibc now has an internal macro, lsl, which
does this:
Right shift is significantly more complicated to implement. What we
want is an arithmetic shift with the sign bit being replicated as the
value is shifted rightwards. C defines no such operator. Instead,
right shift of negative integers is implementation
defined. Fortunately, both gcc and clang define the >> operator on
signed integers as arithmetic shift. Also fortunately, C hasn't made
this undefined, so the program itself doesn't end up undefined.
The trouble with arithmetic right shift is that it is not equivalent
to right shift of unsigned values. Here's what Per Vognsen came up
with using standard C operators:
    int
    __asr_int(int x, int s)
        return x < 0 ? ~(~x >> s) : x >> s;
When the value is negative, we invert all of the bits (making it
positive), shift right, then flip all of the bits back. Both GCC and
Clang seem to compile this to a single asr instruction. This function
is replicated for each of the five standard integer types and then the
set of them wrapped in another sizeof-selecting macro:
The lsl and asr macros use sizeof instead of the type-generic
mechanism to remain compatible with compilers that lack type-generic
support.
Once these macros were written, they needed to be applied where
required. To preserve the benefits of detecting programming errors,
they were only applied where required, not blindly across the whole
codebase.
There are a couple of common patterns in the math code using shift
operators. One is when computing the exponent value for subnormal
numbers.
for (ix = -1022, i = hx << 11; i > 0; i <<= 1)
    ix -= 1;
This code computes the exponent by shifting the significand left by 11
bits (the width of the exponent field) and then incrementally shifting
it one bit at a time until the sign flips, which indicates that the
most-significant bit is set. Use of the pre-C99 definition of the left
shift operator is intentional here; so both shifts are replaced with
our lsl operator.
In the implementation of pow, the final exponent is computed as the
sum of the two exponents, both of which are in the allowed range. The
resulting sum is then tested to see if it is zero or negative to see
if the final value is sub-normal:
hx += n << 20;
if (hx >> 20 <= 0)
    /* do sub-normal things */
In this case, the exponent adjustment, n, is a signed value and so
that shift is replaced with the lsl macro. The test value needs to
compute the correct the sign bit, so we replace this with the asr
macro.
Because the right shift operation is not undefined, we only use our
fancy macro above when the undefined behavior sanitizer is enabled. On
the other hand, the lsl macro should have zero cost and covers
undefined behavior, so it is always used.
Actual Bugs Found!
The goal of this little adventure was both to make using the undefined
behavior sanitizer with picolibc possible as well as to use the
sanitizer to identify bugs in the library code. I fully expected that
most of the effort would be spent masking harmless undefined behavior
instances, but was hopeful that the effort would also uncover real
bugs in the code. I was not disappointed. Through this work, I found
(and fixed) eight bugs in the code:
setlocale/newlocale didn't check for NULL locale names
qsort was using uintptr_t to swap data around. On MSP430 in
'large' mode, that's a 20-bit type inside a 32-bit representation.
random() was returning values in int range rather than long.
m68k assembly for memcpy was broken for sizes > 64kB.
freopen returned NULL, even on success
The optimized version of memrchr was always performing unaligned
accesses.
String to float conversion had a table missing four values. This
caused an array access overflow which resulted in imprecise values
in some cases.
vfwscanf mis-parsed floating point values by assuming that
wchar_t was unsigned.
Sanitizer Wishes
While it's great to have a way to detect places in your C code which
evoke undefined and implementation defined behaviors, it seems like
this tooling could easily be extended to detect other common
programming mistakes, even where the code is well defined according to
the language spec. An obvious example is in unsigned arithmetic. How
many bugs come from this seemingly innocuous line of code?
p = malloc(sizeof(*p) * c);
Because sizeof returns an unsigned value, the resulting computation
never results in undefined behavior, even when the multiplication
wraps around, so even with the undefined behavior sanitizer enabled,
this bug will not be caught. Clang seems to have an unsigned integer
overflow sanitizer which should do this, but I couldn't find anything
like this in gcc.
Summary
The undefined behavior sanitizers present in clang and gcc both
provide useful diagnostics which uncover some common programming
errors. In most cases, replacing undefined behavior with defined
behavior is straightforward, although the lack of an arithmetic right
shift operator in standard C is irksome. I recommend anyone using C to
give it a try.
As usual with these every-two-year posts, probably of direct interest only
to California residents. Maybe the more obscure things we're voting on
will be a minor curiosity to people elsewhere. I'm a bit late this year,
although not as late as last year, so a lot of people may have already
voted, but I've been doing this for a while and wanted to keep it up.
This post will only be about the ballot propositions. I don't have
anything useful to say about the candidates that isn't hyper-local. I
doubt anyone who has read my posts will be surprised by which candidates
I'm voting for.
As always with Calfornia ballot propositions, it's worth paying close
attention to which propositions were put on the ballot by the legislature,
usually because there's some state law requirement (often that I disagree
with) that they be voted on by the public, and propositions that were put
on the ballot by voter petition. The latter are often poorly written and
have hidden problems. As a general rule of thumb, I tend to default to
voting against propositions added by petition. This year, one can
conveniently distinguish by number: the single-digit propositions were
added by the legislature, and the two-digit ones were added by petition.
Proposition 2: YES. Issue $10 billion in bonds for public school
infrastructure improvements. I generally vote in favor of spending
measures like this unless they have some obvious problem. The opposition
argument is a deranged rant against immigrants and government debt and
fails to point out actual problems. The opposition argument also claims
this will result in higher property taxes and, seriously, if only that
were true. That would make me even more strongly in favor of it.
Proposition 3: YES. Enshrines the right to marriage without
regard to sex or race into the California state constitution. This is
already the law given US Supreme Court decisions, but fixing California
state law is a long-overdue and obvious cleanup step. One of the quixotic
things I would do if I were ever in government, which I will never be,
would be to try to clean up the laws to make them match reality, repealing
all of the dead clauses that were overturned by court decisions or are
never enforced. I am in favor of all measures in this direction even when
I don't agree with the direction of the change; here, as a bonus, I also
strongly agree with the change.
Proposition 4: YES. Issue $10 billion in bonds for
infrastructure improvements to mitigate climate risk. This is basically
the same argument as Proposition 2. The one drawback of this measure is
that it's kind of a mixed grab bag of stuff and probably some of it should
be supported out of the general budget rather than bonds, but I consider
this a minor problem. We definitely need to ramp up climate risk
mitigation efforts.
Proposition 5: YES. Reduces the required super-majority to pass
local bond measures for affordable housing from 67% to 55%. The fact that
this requires a supermajority at all is absurd, California desperately
needs to build more housing of any kind however we can, and publicly
funded housing is an excellent idea.
Proposition 6: YES. Eliminates "involuntary servitude" (in other
words, "temporary" slavery) as a legally permissible punishment for crimes
in the state of California. I'm one of the people who think the 13th
Amendment to the US Constitution shouldn't have an exception for
punishment for crimes, so obviously I'm in favor of this. This is one
very, very tiny step towards improving the absolutely atrocious prison
conditions in the state.
Proposition 32: YES. Raises the minimum wage to $18 per hour
from the current $16 per hour, over two years, and ties it to inflation.
This is one of the rare petition-based propositions that I will vote in
favor of because it's very straightforward, we clearly should be raising
the minimum wage, and living in California is absurdly expensive because
we refuse to build more housing (see Propositions 5 and 33). The
opposition argument is the standard lie that a higher minimum wage will
increase unemployment, which we know from numerous other natural
experiments is simply not true.
Proposition 33: NO. Repeals Costa-Hawkins, which prohibits local
municipalities from enacting rent control on properties built after 1995.
This one is going to split the progressive vote rather badly, I suspect.
California has a housing crisis caused by not enough housing supply. It
is not due to vacant housing, as much as some people would like you to
believe that; the numbers just don't add up. There are way more people
living here and wanting to live here than there is housing, so we need to
build more housing.
Rent control serves a valuable social function of providing stability to
people who already have housing, but it doesn't help, and can hurt, the
project of meeting actual housing demand. Rent control alone
creates a two-tier system where people who have housing are protected but
people who don't have housing have an even harder time getting housing
than they do today. It's therefore quite consistent with the general
NIMBY playbook of trying to protect the people who already have housing by
making life harder for the people who do not, while keeping the housing
supply essentially static.
I am in favor of rent control in conjunction with real measures to
increase the housing supply. I am therefore opposed to this proposition,
which allows rent control without any effort to increase housing supply.
I am quite certain that, if this passes, some municipalities will use it
to make constructing new high-density housing incredibly difficult by
requiring it all be rent-controlled low-income housing, thus cutting off
the supply of multi-tenant market-rate housing entirely. This is already
a common political goal in the part of California where I live. Local
neighborhood groups advocate for exactly this routinely in local political
fights.
Give me a mandate for new construction that breaks local zoning
obstructionism, including new market-rate housing to maintain a healthy
lifecycle of housing aging into affordable housing as wealthy people move
into new market-rate housing, and I will gladly support rent control
measures as part of that package. But rent control on its own just
allocates winners and losers without addressing the underlying problem.
Proposition 34: NO. This is an excellent example of why I vote
against petition propositions by default. This is a law designed to
affect exactly one organization in the state of California: the AIDS
Healthcare Foundation. The reason for this targeting is disputed; one
side claims it's because of the AHF support for Proposition 33, and
another side claims it's because AHF is a slumlord abusing California
state funding. I have no idea which side of this is true. I also don't
care, because I am fundamentally opposed to writing laws this way. Laws
should establish general, fair principles that are broadly applicable, not
be written with bizarrely specific conditions (health care providers that
operate multifamily housing) that will only be met by a single
organization. This kind of nonsense creates bad legal codes and the legal
equivalent of technical debt. Just don't do this.
Proposition 35: YES. I am, reluctantly, voting in favor of this
even though it is a petition proposition because it looks like a useful
simplification and cleanup of state health care funding, makes an expiring
tax permanent, and is supported by a very wide range of organizations that
I generally trust to know what they're talking about. No opposition
argument was filed, which I think is telling.
Proposition 36: NO. I am resigned to voting down attempts to
start new "war on drugs" nonsense for the rest of my life because the
people who believe in this crap will never, ever, ever stop. This one has
bonus shoplifting fear-mongering attached, something that touches on nasty
local politics that have included large retail chains manipulating crime
report statistics to give the impression that shoplifting is up
dramatically. It's yet another round of the truly horrific California
"three strikes" criminal penalty obsession, which completely
misunderstands both the causes of crime and the (almost nonexistent)
effectiveness of harsh punishment as deterrence.
Review: The Book That Wouldn't Burn, by Mark Lawrence
Series:
Library Trilogy #1
Publisher:
Ace
Copyright:
2023
ISBN:
0-593-43793-4
Format:
Kindle
Pages:
561
The Book That Wouldn't Burn is apparently high fantasy, but of the
crunchy sort that could easily instead be science fiction. It is the
first of a trilogy.
Livira is a young girl, named after a weed, who lives in a tiny settlement
in the Dust. She is the sort of endlessly curious and irrepressible girl
who can be more annoying than delightful to adults who are barely keeping
everyone alive. Her settlement is not the sort of place that's large
enough to have a name; only their well keeps them alive in the desert and
the ever-present dust. There is a city somewhere relatively near, which
Livira dreams of seeing, but people from the settlement don't go there.
When someone is spotted on the horizon approaching the settlement, it's
the first time Livira has ever seen a stranger. It's also not a good
sign. There's only one reason for someone to seek them out in the Dust:
to take. Livira and the other children are, in short order, prisoners of
the humanoid dog-like sabbers, being dragged off to an unknown fate.
Evar lives in the library and has for his entire life. Specifically, he
lives in a square room two miles to a side, with a ceiling so high that it
may as well be a stone sky. He lived there with his family before he was
lost in the Mechanism. Years later, the Mechanism spit him out alongside
four other similarly-lost kids, all from the same library in different
times. None of them had apparently aged, but everyone else was dead.
Now, years later, they live a strange and claustrophobic life with way too
much social contact between way too few people.
Evar's siblings, as he considers them, were each in the Mechanism with a
book. During their years in the Mechanism they absorbed that book until
it became their focus and to some extent their personality. His brothers
are an assassin, a psychologist, and a historian. His sister, the last to
enter the Mechanism and a refugee from the sabber attack that killed
everyone else, is a warrior. Evar... well, presumably he had a book,
since that's how the Mechanism works. But he can't remember anything
about it except the feeling that there was a woman.
Evar lives in a library in the sense that it's a room full of books, but
those books are not on shelves. They're stacked in piles and massive
columns, with no organizational system that any of them could discern.
There are four doors, all of which are closed and apparently impenetrable.
In front of one of them is a hundred yards of char and burned book
remnants, but that door is just as impenetrable as the others. There is a
pool in the center of the room, crops surrounding it, and two creatures
they call the Soldier and the Assistant. That is the entirety of Evar's
world.
As you might guess from the title, this book is about a library. Evar's
perspective of the library is quite odd and unexplained until well into
the book, and Livira's discovery of the library and subsequent
explorations are central to her story, so I'm going to avoid going into
too many details about its exact nature. What I will say is that I have
read a lot of fantasy novels that are based around a library, but I don't
think I've ever read one that was this satisfying.
I think the world of The Book That Wouldn't Burn is fantasy, in
that there are fundamental aspects of this world that don't seem amenable
to an explanation consistent with our laws of physics. It is, however,
the type of fantasy with discoverable rules. Even better, it's the type
of fantasy where discovering the rules is central to the story, for both
the characters and the readers, and the rules are worth the effort. This
is a world-building tour de force: one of the most engrossing and
deeply satisfying slow revelations that I have read in a long time. This
book is well over 500 pages, the plot never flags, new bits of
understanding were still slotting into place in the last chapter, and
there are lots of things I am desperately curious about that Lawrence left
for the rest of the series. If you like puzzling out the history and
rules of an invented world and you have anything close to my taste in
characters and setting, you are going to love this book.
(Also, there is at least one C.S. Lewis homage that I will not spoil but
that I thought was beautifully done and delightfully elaborated, and I am
fairly sure there is a conversation happening between this book and Philip
Pullman's His Dark Materials series that I didn't quite untangle
but that I am intrigued by.)
I do need to offer a disclaimer: Livira is precisely the type of character
I love reading about. She's stubborn, curious, courageous, persistent,
egalitarian, insatiable, and extremely sharp. I have a particular soft
spot for exactly this protagonist, so adjust the weight of my opinion
accordingly. But Lawrence also makes excellent use of her as a spotlight
to illuminate the world-building. More than anything else in the world,
Livira wants to understand, and there is so much here to
understand.
There is an explanation for nearly everything in this book, and those
explanations usually both make sense and prompt more questions. This is
such a tricky balance for the writer to pull off! A lot of world-building
of this sort fails either by having the explanations not live up to the
mysteries or by tying everything together so neatly that the stakes of the
world collapse into a puzzle box. Lawrence avoids both failures. This
world made sense to me but remained sufficiently messy to feel like humans
were living in it. I also thought the pacing and timing were impeccable:
I figured things out at roughly the same pace as the characters, and
several twists and turns caught me entirely by surprise.
I do have one minor complaint and one caveat. The minor complaint is that
I thought one critical aspect of the ending was a little bit too neat and
closed. It was the one time in the book where I thought Lawrence
simplified his plot structure rather than complicated it, and I didn't
like the effect it had on the character dynamics. There is, thankfully,
the promise of significant new complications in the next book.
The caveat is a bit harder to put my finger on, but a comparison to Alaya
Dawn Johnson's The Library of Broken
Worlds might help. That book was also about a library, featured a
protagonist thrown into the deep end of complex world-building, and put
discovery of the history and rules at the center of the story. I found
the rules structure of The Book That Wouldn't Burn more
satisfyingly complicated and layered, in a way that made puzzle pieces fit
together in my head in a thoroughly enjoyable way. But Johnson's book is
about very large questions of identity, history, sacrifice, and pain, and
it's full of murky ambiguity and emotions that are only approached via
metaphor and symbolism. Lawrence's book is far more accessible, but the
emotional themes are shallower and more straightforward. There is a
satisfying emotional through-line, and there are some larger issues at
stake, but it won't challenge your sense of morality and justice the way
that The Library of Broken Worlds might. I think which of those
books one finds better will depend on what mood you're in and what reading
experience you're looking for.
Personally, I was looking for a scrappy, indomitable character who would
channel her anger into overcoming every obstacle in the way of thoroughly
understanding her world, and that's exactly what I got. This was my most
enjoyable reading experience of the year to date and the best book I've
read since Some Desperate Glory.
Fantastic stuff, highly recommended.
Followed by The Book That Broke the World, and the ending is a bit
of a cliffhanger so you may want to have that on hand. Be warned that the
third book in the series won't be published until 2025.
Rating: 9 out of 10
Bitter Angels is a stand-alone science fiction novel. It won the
Philip K. Dick award for best SF original paperback in 2010. C.L.
Anderson is a pen name for Sarah Zettel.
Terese was a Guardian, one of the agents of the Pax Solaris who find ways
to keep the peace in troubled systems and high-stress situations with the
help of an implanted Companion, an assistant AI. Forty years ago, on one
of those missions, she was captured and her Companion was forcibly
removed. She was rescued by her friend and mentor and retired afterwards,
starting a new life and a new family, trying to leave the memories behind.
Now, the woman who rescued her is dead. She was murdered on duty in the
Erasmus system, a corporate hellhole that appears to be on the verge of
exploding into a political hot spot. Bianca's last instructions asked for
Terese to replace her. Terese's family is furious at her for even
considering returning to the Guardians, but she can't say no. Duty, and
Bianca's dying request, call too strongly.
Amerand is Security on Dazzle, one of the Erasmus stations. He is one of
the refugees from Oblivion, the station that the First Bloods who rule the
system let die. He keeps his head above water and tries to protect his
father and find his mother without doing anything that the ever-present
Clerks might find concerning. Keeping an eye on newly-arriving Solaris
saints is a typical assignment, since the First Bloods don't trust the
meddling do-gooders. But something is not quite right, and a cryptic
warning from his Clerk makes him even more suspicious.
This is the second book by Sarah Zettel that
I've read, and both of them have been tense, claustrophobic thrillers set
in a world with harsh social inequality and little space for the
characters to maneuver. In this case, the structure of her future
universe reminded me a bit of Iain M. Banks's Culture, but with less
advanced technology and only humans. The Pax Solaris has eliminated war
within its borders and greatly extended lifespans. That peace is
maintained by Guardians, who play a role similar to Special Circumstances
but a bit more idealist and less lethal. They show up where there are
problems and meddle, manipulating and pushing to try to defuse the
problems before they reach the Pax Solaris.
Like a Culture novel, nearly all of the action takes place outside the Pax
Solaris in the Erasmus system. Erasmus is a corporate colony that has
turned into a cross between a hereditary dictatorship and the Corporate
Rim from Martha Wells's Murderbot series. Debt
slavery is ubiquitous, economic inequality is inconceivably vast, and the
Clerks are everywhere. Erasmus natives like Amerand have very little
leeway and even fewer options. Survival is a matter of not drawing the
attention of the wrong people. Terese and her fellow Guardians are
appalled, but also keenly aware that destabilizing the local politics may
make the situation even worse and get a lot of people killed.
Bitter Angels is structured like a mystery: who killed Bianca, and
what was her plan when she was killed? Unlike a lot of books of this
type, the villains are not idiots and their plan is both satisfyingly
complex and still depressingly relevant. I don't think I'm giving
anything away by saying that I have read recent news articles about people
with very similar plans, albeit involving less science-fiction technology.
Anderson starts with a tense situation and increases the pressure
relentlessly, leaving the heroes one step behind the villains for almost
the entire novel. It is not happy or optimistic reading at times, the
book is quite dark but it certainly was engrossing.
The one world-building quibble that I had is that the Erasmus system is
portrayed partly as a
hydraulic empire,
and while this is arguably feasible given that spaceship travel is
strictly controlled, it seemed like a weird choice given the prevalence of
water on the nearby moons. Water smuggling plays a significant role in
the plot, and I wasn't entirely convinced of the politics and logistics
behind it. If this sort of thing bugs you, there are some pieces that may
require suspension of disbelief.
Bitter Angels is the sort of tense thriller where catastrophe is
barely avoided and the cost of victory is too high, so you will want to be
in the mood for that before you dive in. But if that's what you're
looking for, I thought Anderson delivered a complex and satisfying story.
Content warning: major character suicide.
Rating: 7 out of 10
In my previous blog, I explored The New APT 3.0 solver.
Since then I have been at work in the test suite making tests pass and fixing some bugs.
You see for all intents and purposes, the new solver is a very stupid naive DPLL SAT solver (it just
so happens we don t actually have any pure literals in there). We can control it in a bunch of ways:
We can mark packages as install or reject
We can order actions/clauses. When backtracking the action that came later will be the first we
try to backtrack on
We can order the choices of a dependency - we try them left to right.
This is about all that we really want to do, we can t go if we reach a conflict, say oh but this
conflict was introduced by that upgrade, and it seems more important, so let s not backtrack on
the upgrade request but on this dependency instead. .
This forces us to think about lowering the dependency problem into this form, such that not only
do we get formally correct solutions, but also semantically correct ones. This is nice because
we can apply a systematic way to approach the issue rather than introducing ad-hoc rules in the
old solver which had a which of these packages should I flip the opposite way to break the conflict
kind of thinking.
Now our test suite has a whole bunch of these semantics encoded in it, and I m going to share some
problems and ideas for how to solve them. I can t wait to fix these and the error reporting and
then turn it on in Ubuntu and later Debian (the defaults change is a post-trixie change, let s
be honest).
apt upgrade is hard
The apt upgrade commands implements a safe version of dist-upgrade that essentially calculates the
dist-upgrade, and then undoes anything that would cause a package to be removed, but it (unlike its
apt-get counterpart) allows the solver to install new packages.
Now, consider the following package is installed:
X Depends: A (= 1) B
An upgrade from A=1 to A=2 is available. What should happen?
The classic solver would choose to remove X in a dist-upgrade, and then upgrade A, so it s answer
is quite clear: Keep back the upgrade of A.
The new solver however sees two possible solutions:
Install B to satisfy X Depends A (= 1) B.
Keep back the upgrade of A
Which one does it pick? This depends on the order in which it sees the upgrade action for A and the
dependency, as it will backjump chronologically. So
If it gets to the dependency first, it marks A=1 for install to satisfy A (= 1). Then it gets
to the upgrade request, which is just A Depends A (= 2) A (= 1) and sees it is satisfied
already and is content.
If it gets to the upgrade request first, it marks A=2 for install to satisfy A (= 2). Then
later it gets to X Depends: A (= 1) B, sees that A (= 1) is not satisfiable, and picks B.
We have two ways to approach this issue:
We always order upgrade requests last, so they will be kept back in case of conflicting dependencies
We require that, for apt upgrade a currently satisfied dependency must be satisfied by currently installed
packages, hence eliminating B as a choice.
Recommends are hard too
See if you have a X Recommends: A (= 1) and a new version of A, A (= 2), the solver currently
will silently break the Recommends in some cases.
But let s explore what the behavior of a X Recommends: A (= 1) in combination with an available upgrade
of A (= 2) should be. We could say the rule should be:
An upgrade should keep back A instead of breaking the Recommends
A dist-upgrade should either keep back A or remove X (if it is obsolete)
This essentially leaves us the same choices as for the previous problem, but with an interesting twist.
We can change the ordering (and we already did), but we could also introduce a new rule, promotions :
A Recommends in an installed package, or an upgrade to that installed package, where the Recommends
existed in the installed version, that is currently satisfied, must continue to be satisfied, that is,
it effectively is promoted to a Depends.
This neatly solves the problem for us. We will never break Recommends that are satisfied.
Likewise, we already have a Recommends demotion rule:
A Recommends in an installed package, or an upgrade to that installed package, where the Recommends
existed in the installed version, that is currently unsatisfied, will not be further evaluated (it
is treated like a Suggests is in the default configuration).
Whether we should be allowed to break Suggests with our decisions or not (the old autoremover did not,
for instance) is a different decision. Should we promote currently satisified Suggests to Depends as well?
Should we follow currently satisified Suggests so the solver sees them and doesn t autoremove them,
but treat them as optional?
tightening of versioned dependencies
Another case of versioned dependencies with alternatives that has complex behavior is something like
X Depends: A (>= 2)   B
X Recommends: A (>= 2)   B
In both cases, installing X should upgrade an A < 2 in favour of installing B. But a naive
SAT solver might not. If your request to keep A installed is encoded as A (= 1) A (= 2), then
it first picks A (= 1). When it sees the Depends/Recommends it will switch to B.
We can solve this again as in the previous example by ordering the keep A installed requests after
any dependencies. Notably, we will enqueue the common dependencies of all A versions first before
selecting a version of A, so something may select a version for us.
version narrowing instead of version choosing
A different approach to dealing with the issue of version selection is to not select a version
until the very last moment. So instead of selecting a version to satisfy A (>= 2) we instead
translate
Depends: A (>= 2)
into two rules:
The package selection rule:
Depends: A
This ensures that any version of A is installed (i.e. it adds a version choice clause, A (= 1) A (= 2)
in an example with two versions for A.
The version narrowing rule:
Conflicts: A (<< 2)
This outright would reject a choice of A (= 1).
So now we have 3 kinds of clauses:
package selection
version narrowing
version selection
If we process them in that order, we should surely be able to find the solution that best matches
the semantics of our Debian dependency model, i.e. selecting earlier choices in a dependency before
later choices in the face of version restrictions.
This still leaves one issue: What if our maintainer did not use Depends: A (>= 2) B but
e.g. Depends: A (= 3) B A (= 2). He d expect us to fall back to B if A (= 3) is not
installable, and not to B. But we d like to enqueue A and reject all choices other than 3
and 2. I think it s fair to say: Don t do that, then here.
Implementing strict pinning correctly
APT knows a single candidate version per package, this makes the solver relatively deterministic:
It will only ever pick the candidate, or an installed version. This also happens to significantly
reduce the search space which is good - less backtracking. An uptodate system will only ever have
one version per package that can be installed, so we never actually have to choose versions.
But of course, APT allows you to specify a non-candidate version of a package to install, for example:
apt install foo/oracular-proposed
The way this works is that the core component of the previous solver, which is the pkgDepCache
maintains what essentially amounts to an overlay of the policy that you could see with
apt-cache policy.
The solver currently however validates allowed version choices against the policy directly,
and hence finds these versions are not allowed and craps out. This is an interesting problem
because the solver should not be dependent on the pkgDepCache as the pkgDepCache initialization
(Building dependency tree...) accounts for about half of the runtime of APT (until the Y/n prompt)
and I d really like to get rid of it.
But currently the frontend does go via the pkgDepCache. It marks the packages in there, building
up what you could call a transaction, and then we translate it to the new solver, and once it is
done, it translates the result back into the pkgDepCache.
The current implementation of allowed version is implemented by reducing the search space, i.e.
every dependency, we outright ignore any non-allowed versions. So if you have a version 3 of A
that is ignored a Depends: A would be translated into A (= 2) A (= 1).
However this has two disadvantages. (1) It means if we show you why A could not be installed,
you don t even see A (= 3) in the list of choices and (2) you would need to keep the pkgDepCache
around for the temporary overrides.
So instead of actually enforcing the allowed version rule by filtering, a more reasonable
model is that we apply the allowed version rule by just marking every other version as not
allowed when discovering the package in the from depcache translation layer. This doesn t
really increase the search space either but it solves both our problem of making overrides
work and giving you a reasonable error message that lists all versions of A.
pulling up common dependencies to minimize backtracking cost
One of the common issues we have is that when we have a dependency group
A B C D
we try them in order, and if one fails, we undo everything it did, and move on to the next one. However,
this isn t perhaps the best choice of operation.
I explained before that one thing we do is queue the common dependencies of a package (i.e. dependencies
shared in all versions) when marking a package for install, but we don t do this here: We have already
lowered the representation of the dependency group into a list of versions, so we d need to extract the
package back out of it.
This can of course be done, but there may be a more interesting solution to the problem, in that we
simply enqueue all the common dependencies. That is, we add n backtracking levels for n possible
solutions:
We enqueue the common dependencies of all possible solutions deps(A)&deps(B)&deps(C)&deps(D)
We decide (adding a decision level) not to install D right now and enqueue deps(A)&deps(B)&deps(C)
We decide (adding a decision level) not to install C right now and enqueue deps(A)&deps(B)
We decide (adding a decision level) not to install B right now and enqueue A
Now if we need to backtrack from our choice of A we hopefully still have a lot of common dependencies
queued that we do not need to redo. While we have more backtracking levels, each backtracking level
would be significantly cheaper, especially if you have cheap backtracking (which admittedly we do not
have, yet anyway).
The caveat though is: It may be pretty expensive to find the common dependencies. We need to iterate
over all dependency groups of A and see if they are in B, C, and D, so we have a complexity of roughly
#A * (#B+#C+#D)
Each dependency group we need to check i.e. is X Y in B meanwhile has linear cost: We need to
compare the memory content of two pointer arrays containing the list of possible versions that
solve the dependency group.
This means that X Y and Y X are different dependencies of course, but that is to be expected
they are. But any dependency of the same order will have the same memory layout.
So really the cost is roughly N^4. This isn t nice.
You can apply various heuristics here on how to improve that, or you can even apply binary logic:
Enqueue common dependencies of A B C D
Move into the left half, enqueue of A B
Again divide and conquer and select A.
This has a significant advantage in long lists of choices, and also in the common case, where the
first solution should be the right one.
Or again, if you enqueue the package and a version restriction instead, you already get the common
dependencies enqueued for the chosen package at least.
APT 2.9.3 introduces the first iteration of the new solver codenamed
solver3, and now available with the solver 3.0 option. The new solver
works fundamentally different from the old one.
How does it work?
Solver3 is a fully backtracking dependency solving algorithm that defers
choices to as late as possible. It starts with an empty set of packages,
then adds the manually installed packages, and then installs packages
automatically as necessary to satisfy the dependencies.
Deferring the choices is implemented multiple ways:
First, all install requests
recursively mark dependencies with a single solution for install, and any
packages that are being rejected due to conflicts or user requests will
cause their reverse dependencies to be transitively marked as rejected,
provided their or group cannot be solved by a different package.
Second, any dependency with more than one choice is pushed to a priority
queue that is ordered by the number of possible solutions, such that we
resolve a b before a b c.
Not just by the number of solutions, though. One important point to
note is that optional dependencies, that is, Recommends, are always
sorting after mandatory dependencies. Do note on that: Recommended
packages do not nest in backtracking - dependencies of a Recommended
package themselves are not optional, so they will have to be resolved
before the next Recommended package is seen in the queue.
Another important step in deferring choices is extracting the common
dependencies of a package across its version and then installing them
before we even decide which of its versions we want to install - one
of the dependencies might cycle back to a specific version after all.
Decisions about package levels are recorded at a certain decision level,
if we reach a conflict we backtrack to the previous decision level,
mark the decision we made (install X) in the inverse (DO NOT INSTALL X),
reset all the state all decisions made at the higher level, and restore
any dependencies that are no longer resolved to the work queue.
Comparison to SAT solver design.
If you have studied SAT solver design, you ll find that essentially
this is a DPLL solver without pure literal elimination. A pure literal
eliminitation phase would not work for a package manager: First negative
pure literals (packages that everything conflicts with) do not exist,
and positive pure literals (packages nothing conflicts with) we do not want
to mark for install - we want to install as little as possible (well subject,
to policy).
As part of the solving phase, we also construct an implication graph, albeit
a partial one: The first package installing another package is marked as the
reason (A -> B), the same thing for conflicts (not A -> not B).
Once we have added the ability to have multiple parents in the implication
graph, it stands to reason that we can also implement the much more advanced
method of conflict-driven clause learning; where we do not jump back to the
previous decision level but exactly to the decision level that caused the
conflict. This would massively speed up backtracking.
What changes can you expect in behavior?
The most striking difference to the classic APT solver is that solver3 always keeps
manually installed packages around, it never offers to remove them. We will relax that
in a future iteration so that it can replace packages with new ones, that is, if your
package is no longer available in the repository (obsolete), but there is one that
Conflicts+Replaces+Provides it, solver3 will be allowed to install that and remove the
other.
Implementing that policy is rather trivial: We just need to queue obsolete replacement
as a dependency to solve, rather than mark the obsolete package for install.
Another critical difference is the change in the autoremove behavior: The new solver
currently only knows the strongest dependency chain to each package, and hence it will
not keep around any packages that are only reachable via weaker chains.
A common example is when gcc-<version> packages accumulate on your system over the
years. They all have Provides: c-compiler and the libtoolDepends: gcc c-compiler
is enough to keep them around.
New features
The new option --no-strict-pinning instructs the solver to consider all versions of
a package and not just the candidate version. For example, you could use apt install foo=2.0 --no-strict-pinning
to install version 2.0 of foo and upgrade - or downgrade - packages as needed to satisfy foo=2.0 dependencies.
This mostly comes in handy in use cases involving Debian experimental or the Ubuntu proposed pockets, where you
want to install a package from there, but try to satisfy from the normal release as much as possible.
The implication graph building allows us to implement an apt why command, that while not as nicely
detailed as aptitude, at least tells you the exact reason why a package is installed. It will only show
the strongest dependency chain at first of course, since that is what we record.
What is left to do?
At the moment, error information is not stored across backtracking in any way, but we generally
will want to show you the first conflict we reach as it is the most natural one; or all conflicts.
Currently you get the last conflict which may not be particularly useful.
Likewise, errors currently are just rendered as implication graphs of the form [not] A -> [not] B -> ...,
and we need to put in some work to present those nicely.
The test suite is not passing yet, I haven t really started working on it. A challenge is that most
packages in the test suite are manually installed as they are mocked, and the solver now doesn t remove
those.
We plan to implement the replacement logic such that foo can be replaced by foo2 Conflicts/Replaces/Provides foo
without needing to be automatically installed.
Improving the backtracking to be non-chronological conflict-driven clause learning would vastly
enhance our backtracking performance. Not that it seems to be an issue right now in my limited
testing (mostly noble 64-bit-time_t upgrades). A lot of that complexity you have normally is not
there because the manually installed packages and resulting unit propagation (single-solution
Depends/Reverse-Depends for Conflicts) already ground us fairly far in what changes we can actually make.
Once all the stuff has landed, we need to start rolling it out and gather feedback. On Ubuntu I d like
automated feedback on regressions (running solver3 in parallel, checking if result is worse and then
submitting an error to the error tracker), on Debian this could just be a role email address to send
solver dumps to.
At the same time, we can also incrementally start rolling this out. Like phased updates in Ubuntu,
we can also roll out the new solver as the default to 10%, 20%, 50% of users before going to the
full 100%. This will allow us to capture regressions early and fix them.
Recently I noticed a new tool called licenserecon written by Peter Blackman, and I helped get licenserecon into Debian. The purpose of licenserecon is to reconcile licenses from debian/copyright against the output from licensecheck, a tool written by Jonas Smedegaard. It assumes DEP5 copyright files. You run the tool in a directory that has a debian/ sub-directory, and its output when it notices mismatches (this is for resolv-wrapper):
Noticing one-character typos like this may not bring satisfaction except to the most obsessive-compulsive among us, however the tool has the potential of discovering more serious mistakes.
Using it manually once in a while may be useful, however I tend to forget QA steps that are not automated. Could we add this to the Salsa CI/CD pipeline? I recently proposed a merge request to add a wrap-and-sort job to the Salsa CI/CD pipeline (disabled by default) and learned how easy it was to extend it. I think licenserecon is still a bit rough on the edges, and I haven t been able to successfully use it on any but the simplest packages yet. I wouldn t want to suggest it is added to the normal Salsa CI/CD pipeline, even if disabled. If you maintain a Debian package on Salsa and wish to add a licenserecon job to your pipeline, I wrote licenserecon.yml for you.
The simplest way to use licenserecon.yml is to replace recipes/debian.yml@salsa-ci-team/pipeline as the Salsa CI/CD configuration file setting with debian/salsa-ci.yml@debian/licenserecon. If you use a debian/salsa-ci.yml file you may put something like this in it instead:
Once you trigger the pipeline, this will result in a new job licenserecon that validates debian/copyright against licensecheck output on every build! I have added this to the libcpucycles package on Salsa and the pipeline contains a new job licenserecon whose output currently ends with:
$ cd $ WORKING_DIR /$ SOURCE_DIR
$ lrc
Parsing Source Tree ....
Running licensecheck ....
No differences found
Cleaning up project directory and file based variables
If upstream releases a new version with files not matching our debian/copyright file, we will detect that on the next Salsa build job rather than months later when somebody happens to run the tools manually or there is some license conflict.
Incidentally licenserecon is written in Pascal which brought back old memories with Turbo Pascal back in the MS-DOS days. Thanks Peter for licenserecon, and Jonas for licensecheck making this possible!
What is this mysterious protocol? Who uses it and what is its story?
This story is a winding one, beginning in 1981. Kermit is, to the best of my knowledge, the oldest actively-maintained software package with an original developer still participating. It is also a scripting language, an Internet server, a (scriptable!) SSH client, and a file transfer protocol.
And my first use of it was talking to my HP-48GX calculator over a 9600bps serial link. Yes, that calculator had a Kermit server built in.
But let s back up and talk about serial ports and Modems.
Serial Ports and Modems
In my piece The PC & Internet Revolution in Rural America, I recently talked about getting a modem what an excitement it was to get one! I realize that many people today have never used a serial line or a modem, so let s briefly discuss.
Before Ethernet and Wifi took off in a big way, in the 1990s-2000s, two computers would talk to each other over a serial line and a modem. By modern standards, these were slow; 300bps was a common early speed. They also (at least in the beginning) had no kind of error checking. Characters could be dropped or changed. Sometimes even those speeds were faster than the receiving device could handle. Some serial links were 7-bit, and wouldn t even pass all 7-bit characters; for instance, sending a Ctrl-S could lock up a remote until you sent Ctrl-Q.
And computers back in the 1970s and 1980s weren t as uniform as they are now. They used different character sets, different line endings, and even had different notions of what a file is. Today s notion of a file as whatever set of binary bytes an application wants it to be was by no means universal; some systems treated a file as a set of fixed-length records, for instance.
So there were a lot of challenges in reliably moving files between systems. Kermit was introduced to reliably move files between systems using serial lines, automatically working around the varieties of serial lines, detecting errors and retransmitting, managing transmit speeds, and adapting between architectures as appropriate. Quite a task! And perhaps this explains why it was supported on a calculator with a primitive CPU by today s standards.
Serial communication, by the way, is still commonplace, though now it isn t prominent in everyone s home PC setup. It s used a lot in industrial equipment, avionics, embedded systems, and so forth.
The key point about serial lines is that they aren t inherently multiplexed or packetized. Whereas an Ethernet network is designed to let many dozens of applications use it at once, a serial line typically runs only one (unless it is something like PPP, which is designed to do multiplexing over the serial line).
So it become useful to be able to both log in to a machine and transfer files with it. That is, incidentally, still useful today.
Kermit and XModem/ZModem
I wondered: why did we end up with two diverging sets of protocols, created at about the same time? The Kermit website has the answer: essentially, BBSs could assume 8-bit clean connections, so XModem and ZModem had much less complexity to worry about. Kermit, on the other hand, was highly flexible. Although ZModem came out a few years before Kermit had its performance optimizations, by about 1993 Kermit was on par or faster than ZModem.
Beyond serial ports
As LANs and the Internet came to be popular, people started to use telnet (and later ssh) to connect to remote systems, rather than serial lines and modems. FTP was an early way to transfer files across the Internet, but it had its challenges. Kermit added telnet support, as well as later support for ssh (as a wrapper around the ssh command you already know). Now you could easily log in to a machine and exchange files with it without missing a beat.
And so it was that the Internet Kermit Service Daemon (IKSD) came into existence. It allows a person to set up a Kermit server, which can authenticate against local accounts or present anonymous access akin to FTP.
And so I established the quux.org Kermit Server, which runs the Unix IKSD (part of the Debian ckermit package).
Trying Out the quux.org Kermit Server
There are more instructions on the quux.org Kermit Server page! You can connect to it using either telnet or the kermit program. I won t duplicate all of the information here, but here s what it looks like to connect:
$ kermit
C-Kermit 10.0 Beta.08, 15 Dec 2022, for Linux+SSL (64-bit)
 Copyright (C) 1985, 2022,
  Trustees of Columbia University in the City of New York.
  Open Source 3-clause BSD license since 2011.
Type ? or HELP for help.
(/tmp/t/) C-Kermit>iksd /user:anonymous kermit.quux.org
 DNS Lookup...  Trying 135.148.101.37...  Reverse DNS Lookup... (OK)
Connecting to host glockenspiel.complete.org:1649
 Escape character: Ctrl-\ (ASCII 28, FS): enabled
Type the escape character followed by C to get back,
or followed by ? to see other options.
----------------------------------------------------

 >>> Welcome to the Internet Kermit Service at kermit.quux.org <<<

To log in, use 'anonymous' as the username, and any non-empty password

Internet Kermit Service ready at Fri Aug  4 22:32:17 2023
C-Kermit 10.0 Beta.08, 15 Dec 2022
kermit

Enter e-mail address as Password: [redacted]

Anonymous login.

You are now connected to the quux kermit server.

Try commands like HELP, cd gopher, dir, and the like.  Use INTRO
for a nice introduction.

(~/) IKSD>
You can even recursively download the entire Kermit mirror: over 1GB of files!
Conclusions
So, have fun. Enjoy this experience from the 1980s.
And note that Kermit also makes a better ssh client than ssh in a lot of ways; see ideas on my Kermit page.
This page also has a permanent home on my website, where it may be periodically updated.
Probably everyone is familiar with a regular VPN. The traditional use case is to connect to a corporate or home network from a remote location, and access services as if you were there.
But these days, the notion of corporate network and home network are less based around physical location. For instance, a company may have no particular office at all, may have a number of offices plus a number of people working remotely, and so forth. A home network might have, say, a PVR and file server, while highly portable devices such as laptops, tablets, and phones may want to talk to each other regardless of location. For instance, a family member might be traveling with a laptop, another at a coffee shop, and those two devices might want to communicate, in addition to talking to the devices at home.
And, in both scenarios, there might be questions about giving limited access to friends. Perhaps you d like to give a friend access to part of your file server, or as a company, you might have contractors working on a limited project.
Pretty soon you wind up with a mess of VPNs, forwarded ports, and tricks to make it all work. With the increasing prevalence of CGNAT, a lot of times you can t even open a port to the public Internet. Each application or device probably has its own gateway just to make it visible on the Internet, some of which you pay for.
Then you add on the question of: should you really trust your LAN anyhow? With possibilities of guests using it, rogue access points, etc., the answer is probably no .
We can move the responsibility for dealing with NAT, fluctuating IPs, encryption, and authentication, from the application layer further down into the network stack. We then arrive at a much simpler picture for all.
So this page is fundamentally about making the network work, simply and effectively.
How do we make the Internet work in these scenarios?
We re going to combine three concepts:
A VPN, providing fully encrypted and authenticated communication and stable IPs
Mesh Networking, in which devices automatically discover optimal paths to reach each other
Zero-trust networking, in which we do not need to trust anything about the underlying LAN, because all our traffic uses the secure systems in points 1 and 2.
By combining these concepts, we arrive at some nice results:
You can ssh hostname, where hostname is one of your machines (server, laptop, whatever), and as long as hostname is up, you can reach it, wherever it is, wherever you are.
Combined with mosh, these sessions will be durable even across moving to other host networks.
You could just as well use telnet, because the underlying network should be secure.
You don t have to mess with encryption keys, certs, etc., for every internal-only service. Since IPs are now trustworthy, that s all you need. hosts.allow could make a comeback!
You have a way of transiting out of extremely restrictive networks. Every tool discussed here has a way of falling back on routing things via a broker (relay) on TCP port 443 if all else fails.
There might sometimes be tradeoffs. For instance:
On LANs faster than 1Gbps, performance may degrade due to encryption and encapsulation overhead. However, these tools should let hosts discover the locality of each other and not send traffic over the Internet if the devices are local.
With some of these tools, hosts local to each other (on the same LAN) may be unable to find each other if they can t reach the control plane over the Internet (Internet is down or provider is down)
Some other features that some of the tools provide include:
Easy sharing of limited access with friends/guests
Taking care of everything you need, including SSL certs, for exposing a certain on-net service to the public Internet
Optional routing of your outbound Internet traffic via an exit node on your network. Useful, for instance, if your local network is blocking tons of stuff.
Let s dive in.
Types of Mesh VPNs
I ll go over several types of meshes in this article:
Fully decentralized with automatic hop routing
This model has no special central control plane. Nodes discover each other in various ways, and establish routes to each other. These routes can be direct connections over the Internet, or via other nodes. This approach offers the greatest resilience. Examples I ll cover include Yggdrasil and tinc.
Automatic peer-to-peer with centralized control
In this model, nodes, by default, communicate by establishing direct links between them. A regular node never carries traffic on behalf of other nodes. Special-purpose relays are used to handle cases in which NAT traversal is impossible. This approach tends to offer simple setup. Examples I ll cover include Tailscale, Zerotier, Nebula, and Netmaker.
Roll your own and hybrid approaches
This is a grab bag of other ideas; for instance, running Yggdrasil over Tailscale.
Terminology
For the sake of consistency, I m going to use common language to discuss things that have different terms in different ecosystems:
Every tool discussed here has a way of dealing with NAT traversal. It may assist with establishing direct connections (eg, STUN), and if that fails, it may simply relay traffic between nodes. I ll call such a relay a broker . This may or may not be the same system that is a control plane for a tool.
All of these systems operate over lower layers that are unencrypted. Those lower layers may be a LAN (wired or wireless, which may or may not have Internet access), or the public Internet (IPv4 and/or IPv6). I m going to call the unencrypted lower layer, whatever it is, the clearnet .
Evaluation Criteria
Here are the things I want to see from a solution:
Secure, with all communications end-to-end encrypted and authenticated, and prevention of traffic from untrusted devices.
Flexible, adapting to changes in network topology quickly and automatically.
Resilient, without single points of failure, and with devices local to each other able to communicate even if cut off from the Internet or other parts of the network.
Private, minimizing leakage of information or metadata about me and my systems
Able to traverse CGNAT without having to use a broker whenever possible
A lesser requirement for me, but still a nice to have, is the ability to include others via something like Internet publishing or inviting guests.
Fully or nearly fully Open Source
Free or very cheap for personal use
Wide operating system support, including headless Linux on x86_64 and ARM.
Fully Decentralized VPNs with Automatic Hop Routing
Two systems fit this description: Yggdrasil and Tinc. Let s dive in.
Yggdrasil
I ll start with Yggdrasil because I ve written so much about it already. It featured in prior posts such as:
Yggdrasil can be a private mesh VPN, or something more
Yggdrasil can be a private mesh VPN, just like the other tools covered here. It s unique, however, in that a key goal of the project is to also make it useful as a planet-scale global mesh network. As such, Yggdrasil is a testbed of new ideas in distributed routing designed to scale up to massive sizes and all sorts of connection conditions. As of 2023-04-10, the main global Yggdrasil mesh has over 5000 nodes in it. You can choose whether or not to participate.
Every node in a Yggdrasil mesh has a public/private keypair. Each node then has an IPv6 address (in a private address space) derived from its public key. Using these IPv6 addresses, you can communicate right away.
Yggdrasil differs from most of the other tools here in that it does not necessarily seek to establish a direct link on the clearnet between, say, host A and host G for them to communicate. It will prefer such a direct link if it exists, but it is perfectly happy if it doesn t.
The reason is that every Yggdrasil node is also a router in the Yggdrasil mesh. Let s sit with that concept for a moment. Consider:
If you have a bunch of machines on your LAN, but only one of them can peer over the clearnet, that s fine; all the other machines will discover this route to the world and use it when necessary.
All you need to run a broker is just a regular node with a public IP address. If you are participating in the global mesh, you can use one (or more) of the free public peers for this purpose.
It is not necessary for every node to know about the clearnet IP address of every other node (improving privacy). In fact, it s not even necessary for every node to know about the existence of all the other nodes, so long as it can find a route to a given node when it s asked to.
Yggdrasil can find one or more routes between nodes, and it can use this knowledge of multiple routes to aggressively optimize for varying network conditions, including combinations of, say, downloads and low-latency ssh sessions.
Behind the scenes, Yggdrasil calculates optimal routes between nodes as necessary, using a mesh-wide DHT for initial contact and then deriving more optimal paths. (You can also read more details about the routing algorithm.)
One final way that Yggdrasil is different from most of the other tools is that there is no separate control server. No node is special , in charge, the sole keeper of metadata, or anything like that. The entire system is completely distributed and auto-assembling.
Meeting neighbors
There are two ways that Yggdrasil knows about peers:
By broadcast discovery on the local LAN
By listening on a specific port (or being told to connect to a specific host/port)
Sometimes this might lead to multiple ways to connect to a node; Yggdrasil prefers the connection auto-discovered by broadcast first, then the lowest-latency of the defined path. In other words, when your laptops are in the same room as each other on your local LAN, your packets will flow directly between them without traversing the Internet.
Unique uses
Yggdrasil is uniquely suited to network-challenged situations. As an example, in a post-disaster situation, Internet access may be unavailable or flaky, yet there may be many local devices perhaps ones that had never known of each other before that could share information. Yggdrasil meets this situation perfectly. The combination of broadcast auto-detection, distributed routing, and so forth, basically means that if there is any physical path between two nodes, Yggdrasil will find and enable it.
Ad-hoc wifi is rarely used because it is a real pain. Yggdrasil actually makes it useful! Its broadcast discovery doesn t require any IP address provisioned on the interface at all (it just uses the IPv6 link-local address), so you don t need to figure out a DHCP server or some such. And, Yggdrasil will tend to perform routing along the contours of the RF path. So you could have a laptop in the middle of a long distance relaying communications from people farther out, because it could see both. Or even a chain of such things.
Yggdrasil: Security and Privacy
Yggdrasil s mesh is aggressively greedy. It will peer with any node it can find (unless told otherwise) and will find a route to anywhere it can. There are two main ways to make sure you keep unauthorized traffic out: by restricting who can talk to your mesh, and by firewalling the Yggdrasil interface. Both can be used, and they can be used simultaneously.
I ll discuss firewalling more at the end of this article. Basically, you ll almost certainly want to do this if you participate in the public mesh, because doing so is akin to having a globally-routable public IP address direct to your device.
If you want to restrict who can talk to your mesh, you just disable the broadcast feature on all your nodes (empty MulticastInterfaces section in the config), and avoid telling any of your nodes to connect to a public peer. You can set a list of authorized public keys that can connect to your nodes listening interfaces, which you ll probably want to do. You will probably want to either open up some inbound ports (if you can) or set up a node with a known clearnet IP on a place like a $5/mo VPS to help with NAT traversal (again, setting AllowedPublicKeys as appropriate). Yggdrasil doesn t allow filtering multicast clients by public key, only by network interface, so that s why we disable broadcast discovery. You can easily enough teach Yggdrasil about static internal LAN IPs of your nodes and have things work that way. (Or, set up an internal gateway node or two, that the clients just connect to when they re local). But fundamentally, you need to put a bit more thought into this with Yggdrasil than with the other tools here, which are closed-only.
Compared to some of the other tools here, Yggdrasil is better about information leakage; nodes only know details, such as clearnet IPs, of directly-connected peers. You can obtain the list of directly-connected peers of any known node in the mesh but that list is the public keys of the directly-connected peers, not the clearnet IPs.
Some of the other tools contain a limited integrated firewall of sorts (with limited ACLs and such). Yggdrasil does not, but is fully compatible with on-host firewalls. I recommend these anyway even with many other tools.
Yggdrasil: Connectivity and NAT traversal
Compared to the other tools, Yggdrasil is an interesting mix. It provides a fully functional mesh and facilitates connectivity in situations in which no other tool can. Yet its NAT traversal, while it exists and does work, results in using a broker under some of the more challenging CGNAT situations more often than some of the other tools, which can impede performance.
Yggdrasil s underlying protocol is TCP-based. Before you run away screaming that it must be slow and unreliable like OpenVPN over TCP it s not, and it is even surprisingly good around bufferbloat. I ve found its performance to be on par with the other tools here, and it works as well as I d expect even on flaky 4G links.
Overall, the NAT traversal story is mixed. On the one hand, you can run a node that listens on port 443 and Yggdrasil can even make it speak TLS (even though that s unnecessary from a security standpoint), so you can likely get out of most restrictive firewalls you will ever encounter. If you join the public mesh, know that plenty of public peers do listen on port 443 (and other well-known ports like 53, plus random high-numbered ones).
If you connect your system to multiple public peers, there is a chance though a very small one that some public transit traffic might be routed via it. In practice, public peers hopefully are already peered with each other, preventing this from happening (you can verify this with yggdrasilctl debug_remotegetpeers key=ABC...). I have never experienced a problem with this. Also, since latency is a factor in routing for Yggdrasil, it is highly unlikely that random connections we use are going to be competitive with datacenter peers.
Yggdrasil: Sharing with friends
If you re open to participating in the public mesh, this is one of the easiest things of all. Have your friend install Yggdrasil, point them to a public peer, give them your Yggdrasil IP, and that s it. (Well, presumably you also open up your firewall you did follow my advice to set one up, right?)
If your friend is visiting at your location, they can just hop on your wifi, install Yggdrasil, and it will automatically discover a route to you. Yggdrasil even has a zero-config mode for ephemeral nodes such as certain Docker containers.
Yggdrasil doesn t directly support publishing to the clearnet, but it is certainly possible to proxy (or even NAT) to/from the clearnet, and people do.
Yggdrasil: DNS
There is no particular extra DNS in Yggdrasil. You can, of course, run a DNS server within Yggdrasil, just as you can anywhere else. Personally I just add relevant hosts to /etc/hosts and leave it at that, but it s up to you.
Yggdrasil: Source code, pricing, and portability
Yggdrasil is fully open source (LGPLv3 plus additional permissions in an exception) and highly portable. It is written in Go, and has prebuilt binaries for all major platforms (including a Debian package which I made).
There is no charge for anything with Yggdrasil. Listed public peers are free and run by volunteers. You can run your own peers if you like; they can be public and unlisted, public and listed (just submit a PR to get it listed), or private (accepting connections only from certain nodes keys). A peer in this case is just a node with a known clearnet IP address.
Yggdrasil encourages use in other projects. For instance, NNCP integrates a Yggdrasil node for easy communication with other NNCP nodes.
Yggdrasil conclusions
Yggdrasil is tops in reliability (having no single point of failure) and flexibility. It will maintain opportunistic connections between peers even if the Internet is down.
The unique added feature of being able to be part of a global mesh is a nice one.
The tradeoffs include being more prone to need to use a broker in restrictive CGNAT environments. Some other tools have clients that override the OS DNS resolver to also provide resolution of hostnames of member nodes; Yggdrasil doesn t, though you can certainly run your own DNS infrastructure over Yggdrasil (or, for that matter, let public DNS servers provide Yggdrasil answers if you wish).
There is also a need to pay more attention to firewalling or maintaining separation from the public mesh. However, as I explain below, many other options have potential impacts if the control plane, or your account for it, are compromised, meaning you ought to firewall those, too. Still, it may be a more immediate concern with Yggdrasil.
Although Yggdrasil is listed as experimental, I have been using it for over a year and have found it to be rock-solid. They did change how mesh IPs were calculated when moving from 0.3 to 0.4, causing a global renumbering, so just be aware that this is a possibility while it is experimental.
tinc
tinc is the oldest tool on this list; version 1.0 came out in 2003! You can think of tinc as something akin to an older Yggdrasil without the public option.
I will be discussing tinc 1.0.36, the latest stable version, which came out in 2019. The development branch, 1.1, has been going since 2011 and had its latest release in 2021. The last commit to the Github repo was in June 2022.
Tinc is the only tool here to support both tun and tap style interfaces. I go into the difference more in the Zerotier review below. Tinc actually provides a better tap implementation than Zerotier, with various sane options for broadcasts, but I still think the call for an Ethernet, as opposed to IP, VPN is small.
To configure tinc, you generate a per-host configuration and then distribute it to every tinc node. It contains a host s public key. Therefore, adding a host to the mesh means distributing its key everywhere; de-authorizing it means removing its key everywhere. This makes it rather unwieldy.
tinc can do LAN broadcast discovery and mesh routing, but generally speaking you must manually teach it where to connect initially. Somewhat confusingly, the examples all mention listing a public address for a node. This doesn t make sense for a laptop, and I suspect you d just omit it. I think that address is used for something akin to a Yggdrasil peer with a clearnet IP.
Unlike all of the other tools described here, tinc has no tool to inspect the running state of the mesh.
Some of the properties of tinc made it clear I was unlikely to adopt it, so this review wasn t as thorough as that of Yggdrasil.
tinc: Security and Privacy
As mentioned above, every host in the tinc mesh is authenticated based on its public key. However, to be more precise, this key is validated only at the point it connects to its next hop peer. (To be sure, this is also the same as how the list of allowed pubkeys works in Yggdrasil.) Since IPs in tinc are not derived from their key, and any host can assign itself whatever mesh IP it likes, this implies that a compromised host could impersonate another.
It is unclear whether packets are end-to-end encrypted when using a tinc node as a router. The fact that they can be routed at the kernel level by the tun interface implies that they may not be.
tinc: Connectivity and NAT traversal
I was unable to find much information about NAT traversal in tinc, other than that it does support it. tinc can run over UDP or TCP and auto-detects which to use, preferring UDP.
tinc: Sharing with friends
tinc has no special support for this, and the difficulty of configuration makes it unlikely you d do this with tinc.
tinc: Source code, pricing, and portability
tinc is fully open source (GPLv2). It is written in C and generally portable. It supports some very old operating systems. Mobile support is iffy.
tinc does not seem to be very actively maintained.
tinc conclusions
I haven t mentioned performance in my other reviews (see the section at the end of this post). But, it is so poor as to only run about 300Mbps on my 2.5Gbps network. That s 1/3 the speed of Yggdrasil or Tailscale. Combine that with the unwieldiness of adding hosts and some uncertainties in security, and I m not going to be using tinc.
Automatic Peer-to-Peer Mesh VPNs with centralized control
These tend to be the options that are frequently discussed. Let s talk about the options.
Tailscale
Tailscale is a popular choice in this type of VPN. To use Tailscale, you first sign up on tailscale.com. Then, you install the tailscale client on each machine. On first run, it prints a URL for you to click on to authorize the client to your mesh ( tailnet ). Tailscale assigns a mesh IP to each system. The Tailscale client lets the Tailscale control plane gather IP information about each node, including all detectable public and private clearnet IPs.
When you attempt to contact a node via Tailscale, the client will fetch the known contact information from the control plane and attempt to establish a link. If it can contact over the local LAN, it will (it doesn t have broadcast autodetection like Yggdrasil; the information must come from the control plane). Otherwise, it will try various NAT traversal options. If all else fails, it will use a broker to relay traffic; Tailscale calls a broker a DERP relay server. Unlike Yggdrasil, a Tailscale node never relays traffic for another; all connections are either direct P2P or via a broker.
Tailscale, like several others, is based around Wireguard; though wireguard-go rather than the in-kernel Wireguard.
Tailscale has a number of somewhat unique features in this space:
Funnel, which lets you expose ports on your system to the public Internet via the VPN.
Exit nodes, which automate the process of routing your public Internet traffic over some other node in the network. This is possible with every tool mentioned here, but Tailscale makes switching it on or off a couple of quick commands away.
Node sharing, which lets you share a subset of your network with guests
Funnel, in particular, is interesting. With a couple of tailscale serve -style commands, you can expose a directory tree (or a development webserver) to the world. Tailscale gives you a public hostname, obtains a cert for it, and proxies inbound traffic to you. This is subject to some unspecified bandwidth limits, and you can only choose from three public ports, so it s not really a production solution but as a quick and easy way to demonstrate something cool to a friend, it s a neat feature.
Tailscale: Security and Privacy
With Tailscale, as with the other tools in this category, one of the main threats to consider is the control plane. What are the consequences of a compromise of Tailscale s control plane, or of the credentials you use to access it?
Let s begin with the credentials used to access it. Tailscale operates no identity system itself, instead relying on third parties. For individuals, this means Google, Github, or Microsoft accounts; Okta and other SAML and similar identity providers are also supported, but this runs into complexity and expense that most individuals aren t wanting to take on. Unfortunately, all three of those types of accounts often have saved auth tokens in a browser. Personally I would rather have a separate, very secure, login.
If a person does compromise your account or the Tailscale servers themselves, they can t directly eavesdrop on your traffic because it is end-to-end encrypted. However, assuming an attacker obtains access to your account, they could:
Tamper with your Tailscale ACLs, permitting new actions
Add new nodes to the network
Forcibly remove nodes from the network
Enable or disable optional features
Of note is that they cannot just commandeer an existing IP. I would say the riskiest possibility here is that could add new nodes to the mesh. Because they could also tamper with your ACLs, they could then proceed to attempt to access all your internal services. They could even turn on service collection and have Tailscale tell them what and where all the services are.
Therefore, as with other tools, I recommend a local firewall on each machine with Tailscale. More on that below.
Tailscale has a new alpha feature called tailnet lock which helps with this problem. It requires existing nodes in the mesh to sign a request for a new node to join. Although this doesn t address ACL tampering and some of the other things, it does represent a significant help with the most significant concern. However, tailnet lock is in alpha, only available on the Enterprise plan, and has a waitlist, so I have been unable to test it.
Any Tailscale node can request the IP addresses belonging to any other Tailscale node. The Tailscale control plane captures, and exposes to you, this information about every node in your network: the OS hostname, IP addresses and port numbers, operating system, creation date, last seen timestamp, and NAT traversal parameters. You can optionally enable service data capture as well, which sends data about open ports on each node to the control plane.
Tailscale likes to highlight their key expiry and rotation feature. By default, all keys expire after 180 days, and traffic to and from the expired node will be interrupted until they are renewed (basically, you re-login with your provider and do a renew operation). Unfortunately, the only mention I can see of warning of impeding expiration is in the Windows client, and even there you need to edit a registry key to get the warning more than the default 24 hours in advance. In short, it seems likely to cut off communications when it s most important. You can disable key expiry on a per-node basis in the admin console web interface, and I mostly do, due to not wanting to lose connectivity at an inopportune time.
Tailscale: Connectivity and NAT traversal
When thinking about reliability, the primary consideration here is being able to reach the Tailscale control plane. While it is possible in limited circumstances to reach nodes without the Tailscale control plane, it is a fairly brittle setup and notably will not survive a client restart. So if you use Tailscale to reach other nodes on your LAN, that won t work unless your Internet is up and the control plane is reachable.
Assuming your Internet is up and Tailscale s infrastructure is up, there is little to be concerned with. Your own comfort level with cloud providers and your Internet should guide you here.
Tailscale wrote a fantastic article about NAT traversal and they, predictably, do very well with it. Tailscale prefers UDP but falls back to TCP if needed. Broker (DERP) servers step in as a last resort, and Tailscale clients automatically select the best ones. I m not aware of anything that is more successful with NAT traversal than Tailscale. This maximizes the situations in which a direct P2P connection can be used without a broker.
I have found Tailscale to be a bit slow to notice changes in network topography compared to Yggdrasil, and sometimes needs a kick in the form of restarting the client process to re-establish communications after a network change. However, it s possible (maybe even probable) that if I d waited a bit longer, it would have sorted this all out.
Tailscale: Sharing with friends
I touched on the funnel feature earlier. The sharing feature lets you give an invite to an outsider. By default, a person accepting a share can make only outgoing connections to the network they re invited to, and cannot receive incoming connections from that network this makes sense. When sharing an exit node, you get a checkbox that lets you share access to the exit node as well. Of course, the person accepting the share needs to install the Tailnet client. The combination of funnel and sharing make Tailscale the best for ad-hoc sharing.
Tailscale: DNS
Tailscale s DNS is called MagicDNS. It runs as a layer atop your standard DNS taking over /etc/resolv.conf on Linux and provides resolution of mesh hostnames and some other features. This is a concept that is pretty slick.
It also is a bit flaky on Linux; dueling programs want to write to /etc/resolv.conf. I can t really say this is entirely Tailscale s fault; they document the problem and some workarounds.
I would love to be able to add custom records to this service; for instance, to override the public IP for a service to use the in-mesh IP. Unfortunately, that s not yet possible. However, MagicDNS can query existing nameservers for certain domains in a split DNS setup.
Tailscale: Source code, pricing, and portability
Tailscale is almost fully open source and the client is highly portable. The client is open source (BSD 3-clause) on open source platforms, and closed source on closed source platforms. The DERP servers are open source. The coordination server is closed source, although there is an open source coordination server called Headscale (also BSD 3-clause) made available with Tailscale s blessing and informal support. It supports most, but not all, features in the Tailscale coordination server.
Tailscale s pricing (which does not apply when using Headscale) provides a free plan for 1 user with up to 20 devices. A Personal Pro plan expands that to 100 devices for $48 per year - not a bad deal at $4/mo. A Community on Github plan also exists, and then there are more business-oriented plans as well. See the pricing page for details.
As a small note, I appreciated Tailscale s install script. It properly added Tailscale s apt key in a way that it can only be used to authenticate the Tailscale repo, rather than as a systemwide authenticator. This is a nice touch and speaks well of their developers.
Tailscale conclusions
Tailscale is tops in sharing and has a broad feature set and excellent documentation. Like other solutions with a centralized control plane, device communications can stop working if the control plane is unreachable, and the threat model of the control plane should be carefully considered.
Zerotier
Zerotier is a close competitor to Tailscale, and is similar to it in a lot of ways. So rather than duplicate all of the Tailscale information here, I m mainly going to describe how it differs from Tailscale.
The primary difference between the two is that Zerotier emulates an Ethernet network via a Linux tap interface, while Tailscale emulates a TCP/IP network via a Linux tun interface.
However, Zerotier has a number of things that make it be a somewhat imperfect Ethernet emulator. For one, it has a problem with broadcast amplification; the machine sending the broadcast sends it to all the other nodes that should receive it (up to a set maximum). I wouldn t want to have a lot of programs broadcasting on a slow link. While in theory this could let you run Netware or DECNet across Zerotier, I m not really convinced there s much call for that these days, and Zerotier is clearly IP-focused as it allocates IP addresses and such anyhow. Zerotier provides special support for emulated ARP (IPv4) and NDP (IPv6). While you could theoretically run Zerotier as a bridge, this eliminates the zero trust principle, and Tailscale supports subnet routers, which provide much of the same feature set anyhow.
A somewhat obscure feature, but possibly useful, is Zerotier s built-in support for multipath WAN for the public interface. This actually lets you do a somewhat basic kind of channel bonding for WAN.
Zerotier: Security and Privacy
The picture here is similar to Tailscale, with the difference that you can create a Zerotier-local account rather than relying on cloud authentication. I was unable to find as much detail about Zerotier as I could about Tailscale - notably I couldn t find anything about how sticky an IP address is. However, the configuration screen lets me delete a node and assign additional arbitrary IPs within a subnet to other nodes, so I think the assumption here is that if your Zerotier account (or the Zerotier control plane) is compromised, an attacker could remove a legit device, add a malicious one, and assign the previous IP of the legit device to the malicious one. I m not sure how to mitigate against that risk, as firewalling specific IPs is ineffective if an attacker can simply take them over. Zerotier also lacks anything akin to Tailnet Lock.
For this reason, I didn t proceed much further in my Zerotier evaluation.
Zerotier: Connectivity and NAT traversal
Like Tailscale, Zerotier has NAT traversal with STUN. However, it looks like it s more limited than Tailscale s, and in particular is incompatible with double NAT that is often seen these days. Zerotier operates brokers ( root servers ) that can do relaying, including TCP relaying. So you should be able to connect even from hostile networks, but you are less likely to form a P2P connection than with Tailscale.
Zerotier: Sharing with friends
I was unable to find any special features relating to this in the Zerotier documentation. Therefore, it would be at the same level as Yggdrasil: possible, maybe even not too difficult, but without any specific help.
Zerotier: DNS
Unlike Tailscale, Zerotier does not support automatically adding DNS entries for your hosts. Therefore, your options are approximately the same as Yggdrasil, though with the added option of pushing configuration pointing to your own non-Zerotier DNS servers to the client.
Zerotier: Source code, pricing, and portability
The client ZeroTier One is available on Github under a custom business source license which prevents you from using it in certain settings. This license would preclude it being included in Debian. Their library, libzt, is available under the same license. The pricing page mentions a community edition for self hosting, but the documentation is sparse and it was difficult to understand what its feature set really is.
The free plan lets you have 1 user with up to 25 devices. Paid plans are also available.
Zerotier conclusions
Frankly I don t see much reason to use Zerotier. The virtual Ethernet model seems to be a weird hybrid that doesn t bring much value. I m concerned about the implications of a compromise of a user account or the control plane, and it lacks a lot of Tailscale features (MagicDNS and sharing). The only thing it may offer in particular is multipath WAN, but that s esoteric enough and also solvable at other layers that it doesn t seem all that compelling to me. Add to that the strange license and, to me anyhow, I don t see much reason to bother with it.
Netmaker
Netmaker is one of the projects that is making noise these days. Netmaker is the only one here that is a wrapper around in-kernel Wireguard, which can make a performance difference when talking to peers on a 1Gbps or faster link. Also, unlike other tools, it has an ingress gateway feature that lets people that don t have the Netmaker client, but do have Wireguard, participate in the VPN. I believe I also saw a reference somewhere to nodes as routers as with Yggdrasil, but I m failing to dig it up now.
The project is in a bit of an early state; you can sign up for an upcoming closed beta with a SaaS host, but really you are generally pointed to self-hosting using the code in the github repo. There are community and enterprise editions, but it s not clear how to actually choose. The server has a bunch of components: binary, CoreDNS, database, and web server. It also requires elevated privileges on the host, in addition to a container engine. Contrast that to the single binary that some others provide.
It looks like releases are frequent, but sometimes break things, and have a somewhat more laborious upgrade processes than most.
I don t want to spend a lot of time managing my mesh. So because of the heavy needs of the server, the upgrades being labor-intensive, it taking over iptables and such on the server, I didn t proceed with a more in-depth evaluation of Netmaker. It has a lot of promise, but for me, it doesn t seem to be in a state that will meet my needs yet.
Nebula
Nebula is an interesting mesh project that originated within Slack, seems to still be primarily sponsored by Slack, but is also being developed by Defined Networking (though their product looks early right now). Unlike the other tools in this section, Nebula doesn t have a web interface at all. Defined Networking looks likely to provide something of a SaaS service, but for now, you will need to run a broker ( lighthouse ) yourself; perhaps on a $5/mo VPS.
Due to the poor firewall traversal properties, I didn t do a full evaluation of Nebula, but it still has a very interesting design.
Nebula: Security and Privacy
Since Nebula lacks a traditional control plane, the root of trust in Nebula is a CA (certificate authority). The documentation gives this example of setting it up:
So the cert contains your IP, hostname, and group allocation. Each host in the mesh gets your CA certificate, and the per-host cert and key generated from each of these steps.
This leads to a really nice security model. Your CA is the gatekeeper to what is trusted in your mesh. You can even have it airgapped or something to make it exceptionally difficult to breach the perimeter.
Nebula contains an integrated firewall. Because the ability to keep out unwanted nodes is so strong, I would say this may be the one mesh VPN you might consider using without bothering with an additional on-host firewall.
You can define static mappings from a Nebula mesh IP to a clearnet IP. I haven t found information on this, but theoretically if NAT traversal isn t required, these static mappings may allow Nebula nodes to reach each other even if Internet is down. I don t know if this is truly the case, however.
Nebula: Connectivity and NAT traversal
This is a weak point of Nebula. Nebula sends all traffic over a single UDP port; there is no provision for using TCP. This is an issue at certain hotel and other public networks which open only TCP egress ports 80 and 443.
I couldn t find a lot of detail on what Nebula s NAT traversal is capable of, but according to a certain Github issue, this has been a sore spot for years and isn t as capable as Tailscale.
You can designate nodes in Nebula as brokers (relays). The concept is the same as Yggdrasil, but it s less versatile. You have to manually designate what relay to use. It s unclear to me what happens if different nodes designate different relays. Keep in mind that this always happens over a UDP port.
Nebula: Sharing with friends
There is no particular support here.
Nebula: DNS
Nebula has experimental DNS support. In contrast with Tailscale, which has an internal DNS server on every node, Nebula only runs a DNS server on a lighthouse. This means that it can t forward requests to a DNS server that s upstream for your laptop s particular current location. Actually, Nebula s DNS server doesn t forward at all. It also doesn t resolve its own name.
The Nebula documentation makes reference to using multiple lighthouses, which you may want to do for DNS redundancy or performance, but it s unclear to me if this would make each lighthouse form a complete picture of the network.
Nebula: Source code, pricing, and portability
Nebula is fully open source (MIT). It consists of a single Go binary and configuration. It is fairly portable.
Nebula conclusions
I am attracted to Nebula s unique security model. I would probably be more seriously considering it if not for the lack of support for TCP and poor general NAT traversal properties. Its datacenter connectivity heritage does show through.
Roll your own and hybrid
Here is a grab bag of ideas:
Running Yggdrasil over Tailscale
One possibility would be to use Tailscale for its superior NAT traversal, then allow Yggdrasil to run over it. (You will need a firewall to prevent Tailscale from trying to run over Yggdrasil at the same time!) This creates a closed network with all the benefits of Yggdrasil, yet getting the NAT traversal from Tailscale.
Drawbacks might be the overhead of the double encryption and double encapsulation. A good Yggdrasil peer may wind up being faster than this anyhow.
Public VPN provider for NAT traversal
A public VPN provider such as Mullvad will often offer incoming port forwarding and nodes in many cities. This could be an attractive way to solve a bunch of NAT traversal problems: just use one of those services to get you an incoming port, and run whatever you like over that.
Be aware that a number of public VPN clients have a kill switch to prevent any traffic from egressing without using the VPN; see, for instance, Mullvad s. You ll need to disable this if you are running a mesh atop it.
Other
Combining with local firewalls
For most of these tools, I recommend using a local firewal in conjunction with them. I have been using firehol and find it to be quite nice. This means you don t have to trust the mesh, the control plane, or whatever. The catch is that you do need your mesh VPN to provide strong association between IP address and node. Most, but not all, do.
Performance
I tested some of these for performance using iperf3 on a 2.5Gbps LAN. Here are the results. All speeds are in Mbps.
Tool
iperf3 (default)
iperf3 -P 10
iperf3 -R
Direct (no VPN)
2406
2406
2764
Wireguard (kernel)
1515
1566
2027
Yggdrasil
892
1126
1105
Tailscale
950
1034
1085
Tinc
296
300
277
You can see that Wireguard was significantly faster than the other options. Tailscale and Yggdrasil were roughly comparable, and Tinc was terrible.
IP collisions
When you are communicating over a network such as these, you need to trust that the IP address you are communicating with belongs to the system you think it does. This protects against two malicious actor scenarios:
Someone compromises one machine on your mesh and reconfigures it to impersonate a more important one
Someone connects an unauthorized system to the mesh, taking over a trusted IP, and uses the privileges of the trusted IP to access resources
To summarize the state of play as highlighted in the reviews above:
Yggdrasil derives IPv6 addresses from a public key
tinc allows any node to set any IP
Tailscale IPs aren t user-assignable, but the assignment algorithm is unknown
Zerotier allows any IP to be allocated to any node at the control plane
I don t know what Netmaker does
Nebula IPs are baked into the cert and signed by the CA, but I haven t verified the enforcement algorithm
So this discussion really only applies to Yggdrasil and Tailscale. tinc and Zerotier lack detailed IP security, while Nebula expects IP allocations to be handled outside of the tool and baked into the certs (therefore enforcing rigidity at that level).
So the question for Yggdrasil and Tailscale is: how easy is it to commandeer a trusted IP?
Yggdrasil has a brief discussion of this. In short, Yggdrasil offers you both a dedicated IP and a rarely-used /64 prefix which you can delegate to other machines on your LAN. Obviously by taking the dedicated IP, a lot more bits are available for the hash of the node s public key, making collisions technically impractical, if not outright impossible. However, if you use the /64 prefix, a collision may be more possible. Yggdrasil s hashing algorithm includes some optimizations to make this more difficult. Yggdrasil includes a genkeys tool that uses more CPU cycles to generate keys that are maximally difficult to collide with.
Tailscale doesn t document their IP assignment algorithm, but I think it is safe to say that the larger subnet you use, the better. If you try to use a /24 for your mesh, it is certainly conceivable that an attacker could remove your trusted node, then just manually add the 240 or so machines it would take to get that IP reassigned. It might be a good idea to use a purely IPv6 mesh with Tailscale to minimize this problem as well.
So, I think the risk is low in the default configurations of both Yggdrasil and Tailscale (certainly lower than with tinc or Zerotier). You can drive the risk even lower with both.
Final thoughts
For my own purposes, I suspect I will remain with Yggdrasil in some fashion. Maybe I will just take the small performance hit that using a relay node implies. Or perhaps I will get clever and use an incoming VPN port forward or go over Tailscale.
Tailscale was the other option that seemed most interesting. However, living in a region with Internet that goes down more often than I d like, I would like to just be able to send as much traffic over a mesh as possible, trusting that if the LAN is up, the mesh is up.
I have one thing that really benefits from performance in excess of Yggdrasil or Tailscale: NFS. That s between two machines that never leave my LAN, so I will probably just set up a direct Wireguard link between them. Heck of a lot easier than trying to do Kerberos!
Finally, I wrote this intending to be useful. I dealt with a lot of complexity and under-documentation, so it s possible I got something wrong somewhere. Please let me know if you find any errors.
This blog post is a copy of a page on my website. That page may be periodically updated.
 Rendering in Lynx, a text browser
 Rendering below the paragraph on a narrow viewport
 Rendering in the margin on a large viewport
 The three cases for the vertical position of a note
 SIMD bitpacking works like regular bitpacking, but processes 8

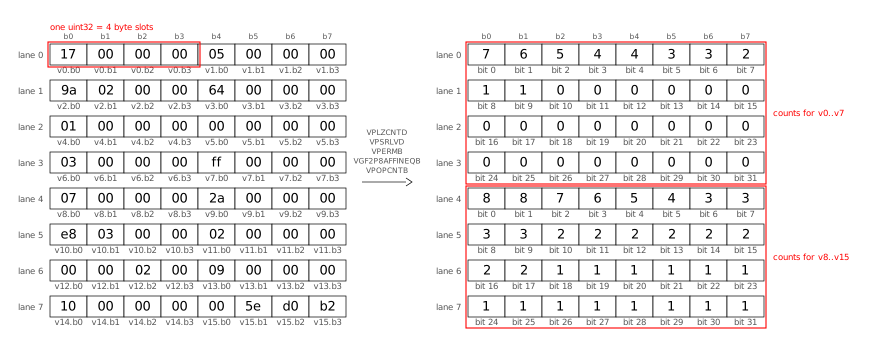
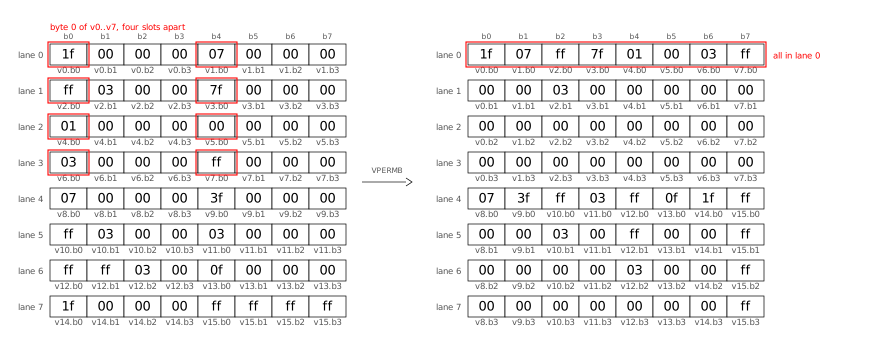
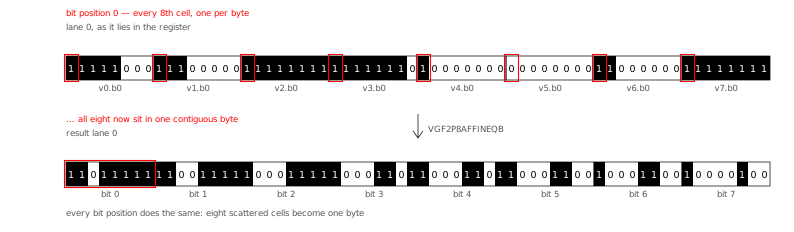
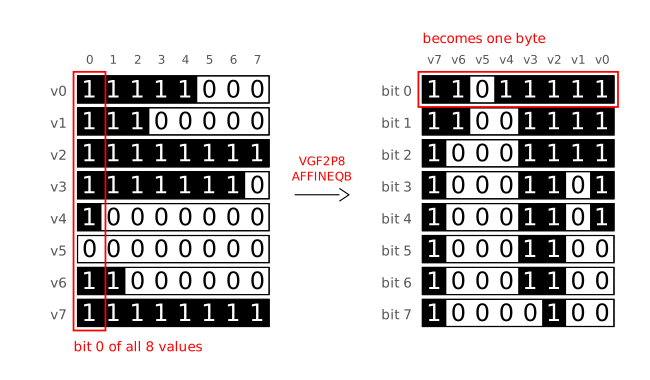
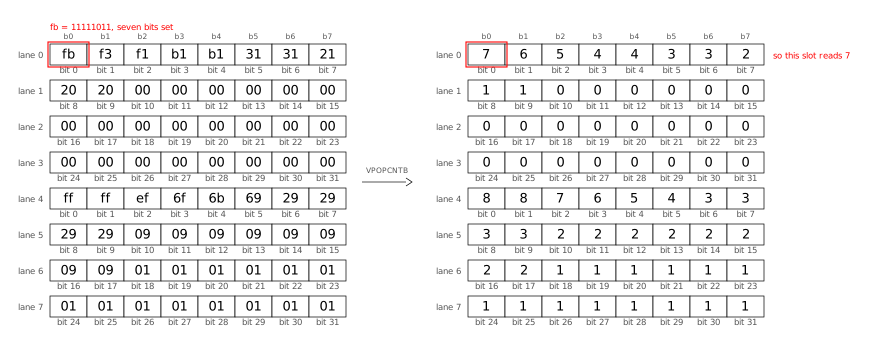
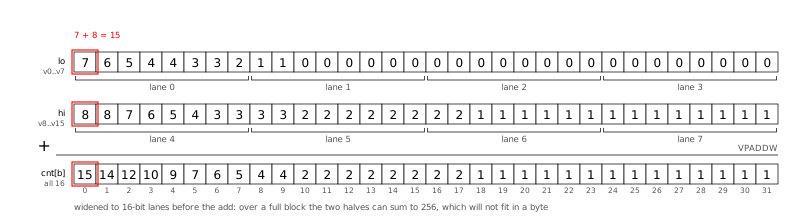

 I had to rent a house for a couple of months recently, which is long enough in California that it pushes you into proper tenant protection law. As landlords tend to do, they failed to return my security deposit within the 21 days
 Fun with -fsanitize=undefined and Picolibc
Both GCC and Clang support the -fsanitize=undefined flag which
instruments the generated code to detect places where the program
wanders into parts of the C language specification which are either
undefined or implementation defined. Many of these are also common
programming errors. It would be great if there were sanitizers for
other easily detected bugs, but for now, at least the undefined
sanitizer does catch several useful problems.
Supporting the sanitizer
The sanitizer can be built to either trap on any error or call
handlers. In both modes, the same problems are identified, but when
trap mode is enabled, the compiler inserts a trap instruction and
doesn't expect the program to continue running. When handlers are in
use, each identified issue is tagged with a bunch of useful data and
then a specific sanitizer handling function is called.
The specific functions are not all that well documented, nor are the
parameters they receive. Maybe this is because both compilers provide
an implementation of all of the functions they use and don't really
expect external implementations to exist? However, to make these useful in an
embedded environment, picolibc needs to provide a complete set of
handlers that support all versions both gcc and clang as the
compiler-provided versions depend upon specific C (and C++) libraries.
Of course, programs can be built in trap-on-error mode, but that makes
it much more difficult to figure out what went wrong.
Fixing Sanitizer Issues
Once the sanitizer handlers were implemented, picolibc could be
built with them enabled and all of the picolibc tests run to uncover
issues within the library.
As with the static analyzer adventure from last year, the vast bulk of
sanitizer complaints came from invoking undefined or
implementation-defined behavior in harmless ways: