Search Results: "bod"

7 September 2026

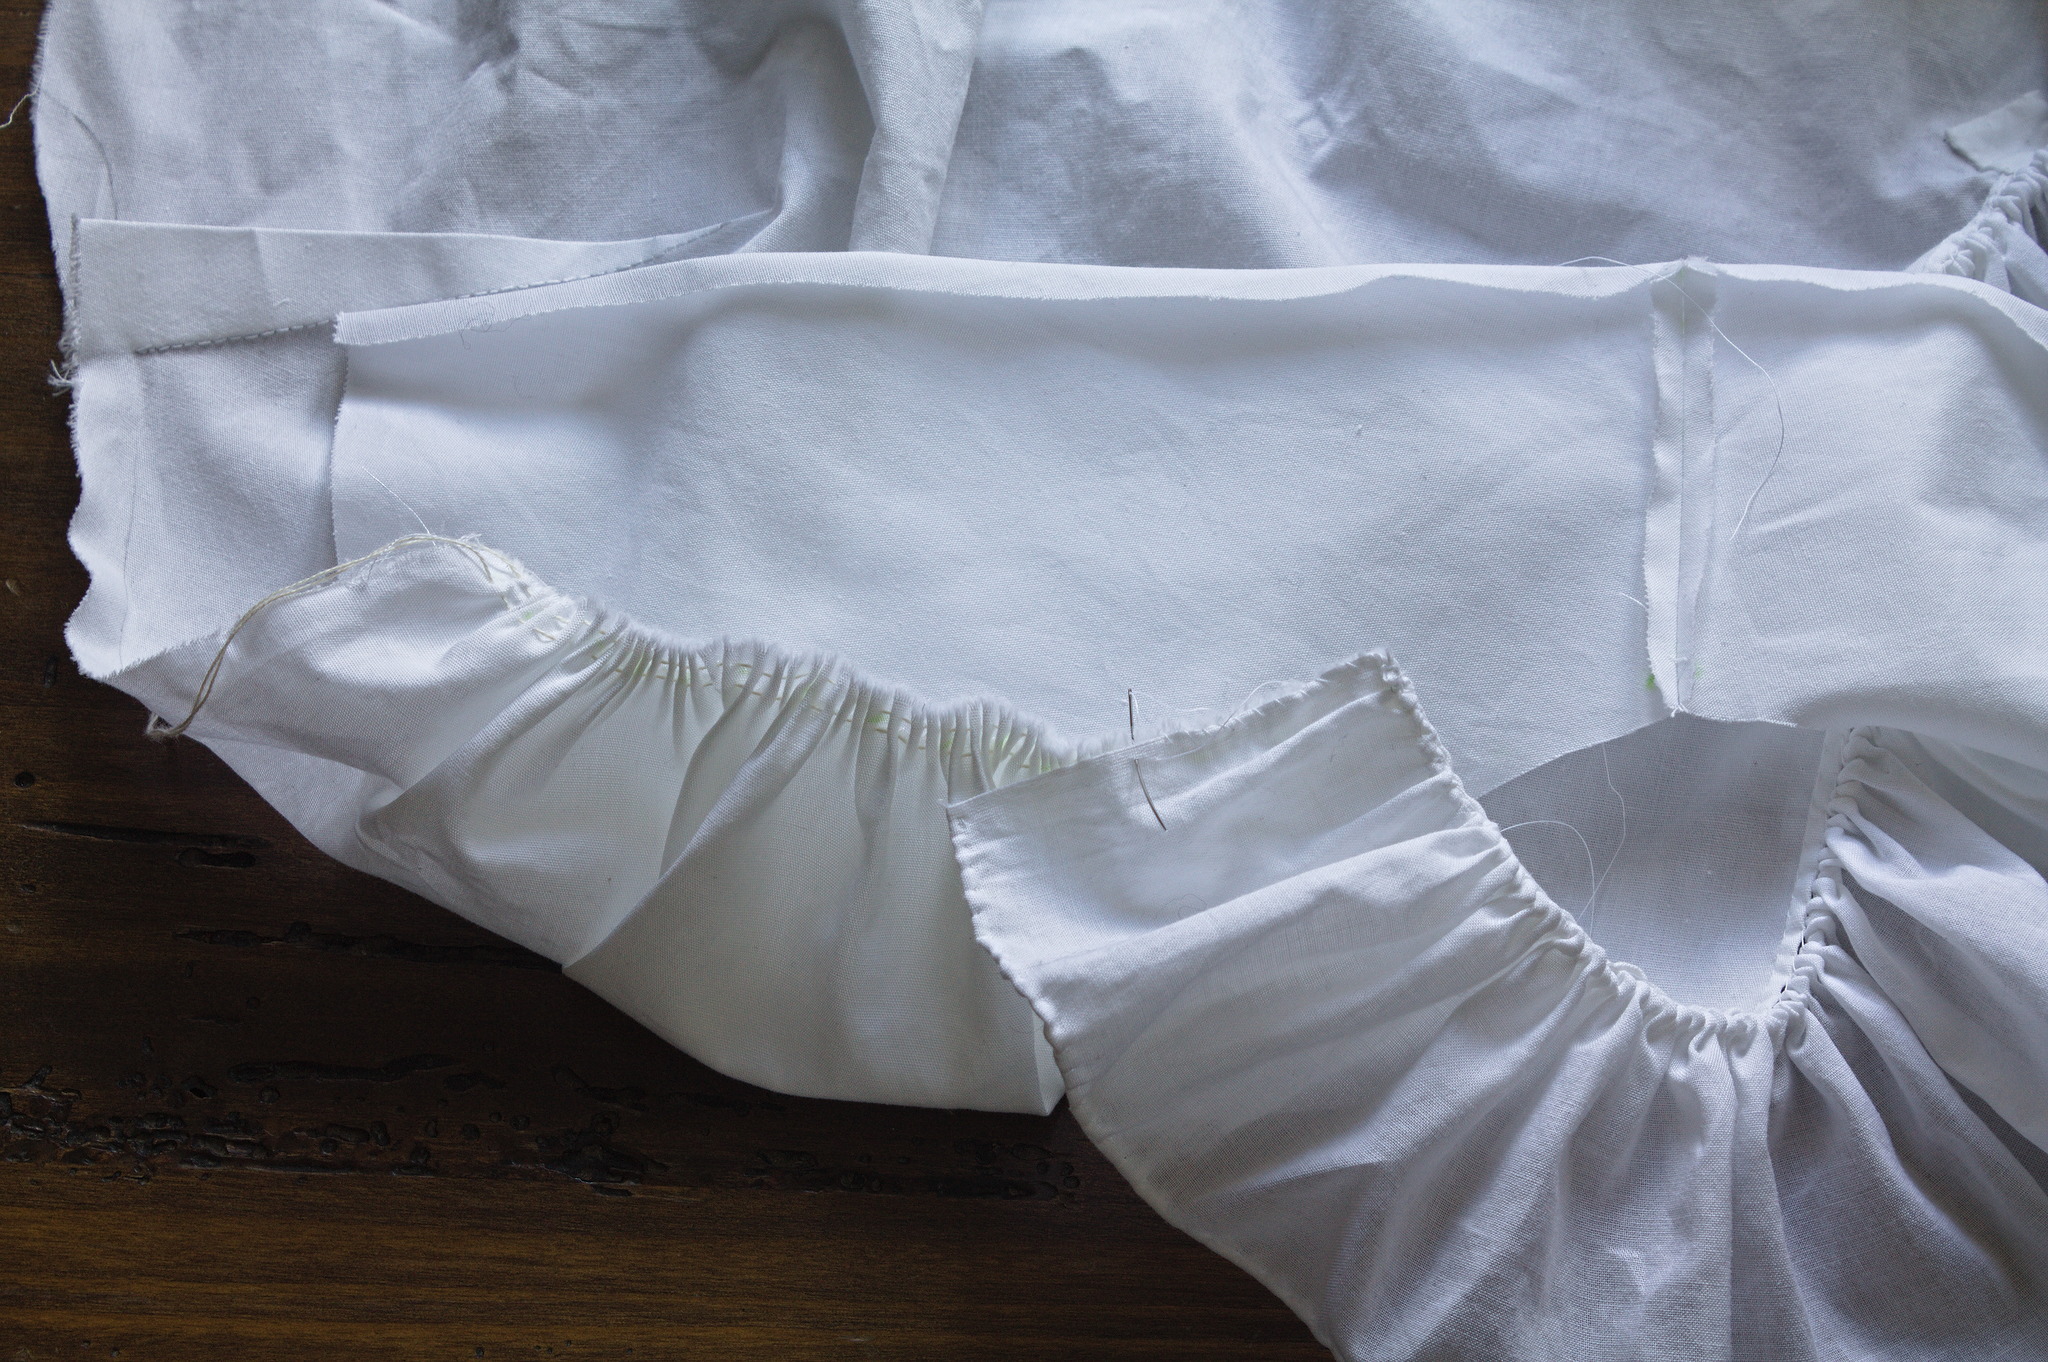
Freexian Collaborators: Debusine can now hand you debug symbols! (by Jugal Patel)
Contributor: Jugal Patel (Jugal59)
Organization: Debian
Project: Provide debuginfod server
Mentor: Colin Watson

About the project and me Your program crashes. You open gdb and get ?? instead of a stack trace. So you go find the right -dbgsym package, for the right version, for the right architecture, install it, and start again. Debuginfod removes that entire detour: gdb asks a server for symbols by the build-ID baked into the binary. Debusine already built packages, already produced -dbgsym files, and already hosted the archives; it just couldn t answer the question. This summer I made it answer. My project was to add debuginfod server functionality to Debusine so that it not only hosts -dbgsym packages, but also serves their debug symbols over the debuginfod(8) protocol. Debian developers can then debug binaries by setting a single URL that gdb uses to fetch the matching debug symbols. This project took me through design, backend work, an extraction pipeline on the worker, HTTP serving, documentation, and testing from the first blueprint all the way to a live demo on debusine.debian.net.

Initial planning and design changes A design first, in !3030. The proposal submitted for GSoC 2026 was just an overview of how things will work, but in reality there were a lot of design questions which needed to be answered before starting with contribution. Debusine keeps development blueprints in its docs tree, reviewed like code, it s basically a blueprint of what feature or new changes are we going to make. I was assigned the work item #957, which was basically about how the idea of implementing a debuginfod server functionality inside Debusine was initially proposed by a fellow member which later became a project idea under GSoC 2026. My developer blueprint pinned down the four decisions everything else depends on: extraction happens on the worker after the build, symbols are stored as artifacts keyed by build-ID, they re published into suites alongside their binaries, and they re served from the archive root rather than per-suite. Settling that up front meant the design discussions happened in a document instead of across three merged branches. Provide debuginfod server work item and all my merged PRs till now One of those arguments became its own fix. My wording implied symbols were unpacked inside the isolated sbuild environment (the consequence was I was handed a bug to be solved in the first week of contribution period), when they re actually extracted afterwards on the worker, where the build output already sits, a distinction that matters, because doing work inside the unshare environment means extra tooling in the chroot and more ways to affect the build. !3119 corrected it before the wrong model spread into the code. Bug raised for inconsistent wordings in developer blueprint

A new artifact type Artifacts are a major concept in Debusine overall, so as per the developer blueprint we introduced a new artifact which was debian:debug-symbols. It holds every .debug file from one -dbgsym package. Its data is a validated list of lowercase 40-character build-IDs, and each file is stored under its build-ID as the path, so answering what are the symbols for this ID? is a direct lookup, with no path translation in the request handler. One artifact per package rather than per file: a util-linux build would otherwise spray hundreds of artifacts, collection items and relations across the database for no benefit. For implementing debian:debug-symbols artifact, I changed the main models.py file, along with that since it s a norm to write unit tests, all mentioned under !3088. sbuild task output showing the new debian:debug-symbols artifact

Publishing workflow and solving a bug Extracting symbols is only useful if they reach the archive people actually install from, so !3180 taught package_publish to follow the relates-to relation: copying binaries into a suite now brings their debug symbols along automatically, with nothing extra for the publisher to configure. Each build-ID becomes its own collection item, for example debugsym:hello_2.10-5_amd64_fcc9064 each carrying the package name, version and architecture copied from the binary, so the item is meaningful on its own without dereferencing anything. Uniqueness is enforced at both the suite and archive level, because the serving URLs are archive-wide and two suites must never disagree about what a build-ID means: republishing an identical file is accepted quietly, while two different files claiming the same ID is an error worth failing on. A partial index on the build-ID keeps the eventual HTTP lookup fast. That looked finished until symbols started arriving in target suites disconnected from their binaries published, but unfindable, because copying items between collections silently dropped their artifact relations, and that relation is the only thing tying the two together. The fix sat one level above my feature, in the generic CopyCollectionItems task that does the copying, and since it was reusable infrastructure rather than anything debuginfod-specific, Colin implemented it himself in !3228. My project needed it to work at all; every other Debusine feature that copies items now gets it for free.

Endpoint and CI tests With symbols in the archive, !3212 added the part users actually touch: GET / scope / workspace /buildid/<build-id>/debuginfo looks the ID up across every suite in that workspace s archive, streams the file, and sets the X-DEBUGINFOD-FILE and X-DEBUGINFOD-SIZE headers the protocol expects. It also handles the two things gdb actually does: a HEAD probe before committing to a download, and ranged requests to pull individual ELF sections instead of the whole file. Scoping it to the archive rather than the suite is what lets one URL cover a whole workspace, so the developer never has to know which suite their binary came from. Fetching debug files from debusine.debian.net Every merge request above landed with unit tests, but those only tell you that the pieces behave correctly. What Colin and I wanted was a real gdb fetching real symbols from a real instance, so !3261 adds an autopkgtest that builds a package, publishes it, checks the HTTP headers, then sets DEBUGINFOD_URLS and makes gdb go and get the symbols, wired into the CI integration tests so it runs on every change. It took me a day to learn that skipping the signing worker doesn t simplify that test, it just hangs until the 30-minute timeout, because update_suites needs signing to produce a usable repository. The last piece, !3301 covers the new artifact, the suite and archive changes, the new archive URL, and a how-to for using it. My first how-to draft explained how everything worked and offered four ways to set DEBUGINFOD_URLS; the version that shipped gives one recommended setup and gets out of the way. The same pass trimmed the blueprint down to only what s still unimplemented, since a design document describing merged code is just an obstacle for the next reader. Setting debuginfod url for gdb and debugging session!

What s left Only one item on my original plan didn t land: an archive-level build_debug_symbols switch, modelled on Launchpad s equivalent, letting an archive skip building -dbgsym packages entirely by passing DEB_BUILD_OPTIONS=noautodbgsym to sbuild. It was always the stretch goal rather than core scope, landing the extract-publish-serve path solidly mattered more than landing it broadly. The design is written up in the blueprint, and I intend to implement it myself. The other gaps were deliberately out of scope from the start, and the blueprint says so. DWZ supplement files aren t ingested, so packages using compressed debug info may render without the alternate strings table; debugging still works, it s just less complete. Source-file serving runs into the same Debian packaging limits that constrain debuginfod.debian.net today, making it a design question rather than a coding one. Executable serving, the metrics and metadata endpoints, and federation to upstream debuginfod servers were excluded for similar reasons, none of them are needed for Debusine s core use case, and each would have crowded out the parts that are. One open bug is left too. On the last day of the coding period, Stefano Rivera found that publishing ledger and linux was failing, because I had told the database that a build-ID identifies one exact debug file which isn t true in Debian, since dh_dwz runs once per binary package, so when one object ships in two binary packages their .debug files differ while describing identical code. How to fix it is still an open discussion #1582, though it may not land before the formal end of the project. None of that is a handoff. GSoC s timeline is ending, my involvement isn t, I m carrying on with Debusine until both the build_debug_symbols switch and DWZ supplement support are merged, and I expect to keep contributing beyond that. This project got me familiar with a codebase I enjoy working in, and the remaining pieces are mine to finish.

Thanks! The biggest thanks go to my mentor, Colin Watson, whose reviews consistently found the thing I hadn t thought about. He also gave me room to get things wrong first and understand why, which taught me more than being handed the answer would have. Thanks as well to Rapha l Hertzog, Enrico Zini, Stefano Rivera, Carles Pina i Estany and Helmut Grohne and everyone else around Debusine and Freexian for reviews, comments and patience with my questions. Special thanks to Freexian for developing Debusine in the open and for giving me access to test on debusine.debian.net. Finally, thanks to the wider Debian community, whose build-ID and -dbgsym conventions did most of the hard work before I arrived and to Google Summer of Code for providing a platform and the time to do this properly.

6 September 2026

Michael Stapelberg: Debian Code Search: Fast TurboPFor with Go SIMD

This August, I accomplished what I wanted for many years: I deleted the last cgo dependency in Debian Code Search! This was made possible by Go s recently introduced SIMD support, because now we can implement the TurboPFor integer compression format as efficiently more efficiently, in fact, by using the newer AVX512 instruction set! as the reference implementation.

Background: Why does DCS need a fast Integer Codec? Debian Code Search (DCS) is a search engine that allows searching all the Open Source source code within Debian, with either literal search expressions or regular expression search queries. A search engine uses an inverted index: a map from term to documents containing the term. Each document is typically represented most efficiently by using an id, so the index consists of many lists of document ids. When searching, it is important to quickly decode these lists to answer the search query. However, there is a point of diminishing returns where the decoding speed, even though it can still be measurably improved quite a bit, no longer influences the overall query duration. From 2012 (its inception) to 2019, Debian Code Search used to use a small index format, and queries were fast because the index was kept entirely in RAM. In 2019, I implemented the new index format, which adds an on-disk positional index. For literal queries (78.2% of DCS queries), querying the positional index on disk is faster than querying the non-positional index in RAM. The efficient encoding of the TurboPFor format makes it possible to fit such an index on a mid-sized Hetzner server, which I rent with two 1 TB SSD disks. The optimized decoder of the C TurboPFor library is what made decoding fast at query time. If you want to dive deeper into the algorithm, see this blog post from February 2019: If you want to learn more about the positional index, see this blog post from September 2019:

SIMD in Go For many years, you had the following options for using SIMD instructions in Go:
  1. Hand-writing Go assembler code. This is only doable for small functions, for example bytes.IndexByte is implemented with hand-written Go assembly (including AVX2).
  2. Generating Go assembler code with tools like Michael McLoughlin s Avo . This is how crypto/internal/fips140/sha256 uses AVX2. While Avo generator code definitely is higher-level than hand-written assembly, it is still too close to assembly for my taste.
  3. Use a C library via cgo so gcc or clang compiles SIMD code. Debian Code Search used to use the powturbo/TurboPFor C library via cgo for the last 7 years.
The C TurboPFor library has served us well, but Debian Code Search was always intended to be a project using Go, so I would prefer it if I did not have any C code in the project. Go 1.26 (released in February 2026) introduced the simd/archsimd package:
Go 1.26 introduces a new experimental simd/archsimd package, which can be enabled by setting the environment variable GOEXPERIMENT=simd at build time. This package provides access to architecture-specific SIMD operations. It is currently available on the amd64 architecture and supports 128-bit, 256-bit, and 512-bit vector types, such as Int8x16 and Float64x8, with operations such as Int8x16.Add. The API is not yet considered stable. Go 1.26 Release Notes
For my 2019 TurboPFor analysis, I implemented goturbopfor, a native Go teaching decoder (without any SIMD), because I find Go code easier to follow than C code, especially optimized C code. My implementation was intentionally not optimized so that the code was easier to study. The TurboPFor format/algorithm has a vector-optimized part: bitpacking comes in a scalar variant (bitunpack32) and a vector variant (bitunpack256v32), where the vector variant is used for full blocks (256 values) and the scalar variant is used for remainder blocks (< 256 values). When Go 1.26 was released, I used Claude Code to explore whether my native Go decoder s bitunpack256v32 function (for the vertical vector layout) could be implemented using Go SIMD, and the answer was yes, it was possible and it was faster than without SIMD, but not quite at the level of C TurboPFor. If you let Claude Code try for long enough, it eventually finds enough optimizations (about 10) to match C performance. I don t want to vibe-code Debian Code Search, though, so I figured I would find some time to review the SIMD code at some point and see if I could implement something similar myself. Before I found enough time and motivation to complete said review, I discovered that to not regress real-life query performance by more than 10 to 100 milliseconds (which seems acceptable), I don t actually need to add SIMD code to my teaching decoder at all; it would be sufficient to reduce allocations in my teaching decoder and specialize it per bit width. Encouraged by the possibility of using the optimized native Go decoder in Debian Code Search, I explored whether I could also implement a native Go encoder so that I could get rid of the C TurboPFor dependency entirely. The answer is yes, it is doable in a few days, and it isn t even that much slower: Go is at 76% of C, see Debian/dcs commit e920dc7. The goal I set myself at that point was to see if I could learn enough SIMD to optimize the native Go encoder such that its performance would match how DCS uses C TurboPFor (via cgo). Beating C TurboPFor was possible in 2-3 commits (SIMD and bit width specialization). To my surprise, Claude Fable 5 pointed out that the encoder s block scanning could be done more efficiently using a technique called positional popcount, and that is another 2x speed-up! To be clear: I am not saying the Go compiler beats C here. Certainly, the C compiler can also produce fast AVX512 code and can be used to implement positional popcount. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. This spectacular result (much faster than what DCS had before) got me curious how far I could push the decoder with SIMD after all. I ended up matching/exceeding the cgo version here, too! The rest of this article explains a few classes of optimizations I encountered along the way.

Starting Point When I wrote my goturbopfor teaching decoder, I named its functions to match the upstream C TurboPFor library, but now I want to get away from names like p4ndec256v32 they make sense from the TurboPFor perspective, but for Debian Code Search, we can use cleaner names. Before writing any code, I audited how DCS uses integer compression / decompression.

API design: BlockEncoder, BlockDecoder and streaming In Debian Code Search, we have the following usage patterns:
  • Partial Indexing: When a new package (or package version) enters Debian, all of its (text) files are indexed. If the hello-2.12.3-1 package (hypothetically) contained only hello.c with printf("hello!\n");, we would assign document ID 1 to hello.c and store in the partial index that trigrams pri, rin, int, ntf, etc. are all found in doc 1 (hello.c).
  • Full Index Merging: The many thousands of partial index files (for each Debian package) are combined into a small handful of large index files: When searching, it would be expensive to consult thousands of indexes. To merge multiple partial index files into one larger index (which can then be efficiently queried), we need to re-encode the partial index files: what used to be document ID 1 in the partial index might be document ID 2531 in the full index.
  • Querying (searching): When users enter search queries, these queries need to be answered as quickly as possible. The relevant entries in the full indexes are decoded (in parallel).
For reading the index, we do keep the decoded uint32s fully in memory, so we only need DecodeN(input []byte, output []uint32) (read int), a function that reads len(output) values (uint32) from input and returns how many bytes it consumed. For writing the index (both in partial indexing, and when merging), keeping the entire index in memory is prohibitively expensive, so we need a streaming API, for decoding and for encoding. Ultimately, I converged on the following API:
package pforenc

type BlockEncoder struct  
    // scratch buffers can go here
 

// EncodeBlock encodes len(vals)<=256 uint32s into dest (one TurboPFor block).
func (*BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  

// EncodeN calls EncodeBlock in a loop.
func (*BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  

type StreamEncoder struct  
  be   BlockEncoder
  vals [256]uint32
  // scratch buffers
 

// if full, you need to call [EncodeBlock]
func (*StreamEncoder) Add(val uint32) (full bool)

// EncodeBlock must be called after all data was [Add]ed.
//
// Write the returned buffer to file or send it over the network;
// it is only valid until the next [EncodeBlock] call.
func (*StreamEncoder) EncodeBlock() []byte  
  if se.n == 0   return nil   // turn an extra EncodeBlock into a no-op
  //  
 
This API (the decoder works similarly) allows us to process data in TurboPFor format without any memory allocations. The types are not safe for concurrent use by multiple goroutines. The zero value is ready to be used. For the streaming API, the result only stays valid until the next call.

Initial Implementation Before we can optimize anything, we need a working decoder and encoder. The decoder already exists: my goturbopfor teaching decoder. Next up, I needed an encoder. Writing a TurboPFor encoder has a delightfully simple starting point: You can encode all values at bit width 32, in little endian, at which point you only need to add a one-byte TurboPFor block header every 256 values and you re done:
func (be *BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  
  for len(vals) > 0  
    chunk := min(len(vals), 256)
    dest = be.EncodeBlock(dest, vals[:chunk])
    vals = vals[chunk:]
   
  return dest
 

func (be *BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  
  const bitWidth = 32
  dest = append(dest, bitWidth)
  for _, val := range vals  
    dest = binary.LittleEndian.AppendUint32(dest, val)
   
  return dest
 
Of course, this is a terribly inefficient compressor, so after the first commit, the real work starts: implement each block type until the compression matches the original C TurboPFor implementation (same output file size), or in other words: do the reverse of the decoder.
  1. The TurboPFor bitpacking block type (bitpacking implementation commit) encodes a bit stream of variable bit width (where the bit width is in range 0 bitWidth 32) in little endian byte order. By scanning all values and choosing the smallest bit width that allows representing all values, this technique saves disk space (compresses).
  2. The bitpacking with exceptions block type (bitpacking with exceptions implementation commit) determines two bit widths: one for values, the other bit width for encoding exceptions. This allows choosing a lower bit width (that does not cover all values) compared to the bitpacking block type. A bitmap encodes whether a value has an exception or not.
  3. The bitpacking with VB exceptions block type (bitpacking with VB exceptions implementation commit) is a variant which does not use an exception bitmap and encodes exceptions using a variable byte integer encoding. This is more efficient when there are few exceptions (less than 20) or the exceptions are very different in bit width compared to the other values.
  4. Lastly, the constant block type (constant implementation commit) stores just one value on disk. This is useful for all-zero or all-one blocks, for example.
I found it interesting to realize that the main work of the encoder is to scan the input values and choose the optimal block type, whereas the actual encoding itself is cheap in comparison. At this point, we can look at performance and see that the Go encoder is at 76% of the C encoder. In all honesty, I could have probably stopped here, but now that the milestone of a viable replacement was reached, I got curious to see how far it would be possible to push the encoder (how much work to reach C speeds?) and afterwards, the decoder, too.

Setup

The microarchitecture level: set GOAMD64 The microarchitecture of a CPU determines which instructions it provides, and that includes not just SIMD instruction sets (like AVX2), but also other useful instructions like LZCNT (Leading Zero Count), which can be used to implement math/bits.Len32 more efficiently, which the TurboPFor encoder needs to call on every input value to determine the ideal bit width. Let s walk through how to set the microarchitecture level when using Go on 64-bit x86 (x86-64). Go uses the GOARCH environment variable to configure the target compilation architecture, and I am using the value amd64 to select 64-bit x86 (AVX2 and AVX512 are instruction sets found on x86-64 CPUs). With GOARCH=amd64, the architecture-specific variable GOAMD64 configures the microarchitecture level for which to compile and Go 1.18 introduced these 4 different levels:
GOAMD64=v1 (default): The baseline.
Exclusively generates instructions that all 64-bit x86 processors can execute. GOAMD64=v2: all v1 instructions,
plus CMPXCHG16B, LAHF, SAHF, POPCNT, SSE3, SSE4.1, SSE4.2, SSSE3. GOAMD64=v3: all v2 instructions,
plus AVX, AVX2, BMI1, BMI2, F16C, FMA, LZCNT, MOVBE, OSXSAVE. GOAMD64=v4: all v3 instructions,
plus AVX512F, AVX512BW, AVX512CD, AVX512DQ, AVX512VL.
In 2026, I generally recommend compiling with GOAMD64=v3 so that functions like bits.OnesCount8 are compiled into intrinsics (POPCNT) instead of using a lookup table. For Intel CPUs, setting GOAMD64=v3 means your programs will only start on Haswell CPUs (2013) or newer; for AMD CPUs that means Zen 1 (2017) or newer. In this specific case (DCS), I am even compiling with GOAMD64=v4. The v4 microarchitecture level requires AVX512, which means AMD Zen 4, Zen 5 or newer (Intel s story is complicated). Luckily, both my main development PC (Zen 5) and the Debian Code Search server (Zen 4) are recent enough. Setting GOAMD64=v4 has little effect on Go 1.27 itself: the only change is that maps use one less instruction (VPBROADCASTB instead of PSHUFB). But compiling with GOAMD64=v4 allows us to move one more feature check from runtime to compile time, see SIMD build tags. It makes sense to set the microarchitecture level in your benchmark setup so that you don t measure the slow fallback implementations. I use export GOAMD64=v4 in my Makefile.

Benchmarking setup Go s built-in testing package contains support for benchmarks which are written in functions of the form func BenchmarkXxx(b *testing.B). The simplest way to run such benchmarks is go test -bench=., but I ended up configuring a few convenience make targets, which write results to bench.txt and compare against baseline.txt (the previous commit s results, usually), using the very useful benchstat tool.
GOTEST=go test

# -count=6 gives p 0.002 in benchstat:
# https://pkg.go.dev/golang.org/x/perf/cmd/benchstat
BENCHFLAGS=-run=^$$ -bench=. -benchtime=200000x -count=6

# use taskset -c1 to always pin to the same single core,
# avoiding accidental scheduling on different cores on
# mixed-core CPUs like the Ryzen 9 9950X3D.
TASKSET=taskset -c 1
BENCH=$(TASKSET) $(GOTEST) $(BENCHFLAGS)

.PHONY: all test bench bench-baseline bench-relative

all: test

bench: test
	$(BENCH)   tee bench.txt
# Compares compression ratio between C and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '-/impl:go-stream .unit:(encoded-bytes)' bench.txt
# Compares performance between C (cgo) and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '.unit:(Mval/s)' bench.txt

bench-baseline: test
	$(BENCH)   tee baseline.txt

bench-relative: test
	$(BENCH)   tee bench.txt
	benchstat -filter '-/impl:go-stream .unit:(encoded-bytes)' baseline.txt bench.txt
	benchstat -filter '/impl:go .unit:(Mval/s)' baseline.txt bench.txt
The encoded-bytes and Mval/s units are custom metrics I am reporting from the various sub-benchmarks, which are arranged such that I can filter / report them with benchstat. The main encoder (and decoder) benchmarks compare 3 different implementations (cgo, Go, Go with the StreamEncoder API) with a number of benchmark cases that are designed to cover the different block types and contain a similar mix of values as what we see in Debian Code Search:
// reportMetrics adds Mval/s and encoded-bytes metrics to all benchmarks.
func reportMetrics(b *testing.B, n int, nencoded int)  
   b.ReportMetric(float64(nencoded), "encoded-bytes")
   b.ReportMetric(float64(b.N*n)/1e6/b.Elapsed().Seconds(), "Mval/s")
 

// BenchmarkEncode/n=<N>/vals=<testcase>/impl=<c go go-stream>
//
// e.g. BenchmarkEncode/n=2048/vals=one-constant/impl=go-stream
func BenchmarkEncode(b *testing.B)  
   for _, tc := range allBenchCases()  
     n := len(tc.vals)
     b.Run(fmt.Sprintf("n=%d/vals=%s", n, tc.name), func(b *testing.B)  
       b.Run("impl=c", func(b *testing.B)  
         b.ReportAllocs()
         var encoded []byte
         buf := make([]byte, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = turbopfor.P4nenc256v32Buf(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go", func(b *testing.B)  
         b.ReportAllocs()
         var be BlockEncoder
         var encoded []byte
         buf := make([]byte, 0, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = be.EncodeN(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go-stream", func(b *testing.B)  
         b.ReportAllocs()
         var se StreamEncoder
         var encoded int
         for b.Loop()  
           encoded = 0
           for _, val := range tc.vals  
             if se.Add(val)  
               encoded += len(se.EncodeBlock())
              
            
           encoded += len(se.EncodeBlock())
          
         reportMetrics(b, n, encoded)
        )
      )


CPU counters: perf Go has included excellent performance tooling for many years, see the Profiling Go Programs blog post (2011) for an example of how to use pprof, a sampling profiler. This profiler can help track down which part of a program runs slow, or where memory allocations happen. Once you identified the slow part of a program, how do you know why it s slow? To learn more about the specific bottlenecks your program encounters, you can consult your CPU s hardware performance counters. For example, you could check the branch predictor counters to see if your program is slow due to a high number of branch mispredicts. On Linux, the perf tool is the best way to access the CPU hardware performance counters. A good starting point for working with perf is the documentation on Top-down analysis with the perf tool , which describes the optimization method that Intel established. In my Makefile, I set up two perf targets:
# GOTEST and TASKSET like shown in the earlier benchmarking setup section:
GOTEST=go test -pgo=encode.cpuprof
TASKSET=taskset -c 1
PERFBENCHFLAGS=-test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=200000x

# Use perf(1) to capture AMD IBS (the equivalent to Intel PEBS)
# PipelineL1 is roughly equivalent to Intel TopdownL1
perf:
	$(GOTEST) -c
	$(TASKSET) perf stat -M PipelineL1 ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo perf record -F 4999 -e ibs_op// --call-graph fp ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo chmod 644 perf.data

# 488281 iterations   2048 values = 1.000e9 values, so counter/1e9 = per value.
perf-per-value:
	$(GOTEST) -c
	$(TASKSET) perf stat -x, -e cycles:u,instructions:u,branches:u,branch-misses:u ./pforenc.test -test.run=^$$ -test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=488281x 2>&1 >/dev/null   awk -F, ' printf "%-16s %6.2f /val\n", $$3, $$1/1e9 '
The perf-per-value numbers are high level numbers that indicate how much work the implementation is doing. Reducing the number usually increases speed. To see the counters for each instruction (and source code lines), I use make perf, followed by perf report. A quick shortcut is perf annotate, which directly shows the hottest function.

Optimizations (scalar) Let s first see how far we can get without reaching for SIMD instructions. (The examples are not necessarily in commit order, but cherry-picked for clarity.)

Profile-Guided Optimization (PGO) PGO stands for Profile-Guided Optimization and is a feature that Go introduced as a preview in Go 1.20 (released in February 2023) and shipped as ready for general production use in Go 1.21 (released in August 2023). The idea is to capture a CPU profile that records where your program spends most of its CPU time, which you then provide to the Go compiler to give it more data to make better decisions. Most importantly, this way the Go compiler can inline functions much more aggressively than its usual heuristics allow, which does have a measurably positive effect in my series of optimization commits. Another optimization that a PGO profile allows the compiler to do is conditional devirtualization but our TurboPFor code does not use any interfaces. My strategy is to enable PGO before doing any other optimizations, so that we have the full inlining budget available that PGO gives us, and can measure the effect of other commits clearly. Surprisingly, turning on PGO actually decreases our performance (-13% geomean), but a closer investigation reveals that we just got unlucky. Let me explain. Aside from inlining and conditional devirtualization, PGO also influences alignment: The Go compiler sets PCALIGNMAX(64, 31) on the first block of a loop (the loop body ) for all loops in hot functions (per the PGO profile), i.e. Go will insert up to 31 bytes of padding to make the block land on a 64-byte boundary. Documentation like AMD s Software Optimization Guide for the AMD Zen5 Microarchitecture (2024, #58455) explicitly recommends aligning hot loops that way:
[ ] for hot loops, some further knowledge of trade-offs can be helpful. Because the processor can read an aligned 64-byte fetch block every cycle, it is suggested to either align the start of the loop to the beginning of a 64-byte cache line [ ]
Indeed, when compiling with -gcflags=all=-d=alignhot=0 to disable the alignment, performance remains as good as without PGO. How can the padding hurt more than help? The answer is: It s not the padding itself! It s a side-effect of the padding moving instructions to different addresses. In the unlucky arrangement, a macro-fused CMPQ+JGE instruction pair now ends up exactly on a 32-byte boundary. However, the Go compiler ensures fused branch sequences must never cross or end at a 32-byte boundary to fix Intel erratum SKX102 (discussion: Go issue #35881) by inserting NOPs. This NOP padding, unlike the loop alignment padding, is not free; these extra instructions slow down our otherwise dispatch-bound loops. Because the commits after the PGO enabling commit change the code, this unlucky situation is avoided for the rest of the optimization series (by chance).

Reducing memory allocations Memory allocations are quite expensive, at least in comparison to encoding/decoding integers, so I followed my usual strategy of first reducing memory allocations as much as possible. In my goturbopfor teaching decoder, whenever the code needed a scratch buffer, it would allocate it right then and there with make():
// p4dec32 decodes one block of TurboPFor-encoded 32 bit ints
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
    //  
  switch blockType  
  case blockBitpackingExceptions:
    bx, input := input[0], input[1:]
    n := len(output)

    exmap := input
    nex := 0 // number of exceptions
    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        nex++
       
     
    input = input[(n+7)/8:]

    exceptions := make([]uint32, nex)
    input = input[bitunpack32(input, exceptions, bx):]
    input = input[d.bitunpack(input, output, b):]

    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        output[i] += exceptions[0] << b
        exceptions = exceptions[1:]


    return before - len(input)
   
 
The Go compiler can turn make(T, n) calls into stack allocations, if n is known at compile-time. But, in this case nex is not known at compile-time. We can verify that Go calls into the runtime (runtime.makeslice) by dumping the object code (assembly) with source annotated (-S):
% cd ~/go/src/github.com/stapelberg/goturbopfor
% git reset --hard 49b7c05cc61e77f0257568eb73833467714d2b4a
% go test -c  # go1.27.0
% go tool objdump -S goturbopfor.test   perl -nlE 'say if /p4dec32/ .. /^$/'
TEXT github.com/stapelberg/goturbopfor.(*decoder).p4dec32(SB) /home/michael/go/src/github.com/stapelberg/goturbopfor/goturbopfor.go
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
  0x549f60		4c8da42460ffffff	LEAQ 0xffffff60(SP), R12
  0x549f68		4d3b6610		CMPQ R12, 0x10(R14)
  0x549f6c		0f86d9070000		JBE 0x54a74b
  0x549f72		55			PUSHQ BP
  0x549f73		4889e5			MOVQ SP, BP
  0x549f76		4881ec18010000		SUBQ $0x118, SP
  0x549f7d		48899c2430010000	MOVQ BX, 0x130(SP)
  0x549f85		4889b42448010000	MOVQ SI, 0x148(SP)
	if len(output) == 0  
  0x549f8d		4d85c0			TESTQ R8, R8
  0x549f90		0f84a7030000		JE 0x54a33d
  0x549f96		660f1f840000000000	NOPW 0(AX)(AX*1)
  0x549f9f		90			NOPL
[ ]
		exceptions := make([]uint32, nex)
  0x54a4be		488d057bec1700		LEAQ 0x17ec7b(IP), AX
  0x54a4c5		4c89fb			MOVQ R15, BX
  0x54a4c8		4889d9			MOVQ BX, CX
  0x54a4cb		e8f0ddf3ff		CALL runtime.makeslice(SB)
[ ]
An easy speed-up was to avoid allocations through reuse (in goturbopfor). In the DCS pfordec package (with the improved API design), I ended up with a vals [256]uint32 field in the StreamDecoder type, which brings us from 773 Mval/s to 858 Mval/s on the debian-mix:
% benchstat -filter '/impl:go /vals:debian-mix .unit:(Mval/s)' \
  baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pfordec
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
             baseline.txt               bench.txt               
                Mval/s        Mval/s     vs base                
n=2048        1.089k   1%   1.175k   0%   +7.85% (p=0.002 n=6)
n=2039         974.7   0%   1046.0   0%   +7.32% (p=0.002 n=6)
n=160          434.9   1%    513.6   5%  +18.11% (p=0.002 n=6)
geomean        772.9         857.7       +10.98%
Aside from the speed-up, avoiding memory allocations is generally nice in benchmarks because it removes the garbage collector from the equation and makes it less likely that your benchmarks get other processes OOM-killed on the same machine.

Generics for bit width specialization In general, we want to make it easy for the compiler to understand as much as possible about our algorithm. Consider this bitpack implementation:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 
Let s think through what determines the iterations and control flow this function uses:
  1. The number of input values (vals), but not their actual value.
  2. The bit width to pack into (bitWidth).
With a bit of careful rearrangement, we can provide the compiler with both, a fixed number of input values (say, 32), and a bit width, both known at compile time. Why is this worthwhile? Because we can manually unroll the loop, let the compiler eliminate much of the repetition and get much faster compiled code as a result! Let s first fix the number of input values to 32 and rewrite the loop to calculate the position offsets within dest instead of changing dest on each value (with AppendUint32):
func bitpack32Unrolled(dest []byte, vals *[32]uint32, bitWidth int)  
  // only one bounds check for 32 values
  dest = dest[: 4*bitWidth : 4*bitWidth]
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[30] elided for brevity

  // Each loop iteration is 8 lines of Go code, so for 32 input values,
  // bitpack32Unrolled contains 8*32 = 256 lines of code.

  acc  = uint64(vals[31]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // have == 0; for all bitWidths
 
Next, we want to specialize not just for 32 input values, but also for each of the 32 bit widths. Can we do better than hand-copying bitpack32Unrolled 32 times (= 8192 lines of Go code)? Yes, we can use Go generics to help us with the code generation! In Go, array types like [4]byte (not slices like []byte!) contain the length of the array as part of their type, meaning [1]byte (an array of length 1) is a different type than [2]byte. Instead of passing the bit width as a function parameter, we can declare 32 different types (one for each bit width) and recover the bit width (at compile time!) from the type system:
type bitWidthT interface  
  [1]byte   [2]byte   [3]byte   [4]byte   [5]byte  
  [6]byte   [7]byte   [8]byte   [9]byte   [10]byte  
  [11]byte   [12]byte   [13]byte   [14]byte   [15]byte  
  [16]byte   [17]byte   [18]byte   [19]byte   [20]byte  
  [21]byte   [22]byte   [23]byte   [24]byte   [25]byte  
  [26]byte   [27]byte   [28]byte   [29]byte   [30]byte  
  [31]byte   [32]byte
 

func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  var zero T
  bitWidth := len(zero)                  // known at compile time
  dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[31] elided for brevity
 
When we instantiate bitpack32Unrolled[bitWidthT] with all 32 different types ([1]byte, [2]byte, , [32]byte), the compiler substitutes the bitWidthT type parameter and produces 32 copies of the function, which we can find in our compiled executable with names like github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[12]uint8]. The shape of a generic type is based on its memory layout, so a shape for [1]byte must be different than the shape for [2]byte. Because the bitWidth is now known at compile time, the Go compiler can generate close to the optimal machine code for each bit width, which we can confirm using go tool objdump. The code is branchless (after the one bounds check per 32 values) and aside from the loads and stores (from/to memory) consists only of shifts and bit operations, all with constant operands:
% go test -c && go tool objdump -S pforenc.test
[ ]
TEXT github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[28]uint8](SB) /home/michael/dcs/internal/turbopfor/pforenc/bitpackunroll.go
func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  0x660580              55                      PUSHQ BP
  0x660581              4889e5                  MOVQ SP, BP
  0x660584              48895c2418              MOVQ BX, 0x18(SP)
        dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  0x660589              4883ff70                CMPQ DI, $0x70
  0x66058d              0f820b030000            JB 0x66089e
        acc  = uint64(vals[0]&mask) << have
  0x660593              8b06                    MOVL 0(SI), AX
  0x660595              25ffffff0f              ANDL $0xfffffff, AX
        acc  = uint64(vals[1]&mask) << have
  0x66059a              8b4e04                  MOVL 0x4(SI), CX
  0x66059d              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605a3              48c1e11c                SHLQ $0x1c, CX
  0x6605a7              4809c8                  ORQ CX, AX
                acc >>= 32
  0x6605aa              4889c1                  MOVQ AX, CX
  0x6605ad              48c1e820                SHRQ $0x20, AX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605b1              90                      NOPL
        b[0] = byte(v)
  0x6605b2              890b                    MOVL CX, 0(BX)
        acc  = uint64(vals[2]&mask) << have
  0x6605b4              8b4e08                  MOVL 0x8(SI), CX
  0x6605b7              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605bd              48c1e118                SHLQ $0x18, CX
  0x6605c1              4809c1                  ORQ AX, CX
                acc >>= 32
  0x6605c4              4889c8                  MOVQ CX, AX
  0x6605c7              48c1e920                SHRQ $0x20, CX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605cb              90                      NOPL
        b[0] = byte(v)
  0x6605cc              894304                  MOVL AX, 0x4(BX)
Now we need to actually call bitpack32 from the general bitpack function:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  if bitWidth == 0  
    return dest // no payload, sparse block with only exceptions
   
  if len(vals) >= 32  
    size := 4 * bitWidth
    for len(vals) >= 32  
      existing := len(dest)
      dest = slices.Grow(dest, size)[:existing+size]
      bitpack32(dest[existing:] /*append*/, (*[32]uint32)(vals), bitWidth)
      vals = vals[32:]
     
   
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 

func bitpack32(dest []byte, vals *[32]uint32, bitWidth int)  
  switch bitWidth  
  case 1: bitpack32Unrolled[[1]byte](dest, vals)
  case 2: bitpack32Unrolled[[2]byte](dest, vals)
  case 3: bitpack32Unrolled[[3]byte](dest, vals)
  case 4: bitpack32Unrolled[[4]byte](dest, vals)
  case 5: bitpack32Unrolled[[5]byte](dest, vals)
  case 6: bitpack32Unrolled[[6]byte](dest, vals)
  case 7: bitpack32Unrolled[[7]byte](dest, vals)
  case 8: bitpack32Unrolled[[8]byte](dest, vals)
  case 9: bitpack32Unrolled[[9]byte](dest, vals)
  case 10: bitpack32Unrolled[[10]byte](dest, vals)
  case 11: bitpack32Unrolled[[11]byte](dest, vals)
  case 12: bitpack32Unrolled[[12]byte](dest, vals)
  case 13: bitpack32Unrolled[[13]byte](dest, vals)
  case 14: bitpack32Unrolled[[14]byte](dest, vals)
  case 15: bitpack32Unrolled[[15]byte](dest, vals)
  case 16: bitpack32Unrolled[[16]byte](dest, vals)
  case 17: bitpack32Unrolled[[17]byte](dest, vals)
  case 18: bitpack32Unrolled[[18]byte](dest, vals)
  case 19: bitpack32Unrolled[[19]byte](dest, vals)
  case 20: bitpack32Unrolled[[20]byte](dest, vals)
  case 21: bitpack32Unrolled[[21]byte](dest, vals)
  case 22: bitpack32Unrolled[[22]byte](dest, vals)
  case 23: bitpack32Unrolled[[23]byte](dest, vals)
  case 24: bitpack32Unrolled[[24]byte](dest, vals)
  case 25: bitpack32Unrolled[[25]byte](dest, vals)
  case 26: bitpack32Unrolled[[26]byte](dest, vals)
  case 27: bitpack32Unrolled[[27]byte](dest, vals)
  case 28: bitpack32Unrolled[[28]byte](dest, vals)
  case 29: bitpack32Unrolled[[29]byte](dest, vals)
  case 30: bitpack32Unrolled[[30]byte](dest, vals)
  case 31: bitpack32Unrolled[[31]byte](dest, vals)
  case 32: bitpack32Unrolled[[32]byte](dest, vals)
   
 
Encoding remainder blocks is quite a bit faster (full blocks use the vertical layout anyway):
% benchstat -filter '/impl:go /n:160 .unit:(Mval/s)' baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pforenc
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
                           baseline.txt               bench.txt               
                              Mval/s        Mval/s     vs base                
vals=bitpacking-bw1          751.2   3%   1120.5   0%  +49.15% (p=0.002 n=6)
vals=bitpacking-bw2          716.8   2%   1176.0   0%  +64.07% (p=0.002 n=6)
vals=bitpacking-bw7          700.0   1%   1078.5   0%  +54.08% (p=0.002 n=6)
vals=bitpacking-bw1-exc      524.8   1%    736.8   0%  +40.40% (p=0.002 n=6)
vals=bitpacking-bw2-exc      543.7   1%    758.2   0%  +39.46% (p=0.002 n=6)
vals=bitpacking-bw7-exc      566.7   1%    787.7   0%  +38.99% (p=0.002 n=6)
vals=bitpacking-vb-exc       442.6   1%    616.5   0%  +39.29% (p=0.002 n=6)
vals=sparse-exc              532.4   0%    787.8   0%  +47.97% (p=0.002 n=6)
vals=sparse-vb-exc           408.9   1%    597.8   0%  +46.20% (p=0.002 n=6)
vals=debian-mix              559.5   0%    783.8   9%  +40.09% (p=0.002 n=6)
This performance win comes at the cost of binary size increase. In this case, the .text section (executable code) grows by about 20 KB and the .gopclntab section grows by another 26 KB. Definitely a price I am very willing to pay, but the case might not be as clear in all circumstances.

Optimization: Bigger strides with SIMD Even without reaching for SIMD instructions, a TurboPFor implementation can be made faster by making it work bigger strides. Take this code from the goturbopfor teaching decoder which counts the number of exceptions by checking if each value s bit is set in the exception bitmap:
case blockBitpackingExceptions:
  bx, input := input[0], input[1:]
  n := len(output)

  exmap, input := input, input[(n+7)/8:]
  nex := 0 // number of exceptions
  for i := range n  
    if exmap[i/8]&(1<<uint(i%8)) != 0  
      nex++
     
   
  exceptions := d.scratch[:nex]
We can use the bits.OnesCount64 functions to count ones bits in the exception bitmap, 64 values at a time. For remainder blocks, the rest is processed 8 values (1 byte) at a time:
i := 0
for ; i+8 <= n/8; i += 8  
  xm8 := binary.LittleEndian.Uint64(exmap[i:])
  nex += bits.OnesCount64(xm8)
 
for ; i < (n+7)/8; i++  
  xmb := exmap[i]
  // Clear the bits which do not belong to the exception map:
  if rem := n - i*8; rem < 8  
    xmb &= 1<<rem - 1
   
  // Go compiles OnesCount32 into an intrinsic,
  // but not OnesCount8, so we convert to uint32:
  nex += bits.OnesCount32(uint32(xmb))
 
OnesCount64 uses a 64-bit register. For comparison, AVX2 SIMD instructions use 256-bit registers (= 8 uint32) and AVX512 SIMD instructions use 512-bit registers. In the following sections, we will first set up our build tags for conditional compilation to use a trivial SIMD instruction, then walk through an AVX2 and AVX512 SIMD kernel.

SIMD build tags Let s assume we have the following scalar code: constant.go:
package pfordec

func fillConstant(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
To increase throughput, we can use AVX2 instructions if they are available on the CPU on which the program runs, i.e. using runtime dispatch. We ll first rename fillConstant to fillConstantScalar (it s now the fallback path): constant.go:
package pfordec

func fillConstantScalar(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
Next, we ll supply two different implementations (constant_nosimd.go and constant_amd64.go), the latter of which is selected when compiling for GOARCH=amd64 with GOEXPERIMENT=simd (the latter will hopefully be dropped in a later version of Go). The nosimd variant just dispatches to the fillConstantScalar, which will likely be inlined:
//go:build !goexperiment.simd   !amd64

package pfordec

func fillConstant(output []uint32, val uint32)  
  fillConstantScalar(output, val)
 
The constant_amd64.go variant assigns the hasAVX2 global variable by doing a CPUID check and then jumps to the scalar fallback if !hasAVX2, i.e. the CPU is too old:
//go:build goexperiment.simd && amd64

package pfordec

import "simd/archsimd"

var hasAVX2 = archsimd.X86.AVX2()

func fillConstant(output []uint32, val uint32)  
  if !hasAVX2  
    fillConstantScalar(output, val)
    return
   
  val8 := archsimd.BroadcastUint32x8(val)
  i := 0
  for ; i+8 <= len(output); i += 8  
    val8.StoreArray((*[8]uint32)(output[i : i+8]))
   
  // use the scalar implementation for the last <= 7 elements
  fillConstantScalar(output[i:], val)
 
We can go one step further by conditionally compiling const hasAVX2 = true when GOAMD64 is set to v3 or higher (i.e. the amd64.v3 build tag is set). As a practical example from Debian Code Search, we currently need the following checks / dispatches:
code function vector instruction set GOAMD64
encoder bitpack256v AVX2 GOAMD64=v3
encoder exbitmap AVX512 GOAMD64=v4
encoder scan AVX512+VBMI+GFNI+BITALG n/a
decoder bitunpack AVX2 GOAMD64=v3
decoder bitunpack256v32 AVX2 GOAMD64=v3
decoder bitunpack256v32Ex AVX512 GOAMD64=v4
In DCS, the effect is measurably positive, but small.

The 256 uint32 vertical layout First, here is the layout explanation from my 2019 TurboPFor analysis blog post:
In regular (non-SIMD) bitpacking, integers are stored on disk one after the other, padded to a full byte, as a byte is the smallest addressable unit when reading data from disk. For example, if you bitpack only one 3 bit int, you will end up with 5 bits of padding. SIMD bitpacking works like regular bitpacking, but processes 8 uint32 little-endian values at the same time, leveraging the AVX instruction set. The following illustration shows the order in which 3-bit integers are decoded from disk:
The scalar implementation uses an array of 8 uint64 to process 8 values at a time:
func bitunpack256v32(input []byte, dest []uint32, bitWidth int) (read int)  
  mask := uint64(1)<<bitWidth - 1
  orig := len(input)
  var bits uint
  var acc [8]uint64 // accumulator: current+next bits
  for op := 0; op < len(dest);  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      for i := range 8  
        acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
        input = input[4:]
       
      bits += 32
     
    for i := range 8  
      dest[op] = uint32(acc[i] & mask)
      op++
      acc[i] >>= bitWidth
     
    bits -= uint(bitWidth)
   
  return orig - len(input)
 
The SIMD version also processes 8 values, but without a for i := range 8 loop! One difference is that we no longer have the luxury of using uint64 for acc (holding rest and current bits); because AVX2 registers only fit 8 uint32 (not 8 uint64). Instead, we split acc into rest8 and cur8.
func bitunpack256v32(fullinput []byte, fulldest []uint32, bitWidth int) (read int)  
  dest := fulldest[:256]
  if bitWidth == 0  
    clear(dest)
    return 0
   
  n := 32 * int(bitWidth)
  input := fullinput[:n] // tell the Go compiler how long the input is
  mask8 := archsimd.BroadcastUint32x8(uint32(1)<<bitWidth - 1)
  bitWidth8 := archsimd.BroadcastUint32x8(uint32(bitWidth))
  var bits uint
  pos := 0
  // var acc [8]uint64
  var rest8 archsimd.Uint32x8
  var cur8 archsimd.Uint32x8
  for op := 0; op < 256; op += 8  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      // acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
      next := archsimd.LoadUint8x32(input[pos : pos+32]).ReshapeToUint32s()
      pos += 32  // input = input[4:]
      cur8 = rest8.Or(next.ShiftAllLeft(uint64(bits)))
      // acc[i] >>= bitWidth
      rest8 = next.ShiftAllRight(uint64(uint(bitWidth) - bits))
      bits += 32
      else  
      cur8 = rest8
      // acc[i] >>= bitWidth
      rest8 = rest8.ShiftRight(bitWidth8)
     
    // dest[op] = uint32(acc[i] & mask)
    cur8.And(mask8).Store(dest[op : op+8])
    bits -= uint(bitWidth)
   
  return n
 
The SIMD version benchmarks about 3x as fast as the scalar version. Another significant speedup is to use generics for bit width specialization for this SIMD kernel so that bitWidth becomes a compile-time constant and the compiler can generate better code.

Positional Popcount For my TurboPFor encoder, I implemented the same techniques as described above:
  1. Bitpack full blocks with SIMD (AVX2)
  2. Gather exceptions using SIMD (AVX512)
  3. Use generics to specialize per bit width
These changes are sufficient to roughly match the cgo performance, but then Claude Fable 5 found another 2x speed-up on top of that! The key observation is that once encoding blocks is fast, the preceding step of scanning the input values to decide which block type to use becomes the bottleneck. Here is the encoder s main encode function, which first does one pass over the input values (scan) and then prices all different block types at all relevant bit widths (requires fast access to the scan histogram):
func (be *BlockEncoder) encode(dest []byte, vals []uint32, layout blockLayout) []byte  
  var stats stats
  scan(&stats, vals) // gathers statistics from every value in vals
  bitWidth := bits.Len32(stats.or)
  if stats.or == stats.and  
    return be.encodeConstant(dest, vals, bitWidth)
   
  n := len(vals)
  // bitpacking is the default, unless we find a more efficient block type.
  bestType := blockBitpacking
  bestB := bitWidth
  best := priceBitpack(n, bitWidth, layout)

  // Walk from high bitWidths to low: to break ties, we prefer
  // the encoding with fewer exceptions (for faster decoding).
  for b := bitWidth - 1; b >= 0; b--   // up to 32 iterations
    nex := int(stats.cnt[b])
    size := priceBitpackExceptions(n, b, bitWidth, nex, layout)
    if size < best  
      bestType = blockBitpackingExceptions
      bestB = b
      best = size
     
    // Over-approximate the number of VB bytes.
    vb := nex + // exceptions using 1, 2, 3, 4, or 5 VB bytes
      int(stats.cnt[b+7]+ // exceptions using 2, 3, 4, or 5 VB bytes
        stats.cnt[b+14]+ // exceptions using 3, 4, or 5 VB bytes
        stats.cnt[b+19]+ // exceptions using 4 or 5 VB bytes
        stats.cnt[b+24]) // exceptions using 5 VB bytes
    size = headerBytes + headerExBytes + payloadBytes(n, b, layout) + vb + nex
    if size < best  
      bestType = blockBitpackingVBExceptions
      bestB = b
      best = size
     
   
  switch bestType  
  case blockBitpacking:
    return be.encodeBitpack(dest, vals, layout, bitWidth)
  case blockBitpackingExceptions:
    return be.encodeBitpackExc(dest, vals, layout, bestB, bitWidth-bestB)
  case blockBitpackingVBExceptions:
    return be.encodeBitpackVBExc(dest, vals, layout, bestB, int(stats.cnt[bestB]))
  default:
    panic("BUG: bestType not implemented")
   
 
I ll show you a slightly shortened version of scan, the function which is the bottleneck:
type stats struct  
  // cnt[n] = how many values where bits.Len32(val)>n,
  // i.e. how many exceptions are required for bitWidth=n.
  // Padded so that cnt[b+24] is always in bounds.
  cnt [32 + 24]uint32
 

func scan(output *stats, vals []uint32)  
  for _, val := range vals  
    for b := range bits.Len32(val)  
      output.cnt[b]++ // b bits are not enough to store val


Let s consider the following 3 example values to understand the resulting cnt:
input input (bin) bits.Len32
23 0b0000010111 5
5 0b0000000101 3
666 0b1010011010 10
The resulting cnt exception count histogram would contain (cnt shortened to c):
c[0] c[1] c[2] c[3] c[4] c[5] c[6] c[7] c[8] c[9] c[10]
3 3 3 2 2 1 1 1 1 1 0
In words, this means that at bit width 10, we could encode all the values without any exceptions. But most values do not need 10 bits, so a bit width of 5 would be more efficient, but requires storing one exception. Encoding at bit width 4 requires 2 exceptions, and so on. The scan function above is intentionally kept simple for illustration. We can make it faster by moving the per-bit-width loop outside the per-element loop. The fast version still needs about 12 instructions per value. With SIMD, we can reduce this to by 8x to only 1.5 instructions per value!

The trick: smear masks enable positional popcount The trick is to turn each input value into its smear mask (imagine taking the first 1 bit and smearing it across the remaining positions). Here are the smear masks for our example:
input input (bin) bits.Len32 smear mask
23 0b0000010111 5 0b0000011111
5 0b0000000101 3 0b0000000111
666 0b1010011010 10 0b1111111111
Turning a value into its smear mask is computationally cheap: Go implements BitLen(x) (functions like bits.Len32) by calculating 32 - LZCNT(x). We can calculate the smear mask of a value with ^uint32(0) >> LZCNT(x), i.e. starting with a 32-one-bits mask and shifting it by the number of leading zeros. Now, to obtain e.g. cnt[4], we can count the 1 bits at bit position 4 of all input values. The POPCNT instruction counts bits very efficiently, but it counts one bits within a register, so it counts rows, not columns. Counting columns is called Positional Population Count. I found the following papers that describe positional popcount with SIMD:

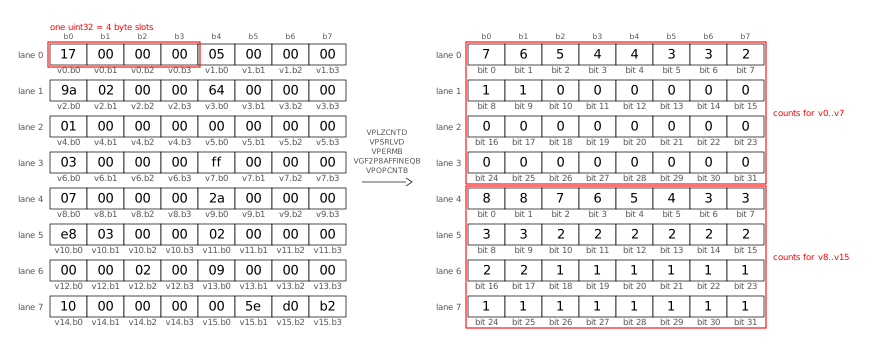
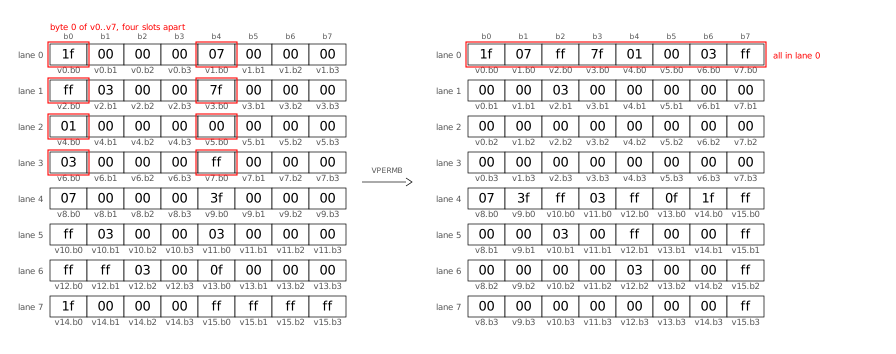
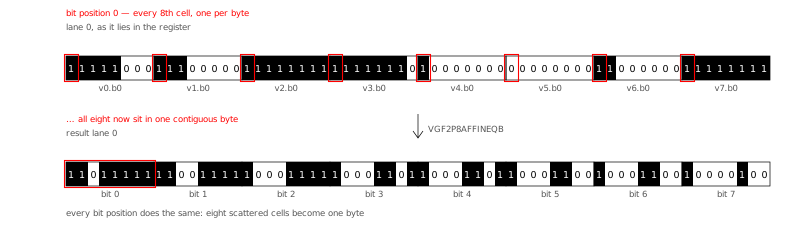
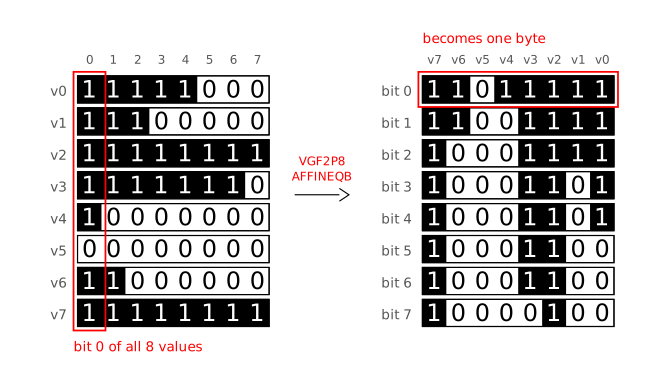
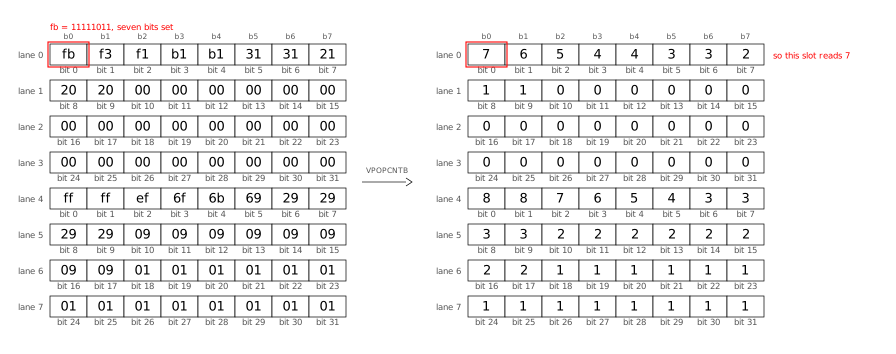
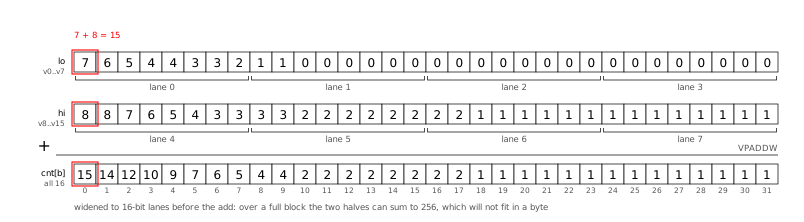
Positional Popcount: a visual explanation To understand the AVX512 implementation of positional popcount, I found it most helpful to visualize an AVX512 register (512 bits, i.e. 64 bytes). The graphic below uses the Uint64x8 layout, meaning it divides the register into 8 lanes of 64 bits (= 8 bytes) each. This illustration shows the whole process: how uint32s are loaded into an AVX512 register (all 4 of its bytes, in sequence) and where we end up, i.e. the 32 positional popcounts: Let s break down this process into its individual steps. First, we turn each loaded value into its smear mask as explained above. The VPOPCNTB vector instruction calculates POPCNT (1 byte) of 64 bytes at once, but first we need to shuffle the bytes inside the register: in load order, we have a full uint32 (4 bytes), followed by another uint32, per lane. First, we permute the bytes (VPERMB) such that all the first bytes of each value end up in one lane ( transpose the bytes ): Next, we transpose the bits using the GF2P8AFFINEQB instruction, which sounds scary but turns out to be quite flexible for bit manipulation of all kinds. The GF2P8AFFINEQB instruction is also the star of the show in Go s Green Tea Garbage Collector (2025). Here is the bit transpose, shown in the AVX512 register layout (see below for a different layout): I found it easier to understand the transpose step when arranging the 8 bytes of lane 0 from top-to-bottom (instead of left-to-right), because then it looks like a 90 degree clockwise rotation: Now we can use VPOPCNTB to count the bits in all 64 bytes at once: After all loop iterations (processing 16 values each) are done, we add the two groups (first 8 values, second 8 values) to obtain the 32 exception counts:

Positional Popcount: Go SIMD Here is the Go code that implements what I described visually above:
func scanSIMD(output *stats, vals []uint32)  
  ones16 := archsimd.BroadcastUint32x16(^uint32(0)) // 16 32-one-bits masks
  shuffle := archsimd.LoadUint8x64Array(&scanShuffle)
  units := archsimd.LoadUint8x64Array(&scanUnits)
  var acc archsimd.Uint8x64
  idx := 0
  for ; idx+16 <= len(vals); idx += 16  
    v := archsimd.LoadUint32x16(vals[idx : idx+16])
    // Replace all values with their smear masks.
    smear := ones16.ShiftRight(v.LeadingZeros()).ReshapeToUint8s()
    // Transpose: shuffle the bytes, then transpose the bits.
    matrices := smear.Permute(shuffle).ReshapeToUint64s()
    transposed := units.GaloisFieldAffineTransform(matrices, 0)
    // Popcount 64 bytes at once into the accumulator.
    acc = acc.Add(transposed.OnesCount())
   
  // Store the accumulator into output.cnt:
  // Widen the two groups of byte counts to uint16 lanes (so that
  // 128+128 = 256 fits), fold them into cnt[b] for b=0..31,
  // then widen again to the uint32 lanes of output.cnt.
  sum := acc.GetLo().ExtendToUint16().Add(acc.GetHi().ExtendToUint16())
  sum.GetLo().ExtendToUint32().Store(output.cnt[0:16])
  sum.GetHi().ExtendToUint32().Store(output.cnt[16:32])
  // scalar tail for the 0..15 remaining values
  for _, val := range vals[idx:]  
    for b := range bits.Len32(val)  
      output.cnt[b]++


Have a look at the commit introducing positional popcount to DCS for the full code (including shuffle tables and ISA checks) as well as the detailed benchmark results.

Go even faster? The SIMD optimizations I showed above beat the cgo TurboPFor library that Debian Code Search used before. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. Could we make my Go TurboPFor implementation even faster, to truly match the C speed? Yes! But also no. Let me explain:
  1. We could use more SIMD instructions to remove all code that still processes one value at a time. For example, in my encoder s encodeBitpackVBExc function. Or we could price all bit widths concurrently in encode. Or in the decoder s exception apply code path.
    But all of these SIMD instructions make understanding (and changing) the code harder, so I am cautious regarding which ones I introduce.
  2. A big part of the performance gap is due to Go s bounds checks. While it costs performance, bounds checking is great for safety, so I will not turn off bounds checking. The Go compiler eliminates a number of bounds checks when it understands it s safe to do so. One optimization avenue could be to make the prove pass in the Go compiler smarter to eliminate more bounds checks.
  3. When doing mid-stack inlining (proposal #19348) (2017), Go sometimes needs to put NOP instructions into the binary so that it can attach inlining markers. For dispatch-bound functions, these extra NOPs can measurable slow down execution.
  4. The Go compiler currently allows specifying the architecture (GOARCH=amd64) and microarchitecture (GOAMD64=v3), but not a specific CPU architecture (like AMD Zen 4). Therefore, CPU-specific workarounds for one vendor affect all the generated code. The specific one I encountered in my code is that the Go compiler emits XORL CX,CX before every POPCNT to break a false-output-dependency from the Intel Sandy Bridge Skylake era, which is unnecessary on AMD Zen CPUs.
    I suspect that Go intentionally does not offer this level of customizability.
  5. After all of the above points are addressed, what remains is better code generation in specific cases. To illustrate what I mean, consider the example of incrementing a loop variable, where Go re-derives an index every time:
    Go: POPCNTL; ADDQ DI,CX; LEAQ (base)(CX*4) (3 instructions)
    clang: popcnt; lea rax,[rax+4*rdi] (2 instructions)
    Depending on the specific case, improving the compiler might be easy or prohibitively complex. Often, such improvements are hard to measure conclusively.

Conclusion Go s SIMD support makes available in Go code without having to resort to cgo or assembly a powerful part of modern CPUs which allows speeding up the kind of computation that TurboPFor needs by an order of magnitude! I found it very valuable to use a coding agent (Claude Code, with Opus 5 and Fable 5 in this case) to help with the many tedious parts of such performance work (and still it took me weeks!). The LLM can read objdump output much faster than I can, can see patterns and correlations I might never identify, never becomes frustrated after a compiler error or runtime panic, and never runs out of patience to run one more experiment, as long as I give it measurable and reachable goals. The performance of the SIMD code which one can get from the Go compiler is pretty close to what a good C compiler like clang provides. The CPU performance counters show value decoding speeds of 7 instructions/cycle (IPC) on a machine where the maximum is 8 IPC. To me, SIMD support is a very welcome addition to Go.

4 September 2026

Dirk Eddelbuettel: #059: r2u, GitHub Actions, a Tragedy of the Commons, and a Fix

Welcome to post 59 in the R4 series. How did we get here: A initial words about GitHub. GitHub Actions provides (essentially unlimited) compute time. This further boosts a service already in a market-dominating position: GitHub1 as a code repository. Those of us old enough to remember the start of git (the program and protocol) may remember the extremely bare-bones initial hosting site repo.or.cz (launched in 2006). GitHub came two years later, and put an enormous amount of focus into design and user interfaces. To cut a long story short, GitHub won the services war. And with it git won the platform war. To a first approximation, everybody and everything is on GitHub.2 So the repository is already dominant.3 And then free compute was added. So given its scale and positioning, and its essentially free provisioning of free multi-core compute setups with generally decent connectivity, widespread adoption happened. And as is goes, some mischief is bound to happen. And it did. More on that below. A few words about r2u: r2u makes all packages on CRAN, i.e. the code repository network for R, install fast, reliably and easy on Ubuntu by making them available to apt, the native package manager. It is to our knowledge also the first and only time an entire open source programming repository is available in binary form with all dependencies resolved. It is going strongly: the last monthly use topped five million packages. See the r2u website for more. r2u and GitHub: For the first few years, builds for r2u were done locally on my machine, and then uploaded to the primary repositry r2u.stat.illinois.edu. I do not recall systemic outages or connection issues though occassional network timeouts were seen. Once we started to support arm64 (in addition to the default amd64) binaries, building those switched to GitHub Actions simply because they had runners for arm64 while I had no arm64 hardware. The experience of building packages (in bulk) was rather positive. So we investigated builds for amd64 too. If memory serves we first did this for either one of the semi-annual BioConductor updates. Before long, builds for amd64 followed meaning all of r2u was being built in GitHub Actions. During these builds, I would regularly encounter builds failures: cannot connect to r2u.stat.illinois.edu . I misdiagnosed this as a resource issue on the GitHub side, and consequently made (several) attempts at robustifying the builds via for example longer (download) timeout limits as well as checks for build failures and conditional rebuilds. Needless to say, and given what we know now (more on that below), this did not work. But it went on for a few months this spring and summer. What did work was to simply relaunch under re-run failed jobs . Given the distributed nature of GitHub Action this generally allocates to a different machine and address and succeeds. In the grand scheme of things a nuisance as we a need second run, but given the fourty (!!) concurrent jobs this tends to be quick. So a minor nuisance. This discribed the production side. On the consumption side, one prominent user of r2u, especially at GitHub, is our r-ci setup for continuous integration. It too could fail at times, and a simple re-run would fix it. Annoying, if addressable manually. Usage by others I cannot monitor so I can only assume that the random failure nature must have frustrated them too. Potentially a much bigger nuisance. As users were getting annoyed, some took action. Jeffrey Girard opened discussion topic #159 which contained a thorough investigation of his confirming that only amd64 nodes were affected. This had not been noticed before. Troy Hernandez set up a full harness with tests in an ad-hoc repo designed for repeated remote triggering. This also logged the IP addresses for success or failure. Through both these approaches it became (eventually) clear that the failures were limited to either certain (individual) IP addresses, or IP subnets. When taking the conversation back to network service at U of Illinois, we realized that the issue was in fact caused by a network policy at the university. And specific to GitHub. In fact, what happened initially were waves of port scanning attacks originating from GitHub IP addresses. As (essentially) anybody can run code there, bad actors can too. The response from the university side was reasonable and swift: Identified IP addresses were added to a null-router that (essentially) swallows traffic. And that was the cause of the perceived-as-random outages: Jobs that ended up failing at GitHub Actions were the ones assigned to addresses that have previously been seen as port scanning. Shifting production: Once this was confirmed, I investiaged alternatives. On the production side using different machines would help. So I tried blacksmith.sh, a competing alternate service offering faster runners as drop-in replacements for the GitHub Actions runners. This worked great, until I ran up against my free cpu minutes quota . In a mere two days (that were arguably overly busy as it was shortly after CRAN reopened after the summer break). Given that the service would not sponsor us a supported open source software project with sufficient quota, we moved off blacksmith.sh after two days. A first programmatic response: consumption-side: For the r-ci client side, it was straightforward to setup a check and subsequent workaround. When curl fails with a silent HEAD attempt at the primary repository failed, we take this to be caused by presence of a null-router entry for the IP we are on, and switch the apt setup to the secondary repository. Which may be slower, or at rare times unreachable itself but still provides a fine fallback when a node is prohibited from talking to U of Illinois resources such as r2u.stat.illinois.edu. Having used this for a few days in r-ci it seems to work. A second programmatic response: production-side: For the r2u builds, and given that blacksmith.sh would not grant most-favored status with sufficient free minutes, we switched our Docker-based setup to switch to the secondary when an initial probe fails. That was added last weekend, and appears to work just swimmingly. Another application to the fundamental theorem of software engineering: another layer of indirection can solve just about any problem. For completeness, the corresponding code is
webstatus=$(curl --head --silent --no-fail --output /dev/null \
                 --write-out "% http_code " https://r2u.stat.illinois.edu   true)
if test "$ webstatus " = "200"; then
    echo "The r2u repository is reachable."
else
    extip=$(curl --silent https://ipinfo.io/ip)
    echo "::notice::The primary r2u repository is **not reachable** from $ extip ."
fi
We run an initial curl test (without failing) and have it report the HTTP return code. 200 means no issue, all others are suspect here so we run a second curl query to obtain our external IP and log it. We use the same logic in another spot from inside the build container and use the else branch to switch apt to the secondary repository via sed call on the .sources file. Logging of bad IPs: On both our sides, i.e. production as well as consumption, we now also log the IP addresses of the failing nodes and will ask network security to remove these from the null router. If our jobs can be assigned to them it clearly shows the machines are part of the normal compute pool and are not doing anything nefarious at the moment. So they should be removed from the null-router list. We will see how that fares. Putting it all together: Providing a free resources can, sadly, lead to an a decline the service experience just as the tragedy of the commons analysis would predict. Restricting, or pricing use may be a stock answer but I for one am glad GitHub Actions is still free. But we need to do our bit of upkeep. Just as network security logs bad actors (taking advantage of the free resource) we should make an effort to unlist nodes no longer part of any portscan (or alike) swarm. For r-ci users, there is hopefully little to do (if you rely on the standard action). We do now catch a node that was assigned a continuous integration job cannot connect to r2u as we can test this easily (and cheaply). Pivoting to the secondary repository is a valid, and working, answer. Hopefully over time we can also work towards restricting the null-router list down to recent entries and fewer overall, thereby lowering the chance of gitting a bad IP. Eventually, we could also overly a CDN proxy to avoid the bad IP problem. It is something to consider. Summing up: We are still chuffed at how successful r2u has become, and how much can be done with GitHub Actions. Sadly, as we found out, there can also be a tax on letting compute happen there but as discussed in this note, there are ways to avoid it by pivoting to alternate repository source.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.


  1. Before we really get started, one clarification. GitHub and its services including GitHub Actions have been in the news lately as they suffered a number of high-profile outages. While also arguably a tragedy of the commons problem, it is not what this note is about. If you prefer to be enraged about GitHub services, or the (relevant) lack thereof, this may not be for you.
  2. The year is 2026 and politics is what it is, of course non-US alternatives emerged and will remain available and used. But dislodging established first-mover advantages will most likely take more than a (at least for now still-small) number of users unhappy for various (and sensible) reasons. We will see how this pans out.
  3. Entire essays (or book) can be / will be / have been written about the competitive situation, how GitLab did not make enough of a dent, how Gitea remained niche and of course now Codeberg. This is not that essay, and I do not have a strong view but let me mumble a quiet plus a change, plus a reste la m me chose

2 September 2026

Russ Allbery: Review: Too Like the Lightning

Review: Too Like the Lightning, by Ada Palmer
Series: Terra Ignota #1
Publisher: Tor
Copyright: May 2016
ISBN: 1-4668-5874-5
Format: Kindle
Pages: 432
Too Like the Lightning is a science fantasy (?) novel and the first of a four-book series. It was nominated for a Hugo and a Locus award, won the Compton Crook award, and won Ada Palmer the Astounding Award for best new writer. It was Palmer's first novel. Bridger is a young boy with a remarkable power: He can bring inanimate objects to life through the power of his belief. He is being hidden by the Saneer-Weeksbooth bash', a family (?) business (?) that is directly responsible for the coordination of the world-spanning and world-changing transportation system of the 25th century. Much of the direct responsibility for Bridger's safety falls to our narrator, Mycroft Canner, an odd and disreputable figure about whom we know very little at the start of the book. As this book opens, two things are happening simultaneously. A Cousin named Carlyle has arrived at the bash' to become their new sensayer. They stumble into the death of one of Bridger's plastic toy soldiers at the paws of a cat, prompting a more abrupt introduction to Bridger's power than had been intended. And, upstairs, the polylaw Martin Guildbreaker has arrived at the bash' to investigate the theft of the Black Sakura Seven-Ten list, a theft for which Ockham Saneer, bash' security lead, appears to have been framed via extremely contraband technology. Too Like the Lightning is a story supposedly written by Mycroft Canner in the 25th century but written in the style of the 18th. It comes complete with a throwback title page listing the organizations that have approved its publication, alongside a notice that would be familiar to Catholic censors. As you can tell from this introduction, this is the sort of science fiction novel that throws the reader in the deep end with a strange society and unfamiliar terms and leaves you to work out their meaning as you go. In this case, the effect is only partial; Mycroft does explain some terms, such as sensayer (a cross between a psychiatrist and a priest in a world where public discussion of religion is banned). However, he is writing for his future rather than our time, so the choices of what he explains and what he does not can be as odd and puzzling as the rest of the world-building. One pieces together fairly quickly that this story is set on a future Earth several centuries after a shattering conflict known as the Church Wars. Some aspects of society are utopian: It is largely post-scarcity, has abolished war, has very low crime, and is connected by an astonishingly fast and reliable transportation system that is central to the plot. Most aspects, though, are ambiguous, mixed, or just deeply weird. Geography-based political polities have been mostly abolished. Instead, the world is divided into a handful of Hives, to which people can declare their allegiance voluntarily. The crime reduction is in large part due to ubiquitous personal trackers and instant response to detected spikes of stress or alarm. Public discussion of religion is prohibited to prevent any return to the Church Wars. Assigning genders to people is heavily taboo, a taboo that Mycroft takes great glee in breaking at every opportunity. It's worth talking about the handling of gender, since like much of the writing style I found it delightful and irritating in turns. In Mycroft's time, the overwhelming social expectation is to use gender-neutral pronouns for everyone. Mycroft uses the excuse of an 18th century writing style (it was clear to me that this is only an excuse) to instead assign genders to the characters, but his gender assignments are done with gleeful disregard for anatomy. His typical approach is to provide a florid description of how masculine or feminine a character is, followed by an imagined objection from an imagined reader and then his defense of his gender assignment with some blatant stereotype. Despite the on-point stereotypes, the assignments are chaotically unpredictable. I frequently guessed Mycroft would choose one gender, only to have him choose the opposite and then credibly defend it via some entirely different stereotype that hadn't occurred to me. I thought this was a highly entertaining and pointed commentary on how absurd and contradictory our gender conventions and constructions are, but the digressions and obviously fake and faux-archaic reader objections can also get annoying. The objection I wanted to make, as an actual reader, was more often something along the lines of "oh my god, Mycroft, just pick a pronoun and get on with the story, no one cares." Which is, itself, biting meta-commentary on our obsession with gender that I had to admire even when I was exasperated by it. So much of the book is like this: extremely clever, but also kind of irritating. Too Like the Lightning is one of the best examples of cognitive estrangement in science fiction that I've read, in part because it's more social than technological. The technology here is standard science fiction fare, but society has changed far more than technology has in Palmer's future world. All (I think?) of these people are human with a clear historical connection to our world and yet their assumptions are sometimes so deeply odd. Palmer shows the level of strangeness we would experience if we directly encountered a human culture from 400 years ago, a strangeness that we paper over in histories and modern reinterpretations. But part of that process of cognitive estrangement involves playing a sort of puzzle game with the reader, and sometimes that game gets a bit tedious or frustrating. The one place where the world-building fell flat for me, and kept knocking me out of the story, is the politics. Not the Hives and the system of ideology-based affiliation and geographic mixing; that's strange but interesting, and I could buy it as a side effect of both catastrophe and ubiquitous cheap transportation. Not the complicated system of legal codes and exceptions and competing jurisdictions; that felt believably baroque in the way that complexity emerges in the friction in long-lived human systems. My problem was with the scale, or rather the lack of scale. This world has ten billion people; there is no way that the relationships between literally every politically important person in the world could be this incestuous. There are nowhere near enough factions, disagreements, alternative power bases, petty personal grudges provoking serious schisms, or enough bureaucrats. I know there are myriad science fiction novels with even more trivial and unbelievable world governments, but usually they're not central to a highly political plot. Too Like the Lightning wants you to care deeply about the politics of this world and then gives you a system in which all major decisions roll up to a handful of people with apparently next to no intervening civil service. Also, why is there so little redundancy? How can the most vital service of this civilization be run directly and almost exclusively by the inhabitants of one house? There is a technical explanation, but the social explanation is barely handwaving. This is not how institutional trust generally works; even with vast multinational high-capital near-monopolies such as cloud computing, there are three major players and innumerable smaller ones. Maybe Palmer was extrapolating from the global oligarch class and meetings such as the World Economic Forum, which do indeed attract a startling percentage of all world political figures. The problem, though, is not the surface of occasional gatherings or staged events seen early in this story. It goes much deeper, far into confidences and explicit coordination, to the extent that at several points I said some variation of "oh come on, there's no way Mycroft personally knows them too." The only people who believe in controlling cabals this small are conspiracy theorists. This is simply not how humans work when this much power is at stake. Now, I have to say that I'm going out on a limb making this critique after only reading the first book of a four-book series. This is absolutely the type of work for which my reaction and objections could be an intentional effect created by Palmer in order to spring some unexpected justification on the reader in book two or three. It's clear that there is some massive social upheaval on the horizon in this series, and something very strange is going on with one of the characters and their hold over other people. Perhaps the reader disbelief is setting up that upheaval. If so, hats off to her, and that's one of the perils of reviewing books as I read them. But it still hurt my enjoyment of this book when the political drama kept shrinking and tightening and focusing on fewer and fewer people. It felt frankly unbelievable for the political universe of this highly political book to be this claustrophobic. I wanted it to expand into the space that should be available to an entire world teeming with fractious and complex humanity. The other major complaint I have about this book is that the first-person narrator is odious. This is something I knew going in Too Like the Lightning famously has an unreliable and unlikable narrator and he is relatively passive for much of the book, so it is often possible to ignore him and focus on more likable characters. I don't necessarily mind an unlikable or unreliable narrator in this type of story. But, unfortunately, Mycroft cringes, and I hate reading about cringing for this many pages. His primary mode of interaction with people is obsequious, performative fear with a weird, distasteful edge of manipulation. Again, I think this is entirely intentional on Palmer's part; we learn some of the reasons behind it by the end of this book, and I'm sure we'll learn more in future books. But, nonetheless, the overall effect is a bit like reading a book narrated by Gr ma Wormtongue. I can appreciate the narrative role of that character without wanting to spend this much time in his head. I have very mixed feelings about this book. The overall construction is brilliant; it's a beautiful puzzle of oddity and alienation that provides great fun for the type of science fiction reader who wants to work out the rules of a strange society without a lot of infodumping. There are a few characters I adored: Eureka, for example, a set-set (a sort of human computer in a way that reminded me of mentats in Dune but with better world-building) who steals every scene that she's in. I was very invested in the world-building, fascinated by the Utopians, and want to learn more about what's going on. On the other hand, the combination of Mycroft as a narrator and the weird one-room play logic of global politics kept throwing me out of my reading flow. It took me about a month to finish this book. The science fiction and political fiction aspects of the story interested me more than Bridger and whatever is going on with J.E.D.D. Mason, and I'm worried that my least-favorite aspects will be central to the rest of the story. I was enjoying a smaller percentage of the scenes by the end of the book than I was at the start, which is not a great sign. And yet, the ending absolutely worked on me. I don't want to stop here! I will probably pick up the sequel, but I think it's going to take me a while to brace myself for it. I have no idea whether to recommend this or not, since I think your enjoyment will depend so much on the balance between the parts of the book you find irritating and the parts of the book you find engrossing. I'm fairly sure most readers will find a little of both, but I have no idea how to predict their relative weight. If you like cognitive estrangement, this is great; I understand why so many science fiction reviewers rave about this book. If you need to like the first-person protagonist, uh, good luck. Maybe you'll have more tolerance for cringing than I do. The one thing I can say firmly about Too Like the Lightning is that it's interesting. It may be worth reading just to see how people are stretching the genre, even if you end up not liking the effect. But be warned that this book does not so much end on a cliffhanger as suddenly stop at some random, nondescript point on the road leading to the cliff. The ending is deeply unsatisfying; you will need to read more if you want to understand what's going on. Followed by Seven Surrenders. Rating: 7 out of 10

1 September 2026

Russ Allbery: Review: Last Chance to Save the World

Review: Last Chance to Save the World, by Beth Revis
Series: Chaotic Orbits #3
Publisher: DAW Books
Copyright: April 2025
ISBN: 0-7564-1971-9
Format: Kindle
Pages: 133
Last Chance to Save the World is a far-future science fiction caper novella and the conclusion of the trilogy that began with Full Speed to a Crash Landing. This is a direct sequel to How to Steal a Galaxy, picking up right after that story leaves off, but you don't have to remember the details to enjoy this installment. Ada has finally achieved a (temporary, contingent) alliance with government agent Rian White by convincing Rian that some things are more important than Ada's disregard for the law. She's going to need his help. They have once chance to save Earth from a new and even more malicious round of capitalist environmental blackmail, and it's going to require Rian's security access as well as all of Ada's heist skills. But first, a visit with Ada's mother, who lives in an old watchtower on Malta and keeps pigeons. Each entry in this series has been a little shorter than the last, and Last Chance to Save the World is definitely a novella. This is a great length for a heist story: enough room for some setup and a couple of major plot twists, but short enough that the story can maintain a headlong pace. Even in the third novella of a series and a novel's worth of time in Ada's head, Revis has one major surprise for the reader left. And, as usual, there's a lot of misdirection, sarcastic commentary, and the delightful competence of a protagonist who puts considerable professional effort into being underestimated. The bits with Ada's mother were great. This is the first time we've seen Ada have significant interactions other than her flirting and teasing of Rian, and I loved seeing a different side of her. The heist itself was satisfying, although not quite as good as How to Steal a Galaxy. Ada gets to throw a few more verbal daggers, but there are more events in this installment and therefore more action and less dialogue. Ada's commentary and dialogue is still my favorite part, though.
For all that Rian says I like to break the law, it should be illegal for any one man to be both this dumb and this rich. It's astounding, really. Any of his employees could run circles around him, but it doesn't take brains to buy stuff. Strom Fetor sees nothing clearly except profit margins.
There is, of course, even more flirting and semi-fake romance. Those were not my favorite part, mostly because while it's obvious what Rian sees in Ada, it baffles me what Ada sees in Rian. I know the star-crossed romance between the law man and the charismatic thief is an old fictional trope, but I found it very hard to justify Rian's continuing commitment to his law and government given the clear facts of this setting. Up until this novella, one could excuse Rian as the sort of person whose belief in order, stability, and rules combines with possibly excessive optimism to create a belief in an imperfect system. But here, Ada has finally convinced Rian that some great evils truly will not be fixed by following the rules. He's onboard, but somehow in a way that leads to precisely no reconsideration, soul-searching, or breach in his commitment to defending a clearly corrupt and failing political system. My objection is not that this is unrealistic; sadly, it's very realistic. My objection is that Rian is dumber than a bag of hammers, I don't like reading about his blind allegiance to a bad system, and I do not understand how that goes with the sexy feelings. I'm sure this is my lack of understanding of physical affection overriding common sense, and Ada is at least not a complete idiot about her attraction. But I felt like this novella expected me to like Rian as more than a foil for Ada, and I very much did not. That knocked a point off my enjoyment of this entry, but the heist is great, the politics are interesting, and the climax was very satisfying. This is not quite as good as the middle book of the trilogy, but it's a satisfying conclusion. If you liked the previous entries, you'll want to read this one for the conclusion. Last Chance to Save the World resolves the main plot driver of the trilogy, but there's a lot of space for more sequels. If they materialize, I will probably keep reading, although I hope someone knocks some sense into Rian. Rating: 8 out of 10

31 August 2026

Russ Allbery: Review: The Hands of the Emperor

Review: The Hands of the Emperor, by Victoria Goddard
Series: Lays of the Hearth-Fire #1
Publisher: Underhill Books
Copyright: January 2019
ISBN: 1-988908-15-9
Format: Kindle
Pages: 739
The Hands of the Emperor is a self-published political fantasy novel. It's the recommended first book (although not the first published book) in a complicated set of interrelated series. I was not able to definitively confirm that Underhill Books is Goddard's self-publishing press name, but the press does not appear to have an Internet presence apart from Goddard's books and her books appear to be using the standard self-publishing channels. Cliopher Mdang is the personal secretary of the last emperor of Astandalas, the magical heart of Zunidh, a man worshiped as a god. The emperor's word is absolute, his magic supports the health of the entire world, and he cannot be physically touched without risking physical damage and severe political and religious punishment. Cliopher is one of the emperor's closest associates, but the distance between them is still vast. It therefore represents a terrifying and dangerous breach of etiquette for him to suggest the emperor may enjoy a vacation on a tropical island near Cliopher's remote home. The emperor's acceptance of the invitation is even more startling. The emperor has opinions about his life as the emperor that no one had guessed. Cliopher has not assimilated as completely into the bureaucratic machinery of the empire as it first may appear. And Cliopher's family have vastly misunderstood the nature of his role in the emperor's government. I find the marketing blurb for this book unfortunate since, at least to me, the emphasis on physical touch and intimacy implies that The Hands of the Emperor is a romance novel or at least has significant romantic elements. I've been aware of this book for years but put off reading it because I wasn't quite in the mood for that story. This is not a romance novel; there is no romance in this book whatsoever. It is a political fantasy, both in the sense that it is set in a secondary fantasy world with magic and (apparently) some form of interplanetary travel, and in the sense that it is a fantasy of governance. When I say that this book blew up in certain corners of the Internet during the pandemic, I think you will still underestimate the passion of its advocates. I heard about this book constantly, in a way that reminded me of Kushiel's Dart and the time when fans of Jacqueline Carey would bring her up in every fantasy conversation, or when we created a Usenet newsgroup for The Wheel of Time mostly to get the voluminous conversations off of the regular SFF newsgroup. I'm one of those mildly contrarian people for whom that degree of enthusiasm is a little off-putting, which is another reason why I resisted buying a copy for years and only read it in 2026. It's delightful, although also a bit embarrassing, when the book everyone was in love with turns out to be just as good as everyone said it was. I adore stories about friendship, and this is one of the best stories about friendship that I've ever read. It is a very, very slow burn, but I also thought the first three quarters of the book was exquisitely paced. There were long sections where not very much was happening, and yet I couldn't put the book down because there was so much subtle character work just beneath the surface. Almost all of the novel is told in tight third person from Cliopher's perspective, and I thought that was an excellent choice. Neither Cliopher nor the narrator comment on things that Cliopher finds obvious, which is both immersive and critical to the pacing. There are discoveries for the reader throughout the book, the sort of discoveries that make pieces fit together satisfyingly in retrospect, and the reader stays sufficiently ahead of the misunderstandings of Cliopher's friends and family that one also gets the joy of watching other people discover things that one figured out a hundred pages earlier. It helps that I truly liked nearly everyone in this book. There are no real villains, only a few supporting characters whose role is to be irritating or corrupt. If you're looking for a lot of conflict and drama, you may want to save this book for a different mood, but if you're in the mood for a varied collection of fundamentally good characters working methodically through the complexities and obstacles of politics and social systems to improve the world, there are few books I would recommend more. Goddard achieves one of the hardest tricks of slow burns: steady forward progress that does not rely on reversals, misunderstandings, or the friendship equivalent of the third-act breakup. This book spends 700 pages building towards a climax that managed to be worthy of all 700 pages without ever annoying me with artificial obstacles, and that's quite a feat. I've not said much about the details of the plot. There is one it's not just character work but I think this book benefits immensely from going in as blind as possible. I found the twists and turns and growing revelations so deeply satisfying that I don't want to rob any other reader of the experience. The fantasy world-building is intriguing but a bit unsatisfying because it is so unexplained. We get a few details of the magic system, but since Cliopher has no magic, he isn't that interested in the details. There is a catastrophic magical event in the world background, and we learn some of the details of its practical effects, but the nature of the world before the cataclysm is so obvious to the characters that it's never explained. I'm not even certain that this civilization is interplanetary; that feels like the implication of how characters talk about multiple worlds, but the method of travel is left entirely undefined. This might be frustrating to some genre readers, but I personally enjoy books where the world-building is a bit mysterious. It's a good reason to read more of Goddard's books set in the same universe. This was my favorite of the books I've read so far this year, but I do have one caution and a couple of caveats. The caution is that Cliopher comes from an island culture based heavily on (I think) Polynesian cultures. That culture is very central to the story and is treated with considerable respect, but I still get a bit nervous when a Canadian author from Nova Scotia with an academic background in European medieval studies writes a story focused this deeply on a non-European culture. Nothing about her portrayal seemed off to me (although there is a very clunky and ham-handed scene about a different native culture that worries me), and for all I know she has family background or other connections to the culture she is borrowing from, but it's possible I missed serious problems. The flip side of that caution is that I'm delighted to see a fantasy author drawing on a non-European culture, and I thought the clash of cultures was very well-handled. The first caveat is that the story is very focused on good governance, but both the process and the details of that governance are not going to satisfy someone reading primarily for the politics. The policies and reforms are very standard 21st century progressive material that felt a bit out of place in a quasi-medieval world with magic and airships. Their implementation is not the point of the story, and is therefore heavily backgrounded, but that means Goddard barely mentions the inevitable practical implementation difficulties and does not discuss how they're overcome. The world structure also means that Goddard can make use of the favorite cheat of political reformers in fiction: Absolute monarchy lets you enact a political agenda without having to do the hard and frustrating work of persuasion or political (or actual) warfare. This objection is not entirely fair because we do get some memorable scenes of persuasion, but the political portion of the plot is unrealistically devoid of setbacks or resistance that goes beyond token arguments. Whether this will bother you will depend heavily on what parts of the book you'd rather focus on. I can see why this was such a popular pandemic read: The Hands of the Emperor is focused tightly on the joy of competent people fixing things and does not focus on the arguments, division, or polarization. The heart of the book is the friendship and characterization of some deeply admirable people, and the political reform is incidental background material. I suspect this is the right choice for readers who aren't political junkies, but I kept having the niggling objection that the politics felt a bit too pat and simplistic. Goddard stressed that the characters were investing considerable effort, but even still, it is not this easy to change the direction of a political system and idealistic plans usually do not work out this neatly. The second caveat is that, as previously mentioned, I thought the pacing was excellent for about three quarters of the book. Goddard is building towards a grand climax, and I think she built a little too much and tried to make the climax a bit too grand and risked over-egging the pudding. That made the payoff feel a bit belabored to me. I still enjoyed it, and parts of it are wonderfully emotional, but I think the ending might have been stronger if Goddard had dialed Cliopher back just a little and tightened up the climax a touch. That said, this book fully commits to being a sprawling slow burn and that's part of its appeal, so it's probably better for Goddard to err in that direction than it would have been to cut short the denouement. This is one of those books that I'm not sure would exist without self-publishing. It's a little too long, a little too political in the wrong ways, a little too devoid of the typical sorts of conflicts expected in a fantasy book, and too determined to be its own peculiar thing. I think it would scare off publishers. Unlike some self-published books, though, I didn't notice any obvious editing flaws or lack of polish. It's one of those glorious novels that is so very much its own type of story that it provides an experience that would be hard to replicate with another book. I was so deeply satisfied by this book. It's a wish-fulfillment political fantasy full of diligent restraint and competence porn, so you have to be in the mood for that. This is not the book to read when you're feeling cynical, or are in the mood for action and high drama. But if you're in the mood for a long, slow, open-hearted story of friendship that offers the fantasy of giving truly good people enough power to be effective, I highly recommend this one. Followed in the direct sequel sense by At the Feet of the Sun, but there is a very complex story progression in this world that I think I'd have to read all the other books to understand. This was such a satisfying and complete experience that I'm not in a hurry to figure out which Goddard book to read next, but I'm sure I'll be returning to this world at some point. Rating: 9 out of 10

Valhalla's Things: 3D Models

Posted on August 31, 2026
Tags: madeof:atoms, madeof:bits, craft:3dprinting
A lucet fork: a two pronged device with a handle with yarn wrapped once around each fork and a knot forming in the middle, out of which a piece of cord is growing. The working yarn is in a ball nearby.
Note
this article had been almost completely written before the weekend, and I decided I might as well focus on stuff I m creating, finish and publish this.
For many years, I ve been sporadically dabbling in creating 3D models; for reasons that are probably obvious to anybody who knows me I used OpenSCAD and saved my projects in git, which made them at least somewhat public. However, SCAD sources in a git repository aren t the most convenient way to get a 3D model, and for a long time I never had a consistent way to publish binaries for my models: some have been added to my old website, some to my craft patterns site, but it was always an ad-hoc thing. Then two things happened more or less at the same time. One was me finding out that slic3r had been definitely removed from Debian. I know it was going to happen, and I postponed thinking about it as long as I could, but eventually I had to move over to PrusaSlicer, whose packaging is in better shape. The other was that lately I ve been doing a bit of lucet, and talking about it online, and I m really happy with the shape of the lucet I ve designed and printed, the one in the picture at the beginning of this post, and while there are other models available, I wanted to make it more convenient for people to also get mine. Since PrusaSlicer did look still maintained upstream in a way that doesn t feel like at danger of immediate enshittification, I considered making an account on Printables, and asked on the Fediverse if somebody knew something bad about the company behind it, as it s getting more an more common these days. Apparently nobody did, but in the thread somebody mentioned that there is a federated platform for publishing 3D models, called manyfold ! I didn t want to add self host a(nother) web thing , especially not one that is not in Debian, to my list of projects, but I did create an account on a public instance: @valhalla@3dprint.social <https://3dprint.social/creators/valhalla> and started publishing models, both a selection of old ones and a few new ones I designed in the last few days, since I was in a 3D printing mindset. Then I decided that since nobody had serious objections to it, I could also create an account on printables, as that s probably more easily accessible to the general public. I have been somewhat slower at publishing models on the latter, but I expect that eventually most of what I design will end up on both platforms; I still have a few older models I want to add, and a few ideas for new models to make, then I guess stuff will slow down, and only get new ones now and then, as that s how I usually approach hobbies. Of course, the self-hosted git repository is not going away: that s still the canonical location for my models, with all of the non-self-hosted options as a convenience option.

27 August 2026

Gunnar Wolf: As far as LLMs go in Debian, I think that 936241857

I believe that, in the context of Debian voting, we are better off when we know the opinion of our peers, however, since the 2022-001 vote, it is no longer the case. Still, some DDs have disclosed the way they are voting on the 2026-002 General Resolution currently in progress, regarding LLM usage in Debian. So, here goes my vote and reasoning as briefly as possible. This is the ballot I sent to devotee, the Debian Vote Engine:
-=-=-=-=-=- Don't Delete Anything Between These Lines =-=-=-=-=-=-=-=-
d69f9187-ed2f-40b6-a2eb-4211d3f84d86
[9] Choice 1: Ban LLM contributions from Debian via Social Contract
[3] Choice 2: Allow AI-Assisted Contributions with conditions
[6] Choice 3: Reject LLMs as far as practical, update Code of Conduct
[2] Choice 4: Accept AI contributions for Debian specific work
[4] Choice 5: Responsible Use of Generative AI
[1] Choice 6: A cautious approach to generative AI
[8] Choice 7: Debian is created by humans
[5] Choice 8: Avoid the use of LLM: climate destruction is a deal breaker
[7] Choice 9: None of the above
-=-=-=-=-=- Don't Delete Anything Between These Lines =-=-=-=-=-=-=-=-
This is the first time I can recall I delay my voting until after receiving the final call for votes (the vote will be over two days from now). I had some participation in the discussion, so I guess my position will be of no big surprise to anybody. I was also a seconder for choices D and F (4 and 6 in the vote text). This does not necessarily mean I believe they are the best (although I did rank them as 2 and 1, meaning I do): sometimes you agree a given text needs to be in the ballot, and second it even though you don t intend to vote for it. LLM? Ranking this ballot was a mess due to the complex array of options it encodes. I warmly thank Lucas Nussbaum for coming up with the LLM usage in Debian: ballot option comparison (URL shown with my particular ballot ordering). How do you read a complex Debian ballot like this one? I rank with [1] my favorite option, [2] for the next one, etc. We can encode options to be tied (i.e. setting more than options to the same value), and we can implicitly push options to the worst position by leaving them blank (so, with[ ]); I chose not to do any of those. What were my voting guidelines? First, I don t want anything banning or that threatens with disciplinary action, so I push them below the special none of the above marker. Second Some time ago I published a review in my blog (and in Computing Reviews) about the unfeasibility and unfairness of detecting LLM output on students assignments. I strongly believe we ought to appeal to the human responsibility and professionalism in all Debian contributors. This is the reason I proposed this amendment paragraph, that was accepted in choice F (6), which I ranked as my favorite:
The Debian project has always recognized the commitment and
professionalism of its members. All contributions are under the
responsibility of the Debian Contributor making it, no matter the
technology they have behind. We trust all Debian Developers,
Maintainers and Contributors will continue to uphold the high quality
values that have distinguished our project from its onset.
Other than that I do not consider myself to be in any way an LLM fanboy nor anything like that. I distrust and dislike the excessive use of this technology, and continue to warn about the dangers and bad points of its abuse. But in my day-to-day professional work, I am also starting to rely on it for some tasks. I recognize it needs a lot of human oversight and lets call it hand-holding to produce anything worth it, at least in my experience. But I do benefit from it and always disclose its use to people who might be affected by it. I would like Debian to adopt such a stance. Of course, I recgnize proposal H/8 as important (Avoid the use of LLM: climate destruction is a deal breaker). Some people have argued it s not bad at all. I do not buy such claims: LLMs are f*cking expensive to train. But training can be seen as a once-per-model cost, and fine-tuning a good model to be run locally can be really worth it. It still pains me somewhat, but I cannot push this option higher than its #5 position in my list.

26 August 2026

Ian Jackson: Debian LLM GR - Summary of the options

Debian LLM GR - Summary of the options Introduction LLMs have finally made it to the ultimate stage of Debian s governance processes, a General Resolution of all the project s full governing members (DDs). There are a lot of options on the ballot, and they all have a different structure and approach the question in a different way. It can be hard to see the wood for the trees. I have made a summary table to try to capture the main differences, both in effect, and sentiment. A plea to the undecided voter Suspending briefly my attempt to be neutral: Before voting, I encourage you to read the passionate rationales in options H and A, or at least the summary in my option C. Few of the LLM defences in the discussion threads, and none of the LLM-positive proposals, provide answers to any of these profound ethical concerns, many of which ought individually to be a deal-breaker. Instead, these crucial questions are simply dismissed or even ignored. Some will tell you we should keep politics out of software but as we can see in the world around us, software is political - now more than ever. Debian s mission is a highly political one: developing a fully-free operating system, and defending its freeness as we do, is far from neutral! And of course many of LLMs harms affect Debian directly. Table
A G C H F D B E
LLM harms Robustly discussed Discussed Robustly summarised Robustly discussed; especially re climate Summarised Accepted as inevitable Disregarded [1] Ignored
Direct contributions of LLM-generated code Forbidden Forbidden Strongly discouraged Strongly discouraged Discouraged Permitted Permitted Permitted
Direct use of LLM output in communications (bugs, mailing lists, etc.) Forbidden Forbidden Forbidden (with possible exceptions) Strongly discouraged Discouraged Permitted Permitted Permitted
LLM use where LLM output does not end up in the code/message Forbidden No position, so permitted Strongly discouraged Strongly discouraged Discouraged Permitted Permitted Permitted
Disclosure of LLM use LLM use forbidden LLM use largely forbidden, no further disclosure requirement Disclosure required Disclosure encouraged Disclosure encouraged Disclosure required Disclosure required Undisclosed LLM use is OK
Use of LLMs by upstreams Condemned Not recommended
Positive statements about LLMs Here to stay Moderate Strong
Notes Ordering I have tried to present the options in semantic order, with most LLM-negative proposals to the left, and the most LLM-positive to the right. I have not quoted the one-line titles for the options. These have generally been provided by the proponents of each option, and, unfortunately, some of them are IMO quite misleading. Note that, unfortunately, the voting software likes to assign numbers to options but also to preferences. Be mindful of this possible confusion when casting your vote. For clarity I quote only the option letters. Upstream LLM code contributions Some of the proposals acknowledge the uncertain legal status of LLM output. But all of them implicitly or explicitly assume that LLM output is or can be DFSG free. So none of the proposals forbid upstream projects with LLM-generated contents. None of the proposals would require us to go back to pre-LLM versions of the upstream projects we use, and attempt to fork and maintain them. I very much think there is room in the world for people to try to do that, but I don t think the Debian project can be that effort. Given that the conclusions are the same in each case, whether the matter is discussed does not seem to me to be a significant difference. I have therefore not included a column for it. Ability of individual teams to set their own rules My proposal has a specific paragraph (7) explicitly permitting teams to set a no LLM policy. The other proposals do not discuss this point specifically. During the discussion, it seemed that most participants agreed that even options which explicitly permit LLM use generally do not prevent a team from setting its own more restrictive LLM policy. I have therefore not tabulated this aspect. Exceptions and nuances Few of the permissive texts are absolute or unconditional. To summarise I have necessarily left out some nuance. So for example when an entry says permitted , that generally means permitted with conditions which are believed by LLM users to be readily satisfiable (for example, DFSG-compatibility - see above). [1] Footnote re proposal B Proposal B does mention that there are concerns about LLM use. But it fails to make an explicit statement about whether these concerns are justified. It then proceeds exactly as if they are not justified. IMO disregarded is a relatively mild term for such a rhetorical technique.
Edited 2026-08-18 09:02 UTC to make the proposal letters in the table be links; 2026-08-26 09:11 UTC to fix typos.


comment count unavailable comments

24 August 2026

Matthias Klumpp: Sovereign Tech Fellowship for Freedesktop Tasks

In 2025 I was honored to be selected for the first cohort of Sovereign Tech Fellows, a program by Germany s Sovereign Tech Agency to improve the resilience of the open source ecosystem by supporting maintainers directly (complementing their existing support for larger FOSS organizations). Back in 2025, I was only working very limited hours however, this has changed in 2026.

For the second half of 2026, I am working again as a Sovereign Tech Fellow, but this time with significantly increased hours. After finishing my PhD, I do have time now for new tasks (and new jobs!), and the fellowship presents an amazing opportunity to really advance projects that I maintain or am part of. This also has a very nice effect on contributors and bug reporters, as their feedback gets addressed a lot faster. With some luck, this ultimately will help finding new (co)maintainers for projects as well (although in the age of AI, a lot of how open source used to work is much more uncertain, but that is a matter for a different blog post).

The fellowship is time-limited, so I am intending to make the time I currently have count!

So, what s planned?

I am involved in many projects, but three of them will be getting attention as part of the fellowship. I know I am notoriously slow at blogging, but expect more details on each of them very soon. Here s an overview:

Freedesktop.org, Specifications and Organization

I maintain the Freedesktop Specifications, which is an area of Freedesktop that has traditionally been a bit chaotic. This worked in the past, because Freedesktop was never intended to be a formal standards body, but more a shared space where people could throw a lot of code and ideas over the wall and see what sticks and what people can collaborate on.

While I very much love the spirit of this and want to keep it in some form, we definitely would benefit not just from more formalization and better procedures, but also from better organization of the specifications in general. A lot of conflicts can be avoided by that. I will work on improving procedures, crunching through the (lots!) of pending bug reports and MRs, and to make the specifications site better searchable and accessible (similar to how Mozilla s MDN presents information, but I am not sure if we will get quite that far). I also intent to add a compatibility matrix for specifications, so if a desktop opts out of any one of them (or does not implement them yet) that fact is documented and authors of applications know what they can expect. This will allow us to move a lot faster and avoid a lot of conflict, because there is no implicit assumption that everybody will implement everything anymore (which has never been quite true anyway).

Hopefully, this will ultimately result in a Freedesktop that is both a lot more useful for application authors who want to bring their project to Linux, as well as developers of desktop environments who need to see which specifications are available and which ones are current.

In addition to that, I have also worked on a Freedesktop.org website refresh, which is pretty much done in its first iteration (pending sysadmin action). The aim there is to have a more official website, separate from user-contributed wiki content, that showcases what Freedesktop is and which projects are using it for hosting. Once the new website is live, I will also review every page again, archive dead projects in their own section and reorganize the software and specifications directory. Those sections are severely outdated and are missing recent efforts from the community, while still containing long-dead old projects (remember HAL?  ).

AppStream

A lot of extra maintenance work will be (has been!) done on it. This includes things such as JPEG-XL support (blog post soon), sandboxed media processing, support for newer specification additions, better OARS integration (and potentially migrating it to fd.o infrastructure), improvements and API stabilization for libappstream-compose and a lot of bugfixing and resolution of issues found by AI code review.

AppStream was originally designed to parse only trusted data from vetted Linux distribution sources this is no longer the case in today s world and in the way Flatpak uses it, so we need to increase resilience of the project.

I am also exploring a project that could vastly improve search accuracy for AppStream. Stay tuned for that.

PackageKit & System Upgrades

Many years ago, people thought we would all migrate to atomic Linux distributions and slowly not need PackageKit anymore. This has not turned out to be the case, and there are still plenty of reasons to use a package-based OS, especially in development environments. At the same time, PackageKit has been basically the same for years, and its older architecture is beginning to show. It being a daemon who s literal job it is to modify the entire system also makes it one of the most security-sensitive components that a Linux system can have, while simultaneously making it near-impossible to sandbox.

My plan is to create PackageKit 2.0 by building on the great foundation of PackageKit 1.0, but modernizing it. This will include simplifying its code and removing a bunch of features that have no more use in modern desktops, while also adding some features that PackageKit never had but that would be useful to expose to frontends (still no to interactivity an terminal-progress forwarding though!). PK 2.0 will also allow me to solve a few design issues that have been worked around in the past, by replacing them with better solutions. This will be a painful transition, as PackageKit 2.0 will break all interfaces PackageKit has and those interfaces have been frozen for more than a decade. However, I do fully expect this change to be worth the effort.

In addition to that, I intend to look into the offline-update procedure again and improve it. The current multi-reboot operation comes with downsides, that newer systemd features such as soft-reboot can alleviate. The end result should be a much smoother, less annoying offline-update experience for users (I especially want to get rid of updates running on system startup, which I consider quite bad from a usability perspective). The new behavior is in the early drafting stages and may need direct support from systemd. I will share more about it once I can.

That s a lot of tasks!

Yes! I will see how far I get. I am moving project-by-project though, to allow me to focus on one project at a time, rather than scattering my attention continuously. Amazingly, this means that the major tasks for AppStream are already almost done, and we are nearing the 1.2.0 release. AppStream got priority, because the new Freedesktop Flatpak runtime will be released soon, and because I want FlatHub/Flatpak to have access to the new AppStream release sooner. Freedesktop and PackageKit are next on the task list.

Either way, a lot of progress is coming if you have any feedback or want to help out, please don t hesitate to reach out! All work is happening fully in the open, so you can also chime in on the respective GitHub/GitLab tasks  .

You can also expect blog posts about key features or interesting changes, so stay tuned!

23 August 2026

Russ Allbery: Long delayed haul

I haven't made a new book haul post in I don't know how long, so a lot of books have piled up and many have already been reviewed. Here's the overdue catch-up in case anyone is curious what books I am finding interesting before the reviews get posted. Ilona Andrews Magic Bites (sff)
Elizabeth Bear In the House of Aryaman, a Lonely Signal Burns (sff)
Oliver Burkeman Four Thousand Weeks (non-fiction)
Miles Cameron Whalesong (sff)
Lee Child Killing Floor (thriller)
august clarke The Felicity Complex (sff)
Alison Cochrun Here We Go Again (romance)
Dan Davies The Unaccountability Machine (non-fiction)
Linzi Day Midlife in Gretna Green (sff)
Linzi Day Painting the Blues in Gretna Green (sff)
Linzi Day Ties that Bond in Gretna Green (sff)
Linzi Day Spilling the Tea in Gretna Green (sff)
Michelle Diener Dark Ambitions (sff)
Michelle Diener Dark Class (sff)
Michelle Diener Collision Course (sff)
Michelle Diener Crash Course (sff)
Henry Farrell Underground Empire (non-fiction)
Kathleen A. Flynn The Jane Austen Project (sff)
Victoria Goddard The Hands of the Emperor (sff)
James Herriot All Creatures Great and Small (mainstream)
James Herriot All Things Bright and Beautiful (mainstream)
James Herriot All Things Wise and Wonderful (mainstream)
James Herriot The Lord God Made Them All (mainstream)
James Herriot Every Living Thing (mainstream)
Lauren Hough Monster of a Land (non-fiction collection)
Bethany Jacobs This Brutal Moon (sff)
Guy Gavriel Kay Written on the Dark (sff)
Mary Robinette Kowal The Martian Contingency (sff)
Ann Leckie Radiant Star (sff)
C.B. Lee Coffeeshop in an Alternate Universe (sff)
Fonda Lee The Last Contract of Isako (sff)
Julie Leong The Teller of Small Fortunes (sff)
Julie Leong The Keeper of Magical Things (sff)
R.Z. Nicolet The Cloak and Its Wizard (sff)
Claire North Slow Gods (sff)
Rebecca Ore Writing's Writing (non-fiction collection)
Suzanne Palmer Ode to the Half-Broken (sff)
Gareth L. Powell Fleet of Knives (sff)
Cameron Reed What We Are Seeking (sff)
Beth Revis Full Speed to a Crash landing (sff)
Beth Revis How to Steal a Galaxy (sff)
Beth Revis Last Chance to Save the World (sff)
Natalie Zina Walschots Villain (sff)
Jo Walton Everybody's Perfect (sff)
Martha Wells Platform Decay (sff)
James White The Galactic Gourmet (sff)
James White Final Diagnosis (sff)
The James Herriot books were ones my parents were getting rid of. I have them marked as mainstream fiction as a short-hand since "fictionalized autobiography" seemed like too much of a mouthful.

16 August 2026

Bits from Debian: Debian turns 33!

It has now been thirty-three years since the Debian project was announced to the world by Ian Murdock, on August 16, 1993. This anniversary is an opportunity to reaffirm the goals, characteristics, and qualities of the Debian project: it s an association of individuals who have made common cause to create a free operating system. Our distribution is characterized by a commitment to software freedom, as enshrined in the Debian Social Contract and the Debian Free Software Guidelines. It focuses on security and stability. This stability is crucial to Debian position in the free software ecosystem. With our users as our priority, Debian makes special efforts regarding accessibility with Debian-Accessibility and diversity with our Outreach Programs. Debian Day is a great opportunity to get together, whether for a local meetup, or simply to grab a coffee with other members of the Debian community. Check out the Debian Day wiki to see if there is a celebration near you. And if there isn't, maybe you can organize it next year! Today is also an opportunity for you to start or resume your contributions to Debian. For example, you can install the how-can-i-help package and see if there is a bug in any of the software that you use that you can help to fix, contribute small tips on how to install Debian on your machines to our wiki pages, or put a Debian live image in an USB memory and give it to some person near you, who still didn't discover Debian. Thanks to everybody who has contributed to develop our beloved operating system in these 33 years, and Happy birthday Debian!
4 August 2026

Anuradha Weeraman: Plan 9 from Bell Labs, the little OS that could

Plan 9 Fourth Edition showing the rio windowing systemScreenshot by VulcanSphere via Wikimedia Commons MIT License
I first heard of Plan 9 from my friend Vajra in 1999 or so, as we were distro-hopping on early Linux distributions and trying to find our way. Vajra is now a Nebula Award-winning science fiction author - have a look at his work. We had just been through Tom's Root Boot, a UNIX-like operating system crammed into a single floppy, and through it discovered a whole new world outside of DOS 6.22. Combing through old UNIX manuals, we went in search of the perfect OS, through Slackware, Caldera, TurboLinux, SUSE and Red Hat. I finally settled on Debian, which lived up to everything I stood for. Plan 9 was distinct. It came out of the Computing Sciences Research Center at Bell Labs, built by Rob Pike, Ken Thompson, Dave Presotto and Phil Winterbottom, with Dennis Ritchie heading the department. The name is a joke at their own expense, borrowed from Ed Wood's 1959 Plan 9 from Outer Space, routinely nominated as the worst film ever made. Thompson and Ritchie had, of course, built the original UNIX; it almost seemed as if they were building a new OS from the lessons learnt from building it - which was in turn built on the lessons from Multics. I remember the awe I felt playing around with Plan 9, and I've not been able to replicate it since. Plan 9 was different in a couple of fundamental ways: per-process namespaces, and a protocol that abstracted locality of resources to processes. As a consequence of these core primitives, the OS surface area was distinctly small. The entire system from the core kernel, to the system call interface, to the compiler, linker and shell was reduced to a form small enough that a single developer could hold it in their head. Lessons from the implementation of UNIX helped the designers make the system leaner, and in Ken Thompson's words, it's the "best operating system out except that it doesn't have the apps that everybody demands" [1]. It also took the concept of "everything is a file" in UNIX to a whole new level. The network stack is a filesystem (/net), processes are files, the display is a file (/dev/draw). Because every resource speaks 9P and every process has its own namespace, you can mount another machine's /net into your namespace and your program makes network calls through that machine's stack without knowing or caring. No sockets API, no RPC layer, just ordinary file system operations through a simple system call interface. Some would say that OS research is dead, and that backwards-compatibility and POSIX killed it. Rob Pike himself argued as much in his 2000 talk, "Systems Software Research is Irrelevant" - but we didn't care at the time. There was so much happening that we didn't have time to take it all in. And then Linux happened, and Software Freedom became a focal point (more on that in a later post). In the summer of 2020, with the world deep in Covid lockdowns, I decided to build a toy operating system, just to try my hand at the the thing that I had always wanted to do. I spent three feverish months working on Odyssey and, looking back, it is perhaps the most fun I have ever had. I would not dare compare it to the magnum opus that is Plan 9, but it gave me perspective: how hard it is to build an OS from scratch, and above all, how fun it is to build an OS from scratch, and why the original creators kept coming back to the same problem. The highlight of those three months was booting the OS and watching it render "The Great Wave off Kanagawa". Nothing in my professional achievements to date captures what that meant to me.
Odyssey rendering The Great Wave off Kanagawa during boot Odyssey displaying "The Great Wave Off Kanagawa"
Decades on from the first time I booted Plan 9, I look back with nothing but awe and respect for the creators of this little operating system and marvel at the foresight that went into it. While many readers will not have heard of Plan 9, they have almost certainly worked with the ideas that came from it: 9P (if you ever used the Windows Subsystem for Linux), UTF-8 (if you ever used any modern operating system), per-process namespaces (if you've ever run a container), Go (whose assembler still uses Plan 9 syntax). Plan 9 still lives on in 9front, a community-maintained fork. Separately, Yoann Padioleau [2] has produced a set of annotated books at principia-softwarica.org, presenting the Plan 9 source in the spirit of Donald Knuth's literate programming - an admirable effort to introduce new readers to the art of operating systems engineering. Pike thought systems research had become irrelevant, and Thompson thought Plan 9 would never "make it" [1]. Both were right about the industry, but may have been pessimistic about the impact. The system lost as a product but won as a set of ideas, assimilated one at a time by modern operating systems. Success is not always measured by popularity. The mark that Plan 9 left behind is greater than what's reflected in its current user base. To me, Plan 9 will always be the OS that punched above its weight class, the little OS that could. References [1] Ken Thompson Interview, March 6, 2024 [2] Yoann Padioleau Principia Softwarica, May 9, 2026

1 August 2026

Russ Allbery: Review: How to Steal a Galaxy

Review: How to Steal a Galaxy, by Beth Revis
Series: Chaotic Orbits #2
Publisher: DAW Books
Copyright: December 2024
ISBN: 0-7564-1949-2
Format: Kindle
Pages: 143
How to Steal a Galaxy is a far-future science fiction caper short novel (maybe a novella?) and the sequel to Full Speed to a Crash Landing. You don't have to remember the details of the previous book to enjoy this one. There's an excellent inline summary at the start of this installment. After an annoying negotiation with people who keep trying to preach at her about causes, Ada Lamarr has a new contract. She is going undercover, after a fashion, at a charity gala and auction on Rigel-Earth. While she's there, she's going to steal something. What, precisely, she keeps a mystery from both the other characters and from the reader until the end of the story. Government agent Rian White is working security at this charity gala. Due to its link with the plot of Full Speed to a Crash Landing, he was fairly certain Ada would be there, as indeed she is. What she is planning, however, is maddeningly unclear. Also maddening is how good Ada looks in a dress. As with the previous book, How to Steal a Galaxy is told by Ada in the first person using the same teasing tone and constant misdirection that she uses when verbally fencing with Rian and the other characters. I found this novella even more entertaining and satisfying than the previous one. The charity gala is supposedly intended to benefit the poor people of Earth, and is run with exactly the sort of condescension and disguised capitalist looting typical of such exercises in elite charity. Ada's narration is scathing in a deeply relatable way. Also, there is a trillionaire tech-bro fake philanthropist who is smug and condescending and accustomed to getting exactly what he wants.
"I don't think anyone should have enough personal wealth to decimate a large country's income just because he's going through a midlife crisis."
Ada's interactions with Strom Fetor are an absolute delight. He is so sure of himself that he is incapable of registering her as a threat, and she effortlessly deceives him by hiding in plain sight.
"You really shouldn't be talking about this," Rian starts. Fetor waves aside his concerns. "We're all friends here." "Not me," I say. "I hate you. Remember?" Fetor laughs in a tone I'm sure he thinks is charming.
Fetor's complete inability to realize that a beautiful woman might both sincerely not like him and not be flirting with him is perfect. I was cackling through half of this book. Like any good heist story, there are twists and turns, surprises, double agents, unexpected complications, and a delightful amount of verbal fencing. I adore the narrative tone Revis uses for these stories. Ada has just the right mix of idealism, cynicism, professionalism, and irreverence to carry off the feeling that she's a step ahead of everyone else. Underneath the bones of a delightful plot is a character who cares deeply but is very aware of her limitations, and therefore has taught herself to laugh at and be ruthless with her own emotions. I am finding it an incredibly compelling type of competence porn. I enjoyed the first book of this series, but this one was so much better. These stories are exactly the right length to keep the reader engrossed throughout and satisfied but wanting more at the end. How to Steal a Galaxy ends on a cliffhanger of sorts, to be resolved in the next and final book. I can hardly wait to start it. Highly recommended. Followed by Last Chance to Save the World. Rating: 9 out of 10

31 July 2026

Russ Allbery: Review: Painting the Blues in Gretna Green

Review: Painting the Blues in Gretna Green, by Linzi Day
Series: Midlife Recorder #2
Publisher: Linzi Day
Copyright: November 2022
ISBN: 9798360228431
Format: Kindle
Pages: 577
Painting the Blues in Gretna Green is a self-published fantasy novel and the second in the Midlife Recorder series. It picks up immediately after the end of Midlife in Gretna Green. I also read it almost immediately after, so I didn't pay attention to how good the recap of previous events was. As before, this is urban fantasy except not urban. Day calls it paranormal women's fantasy, which I suppose is as good of a genre label as any. The other book I can think of off-hand that would go into that genre would be Nancy Springer's Larque on the Wing, although it is considerably more literary. I suspect I'm going to read this whole series and it's going to be impossible to review these books without talking about Niki's job, so I'm not going to treat that as a spoiler. It's fairly well-advertised in the marketing for the book, so that feels justified. If you're particularly averse to any spoilers, though, you may want to stop reading here until you've gotten to the reveal in the first book. Niki is now officially the Recorder, with the power, advice book, and sentient house to go with it. She's about to face her first test in managing interworld politics: There's something amiss in the world of the Picts. Her allies are dropping hints, there's a petition from a group on the Pict world that she can't make sense of, and although she likes the queen of the Picts, there is a great deal of tension beneath the surface that she doesn't understand. Meanwhile, after the incompetent disaster that she uncovered in the first book, Niki is determined to pick her new staff by her own criteria. The second book leans even harder into giving Niki both a tangled mess created by previous incompetence and enough power to fix it. Watching that happen is very satisfying, particularly when it involves surprising people who are rather too used to getting their own way. I was somewhat less convinced that Niki is getting the right training to make the decisions that she's making. Diplomacy and staff management are real skills that one needs to learn, not just wing on vibes and gut instinct. My love of competence porn occasionally wishes that Niki had a bit more structure around her competence. We do at least get a new fictional self-help book on how to rule that contributes the quotes that open each chapter. Not the ethics and management training that I would have chosen, but it's something! In defense of Niki's technique, it becomes clear in this book that the last few recorders have been far too cautious, conservative, and content with a status quo that involved a minimum of work. One of the delights of this book is that Niki thinks power exists to be used to fix things and is determined to use it, not just sit on it. I had more suspension of disbelief issues with this book than with the first some of the problems Niki is solving seem far too obvious to have been in stasis for this long while also having this easy of a solution, and the level of political power given to the Recorder is a bit unbelievable but it is so satisfying to see Niki cajole and bully people into being sensible. I have no idea if this is intentional on Day's part, but I will not be at all surprised if adult-diagnosed ADHD comes up at some point in this series. The way that Niki's focus jumps, her tendency to veer between focusing on a problem and forgetting about it, and something about the way she switches between trains of thought or misses important context because she's jumping to conclusions is making me wonder. This, to be clear, is not a complaint; I think it makes Niki more relatable and more interesting. It's a good thing that she has a sentient house to serve as her assistant. The glee with which she's delegating any task that involves keeping track of details or following up with other people feels like a bit of an indicator by itself. I did get a bit frustrated with the plot structure of this book. Niki keeps mentioning that a critical petition submitted to her office makes no sense, but it takes half of this (rather long) book before she finally explains to anyone else, even the reader, what's deficient about it. The excuse within the book is that she's having a rather busy day, but by the third time Niki mentions and then fails to do anything about the petition, I was wishing Day would stop bringing it up until she was ready for that part of the plot. This, as with a few issues in the previous book, feels partly like an editing problem. There is something joyful in indulgent, sprawling books, but only up to the point where they become repetitive. Painting the Blues was right at that line, and once again I wish someone had helped Day trim about fifty pages out of it. All that said, and despite having more quibbles with this book than the previous one, this continues to be great fun. It's satisfying wish-fulfillment about fixing long-standing problems and having the power to not have to put up with abusive nonsense and ridiculous bullshit, and I am so here for that. I hope Niki realizes she's eventually going to need more refined skills than a heart-to-heart over wine, but she's learning on the job and I'm happily along for the ride. She's also capable of recognizing skill in other people, and that goes a long way. Recommended if you liked the first one and are in the mood for another fantasy of "no, we're not going to leave it that way, we're going to fix that right now." Followed by Ties that Bond in Gretna Green. Rating: 7 out of 10

Otto Kek l inen: Estonia, the country of the fit and the wit

Featured image of post Estonia, the country of the fit and the witWhile many Western democracies seem to be in a state of decay and are no longer the safe, civilized and prosperous countries they once were, there are still some European countries that are governed well. One of those that stand out is Estonia. Estonia is probably most well known for multiple software companies that originated from there, such as Wise, Bolt, Pipedrive and Skype. The government itself is also famous for being early in issuing government IDs with an embedded smart chip for online authentication already in the 1990s. Via the national portal at eesti.ee all residents can access extensive eServices ranging from viewing their health benefits to filing taxes. Estonia has also been running an e-Residency program since 2014, where they issue digital ID cards to foreigners, making it easy for them to remotely log into the government portals and for example, establish businesses, file annual reports and so forth. Note that the e-Residency is not a path to physical residency. Estonia does, however, have a separate Digital Nomad visa program that makes it easy for non-EU citizens to also physically establish themselves in Estonia, assuming, of course, you meet the criteria, which includes, among others, a minimum monthly income of 3960 from outside Estonia. EU citizens naturally have free mobility inside the EU and can simply get an apartment and register as a resident in Estonia if they so choose. And there are plenty of reasons to do so.
Estonians value health, education and entrepreneurship I moved to Estonia about one and a half years ago. In my observations Estonia strikes me as a country that values health, education (in particular programming and natural sciences) and entrepreneurship highly. I don t know how Estonians achieve it, but they look pretty fit and rarely obese. Estonia has rye bread and sauna in their culture just like Finland, and in addition the flat terrain and well-planned bike routes and extensive network of parks (and pull-up bars everywhere) seem to create an environment where it is easy to live in a healthier way. The consumption of processed foods and candy also seems relatively low among Estonians. The gym chain MyFitness also seems to be present everywhere. Even the Tallinn airport has a calisthenics workout station right at the departure gates, which anyone is free to use while waiting for their flight to take off. One of the top longevity influencers in Europe, Siim Land, is Estonian. Estonia has lots of good bike paths, parks and outdoor gyms There is even a calisthenics station with pull-up bar and more at the departure gates at Tallinn airport Estonians also seem to value the school system highly. The government has been actively raising teacher pay and has a stated goal of reaching 120% of the national average by 2027. The students are also expected to value the education and respect their teachers. According to the TALIS 2024 survey (OECD s international teacher survey), Estonian teachers spend significantly more time on actual teaching and learning and waste less time on interruptions or keeping classroom order compared to the OECD average. This is among the highest rates internationally, meaning they spend relatively little time on maintaining order or dealing with disruptions. While the international education benchmark PISA scores have been dropping globally, Estonia has consistently been climbing the ranks in past decades. In the latest PISA study (from 2022), Estonia ranked number one in Europe for reading, mathematics and science. In the overall results, Estonia ranked seventh globally, only behind countries such as Japan, Korea and Singapore. Valuing entrepreneurship is evident in how the taxation system is set up in Estonia. Famously, in Estonia, companies can defer taxes on annual earnings and reinvest all of their profit in growing the company. Taxes are due only later, when paid out from the company, for example as dividends. For individuals, receiving dividends from any Estonian or foreign company is tax-free as long as the company paying dividends already paid corporate tax on the same income. The tax system is also very simple. For all individuals, all types of income, including salary and capital gains, are always taxed at a flat rate of 22%. This removes the incentive for anyone to try to convert income into different types, setting up holding company structures and other optimizations as there is no gain. All entrepreneurs can simply focus on growing their business and forget extra bureaucracy. There is also no marginal tax rate cliff to stop working at everyone is encouraged to always try to produce as much value as they can. A simple tax system is also reflected in the fact that anyone can easily read all tax rules that apply to individuals in plain English on the Estonian tax authority website, and one does not need to hire any accountants simply to file taxes. Estonia also has a very straightforward investment account system: any person can freely open a self-directed investment account at any brokerage at no extra cost and report it as such to the tax authority, and then use it to save for an apartment, retirement, or other purposes, and defer all income taxes until withdrawal. There are no caps or time limits, and all residents are encouraged to save and invest as much as they can and thus take responsibility for their own wealth accumulation. It seems that culturally Estonians respect people who are active and progress in their careers and businesses more than in other countries. Unlike in Finland, successful people are admired and living on government welfare is not romanticized. At the same time, the government benefits are less generous so people can t live comfortably on them and, for example, many of the asylum seekers Estonia accepted have since left on their own initiative to other European countries in search of better benefits.
Low crime, high trust Another thing that strikes me when walking the streets of Tallinn is that there are no drug addicts, beggars, thugs or the like. The difference compared to, for example, Vancouver (where I lived previously) is stark. In public buildings, people leave their coats and bags hanging in the lobby while visiting. Private houses and apartment block yards are not fenced. In my building, I noticed people even leave their bikes unlocked in the bike shed. I have also seen the staff of a coffee stall in a shopping mall going for a break and leaving everything unattended, not worrying that anyone would take anything while the staff is away. Nobody is stealing anything from the unattended coffee shop while staff is having a break at  lemiste shopping mall This is not just my personal experience. According to the Numbeo crime index, Estonia has one of the lowest crime rates in the world. Also, comparing drug and property crime stats, for example, Finland has twice as much crime per capita, and places like Vancouver in Canada almost five times more. I don t have any clear explanation for why crime is so much lower in Estonia, but some suggest that higher social cohesion and lower levels of welfare contribute to people standing to lose more if they behave antisocially. Compared to Finland, Estonia also more readily jails repeat offenders, and those who are put on trial will experience a swifter court process thanks to simplified legal processes and more efficient governance.
Moving to Estonia: quick checklist Moving to Estonia is very easy for any EU citizen, in particular if your work is not location-dependent (e.g., remote work or an online business) and you are simply looking for the cleanest and safest environment to live in. First, check into a hotel in Tallinn, check out various neighborhoods to figure out what area you like (my favorites are Kalaranna, Kalamaja, Noblessner and Volta) and start browsing available apartments in English at kv.ee. Most professionals speak fluent English, so there should not be any difficulty in reaching out to people by email or phone. Tallinn is famous for the old town The economic boom of recent decades created a lot of new construction, with Kalaranna being among the newest areas The next step is to buy a local prepaid SIM card at e.g., an R-Kiosk or a convenience store as signing up for other matters later on will require an Estonian phone number. Once you have an apartment and e.g., signed a rental agreement, you can register in the population registry online. After that, you have proof you are a local resident with an address and telephone number in Estonia. With local resident status, you can go to the police station to get a local ID card. Don t bother scheduling an appointment, just go to the Tammesaare police station in Tallinn, take a queue number and wait. Once it is your turn, they will guide you on how to use the photo booth, fingerprint registration device, and file your application. A few days later you will receive an email confirming whether your application was accepted, and after a few more days, you will get another email notifying you that your ID card has been printed and is available for pick-up at the same location. This will also be your first practical experience of how fast and efficient the government in Estonia is. Once you have the local ID card, you can use the smart card feature to log into all the government eServices and sort out the rest of the relocation process, such as registering tax residency and getting a family doctor. The main eServices portal in Estonia: eesti.ee
How did Estonia evolve to be like this? After Estonia regained its independence after the fall of the Soviet Union in 1991, the first elected government in 1992 was led by a very progressive 31-year-old Prime Minister Mart Laar, who managed to set up some very good policies and laid the foundation of a society that has evolved well in the decades since. Estonia was very lucky to have people in power in the 1990s who didn t simply copy what other Western countries were doing, but who tried to think about things from first principles and create Estonia s own model for efficient and fair governance. As a post-Soviet country, the population had also been vaccinated against overly socialist and unrealistic ideals, and everyone had a healthy distrust of the government s ability to solve problems and emphasis was placed on people s liberty to work for themselves as they best see fit. The improvement in living standards over the past 35+ years has also been witnessed by the population, and voting behavior supports keeping the country on the same trajectory. General living standards still continue to improve as the nominal wage growth sits at around 6%, clearly above the annual inflation rate of about 3%. In 2026, the Estonian economy is expected to grow about 2.4%, which is faster than the EU average. The growth in Estonia is not the result of any accounting tricks - Estonia is part of the euro and can t print its own currency, nor has it been funding the public sector with excessive debt. With a 24% debt-to-GDP ratio, Estonia consistently ranks as one of the most responsibly managed countries among advanced Western economies. As wages in Estonia soon catch up with the EU average, and higher defence spending has forced the government to raise taxes in recent years, the economic growth that Estonia has enjoyed for 35+ years since it exited the Soviet Union might slow down a bit in future years. The policies that fueled this growth in living standards, however, are likely to stay.

The tiger leap There is one specific government policy in Estonia s history that I think should be highlighted in particular. Estonia was very progressive by announcing the Tiigrih pe (Tiger Leap) program in 1996 with the goal of equipping all schools with computers and teaching all students the basics of programming. This surely had a large influence on why Estonia has so many successful software companies, why the government eServices are so mature that even neighboring countries like Finland are striving to copy the Estonian government s IT architecture called X-road. The Tiigrih pe project was originally suggested in the mid-1990s by Toomas Hendrik Ilves, then ambassador of Estonia to the United States, Canada and Mexico, and later President of Estonia in 2006 2016. While he was a psychologist by education, he was also a self-taught amateur programmer and used his political influence to promote sensible adoption of information technology in both Estonia and the EU. The history of Estonia has several prominent figures who were not lawyers by profession but engineers, scientists and historians who were very practical in their political decisions, which I think is now reflected in how government processes were formed. The video below shows how the Estonian government advertises itself and what values they choose to highlight:

Should other countries adopt policies from Estonia? Of course, not everything is perfect in Estonia either. The fertility rate of 1.16 in Estonia is very low. This trend is present globally, but in Estonia it is way below the EU average. Also, the service culture is something that needs to improve in Estonia. While services are in general fast and efficient, the attitude of people working in cafes and stores does not reflect a willingness to fill in gaps if the standard process falls short, nor are visitors actively made to feel welcome as individual humans, but are treated as mere process inputs. However, many of the things listed earlier I think should be studied by policymakers elsewhere. Societies are complex systems and there is of course no guarantee that copying a single policy to another country with different ethnicities, history and ingrained culture would lead to the same policy outcomes. But considering that Estonia is a small country without favorable geography and no natural resources, and that it started out from a place of total chaos, low economic activity and high crime in 1992 to rise to what it is now in 2026, the success it has seen is surely largely a result of good policies, governance and culture that other countries can and should mimic.

30 July 2026

Russ Allbery: Review: In the House of Aryaman, a Lonely Signal Burns

Review: In the House of Aryaman, a Lonely Signal Burns, by Elizabeth Bear
Series: Sub-Inspector Ferron Mysteries #1
Publisher: Sobbing Squonk Press
Copyright: 2012
Printing: 2018
ISBN: 0-9863735-1-6
Format: Kindle
Pages: 73
In the House of Aryaman, a Lonely Signal Burns is a science fiction police procedural set in relatively near-future India. This novella was originally published in Asimov's SF and collected in several anthologies as well as Bear's Shuggoths in Bloom collection, which I have on my shelf but have not yet read. I probably should have checked that before I got another copy. It is the first story of a series in the sense that there is an Audible-only sequel available. Like many police procedurals, this one opens with a crime scene. Sub-Inspector Ferron and her partner are inspecting a tube of human meat in the middle of the rug of a luxurious apartment in Bengaluru. The tube is apparently the remains of one Dexter Coffin, an American with a high tech workspace who was apparently mangled beyond recognition in his locked apartment near a table set for two. Dexter's cat is a witness. In this future world of cats enhanced with limited language skills, this would have been very useful, but the cat's memory was apparently wiped. Ferron will have to get to the bottom of the mystery some other way. Also, she apparently now has a new cat. Meanwhile, Ferron is worrying about her partner's mental health, her partner is worrying about her use of stimulants to stay on duty for this murder investigation, and Ferron's mother is harassing her for money to pay the bills of her virtual reality addiction. Her job is a good distraction from other problems she'd rather not deal with. I am trying to come up with something insightful to say about this story, and I'm not having much success. It's a police procedural with a bit of a science fiction twist. The characters are fine but not, at least for me, particularly engaging. There is some deft world-building, but nothing that grabbed my attention or made me desperate to read more stories in this world. Perhaps the most interesting part of the background, and the reason why I picked up this novella, is that this is the universe that eventually becomes the setting of the White Space series. There is an early version of right-minding handled entirely through medicine without the later invention of the fox implant, and there are some signs that humanity is slowly digging itself out of the hole of climate change and antisocial behavior that it had dug. I found this mildly interesting, but it doesn't add much to the later series and is very skippable. The source of the title is a bright light originating in the Andromeda galaxy, which is contained in Uttara Bh drapad in Vedic astrology. Ferron says this is under the influence of the god Aryaman. This is unrelated to the plot; it's just a background event that prompts some introspective musing from Ferron at the end of the story. It's a nice moment, but I would have been more interested in the full story of first contact between Earth and the Synarche. This was a mildly pleasant way to spend a few hours and I'm already forgetting all of the details. It's a competent story, but not one I feel a need to recommend to others. Followed by A Blessing of Unicorns, which appears to be an Audible audiobook exclusive. Rating: 6 out of 10

29 July 2026

Russ Allbery: Review: Midlife in Gretna Green

Review: Midlife in Gretna Green, by Linzi Day
Series: Midlife Recorder #1
Publisher: Linzi Day
Copyright: July 2022
ISBN: 9798837010774
Format: Kindle
Pages: 464
Midlife in Gretna Green is a self-published fantasy novel. It's urban fantasy in the sense that it's set in our world but with magic that most people don't know about, but the primary setting is a parish in rural Scotland and therefore the genre is not urban in that sense. It was Linzi Day's published first novel. As the story opens, Niki McKnight is a widow in Manchester, England with a job in the Register Office she likes, a boss she hates, and a Bichon Frise dog she adores. In the year since her husband Nick died, she's put her life on hold and made as few decisions as possible, despite some concerned pushing from her best friend Aysha. The death of her grandmother is not entirely unexpected, but her inheritance is about to upend her life. Niki assumes that her grandmother has a modest cottage and a small estate, and therefore being the named heir will mostly involve cleaning up the details of a modest life. She is caught by surprise by a requirement in the will that she live in Gretna Green for a year and a day in order to inherit. Her initial reaction is to treat this as an absurd impossibility given her life and job in Manchester, but she slowly realizes something strange is going on. Her grandmother's lawyer is lying to her, he refuses to tell her the value of the estate and seems to think it's more valuable than she expected, and her grandmother's tiny cottage does not seem to be following the seasons of the rest of the world. There is something magical at work. I will not spoil the rest of the reveal. I will say that this is a magical house book because, if you are anything like me, that is why you will want to read this series. There are not enough magical house books, and this is one of the better kind that allow the house to be a full speaking character. Midlife in Gretna Green is an unapologetic fantasy of personal agency. Niki starts the novel with a miserable manager, a messy pile of unread mail she doesn't want to deal with, and a lot of personal emotional baggage. She gets handed a position that requires and rewards standing up for herself and being decisive. It comes with a pile of unresolved but not horribly complex problems that were waiting for someone who would listen, make sensible decisions, and treat other people with respect. Oh, and there are a few assholes in the way, but they seriously underestimate the power she has to put a stop to their bullshit. This is the sort of book that traditional publishers tended not to buy (although Day apparently did get an offer for this one and turned it down), and I'm not sure why. Editors thought protagonists should have to work harder for their payoff? Some lingering Calvinist dourness in English language publishing mistrusted triumphant books? Obvious wish fulfillment was considered embarrassing or low-class and thus didn't warrant publication? This didn't apply to the endless bildungsromans about magically talented boys, so some level of sexism was probably in play. Maybe this is finally changing? It reminds me of the bias against romance novels and their guaranteed happily ever after, and in the case of romance there was too much money for publishers to leave it on the table. In any case, the growth of self-publishing has created an alternative market that let these books reach an audience and I for one am here for it. A lot of wish-fulfillment books, and a lot of self-published books, are not very good, but the ones that have a spark of originality and character can be a delight worth tolerating the somewhat rocky editing and pacing problems that a full editorial staff might have cleaned up.
I loved reading books about kickass women who took no crap and fixed their lives up exactly how they wanted them to be. But how did they get to be that way? They always started out awesome in the books. Seriously, did they kick ass at sixteen? Or did their superpower kickassery not kick in until they were thirty? Forty? If so, then I was screwed. Would I need to wait till I was fifty or until a genie arrived offering wishes? I already felt as if I d spent my whole life waiting for something wild and wonderful to happen.
Niki is a Specific Type to a somewhat hilarious degree, and I'm not sure if Day is playing into that intentionally or if she's projecting herself into the book. The amount of self-insertion is not zero: Day also lives in Gretna Green, owns a Bichon Frise, and worked as an assistant registrar and civil celebrant. Niki also drinks wine regularly, has a psychic gift, occasionally reads tarot cards, is an accommodating pushover at work who struggles to say no to her abusive boss, has impostor syndrome problems, and swears by a fictional self-help book about grief that provides the quotes at the starts of chapters. There is a cat, because of course there's a cat. (The fictional self-help book is a spot-on parody played entirely straight in the story. I think Day is having some fun with the reader? I can't tell!) This is what I mean by unapologetic. It's easy to read Niki as a stereotype, but she's a stereotype a lot of real people can identify with and there's something highly satisfying in watching her find her footing. I like wish fulfillment books; it's fun to see someone's wishes come true! Particularly in the year of 2026, there's something immensely satisfying in seeing an ordinary, insecure person get a massive amount of power and use it to make the world better. I don't need everything to be hard, fraught, and laden with costs in fiction, although I wouldn't want every book I read to be like this. Also, the world building is great. It's not polished; there's a bit of a grab bag feeling to it, I'm dubious the magic system has any underlying rigorous rule set, and Niki's powers, once she has access to them, are more of a semi-sentient genie than a skill she has to learn with hard practice. But the magic is fun. The sentient house is one of the best characters, particularly after Niki realizes how underused it has been, and I am a sucker for any good sentient house book. The cat is a far more interesting character than I first thought she would be. And Niki's new magical job is more complicated and less typical than the normal Celtic-inspired fantasy that I thought it was going to be at first. My primary warning about this book is that Niki starts out beaten down and grieving her dead husband, and it took me about five pages to decide that her dead husband was a complete piece of shit who was not worth any of the grief Niki puts into him. She also doesn't stand up for herself for the first hundred pages or so, which made me want to yell at the book a few times. Both of these problems go away farther into the book, and Niki does eventually figure out that Nick was abusive trash, but I was relieved when the "make endless excuses for worthless men" portion of the story was finally over. You have to stick with it until Niki gets brave enough to try being the protagonist; once that happens, it becomes great fun. It is fairly obvious that Midlife in Gretna Green was self-published, and I wish it had gotten the editing that it deserved. My copy had a couple of obvious formatting errors, the plot veers about more than was strictly necessary, and I think a careful editing pass could have tightened the writing by about fifty pages or so without losing any important detail. If that sort of thing bothers you, make sure you're in self-published fiction mode before starting this one. But it also has that irrepressible, bubbling-with-ideas feeling of a book where nothing has suppressed the author's enthusiasm. It's a very grabby book; once Niki starts embracing her new life, I could barely put it down. If you're in the mood for a good fantasy wish-fulfillment story that has no romance and a whole lot of "why are things run this way, no, we're changing that," highly recommended. I had so much fun with this book, and the series is currently making the rounds of my whole family. Don't read this when you're looking for something challenging and literary and deep; save it for when you desperately want to watch someone just fix something for once, damn it. Followed by Painting the Blues in Gretna Green, which I have already read, breaking my usual rule of writing reviews before reading the next book in a series. Rating: 8 out of 10

27 July 2026

Valhalla's Things: Late Victorian Vampire Shirt

Posted on July 27, 2026
Tags: madeof:atoms, craft:sewing, FreeSoftWear
A woman wearing an old-style white shirt with lots of fullness, wide and long sleeves and ruffles at the collar that spread out framing the neck, down the center front to underbust height, covering the slit and at the cuffs, reaching to mid-hand. The shirt is gathered at the waist with a belt, and worn over the bottom garment to show that it reaches to mid tight. Drama levels in the pose are pretty low. The recurring joke is that because of some health issues, in summer I dress like a Victorian Vampire. But how would an actual Late Victorian Vampire dress? Picture her, she would look like some kind of eccentric gentlewoman, as vampires usually do, probably with a style that is a bit conservative, rather than following the latest fashions. Same woman, same shirt, posing as a vampire ready to attack a victim. Drama levels increasing. Now, she wouldn t probably wear men s shirts. But what if she was a lesbian1 vampire? Wouldn t she need a fancy, frilly shirt to go with her tailored cycling suit when she s out seducing the more active ladies in the neighbourhood? Or maybe not. It s not making a lot of sense, is it? But I do have a lot of shirt fabric in my stash2, and I could use a few more shirts that were practical and comfortable, but also somewhat over the top. For the practical and comfortable I went to my trusted 1880s shirt, while for the over the top part I looked at inspiration from the earlier 18th century frilly shirts, and their later imitations. I decided to use some nice cotton batiste I had bought quite a few years ago to make one of my first historically inspired shirtwaists: I may have a tendency to buy a bit more fabric than actually needed by the pattern, but that s what everybody does, right? For the ruffles I decided to use a lighter weight cotton voile, also from the stash. the top edge of a ruffle being whipstitched over some gathered fabric; the rest of the unfinished shirt is visible in the background. At the front, I wanted the ruffle to be inserted in the yoke, but I was also whipstitching the gathers to it to make them neater, so I started bu attaching the yoke lining to the gathered front, then I whipstitched the ruffle to the front, catching each gather, and finally I whipstitched the other yoke on the ruffle and the rest of the gathered front. The front of a shirt: the body was gathered into a yoke, but it has been unpicked and pulled out to extend a bit past the end of it, into where the collar will be sewn. And then after sewing the collar, I realized that this way the slit would have remained open in the front (or the collar too narrow), so I had to unpick the front part of the yoke, and sew it again, this time leaving an excess of fabric as wide as half the placket width from the pattern, to be sewn directly in the collar band. From then, things progressed smoothly, with some interruptions, until I got to the first sleeve, which I failed to insert twice, as one does. The same shirt worn without the ruffle at the collar, with just what looks like a mandarin collar, closed with a clip with an amethyst. Drama levels have gone way down. On the third attempt, with a different method, I succeeded, I tried the shirt on, and it already felt extra. Close up of the collar on a table: at the center back of the shirt collar there is a buttonhole, and a double button is used to keep the detached collar in place, while at the front both the shirt collar and the detached collar have buttonholes. But it could be even more extra. With some ruffles also at the collar. Same close up, but now the collar has been closed with a clip-on earring with an amethyst and some small fake clear stones, and it looks as if the skirt had a ruffle collar and a jewel button (or a pin). The shirt had been made with a simple collar band, and I could have just added the ruffle to it, but I also wanted to be able to wear it with other detachable collars, so I decided to make another collar band with ruffles, to wear on top. And that was mostly it, except for the reinforcement patches at the side seams and cuffs: I love having them, because they make the seam end neater and stronger, but they are a bit of a hassle to make, so they got postponed a few days. Same woman and shirt, back with the ruffled collar, in a pose like that of an artist that is fainting for futile reasons. Drama levels over the top. But finally, the shirt was done. And I tried it on, and it was good. But now I really need a pair of cycling breeches, don t I?
  1. ok, maybe straight passing bi? anyway.
  2. I have no idea how they got there.

26 July 2026

Russ Allbery: Review: Radiant Star

Review: Radiant Star, by Ann Leckie
Publisher: Orbit
Copyright: May 2026
ISBN: 0-316-29068-8
Format: Kindle
Pages: 359
Radiant Star is a science fiction novel set in the Imperial Radch universe without being a direct sequel to the other books in that universe. It will badly spoil the end of Ancillary Mercy, and I recommend reading that trilogy first, but it's independent of the other books in the same universe.
In the 3,008th year after the manifestation of the Radiant Star (the 1,024th since the founding of the Consorority itself), Zaved, a newly minted consoror, disappeared a mere two days after the ceremony that elevated her to womanhood. She left a note that read, Bored. Back whenever. This was not normal or even remotely acceptable behavior in a consoror, particularly one who held as much promise as Zaved had, but what could the consorors do?
Zaved, faced with the unpleasant prospect of running out of money during her galactic tour, plied a rich benefactor with tales of how talented, polite, and obedient the boys of the Consorority are. Her plan worked brilliantly. After funding further non-boring adventures, she arrived home in Ooioiaa with a chest full of money and a pregnancy. Great for Zaved and the Consorority; kind of a shame for her son Jonr, who is to be delivered to her benefactor after proper training. Oh well, telling Jonr about that is a problem for future Zaved. After a strained childhood in which he convinces himself he is a misfit with few redeeming qualities, Jonr ends up in a suspension pod. Before shipping can be arranged, however, external events intervene, leaving Jonr sitting unnoticed in a warehouse. The planet of Aaa is in a highly inconvenient location, drifting as it does through interstellar space unattached to any star. It would be as irrelevant and overlooked as any other random interstellar object except for two critical properties. The first is that Aaa and its sole city of Ooioiaa are sacred to a religion of obscure origin. Its primary population are members of a religious cult who believe the Radiant Star manifested in the Temporal Location on Ooioiaa and will eventually return to bring light to the galaxy. The second interesting property of Aaa is that it is drifting ever so slowly towards a strategic system of military importance. The first property brings pilgrims and their accompanying bounty of money, food, and other resources necessary to dig a small city out of rock, make it habitable, and supplement the sparse and strange native edible life. The second property brings the Radchaai, who easily conquer the city of Ooioiaa and are now faced with the unpleasant task of running it. Some decades after the Radchaai conquest, having never left Aaa, Jonr is woken up. He will not be sent off into the broader galaxy as a slave to pay off a vacation debt. Instead, he will be one of the many protagonists in this novel about the perils of living through supply chain disruptions on a planet full of status-obsessed religious fanatics who would drown in a rain shower. The other books set in this universe make abundantly clear that the Radch is a voracious colonial power that enslaves native populations and enforces their own cultural preferences at the point of a gun. A reader familiar with this series is predisposed to take whatever side is not the Radch. Radiant Star adds a complication, however. Charak Svo, the Radchaai governor, is impatient with native inhabitants and strongly dislikes their religion, but she is reasonably competent. The religious factions that ran Ooioiaa before the arrival of the Radchaai, on the other hand, are dogmatic authoritarians with the collective wisdom of a sack of turnips. Charak does not get everything right and is arguably responsible for at least one catastrophe. By the end of the book, though, I was firmly convinced that had the original religious government still been in charge, everyone would have died. I found the structure of this book a little odd. The omniscient narrator tells the story in the form of a history. The target audience appears to be future inhabitants of Ooioiaa and adherents to the Radiant Star religion, and the narrator is often maddeningly uninterested in topics that a reader of the rest of the Imperial Radch books is intensely curious about. This same property carries through to the plot: I was interested in how all of the tensions in this obviously absurd society could be resolved or, preferably, overturned entirely. The narrator, on the other hand, is far more interested in Serque Tais's intent to become the last saint in the Temporal Location, and in the details of the subsequent political, economic, and religious fallout. Leckie has written three novels set in the Imperial Radch after the original trilogy: Provenance, Translation State, and now Radiant Star. I am sure that I'm not the only person who wants a direct continuation of the original trilogy, but I'm drawing the conclusion that Leckie doesn't want to write that. Instead, she's writing around the edges of the subsequent events, in effect showing readers the shape of them and their broader implications without showing the details. Now that I can see what she's doing, I kind of like it. Given what we now know from the books written around the edges, the ensuing events in the center of galactic politics are chaotic in a way that could easily devolve into tedious accounts of messy conflicts. Seeing the effects from afar lets the reader fill in some of the blanks and speculate, and it makes the moments where we get a concrete update (such as at the end of this book) all the more rewarding. I still find it odd, though, to read a book where the narrator's interests so sharply diverge from mine. I wish I could say that Radiant Star sucked me in as the story developed, but it never did. Part of the problem is that I think this book is intended as a very dry farce, and farce often doesn't work with my reading style. I prefer to attach myself to a protagonist and hope they do competent things, and this book is full of characters who are being themselves far too aggressively and loudly to have time to be competent at anything. My favorite moments were therefore the small pockets of people with sense: The governor, Jonr, his charge, and the delightfully strange Justice of Albis. I enjoyed all of them, but I had trouble caring about the overall plot and kept putting this book down for days between chapters. I think this is mostly personal taste, though. Like all of Leckie's novels since the original Imperial Radch trilogy, Radiant Star is competently executed and a little strange. When that strangeness aligns with your tastes, it's a great deal of fun and rather unlike other science fiction novels. In this case, it didn't quite work for me, but I suspect it will for others. I still want another Leckie novel with a ship as a protagonist, though. Content notes: Rather disturbing (although bloodless) religious practices, mass death. Rating: 6 out of 10

Next.