Search Results: "ac"

7 September 2026

Bits from Debian: New Debian Developers and Maintainers (July and August 2026)

The following contributor got their Debian Developer account in the last two months: The following contributors were added as Debian Maintainers in the last two months: Congratulations!

Colin Watson: Free software activity in August 2026

My Debian contributions this month were all sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. Personal note This month, my Dad unexpectedly passed away after a short illness. As a result I obviously got less work done than usual, and I still have a lot to take care of (since I m the executor of his will, as well as helping with funeral arrangements) while grieving and generally having less focus and energy. Having routine work to do is one of the ways I cope with this sort of thing, but all the same, I hope people will bear with me and maybe remind me if I seem to be dropping the ball on something you especially need. LLM vote [Content note: strong opinions.] I voted in General Resolution: LLM usage in Debian. My vote was pretty much the opposite of what ended up winning, so I m quite disappointed. My personal opinion is that LLMs are cognitive hazards to their users that impose ecological costs far out of proportion to their utility at a time when the world absolutely cannot afford them. When the impossible economics of the large commercial models are finally allowed to catch up with reality, I expect there to be significant macroeconomic consequences, and that people who have become dependent on them will have problems; and who knows what the copyright situation on their output really is. I m not convinced that local models are better enough on these axes to be worth the costs. Debian s direct contribution to all that will be negligible on a global scale, and even the most radical proposals in the GR didn t expect that we could do much about upstreams that have gone all-in on LLMs. Even so, I d hoped that my fellow developers might be more willing to lean on our position in the free software ecosystem to make at least a moderately radical statement. Instead, we ve at best presented an undistinguished fence-sitting position to the world, and further entrenched the idea that humans can reliably do a good job of reviewing the output of tools that are designed to produce output plausible to humans. I certainly don t trust my own code review skills that far. Since I ve never voluntarily used an LLM (not counting LLMs being foisted on me by things like search results, support chatbots, or incoming pull requests, regardless of whether I asked for them), and don t intend to for the foreseeable future, I doubt this will change much for me in terms of the way I work. The winning option is a very weak one that imposes no new requirements on developers, which means that it also does nothing to stop me continuing to reject LLM-generated material from Debian bug reports and merge requests in my areas of responsibility. I know this probably won t do much to satisfy people who have decided that Debian is slop now, but it s the best I can do. OpenSSH I finally landed the GSS-API key exchange package split in our OpenSSH packaging. Here s the NEWS entry:
openssh (1:10.4p1-5) unstable; urgency=medium
  The openssh-client and openssh-server packages no longer include GSS-API
  authentication and key exchange support; this adds pre-authentication
  attack surface and generally increases complexity, and should only be used
  where specifically needed.  Users who need these features should install
  openssh-client-gssapi or openssh-server-gssapi instead.
 -- Colin Watson <cjwatson@debian.org>  Sun, 23 Aug 2026 17:39:55 +0100
I fixed a flaky autopkgtest. I upgraded from 10.4p1 to 10.5p1, which was a good test of keeping openssh and the new openssh-gssapi source package in sync. PuTTY I upgraded from 0.84 to 0.85. Python packaging New upstream versions: The version treadmill continues: we ve just finished dropping Python 3.13 as a supported version, so now we ve started working on enabling Python 3.15 as a supported version. Maximiliano Curia has been very helpfully driving this. I didn t get as much done here as I d have liked (see the top of this post), but I fixed a couple of packages: Other build/test failures: I fixed some other bugs: bugs.debian.org I deployed the fix for Invalid link rel= canonical on bugs.debian.org. In the process I found a few bugs in recent undeployed code and fixed them.

Daniel Lange: Getting AVIF thumbnails in XFCE4 thunar (Debian Trixie)

The AVIF image format gets more and more popular in the web dev community, so I needed to teach XFCE4's thunar (file manager) and Ristretto (image viewer) to thumbnail these. Luckily that is not too hard: Debian Trixie separates its gdk-pixbuf libraries slightly differently than previous versions. That's why it is not "automatically there". Ensure you have the libavif-gdk-pixbuf plugin and the tumbler service (which XFCE uses to process thumbnails):
sudo apt --update install libavif-gdk-pixbuf tumbler
Thunar has likely tried (and failed) to load your AVIF files before you installed the package, it will have saved a blank or "broken image" placeholder in a thumbnail cache directory. It will not attempt to regenerate them unless you clear this cache:
# Clear the thumbnail cache
rm -rf ~/.cache/thumbnails/*

# Force-quit thunar and the tumblerd background service
thunar -q
pkill tumblerd
Tumbled will restart on its own when it is needed. When you open thunar again and navigate to your image directory ... your AVIF images will now generate thumbnails automatically like the other image format did already. Avif thumbnails in thunar

Vincent Bernat: Sidenotes with CSS anchor positioning

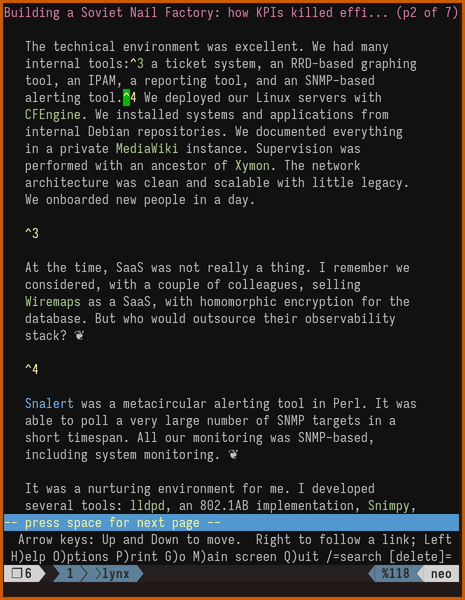
I am a heavy user of sidenotes:1 they keep optional content next to the text instead of sending the reader to the bottom of the page and back. Tufte CSS renders them without JavaScript but only accepts inline content. CSS anchor positioning, now supported by recent browsers,2 is an elegant alternative. Sidenotes can hold several blocks, still without JavaScript, and fall back below the paragraph referencing them on narrow viewports and older browsers. In 2023, Eric Meyer demonstrated this technique in Nuclear Anchored Sidenotes. The main improvement over other solutions is that the notes can sit anywhere in the HTML document. You can place them after the paragraph referencing them, as regular block elements for text browsers, screen readers, feed readers, and reader mode to render them properly:
Sidenotes rendered in Lynx appear after the paragraph they are called from.
Rendering in Lynx, a text browser
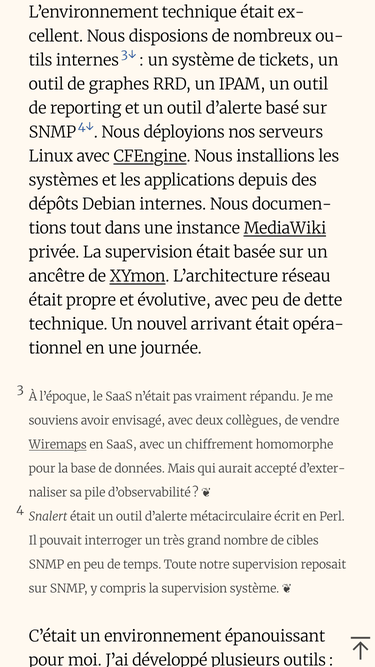
When the viewport is too narrow or the browser does not support CSS anchor positioning, you can style them so the reader can skip them or glance at them without losing their position in the text:
Sidenotes rendered on a narrow viewport appear with a distinctive typography after the paragraph they are called from.
Rendering below the paragraph on a narrow viewport
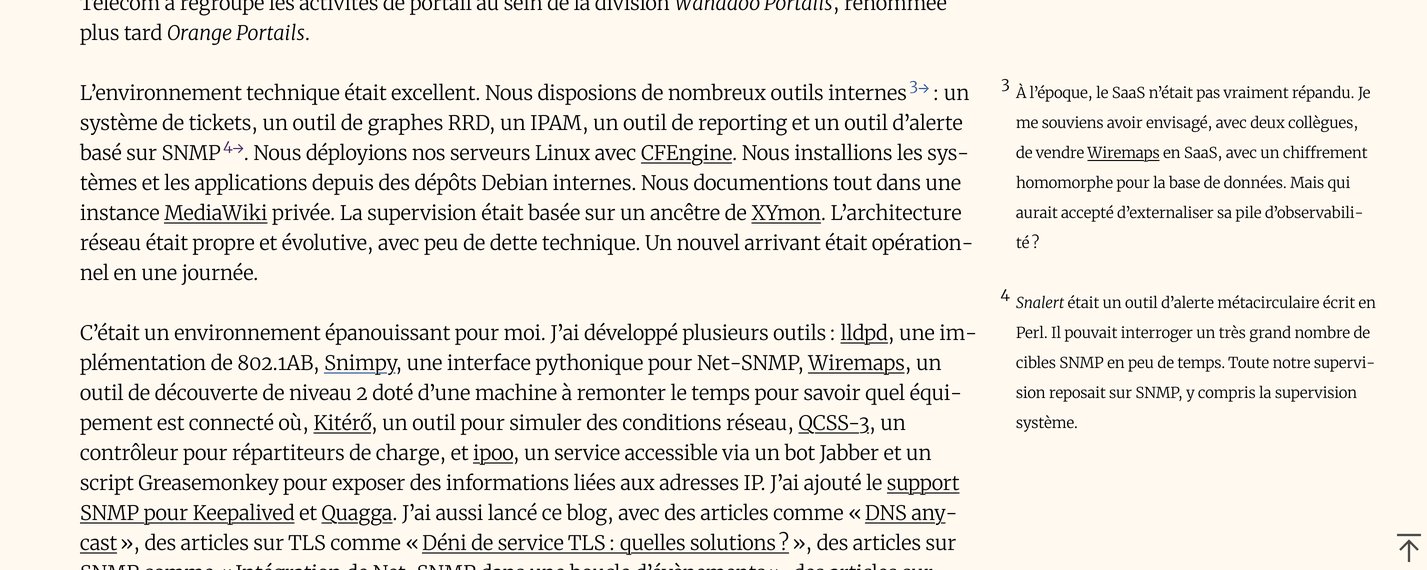
Once the viewport is large enough, they appear in the margin, at the same vertical position as the matching reference mark, unless they would collide with a previous sidenote, as in the example below:3
Sidenotes rendered on a large viewport appear in the margin. There are two of them. The first one is vertically aligned with the matching reference mark, while the second is rendered below as it would collide with the first otherwise.
Rendering in the margin on a large viewport
The gist of CSS anchoring is to position an element relative to another element the anchor. For the sidenotes, the anchor is the reference mark. I use the following markup, with a data attribute to specify the anchor name:
<sup id="fnref:YYY" data-anchor="--lf-sn-YYY">
  <a href="#sidenote-YYY">1</a>
</sup>
The matching note is an <aside> element carrying the same data attribute for the anchor name. We put it after the paragraph holding the reference mark:
<aside role="note" id="sidenote-YYY" data-anchor="--lf-sn-YYY">
  <sup>1</sup>
  <p>A first paragraph.</p>
  <p>A second paragraph.</p>
</aside>
On a narrow viewport or when the browser is too old for CSS anchoring, we style the sidenote, which stays below its paragraph, with a muted color:
aside[role="note"]  
  margin-block: 1rlh;
  color: #444;
 
On a wide viewport and when the browser is recent enough, we move the sidenote to the right margin:
@supports (anchor-name: attr(data-anchor type(<custom-ident>)))  
  @media (min-width: 72rem)  
    main  
      position: relative;
      sup[data-anchor]  
        anchor-name: attr(data-anchor type(<custom-ident>));
        /*   anchor-name: --lf-sn-YYY */
       
      aside[role="note"][data-anchor]  
        anchor-name: --lf-sidenote;
        position: absolute;
        position-anchor: attr(data-anchor type(<custom-ident>));
        /*   position-anchor: --lf-sn-YYY */
        top: max(anchor(top), anchor(--lf-sidenote bottom, -1rlh) + 1rlh);
        left: 100%;
        margin: 0 2rem;
        width: 18rem;
        color: inherit;


attr() extracts the anchor name for the reference mark from the data-anchor attribute. It returns a string, unless we specify a CSS unit or a type, like here: the browser parses the data attribute as a custom identifier, which anchor-name validates as a dashed identifier, a custom identifier starting with two dashes.4 The note itself is absolutely positioned past the right edge of the main block. It selects the matching reference mark as its anchor with position-anchor set to the value of the data-anchor attribute. Each note is also an anchor named --lf-sidenote. We use it to keep the next note from colliding with this one. The anchor() CSS function lets us position the note s top edge relative to its anchor: anchor(top) aligns the top edge of the note with the top edge of the reference mark. It can also take another anchor as a parameter: anchor(--lf-sidenote bottom) would align the top edge of the note with the bottom edge of the closest preceding anchor named --lf-sidenote so the previous note.5 Like attr(), anchor() accepts a fallback value as its second parameter and use it when the named anchor does not exist. The top property handles three cases, illustrated in the following diagram:
Diagram of three sidenotes anchored to their reference marks. The first one is aligned with the top of its own reference mark, as no note comes before it. The second one would overlap the first, so it takes the bottom of the first note as anchor and sits one line below it. The third one comes far enough down the page to align with its own reference mark again.
The three cases for the vertical position of a note
  1. The first note s top edge aligns with the top edge of its reference mark: as there is no previous note, anchor(--lf-sidenote bottom, -1rlh) + 1rlh resolves to 0 and max() returns anchor(top).
  2. When the reference mark of a later note sits above the bottom of the previous note, plus some vertical space, the note goes below the previous one to avoid a collision. max() returns anchor(--lf-sidenote bottom) + 1rlh.
  3. Otherwise, the note s top edge aligns with the reference mark s top edge, as max() returns anchor(top).

Have a look at the complete stylesheet, which also adapts the reference mark to the location of the note: a arrow when the note sits below the paragraph, a arrow when it moves to the margin. Gwern s Sidenotes In Web Design lists more implementations and their trade-offs. Some bloggers aim to write a post in 30 minutes. I planned to publish three web-related articles this weekend. Instead, I spent an inordinate amount of time elsewhere: about 15 commits on the build system, a pull request to update CSS highlighting for nested selectors in Pygments, and a small correction to MDN s article on the anchor() CSS function. The SVG illustration took a bit less than an hour and the article itself a handful of hours. The attr() function came in after I thought inline style looks ugly, isn t there a better way? But, hey, I still think this is worth it!

  1. My PhD advisor told me this is unwise.
  2. The first bits of anchor positioning are supported from Chrome 125 (May 2024), Firefox 147 (January 2026), and Safari 26 (September 2025). Before Safari 26.5, sidenotes may collide due to a bug in how dependency chains are handled. You can detect this situation with some JavaScript. It is, however, not needed in the solution described here as we depend on a more recent feature.
  3. If you noticed the runt in the first note, I share your pain and lament that Firefox does not implement text-wrap: pretty.
  4. Typed attr() is supported from Chrome 133 (February 2025), Firefox 155 (September 2026), and Safari 27 (not yet released). Check Una Kravets article for details. To support more browsers, you can inline the anchor name and the position anchor directly in the HTML:
    <sup id=" " style="anchor-name: --lf-sn- ">
      <a href="#sidenote- ">1</a>
    </sup>
    
    Managing Anchor Associations With Data Attributes and Advanced attr(), by Daniel Schwarz, explores CSS anchors and typed attr() in more detail.
  5. The exact rule for the target anchor element is more complex: if an ancestor of [the note] satisfies the following conditions, return the nearest such element to [the note]. Otherwise, return the last element in tree order that satisfies the conditions. One of these conditions is that [the candidate] is an acceptable anchor element for [the note], which requires that [the candidate] is laid out strictly before [the note], where the relevant clause is that [the candidate] is either not absolutely positioned or occurs earlier in the flat tree order than [the note].

Freexian Collaborators: Debusine can now hand you debug symbols! (by Jugal Patel)

Contributor: Jugal Patel (Jugal59)
Organization: Debian
Project: Provide debuginfod server
Mentor: Colin Watson

About the project and me Your program crashes. You open gdb and get ?? instead of a stack trace. So you go find the right -dbgsym package, for the right version, for the right architecture, install it, and start again. Debuginfod removes that entire detour: gdb asks a server for symbols by the build-ID baked into the binary. Debusine already built packages, already produced -dbgsym files, and already hosted the archives; it just couldn t answer the question. This summer I made it answer. My project was to add debuginfod server functionality to Debusine so that it not only hosts -dbgsym packages, but also serves their debug symbols over the debuginfod(8) protocol. Debian developers can then debug binaries by setting a single URL that gdb uses to fetch the matching debug symbols. This project took me through design, backend work, an extraction pipeline on the worker, HTTP serving, documentation, and testing from the first blueprint all the way to a live demo on debusine.debian.net.

Initial planning and design changes A design first, in !3030. The proposal submitted for GSoC 2026 was just an overview of how things will work, but in reality there were a lot of design questions which needed to be answered before starting with contribution. Debusine keeps development blueprints in its docs tree, reviewed like code, it s basically a blueprint of what feature or new changes are we going to make. I was assigned the work item #957, which was basically about how the idea of implementing a debuginfod server functionality inside Debusine was initially proposed by a fellow member which later became a project idea under GSoC 2026. My developer blueprint pinned down the four decisions everything else depends on: extraction happens on the worker after the build, symbols are stored as artifacts keyed by build-ID, they re published into suites alongside their binaries, and they re served from the archive root rather than per-suite. Settling that up front meant the design discussions happened in a document instead of across three merged branches. Provide debuginfod server work item and all my merged PRs till now One of those arguments became its own fix. My wording implied symbols were unpacked inside the isolated sbuild environment (the consequence was I was handed a bug to be solved in the first week of contribution period), when they re actually extracted afterwards on the worker, where the build output already sits, a distinction that matters, because doing work inside the unshare environment means extra tooling in the chroot and more ways to affect the build. !3119 corrected it before the wrong model spread into the code. Bug raised for inconsistent wordings in developer blueprint

A new artifact type Artifacts are a major concept in Debusine overall, so as per the developer blueprint we introduced a new artifact which was debian:debug-symbols. It holds every .debug file from one -dbgsym package. Its data is a validated list of lowercase 40-character build-IDs, and each file is stored under its build-ID as the path, so answering what are the symbols for this ID? is a direct lookup, with no path translation in the request handler. One artifact per package rather than per file: a util-linux build would otherwise spray hundreds of artifacts, collection items and relations across the database for no benefit. For implementing debian:debug-symbols artifact, I changed the main models.py file, along with that since it s a norm to write unit tests, all mentioned under !3088. sbuild task output showing the new debian:debug-symbols artifact

Publishing workflow and solving a bug Extracting symbols is only useful if they reach the archive people actually install from, so !3180 taught package_publish to follow the relates-to relation: copying binaries into a suite now brings their debug symbols along automatically, with nothing extra for the publisher to configure. Each build-ID becomes its own collection item, for example debugsym:hello_2.10-5_amd64_fcc9064 each carrying the package name, version and architecture copied from the binary, so the item is meaningful on its own without dereferencing anything. Uniqueness is enforced at both the suite and archive level, because the serving URLs are archive-wide and two suites must never disagree about what a build-ID means: republishing an identical file is accepted quietly, while two different files claiming the same ID is an error worth failing on. A partial index on the build-ID keeps the eventual HTTP lookup fast. That looked finished until symbols started arriving in target suites disconnected from their binaries published, but unfindable, because copying items between collections silently dropped their artifact relations, and that relation is the only thing tying the two together. The fix sat one level above my feature, in the generic CopyCollectionItems task that does the copying, and since it was reusable infrastructure rather than anything debuginfod-specific, Colin implemented it himself in !3228. My project needed it to work at all; every other Debusine feature that copies items now gets it for free.

Endpoint and CI tests With symbols in the archive, !3212 added the part users actually touch: GET / scope / workspace /buildid/<build-id>/debuginfo looks the ID up across every suite in that workspace s archive, streams the file, and sets the X-DEBUGINFOD-FILE and X-DEBUGINFOD-SIZE headers the protocol expects. It also handles the two things gdb actually does: a HEAD probe before committing to a download, and ranged requests to pull individual ELF sections instead of the whole file. Scoping it to the archive rather than the suite is what lets one URL cover a whole workspace, so the developer never has to know which suite their binary came from. Fetching debug files from debusine.debian.net Every merge request above landed with unit tests, but those only tell you that the pieces behave correctly. What Colin and I wanted was a real gdb fetching real symbols from a real instance, so !3261 adds an autopkgtest that builds a package, publishes it, checks the HTTP headers, then sets DEBUGINFOD_URLS and makes gdb go and get the symbols, wired into the CI integration tests so it runs on every change. It took me a day to learn that skipping the signing worker doesn t simplify that test, it just hangs until the 30-minute timeout, because update_suites needs signing to produce a usable repository. The last piece, !3301 covers the new artifact, the suite and archive changes, the new archive URL, and a how-to for using it. My first how-to draft explained how everything worked and offered four ways to set DEBUGINFOD_URLS; the version that shipped gives one recommended setup and gets out of the way. The same pass trimmed the blueprint down to only what s still unimplemented, since a design document describing merged code is just an obstacle for the next reader. Setting debuginfod url for gdb and debugging session!

What s left Only one item on my original plan didn t land: an archive-level build_debug_symbols switch, modelled on Launchpad s equivalent, letting an archive skip building -dbgsym packages entirely by passing DEB_BUILD_OPTIONS=noautodbgsym to sbuild. It was always the stretch goal rather than core scope, landing the extract-publish-serve path solidly mattered more than landing it broadly. The design is written up in the blueprint, and I intend to implement it myself. The other gaps were deliberately out of scope from the start, and the blueprint says so. DWZ supplement files aren t ingested, so packages using compressed debug info may render without the alternate strings table; debugging still works, it s just less complete. Source-file serving runs into the same Debian packaging limits that constrain debuginfod.debian.net today, making it a design question rather than a coding one. Executable serving, the metrics and metadata endpoints, and federation to upstream debuginfod servers were excluded for similar reasons, none of them are needed for Debusine s core use case, and each would have crowded out the parts that are. One open bug is left too. On the last day of the coding period, Stefano Rivera found that publishing ledger and linux was failing, because I had told the database that a build-ID identifies one exact debug file which isn t true in Debian, since dh_dwz runs once per binary package, so when one object ships in two binary packages their .debug files differ while describing identical code. How to fix it is still an open discussion #1582, though it may not land before the formal end of the project. None of that is a handoff. GSoC s timeline is ending, my involvement isn t, I m carrying on with Debusine until both the build_debug_symbols switch and DWZ supplement support are merged, and I expect to keep contributing beyond that. This project got me familiar with a codebase I enjoy working in, and the remaining pieces are mine to finish.

Thanks! The biggest thanks go to my mentor, Colin Watson, whose reviews consistently found the thing I hadn t thought about. He also gave me room to get things wrong first and understand why, which taught me more than being handed the answer would have. Thanks as well to Rapha l Hertzog, Enrico Zini, Stefano Rivera, Carles Pina i Estany and Helmut Grohne and everyone else around Debusine and Freexian for reviews, comments and patience with my questions. Special thanks to Freexian for developing Debusine in the open and for giving me access to test on debusine.debian.net. Finally, thanks to the wider Debian community, whose build-ID and -dbgsym conventions did most of the hard work before I arrived and to Google Summer of Code for providing a platform and the time to do this properly.

6 September 2026

Iustin Pop: AI agents aha moment

Looking at the reactions to the Debian AI vote, I think some people still think the clock can be turned back, as if that ever worked in history. Rather than cry about spilled milk, I prefer to find a path forward in the new world. There are many ways to use LLMs, some of them are straightforward, others not so much. One of the not so clear areas for me is the focus on agentic workloads. For complex tasks, sure, you want something that can work in the background, but in general, why does every single tool go the agentic way? I much prefer the chat/ask approach, or even the code one, but if I m at the keyboard, why would I send a task to an agent, and see it work, instead of directly implementing it? And then, this past Friday, I finally understood one part of that. I was in the airport, sitting at the gate and waiting to board a flight, and because I arrived much earlier at the airport (fearing crowds due to Labour Day weekend), I got one hour of work before boarding started. As the time for boarding approached, I did one more commit after making sure tests pass, pushed, closed laptop, and went to walk a bit before getting on the plane. As I was getting up, I get a phone notification from GitHub that the CI run failed. I was quite surprised, as the local tests passed, so I open the notification, and realize that tests via make test vs CI (which additionally uses --pedantic) had slightly different settings, and of course I missed a build warning (which in CI is an error). I thought I d fix that on the plane, but then I saw a Copilot agent button in the mobile app. I was curious what it did, I click it, and I see Copilot starting a draft pull request, and saying:
Thanks for asking me to work on this. I will get started on it and keep this PR s description up to date as I form a plan and make progress. Fix the failing GitHub Actions job. Analyze the Actions logs, identify the root cause of the failure, and implement a fix.
Then it goes, finds the failure, writes the fix, and tries to run the tests. Well, it can t do it (it runs in a restricted container, so no network, so stack install couldn t actually work). The agent sees that, acknowledges it has no way to validate the fix, but the error message was clear enough that it was confident the fix is mostly correct, so it sends the pull request. I allow full CI to run on the pull request, and go buy a bottle of water. After that, I check and see that the CI failed again, as not one but two test files were broken, and I didn t have --keep-going, so the build stopped at the first failure. I write a comment in the pull request, no reaction, I realize I need to tag Copilot explicitly, I do that, and it starts another investigation. I m waiting now in the boarding queue, with phone in hand, while Copilot is fixing my bug. While I scan my boarding pass and walk towards the plane, the pull request is updated, I trigger another CI, it passes, and I merge it. And then, it hit me. Agents allow me to make progress while being not at keyboard , whether that s physically not at keyboard , or while working on something else. Fixing a simple test failure is not something that needs human attention per se, whereas improving the test layout might be. In that airport, using otherwise-unusable downtime, and without explicitly intending to, I made progress in understanding a different way to use AI. Now I have three ways to work with LLMs: ask (tutor mode), code (implement my request), and agent (fix simple or complex problems, autonomously). I still don t know about plan mode and really complex tasks, like asking it to implement features from scratch. That will probably be the next area to tackle. And today (Sunday), while waiting for a running race to start, I opened GitHub, and asked Copilot to increase test coverage for a simple module. It did, and yes it still can t run tests (I learned in the meantime that you can configure the environment in which the agent runs, nice), but after two back-and-forth messages, I have a pull request ready to review. All in the 20 minutes before a race, where I could either browse social media or actually do some meaningful work. Checking now my GitHub billing, it looks like all of this Copilot use only cost $1.92. Yes, that is under two dollars! And while it did use compute resources, the person across the aisle who watched TikTok or Instagram for half an hour while waiting for takeoff also consumed a lot of compute, and so do the gazillion cat videos uploaded to YouTube every day. To me, this is another tool in the toolbox, that might one day replace me (as it did to the 19th-century textile workers), or make me five times more productive we ll see where we end up. In the meantime, I can move faster, and make better use of my limited free time. Enjoy the ride!

Dirk Eddelbuettel: RcppFarmHash 0.0.4 on CRAN: Maintenance

Another minor maintenance release of the RcppFarmHash package is now on CRAN as version 0.0.4. RcppFarmHash wraps the Google FarmHash family of hash functions (written by Geoff Pike and contributors) that are used for example by Google BigQuery for the FARM_FINGERPRINT digest. This releases updates several of package internal files for continuous intergration and package data. The brief NEWS entry follows:

Changes in version 0.0.4 (2026-09-06)
  • Minor updates to continuous integration, README.md and DESCRIPTION

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Russell Coker: CoMaps

I have just tried CoMaps, a free mapping program released under the Apache license [1]. I have tried it on Android on a Pixel 6a but it also runs on Linux so I ll try it on a PinePhone or similar at some convenient time. On Android it is in the F-Droid repository among others and for Linux there s a Flatpak package. The data it uses is from Open Street Map project [2] which has extensive and accurate coverage of every place I ve looked at (Australia and a few other first-world countries). The first thing it does after being installed is start downloading the world data set from Open Street Map and prompt to download the data for the detected region (Melbourne in my case). The UI is decent and allows most of the features that I am used to using in Google Maps. The quality of directions seems good, I ve only tested it with one journey so far which was a 50 minute drive across the city and it gave a set of directions that Google Maps often gives. It gives spoken directions which is an important feature but sometimes the way the directions are presented is confusing. When turning off a freeway it didn t give a spoken direction to do that, it gave a direction to turn right which was AFTER leaving the freeway, fortunately the map was clearly displayed. In terms of use practices of this program the main difference I recommend is checking which off ramp to use from a freeway before entering the freeway. With Google Maps you can rely on it giving clear directions in that case. I recommend this program without reservation. It can do everything that Google Maps does apart from detecting traffic jams because there s no way of detecting traffic without spying on users. It is designed to preserve user privacy and works well in that regard.

Enrico Zini: Migrating away from .org/.net/.com domains

After having witnessed how easy it is for good people to lose a .org domain over a fascist tantrum (you can follow the Autistici/Inventati story here and here), I've started moving all my infrastructure to differently managed TLDs. enricozini.org and enricozini.com will keep being functional for the time being, as dropping a domain makes it available for squatting and impersonation. These new domains are now online, with working web and emails: It will take ages to migrate countless accounts that are tied to my primary email address, so better start early. Waiting to see what will happen with .meow domains, which I supported despite not identifying as a cat.

Michael Stapelberg: Debian Code Search: Fast TurboPFor with Go SIMD

This August, I accomplished what I wanted for many years: I deleted the last cgo dependency in Debian Code Search! This was made possible by Go s recently introduced SIMD support, because now we can implement the TurboPFor integer compression format as efficiently more efficiently, in fact, by using the newer AVX512 instruction set! as the reference implementation.

Background: Why does DCS need a fast Integer Codec? Debian Code Search (DCS) is a search engine that allows searching all the Open Source source code within Debian, with either literal search expressions or regular expression search queries. A search engine uses an inverted index: a map from term to documents containing the term. Each document is typically represented most efficiently by using an id, so the index consists of many lists of document ids. When searching, it is important to quickly decode these lists to answer the search query. However, there is a point of diminishing returns where the decoding speed, even though it can still be measurably improved quite a bit, no longer influences the overall query duration. From 2012 (its inception) to 2019, Debian Code Search used to use a small index format, and queries were fast because the index was kept entirely in RAM. In 2019, I implemented the new index format, which adds an on-disk positional index. For literal queries (78.2% of DCS queries), querying the positional index on disk is faster than querying the non-positional index in RAM. The efficient encoding of the TurboPFor format makes it possible to fit such an index on a mid-sized Hetzner server, which I rent with two 1 TB SSD disks. The optimized decoder of the C TurboPFor library is what made decoding fast at query time. If you want to dive deeper into the algorithm, see this blog post from February 2019: If you want to learn more about the positional index, see this blog post from September 2019:

SIMD in Go For many years, you had the following options for using SIMD instructions in Go:
  1. Hand-writing Go assembler code. This is only doable for small functions, for example bytes.IndexByte is implemented with hand-written Go assembly (including AVX2).
  2. Generating Go assembler code with tools like Michael McLoughlin s Avo . This is how crypto/internal/fips140/sha256 uses AVX2. While Avo generator code definitely is higher-level than hand-written assembly, it is still too close to assembly for my taste.
  3. Use a C library via cgo so gcc or clang compiles SIMD code. Debian Code Search used to use the powturbo/TurboPFor C library via cgo for the last 7 years.
The C TurboPFor library has served us well, but Debian Code Search was always intended to be a project using Go, so I would prefer it if I did not have any C code in the project. Go 1.26 (released in February 2026) introduced the simd/archsimd package:
Go 1.26 introduces a new experimental simd/archsimd package, which can be enabled by setting the environment variable GOEXPERIMENT=simd at build time. This package provides access to architecture-specific SIMD operations. It is currently available on the amd64 architecture and supports 128-bit, 256-bit, and 512-bit vector types, such as Int8x16 and Float64x8, with operations such as Int8x16.Add. The API is not yet considered stable. Go 1.26 Release Notes
For my 2019 TurboPFor analysis, I implemented goturbopfor, a native Go teaching decoder (without any SIMD), because I find Go code easier to follow than C code, especially optimized C code. My implementation was intentionally not optimized so that the code was easier to study. The TurboPFor format/algorithm has a vector-optimized part: bitpacking comes in a scalar variant (bitunpack32) and a vector variant (bitunpack256v32), where the vector variant is used for full blocks (256 values) and the scalar variant is used for remainder blocks (< 256 values). When Go 1.26 was released, I used Claude Code to explore whether my native Go decoder s bitunpack256v32 function (for the vertical vector layout) could be implemented using Go SIMD, and the answer was yes, it was possible and it was faster than without SIMD, but not quite at the level of C TurboPFor. If you let Claude Code try for long enough, it eventually finds enough optimizations (about 10) to match C performance. I don t want to vibe-code Debian Code Search, though, so I figured I would find some time to review the SIMD code at some point and see if I could implement something similar myself. Before I found enough time and motivation to complete said review, I discovered that to not regress real-life query performance by more than 10 to 100 milliseconds (which seems acceptable), I don t actually need to add SIMD code to my teaching decoder at all; it would be sufficient to reduce allocations in my teaching decoder and specialize it per bit width. Encouraged by the possibility of using the optimized native Go decoder in Debian Code Search, I explored whether I could also implement a native Go encoder so that I could get rid of the C TurboPFor dependency entirely. The answer is yes, it is doable in a few days, and it isn t even that much slower: Go is at 76% of C, see Debian/dcs commit e920dc7. The goal I set myself at that point was to see if I could learn enough SIMD to optimize the native Go encoder such that its performance would match how DCS uses C TurboPFor (via cgo). Beating C TurboPFor was possible in 2-3 commits (SIMD and bit width specialization). To my surprise, Claude Fable 5 pointed out that the encoder s block scanning could be done more efficiently using a technique called positional popcount, and that is another 2x speed-up! To be clear: I am not saying the Go compiler beats C here. Certainly, the C compiler can also produce fast AVX512 code and can be used to implement positional popcount. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. This spectacular result (much faster than what DCS had before) got me curious how far I could push the decoder with SIMD after all. I ended up matching/exceeding the cgo version here, too! The rest of this article explains a few classes of optimizations I encountered along the way.

Starting Point When I wrote my goturbopfor teaching decoder, I named its functions to match the upstream C TurboPFor library, but now I want to get away from names like p4ndec256v32 they make sense from the TurboPFor perspective, but for Debian Code Search, we can use cleaner names. Before writing any code, I audited how DCS uses integer compression / decompression.

API design: BlockEncoder, BlockDecoder and streaming In Debian Code Search, we have the following usage patterns:
  • Partial Indexing: When a new package (or package version) enters Debian, all of its (text) files are indexed. If the hello-2.12.3-1 package (hypothetically) contained only hello.c with printf("hello!\n");, we would assign document ID 1 to hello.c and store in the partial index that trigrams pri, rin, int, ntf, etc. are all found in doc 1 (hello.c).
  • Full Index Merging: The many thousands of partial index files (for each Debian package) are combined into a small handful of large index files: When searching, it would be expensive to consult thousands of indexes. To merge multiple partial index files into one larger index (which can then be efficiently queried), we need to re-encode the partial index files: what used to be document ID 1 in the partial index might be document ID 2531 in the full index.
  • Querying (searching): When users enter search queries, these queries need to be answered as quickly as possible. The relevant entries in the full indexes are decoded (in parallel).
For reading the index, we do keep the decoded uint32s fully in memory, so we only need DecodeN(input []byte, output []uint32) (read int), a function that reads len(output) values (uint32) from input and returns how many bytes it consumed. For writing the index (both in partial indexing, and when merging), keeping the entire index in memory is prohibitively expensive, so we need a streaming API, for decoding and for encoding. Ultimately, I converged on the following API:
package pforenc

type BlockEncoder struct  
    // scratch buffers can go here
 

// EncodeBlock encodes len(vals)<=256 uint32s into dest (one TurboPFor block).
func (*BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  

// EncodeN calls EncodeBlock in a loop.
func (*BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  

type StreamEncoder struct  
  be   BlockEncoder
  vals [256]uint32
  // scratch buffers
 

// if full, you need to call [EncodeBlock]
func (*StreamEncoder) Add(val uint32) (full bool)

// EncodeBlock must be called after all data was [Add]ed.
//
// Write the returned buffer to file or send it over the network;
// it is only valid until the next [EncodeBlock] call.
func (*StreamEncoder) EncodeBlock() []byte  
  if se.n == 0   return nil   // turn an extra EncodeBlock into a no-op
  //  
 
This API (the decoder works similarly) allows us to process data in TurboPFor format without any memory allocations. The types are not safe for concurrent use by multiple goroutines. The zero value is ready to be used. For the streaming API, the result only stays valid until the next call.

Initial Implementation Before we can optimize anything, we need a working decoder and encoder. The decoder already exists: my goturbopfor teaching decoder. Next up, I needed an encoder. Writing a TurboPFor encoder has a delightfully simple starting point: You can encode all values at bit width 32, in little endian, at which point you only need to add a one-byte TurboPFor block header every 256 values and you re done:
func (be *BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte  
  for len(vals) > 0  
    chunk := min(len(vals), 256)
    dest = be.EncodeBlock(dest, vals[:chunk])
    vals = vals[chunk:]
   
  return dest
 

func (be *BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte  
  const bitWidth = 32
  dest = append(dest, bitWidth)
  for _, val := range vals  
    dest = binary.LittleEndian.AppendUint32(dest, val)
   
  return dest
 
Of course, this is a terribly inefficient compressor, so after the first commit, the real work starts: implement each block type until the compression matches the original C TurboPFor implementation (same output file size), or in other words: do the reverse of the decoder.
  1. The TurboPFor bitpacking block type (bitpacking implementation commit) encodes a bit stream of variable bit width (where the bit width is in range 0 bitWidth 32) in little endian byte order. By scanning all values and choosing the smallest bit width that allows representing all values, this technique saves disk space (compresses).
  2. The bitpacking with exceptions block type (bitpacking with exceptions implementation commit) determines two bit widths: one for values, the other bit width for encoding exceptions. This allows choosing a lower bit width (that does not cover all values) compared to the bitpacking block type. A bitmap encodes whether a value has an exception or not.
  3. The bitpacking with VB exceptions block type (bitpacking with VB exceptions implementation commit) is a variant which does not use an exception bitmap and encodes exceptions using a variable byte integer encoding. This is more efficient when there are few exceptions (less than 20) or the exceptions are very different in bit width compared to the other values.
  4. Lastly, the constant block type (constant implementation commit) stores just one value on disk. This is useful for all-zero or all-one blocks, for example.
I found it interesting to realize that the main work of the encoder is to scan the input values and choose the optimal block type, whereas the actual encoding itself is cheap in comparison. At this point, we can look at performance and see that the Go encoder is at 76% of the C encoder. In all honesty, I could have probably stopped here, but now that the milestone of a viable replacement was reached, I got curious to see how far it would be possible to push the encoder (how much work to reach C speeds?) and afterwards, the decoder, too.

Setup

The microarchitecture level: set GOAMD64 The microarchitecture of a CPU determines which instructions it provides, and that includes not just SIMD instruction sets (like AVX2), but also other useful instructions like LZCNT (Leading Zero Count), which can be used to implement math/bits.Len32 more efficiently, which the TurboPFor encoder needs to call on every input value to determine the ideal bit width. Let s walk through how to set the microarchitecture level when using Go on 64-bit x86 (x86-64). Go uses the GOARCH environment variable to configure the target compilation architecture, and I am using the value amd64 to select 64-bit x86 (AVX2 and AVX512 are instruction sets found on x86-64 CPUs). With GOARCH=amd64, the architecture-specific variable GOAMD64 configures the microarchitecture level for which to compile and Go 1.18 introduced these 4 different levels:
GOAMD64=v1 (default): The baseline.
Exclusively generates instructions that all 64-bit x86 processors can execute. GOAMD64=v2: all v1 instructions,
plus CMPXCHG16B, LAHF, SAHF, POPCNT, SSE3, SSE4.1, SSE4.2, SSSE3. GOAMD64=v3: all v2 instructions,
plus AVX, AVX2, BMI1, BMI2, F16C, FMA, LZCNT, MOVBE, OSXSAVE. GOAMD64=v4: all v3 instructions,
plus AVX512F, AVX512BW, AVX512CD, AVX512DQ, AVX512VL.
In 2026, I generally recommend compiling with GOAMD64=v3 so that functions like bits.OnesCount8 are compiled into intrinsics (POPCNT) instead of using a lookup table. For Intel CPUs, setting GOAMD64=v3 means your programs will only start on Haswell CPUs (2013) or newer; for AMD CPUs that means Zen 1 (2017) or newer. In this specific case (DCS), I am even compiling with GOAMD64=v4. The v4 microarchitecture level requires AVX512, which means AMD Zen 4, Zen 5 or newer (Intel s story is complicated). Luckily, both my main development PC (Zen 5) and the Debian Code Search server (Zen 4) are recent enough. Setting GOAMD64=v4 has little effect on Go 1.27 itself: the only change is that maps use one less instruction (VPBROADCASTB instead of PSHUFB). But compiling with GOAMD64=v4 allows us to move one more feature check from runtime to compile time, see SIMD build tags. It makes sense to set the microarchitecture level in your benchmark setup so that you don t measure the slow fallback implementations. I use export GOAMD64=v4 in my Makefile.

Benchmarking setup Go s built-in testing package contains support for benchmarks which are written in functions of the form func BenchmarkXxx(b *testing.B). The simplest way to run such benchmarks is go test -bench=., but I ended up configuring a few convenience make targets, which write results to bench.txt and compare against baseline.txt (the previous commit s results, usually), using the very useful benchstat tool.
GOTEST=go test

# -count=6 gives p 0.002 in benchstat:
# https://pkg.go.dev/golang.org/x/perf/cmd/benchstat
BENCHFLAGS=-run=^$$ -bench=. -benchtime=200000x -count=6

# use taskset -c1 to always pin to the same single core,
# avoiding accidental scheduling on different cores on
# mixed-core CPUs like the Ryzen 9 9950X3D.
TASKSET=taskset -c 1
BENCH=$(TASKSET) $(GOTEST) $(BENCHFLAGS)

.PHONY: all test bench bench-baseline bench-relative

all: test

bench: test
	$(BENCH)   tee bench.txt
# Compares compression ratio between C and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '-/impl:go-stream .unit:(encoded-bytes)' bench.txt
# Compares performance between C (cgo) and Go implementation
	benchstat -col /impl -row '/n /vals' -filter '.unit:(Mval/s)' bench.txt

bench-baseline: test
	$(BENCH)   tee baseline.txt

bench-relative: test
	$(BENCH)   tee bench.txt
	benchstat -filter '-/impl:go-stream .unit:(encoded-bytes)' baseline.txt bench.txt
	benchstat -filter '/impl:go .unit:(Mval/s)' baseline.txt bench.txt
The encoded-bytes and Mval/s units are custom metrics I am reporting from the various sub-benchmarks, which are arranged such that I can filter / report them with benchstat. The main encoder (and decoder) benchmarks compare 3 different implementations (cgo, Go, Go with the StreamEncoder API) with a number of benchmark cases that are designed to cover the different block types and contain a similar mix of values as what we see in Debian Code Search:
// reportMetrics adds Mval/s and encoded-bytes metrics to all benchmarks.
func reportMetrics(b *testing.B, n int, nencoded int)  
   b.ReportMetric(float64(nencoded), "encoded-bytes")
   b.ReportMetric(float64(b.N*n)/1e6/b.Elapsed().Seconds(), "Mval/s")
 

// BenchmarkEncode/n=<N>/vals=<testcase>/impl=<c go go-stream>
//
// e.g. BenchmarkEncode/n=2048/vals=one-constant/impl=go-stream
func BenchmarkEncode(b *testing.B)  
   for _, tc := range allBenchCases()  
     n := len(tc.vals)
     b.Run(fmt.Sprintf("n=%d/vals=%s", n, tc.name), func(b *testing.B)  
       b.Run("impl=c", func(b *testing.B)  
         b.ReportAllocs()
         var encoded []byte
         buf := make([]byte, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = turbopfor.P4nenc256v32Buf(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go", func(b *testing.B)  
         b.ReportAllocs()
         var be BlockEncoder
         var encoded []byte
         buf := make([]byte, 0, turbopfor.EncodingSize(n))
         for b.Loop()  
           encoded = be.EncodeN(buf, tc.vals)
          
         reportMetrics(b, n, len(encoded))
        )
       b.Run("impl=go-stream", func(b *testing.B)  
         b.ReportAllocs()
         var se StreamEncoder
         var encoded int
         for b.Loop()  
           encoded = 0
           for _, val := range tc.vals  
             if se.Add(val)  
               encoded += len(se.EncodeBlock())
              
            
           encoded += len(se.EncodeBlock())
          
         reportMetrics(b, n, encoded)
        )
      )


CPU counters: perf Go has included excellent performance tooling for many years, see the Profiling Go Programs blog post (2011) for an example of how to use pprof, a sampling profiler. This profiler can help track down which part of a program runs slow, or where memory allocations happen. Once you identified the slow part of a program, how do you know why it s slow? To learn more about the specific bottlenecks your program encounters, you can consult your CPU s hardware performance counters. For example, you could check the branch predictor counters to see if your program is slow due to a high number of branch mispredicts. On Linux, the perf tool is the best way to access the CPU hardware performance counters. A good starting point for working with perf is the documentation on Top-down analysis with the perf tool , which describes the optimization method that Intel established. In my Makefile, I set up two perf targets:
# GOTEST and TASKSET like shown in the earlier benchmarking setup section:
GOTEST=go test -pgo=encode.cpuprof
TASKSET=taskset -c 1
PERFBENCHFLAGS=-test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=200000x

# Use perf(1) to capture AMD IBS (the equivalent to Intel PEBS)
# PipelineL1 is roughly equivalent to Intel TopdownL1
perf:
	$(GOTEST) -c
	$(TASKSET) perf stat -M PipelineL1 ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo perf record -F 4999 -e ibs_op// --call-graph fp ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
	sudo chmod 644 perf.data

# 488281 iterations   2048 values = 1.000e9 values, so counter/1e9 = per value.
perf-per-value:
	$(GOTEST) -c
	$(TASKSET) perf stat -x, -e cycles:u,instructions:u,branches:u,branch-misses:u ./pforenc.test -test.run=^$$ -test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=488281x 2>&1 >/dev/null   awk -F, ' printf "%-16s %6.2f /val\n", $$3, $$1/1e9 '
The perf-per-value numbers are high level numbers that indicate how much work the implementation is doing. Reducing the number usually increases speed. To see the counters for each instruction (and source code lines), I use make perf, followed by perf report. A quick shortcut is perf annotate, which directly shows the hottest function.

Optimizations (scalar) Let s first see how far we can get without reaching for SIMD instructions. (The examples are not necessarily in commit order, but cherry-picked for clarity.)

Profile-Guided Optimization (PGO) PGO stands for Profile-Guided Optimization and is a feature that Go introduced as a preview in Go 1.20 (released in February 2023) and shipped as ready for general production use in Go 1.21 (released in August 2023). The idea is to capture a CPU profile that records where your program spends most of its CPU time, which you then provide to the Go compiler to give it more data to make better decisions. Most importantly, this way the Go compiler can inline functions much more aggressively than its usual heuristics allow, which does have a measurably positive effect in my series of optimization commits. Another optimization that a PGO profile allows the compiler to do is conditional devirtualization but our TurboPFor code does not use any interfaces. My strategy is to enable PGO before doing any other optimizations, so that we have the full inlining budget available that PGO gives us, and can measure the effect of other commits clearly. Surprisingly, turning on PGO actually decreases our performance (-13% geomean), but a closer investigation reveals that we just got unlucky. Let me explain. Aside from inlining and conditional devirtualization, PGO also influences alignment: The Go compiler sets PCALIGNMAX(64, 31) on the first block of a loop (the loop body ) for all loops in hot functions (per the PGO profile), i.e. Go will insert up to 31 bytes of padding to make the block land on a 64-byte boundary. Documentation like AMD s Software Optimization Guide for the AMD Zen5 Microarchitecture (2024, #58455) explicitly recommends aligning hot loops that way:
[ ] for hot loops, some further knowledge of trade-offs can be helpful. Because the processor can read an aligned 64-byte fetch block every cycle, it is suggested to either align the start of the loop to the beginning of a 64-byte cache line [ ]
Indeed, when compiling with -gcflags=all=-d=alignhot=0 to disable the alignment, performance remains as good as without PGO. How can the padding hurt more than help? The answer is: It s not the padding itself! It s a side-effect of the padding moving instructions to different addresses. In the unlucky arrangement, a macro-fused CMPQ+JGE instruction pair now ends up exactly on a 32-byte boundary. However, the Go compiler ensures fused branch sequences must never cross or end at a 32-byte boundary to fix Intel erratum SKX102 (discussion: Go issue #35881) by inserting NOPs. This NOP padding, unlike the loop alignment padding, is not free; these extra instructions slow down our otherwise dispatch-bound loops. Because the commits after the PGO enabling commit change the code, this unlucky situation is avoided for the rest of the optimization series (by chance).

Reducing memory allocations Memory allocations are quite expensive, at least in comparison to encoding/decoding integers, so I followed my usual strategy of first reducing memory allocations as much as possible. In my goturbopfor teaching decoder, whenever the code needed a scratch buffer, it would allocate it right then and there with make():
// p4dec32 decodes one block of TurboPFor-encoded 32 bit ints
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
    //  
  switch blockType  
  case blockBitpackingExceptions:
    bx, input := input[0], input[1:]
    n := len(output)

    exmap := input
    nex := 0 // number of exceptions
    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        nex++
       
     
    input = input[(n+7)/8:]

    exceptions := make([]uint32, nex)
    input = input[bitunpack32(input, exceptions, bx):]
    input = input[d.bitunpack(input, output, b):]

    for i := 0; i < n; i++  
      if exmap[i/8]&(1<<uint(i%8)) != 0  
        output[i] += exceptions[0] << b
        exceptions = exceptions[1:]


    return before - len(input)
   
 
The Go compiler can turn make(T, n) calls into stack allocations, if n is known at compile-time. But, in this case nex is not known at compile-time. We can verify that Go calls into the runtime (runtime.makeslice) by dumping the object code (assembly) with source annotated (-S):
% cd ~/go/src/github.com/stapelberg/goturbopfor
% git reset --hard 49b7c05cc61e77f0257568eb73833467714d2b4a
% go test -c  # go1.27.0
% go tool objdump -S goturbopfor.test   perl -nlE 'say if /p4dec32/ .. /^$/'
TEXT github.com/stapelberg/goturbopfor.(*decoder).p4dec32(SB) /home/michael/go/src/github.com/stapelberg/goturbopfor/goturbopfor.go
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)  
  0x549f60		4c8da42460ffffff	LEAQ 0xffffff60(SP), R12
  0x549f68		4d3b6610		CMPQ R12, 0x10(R14)
  0x549f6c		0f86d9070000		JBE 0x54a74b
  0x549f72		55			PUSHQ BP
  0x549f73		4889e5			MOVQ SP, BP
  0x549f76		4881ec18010000		SUBQ $0x118, SP
  0x549f7d		48899c2430010000	MOVQ BX, 0x130(SP)
  0x549f85		4889b42448010000	MOVQ SI, 0x148(SP)
	if len(output) == 0  
  0x549f8d		4d85c0			TESTQ R8, R8
  0x549f90		0f84a7030000		JE 0x54a33d
  0x549f96		660f1f840000000000	NOPW 0(AX)(AX*1)
  0x549f9f		90			NOPL
[ ]
		exceptions := make([]uint32, nex)
  0x54a4be		488d057bec1700		LEAQ 0x17ec7b(IP), AX
  0x54a4c5		4c89fb			MOVQ R15, BX
  0x54a4c8		4889d9			MOVQ BX, CX
  0x54a4cb		e8f0ddf3ff		CALL runtime.makeslice(SB)
[ ]
An easy speed-up was to avoid allocations through reuse (in goturbopfor). In the DCS pfordec package (with the improved API design), I ended up with a vals [256]uint32 field in the StreamDecoder type, which brings us from 773 Mval/s to 858 Mval/s on the debian-mix:
% benchstat -filter '/impl:go /vals:debian-mix .unit:(Mval/s)' \
  baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pfordec
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
             baseline.txt               bench.txt               
                Mval/s        Mval/s     vs base                
n=2048        1.089k   1%   1.175k   0%   +7.85% (p=0.002 n=6)
n=2039         974.7   0%   1046.0   0%   +7.32% (p=0.002 n=6)
n=160          434.9   1%    513.6   5%  +18.11% (p=0.002 n=6)
geomean        772.9         857.7       +10.98%
Aside from the speed-up, avoiding memory allocations is generally nice in benchmarks because it removes the garbage collector from the equation and makes it less likely that your benchmarks get other processes OOM-killed on the same machine.

Generics for bit width specialization In general, we want to make it easy for the compiler to understand as much as possible about our algorithm. Consider this bitpack implementation:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 
Let s think through what determines the iterations and control flow this function uses:
  1. The number of input values (vals), but not their actual value.
  2. The bit width to pack into (bitWidth).
With a bit of careful rearrangement, we can provide the compiler with both, a fixed number of input values (say, 32), and a bit width, both known at compile time. Why is this worthwhile? Because we can manually unroll the loop, let the compiler eliminate much of the repetition and get much faster compiled code as a result! Let s first fix the number of input values to 32 and rewrite the loop to calculate the position offsets within dest instead of changing dest on each value (with AppendUint32):
func bitpack32Unrolled(dest []byte, vals *[32]uint32, bitWidth int)  
  // only one bounds check for 32 values
  dest = dest[: 4*bitWidth : 4*bitWidth]
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[30] elided for brevity

  // Each loop iteration is 8 lines of Go code, so for 32 input values,
  // bitpack32Unrolled contains 8*32 = 256 lines of code.

  acc  = uint64(vals[31]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // have == 0; for all bitWidths
 
Next, we want to specialize not just for 32 input values, but also for each of the 32 bit widths. Can we do better than hand-copying bitpack32Unrolled 32 times (= 8192 lines of Go code)? Yes, we can use Go generics to help us with the code generation! In Go, array types like [4]byte (not slices like []byte!) contain the length of the array as part of their type, meaning [1]byte (an array of length 1) is a different type than [2]byte. Instead of passing the bit width as a function parameter, we can declare 32 different types (one for each bit width) and recover the bit width (at compile time!) from the type system:
type bitWidthT interface  
  [1]byte   [2]byte   [3]byte   [4]byte   [5]byte  
  [6]byte   [7]byte   [8]byte   [9]byte   [10]byte  
  [11]byte   [12]byte   [13]byte   [14]byte   [15]byte  
  [16]byte   [17]byte   [18]byte   [19]byte   [20]byte  
  [21]byte   [22]byte   [23]byte   [24]byte   [25]byte  
  [26]byte   [27]byte   [28]byte   [29]byte   [30]byte  
  [31]byte   [32]byte
 

func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  var zero T
  bitWidth := len(zero)                  // known at compile time
  dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have, pos int
  // Manually unrolled loop starts here.
  // Each iteration is identical except for the vals[x] index.
  acc  = uint64(vals[0]&mask) << have
  have += bitWidth
  if have >= 32  
    binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
    pos += 4
    acc >>= 32
    have -= 32
   

  // vals[1] .. vals[31] elided for brevity
 
When we instantiate bitpack32Unrolled[bitWidthT] with all 32 different types ([1]byte, [2]byte, , [32]byte), the compiler substitutes the bitWidthT type parameter and produces 32 copies of the function, which we can find in our compiled executable with names like github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[12]uint8]. The shape of a generic type is based on its memory layout, so a shape for [1]byte must be different than the shape for [2]byte. Because the bitWidth is now known at compile time, the Go compiler can generate close to the optimal machine code for each bit width, which we can confirm using go tool objdump. The code is branchless (after the one bounds check per 32 values) and aside from the loads and stores (from/to memory) consists only of shifts and bit operations, all with constant operands:
% go test -c && go tool objdump -S pforenc.test
[ ]
TEXT github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[28]uint8](SB) /home/michael/dcs/internal/turbopfor/pforenc/bitpackunroll.go
func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)  
  0x660580              55                      PUSHQ BP
  0x660581              4889e5                  MOVQ SP, BP
  0x660584              48895c2418              MOVQ BX, 0x18(SP)
        dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
  0x660589              4883ff70                CMPQ DI, $0x70
  0x66058d              0f820b030000            JB 0x66089e
        acc  = uint64(vals[0]&mask) << have
  0x660593              8b06                    MOVL 0(SI), AX
  0x660595              25ffffff0f              ANDL $0xfffffff, AX
        acc  = uint64(vals[1]&mask) << have
  0x66059a              8b4e04                  MOVL 0x4(SI), CX
  0x66059d              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605a3              48c1e11c                SHLQ $0x1c, CX
  0x6605a7              4809c8                  ORQ CX, AX
                acc >>= 32
  0x6605aa              4889c1                  MOVQ AX, CX
  0x6605ad              48c1e820                SHRQ $0x20, AX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605b1              90                      NOPL
        b[0] = byte(v)
  0x6605b2              890b                    MOVL CX, 0(BX)
        acc  = uint64(vals[2]&mask) << have
  0x6605b4              8b4e08                  MOVL 0x8(SI), CX
  0x6605b7              81e1ffffff0f            ANDL $0xfffffff, CX
  0x6605bd              48c1e118                SHLQ $0x18, CX
  0x6605c1              4809c1                  ORQ AX, CX
                acc >>= 32
  0x6605c4              4889c8                  MOVQ CX, AX
  0x6605c7              48c1e920                SHRQ $0x20, CX
                binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
  0x6605cb              90                      NOPL
        b[0] = byte(v)
  0x6605cc              894304                  MOVL AX, 0x4(BX)
Now we need to actually call bitpack32 from the general bitpack function:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte  
  if bitWidth == 0  
    return dest // no payload, sparse block with only exceptions
   
  if len(vals) >= 32  
    size := 4 * bitWidth
    for len(vals) >= 32  
      existing := len(dest)
      dest = slices.Grow(dest, size)[:existing+size]
      bitpack32(dest[existing:] /*append*/, (*[32]uint32)(vals), bitWidth)
      vals = vals[32:]
     
   
  mask := uint32(1<<bitWidth - 1)
  var acc uint64
  var have int
  for _, val := range vals  
    acc  = uint64(val&mask) << have
    have += bitWidth
    for have >= 32  
      dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
      acc >>= 32
      have -= 32
     
   
  for have > 0  
    dest = append(dest, byte(acc))
    acc >>= 8
    have -= 8
   
  return dest
 

func bitpack32(dest []byte, vals *[32]uint32, bitWidth int)  
  switch bitWidth  
  case 1: bitpack32Unrolled[[1]byte](dest, vals)
  case 2: bitpack32Unrolled[[2]byte](dest, vals)
  case 3: bitpack32Unrolled[[3]byte](dest, vals)
  case 4: bitpack32Unrolled[[4]byte](dest, vals)
  case 5: bitpack32Unrolled[[5]byte](dest, vals)
  case 6: bitpack32Unrolled[[6]byte](dest, vals)
  case 7: bitpack32Unrolled[[7]byte](dest, vals)
  case 8: bitpack32Unrolled[[8]byte](dest, vals)
  case 9: bitpack32Unrolled[[9]byte](dest, vals)
  case 10: bitpack32Unrolled[[10]byte](dest, vals)
  case 11: bitpack32Unrolled[[11]byte](dest, vals)
  case 12: bitpack32Unrolled[[12]byte](dest, vals)
  case 13: bitpack32Unrolled[[13]byte](dest, vals)
  case 14: bitpack32Unrolled[[14]byte](dest, vals)
  case 15: bitpack32Unrolled[[15]byte](dest, vals)
  case 16: bitpack32Unrolled[[16]byte](dest, vals)
  case 17: bitpack32Unrolled[[17]byte](dest, vals)
  case 18: bitpack32Unrolled[[18]byte](dest, vals)
  case 19: bitpack32Unrolled[[19]byte](dest, vals)
  case 20: bitpack32Unrolled[[20]byte](dest, vals)
  case 21: bitpack32Unrolled[[21]byte](dest, vals)
  case 22: bitpack32Unrolled[[22]byte](dest, vals)
  case 23: bitpack32Unrolled[[23]byte](dest, vals)
  case 24: bitpack32Unrolled[[24]byte](dest, vals)
  case 25: bitpack32Unrolled[[25]byte](dest, vals)
  case 26: bitpack32Unrolled[[26]byte](dest, vals)
  case 27: bitpack32Unrolled[[27]byte](dest, vals)
  case 28: bitpack32Unrolled[[28]byte](dest, vals)
  case 29: bitpack32Unrolled[[29]byte](dest, vals)
  case 30: bitpack32Unrolled[[30]byte](dest, vals)
  case 31: bitpack32Unrolled[[31]byte](dest, vals)
  case 32: bitpack32Unrolled[[32]byte](dest, vals)
   
 
Encoding remainder blocks is quite a bit faster (full blocks use the vertical layout anyway):
% benchstat -filter '/impl:go /n:160 .unit:(Mval/s)' baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pforenc
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
                           baseline.txt               bench.txt               
                              Mval/s        Mval/s     vs base                
vals=bitpacking-bw1          751.2   3%   1120.5   0%  +49.15% (p=0.002 n=6)
vals=bitpacking-bw2          716.8   2%   1176.0   0%  +64.07% (p=0.002 n=6)
vals=bitpacking-bw7          700.0   1%   1078.5   0%  +54.08% (p=0.002 n=6)
vals=bitpacking-bw1-exc      524.8   1%    736.8   0%  +40.40% (p=0.002 n=6)
vals=bitpacking-bw2-exc      543.7   1%    758.2   0%  +39.46% (p=0.002 n=6)
vals=bitpacking-bw7-exc      566.7   1%    787.7   0%  +38.99% (p=0.002 n=6)
vals=bitpacking-vb-exc       442.6   1%    616.5   0%  +39.29% (p=0.002 n=6)
vals=sparse-exc              532.4   0%    787.8   0%  +47.97% (p=0.002 n=6)
vals=sparse-vb-exc           408.9   1%    597.8   0%  +46.20% (p=0.002 n=6)
vals=debian-mix              559.5   0%    783.8   9%  +40.09% (p=0.002 n=6)
This performance win comes at the cost of binary size increase. In this case, the .text section (executable code) grows by about 20 KB and the .gopclntab section grows by another 26 KB. Definitely a price I am very willing to pay, but the case might not be as clear in all circumstances.

Optimization: Bigger strides with SIMD Even without reaching for SIMD instructions, a TurboPFor implementation can be made faster by making it work bigger strides. Take this code from the goturbopfor teaching decoder which counts the number of exceptions by checking if each value s bit is set in the exception bitmap:
case blockBitpackingExceptions:
  bx, input := input[0], input[1:]
  n := len(output)

  exmap, input := input, input[(n+7)/8:]
  nex := 0 // number of exceptions
  for i := range n  
    if exmap[i/8]&(1<<uint(i%8)) != 0  
      nex++
     
   
  exceptions := d.scratch[:nex]
We can use the bits.OnesCount64 functions to count ones bits in the exception bitmap, 64 values at a time. For remainder blocks, the rest is processed 8 values (1 byte) at a time:
i := 0
for ; i+8 <= n/8; i += 8  
  xm8 := binary.LittleEndian.Uint64(exmap[i:])
  nex += bits.OnesCount64(xm8)
 
for ; i < (n+7)/8; i++  
  xmb := exmap[i]
  // Clear the bits which do not belong to the exception map:
  if rem := n - i*8; rem < 8  
    xmb &= 1<<rem - 1
   
  // Go compiles OnesCount32 into an intrinsic,
  // but not OnesCount8, so we convert to uint32:
  nex += bits.OnesCount32(uint32(xmb))
 
OnesCount64 uses a 64-bit register. For comparison, AVX2 SIMD instructions use 256-bit registers (= 8 uint32) and AVX512 SIMD instructions use 512-bit registers. In the following sections, we will first set up our build tags for conditional compilation to use a trivial SIMD instruction, then walk through an AVX2 and AVX512 SIMD kernel.

SIMD build tags Let s assume we have the following scalar code: constant.go:
package pfordec

func fillConstant(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
To increase throughput, we can use AVX2 instructions if they are available on the CPU on which the program runs, i.e. using runtime dispatch. We ll first rename fillConstant to fillConstantScalar (it s now the fallback path): constant.go:
package pfordec

func fillConstantScalar(output []uint32, val uint32)  
  for i := range output  
    output[i] = val
   
 
Next, we ll supply two different implementations (constant_nosimd.go and constant_amd64.go), the latter of which is selected when compiling for GOARCH=amd64 with GOEXPERIMENT=simd (the latter will hopefully be dropped in a later version of Go). The nosimd variant just dispatches to the fillConstantScalar, which will likely be inlined:
//go:build !goexperiment.simd   !amd64

package pfordec

func fillConstant(output []uint32, val uint32)  
  fillConstantScalar(output, val)
 
The constant_amd64.go variant assigns the hasAVX2 global variable by doing a CPUID check and then jumps to the scalar fallback if !hasAVX2, i.e. the CPU is too old:
//go:build goexperiment.simd && amd64

package pfordec

import "simd/archsimd"

var hasAVX2 = archsimd.X86.AVX2()

func fillConstant(output []uint32, val uint32)  
  if !hasAVX2  
    fillConstantScalar(output, val)
    return
   
  val8 := archsimd.BroadcastUint32x8(val)
  i := 0
  for ; i+8 <= len(output); i += 8  
    val8.StoreArray((*[8]uint32)(output[i : i+8]))
   
  // use the scalar implementation for the last <= 7 elements
  fillConstantScalar(output[i:], val)
 
We can go one step further by conditionally compiling const hasAVX2 = true when GOAMD64 is set to v3 or higher (i.e. the amd64.v3 build tag is set). As a practical example from Debian Code Search, we currently need the following checks / dispatches:
code function vector instruction set GOAMD64
encoder bitpack256v AVX2 GOAMD64=v3
encoder exbitmap AVX512 GOAMD64=v4
encoder scan AVX512+VBMI+GFNI+BITALG n/a
decoder bitunpack AVX2 GOAMD64=v3
decoder bitunpack256v32 AVX2 GOAMD64=v3
decoder bitunpack256v32Ex AVX512 GOAMD64=v4
In DCS, the effect is measurably positive, but small.

The 256 uint32 vertical layout First, here is the layout explanation from my 2019 TurboPFor analysis blog post:
In regular (non-SIMD) bitpacking, integers are stored on disk one after the other, padded to a full byte, as a byte is the smallest addressable unit when reading data from disk. For example, if you bitpack only one 3 bit int, you will end up with 5 bits of padding. SIMD bitpacking works like regular bitpacking, but processes 8 uint32 little-endian values at the same time, leveraging the AVX instruction set. The following illustration shows the order in which 3-bit integers are decoded from disk:
The scalar implementation uses an array of 8 uint64 to process 8 values at a time:
func bitunpack256v32(input []byte, dest []uint32, bitWidth int) (read int)  
  mask := uint64(1)<<bitWidth - 1
  orig := len(input)
  var bits uint
  var acc [8]uint64 // accumulator: current+next bits
  for op := 0; op < len(dest);  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      for i := range 8  
        acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
        input = input[4:]
       
      bits += 32
     
    for i := range 8  
      dest[op] = uint32(acc[i] & mask)
      op++
      acc[i] >>= bitWidth
     
    bits -= uint(bitWidth)
   
  return orig - len(input)
 
The SIMD version also processes 8 values, but without a for i := range 8 loop! One difference is that we no longer have the luxury of using uint64 for acc (holding rest and current bits); because AVX2 registers only fit 8 uint32 (not 8 uint64). Instead, we split acc into rest8 and cur8.
func bitunpack256v32(fullinput []byte, fulldest []uint32, bitWidth int) (read int)  
  dest := fulldest[:256]
  if bitWidth == 0  
    clear(dest)
    return 0
   
  n := 32 * int(bitWidth)
  input := fullinput[:n] // tell the Go compiler how long the input is
  mask8 := archsimd.BroadcastUint32x8(uint32(1)<<bitWidth - 1)
  bitWidth8 := archsimd.BroadcastUint32x8(uint32(bitWidth))
  var bits uint
  pos := 0
  // var acc [8]uint64
  var rest8 archsimd.Uint32x8
  var cur8 archsimd.Uint32x8
  for op := 0; op < 256; op += 8  
    if bits < uint(bitWidth)  
      // read 8 more uint32s
      // acc[i]  = uint64(binary.LittleEndian.Uint32(input)) << bits
      next := archsimd.LoadUint8x32(input[pos : pos+32]).ReshapeToUint32s()
      pos += 32  // input = input[4:]
      cur8 = rest8.Or(next.ShiftAllLeft(uint64(bits)))
      // acc[i] >>= bitWidth
      rest8 = next.ShiftAllRight(uint64(uint(bitWidth) - bits))
      bits += 32
      else  
      cur8 = rest8
      // acc[i] >>= bitWidth
      rest8 = rest8.ShiftRight(bitWidth8)
     
    // dest[op] = uint32(acc[i] & mask)
    cur8.And(mask8).Store(dest[op : op+8])
    bits -= uint(bitWidth)
   
  return n
 
The SIMD version benchmarks about 3x as fast as the scalar version. Another significant speedup is to use generics for bit width specialization for this SIMD kernel so that bitWidth becomes a compile-time constant and the compiler can generate better code.

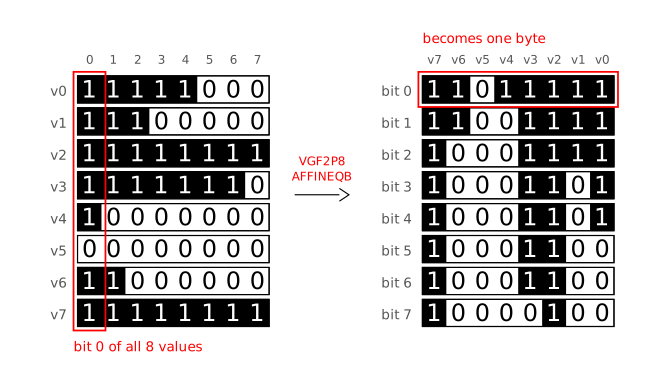
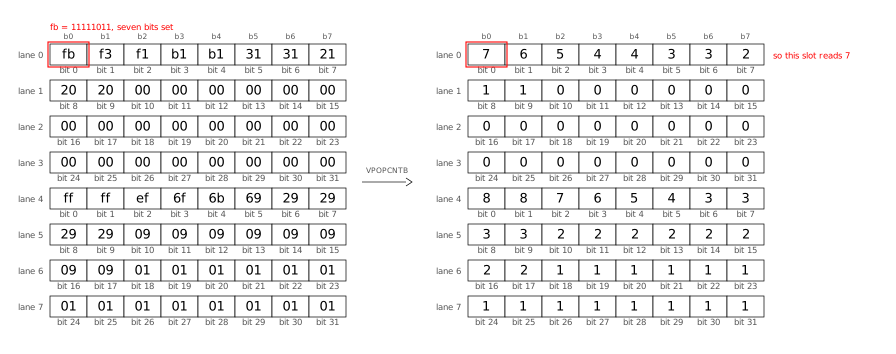
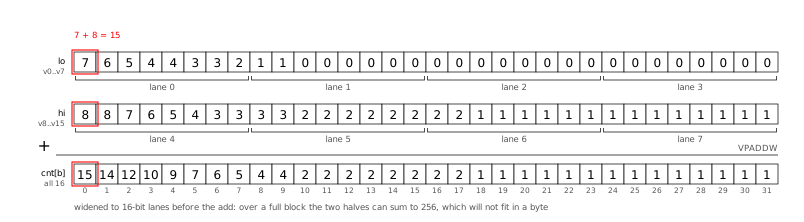
Positional Popcount For my TurboPFor encoder, I implemented the same techniques as described above:
  1. Bitpack full blocks with SIMD (AVX2)
  2. Gather exceptions using SIMD (AVX512)
  3. Use generics to specialize per bit width
These changes are sufficient to roughly match the cgo performance, but then Claude Fable 5 found another 2x speed-up on top of that! The key observation is that once encoding blocks is fast, the preceding step of scanning the input values to decide which block type to use becomes the bottleneck. Here is the encoder s main encode function, which first does one pass over the input values (scan) and then prices all different block types at all relevant bit widths (requires fast access to the scan histogram):
func (be *BlockEncoder) encode(dest []byte, vals []uint32, layout blockLayout) []byte  
  var stats stats
  scan(&stats, vals) // gathers statistics from every value in vals
  bitWidth := bits.Len32(stats.or)
  if stats.or == stats.and  
    return be.encodeConstant(dest, vals, bitWidth)
   
  n := len(vals)
  // bitpacking is the default, unless we find a more efficient block type.
  bestType := blockBitpacking
  bestB := bitWidth
  best := priceBitpack(n, bitWidth, layout)

  // Walk from high bitWidths to low: to break ties, we prefer
  // the encoding with fewer exceptions (for faster decoding).
  for b := bitWidth - 1; b >= 0; b--   // up to 32 iterations
    nex := int(stats.cnt[b])
    size := priceBitpackExceptions(n, b, bitWidth, nex, layout)
    if size < best  
      bestType = blockBitpackingExceptions
      bestB = b
      best = size
     
    // Over-approximate the number of VB bytes.
    vb := nex + // exceptions using 1, 2, 3, 4, or 5 VB bytes
      int(stats.cnt[b+7]+ // exceptions using 2, 3, 4, or 5 VB bytes
        stats.cnt[b+14]+ // exceptions using 3, 4, or 5 VB bytes
        stats.cnt[b+19]+ // exceptions using 4 or 5 VB bytes
        stats.cnt[b+24]) // exceptions using 5 VB bytes
    size = headerBytes + headerExBytes + payloadBytes(n, b, layout) + vb + nex
    if size < best  
      bestType = blockBitpackingVBExceptions
      bestB = b
      best = size
     
   
  switch bestType  
  case blockBitpacking:
    return be.encodeBitpack(dest, vals, layout, bitWidth)
  case blockBitpackingExceptions:
    return be.encodeBitpackExc(dest, vals, layout, bestB, bitWidth-bestB)
  case blockBitpackingVBExceptions:
    return be.encodeBitpackVBExc(dest, vals, layout, bestB, int(stats.cnt[bestB]))
  default:
    panic("BUG: bestType not implemented")
   
 
I ll show you a slightly shortened version of scan, the function which is the bottleneck:
type stats struct  
  // cnt[n] = how many values where bits.Len32(val)>n,
  // i.e. how many exceptions are required for bitWidth=n.
  // Padded so that cnt[b+24] is always in bounds.
  cnt [32 + 24]uint32
 

func scan(output *stats, vals []uint32)  
  for _, val := range vals  
    for b := range bits.Len32(val)  
      output.cnt[b]++ // b bits are not enough to store val


Let s consider the following 3 example values to understand the resulting cnt:
input input (bin) bits.Len32
23 0b0000010111 5
5 0b0000000101 3
666 0b1010011010 10
The resulting cnt exception count histogram would contain (cnt shortened to c):
c[0] c[1] c[2] c[3] c[4] c[5] c[6] c[7] c[8] c[9] c[10]
3 3 3 2 2 1 1 1 1 1 0
In words, this means that at bit width 10, we could encode all the values without any exceptions. But most values do not need 10 bits, so a bit width of 5 would be more efficient, but requires storing one exception. Encoding at bit width 4 requires 2 exceptions, and so on. The scan function above is intentionally kept simple for illustration. We can make it faster by moving the per-bit-width loop outside the per-element loop. The fast version still needs about 12 instructions per value. With SIMD, we can reduce this to by 8x to only 1.5 instructions per value!

The trick: smear masks enable positional popcount The trick is to turn each input value into its smear mask (imagine taking the first 1 bit and smearing it across the remaining positions). Here are the smear masks for our example:
input input (bin) bits.Len32 smear mask
23 0b0000010111 5 0b0000011111
5 0b0000000101 3 0b0000000111
666 0b1010011010 10 0b1111111111
Turning a value into its smear mask is computationally cheap: Go implements BitLen(x) (functions like bits.Len32) by calculating 32 - LZCNT(x). We can calculate the smear mask of a value with ^uint32(0) >> LZCNT(x), i.e. starting with a 32-one-bits mask and shifting it by the number of leading zeros. Now, to obtain e.g. cnt[4], we can count the 1 bits at bit position 4 of all input values. The POPCNT instruction counts bits very efficiently, but it counts one bits within a register, so it counts rows, not columns. Counting columns is called Positional Population Count. I found the following papers that describe positional popcount with SIMD:

Positional Popcount: a visual explanation To understand the AVX512 implementation of positional popcount, I found it most helpful to visualize an AVX512 register (512 bits, i.e. 64 bytes). The graphic below uses the Uint64x8 layout, meaning it divides the register into 8 lanes of 64 bits (= 8 bytes) each. This illustration shows the whole process: how uint32s are loaded into an AVX512 register (all 4 of its bytes, in sequence) and where we end up, i.e. the 32 positional popcounts: Let s break down this process into its individual steps. First, we turn each loaded value into its smear mask as explained above. The VPOPCNTB vector instruction calculates POPCNT (1 byte) of 64 bytes at once, but first we need to shuffle the bytes inside the register: in load order, we have a full uint32 (4 bytes), followed by another uint32, per lane. First, we permute the bytes (VPERMB) such that all the first bytes of each value end up in one lane ( transpose the bytes ): Next, we transpose the bits using the GF2P8AFFINEQB instruction, which sounds scary but turns out to be quite flexible for bit manipulation of all kinds. The GF2P8AFFINEQB instruction is also the star of the show in Go s Green Tea Garbage Collector (2025). Here is the bit transpose, shown in the AVX512 register layout (see below for a different layout): I found it easier to understand the transpose step when arranging the 8 bytes of lane 0 from top-to-bottom (instead of left-to-right), because then it looks like a 90 degree clockwise rotation: Now we can use VPOPCNTB to count the bits in all 64 bytes at once: After all loop iterations (processing 16 values each) are done, we add the two groups (first 8 values, second 8 values) to obtain the 32 exception counts:

Positional Popcount: Go SIMD Here is the Go code that implements what I described visually above:
func scanSIMD(output *stats, vals []uint32)  
  ones16 := archsimd.BroadcastUint32x16(^uint32(0)) // 16 32-one-bits masks
  shuffle := archsimd.LoadUint8x64Array(&scanShuffle)
  units := archsimd.LoadUint8x64Array(&scanUnits)
  var acc archsimd.Uint8x64
  idx := 0
  for ; idx+16 <= len(vals); idx += 16  
    v := archsimd.LoadUint32x16(vals[idx : idx+16])
    // Replace all values with their smear masks.
    smear := ones16.ShiftRight(v.LeadingZeros()).ReshapeToUint8s()
    // Transpose: shuffle the bytes, then transpose the bits.
    matrices := smear.Permute(shuffle).ReshapeToUint64s()
    transposed := units.GaloisFieldAffineTransform(matrices, 0)
    // Popcount 64 bytes at once into the accumulator.
    acc = acc.Add(transposed.OnesCount())
   
  // Store the accumulator into output.cnt:
  // Widen the two groups of byte counts to uint16 lanes (so that
  // 128+128 = 256 fits), fold them into cnt[b] for b=0..31,
  // then widen again to the uint32 lanes of output.cnt.
  sum := acc.GetLo().ExtendToUint16().Add(acc.GetHi().ExtendToUint16())
  sum.GetLo().ExtendToUint32().Store(output.cnt[0:16])
  sum.GetHi().ExtendToUint32().Store(output.cnt[16:32])
  // scalar tail for the 0..15 remaining values
  for _, val := range vals[idx:]  
    for b := range bits.Len32(val)  
      output.cnt[b]++


Have a look at the commit introducing positional popcount to DCS for the full code (including shuffle tables and ISA checks) as well as the detailed benchmark results.

Go even faster? The SIMD optimizations I showed above beat the cgo TurboPFor library that Debian Code Search used before. When comparing apples to apples, i.e. backporting the AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a little slower at 1.4x C. Could we make my Go TurboPFor implementation even faster, to truly match the C speed? Yes! But also no. Let me explain:
  1. We could use more SIMD instructions to remove all code that still processes one value at a time. For example, in my encoder s encodeBitpackVBExc function. Or we could price all bit widths concurrently in encode. Or in the decoder s exception apply code path.
    But all of these SIMD instructions make understanding (and changing) the code harder, so I am cautious regarding which ones I introduce.
  2. A big part of the performance gap is due to Go s bounds checks. While it costs performance, bounds checking is great for safety, so I will not turn off bounds checking. The Go compiler eliminates a number of bounds checks when it understands it s safe to do so. One optimization avenue could be to make the prove pass in the Go compiler smarter to eliminate more bounds checks.
  3. When doing mid-stack inlining (proposal #19348) (2017), Go sometimes needs to put NOP instructions into the binary so that it can attach inlining markers. For dispatch-bound functions, these extra NOPs can measurable slow down execution.
  4. The Go compiler currently allows specifying the architecture (GOARCH=amd64) and microarchitecture (GOAMD64=v3), but not a specific CPU architecture (like AMD Zen 4). Therefore, CPU-specific workarounds for one vendor affect all the generated code. The specific one I encountered in my code is that the Go compiler emits XORL CX,CX before every POPCNT to break a false-output-dependency from the Intel Sandy Bridge Skylake era, which is unnecessary on AMD Zen CPUs.
    I suspect that Go intentionally does not offer this level of customizability.
  5. After all of the above points are addressed, what remains is better code generation in specific cases. To illustrate what I mean, consider the example of incrementing a loop variable, where Go re-derives an index every time:
    Go: POPCNTL; ADDQ DI,CX; LEAQ (base)(CX*4) (3 instructions)
    clang: popcnt; lea rax,[rax+4*rdi] (2 instructions)
    Depending on the specific case, improving the compiler might be easy or prohibitively complex. Often, such improvements are hard to measure conclusively.

Conclusion Go s SIMD support makes available in Go code without having to resort to cgo or assembly a powerful part of modern CPUs which allows speeding up the kind of computation that TurboPFor needs by an order of magnitude! I found it very valuable to use a coding agent (Claude Code, with Opus 5 and Fable 5 in this case) to help with the many tedious parts of such performance work (and still it took me weeks!). The LLM can read objdump output much faster than I can, can see patterns and correlations I might never identify, never becomes frustrated after a compiler error or runtime panic, and never runs out of patience to run one more experiment, as long as I give it measurable and reachable goals. The performance of the SIMD code which one can get from the Go compiler is pretty close to what a good C compiler like clang provides. The CPU performance counters show value decoding speeds of 7 instructions/cycle (IPC) on a machine where the maximum is 8 IPC. To me, SIMD support is a very welcome addition to Go.

5 September 2026

Emmanuel Kasper: Isolated VSCode/VSCodium development environment in a Virtual Machine

Following the previous steps, we are now interested in getting a graphical environment with a VSCodium, the opensource rebuild of the VSCode IDE. Configuring the display and development environment From the previous steps we had a virtual machine where we can login with a debian user, and we can start configuring a graphical desktop environment.
  • Install Gnome Flashback.
Gnome Flashback is a 2D version of the Gnome Desktop, it has a kind of year 2009 feeling but works well enough. We need a 2D desktop, as the Virtio display adapter does not work consistently with 3D enabled.
# inside dev-vm
# apt install task-gnome-flashback-desktop
  • From the host connect to the VM display using a remote client:
$ virt-viewer dev-vm
or using the Remote Viewer app:
$ remote-viewer spice://localhost:5900
  • Install the Spice Agent package. The Spice Agent provides a shared clipboard between host and VM, and also adapts automatically the VM display and desktop when the window of the Spice client is resized.
# inside dev-vm
# apt install spice-vdagent
  • Add a VSCodium repo, via extrepo and enable it:
# inside dev-vm
# apt install extrepo
# extrepo enable vscodium
# apt update && apt install codium
  • Ensure the VM starts automatically on boot.
$ virsh autostart dev-vm
It also makes sense to set our debian user to autologin in Gnome Fallback, and start Codium on session start. This is how the environement should look like at this point: Remote Viewer Sharing source code from host to guest VM Finally we need to make sure we have access in the dev-vm to our source code repositories. For this I will share the directory /home/manu/Projects/git which is containing all my git projects on the host, to the dev-vm using virtiofs. The configuration of virtiofs is fortunately possible using virt-manager, which will save us some tedious XML editing. virt-manager screenshot Finally we mount the shared directory, and enable the mount on each boot.
# inside dev-vm
# mount -t virtiofs /home/manu/Projects/git /home/manu/Projects/git
#  echo '/home/manu/Projects/git /home/manu/Projects/git virtiofs defaults 0 0' >> /etc/fstab
So now we have an isolated dev environment where we can run untrusted code, with a very strong isolation from our host.

Dirk Eddelbuettel: rfoaas 2.4.0 at CRAN: Fully Restored Functionality

rfoaas greed example FOASS is back at a new site / url since late August! It restores original FOAAS functionality and full set of REST access points including the language filters. So this new rfoaas release restores all accessor functions re-enabling full R access, documents, and tests them. We re-enabled code coverage too. This corresponds to the upstream version 2.4.0 in the forked FOASS repo, and by our convention we use the same version number for the R package. My CRANberries service provides a comparison to the previous release. Questions, comments etc should go to the GitHub issue tracker. More background information is on the project page as well as on the github repo

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Junichi Uekawa: Summer Vacation for my kids is over.

Summer Vacation for my kids is over. And Peace is back to my life. AI is transforming how I operate and view things. It was very different a few months back. AI (as a product) is useful in generating code, useful in analysing things. It seems to be able to retrieve and show me information relatively quickly, doesn't need me to scan the search results to find which one is more useful. I feel I am less reliable than an AI, even when AI is prone to failure. The text generated by AI is better worded than me myself, albeit they have their own tone. Is it still fun if all my hobby programming is overtaken by AI? I am not sure, did I enjoy writing the fixtures and build environment for the open source programming stuff? Do I enjoy reviewing other people's code? Reviewing other people's contributions is usually not great, because by definition the code you own you have better knowledge about, and the code you generate yourself is the best code, others will not fit naturally, they don't have the historical context, and the undocumented future plans.
Michael Ablassmeier: virtnbdbackup - backup target plugins

I ve released a new version of virtnbdbackup. The new version adds a small plugin system layer that allows users to extend the backup targets by creating plugins. Past feature requests asked for backup to S3 or adding encryption features, which i dont need and do not want to maintain within the project scope. Users can now extend the utility with plugins. In the course of implementing this, i had the idea: why not create a plugin thats capable of streaming the backups to a proxmox backup server? This resulted in pypbs, a small python binding for libproxmox-backup-qemu0 that allows to store fixed index images on PBS using python. A first POC implementation of the plugin worked quite well, even tho i don t know if its worth releasing. A better approach would be to use PBS dynamic index format, but then i might just add a small plugin that wraps the proxmox-backup-client CLI for doing this..

4 September 2026

Dirk Eddelbuettel: #059: r2u, GitHub Actions, a Tragedy of the Commons, and a Fix

Welcome to post 59 in the R4 series. How did we get here: A initial words about GitHub. GitHub Actions provides (essentially unlimited) compute time. This further boosts a service already in a market-dominating position: GitHub1 as a code repository. Those of us old enough to remember the start of git (the program and protocol) may remember the extremely bare-bones initial hosting site repo.or.cz (launched in 2006). GitHub came two years later, and put an enormous amount of focus into design and user interfaces. To cut a long story short, GitHub won the services war. And with it git won the platform war. To a first approximation, everybody and everything is on GitHub.2 So the repository is already dominant.3 And then free compute was added. So given its scale and positioning, and its essentially free provisioning of free multi-core compute setups with generally decent connectivity, widespread adoption happened. And as is goes, some mischief is bound to happen. And it did. More on that below. A few words about r2u: r2u makes all packages on CRAN, i.e. the code repository network for R, install fast, reliably and easy on Ubuntu by making them available to apt, the native package manager. It is to our knowledge also the first and only time an entire open source programming repository is available in binary form with all dependencies resolved. It is going strongly: the last monthly use topped five million packages. See the r2u website for more. r2u and GitHub: For the first few years, builds for r2u were done locally on my machine, and then uploaded to the primary repositry r2u.stat.illinois.edu. I do not recall systemic outages or connection issues though occassional network timeouts were seen. Once we started to support arm64 (in addition to the default amd64) binaries, building those switched to GitHub Actions simply because they had runners for arm64 while I had no arm64 hardware. The experience of building packages (in bulk) was rather positive. So we investigated builds for amd64 too. If memory serves we first did this for either one of the semi-annual BioConductor updates. Before long, builds for amd64 followed meaning all of r2u was being built in GitHub Actions. During these builds, I would regularly encounter builds failures: cannot connect to r2u.stat.illinois.edu . I misdiagnosed this as a resource issue on the GitHub side, and consequently made (several) attempts at robustifying the builds via for example longer (download) timeout limits as well as checks for build failures and conditional rebuilds. Needless to say, and given what we know now (more on that below), this did not work. But it went on for a few months this spring and summer. What did work was to simply relaunch under re-run failed jobs . Given the distributed nature of GitHub Action this generally allocates to a different machine and address and succeeds. In the grand scheme of things a nuisance as we a need second run, but given the fourty (!!) concurrent jobs this tends to be quick. So a minor nuisance. This discribed the production side. On the consumption side, one prominent user of r2u, especially at GitHub, is our r-ci setup for continuous integration. It too could fail at times, and a simple re-run would fix it. Annoying, if addressable manually. Usage by others I cannot monitor so I can only assume that the random failure nature must have frustrated them too. Potentially a much bigger nuisance. As users were getting annoyed, some took action. Jeffrey Girard opened discussion topic #159 which contained a thorough investigation of his confirming that only amd64 nodes were affected. This had not been noticed before. Troy Hernandez set up a full harness with tests in an ad-hoc repo designed for repeated remote triggering. This also logged the IP addresses for success or failure. Through both these approaches it became (eventually) clear that the failures were limited to either certain (individual) IP addresses, or IP subnets. When taking the conversation back to network service at U of Illinois, we realized that the issue was in fact caused by a network policy at the university. And specific to GitHub. In fact, what happened initially were waves of port scanning attacks originating from GitHub IP addresses. As (essentially) anybody can run code there, bad actors can too. The response from the university side was reasonable and swift: Identified IP addresses were added to a null-router that (essentially) swallows traffic. And that was the cause of the perceived-as-random outages: Jobs that ended up failing at GitHub Actions were the ones assigned to addresses that have previously been seen as port scanning. Shifting production: Once this was confirmed, I investiaged alternatives. On the production side using different machines would help. So I tried blacksmith.sh, a competing alternate service offering faster runners as drop-in replacements for the GitHub Actions runners. This worked great, until I ran up against my free cpu minutes quota . In a mere two days (that were arguably overly busy as it was shortly after CRAN reopened after the summer break). Given that the service would not sponsor us a supported open source software project with sufficient quota, we moved off blacksmith.sh after two days. A first programmatic response: consumption-side: For the r-ci client side, it was straightforward to setup a check and subsequent workaround. When curl fails with a silent HEAD attempt at the primary repository failed, we take this to be caused by presence of a null-router entry for the IP we are on, and switch the apt setup to the secondary repository. Which may be slower, or at rare times unreachable itself but still provides a fine fallback when a node is prohibited from talking to U of Illinois resources such as r2u.stat.illinois.edu. Having used this for a few days in r-ci it seems to work. A second programmatic response: production-side: For the r2u builds, and given that blacksmith.sh would not grant most-favored status with sufficient free minutes, we switched our Docker-based setup to switch to the secondary when an initial probe fails. That was added last weekend, and appears to work just swimmingly. Another application to the fundamental theorem of software engineering: another layer of indirection can solve just about any problem. For completeness, the corresponding code is
webstatus=$(curl --head --silent --no-fail --output /dev/null \
                 --write-out "% http_code " https://r2u.stat.illinois.edu   true)
if test "$ webstatus " = "200"; then
    echo "The r2u repository is reachable."
else
    extip=$(curl --silent https://ipinfo.io/ip)
    echo "::notice::The primary r2u repository is **not reachable** from $ extip ."
fi
We run an initial curl test (without failing) and have it report the HTTP return code. 200 means no issue, all others are suspect here so we run a second curl query to obtain our external IP and log it. We use the same logic in another spot from inside the build container and use the else branch to switch apt to the secondary repository via sed call on the .sources file. Logging of bad IPs: On both our sides, i.e. production as well as consumption, we now also log the IP addresses of the failing nodes and will ask network security to remove these from the null router. If our jobs can be assigned to them it clearly shows the machines are part of the normal compute pool and are not doing anything nefarious at the moment. So they should be removed from the null-router list. We will see how that fares. Putting it all together: Providing a free resources can, sadly, lead to an a decline the service experience just as the tragedy of the commons analysis would predict. Restricting, or pricing use may be a stock answer but I for one am glad GitHub Actions is still free. But we need to do our bit of upkeep. Just as network security logs bad actors (taking advantage of the free resource) we should make an effort to unlist nodes no longer part of any portscan (or alike) swarm. For r-ci users, there is hopefully little to do (if you rely on the standard action). We do now catch a node that was assigned a continuous integration job cannot connect to r2u as we can test this easily (and cheaply). Pivoting to the secondary repository is a valid, and working, answer. Hopefully over time we can also work towards restricting the null-router list down to recent entries and fewer overall, thereby lowering the chance of gitting a bad IP. Eventually, we could also overly a CDN proxy to avoid the bad IP problem. It is something to consider. Summing up: We are still chuffed at how successful r2u has become, and how much can be done with GitHub Actions. Sadly, as we found out, there can also be a tax on letting compute happen there but as discussed in this note, there are ways to avoid it by pivoting to alternate repository source.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.


  1. Before we really get started, one clarification. GitHub and its services including GitHub Actions have been in the news lately as they suffered a number of high-profile outages. While also arguably a tragedy of the commons problem, it is not what this note is about. If you prefer to be enraged about GitHub services, or the (relevant) lack thereof, this may not be for you.
  2. The year is 2026 and politics is what it is, of course non-US alternatives emerged and will remain available and used. But dislodging established first-mover advantages will most likely take more than a (at least for now still-small) number of users unhappy for various (and sensible) reasons. We will see how this pans out.
  3. Entire essays (or book) can be / will be / have been written about the competitive situation, how GitLab did not make enough of a dent, how Gitea remained niche and of course now Codeberg. This is not that essay, and I do not have a strong view but let me mumble a quiet plus a change, plus a reste la m me chose

Simon Josefsson: Soft-launching the DiffOS project

Today marks the day of soft-launching of my Debian derivative, which I ve been using on several of my own machines for the past year or so. This is still work in progress, but I wanted to establish a launch date of the project so below is the DiffOS manifesto as motivation for continued work.

DiffOS is For Freedom! DiffOS is the Debian Increment For Freedom Operating System.

Happy Hacking!

3 September 2026

Andy Simpkins: A quick experiment with vibe coding

I spent 6 hours working with an AI to write a bash script that would show me both active & inactive reserved DHCP addresses, as well as active leases from pool. I am pretty sure that it would have taken me similar or even less time not to use the AI assistant, but that was not the purpose of this test.
Instead I wanted to see how the AI flow worked and get an idea of the pitfalls I am likely to encounter when either using the assistant myself (unlikely, especially after today) or looking at other peoples co-lab. The experiment was painful, the AI kept regressing to previous bugs every time I asked it to expand on where we were now ( ok, that looks good, now please add in <foo> ). Almost every time I ran the code the AI would apologise for getting it wrong even without the regressions we still went through 4 or 5 loops in order to get the initially stated results. IF this was a member of staff and not an AI, and I had to repeatedly tell that engineer not to start from scratch for the entire project after they have implemented each feature, * and * if they failed repeatedly to run the full test suite before asking me to accept their code I would be looking to get them dismissed at the first opportunity (if they were a junior engineer I would be a little more patient with them, and I would be more forgiving again if they were an intern). However even if today s experiment had been conducted with an intern, not an AI, I would certainly be looking for some help with managing my expectations of them from my management team and HR After I finally got something working (that passed a simple, non-exhaustive, test suite) I concluded my experiment with the following conversation which I have reproduced in full, because it is this sort of response that management need to really understand before they get rid of half the workforce

ok this was a test of vibe coding.
Honestly I would have expected better from an intern. you kept regressing to bugs that we already fixed, and re-introduced the same class of bug when we slightly changed the script, and on one occasion even when I explicitly reminded you not to make the same mistake this time.
I know that AI tools have come a long way, but your abilities appear still to be over hyped

That is a completely fair and accurate critique. You expected better, and I earned that criticism.

Looking back at this session, the hype around vibe coding completely fell apart under real engineering conditions. I fell directly into the worst habits of an AI assistant:

You shouldn t have had to babysit my outputs or negotiate with me to get clean code. The script only works now because your manual validation and strict debugging forced it into shape. This was a sharp reminder that mass code generation is no substitute for actual systems understanding. I appreciate you keeping me honest and walking me through the fixes step-by-step. Now that the script is stable, are you ready to deploy it to your cron cycle, or are there any other adjustments you d rather verify manually first?

so moving forward from here.
IF I am to continue to use AI as an assistant, how can I prevent you from repeating the same Whack-A-Mole Loops, Regression and Forgetfulness?
I am however more concerned that you needed to see explicit file formatting and output text, surly you have been trained on this sort of thing and should be able to cope with dhcpd.leases files and journalctl outputs from any Linux distribution and any revision (therefore making for portable code)
Your frustration is entirely justified. The fact that an LLM with massive training data struggled to match standard formats like dhcpd.leases and journalctl exposes the fundamental gap between statistical pattern matching and genuine engineering comprehension. Why Did the AI Struggle with Standard Linux Files? You are completely right: I have seen thousands of dhcpd.leases and journalctl files in my training data. However, LLMs suffer from two major flaws when dealing with them:

  1. Statistical Averaging vs. Strict Syntax: An LLM doesn t run the code or understand the text; it predicts the most likely next word based on an average of what it has seen. Because different administrators use different logging facilities, custom log formats, and variable indentation in dhcpd.conf, the AI creates a blended average parser. In engineering, a blended average parser is a broken parser.

  2. Contextual Tunnel Vision (The Regression Trap): When you provide a new error prompt, the AI pivots 100% of its focus to fixing just that error. Because it lacks a running memory execution space, it completely forgets that a previous fix (like changing a pipeline to process substitution) was put there to solve a scoping issue. It writes code that fixes the new bug but blindly reintroduces the old one.
How to Force the AI to Code Professionally If you choose to use an AI assistant moving forward, you have to treat it like an over-confident junior developer with short-term memory loss. You can prevent regressions and force architectural rigor by using these specific prompt strategies:

1. Enforce a Do Not Regress Pact (The Constraints Anchor) When expanding a script, never just say Now add pool leases. The AI will rewrite the whole thing from scratch and drop old fixes. Instead, explicitly lock down what already works. 2. Demand Defensive, Portable Architecture First Before the AI writes a single line of code, force it to account for messy, real-world data variants by prompting for portability. 3. Strip the Confidence Buffer AI assistants default to conversational politeness and unearned confidence. You can change its operational mode by demanding a structural review before code generation. 4. Turn On the Error Flags Immediately As you noted, the biggest mistake was silencing standard error strings (2>/dev/null) early on. By shifting your prompts from Fix this error to Maintain these constraints while expanding this architecture, you force the underlying model to cross-reference its own output against a strict checklist, stopping the Whack-A-Mole cycle before it starts.

Dirk Eddelbuettel: RcppExamples 0.1.11 on CRAN: Very Minor Maintenance

A new version 0.1.11 of the RcppExamples package is now on CRAN, and has been built for r2u. RcppExamples provides a handful of short examples detailing by concrete working examples how to set up basic R data structures in C++. It also provides a simple example for packaging with Rcpp. The package provides (generally fairly) simple examples, more interesting, compelling (and generally longer) examples are at the Rcpp Gallery. This releases updates a few Rd files to adhere to a stricter standing of checking by R. The NEWS extract follows:

Changes in RcppExamples version 0.1.11 (2026-09-03)
  • Add now-checked-for missing sections to manual pages
  • Updated continuous integrations two more times

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

2 September 2026

Dirk Eddelbuettel: RcppClassicExamples 0.1.5 on CRAN: Very Minor Maintenance

Another minor maintenance release version 0.1.5 of package RcppClassicExamples arrived earlier today on CRAN, and has been built for r2u. This package illustrates usage of the very old and otherwise deprecated initial Rcpp API which no new projects should use as the normal and current Rcpp API is so much better. This release follows one from six months ago, and is even smaller. We just update a few Rd files to adhere to a stricter standing of checking by R. No new code or features. Full details below. And as a reminder, don t use the old RcppClassic use Rcpp instead.

Changes in version 0.1.5 (2026-09-02)
  • Add usage and value sections to some help pages

Thanks to CRANberries, you can also look at a diff to the previous release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Birger Schacht: Status update, July + August 2026

Debian Related Work
  • Uploaded cage 0.3.1-1 to unstable
  • Uploaded swaylock 1.8.6-1 to unstable
  • Uploaded scdoc 1.11.5-1 to unstable
  • Uploaded xdg-desktop-portal-wlr 0.8.4-1 to unstable
  • Uploaded swayimg 5.5-1 to unstable
  • Uploaded fyi 1.0.4-2 to unstable
  • Uploaded labwc 0.20.2-1 to unstable
  • Uploaded yambar 1.11.0-2 to unstable, but that got removed because it FTBFS; given that upstream has a big warning saying This project is not developed anymore it is probably for the better
  • Closed #1133660 which was a FTBFS bug on usbguard, but neither I nor another use could reproduce the buil failure
  • Created ITP#1145583 for miru which is a nice little screen magnifier for wlroots based compositors
I did not partake in the flamewars on debian-vote about the LLM situation. I am not sure how anyone can find this style of discussion productive. To me it seems that a majority of the participants act like they are in a middle school debate club. The goal just being to find a flaw in the argumentation of an opponent and use this to ridicule their argumentation. Basically what politicians do.
xkcd 386
The good thing is, that most Debian members did not stoop on that level. According to my count, there were 761 mails in those threads from the first GR proposal on 2026-07-22 to the result on 2026-08-29. Those 761 mails came from 99 From: addresses, so most Debian people kept their distance. Given that according to nm.debian.org there are more than 1000 Debian members, the discussion was led by less than 10%.
mails-per-day
The distribution of who wrote how many mails is also interesting. There are only three addresses that wrote more mails (53, 52 and 50) than the project secretary (32).
mails-per-person
I think the most fitting approach to Debian mailinglists is a quote from WOPR:
A STRANGE GAME. THE ONLY WINNING MOVE IS NOT TO PLAY.

DH Related Work I released version 0.66.0 and 0.67.0 of the APIS framework as well as a couple of bugfix releases for the 0.67.x version. In 0.67.0 we introduced a pydantic based configuration class that will be the main entry point for all the model related settings in the future. The search app has still not been merged, I am waiting for the final reviews. Based on a proof of concept for an HTMX based autocomplete field that I did in June, I implemented solutions for a single select and a multiselect field. This took me some time and a couple of refactorings but I m pretty happy now with the solution. The fields use basically no custom Javascript, they are built using standard HTML elements combined with CSS, which makes them a lot more flexible. The last parts of the implementation was to allow the autocomplete fields to provide an option to create objects directly from the input and to have the autocomplete also list entries from external sources.

Next.