Search Results: "Yadd"

9 September 2025

Sven Hoexter: debian/watch version 5 is a beauty

Kudos to yadd@ (and who else was involved to make that happen), for the new watch file v5 format. Especially templates for the big git hoster make it much nicer. Prepared two of my packages to switch on the next upload, exfatprogs tracking github releases and pflogsumm scraping a web page. That is much easier to read and less error prone.

16 May 2025

Freexian Collaborators: Monthly report about Debian Long Term Support, April 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In April, 22 contributors have been paid to work on Debian LTS, their reports are available:
  • Adrian Bunk did 56.25h (out of 56.25h assigned).
  • Andreas Henriksson did 15.0h (out of 20.0h assigned), thus carrying over 5.0h to the next month.
  • Andrej Shadura did 10.0h (out of 6.0h assigned and 4.0h from previous period).
  • Bastien Roucari s did 31.5h (out of 31.5h assigned).
  • Ben Hutchings did 8.0h (out of 0.0h assigned and 12.0h from previous period), thus carrying over 4.0h to the next month.
  • Carlos Henrique Lima Melara did 11.0h (out of 12.0h assigned), thus carrying over 1.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 26.0h (out of 26.0h assigned).
  • Emilio Pozuelo Monfort did 30.0h (out of 39.25h assigned and 0.25h from previous period), thus carrying over 9.5h to the next month.
  • Guilhem Moulin did 8.5h (out of 3.25h assigned and 11.75h from previous period), thus carrying over 6.5h to the next month.
  • Jochen Sprickerhof did 12.5h (out of 20.75h assigned and 9.25h from previous period), thus carrying over 17.5h to the next month.
  • Lee Garrett did 26.25h (out of 7.75h assigned and 31.75h from previous period), thus carrying over 13.25h to the next month.
  • Lucas Kanashiro did 50.0h (out of 0.0h assigned and 52.0h from previous period), thus carrying over 2.0h to the next month.
  • Markus Koschany did 39.5h (out of 39.5h assigned).
  • Roberto C. S nchez did 9.0h (out of 0.0h assigned and 12.0h from previous period), thus carrying over 3.0h to the next month.
  • Santiago Ruano Rinc n did 12.5h (out of 7.5h assigned and 7.5h from previous period), thus carrying over 2.5h to the next month.
  • Sean Whitton did 7.0h (out of 7.0h assigned).
  • Stefano Rivera did 0.5h (out of 0.0h assigned and 10.0h from previous period), thus carrying over 9.5h to the next month.
  • Sylvain Beucler did 39.5h (out of 39.25h assigned and 0.25h from previous period).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Tobias Frost did 12.0h (out of 7.75h assigned and 4.25h from previous period).
  • Utkarsh Gupta did 2.0h (out of 2.0h assigned).

Evolution of the situation In April, we released 46 DLAs.
  • Notable security updates:
    • jetty9, prepared by Markus Koschany, fixes an information disclosure and potential remote code execution vulnerability
    • zabbix, prepared by Tobias Frost, fixes several vulnerabilities, encompassing denial of service, information disclosure or remote code inclusion
    • glibc, prepared by Sean Whitton, fixes a buffer overflow vulnerability
  • Notable non-security updates:
    • tzdata, prepared by Emilio Pozuelo Monfort, brings the latest timezone database release
    • php-horde-editor and php-horde-imp, prepared by Sylvain Beucler, have been updated to switch from CKEditor v3, which is EOL, to CKEditor v4; this builds upon work done last month by Sylvain and Bastien for the complete removal of ckeditor3
    • distro-info-data, prepared by Stefano Rivera, adds information concerning future Debian and Ubuntu releases
The LTS team continues to welcome the collaboration of maintainers and other interested parties from outside the regular team. In April, we had external updates contributed by: Yadd - lemonldap-ng and Moritz Schlarb - libapache2-mod-auth-openidc A point release of the current stable Debian 12 (codename bookworm ) is planned for mid-May and several LTS contributors have prepared packages for this update, many of them prepared in conjunction with related LTS updates of the same packages:
  • glib2.0, haproxy, imagemagick, poppler, and python-h11, prepared by Adrian Bunk
  • rubygems, prepared by Lucas Kanashiro
  • ruby3.1 (in collaboration with Lucas Kanashiro), twitter-bootstrap3, twitterboot-strap4, wpa, and erlang, prepared by Bastien Roucari s (corresponding updates of twitter-bootstrap3 and twitter-bootstrap4 were also uploaded to Debian unstable)
  • abseil, prepared by Tobias Frost (a corresponding update was also uploaded to Debian unstable)
  • vips, prepared by Guilhem Moulin
Additional updates of ruby3.3 and rubygems were prepared for Debian unstable by Lucas Kanashiro. And finally, a highlight of our continued commitment to enhancing long term support efforts in upstream projects. Freexian, as the primary entity behind the management and execution of the LTS project, has partnered with Invisible Things Lab to extend the upstream security support of Xen 4.17, which is shipped in Debian 12 bookworm (the current stable release). This partnership will result in significantly improved lifecycle support for users of Xen on bookworm, and members of the LTS team will play a part in this endeavour. The Freexian announcement has additional details.

Thanks to our sponsors Sponsors that joined recently are in bold.

7 May 2025

Jonathan Dowland: procmail versus exim filters

I ve been using Procmail to filter mail for a long time. Reading Antoine s blog post procmail considered harmful, I felt motivated (and shamed) into migrating to something else. Luckily, Enrico's shared a detailed roadmap for moving to Sieve, in particular Dovecot's Sieve implementation (which provides "pipe" and "filter" extensions). My MTA is Exim, and for my first foray into this, I didn't want to change that1. Exim provides two filtering languages for users: an implementation of Sieve, and its own filter language. Requirements A good first step is to look at what I'm using Procmail for:
  1. I invoke external mail filters: processes which read the mail and emit a possibly altered mail (headers added, etc.). In particular, crm114 (which has worked remarkably well for me) to classify mail as spam or not, and dsafilter, to mark up Debian Security Advisories
  2. I file messages into different folders depending on the outcome of the above filters
  3. I drop mail ("killfile") some sender addresses (persistent pests on mailing lists); and mails containing certain hosts in the References header (as an imperfect way of dropping mailing list threads which are replies to someone I've killfiled); and mail encoded in a character set for a language I can't read (Russian, Korean, etc.), and several other simple static rules
  4. I move mailing list mail into folders, semi-automatically (see list filtering)
  5. I strip "tagged" subjects for some mailing lists: i.e., incoming mail has subjects like "[cs-historic-committee] help moving several tons of IBM360", and I don't want the "[cs-historic-committee]" bit.
  6. I file a copy of some messages, the name of which is partly derived from the current calendar year
Exim Filters I want to continue to do (1), which rules out Exim's implementation of Sieve, which does not support invoking external programs. Exim's own filter language has a pipe function that might do what I need, so let's look at how to achieve the above with Exim Filters. autolists Here's an autolist recipe for Debian's mailing lists, in Exim filter language. Contrast with the Procmail in list filtering:
if $header_list-id matches "(debian.*)\.lists\.debian\.org"
then
  save Maildir/l/$1/
  finish
endif
Hands down, the exim filter is nicer (although some of the rules on escape characters in exim filters, not demonstrated here, are byzantine). killfile An ideal chunk of configuration for kill-filing a list of addresses is light on boiler plate, and easy to add more addresses to in the future. This is the best I could come up with:
if foranyaddress "someone@example.org,\
                  another@example.net,\
                  especially-bad.example.com,\
                 "
   ($reply_address contains $thisaddress
    or $header_references contains $thisaddress)
then finish endif
I won't bother sharing the equivalent Procmail but it's pretty comparable: the exim filter is no great improvement. It would be lovely if the list of addresses could be stored elsewhere, such as a simple text file, one line per address, or even a database. Exim's own configuration language (distinct from this filter language) has some nice mechanisms for reading lists of things like addresses from files or databases. Sadly it seems the filter language lacks anything similar. external filters With Procmail, I pass the mail to an external program, and then read the output of that program back, as the new content of the mail, which continues to be filtered: subsequent filter rules inspect the headers to see what the outcome of the filter was (is it spam?) and to decide what to do accordingly. Crucially, we also check the return status of the filter, to handle the case when it fails. With Exim filters, we can use pipe to invoke an external program:
pipe "$home/mail/mailreaver.crm -u $home/mail/"
However, this is not a filter: the mail is sent to the external program, and the exim filter's job is complete. We can't write further filter rules to continue to process the mail: the external program would have to do that; and we have no way of handling errors. Here's Exim's documentation on what happens when the external command fails:
Most non-zero codes are treated by Exim as indicating a failure of the pipe. This is treated as a delivery failure, causing the message to be returned to its sender.
That is definitely not what I want: if the filter broke (even temporarily), Exim would seemingly generate a bounce to the sender address, which could be anything, and I wouldn't have a copy of the message. The documentation goes on to say that some shell return codes (defaulting to 73 and 75) cause Exim to treat it as a temporary error, spool the mail and retry later on. That's a much better behaviour for my use-case. Having said that, on the rare occasions I've broken the filter, the thing which made me notice most quickly was spam hitting my inbox, which my Procmail recipe achieves. removing subject tagging Here, Exim's filter language gets unstuck. There is no way to add or alter headers for a message in a user filter. Exim uses the same filter language for system-wide message filtering, and in that context, it has some extra functions: headers add <string>, headers remove <string>, but (for reasons I don't know) these are not available for user filters. copy mail to archive folder I can't see a way to derive a folder name from the calendar year. next steps Exim Sieve implementation and its filter language are ruled out as Procmail replacements because they can't do at least two of the things I need to do. However, based on Enrico's write-up, it looks like Dovecot's Sieve implementation probably can. I was also recommended maildrop, which I might look at if Dovecot Sieve doesn't pan out.

  1. I should revisit this requirement because I could probably reconfigure exim to run my spam classifier at the system level, obviating the need to do it in a user filter, and also raising the opportunity to do smtp-time rejection based on the outcome

5 March 2025

Otto Kek l inen: Will decentralized social media soon go mainstream?

Featured image of post Will decentralized social media soon go mainstream?In today s digital landscape, social media is more than just a communication tool it is the primary medium for global discourse. Heads of state, corporate leaders and cultural influencers now broadcast their statements directly to the world, shaping public opinion in real time. However, the dominance of a few centralized platforms X/Twitter, Facebook and YouTube raises critical concerns about control, censorship and the monopolization of information. Those who control these networks effectively wield significant power over public discourse. In response, a new wave of distributed social media platforms has emerged, each built on different decentralized protocols designed to provide greater autonomy, censorship resistance and user control. While Wikipedia maintains a comprehensive list of distributed social networking software and protocols, it does not cover recent blockchain-based systems, nor does it highlight which have the most potential for mainstream adoption. This post explores the leading decentralized social media platforms and the protocols they are based on: Mastodon (ActivityPub), Bluesky (AT Protocol), Warpcast (Farcaster), Hey (Lens) and Primal (Nostr).

Comparison of architecture and mainstream adoption potential
Protocol Identity System Example Storage model Cost for end users Potential
Mastodon Tied to server domain @ottok@mastodon.social Federated instances Free (some instances charge) High
Bluesky Portable (DID) ottoke.bsky.social Federated instances Free Moderate
Farcaster ENS (Ethereum) @ottok Blockchain + off-chain Small gas fees Moderate
Lens NFT-based (Polygon) @ottok Blockchain + off-chain Small gas fees Niche
Nostr Cryptographic Keys npub16lc6uhqpg6dnqajylkhwuh3j7ynhcnje508tt4v6703w9kjlv9vqzz4z7f Federated instances Free (some instances charge) Niche

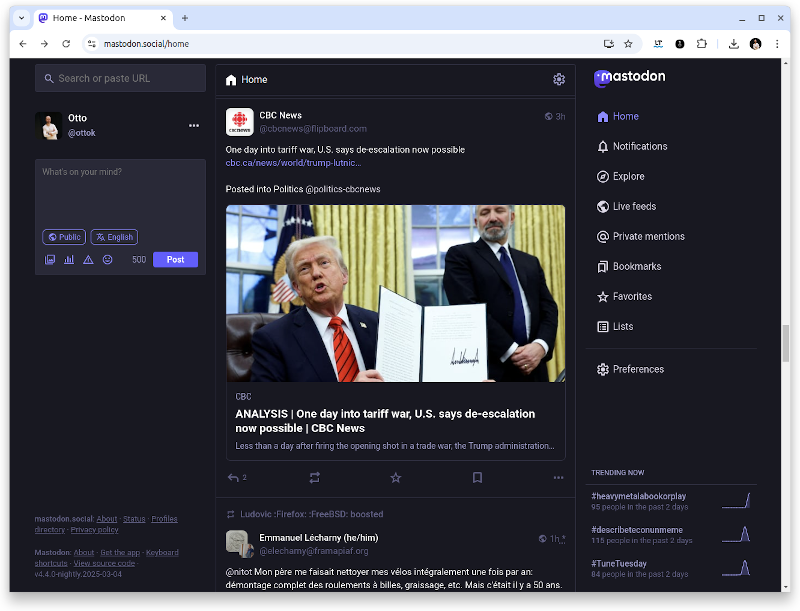
1. Mastodon (ActivityPub) Screenshot of Mastodon Mastodon was created in 2016 by Eugen Rochko, a German software developer who sought to provide a decentralized and user-controlled alternative to Twitter. It was built on the ActivityPub protocol, now standardized by W3C Social Web Working Group, to allow users to join independent servers while still communicating across the broader Mastodon network. Mastodon operates on a federated model, where multiple independently run servers communicate via ActivityPub. Each server sets its own moderation policies, leading to a decentralized but fragmented experience. The servers can alternatively be called instances, relays or nodes, depending on what vocabulary a protocol has standardized on.
  • Identity: User identity is tied to the instance where they registered, represented as @username@instance.tld.
  • Storage: Data is stored on individual instances, which federate messages to other instances based on their configurations.
  • Cost: Free to use, but relies on instance operators willing to run the servers.
The protocol defines multiple activities such as:
  • Creating a post
  • Liking
  • Sharing
  • Following
  • Commenting

Example Message in ActivityPub (JSON-LD Format)
json
 
 "@context": "https://www.w3.org/ns/activitystreams",
 "type": "Create",
 "actor": "https://mastodon.social/users/ottok",
 "object":  
 "type": "Note",
 "content": "Hello from #Mastodon!",
 "published": "2025-03-03T12:00:00Z",
 "to": ["https://www.w3.org/ns/activitystreams#Public"]
  
 
Servers communicate across different platforms by publishing activities to their followers or forwarding activities between servers. Standard HTTPS is used between servers for communication, and the messages use JSON-LD for data representation. The WebFinger protocol is used for user discovery. There is however no neat way for home server discovery yet. This means that if you are browsing e.g. Fosstodon and want to follow a user and press Follow, a dialog will pop up asking you to enter your own home server (e.g. mastodon.social) to redirect you there for actually executing the Follow action on with your account. Mastodon is open source under the AGPL at github.com/mastodon/mastodon. Anyone can operate their own instance. It just requires to run your own server and some skills to maintain a Ruby on Rails app with a PostgreSQL database backend, and basic understanding of the protocol to configure federation with other ActivityPub instances.

Popularity: Already established, but will it grow more? Mastodon has seen steady growth, especially after Twitter s acquisition in 2022, with some estimates stating it peaked at 10 million users across thousands of instances. However, its fragmented user experience and the complexity of choosing instances have hindered mainstream adoption. Still, it remains the most established decentralized alternative to Twitter. Note that Donald Trump s Truth Social is based on the Mastodon software but does not federate with the ActivityPub network. The ActivityPub protocol is the most widely used of its kind. One of the other most popular services is the Lemmy link sharing service, similar to Reddit. The larger ecosystem of ActivityPub is called Fediverse, and estimates put the total active user count around 6 million.

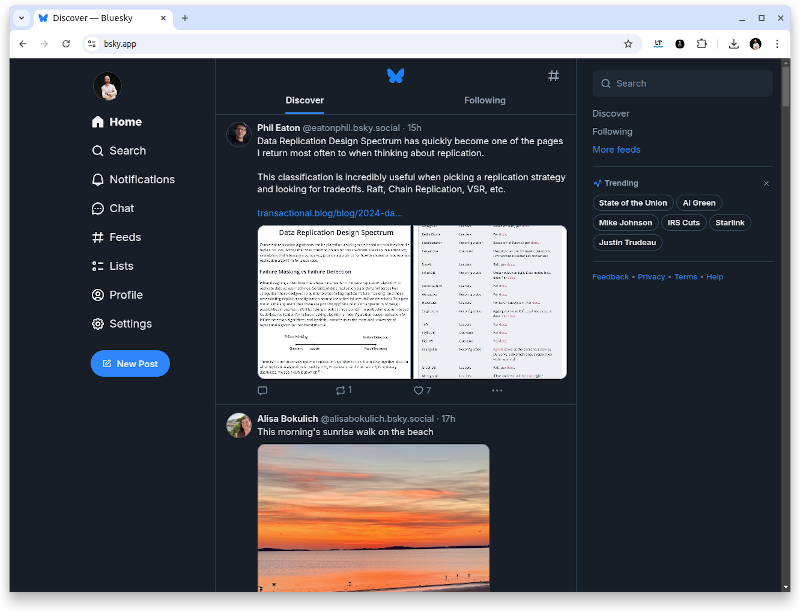
2. Bluesky (AT Protocol) Screenshot of Bluesky Interestingly, Bluesky was conceived within Twitter in 2019 by Twitter founder Jack Dorsey. After being incubated as a Twitter-funded project, it spun off as an independent Public Benefit LLC in February 2022 and launched its public beta in February 2023. Bluesky runs on top of the Authenticated Transfer (AT) Protocol published at https://github.com/bluesky-social/atproto. The protocol enables portable identities and data ownership, meaning users can migrate between platforms while keeping their identity and content intact. In practice, however, there is only one popular server at the moment, which is Bluesky itself.
  • Identity: Usernames are domain-based (e.g., @user.bsky.social).
  • Storage: Content is theoretically federated among various servers.
  • Cost: Free to use, but relies on instance operators willing to run the servers.

Example Message in AT Protocol (JSON Format)
json
 
 "repo": "did:plc:ottoke.bsky.social",
 "collection": "app.bsky.feed.post",
 "record":  
 "$type": "app.bsky.feed.post",
 "text": "Hello from Bluesky!",
 "createdAt": "2025-03-03T12:00:00Z",
 "langs": ["en"]


Popularity: Hybrid approach may have business benefits? Bluesky reported over 3 million users by 2024, probably getting traction due to its Twitter-like interface and Jack Dorsey s involvement. Its hybrid approach decentralized identity with centralized components could make it a strong candidate for mainstream adoption, assuming it can scale effectively.

3. Warpcast (Farcaster Network) Farcaster was launched in 2021 by Dan Romero and Varun Srinivasan, both former crypto exchange Coinbase executives, to create a decentralized but user-friendly social network. Built on the Ethereum blockchain, it could potentially offer a very attack-resistant communication medium. However, in my own testing, Farcaster does not seem to fully leverage what Ethereum could offer. First of all, there is no diversity in programs implementing the protocol as at the moment there is only Warpcast. In Warpcast the signup requires an initial 5 USD fee that is not payable in ETH, and users need to create a new wallet address on the Ethereum layer 2 network Base instead of simply reusing their existing Ethereum wallet address or ENS name. Despite this, I can understand why Farcaster may have decided to start out like this. Having a single client program may be the best strategy initially. One of the decentralized chat protocol Matrix founders, Matthew Hodgson, shared in his FOSDEM 2025 talk that he slightly regrets focusing too much on developing the protocol instead of making sure the app to use it is attractive to end users. So it may be sensible to ensure Warpcast gets popular first, before attempting to make the Farcaster protocol widely used. As a protocol Farcaster s hybrid approach makes it more scalable than fully on-chain networks, giving it a higher chance of mainstream adoption if it integrates seamlessly with broader Web3 ecosystems.
  • Identity: ENS (Ethereum Name Service) domains are used as usernames.
  • Storage: Messages are stored in off-chain hubs, while identity is on-chain.
  • Cost: Users must pay gas fees for some operations but reading and posting messages is mostly free.

Example Message in Farcaster (JSON Format)
json
 
 "fid": 766579,
 "username": "ottok",
 "custodyAddress": "0x127853e48be3870172baa4215d63b6d815d18f21",
 "connectedWallet": "0x3ebe43aa3ae5b891ca1577d9c49563c0cee8da88",
 "text": "Hello from Farcaster!",
 "publishedAt": 1709424000,
 "replyTo": null,
 "embeds": []
 

Popularity: Decentralized social media + decentralized payments a winning combo? Ethereum founder Vitalik Buterin (warpcast.com/vbuterin) and many core developers are active on the platform. Warpcast, the main client for Farcaster, has seen increasing adoption, especially among Ethereum developers and Web3 enthusiasts. I too have an profile at warpcast.com/ottok. However, the numbers are still very low and far from reaching network effects to really take off. Blockchain-based social media networks, particularly those built on Ethereum, are compelling because they leverage existing user wallets and persistent identities while enabling native payment functionality. When combined with decentralized content funding through micropayments, these blockchain-backed social networks could offer unique advantages that centralized platforms may find difficult to replicate, being decentralized both as a technical network and in a funding mechanism.

4. Hey.xyz (Lens Network) The Lens Protocol was developed by decentralized finance (DeFi) team Aave and launched in May 2022 to provide a user-owned social media network. While initially built on Polygon, it has since launched its own Layer 2 network called the Lens Network in February 2024. Lens is currently the main competitor to Farcaster. Lens stores profile ownership and references on-chain, while content is stored on IPFS/Arweave, enabling composability with DeFi and NFTs.
  • Identity: Profile ownership is tied to NFTs on the Polygon blockchain.
  • Storage: Content is on-chain and integrates with IPFS/Arweave (like NFTs).
  • Cost: Users must pay gas fees for some operations but reading and posting messages is mostly free.

Example Message in Lens (JSON Format)
json
 
 "profileId": "@ottok",
 "contentURI": "ar://QmExampleHash",
 "collectModule": "0x23b9467334bEb345aAa6fd1545538F3d54436e96",
 "referenceModule": "0x0000000000000000000000000000000000000000",
 "timestamp": 1709558400
 

Popularity: Probably not as social media site, but maybe as protocol? The social media side of Lens is mainly the Hey.xyz website, which seems to have fewer users than Warpcast, and is even further away from reaching critical mass for network effects. The Lens protocol however has a lot of advanced features and it may gain adoption as the building block for many Web3 apps.

5. Primal.net (Nostr Network) Nostr (Notes and Other Stuff Transmitted by Relays) was conceptualized in 2020 by an anonymous developer known as fiatjaf. One of the primary design tenets was to be a censorship-resistant protocol and it is popular among Bitcoin enthusiasts, with Jack Dorsey being one of the public supporters. Unlike the Farcaster and Lens protocols, Nostr is not blockchain-based but just a network of relay servers for message distribution. If does however use public key cryptography for identities, similar to how wallets work in crypto.
  • Identity: Public-private key pairs define identity (with prefix npub...).
  • Storage: Content is federated among multiple servers, which in Nostr vocabulary are called relays.
  • Cost: No gas fees, but relies on relay operators willing to run the servers.

Example Message in Nostr (JSON Format)
json
 
 "id": "note1xyz...",
 "pubkey": "npub1...",
 "kind": 1,
 "content": "Hello from Nostr!",
 "created_at": 1709558400,
 "tags": [],
 "sig": "sig1..."
 

Popularity: If Jack Dorsey and Bitcoiners promote it enough? Primal.net as a web app is pretty solid, but it does not stand out much. While Jack Dorsey has shown support by donating $1.5 million to the protocol development in December 2021, its success likely depends on broader adoption by the Bitcoin community.

Will any of these replace X/Twitter? As usage patterns vary, the statistics are not fully comparable, but this overview of the situation in March 2025 gives a decent overview.
Platform Total Accounts Active Users Growth Trend
Mastodon ~10 million ~1 million Steady
Bluesky ~33 million ~1 million Steady
Nostr ~41 million ~20 thousand Steady
Farcaster ~850 thousand ~50 thousand Flat
Lens ~140 thousand ~20 thousand Flat
Mastodon and Bluesky have already reached millions of users, while Lens and Farcaster are growing within crypto communities. It is however clear that none of these are anywhere close to how popular X/Twitter is. In particular, Mastodon had a huge influx of users in the fall of 2022 when Twitter was acquired, but to challenge the incumbents the growth would need to significantly accelerate. We can all accelerate this development by embracing decentralized social media now alongside existing dominant platforms. Who knows, given the right circumstances maybe X.com leadership decides to change the operating model and start federating contents to break out from a walled garden model. The likelyhood of such development would increase if decentralized networks get popular, and the encumbents feel they need to participate to not lose out.

Past and future The idea of decentralized social media is not new. One early pioneer identi.ca launched in 2008, only two years after Twitter, using the OStatus protocol to promote decentralization. A few years later it evolved into pump.io with the ActivityPump protocol, and also forked into GNU Social that continued with OStatus. I remember when these happened, and that in 2010 also Diaspora launched with fairly large publicity. Surprisingly both of these still operate (I can still post both on identi.ca and diasp.org), but the activity fizzled out years ago. The protocol however survived partially and evolved into ActivityPub, which is now the backbone of the Fediverse. The evolution of decentralized social media over the next decade will likely parallel developments in democracy, freedom of speech and public discourse. While the early 2010s emphasized maximum independence and freedom, the late 2010s saw growing support for content moderation to combat misinformation. The AI era introduces new challenges, potentially requiring proof-of-humanity verification for content authenticity. Key factors that will determine success:
  • User experience and ease of onboarding
  • Network effects and critical mass of users
  • Integration with existing web3 infrastructure
  • Balance between decentralization and usability
  • Sustainable economic models for infrastructure
This is clearly an area of development worth monitoring closely, as the next few years may determine which protocol becomes the de facto standard for decentralized social communication.

12 June 2024

Freexian Collaborators: Monthly report about Debian Long Term Support, May 2024 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In May, 17 contributors have been paid to work on Debian LTS, their reports are available:
  • Adrian Bunk did 34.25h (out of 24.0h assigned and 22.0h from previous period), thus carrying over 11.75h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 16.0h (out of 24.0h assigned), thus carrying over 8.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 8.0h (out of 10.0h assigned), thus carrying over 2.0h to the next month.
  • Emilio Pozuelo Monfort did 35.5h (out of 46.0h assigned), thus carrying over 10.5h to the next month.
  • Guilhem Moulin did 13.0h (out of 14.75h assigned and 5.25h from previous period), thus carrying over 7.0h to the next month.
  • Lee Garrett did 11.0h (out of 37.25h assigned and 8.75h from previous period), thus carrying over 35.0h to the next month.
  • Lucas Kanashiro did 10.0h (out of 20.0h assigned), thus carrying over 10.0h to the next month.
  • Markus Koschany did 40.0h (out of 40.0h assigned).
  • Ola Lundqvist did 6.5h (out of 22.5h assigned and 1.5h from previous period), thus carrying over 17.5h to the next month.
  • Roberto C. S nchez did 7.75h (out of 11.0h assigned and 1.0h from previous period), thus carrying over 4.25h to the next month.
  • Santiago Ruano Rinc n did 8.0h (out of 16.0h assigned), thus carrying over 8.0h to the next month.
  • Sean Whitton did 5.5h (out of 5.5h assigned and 0.5h from previous period), thus carrying over 0.5h to the next month.
  • Sylvain Beucler did 10.5h (out of 0.75h assigned and 45.25h from previous period), thus carrying over 35.5h to the next month.
  • Thorsten Alteholz did 14.0h (out of 14.0h assigned).
  • Tobias Frost did 7.75h (out of 10.0h assigned and 2.0h from previous period), thus carrying over 4.25h to the next month.

Evolution of the situation In May, we have released 20 DLAs. Notable security updates in May included:
  • apache2: multiple vulnerabilities which may result in HTTP response splitting, denial of service, or authorization bypass (by Bastien Roucari s, in collaboration with apache2 maintainer Yadd)
  • bind9: two vulnerabilities, called KeyTrap and NSEC3, which may result in denial of service (by Santiago Ruano Rinc n)
  • python-pymysql: potential SQL injection attack (by Chris Lamb)
The aforementioned apache2 was prepared by its Debian maintainer Yadd. This update also involved work on the package test suite in buster, which contributor Bastien Roucari s then forwarded to the apache2 package in unstable. More importantly, a regression in fossil was reported, and Bastien prepared a fix for it. Bastien coordinated the upload of both packages to minimize the introduction of regressions. Contributor Daniel Leidert also prepared an upload of runc to Debian 11 in order fix a number of CVEs still affecting that package. Finally, contributor Thorsten Alteholz prepared uploads for qtbase-opensource-src, libjwt, and libmicrohttpd in Debian 11. Note that Debian 11 will pass into the LTS phase of support in August and these updates will improve the state and long-term supportability of Debian 11. Debian 10 is presently in its final month of LTS support (as announced on the debian-lts-announce mailing list, support will end on June 30th), after which no new security updates will be made available on security.debian.org. However, Freexian and its team of paid Debian contributors will continue to maintain Debian 10 going forward for the customers of the Extended LTS offer. Subscribe right away if you sill have Debian 10 which must be kept secure (and which cannot yet be upgraded).

Thanks to our sponsors Sponsors that joined recently are in bold.

5 June 2021

Utkarsh Gupta: FOSS Activites in May 2021

Here s my (twentieth) monthly update about the activities I ve done in the F/L/OSS world.

Debian
This was my 29th month of actively contributing to Debian. I became a DM in late March 2019 and a DD on Christmas 19! \o/ Interesting month, surprisingly. Lots of things happening and lots of moving parts; becoming the new normal , I believe. Anyhow, working on Ubuntu full-time has its own advantage and one of them is being able to work on Debian stuff! So whilst I couldn t upload a lot of packages because of the freeze, here s what I worked on:

Uploads and bug fixes:

Other $things:
  • Mentoring for newcomers and assisting people in BSP.
  • Moderation of -project mailing list.

Ubuntu
This was my 4th month of actively contributing to Ubuntu. Now that I ve joined Canonical to work on Ubuntu full-time, there s a bunch of things I do! \o/ This month, by all means, was dedicated mostly to PHP 8.0, transitioning from PHP 7.4 to 8.0. Naturally, it had so many moving parts and moments of utmost frustration, shared w/ Bryce. :D So even though I can t upload anything, I worked on the following stuff & asked for sponsorship.
But before, I d like to take a moment to stress how kind and awesome Gianfranco Costamagna, a.k.a. LocutusOfBorg is! He s been sponsoring a bunch of my things & helping with re-triggers, et al. Thanks a bunch, Gianfranco; beers on me whenever we meet!

Merges:

Uploads & Syncs:

MIRs:

Seed Operations:

Debian (E)LTS
Debian Long Term Support (LTS) is a project to extend the lifetime of all Debian stable releases to (at least) 5 years. Debian LTS is not handled by the Debian security team, but by a separate group of volunteers and companies interested in making it a success. And Debian Extended LTS (ELTS) is its sister project, extending support to the Jessie release (+2 years after LTS support). This was my twentieth month as a Debian LTS and eleventh month as a Debian ELTS paid contributor.
I was assigned 29.75 hours for LTS and 40.00 hours for ELTS and worked on the following things:

LTS CVE Fixes and Announcements:

ELTS CVE Fixes and Announcements:

Other (E)LTS Work:
  • Front-desk duty from 24-05 until 30-05 for both LTS and ELTS.
  • Triaged rails, libimage-exiftool-perl, hivex, graphviz, glibc, libexosip2, impacket, node-ws, thunar, libgrss, nginx, postgresql-9.6, ffmpeg, composter, and curl.
  • Mark CVE-2019-9904/graphviz as ignored for stretch and jessie.
  • Mark CVE-2021-32029/postgresql-9.6 as not-affected for stretch.
  • Mark CVE-2020-24020/ffmpeg as not-affected for stretch.
  • Mark CVE-2020-22020/ffmpeg as postponed for stretch.
  • Mark CVE-2020-22015/ffmpeg as ignored for stretch.
  • Mark CVE-2020-21041/ffmpeg as postponed for stretch.
  • Mark CVE-2021-33574/glibc as no-dsa for stretch & jessie.
  • Mark CVE-2021-31800/impacket as no-dsa for stretch.
  • Mark CVE-2021-32611/libexosip2 as no-dsa for stretch.
  • Mark CVE-2016-20011/libgrss as ignored for stretch.
  • Mark CVE-2021-32640/node-ws as no-dsa for stretch.
  • Mark CVE-2021-32563/thunar as no-dsa for stretch.
  • [LTS] Help test and review bind9 update for Emilio.
  • [LTS] Suggest and add DEP8 tests for bind9 for stretch.
  • [LTS] Sponsored upload of htmldoc to buster for Havard as a consequence of #988289.
  • [ELTS] Fix triage order for jetty and graphviz.
  • [ELTS] Raise issue upstream about cloud-init; mock tests instead.
  • [ELTS] Write to private ELTS list about triage ordering.
  • [ELTS] Review Emilio s new script and write back feedback, mentioning extra file created, et al.
  • [ELTS/LTS] Raise upgrade problems from LTS -> LTS+1 to the list. Thread here.
    • Further help review and raise problems that could occur, et al.
  • [LTS] Help explain path forward for firmware-nonfree update to Ola. Thread here.
  • [ELTS] Revert entries of TEMP-0000000-16B7E7 and TEMP-0000000-1C4729; CVEs assigned & fix ELTS tracker build.
  • Auto EOL ed linux, libgrss, node-ws, and inspircd for jessie.
  • Attended monthly Debian LTS meeting, which didn t happen, heh.
  • Answered questions (& discussions) on IRC (#debian-lts and #debian-elts).
  • General and other discussions on LTS private and public mailing list.

Until next time.
:wq for today.

25 March 2015

Francois Marier: Keeping up with noisy blog aggregators using PlanetFilter

I follow a few blog aggregators (or "planets") and it's always a struggle to keep up with the amount of posts that some of these get. The best strategy I have found so far to is to filter them so that I remove the blogs I am not interested in, which is why I wrote PlanetFilter.

Other options In my opinion, the first step in starting a new free software project should be to look for a reason not to do it :) So I started by looking for another approach and by asking people around me how they dealt with the firehoses that are Planet Debian and Planet Mozilla. It seems like a lot of people choose to "randomly sample" planet feeds and only read a fraction of the posts that are sent through there. Personally however, I find there are a lot of authors whose posts I never want to miss so this option doesn't work for me. A better option that other people have suggested is to avoid subscribing to the planet feeds, but rather to subscribe to each of the author feeds separately and prune them as you go. Unfortunately, this whitelist approach is a high maintenance one since planets constantly add and remove feeds. I decided that I wanted to follow a blacklist approach instead.

PlanetFilter PlanetFilter is a local application that you can configure to fetch your favorite planets and filter the posts you see. If you get it via Debian or Ubuntu, it comes with a cronjob that looks at all configuration files in /etc/planetfilter.d/ and outputs filtered feeds in /var/cache/planetfilter/. You can either:
  • add file:///var/cache/planetfilter/planetname.xml to your local feed reader
  • serve it locally (e.g. http://localhost/planetname.xml) using a webserver, or
  • host it on a server somewhere on the Internet.
The software will fetch new posts every hour and overwrite the local copy of each feed. A basic configuration file looks like this:
[feed]
url = http://planet.debian.org/atom.xml
[blacklist]

Filters There are currently two ways of filtering posts out. The main one is by author name:
[blacklist]
authors =
  Alice Jones
  John Doe
and the other one is by title:
[blacklist]
titles =
  This week in review
  Wednesday meeting for
In both cases, if a blog entry contains one of the blacklisted authors or titles, it will be discarded from the generated feed.

Tor support Since blog updates happen asynchronously in the background, they can work very well over Tor. In order to set that up in the Debian version of planetfilter:
  1. Install the tor and polipo packages.
  2. Set the following in /etc/polipo/config:
     proxyAddress = "127.0.0.1"
     proxyPort = 8008
     allowedClients = 127.0.0.1
     allowedPorts = 1-65535
     proxyName = "localhost"
     cacheIsShared = false
     socksParentProxy = "localhost:9050"
     socksProxyType = socks5
     chunkHighMark = 67108864
     diskCacheRoot = ""
     localDocumentRoot = ""
     disableLocalInterface = true
     disableConfiguration = true
     dnsQueryIPv6 = no
     dnsUseGethostbyname = yes
     disableVia = true
     censoredHeaders = from,accept-language,x-pad,link
     censorReferer = maybe
    
  3. Tell planetfilter to use the polipo proxy by adding the following to /etc/default/planetfilter:
     export http_proxy="localhost:8008"
     export https_proxy="localhost:8008"
    

Bugs and suggestions The source code is available on repo.or.cz. I've been using this for over a month and it's been working quite well for me. If you give it a go and run into any problems, please file a bug! I'm also interested in any suggestions you may have.

8 August 2014

Ian Donnelly: How-To: Write a Plug-In (Part 3, Coding)

Hi Everybody! Hope you have been enjoying my tutorial on writing plug-ins so far. In Part 1 we covered the basic overview of a plug-in. Part 2 covered a plug-in s contract and the best way to write one. Now, for Part 3 we are going to cover the meat of a plug-in, the actual coding. As you should know from reading Part 1, there are five main functions used for plug-ins, elektraPluginOpen, elektraPluginGet, elektraPluginSet, ELEKTRA_PLUGIN_EXPORT(Plugin), where Plugin should be replaced with the name of your plug-in. We are going to start this tutorial by focusing on the elektraPluginGet because it usually is the most critical function. As we discussed before, elektraPluginGet is the function responsible for turning information from a file into a usable KeySet. This function usually differs pretty greatly between each plug-in. This function should be of type int, it returns 0 on success or another number on an error. The function will take in a Key, usually called parentKey which contains a string containing the path to the file that is mounted. For instance, if you run the command kdb mount /etc/linetest system/linetest line then keyString(parentKey) should be equal to /etc/linetest . At this point, you generally want to open the file so you can begin saving it into keys. Here is the trickier part to explain. Basically, at this point you will want to iterate through the file and create keys and store string values inside of them according to what your plug-in is supposed to do. I will give a few examples of different plug-ins to better explain. My line plug-in was written to read files into a KeySet line by line using the newline character as a delimiter and naming the keys by their line number such as (#1, #2, .. #_22) for a file with 22 lines. So once I open the file given by parentKey, every time a I read a line I create a new key, let s call it new_key using dupKey(parentKey). Then I set new_keys s name to lineNN (where NN is the line number) using keyAddBaseName and store the string value of the line into the key using keySetString. Once the key is initialized, I append it to the KeySet that was passed into the elektraPluginGet function, let s call it returned for now, using ksAppendKey(return, new_key). Now the KeySet will contain new_key with the name lineNN properly saved where it should be according to the kdb mount command (in this case, system/linetest/lineNN), and a string value equal to the contents of that line in the file. MY plug-in repeats these steps as long as it hasn t reached end of file, thus saving the whole file into a KeySet line by line. The simpleini plug-in works similarly, but it parses for ini files instead of just line-by-line. At their most simple level, ini files are in the format of name=value with each pair taking one line. So for this plug-in, it makes a lot of sense to name each Key in the KeySet by the string to the left of the = sign and store the value into each key as a string. For instance, the name of the key would be name and keyGetString(name) would return value .
As you may have noticed, simpleini and line plug-ins work very similarly. However, they just parse the files differently. The simpleini plug-in parses the file in a way that is more natural to ini file (setting the key s name to the left side of the equals sign and the value to the right side of the equals sign.) The elektraPluginGet function is the heart of a storage plug-in, its what allows Elektra to store configurations in it s database. This function isn t just run when a file is first mounted, but whenever a file gets updated, this function is run to update the Elektra Key Database to match. We also gave a brief overview of elektraPluginSet function. This function is basically the opposite of elektraPluginGet. Where elektraPluginGet reads information from a file into the Elektra Key Database, elektraPluginSet writes information from the database back into the mounted file. First have a look at the signature of elektraLineSet: elektraLineSet(Plugin *handle ELEKTRA_UNUSED, KeySet *toWrite, Key *parentKey) Lets start with the most important parameters, the KeySet and the parentKey. The KeySet supplied is the KeySet that is going to be persisted in the file. In our case it would contain the Keys representing the lines. The parentKey is the topmost Key of the KeySet at serves several purposes. First, it contains the filename of the destination file as its value. Second, errors and warnings can be emitted via the parentKey. We will discuss error handling in more detail later. The Plugin handle can be used to persist state information in a threadsafe way with elektraPluginSetData. As our plugin is not stateful and therefore does not use the handle, it is marked as unused in order to supress compiler warnings. Basically the implementation of elektraLineSet can be described with the following pseudocode:

open the file
if (error)

ELEKTRA_SET_ERROR(74, parentKey, keyString(parentKey));

for each key

write the key value together with a newline

close the file
The fullblown code can be found at https://github.com/ElektraInitiative/libelektra/blob/master/src/plugins/line/line.c As you can see, all elektraLineSet does is open a file, take each Key from the KeySet (remember they are named #1, #2 #_22) in order, and write each key as it s own line in the file. Since we don t care about the name of the Key in this case (other than for order), we just write the value of keyString for each Key as a new line in the file. That s it. Now, each time the mounted KeySet is modified, elektraPluginSet will be called and the mounted file will be updated. We haven t discussed ELEKTRA_SET_ERROR yet. Because Elektra is a library, printing errors to stderr wouldn t be a good idea. Instead, errors and warnings can be appended to a key in the form of metadata. This is what ELEKTRA_SET_ERROR does. Because the parentKey always exists even if a critical error occurres, we append the error to the parentKey. The first parameter is an id specifying the general error that occurred. A listing of existing errors together with a short description and a categorization can be found at https://github.com/ElektraInitiative/libelektra/blob/master/src/liberror/specification. The third parameter can be used to provide additional information about the error. In our case we simply supply the filename of the file that caused the error. The kdb tools will interprete this error and print it in a pretty way. Notice that this can be used in any plugin function where the parentKey is available. The elektraPluginOpen and elektraPluginClose functions are not commonly used for storage plug-ins, but they can be useful and are worth reviewing. elektraPluginOpen function runs before elektraPluginGet and is useful to do initialization if necessary for the plug-in. On the other hand elektraPluginClose is run after other functions of the plug-in and can be useful for freeing up resources. The last function, one that is always needed in a plug-in, is ELEKTRA_PLUGIN_EXPORT. This functions is responsible for letting Elektra know that the plug-in exists and which methods it implements. The code from my line function is a good example and pretty self-explanatory:

Plugin *ELEKTRA_PLUGIN_EXPORT(line)

return elektraPluginExport("line",
ELEKTRA_PLUGIN_GET, &elektraLineGet,
ELEKTRA_PLUGIN_SET, &elektraLineSet,
ELEKTRA_PLUGIN_END);

There you have it! This is the last part of my tutorial on writing a storage plug-in for Elektra. Hopefully you now have a good understanding of how Elektra plug-ins work and you ll be able to add some great functionality into Elektra through development of new plug-ins. I hope you enjoyed this tutorial and if you have any questions just leave a comment! Happy coding!
Ian S. Donnelly

6 November 2013

Olivier Berger: Generating WebID profiles for Debian project members

I ve been investigating the generation of WebID profiles for Debian project members for some time. After earlier experiments on webid.debian.net, in a static and very hackish manner, I ve investigated the use of Django. Django is no random choice, as it is being used in several ongoing efforts to rewrite some Debian Web services. Among these is a new LDAP UserDir, which could replace the current version which runs db.debian.org, started by Luca Filipozzi and Martin Zobel-Helas. I ve worked on integrating some of the LDAP querying code written by Luca together with the Django WebID provider app written by Ben Nomadic (both modified by me), and the result is a bit hackish for the moment. It s very early, but allows the generation of WebID profiles for Debian project members, using data queried in Debian s LDAP directory, and adding TLS certs to the profiles. The TLS certs could in principle be used later as a WebID + TLS authentication mechanism. There s plenty of work ahead, and this may never be deployed, but as an example see the kind of way such WebID profile documents may look (in Turtle format) :
@prefix cert: <http://www.w3.org/ns/auth/cert#> .
@prefix foaf: <http://xmlns.com/foaf/0.1/> .
@prefix rdf: <http://www.w3.org/1999/02/22-rdf-syntax-ns#> .
@prefix rdfs: <http://www.w3.org/2000/01/rdf-schema#> .
@prefix wot: <http://xmlns.com/wot/0.1/> .
@prefix xml: <http://www.w3.org/XML/1998/namespace> .
@prefix xsd: <http://www.w3.org/2001/XMLSchema#> .
<> a foaf:PersonalProfileDocument ;
    foaf:primaryTopic <http://db.debian.org/olivier#me> .
<#gpgkey> a wot:Pubkey ;
    wot:fingerprint "ACE46EBD89F6656D6642660BE941DEDA7C5BB6A5" ;
    wot:pubkeyAddress <ttps://db.debian.org/fetchkey.cgi?fingerprint=ACE46EBD89F6656D6642660BE941DEDA7C5BB6A5> .
<http://db.debian.org/olivier#me> a foaf:Person ;
    cert:key [ a cert:RSAPublicKey ;
            rdfs:label "key made on [...] on my laptop" ;
            cert:exponent 65537 ;
            cert:modulus "bb7d5735181c7687a09abf3c88a064513badfe351f14fc2d738978a7f573d12eb831140a7a02c579f31f4617c14145493aeff4009832ba7fd1c579d6da92f68cd4437072266b000451d6eb45c03cd00b20e1f2230d83bdc3caeebb317e6618dd38a3f53abbbb2b6495a893495d3df685a2f0f599be8a74ef88841ce283dd8f65"^^xsd:hexBinary ],
        [ a cert:RSAPublicKey ;
            rdfs:label "key made on [...] on my laptop" ;
            cert:exponent 65537 ;
            cert:modulus "b078dedb61d215348adaa3315f478eca803513a8750753255f50fd335e3b6afdafd385afb62878edc412bbbc0c125d1805abef2920cb3dccb94d818b4973435f4f312ddfad960db7b7ec4522036e5c1fb1e5d7154756a97e924075b301cdf95e97e3bb665a97cdf0187c2aa229939962b0e9975dfb97c71ea60384af465aa40726fe8a2a1dd504da6a168e7f80fc37a1363d5f583a1a8d4f8253af0e7e5c0f3d2fabb61dd9cde17aba328022fd4be4e0214f407d83a95ec06b2d70c61835bb78ba3b46e8b82be3a4d6d53d88a94123144ef9b7a7c97e9396767505f34995488c62bcd697180f92244c82147a71a5b86a25f2c8ddf0ea965fc8ced8d6b84cff97"^^xsd:hexBinary ] ;
    foaf:homepage <http://www.olivierberger.org/> ;
    foaf:mbox "mailto:obergix@debian.org" ;
    foaf:name "Olivier Berger" ;
    foaf:nick "obergix" ;
    wot:hasKey <#gpgkey> .
If you re interested in WebID in the frame of Debian project services, see the discussion list.

25 January 2013

Russ Allbery: The "Why?" of Work

(This is going to be long and rambling. Hopefully at some point I'll be able to distill it into something shorter.) In preparation for a tech leads retreat tomorrow, several of us at work were asked to watch Simon Sinek's TED talk, "How great leaders inspire action". I'll be honest with you: I hated this talk. Sinek lost me right at the start by portraying his idea as the point of commonality among great leaders (don't get me started on survivorship bias; it's a pet peeve) and then compounded the presentation problem with some dubious biology about brain structure. So, after watching it, I ranted a bit about how much I disliked it (to, as it turns out, people who had gotten a lot out of it). (Don't do this, btw. It's nearly always worthwhile to suppress negativity about something someone else enjoyed. I say this to increase the pool of people who can remind me of what I said the next time I forget. Which, if my normal pattern holds, will be about five minutes from now.) Thankfully, I work with tolerant and forgiving people who kindly pointed out the things they saw in the video that I missed, and we ended up having a really good hour and a half discussion, which convinced me that there's an idea under here that's worth talking about. It also helped clarify for me just how much I hate the conventional construction of both leadership and success. This talk is framed around getting other people to do things, which is one of the reasons why I had such a negative reaction to it. It's right there in the title: leaders inspiring action. This feeds into what at least in the United States is an endemic belief that the world consists of leaders and followers, and that the key to success in the world (in business, in politics, in everything else) is to become one of the leaders and accumulate followers (most frequently as customers, since we have a capitalist obsession). This is then defined as success. I think this idea of success is bullshit. Now, that statement requires an immediate qualification. Saying that the societal definition of success is bullshit is a statement from privilege. I have the luxury of saying that because I am successful; I'm in a position where I have a lot of control over my own job, I'm not struggling to make ends meet, and I can spend my time pondering existential questions like how to define success. If I were a little less lucky, success would be whatever put food on the table and kept a roof over my head. I'm making an argument from the top of Maslow's hierarchy. But that is, in a roundabout way, my point: why is defining and constructing success still so hard, and why do we do such a bad job at it, even when we're at the top of the pyramid and able to focus on self-actualization? The context of this talk for my group is pre-work for a discussion about, in Sinek's construction, the "why?" of our group. Why are we here, what is our purpose, and what do we care about? By the mere fact that we are able to ask questions like that, you can correctly surmise that we're already successful. The question, therefore, is what should we do with that success? I normally hear one or more of the following answers, all of which I find unsatisfying or problematic. So, what should I do with success? Or, put another way, since I have the luxury of figuring out a "why?", what's my "why?" This question comes at a good time. As I've mentioned the last couple of days here, I've just come off of two days of the most fun I've had at work in the last several years. I spent about 25 hours total building a log parsing infrastructure that I'm quite fond of, and which may even be useful to other people. And I did that in response to a rather prosaic request: produce a report of user agents by authenticated unique users, rather than by hits, so that we can get an idea of what percentage of our community uses different devices or browsers. This was a problem that I probably could have solved adequately enough for the original request in four hours, maybe less, and then moved on to something else. I spent six times that long on it. That's something I can do because I'm successful: that's the sort of luxury you get when you can define how you want to do your job. So, apparently I have an answer to my question staring me in my face: what I do with success, when I have it, is use that leeway to produce elegant and comprehensive solutions to problems in a way that fully engages me, makes the problem more interesting, and constructs infrastructure that I can reuse for other problems. Huh. That sounds like a "why?" response that's quite common among hackers and software developers. Nothing earth-shattering there... except why is that so rare in a business context? Why isn't it common to answer questions like "what is our group mission statement" with answers like that? This is what I missed in the TED talk, and what the subsequent discussion with my co-workers brought to light for me. I think Sinek was getting at this, but I think he buried the lede. The "why?" should be something that excites you. Something that you're passionate about. Something that you believe in. He says that's because other people will then believe in it too and will buy it from you. I personally don't care about (or, to be honest, have active antipathy towards) that particular outcome, but that's fine; that's not the point. The point is that a "why?" comes from the heart, from something that actually matters, and it creates a motivating and limiting principle. It defines both what you want to do and what you don't want to do. That gives me a personal answer. My "why?" is that I want to build elegant solutions to problems and do work that I find engaging and can be proud of afterwards. I automate common tasks not because I particularly care about being efficient, but because manually doing common tasks is mind-numbing and boring, and I don't like being bored. I write reliable systems not particularly because that helps clients, but primarily because reliable software is more elegant and beautiful and unreliable software offends me. (Being more usable and frustrating for clients is also good; don't get me wrong. It's just not a motive. It's an outcome.) What does that mean for a group mission statement, a group "why?" Usually these exercises produce some sort of distillation of the collective job responsibilities of the people in the group. Our mission is to maintain core infrastructure to let people do their work and to support authentication and authorization services for the university, yadda yadda yadda... this is all true, in its way, but it's also boring. One can work oneself up to caring about things like that, but it requires a lot of effort. But we all have individual "why?" answers, and I bet they look more like my answer than they do like traditional mission statements. If we're in a place where we have the luxury of worrying about self-actualization questions, what gets us up in the morning, what makes it exciting to go into work, is probably some variation on doing interesting and engaging work. But it's probably a different variation for everyone in the group. For example, as you can see from above, I like building things. My happiest moments are when someone gives me a clearly-defined problem statement that fills a real need and then goes away and leaves me in peace to solve it. One thing I've learned is that I'm not very good at coming up with the problem statements myself; I can do it, but usually I end up solving some problem that isn't very important to other people. I love it when my employer can hand me real problems that will make the world better for people, since often they're a lot more interesting (and meaningful) than the problems I come up with on my own. But that's all highly idiosyncratic and is not going to be shared by everyone in my group. I'm an introvert; the "leave me alone" part of that is important. Other people are extroverts; what gets them up in the morning is, in part, engaging with other people. Some people care passionately about UI design. (I also care passionately about UI design, but the UI designs that I'm passionate about are the ones that are natural for my people, who are apparently aliens from another galaxy, so I'm not the person you want doing UI design for things used by humans.) Others might be particularly interested in researching new technology, or coming up with those problem statements, or in smoothly-running production systems, or in metrics and reporting... I don't really know, but I do know that there's no one answer that fits everyone. Which means that none of our individual "why?" responses should become the group "why?". However, I think that leads to an answer, and it's the answer I'm going to advocate for in the meeting tomorrow. I believe the "why?" of our team should be to use the leeway, trust, and credibility that we have because we're successful to try to create an environment in which every individual member of the team can follow their own "why?" responses. In other words, I think the mission of our group should not be about any specific technology, or about any specific set of services, or outcomes. The way we should use our success is to let every member of our team work in a way that lights their fire. That makes them excited to come into work. That lets each of us have as much fun as I had in the past two days. We should have as our goal to create passionate and empowered employees. Nothing more, but nothing less. This is totally not how group mission statements are done. They're always about blending in to some larger overall technological purpose. But I think that's a mistake, and (despite disliking the presentation), I think that's what this TED talk does actually get at. The purpose is the what, or sometimes the how. It's not the why. And the why isn't static; technology is changing fast, and people are using technology in different ways. Any mission statement around technology today is going to be obsolete in short order, and is going to be too narrow. But I think the flip side is that good technological solutions to the problems of the larger organization are outcomes that fall out of having passionate and inspired employees. If people can work in ways that engage and excite them, they will end up solving problems. We're all adults; we know that we're paid to do a job and that job needs to involve solving real problems for the larger organization. All of that is obvious, and therefore none of that belongs in a mission statement. A mission statement should state the inobvious. And while some visionary people can come up with mission statements around technology or around how people use technology that can be a rallying point for a team or organization, I think that's much rarer than people like to think it is. If you stumble across one like that, great, but I think most teams, and certainly our team, would be better served by having the team mission statement be to enable every individual on the team to be passionate about their work. What should our group work on next? Figure out what the university's problems are, line those needs up with the passions of the members of the team, ask the people most excited about each problem how they want to solve that problem, and write down the answers. There's our roadmap and our strategy, all rolled into one.

7 March 2012

Enrico Zini: Resolving IP addresses in vim

Resolving IP addresses in vim A friend on IRC said: "I wish vim had a command to resolve all the IP addresses in a block of text". But it does:
:<block>!perl -MSocket -pe 's/(\d+\.\d+\.\d+\.\d+)/gethostbyaddr(inet_aton($1), AF_INET)/ge'
If you use it often, put the perl command in a one-liner script and call it an editor macro. It works on other editors, too, and even without an editor at all. And it can be scripted! We live with the power of Unix every day, so much that we risk forgetting how awesome it is.

19 April 2010

Mike Hommey: A new world of possibilities is opening up

Account created for myaddress<at>glandium.org with hg_mozilla and mg_mozsrc bits enabled.
Yes, this means I now have commit access on hg.mozilla.org. Thanks to those who vouched for me, namely Justin Wood, Christian Biesinger and Benjamin Smedberg. And thanks to the Mozilla governance for having changed the commit access requirements just in time for me to take advantage of the new ones: under the old rules, it was required that the vouching superreviewer had never reviewed a patch from the person applying for commit access. Of the 31 superreviewers, 14 (almost half of them) already had reviewed one or more patches from me (which is not really unexpected, considering the number of patches I sent in the past). One could wonder why I never applied for access earlier, though.

9 September 2009

Matthew Palmer: Water Tanks, Reliability, and Redundancy

Water supply, in the developed world, is one of those things you just pretty much take for granted. You turn on the tap, and clean, cool, refreshing water comes out. Similarly, when I go to a fire in my shiny fire truck, no matter what time of the day or night, I expect to able to hook up to a hydrant and have a strong, steady supply of water available. This level of reliability is something that we in the IT industry can typically only dream of. Practically 100% reliability over a period of decades, without constant maintenance and tweaking? Not a hope. To even get close to that, we need clusters of fully-redundant servers, fancy database replication techniques, and probably something totally out of left-field like Erlang's ability to reload code on the fly. But how do the water utilities do it? Clusters of fully-redundant high-capacity pumps, fancy pipe re-routing techniques? Or something totally out of left-field like a big water tank and gravity? Where I live, we've got the latter. Thinking about how it probably operates and is managed, I'm blown away by the sheer simplicity and robustness of the whole design, and how it can handle all manner of failures. First off, consider how few components have to be working in order for the water supply to continue for a while after some sort of catastrophic failure. We need: Note that this list of elements doesn't include any moving parts, or even guaranteed continuous water supply from a dam or other huge supply store. You can lose your feed pump(s), supply lines, or anything else that's on the supply side of the water tank for some period of time and nobody on the consumption side will know or care. Need more resilience to supply-side failure? Just build a bigger tank. This blows my mind, it really does. Need to do pump maintenance? No problem, just make sure that the tank is large enough to service demand over the period of the "outage", and go for it. Can't find a pump supplier to give you a restoration SLA of less than a week? Just make sure you've got a water tank that'll provide for a week's consumption. Basically, any supply-side reliability problem can be solved with "build a bigger tank", and while there's a limit to how big we can make tanks, I'll bet we know a lot more about building huge water tanks to withstand some freaky failure conditions than we do about building pumps that won't fail for 100 years. If you do need more capacity than a single tank can provide, just parallelise -- horizontal scaling of the water supply. Woohoo! Your big water tank also provides cost savings in your other equipment. If you had to pressurise a water supply using pumps, not only would you need your redundant array of very expensive pumps (Hmm, RAVEP-5 sounds like a Doctor Who villain), but those pumps would need to be able to provide your peak consumption flow (toilet breaks during the Super Bowl, probably). I'd imagine that could get mighty expensive, and without providing much benefit for 99% of the time. I see this capacity problem at work all the time. Customers who have the occasional massive traffic spikes need to massively over-provision their average utilisation to successfully service that 1% of the time that they're doing heavy traffic. Yes, I know, cloud computing, horizontal scaling, capacity on demand, yadda yadda yadda. It's not a panacea, and the number of apps that are designed to properly scale horizontally over a large range of traffic volumes is miniscule. My general point, though, is that it when you've got a variable load, it costs a whole lot more to provision systems to supply peak demand than to provision systems that can deal with average demand. A suitably large water tank means you can easily deploy a much smaller capacity feed pump. All you have to do is make sure that when demand exceeds supply, you've got enough water in your tank to cover the difference between the demand and supply over that period. When your peak capacity increases, and is starting to strain your infrastructure, you've got a choice, too: you can upgrade the pump or increase your storage capacity, whichever is cheaper / easier / quicker / provides better kickbacks / whatever. This is all well and good, you say, but computer systems aren't water supplies. There's a lot more moving parts, inputs, and outputs, and those all have to be handled. This is quite true. Water-powered computers are not in high demand. However, I think we could produce some much more reliable systems if we looked for ways we could simplify capacity and redundancy issues, water supply style, instead of layering more and more cruft into our solutions.
Ironically, just after I started writing this post (and this gives you an idea of how long it's been sitting in my drafts folder), I saw an article in the RISKS digest about a water supply problem in Santa Cruz, caused by a power outage killing the refill pump for an extended period and resulting in the storage tank running dry. Hey, I never said that it was a foolproof system -- especially when you've got failures of imagination that result in the system that tells people that there's no power relying on the power source it's monitoring being up in order to be able to tell people that there's no power...

2 December 2007

Matthew Johnson: Passwordless Encrypted Root in Debian

If, like me, you wanted both an encrypted root filesystem and some form of bootsplash you may have discovered that this is tricky. You need to enter the decryption passphrase on the terminal which means exiting the bootsplash. I decided it must be possible to use a USB token with the key on it rather than a passphrase to decrypt the drive and while this seems supported upstream, it is not supported out of the box on Debian. This is a short howto explaining my solution. Pre-requisites You will need a USB hard disk and a computer using Debian with an encrypted root filesystem. I am assuming that you are using a stock kernel with an initramfs image and have a luks encrypted LVM containing the root filesystem. You will have to change some of the details below to match your specific system. In the examples below /dev/hda5 is the encrypted partition and /dev/sda2 is the partition on the USB disk holding the key. Setting up the key First we need to generate a random key and put it on the disk. To save having to mount things in the initramfs, I chose to use a partition at the end of the USB flash disk. This means repartitioning and reformatting your USB disk. I recommend allocating the last cylinder in fdisk to primary partition 2. Once you have the second, small partition (you are only going to use 1k, so as small a partition as possible) you can put a key on it. This is as simple as dd if=/dev/urandom of=/dev/sda2 bs=1M . Adding the key to the luks partition Next, you need to add your new key as able to decrypt the partition. Luks allows several keys to be able to unlock the partition. The real key is decrypted under each of the user keys or passphrases and stored in a key slot' in the partition. To add your key type:
touch /tmp/keyfile
chmod 600 /tmp/keyfile 
dd if=/dev/sda2 bs=1k count=1 of=/tmp/keyfile
cryptsetup luksAddKey /dev/hda5 /tmp/keyfile
wipe /tmp/keyfile
Note the careful handling of the temporary key file (luksKeyAdd won't read from stdin, whereas luksOpen will), I recommend storing it on a ramdisk and you should certainly use wipe rather than rm if you don't. Once you have added your USB key you could remove the passphrase from the key list with luksDelKey, but if for any reason you lose the USB hdd you will be unable to decrypt the partition; I recommend leaving both keys available. Booting automatically In order to boot using the USB key we need to provide a couple of helper scripts in order for the initramfs to work. We also need to set some parameters on the kernel command line. In Debian these scripts can be added to the initramfs by putting them in /etc/initramfs-tools/. The first script is a helper script used when building the initramfs. This writes a second script into the initramfs itself which takes the partition as a parameter and prints the key on stdout. This should be written to /etc/initramfs-tools/hooks/cryptkey (executable) and contain:
#!/bin/sh --
PREREQ=""
prereqs()
 
   echo "$PREREQ"
 
case $1 in
prereqs)
   prereqs
   exit 0
   ;;
esac
. /usr/share/initramfs-tools/hook-functions
cat > $ DESTDIR /bin/loadkey 
The second script runs immediately before the cryptsetup script in the initramfs and ensures that the USB disk is available. This will cause the boot sequence to block until the USB disk is inserted and the device nodes created by udev. It can be provided directly in /etc/initramfs-tools/scripts/local-top/00ensureusb (executable) and should contain:
#!/bin/sh --
PREREQ=""
prereqs()
 
   echo "$PREREQ"
 
case $1 in
   prereqs)
      prereqs
      exit 0
   ;;
esac
if ! grep cryptopts /proc/cmdline >/dev/null; then return; fi
. /scripts/functions
log_begin_msg "Waiting for USB to become available..."
modprobe usbcore
modprobe uhci_hcd
modprobe ehci_hcd
modprobe usb_storage
while [ ! -b /dev/sda2 ]; do
   sleep 1
done
log_end_msg
exit 0
The cryptsetup script itself reads configuration from the kernel command line. Here you can give it a script which will read the key and the source for the key to read. Edit your grub or lilo config and append the following to the kernel command line: cryptopts=keyscript=/bin/loadkey,key=/dev/sda2,source=/dev/hda5,target=hda5_crypt,lvm=hecate-root You will obviously have to change the name of your lvm root partition (volumegroup-logicalvolume). I recommend having two entries in the boot menu, one with the cryptopts and one without to allow easy decryption using the passphrase instead. Conclusion That should be everything. Boot your computer and inset the usb hdd. When the boot process passes decryption you can remove it again. You may have to replug it if you boot with it inserted to start with.

5 June 2006

Uwe Hermann: CC Hits [Update]

I stumbled over CC Hits today, which looks like an interesting site with great potential. It's basically a digg-like site (implemented using ning.com, it seems) which doesn't list articles, but rather Creative Commons licensed songs. You can vote for the songs you like, just like you vote for articles on digg.com. The site seems to be quite new, and there's not too much traffic yet, but I imagine it could become a very useful resource to find high-quality Creative Commons music. Which is similar to what I'm doing with my Creative Commons music podcast (subscribe here, yadda yadda), and most of the other CC music podcasts do, for that matter. There's just too much CC music of varying quality out there by now — it's not so much a problem anymore to find some freely and legally available CC music (like it used to be a few years ago). It's more an issue of finding good music and/or music of certain genres you like... Anyways, I'm surely going to checkout CC Hits and use it to find new CC artists and songs for my podcast. Oh, and if you have any suggestions for more sources for good CC music, please leave a comment. </spam> Update 2006-06-05: On a related note, here's a song for all the geeks reading this: Code Monkey (MP3, 3.6 MB) by Jonathan Coulton, Creative Commons licensed, of course.

10 January 2006

Jacobo Tarr&#237;o Barreiro: Trademarks

So after feeling motivated again, I’ve updated my old Galician translation of Mozilla Firefox 0.8 for Firefox 1.0.7, I have some people testing the translation and will soon update it for Firefox 1.5. As I’m keeping my translation strictly unofficial (I want nothing to do with upstream Mozilla), it’s possible that I’ll receive some messages about how I’m infringing on the Mozilla Foundation’s holy trade marks, and how I’m not keeping the standards of extremely high quality that the Mozilla Foundation guarantees, yadda yadda yadda., so I’m already prepared for that eventuality: The Firechicken web browser I don’t know the English idiom for “tocar las narices”, but if they do it to me, I’ll adopt this name and logo for my translation. And then, if I translate Thunderbird, I’ll call this one “Thunderchicken” :-)

11 December 2005

Marc 'HE' Brockschmidt: About lost Debian NM applicants

As it looks like blogging is now the preferred way of sharing your thoughts, I guess I'll have to answer in my own blog to the problems starting with Thomas Hood post about withdrawing from the NM process.

Some people have replied to this and I think I should present my position, as I'm the most active of the unresponsive NM Front Desk, yaddayaddayadda.

Until Thomas blogged, I did not know that he considered the missing report as an issue.

To clear up the situation: Thomas completed all stages of the AM checks after he was reassigned to Alexander (formorer) this spring.
When Alex wanted to prepare the reported, he noted that some mails from the conversation between Madkiss (the old AM) and Thomas were missing. No problem, FD to the rescue, I still had those mails in my archive. After these initial problems, Alex' daytime job needed a lot of attention, so he didn't write the application report. I kicked him on a regular basis to do so, but it needs time and is not really very interesting, so it got delayed.

OK, that delay is not a good thing, but Alex told me that he planned to do the report on Saturday. Yes, this delay is quite annoying if you worked so hard and always had to wait for your AM to check your stuff and blabla. Now, the problem I have is that in this case, it's simply not true. Madkiss was assigned as AM to Thomas for 18 months - of these 18 months, 15 were spent waiting on a reply from Thomas to the usual NM questions.

Thomas, I can understand if you don't like the templates and think that they're boring, useless and whatever. But don't blame other people for time you have lost.