RewriteEngine On
RewriteMap lc int:tolower
RewriteMap unescape int:unescape
RewriteCond % REQUEST_URI ^/\.well-known/webfinger$
RewriteCond $ lc:$ unescape:% QUERY_STRING (?:^ &)resource=acct:xxx@yyy\.com(?:$ &)
RewriteRule ^(.*)$ https://zzz.social/.well-known/webfinger?resource=acct:xxx@zzz.social [L,R=302]
RewriteCond % REQUEST_URI ^/\.well-known/host-meta$
RewriteCond $ lc:$ unescape:% QUERY_STRING (?:^ &)resource=acct:xxx@yyy\.com(?:$ &)
RewriteRule ^(.*)$ https://zzz.social/.well-known/host-meta?resource=acct:xxx@zzz.social [L,R=302]
RewriteCond % REQUEST_URI ^/\.well-known/nodeinfo$
RewriteCond $ lc:$ unescape:% QUERY_STRING (?:^ &)resource=acct:xxx@yyy\.org(?:$ &)
RewriteRule ^(.*)$ https://zzz.social/.well-known/nodeinfo?resource=acct:xxx@zzz.social [L,R=302]
./autogen.sh
PATH_TO_TC=/home/your/path
export CC=$ PATH_TO_CC /x86_64-pc-linux-gnu/bin/x86_64-pc-linux-gnu-gcc
export LD=$ PATH_TO_LD /x86_64-pc-linux-gnu/bin/x86_64-pc-linux-gnu-ld
./configure \
--prefix= \
--with-statepath=/var/run/ups_state \
--sysconfdir=/etc/ups \
--with-sysroot=$ PATH_TO_TC /usr/local/sysroot \
--with-usb=yes
--with-usb-libs="-L$ PATH_TO_TC /usr/local/x86_64-pc-linux-gnu/x86_64-pc-linux-gnu/sys-root/usr/lib/ -lusb" \
--with-usb-includes="-I$ PATH_TO_TC /usr/local/sysroot/usr/include/"
make
T: Bus=01 Lev=01 Prnt=01 Port=00 Cnt=01 Dev#= 3 Spd=1.5 MxCh= 0
D: Ver= 2.00 Cls=00(>ifc ) Sub=00 Prot=00 MxPS= 8 #Cfgs= 1
P: Vendor=0001 ProdID=0000 Rev= 1.00
S: Product=MEC0003
S: SerialNumber=ffffff87ffffffb7ffffff87ffffffb7
C:* #Ifs= 1 Cfg#= 1 Atr=80 MxPwr=100mA
I:* If#= 0 Alt= 0 #EPs= 2 Cls=03(HID ) Sub=00 Prot=00 Driver=usbfs
E: Ad=81(I) Atr=03(Int.) MxPS= 8 Ivl=10ms
E: Ad=02(O) Atr=03(Int.) MxPS= 8 Ivl=10ms
static usb_device_id_t usb_device_table[] =
0x0001, 0x0000, "nutdrv_qx" ,
0x03f0, 0x0001, "usbhid-ups" ,
... and so on ...
local DRV_LIST="nutdrv_qx usbhid-ups blazer_usb bcmxcp_usb richcomm_usb tripplite_usb"
user=root
[ups]
driver = nutdrv_qx
port = auto
subdriver = hunnox
vendorid = "0001"
productid = "0000"
langid_fix = 0x0409
novendor
noscanlangid
#pollonly
#community =
#snmp_version = v2c
#mibs =
#secName =
#secLevel =
#authProtocol =
#authPassword =
#privProtocol =
#privPassword =
2021-08-09T18:14:51+10:00 synology synoups[11994]: =====log UPS status start=====
2021-08-09T18:14:51+10:00 synology synoups[11996]: device.mfr=
2021-08-09T18:14:51+10:00 synology synoups[11998]: device.model=
2021-08-09T18:14:51+10:00 synology synoups[12000]: battery.charge=
2021-08-09T18:14:51+10:00 synology synoups[12002]: battery.runtime=
2021-08-09T18:14:51+10:00 synology synoups[12004]: battery.voltage=13.80
2021-08-09T18:14:51+10:00 synology synoups[12006]: input.voltage=232.0
2021-08-09T18:14:51+10:00 synology synoups[12008]: output.voltage=232.0
2021-08-09T18:14:51+10:00 synology synoups[12010]: ups.load=31
2021-08-09T18:14:51+10:00 synology synoups[12012]: ups.status=OL
2021-08-09T18:14:51+10:00 synology synoups[12013]: =====log UPS status end=====
It is fairly locked down. I found a couple of ways in; installing the
Disney+ app from the "Aptoide TV" store it ships with does not work,
but the app prompts you to update it, which sends you to an action
where you can then choose to open the Google Play store. From there,
you can install things that work on it's Android 7 OS. This allowed
me to install a system-viewer app which revealed its specs:
OpenStack Newton is released, and uploaded to Sid
OpenStack Newton was released on the Thursday 6th of October. I was able to upload nearly all of it before the week-end, though there was a bit of hick-ups still, as I forgot to upload python-fixtures 3.0.0 to unstable, and only realized it thanks to some bug reports. As this is a build time dependency, it didn t disrupt Sid users too much, but 38 packages wouldn t build without it. Thanks to Santiago Vila for pointing at the issue here.
As of writing, a lot of the Newton packages didn t migrate to Testing yet. It s been migrating in a very messy way. I d love to improve this process, but I m not sure how, if not filling RC bugs against 250 packages (which would be painful to do), so they would migrate at once. Suggestions welcome.
Bye bye Jenkins
For a few years, I was using Jenkins, together with a post-receive hook to build Debian Stable backports of OpenStack packages. Though nearly a year and a half ago, we had that project to build the packages within the OpenStack infrastructure, and use the CI/CD like OpenStack upstream was doing. This is done, and Jenkins is gone, as of OpenStack Newton.
Current status
As of August, almost all of the packages Git repositories were uploaded to OpenStack Gerrit, and the build now happens in OpenStack infrastructure. We ve been able to build all packages a release OpenStack Newton Debian packages using this system. This non-official jessie backports repository has also been validated using Tempest.
Goodies from Gerrit and upstream CI/CD
It is very nice to have it built this way, so we will be able to maintain a full CI/CD in upstream infrastructure using Newton for the life of Stretch, which means we will have the tools to test security patches virtually forever. Another thing is that now, anyone can propose packaging patches without the need for an Alioth account, by sending a patch for review through Gerrit. It is our hope that this will increase the likeliness of external contribution, for example from 3rd party plugins vendors (ie: networking driver vendors, for example), or upstream contributors themselves. They are already used to Gerrit, and they all expected the packaging to work this way. They are all very much welcome.
The upstream infra: nodepool, zuul and friends(It is a gross oversimplification, but for the purposes of OpenStack CI, Jenkins is pretty much used as a glorified ssh/scp wrapper. Zuul Version 3, under development, is working to remove the need for Jenkins to be involved at all).Well some recent security issues with Jenkins and other changes has led to a roll-out of what is being called Zuul 2.5, which has indeed removed Jenkins and makes extensive use of Ansible as the basis for running CI tests in OpenStack. Since I already had the diagram, it seems worth updating it for the new reality.
The process starts when a developer uploads their code to gerrit via the git-review tool. There is no further action required on their behalf and the developer simply waits for results of their jobs.
Gerrit provides a JSON-encoded "fire-hose" output of everything happening to it. New reviews, votes, updates and more all get sent out over this pipe. Zuul is the overall scheduler that subscribes itself to this information and is responsible for managing the CI jobs appropriate for each change.
Zuul has a configuration that tells it what jobs to run for what projects. Zuul can do lots of interesting things, but for the purposes of this discussion we just consider that it puts the jobs it wants run into gearman for a launcher to consume. gearman is a job-server; as they explain it "[gearman] provides a generic application framework to farm out work to other machines or processes that are better suited to do the work". Zuul puts into gearman basically a tuple (job-name, node-type) for each job it wants run, specifying the unique job name to run and what type of node it should be run on.
A group of Zuul launchers are subscribed to gearman as workers. It is these Zuul launchers that will consume the job requests from the queue and actually get the tests running. However, a launcher needs two things to be able to run a job a job definition (what to actually do) and a worker node (somewhere to do it). The first part what to do is provided by job-definitions stored in external YAML files. The Zuul launcher knows how to process these files (with some help from Jenkins Job Builder, which despite the name is not outputting XML files for Jenkins to consume, but is being used to help parse templates and macros within the generically defined job definitions). Each Zuul launcher gets these definitions pushed to it constantly by Puppet, thus each launcher knows about all the jobs it can run automatically. Of course Zuul also knows about these same job definitions; this is the job-name part of the tuple we said it put into gearman. The second part somewhere to run the test takes some more explaining. To the next point...
Several cloud companies donate capacity in their clouds for OpenStack to run CI tests. Overall, this capacity is managed by a customized management tool called nodepool (you can see the details of this capacity at any given time by checking the nodepool configuration). Nodepool watches the gearman queue and sees what requests are coming out of Zuul. It looks at node-type of jobs in the queue (i.e. what platform the job has requested to run on) and decides what types of nodes need to start and which cloud providers have capacity to satisfy demand. Nodepool will start fresh virtual machines (from images built daily as described in the prior post), monitor their start-up and, when they're ready, put a new "assignment job" back into gearman with the details of the fresh node. One of the active Zuul launchers will pick up this assignment job and register the new node to itself.
At this point, the Zuul launcher has what it needs to actually get jobs started. With an fresh node registered to it and waiting for something to do, the Zuul launcher can advertise its ability to consume one of the waiting jobs from the gearman queue. For example, if a ubuntu-trusty node is provided to the Zuul launcher, the launcher can now consume from gearman any job it knows about that is intended to run on an ubuntu-trusty node type. If you're looking at the launcher code this is driven by the NodeWorker class you can see this being created in response to an assignment via LaunchServer.assignNode. To actually run the job where the "job hits the metal" as it were the Zuul launcher will dynamically construct an Ansible playbook to run. This playbook is a concatenation of common setup and teardown operations along with the actual test scripts the jobs wants to run. Using Ansible to run the job means all the flexibility an orchestration tool provides is now available to the launcher. For example, there is a custom console streamer library that allows us to live-stream the console output for the job over a plain TCP connection, and there is the possibility to use projects like ARA for visualisation of CI runs. In the future, Ansible will allow for better coordination when running multiple-node testing jobs after all, this is what orchestration tools such as Ansible are made for! While the Ansible run can be fairly heavyweight (especially when you're talking about launching thousands of jobs an hour), the system scales horizontally with more launchers able to consume more work easily. When checking your job results on logs.openstack.org you will see a _zuul_ansible directory now which contains copies of the inventory, playbooks and other related files that the launcher used to do the test run.
Eventually, the test will finish. The Zuul launcher will put the result back into gearman, which Zuul will consume (log copying is interesting but a topic for another day). The testing node will be released back to nodepool, which destroys it and starts all over again nodes are not reused and also have no sensitive details on them, as they are essentially publicly accessible. Zuul will wait for the results of all jobs for the change and post the result back to Gerrit; it either gives a positive vote or the dreaded negative vote if required jobs failed (it also handles merges to git, but that is also a topic for another day).
The developer uploads their code to gerrit via the git-review tool. There is no further action required on their behalf and the developer simply waits for results.
Gerrit provides a JSON-encoded "firehose" output of everything happening to it. New reviews, votes, updates and more all get sent out over this pipe. Zuul is the overall scheduler that subscribes itself to this information and is responsible for managing the CI jobs appropriate for each change.
Zuul has a configuration that tells it what jobs to run for what projects. Zuul can do lots of interesting things, but for the purposes of this discussion we just consider that it puts the jobs it wants run into gearman for a Jenkins master to consume. gearman is a job-server; as they explain it "[gearman] provides a generic application framework to farm out work to other machines or processes that are better suited to do the work". Zuul puts into gearman basically a tuple (job-name, node-type) for each job it wants run, specifying the unique job name to run and what type of node it should be run on.
A group of Jenkins masters are subscribed to gearman as workers. It is these Jenkins masters that will consume the job requests from the queue and actually get the tests running. However, Jenkins needs two things to be able to run a job a job definition (what to actually do) and a slave node (somewhere to do it). The first part what to do is provided by job-definitions stored in external YAML files and processed by Jenkins Job Builder (jjb) in to job configurations for Jenkins. Each Jenkins master gets these definitions pushed to it constantly by Puppet, thus each Jenkins master instance knows about all the jobs it can run automatically. Zuul also knows about these job definitions; this is the job-name part of the tuple we said it put into gearman. The second part somewhere to run the test takes some more explaining. To the next point...
Several cloud companies donate capacity in their clouds for OpenStack to run CI tests. Overall, this capacity is managed by a customised orchestration tool called nodepool. Nodepool watches the gearman queue and sees what requests are coming out of Zuul. It looks at node-type of jobs in the queue and decides what types of nodes need to start and which cloud providers have capacity to satisfy demand. Nodepool will monitor the start-up of the virtual-machines and register the new nodes to the Jenkins master instances.
At this point, the Jenkins master has what it needs to actually get jobs started. When nodepool registers a host to a Jenkins master as a slave, the Jenkins master can now advertise its ability to consume jobs. For example, if a ubuntu-trusty node is provided to the Jenkins master instance by nodepool, Jenkins can now consume from gearman any job it knows about that is intended to run on an ubuntu-trusty slave. Jekins will run the job as defined in the job-definition on that host ssh-ing in, running scripts, copying the logs and waiting for the result. (It is a gross oversimplification, but for the purposes of OpenStack CI, Jenkins is pretty much used as a glorified ssh/scp wrapper. Zuul Version 3, under development, is working to remove the need for Jenkins to be involved at all).
Eventually, the test will finish. The Jenkins master will put the result back into gearman, which Zuul will consume. The slave will be released back to nodepool, which destroys it and starts all over again (slaves are not reused and also have no sensitive details on them, as they are essentially publicly accessible). Zuul will wait for the results of all jobs for the change and post the result back to Gerrit; it either gives a positive vote or the dreaded negative vote if required jobs failed (it also handles merges to git, but we'll ignore that bit for now).
The developer uploads their code to gerrit via the git-review tool. They wait.
Gerrit provides a JSON-encoded "firehose" output of everything happening to it. New reviews, votes, updates and more all get sent out over this pipe. Zuul is the overall scheduler that subscribes itself to this information and is responsible for managing the CI jobs appropriate for each change.
Zuul has a configuration that tells it what jobs to run for what projects. Zuul can do lots of interesting things, but for the purposes of this discussion we just consider that it puts the jobs it wants run into gearman for a Jenkins host to consume. gearman is a job-server; as they explain it "[gearman] provides a generic application framework to farm out work to other machines or processes that are better suited to do the work".
A group of Jenkins hosts are subscribed to gearman as workers. It is these Jenkins hosts that will consume the job requests from the queue and actually get the tests running. Jenkins needs two things to be able to run a job -- a job definition (what to actually do) and a slave node (somewhere to do it). The first part -- what to do -- is provided by job-definitions stored in external YAML files and processed by Jenkins Job Builder (jjb) in to job configurations for Jenkins. Thus each Jenkins instance knows about all the jobs it might need to run. Zuul also knows about these job definitions, so you can see how we now have a mapping where Zuul can put a job into gearman saying "run test foo-bar-baz" and a Jenkins host can consume that request and know what to do. The second part -- somewhere to run the test -- takes some more explaining. To the next point...
Several cloud companies donate capacity in their clouds for OpenStack to run CI tests. Overall, this capacity is managed by nodepool -- a customised orchestration tool. Nodepool watches the gearman queue and sees what requests are coming out of Zuul, and decides what type of capacity to provide and in what clouds to satisfy the outstanding job queue. Nodepool will start-up virtual-machines as required, and register those nodes to the Jenkins instances.
At this point, Jenkins has what it needs to actually get jobs started. When nodepool registers a host to Jenkins as a slave, the Jenkins host can now advertise its ability to consume jobs. For example, if a ubuntu-trusty node is provided to the Jenkins instance by nodepool, Jenkins can now consume a job from the queue intended to run on an ubuntu-trusty host. It will run the job as defined in the job-definition -- ssh-ing into the host, running scripts, copying the logs and waiting for the result. (It is a gross oversimplification, but but Jenkins is pretty much a glorified ssh/scp wrapper to OpenStack CI. Zuul Version 3, under development, is working to remove the need for Jenkins to be involved at all).
Eventually, the test will finish. Jenkins will put the result back into gearman, which Zuul will consume. The slave will be released back to nodepool, which destroys it and starts all over again (slaves are not reused and also have no sensitive details on them, as they are essentially publicly accessible). Zuul will wait for the results of all jobs and post the result back to Gerrit and give either a positive vote or the dreaded negative vote if required jobs failed (it also handles merges to git, but we'll ignore that bit for now).
# AICCU Configuration # Login information username USERNAME password PASSWORD # Protocol and server listed on your tunnel protocol tic server tic.sixxs.net # Interface names to use ipv6_interface sixxs # The tunnel_id to use # (only required when there are multiple tunnels in the list) #tunnel_id <your tunnel id> # Be verbose? verbose false # Daemonize? daemonize true # Require TLS? requiretls true # Set default route? defaultroute trueNow you can add a script to bring up the tunnel and interface to /jffs/config/sixxs.ipup (make sure you make it executable) where you replace your tunnel address in the ip commands.
# wait until time is synced
while [ date +%Y -eq 1970 ]; do
sleep 5
done
# check if aiccu is already running
if [ -n " ps grep etc/aiccu grep -v grep " ]; then
aiccu stop
sleep 1
killall aiccu
fi
# start aiccu
sleep 3
aiccu start /jffs/etc/aiccu.conf
sleep 3
ip -6 addr add 2001:....:....:....::/64 dev br0
ip -6 route add 2001:....:....:....::/64 dev br0
sleep 5
#### BEGIN FIREWALL RULES ####
WAN_IF=sixxs
LAN_IF=br0
#flush tables
ip6tables -F
#define policy
ip6tables -P INPUT DROP
ip6tables -P FORWARD DROP
ip6tables -P OUTPUT ACCEPT
# Input to the router
# Allow all loopback traffic
ip6tables -A INPUT -i lo -j ACCEPT
#Allow unrestricted access on internal network
ip6tables -A INPUT -i $LAN_IF -j ACCEPT
#Allow traffic related to outgoing connections
ip6tables -A INPUT -i $WAN_IF -m state --state RELATED,ESTABLISHED -j ACCEPT
# for multicast ping replies from link-local addresses (these don't have an
# associated connection and would otherwise be marked INVALID)
ip6tables -A INPUT -p icmpv6 --icmpv6-type echo-reply -s fe80::/10 -j ACCEPT
# Allow some useful ICMPv6 messages
ip6tables -A INPUT -p icmpv6 --icmpv6-type destination-unreachable -j ACCEPT
ip6tables -A INPUT -p icmpv6 --icmpv6-type packet-too-big -j ACCEPT
ip6tables -A INPUT -p icmpv6 --icmpv6-type time-exceeded -j ACCEPT
ip6tables -A INPUT -p icmpv6 --icmpv6-type parameter-problem -j ACCEPT
ip6tables -A INPUT -p icmpv6 --icmpv6-type echo-request -j ACCEPT
ip6tables -A INPUT -p icmpv6 --icmpv6-type echo-reply -j ACCEPT
# Forwarding through from the internal network
# Allow unrestricted access out from the internal network
ip6tables -A FORWARD -i $LAN_IF -j ACCEPT
# Allow some useful ICMPv6 messages
ip6tables -A FORWARD -p icmpv6 --icmpv6-type destination-unreachable -j ACCEPT
ip6tables -A FORWARD -p icmpv6 --icmpv6-type packet-too-big -j ACCEPT
ip6tables -A FORWARD -p icmpv6 --icmpv6-type time-exceeded -j ACCEPT
ip6tables -A FORWARD -p icmpv6 --icmpv6-type parameter-problem -j ACCEPT
ip6tables -A FORWARD -p icmpv6 --icmpv6-type echo-request -j ACCEPT
ip6tables -A FORWARD -p icmpv6 --icmpv6-type echo-reply -j ACCEPT
#Allow traffic related to outgoing connections
ip6tables -A FORWARD -i $WAN_IF -m state --state RELATED,ESTABLISHED -j ACCEPT
interface br0 AdvSendAdvert on; prefix 2001:....:....:....::/64 ; RDNSS 2001:4860:4860::8888 2001:4860:4860::8844 ; ;(again, replace the prefix with your own) That is pretty much it; at this point, you should have an IPv6 network and it's most likely that all your network devices will "just work" with it. I got full scores on the IPv6 test sites on a range of devices. Unfortunately, even a geographically close tunnel still really kills latency; compare these two traceroutes:
$ mtr -r -c 1 google.com Start: Fri Jan 15 14:51:18 2016 HOST: jj Loss% Snt Last Avg Best Wrst StDev 1. -- 2001:....:....:....:: 0.0% 1 1.4 1.4 1.4 1.4 0.0 2. -- gw-163.syd-01.au.sixxs.ne 0.0% 1 12.0 12.0 12.0 12.0 0.0 3. -- ausyd01.sixxs.net 0.0% 1 13.5 13.5 13.5 13.5 0.0 4. -- sixxs.sydn01.occaid.net 0.0% 1 13.7 13.7 13.7 13.7 0.0 5. -- 15169.syd.equinix.com 0.0% 1 11.5 11.5 11.5 11.5 0.0 6. -- 2001:4860::1:0:8613 0.0% 1 14.1 14.1 14.1 14.1 0.0 7. -- 2001:4860::8:0:79a0 0.0% 1 115.1 115.1 115.1 115.1 0.0 8. -- 2001:4860::8:0:8877 0.0% 1 183.6 183.6 183.6 183.6 0.0 9. -- 2001:4860::1:0:66d6 0.0% 1 196.6 196.6 196.6 196.6 0.0 10. -- 2001:4860:0:1::72d 0.0% 1 189.7 189.7 189.7 189.7 0.0 11. -- kul01s07-in-x09.1e100.net 0.0% 1 194.9 194.9 194.9 194.9 0.0 $ mtr -4 -r -c 1 google.com Start: Fri Jan 15 14:51:46 2016 HOST: jj Loss% Snt Last Avg Best Wrst StDev 1. -- gateway 0.0% 1 1.3 1.3 1.3 1.3 0.0 2. -- 10.50.0.1 0.0% 1 11.0 11.0 11.0 11.0 0.0 3. -- ??? 100.0 1 0.0 0.0 0.0 0.0 0.0 4. -- ??? 100.0 1 0.0 0.0 0.0 0.0 0.0 5. -- ??? 100.0 1 0.0 0.0 0.0 0.0 0.0 6. -- riv4-ge4-1.gw.optusnet.co 0.0% 1 12.1 12.1 12.1 12.1 0.0 7. -- 198.142.187.20 0.0% 1 10.4 10.4 10.4 10.4 0.0When you watch what is actually using ipv6 (the ipvfoo plugin for Chrome is pretty cool, it shows you what requests are going where), it's mostly all just traffic to really big sites (Google/Google Analytics, Facebook, Youtube, etc) who have figured out IPv6. Since these are exactly the type of places that have made efforts to get caching as close as possible to you (Google's mirror servers are within Optus' network, for example) and so you're really shooting yourself in the foot going around it using an external tunnel. The other thing is that I'm often hitting IPv6 mirrors and downloading larger things for work stuff (distro updates, git clones, image downloads, etc) which is slower and wasting someone else's bandwith for really no benefit. So while it's pretty cool to have an IPv6 address (and a fun experiment) I think I'm going to turn it off. One positive was that after running with it for about a month, nothing has broken -- which suggests that most consumer level gear in a typical house (phones, laptops, TVs, smart-watches, etc) is either ready or ignores it gracefully. Bring on native IPv6!
apt-get install yum yum-utils python-lzma
git clone git://git.openstack.org/openstack/diskimage-builder
virtualenv dib_env
. dib_env/bin/activate
pip install dib-utils
git clone git://git.openstack.org/openstack-infra/project-config
break=after-error \
TMP_DIR=~/tmp \
ELEMENTS_PATH=~/project-config/nodepool/elements \
DIB_DEV_USER_PASSWORD="password" DIB_DEV_USER_PWDLESS_SUDO=1 \
DISTRO=23 \
./bin/disk-image-create -x --no-tmpfs -t vhd \
fedora-minimal vm devuser simple-init \
openstack-repos puppet nodepool-base node-devstack
pip install shade
clouds:
rax:
profile: rackspace
auth:
username: your_rax_username
password: your_rax_password
project_id: your_rax_accountnum
regions:
- IAD
import shade
shade.simple_logging(debug=True)
cloud = shade.openstack_cloud(cloud='rax')
image = cloud.create_image('image-name', filename='image.vhd', wait=True)
nova boot --flavor=2 --image=image-uuid --config-drive 1 test-image
There is no question that ESXi uses a lot of Linux kernel code and
drivers. The question as I see it is more around the interface. The
vmkernel provides a well-described API known as vmkapi. You can
write drivers directly to this API; indeed some do. You can download
a SDK.
A lot of Linux code has been extracted into vmkLinux; this is a
shim between Linux drivers and the vmkapi interface. The intent
here is to provide an environment where almost unmodified Linux
drivers can interface to the proprietary vmkernel. This means
vendors don't have to write two drivers, they can re-use their Linux
ones. Of course, large parts of various Linux sub-systems' API are
embedded in here. But the intent is that this code is modified to
communicate to the vmkernel via the exposed vmkapi layer. It
is conceivable that you could write a vmkWindows or vmkOpenBSD
and essentially provide a shim-wrapper for drivers from other
operating systems too.
vmkLinux and all the drivers are GPL, and released as such. I do
not think there could be any argument there. But they interface to
vmkapi which, as stated, is an available API but part of the
proprietary kernel. So, as I see it, this is a much more subtle
question than "did VMware copy-paste a bunch of Linux code into their
kernel". It goes to where the GPL crosses API boundaries and what is
considered a derived work.
If nothing else, this enforcement increasing clarity around that point
would be good for everyone I think.
/***************************************************************************
* C++ New and delete operator functions
***************************************************************************/
/* void *operator new(unsigned int sz) */
void *_Znwj(unsigned int sz)
return( kmalloc(sz, GFP_KERNEL) );
/* void *operator new[](unsigned int sz)*/
void *_Znaj(unsigned int sz)
return( kmalloc(sz, GFP_KERNEL) );
...
BCM338332 TP0 346890
Reset Switch - Low GPIO-18 50ms
MemSize: 128 M
Chip ID: BCM3383G-B0
BootLoader Version: 2.4.0alpha14R6T Pre-release Gnu spiboot dual-flash reduced DDR drive linux
Build Date: Mar 24 2012
Build Time: 14:04:50
SPI flash ID 0x012018, size 16MB, block size 64KB, write buffer 256, flags 0x0
Dual flash detected. Size is 32MB.
parameter offset is 49944
Signature/PID: a0e8
Image 1 Program Header:
Signature: a0e8
Control: 0005
Major Rev: 0003
Minor Rev: 0000
Build Time: 2013/4/18 04:01:11 Z
File Length: 3098751 bytes
Load Address: 80004000
Filename: CG3100D_2BPAUS_V2.06.02u_130418.bin
HCS: 1e83
CRC: b95f4172
Found image 1 at offset 20000
Image 2 Program Header:
Signature: a0e8
Control: 0005
Major Rev: 0003
Minor Rev: 0000
Build Time: 2013/10/17 02:33:29 Z
File Length: 3098198 bytes
Load Address: 80004000
Filename: CG3100D_2BPAUS_V2.06.05u_131017.bin
HCS: 2277
CRC: a6c0fd23
Found image 2 at offset 800000
Image 3 Program Header:
Signature: a0e8
Control: 0105
Major Rev: 0002
Minor Rev: 0017
Build Time: 2013/10/17 02:22:30 Z
File Length: 8277924 bytes
Load Address: 84010000
Filename: CG3100D_2BPAUS_K2630V2.06.05u_131017.bin
HCS: 157e
CRC: 57bb0175
Found image 3 at offset 1000000
Enter '1', '2', or 'p' within 2 seconds or take default...
. .
Board IP Address [0.0.0.0]: 192.168.2.10
Board IP Mask [255.255.255.0]:
Board IP Gateway [0.0.0.0]:
Board MAC Address [00:10:18:ff:ff:ff]:
Internal/External phy? (e/i/a)[a]
Switch detected: 53125
ProbePhy: Found PHY 0, MDIO on MAC 0, data on MAC 0
Using GMAC0, phy 0
Enet link up: 1G full
Main Menu:
==========
b) Boot from flash
g) Download and run from RAM
d) Download and save to flash
e) Erase flash sector
m) Set mode
s) Store bootloader parameters to flash
i) Re-init ethernet
p) Print flash partition map
r) Read memory
w) Write memory
j) Jump to arbitrary address
X) Erase all of flash except the bootloader
z) Reset
Flash Partition information:
Name Size Offset
=====================================
bootloader 0x00010000 0x00000000
image1 0x007d0000 0x00020000
image2 0x007c0000 0x00800000
linux 0x00800000 0x01000000
linuxapps 0x00600000 0x01800000
permnv 0x00010000 0x00010000
dhtml 0x00200000 0x01e00000
dynnv 0x00040000 0x00fc0000
vennv 0x00010000 0x007f0000
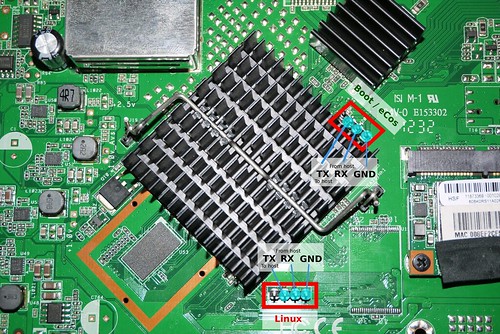
The "read memory" seems to give you one byte at a time and I'm not
certain it actually works. So I think the next step is solder some
leads to dump out the firmware from the flash-chip directly, which is
on the underside of the board. At that point, I imagine the passwords
would be easily found in the image and you might then be able to
leverage this into some sort of further hackability.
If you want a challenge and have a lot of time on your hands, this
might be your platform but practically I think the best place for
this is the recycling bin.
function is_rackspace
if [ ! -f /usr/bin/xenstore-ls ]; then
return 1
fi
/usr/bin/xenstore-ls vm-data grep -q "Rackspace"
if is_rackspace; then
echo "I am on Rackspace"
fi
count=0
things="0 1 0 0 1"
for i in $things;
do
if [ $i == "1" ]; then
(( count++ ))
fi
done
echo "Count is $ count "
When you run this script with -e or enable errexit -- probably because the script has become too big to be reliable without it -- count++ is going to return 0 (post-increment) and per above stop the script. A definite trap to watch out for!
- ((expression))
- The expression is evaluated according to the rules described below under ARITHMETIC EVALUATION. If the value of the expression is non-zero, the return status is 0; otherwise the return status is 1. This is exactly equivalent to let "expression".
$ ip link 1: lo: <LOOPBACK,UP,LOWER_UP> mtu 65536 qdisc noqueue state UNKNOWN mode DEFAULT group default link/loopback 00:00:00:00:00:00 brd 00:00:00:00:00:00 2: eth0: <BROADCAST,MULTICAST> mtu 1500 qdisc noop state DOWN mode DEFAULT group default qlen 1000 link/ether e8:03:9a:b6:46:b3 brd ff:ff:ff:ff:ff:ff 3: wlan0: <BROADCAST,MULTICAST,UP,LOWER_UP> mtu 1500 qdisc mq state UP mode DORMANT group default qlen 1000 link/ether c4:85:08:2a:6e:3a brd ff:ff:ff:ff:ff:ffIt is not described what the difference is between these two. The state output is derived from IFLA_OPERSTATE as per this little bit in ip/ipaddress.c in iproute2
if (tb[IFLA_OPERSTATE])
print_operstate(fp, rta_getattr_u8(tb[IFLA_OPERSTATE]));
if (filter.up && !(ifi->ifi_flags&IFF_UP))
return 0;
-rw-r--r-- 1 nobody nogroup 69M Mar 11 01:25 0-003035.v264 -rw-r--r-- 1 nobody nogroup 69M Mar 11 02:25 0-013049.v264 -rw-r--r-- 1 nobody nogroup 69M Mar 11 03:26 0-023103.v264 -rw-r--r-- 1 nobody nogroup 5.9M Mar 11 03:31 0-033117.v264 -rw-r--r-- 1 nobody nogroup 1.5M Mar 11 03:40 0-034350.v264 -rw-r--r-- 1 nobody nogroup 17M Mar 11 04:02 0-035259.v264 -rw-r--r-- 1 nobody nogroup 306K Mar 11 04:10 0-041548.v264 -rw-r--r-- 1 nobody nogroup 4.9M Mar 11 04:23 0-042457.v264There is a support forum, where I found the following files scattered in various posts. From what I can tell, they are the latest as of this writing. I can confirm they work with my IP391W-HD, which the system tells me is GM8126 hardware and came with firmware 1.2.8.3.
www.modern.ie offers free limited-time Windows VM's which will work to upload this firmware. Just make sure you use a bridged network in the VM; I'm guessing the firmware ActiveX control tells the camera to TFTP the data from it, which doesn't work via NAT. Somewhat worryingly, you can telnet to it and get a login prompt (TASTECH login). So it has a built-in backdoor you can't disable. There have been some efforts to hack the device. leecher@dose.0wnz.at did an excellent job reverse engineering the .pk2 format and writing tenvis_pack.c (no license, I'm generously assuming public domain). I used this to recreate the firmware above with a telnet daemon listening with a shell on port 2525 (no password, just telnet to it)
- 1.3.3.3.pk2 - firmware (b56f211a569fb03a37d13b706c660dcb)
- web.pk2 - a UI update that includes dropbox support. This is really for the model that has pan and tilt, so those buttons don't work. (0e42e42bd6f8034e87dcd443dcc3594d)
- V264ToAVIen.exe - converts the output to an AVI file that mplayer will play (with some complaints) (9c5a858aa454fed4a0186cf244c0d234)
It's interesting to poke around, but it seems like the whole thing is really driven by a binary called ipc8126
- 1.3.3.3-telnet.pk2 (19cf63ca8f0928af8ef5a9eb8326aae6)
/ # ipc8126 --help *** TAS-Tech IPCAM/DVS *** Version: 1.3.3.3 *** Release date: 2013-08-05 15:48:32In general, I'd say hackability is quite low. Warning : any of the above might turn your camera into a paperweight. It worked for me, but that's all I can say...
Next.