Search Results: "Martin"

28 July 2007

Martin-Éric Racine: Localisation beyond language packs

In my previous post, I briefly mentioned my K750i Sony-Ericsson mobile phone. I received it as a birthday gift this year, to replace my aging but trustworthy Nokia 3210 and, as with any multifunctional digital device, there was a learning curve during the adoption period. While some features were gladly and swiftly taken into use, some of the handset's usability issues became my pet peeve and, among them, the localization pack wins the jackpot. First, let's make one thing clear: I fully understand that memory constraints prevent manufacturers from including support for every language known to man, so a handset can only be loaded with a limited set of languages for the User Interface and for T9 predictive text input dictionaries. My issue is with the concept of grouping languages by linguistic families or continental areas, when compiling the localization packs for those handsets. In this particular case, I had a choice between the Baltic or Nordic packs. The former has UI language support for Estonian, Latvian, Lithuanian, Polish, Russian and Ukrainian, while the later has support for Finnish and the Scandinavian languages; English is also included in both cases. T9 support is a strangely mixed bag: the Baltic pack only includes predictive input for the Slavic languages, while the Nordic pack supports all the languages of its UI. What's my problem with the above language combinations? For starters, I'm in Finland. We don't interact with Danes or Icelanders outside very occasional pan-Nordic meetings and that mostly concerns politicians. Meanwhile, average Finns travel for work and play to Estonia and Russia on a fairly regular basis, which makes sense, since they are neighboring countries. However, available language packs don't take this into account. How should this be resolved? Either language packs are produced with specific countries in mind, rather than generic geographic areas, or the users should be allowed to freely mix and match among all available languages and get the result flashed into their handset at purchase time. The K750i language pack for Finland should therefore include: Finnish, Swedish, Estonian, Russian, English and Norwegian (essentially the current Nordic language pack, but with Danish and Icelandic replaced with Estonian and Russian). Then again, this only covers official state languages. Sam dialects, anyone? I guess not, because we'd soon be exceeding the handset's capacity. Hmm... Thus, the only real solution is to allow people to freely mix and match UI and T9 languages of their choice at purchase time. As a bonus, this would allow me to drop Norwegian and replace it with Joual... ... c lisse, French and finally have a language pack that I can truly find useful. I can easily picture a Transylvanian engineer working in Finland wanting to get Romanian support or a Kurdish immigrant preferring Turkish support instead. Sony-Ericsson, how about it?

27 July 2007

Michael Prokop: Use root=UUID on NSLU2

As I wrote a few monce ago I’m owner of a NSLU2 device powered by Debian. Now I had to install another device (using di-nslu2-etch-4.0r0.bin - md5: db8e8ec3571aff8fb2132479f860f16b this time) and I wanted to change the setup from using /dev/sda2 to a UUID based one - to get a stable root device. Nothing really tricky (thanks to the existing documentation) but just as a reference (for myself and other users considering the switch as well) the relevant steps… First of all identify the root-device (/dev/sda2 in my case) and get its UUID:
# /lib/udev/vol_id -u /dev/sda2
a98ebb0f-84ae-4f7a-a070-b94ecee3f94a
Make sure initramfs-tools use the given UUID as ROOT-option:
# echo "ROOT=/dev/disk/by-uuid/a98ebb0f-84ae-4f7a-a070-b94ecee3f94a" > \
/etc/initramfs-tools/conf.d/root-device-hack
# update-initramfs -k all -u
Replace the /dev/sda2 line in your /etc/fstab with:
/dev/disk/by-uuid/a98ebb0f-84ae-4f7a-a070-b94ecee3f94a /               ext3    defaults,errors=remount-ro 0       1
Make a backup of the original mtdblock2 and install the one Martin Michlmayr thankfully provides:
# cat /dev/mtdblock* > mtdblock.backup
# cat /dev/mtdblock2 > mtdblock2.original
# wget http://www.cyrius.com/debian/nslu2/files/etch-modified-mtdblock2.bin
# md5sum etch-modified-mtdblock2.bin
e5154ceed8ad7de5bca83cc98fbb4d79  etch-modified-mtdblock2.bin
# cat etch-modified-mtdblock2.bin > /dev/mtdblock2
# apex-env printenv
... compare output with http://www.nslu2-linux.org/wiki/Debian/ChangeKernelCommandLine
Finally set the new kernel commandline:
apex-env setenv cmdline 'console=ttyS0,115200 rtc-x1205.probe=0,0x6f noirqdebug rootdelay=10 root=UUID=a98ebb0f-84ae-4f7a-a070-b94ecee3f94a'
That’s it. Now after rebooting your system should use the UUID-approach instead of /dev/sd*. Check via:
# cat /proc/cmdline
console=ttyS0,115200 rtc-x1205.probe=0,0x6f noirqdebug rootdelay=10 \
root=UUID=a98ebb0f-84ae-4f7a-a070-b94ecee3f94a
Ressources:

Martin Zobel-Helas: chinese-big5 list moderator wanted

The chinese-big5 is moderated since quite some time, because of to much unfilterable spam. Now the last remaining listmoderator asks for help as won’t be able to do listmoderation in near future. If you are able to read/write chinese-big5 and want to do listmoderation, please contact listmaster@lists.debian.org and/or write to 434837@bugs.debian.org.

Raphaël Hertzog: Is forking NM good?

In a discussion with Bdale, he suggested that DM is seen as forking NM. And some people do not like forks. They are not opposed to DM in principle but do not want it outside of the current NM team. Obviously DM tries to respond to cases that NM is not prepared to handle. Furthermore, the DM discussion has been active for quite some time and the various members of the NM team (Frontdesk, DAM) have not participated much in the public discussion. Only when it comes to a vote do we hear some more (negative) opinions. I don’t see that as a sign of willingness to integrate DM or something similar in the current NM structure. So people who are requesting DM to be integrated in NM, please take it up with the frontdesk/DAM… and don’t oppose the principle just because of organizational matters. Internal organization always change and adapt themselves to the situation. Joey is right when he compares this to the introduction of the sponsorship process. I was one of the main actor in that process. I introduced the concept without the consent of the NM team (James Troup, Martin “Joey” Schulze) at that time. It was a fork, a new way to proceed and it became mainstream with the creation of the current NM process. It’s the natural way of doing things in a free software project. That said, I’m not opposed to improving our NM process. It really needs to be reworked in a “Membership Process” and be open to various kinds of contributors. That’s why I created a dedicated wiki page: http://wiki.debian.org/Projects/ReformedMembershipProcess Let’s see if we’re ready to really fix that! I hope to have comments from all the people who look to be so eager to fix the NM process. :-)

26 July 2007

Raphaël Hertzog: Some changes concerning DSA

Since march the DSA team uses a request tracker to handle all the requests that they get. Therefore you should no more use the debian-admin@debian.org alias (DSA members only). The debian-admin@lists.debian.org mailing list (DSA + local admins) is also scheduled for removal. Instead you should mail admin@rt.debian.org making sure to put “Debian RT” somewhere in the subject (crude but working spam prevention). By default, your ticket ends up in a private incoming queue. Up to now only DSA members had access to those queues. They moved most tickets in the public queue but it happened several times that this simple administrative burden took several weeks. Since a few days, Matt Taggart and myself have been granted RT accounts with required privileges to handle tickets and move them between the various queues. So from now on, all tickets will be quickly moved in the public queue (when they don’t contain sensitive information of course). We’ll be able to do some triage and ping DSA members for urgent requests. Matt and me have been trying to help out the DSA team for quite some time now, and while we’re not DSA with root rights, we’re in regular contact with the members (except Martin “Joey” Schulze who refuses to join the DSA IRC channel, who doesn’t use the request tracker and who doesn’t read the DSA mails either) and with several local admins. So if you have some troubles interacting with the DSA team, you can try to get in touch with us and we’ll see if we can help you. In too many cases people contact directly individual DSA members (Joey in particular). Please refrain from doing so, other volunteers (who might help you) won’t notice your request. Furthermore systematic request tracker usage helps us identifying what is well handled and what’s not. And it’s not more complicated than a simple email for you. Update: currently local admins are not subscribed to the request tracker. The RT setup will need some further adjustment for that, so the debian-admin@lists.debian.org list can still be useful if you want to reach them.

Martin F. Krafft: A new list: mailtags

I've received a fair number of responses to my previous blog post on labelling/tagging mail and have created a list for public discussion of the topic. Please subscribe if you're interested in this topic. I am also trying to get permission to repost some of the responses I got there. Furthermore an update of my blog post with some of these comments is pending. Busy times NP: Dredg: Catch without Arms

25 July 2007

Martin F. Krafft: They could be onto something

The Neue Z rcher Zeitung relayed today the warning by the US American TSA (travel security agency) that terrorists may be practicing attacks on airplanes (in German) (sic), because the USA has recently found loads of highly suspicious substances all over the place. I love the warning, which states that they could be practicing attacks. They could also be tanning on the beach somewhere and laughing their ass off at the idiots in Washington. And the rest of the world, who have not enough guts to stand up against the crap emerging from the White House but instead just shamble along like brainless ducklings. Some have claimed that the terrorists have already won because nothing is as it used to be, and fear and chaos are spreading. I agree. I'll also claim that they're highly successful recruiters: after all, the governments of the Excited States of America and most of the European nations who like to grease up to Washington have long joined their ranks and are now themselves terrorising their people. Yet, if you ask them, they'll deny it. Brilliant recruiters. NP: Dominici: O3 A Trilogy - Part 2

24 July 2007

Martin F. Krafft: A user-space filesystem for mail labeling

I am still looking for a solution that allows me to tag my mails similar to what Gmail offers. Having thought about this for quite a bit now, I can see three solutions, implemented at different levels in the mail flow: as filesystem, patch to the IMAP server (Dovecot), or patch to mutt. Since this post is about the filesystem, I'll concentrate on that, but I'll also touch upon the other two solutions briefly.
A bit of theory First, let's dig into the theory and requirements for a bit. Instead of sorting mails into folders (one mail can only ever live in one folder), I want to tag my mails, such that a single message can have multiple tags and hence be relevant to multiple categories. If you want to think in terms of folders, then a single message could be attached to multiple folders, e.g. via hard links. This is what Mairix approximates. The problem with this approach is that simple operations, such as deleting a message (removing it from the enclosing folder) or marking it as read (renaming the file) only affect the message in the current folder, not its duplicates/clones in the other folders. So it's best to stay with a single file per message and to associate tags with it. Here, two approaches seem plausible: (a) extracting tags from the individual message files, and (b) storing tags/message pairs in a separate database. I have a gut feeling that (a) is the better approach, especially since the files we're dealing with all have the same format. And in fact, there is a semi-standard header for email messages to store such tags: X-Label. One more paragraph of theory: instead of simple tags, like Gmail provides, I want hierarchical tags, for instance:
X-Label: Debian::pkg::mdadm
X-Label: Debian::popcon, PhD::Debian::stats
Hierarchical tags work similar to folders in that any message tagged as Debian::pkg::mdadm also belongs to the Debian::pkg and Debian categories. No rocket science.
mutt Now it would probably be trivial to hack mutt and add a new layer of I mentioned earlier that this could be implemented in various places, and I'll start at the highest level, with mutt, the mail reader. For quite a while now, mutt provides search operators for the X-Label header, such that you can search or limit your mailbox e.g. like so: ~y \\<PhD::Debian\\> ~y \\<popcon\\>. The problem with this approach is that it reuses existing functionality, which I need on a regular basis: searching and limiting. Furthermore, I think this approach is hackish and brittle and exposes too much of the underlying workings. filters, which would be used in addition to the user-specified limit. On a high-level, the user would set a tag expression, like PhD::Debian ::popcon, and may additionally choose to limit the display of messages to those sent from the debian.org domain: ~f debian.org$. mutt would then assemble the pieces and apply the filter (~y \\<PhD::Debian\\> ~y \\<popcon\\>) ~f debian.org$ to the current view. With a reasonable user interface to specify or pick labels, as well as a simple label editor, this would almost cut the mustard. Thanks to the header_cache patch (which also indexes the X-Label header), mutt fares reasonably well on Maildirs with thousands of messages (well, not always), and binding keys like s (save) and d (delete) to appropriate actions to add and remove labels determined from the destination or the current tags filter, would make mutt a force to be reckoned with.
Dovecot Unfortunately, implementing this in mutt would mean that I'd be bound to the mail reader forever (and I like to pretend that's not the case, haha!). An alternative would be to implement this on the IMAP server, which already provides IMAP folders which are not necessarily bound to physical, filesystem folders and can intercept all commands that manipulate messages or their status. But while in theory this works fine, it'll break when offline tools, such as offlineimap come into play, as those (need to) instantiate every message they download, which brings us right back to the problem with duplicate/cloned files discussed before.
A filesystem idea Trying to stay independent of the tools I use, I started playing with the idea of implementing mail message tagging at the filesystem level, using Fuse. The user would run a daemon process against a given Maildir holding all mail (the base store) and export a virtual directory hierarchy in which tags become Maildirs, backed by a cache of X-Label:filename pairs.
  • the root folder contains one Maildir dor every tag present in all messages in the base store.
  • each of those Maildirs, in addition to the new/cur/tmp directories, provides a subdirectory for every tag minus the ones already in the path, recursively. Navigating to /PhD/Debian::pkg would result in a logical-AND query for all messages tagged PhD (and thus PhD::*) and Debian::pkg. I am not sure how to implement OR and NOT queries yet.
  • every Maildir in the entire hierarchy contains the messages satisfying the query inherent in the path.
  • the special directory /INCOMING can be used to write messages to the hierarchy in such a way that the cache gets updated. Alternatively, one could register inotify hooks with the kernel on the base store and let others write to it as usual.
  • the special directory /::UNTAGGED might enumerate all messages without any tags.
The virtual directory hierarchy should also export the familiar filesystem semantics:
  • creating a file automatically adds the tags encoded in the file's path.
  • copying, linking, and symlinking a file within the hierarchy are all equivalent and cause the tag associated with the destination to be added to the file.
  • copying, linking, and symlinking into the hierarchy should probably result in an error, unless the source is clearly an RFC822 message.
  • mkdir creates a new tag in the cache, but without any files associated with it.
  • rmdir removes tags without any associated files.
  • rm on a file removes a tag from a file. rm -r on a directory removes the associated tag from all files (and the cache).
  • moving files is equivalent to copy-remove, but needs to be atomic.
Unlike tagfs, which uses an external SQLite database for tags, this filesystem should not use an external database for tags, but rather a run-time cache. That way, tags can be propagated to other machines with IMAP synchronisation tools. Initially, I thought such a fileystem could even be deployed "underneath" the IMAP server, but then we obviously run into the same problems with offline tools as before. Potentially, such a filesystem could be incredibly powerful as it could do its work for any user agent directly dealing with Maildirs (such as mutt), and it could also be used as basis for an IMAP server which is only ever accessed synchronously (in online vs. offline mode). In the latter case, one would have to ensure that filenames don't change across IMAP operations, or use the message IDs instead from the start. But as good as it may sound, getting it to work right will require quite some attention, I think. Especially guaranteeing filesystem atomicity, as required for Maildirs, might be impossible through the Fuse layer.
The sad end Unfortunately, I don't have the time to implement any of the above, but if I did, I would probably try to patch mutt first, even though such a patch may not make it into the upstream source any time soon. The filesystem idea sounds cooler and cleaner, but it does not yet support OR/NOT queries, and it will be quite a task to implement and debug. On the other hand, dealing with Maildirs of several thousand messages in mutt is a bit of a pain if those Maildirs are being updated externally (e.g. mail is delivered to them). At least the idea is out now. If you are interested and want to work on this, please let me know so that I can link you up with other interested people. And if you have any other input, please let me know. And no, I don't really want to install emacs to read my mail. NP: Dream Theater: Train of Thought Update: I've created a mailing list for public discussion of this topic, so please subscribe if you're interested. Thomas Viemann suggested to use IMAP flags for the task, as these are standardised. However, I see two show-stoppers here: first, I am not sure whether it would be possible to set those flags from procmail on delivery (sieve can supposedly do it, but I consider sieve not adequate for my needs). And second, offline tools, such as offlineimap, which map IMAP folders to filesystem Maildirs, would have exactly the same problem with representing affiliation of a single message with multiple tags. You can read up on the discussion in the archives of the offlineimap mailing list, and soon the new mailtags list. Martin Scholl had the idea to extend dbmail with the concepts of virtual folders (or stored searches). Naturally, as database-backed mail system, it would be trivial and fast to implement, but this approach bears two problems for me: first, it also falls short with respect to offline tools (see above), and second it would require me to replace my entire mail infrastructure. I am not even considering the implications of using a database for mail storage.

Martin F. Krafft: Iceweasel/Firefox brings you the Windows experience!

For a while now, Iceweasel/Firefox comes with built-in phishing protection, which is undoubtedly a good thing given the number of idiots using the Web these days.
Screenshot of iceweasel's phishing protection warning
But the implementation is crap. If you surf to a phishing site, such as this test site, the page loads as you would expect and then the first strange things happen: I get similar performance problems on the StaTravel website, and on map.search.ch, it almost always crashes. Thank you, Firefox developers, for bringing the joys of the Windows world to Linux! NP: Dream Theater: Metropolis Pt 2: Scenes from a Memory Update: several people have responded that they cannot reproduce the problem. I thus created a new profile, uninstalled all system-wide extensions, removed all plugins such that about:plugins was empty and tried again. The problems persist, although I think the lags are not quite as long as before and the memory consumption is obviously down. Maybe this is amd64-related? Update: It's not amd64-related, as several users have pointed out. Update: still no luck, but James Andrewart pointed me to this bug report, which might improve things a bit:
"The new protocol specifies a single lookup algorithm for all tables, rather than having per-table logic. This lookup logic was moved in to the db service from the javascript. URL canonicalization was moved completely into C++ too. The DB service can now handle a query from a raw URI, which will be needed for malware blocking."

22 July 2007

Martin Michlmayr: Dr Michlmayr

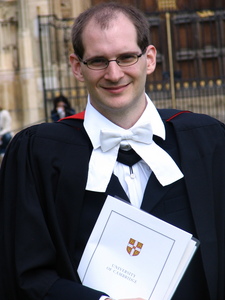
Martin at his PhD graduation Having passed all requirements for the Doctor of Philosophy, I had my graduation today.

20 July 2007

MJ Ray: Comment on the netpbm/debian-netpbm split

Daniel Martin commented:
"Often, dustups like these are the result of upstream not caring about one or more of the following: 1) Licenses. Many people will release code with no license attached to it at all, which means (Thanks to the wonders of the Berne convention) that no one else can distribute it. 2) Patent restrictions (the gif patent issue is now dead, but there's still patents on some other graphic formats) 3) Restrictions against selling the software for commercial gain, using the software in the military, in biotech, etc. The netpbm copyright file seems to include instances of each of these. I don't know how it escalated into being unable to build based on upstream."
Thanks for the info. I'm still surprised debian doesn't keep a (maybe big) patchset rather than a fork on this one. I don't remember what put me off it, but maybe imagemagick isn't so bad...

19 July 2007

Martin F. Krafft: Chinese charity sought

Remember the free laptop I got, which I wanted to sell and donate the proceeds to a Chinese charity? Well, I finally managed to get off my butt and contact interested buyers and it looks like I'll be able to get rid of it for around 1000 (if you would pay more, let me know). Now I am looking for a Chinese organisation that is dedicated to protecting the environment in China. It should be small and effective such that the money can be put to good use. If you have any idea or even better, direct contacts to an organisation, please get in touch with me. I found a list of NGOs in China lists a number of NGOs in China I will consider, but having a direct contact would be better, especially to help me figure out how to get the money there. Also, if you know of forums or people who could help, please point them to this post. NP: Amorphis: Far from the Sun Update: I have enquired contact information for this group of students. Obviously, if you know those people or are involved with them, let me know.

18 July 2007

Martin Zobel-Helas: Mails blocked on lists.debian.org containing non-text elements

due to the constant high volume of incoming spam containing attachments
which are not easy parseable for our filters, the listmasters decided
now to block the following types of attachments: Content-Type: image/(gif jpeg)
Content-Type: application/pdf This is only a temporary solution, until we have better methods to
filter out spam mails containing these types of attachments. If you know better solutions, let us know!

Martin F. Krafft: They don't want my business

I have been trying all day to get price quotes for a couple of flights within the next twelve months. I have not managed. Here is why, sorted by company, and for all companies that make sense for the routes:
Swiss When you click on the calendar fields to choose the departure date, a window pops up:
Shortly you see if there are flights available on your preferred date.
"Shortly" has lasted for as long as 3 hours, which is when I decided to try again, and ultimately to try someone else.
Emirates On submission of their form, I am being told:
Sorry, we were temporarily unable to process your request due to a technical problem. Please wait a moment and try again.
I've waited countless moments, and now, 11 hours since my first try, their idea of a moment still isn't over. But what kind of technical problem is this anyway, which resolves itself on retry after waiting a moment?
Austrian Airlines
Our website is currently undergoing maintenance. Please come back later.
All day.
Air New Zealand Once I hit "search flights", I get a blank page: a proper HTTP response followed by 0 bytes of HTML.
British Airways Whenever I hit submit, I am told that the return date has to be after the outbound date. I am then taken back to the form, which preserved all fields, except for resetting both dates to the same day, a week from now.
Malaysia Airlines
An error has occurred processing your request. Please contact our technical staff.
without a link or any hint as to how to contact them. I just tried them all again, without any changes; 11 hours later. Apparently they don't want my business. I really wonder what the future of air travel will be. In many ways, I hope they stop dumping prices and concentrate again on customer satisfaction. But I guess that applies to pretty much everything these days. PS: I especially appreciate Easyjet's policy of separating friends: after buying one ticket on a given route in August and finding out that we need a second one, I am told that "the route you have selected will be available from 28 October 2007". The funny thing is that we already have a ticket for that route in August. They just don't want my friend to fly along... NP: Gazpacho: Firebird Update: Sam Morris alerted me to Kayak, a very impressive meta-search engine for flights. Sure beats visiting each site in turn (although that could get you better deals through specials), and also replaces STA Travel and Opodo for me. Update: Enrico Zini points me to skyscanner, which complements Kayak in that it searches only the low-cost airlines. Kayak does include EasyJet, but they aren't always the cheapest.

13 July 2007

Steve Kemp: Push the button

Martin f. Krafft wrote about the Edinburgh Keysigning, and I find his post very interesting. I did not take part in either keysigning. The first one I missed because I was in the sauna (which was a lot of fun). The second I missed because my uncle died that evening (which was less fun; but mostly expected). So I expected to receive no new signatures:
skx@vain:~/Debian/Etch/hiki$ gpg-get-key
No key specified, defaulting to Steve's.
Updating key from keyring.debian.org
gpg: requesting key CD4C0D9D from hkp server keyring.debian.org
gpg: key CD4C0D9D: "Steve Kemp <skx>" 18 new signatures
So <strike>18</strike> several people signed my key without checking for valid identification. Is that good? Is that bad? I think it is appalling. But maybe I'm taking it too seriously. (I just realised 18 sigs != 18 people. So not quite as bad as I initially thought.)

11 July 2007

Martin F. Krafft: Creating a git branch without ancestry

Robin Rosenberg introduced me to the simplest method of creating a new git branch without any ancestors:
$ echo ref: refs/heads/newbranch > .git/HEAD
$ git branch
  master
[...]
$ git commit -m 'creating newbranch'
$ git branch
  master
* newbranch
This comes in handy if you want to maintain two separate components without any common files in the same repository. I am using it currently while experimenting with a new method of storing my home directory in git, which is still far from anywhere. I shall report once I reach a point of success or failure. NP: Rush: Moving Pictures Update: Johannes Schindelin taught me how to do the same without touching files in .git/:
$ git symbolic-ref HEAD refs/heads/newbranch
[...]
and also addressed the issue which would have all files already committed to the "master" branch now appear in the git status output as staged. This is because the index contains the full copy of a revision of a file, as it would be if committed at any point. git status shows the differences between what has been committed, what would be committed, and what is available in the working tree. Since we pointed HEAD to nowhere ("newbranch" does not yet exist), the index and what has been committed (nothing in this case) diverge, the files are still staged, and thus are scheduled to be part of the impending commit. The way to fix this is to remove the index:
$ rm .git/index
This may seem weird, but it works, because git recreates the index whenever you switch branches:
piper:~> git init-db
Initialized empty Git repository in .git/
piper:~> echo 1 > a; git add a; git commit -m.
Created initial commit e774324: .
1 files changed, 1 insertions(+), 0 deletions(-)
create mode 100644 a
piper:~> git symbolic-ref HEAD refs/heads/newbranch
piper:~> rm .git/index
piper:~> git status
# On branch newbranch
#
# Initial commit
#
# Untracked files:
#   (use "git add <file>..." to include in what will be committed)
#
#       a
nothing added to commit but untracked files present (use "git add" to track)
piper:~> echo 2 > b; git add b; git commit -m.
Created initial commit 54ff342: .
1 files changed, 1 insertions(+), 0 deletions(-)
create mode 100644 b
piper:~> git branch
  master
* newbranch
piper:~> git checkout master
fatal: Untracked working tree file 'a' would be overwritten by merge.
piper:~> git checkout -f master
Switched to branch "master"
piper:~> git status
# On branch master
nothing to commit (working directory clean)
piper:~> ls
a
piper:~> git checkout newbranch
Switched to branch "newbranch"
piper:~> git status
# On branch newbranch
nothing to commit (working directory clean)
piper:~> ls
b
As you can see, the creation of the branch is a bit complex, but once you (forcefully) switched back to master, you can then freely switch between and commit to them.

Martin F. Krafft: Publishing git repositories

Despite a distributed version control system by design, git can just as well be used in a centralised fashion. When a user clones a git repository, git sets up the local clone such that it is aware of its origin. Let's have a look at the relevant lines in .git/config:
[remote "origin"]
  url = ssh://server/path/to/repo.git
  fetch = +refs/heads/*:refs/remotes/origin/*
[branch "master"]
  remote = origin
  merge = refs/heads/master
The "remote" stanza defines a remote repository with the nickname "origin". If the user calls git fetch without arguments, it will download all remote branches (refs/heads/*) and store those as remote branches with the origin/ prefix. Thus, the branch "big-fat-feature" in refs/heads/big-fat-feature on the other side becomes the remote branch "origin/big-fat-feature" (refs/remotes/origin/big-fat-feature). The "branch" stanza informs git about the default source for merges when the "master" branch is current. If the local "master" branch is checked out and the user calls git pull without arguments, it instructs git to fetch all branches (see above), then merge the remote "master" branch (refs/heads/master) into the current branch. I started a new project in git today and decided to go public after I had already made a few commits and created a number of branches. So I set out to learn a bit more about git internals and came up with two ways to publish the repository such that my local repository would also know about the remote side as if it had been cloned from the start. The documentation didn't leave me satisfied, so I had to try it all out. Being new to git, my first thought was to push/publish my repository to a public location, and so I did:
### assuming ssh://server/remote.git resolves to an empty, bare git repo
### and that we are chdir()'d to the local repository:
$ git push --all ssh://server/remote.git
$ git remote add origin ssh://server/remote.git
$ git config branch.master.remote origin
$ git config branch.master.merge refs/heads/master
$ git fetch
$ git merge master
$ git branch
  big-fat-feature
* master
  ponies
$ git branch -r
  origin/big-fat-feature
  origin/master
  origin/ponies
Another method then dawned on me, but it's not necessarily better. Instead of pushing, let's copy a clone over and then clone that once more:
$ git config core.bare true
$ scp -r .git server:/remote.git
$ mv  pwd   pwd /../OLD
$ cd ..
$ git clone ssh://server/remote.git
$ cd remote
$ git branch
  big-fat-feature
* master
  ponies
$ git branch -r
  origin/HEAD
  origin/big-fat-feature
  origin/master
  origin/ponies
This does almost the same, except for that origin/HEAD branch, but that's just a local symbolic ref (a "symlink") and can just be removed, really:
$ rm .git/refs/remotes/origin/HEAD
$ git branch -r
  origin/big-fat-feature
  origin/master
  origin/ponies
Now the only thing left is setting core.sharedRepository on the remote side to let git know how to handle the Unix permissions. And that's it. NP: Antimatter: Lights Out

10 July 2007

Nacho Barrientos Arias: Discovering new bands

Paying tribute to the girl who pointed me out to this fantastic indie band, I’d recommend listen to Move on Now, crafted by Hard-Fi. Sweet taste, deep melody. P.S.) Martin, Gazpacho sounds nice ;)

9 July 2007

Mart&iacute;n Ferrari: DebConf, travelling, pictures, SoC... Oh my!

I'm still lacking the obligatory post-DebConf7 post... These weeks had been intense... So, first of all, thanks to all the DC-team for another wonderful conference. Next year I'll feel how it's done one of the two things that everybody likes but nobody wants to know how it's done. Hint: not sausages. This is the first time I've also attended DebCamp, and it was very useful. Not that I could do any real work, as very few people are able to do that during DebConf, but I managed to do what I planned, that is talk with many people who are working on debian-cd, debian-installer and custom-cdds. I've already uploaded my pictures to a temporary place, whitout captions, until I decide how I will replace the stinko called gallery. And there you can see that I was one of the few that actually wore a kilt during the event —not a proper Debian kilt, but hey... After DebConf, and after a year of hard work, I took a seven days vacation in the UK. So I was able to know Edinburgh (I prefer to hang out with Debian people that doing tourism during the conference, so I only knew the way to the supermarket). I also went to the Arthur's Seat HIll, which was very beautiful, and was only a 1-hour walk from the hostel to the top. Then I did a small visit to Stirling and concluded that castles in Scotland are not that interesting (but go to the Smith Museum!). Then, I went to London for a couple of days (dang, that was expensive!!), visited Marx's tomb, rided near the car bombs, got to know all the nice stuff that the british stole from around the world in the British Museum (it's really great, and free), and went to Cambridge to spend a day (and punting, I even did the punting myself!). Finally I spent my last day walking around that beatiful city, in the Soho and South Bank areas. I don't want to forget to say thanks to Nattie, Kai and Ben for hosting me, you guys rock!! This last week has been very productive. I was working GSoC project, trying to recover from lateness, and staying until late. It was worth it, I have finished settling down the architecture and overall design, and wrote the main program which will coordinate all the tests to be run. It includes from the begining dependency-based scheduling and paralellism, so I hope it will scale well in SMP computers. I also wrote a draft specification for the plugins and description of the running plan in the wiki page. I've also asked for the creation of a Alioth's project, so I can start publishing the code, and get feedback from the people that will use it.

Mart&iacute;n Ferrari: DebConf, travelling, pictures, SoC... Oh my!

I'm still lacking the obligatory post-DebConf7 post... These weeks had been intense... So, first of all, thanks to all the DC-team for another wonderful conference. Next year I'll feel how it's done one of the two things that everybody likes but nobody wants to know how it's done. Hint: not sausages. This is the first time I've also attended DebCamp, and it was very useful. Not that I could do any real work, as very few people are able to do that during DebConf, but I managed to do what I planned, that is talk with many people who are working on debian-cd, debian-installer and custom-cdds. I've already uploaded my pictures to a temporary place, whitout captions, until I decide how I will replace the stinko called gallery. And there you can see that I was one of the few that actually wore a kilt during the event —not a proper Debian kilt, but hey... After DebConf, and after a year of hard work, I took a seven days vacation in the UK. So I was able to know Edinburgh (I prefer to hang out with Debian people that doing tourism during the conference, so I only knew the way to the supermarket). I also went to the Arthur's Seat HIll, which was very beautiful, and was only a 1-hour walk from the hostel to the top. Then I did a small visit to Stirling and concluded that castles in Scotland are not that interesting (but go to the Smith Museum!). Then, I went to London for a couple of days (dang, that was expensive!!), visited Marx's tomb, rided near the car bombs, got to know all the nice stuff that the british stole from around the world in the British Museum (it's really great, and free), and went to Cambridge to spend a day (and punting, I even did the punting myself!). Finally I spent my last day walking around that beatiful city, in the Soho and South Bank areas. I don't want to forget to say thanks to Nattie, Kai and Ben for hosting me, you guys rock!! This last week has been very productive. I was working GSoC project, trying to recover from lateness, and staying until late. It was worth it, I have finished settling down the architecture and overall design, and wrote the main program which will coordinate all the tests to be run. It includes from the begining dependency-based scheduling and paralellism, so I hope it will scale well in SMP computers. I also wrote a draft specification for the plugins and description of the running plan in the wiki page. I've also asked for the creation of a Alioth's project, so I can start publishing the code, and get feedback from the people that will use it. PS: do MIND THE GAP, please. :-)

Next.

Previous.