Search Results: "will"

10 January 2011

Cyril Brulebois: Giving Squeeze s d-i rc1 a (snap)shot

Otavio Salvador requested early testers for squeeze debian-installer rc1. (This paragraph will be edited once the official announcement is published.) Graphical installer snapshots A few snapshots follow, using various non-Latin languages to make sure rendering was doing fine. To avoid any manual drawing, tiny imagemagick magick for the snapshots cropped to 800x300:
convert cropped-snap.png -fill none -stroke black -draw \
    "stroke-dasharray 10 10 path 'M 0,299 L 800,299'" dashed-cropped-snap.png
X/experimental + g-i = ? Premises: Result:
X/experimental + g-i = Win
Proof: g-i running with Xorg from experimental Comments:

9 January 2011

Nikita Youshchenko: checkrestart

After aptitude or similar upgrade tool completes its job, new versions of files are installed into filesystem. However, some running processes may be still using old files (and actually Linux file systems continue to store invisible copies of old files while those are mapped by running processes). In case of a security update, having old versions running keeps system vulnerable even after update completes, which is not good. A reboot is possible, but that s an ugly solution. Fortunately tools exist to find processes that have deleted files mapped. One of these tools is checkrestart (from debian-goodies package). Just run checkrestart -p after upgrade, and you will see what to restart to be safe and even what init.d scripts to run with restart argument. P.S.
On a server with hundreds of running processes, checkrestart -p is terribly slow, likely because it makes separate queries to dpkg about files mapped by each process. Perhaps it could be seriously accelerated if first all names to query are gathered, and then each name is queried only once. Any volunteers to do that? :)

Ana Beatriz Guerrero Lopez: KOffice 2.3.0 and future

It took a bit of time due to the holidays, but KOffice 2.3.0 is finally available from Debian experimental (give some hours to your mirror to sync!). If you are unstable user don t be afraid to fetch it from experimental, it is there only because the Squeeze freeze. Squeeze will ship with KOffice 2.2.1, while not all the applications are so polished as it would be desirable, it clearly offers huge improvements over old KOffice 1.6.3. I do not know if there will be a KOffice 2.3.1 upload but I know for sure the future is with Calligra :)

8 January 2011

Nikita Youshchenko: Psi / Psi+: want to avoid auto-online after auto-offline

Older versions of Psi jabber client required manual changing status to online to leave auto-offline state. It was very handy for me: I connect to my jabber account from two locations (from home and from office), so after I left one of these locations, auto-offline soon happened, and Psi at that location did not return online until I returned and manually instructed it to re-login. Unfortunately newer versions of Psi (I guess, starting from commit 4a54500c on git://git.psi-im.org/psi.git, which was between 0.11 and 0.12 releases), and also Psi+, behave differently: if user activity is detected on the desktop, auto-offline state is left, and status becomes online again similar to leaving auto-away and auto-xa states. This change is not good for me, at least in two situations: In both these situations, Psi client not at my current location becomes online, which can cause routing incoming messages to wrong location. I don t state that new behaviour is somehow worse than old behaviour. But for my use cases, I want to get old behaviour back. I ve done some code reading. I think that point to fix is near the bottom of PsiAccount::secondsIdle() method, where any auto status is disabled if no timeout condition currently exists. This should be changed so that auto-offline state won t be left if some config key is set. I will try to implement this change soon (or at least I hope I will try ) P.S.
To make things even better, a check of some external condition could be performed to decide if client should return online from auto-offline or not. Then fancy things could be set up, e.g. return to online at office only if my mobile phone is currently registered in the office wifi network not really required but cool.

Joerg Jaspert: Keyboard layout - 10 finger typing

For some reason, I don t really know why, I decided to switch my keyboard layout over to something weird. No, not the french brainfuck :) that is actually possible to type on in a halfway acceptable speed (shutup Bubulle), but the Neo thing for german keyboards. Hell. I didn t know how slow one can be typing. About a letter in 3 seconds, or something like it. I think, we should add something to our mandantory set of rules for anyone on any Debian Mailinglist: Whenever a flamewar starts, everyone who participates has to switch their keyboard layout to a random new layout. For every paragraph of every mail they write. Would stop the thread before it really happens. Ohwell, lets see where I stand in a week/month from now. Maybe I can actually use it then. And maybe I really type with 10 fingers then, and not something like the 3 til 8 i currenly use (depends on moon phase how many, i think). I m not slow with my current system, far from it, but I do sometimes have pain in my hands. Maybe that goes away too if I adopt something better, with less weird hand/finger movings. Though the way over will be painful in itself.

Christian Perrier: Becoming Libre (update)

I have been pointed that the changelog for libreoffice packages in Debian shows that the Debian maintainer (Ren Engelhard) and the Ubuntu maintainer (Matthias Klose, aka doko) for LibreOffice are obviously sharing their packaging work. That's of course what I would expect to happen...so let's put some light on this. I can actually only hope that more formal announcements from Canonical won't forget to mention such contribution. The link pointed by the announcement I indirectly linked in my former blog post was a post by Matthias in ubuntu-devel. It does not mention the work in Debian, but I can't really blame doko for that....that wasn't meant to be a formal announcement (doko even said he should have been skiing instead of doing libreoffice packaging work...:-)). So, shortly said, my concerns were probably exxagerated and we should celebrate the arrival of LibreOffice packages in both Debian and Ubuntu. And let's hope that both communities will cook together a nice formal announcement about this! It could very well be posted the same day in Debian News and the equivalent announcement channel in the Ubuntu community. And, let's dream, even involve people from The Document Foundation too.

7 January 2011

Peter Eisentraut: Git commit mode

Hardly anything ruins a glorious day of coding like fat-fingering the commit message late at night as you doze off, and then pushing it out for the world to see. To prevent that, I have equipped my Emacs configuration with a few little tools now.

First, I found the git-commit-mode, a special mode for Git commit messages. This helps you format the commit messages according to convention, and will use ugly colors if, for example, you write lines that are too long or you do not keep the second line blank. It also allows the use of things like M-q without shredding the whole file template.

Second, I integrated on-the-fly spell checking into the git-commit-mode. It won't stop you from writing nonsense, but it will catch the silly mistakes.

Here's a simple configuration snippet:
(require 'git-commit)
(add-hook 'git-commit-mode-hook 'turn-on-flyspell)
(add-hook 'git-commit-mode-hook (lambda () (toggle-save-place 0)))
The last line is handy if you have save-place on by default. When you make a new commit, it would then normally place the cursor where a previously edited commit message was finished, because to the save-place functionality, it looks as though it's the same file.

Evgeni Golov: Is Delicious loosing their data?

I use Delicious from time to time to save bookmarks and search for stuff I can t remember where I found it. It was sad to read rumors that Yahoo! will shut it down, but that s not the point here now.In the last months I noticed some strange behavior with their site: when surfing a page of a bookmark, you see the total number of people who have bookmarked that particular link and that number started to jump from view to view. First loaded you see a total of 183 bookmarks, 10 minutes later it s 265 bookmarks, and then 183 again. What s going on there? I guess that is some inconsistency between their datacentres or something, but I m not sure (and I am sure that this should not happen!).Today I noticed another funny thing: bookmarks without an owner:

Again, not sure what is happening here. Did the user delete his account? Delicious says all bookmarks will be gone when deleting, so this should be something different, but again, I have no clue.I fear I will have to search a new home for my bookmarks. Any (open-source) social bookmarking service out there worth a try?

Steve McIntyre: Isohybrid CDs being produced

New feature for Debian CDs We've had a wishlist bug (#551951) open against debian-cd for some time, asking for the creation of "isohybrid" CD images for i386 and amd64. These are special in that as well as the normal CD-based ISO9660 filesystem they also contain a valid-looking DOS-style partition table. Thus, if you simply copy one of these images raw to a USB stick a normal PC BIOS will boot the image directly. This would be a neat feature, making it much easier for people to use standard Debian installer images on their USB sticks without having to follow a lot more instructions. Support for this feature was added in syslinux/isolinux quite a while back (thanks to H Peter Anvin and the other syslinux contributors), but this depended on post-processing images with the isohybrid program. Due to the special way that we make our CD and DVD images to produce jigdo images as well, that wouldn't work for us: the jigdo files would no longer match the ISO files. Bugger...! Recently, along came more help in the form of Thomas Schmitt (author of xorriso) and George Danchev, its Debian maintainer. Recent versions of xorriso support creating isohybrid images directly, which is very handy. We've worked together in the last few months on porting my old JTE code (which creates our jigdo images) from cdrkit to xorriso, and after a lot of testing and debugging we now have things working fully. I've added a small amount of code in debian-cd to use the new xorriso features, and for the last couple of weeks all of the i386, amd64 and i386-amd64 multi-arch CDs and DVDs have been built as hybrids. It's been a delight working with Thomas and George - they're enthusiastic, helpful and friendly. Thanks, guys! What does this mean for end users? Instead of having to specially prepare USB sticks for the installer, you can now simply use dd to write the image straight to the raw stick, e.g.:
# dd if=debian-testing-i386-netinst.iso of=/dev/sdX
The USB stick should now boot directly, showing exactly the same bootup screen as if you'd written the image directly to a CD. Yay! I'm expecting to be using this code from now on for new releases, i.e. d-i beta and RC releases and for Squeeze itself when we get there. I'm not planning on backporting this code into the Lenny branch of debian-cd as it's a lot of work and I don't want to destabilise things there. What's next? We need to clear up some of the maintenance around the code as it stands; I'm planning on moving libjte inside my existing jigit package, as that's a sensible place to put it. That will come after the Squeeze release, though. We need to finalise boot support for other architectures in xorriso; I added support for them into mkisofs/genisoimage a long time ago and we've already moved some of that into xorriso. Thomas and George have also been working hard to give me faster/better size estimation code, useful for making debian-cd run faster. Finally: I'd like to add support into xorriso for creating the nasty HFS hybrid images that are needed for booting Macs. The code that does this in cdrkit is probably some of the worst that I've ever worked with, and I'd like to get away from it. If only Apple hadn't stupidly built their proprietary platform around this shit and had used open standards instead. :-( Once we have these bits in xorriso, I'll be able to move production of all of the CDs across from genisoimage to xorriso. Very nearly there for being able to drop the last remnants of Schily-ware from the Debian archive...

Raphaël Hertzog: How to create custom RSS feeds with WordPress

WordPress has many alternate built-in feeds: per category, per tag, per author, per search-keyword. But in some cases, you want feeds built with some more advanced logic. Let s look at the available options. WordPress advanced built-in feeds You can create feeds for unions or intersections of tags, you just have to use a URL like /tag/foo,bar/feed/ (all articles tagged with foo or bar) or /tag/foo+bar/feed/ (all articles tagged with foo and bar). You can also have feeds excluding a category, although that requires you to know the category identifier (and hardcode it in the URL like this: /?feed=rss2&cat=-123 where 123 is the category id that you want to exclude). But there s no simple way to have a feed that excludes articles with a given tag. The best solution found involves creating a custom feed. I ll show you a variation of this below. Creating a custom feed
  1. First of, install the Feed Wrangler plugin, it will take care of registering our custom feeds with wordpress.
  2. Go to Settings > Feed Wrangler in your WordPress administrative interface and create a new feed, let s call it myfeed .
  3. You should now create a feed-myfeed.php file and put it in your current theme s directory. The initial content of that file should be this:
    <?php
    include('wp-includes/feed-rss2.php');
    ?>
  4. At this point, you already have a new feed that you can access at /feed/myfeed/ (or /?feed=myfeed). It s a complete feed like the main one.
Now, we re going to look at ways to customize this feed. We re going to do this by changing/overriding the default query that feed-rss2.php s loop will use. A feed excluding articles with a tag If you want to create a feed that excludes the tag foo , you could use this:
<?php
global $wp_query;
$tag = get_term_by("slug", "foo", "post_tag");
$args = array_merge(
        $wp_query->query,
        array('tag__not_in' => array($tag->term_id))
);
query_posts($args);
include('wp-includes/feed-rss2.php');
?>
That was relatively easy, thanks to the tag__not_in query parameter. Now you can further customize the feed by adding supplementary query parameters to the $args array. The documentation of query_posts details the various parameters that you can use. A feed excluding articles with a custom field (meta-data) I went further because I did not want to use a tag to exclude some posts: that tag would have been public even if it was only meaningful to me. So I decided to use a custom field to mark the posts to exclude from my new feed. I named the field no_syndication and I always give it the value 1 . This time it s not so easy because we have no query parameter that can be used to exclude posts based on custom fields. We re going to use the post__not_in parameter that can be used to exclude a list of posts. But we must first generate the list of posts that we want to exclude. Here we go:
<?php
global $wp_query;
$excluded = array();
$args_excluded = array(
    'numberposts'     => -1,
    'meta_key'        => 'no_syndication',
    'meta_value'      => 1,
    'post_type'       => 'post',
    'post_status'     => 'published'
);
foreach (get_posts($args_excluded) as $item)  
        $excluded[] = $item->ID;
 
$args = array_merge(
        $wp_query->query,
        array('post__not_in' => $excluded)
);
query_posts($args);
include('wp-includes/feed-rss2.php');
?>
A feed with modified content You might want to add a footer to the articles that are syndicated. I use the Ozh Better Feed plugin for this but it applies to all your feeds. You could do that sort of transformation only in your customized feed by using the WordPress filter named the_content_feed. Here s a simple example:
<?php
function myfeed_add_footer($content)  
        return $content . "<hr/>My footer here";
 
add_filter('the_content_feed', 'myfeed_add_footer');
include('wp-includes/feed-rss2.php');
?>
I ll stop here but obviously you have lots of options and many ways to tweak all the snippets above. They have been tested with WordPress 3.0.4. Note that in all those examples, I took care to not duplicate the code from feed-rss2.php, instead I used include() to execute it. That way my custom feeds will automatically benefit from all the future enhancements and fixes made by the WordPress developers. But if you have to modify the XML structure of your custom feeds, you can paste the content of feed-rss2.php in your file and change it like you want

One comment Liked this article? Click here. My blog is Flattr-enabled.

Amaya Rodrigo: The Debian empanada

http://es.wikipedia.org/wiki/Empanada

Cod fish, fried tomato, green and red peppers. Home made from scratch. And delicious.

I wonder why I feel the need to swirl everything up :)


Originally uploaded by Amayita.

I will one day learn how to propperly cook.

Simon Josefsson: On Password Hashing and RFC 6070

The RFC Editor has announced a new document, RFC 6070, with test vectors for PKCS5 PBKDF2. The document grow out of my implementation of SCRAM for GNU SASL. During interop testing, more than one other implementation turned out to have mistakes in the PBKDF2 implementation. It didn t help that there weren t any stable test vectors for PBKDF2, so that we could do black-box testing of our PBKDF2 implementations against well-known and stable test vectors. Debugging this was time consuming. The document addresses this problem. So what is PBKDF2?

Briefly, the PBKDF2 is the state of the art way to convert a password string into a cryptographic binary key. There are many ways to design such an algorithm. To understand why PBKDF2 is designed the way it is we need some basic understanding. The typical attack you would be concerned with is if someone compromises your authentication servers and steals the credential database. This is what happened with the recent Gawker attack, where passwords were apparently stored in clear text. The first security improvement compared to storing passwords in clear text is to only store a hashed or encrypted form of the password. Hashing is preferable over encryption in this context, because with encryption it is possible to go back to the unencrypted form (if you know the key) whereas with a hash it is computationally infeasible to do so. The downside of hashing is that it is impossible to be compatible with all kind of authentication systems: the hash of the password in the database needs to be computed using the same algorithm as the system will be using. Unfortunately there are many different schemes out there to do password hashing, including the old Unix crypt(3) algorithm and the Windows LM-hash. You normally never know in advance what kind of systems your hashed credential database needs to work for, so you have to pick some set of algorithms and hope for the best. The next security improvements are iterations and salting. Iterations means to run the hash function not once, but hundreds or even thousands of times, on the input data (e.g., password). The extra time is hardly noticeable for the user, but for an attacker who is testing an entire dictionary of common passwords against your hash, making the work cost thousand times higher quickly makes the attack vector computationally infeasible. Salting means to include something other than the password in the input to the hash function, typically a random string. Without salting, a pre-computed rainbow table would provide a dictionary attack against all hashed password databases (one rainbow table per hashing algorithm). By using a sufficiently long and random salt, a rainbow table for one system is not applicable to another system. Since generating a rainbow table is time consuming, this adds another barrier to the attacker. PBKDF2 combines these three concepts hashing, iteration and salting into one construct, and it is designed flexible enough so that it can work on any pseudo-random function. In practice, I ve only ever seen HMAC-SHA1 be used. Some final words on the publication behind RFC 6070: Out of my earlier publications, this was the document that (by a large margin) spent the least time in the IETF process. You see various milestones of the document in the RFC 6070 datatracker history page. The time in the publication process was from 2010-08-09 to 2011-01-06. One month was in the AUTH48 state, of which the initial 20 days were waiting for me to respond. Thank you to my sponsoring AD, Sean Turner, for making this possible!

Daniel Baumann: Booting images from within EXTLINUX

Similar as people are doing with a seperate package for grub, Debians extlinux package as of version 2:4.03+dfsg-5 (and if you want a graphical boot menu, you will need syslinux-themes-debian version 4-1 or newer; both uploaded to experimental) handles booting images through memdisk out of the box now. After you have upgraded your packages, just do: Booting images from within EXTLINUX Update: After some more testing, EXTLINUX_MEMDISK defaults to true now.

Michal &#268;iha&#345;: Gammu supports Samsung phone through m-obex

The main part of the code was in Gammu for almost two months, but now it was finally debugged and confirmed working. For now you need to use version from git, but upcoming 1.28.95 will include it as well. The support is implemented through m-obex protocol, which can be switched on from standard AT commands, giving transparent support for all supporting phones without need to change existing configuration. The code was heavily based on documentation and code created by samsyncro project, thought their documentation missed some important bits. I'd really like to thank to Matthieu Patou for debugging problems of code I blindly wrote, because there were lot of issues (well it's hard to write code if you have no chance to test it).

Filed under: English Gammu 0 comments Flattr this!

6 January 2011

Michael Prokop: Booting ISO images from within GRUB2

You might be aware of GRUB s loopback option for booting an ISO, I wrote about it in Boot an ISO via Grub2 more than a year ago. A few months ago Goswin von Brederlow came up with this idea:
grml functions great as rescue system. So it would be nice to have a boot entry for it in grub instead of having to go look for the CD when needed. To make installing and updating simple it would be great if one could install this as a normal debian package which would register itself in grub (and maybe lilo too).
What a lovely idea: no need for a CD or USB stick as long as the bootloader and the harddisk are still working. Minimal manual intervention needed to keep it up2date and working sounds like the perfect rescue system. 8-) Now since end of 2010 a new stable version of sysadmin s favorite live system (AKA Grml 2010.12) is available and the great news is that we came up with two independent solutions known as grml-rescueboot and grub-imageboot. Having shipped them to one of my customers already I d like to write some words about it and why you should also consider using it on all your systems where GRUB2 is available. grml-rescueboot uses GRUB2 and its loopback feature for booting. Grml as well as Ubuntu provide all what s needed out-of-the-box. If you re interested in the details check out Jordan Uggla s excellent Loopback.cfg webpage in the supergrubdisk wiki. The best about it: you can provide custom bootoptions automatically when booting Grml. For example just set CUSTOM_BOOTOPTIONS= ssh=grml2011 in /etc/default/grml-rescueboot and the Grml rescue system will automatically start the OpenSSH server with the specified argument as password for user grml. Of course you can use all the other nifty bootoptions like scripts/netscript/ to further customize your Grml rescue system. [A note to other distributions like Ubuntu: I'd be interested to establish a mechanism to pass kernel options for loopback boot in a standardized way, drop me a note if you're interested in this.] grub-imageboot uses GRUB2 and syslinux memdisk to boot ISOs and floppy images. It doesn t rely on the loopback feature but instead maps the ISO into the memory directly. This is great for Linux ISOs that can t and won t support the the loopback feature (and have everything inside their initrd so the ISO doesn t have to find itself during booting), like BIOS or firmware updates. Also for example FreeDOS and Alpharev are known to work just fine. But sadly memdisk ISO emulation doesn t work with all Linux systems, as documented in the syslinux wiki. The good news is that Grml supports the memdiskfind/phram/mtdblock approach out-of-the-box. As far as I know therefore Grml is the first Debian based live system supporting memdisk ISO boot, though my patches already went to the Debian-Live project so if you re using live-boot >=2.0.14-1 or >=2.0.12-1+grml.04 your live system should be able to boot via memdisk ISO emulation as well. Summary: If you want to boot a Linux system which supports loopback.cfg use grml-rescueboot as its a more powerful tool to boot Linux live systems like Grml and Ubuntu. If you want to boot non-Linux systems (BIOS-/Firmware-Updates/FreeDOS/ .) use grub-imageboot. Alright how do you deploy this solution? Just grab and install grml-rescueboot and/or grub-imageboot. To deploy grml-rescueboot (adjust $VERSION if you want to use another flavour):
# choose Grml version:
VERSION=grml64-medium_2010.12
# create directory
mkdir -p /boot/grml
# download and verify ISO
cd /boot/grml
wget download.grml.org/$ VERSION .iso ,.md5 
md5sum -c $ VERSION .iso.md5
To deploy grub-imageboot:
# choose Grml version:
VERSION=grml64-medium_2010.12
# create directory
mkdir -p /boot/images
# download and verify ISO
cd /boot/images
wget download.grml.org/$ VERSION .iso ,.md5 
md5sum -c $ VERSION .iso.md5
That s it! Now when running update-grub you should get something like:
# update-grub
Generating grub.cfg ...
Found linux image: /boot/vmlinuz-2.6.36-grml64
Found initrd image: /boot/initrd.img-2.6.36-grml64
Found memtest86+ image: /boot/memtest86+.bin
Found memtest86+ multiboot image: /boot/memtest86+_multiboot.bin
  No volume groups found
Found Grml ISO image: /boot/grml/grml64-medium_2010.12.iso
Found memdisk: /boot/memdisk
Found iso image: /boot/images/grml64-medium_2010.12.iso
done
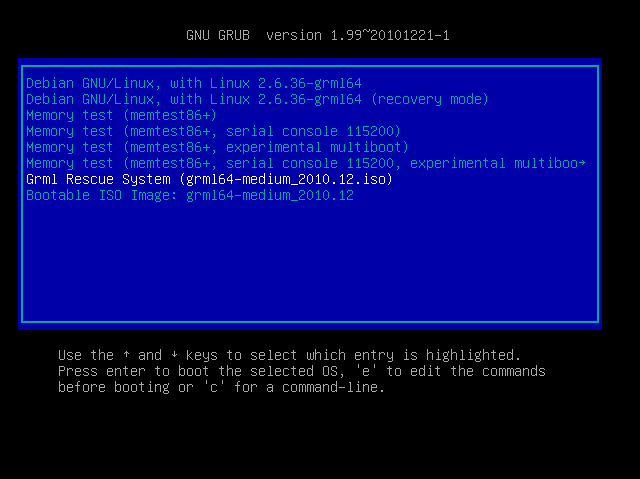
Voil , when rebooting your system you should see something like: Screenshot: grml-rescueboot The Grml Rescue System entry is what grml-rescueboot provides and Bootable ISO Image is what s provided by grub-imageboot. Just select the entry you d like to use, press enter and and you should get the bootsplash of the according ISO. BTW: I ve tested this with Ubuntu 10.10 too, grml-rescueboot works out-of-the-box with the Ubuntu ISO as well, it just doesn t support the memdisk ISO boot by grub-imageboot (yet). Tip: if you want to use grml-rescueboot and grub-imageboot with the same ISOs without having them twice on the disk just point the configuration option IMAGES in /etc/default/grub-imageboot to the according directory (like /boot/grml). Note: if you re using the ext 2,3,4 filesystem on the partition that s being used for /boot please be aware that you need GRUB >=1.98+20100804-12 (newer version is already available in Debian/unstable and hopefully migrates to squeeze in time) or GRUB >=1.99~20101122-1 because of the INDIRECT_BLOCKS support, see #543924 for the details. PS: We think about providing grml-rescueboot and grub-imageboot within official Debian. If you re interested in seeing integration support for other distributions as well please help and drop us a note.

Michael Prokop: Simple DNS in chroots

Update: Ulrich mru Dangel suggested pdnsd as nice alternative to dnsmasq and Cyril KiBi Brulebois pointed out, that it s not necessary to invoke dnsmasq after fresh installation as it s running by default then I adjusted the text accordingly, thanks for the pointers! If /etc/resolv.conf doesn t provide any nameserver entries glibc[1] will automatically initialize the nameserver to the loopback address. This is nice for dealing with chroots without having to manually edit resolv.conf to get working DNS. Just install a basic DNS forwarder like dnsmasq ( apt-get install dnsmasq ) or if it s already on your box just start it ( /etc/init.d/dnsmasq start ). That s it. Now when chrooting into a system without an existing resolv.conf configuration it will give you a working DNS setup without any further work. PS: Grml ships dnsmasq by default and /etc/init.d/dnsmasq start or Start dnsmasq will work out-of-the box. In Ubuntu the dnsmasq package is available only through the universe repository but the dnsmasq-base package (providing e.g. the init script) is shipped by default, so replace the /etc/init.d/dnsmasq command with a simple dnsmasq there. [1] At least the [e]glibc versions provided on Debian and Ubuntu are known to provide this glibc extension. Other libc implementations like dietlibc and uclibc don t seem to provide it, so don t strictly rely on this feature but use it as the icing on the cake.

Christian Perrier: [life] [running] 2010 summary and early 2011 plans

So, 2010 ended and it's now time for me to make a small summary for my running activities. At first, it's more and more obvious that running became an increasing part of my life. Sometimes eating the free time I was using for Debian work....and sometimes just filling holes in my daily activities, where I was just doing nothing..:-) According to my running watch(es) records, I ran for 2172km this year in about 196 hours (8.25 days) at an average speed of 11.1km/h. Indeed, the speed ranges from 10km/h in the hardest trail runs up to 13.5km/h in the fastest (and shortest) asphalt runs. I actually never run at "slow" paces, which is probably not the best for training as all official training plans do include slow runs. But, eh, this is how it works for me..:) I ran 12 official or semi official races, ranging from 5km cross-country races up to marathons. More proeminently speaking, I ran 3 half-marathons, 2 marathons and one long distance trail race (33km) that is worth being counted as a marathon..:). I also broke my personal best times for 10km (48'05", ran alone), half-marathon (1h37') and marathon (3h40'). Quite a good year, indeed..:-) I'm currently busy building my plans for 2011. Some are already decided: In general, I'll probably put more focus on trail and ultra (above martahon) runs. 2012 could then be the year of my first 100km race..:-) What will be fun will be reading this in January 2012 and see what I have completed among all these goals..:-)

Michal &#268;iha&#345;: Finding a GPL violation

As the communication in this case seems to be stuck and the issue is almost one year old, it's time to make bits of it public. The first post will just describe how I've discovered it, later will bring more details. All started innocently with bug report on Gammu that it fails to work with some Sonim phones. We started to dig some information about what extensions does Sonim use and one of obvious ways was to try their software. I picked up software for Sonim XP3.20 Quest and started to look at it (if you are not going to install them, but want to look, you need unrar and unshield to unpack it). At first look the names of DLLs looked familiar to me and running strings on the DLLs just confirmed my suspicion - the phone which is not supported by Gammu bases it's official software on it. I was able to recognize at least seven DLLs derived from (GPL licensed) Gammu (they even use same names as Gammu modules had in that time): To make the thing more interesting they use several other components released under free software licenses, where they also should provide sources for them: There might be more, but I did not want to spend more time on deep analysis, because I already had enough information.

Filed under: English Gammu Gpl 6 comments Flattr this!

Gunnar Wolf: Back with Ruby on Debian polemics

Once again, a polemic regarding how to properly integrate the Ruby language and libraries with the Debian distribution has been ignited. Similar arguments were presented in November and December 2008 and September 2010 And excuse me for just refering to my own blog, but there are links to some other posts from there... and there will surely be many others I just missed. There were even nice collaboration attempts (such as DebGem, announced in January 2009... But which apparently never stuck on, as it is still listed as in its public Beta period and lists only support for Debian 4.0 and Ubuntu 8.04 and 8.10). Some days ago, while I was on vacation, I received a mail from Lucas Nussbaum expressing the burnout he had been suffering from this situation. Some days after that, he posted a corresponding blog post - Giving up on Ruby packaging. The comments following his post are most interesting The one comment I'd like to highlight (noting I skimmed a whole deal of them) is by Paul Brannan, one of the original RubyGems authors. Yes, possibly the design criteria for Gems included some mutually-conflicting goals, and they cover some of Debian's goals. Unfortunately, this conflicting criteria... Was resolved to the opposite way we would have wanted (specifically, that a sysadmin should be able to install software with the same tools he was already familiar with). And of course, there are deeper disagreements, which are rightly stemmed from different priorities: Debian (+derivatives) is meant to make user's and sysadmin's lifes simpler. Gems are meant to make developers' lifes simpler. And while all developers are some sort of users, and sysadminsthe reverse is (obviously) not so. A developer maintaining several different codebases will surely suffer (well, this particular developer has surely suffered) if he has to maintain them all using coherent versions of system libraries. When a system is programmed, its developers want to use the greatest, latest tools to offer the best experience and functionality. And it's natural for libraries to evolve over time. However, any sysadmin will grind their teeth at the prospect of having many different versions of libraries, as the Gem model proposes. Why? Well, I was bitten by a minor example of it Bug fixes do not get backported. Of course, if simple bugs are not backported, security and stability of the system as a whole suffers. Often, new software versions will not only add functionality, but improve on how things are done. Not only bugs get corrected, but we get better response times, better memory handling, etc. It might sound harsh to say this, and even more, as a developer it feels I am talking against myself But while development time should be minimized during the system design/implementation, once systems are in production, it should be used to allow for friendlier sysadmin relations. I have to wear both hats at my real-life job. So, what is my take on this? Of course, blaming myself for choosing the wrong version is a no-go. When evaluating a library before using it in my projects, I try to look at its history and API-stability. APIs that change often speak about immature libraries which are still trying to get the right way to implement their functionality; just-started projects might be great and revolutionary, but they do not yet show any kind of long-term committment... And can lead (and have often led me) to painful rewrites when the Next Big Thing is reached. As for the users: Even if your favorite language has the best and friendliest distribution method, users just do not care about what language was a particular piece of software implemented in. Users want to be able to install and uninstall with their system's usual tools. Directly using Gems, CPAN, PEAR and whatnot is just unnatural for users, however convenient they are for developers. Distributions offer a non-technical advantage in this regard as well: A human filter. As an example, as I write this there are 19392 Ruby Gems and 19092 Perl modules in CPAN (note that CPAN stores some older versions but discourages authors from keeping too many - So no, they are still very different in size). Debian has around 30,000 packages. Why is that? Because all Debian packages _must_ be human-generated, human-reviewed, human-submitted. This means, a person must think each packaged piece of code is worth packaging, is stable enough and provides value to users as it is, and is fit for being part of a stable release. I am not saying with this that 90% of CPAN and Gems are crap I am saying that they are probably early implementations, to be installed, tested and improved by developers, and still not apt for general public use. Or maybe not interesting enough to be packaged as a service for the non-techie public at large. Oh, and one last point: Ruby is not a new language anymore. It is a mature, powerful language with different implementations, every time more stable... But it is a language deeply affected by the (not so new anymore either) the appearance of Rails. Why do I say this? Because although the language is in no way tied to Web development, many of its strongest uses are Web-oriented. How does this affect the current discussion? Well, because many people argue that users are no longer needed to install the software. Web systems are installed by sysadmins and used via a Web browser, and sysadmins are expected be more skilled than casual users. Still, in Debian (and in other distributions, surely) we try to make sysadmin's lives simpler I have (again, talking out of personal experience) installed several webapps (and system tools, and whatnot) for which I never followed any instructions besides aptitude install foo Using different languages, frameworks, and so on. Can I troubleshoot their installs? Probably, as there is a common logic for how the distribution I have chosen and specialized in works. Can I find causes for bugs in them? Possibly, although there are some languages and frameworks I dare not touch. Can I get help on getting them out of a tight spot? Surely, as there is a central bug tracking system for my distribution And one of the maintainer's tasks is to separate the problems related to the distribution (packaging, installing, simple user questions and misconceptions) to those derived from real bugs upstream. Anyway I am not saying that our way is the best way. No, by a long shot. Again, developers should have an easy, convenient way for installing whatever they want to play with. And to publish it without jumping through hoops. With this post, I'm only trying to express again why Debian works the way it does. And hope for better cooperation in the future. And as for several comments of what I read in Lucas' post, I think that there is interest for this synergy among some of the most committed Ruby people.

5 January 2011

Wouter Verhelst: Substituting gdb debug paths

Gdb is a debugger with many, many, many(1) options. Some of them are rather obscure, others... less so. While it's always had the ability to read source files and do useful stuff with them, recent versions of gdb have gained another interface (which you get by calling "gdb -tui") that makes it a bit easier to watch the source as you step through the code. Additionally (and I don't know how long that feature's been there), you can do some interesting things with source paths. Such as substituting a source path prefix by another prefix -- useful if you've moved sources around. This is accomplished by way of the 'set substitute-path' command:
(gdb) set substitute-path /home/buildd /home/wouter
Now whenever gdb is told by the debugging info to search for a file /home/buildd/foo/bar/baz.c, it will instead search for /home/wouter/foo/bar/baz.c. Very useful. One problem with the above approach, however, is that you need to know what the original path is the /home/buildd in our example. If you've built the binary yourself, you just need to remember where you built it, and you're all set. But what if you haven't built the binary yourself? I used to use strings for that, and look for any likely candidates, but that isn't very reliable and requires a bit of hunting through many many lines that just happen to look like strings to what really is a fairly naive program. Additionally, it doesn't work when the debugging symbols are in a separate file (as implemented by dh_strip), amongst others. But no worries! There's a simple solution. Rather than using strings, use readelf -w instead, and grep for DW_AT_comp_dir, which will give you the correct source directory to substitute. I'm happily single-stepping through a library now. If that isn't nice. 1 no really, many

Next.

Previous.