Search Results: "ron"

26 September 2007

Miriam Ruiz: Piklab in Debian

I’ve been so busy lately that I forgot to write about it: Piklab is now in Debian. I don’t know if any of you has done and development with PIC microcontrollers, but it’s not that there was a lot of free programs for doing so. Even now, it might be problematic depending on which hardware you have for programming them. In any case, Piklab is an integrated development environment for applications based on Microchip PIC and dsPIC microcontrollers similar to the MPLAB environment, which makes it easier to develop. It’s a real pity that we cannot consider the newer versions of SDCC as DFSG-free, due some non-commercial clauses, because it is a real nice companion compiler for Piklab.

Scott James Remnant: Why I choose Bazaar (a history of revision control)

Like any sensible software developer, I have a close relationship with revision control systems. In my previous job, I was an SCM Engineer (see Software configuration management) which meant I had an even closer relationship than most, since we were running the CVS servers and actively using them to track changes and deployments. We all know, deep down, that revision control systems shouldn’t exist. This kind of thing should be inherent in the design of the operating system, through standard file and filesystem formats. The OLPC interface is making some headway towards that, but for the rest of us, it means using a revision control tool throughout the development process. Unfortunately, even though the tool is expected to be the most-used command on your system, very few of them are particularly easy to use. Thus there’s a large learning curve, and people become religious about their choice since they have invested significant time in using it. Just to spice the mix up, not only will people religiously defend their choice of revision control system, but they’ll do so while actively hating it. In the beginning there was CVS and we all thought that it was pretty good. It was based on the simpler RCS and shared a file-format with it, but introduced control of directory trees and remote operation. Actually, in reality, CVS wasn’t that good. Its command set could be a little strange and inconsistent (e.g. it’s not possible to diff between two dates on a branch); the support for branching assumed that all branches would be merged into the mainline, and only once; and nobody ever really knew how to create a new project in a repository (tip. cvs import is wrong). But we all used it anyway, and we muddled through. It did have some good features; it was simple, fast and pretty reliable–when it did break, you could usually fix the repository yourself. And most importantly of all, we understood how to drive it. And so it was for many years, until Subversion (SVN) came along. Subversion intended to be “a better CVS”, perhaps this goal should have made us suspicious at the time since CVS was already being a pretty good CVS by itself; unfortunately we hated CVS so much we flocked to the new system in hope. In hindsight, Subversion didn’t really improve on CVS much at all. In fact, arguably, the only real improvement was the addition of atomic commits (in CVS, each commit is per-file, so it’s manual labour to work out which change was made to two files at the same time). (Its support for branching, tagging, copying, renaming, etc. were no better than CVS’s when done in the repository by hand.) The cost of this single new feature was a much more complicated interface (with two separate commands), a backend that tended to break down weekly and a lethargic slowness to its operation. Most people I know now justify their use of Subversion instead of CVS by “Subversion is maintained, CVS isn’t” which is a somewhat self-fulfilling justification. While the mass conversion to Subversion, and ensuing disappointment and frustration, was going on; something new appeared on the horizon: Arch. Arch was different, it broke one of the core assumptions of revision control, that of the repository as a cathedral. In CVS, and Subversion like it, if somebody wants to modify your code (even if on a branch) you need to give them access to your own repository. In some cases (especially with CVS), vast access control and permission structures would be in place to ensure proper behaviour. With Arch, you don’t; all you need to give to anyone is read access. Anybody can make their own branch by copying yours and committing to their own copy. This model also necessitated fixing a long standing problem that CVS had; Arch has repeatable (smart) merging. If you merge from a branch, you can merge again later, and again, and again. Arch made this possible through each commit (changeset) having a globally unique identifier; made from the branch’s own globally unique identifier and the changeset number in the branch. Unfortunately while this was a massive step in a new direction, Arch had an absolutely terrible user interface. Its command list was terrifying with over 100 commands, many of which had multiple word names (tla set-tree-version). It exposed too many of its own innards, and expected you to learn them. It also forced baroque file naming semantics on its users and strange policy (though shalt not commit without first running “make clean”). Efforts were made to improve Arch’s user interface through projects such as baz, but they were always to be doomed from the start. We’ve since seen an explosion of new revision control systems; Monotone, Darcs, Git and Bazaar. What’s especially interesting is the commonality between these systems. They are all “distributed” like Arch, though they also all discard the strange “unique branch identifier” convention and instead simply assign a unique identifier to each file or commit. This means that they all support personal branches, and by necessity all support repeatable (smart) merging. So how do they differ, what are their killer features and killer problems? Monotone is all about repository integrity, ensuring that every commit is both authorised and intact. It pays for this with a severe lack of speed. Darcs is based around a “theory of patches”, a branch is not made up of its history but by the collection of patches in it. Unfortunately this often breaks down, and darcs frequently gets stuck calculating even trial and commonplace branch models. Git is very strange to me; its killer feature appears to be the speed at which it can handle very large trees, but the interface is as insane as Arch’s was. It is heavily optimised for the “I only apply patches” development model, at the expense of ordinary development models (it shares an issue with Arch where calculating annotations on an individual file is an expensive operation). What about Bazaar? Its killer feature is that it is designed to work the way you do. The command set is relatively small, and each of them works in the most obvious manner. It also supports plugins so that you can always implement your own workflow. Of all the revision control systems, it’s the only one (that I’m aware of) that supports both distributed and centralised workflows (and lets you go distributed when you need to, e.g. when you’re on a plane). Here’s a few examples of how Bazaar’s command set works the way you do. To start managing some code in bzr:
$ cd myproject
$ bzr init
To add the files, copy in your usual .bzrignore file and just add everything:
$ cp ~/bzrignore .bzrignore
$ bzr add
added foo.c
added bar.c
Check the output for mistakenly added files, adjust .bzrignore and remove the file with bzr rm. A common operation is realising that the commit you’re about to make should really go on a new branch for now:
$ cd ..
$ cp -a myproject myproject-foo
$ cd myproject-foo
$ bzr commit
A copy of a Bazaar branch is a different branch, you can commit to it separately. There’s a bzr branch command for it too (which deals with issues such as bound branches, checkouts, etc.) but it’s nice to demonstrate that Bazaar does what you’d expect even when you don’t use its own commands. Pulling changes from another branch (where you haven’t made any modifications yet) is easy:
$ bzr pull ../myproject
As is merging (when your branches have diverged):
$ bzr merge ../myproject
One particularly nice feature is that after a merge, you see the merge as a single commit and it can be treated as such; but it also has the set of merged commits indented under it–you can examine these as individual commits as well! What’s the downside of Bazaar? Well, it’s not the fastest system (but by no means the slowest), for small to medium sized projects this is never an issue but may be for extremely large projects–fortunately the developers are improving its performance all the time! But that doesn’t matter; it is, honestly, the first revision control system that I don’t hate.

MJ Ray: Places to Visit / Re: WSM Season?

I was trying to figure out when "the season" ends in Weston, but it's not obvious any more.

The seafront/Sand Bay bus service reduced at the start of September (end of the Peak Summer open-top service) and again on the 22nd (end of the Summer service), which makes things a bit less convenient, but that's about the only major change I can spot.  Some of the council services reduce in winter, but that won't really affect tourists.  I asked a neighbour who works at a holiday park and he said they're still busy and won't really be quiet all winter, except about four days closed around Christmas.

I'm not a big fan of autumn, but it's better here than many places, with several good firework events to cheer things up and then the town carnival, which I think is linked to Bridgwater's somehow, so looking at their gallery will give an idea of what's coming.
http://www.bridgwatercarnival.org.uk/carnival_gallery/2006-gallery.php

Only downside of the carnival IMO is the travel chaos as large parts of the bus network shut down instead of routing around the road closures, so almost everyone hits the cars - but they can't reach some of the car parks because of the road closures...

Alastair McKinstry: GIT Changelog comments

My job involves working on other peoples scientific codes, and recently I've been experimenting with using GIT as a VCS. Its very handy for making a quick repository while you change one or two files, nice and lightweight. What distinguishes science codes from other software projects, both open-source and proprietary, is the comparative lack of formal releases. Often the developers are the users, making changes for their own use. They make a model, write a paper, done. They'll take their old code and edit it to add features, but don't plan on "releasing" it in any formal way. So, often you get a tarball from a fellow researcher with the name 'astro.tar.gz', and beyond the paper describing the science, you'll be lucky to find a changelog. Online repositories, test suites, etc. are a rarity. So I've been wondering how to improve on this, in terms of refactoring, etc. and how GIT and other Distributed VCS's can best be used in science. Some ideas: Has anyone else seen similar techniques or tags in use, particularly for science ? Tags , ,

25 September 2007

Christian Perrier: RWC: AUS-FID, NZL-SCO

Sunday was a quiet day for the top teams. Neither Australia nor New Zealand were in danger against Fidji (55-12) or Scotland (44-0). I'm still impressed by the australian team. They didn't show much weaknesses against Fidji, despite the strong physical contest bringed by the Fidjian forward players. The australian rear lanes were impressive, particularly Matt Giteau, scoring 27 points and designed as MVP for Australia-Fidji. The All Blacks crushed a B team from Scotland. The scottish staff decided that winning against New Zealand is nearly impossible and therefore they choosed to have their key players resting, which is a wise choice, but not a gift for the Murrayfield supporters. As a consequence, New Zealand quitely won the match and therefore qualifies for 1/4th finals (and they'll win their pool unless Romania plays with 30 players against them....). No match for yesterday and two matches today. Unfortunately, Canada-Japan (12-12) in Bordeaux was broadcasted too early for me and I haven't seen it. For Japan, this is the end of 13 consecutively lost matches in RWC for Japan, so kind of victory. I've seen parts of Romania-Portugal. I wished Portugal wins that one as they're clearly the most courageous team in the RWC and certainly, among the non top teams, the most promising one. The Portuguese lost 10-14 even though they lead 10-7 for a while. Quite a deception for me but surely these players will never forget the support of the French crowd (most of these being the strong portuguese community we have in our country). Tomorrow will feature Georgia-Namibia and Samoa-USA. I'll try to watch the latter, which is played in St-Etienne, my welcoming home town (ask the Scots supporter and team!).

David Nusinow: More Code And Less User Support For A While

While it's cute that atoponce wants to blame #debian for his problems, what he neglects to mention is that I spent some time with him in #debian finding his bug and telling him that his best bet was to watch that bug report because that's the most up to date information available on the problem. Furthermore, I told him how to add a "me too" to the report so that he would be taken care of. I also googled him up a wiki page that explained what GLcore was better than I ever could. And I tried to do it as politely and respectfully as I could.

I'm not sure what more people want from the channel. The #debian policy is that "if you're running sid, you're on your own." The reason is that it's your machine and you're responsible for it. The fact that Aaron chooses to blame other people for his decision to run a development version of a package (and then to not downgrade it when it becomes too problematic) is the kind of frustrating attitude that makes me want to stay away from being active in user support.

Fortunately, #debian is actually a very good channel on the whole, especially in comparison to the past, where some individuals really were just plain mean spirited. It's full of knowledgeable users who are generally willing to help you find a solution to your Debian problem. Sure, they're wrong sometimes, everyone is. And no matter how knowledgeable you are, you're not going to be able to predict that the next upgrade will hose some random guy's system. If you want to run unstable, be prepared for what's in store and learn how to downgrade.

Joerg Jaspert: Password Manager

Dear Lazyweb, im looking for a “password management” application that does not suck. Any suggestions? I am currently using fpm for some low-security passwords and a gpg encrypted textfile for some more important ones. (And having some really important ones only in my head, stored nowhere else). While it works its not really comfortable or fun to use. Now, I would want an app where i can trust its encryption (while I do have my harddisks crypted the file should still be encrypted), so usage of GPG would be nice. It should also be able to group passwords, like fpm can. I do not care about any kind of “URL launcher”, thats a feature i never use. Most important - it should be able to merge its dataset. Use case: I want to use it on multiple systems and have it synchronize the data itself. The sync can be a process I manually have to start, I dont care. But trying to keep the datafiles in sync and hope I never accidently overwrite them just does not work. I also dont care about X or not (as long its not one of the gnome or kde integrated keyring things), as long as I can easily get the password out of it into a copy/paste buffer, without displaying it… Suggestions?

Masayuki Hatta: ghostscript 8.61.dfsg.1~svn8187-1 uploaded

So, brand-new packages are now in the NEW queue. Sorry it took soooo long time(my life has been hectic these days). I guess it might take another long time to make them entered into the archive, so I give you some apt-line:
deb http://people.debian.org/~mhatta/debian/ghostscript/ ./
deb-src http://people.debian.org/~mhatta/debian/ghostscript/ ./
Tell me if something goes wrong in the process of transition. One of the reason I was reluctant to upload them (while Ubuntu has already did almost 2 month ago) was, the CJKV support in GPL Ghostscript 8.60 is notably regressed from the level of ESP Ghostscript 8.15.1. Seems Till Kamppeter once merged some key CJKV patches into the mainline SVN repository, but later they were revoked. Until recently, I didn't realize why Till used a rather peculiar old SVN snapshot 8187 for Ubuntu (the current SVN revision is something like 8249), but now it's clear for me. I could choose to apply those revoked patches to the 8.60 source by myself, but as you might know I'm a lazy bastard, so I simply follow the Ubuntu path, with some Debian-specific tweaks. Well, let's hope this issue will be fixed before the official 8.61 is released...or I'll try, hopefully.

Tag this post with del.icio.us!

24 September 2007

Adeodato Sim : Dear Lazyweb, an RSS reader that with new != unread count?

I’m looking (or I’m desperate) for an RSS reader which differentiates between new and unread articles, and can show a count that only includes new articles for each feed. My current reader, Akregator, sort of fulfills the first requirement, but not the second. If you know of one, please let me know. I’m willing to give it a try even if it’s written for another desktop environment than my own, or in a language that I don’t like. If I can’t find one, I will try to go back to rss2email and Mutt. But I really, really, really dislike the management of feeds with rss2email. I would love to have it read a simple text file where feeds are listed in groups, each group has a keyword to add as an email header, and I’m free to add/delete/move feeds in the text file with changes being effective in the next r2e run. Any suggestions on this side?

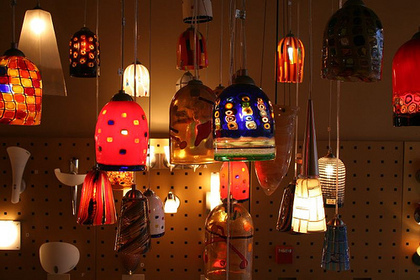
Benjamin Mako Hill: Lamp Stores

I have an intense, unexplainable, uneasiness around lamp stores. Perhaps it's even a fear. /copyrighteous/images/lamp_store.jpg Something about so many lamps, so close together. It seems unnatural. Very Wrong.

Simon Richter: Some status bits

Progress on most fronts. Life is mostly good thus. Reading email only once a day also helps a lot in remaining sane. If it can be urgent, I have given you my phone number. It seems that Planet Debian has a new meme, namely unveilling replacements for the ion window manager. I'm late to the party as I'm using mine as the example code in the componentisation tutorial to introduce the concepts and language bindings one by one -- obviously I have to make that work with a few languages first. And at the same time, work for a living.

23 September 2007

Russell Coker: DMCA and Sci-Fi

My previous post about the SFWA falsely issuing DMCA take-down notices [1] has got some reactions, many of which indicate a lack of clear reading of my post. I am not advocating boycotting sci-fi. I am merely changing the priorities for my reading list. There must be at least 10 sci-fi books on my shelf of books to read, so refraining from buying more for a while isn’t going to impact my reading much either. In regard to whether boycots are good or bad, it should be considered that the enjoyment of a work of art is highly subjective. If you don’t like the artist then you probably won’t enjoy the art. Boycots on products for which there are objective criteria of quality are often unsuccessful because the buyers have to make a conscious decision to buy a product of a lower quality or a higher price. I can’t make any objective claim about the relative merits of the work of Cory Doctorow and Jerry Pournelle. But it is impossible for me to enjoy reading Jerry’s work as much as I enjoy reading Cory’s work due to my opinion of the two authors. I have just read a post by Eva Whitley [2] (the widow of Jack L. Chalker - one of my favourite authors when I was younger). She starts by describing Jack’s attitude towards electronic publishing, which sounds quite enlightened. She then notes that Del Rey has the rights to some of his books which are officially still in-print but in practice impossible to get, Baen is still paying royalties but had paid him a large advance so he won’t receive money until the royalties exceed the advance, and some books are out of print but no publisher wants to buy the rights to do a re-print. So it seems that she is not receiving money from her late husbands work partly due to book companies being uncooperative (not printing the books and not permitting others to print them without payment) and partly due to being paid in advance. Eva states that she is happy that the SFWA issued take-down requests for copies of the work of her late husband. That is good and in fact it’s a legal requirement. No-one can legally get copyright laws enforced unless they own the copyright or they are acting on behalf of the copyright owner. She is entitled to authorise the SFWA (or any other group) to act on her behalf in regard to her copyright violations. Neither the SFWA nor anyone else can take action against copyright violations without such permission. Jerry Pournelle has written about the situation [3]. He complains that the site owners wanted the items listed individually. The Wikipedia page about the DMCA [4] makes it quite clear that you must provide such detailed information to get something taken offline, and that the DMCA take-down request MUST include a statement claiming ownership of the material UNDER PENALTY OF PERJURY. If you make a false DMCA claim then you are committing perjury, according to Wikipedia the penalty for perjury in the US is up to five years in prison [5]. Sure any idiot can write up DMCA take-down requests for random stuff on the net and get them acted on (here’s an example of a 15yo idiot who did just that [6]). But if you want to stay out of jail you have to avoid making such false claims. Jerry expresses a total lack of sympathy for Cory Doctorow and other people who have been victims of slander of title [7]. I wonder how he would react if someone started making public statements under penalty of perjury claiming that he didn’t own the title to some of his work. I suspect that he would desire something similar to what he desires to be done to people associated with 9-11 [8]. Finally one thing that I suggest doing to make some additional money from writing sci-fi is to release T-shirts. A basic T from cafepress.com was $7 last time I checked. $11 for a shirt based on a sci-fi book is not overly expensive and gives $4 profit for the author (more than twice what most authors make from a book sale). Shirt sales are unlikely to make as much money as book sales due to lower volumes, but the effort involved in creating a shirt design is not so great. A publishing company may deny an author (or their estate) future revenue by refraining from printing further copies, but unless they also own the trademarks related to the book and deny the author (or their estate) the right to use them then it should still be possible to make money from merchandise. Making money from merchandise is not as glamourous as making money from book royalties, but it can be effective as demonstrated by xkcd.com.

Christian Perrier: RWC: ARG nearly in 1/4th, ENG wakes up

After the stunning match between RSA and Tonga, we watched an also very good England-Samoa (44-22). Even if their play was still far from perfect (lack of imagintation, mostly), the English players succeeded quite easily against Samoa who never gave up. Johny Wilkinson's come back is a success, imho, and England will then play against Tonga for qualification on Thursday. The winner of that match will end up 2nd of that pool (assuming that RSA wins over USA) and should logically play against Australia (while RSA will play against Wales or Fidji, this assuming that Australia wins over Fidji today). Argentina had to win against Namibia with the bonus point. They easily made it (63-3). As usual in such situations, Namibia resisted about 30 minutes (and were even leading 3-0 for a few minutes). However, the imprecision of their game (a disastrous kick play) left dozens of balls to the Argentinians who then could easily score lots of tries. The Argentinian were, at the end, obviously sparing their energy for the upcoming fight against Ireland next Sunday. In this pool everything can happen (even Argentina being eliminated, which is however not very probable). From what they showed, the Argentinians can definitely win over Ireland, which would then give them the first rank and an easier 1.4th final against Scotland or Italy. Two matches today: Australia-Fidji and Scotland-New Zealand. Australia and New Zealand have a strong advantage and I don't really expect any surprise here.

22 September 2007

Christian Perrier: RWC: Wales quietly to the 1/4th, France still alive

Thursday featured Wales-Japan which we briefly watched. Easy win for the Welsh who begin to secure down their qualification for the 1/4th finals. They'll just need a victory over Fidji on Sept 29th to do so (but Fidji would qualify by winning so that match will be one of those to watch during last round). Nothing really interesting to say about WAL-JPN (72-10). The difference in the front lines was too obvious for Japan to get any chance to win. However, at least during the first half of the first half-time, the were even leading after scoring one of the best tries as of now in the tournament. Yesterday was a key day for the French team. Victory against Ireland was mandatory. They made it (25-3, two tries) which is by far the most important. That wasn't definitely an easy match but noone was hoping it to be one. The french game is still far from being perfect (sometimes strange kick play and weird decisions by the rear players, sometimes slow assistance to players in rucks and sometimes stupid fouls giving their opponents opportunities to kick penalties (or expelled players as Traille was at the end of the game). On the other hand, some parts of the game were good quality: scrums (two balls won), line-outs (4 or 5 balls won on opponents' throw: great Julien Bonnaire there) and the magic inspiration of Elissalde and Michalak on the two tries as well as Clerc scoring these tries. There is still room for progress for the French, definitely (the same play against New Zealand, Australia or South Africa would be a loss). They're however on a good way. Next step is winning over Georgia, hopefully scoring a bonus point (that may be harder than expected as Georgia showed good defense) and hope that the Irish team will win over Argentina. Again, this week-end will be busy:

David Welton: Erlang

As someone who tries to read a lot about my field, I feel I have my "ear to the ground", so to speak. And right now, I'm picking up a lot of hype-rumblings about the Erlang programming language. I have a little bit of experience with it, having used it briefly about 3 years, and having made a few minor contributions. Why are people interested in it? Picking up new programming languages is fun for some people, but in general, unless it's something backed by millions of dollars of marketing and development (Java, C#/.Net) there needs to be a 'killer feature' to drive adoption. Tk and Tcl, ease of developing simple dynamic web content with PHP, Rails and Ruby, and so on. Erlang, in many people's eyes:
  1. gets concurrency right, or at least is a big improvement over existing models (threads).
  2. Makes distributed computing easier and does it naturally.
  3. Is a solid base on which to construct reliable applications.
That appears to be enough to have nudged Erlang into a position where it has a chance at the big time. While I would highly encourage people to learn a bit of Erlang, and to seriously consider its use for the type of systems for which it was created, I have some doubts about it becoming that widespread. Please read the following as the thoughts of a critical mind, and keep in mind that it's far easier to zero in on defects than it is to create something from scratch, so do not misconstrue my writing as being "against" Erlang (I do use it, enjoy it, and recommend learning it!), but as an honest appraisal colored by my own view of the world, which might not be like yours. To begin with the superficial, its syntax is a bit odd. For a professional programmer, that shouldn't present much of an obstacle, and indeed isn't after a few days of using it, but there are a few things that I do find a bit annoying despite being used to the syntax, first and foremost being the use of . and , to separate lines of code, rather than a newline, or ; (which is used elsewhere). They're like little mouse droppings - hard to spot, and they get in your way when you swap out bits of code here and there. The last line of a function must end with a ., but other lines are separated with commas, so when you're cutting and pasting lines from here to there, you end up having to recheck the line endings each time. Erlang is a functional programming language. Once again, someone with a wide exposure to many programming styles will not find this difficult after a week or so of practice, to wrap your mind around a different way of thinking. However, I have some doubts as to whether a functional language will be able to bring on board the numbers necessary to be widely adopted (see Scaling Down). One of the benefits of wider adoption is, indeed, having a wider set of libraries - it's a "positive network externality" in terms of economics. Other people have written about the relative lack of Erlang libraries to do various things, but it's actually not one of the things I'm worried about - it's something that will take care of itself if the language grows in popularity. After being spoiled by Ruby's gems, what I really miss, though, is a nice, simple, easy distribution mechanism. Related to making it easier for J Q Programmer to adopt, the error messages are at times not the most helpful I've seen in the computing industry:
Error in process <0.29.0> with exit value:
 undef,[ shell_default,sfdsf,[] , erl_eval,do_apply,5 , shell,exprs,6 , shell,eval_loop,3 ] 
In English, that means that I tried to execute the function sfdsf(), which doesn't exist. It seems that there ought to be a way to keep the nice, computer parseable error messages, and add in something that humans would find just a bit easier. Other people have already covered the problems with Erlang's strings, so I won't belabor the point. Suffice it to say that, in my opinion, is_list([foo, bar, baz]) and is_list("hello") should probably not both be true. Which brings us to another issue. Erlang is a language used in big, reliable systems like telephony switches. That's not the sort of environment where you want to break things, so I doubt that Erlang will ever see big changes that introduce incompatibilities, like Python has recently done. This one is a tradeoff - stable, reliable and backwards compatible is simply not compatible with rapid development of the language - it's a zero-sum game, you want more of one, you get less of the other. Related, is the "open sourceness" of the language. It is open source, which for me is very nearly a prerequisite for dedicating my time to a language, but Ericsson appears to maintain firm control over it. This is another thing that's both good and bad. Having the backing of a large corporation means that developers are paid to work on and enhance Erlang, which is beneficial to everyone. On the other hand, as some people say, open source is just the start, open development is important too. Random thought: I bet Erlang would make a nice Apache project, but I'm sure the bureaucracy involved would be a nightmare. In terms of the language itself, beyond the syntax, it feels a little bit too verbose. Perhaps not as much as Java (that would be difficult, wouldn't it)... maybe I'm just used to Ruby, which is about as concise as I'm comfortable with while still being readable. Sometimes, though, there is a little bit more 'repeat yourself' than I would like to see. For instance, in this implementation of string_join (something else that ought to be in the standard library, but still isn't), it's necessary to create the same function, with different arity, simply to work around the fact that it's not possible to say the default separator should be " ":
string_join(Items) ->
    string_join(Items, " ").
string_join(Items, Sep) ->
    lists:flatten(lists:reverse(string_join1(Items, Sep, []))).
Which is a lot more typing than string_join(Items, Sep=" "). This is pure opinion, and very subjective, but Erlang to me feels like it falls more in the "systems programming language" category than "scripting language". It's a bit more verbose, it needs to be compiled to run it, modules need to have an entry point... it's not as suitable to quick throwaways as Ruby, Tcl or Python. Of course, it is certainly higher level than C, and leaner than Java, but still falls an the other side of an admittedly fuzzy line in my head. Its command line options reinforce that. Whereas "scripting" languages do the obvious thing first:
ruby foo/bar.rb
Erlang is a little bit more complex:
erl -noshell -pa foo/ -run bar
A minor detail, once you get used to it, but still, I prefer the "do the obvious thing first, and let the user have some say in the matter if they want to do something else" approach to systems design. One of the wonderful things about Ruby on Rails, is that it uses Ruby throughout, templates included. Without getting into the merits of using templates vs other systems, my own opinion is that Rails gets them right, and demonstrates the flexibility of Ruby by using it as the language for the templates, rather than inventing some other solution. I don't see the same flexibility in Erlang, which is unfortunate, as it blows Ruby out of the water in terms of being a very solid solution to deploy on a server (no fiddling with proxies and load balancers and single threaded mini-servers + hot code replacement = nice). Of course, there are lots of good things about Erlang, as mentioned at the beginning of this article - concurrency and distribution, but also language features like pattern matching that are a lot of fun to use, a pleasant syntax for dealing with binary data, list comprehensions, first class functions, tail recursion, and lots of other goodies. However, if I had to try and predict the future, I could easily imagine another language grabbing some of Erlang's good ideas and running with them, perhaps being more "conventional" in other respects - this isn't uncommon in the languages field, as we've seen with things like Lisp and Smalltalk. On the other hand, one of the reasons I *am* quite happy with Erlang is that it is most certainly not a proof of concept - it is a very practical language that excels at solving certain classes of problem, and does so in many commercial settings. If you're the kind of person who enjoys new things, check it out!

Theodore Ts'o: How to properly support writers/artists?

Russell Coker, commenting on my last blog, and apparently after exploring some of the links stemming from the SFWA kerfuflle, apparently stumbled on a post from former SFWA VP Howard V. Hendrix, where he took the amazing position (for a SF writer) that he hated the using the internet, and that people who posted their stories on the web for free download were web-scabs, has taken the position that since such comments were an attack on our (Open Source Developer’s) community, that he would resolve “to not buy any more Sci-Fi books until I have read all the freely available books that I want to read”. Obviously, that’s his choice, but while I don’t have much respect for SFWA the organization, and certainly not for their choice in past and current vice presidents, there’s another side of the story here. First of all, Dr. Hendrix comments are not the official position of the SFWA, and there are many others who are SFWA members who would very strongly disagree with both the attitudes of Dr. Hendrix as well as the ham-handed DMCA pseudo-invocation by Dr. Burt. In addition, to quote Rick Cook:
The first thing you ve got to understand about the Science Fiction and Fantasy Writers of America is that it isn t. Like the Holy Roman Empire, which in Voltaire s phrase was neither holy, Roman nor an empire, SFWA is not an organization of science fiction and fantasy writers. While some of the leading SF and Fantasy writers belong, the vast majority of the members are people who barely meet SFWA s extremely lax publication requirements. They are not professional SF or Fantasy writers in any meaningful sense of the term and many of them haven t published a word of either science fiction or fantasy in years.
Secondly, there are plenty of Science Fiction writers that do really understand this issue quite well. In addition Rick Cook, whom I recommended in my last post, another example of a Science Function writer who has penned a very cogent series of articles about copyright, science fiction, and the business issues of being a SFF writer is Eric Flint. I strongly recommend his series, “Salvos Against Big Brother”,which includes a back-to-the basics examination of copyright quoting and reprinting two speeches by British Parliamentarian Thomas McCauley in 1841. Definitely worth a read, and again a demonstration that there exists Science Fiction authors that aren’t stuck in the dark ages; few (at least it is to be hoped) are like Dr. Hendrix. Eric Flint is also a senior editor for Baen Books (read more about the founder, Jim Baen here). Baen makes all of its titles available in e-book form without DRM, and many of its authors have agreed to make their books available completely free of charge. Eric Flint does so for all or most of his books shortly after they are published in mass-market paperback form; others only make a few of their books available, typically the first or second books in a series (in the hopes you will buy the rest of their books) — a wise strategy, as he explains in one of his Salvos Against Big Brother columns. More importantly, I strongly believe that if we enjoy an artist’s works, we should support the artist. That’s why I’ve directly reached out and given money to musicians, authors, and Debian release engineers. (Yes, that last was controversial, but to me and personal ethics, it’s all of the same piece.) Is patronage the right way to support musicians? Well, it’s one way, and I’ve always been fond of the “distributed patronage” model where we use the Internet to allow a large number of people to each contribute to support an artist’s work. The Big Meow is a good example how it might work. (By the way, to people who are wondering what is happening with The Big Meow — I have very recently pinged Diane, and she’s working on it. Between health and family emergencies, the last 12 months have thrown a lot of delays into her writing schedule.) Are there other models other than patronage that might work? Well, there is the traditional one — just buying the author’s books. But what if we don’t want a dead-tree copy and just want to be able to read it on our Irex Iliad, and the book wasn’t published by Baen Books, or one of the few enlightened publishers who make non-DRM’d eBooks available? That’s a harder question. Personally, I don’t find “Copyright Theft” immoral per se. Illegal, yes, but immoral only if I haven’t done something to materially support the author. If I’ve purchased a new copy of a book, and the eBook version isn’t available via legal means, I don’t believe it is immoral to download it from a site like scribd so I can read it on my laptop. Of course, that brings up other questions, such as what if the book is out of print (because the publisher don’t think it’s commercially viable to reissue the books), the author is dead, and the widow needs money? Lots of hard questions, and no good answers…. But in any case, I think it is the right thing to do to support those authors we care about as we can, and boyotting all SFF books isn’t necessarily appropriate or helpful.

Andrew McMillan: Software of the week

This week has been a week of pictures for me. I was looking around on Wikipedia earlier in the week and decided that the articles around the Porirua area where I live was looking a little barren. So I've been out taking a few snaps to liven it up a little. The articles themselves don't look that great either so I'll see if I can't put some effort into improving them as well. As a result though, I've been playing with photographs and I'm finding that the graphics landscape on Linux has improved significantly since last time I was playing around with things. I've been using Hugin for making panoramas since someone pointed me to it at Debconf5 in Helsinki, but version 0.7beta4 with Panorama Tools 13 is an immense improvement. It seems that now if I take my photos the right way I can expect Hugin to create a panorama with only a couple of minutes of time, and no real effort to speak of. I built some Debian packages of Hugin 0.7beta4 and libpano13 which are here, if you're interested. Sadly, it seems that the current maintainer has not updated these packages for a long time. Something I've also been trying to do properly for some time is to produce decent HDR images. Although the tools have been around for a while they are somewhat inaccessible to people, taking a long time to gain any kind of intuitive understanding about how they work and what parameters a person should use. The answer, it turns out, is something like the Hugin one: provide a GUI front end. Well there now is one, and it's damn good. I've now started taking a few photos in triplicate so I can fiddle around with QtPfsGUI and learn to recognise the situations where HDR can make a better photo. It's not an addictive name, but it's great software and when I've managed to get my head around it I will create an HDR area on my gallery and put a few fun images in there. I've built some Debian packages of this also, but I've never had to deal with something using QMake before and it doesn't seem particularly friendly to packaging. Probably I'm just beating on it the wrong way. Anyway, here are some Debian QtPfsGui packages for anyone who is interested. Maybe if you know how better to drive qmake from a distribution point of view you could send me some tips. Something that I really like about both Hugin and QtPfsGui is the way that they are providing a GUI framework for some pre-existing command-line tools. The separation of UI from function is a classic application of the Unix model that will be familiar to anyone who has ever piped find into xargs, and it really does allow for the whole to be greater than the sum of the parts. What is interesting about the two above, seems to be that by providing the UI they have managed to breathe some new life into the underlying functions as well. The next thing that I'm really looking forward to is the upcoming 0.46 release of Inkscape SVG editor. This totally awesome program just gets better and better and a bunch of the upcoming enhancements come from the Google Summer of Code. Actually all of these programs are quite a bit better recently because of the sponsorship they have received from the GSoC. There have been a few Catalyst people mentoring some GSoC projects - mostly around Moodle, Lisp and Git - so a couple of the Catalyst folks will be off to the big meetup / review in a couple of weeks. I hope those lucky stiffs pass on my thanks to everyone involved.

21 September 2007

Cameron Dale: 2Wire Router 2700HG-E Violates HTTP/1.1

I recently upgraded my Internet service with Telus, which included a new wireless router to replace my old high-speed modem. The new router is a 2Wire 2700HG-E which is configured through a web interface. The web interface worked fine at first on some other machines, but whenever I accessed it from my main desktop machine the pages would either fail to load, or have the images in the wrong locations. After much debugging (though it seems obvious now) I finally discovered that this was due to my enabling HTTP pipelining in FireFox on that machine (as suggested by Mozilla). Being the diligent citizen that I am, I of course filed a support request so that this could be fixed in the next version of the 2Wire software. Here is the response I received:
The HomePortal GUI was designed for internet browsers on default settings. We recommend keeping the pipelineing [sic] setting on "false".
Not exactly a good solution, and a little surprising, considering it's relatively straight-forward to implement. I know because I recently upgraded a simple HTTP handler from 1.0 to 1.1 specifically to support pipelining, as part of my work on DebTorrent. Now I've just read "Structured streams: a new transport abstraction", in which the authors state:
implementing pipelining correctly in web servers has proven challenging enough that seven years after the standardization of HTTP/1.1, popular browsers still leave pipelining disabled for compatibility
So it seems pipelining is disabled for a reason, though I had it enabled for years in FireFox and saw no problems (that I know of) until now. Maybe the problems are a thing of the past. Does anyone else have any experiences (good or bad) with pipelining to share?

Holger Levsen: Democracy as you knew it is over

A new law is being made in germany, which will make consentual sex between minors a crime, which has to be punished with four years of prison at least, plus ending up in a sexual offenders database for life. I, for one, do not welcome our new taliban overlords.

These two articles explain the situation in full detail (in german).

In other news, it's 102 days until all electronic communication in germany (as in the EU) will be logged for half a year. (Until a terrorist attack happens which was planned for more than half a year...) This includes all emails sent, the location data of all mobile phones, every webpage visited and so on. From everybody. If you are in Berlin tomorrow, go demonstrate. I, for one, do not welcome George Orwells lack of imagination, 1984 looks really pale today. (But it's still a good read.)

My next blog post shall take place in teletubby land again and shall feature smileys as well. Sigh.

Russell Coker: Multiple DNS Names

There are many situations where multiple DNS names for a single IP address that runs a single service are useful. One common example is with business web servers that have both www.example.com and example.com being active, so whichever a customer hits they will get the right content (the last thing you want is for a potential customer to make some trivial mistake and then give up). Having both DNS names be equal and separate is common. One example of this is the way http://planet.ubuntulinux.org/ and http://planet.ubuntu.com/ both have the same content, it seems to me that planet.ubuntu.com is the more official name as the wiki for adding yourself to the Planet is wiki.ubuntu.com. Another example of this is the way http://planet.debian.org/ and http://planet.debian.net/ both have the same content. So far this month I have had 337 referrals to my blog from planet.debian.org and 147 from planet.debian.net. So even though I can’t find any official reason for preferring one over another the fact that more than 2/3 of the referrals from that planet come from the planet.debian.org address indicates that most people regard it as the canonical one. In times past there was no problem with such things, it was quite routine to have web servers with multiple names and no-one cared about this (until of course one name went away and a portion of the user-base had broken links). Now there are three main problems with having two names visible:

  1. Confusion for users. When a post on thedebianuser.org referred to my post about Planet Ubuntu it used a different URL to the one I had used. I was briefly worried that I had missed half (or more) of the content by getting my links from the wrong blog - but it turned out that the same content was on both addresses.

  2. More confusing web stats for the people who run sites that are referenced (primarily the bloggers in the case of a Planet installation). This also means a lower ranking as the counts are split. In my Webalizer logs planet.debian.org is in position #5 and planet.debian.net is in position #14. If they were combined they would get position #3. One thing to keep in mind is that the number of hits that you get has some impact on the content. If someone sees repeated large amounts of traffic coming from planet.debian.org then they are likely to write more content that appeals to those users.

  3. Problems with sites that have strange security policies. Some bloggers configure their servers to only serve images if the referrer field in the HTTP protocol has an acceptable value (to prevent bandwidth theft by unethical people who link to their pictures). My approach to this problem is reactive (I rename the picture to break the links when it happens) because I have not had it happen often enough to do anything else. But I can understand why some people want to do more. If we assume that an increasing number of bloggers do this, it would be good to not make things difficult for them by having the smallest possible number of referrer URLs. It would suck for the readers to find that planet.debian.org has the pictures but planet.debian.net doesn’t.

The solution to this is simple, one name should redirect to the other. Having something like the following in the Apache virtual host configuration (or the .htaccess) file for the least preferred name should redirect all access to the other name. RewriteCond % REQUEST_URI ^(.*$) [NC]
RewriteRule . http://planet.example.com/%1 [R=301,L] In my posts last night I omitted the URLs for the Planet Searches from the email version (by not making them human readable). Here they are:

Next.

Previous.