Search Results: "tar"

6 February 2011

Jan Wagner: Debian 6.0 squeeze released

Our baby was release just some moments ago. Many thanks to all who made this happen, I m very proud!
Also many thanks to the release team, ftpmaster, cd people, www-team, press folks and all who worked so hard today instead of having release party, to make it real.

5 February 2011

Joerg Jaspert: Squeeze Release

So after quite a while I again had the opportunity to do the ftpmaster works of a Debian release. Not quite my first and hopefully not my last one, lets see. And, like last time, Mark joined to help with the work. Again, a few moments and not a detailed log (times in UTC): Right now (that is, 21:38 UTC) I am mosty waiting for the rest of the people working on the release (CD builders, press, website, ) to finish their task (building hundreds of images just takes ages). When that is done we can then do a coordinated push to the world. Last plans for that would mean in about an hour . Lets see, Mr. Murphy sure can be around. Thanks go out to everyone involved in preparing this release, be it in the past by fixing bugs, uploading packages, doing whatever was needed, as well as doing the work today. Update: If you miss us setting the new testing AKA wheezy to something inside there - there is no need to. It is simply the continutation of testing with just another name, which did not get changed contents, so nothing done for that. :)

Vincent Fourmond: ctioga superseded by ctioga2

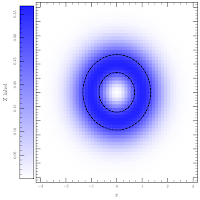
First, some historical details: some 6 years ago, I discovered Ruby together with Tioga, a great library for producing plots. That immediately resulted in my first Ruby program, ctioga. But as years passed and more features were forced into ctioga, I was compelled to see my initial design mistakes, and think about a complete rewrite. This is where ctioga2 was born, some time at the beginning of 2009. I completely stopped using the old ctioga a few month after starting to work on ctioga2, but it took ages before I finally came up with a decent enough documentation to release and announce publicly. But now, it's done, and the first public release of ctioga2 is out, still fresh ! Here are a few highlights of the differences: In any case, you can make yourself an opinion of ctioga2 by looking at the galleries. Enjoy !

Andrew Cater: Debian 6.0 release is happening now

Debian Squeeze 6.0

As predicted - the release is starting this weekend 5/6 February 2011. IRC channels are starting to buzz -- irc.debian.org #debian-release - and there's also a live commentary session at http://identi.ca/debian

For many people, this is yawn-worthy: Debian stable is seen as old, outdated, outmoded. This is the climax of two years work.

Debian 6.0 will be supported for the lifetime of this release + one year if the past few releases are a guide.

A wrap up release 5.0.9 is planned for the previous Debian 5.0 [Etch Lenny] which will be supported for another year.

Debian works on many machine architectures: it's the upstream for Ubuntu and many other Debian derivatives: it works in many languages, has 1034 developers and maintainers maintaining 28693 packages [last number may vary fractionally depending on machine/architecture].

This is big - and I'm pleased and proud to be part of it. Oh, and there's now over 80 parties worldwide to celebrate :)

[UPDATE - Thanks to my colleagues who pointed out my mistake - Debian 4.0 was Etch, 5.0 is Lenny, 6.0 is Squeeze and 7.x will be Wheezy. Developer/maintainer and party numbers also updated]

Matthew Palmer: I Am Certified!

I figured I may as well give the Hurricane Electric IPv6 certification a go, just for shits and giggles. As it turns out, it was pretty simple -- it took me about an hour to get through it all -- and it prodded me into doing a few things I'd never bothered with before (like finding out that my DNS registrar already supports v6 glue, which is nice). As a result: IPv6 Certification Badge for mpalmer YAY!

Ian Wienand: Comcast self-setup with Netgear routers

I just got a Zoom 5341 modem to replace a very sketchy old Motorola model and so far it seems to work fine. However, the Comcast self-install switch process was not seamless. After you plug your new modem in the process starts fine, capturing your session and prompting you for your account. However at the next step it prompts you to download the Windows or Mac only client, directing you to an address http://cdn/.... It is at this point you can get stuck if you're behind a Netgear router (I have a WNDR3700) and probably others. The simple problem is that, for whatever reason, the factory firmware in this router does not pass on the domain search suffix through its inbuilt DHCP client. Without that, cdn doesn't resolve to anything, so you can't download the self-help tool and you're effectively stuck at a "can not find this page" screen. If you google at this point you can find many people who have hit this problem, and various information from erroneous suggestions that you've been hacked (?) to most people just giving up and moving into Comcast phone support hell. Assuming you now don't have internet access, you can complete the process with a quick swizzle. Somebody might be able to correct me on this, but I don't think you want to run the self-install tool from an actual computer plugged directly into the modem if you have a router in the picture, because the wrong MAC address will get registered. So, your best solution is to turn everything off, plug your computer directly into the modem, turn it on, get an address, download the tool, turn everything off, plug the router back-in to the modem and then run the self install tool. At this point, everything just worked fine for me. Netgear should probably fix this by correctly passing through the domain search suffixes in their routers. Comcast should probably fix this by doing some sort of geo-ip lookup to give clients a fully-qualified address in that webpage to download the tool even if their router is broken (or really, does downloading that file really require a content-delivery network?). You can probably fix this by running Openwrt on your router before you start. Otherwise, the Zoom modem and the Netgear WNDR3700 seem to make a very nice combination which I would reccommend.

Craig Small: A few minor updates

No real terribly exciting updates lately but all important in their own way. ncurses A new version of ncurses got uploaded into sid. It should hopefully fix the backspace versus delete problem some of the FreeBSD people have been having with some of the terminal emulators. Oh, and if you are pining for the good old days when 8 colours and 64kB of memory was good enough for everyone, checkout ncurses-examples which have a bunch of interesting things you can do with curses, including some games. Anyone remeber the tower of Hanoi? dh-make dh-make, the tool to take a raw tar (or zip) archive and make a Debian package has been updated too. One of the interesting side-effects of maintaining dh-make is you find out (usually through bug reports) the little changes that happen to the Debian package build process. Most people, including myself, though the main big thing between versions 1 and 2 and version 3 of the source formats was the inclusion of quilt patches right inside the source files. And probably for the sake of "main things" this is true. What I didn't realise is that dpkg-source has changed in other ways too. Bug 580804 tripped this one up. For most people, you run dh_make, fix some things up and use debuild. If you didn't have the original tar file (perhaps you got the source from git or svn) you just use --creatorig and it copies the current directory into ../whatever-1.2.3.orig Source format 3 doesn't like this. Previously it would find that there was no orig.tar.gz archive but there was a orig directory and make the archive from that. Now you have to do it yourself and dh_make does it like that too. pidgin-musictracker Now this should of been a pretty simple stock-standard upstream upgrade. Download the file, uupdate, debuild and release. The problem is that upstream didn't fix their po files. These are the translation files that convert the raw english texts in a program into whatever language. This means the first time you run the build process, you have no diff file. However when you run it the second time, part of the install target rebuilds the po files (mainly the line references), you have differences and then a big diff file of these po updates. The real fix is to make sure your po files are up to date before you release! The trick is that they don't automatically and I have been caught myself; though it happens in the release testing phase (because my release testing involves usually building the debian archive so I see my own problem). irc came to the rescue again. Someone there suggested getting dpkg-source to ignore the changes. The way you do that is put parameters into debian/source/options. I wanted to ignore the changes to the po and pot files so my file has:
extend-diff-ignore=po/.*\.pot?
I put that in and it works!

Craig Small: Playing text adventures with mudlet

Mudlet I've been playing text based multi-user games on and off for years, or perhaps that's decades. When I first started playing them, all you had was telnet. Then this program called TinyFugue appeared which is still shipped by Debian. The generic term for these sorts of games are MUDs, or Multi User Dungeons. Anyhow, I recently came across a new MUD client called Mudlet. It's a very slick program and works quite well. The way it does its triggers (reactions to what the mud sends you) and aliases (reactions to what you type) is done well and is fast. For some people you may have 100s of potiential matches on a incoming or outgoing line so you want it to be fast. After trying it out, my next reaction was "ok, so is it packaged in Debian?". To my surprise, it wasn't so the only obvious thing to do was for me to package it. It is now sitting in the NEW queue waiting for our ever-overloaded ftp masters to have a look at it. While the program is done well, as shipped it doesn't play too well with a Linux system. The package carries about 4 different other packages around. I've changed that now so it uses the system libraries and fonts. All of them are shipped in Debian and I'm sure they individually get more attention and love then I would give them being a sub-part of the main package. It of course cuts down on build times and archive sizes too. I still play muds, no matter what client. For me there they're fun on two levels. The first is the puzzles and gameplay of the MUD itself. I play some MUDs run by Iron Realms who continuously update them, giving you new challenges. The second level is the scripting and customisation you can do. Instead of typing "sip health" you can write some scripts to check your health level and get the script to do it. Mudlet (and a lot of other MUD clients) use the Lua langauge to do this scripting. It's a little funny language but is easy to learn and use. You won't be able to build some epic programs with it, but for scripting it is pretty good. Languages in Hunspell Mudlet uses the hunspell library for spell checking. I have, of course, linked it with the Debian library. The difficulty now is what language? I was surprised that when you intialise the library, you specify what language files to use right there. Now for me its simple, the english dictionaries should be used! What I don't undertand is if there is a way of determining the right dictionary globally for a user. I first though it would be one of the locale parameters, those LC_whatever fields. Mine is en_AU.UTF8, which there is no dictionary for as I'd use en_US or en_UK. I could possibly patch Mudlet and find a dialog box somewhere where you can set the language, but to me an environment variable makes more sense. Does anyone use the DICTIONARY variable, for example?

4 February 2011

Robert Millan: Diskless Debian GNU/kFreeBSD HOWTO

It was completely non-obvious; In some cases I had to figure it out by reading kFreeBSD source code; I write it down here so it s not forgotten ;-) This is a short guide on how to boot Debian GNU/kFreeBSD via network on a diskless machine, using GRUB as the bootloader.
  • Step 1: Configure your DHCP/TFTP environment to load GRUB from network. See the PXE GRUB documentation for details.
  • Step 2: Rebuild kfreebsd-8 package with BOOTP and BOOTP_NFSROOT options, as described in upstream handbook. They need to be added to the debian/arch/*/*.config file for your architecture. This kernel can still be used for normal, disk-based boot, but it will issue DHCP requests to attempt network boot every time you start it.
  • Step 3: Put your kFreeBSD in TFTP directory and configure GRUB to load it. This requires only one command in grub.cfg. My setup:
    set timeout=1
    set default=0 menuentry Debian GNU/kFreeBSD
    echo Loading kFreeBSD
    kfreebsd /beastie/boot/kfreebsd-8.1-1-amd64.gz
    echo Booting
    boot
  • Step 4: Build a directory tree with your GNU/kFreeBSD userland, and export it via NFS. I copied it from an existing Debian GNU/kFreeBSD install, but I suppose debootstrap could do the job as well.
  • Step 5: kFreeBSD mounts root NFS in readonly mode initially, and Debian userland turns out to be very unhappy with that. If you want things to work you ll need to either setup tmpfs in a few places (e.g. /tmp) or adjust fstab so that / is remounted as writable by the INIT scripts. Example fstab line:
    192.168.1.3:/srv/netboot/beastie / nfs rw 0 0
    This, however, will only work if mount_nfs(8) is in your system. And (well, too bad) it hasn t been packaged yet. So you can copy it from a FreeBSD base tarball, along with its dependencies (/lib/libc.so.7, /libexec and /etc/netconfig).
  • Step 6: Finally the system boots, but you ll soon notice that file locks don t work. This breaks some daemons (rsyslog), dpkg, apt and possibly a lot other things. Actual (i.e. non-local) file locking on NFS requires a running lock daemon, both on client and on server. However, since FreeBSD lockd isn t packaged either, and you probably don t need global locks anyway, I suggest you disable it with nolockd mount option.
    The tricky part is that as explained in mount_nfs manpage, nolockd will only be honored when performing the initial mount, and it will be silently ignored if used while updating the mount options. So fstab is not an option.
    The only way I could find of telling the kernel to use arbitrary options when mounting / is by sending them via DHCP. Use the following options in your dhcpd.conf:
    option option-130 code 130 = text;
    option option-130 nolockd ;
  • Et voil . A Debian GNU/kFreeBSD system running completely in diskless mode. Enjoy!

    3 February 2011

    Stefano Zacchiroli: how to use Notmuch with Mutt

    Mutt mail indexing on steroids! I've been using external mail indexing with Mutt for quite a while now. Before now I haven't given Notmuch a try, as it seemed too much experimental at the time of my initial review of mail indexing tools. As there is nothing better than a long oversea flight to perpetrate new hacks, I've now not only tested it, but also switched to Notmuch without looking back at maildir-utils for a split second. Getting started with Notmuch is trivial: Some performance figures: (1) the size of the index is a bit larger than the size of the mails (on my laptop: 535 Mb of index vs 375 Mb of mails stored in 60 maildirs); (2) even if the underlying indexing engine is the same (Xapian) as maildir-utils, Notmuch is much faster. With my setup it is so fast that I've added it as a hook triggered by offlineimap at the end of each synchronization:
        zack@usha:~$ grep -B 1 hook .offlineimaprc
        [Account Upsilon]
        postsynchook = notmuch new
    
    
    With the big round of new mail downloaded in the morning, it hardly takes more than a few seconds to update Notmuch index, while with other periodic downloads Notmuch almost invariably reports "... in almost no time" (i.e. less than 1 second). Integrating Notmuch with Mutt The basic integration I want between Mutt and a mail indexer is the ability of stating a search query interactively and then jump to a fresh Maildir containing search results only. Additionally, given that Notmuch has neat thread reconstruction abilities, I also want to be able to reconstruct on the fly the thread corresponding to the currently highlighted mail: it comes handy when a thread has been split across different maildirs, archived, or the like. To that end, I've cooked up a little helper, called mutt-notmuch, that enables to trigger mail searches via a Mutt macro (F8 being my choice) and reconstruct threads via another (F9). Check the manpage for the 2-liner configuration snippet for your ~/.muttrc. Arguably, some of the logics of mutt-notmuch could disappear by adding support for a --output=symlinks flag to Notmuch. A bug report requesting that is pending: too bad oversea flights are not as good for accessing the Internet as they are for perpetrating hacks! Download

    Pietro Abate: Package Managers Comparison

    The Mancoosi Team has recently published the details of a study we conducted analyzing different packages managers available in debian. The goal of this study was to compare MPM (the mancoosi package manager) to other legacy solvers and try to get a big picture regarding of the state of the art. A similar study was conduct during EDOS and the results are still available here. As I wrote few months ago, MPM is a proof of concept that we wrote to test the behavior of a number of solvers that have been developed for the MISC competition in a real world scenario. These results do not show anything new w.r.t. the experience of a lot of poeple dueling daily with their machines in order to install a new piece of software. In a nutshell, we have shown that apt-get, aptitude, smart and cupt perform pretty well when used only with one baseline (for example a stable release) : this conforms with the experience of the majority of users of debian based systems. However problems start to arise when a user start mixing more then one baseline putting a lot of stress on the solver in order to find a satisfying solution. This solution of course exists, but it is cleverly hidden in the dependency structure of more then 40K packages... MPM is not as fast as other package solvers (say 10 seconds for mpm, while apt-get is able to find a solution in 3 second), but is remarkably stable. It is always able to find a satisfying solution, even in the harder cases where all the other failed. In these experiments MPM uses the postdam solver aspcud. This solver uses only GPL components and it would be a good candidate for inclusion in debian (there are actually a couple of ITP already filled for clasp and gringo). The results (with a lot of details) are published on the mancoosi website (a more detailed report is in the works). Enjoy ! During fosdem the Mancoosi team that authored this work (Roberto, Ralf, Zack and Me) will be around, so, please stop us for a chat ! And don't miss Ralf's talk !!

    Raphaël Hertzog: People behind Debian: Mike Hommey, Firefox/Iceweasel maintainer

    Mike Hommey, our Iceweasel maintainer

    For as long as I have known Mike, he s been maintaining one of the largest (and most widely used) package: Iceweasel, Debian s default web browser. It s effectively Mozilla s Firefox although it has been renamed to avoid some rules enforced by Mozilla s trademark policy. But we might see Firefox back in Debian read on to know Mike s plans. His story is also very interesting in that he went from simple user to Iceweasel maintainer, and now he s working for Mozilla Corporation. But you already knew that contributing to free software is a good way to grow skills and gain experience that are valuable on the job market, right? ;-) My questions are in bold, the rest is by Mike. Who are you? I am Mike Hommey. I am French, even if my name doesn t sound so. I have been a GNU/Linux user since 1995, using Debian since 1999, and started packaging in 2003. After a long time in the NM queue, I became a DD in 2005. The main reason I started being actively involved is quite selfish: I wanted some things done, and I just did them. My first packages were extensions for the Mozilla Suite, the old one that directly inherited from Netscape Communicator. Later on, I wanted some of these extensions to work with the new kid on the block: Phoenix; or maybe it was already Firebird. By then, integrating extensions was a hassle, and the mozilla-browser maintainer had come up with a script that would make it easier for extension packages. So I ported that script for use with Phoenix/Firebird and sent it to the BTS. Then Phoenix/Firebird became Firefox, and it grew a real extension manager. Except that is was entirely not suited for extensions installed by the packaging system. So I made it work better. And made a few more changes to make Firefox work better. All through patches or NMUs. Then I became co-maintainer, then Firefox couldn t keep its name and became Iceweasel, and, fast-forward until today, I m now taking care of Iceweasel/Xulrunner and Iceape in stable, unstable, experimental and an external repository. This 8 years-long story (wow, I hadn t even realized it had been that long until I wrote it) tells you something: newcomers shouldn t be afraid to stick their hands anywhere, even in big packages. I was only a Mozilla and Phoenix end-user when I started. Apart from Mozilla-related packaging, I also happen to (co-)maintain some other packages in Debian, most notably webkit, though I haven t been very active in the pkg-webkit team recently. There are several reasons for that, the main one being that there are other team members getting the job done. And I can t say that much about the pkg-mozilla team, since there are effectively no other team members. What s your biggest achievement within Debian? I am quite proud that Squeeze will be the first Debian release where Iceweasel works on all supported architectures. Previously, we only knew the package compiled on all these architectures. Starting with Squeeze, we know it passes several of the test suites coming with the source code. This ensures most of the browser is functional. It was actually far from being the case before, as it appeared when the test suites were first enabled. I think it is very important to have properly working packages on all our supported architectures. The current evolution of hardware shows how important it still is. Who would have thought a few years back that we would see ARM or MIPS based netbooks today ? What are your plans for Debian Wheezy? For Debian Wheezy, I would like to improve Iceweasel/Icedove/Iceape integration with the packaging system. Something that would allow to use the apt database to find extensions or plugins, on top of the current behaviour. I also want to improve desktop integration, most notably for KDE. Another thing I d like to see happen is to package google breakpad independently (its source code is currently embedded in chromium and iceweasel, though not built, as far as I know), and have our Mozilla products builds be able to send their crash reports upstream. It is very important that upstream gets direct visibility over what crashes on GNU/Linux systems. It helps making them aware of issues that would otherwise probably remain unnoticed, as there are much more users using distributions packages than upstream tarballs. And not all Debian users report crashes to the BTS. I know at least Fedora and SuSE are already doing it. More importantly, I want to avoid the sad situation we got with Squeeze, where we re going to release a 18 months old Iceweasel. We got there for a combination of reasons, one being that I was preparing for a freeze in December 2009 and focusing on getting 3.5 in shape instead of the then upcoming 3.6. The result was that we didn t get 3.6 packages before upstream released 3.6.3 in April 2010. By then it was too late, considering the uncertainty of the release schedule, to update reverse dependencies and get 3.6 ready for Squeeze. Things are different for 4.0. I m already getting ahead of things, and while reverse dependencies haven t been taken care of, all beta releases have been made available through http://mozilla.debian.net/, usually within hours after upstream release (sometimes even a few hours before official announcement, but always after availability on ftp.mozilla.org). A great share of our patches were also pushed upstream. Several things made that possible: There will be a couple major upstream releases until Wheezy comes along, and I want to make them available early in unstable, even if that means breaking reverse dependencies until they are fixed. Finally, I would like to get other people involved, starting with the Icedove maintainer. Volunteers are very much welcome, for any kind of involvement: bug triaging, documentation (which we are deeply lacking), testing, code People interested can contact the pkg-mozilla team list. As the Debian packaging gets less time consuming, I should be able to spend more time mentoring, which should help. If you could spend all your time on Debian, what would you work on? I actually have been working almost full time on Debian for a few months during a more-or-less purposeful unemployment period. That s when I attempted to add an alert popup when Iceweasel or extensions are upgraded (which was eventually removed because not working very effectively). That s when I worked on Iceweasel 3.6 and the first 4.0 betas. That s when I pushed more than 70 patches upstream, and got upstream commit access. I know for a fact that keeping up with upstream and answering bug reports is already time consuming, and time comes in finite quantity. Working full time on Debian allows to do more than that, as I ve been able to experience first hand. Unfortunately, that doesn t help pay the bills, so it would be best if time could be shared with other persons. Like, actual members in the pkg-mozilla team. ;) Anyways, if I were to work full time on Debian again, I d like to do more than packaging, and help improve some of our infrastructure, most notably the buildd network, to grow some automated way to get packages built on all or some of our architectures. Call that PPA if you want, though I don t think we need something exactly like PPA. We sure do have porter boxes, but there is a huge overhead to get packages built there: you need to first try, then see you lack build dependencies, then wait for admins to install them, then come back and launch your build, and finally come back again much later to see how it went. And that s when it goes smoothly. Repeat for each architecture. It s already cumbersome when it s a small package, so imagine when it s Iceweasel. I d like to be able to push a (signed) .dsc somewhere, say I want it built on that and that architecture, and get binary packages and logs back. It could then be up to developers to distribute them, or not. Sometimes, you re just interested in test suite results. Another related wish would be a way to access build trees of failed builds, possibly on the buildd where it failed. What s the biggest problem of Debian? Lack of contributors, lack of contributors, and lack of contributors. It can sound weird to say that in a community of 1000+ people. But the sad reality is that we ve seen, repeatedly, calls for help in various places from various understaffed teams (most often of effectively one member) for years. So there is obviously a problem getting people to invest time in these teams either on the long term, or at all. I know this is not a very significant metric, but it already should say a lot: I wouldn t be surprised if more than 2/3 of the number of source lines of code in Debian come from less than 5% of the number of packages in the archive, and see less than 5% of the DD/DM population involved. If someone feels like doing the actual math, I m curious to know how far I m from reality, and in what direction. We also lack manpower to be able to make our release development smoother. In a perfect world where manpower is not a scarce resource, we should work on $release+1 when $release is being frozen. Said otherwise, we should have been able to start working on Wheezy in August 2010, or even earlier. You ve been working for Mozilla Corporation for a few months. How does the work look like and what are you working on? I am actually not working full time for MoCo; I am only contracting for 4 days a week. That was a request I made to keep having enough spare time for Debian or other activities. I am working from home, and am pretty much free about when I work, as long as I work long enough. I take advantage of this freedom and the saved commuting time to live a healthier life by doing some sports in the daytime (which also happens to be cheaper). I mostly work with Taras Glek and other people on various aspects of Firefox startup performance. This involves pretty interesting low-level stuff, in which I actually got involved before being contracted. This work has nothing to do with packaging Iceweasel, though I can have a few opportunities to do things somehow related. You told in your blog that you were discussing with Mozilla how Debian could use the Firefox trademark. Can you tell us a bit about the progress you made? I have got an informal approval of the patches we are applying to the Iceweasel 4.0 beta packages. There are a few concerns about using the system cairo library, and the embedded copy of libpng needs to be used to have support for the animated PNGs that are used in the user interface and that are required in Firefox feature-set. Other than that, there are pretty much no objection on the technical side. We managed to get to some common ground as to how to manage stable updates and more generally, changes to our packages, but I m still waiting for an actual agreement draft. While I, as the maintainer, am fine with the way it should look according to my discussions with the people involved at Mozilla, I ll seek review from my fellow Debian Developers when I ll have something to show. I haven t decided yet how this will reflect on the Debian packages, though. For example, would Iceweasel stay? But I do hope Wheezy will get Firefox back. Is there someone in Debian that you admire for their contributions? Not someone, but all past, present and future release team members. This is a team that receives a lot of critics (and I indirectly gave one a few paragraphs ago), yet manages to keep doing an amazing job and its members are very committed to their task. I admire their dedication.
    Thank you to Mike for the time spent answering my questions. I hope you enjoyed reading his answers as I did. Subscribe to my newsletter to get my monthly summary of the Debian/Ubuntu news and to not miss further interviews. You can also follow along on Identi.ca, Twitter and Facebook.

    8 comments Liked this article? Click here. My blog is Flattr-enabled.

    2 February 2011

    Enrico Zini: Gzip streaming in Python (or lack thereof)

    Gzip streaming in Python (or lack thereof) Consider this simple Python snippet:
    #!/usr/bin/python
    import gzip
    from urllib import urlopen
    zfd = urlopen("http://ftp.debian.org/debian/dists/sid/Contents-udeb.gz")
    fd = gzip.GzipFile(fileobj=zfd, mode="r")
    for line in fd:
        foobar(line)
    
    It does not work: it turns out GzipFile wants to seek() and tell() on its file object:
    $ /tmp/z.py 
    Traceback (most recent call last):
      File "/tmp/z.py", line 8, in <module>
        for line in fd:
      File "/usr/lib/python2.6/gzip.py", line 438, in next
        line = self.readline()
      File "/usr/lib/python2.6/gzip.py", line 393, in readline
        c = self.read(readsize)
      File "/usr/lib/python2.6/gzip.py", line 219, in read
        self._read(readsize)
      File "/usr/lib/python2.6/gzip.py", line 247, in _read
        pos = self.fileobj.tell()   # Save current position
    AttributeError: addinfourl instance has no attribute 'tell'
    
    Oh dear... this really shouldn't be. Let's look around the internet for details:
    Since opener.open returns a file-like object, and you know from the headers that when you read it, you're going to get gzip-compressed data, why not simply pass that file-like object directly to GzipFile? As you read from the GzipFile instance, it will read compressed data from the remote HTTP server and decompress it on the fly. It's a good idea, but unfortunately it doesn't work. Because of the way gzip compression works, GzipFile needs to save its position and move forwards and backwards through the compressed file. This doesn't work when the file is a stream of bytes coming from a remote server; all you can do with it is retrieve bytes one at a time, not move back and forth through the data stream. So the inelegant hack of using StringIO is the best solution: download the compressed data, create a file-like object out of it with StringIO, and then decompress the data from that.
    Oh really, so it's a limitation of "the way gzip compression works", and the only way to work around this fundamental design flaw of gzip is to buffer the lot in memory or to a temporary file? [facepalm]
    # Apparently, this is not how gzip compression works:
    curl http://ftp.debian.org/debian/dists/sid/Contents-udeb.gz   zcat
    
    This is not the first time that, after finding a frustrating spot in core Python things, looking around the internet for extra information has the effect of amplifying my frustration by destroying my expectations of common sense. What is the gzip module doing anyway?
        if self._new_member:
            # If the _new_member flag is set, we have to
            # jump to the next member, if there is one.
            #
            # First, check if we're at the end of the file;
            # if so, it's time to stop; no more members to read.
            pos = self.fileobj.tell()   # Save current position
            self.fileobj.seek(0, 2)     # Seek to end of file
            if pos == self.fileobj.tell():
                raise EOFError, "Reached EOF"
            else:
                self.fileobj.seek( pos ) # Return to original position
            self._init_read()
            self._read_gzip_header()
            self.decompress = zlib.decompressobj(-zlib.MAX_WBITS)
            self._new_member = False
    
    Right, tell() and seek() in order to check if it's reached end of file. Oh dear... So, there's a flaw in the Python standard library, and: I wish core Python documentation started properly documenting Python flaws so that one can code with language limitations in mind, insted of having to rediscover them and their work arounds every time.

    1 February 2011

    Ana Beatriz Guerrero Lopez: Debian at the Google Code-in 2010-11

    As you might know, Debian was one of the 20 organizations selected to participate in the first Google Code-in. We got a moderate success since we started preparing the contest very late (I joined as mentor/admin the very first day of the contest!). Because of this, unlike other organizations, we did not manage to engage interested students from the very beginning of the Code-in. Since we did not have too many Debian tasks the first days, we did not attract many students, and thus did not have very many throughout the contest. Given Debian tasks were mostly about improving and contributing to Debian, it was quite hard having tasks that did not require having a Debian installation and that made it difficult for many students to get involved. Also, until the last two weeks we did not have any translation task that could have attracted earlier students without too much confidence in their technical and English skills. Nonetheless, Debian got 39 tasks done: With about 30 students participating and at least one of the students has keep contributing to Debian after the contest! The contest was sometimes stressful with several students wanting their tasks to be reviewed at the same time, and the date was problematic due to the winter (or summer!) holidays but still I am quite happy with the final result :D Debian will be also participating again this year in the Google Summer of Code 2011. Join the soc-coordination mailing list and stay tunned if you want to participate as mentor or student.

    Cyril Brulebois: Debian XSF News #3

    Time for a third Debian XSF News issue! Debian XSF News #3 It s been a year On a personal note, it s been a year to the day since I first looked into X. After having hacked on the Debian Installer to make it use X.Org instead of DirectFB, I did some heavy bug triaging, resulting in a drop in the xorg-server bug count in March. The same happened past week as written above, resulting in a second drop. In the meanwhile, the bug count remained more or less stable, since we try to reply quickly to new bugs, and since Julien Viard de Galbert does bug triaging on a weekly basis: BTS graph for xorg-server One might ask: what does maintaining X mean?

    31 January 2011

    Tiago Bortoletto Vaz: TXT2TAGS SAMPLE - Aurelio Jargas

    Before you start reading: this post is only intended to test a plugin that I've just written to give PyBlosxom a txt2tags formatting support. The original txt2tag sample used here is available at txt2tag website. Mine with few changes is here.IntroductionWelcome to the txt2tags sample file.Here you have examples and a brief explanation of allmarks.The first 3 lines of the this file are used as headers,on the following format:
      line1: document title  line2: author name, email  line3: date, version
    Lines with balanced equal signs = around are titles.Fonts and BeautifiersWe have two sets of fonts:The NORMAL type that can be improved with beautifiers.The TYPEWRITER type that uses monospaced font forpre-formatted text.We will now enter on a subtitle...BeautifiersThe text marks for beautifiers are simple, just as youtype on a plain text email message.We use double *, /, - and _ to represent bold,italic, strike and underline.The bold italic style is also supported as acombination.Pre-Formatted TextWe can put a code sample or other pre-formatted text:
        here    is     pre-formatted  //marks// are  **not**   interpreted 
    And also, it's easy to put a one line pre-formattedtext:
      prompt$ ls /etc
    Or use pre-formatted inside sentences.More CosmeticsSpecial entities like email (duh@somewhere.com) and URL (http://www.duh.com)are detected automagically, as long as the horizontal line:
    ^ thin or large v
    You can also specify an explicit link with label.And remember,
    A TAB in front of the line does a quotation.
    More TABs, more depth (if allowed).
    Nice.ListsA list of items is natural, just putting a dash ora plus at the beginning of the line.Plain ListThe dash is the default list identifier. For sublists,just add spaces at the beginning of the line. Morespaces, more sublists.The list ends with two consecutive blank lines.Numbered ListThe same rules as the plain list, just a differentidentifier (plus).
    1. one
    2. two
    3. three
      • mixed lists!
      • what a mess
        1. counting again
        2. ...
    4. four
    Definition ListThe definition list identifier is a colon, followed bythe term. The term contents is placed on the next line.
    orange
    a yellow fruit
    apple
    a green or red fruit
    other fruits
    • wee!
    • mixing lists
      1. again!
      2. and again!
    TablesUse pipes to compose table rows and cells.Double pipe at the line beginning starts a heading row.Natural spaces specify each cell alignment.
    heading 1heading 2heading 3
    cell 1.1cell 1.2cell 1.3
    cell 2.1cell 2.2cell 2.3
    Without the last pipe, no border:
    heading 1heading 2heading 3
    cell 1.1cell 1.2cell 1.3
    cell 2.1cell 2.2cell 2.3
    Special EntitiesBecause things were too simple.ImagesThe image mark is as simple as it can be: [filename]. OtherThe handy %%date macro expands to the current date.So today is 20110206 on the ISO YYYYMMDD format.You can also specify the date format with the %? flags,as %%date(%m-%d-%Y) which gives: 02-06-2011.That's all for now.

    Stefano Zacchiroli: who the bloody hell cares about Debian

    A down-under talk on the role of Debian, A.D. 2011 I'm back from LCA 2011, which I've attended to share some thoughts about the role that Debian plays in the Free Software ecosystem, 18 years after its inception (yes, we are that old^Welder). The talk title---Who the bloody hell cares about Debian? [1]---was meant to be rather provocative. The idea was indeed to challenge the meme that, in the era of distributions that release every 6 months, a distribution with a release cycle of circa 2 years (like Debian, considering the past 5 years) is not a project that deserves your attention anymore. Is it really the case? In the talk I (obviously) claim it is not, using two main arguments. The first argument is based on the observation that Debian offers a set of pretty rare, if not unique, features among mainstream FOSS distributions. Those features consist of a mix of technical and "political" aspects: (1) a focus on package quality, with no distinction among first and second class packages; (2) a strong culture of software freedom, which refuses to offer non-free software (or firmware) by default to users and distribution developers (as parts of the infrastructure used to make Debian); (3) independence from commercial interests, with no single company or entity that could claim to babysit Debian; and (4) a decision making model based on a weighted sum of do-ocracy and democracy, which implies that by doing (rather than talking) everyone has a chance to have an impact on Debian. Considering all that and looking at the most popular FOSS distributions, one can easily identify Debian as one of the few remaining players who both care about Free Software and can be trusted in making choices not driven by profit. Mind you, I've nothing against companies in general and I'm very well aware that many FOSS companies carry a good deal of the burden of developing and promoting Free Software. Nonetheless, in days in which it is striking how quickly FOSS-friendly companies can become very much FOSS-unfriendly, I can't help putting my trust and efforts into community-driven projects, better if with no attached company label whatsoever. Furthermore, having distributions like Debian around can encourage other company-backed distributions to demand more and more independence and clarifications about the relationships between the community and the backing company. The second argument about the relevance of Debian is more pragmatic and rather straightforward: Debian is the root of a huge tree of derived-distribution (AKA "derivatives"), more than 120 according to popular distribution indexing sites. Each Debian derivative focuses its attention on, and directs its people power to, customizing Debian for a specific target and build entierly upon Debian work for all parts that do not need customization. That possibility is one key advantage of Free Software, after all. A well-known derivative example is Ubuntu, which is probably the most popular Debian derivative, enjoying a user base way larger than that of Debian itself. Ubuntu is heavily customized with respect to Debian and still had only about (at the time of Natty) 25% of packages which either differed from their Debian counterparts or that did not exist in Debian at all. Other Debian derivatives tend to be way less customized than that. Either way, if you are running a Debian derivative, chances are that you heavily depend on Debian and on its well-being. (Yes, it is so also if you didn't know about that, sorry.) Let's now fast-forward to the end of the talk, skipping my usual comments on how to keep the whole tree of Debian derivatives sustainable and beneficial for Free Software as a whole (i.e. by reducing as much as possible the viscosity of patch flow along the derivatives tree). Feedback People's reaction to such a provocative talk has been positive and we have enjoyed a fairly long Q&A session discussing the topics mentioned above as well as other Debian-related topics. A (commented) summary of the obtained feedback is reported below. Judging from the recurrent questions and suggestions I've received doing Debian talks in the past 8 months, I dare to say that LCA feedback is fairly representative of the feelings of many Debian users. Slides of the talk are available, while a video will eventually be posted at http://linuxconfau.blip.tv.
    [1] Kudos to Francois Marier for suggesting the title. If the title doesn't ring a bell for you (it didn't for me in the beginning), you might want to check out the story of this ad. Update: minor rephrasing in the 4th paragraph

    Michael Banck: 31 Jan 2011

    Debian Med Bioinformatics Sprint Last weekend, I was at the Debian Med Meeting in Travem nde near L beck, thanks to an invitation by Steffen M ller and Andreas Tille. It was a great opportunity to finally meet Steffen and some of the other bioinformatics people in Debian like Manuel Prinz face-to-face for the first time. Also, lots of upstream and related bioinformatics packagers from e.g. Biolinux were present as well, many of them from the UK. I discussed with and helped some people about Debian packaging. There is a big push to get Debian packages done and integrated in Debian and Ubuntu, but often enough people are not exactly sure what the requirements are and what needs to be done. Hopefully, the sprint was successful to clear things up and move forward. I also managed to finalize the initial Jmol packaging and uploaded it to Debian towards the end of the sprint. I plan to update the other bioinformatics related packages in debichem like pymol and openbabel as soon as squeeze is released. Overall, it was a great weekend, many thanks to NERC and Debian for making it possible, and to Steffen M ller for organizing it!

    Julien Danjou: Naquadah theme for Emacs

    I often post Emacs screenshots on this blog, and consequently receive a bunch of request for my Emacs theme. Therefore I decided to publish it. Flattr this

    David Welton: Parallelized web site creating and selling - underperformingstocks.com

    I often have ideas for little web sites, stuff I just get the urge to create for the fun of it. Some of them have done rather well, like langpop.com but even that doesn't make any money, and, sadly, as I age, that is becoming a more important factor in life. So I decided to try a little experiment. I was thinking some about "value" stocks, and fiddling around with Google's stock screener, and thought of the idea of a site that highlights underperforming stocks: http://underperformingstocks.com - so far so good - I went ahead and registered the domain, and put together the beginnings of a Rails application. At the same time though, I decided I have enough things to do in my evenings and weekends, so I decided that it might be interesting to start selling the site at the same time I'm building it. I'm not really sure how it will work out: perhaps people will see that there's not much there and not bid for it. Perhaps someone likes the idea behind it and is willing to buy on that. My idea, in any case, is to keep working on it as the auction progresses. As an additional twist, there are obviously a lot of features that could be added to the site, so I'll prioritize work on features suggested by users who have bid on the site. Here's the auction listing on Flippa.com: www.underperformingstocks.com is For Sale on Flippa! Edit: I'll also be posting updates to the twitter account I created for the project: http://twitter.com/#!/underpstocks

    Next.

    Previous.