Welcome to the June 2024 report from the Reproducible Builds project!
In our reports, we outline what we ve been up to over the past month and highlight news items in software supply-chain security more broadly. As always, if you are interested in contributing to the project, please visit our Contribute page on our website.
Table of contents:
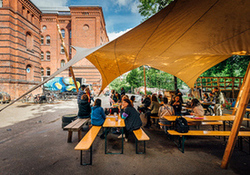
We are very pleased to announce the upcoming Reproducible Builds Summit, set to take place from September 17th 19th 2024 in Hamburg, Germany.
We are thrilled to host the seventh edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin and Athens. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving.
If you re interesting in joining us this year, please make sure to read the event page which has more details about the event and location. We are very much looking forward to seeing many readers of these reports there.
Vagrant Cascadian will be holding a Reproducible Builds session as part of the monthly Guix patch review series on July 11th at 17:00 UTC.
These online events are intended to encourage everyone everyone becoming a patch reviewer and the goal of reviewing patches is to help Guix project accept contributions while maintaining our quality standards and learning how to do patch reviews together in a friendly hacking session.
An Industry Interview Study of Software Signing for Supply Chain Security was published by Kelechi G. Kalu, Tanmay Singla, Chinenye Okafor, Santiago Torres-Arias and James C. Davis of Electrical and Computer Engineering department of Purdue University, Indiana, USA, and is concerned with:
To understand software signing in practice, we interviewed 18 high-ranking industry practitioners across 13 organizations. We provide possible impacts of experienced software supply chain failures, security standards, and regulations on software signing adoption. We also study the challenges that affect an effective software signing implementation.
DiVerify: Diversifying Identity Verification in Next-Generation Software Signing was written by Chinenye L. Okafor, James C. Davis and Santiago Torres-Arias also of Purdue University and is interested in:
Code signing enables software developers to digitally sign their code using cryptographic keys, thereby associating the code to their identity. This allows users to verify the authenticity and integrity of the software, ensuring it has not been tampered with. Next-generation software signing such as Sigstore and OpenPubKey simplify code signing by providing streamlined mechanisms to verify and link signer identities to the public key. However, their designs have vulnerabilities: reliance on an identity provider introduces a single point of failure, and the failure to follow the principle of least privilege on the client side increases security risks. We introduce Diverse Identity Verification (DiVerify) scheme, which strengthens the security guarantees of next-generation software signing by leveraging threshold identity validations and scope mechanisms.
Felix Lagn hed published their thesis on the Integration of Reproducibility Verification with Diffoscope in GNU Make. This work, amongst some other results:
[ ] resulted in an extension of GNU make which is called rmake, where diffoscope a tool for detecting differences between a large number of file types was integrated into the workflow of make. rmake was later used to answer the posed research questions for this thesis. We found that different build paths and offsets are a big problem as three out of three tested Free and Open Source Software projects all contained these variations. The results also showed that gcc s optimisation levels did not affect reproducibility, but link-time optimisation embeds a lot of unreproducible information in build artefacts. Lastly, the results showed that build paths, build ID s and randomness are the three most common groups of variations encountered in the wild and potential solutions for some variations were proposed.
Lastly, Pol Dellaiera completed his master thesis on Reproducibility in Software Engineering at the University of Mons, Belgium, under the supervision of Dr. Tom Mens, professor and director of the Software Engineering Lab.
The thesis serves as an introduction to the concept of reproducibility in software engineering, offering a comprehensive overview of formalizations using mathematical notations for key concepts and an empirical evaluation of several key tools. By exploring various case studies, methodologies and tools, the research aims to provide actionable insights for practitioners and researchers alike.
In Debian this month, 4 reviews of Debian packages were added, 11 were updated and 14 were removed this month adding to our knowledge about identified issues. Only one issue types was updated, though, explaining that we don t vary the build path anymore.
In openSUSE news, Bernhard M. Wiedemann published another report for that distribution.
In NixOS, with the 24.05 release out, it was again validated that our minimal ISO is reproducible by building it on a virtual machine with no access to the binary cache.
qutebrowser, samba and systemd), Chris Lamb filing Debian bug #1074214 against the fastfetch package and Arnout Engelen proposing fixes to refind and for the Scala compiler [ .
Lastly, diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb uploaded two versions (270 and 271) to Debian, and made the following changes as well:
Build-Depends on liblz4-tool in order to fix Debian bug #1072575. [ ]zipdetails version 4.004 that is shipped with Perl 5.40. [ ]
There were a number of improvements made to our website this month, including Akihiro Suda very helpfully making the <h4> elements more distinguishable from the <h3> level [ ][ ] as well as adding a guide for Dockerfile reproducibility [ ]. In addition Fay Stegerman added two tools, apksigcopier and reproducible-apk-tools, to our Tools page.
The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In June, a number of changes were made by Holger Levsen, including:
virt(32 64)c-armhf nodes as down. [ ]osuosl4 node in order to debug a regression on the ppc64el architecture. [ ]osuosl4 node. [ ][ ]/etc/default/jenkins file with changes performed upstream [ ] and changed how configuration files are handled on the rb-mail1 host. [ ], whilst Vagrant Cascadian documented the failure of the virt32c and virt64c nodes after initial investigation [ ].
#reproducible-builds on irc.oftc.net.
rb-general@lists.reproducible-builds.org
| Publisher: | Saga Press |
| Copyright: | July 2023 |
| ISBN: | 1-6680-0849-1 |
| Format: | Kindle |
| Pages: | 372 |
Like each month, have a look at the work funded by Freexian s Debian LTS offering.
Pick a random package from the list and run the latest edition of the script debian-snap-to-salsa with the package name as the argument to prepare a git repository with the existing packaging. This will download old Debian packages from snapshot.debian.org. Note that very recent uploads will not be included, so check out the package on tracker.debian.org. Next, run gbp buildpackage --git-ignore-new to verify that the package build as it should, and then visit https://salsa.debian.org/debian/ and make sure there is not already a git repository for the package there. I also did git log -p debian/control and look for vcs entries to check if the package used to have a git repository on Alioth, and see if it can be a useful starting point moving forward. If all this check out, I created a new gitlab project below the Debian group on salsa, push the package source there and upload a new version. I tend to also ensure build hardening is enabled, if it prove to be easy, and check if I can easily fix any lintian issues or bug reports. If the process took more than 20 minutes, I dropped it and moved on to another package. If I found patches in debian/patches/ that were not yet passed upstream, I would send an email to make sure upstream know about them. This has proved to be a valuable step, and caused several new releases for software that initially appeared abandoned. :) As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.PGPASSWORD="udd-mirror" psql --port=5432 --host=udd-mirror.debian.net \ --username=udd-mirror udd -c "select source from sources \ where release = 'sid' and (vcs_url ilike '%anonscm.debian.org%' \ OR vcs_browser ilike '%anonscm.debian.org%' or vcs_url IS NULL \ OR vcs_browser IS NULL) AND maintainer ilike '%packages@qa.debian.org%' \ order by random() limit 10;"
yubihsm-connector, yubihsm-shell, and
python-yubihsm from
https://developers.yubico.com/, in
some cases based partly on the upstream packaging, and got them all into
Debian unstable.
Backports to bookworm will be forthcoming once they ve all reached
testing.
unschroot by Helmut Grohne
Following an in-person discussion at MiniDebConf Berlin, Helmut
attempted splitting the containment functionality of sbuild --chroot-mode=unshare into a dedicated tool interfacing with sbuild
as a variant of --chroot-mode=schroot providing a sufficiently
compatible
interface.
While this seemed technically promising initially, a discussion on
debian-devel
indicated a desire to rely on an existing container runtime such as
podman instead of using another Debian-specific tool with unclear long
term maintenance.
None of the existing container runtimes meet the specific needs of
sbuild, so further advancing this matter implies a compromise one way
or another.
python-aiohttp), fixing RC bugs in ipykernel, ipywidgets,
khard, and python-repoze.sphinx.autointerface, and packaging
zope.deferredimport which was needed for a new upstream version of
python-persistent.user_readenv option from OpenSSH s PAM
configuration (#1018260), and
prepared a release note.cups.login having become non-essential, Helmut uploaded
debvm to unstable and stable and fixed a crossqa.debian.net worker.guix challenge command.
Or I should say debdistrebuild has attempted to rebuild those distributions. The number of identically built packages are fairly low, so I didn t want to waste resources building the rest of the archive until I understand if the differences are due to consequences of my build environment (plain apt-get build-dep followed by dpkg-buildpackage in a fresh container), or due to some real difference. Summarizing the results, debdistrebuild is able to rebuild 34% of Debian bullseye on amd64, 36% of bookworm on amd64, 32% of bookworm on arm64. The results for trixie and Ubuntu are disappointing, below 10%.
So what causes my rebuilds to be different from the official rebuilds? Some are trivial like the classical problem of varying build paths, resulting in a different NT_GNU_BUILD_ID causing a mismatch. Some are a bit strange, like a subtle difference in one of perl s headers file. Some are due to embedded version numbers from a build dependency. Several of the build logs and diffoscope outputs doesn t make sense, likely due to bugs in my build scripts, especially for Ubuntu which appears to strip translations and do other build variations that I don t do. In general, the classes of reproducibility problems are the expected. Some are assembler differences for GnuPG s gpgv-static, likely triggered by upload of a new version of gcc after the original package was built. There are at least two ways to resolve that problem: either use the same version of build dependencies that were used to produce the original build, or demand that all packages that are affected by a change in another package are rebuilt centrally until there are no more differences.
The current design of debdistrebuild uses the latest version of a build dependency that is available in the distribution. We call this a idempotent rebuild . This is usually not how the binary packages were built originally, they are often built against earlier versions of their build dependency. That is the situation for most binary distributions.
Instead of using the latest build dependency version, higher reproducability may be achieved by rebuilding using the same version of the build dependencies that were used during the original build. This requires parsing buildinfo files to find the right version of the build dependency to install. We believe doing so will lead to a higher number of reproducibly built packages. However it begs the question: can we rebuild that earlier version of the build dependency? This circles back to really old versions and bootstrappable builds eventually.
While rebuilding old versions would be interesting on its own, we believe that is less helpful for trusting the latest version and improving a binary distribution: it is challenging to publish a new version of some old package that would fix a reproducibility bug in another package when used as a build dependency, and then rebuild the later packages with the modified earlier version. Those earlier packages were already published, and are part of history. It may be that ultimately it will no longer be possible to rebuild some package, because proper source code is missing (for packages using build dependencies that were never part of a release); hardware to build a package could be missing; or that the source code is no longer publicly distributable.
I argue that getting to 100% idempotent rebuilds is an interesting goal on its own, and to reach it we need to start measure idempotent rebuild status.
One could conceivable imagine a way to rebuild modified versions of earlier packages, and then rebuild later packages using the modified earlier packages as build dependencies, for the purpose of achieving higher level of reproducible rebuilds of the last version, and to reach for bootstrappability. However, it may be still be that this is insufficient to achieve idempotent rebuilds of the last versions. Idempotent rebuilds are different from a reproducible build (where we try to reproduce the build using the same inputs), and also to bootstrappable builds (in which all binaries are ultimately built from source code). Consider a cycle where package X influence the content of package Y, which in turn influence the content of package X. These cycles may involve several packages, and it is conceivable that a cycle could be circular and infinite. It may be difficult to identify these chains, and even more difficult to break them up, but this effort help identify where to start looking for them. Rebuilding packages using the same build dependency versions as were used during the original build, or rebuilding packages using a bootsrappable build process, both seem orthogonal to the idempotent rebuild problem.
Our notion of rebuildability appears thus to be complementary to reproducible-builds.org s definition and bootstrappable.org s definition. Each to their own devices, and Happy Hacking!
Addendum about terminology: With idempotent rebuild I am talking about a rebuild of the entire operating system, applied to itself. Compare how you build the latest version of the GNU C Compiler: it first builds itself using whatever system compiler is available (often an earlier version of gcc) which we call step 1. Then step 2 is to build a copy of itself using the compiler built in step 1. The final step 3 is to build another copy of itself using the compiler from step 2. Debian, Ubuntu etc are at step 1 in this process right now. The output of step 2 and step 3 ought to be bit-by-bit identical, or something is wrong. The comparison between step 2 and 3 is what I refer to with an idempotent rebuild. Of course, most packages aren t a compiler that can compile itself. However entire operating systems such as Trisquel, PureOS, Ubuntu or Debian are (hopefully) a self-contained system that ought to be able to rebuild itself to an identical copy. Or something is amiss. The reproducible build and bootstrappable build projects are about improve the quality of step 1. The property I am interested is the identical rebuild and comparison in step 2 and 3. I feel the word idempotent describes the property I m interested in well, but I realize there may be better ways to describe this. Ideas welcome!
My previous post mentioned that I'd added some custom syscalls to my CP/M emulator and that lead to some more updates, embedding a bunch of binaries within the emulator so that the settings can be tweaked at run-time, for example running:
!DEBUG 1
!CTRLC 1
!CCP ccpz
!CONSOLE adm-3a
Those embedded binaries show up on A: even if they're not in the pwd when you launch the emulator.
Other than the custom syscalls I've updated the real BDOS/BIOS syscalls a bit more, so that now I can run things like the Small C compiler, BBC BASIC, and more. (BBCBasic.com used to launch just fine, but it turned out that the SAVE/LOAD functions didn't work. Ooops!)
I think I've now reached a point where all the binaries I care about run, and barring issues I will slow down/stop development. I can run Turbo Pascal, WordStar, various BASIC interpreters, and I have a significantly improved understanding of how CP/M works - a key milestone in that understanding was getting SUBMIT.COM to execute, and understanding the split between the BDOS and the BIOS.
I'd kinda like to port CP/M to a new (Z80-based) system - but I don't have such a thing to hand, and I guess there's no real need for it. Perhaps I can say I'm "done" with retro stuff, and go back to playing Super Mario Bros (1985) with my boy!
| Series: | Discworld #40 |
| Publisher: | Anchor Books |
| Copyright: | 2013 |
| Printing: | October 2014 |
| ISBN: | 0-8041-6920-9 |
| Format: | Trade paperback |
| Pages: | 365 |
It is said that a soft answer turneth away wrath, but this assertion has a lot to do with hope and was now turning out to be patently inaccurate, since even a well-spoken and thoughtful soft answer could actually drive the wrong kind of person into a state of fury if wrath was what they had in mind, and that was the state the elderly dwarf was now enjoying.One of the best things about Discworld is Pratchett's ability to drop unexpected bits of wisdom in a sentence or two, or twist a verbal knife in an unexpected and surprising direction. Raising Steam still shows flashes of that ability, but it's buried in run-on sentences, drowned in cliches and repetition, and often left behind as the containing sentence meanders off into the weeds and sputters to a confused halt. The idea is still there; the delivery, sadly, is not. This is the first Discworld novel that I found mentally taxing to read. Sentences are often so overpacked that they require real effort to untangle, and the untangled meaning rarely feels worth the effort. The individual voice of the characters is almost gone. Vetinari's monologues, rather than being a rare event with dangerous layers, are frequent, rambling, and indecisive, often sounding like an entirely different character than the Vetinari we know. The constant repetition of the name any given character is speaking to was impossible for me to ignore. And the momentum of the story feels wrong; rather than constructing the events of the story in a way that sweeps the reader along, it felt like Pratchett was constantly pushing, trying to convince the reader that trains were the most exciting thing to ever happen to Discworld. The bones of a good story are here, including further development of dwarf politics from The Fifth Elephant and Thud! and the further fallout of the events of Snuff. There are also glimmers of Pratchett's typically sharp observations and turns of phrase that could have been unearthed and polished. But at the very least this book needed way more editing and a lot of rewriting. I suspect it could have dropped thirty pages just by tightening the dialogue and removing some of the repetition. I'm afraid I did not enjoy this. I am a bit of a hard sell for the magic fascination of trains I love trains, but my model railroad days are behind me and I'm now more interested in them as part of urban transportation policy. Previous Discworld books on technology and social systems did more of the work of drawing the reader in, providing character hooks and additional complexity, and building a firmer foundation than "trains are awesome." The main problem, though, was the quality of the writing, particularly when compared to the previous novels with the same characters. I dragged myself through this book out of a sense of completionism and obligation, and was relieved when I finished it. This is the first Discworld novel that I don't recommend. I think the only reason to read it is if you want to have read all of Discworld. Otherwise, consider stopping with Snuff and letting it be the send-off for the Ankh-Morpork characters. Followed by The Shepherd's Crown, a Tiffany Aching story and the last Discworld novel. Rating: 3 out of 10
Armadillo is a powerful
and expressive C++ template library for linear algebra and scientific
computing. It aims towards a good balance between speed and ease of use,
has a syntax deliberately close to Matlab, and is useful for algorithm
development directly in C++, or quick conversion of research code into
production environments. RcppArmadillo
integrates this library with the R environment and language and is
widely used by (currently) 1158 other packages on CRAN, downloaded 35.1 million
times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint
/ vignette) by Conrad and myself has been cited 587 times according
to Google Scholar.
Conrad released a new
major upstream version 14.0.0 a couple of days ago. We had been testing
this new version extensively over several rounds of reverse-dependency
checks across all 1100+ packages. This revealed nine packages requiring
truly minor adjustments which eight maintainers made in a matter of
days; all this was coordinated in issue
#443. Following the upload, CRAN noticed one more issue (see
issue
#446) but this turned out to be local to the package. There are also
renewed deprecation warnings with some Armadillo changes which we will
need to address one-by-one. Last but not least with this release we also
changed the package versioning scheme to follow upstream Armadillo more closely.
The set of changes since the last CRAN release follows.
Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.Changes in RcppArmadillo version 14.0.0-1 (2024-07-05)
- Upgraded to Armadillo release 14.0.0 (Stochastic Parrot)
- C++14 is now the minimum recommended C++ standard
- Faster handling of compound expressions by
as_scalar(),accu(),dot()- Faster interactions between sparse and dense matrices
- Expanded
stddev()to handle sparse matrices- Expanded relational operators to handle expressions between sparse matrices and scalars
- Added
.as_dense()to obtain dense vector/matrix representation of any sparse matrix expression- Updated physical constants to NIST 2022 CODATA values
- New package version numbering scheme following upstream versions
- Re-enabling
ARMA_IGNORE_DEPRECATED_MARKEfor silent CRAN builds
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.
| Series: | Beyond #2 |
| Publisher: | Kit Rocha |
| Copyright: | December 2013 |
| ASIN: | B00GIA4GN8 |
| Format: | Kindle |
| Pages: | 364 |
To visualize it with [foo] to mark optional parts, it looks like debian/[PACKAGE.][NAME.]STEM[.ARCH] Detecting whether a given file is in fact a packaging file now boils down to reverse engineering its name against this pattern. Again, so far, it might still look manageable. One major complication is that every part (except ARCH) can contain periods. So a trivial "split by period" is not going to cut it. As an example:
- The package name followed by a period. Optional, but must be the first if present.
- The name segment followed by a period. Optional, but must appear between the package name (if present) and the stem. If the package name is not present, then the name segment must be first.
- The stem. Mandatory.
- An architecture restriction prefixed by a period. Optional, must appear after the stem if present.
debian/g++-3.0.user.serviceThis example is deliberately crafted to be ambiguous and show this problem in its full glory. This file name can be in multiple ways:
Therefore, there are a lot of possible ways to split this filename that all matches the pattern but with vastly different meaning and consequences.
- Is the stem service or user.service? (both are known stems from dh_installsystemd and dh_installsystemduser respectively). In fact, it can be both at the same time with "clever" usage of --name=user passed to dh_installsystemd.
- The g++-3.0 can be a package prefix or part of the name segment. Even if there is a g++-3.0 package in debian/control, then debhelper (until compat 15) will still happily match this file for the main package if you pass --name=g++-3.0 to the helper. Side bar: Woe is you if there is a g++-3 and a g++-3.0 package in debian/control, then we have multiple options for the package prefix! Though, I do not think that happens in practice.
A simple solution to the first problem could be to have a static list of known stems. That will get you started but the debhelper eco-system strive on decentralization, so this feels like a mismatch. There is also a second problem with the static list. Namely, a given stem is only "valid" if the command in question is actually in use. Which means you now need to dumpster dive into the mess that is Turning-complete debhelper configuration file known as debian/rules to fully solve that. Thanks to the Turning-completeness, we will never get a perfect solution for a static analysis. Instead, it is time to back out and instead apply some simplifications. Here is a sample flow:
- We need the possible stems up front to have a chance at all. When multiple stems are an option, go for the longest match (that is, the one with most periods) since --name is rare and "code golfing" is even rarer.
- We can make the package prefix mandatory for files with the name segment. This way, the moment there is something before the stem, we know the package prefix will be part of it and can cut it. It does not solve the ambiguity if one package name is a prefix of another package name (from the same source), but it still a lot better. This made its way into debhelper compat 15 and now it is "just" a slow long way to a better future.
With this logic, you can now:
- Check whether the dh sequencer is used. If so, use some heuristics to figure out which addons are used.
- Delegate to dh_assistant to figure out which commands will be used and which debhelper config file stems it knows about. Here we need to know which sequences are in use from step one (if relevant). Combine this with any other sources for stems you have.
- Deconstruct all files in debian/ against the stems and known package names from debian/control. In theory, dumpster diving after --name options would be helpful here, but personally I skipped that part as I want to keep my debian/rules parsing to an absolute minimum.
I have added the logic for all these features in debputy though the documentation association is currently not in a user facing command. All the others are now diagnostics emitted by debputy in its editor support mode (debputy lsp server) or via debputy lint. In the editor mode, the diagnostics are currently associated with the package name in debian/control due to technical limitations of how the editor integration works. Some of these features will the latest version of debhelper (moving target at times). Check with debputy lsp features for the Extra dh support feature, which will be enabled if you got all you need. Note: The detection is currently (mostly) ignoring files with architecture restrictions. That might be lifted in the future. However, architecture restricted config files tend to be rare, so they were not a priority at this point. Additionally, debputy for technical reasons ignores stem typos with multiple matches. That sadly means that typos of debian/docs will often be unreported due to its proximity to debian/dirs and vice versa.
- Provide typo detection of the stem (debian/foo.intsall -> debian/foo.install) provided to have adequate handling of the corner cases (such as debian/*.conf not needing correction into debian/*.config)
- Detect possible invalid package prefix (debian/foo.install without foo being a package). Note this has to be a weak warning unless the package is using debhelper compat 15 or you dumpster dived to validate that dh_install was not passed dh_install --name foo. Agreed, no one should do that, but they can and false positives are the worst kind of positives for a linting tool.
- With some limitations, detect files used without the relevant command being active. As an example, the some integration modes of debputy removes dh_install, so a debian/foo.install would not be used.
- Associate a given file with a given command to assist users with the documentation look up. Like debian/foo.user.service is related to dh_installsystemduser, so man dh_installsystemduser is a natural start for documentation.
The dh_assistant command uses the same logic as dh to identify the active add-ons and loads them. From there, it scans all commands mentioned in the sequence for the PROMISE: DH NOOP WITHOUT ...-hint and a new INTROSPECTABLE: CONFIG-FILES ...-hint. When these hints reference a packaging file (as an example, via pkgfile(foo)) then dh_assistant records that as a known packaging file for that helper. Additionally, debhelper now also tracks commands that were removed from the sequence. Several of the dh_assistant subcommand now use this to enrich their (JSON) output with notes about these commands being known but not active.
- Its own plugins can provide packager provided files. These are only relevant if the package is using debputy.
- It is als possible to provide a debputy plugin that identifies packaging files (either static or named ones). Though in practice, we probably do not want people to roll their own debputy plugin for this purpose, since the detection only works if the plugin is installed. I have used this mechanism to have debhelper provide a debhelper-documentation plugin to enrich the auto-detected data and we can assume most people interested in this feature would have debhelper installed.
- It asks dh_assistant list-guessed-dh-config-files for config files, which is covered below.
$ apt satisfy 'dh-debputy (>= 0.1.43~), debhelper (>= 13.16~), python3-lsprotocol, python3-levenshtein'
# For demo purposes, pull two known repos (feel free to use your own packages here)
$ git clone https://salsa.debian.org/debian/debhelper.git -b debian/13.16
$ git clone https://salsa.debian.org/debian/debputy.git -b debian/0.1.43
$ cd debhelper
$ mv debian/debhelper.install debian/debhelper.intsall
$ debputy lint
warning: File: debian/debhelper.intsall:1:0:1:0: The file "debian/debhelper.intsall" is likely a typo of "debian/debhelper.install"
File-level diagnostic
$ mv debian/debhelper.intsall debian/debhleper.install
$ debputy lint
warning: File: debian/debhleper.install:1:0:1:0: Possible typo in "debian/debhleper.install". Consider renaming the file to "debian/debhelper.debhleper.install" or "debian/debhelper.install" if it is intended for debhelper
File-level diagnostic
$ cd ../debputy
$ touch debian/install
$ debputy lint --no-warn-about-check-manifest
warning: File: debian/install:1:0:1:0: The file debian/install is related to a command that is not active in the dh sequence with the current addons
File-level diagnostic
| Series: | Earth's Shadow #1 |
| Publisher: | Wizard's Tower Press |
| Copyright: | April 2024 |
| ISBN: | 1-913892-71-9 |
| Format: | Kindle |
| Pages: | 355 |
curl --http3-only https://example.com
Or, if you would like to try it out in a container:
podman run debian:unstable apt install --update -y curl && curl --http3-only https://example.com
(in case you haven't noticed, apt now has the --update option for the
upgrade and install commands, although not available on stable yet)
An SSL library that provides QUIC support is recommended to build nginx, such as BoringSSL, LibreSSL, or QuicTLS. Otherwise, the OpenSSL compatibility layer will be used that does not support early data.As you can see, they don't recommend using OpenSSL, and when doing so, you don't get complete support.
This experimental feature requires a special build of OpenSSL, as ECH is not yet supported in OpenSSL releases. In contrast ECH is supported by the latest BoringSSL and wolfSSL releases.As it turns out,
Encrypted Client Hello is experimental and it's not
supported by the vanilla OpenSSL.
This was enough of an investigation for me to go ahead with the change. Noting
that even in the worst case scenario (we find a horrible regression), we can
rollback without having affected a single stable release.
Now that the package is on Debian unstable, the CI tests (autopkgtest) of every
package that depends on curl is currently running, the results are compared
against the migration-reference (in this case, the curl CLI with OpenSSL,
before the change).
If everything goes right, curl with HTTP3 support will migrate to Debian
testing in around 5 days. If we spot any issues, we'll have to solve them
first and it's going to be hard to predict how long it takes, although it's
fair to expect less than a month.
derive-deftly, the template-based derive-macro facility for Rust, has been a great success.
It s coming up to time to declare a stable 1.x version. If you d like to try it out, and have final comments / observations, now is the time.
Introduction to derive-deftly
Have you ever wished that you could that could write a new derive macro without having to mess with procedural macros?
You can!
derive-deftly lets you write a #[derive] macro, using a template syntax which looks a lot like macro_rules!:
use derive_deftly:: define_derive_deftly, Deftly ;
define_derive_deftly!
ListVariants:
impl $ttype
fn list_variants() -> Vec<&'static str>
vec![ $( stringify!( $vname ) , ) ]
#[derive(Deftly)]
#[derive_deftly(ListVariants)]
enum Enum
UnitVariant,
StructVariant a: u8, b: u16 ,
TupleVariant(u8, u16),
assert_eq!(
Enum::list_variants(),
["UnitVariant", "StructVariant", "TupleVariant"],
);Status
derive-deftly has a wide range of features, which can be used to easily write sophisticated and reliable derive macros. We ve been using it in Arti, the Tor Project s reimplementation of Tor in Rust, and we ve found it very useful.
There is comprehensive reference documentation, and more discursive User Guide for a more gentle introduction. Naturally, everything is fully tested.
History
derive-deftly started out as a Tor Hackweek project. It used to be called derive-adhoc. But we renamed it because we found that many of the most interesting use cases were really not very ad-hoc at all.
Over the past months we ve been ticking off our 1.0 blocker tickets. We ve taken the opportunity to improve syntax, terminology, and semantics. We hope we have now made the last breaking changes.
Plans - call for review/testing
In the near future, we plan to declare version 1.0. After 1.x, we intend to make breaking changes very rarely.
So, right now, we d like last-minute feedback. Are there any wrinkles that need to be sorted out? Please file tickets or MRs on our gitlab. Ideally, anything which might imply breaking changes would be submitted on or before the 13th of August.
In the medium to long term, we have many ideas for how to make derive-deftly even more convenient, and even more powerful. But we are going to proceed cautiously, because we don t want to introduce bad syntax or bad features, which will require difficult decisions in the future about forward compatibility.
wcurl example.com/filename.txt
Manpage:/usr/bin, the code is here:Example to download a single file:
- Encode whitespaces in URLs;
- Download multiple URLs in parallel if the installed curl's version is >= 7.66.0;
- Follow redirects;
- Automatically choose a filename as output;
- Avoid overwriting files if the installed curl's version is >= 7.83.0 (--no-clobber);
- Perform retries;
- Set the downloaded file timestamp to the value provided by the server, if available;
- Default to the protocol used as https if the URL doesn't contain any;
- Disable curl's URL globbing parser so and [] characters in URLs are not treated specially.
wcurl example.com/filename.txt
If you ever need to set a custom flag, you can make use of the --curl-options
wcurl option, anything set there will be passed to the curl invocation.
Just beware that if you need to set any custom flags, it's likely you will be
better served by calling curl directly. The --curl-options option is there to
allow for some flexibility in unforeseen circumstances.
-O, I really want wget like functionality where I don't have to specify the name
Downloading a file (like wget) could be improved - with automatic naming of the file
downloading files - wget is much cleaner
I wish the default behaviour when GETting a binary was to drop it on disk. That's the only reason 'wget foo.tgz" is still ingrained in my muscle memory .
Maybe have a way to download without specifying something in -o (the only reason i used wget still)
--remote-time should be default
--remote-name-all could really use a short flag
"Write the data to the file named in the URL (or in redirects if I'm feeling daring), and timestamp the file to the last-modified-date". This is the main reason I'm still using wget.I can finally feel less bad about falling back to wget due to not remembering the parameters I want.
# image x y z temperature image1.png 1 2 5 34 image2.png 3 4 1 35As usual, I would be using
vnlog.slurp() (a thin wrapper around
numpy.loadtxt()) to read this in, but that doesn't work: the image filenames
aren't parseable as numerical values. Up until now I would work around this by
using the suprocess module to fork off a vnl-filter -p !image and then slurp
that, but it's a pain and slow and has other issues. I just solved this
conclusively using the numpy structured dtypes. I can now do this:
dtype = np.dtype([ ('image', 'U16'), ('x y z', int, (3,)), ('temperature', float), ]) arr = vnlog.slurp("data.vnl", dtype=dtype)
print(arr['image'])
---> array(['image1.png', 'image2.png'], dtype='<U16')
print(arr['x y z'])
---> array([[1, 2, 5],
[3, 4, 1]])
print(arr['temperature'])
---> array([34., 35.])
Notes:
temperature column, for instance
dtype = np.dtype([ ('image', 'U16'), ('x y z', int, (3,)), ('temperature', float), ])
dtype = np.dtype([ ('image', 'U16'), ('x', int), ('y', int), ('z', int), ('temperature', float), ])
x, y, z into separate, individual arrays. Sometime
we want this, sometimes not.
slurp() returns the array only, since the
field names are already available in the dtype
-). This could
probably be handled with the converters kwarg of numpy.loadtxt(), but that
sounds slow. I'll look at that later.
This is available today in vnlog 1.38.
Dear Debian community,
Statement on Daniel Pocock
The Debian project has successfully taken action to secure its
trademarks and interests worldwide, as detailed in our press
statement. I would like
to personally thank everyone in the community who was involved in this
process. I would have loved for you all to have spent your volunteer
time on more fruitful things.
Debian Boot team might need help
I think I've identified the issue that finally motivated me to contact
our teams: for a long time, I have had the impression that Debian is
driven by several "one-person teams" (to varying extents of individual
influence and susceptibility to burnout). As DPL, I see it as my task to
find ways to address this issue and provide support.
I received private responses from Debian Boot team members, which
motivated me to kindly invite volunteers to some prominent and highly
visible fields of work that you might find personally challenging. I
recommend subscribing to the
Debian Boot mailing list to see
where you might be able to provide assistance.
/usrmerge
Helmut Grohne confirmed
that the last remaining packages shipping aliased files inside the package set
relevant to debootstrap were uploaded. Thanks a lot for Helmut and all
contributors that helped to implement
DEP17.
Contacting more teams
I'd like to repeat that I've registered a BoF for DebConf24 in Busan
with the following description:
This BoF is an attempt to gather as much as possible teams inside
Debian to exchange experiences, discuss workflows inside teams, share
their ways to attract newcomers etc.
Each participant team should prepare a short description of their work
and what team roles ( openings ) they have for new contributors. Even
for delegated teams (membership is less fluid), it would be good to
present the team, explain what it takes to be a team member, and what
steps people usually go to end up being invited to participate. Some
other teams can easily absorb contributions from salsa MRs, and at some
point people get commit access. Anyway, the point is that we work on the
idea that the pathway to become a team member becomes more clear from an
outsider point-of-view.
I'm lagging a bit behind my team contacting schedule and will not manage
to contact every team before DebConf. As a (short) summary, I can draw
some positive conclusions about my efforts to reach out to teams. I was
able to identify some issues that were new to me and which I am now
working on. Examples include limitations in Salsa and Salsa CI. I
consider both essential parts of our infrastructure and will support
both teams in enhancing their services.
Some teams confirmed that they are basically using some common
infrastructure (Salsa team space, mailing lists, IRC channels) but that
the individual members of the team work on their own problems without
sharing any common work. I have also not read about convincing
strategies to attract newcomers to the team, as we have established, for
instance, in the Debian Med team.
DebConf attendance
The amount of money needed to fly people to South Korea was higher than
usual, so the DebConf bursary team had to make some difficult decisions
about who could be reimbursed for travel expenses. I extended the budget
for diversity and newcomers, which enabled us to invite some additional
contributors. We hope that those who were not able to come this year can
make it next year to Brest or to MiniDebConf
Cambridge or
Toulouse
tag2upload
On June 12, Sean Whitton requested comments on the debian-vote list
regarding a General Resolution (GR) about
tag2upload.
The discussion began with technical details but unfortunately, as often
happens in long threads, it drifted into abrasive language, prompting
the community team to address the behavior of an opponent of the GR
supporters. After 560 emails covering technical details, including a
detailed security review
by Russ Allbery, Sean finally proposed the
GR
on June 27, 2024 (two weeks after requesting comments).
Firstly, I would like to thank the drivers of this GR and acknowledge
the technical work behind it, including the security review. I am
positively convinced that Debian can benefit from modernizing its
infrastructure, particularly through stronger integration of Git into
packaging workflows.
Sam Hartman provided some historical context
[1],
[2],
[3],
[4],
noting that this discussion originally took place five years ago with no
results from several similarly lengthy threads. My favorite
summary of the
entire thread was given by Gregor Herrmann, which reflects the same gut
feeling I have and highlights a structural problem within Debian that
hinders technical changes. Addressing this issue is definitely a matter
for the Debian Project Leader, and I will try to address it during my
term.
At the time of writing these bits, a
proposal
from ftpmaster, which is being continuously discussed, might lead to a
solution. I was also asked to extend the
GR discussion periods
which I will do in separate mail.
Talk: Debian GNU/Linux for Scientific Research
I was invited to have a
talk
in the Systems-Facing Track of University of British Columbia (who is
sponsoring rack space for several Debian servers). I admit it felt a bit
strange to me after working more than 20 years for establishing Debian in
scientific environments to be invited to such a talk "because I'm DPL".
Kind regards
Andreas.
Next.