Search Results: "spa"

16 November 2023

Dimitri John Ledkov: Ubuntu 23.10 significantly reduces the installed kernel footprint


Photo by Pixabay
Ubuntu systems typically have up to 3 kernels installed, before they are auto-removed by apt on classic installs. Historically the installation was optimized for metered download size only. However, kernel size growth and usage no longer warrant such optimizations. During the 23.10 Mantic Minatour cycle, I led a coordinated effort across multiple teams to implement lots of optimizations that together achieved unprecedented install footprint improvements.

Given a typical install of 3 generic kernel ABIs in the default configuration on a regular-sized VM (2 CPU cores 8GB of RAM) the following metrics are achieved in Ubuntu 23.10 versus Ubuntu 22.04 LTS:

  • 2x less disk space used (1,417MB vs 2,940MB, including initrd)

  • 3x less peak RAM usage for the initrd boot (68MB vs 204MB)

  • 0.5x increase in download size (949MB vs 600MB)

  • 2.5x faster initrd generation (4.5s vs 11.3s)

  • approximately the same total time (103s vs 98s, hardware dependent)


For minimal cloud images that do not install either linux-firmware or modules extra the numbers are:

  • 1.3x less disk space used (548MB vs 742MB)

  • 2.2x less peak RAM usage for initrd boot (27MB vs 62MB)

  • 0.4x increase in download size (207MB vs 146MB)


Hopefully, the compromise of download size, relative to the disk space & initrd savings is a win for the majority of platforms and use cases. For users on extremely expensive and metered connections, the likely best saving is to receive air-gapped updates or skip updates.

This was achieved by precompressing kernel modules & firmware files with the maximum level of Zstd compression at package build time; making actual .deb files uncompressed; assembling the initrd using split cpio archives - uncompressed for the pre-compressed files, whilst compressing only the userspace portions of the initrd; enabling in-kernel module decompression support with matching kmod; fixing bugs in all of the above, and landing all of these things in time for the feature freeze. Whilst leveraging the experience and some of the design choices implementations we have already been shipping on Ubuntu Core. Some of these changes are backported to Jammy, but only enough to support smooth upgrades to Mantic and later. Complete gains are only possible to experience on Mantic and later.

The discovered bugs in kernel module loading code likely affect systems that use LoadPin LSM with kernel space module uncompression as used on ChromeOS systems. Hopefully, Kees Cook or other ChromeOS developers pick up the kernel fixes from the stable trees. Or you know, just use Ubuntu kernels as they do get fixes and features like these first.

The team that designed and delivered these changes is large: Benjamin Drung, Andrea Righi, Juerg Haefliger, Julian Andres Klode, Steve Langasek, Michael Hudson-Doyle, Robert Kratky, Adrien Nader, Tim Gardner, Roxana Nicolescu - and myself Dimitri John Ledkov ensuring the most optimal solution is implemented, everything lands on time, and even implementing portions of the final solution.

Hi, It's me, I am a Staff Engineer at Canonical and we are hiring https://canonical.com/careers.

Lots of additional technical details and benchmarks on a huge range of diverse hardware and architectures, and bikeshedding all the things below:

For questions and comments please post to Kernel section on Ubuntu Discourse.


15 November 2023

Scarlett Gately Moore: Farewell for now, again.

I write this with a heavy heart. Exactly one year ago I lost my beloved job. That was all me, I had a terrible run of bad luck with COVID and I never caught up. In the last year, I have taken on several new projects to re-create a new image for myself and to make up for the previous year, and I believe I worked very hard in doing so. Unfortunately, my seemingly good interviews have not ended in a job. One potential job I did not put as much effort into as I should have because I put all my cards into a project that didn t quite turn out as expected. I do hope it still goes through for the KDE community as a whole, because well it is really cool, but it isn t the job I thought. I have been relying purely on donations for survival and it simply isn t enough. I am faced once again with no internet to even do my open source work ( Snaps, KDE neon, Debian and everything that links to those ). I simply can t put the burden of my stubbornness on my family any longer. Bills are long over due, we have learned to live without many things, but the stress of essential bills, living expenses going unpaid is simply too much. I do thank each and every one of you that has contributed to my fundraisers. It means the world to me that people do care. It just isn t enough. So with the sunset of Witch Wells, I am sun setting my software career for now and will be looking for something, anything local just to pay some bills, calm our nerves and hopefully find some happiness again. I am tired, broke, stressed out and burned out. I will be back when I can breathe again with my finances. If you can spare some changes to help with gas, propane, internet I would be so ever grateful. So long for now. ~ Scarlett https://gofund.me/1346869d

13 November 2023

Freexian Collaborators: Monthly report about Debian Long Term Support, October 2023 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In October, 18 contributors have been paid to work on Debian LTS, their reports are available:
  • Adrian Bunk did 8.0h (out of 7.75h assigned and 10.0h from previous period), thus carrying over 9.75h to the next month.
  • Anton Gladky did 9.5h (out of 9.5h assigned and 5.5h from previous period), thus carrying over 5.5h to the next month.
  • Bastien Roucari s did 16.0h (out of 16.75h assigned and 1.0h from previous period), thus carrying over 1.75h to the next month.
  • Ben Hutchings did 8.0h (out of 17.75h assigned), thus carrying over 9.75h to the next month.
  • Chris Lamb did 17.0h (out of 17.75h assigned), thus carrying over 0.75h to the next month.
  • Emilio Pozuelo Monfort did 17.5h (out of 17.75h assigned), thus carrying over 0.25h to the next month.
  • Guilhem Moulin did 9.75h (out of 17.75h assigned), thus carrying over 8.0h to the next month.
  • Helmut Grohne did 1.5h (out of 10.0h assigned), thus carrying over 8.5h to the next month.
  • Lee Garrett did 10.75h (out of 17.75h assigned), thus carrying over 7.0h to the next month.
  • Markus Koschany did 30.0h (out of 30.0h assigned).
  • Ola Lundqvist did 4.0h (out of 0h assigned and 19.5h from previous period), thus carrying over 15.5h to the next month.
  • Roberto C. S nchez did 12.0h (out of 5.0h assigned and 7.0h from previous period).
  • Santiago Ruano Rinc n did 13.625h (out of 7.75h assigned and 8.25h from previous period), thus carrying over 2.375h to the next month.
  • Sean Whitton did 13.0h (out of 6.0h assigned and 7.0h from previous period).
  • Sylvain Beucler did 7.5h (out of 11.25h assigned and 6.5h from previous period), thus carrying over 10.25h to the next month.
  • Thorsten Alteholz did 14.0h (out of 14.0h assigned).
  • Tobias Frost did 16.0h (out of 9.25h assigned and 6.75h from previous period).
  • Utkarsh Gupta did 0.0h (out of 0.75h assigned and 17.0h from previous period), thus carrying over 17.75h to the next month.

Evolution of the situation In October, we have released 49 DLAs. Of particular note in the month of October, LTS contributor Chris Lamb issued DLA 3627-1 pertaining to Redis, the popular key-value database similar to Memcached, which was vulnerable to an authentication bypass vulnerability. Fixing this vulnerability involved dealing with a race condition that could allow another process an opportunity to establish an otherwise unauthorized connection. LTS contributor Markus Koschany was involved in the mitigation of CVE-2023-44487, which is a protocol-level vulnerability in the HTTP/2 protocol. The impacts within Debian involved multiple packages, across multiple releases, with multiple advisories being released (both DSA for stable and old-stable, and DLA for LTS). Markus reviewed patches and security updates prepared by other Debian developers, investigated reported regressions, provided patches for the aforementioned regressions, and issued several security updates as part of this. Additionally, as MariaDB 10.3 (the version originally included with Debian buster) passed end-of-life earlier this year, LTS contributor Emilio Pozuelo Monfort has begun investigating the feasibility of backporting MariaDB 10.11. The work is in early stages, with much testing and analysis remaining before a final decision can be made, as this only one of several available potential courses of action concerning MariaDB. Finally, LTS contributor Lee Garrett has invested considerable effort into the development the Functional Test Framework here. While so far only an initial version has been published, it already has several features which we intend to begin leveraging for testing of LTS packages. In particular, the FTF supports provisioning multiple VMs for the purposes of performing functional tests of network-facing services (e.g., file services, authentication, etc.). These tests are in addition to the various unit-level tests which are executed during package build time. Development work will continue on FTF and as it matures and begins to see wider use within LTS we expect to improve the quality of the updates we publish.

Thanks to our sponsors Sponsors that joined recently are in bold.

12 November 2023

Lukas M rdian: Netplan brings consistent network configuration across Desktop, Server, Cloud and IoT

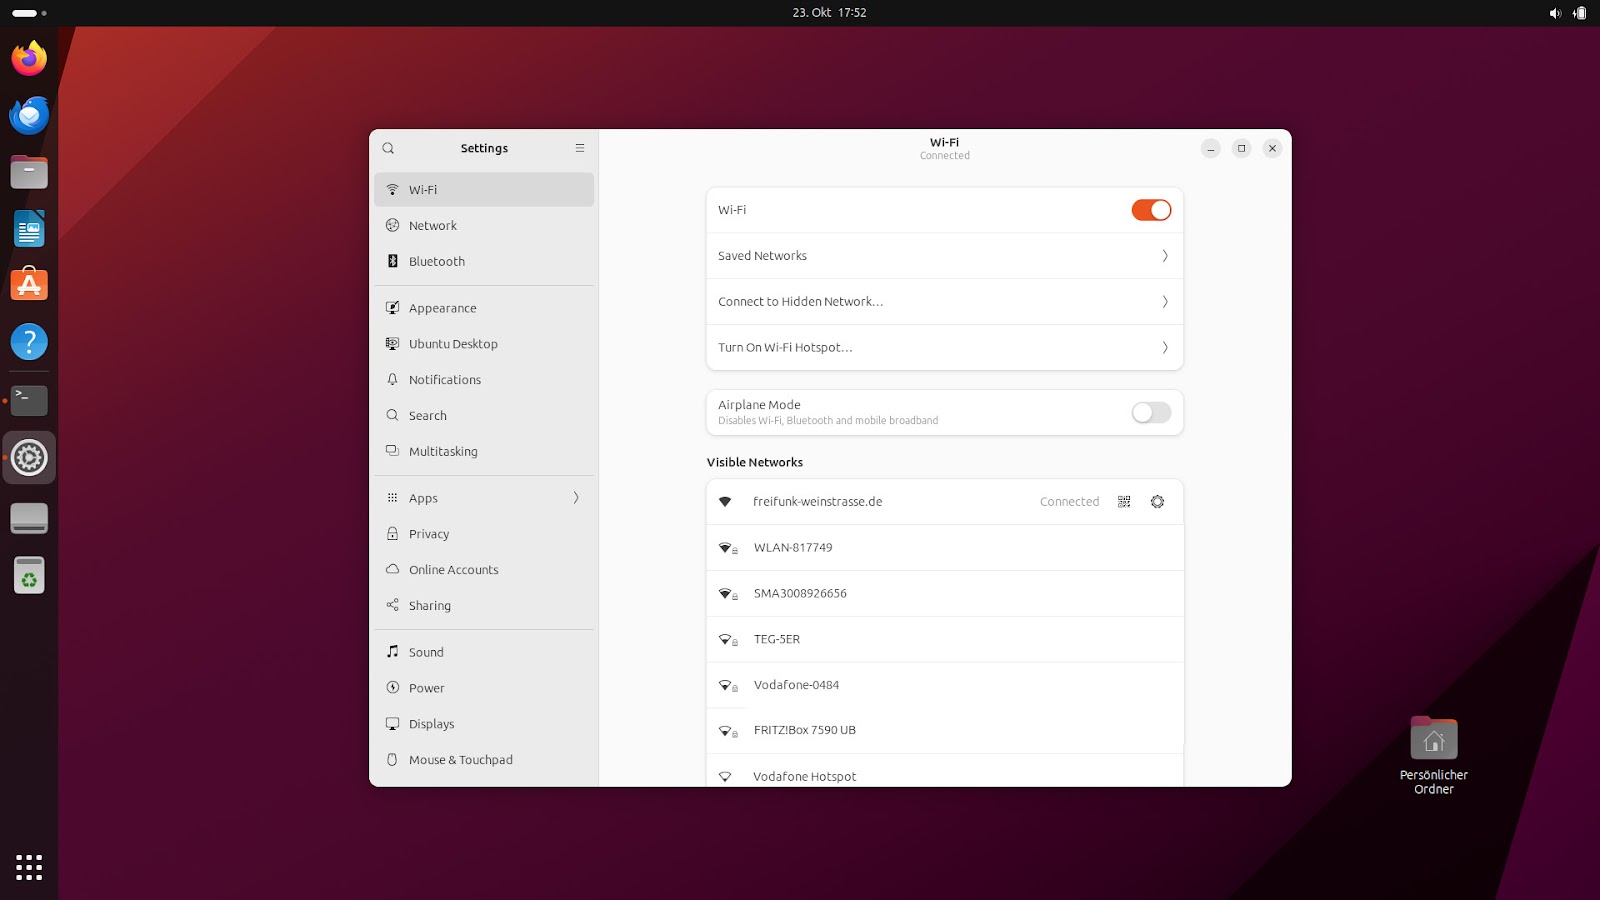
Ubuntu 23.10 Mantic Minotaur Desktop, showing network settings We released Ubuntu 23.10 Mantic Minotaur on 12 October 2023, shipping its proven and trusted network stack based on Netplan. Netplan is the default tool to configure Linux networking on Ubuntu since 2016. In the past, it was primarily used to control the Server and Cloud variants of Ubuntu, while on Desktop systems it would hand over control to NetworkManager. In Ubuntu 23.10 this disparity in how to control the network stack on different Ubuntu platforms was closed by integrating NetworkManager with the underlying Netplan stack. Netplan could already be used to describe network connections on Desktop systems managed by NetworkManager. But network connections created or modified through NetworkManager would not be known to Netplan, so it was a one-way street. Activating the bidirectional NetworkManager-Netplan integration allows for any configuration change made through NetworkManager to be propagated back into Netplan. Changes made in Netplan itself will still be visible in NetworkManager, as before. This way, Netplan can be considered the single source of truth for network configuration across all variants of Ubuntu, with the network configuration stored in /etc/netplan/, using Netplan s common and declarative YAML format.

Netplan Desktop integration On workstations, the most common scenario is for users to configure networking through NetworkManager s graphical interface, instead of driving it through Netplan s declarative YAML files. Netplan ships a libnetplan library that provides an API to access Netplan s parser and validation internals, which is now used by NetworkManager to store any network interface configuration changes in Netplan. For instance, network configuration defined through NetworkManager s graphical UI or D-Bus API will be exported to Netplan s native YAML format in the common location at /etc/netplan/. This way, the only thing administrators need to care about when managing a fleet of Desktop installations is Netplan. Furthermore, programmatic access to all network configuration is now easily accessible to other system components integrating with Netplan, such as snapd. This solution has already been used in more confined environments, such as Ubuntu Core and is now enabled by default on Ubuntu 23.10 Desktop.

Migration of existing connection profiles On installation of the NetworkManager package (network-manager >= 1.44.2-1ubuntu1) in Ubuntu 23.10, all your existing connection profiles from /etc/NetworkManager/system-connections/ will automatically and transparently be migrated to Netplan s declarative YAML format and stored in its common configuration directory /etc/netplan/. The same migration will happen in the background whenever you add or modify any connection profile through the NetworkManager user interface, integrated with GNOME Shell. From this point on, Netplan will be aware of your entire network configuration and you can query it using its CLI tools, such as sudo netplan get or sudo netplan status without interrupting traditional NetworkManager workflows (UI, nmcli, nmtui, D-Bus APIs). You can observe this migration on the apt-get command line, watching out for logs like the following:
Setting up network-manager (1.44.2-1ubuntu1.1) ...
Migrating HomeNet (9d087126-ae71-4992-9e0a-18c5ea92a4ed) to /etc/netplan
Migrating eduroam (37d643bb-d81d-4186-9402-7b47632c59b1) to /etc/netplan
Migrating DebConf (f862be9c-fb06-4c0f-862f-c8e210ca4941) to /etc/netplan
In order to prepare for a smooth transition, NetworkManager tests were integrated into Netplan s continuous integration pipeline at the upstream GitHub repository. Furthermore, we implemented a passthrough method of handling unknown or new settings that cannot yet be fully covered by Netplan, making Netplan future-proof for any upcoming NetworkManager release.

The future of Netplan Netplan has established itself as the proven network stack across all variants of Ubuntu Desktop, Server, Cloud, or Embedded. It has been the default stack across many Ubuntu LTS releases, serving millions of users over the years. With the bidirectional integration between NetworkManager and Netplan the final piece of the puzzle is implemented to consider Netplan the single source of truth for network configuration on Ubuntu. With Debian choosing Netplan to be the default network stack for their cloud images, it is also gaining traction outside the Ubuntu ecosystem and growing into the wider open source community. Within the development cycle for Ubuntu 24.04 LTS, we will polish the Netplan codebase to be ready for a 1.0 release, coming with certain guarantees on API and ABI stability, so that other distributions and 3rd party integrations can rely on Netplan s interfaces. First steps into that direction have already been taken, as the Netplan team reached out to the Debian community at DebConf 2023 in Kochi/India to evaluate possible synergies.

Conclusion Netplan can be used transparently to control a workstation s network configuration and plays hand-in-hand with many desktop environments through its tight integration with NetworkManager. It allows for easy network monitoring, using common graphical interfaces and provides a single source of truth to network administrators, allowing for configuration of Ubuntu Desktop fleets in a streamlined and declarative way. You can try this new functionality hands-on by following the Access Desktop NetworkManager settings through Netplan tutorial.
If you want to learn more, feel free to follow our activities on Netplan.io, GitHub, Launchpad, IRC or our Netplan Developer Diaries blog on discourse.

Petter Reinholdtsen: New and improved sqlcipher in Debian for accessing Signal database

For a while now I wanted to have direct access to the Signal database of messages and channels of my Desktop edition of Signal. I prefer the enforced end to end encryption of Signal these days for my communication with friends and family, to increase the level of safety and privacy as well as raising the cost of the mass surveillance government and non-government entities practice these days. In August I came across a nice recipe on how to use sqlcipher to extract statistics from the Signal database explaining how to do this. Unfortunately this did not work with the version of sqlcipher in Debian. The sqlcipher package is a "fork" of the sqlite package with added support for encrypted databases. Sadly the current Debian maintainer announced more than three years ago that he did not have time to maintain sqlcipher, so it seemed unlikely to be upgraded by the maintainer. I was reluctant to take on the job myself, as I have very limited experience maintaining shared libraries in Debian. After waiting and hoping for a few months, I gave up the last week, and set out to update the package. In the process I orphaned it to make it more obvious for the next person looking at it that the package need proper maintenance. The version in Debian was around five years old, and quite a lot of changes had taken place upstream into the Debian maintenance git repository. After spending a few days importing the new upstream versions, realising that upstream did not care much for SONAME versioning as I saw library symbols being both added and removed with minor version number changes to the project, I concluded that I had to do a SONAME bump of the library package to avoid surprising the reverse dependencies. I even added a simple autopkgtest script to ensure the package work as intended. Dug deep into the hole of learning shared library maintenance, I set out a few days ago to upload the new version to Debian experimental to see what the quality assurance framework in Debian had to say about the result. The feedback told me the pacakge was not too shabby, and yesterday I uploaded the latest version to Debian unstable. It should enter testing today or tomorrow, perhaps delayed by a small library transition. Armed with a new version of sqlcipher, I can now have a look at the SQL database in ~/.config/Signal/sql/db.sqlite. First, one need to fetch the encryption key from the Signal configuration using this simple JSON extraction command:
/usr/bin/jq -r '."key"' ~/.config/Signal/config.json
Assuming the result from that command is 'secretkey', which is a hexadecimal number representing the key used to encrypt the database. Next, one can now connect to the database and inject the encryption key for access via SQL to fetch information from the database. Here is an example dumping the database structure:
% sqlcipher ~/.config/Signal/sql/db.sqlite
sqlite> PRAGMA key = "x'secretkey'";
sqlite> .schema
CREATE TABLE sqlite_stat1(tbl,idx,stat);
CREATE TABLE conversations(
      id STRING PRIMARY KEY ASC,
      json TEXT,
      active_at INTEGER,
      type STRING,
      members TEXT,
      name TEXT,
      profileName TEXT
    , profileFamilyName TEXT, profileFullName TEXT, e164 TEXT, serviceId TEXT, groupId TEXT, profileLastFetchedAt INTEGER);
CREATE TABLE identityKeys(
      id STRING PRIMARY KEY ASC,
      json TEXT
    );
CREATE TABLE items(
      id STRING PRIMARY KEY ASC,
      json TEXT
    );
CREATE TABLE sessions(
      id TEXT PRIMARY KEY,
      conversationId TEXT,
      json TEXT
    , ourServiceId STRING, serviceId STRING);
CREATE TABLE attachment_downloads(
    id STRING primary key,
    timestamp INTEGER,
    pending INTEGER,
    json TEXT
  );
CREATE TABLE sticker_packs(
    id TEXT PRIMARY KEY,
    key TEXT NOT NULL,
    author STRING,
    coverStickerId INTEGER,
    createdAt INTEGER,
    downloadAttempts INTEGER,
    installedAt INTEGER,
    lastUsed INTEGER,
    status STRING,
    stickerCount INTEGER,
    title STRING
  , attemptedStatus STRING, position INTEGER DEFAULT 0 NOT NULL, storageID STRING, storageVersion INTEGER, storageUnknownFields BLOB, storageNeedsSync
      INTEGER DEFAULT 0 NOT NULL);
CREATE TABLE stickers(
    id INTEGER NOT NULL,
    packId TEXT NOT NULL,
    emoji STRING,
    height INTEGER,
    isCoverOnly INTEGER,
    lastUsed INTEGER,
    path STRING,
    width INTEGER,
    PRIMARY KEY (id, packId),
    CONSTRAINT stickers_fk
      FOREIGN KEY (packId)
      REFERENCES sticker_packs(id)
      ON DELETE CASCADE
  );
CREATE TABLE sticker_references(
    messageId STRING,
    packId TEXT,
    CONSTRAINT sticker_references_fk
      FOREIGN KEY(packId)
      REFERENCES sticker_packs(id)
      ON DELETE CASCADE
  );
CREATE TABLE emojis(
    shortName TEXT PRIMARY KEY,
    lastUsage INTEGER
  );
CREATE TABLE messages(
        rowid INTEGER PRIMARY KEY ASC,
        id STRING UNIQUE,
        json TEXT,
        readStatus INTEGER,
        expires_at INTEGER,
        sent_at INTEGER,
        schemaVersion INTEGER,
        conversationId STRING,
        received_at INTEGER,
        source STRING,
        hasAttachments INTEGER,
        hasFileAttachments INTEGER,
        hasVisualMediaAttachments INTEGER,
        expireTimer INTEGER,
        expirationStartTimestamp INTEGER,
        type STRING,
        body TEXT,
        messageTimer INTEGER,
        messageTimerStart INTEGER,
        messageTimerExpiresAt INTEGER,
        isErased INTEGER,
        isViewOnce INTEGER,
        sourceServiceId TEXT, serverGuid STRING NULL, sourceDevice INTEGER, storyId STRING, isStory INTEGER
        GENERATED ALWAYS AS (type IS 'story'), isChangeCreatedByUs INTEGER NOT NULL DEFAULT 0, isTimerChangeFromSync INTEGER
        GENERATED ALWAYS AS (
          json_extract(json, '$.expirationTimerUpdate.fromSync') IS 1
        ), seenStatus NUMBER default 0, storyDistributionListId STRING, expiresAt INT
        GENERATED ALWAYS
        AS (ifnull(
          expirationStartTimestamp + (expireTimer * 1000),
          9007199254740991
        )), shouldAffectActivity INTEGER
        GENERATED ALWAYS AS (
          type IS NULL
          OR
          type NOT IN (
            'change-number-notification',
            'contact-removed-notification',
            'conversation-merge',
            'group-v1-migration',
            'keychange',
            'message-history-unsynced',
            'profile-change',
            'story',
            'universal-timer-notification',
            'verified-change'
          )
        ), shouldAffectPreview INTEGER
        GENERATED ALWAYS AS (
          type IS NULL
          OR
          type NOT IN (
            'change-number-notification',
            'contact-removed-notification',
            'conversation-merge',
            'group-v1-migration',
            'keychange',
            'message-history-unsynced',
            'profile-change',
            'story',
            'universal-timer-notification',
            'verified-change'
          )
        ), isUserInitiatedMessage INTEGER
        GENERATED ALWAYS AS (
          type IS NULL
          OR
          type NOT IN (
            'change-number-notification',
            'contact-removed-notification',
            'conversation-merge',
            'group-v1-migration',
            'group-v2-change',
            'keychange',
            'message-history-unsynced',
            'profile-change',
            'story',
            'universal-timer-notification',
            'verified-change'
          )
        ), mentionsMe INTEGER NOT NULL DEFAULT 0, isGroupLeaveEvent INTEGER
        GENERATED ALWAYS AS (
          type IS 'group-v2-change' AND
          json_array_length(json_extract(json, '$.groupV2Change.details')) IS 1 AND
          json_extract(json, '$.groupV2Change.details[0].type') IS 'member-remove' AND
          json_extract(json, '$.groupV2Change.from') IS NOT NULL AND
          json_extract(json, '$.groupV2Change.from') IS json_extract(json, '$.groupV2Change.details[0].aci')
        ), isGroupLeaveEventFromOther INTEGER
        GENERATED ALWAYS AS (
          isGroupLeaveEvent IS 1
          AND
          isChangeCreatedByUs IS 0
        ), callId TEXT
        GENERATED ALWAYS AS (
          json_extract(json, '$.callId')
        ));
CREATE TABLE sqlite_stat4(tbl,idx,neq,nlt,ndlt,sample);
CREATE TABLE jobs(
        id TEXT PRIMARY KEY,
        queueType TEXT STRING NOT NULL,
        timestamp INTEGER NOT NULL,
        data STRING TEXT
      );
CREATE TABLE reactions(
        conversationId STRING,
        emoji STRING,
        fromId STRING,
        messageReceivedAt INTEGER,
        targetAuthorAci STRING,
        targetTimestamp INTEGER,
        unread INTEGER
      , messageId STRING);
CREATE TABLE senderKeys(
        id TEXT PRIMARY KEY NOT NULL,
        senderId TEXT NOT NULL,
        distributionId TEXT NOT NULL,
        data BLOB NOT NULL,
        lastUpdatedDate NUMBER NOT NULL
      );
CREATE TABLE unprocessed(
        id STRING PRIMARY KEY ASC,
        timestamp INTEGER,
        version INTEGER,
        attempts INTEGER,
        envelope TEXT,
        decrypted TEXT,
        source TEXT,
        serverTimestamp INTEGER,
        sourceServiceId STRING
      , serverGuid STRING NULL, sourceDevice INTEGER, receivedAtCounter INTEGER, urgent INTEGER, story INTEGER);
CREATE TABLE sendLogPayloads(
        id INTEGER PRIMARY KEY ASC,
        timestamp INTEGER NOT NULL,
        contentHint INTEGER NOT NULL,
        proto BLOB NOT NULL
      , urgent INTEGER, hasPniSignatureMessage INTEGER DEFAULT 0 NOT NULL);
CREATE TABLE sendLogRecipients(
        payloadId INTEGER NOT NULL,
        recipientServiceId STRING NOT NULL,
        deviceId INTEGER NOT NULL,
        PRIMARY KEY (payloadId, recipientServiceId, deviceId),
        CONSTRAINT sendLogRecipientsForeignKey
          FOREIGN KEY (payloadId)
          REFERENCES sendLogPayloads(id)
          ON DELETE CASCADE
      );
CREATE TABLE sendLogMessageIds(
        payloadId INTEGER NOT NULL,
        messageId STRING NOT NULL,
        PRIMARY KEY (payloadId, messageId),
        CONSTRAINT sendLogMessageIdsForeignKey
          FOREIGN KEY (payloadId)
          REFERENCES sendLogPayloads(id)
          ON DELETE CASCADE
      );
CREATE TABLE preKeys(
        id STRING PRIMARY KEY ASC,
        json TEXT
      , ourServiceId NUMBER
        GENERATED ALWAYS AS (json_extract(json, '$.ourServiceId')));
CREATE TABLE signedPreKeys(
        id STRING PRIMARY KEY ASC,
        json TEXT
      , ourServiceId NUMBER
        GENERATED ALWAYS AS (json_extract(json, '$.ourServiceId')));
CREATE TABLE badges(
        id TEXT PRIMARY KEY,
        category TEXT NOT NULL,
        name TEXT NOT NULL,
        descriptionTemplate TEXT NOT NULL
      );
CREATE TABLE badgeImageFiles(
        badgeId TEXT REFERENCES badges(id)
          ON DELETE CASCADE
          ON UPDATE CASCADE,
        'order' INTEGER NOT NULL,
        url TEXT NOT NULL,
        localPath TEXT,
        theme TEXT NOT NULL
      );
CREATE TABLE storyReads (
        authorId STRING NOT NULL,
        conversationId STRING NOT NULL,
        storyId STRING NOT NULL,
        storyReadDate NUMBER NOT NULL,
        PRIMARY KEY (authorId, storyId)
      );
CREATE TABLE storyDistributions(
        id STRING PRIMARY KEY NOT NULL,
        name TEXT,
        senderKeyInfoJson STRING
      , deletedAtTimestamp INTEGER, allowsReplies INTEGER, isBlockList INTEGER, storageID STRING, storageVersion INTEGER, storageUnknownFields BLOB, storageNeedsSync INTEGER);
CREATE TABLE storyDistributionMembers(
        listId STRING NOT NULL REFERENCES storyDistributions(id)
          ON DELETE CASCADE
          ON UPDATE CASCADE,
        serviceId STRING NOT NULL,
        PRIMARY KEY (listId, serviceId)
      );
CREATE TABLE uninstalled_sticker_packs (
        id STRING NOT NULL PRIMARY KEY,
        uninstalledAt NUMBER NOT NULL,
        storageID STRING,
        storageVersion NUMBER,
        storageUnknownFields BLOB,
        storageNeedsSync INTEGER NOT NULL
      );
CREATE TABLE groupCallRingCancellations(
        ringId INTEGER PRIMARY KEY,
        createdAt INTEGER NOT NULL
      );
CREATE TABLE IF NOT EXISTS 'messages_fts_data'(id INTEGER PRIMARY KEY, block BLOB);
CREATE TABLE IF NOT EXISTS 'messages_fts_idx'(segid, term, pgno, PRIMARY KEY(segid, term)) WITHOUT ROWID;
CREATE TABLE IF NOT EXISTS 'messages_fts_content'(id INTEGER PRIMARY KEY, c0);
CREATE TABLE IF NOT EXISTS 'messages_fts_docsize'(id INTEGER PRIMARY KEY, sz BLOB);
CREATE TABLE IF NOT EXISTS 'messages_fts_config'(k PRIMARY KEY, v) WITHOUT ROWID;
CREATE TABLE edited_messages(
        messageId STRING REFERENCES messages(id)
          ON DELETE CASCADE,
        sentAt INTEGER,
        readStatus INTEGER
      , conversationId STRING);
CREATE TABLE mentions (
        messageId REFERENCES messages(id) ON DELETE CASCADE,
        mentionAci STRING,
        start INTEGER,
        length INTEGER
      );
CREATE TABLE kyberPreKeys(
        id STRING PRIMARY KEY NOT NULL,
        json TEXT NOT NULL, ourServiceId NUMBER
        GENERATED ALWAYS AS (json_extract(json, '$.ourServiceId')));
CREATE TABLE callsHistory (
        callId TEXT PRIMARY KEY,
        peerId TEXT NOT NULL, -- conversation id (legacy)   uuid   groupId   roomId
        ringerId TEXT DEFAULT NULL, -- ringer uuid
        mode TEXT NOT NULL, -- enum "Direct"   "Group"
        type TEXT NOT NULL, -- enum "Audio"   "Video"   "Group"
        direction TEXT NOT NULL, -- enum "Incoming"   "Outgoing
        -- Direct: enum "Pending"   "Missed"   "Accepted"   "Deleted"
        -- Group: enum "GenericGroupCall"   "OutgoingRing"   "Ringing"   "Joined"   "Missed"   "Declined"   "Accepted"   "Deleted"
        status TEXT NOT NULL,
        timestamp INTEGER NOT NULL,
        UNIQUE (callId, peerId) ON CONFLICT FAIL
      );
[ dropped all indexes to save space in this blog post ]
CREATE TRIGGER messages_on_view_once_update AFTER UPDATE ON messages
      WHEN
        new.body IS NOT NULL AND new.isViewOnce = 1
      BEGIN
        DELETE FROM messages_fts WHERE rowid = old.rowid;
      END;
CREATE TRIGGER messages_on_insert AFTER INSERT ON messages
      WHEN new.isViewOnce IS NOT 1 AND new.storyId IS NULL
      BEGIN
        INSERT INTO messages_fts
          (rowid, body)
        VALUES
          (new.rowid, new.body);
      END;
CREATE TRIGGER messages_on_delete AFTER DELETE ON messages BEGIN
        DELETE FROM messages_fts WHERE rowid = old.rowid;
        DELETE FROM sendLogPayloads WHERE id IN (
          SELECT payloadId FROM sendLogMessageIds
          WHERE messageId = old.id
        );
        DELETE FROM reactions WHERE rowid IN (
          SELECT rowid FROM reactions
          WHERE messageId = old.id
        );
        DELETE FROM storyReads WHERE storyId = old.storyId;
      END;
CREATE VIRTUAL TABLE messages_fts USING fts5(
        body,
        tokenize = 'signal_tokenizer'
      );
CREATE TRIGGER messages_on_update AFTER UPDATE ON messages
      WHEN
        (new.body IS NULL OR old.body IS NOT new.body) AND
         new.isViewOnce IS NOT 1 AND new.storyId IS NULL
      BEGIN
        DELETE FROM messages_fts WHERE rowid = old.rowid;
        INSERT INTO messages_fts
          (rowid, body)
        VALUES
          (new.rowid, new.body);
      END;
CREATE TRIGGER messages_on_insert_insert_mentions AFTER INSERT ON messages
      BEGIN
        INSERT INTO mentions (messageId, mentionAci, start, length)
        
    SELECT messages.id, bodyRanges.value ->> 'mentionAci' as mentionAci,
      bodyRanges.value ->> 'start' as start,
      bodyRanges.value ->> 'length' as length
    FROM messages, json_each(messages.json ->> 'bodyRanges') as bodyRanges
    WHERE bodyRanges.value ->> 'mentionAci' IS NOT NULL
  
        AND messages.id = new.id;
      END;
CREATE TRIGGER messages_on_update_update_mentions AFTER UPDATE ON messages
      BEGIN
        DELETE FROM mentions WHERE messageId = new.id;
        INSERT INTO mentions (messageId, mentionAci, start, length)
        
    SELECT messages.id, bodyRanges.value ->> 'mentionAci' as mentionAci,
      bodyRanges.value ->> 'start' as start,
      bodyRanges.value ->> 'length' as length
    FROM messages, json_each(messages.json ->> 'bodyRanges') as bodyRanges
    WHERE bodyRanges.value ->> 'mentionAci' IS NOT NULL
  
        AND messages.id = new.id;
      END;
sqlite>
Finally I have the tool needed to inspect and process Signal messages that I need, without using the vendor provided client. Now on to transforming it to a more useful format. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

11 November 2023

Gunnar Wolf: There once was a miniDebConf in Uruguay...

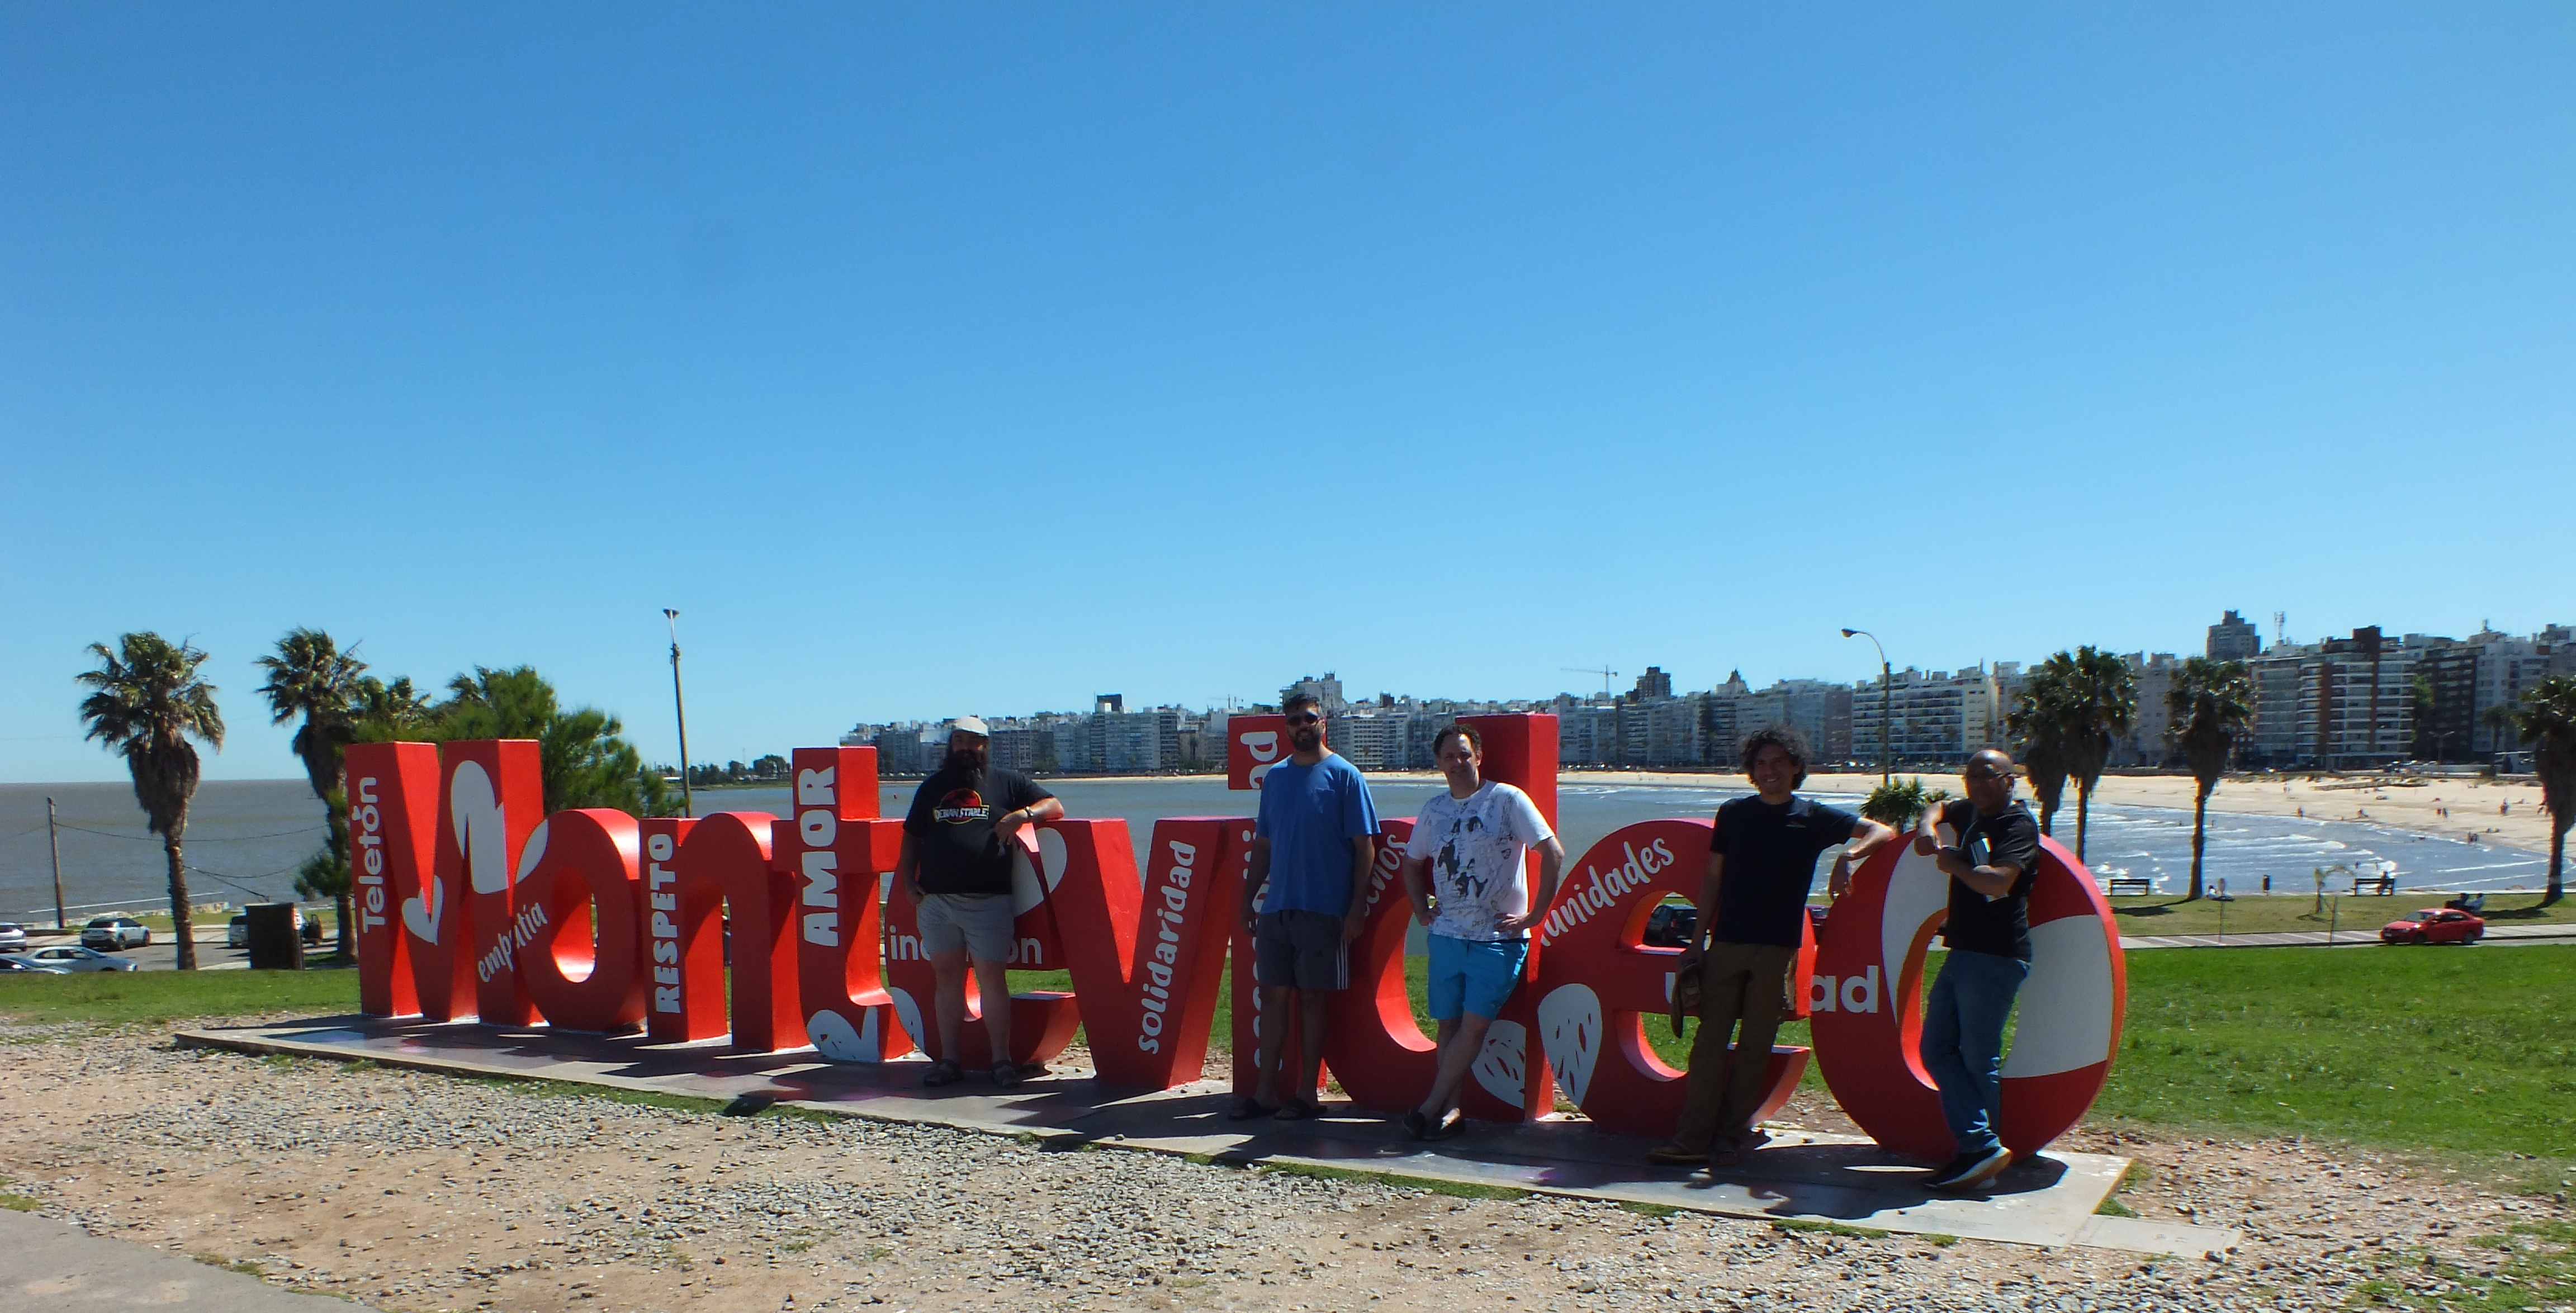
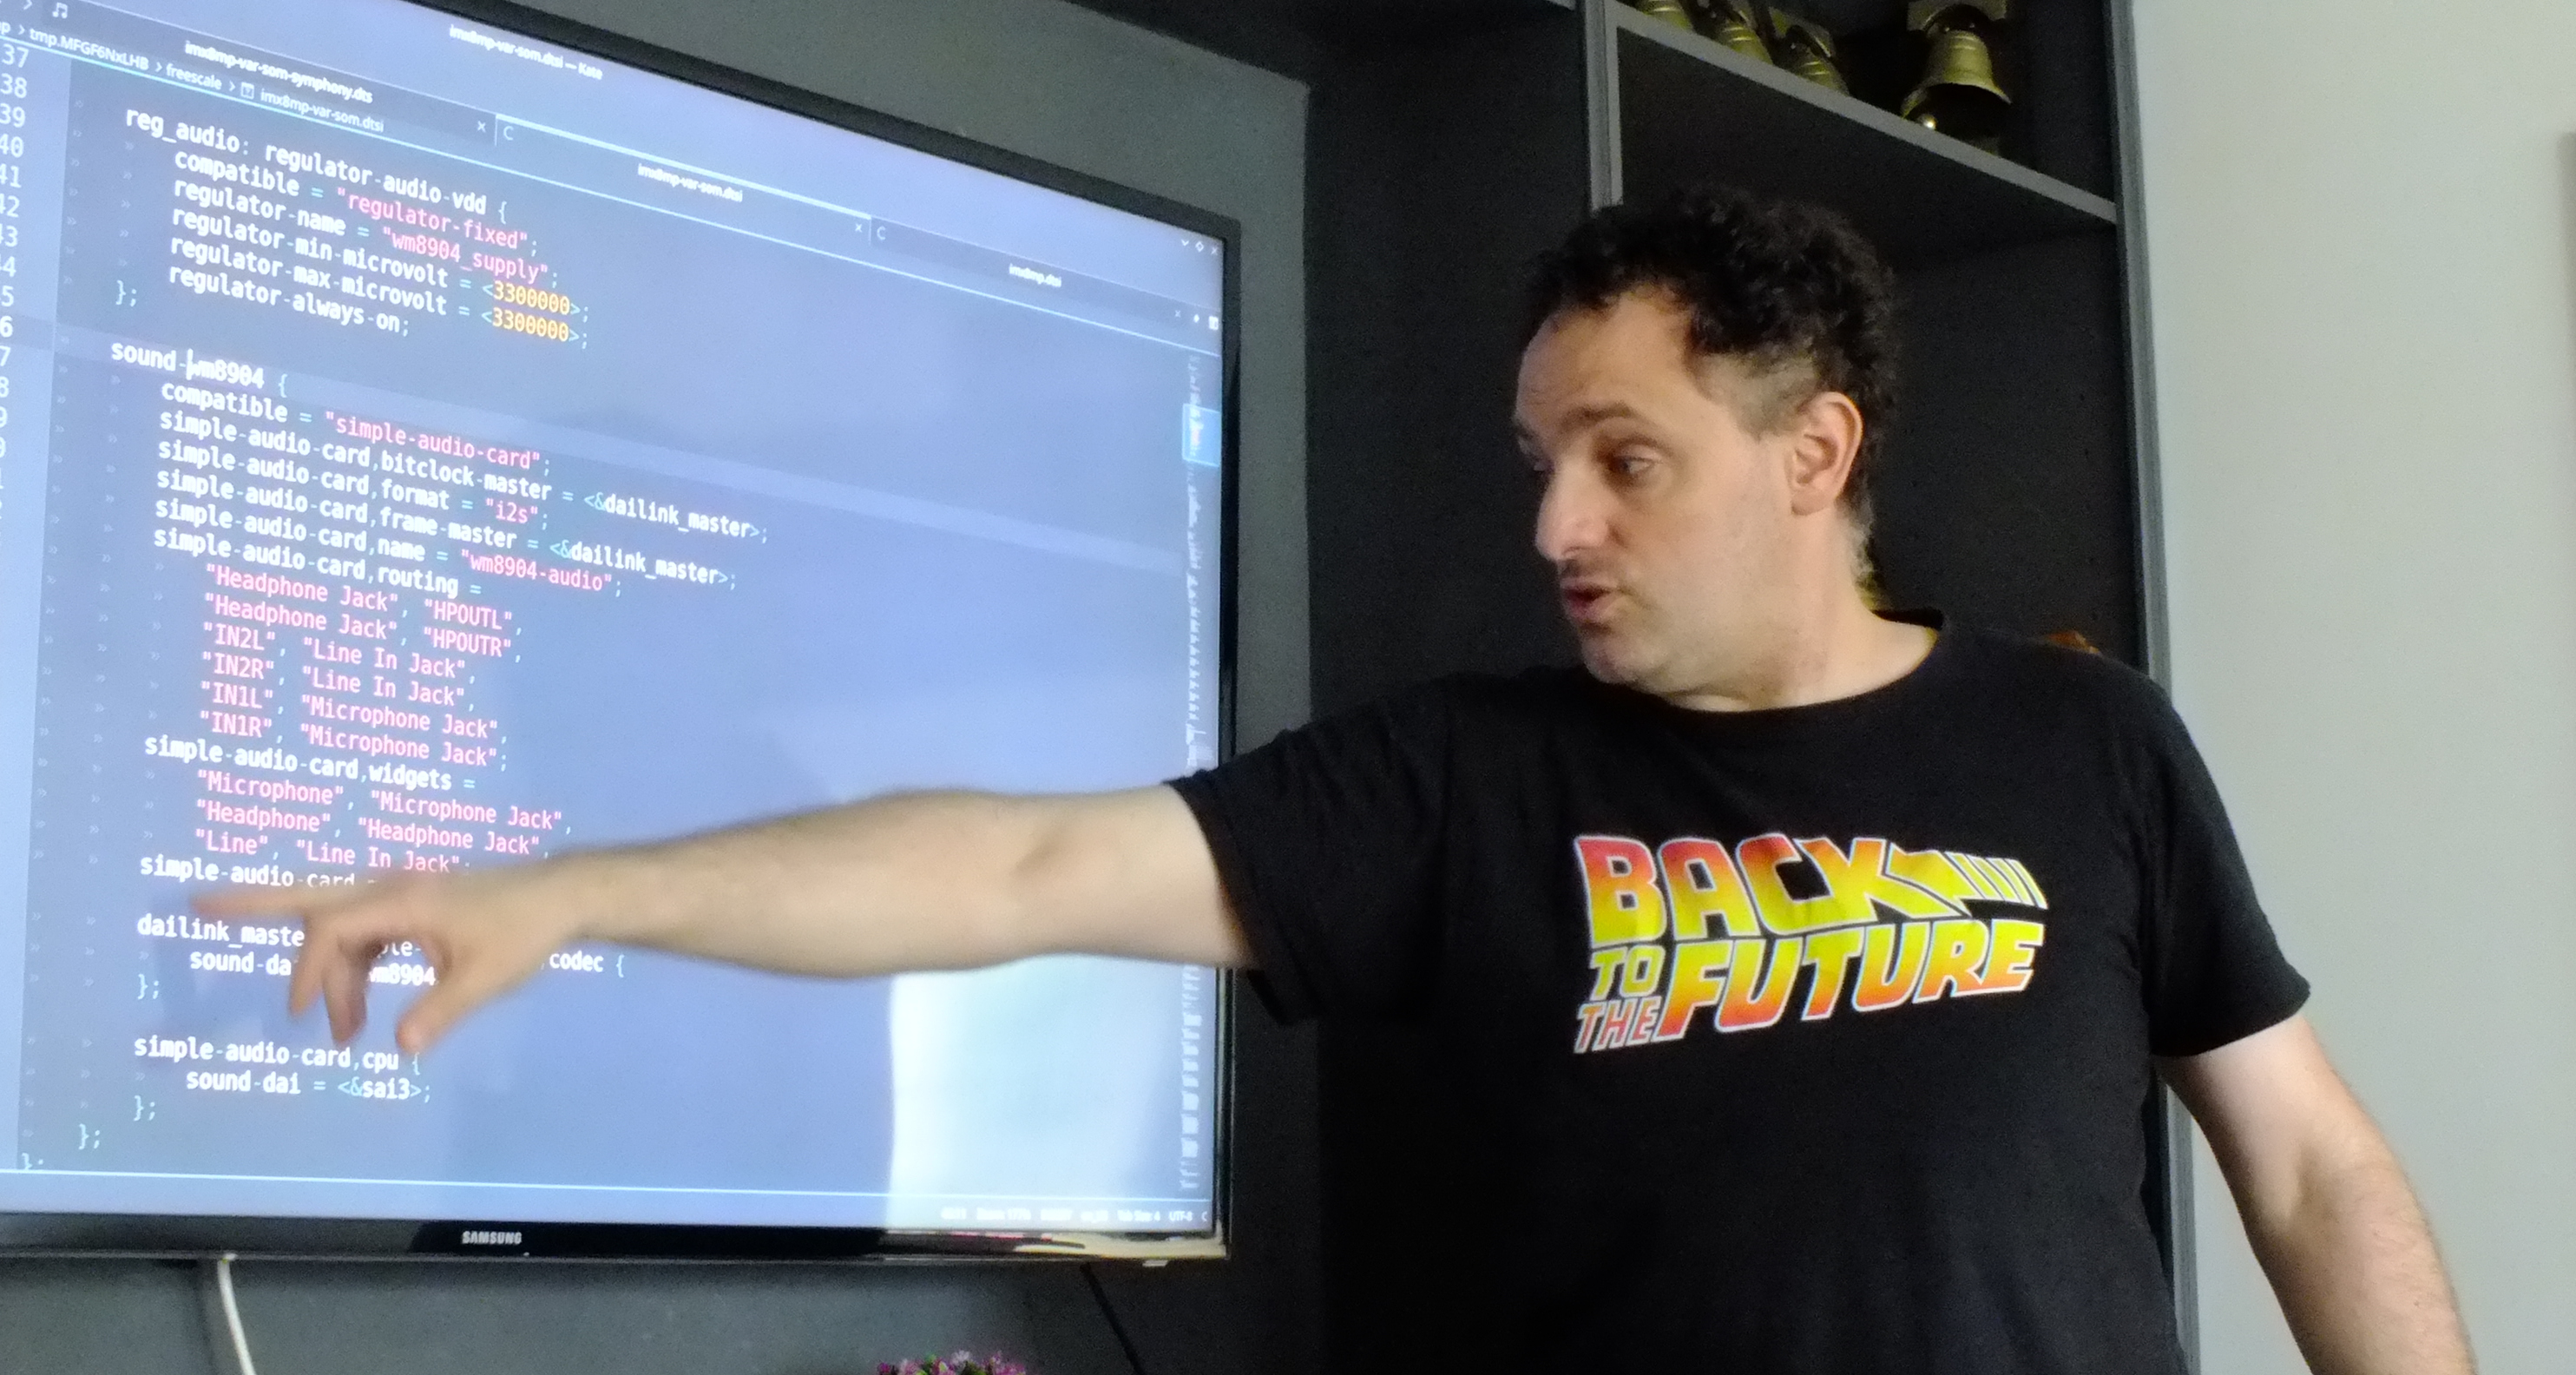
Meeting Debian people for having a good time together, for some good hacking, for learning, for teaching Is always fun and welcome. It brings energy, life and joy. And this year, due to the six-months-long relocation my family and me decided to have to Argentina, I was unable to attend the real deal, DebConf23 at India. And while I know DebConf is an experience like no other, this year I took part in two miniDebConfs. One I have already shared in this same blog: I was in MiniDebConf Tamil Nadu in India, followed by some days of pre-DebConf preparation and scouting in Kochi proper, where I got to interact with the absolutely great and loving team that prepared DebConf. The other one is still ongoing (but close to finishing). Some months ago, I talked with Santiago Ruano, jokin as we were Spanish-speaking DDs announcing to the debian-private mailing list we d be relocating to around R o de la Plata. And things worked out normally: He has been for several months in Uruguay already, so he decided to rent a house for some days, and invite Debian people to do what we do best. I left Paran Tuesday night (and missed my online class at UNAM! Well, you cannot have everything, right?). I arrived early on Wednesday, and around noon came to the house of the keysigning (well, the place is properly called Casa Key , it s a publicity agency that is also rented as a guesthouse in a very nice area of Montevideo, close to Nuevo Pocitos beach). In case you don t know it, Montevideo is on the Northern (or Eastern) shore of R o de la Plata, the widest river in the world (up to 300Km wide, with current and non-salty water). But most important for some Debian contributors: You can even come here by boat! That first evening, we received Ilu, who was in Uruguay by chance for other issues (and we were very happy about it!) and a young and enthusiastic Uruguayan, Felipe, interested in getting involved in Debian. We spent the evening talking about life, the universe and everything Which was a bit tiring, as I had to interface between Spanish and English, talking with two friends that didn t share a common language On Thursday morning, I went out for an early walk at the beach. And lets say, if only just for the narrative, that I found a lost penguin emerging from R o de la Plata! For those that don t know (who d be most of you, as he has not been seen at Debian events for 15 years), that s Lisandro Dami n Nicanor P rez Meyer (or just lisandro), long-time maintainer of the Qt ecosystem, and one of our embedded world extraordinaires. So, after we got him dry and fed him fresh river fishes, he gave us a great impromptu talk about understanding and finding our way around the Device Tree Source files for development boards and similar machines, mostly in the ARM world. From Argentina, we also had Emanuel (eamanu) crossing all the way from La Rioja. I spent most of our first workday getting my laptop in shape to be useful as the driver for my online class on Thursday (which is no small feat people that know the particularities of my much loved ARM-based laptop will understand), and running a set of tests again on my Raspberry Pi labortory, which I had not updated in several months. I am happy to say we are also finally also building Raspberry images for Trixie (Debian 13, Testing)! Sadly, I managed to burn my USB-to-serial-console (UART) adaptor, and could neither test those, nor the oldstable ones we are still building (and will probably soon be dropped, if not for anything else, to save disk space). We enjoyed a lot of socialization time. An important highlight of the conference for me was that we reconnected with a long-lost DD, Eduardo Tr pani, and got him interested in getting involved in the project again! This second day, another local Uruguayan, Mauricio, joined us together with his girlfriend, Alicia, and Felipe came again to hang out with us. Sadly, we didn t get photographic evidence of them (nor the permission to post it). The nice house Santiago got for us was very well equipped for a miniDebConf. There were a couple of rounds of pool played by those that enjoyed it (I was very happy just to stand around, take some photos and enjoy the atmosphere and the conversation). Today (Saturday) is the last full-house day of miniDebConf; tomorrow we will be leaving the house by noon. It was also a very productive day! We had a long, important conversation about an important discussion that we are about to present on debian-vote@lists.debian.org. It has been a great couple of days! Sadly, it s coming to an end But this at least gives me the opportunity (and moral obligation!) to write a long blog post. And to thank Santiago for organizing this, and Debian, for sponsoring our trip, stay, foods and healthy enjoyment!

Reproducible Builds: Reproducible Builds in October 2023

Welcome to the October 2023 report from the Reproducible Builds project. In these reports we outline the most important things that we have been up to over the past month. As a quick recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries.

Reproducible Builds Summit 2023 Between October 31st and November 2nd, we held our seventh Reproducible Builds Summit in Hamburg, Germany! Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort, and this instance was no different. During this enriching event, participants had the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. A number of concrete outcomes from the summit will documented in the report for November 2023 and elsewhere. Amazingly the agenda and all notes from all sessions are already online. The Reproducible Builds team would like to thank our event sponsors who include Mullvad VPN, openSUSE, Debian, Software Freedom Conservancy, Allotropia and Aspiration Tech.

Reflections on Reflections on Trusting Trust Russ Cox posted a fascinating article on his blog prompted by the fortieth anniversary of Ken Thompson s award-winning paper, Reflections on Trusting Trust:
[ ] In March 2023, Ken gave the closing keynote [and] during the Q&A session, someone jokingly asked about the Turing award lecture, specifically can you tell us right now whether you have a backdoor into every copy of gcc and Linux still today?
Although Ken reveals (or at least claims!) that he has no such backdoor, he does admit that he has the actual code which Russ requests and subsequently dissects in great but accessible detail.

Ecosystem factors of reproducible builds Rahul Bajaj, Eduardo Fernandes, Bram Adams and Ahmed E. Hassan from the Maintenance, Construction and Intelligence of Software (MCIS) laboratory within the School of Computing, Queen s University in Ontario, Canada have published a paper on the Time to fix, causes and correlation with external ecosystem factors of unreproducible builds. The authors compare various response times within the Debian and Arch Linux distributions including, for example:
Arch Linux packages become reproducible a median of 30 days quicker when compared to Debian packages, while Debian packages remain reproducible for a median of 68 days longer once fixed.
A full PDF of their paper is available online, as are many other interesting papers on MCIS publication page.

NixOS installation image reproducible On the NixOS Discourse instance, Arnout Engelen (raboof) announced that NixOS have created an independent, bit-for-bit identical rebuilding of the nixos-minimal image that is used to install NixOS. In their post, Arnout details what exactly can be reproduced, and even includes some of the history of this endeavour:
You may remember a 2021 announcement that the minimal ISO was 100% reproducible. While back then we successfully tested that all packages that were needed to build the ISO were individually reproducible, actually rebuilding the ISO still introduced differences. This was due to some remaining problems in the hydra cache and the way the ISO was created. By the time we fixed those, regressions had popped up (notably an upstream problem in Python 3.10), and it isn t until this week that we were back to having everything reproducible and being able to validate the complete chain.
Congratulations to NixOS team for reaching this important milestone! Discussion about this announcement can be found underneath the post itself, as well as on Hacker News.

CPython source tarballs now reproducible Seth Larson published a blog post investigating the reproducibility of the CPython source tarballs. Using diffoscope, reprotest and other tools, Seth documents his work that led to a pull request to make these files reproducible which was merged by ukasz Langa.

New arm64 hardware from Codethink Long-time sponsor of the project, Codethink, have generously replaced our old Moonshot-Slides , which they have generously hosted since 2016 with new KVM-based arm64 hardware. Holger Levsen integrated these new nodes to the Reproducible Builds continuous integration framework.

Community updates On our mailing list during October 2023 there were a number of threads, including:
  • Vagrant Cascadian continued a thread about the implementation details of a snapshot archive server required for reproducing previous builds. [ ]
  • Akihiro Suda shared an update on BuildKit, a toolkit for building Docker container images. Akihiro links to a interesting talk they recently gave at DockerCon titled Reproducible builds with BuildKit for software supply-chain security.
  • Alex Zakharov started a thread discussing and proposing fixes for various tools that create ext4 filesystem images. [ ]
Elsewhere, Pol Dellaiera made a number of improvements to our website, including fixing typos and links [ ][ ], adding a NixOS Flake file [ ] and sorting our publications page by date [ ]. Vagrant Cascadian presented Reproducible Builds All The Way Down at the Open Source Firmware Conference.

Distribution work distro-info is a Debian-oriented tool that can provide information about Debian (and Ubuntu) distributions such as their codenames (eg. bookworm) and so on. This month, Benjamin Drung uploaded a new version of distro-info that added support for the SOURCE_DATE_EPOCH environment variable in order to close bug #1034422. In addition, 8 reviews of packages were added, 74 were updated and 56 were removed this month, all adding to our knowledge about identified issues. Bernhard M. Wiedemann published another monthly report about reproducibility within openSUSE.

Software development The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: In addition, Chris Lamb fixed an issue in diffoscope, where if the equivalent of file -i returns text/plain, fallback to comparing as a text file. This was originally filed as Debian bug #1053668) by Niels Thykier. [ ] This was then uploaded to Debian (and elsewhere) as version 251.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In October, a number of changes were made by Holger Levsen:
  • Debian-related changes:
    • Refine the handling of package blacklisting, such as sending blacklisting notifications to the #debian-reproducible-changes IRC channel. [ ][ ][ ]
    • Install systemd-oomd on all Debian bookworm nodes (re. Debian bug #1052257). [ ]
    • Detect more cases of failures to delete schroots. [ ]
    • Document various bugs in bookworm which are (currently) being manually worked around. [ ]
  • Node-related changes:
    • Integrate the new arm64 machines from Codethink. [ ][ ][ ][ ][ ][ ]
    • Improve various node cleanup routines. [ ][ ][ ][ ]
    • General node maintenance. [ ][ ][ ][ ]
  • Monitoring-related changes:
    • Remove unused Munin monitoring plugins. [ ]
    • Complain less visibly about too many installed kernels. [ ]
  • Misc:
    • Enhance the firewall handling on Jenkins nodes. [ ][ ][ ][ ]
    • Install the fish shell everywhere. [ ]
In addition, Vagrant Cascadian added some packages and configuration for snapshot experiments. [ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

10 November 2023

Scarlett Gately Moore: KDE: Krita 5.2.1 Snap! KDE Gear 23.08.3 Snaps and KDE neon release

Krita 5.2.1
Today https://kde.org/announcements/gear/23.08.3/ ! I have finished all the snaps and have released to stable channel, if the snap you are looking for hasn t arrived yet, there is an MR open and it will be soon! I have finished all the applications in KDE neon and they are available in Unstable and I am snapshotting User edition and they will be available shortly. Krita 5.2.1 Snap is complete and released to stable channel! Enjoy! I fixed some issues with a few of our classic snaps, namely in Wayland sessions by bundling some missing wayland Qt libs. They should no longer go BOOM upon launch. KF6 SDK snap is complete. Next freetime I will work on runtime and launcher. Down to the last part on the akonadi snap build so PIM snaps are coming soon. Personal: As many of you know, I have been out of proper employment for a year now. I had a hopeful project in the works, but it is out of my hands now and the new project holder was only allowed to give me part time and it is still not in stone with further delays. I understand that these things take time and refinement to go through. I have put myself and my family in dire straights with my stubbornness and need to re-evaluate my priorities. I enjoy doing this work very much, but I also need to pay some very over due bills and well life costs money. With that said, I hope to have an interview next week with a local hospital that needs a Linux Administrator. Who knew someone in nowhere Arizona would have a Linux shop! Anyway, I will be going back to my grass roots, network administration is where I started way back in 1996. I will still be around! Just not at the level I am now obviously. I will still be in the project if they allow, I need 2 jobs to clean up this mess I have made for myself. In my spare time I will of course keep up with Debian and KDE neon and Snaps! If you can spare any change to help with my gas for interview and 45 minute commute till I get a paycheck I would be super grateful. Hopefully I won t have to ask for much longer. Thank you so much to everyone that has helped over the last year, it means the world to me. https://gofund.me/b8b69e54

7 November 2023

Melissa Wen: AMD Driver-specific Properties for Color Management on Linux (Part 2)

TL;DR: This blog post explores the color capabilities of AMD hardware and how they are exposed to userspace through driver-specific properties. It discusses the different color blocks in the AMD Display Core Next (DCN) pipeline and their capabilities, such as predefined transfer functions, 1D and 3D lookup tables (LUTs), and color transformation matrices (CTMs). It also highlights the differences in AMD HW blocks for pre and post-blending adjustments, and how these differences are reflected in the available driver-specific properties. Overall, this blog post provides a comprehensive overview of the color capabilities of AMD hardware and how they can be controlled by userspace applications through driver-specific properties. This information is valuable for anyone who wants to develop applications that can take advantage of the AMD color management pipeline. Get a closer look at each hardware block s capabilities, unlock a wealth of knowledge about AMD display hardware, and enhance your understanding of graphics and visual computing. Stay tuned for future developments as we embark on a quest for GPU color capabilities in the ever-evolving realm of rainbow treasures.
Operating Systems can use the power of GPUs to ensure consistent color reproduction across graphics devices. We can use GPU-accelerated color management to manage the diversity of color profiles, do color transformations to convert between High-Dynamic-Range (HDR) and Standard-Dynamic-Range (SDR) content and color enhacements for wide color gamut (WCG). However, to make use of GPU display capabilities, we need an interface between userspace and the kernel display drivers that is currently absent in the Linux/DRM KMS API. In the previous blog post I presented how we are expanding the Linux/DRM color management API to expose specific properties of AMD hardware. Now, I ll guide you to the color features for the Linux/AMD display driver. We embark on a journey through DRM/KMS, AMD Display Manager, and AMD Display Core and delve into the color blocks to uncover the secrets of color manipulation within AMD hardware. Here we ll talk less about the color tools and more about where to find them in the hardware. We resort to driver-specific properties to reach AMD hardware blocks with color capabilities. These blocks display features like predefined transfer functions, color transformation matrices, and 1-dimensional (1D LUT) and 3-dimensional lookup tables (3D LUT). Here, we will understand how these color features are strategically placed into color blocks both before and after blending in Display Pipe and Plane (DPP) and Multiple Pipe/Plane Combined (MPC) blocks. That said, welcome back to the second part of our thrilling journey through AMD s color management realm!

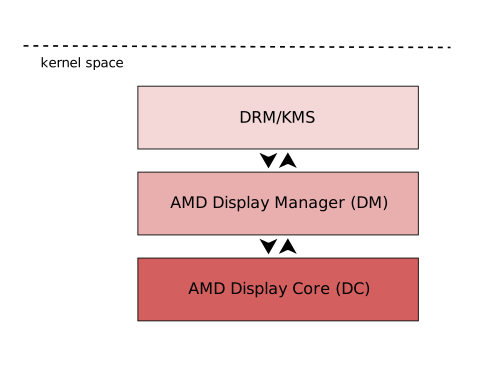
AMD Display Driver in the Linux/DRM Subsystem: The Journey In my 2022 XDC talk I m not an AMD expert, but , I briefly explained the organizational structure of the Linux/AMD display driver where the driver code is bifurcated into a Linux-specific section and a shared-code portion. To reveal AMD s color secrets through the Linux kernel DRM API, our journey led us through these layers of the Linux/AMD display driver s software stack. It includes traversing the DRM/KMS framework, the AMD Display Manager (DM), and the AMD Display Core (DC) [1]. The DRM/KMS framework provides the atomic API for color management through KMS properties represented by struct drm_property. We extended the color management interface exposed to userspace by leveraging existing resources and connecting them with driver-specific functions for managing modeset properties. On the AMD DC layer, the interface with hardware color blocks is established. The AMD DC layer contains OS-agnostic components that are shared across different platforms, making it an invaluable resource. This layer already implements hardware programming and resource management, simplifying the external developer s task. While examining the DC code, we gain insights into the color pipeline and capabilities, even without direct access to specifications. Additionally, AMD developers provide essential support by answering queries and reviewing our work upstream. The primary challenge involved identifying and understanding relevant AMD DC code to configure each color block in the color pipeline. However, the ultimate goal was to bridge the DC color capabilities with the DRM API. For this, we changed the AMD DM, the OS-dependent layer connecting the DC interface to the DRM/KMS framework. We defined and managed driver-specific color properties, facilitated the transport of user space data to the DC, and translated DRM features and settings to the DC interface. Considerations were also made for differences in the color pipeline based on hardware capabilities.
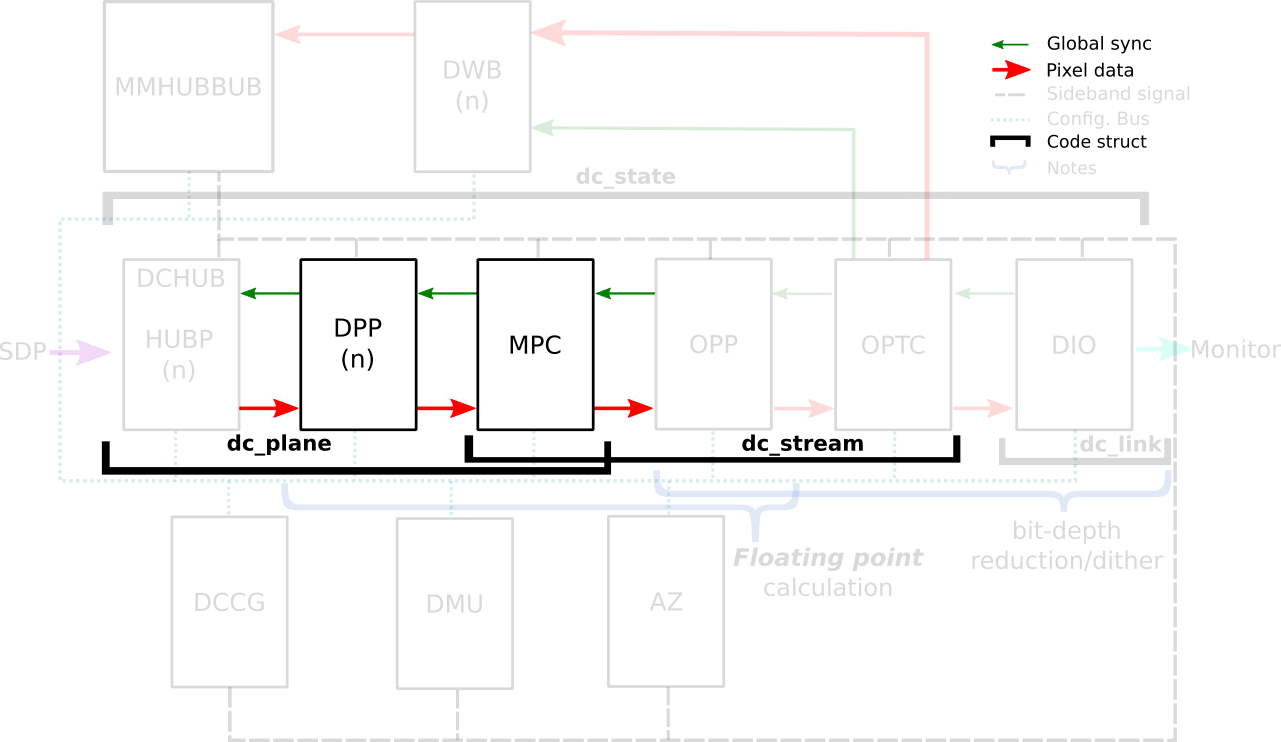
Exploring Color Capabilities of the AMD display hardware Now, let s dive into the exciting realm of AMD color capabilities, where a abundance of techniques and tools await to make your colors look extraordinary across diverse devices. First, we need to know a little about the color transformation and calibration tools and techniques that you can find in different blocks of the AMD hardware. I borrowed some images from [2] [3] [4] to help you understand the information.

Predefined Transfer Functions (Named Fixed Curves): Transfer functions serve as the bridge between the digital and visual worlds, defining the mathematical relationship between digital color values and linear scene/display values and ensuring consistent color reproduction across different devices and media. You can learn more about curves in the chapter GPU Gems 3 - The Importance of Being Linear by Larry Gritz and Eugene d Eon. ITU-R 2100 introduces three main types of transfer functions:
  • OETF: the opto-electronic transfer function, which converts linear scene light into the video signal, typically within a camera.
  • EOTF: electro-optical transfer function, which converts the video signal into the linear light output of the display.
  • OOTF: opto-optical transfer function, which has the role of applying the rendering intent .
AMD s display driver supports the following pre-defined transfer functions (aka named fixed curves):
  • Linear/Unity: linear/identity relationship between pixel value and luminance value;
  • Gamma 2.2, Gamma 2.4, Gamma 2.6: pure power functions;
  • sRGB: 2.4: The piece-wise transfer function from IEC 61966-2-1:1999;
  • BT.709: has a linear segment in the bottom part and then a power function with a 0.45 (~1/2.22) gamma for the rest of the range; standardized by ITU-R BT.709-6;
  • PQ (Perceptual Quantizer): used for HDR display, allows luminance range capability of 0 to 10,000 nits; standardized by SMPTE ST 2084.
These capabilities vary depending on the hardware block, with some utilizing hardcoded curves and others relying on AMD s color module to construct curves from standardized coefficients. It also supports user/custom curves built from a lookup table.

1D LUTs (1-dimensional Lookup Table): A 1D LUT is a versatile tool, defining a one-dimensional color transformation based on a single parameter. It s very well explained by Jeremy Selan at GPU Gems 2 - Chapter 24 Using Lookup Tables to Accelerate Color Transformations It enables adjustments to color, brightness, and contrast, making it ideal for fine-tuning. In the Linux AMD display driver, the atomic API offers a 1D LUT with 4096 entries and 8-bit depth, while legacy gamma uses a size of 256.

3D LUTs (3-dimensional Lookup Table): These tables work in three dimensions red, green, and blue. They re perfect for complex color transformations and adjustments between color channels. It s also more complex to manage and require more computational resources. Jeremy also explains 3D LUT at GPU Gems 2 - Chapter 24 Using Lookup Tables to Accelerate Color Transformations

CTM (Color Transformation Matrices): Color transformation matrices facilitate the transition between different color spaces, playing a crucial role in color space conversion.

HDR Multiplier: HDR multiplier is a factor applied to the color values of an image to increase their overall brightness.

AMD Color Capabilities in the Hardware Pipeline First, let s take a closer look at the AMD Display Core Next hardware pipeline in the Linux kernel documentation for AMDGPU driver - Display Core Next In the AMD Display Core Next hardware pipeline, we encounter two hardware blocks with color capabilities: the Display Pipe and Plane (DPP) and the Multiple Pipe/Plane Combined (MPC). The DPP handles color adjustments per plane before blending, while the MPC engages in post-blending color adjustments. In short, we expect DPP color capabilities to match up with DRM plane properties, and MPC color capabilities to play nice with DRM CRTC properties. Note: here s the catch there are some DRM CRTC color transformations that don t have a corresponding AMD MPC color block, and vice versa. It s like a puzzle, and we re here to solve it!

AMD Color Blocks and Capabilities We can finally talk about the color capabilities of each AMD color block. As it varies based on the generation of hardware, let s take the DCN3+ family as reference. What s possible to do before and after blending depends on hardware capabilities describe in the kernel driver by struct dpp_color_caps and struct mpc_color_caps. The AMD Steam Deck hardware provides a tangible example of these capabilities. Therefore, we take SteamDeck/DCN301 driver as an example and look at the Color pipeline capabilities described in the file: driver/gpu/drm/amd/display/dcn301/dcn301_resources.c
/* Color pipeline capabilities */
dc->caps.color.dpp.dcn_arch = 1; // If it is a Display Core Next (DCN): yes. Zero means DCE.
dc->caps.color.dpp.input_lut_shared = 0;
dc->caps.color.dpp.icsc = 1; // Intput Color Space Conversion  (CSC) matrix.
dc->caps.color.dpp.dgam_ram = 0; // The old degamma block for degamma curve (hardcoded and LUT).  Gamma correction  is the new one.
dc->caps.color.dpp.dgam_rom_caps.srgb = 1; // sRGB hardcoded curve support
dc->caps.color.dpp.dgam_rom_caps.bt2020 = 1; // BT2020 hardcoded curve support (seems not actually in use)
dc->caps.color.dpp.dgam_rom_caps.gamma2_2 = 1; // Gamma 2.2 hardcoded curve support
dc->caps.color.dpp.dgam_rom_caps.pq = 1; // PQ hardcoded curve support
dc->caps.color.dpp.dgam_rom_caps.hlg = 1; // HLG hardcoded curve support
dc->caps.color.dpp.post_csc = 1; // CSC matrix
dc->caps.color.dpp.gamma_corr = 1; // New  Gamma Correction  block for degamma user LUT;
dc->caps.color.dpp.dgam_rom_for_yuv = 0;
dc->caps.color.dpp.hw_3d_lut = 1; // 3D LUT support. If so, it's always preceded by a shaper curve. 
dc->caps.color.dpp.ogam_ram = 1; //  Blend Gamma  block for custom curve just after blending
// no OGAM ROM on DCN301
dc->caps.color.dpp.ogam_rom_caps.srgb = 0;
dc->caps.color.dpp.ogam_rom_caps.bt2020 = 0;
dc->caps.color.dpp.ogam_rom_caps.gamma2_2 = 0;
dc->caps.color.dpp.ogam_rom_caps.pq = 0;
dc->caps.color.dpp.ogam_rom_caps.hlg = 0;
dc->caps.color.dpp.ocsc = 0;
dc->caps.color.mpc.gamut_remap = 1; // Post-blending CTM (pre-blending CTM is always supported)
dc->caps.color.mpc.num_3dluts = pool->base.res_cap->num_mpc_3dlut; // Post-blending 3D LUT (preceded by shaper curve)
dc->caps.color.mpc.ogam_ram = 1; // Post-blending regamma.
// No pre-defined TF supported for regamma.
dc->caps.color.mpc.ogam_rom_caps.srgb = 0;
dc->caps.color.mpc.ogam_rom_caps.bt2020 = 0;
dc->caps.color.mpc.ogam_rom_caps.gamma2_2 = 0;
dc->caps.color.mpc.ogam_rom_caps.pq = 0;
dc->caps.color.mpc.ogam_rom_caps.hlg = 0;
dc->caps.color.mpc.ocsc = 1; // Output CSC matrix.
I included some inline comments in each element of the color caps to quickly describe them, but you can find the same information in the Linux kernel documentation. See more in struct dpp_color_caps, struct mpc_color_caps and struct rom_curve_caps. Now, using this guideline, we go through color capabilities of DPP and MPC blocks and talk more about mapping driver-specific properties to corresponding color blocks.

DPP Color Pipeline: Before Blending (Per Plane) Let s explore the capabilities of DPP blocks and what you can achieve with a color block. The very first thing to pay attention is the display architecture of the display hardware: previously AMD uses a display architecture called DCE
  • Display and Compositing Engine, but newer hardware follows DCN - Display Core Next.
The architectute is described by: dc->caps.color.dpp.dcn_arch

AMD Plane Degamma: TF and 1D LUT Described by: dc->caps.color.dpp.dgam_ram, dc->caps.color.dpp.dgam_rom_caps,dc->caps.color.dpp.gamma_corr AMD Plane Degamma data is mapped to the initial stage of the DPP pipeline. It is utilized to transition from scanout/encoded values to linear values for arithmetic operations. Plane Degamma supports both pre-defined transfer functions and 1D LUTs, depending on the hardware generation. DCN2 and older families handle both types of curve in the Degamma RAM block (dc->caps.color.dpp.dgam_ram); DCN3+ separate hardcoded curves and 1D LUT into two block: Degamma ROM (dc->caps.color.dpp.dgam_rom_caps) and Gamma correction block (dc->caps.color.dpp.gamma_corr), respectively. Pre-defined transfer functions:
  • they are hardcoded curves (read-only memory - ROM);
  • supported curves: sRGB EOTF, BT.709 inverse OETF, PQ EOTF and HLG OETF, Gamma 2.2, Gamma 2.4 and Gamma 2.6 EOTF.
The 1D LUT currently accepts 4096 entries of 8-bit. The data is interpreted as an array of struct drm_color_lut elements. Setting TF = Identity/Default and LUT as NULL means bypass. References:

AMD Plane 3x4 CTM (Color Transformation Matrix) AMD Plane CTM data goes to the DPP Gamut Remap block, supporting a 3x4 fixed point (s31.32) matrix for color space conversions. The data is interpreted as a struct drm_color_ctm_3x4. Setting NULL means bypass. References:

AMD Plane Shaper: TF + 1D LUT Described by: dc->caps.color.dpp.hw_3d_lut The Shaper block fine-tunes color adjustments before applying the 3D LUT, optimizing the use of the limited entries in each dimension of the 3D LUT. On AMD hardware, a 3D LUT always means a preceding shaper 1D LUT used for delinearizing and/or normalizing the color space before applying a 3D LUT, so this entry on DPP color caps dc->caps.color.dpp.hw_3d_lut means support for both shaper 1D LUT and 3D LUT. Pre-defined transfer function enables delinearizing content with or without shaper LUT, where AMD color module calculates the resulted shaper curve. Shaper curves go from linear values to encoded values. If we are already in a non-linear space and/or don t need to normalize values, we can set a Identity TF for shaper that works similar to bypass and is also the default TF value. Pre-defined transfer functions:
  • there is no DPP Shaper ROM. Curves are calculated by AMD color modules. Check calculate_curve() function in the file amd/display/modules/color/color_gamma.c.
  • supported curves: Identity, sRGB inverse EOTF, BT.709 OETF, PQ inverse EOTF, HLG OETF, and Gamma 2.2, Gamma 2.4, Gamma 2.6 inverse EOTF.
The 1D LUT currently accepts 4096 entries of 8-bit. The data is interpreted as an array of struct drm_color_lut elements. When setting Plane Shaper TF (!= Identity) and LUT at the same time, the color module will combine the pre-defined TF and the custom LUT values into the LUT that s actually programmed. Setting TF = Identity/Default and LUT as NULL works as bypass. References:

AMD Plane 3D LUT Described by: dc->caps.color.dpp.hw_3d_lut The 3D LUT in the DPP block facilitates complex color transformations and adjustments. 3D LUT is a three-dimensional array where each element is an RGB triplet. As mentioned before, the dc->caps.color.dpp.hw_3d_lut describe if DPP 3D LUT is supported. The AMD driver-specific property advertise the size of a single dimension via LUT3D_SIZE property. Plane 3D LUT is a blog property where the data is interpreted as an array of struct drm_color_lut elements and the number of entries is LUT3D_SIZE cubic. The array contains samples from the approximated function. Values between samples are estimated by tetrahedral interpolation The array is accessed with three indices, one for each input dimension (color channel), blue being the outermost dimension, red the innermost. This distribution is better visualized when examining the code in [RFC PATCH 5/5] drm/amd/display: Fill 3D LUT from userspace by Alex Hung:
+	for (nib = 0; nib < 17; nib++)  
+		for (nig = 0; nig < 17; nig++)  
+			for (nir = 0; nir < 17; nir++)  
+				ind_lut = 3 * (nib + 17*nig + 289*nir);
+
+				rgb_area[ind].red = rgb_lib[ind_lut + 0];
+				rgb_area[ind].green = rgb_lib[ind_lut + 1];
+				rgb_area[ind].blue = rgb_lib[ind_lut + 2];
+				ind++;
+			 
+		 
+	 
In our driver-specific approach we opted to advertise it s behavior to the userspace instead of implicitly dealing with it in the kernel driver. AMD s hardware supports 3D LUTs with 17-size or 9-size (4913 and 729 entries respectively), and you can choose between 10-bit or 12-bit. In the current driver-specific work we focus on enabling only 17-size 12-bit 3D LUT, as in [PATCH v3 25/32] drm/amd/display: add plane 3D LUT support:
+		/* Stride and bit depth are not programmable by API yet.
+		 * Therefore, only supports 17x17x17 3D LUT (12-bit).
+		 */
+		lut->lut_3d.use_tetrahedral_9 = false;
+		lut->lut_3d.use_12bits = true;
+		lut->state.bits.initialized = 1;
+		__drm_3dlut_to_dc_3dlut(drm_lut, drm_lut3d_size, &lut->lut_3d,
+					lut->lut_3d.use_tetrahedral_9,
+					MAX_COLOR_3DLUT_BITDEPTH);
A refined control of 3D LUT parameters should go through a follow-up version or generic API. Setting 3D LUT to NULL means bypass. References:

AMD Plane Blend/Out Gamma: TF + 1D LUT Described by: dc->caps.color.dpp.ogam_ram The Blend/Out Gamma block applies the final touch-up before blending, allowing users to linearize content after 3D LUT and just before the blending. It supports both 1D LUT and pre-defined TF. We can see Shaper and Blend LUTs as 1D LUTs that are sandwich the 3D LUT. So, if we don t need 3D LUT transformations, we may want to only use Degamma block to linearize and skip Shaper, 3D LUT and Blend. Pre-defined transfer function:
  • there is no DPP Blend ROM. Curves are calculated by AMD color modules;
  • supported curves: Identity, sRGB EOTF, BT.709 inverse OETF, PQ EOTF, HLG inverse OETF, and Gamma 2.2, Gamma 2.4, Gamma 2.6 EOTF.
The 1D LUT currently accepts 4096 entries of 8-bit. The data is interpreted as an array of struct drm_color_lut elements. If plane_blend_tf_property != Identity TF, AMD color module will combine the user LUT values with pre-defined TF into the LUT parameters to be programmed. Setting TF = Identity/Default and LUT to NULL means bypass. References:

MPC Color Pipeline: After Blending (Per CRTC)

DRM CRTC Degamma 1D LUT The degamma lookup table (LUT) for converting framebuffer pixel data before apply the color conversion matrix. The data is interpreted as an array of struct drm_color_lut elements. Setting NULL means bypass. Not really supported. The driver is currently reusing the DPP degamma LUT block (dc->caps.color.dpp.dgam_ram and dc->caps.color.dpp.gamma_corr) for supporting DRM CRTC Degamma LUT, as explaning by [PATCH v3 20/32] drm/amd/display: reject atomic commit if setting both plane and CRTC degamma.

DRM CRTC 3x3 CTM Described by: dc->caps.color.mpc.gamut_remap It sets the current transformation matrix (CTM) apply to pixel data after the lookup through the degamma LUT and before the lookup through the gamma LUT. The data is interpreted as a struct drm_color_ctm. Setting NULL means bypass.

DRM CRTC Gamma 1D LUT + AMD CRTC Gamma TF Described by: dc->caps.color.mpc.ogam_ram After all that, you might still want to convert the content to wire encoding. No worries, in addition to DRM CRTC 1D LUT, we ve got a AMD CRTC gamma transfer function (TF) to make it happen. Possible TF values are defined by enum amdgpu_transfer_function. Pre-defined transfer functions:
  • there is no MPC Gamma ROM. Curves are calculated by AMD color modules.
  • supported curves: Identity, sRGB inverse EOTF, BT.709 OETF, PQ inverse EOTF, HLG OETF, and Gamma 2.2, Gamma 2.4, Gamma 2.6 inverse EOTF.
The 1D LUT currently accepts 4096 entries of 8-bit. The data is interpreted as an array of struct drm_color_lut elements. When setting CRTC Gamma TF (!= Identity) and LUT at the same time, the color module will combine the pre-defined TF and the custom LUT values into the LUT that s actually programmed. Setting TF = Identity/Default and LUT to NULL means bypass. References:

Others

AMD CRTC Shaper and 3D LUT We have previously worked on exposing CRTC shaper and CRTC 3D LUT, but they were removed from the AMD driver-specific color series because they lack userspace case. CRTC shaper and 3D LUT works similar to plane shaper and 3D LUT but after blending (MPC block). The difference here is that setting (not bypass) Shaper and Gamma blocks together are not expected, since both blocks are used to delinearize the input space. In summary, we either set Shaper + 3D LUT or Gamma.

Input and Output Color Space Conversion There are two other color capabilities of AMD display hardware that were integrated to DRM by previous works and worth a brief explanation here. The DC Input CSC sets pre-defined coefficients from the values of DRM plane color_range and color_encoding properties. It is used for color space conversion of the input content. On the other hand, we have de DC Output CSC (OCSC) sets pre-defined coefficients from DRM connector colorspace properties. It is uses for color space conversion of the composed image to the one supported by the sink. References:

The search for rainbow treasures is not over yet If you want to understand a little more about this work, be sure to watch Joshua and I presented two talks at XDC 2023 about AMD/Steam Deck colors on Gamescope: In the time between the first and second part of this blog post, Uma Shashank and Chaitanya Kumar Borah published the plane color pipeline for Intel and Harry Wentland implemented a generic API for DRM based on VKMS support. We discussed these two proposals and the next steps for Color on Linux during the Color Management workshop at XDC 2023 and I briefly shared workshop results in the 2023 XDC lightning talk session. The search for rainbow treasures is not over yet! We plan to meet again next year in the 2024 Display Hackfest in Coru a-Spain (Igalia s HQ) to keep up the pace and continue advancing today s display needs on Linux. Finally, a HUGE thank you to everyone who worked with me on exploring AMD s color capabilities and making them available in userspace.

Matthew Palmer: PostgreSQL Encryption: The Available Options

On an episode of Postgres FM, the hosts had a (very brief) discussion of data encryption in PostgreSQL. While Postgres FM is a podcast well worth a subscribe, the hosts aren t data security experts, and so as someone who builds a queryable database encryption system, I found the coverage to be somewhat lacking. I figured I d provide a more complete survey of the available options for PostgreSQL-related data encryption.

The Status Quo By default, when you install PostgreSQL, there is no data encryption at all. That means that anyone who gets access to any part of the system can read all the data they have access to. This is, of course, not peculiar to PostgreSQL: basically everything works much the same way. What s stopping an attacker from nicking off with all your data is the fact that they can t access the database at all. The things that are acting as protection are perimeter defences, like putting the physical equipment running the server in a secure datacenter, firewalls to prevent internet randos connecting to the database, and strong passwords. This is referred to as tortoise security it s tough on the outside, but soft on the inside. Once that outer shell is cracked, the delicious, delicious data is ripe for the picking, and there s absolutely nothing to stop a miscreant from going to town and making off with everything. It s a good idea to plan your defenses on the assumption you re going to get breached sooner or later. Having good defence-in-depth includes denying the attacker to your data even if they compromise the database. This is where encryption comes in.

Storage-Layer Defences: Disk / Volume Encryption To protect against the compromise of the storage that your database uses (physical disks, EBS volumes, and the like), it s common to employ encryption-at-rest, such as full-disk encryption, or volume encryption. These mechanisms protect against offline attacks, but provide no protection while the system is actually running. And therein lies the rub: your database is always running, so encryption at rest typically doesn t provide much value. If you re running physical systems, disk encryption is essential, but more to prevent accidental data loss, due to things like failing to wipe drives before disposing of them, rather than physical theft. In systems where volume encryption is only a tickbox away, it s also worth enabling, if only to prevent inane questions from your security auditors. Relying solely on storage-layer defences, though, is very unlikely to provide any appreciable value in preventing data loss.

Database-Layer Defences: Transparent Database Encryption If you ve used proprietary database systems in high-security environments, you might have come across Transparent Database Encryption (TDE). There are also a couple of proprietary extensions for PostgreSQL that provide this functionality. TDE is essentially encryption-at-rest implemented inside the database server. As such, it has much the same drawbacks as disk encryption: few real-world attacks are thwarted by it. There is a very small amount of additional protection, in that physical level backups (as produced by pg_basebackup) are protected, but the vast majority of attacks aren t stopped by TDE. Any attacker who can access the database while it s running can just ask for an SQL-level dump of the stored data, and they ll get the unencrypted data quick as you like.

Application-Layer Defences: Field Encryption If you want to take the database out of the threat landscape, you really need to encrypt sensitive data before it even gets near the database. This is the realm of field encryption, more commonly known as application-level encryption. This technique involves encrypting each field of data before it is sent to be stored in the database, and then decrypting it again after it s retrieved from the database. Anyone who gets the data from the database directly, whether via a backup or a direct connection, is out of luck: they can t decrypt the data, and therefore it s worthless. There are, of course, some limitations of this technique. For starters, every ORM and data mapper out there has rolled their own encryption format, meaning that there s basically zero interoperability. This isn t a problem if you build everything that accesses the database using a single framework, but if you ever feel the need to migrate, or use the database from multiple codebases, you re likely in for a rough time. The other big problem of traditional application-level encryption is that, when the database can t understand what data its storing, it can t run queries against that data. So if you want to encrypt, say, your users dates of birth, but you also need to be able to query on that field, you need to choose between one or the other: you can t have both at the same time. You may think to yourself, but this isn t any good, an attacker that breaks into my application can still steal all my data! . That is true, but security is never binary. The name of the game is reducing the attack surface, making it harder for an attacker to succeed. If you leave all the data unencrypted in the database, an attacker can steal all your data by breaking into the database or by breaking into the application. Encrypting the data reduces the attacker s options, and allows you to focus your resources on hardening the application against attack, safe in the knowledge that an attacker who gets into the database directly isn t going to get anything valuable.

Sidenote: The Curious Case of pg_crypto PostgreSQL ships a contrib module called pg_crypto, which provides encryption and decryption functions. This sounds ideal to use for encrypting data within our applications, as it s available no matter what we re using to write our application. It avoids the problem of framework-specific cryptography, because you call the same PostgreSQL functions no matter what language you re using, which produces the same output. However, I don t recommend ever using pg_crypto s data encryption functions, and I doubt you will find many other cryptographic engineers who will, either. First up, and most horrifyingly, it requires you to pass the long-term keys to the database server. If there s an attacker actively in the database server, they can capture the keys as they come in, which means all the data encrypted using that key is exposed. Sending the keys can also result in the keys ending up in query logs, both on the client and server, which is obviously a terrible result. Less scary, but still very concerning, is that pg_crypto s available cryptography is, to put it mildly, antiquated. We have a lot of newer, safer, and faster techniques for data encryption, that aren t available in pg_crypto. This means that if you do use it, you re leaving a lot on the table, and need to have skilled cryptographic engineers on hand to avoid the potential pitfalls. In short: friends don t let friends use pg_crypto.

The Future: Enquo All this brings us to the project I run: Enquo. It takes application-layer encryption to a new level, by providing a language- and framework-agnostic cryptosystem that also enables encrypted data to be efficiently queried by the database. So, you can encrypt your users dates of birth, in such a way that anyone with the appropriate keys can query the database to return, say, all users over the age of 18, but an attacker just sees unintelligible gibberish. This should greatly increase the amount of data that can be encrypted, and as the Enquo project expands its available data types and supported languages, the coverage of encrypted data will grow and grow. My eventual goal is to encrypt all data, all the time. If this appeals to you, visit enquo.org to use or contribute to the open source project, or EnquoDB.com for commercial support and hosted database options.

5 November 2023

Vincent Bernat: Non-interactive SSH password authentication

SSH offers several forms of authentication, such as passwords and public keys. The latter are considered more secure. However, password authentication remains prevalent, particularly with network equipment.1 A classic solution to avoid typing a password for each connection is sshpass, or its more correct variant passh. Here is a wrapper for Zsh, getting the password from pass, a simple password manager:2
pssh()  
  passh -p <(pass show network/ssh/password   head -1) ssh "$@"
 
compdef pssh=ssh
This approach is a bit brittle as it requires to parse the output of the ssh command to look for a password prompt. Moreover, if no password is required, the password manager is still invoked. Since OpenSSH 8.4, we can use SSH_ASKPASS and SSH_ASKPASS_REQUIRE instead:
ssh()  
  set -o localoptions -o localtraps
  local passname=network/ssh/password
  local helper=$(mktemp)
  trap "command rm -f $helper" EXIT INT
  > $helper <<EOF
#!$SHELL
pass show $passname   head -1
EOF
  chmod u+x $helper
  SSH_ASKPASS=$helper SSH_ASKPASS_REQUIRE=force command ssh "$@"
 
If the password is incorrect, we can display a prompt on the second tentative:
ssh()  
  set -o localoptions -o localtraps
  local passname=network/ssh/password
  local helper=$(mktemp)
  trap "command rm -f $helper" EXIT INT
  > $helper <<EOF
#!$SHELL
if [ -k $helper ]; then
   
    oldtty=\$(stty -g)
    trap 'stty \$oldtty < /dev/tty 2> /dev/null' EXIT INT TERM HUP
    stty -echo
    print "\rpassword: "
    read password
    printf "\n"
    > /dev/tty < /dev/tty
  printf "%s" "\$password"
else
  pass show $passname   head -1
  chmod +t $helper
fi
EOF
  chmod u+x $helper
  SSH_ASKPASS=$helper SSH_ASKPASS_REQUIRE=force command ssh "$@"
 
A possible improvement is to use a different password entry depending on the remote host:3
ssh()  
  # Grab login information
  local -A details
  details=($ =$ (M)$ :-"$ (@f)$(command ssh -G "$@" 2>/dev/null) " :#(host hostname user) * )
  local remote=$ details[host]:-details[hostname] 
  local login=$ details[user] @$ remote 
  # Get password name
  local passname
  case "$login" in
    admin@*.example.net)  passname=company1/ssh/admin ;;
    bernat@*.example.net) passname=company1/ssh/bernat ;;
    backup@*.example.net) passname=company1/ssh/backup ;;
  esac
  # No password name? Just use regular SSH
  [[ -z $passname ]] &&  
    command ssh "$@"
    return $?
   
  # Invoke SSH with the helper for SSH_ASKPASS
  # [ ]
 
It is also possible to make scp invoke our custom ssh function:
scp()  
  set -o localoptions -o localtraps
  local helper=$(mktemp)
  trap "command rm -f $helper" EXIT INT
  > $helper <<EOF 
#!$SHELL
source $ (%):-%x 
ssh "\$@"
EOF
  command scp -S $helper "$@"
 
For the complete code, have a look at my zshrc. As an alternative, you can put the ssh() function body into its own script file and replace command ssh with /usr/bin/ssh to avoid an unwanted recursive call. In this case, the scp() function is not needed anymore.

  1. First, some vendors make it difficult to associate an SSH key with a user. Then, many vendors do not support certificate-based authentication, making it difficult to scale. Finally, interactions between public-key authentication and finer-grained authorization methods like TACACS+ and Radius are still uncharted territory.
  2. The clear-text password never appears on the command line, in the environment, or on the disk, making it difficult for a third party without elevated privileges to capture it. On Linux, Zsh provides the password through a file descriptor.
  3. To decipher the fourth line, you may get help from print -l and the zshexpn(1) manual page. details is an associative array defined from an array alternating keys and values.

4 November 2023

Dirk Eddelbuettel: RcppEigen 0.3.3.9.4 on CRAN: Maintenance, Matrix Changes

A new release 0.3.3.9.4 of RcppEigen arrived on CRAN yesterday, and went to Debian today. Eigen is a C++ template library for linear algebra: matrices, vectors, numerical solvers, and related algorithms. This update contains a small amount of the usual maintenance (see below), along with a very nice pull request by Mikael Jagan which simplifies to interface with the Matrix package and inparticular the CHOLMOD library that is part of SuiteSparse. This release is coordinated with lme4 and OpenMx which are also being updated. The complete NEWS file entry follows.

Changes in RcppEigen version 0.3.3.9.4 (2023-11-01)
  • The CITATION file has been updated for the new bibentry style.
  • The package skeleton generator has been updated and no longer sets an Imports:.
  • Some README.md URLs and badged have been updated.
  • The use of -fopenmp has been documented in Makevars, and a simple thread-count reporting function has been added.
  • The old manual src/init.c has been replaced by an autogenerated version, the RcppExports file have regenerated
  • The interface to package Matrix has been updated and simplified thanks to an excllent patch by Mikael Jagan.
  • The new upload is coordinated with packages lme4 and OpenMx.

Courtesy of CRANberries, there is also a diffstat report for the most recent release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 November 2023

Scarlett Gately Moore: KDE: Big fixes for Snaps! Debian and KDE neon updates.

KDE Snap Marble
A big thank you goes to my parents this week for contributing to my survival fund. With that I was able to make a big push on fixing some outstanding issues on some of our snaps.
KDE neon: No major blowups this week. Worked out issues with kmail-account-wizard thanks to David R! This is now in the hands of upstream ( porting not complete ) Worked on more orange -> green packaging fixes. Debian: Fixed bug https://bugs.debian.org/cgi-bin/bugreport.cgi?bug=1054713 in squashfuse Thanks for stopping by. Please help fund my efforts! <noscript><a href="https://liberapay.com/sgmoore/donate"><img alt="Donate using Liberapay" src="https://liberapay.com/assets/widgets/donate.svg" /></a></noscript> Donate https://gofund.me/b8b69e54

2 November 2023

Fran ois Marier: Upgrading from Debian 11 bullseye to 12 bookworm

Over the last few months, I upgraded my Debian machines from bullseye to bookworm. The process was uneventful, but I ended up reconfiguring several things afterwards in order to modernize my upgraded machines.

Logcheck I noticed in this release that the transition to journald is essentially complete. This means that rsyslog is no longer needed on most of my systems:
apt purge rsyslog
Once that was done, I was able to comment out the following lines in /etc/logcheck/logcheck.logfiles.d/syslog.logfiles:
#/var/log/syslog
#/var/log/auth.log
I did have to adjust some of my custom logcheck rules, particularly the ones that deal with kernel messages:
--- a/logcheck/ignore.d.server/local-kernel
+++ b/logcheck/ignore.d.server/local-kernel
@@ -1,1 +1,1 @@
-^\w 3  [ :[:digit:]] 11  [._[:alnum:]-]+ kernel: \[[0-9. ]+]\ IN=eno1 OUT= MAC=[0-9a-f:]+ SRC=[0-9a-f.:]+
+^\w 3  [ :[:digit:]] 11  [._[:alnum:]-]+ kernel: (\[[0-9. ]+]\ )?IN=eno1 OUT= MAC=[0-9a-f:]+ SRC=[0-9a-f.:]+
Then I moved local entries from /etc/logcheck/logcheck.logfiles to /etc/logcheck/logcheck.logfiles.d/local.logfiles (/var/log/syslog and /var/log/auth.log are enabled by default when needed) and removed some files that are no longer used:
rm /var/log/mail.err*
rm /var/log/mail.warn*
rm /var/log/mail.info*
Finally, I had to fix any unescaped characters in my local rules. For example error == NULL \*error == NULL must now be written as error == NULL \ \ \*error == NULL.

Networking After the upgrade, I got a notice that the isc-dhcp-client is now deprecated and so I removed if from my system:
apt purge isc-dhcp-client
This however meant that I need to ensure that my network configuration software does not depend on the now-deprecated DHCP client. On my laptop, I was already using NetworkManager for my main network interfaces and that has built-in DHCP support.

Migration to systemd-networkd On my backup server, I took this opportunity to switch from ifupdown to systemd-networkd by removing ifupdown:
apt purge ifupdown
rm /etc/network/interfaces
putting the following in /etc/systemd/network/20-wired.network:
[Match]
Name=eno1
[Network]
DHCP=yes
MulticastDNS=yes
and then enabling/starting systemd-networkd:
systemctl enable systemd-networkd
systemctl start systemd-networkd
I also needed to install polkit:
apt install --no-install-recommends policykit-1
in order to allow systemd-networkd to set the hostname. In order to start my firewall automatically as interfaces are brought up, I wrote a dispatcher script to apply my existing iptables rules.

Migration to predictacle network interface names On my Linode server, I did the same as on the backup server, but I put the following in /etc/systemd/network/20-wired.network since it has a static IPv6 allocation:
[Match]
Name=enp0s4
[Network]
DHCP=yes
Address=2600:3c01::xxxx:xxxx:xxxx:939f/64
Gateway=fe80::1
and switched to predictable network interface names by deleting these two files:
  • /etc/systemd/network/50-virtio-kernel-names.link
  • /etc/systemd/network/99-default.link
and then changing eth0 to enp0s4 in:
  • /etc/network/iptables.up.rules
  • /etc/network/ip6tables.up.rules
  • /etc/rc.local (for OpenVPN)
  • /etc/logcheck/ignored.d.*/*
Then I regenerated all initramfs:
update-initramfs -u -k all
and rebooted the virtual machine. Giving systemd-resolved control of /etc/resolv.conf After reading this history of DNS resolution on Linux, I decided to modernize my resolv.conf setup and let systemd-resolved handle /etc/resolv.conf. I installed the package:
apt install systemd-resolved
and then removed no-longer-needed packages:
apt purge resolvconf avahi-daemon
I also disabled support for Link-Local Multicast Name Resolution (LLMNR) after reading this person's reasoning by putting the following in /etc/systemd/resolved.conf.d/llmnr.conf:
[Resolve]
LLMNR=no
I verified that mDNS is enabled and LLMNR is disabled:
$ resolvectl mdns
Global: yes
Link 2 (enp0s25): yes
Link 3 (wlp3s0): yes
$ resolvectl llmnr
Global: no
Link 2 (enp0s25): no
Link 3 (wlp3s0): no
Note that if you want auto-discovery of local printers using CUPS, you need to keep avahi-daemon since cups-browsed doesn't support systemd-resolved. You can verify that it works using:
sudo lpinfo --include-schemes dnssd -v

Dynamic DNS I replaced ddclient with inadyn since it doesn't work with no-ip.com anymore, using the configuration I described in an old blog post.

chkrootkit I moved my customizations in /etc/chkrootkit.conf to /etc/chkrootkit/chkrootkit.conf after seeing this message in my logs:
WARNING: /etc/chkrootkit.conf is deprecated. Please put your settings in /etc/chkrootkit/chkrootkit.conf instead: /etc/chkrootkit.conf will be ignored in a future release and should be deleted.

ssh As mentioned in Debian bug#1018106, to silence the following warnings:
sshd[6283]: pam_env(sshd:session): deprecated reading of user environment enabled
I changed the following in /etc/pam.d/sshd:
--- a/pam.d/sshd
+++ b/pam.d/sshd
@@ -44,7 +44,7 @@ session    required     pam_limits.so
 session    required     pam_env.so # [1]
 # In Debian 4.0 (etch), locale-related environment variables were moved to
 # /etc/default/locale, so read that as well.
-session    required     pam_env.so user_readenv=1 envfile=/etc/default/locale
+session    required     pam_env.so envfile=/etc/default/locale
 # SELinux needs to intervene at login time to ensure that the process starts
 # in the proper default security context.  Only sessions which are intended
I also made the following changes to /etc/ssh/sshd_config.d/local.conf based on the advice of ssh-audit 2.9.0:
-KexAlgorithms curve25519-sha256@libssh.org,curve25519-sha256,diffie-hellman-group14-sha256,diffie-hellman-group16-sha512,diffie-hellman-group18-sha512,diffie-hellman-group-exchange-sha256
+KexAlgorithms curve25519-sha256@libssh.org,curve25519-sha256,sntrup761x25519-sha512@openssh.com,diffie-hellman-group16-sha512,diffie-hellman-group18-sha512

1 November 2023

Matthew Garrett: Why ACPI?

"Why does ACPI exist" - - the greatest thread in the history of forums, locked by a moderator after 12,239 pages of heated debate, wait no let me start again.


Why does ACPI exist? In the beforetimes power management on x86 was done by jumping to an opaque BIOS entry point and hoping it would do the right thing. It frequently didn't. We called this Advanced Power Management (Advanced because before this power management involved custom drivers for every machine and everyone agreed that this was a bad idea), and it involved the firmware having to save and restore the state of every piece of hardware in the system. This meant that assumptions about hardware configuration were baked into the firmware - failed to program your graphics card exactly the way the BIOS expected? Hurrah! It's only saved and restored a subset of the state that you configured and now potential data corruption for you. The developers of ACPI made the reasonable decision that, well, maybe since the OS was the one setting state in the first place, the OS should restore it.

So far so good. But some state is fundamentally device specific, at a level that the OS generally ignores. How should this state be managed? One way to do that would be to have the OS know about the device specific details. Unfortunately that means you can't ship the computer without having OS support for it, which means having OS support for every device (exactly what we'd got away from with APM). This, uh, was not an option the PC industry seriously considered. The alternative is that you ship something that abstracts the details of the specific hardware and makes that abstraction available to the OS. This is what ACPI does, and it's also what things like Device Tree do. Both provide static information about how the platform is configured, which can then be consumed by the OS and avoid needing device-specific drivers or configuration to be built-in.

The main distinction between Device Tree and ACPI is that Device Tree is purely a description of the hardware that exists, and so still requires the OS to know what's possible - if you add a new type of power controller, for instance, you need to add a driver for that to the OS before you can express that via Device Tree. ACPI decided to include an interpreted language to allow vendors to expose functionality to the OS without the OS needing to know about the underlying hardware. So, for instance, ACPI allows you to associate a device with a function to power down that device. That function may, when executed, trigger a bunch of register accesses to a piece of hardware otherwise not exposed to the OS, and that hardware may then cut the power rail to the device to power it down entirely. And that can be done without the OS having to know anything about the control hardware.

How is this better than just calling into the firmware to do it? Because the fact that ACPI declares that it's going to access these registers means the OS can figure out that it shouldn't, because it might otherwise collide with what the firmware is doing. With APM we had no visibility into that - if the OS tried to touch the hardware at the same time APM did, boom, almost impossible to debug failures (This is why various hardware monitoring drivers refuse to load by default on Linux - the firmware declares that it's going to touch those registers itself, so Linux decides not to in order to avoid race conditions and potential hardware damage. In many cases the firmware offers a collaborative interface to obtain the same data, and a driver can be written to get that. this bug comment discusses this for a specific board)

Unfortunately ACPI doesn't entirely remove opaque firmware from the equation - ACPI methods can still trigger System Management Mode, which is basically a fancy way to say "Your computer stops running your OS, does something else for a while, and you have no idea what". This has all the same issues that APM did, in that if the hardware isn't in exactly the state the firmware expects, bad things can happen. While historically there were a bunch of ACPI-related issues because the spec didn't define every single possible scenario and also there was no conformance suite (eg, should the interpreter be multi-threaded? Not defined by spec, but influences whether a specific implementation will work or not!), these days overall compatibility is pretty solid and the vast majority of systems work just fine - but we do still have some issues that are largely associated with System Management Mode.

One example is a recent Lenovo one, where the firmware appears to try to poke the NVME drive on resume. There's some indication that this is intended to deal with transparently unlocking self-encrypting drives on resume, but it seems to do so without taking IOMMU configuration into account and so things explode. It's kind of understandable why a vendor would implement something like this, but it's also kind of understandable that doing so without OS cooperation may end badly.

This isn't something that ACPI enabled - in the absence of ACPI firmware vendors would just be doing this unilaterally with even less OS involvement and we'd probably have even more of these issues. Ideally we'd "simply" have hardware that didn't support transitioning back to opaque code, but we don't (ARM has basically the same issue with TrustZone). In the absence of the ideal world, by and large ACPI has been a net improvement in Linux compatibility on x86 systems. It certainly didn't remove the "Everything is Windows" mentality that many vendors have, but it meant we largely only needed to ensure that Linux behaved the same way as Windows in a finite number of ways (ie, the behaviour of the ACPI interpreter) rather than in every single hardware driver, and so the chances that a new machine will work out of the box are much greater than they were in the pre-ACPI period.

There's an alternative universe where we decided to teach the kernel about every piece of hardware it should run on. Fortunately (or, well, unfortunately) we've seen that in the ARM world. Most device-specific simply never reaches mainline, and most users are stuck running ancient kernels as a result. Imagine every x86 device vendor shipping their own kernel optimised for their hardware, and now imagine how well that works out given the quality of their firmware. Does that really seem better to you?

It's understandable why ACPI has a poor reputation. But it's also hard to figure out what would work better in the real world. We could have built something similar on top of Open Firmware instead but the distinction wouldn't be terribly meaningful - we'd just have Forth instead of the ACPI bytecode language. Longing for a non-ACPI world without presenting something that's better and actually stands a reasonable chance of adoption doesn't make the world a better place.

comment count unavailable comments

Paul Wise: FLOSS Activities October 2023

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review
  • Debian wiki: RecentChanges for the month
  • Debian BTS usertags: changes for the month
  • Debian screenshots:

Administration
  • Debian IRC: rescue obsolete/unused #debian-wiki channel
  • Debian servers: rescue data from an old DebConf server
  • Debian wiki: approve accounts

Communication
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors The SWH, golang-ginkgo, DBD-ODBC, sqliteodbc work was sponsored. All other work was done on a volunteer basis.

Dirk Eddelbuettel: RcppArmadillo 0.12.6.6.0 on CRAN: Bugfix, Thread Throttling

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1110 other packages on CRAN, downloaded 31.2 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 563 times according to Google Scholar. This release brings upstream bugfix releases 12.6.5 (sparse matrix corner case) and 12.6.6 with an ARPACK correction. Conrad released it this this morning, I had been running reverse dependency checks anyway and knew we were in good shape so for once I did not await a full run against the now over 1100 (!!) packages using RcppArmadillo. This release also contains a change I prepared on Sunday and which helps with much-criticized (and rightly I may add) insistence by CRAN concerning throttling . The motivation is understandable: CRAN tests many packages at once on beefy servers and can ill afford tests going off and requesting numerous cores. But rather than providing a global setting at their end, CRAN insists that each package (!!) deals with this. The recent traffic on the helpful-as-ever r-pkg-devel mailing clearly shows that this confuses quite a few package developers. Some have admitted to simply turning examples and tests off: a net loss for all of us. Now, Armadillo defaults to using up to eight cores (which is enough to upset CRAN) when running with OpenMP (which is generally only on Linux for reasons I rather not get into ). With this release I expose a helper functions (from OpenMP) to limit this. I also set up an example package and repo RcppArmadilloOpenMPEx detailing this, and added a demonstration of how to use the new throttlers to the fastLm example. I hope this proves useful to users of the package. The set of changes since the last CRAN release follows.

Changes in RcppArmadillo version 0.12.6.6.0 (2023-10-31)
  • Upgraded to Armadillo release 12.6.6 (Cortisol Retox)
    • Fix eigs_sym(), eigs_gen() and svds() to generate deterministic results in ARPACK mode
  • Add helper functions to set and get the number of OpenMP threads
  • Store initial thread count at package load and use in thread-throttling helper (and resetter) suitable for CRAN constraints

Changes in RcppArmadillo version 0.12.6.5.0 (2023-10-14)
  • Upgraded to Armadillo release 12.6.5 (Cortisol Retox)
    • Fix for corner-case bug in handling sparse matrices with no non-zero elements

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

29 October 2023

Aigars Mahinovs: Figuring out finances part 4

At the end of the last part of this, we got a Home Assistant OS installation that contains in itself a Firefly III instance and that contains all the current financial information. Now I will try to connect the two. While it could be nice to create a fully-featured integration for Firefly III to Home Assistant to communicate all interesting values and events, I have an interest on programming a more advanced data point calculation for my budget needs, so a less generic, but more flexible approch is a better one for me. So I was quite interested when among the addons in the Home Assistant Addon Store I saw AppDaemon - a way to simply integrate arbitrary Python processing with Home Assistant. Let's see if that can do what I want. For start, after reading the tutorial , I wanted to create a simple script that would use Firefly III REST API to read the current balance of my main account and then send that to Home Assistant as a sensor value, which then can be displayed on a dashboard. As a quick try I modified the provided hello_world.py that is included in the default AppDaemon installation:
import requests
from datetime import datetime
import appdaemon.plugins.hass.hassapi as hass
app_token = "<FIREFLY_PERSONAL_ACCESS_TOKEN>"
firefly_url = "<FIREFLY_URL>"
class HelloWorld(hass.Hass):
    def initialize(self):
        self.run_every(self.set_asset, "now", 60 * 60)
    def set_asset(self, kwargs):
        ent = self.get_entity("sensor.firefly3_asset_sparkasse_main")
        if not ent.exists():
            ent.add(
                state=0.0,
                attributes= 
                    "native_value": 0.0,
                    "native_unit_of_measurement": "EUR",
                    "state_class": "measurement",
                    "device_class": "monetary",
                    "current_balance_date": datetime.now(),
                 )
        r = requests.get(
            firefly_url + "/api/v1/accounts?type=asset",
            headers= 
                "Authorization": "Bearer " + app_token,
                "Accept": "application/vnd.api+json",
                "Content-Type": "application/json",
         )
        data = r.json()
        for account in data["data"]:
            if not "attributes" in account or "name" not in account["attributes"]:
                continue
            if account["attributes"]["name"] != "Sparkasse giro":
                continue
            self.log("Account :" + str(account["attributes"]))
            ent.set_state(
                state=account["attributes"]["current_balance"],
                attributes= 
                    "native_value": account["attributes"]["current_balance"],
                    "current_balance_date": datetime.fromisoformat(account["attributes"]["current_balance_date"]),
                 )
            self.log("Entity updated")
It uses a URL and personal access token to access Firefly III API, gets the asset accounts information, then extracts info about current balance and balance date of my main account and then creates and/or updates a "sensor" value into Home Assistant. This sensor is with metadata marked as a monetary value and as a measurement. This makes Home Assistant track this value in the database as a graphable changing value. I modified the file using the File Editor addon to edit the /config/appdaemon/apps/hello.py file. Each time the file is saved it is reloaded and logs can be seen in the AppDaemon Logs section - main_log for logging messages or error_log if there is a crash. Useful to know that requests library is included, but it hard to see in the docks what else is included or if there is an easy way to install extra Python packages. This is already a very nice basis for custom value insertion into Home Assistant - whatever you can with a Python script extract or calculate, you can also inject into Home Assistant. With even this simple approach you can monitor balances, budgets, piggy-banks, bill payment status and even sum of transactions in particular catories in a particular time window. Especially interesting data can be found in the insight section of the Firefly III API. The script above uses a trigger like self.run_every(self.set_asset, "now", 60 * 60) to simply run once per hour. The data in Firefly will not be updated too often anyway, at least not until we figure out how to make bank connection run automatically without user interaction and not screw up already existing transactions along the way. In theory a webhook API of the Firefly III could be used to trigger the data update instantly when any transaction is created or updated. Possibly even using Home Assistant webhook integration. Hmmm. Maybe. Who am I kiddind? I am going to make that work, for sure! :D But first - how about figuring out the future? So what I want to do? In short, I want to predict what will be the balance on my main account just before the next months salary comes in. To do this I would:
  • take the current balance of the main account
  • if this months salary is not paid out yet, then add that into the balance
  • deduct all still unpaid bills that are due between now and the target date
  • if the credit card account has not yet been reset to the main account, deduct current amount on the cards
  • if credit card account has been reset, but not from main account deducted yet, deduct the reset amount
To do that I need to use the Firefly API to read: current account info, status of all bills including next due date and amount, transfer transactions between credit cards and main account and something that would store the expected salary date and amount. Ideally I'd use a recurring transaction or a income bill for this, but Firefly is not really cooperating with that. The easiest would be just to hardcode that in the script itself. And this is what I have come up with so far. To make the development process easier, I separated put the params for the API key and salary info and app params for the month to predict for, and predict both this and next months balances at the same time. I edited the script locally with Neovim and also ran it locally with a few mocks, uploading to Home Assistant via the SSH addon when the local executions looked good. So what's next? Well, need to somewhat automate the sync with the bank (if at all possible). And for sure take a regular database and config backup :D

27 October 2023

Scarlett Gately Moore: KDE: KDEneon Plasma Release, Unstable BOOM, Snaps, and Debian

Yang the cat birdYang the cat bird
While Yang our cat tries to lure in unsuspecting birds on the bird feeder, I have been busy working on many things. First things first though, a big thank you to all that donated to my Internet bill. I was able to continue my work without interruption. KDE neon: A busy week in KDE neon as https://kde.org/announcements/plasma/5/5.27.9/ was released! We have it ready to update in User edition or if you would like to download the new ISO you can find it here: https://neon.kde.org/download I highly advise the User Edition as Unstable is volatile right now with Qt6 transition and ABI breakage. Which leads me to the next busy work for the week. Plasma 6 exploded breaking unstable desktops all over, including mine! A library changed and it was not backward compatible, so we had to rebuild the Qt6 $world to get Plasma and PIM functional again. I am happy to report it is all fixed now, but I cannot stress enough, if you don t want to chance broken things, please use the User Edition! I also continued the orange -> green build effort in making sure all our runtime dependencies are up to date. This fixes odd UI bugs and developers have all the build dependencies needed to build their applications. KDE Snaps: Several more 23.08.2 snaps have arrived in the snap store including the new to snaps Kamoso!
KDE snap KamosoKDE snap Kamoso
I have an auto-connect request to the snap-store policy folks, but until it is approved please snap connect kamoso:camera :camera I have a pile of new MR s in for non release service applications and some fixes for issues found while testing. While this new workflow does take a bit longer waiting for approvals I like it much better as I am developing closer relationships with the application developers. I have made significant progress on the Kf6 ( Qt6 based ) content snap. I am about 90% complete. While this doesn t mean much for users yet, it will when KDE applications release their qt6 ports starting the next major release cycle. I will be ready! The last bit for snap work is I have almost completed my akonadi service snap. This will connect to all KDE PIM snaps so they share data. Akonadi is the background database that ties all the PIM applications together. Debian: This week I have worked on updates for several golang packages including charmbracelet/lipgloss charmbracelet/bubbles, and muesli-termenv. unfortunately I am stuck golang-github-aymanbagabas-go-osc52. The work is done in salsa but the maintainer has not uploaded. I have shot an email to the maintainer. I have also begun mentoring my first potential future DD! I reviewed his python-scienceplots and python-art which should land in Debian soon. Thanks for stopping by! As usual, if you can please spare some change, consider a donation. All proceeds go to surviving another day to work on cool things to land on your desktop! https://gofund.me/b8b69e54 <noscript><a href="https://liberapay.com/sgmoore/donate"><img alt="Donate using Liberapay" src="https://liberapay.com/assets/widgets/donate.svg" /></a></noscript> Donate

26 October 2023

Dima Kogan: Talking to ROS from outside a LAN

The problem
This is about ROS version 1. Version 2 is different, and maybe they fixed stuff. But I kinda doubt it since this thing is heinous in a million ways. Alright so let's say we have have some machines in a LAN doing ROS stuff and we have another machine outside the LAN that wants to listen in (like to get a realtime visualization, say). This is an extremely common scenario, but they created enough hoops to make this not work. Let's say we have 3 computers:
  • router: the bridge between the two networks. This has two NICs. The inner IP is 10.0.1.1 and the outer IP is 12.34.56.78
  • inner: a machine in the LAN that's doing ROS stuff. IP 10.0.1.99
  • outer: a machine outside that LAN that wants to listen in. IP 12.34.56.99
Let's say the router is doing ROS stuff. It's running the ROS master and some nodes like this:
ROS_IP=10.0.1.1 roslaunch whatever
If you omit the ROS_IP it'll pick router, which may or may not work, depending on how the DNS is set up. Here we set it to 10.0.1.1 to make it possible for the inner machine to communicate (we'll see why in a bit). An aside: ROS should use the IP by default instead of the name because the IP will work even if the DNS isn't set up. If there are multiple extant IPs, it should throw an error. But all that would be way too user-friendly. OK. So we have a ROS master on 10.0.1.1 on the default port: 11311. The inner machine can rostopic echo and all that. Great. What if I try to listen in from outer? I say
ROS_MASTER_URI=http://12.34.56.78:11311 rostopic list
This connects to the router on that port, and it works well: I get the list of available topics. Here this works because the router is the router. If inner was running the ROS master then we'd need to do a forward for port 11311. In any case, this works and we understand it. So clearly we can talk to the ROS master. Right? Wrong! Let's actually listen in on a specific topic on outer:
ROS_MASTER_URI=http://12.34.56.78:11311 rostopic echo /some/topic
This does not work. No errors are reported. It just sits there, which looks like no data is coming in on that topic. But this is a lie: it's actually broken.

The diagnosis
So this is our problem. It's a very common use case, and there are plenty of internet people asking about it, with no specific solutions. I debugged it, and the details are here. To figure out what's going on, I made a syscall log on a machine inside the LAN, where a simple rostopic echo does work:
sysdig -A proc.name=rostopic and fd.type contains ipv -s 2000
This shows us all the communication between inner running rostopic and the server. It's really chatty. It's all TCP. There are multiple connections to the router on port 11311. It also starts up multiple TCP servers on the client that listen to connections; these are likely to be broken if we were running the client on outer and a machine inside the LAN tried to talk to them; but thankfully in my limited testing nothing actually tried to talk to them. The conversations on port 11311 are really long, but here's the punchline. inner tells the router:
POST /RPC2 HTTP/1.1                                                                                                                 
Host: 10.0.1.1:11311                                                                                                          
Accept-Encoding: gzip                                                                                                               
Content-Type: text/xml                                                                                                              
User-Agent: Python-xmlrpc/3.11                                                                                                      
Content-Length: 390                                                                                                                 
<?xml version='1.0'?>
<methodCall>
<methodName>registerSubscriber</methodName>
<params>
<param>
<value><string>/rostopic_2447878_1698362157834</string></value>
</param>
<param>
<value><string>/some/topic</string></value>
</param>
<param>
<value><string>*</string></value>
</param>
<param>
<value><string>http://inner:38229/</string></value>
</param>
</params>
</methodCall>
Yes. It's laughably chatty. Then the router replies:
HTTP/1.1 200 OK
Server: BaseHTTP/0.6 Python/3.8.10
Date: Thu, 26 Oct 2023 23:15:28 GMT
Content-type: text/xml
Content-length: 342
<?xml version='1.0'?>
<methodResponse>
<params>
<param>
<value><array><data>
<value><int>1</int></value>
<value><string>Subscribed to [/some/topic]</string></value>
<value><array><data>
<value><string>http://10.0.1.1:45517/</string></value>
</data></array></value>
</param>
</params>
</methodResponse>
Then this sequence of system calls happens in the rostopic process (an excerpt from the sysdig log):
> connect fd=10(<4>) addr=10.0.1.1:45517
< connect res=-115(EINPROGRESS) tuple=10.0.1.99:47428->10.0.1.1:45517 fd=10(<4t>10.0.1.99:47428->10.0.1.1:45517)
< getsockopt res=0 fd=10(<4t>10.0.1.99:47428->10.0.1.1:45517) level=1(SOL_SOCKET) optname=4(SO_ERROR) val=0 optlen=4
So the inner client makes an outgoing TCP connection on the address given to it by the ROS master above: 10.0.1.1:45517. This IP is only accessible from within the LAN, which works fine when talking to it from inner, but would be a problem from the outside. Furthermore, some sort of single-port-forwarding scheme wouldn't fix connecting from outer either, since the port number is dynamic. To confirm what we think is happening, the sequence of syscalls when trying to rostopic echo from outer does indeed fail:
connect fd=10(<4>) addr=10.0.1.1:45517 
connect res=-115(EINPROGRESS) tuple=10.0.1.1:46204->10.0.1.1:45517 fd=10(<4t>10.0.1.1:46204->10.0.1.1:45517)
getsockopt res=0 fd=10(<4t>10.0.1.1:46204->10.0.1.1:45517) level=1(SOL_SOCKET) optname=4(SO_ERROR) val=-111(ECONNREFUSED) optlen=4
That's the breakage mechanism: the ROS master asks us to communicate on an address we can't talk to. Debugging this is easy with sysdig:
sudo sysdig -A -s 400 evt.buffer contains '"Subscribed to"' and proc.name=rostopic
This prints out all syscalls seen by the rostopic command that contain the string Subscribed to, so you can see that different addresses the ROS master gives us in response to different commands. OK. So can we get the ROS master to give us an address that we can actually talk to? Sorta. Remember that we invoked the master with
ROS_IP=10.0.1.1 roslaunch whatever
The ROS_IP environment variable is exactly the address that the master gives out. So in this case, we can fix it by doing this instead:
ROS_IP=12.34.56.78 roslaunch whatever
Then the outer machine will be asked to talk to 12.34.56.78:45517, which works. Unfortunately, if we do that, then the inner machine won't be able to communicate. So some sort of ssh port forward cannot fix this: we need a lower-level tunnel, like a VPN or something. And another rant. Here rostopic tried to connect to an unreachable address, which failed. But rostopic knows the connection failed! It should throw an error message to the user. Something like this would be wonderful:
ERROR! Tried to connect to 10.0.1.1:45517 ($ROS_IP:dynamicport), but connect() returned ECONNREFUSED
That would be immensely helpful. It would tell the user that something went wrong (instead of no data being sent), and it would give a strong indication of the problem and how to fix it. But that would be asking too much.

The solution
So we need a VPN-like thing. I just tried sshuttle, and it just works. Start the ROS node in the way that makes connections from within the LAN work:
ROS_IP=10.0.1.1 roslaunch whatever
Then on the outer client:
sshuttle -r router 10.0.1.0/24
This connects to the router over ssh and does some hackery to make all connections from outer to 10.0.1.x transparently route into the LAN. On all ports. rostopic echo then works. I haven't done any thorough testing, but hopefully it's reliable and has low overhead; I don't know. I haven't tried it but almost certainly this would work even with the ROS master running on inner. This would be accomplished like this:
  1. Tell ssh how to connect to inner. Dropping this into ~/.ssh/config should do it:
    Host inner
    HostName 10.0.1.99
    ProxyJump router
    
  2. Do the magic thing:
    sshuttle -r inner 10.0.1.0/24
    
I'm sure any other VPN-like thing would work also.

Next.

Previous.