Search Results: "ed"

4 September 2015

Riku Voipio: Migration to Scaleway ARM server

The C1 ServerScaleway started selling ARM based hosted server in April. I've intended to blog about this for a while, since it was time to upgrade from wheezy to jessie was timely, why not switch provider from an X86 based to ARM one at the same time? In many ways scaleway node is opposite to what "Enterprise ARM" people are working on. Each server is based on an oldish ARMv7 Quad-Core Marvell Armada XP, instead of a brand new 64-bit ARMv8 cpu. There is no UEFI, ACPI or any other "industry standards" involved, just a smooth web interface and a command line tool to manage your node(s). And the node is yours, it's not shared with others with virtualization. The picture above is a single node, which is stacked with 911 other nodes into a single rack. This week, the C1 price was dropped to a very reasonable 2.99 per month, or 0.006 per hour. Software runs on hardware, news at 11The performance is more than enough for my needs - shell, email and light web serving. dovecot, postfix, irssi and apache2 are just an apt-get away. Anyone who says you need x86 for Linux servers is forgetting that Linux software is open source, and if not already available, can be compiled to any architecture with little effort. Thus the migration pains were only because I chose to modernize configuration of dovecot and friends. Details of the new setup shall be left for another post.

Guido G nther: Debian work in August 2015

Debian LTS August was the fourth month I contributed to Debian LTS under the Freexian umbrella. In total I spent four hours working on: Besides that I did CVE triaging of 9 CVEs to check if and how they affect oldoldstable security as part of my LTS front desk work. Debconf 15 was a great opportunity to meet some of the other LTS contributors in person and to work on some of my packages: Git-buildpackage git-buildpackage gained buildpackage-rpm based on the work by Markus Lehtonnen and merging of mock support is hopefully around the corner. Debconf had two gbp skill shares hosted by dkg and a BoF by myself. A summary is here. Integration with dgit as (discussed with Ian) looks doable and I have parts of that on my todo list as well. Among other things gbp import-orig gained a --merge-mode option so you can replace the upstream branches verbatim on your packaging branch but keep the contents of the debian/ directory. Libvirt I prepared an update for libvirt in Jessie fixing a crasher bug, QEMU error reporting. apparmor support now works out of the box in Jessie (thanks to intrigeri and Felix Geyer for that). Speaking of apparmor I learned enough at Debconf to use this now by default so we hopefully see less breackage in this area when new libvirt versions hit the archive. The bug count wen't down quiet a bit and we have a new version of virt-manager in unstable now as well. As usual I prepared the RC candidates of libvirt 1.2.19 in experimental and 1.2.19 final is now in unstable.

Julien Danjou: Data validation in Python with voluptuous

Continuing my post series on the tools I use these days in Python, this time I would like to talk about a library I really like, named voluptuous. It's no secret that most of the time, when a program receives data from the outside, it's a big deal to handle it. Indeed, most of the time your program has no guarantee that the stream is valid and that it contains what is expected. The robustness principle says you should be liberal in what you accept, though that is not always a good idea neither. Whatever policy you chose, you need to process those data and implement a policy that will work lax or not. That means that the program need to look into the data received, check that it finds everything it needs, complete what might be missing (e.g. set some default), transform some data, and maybe reject those data in the end.
Data validation The first step is to validate the data, which means checking all the fields are there and all the types are right or understandable (parseable). Voluptuous provides a single interface for all that called a Schema.
>>> from voluptuous import Schema
>>> s = Schema(
... 'q': str,
... 'per_page': int,
... 'page': int,
... )
>>> s( "q": "hello" )
'q': 'hello'
>>> s( "q": "hello", "page": "world" )
voluptuous.MultipleInvalid: expected int for dictionary value @ data['page']
>>> s( "q": "hello", "unknown": "key" )
voluptuous.MultipleInvalid: extra keys not allowed @ data['unknown']

The argument to voluptuous.Schema should be the data structure that you expect. Voluptuous accepts any kind of data structure, so it could also be a simple string or an array of dict of array of integer. You get it. Here it's a dict with a few keys that if present should be validated as certain types. By default, Voluptuous does not raise an error if some keys are missing. However, it is invalid to have extra keys in a dict by default. If you want to allow extra keys, it is possible to specify it.
>>> from voluptuous import Schema
>>> s = Schema( "foo": str , extra=True)
>>> s( "bar": 2 )
"bar": 2

It is also possible to make some keys mandatory.
>>> from voluptuous import Schema, Required
>>> s = Schema( Required("foo"): str )
>>> s( )
voluptuous.MultipleInvalid: required key not provided @ data['foo']

You can create custom data type very easily. Voluptuous data types are actually just functions that are called with one argument, the value, and that should either return the value or raise an Invalid or ValueError exception.
>>> from voluptuous import Schema, Invalid
>>> def StringWithLength5(value):
... if isinstance(value, str) and len(value) == 5:
... return value
... raise Invalid("Not a string with 5 chars")
...
>>> s = Schema(StringWithLength5)
>>> s("hello")
'hello'
>>> s("hello world")
voluptuous.MultipleInvalid: Not a string with 5 chars

Most of the time though, there is no need to create your own data types. Voluptuous provides logical operators that can, combined with a few others provided primitives such as voluptuous.Length or voluptuous.Range, create a large range of validation scheme.
>>> from voluptuous import Schema, Length, All
>>> s = Schema(All(str, Length(min=3, max=5)))
>>> s("hello")
"hello"
>>> s("hello world")
voluptuous.MultipleInvalid: length of value must be at most 5

The voluptuous documentation has a good set of examples that you can check to have a good overview of what you can do. Data transformation
What's important to remember, is that each data type that you use is a function that is called and returns a value, if the value is considered valid. That value returned is what is actually used and returned after the schema validation:
>>> import uuid
>>> from voluptuous import Schema
>>> def UUID(value):
... return uuid.UUID(value)
...
>>> s = Schema( "foo": UUID )
>>> data_converted = s( "foo": "uuid?" )
voluptuous.MultipleInvalid: not a valid value for dictionary value @ data['foo']
>>> data_converted = s( "foo": "8B7BA51C-DFF5-45DD-B28C-6911A2317D1D" )
>>> data_converted
'foo': UUID('8b7ba51c-dff5-45dd-b28c-6911a2317d1d')

By defining a custom UUID function that converts a value to a UUID, the schema converts the string passed in the data to a Python UUID object validating the format at the same time. Note a little trick here: it's not possible to use directly uuid.UUID in the schema, otherwise Voluptuous would check that the data is actually an instance of uuid.UUID:
>>> from voluptuous import Schema
>>> s = Schema( "foo": uuid.UUID )
>>> s( "foo": "8B7BA51C-DFF5-45DD-B28C-6911A2317D1D" )
voluptuous.MultipleInvalid: expected UUID for dictionary value @ data['foo']
>>> s( "foo": uuid.uuid4() )
'foo': UUID('60b6d6c4-e719-47a7-8e2e-b4a4a30631ed')

And that's not what is wanted here. That mechanism is really neat to transform, for example, strings to timestamps.
>>> import datetime
>>> from voluptuous import Schema
>>> def Timestamp(value):
... return datetime.datetime.strptime(value, "%Y-%m-%dT%H:%M:%S")
...
>>> s = Schema( "foo": Timestamp )
>>> s( "foo": '2015-03-03T12:12:12' )
'foo': datetime.datetime(2015, 3, 3, 12, 12, 12)
>>> s( "foo": '2015-03-03T12:12' )
voluptuous.MultipleInvalid: not a valid value for dictionary value @ data['foo']

Recursive schemas So far, Voluptuous has one limitation so far: the ability to have recursive schemas. The simplest way to circumvent it is by using another function as an indirection.
>>> from voluptuous import Schema, Any
>>> def _MySchema(value):
... return MySchema(value)
...
>>> from voluptuous import Any
>>> MySchema = Schema( "foo": Any("bar", _MySchema) )
>>> MySchema( "foo": "foo": "bar" )
'foo': 'foo': 'bar'
>>> MySchema( "foo": "foo": "baz" )
voluptuous.MultipleInvalid: not a valid value for dictionary value @ data['foo']['foo']

Usage in REST API
I started to use Voluptuous to validate data in a the REST API provided by Gnocchi. So far it has been a really good tool, and we've been able to create a complete REST API that is very easy to validate on the server side. I would definitely recommend it for that. It blends with any Web framework easily. One of the upside compared to solution like JSON Schema, is the ability to create or re-use your own custom data types while converting values at validation time. It is also very Pythonic, and extensible it's pretty great to use for all of that. It's also not tied to any serialization format. On the other hand, JSON Schema is language agnostic and is serializable itself as JSON. That makes it easy to be exported and provided to a consumer so it can understand the API and validate the data potentially on its side.

Norbert Preining: How to rename a local OfflineIMAP managed folder

Since quite some time I am using OfflineIMAP to keep my mailbox status from various servers locally available on my machine. I did more or less follow the excellent guide A unix style mail setup, but didn t use folder name translation right from the beginning. So I got stuck with four folders named INBOX: acc1/INBOX, acc2/INBOX, etc. This wouldn t be a big problem, but when using Mutt with the folder sidebar patch (as available in the mutt-patched package in Debian), there is the problem that only the INBOX part is shown. offlineimap So I decided to rename all the local folders to the scheme described in the above guide. At the end I want to have a folder layout as follows:
  Maildir/acc1/acc1
  Maildir/acc1/acc1.folder1
  Maildir/acc1/acc1.folder2
where the acc1 related to the INBOX on the remote account acc1, and the others are folders on the remote end. Unfortunately, renaming is not supported in offlineimap, it would simply download everything again at best! So I checked what needs to be done, and it turned out it is not as complicated as I thought. The necessary steps are: To make this more specific, let us assume I want to reorganize the account acc1 in this way, and there are two folders synced. That is, before we start the Maildir folder contains:
Maildir/acc1/INBOX
Maildir/acc1/folder1
Maildir/acc1/folder2
and we want to achieve that the layout is
Maildir/acc1/acc1
Maildir/acc1/acc1.folder1
Maildir/acc1/acc1.folder2
Due to the fact that both the LocalStatus files and the FolderValidity files are naned in the same way as the folders, the following trivial script does all the necessary renaming for this simple case:
for d in ~/Maildir/acc1 ~/.offlineimap/Account-acc1/LocalStatus ~/.offlineimap/Repository-acc1local/FolderValidity ; do
  mv $d/INBOX $d/acc1
  mv $d/folder1 $d/acc1.folder1
  mv $d/folder2 $d/acc1.folder2
done
Finally, the correct renaming has to be done by adding nametrans rules to the helper script. The functions oimaptransfolder_acc1 and localtransfolder_acc1 as defined in the above tutorial can be used as is, and need only be added to the respective Repository sections in the configuration file. After having done the necessary renaming, what remains is to give it a good test. Best way to do it is with
offlineimap --dry-run -o -a acc1
which runs the syncronization in dry-run mode, so nothing is actually copied, and only once and only for acc1. If during this test run nothing strange appears, like many many emails are deleted on either end, then you are fine. Enjoy.

Sven Hoexter: wildcard SubjectAlternativeNames

After my experiment with a few more SANs then usual, I received the advice that multiple wildcards should in theory work as well. In practise I could not get something like 'DNS: . .sven.stormbind.net' to be accepted by any decent browser. The other obstacle would be to find a CA to sign it for you. As far as I can tell everyone sticks to the wildcard definition given in the CAB BR.
Wildcard Certificate: A Certficiate containing an asterisk (*) in the left-most position of any of the
Subject Fully-Qualified Domain Names contained in the Certificate.
That said I could reduce the number of SANs from 1960 to 90 when I added a wildcard SAN per person. That's also a number small enough for the Internet Explorer to not fail during the handshake. I rejected that option initially because I thought that multiple wildcards on one certificate are not accepted by browsers. In practise it just seems to be a rarely available option provided on the market.

Dirk Eddelbuettel: RcppArmadillo 0.5.500.2.0

armadillo image Once again time for the monthly upstream Armadillo update -- version 5.500.2 was released earlier today by Conrad. And a new and matching RcppArmadillo release 0.5.500.2.0 in already on CRAN and will go to Debian shortly. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. This release contains mostly bug fixes and some internal code refactoring:
Changes in RcppArmadillo version 0.5.500.2.0 (2015-09-03)
  • Upgraded to Armadillo 5.500.2 ("Molotov Cocktail")
    • expanded object constructors and generators to handle size() based specification of dimensions
    • faster handling of submatrix rows
    • faster clamp()
    • fixes for handling sparse matrices
Courtesy of CRANberries, there is also a diffstat report for the most recent CRAN release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 September 2015

Vincent Fourmond: Releases 1.19.1 of Tioga and 0.13.1 of ctioga2

I've just released the versions 1.19.1 of Tioga and 0.13.1 of ctioga2. They both fix installation problems with recent versions of Ruby. Update as usual, though that isn't strictly necessary if you've managed to install them properly.
~ gem update tioga ctioga2

John Goerzen: There s still a chance to save WiFi

You may not know it, but wifi is under assault in the USA due to proposed FCC regulations about modifications to devices with modular radios. In short, it would make it illegal for vendors to sell devices with firmware that users can replace. This is of concern to everyone, because Wifi routers are notoriously buggy and insecure. It is also of special concern to amateur radio hobbyists, due to the use of these devices in the Amateur Radio Service (FCC Part 97). I submitted a comment to the FCC about this, which I am pasting in here. This provides a background and summary of the issues for those that are interested. Here it is: My comment has two parts: one, the impact on the Amateur Radio service; and two, the impact on security. Both pertain primarily to the 802.11 ( Wifi ) services typically operating under Part 15. The Amateur Radio Service (FCC part 97) has long been recognized by the FCC and Congress as important to the nation. Through it, amateurs contribute to scientific knowledge, learn skills that bolster the technological competitiveness of the United States, and save lives through their extensive involvement in disaster response. Certain segments of the 2.4GHz and 5GHz Wifi bands authorized under FCC Part 15 also fall under the frequencies available to licensed amateurs under FCC Part 97 [1]. By scrupulously following the Part 97 regulations, many amateur radio operators are taking devices originally designed for Part 15 use and modifying them for legal use under the Part 97 Amateur Radio Service. Although the uses are varied, much effort is being devoted to fault-tolerant mesh networks that provide high-speed multimedia communications in response to a disaster, even without the presence of any traditional infrastructure or Internet backbone. One such effort [2] causes users to replace the firmware on off-the-shelf Part 15 Wifi devices, reconfiguring them for proper authorized use under Part 97. This project has many vital properties, particularly the self-discovery of routes between nodes and self-healing nature of the mesh network. These features are not typically available in the firmware of normal Part 15 devices. It should also be noted that there is presently no vendor of Wifi devices that operate under Part 97 out of the box. The only route available to amateurs is to take Part 15 devices and modify them for Part 97 use. Amateur radio users of these services have been working for years to make sure they do not cause interference to Part 15 users [3]. One such effort takes advantage of the modular radio features of consumer Wifi gear to enable communication on frequencies that are within the Part 97 allocation, but outside (though adjacent) to the Part 15 allocation. For instance, the chart at [1] identifies frequencies such as 2.397GHz or 5.660GHz that will never cause interference to Part 15 users because they lie entirely outside the Part 15 Wifi allocation. If the FCC prevents the ability of consumers to modify the firmware of these devices, the following negative consequences will necessarily follow: 1) The use of high-speed multimedia or mesh networks in the Amateur Radio service will be sharply curtailed, relegated to only outdated hardware. 2) Interference between the Amateur Radio service which may use higher power or antennas with higher gain and Part 15 users will be expanded, because Amateur Radio service users will no longer be able to intentionally select frequencies that avoid Part 15. 3) The culture of inventiveness surrounding wireless communication will be curtailed in an important way. Besides the impact on the Part 97 Amateur Radio Service, I also wish to comment on the impact to end-user security. There have been a terrible slew of high-profile situations where very popular consumer Wifi devices have had incredible security holes. Vendors have often been unwilling to address these issues [4]. Michael Horowitz maintains a website tracking security bugs in consumer wifi routers [5]. Sadly these bugs are both severe and commonplace. Within just the last month, various popular routers have been found vulnerable to remote hacking [6] and platforms for launching Distributed Denial-of-Service (DDoS) attacks [7]. These impacted multiple models from multiple vendors. To make matters worse, most of these issues should have never happened in the first place, and were largely the result of carelessness or cluelessness on the part of manufacturers. Consumers should not be at the mercy of vendors to fix their own networks, nor should they be required to trust unauditable systems. There are many well-regarded efforts to provide better firmware for Wifi devices, which still keep them operating under Part 15 restrictions. One is OpenWRT [8], which supports a wide variety of devices with a system built upon a solid Linux base. Please keep control of our devices in the hands of consumers and amateurs, for the benefit of all. References: [1] https://en.wikipedia.org/wiki/High-speed_multimedia_radio [2] http://www.broadband-hamnet.org/just-starting-read-this.html [3] http://www.qsl.net/kb9mwr/projects/wireless/modify.html [4] http://www.tomsitpro.com/articles/netgear-routers-security-hole,1-2461.html [5] http://routersecurity.org/bugs.php [6] https://www.kb.cert.org/vuls/id/950576 [7] https://www.stateoftheinternet.com/resources-cloud-security-2015-q2-web-security-report.html [8] https://openwrt.org/

Petter Reinholdtsen: Book cover for the Free Culture book finally done

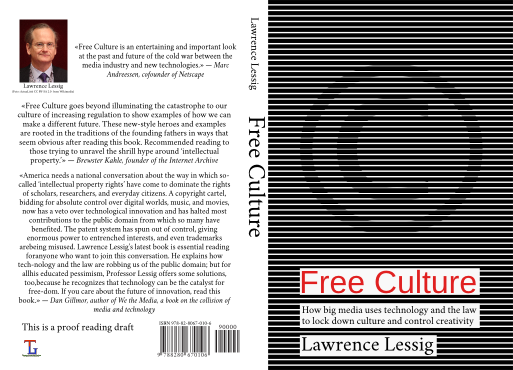
Creating a good looking book cover proved harder than I expected. I wanted to create a cover looking similar to the original cover of the Free Culture book we are translating to Norwegian, and I wanted it in vector format for high resolution printing. But my inkscape knowledge were not nearly good enough to pull that off. But thanks to the great inkscape community, I was able to wrap up the cover yesterday evening. I asked on the #inkscape IRC channel on Freenode for help and clues, and Marc Jeanmougin (Mc-) volunteered to try to recreate it based on the PDF of the cover from the HTML version. Not only did he create a SVG document with the original and his vector version side by side, he even provided an instruction video explaining how he did it. But the instruction video is not easy to follow for an untrained inkscape user. The video is a recording on how he did it, and he is obviously very experienced as the menu selections are very quick and he mentioned on IRC that he did use some keyboard shortcuts that can't be seen on the video, but it give a good idea about the inkscape operations to use to create the stripes with the embossed copyright sign in the center. I took his SVG file, copied the vector image and re-sized it to fit on the cover I was drawing. I am happy with the end result, and the current english version look like this: I am not quite sure about the text on the back, but guess it will do. I picked three quotes from the official site for the book, and hope it will work to trigger the interest of potential readers. The Norwegian cover will look the same, but with the texts and bar code replaced with the Norwegian version. The book is very close to being ready for publication, and I expect to upload the final draft to Lulu in the next few days and order a final proof reading copy to verify that everything look like it should before allowing everyone to order their own copy of Free Culture, in English or Norwegian Bokm l. I'm waiting to give the the productive proof readers a chance to complete their work.

2 September 2015

Luca Falavigna: Resource control with systemd

I m receiving more requests for upload accounts to the Deb-o-Matic servers lately (yay!), but that means the resources need to be monitored and shared between the build daemons to prevent server lockups. My servers are running systemd, so I decided to give systemd.resource-control a try. My goal was to assign lower CPU shares to the build processes (debomatic itself, sbuild, and all the related tools), in order to avoid blocking other important system services from being spawned when necessary. I created a new slice, and set a lower CPU share weight:
$ cat /etc/systemd/system/debomatic.slice
[Slice]
CPUAccounting=true
CPUShares=512
$
Then, I assigned the slice to the service unit file controlling debomatic daemons by adding the Slice=debomatic.slice option under the Service directive. That was not enough, though, as some processes were assigned to the user slice instead, which groups all the processes spawned by users:
systemd-cgls This is probably because schroot spawns a login shell, and systemd considers it belonging to a different process group. So, I had to launch the command systemctl set-property user.slice CPUShares=512, so all processes belonging to the user.slice will receive the same share of the debomatic ones. I consider this a workaround, I m open to suggestions how to properly solve this issue :) I ll try to explore more options in the coming days, so I can improve my knowledge of systemd a little bit more :)

1 September 2015

Enrico Zini: if-you-know-a-browser-developer

If you happen to know a browser developer... Do you happen to know a developer of Firefox or Chrome or some other mainstream browser? If so, can you please talk to them about our experiments with Client Certificate authentication in Debian? Client Certificate authentication rocks; with just a couple of little tweaks in the interface, it would be pretty close to perfect. Visiting sites without using a certificate If I want to browse a site unauthenticated instead of using a certificate, at the moment I can hit "Cancel" on the certificate popup menu, and it works nicely. I feel quite confused when I do that, though, because it's not clear to me if I am canceling use of certificates, or canceling the visit to the site. Can you please change the wording on the Cancel button to something more descriptive? See/change current certificate selection My top wish is, once I choise to use (or not use) a certificate for a site, to be able to see which certificate I'm using and possibly change it. At the moment I did not find a way to see what certificate I'm using, and the browser will remember the choice until it gets closed and reopened. At the moment I can use a Private or Incognito window to switch identities or to stop authenticated access and continue anonymously, and that helps me immensely. I think however that the ultimate solution could be to have the https lockpad popup show an indication of what certificate is currently being used, and offer a way to re-trigger certificate selection. That would be so cool. Also, once the certificate choice can be seen and changed at any time, it could just get remembered so that sites can be visited again without any prompts, even after the browser has been closed and reopened. That would be, to me, the ultimate convenience. Thanks! <3 Thank you very much for all the work you have already put into this: I have been told that a few years ago using client certificate was unthinkable, and now it seems to be down to just a couple of papercuts. And SPKAC/keygen seriously rocks! I have been constantly impressed by how well this all works right now.

Lunar: Reproducible builds: week 18 in Stretch cycle

What happened in the reproducible builds effort this week: Toolchain fixes Aur lien Jarno uploaded glibc/2.21-0experimental1 which will fix the issue were locales-all did not behave exactly like locales despite having it in the Provides field. Lunar rebased the pu/reproducible_builds branch for dpkg on top of the released 1.18.2. This made visible an issue with udebs and automatically generated debug packages. The summary from the meeting at DebConf15 between ftpmasters, dpkg mainatainers and reproducible builds folks has been posted to the revelant mailing lists. Packages fixed The following 70 packages became reproducible due to changes in their build dependencies: activemq-activeio, async-http-client, classworlds, clirr, compress-lzf, dbus-c++, felix-bundlerepository, felix-framework, felix-gogo-command, felix-gogo-runtime, felix-gogo-shell, felix-main, felix-shell-tui, felix-shell, findbugs-bcel, gco, gdebi, gecode, geronimo-ejb-3.2-spec, git-repair, gmetric4j, gs-collections, hawtbuf, hawtdispatch, jack-tools, jackson-dataformat-cbor, jackson-dataformat-yaml, jackson-module-jaxb-annotations, jmxetric, json-simple, kryo-serializers, lhapdf, libccrtp, libclaw, libcommoncpp2, libftdi1, libjboss-marshalling-java, libmimic, libphysfs, libxstream-java, limereg, maven-debian-helper, maven-filtering, maven-invoker, mochiweb, mongo-java-driver, mqtt-client, netty-3.9, openhft-chronicle-queue, openhft-compiler, openhft-lang, pavucontrol, plexus-ant-factory, plexus-archiver, plexus-bsh-factory, plexus-cdc, plexus-classworlds2, plexus-component-metadata, plexus-container-default, plexus-io, pytone, scolasync, sisu-ioc, snappy-java, spatial4j-0.4, tika, treeline, wss4j, xtalk, zshdb. The following packages became reproducible after getting fixed: Some uploads fixed some reproducibility issues but not all of them: Patches submitted which have not made their way to the archive yet: Chris Lamb also noticed that binaries shipped with libsilo-bin did not work. Documentation update Chris Lamb and Ximin Luo assembled a proper specification for SOURCE_DATE_EPOCH in the hope to convince more upstreams to adopt it. Thanks to Holger it is published under a non-Debian domain name. Lunar documented easiest way to solve issues with file ordering and timestamps in tarballs that came with tar/1.28-1. Some examples on how to use SOURCE_DATE_EPOCH have been improved to support systems without GNU date. reproducible.debian.net armhf is finally being tested, which also means the remote building of Debian packages finally works! This paves the way to perform the tests on even more architectures and doing variations on CPU and date. Some packages even produce the same binary Arch:all packages on different architectures (1, 2). (h01ger) Tests for FreeBSD are finally running. (h01ger) As it seems the gcc5 transition has cooled off, we schedule sid more often than testing again on amd64. (h01ger) disorderfs has been built and installed on all build nodes (amd64 and armhf). One issue related to permissions for root and unpriviliged users needs to be solved before disorderfs can be used on reproducible.debian.net. (h01ger) strip-nondeterminism Version 0.011-1 has been released on August 29th. The new version updates dh_strip_nondeterminism to match recent changes in debhelper. (Andrew Ayer) disorderfs disorderfs, the new FUSE filesystem to ease testing of filesystem-related variations, is now almost ready to be used. Version 0.2.0 adds support for extended attributes. Since then Andrew Ayer also added support to reverse directory entries instead of shuffling them, and arbitrary padding to the number of blocks used by files. Package reviews 142 reviews have been removed, 48 added and 259 updated this week. Santiago Vila renamed the not_using_dh_builddeb issue into varying_mtimes_in_data_tar_gz_or_control_tar_gz to align better with other tag names. New issue identified this week: random_order_in_python_doit_completion. 37 FTBFS issues have been reported by Chris West (Faux) and Chris Lamb. Misc. h01ger gave a talk at FrOSCon on August 23rd. Recordings are already online. These reports are being reviewed and enhanced every week by many people hanging out on #debian-reproducible. Huge thanks!

Rapha&#235;l Hertzog: My Free Software Activities in August 2015

My monthly report covers a large part of what I have been doing in the free software world. I write it for my donators (thanks to them!) but also for the wider Debian community because it can give ideas to newcomers and it s one of the best ways to find volunteers to work with me on projects that matter to me. Debian LTS This month I have been paid to work 6.5 hours on Debian LTS. In that time I did the following: Apart from that, I also gave a talk about Debian LTS at DebConf 15 in Heidelberg and also coordinated a work session to discuss our plans for Wheezy. Have a look at the video recordings: DebConf 15 I attended DebConf 15 with great pleasure after having missed DebConf 14 last year. While I did not do lots of work there, I participated in many discussions and I certainly came back with a renewed motivation to work on Debian. That s always good. :-) For the concrete work I did during DebConf, I can only claim two schroot uploads to fix the lack of support of the new overlay filesystem that replaces aufs in the official Debian kernel, and some Distro Tracker work (fixing an issue that some people had when they were logged in via Debian s SSO). While the numerous discussions I had during DebConf can t be qualified as work , they certainly contribute to build up work plans for the future: As a Kali developer, I attended multiple sessions related to derivatives (notably the Debian Derivatives Panel). I was also interested by the Debian in the corporate IT BoF led by Michael Meskes (Credativ s CEO). He pointed out a number of problems that corporate users might have when they first consider using Debian and we will try to do something about this. Expect further news and discussions on the topic. Martin Kraff, Luca Filipozzi, and me had a discussion with the Debian Project Leader (Neil) about how to revive/transform the Debian s Partner program. Nothing is fleshed out yet, but at least the process initiated by the former DPL (Lucas) is again moving forward. Other Debian work Sponsorship. I sponsored an NMU of pep8 by Daniel Stender as it was a requirement for prospector which I also sponsored since all the required dependencies are now available in Debian. \o/ Packaging. I NMUed libxml2 2.9.2+really2.9.1+dfsg1-0.1 fixing 3 security issues and a RC bug that was breaking publican. Since there s no upstream fix for more than 8 months, I went back to the former version 2.9.1. It s in line with the new requirement of release managers a package in unstable should migrate to testing reasonably quickly, it s not acceptable to keep it unfixed for months. With this annoying bug fixed, I could again upload a new upstream release of publican so I prepared and uploaded 4.3.2-1. It was my first source only upload. This release was more work than I expected and I filed no less than 3 bug to upstream (new bash-completion install path, request to provide sources of a minified javascript file, drop a .po file for an invalid language code). GPG issues with smartcard. Back from DebConf, when I wanted to sign some key, I stumbled again upon the problem which makes it impossible for me to use my two smartcards one after the other without first deleting the stubs for the private key. It s not a new issue but I decided that it was time to report it upstream, so I did it: #2079 on bugs.gnupg.org. Some research helped me to find a way to work-around the problem. Later in the month, after a dist-upgrade and a reboot, I was no longer able to use my smartcard as a SSH authentication key again it was already reported but there was no clear analysis, so I tried to do my own one and added the results of my investigation in #795368. It looks like the culprit is pinentry-gnome3 not working when started by the gpg-agent which is started before the DBUS session. Simple fix is to restart the gpg-agent in the session but I have no idea yet of what the proper fix should be (letting systemd manage the graphical user session and start gpg-agent would be my first answer, but that doesn t solve the issue for users of other init systems so it s not satisfying). Distro Tracker. I merged two patches from Orestis Ioannou fixing some bugs tagged newcomer. There are more such bugs (I even filed two: #797096 and #797223), go grab them and do a first contribution to Distro Tracker like Orestis just did! I also merged a change from Christophe Siraut who presented Distro Tracker at DebConf. I implemented in Distro Tracker the new authentication based on SSL client certificates that was recently announced by Enrico Zini. It s working nice, and this authentication scheme is far easier to support. Good job, Enrico! tracker.debian.org broke during DebConf, it stopped being updated with new data. I tracked this down to a problem in the archive (see #796892). Apparently Ansgar Burchardt changed the set of compression tools used on some jessie repositorie, replacing bz2 by xz. He dropped the old Packages.bz2 but missed some Sources.bz2 which were thus stale and APT reported Hashsum mismatch on the uncompressed content. Misc. I pushed some small improvement to my Salt formulas: schroot-formula and sbuild-formula. They will now auto-detect which overlay filesystem is available with the current kernel (previously aufs was hardcoded). Thanks See you next month for a new summary of my activities.
No comment Liked this article? Click here. My blog is Flattr-enabled.

Bits from Debian: New Debian Developers and Maintainers (July and August 2015)

The following contributors got their Debian Developer accounts in the last two months: The following contributors were added as Debian Maintainers in the last two months: Congratulations!

Russ Allbery: Review: Kanban

Review: Kanban, by David J. Anderson
Publisher: Blue Hole
Copyright: 2010
ISBN: 0-9845214-0-2
Format: Trade paperback
Pages: 240
Another belated review, this time of a borrowed book. Which I can now finally return! A delay in the review of this book might be a feature if I had actually used it for, as the subtitle puts it, successful evolutionary change in my technology business. Sadly, I haven't, so it's just late. So, my background: I've done a lot of variations of traditional project management for IT projects (both development and more operational ones), both as a participant and as a project manager. (Although I've never done the latter as a full-time job, and have no desire to do so.) A while back at Stanford, my team adopted Agile, specifically Scrum, so I did a fair bit of research about Scrum including a couple of training courses. Since then, at Dropbox, I've used a few different variations on a vaguely Agile-inspired planning process, although it's not particularly consistent with any one system. I've been hearing about Kanban for a while and have friends who swear by it, but I only had a vague idea of how it worked. That seemed like a good excuse to read a book. And Anderson's book is a good one if, like me, you're looking for a basic introduction. It opens with a basic description and definition, talks about motivation and the expected benefits, and then provides a detailed description of Kanban as a system. The tone is on the theory side, written using the terminology of (I presume) management theory and operations management, areas about which I know almost nothing, but the terminology wasn't so heavy as to make the book hard to read. Anderson goes into lots of detail, and I thought he did a good job of distinguishing between basic principles, optional techniques, and variations that may be appropriate for particular environments. If you're also not familiar, the basic concept of Kanban is to organize work using an in-progress queue. It eschews time-bounded planning entirely in favor of staging work at the start of a sequence of queues and letting the people working on each queue pull from the previous queue when they're ready to take on a new task. As you might guess from that layout, Kanban was originally invented for assembly-line manufacturing (at Toyota). That was one of the problems that I had with it, or at least the presentation in this book: most of my software development doesn't involve finishing one part of something and handing it off to someone else, which made it hard to identify with the pipeline model. Anderson has clearly spent a lot of time working with large-scale programming shops, including outsourced development firms, with dedicated QA and operations roles. This is not at all how Silicon Valley agile development works, so parts of this book felt like missives from a foreign country. That said, the key point of Kanban is not the assembly line but the work limit. One of the defining characteristics of Kanban, at least as Anderson presents it, is that one does not try to estimate work and tile it based on estimates, not even to the extent that Scrum and other Agile methodologies do within the sprint. Instead, each person takes as long as they take on the things they're working on, and pulls a new task when they have free capacity. The system instead puts a limit on how many things they can have in progress at a time. The problem of pipeline stalls is dealt with both via continuous improvement and "swarming" of a problem to unblock the line (since other teams may not be able to work until the block is fixed), and with being careful about the sizing of work items (I'm used to calling them stories) that go in the front end. Predictability, which Scrum uses story sizing and team velocity analysis to try to achieve, is basically statistical. One uses a small number of buckets of sizes of stories, and the whole pipeline will finish some number of work items per unit time, with a variance. The promise made to clients and other teams is that some percentage of the work items will be finished within some time frame from when they enter the system. Most importantly, these are all descriptive properties, determined statistically after the fact, rather than planned properties worked out through story sizing and extensive team discussion. If you, like me, are pretty thoroughly sick of two-hour sprint planning meetings and endless sizing exercises, this is rather appealing. My problem with most work planning systems is that I think they overplan and put too much weight our ability to estimate how long work will take. Kanban is very appealing when viewed through that lens: it gives up on things we're bad at in favor of simple measurement and building a system with enough slack that it can handle work of various different sizes. As mentioned at the top, I haven't had a chance to try it (and I'm not sure it's a good fit with the inter-group planning methods in use at my current workplace), but I came away from this book wanting to do so. If, like me, your experience is mostly with small combined teams or individual programming work, Anderson's examples may seem rather large, rather formal, and bureaucratic. But this is a solid introduction and well worth reading if your only experience with Agile is sprint planning, story writing and sizing, and fast iterations. Rating: 7 out of 10

Norbert Preining: PiwigoPress release 2.31

I just pushed a new release of PiwigoPress (main page, WordPress plugin dir) to the WordPress servers. This release incorporates new features for the sidebar widget, and better interoperability with some Piwigo galleries. piwigopress-logo The new features are: That s all, enjoy, and leave your wishlist items and complains at the issue tracker on the github project piwigopress.

31 August 2015

Junichi Uekawa: I've been writing ELF parser for fun using C++ templates to see how much I can simplify.

I've been writing ELF parser for fun using C++ templates to see how much I can simplify. I've been reading bionic loader code enough these days that I already know how it would look like in C and gradually converted into C++ but it's nevertheless fun to have a pet project that kind of grows.

Matthew Garrett: Working with the kernel keyring

The Linux kernel keyring is effectively a mechanism to allow shoving blobs of data into the kernel and then setting access controls on them. It's convenient for a couple of reasons: the first is that these blobs are available to the kernel itself (so it can use them for things like NFSv4 authentication or module signing keys), and the second is that once they're locked down there's no way for even root to modify them.

But there's a corner case that can be somewhat confusing here, and it's one that I managed to crash into multiple times when I was implementing some code that works with this. Keys can be "possessed" by a process, and have permissions that are granted to the possessor orthogonally to any permissions granted to the user or group that owns the key. This is important because it allows for the creation of keyrings that are only visible to specific processes - if my userspace keyring manager is using the kernel keyring as a backing store for decrypted material, I don't want any arbitrary process running as me to be able to obtain those keys[1]. As described in keyrings(7), keyrings exist at the session, process and thread levels of granularity.

This is absolutely fine in the normal case, but gets confusing when you start using sudo. sudo by default doesn't create a new login session - when you're working with sudo, you're still working with key posession that's tied to the original user. This makes sense when you consider that you often want applications you run with sudo to have access to the keys that you own, but it becomes a pain when you're trying to work with keys that need to be accessible to a user no matter whether that user owns the login session or not.

I spent a while talking to David Howells about this and he explained the easiest way to handle this. If you do something like the following:
$ sudo keyctl add user testkey testdata @u
a new key will be created and added to UID 0's user keyring (indicated by @u). This is possible because the keyring defaults to 0x3f3f0000 permissions, giving both the possessor and the user read/write access to the keyring. But if you then try to do something like:
$ sudo keyctl setperm 678913344 0x3f3f0000
where 678913344 is the ID of the key we created in the previous command, you'll get permission denied. This is because the default permissions on a key are 0x3f010000, meaning that the possessor has permission to do anything to the key but the user only has permission to view its attributes. The cause of this confusion is that although we have permission to write to UID 0's keyring (because the permissions are 0x3f3f0000), we don't possess it - the only permissions we have for this key are the user ones, and the default state for user permissions on new keys only gives us permission to view the attributes, not change them.

But! There's a way around this. If we instead do:
$ sudo keyctl add user testkey testdata @s
then the key is added to the current session keyring (@s). Because the session keyring belongs to us, we possess any keys within it and so we have permission to modify the permissions further. We can then do:
$ sudo keyctl setperm 678913344 0x3f3f0000
and it works. Hurrah! Except that if we log in as root, we'll be part of another session and won't be able to see that key. Boo. So, after setting the permissions, we should:
$ sudo keyctl link 678913344 @u
which ties it to UID 0's user keyring. Someone who logs in as root will then be able to see the key, as will any processes running as root via sudo. But we probably also want to remove it from the unprivileged user's session keyring, because that's readable/writable by the unprivileged user - they'd be able to revoke the key from underneath us!
$ sudo keyctl unlink 678913344 @s
will achieve this, and now the key is configured appropriately - UID 0 can read, modify and delete the key, other users can't.

This is part of our ongoing work at CoreOS to make rkt more secure. Moving the signing keys into the kernel is the first step towards rkt no longer having to trust the local writable filesystem[2]. Once keys have been enrolled the keyring can be locked down - rkt will then refuse to run any images unless they're signed with one of these keys, and even root will be unable to alter them.

[1] (obviously it should also be impossible to ptrace() my userspace keyring manager)
[2] Part of our Secure Boot work has been the integration of dm-verity into CoreOS. Once deployed this will mean that the /usr partition is cryptographically verified by the kernel at runtime, making it impossible for anybody to modify it underneath the kernel. / remains writable in order to permit local configuration and to act as a data store, and right now rkt stores its trusted keys there.

comment count unavailable comments

Mart&iacute;n Ferrari: Romania

It's been over 2 years since I decided to start a new, nomadic life. I had the idea of blogging about this experience as it happened, but not only I am incredibly lazy when it comes to writing, most of the time I have been too busy just enjoying this lifestyle! The TL;DR version of these last 2 years: And now, I am in Cluj-Napoca, Romania.
View from my window
View from my window
2 comments

Mart&iacute;n Ferrari: IkiWiki

I haven't posted in a very long time. Not only because I suck at this, but also because IkiWiki decided to stop working with OpenID, so I can't use the web interface any more to post.. Very annoying. Already spent a good deal of time trying to find a solution, without any success.. I really don't want to migrate to another software again, but this is becoming a showstopper for me. 7 comments

Next.

Previous.