Search Results: "tar"

15 March 2011

Josselin Mouette: Copyright assignment is killing the free in free software

A few weeks ago, at work, we were looking for a solution to a tricky printing problem: how to manage, in a centralized infrastructure, a large number of locations, worstations and printers? One of the consultants working for us came up with a great idea. With only a 20-line patch to CUPS, workstations would be able to find which printers are on the same location. 20 lines of code, instead of a complex virtualisation solution? This is exactly the kind of reasons why we use free software: when there s something wrong, you can fix it. When you need something more, you can code it. Now, many others could benefit of such an improvement, and we don t want to maintain a forked version of CUPS, so we forwarded it upstream, who looked interested. But upstream now being Apple, they requested a stupid copyright assignment agreement. I will leave to the reader s imagination the complexity of getting such a document signed in a Fortune 500 company with no business with Apple. This will, of course, not happen - and if the decision was mine, the answer would have been a clear No. No, because I want to improve free software, not to contribute to Apple s proprietary version. No, because copyleft is about giving as much as you take. How many contributions are being left out of CUPS because of this stupid copyright assignment? It looks to me that such software is doomed to remain crippled as long as companies like Apple are in charge of their maintenance. There is free software. And there is free software by Apple. And Oracle. And Canonical.

Colin Watson: Wubi bug 693671

I spent most of last week working on Ubuntu bug 693671 ("wubi install will not boot - phase 2 stops with: Try (hd0,0): NTFS5"), which was quite a challenge to debug since it involved digging into parts of the Wubi boot process I'd never really touched before. Since I don't think much of this is very well-documented, I'd like to spend a bit of time explaining what was involved, in the hope that it will help other developers in the future. Wubi is a system for installing Ubuntu into a file in a Windows filesystem, so that it doesn't require separate partitions and can be uninstalled like any other Windows application. The purpose of this is to make it easy for Windows users to try out Ubuntu without the need to worry about repartitioning, before they commit to a full installation. Wubi started out as an external project, and initially patched the installer on the fly to do all the rather unconventional things it needed to do; we integrated it into Ubuntu 8.04 LTS, which involved turning these patches into proper installer facilities that could be accessed using preseeding, so that Wubi only needs to handle the Windows user interface and other Windows-specific tasks. Anyone familiar with a GNU/Linux system's boot process will immediately see that this isn't as simple as it sounds. Of course, ntfs-3g is a pretty solid piece of software so we can handle the Windows filesystem without too much trouble, and loopback mounts are well-understood so we can just have the initramfs loop-mount the root filesystem. Where are you going to get the kernel and initramfs from, though? Well, we used to copy them out to the NTFS filesystem so that GRUB could read them, but this was overly complicated and error-prone. When we switched to GRUB 2, we could instead use its built-in loopback facilities, and we were able to simplify this. So all was more or less well, except for the elephant in the room. How are you going to load GRUB? In a Wubi installation, NTLDR (or BOOTMGR in Windows Vista and newer) still owns the boot process. Ubuntu is added as a boot menu option using BCDEdit. You might then think that you can just have the Windows boot loader chain-load GRUB. Unfortunately, NTLDR only loads 16 sectors - 8192 bytes - from disk. GRUB won't fit in that: the smallest core.img you can generate at the moment is over 18 kilobytes. Thus, you need something that is small enough to be loaded by NTLDR, but that is intelligent enough to understand NTFS to the point where it can find a particular file in the root directory of a filesystem, load boot loader code from it, and jump to that. The answer for this was GRUB4DOS. Most of GRUB4DOS is based on GRUB Legacy, which is not of much interest to us any more, but it includes an assembly-language program called GRLDR that supports doing this very thing for FAT, NTFS, and ext2. In Wubi, we build GRLDR as wubildr.mbr, and build a specially-configured GRUB core image as wubildr. Now, the messages shown in the bug report suggested a failure either within GRLDR or very early in GRUB. The first thing I did was to remember that GRLDR has been integrated into the grub-extras ntldr-img module suitable for use with GRUB 2, so I tried building wubildr.mbr from that; no change, but this gave me a modern baseline to work on. OK; now to try QEMU (you can use tricks like qemu -hda /dev/sda if you're very careful not to do anything that might involve writing to the host filesystem from within the guest, such as recursively booting your host OS ... [update: Tollef Fog Heen and Zygmunt Krynicki both point out that you can use the -snapshot option to make this safer]). No go; it hung somewhere in the middle of NTLDR. Still, I could at least insert debug statements, copy the built wubildr.mbr over to my test machine, and reboot for each test, although it would be slow and tedious. Couldn't I? Well, yes, I mostly could, but that 8192-byte limit came back to bite me, along with an internal 2048-byte limit that GRLDR allocates for its NTFS bootstrap code. There were only a few spare bytes. Something like this would more or less fit, to print a single mark character at various points so that I could see how far it was getting:
	pushal
	xorw	%bx, %bx	/* video page 0 */
	movw	$0x0e4d, %ax	/* print 'M' */
	int	$0x10
	popal
In a few places, if I removed some code I didn't need on my test machine (say, CHS compatibility), I could even fit in cheap and nasty code to print a single register in hex (as long as you didn't mind 'A' to 'F' actually being ':' to '?' in ASCII; and note that this is real-mode code, so the loop counter is %cx not %ecx):
	/* print %edx in dumbed-down hex */
	pushal
	xorw	%bx, %bx
	movb	$0xe, %ah
	movw	$8, %cx
1:
	roll	$4, %edx
	movb	%dl, %al
	andb	$0xf, %al
	int	$0x10
	loop	1b
	popal
After a considerable amount of work tracking down problems by bisection like this, I also observed that GRLDR's NTFS code bears quite a bit of resemblance in its logical flow to GRUB 2's NTFS module, and indeed the same person wrote much of both. Since I knew that the latter worked, I could use it to relieve my brain of trying to understand assembly code logic directly, and could compare the two to look for discrepancies. I did find a few of these, and corrected a simple one. Testing at this point suggested that the boot process was getting as far as GRUB but still wasn't printing anything. I removed some Ubuntu patches which quieten down GRUB's startup: still nothing - so I switched my attentions to grub-core/kern/i386/pc/startup.S, which contains the first code executed from GRUB's core image. Code before the first call to real_to_prot (which switches the processor into protected mode) succeeded, while code after that point failed. Even more mysteriously, code added to real_to_prot before the actual switch to protected mode failed too. Now I was clearly getting somewhere interesting, but what was going on? What I really wanted was to be able to single-step, or at least see what was at the memory location it was supposed to be jumping to. Around this point I was venting on IRC, and somebody asked if it was reproducible in QEMU. Although I'd tried that already, I went back and tried again. Ubuntu's qemu is actually built from qemu-kvm, and if I used qemu -no-kvm then it worked much better. Excellent! Now I could use GDB:
(gdb) target remote   qemu -gdb stdio -no-kvm -hda /dev/sda
This let me run until the point when NTLDR was about to hand over control, then interrupt and set a breakpoint at 0x8200 (the entry point of startup.S). This revealed that the address that should have been real_to_prot was in fact garbage. I set a breakpoint at 0x7c00 (GRLDR's entry point) and stepped all the way through to ensure it was doing the right thing. In the process it was helpful to know that GDB and QEMU don't handle real mode very well between them. Useful tricks here were: Single-stepping showed that GRLDR was loading the entirety of wubildr correctly and jumping to it. The first instruction it jumped to wasn't in startup.S, though, and then I remembered that we prefix the core image with grub-core/boot/i386/pc/lnxboot.S. Stepping through this required a clear head since it copies itself around and changes segment registers a few times. The interesting part was at real_code_2, where it copies a sector of the kernel to the target load address, and then checks a known offset to find out whether the "kernel" is in fact GRUB rather than a Linux kernel. I checked that offset by hand, and there was the smoking gun. GRUB recently acquired Reed-Solomon error correction on its core image, to allow it to recover from other software writing over sectors in the boot track. This moved the magic number lnxboot.S was checking somewhat further into the core image, after the first sector. lnxboot.S couldn't find it because it hadn't copied it yet! A bit of adjustment and all was well again. The lesson for me from all of this has been to try hard to get an interactive debugger working. Really hard. It's worth quite a bit of up-front effort if it saves you from killing neurons stepping through pages of code by hand. I think the real-mode debugging tricks I picked up should be useful for working on GRUB in the future.

14 March 2011

Axel Beckert: Planet Commandline officially online

Around the first bunch of postings in my Useful but Unknown Unix Tools, Tobias Klauser of inotail and Symlink fame came up with the idea of making a Planet (i.e. a blog aggregator) of all the comandline blogs and blog categories out there. A first Planet Venus running prototype based on the template and style sheets of Planet Symlink was quickly up and running. I just couldn t decide if I should use an amber or phosphor green style for this new planet. Marius Rieder finally had the right idea to solve this dilemma: Offer both, an amber and a phosphor green style. Christian Herzog pointed me to the right piece of code at A List Apart. So here is it, available in you favourite screen colors:

Planet Commandline For a beginning, the following feeds are included:

Which leads us to the discussion what kind of feeds should be included in Planet Commandline. Of course, all blogs or blog categories which (nearly) solely post neat tips and tricks about the command line in English are welcome. Microblogging feeds containing (only) small but useful command line tips are welcome, too, if they neither permanently contain dozens of posts per day nor have a low signal-to-noise ratio. Unfortunately most identi.ca groups do, so they re not suitable for such a planet. What I m though unsure about are non-English feeds. Yes, there s one in already, but I noticed this only after including Beat s Chr tertee and his FreeBSD command line tips are really good. So if it doesn t go overboard, I think it s ok. If there are too many non-English feeds, I ll probably split Planet Commandline off into at least three Planets: One with all feeds, one with English only and one with all non-English feeds or maybe even one feed per language. But for now that s still a long way off. Another thing I m unsure about are more propgram specific blogs like the impressive Mastering Emacs blog about mastering the world s best text editor . *g* (Yeah, I didn t include that one yet. But as soon someone shows me the vi-equivalent of that blog, I ll include both. Anyone thinks, spf13 s vim category is up to that?) Oh, and sure, any shell-specific (zsh, tcsh, bash, mksh, busybox) tips & tricks blogs don t count as program-specific blogs like some $EDITOR, $BROWSER, or $VCS specific blogs do. :-) Of course I m happy about further suggestions for feeds to include in Planet Commandline. Just remember that the feed should provide (at least nearly) exclusively command line tips, tricks or howtos. Suggestions for links to other commandline related planets are welcome, too.

Gerfried Fuchs: Squeeze RC bugs, #2

Another week, though this one wasn't as fruitful as the last one. My excuse here is that I was overwhelmed with private stuff like acquiring a house and starting with cleaning it up so it can become a home. This is the list for my second week of my stable RC bug squashing: I know three isn't much, and actually it doesn't impact the list of stable RC bugs not much, we are at 172 open RC bugs against squeeze now. I can only attribute it to that new bugs were filed since, because I am aware that I'm not the only one working on this front, I've been contacted by at least two other people in the last week that are investing some time into this, too. Mostly for self-reference, the highest reported squeeze RC bugs in the list is 618295. This should help me to get a number of newly reported issues (ignoring severity-bump in lower bug numbers). Read you next week!

/debian permanent link Comments: 0 Flattr this

Evgeni Golov: Desktop in a shell: newsbeuter

Another week, another post from my desktop in a shell series. This time: newsbeuter, my RSS/Atom/whatever feed-reader of choice.Newsbeuter is a config-and-forget kind of tool. You only have to touch it when you change from a static ~/.newsbeuter/urls to Google Reader or something (like I did some time ago). In the following I will explain both ways (as both are short and it would not fill a whole post then *g*).newsbeuter with a static urls fileFirst you create a ~/.newsbeuter/urls with all your feed URLs (one per line). Then you already can start newsbeuter and it will just work . But you also can customize it (see newsbeuter s online doc) by writing a ~/.newsbeuter/config. Mine was rather short:
 auto-reload yes
 refresh-on-startup yes
 goto-next-feed no
Which means newsbeuter will refresh the feeds every 60 minutes (tuneable via reload-time) and on startup and won t jump to the next feed when pressing n in a feed which has no unread items.Yes, sorry, this is all. Newsbeuter just works ;)newsbeuter with Google ReaderWant to use newsbeuter with your Google Reader account? Add
 urls-source "googlereader"
 googlereader-login "you@gmail.com"
 googlereader-password "password"
to your ~/.newsbeuter/config and it works :)
Most people want to add googlereader-show-special-feeds no as they do not care about Google s suggestions etc.
The only culprit here is than one has to use Google Reader to subscribe to feeds, as newsbeuter does not support this (it s a viewer only).Oh, and here comes the screenshot you waited for:

And no, I do not post my config here, you have to copy-paste it from above, hard, isn t it? :)

Mike Hommey: Avoiding dependencies upon recent libstdc++

Mozilla has been distributing Firefox builds for GNU/Linux systems for a while, and 4.0 should even bring official builds for x86-64 (finally, some would say). The buildbots configuration for these builds uses gcc 4.3.3 to compile the Firefox source code. With the C++ part of gcc, it can sometimes mean side effects when using the C++ STL. Historically, the Mozilla code base hasn t made a great use of the STL, most probably because 10+ years back, portability and/or compiler support wasn t very good. More recently, with the borrowing of code from the Chromium project, this changed. While the borrowed code for out-of-process plugins support didn t have an impact on libstdc++ usage, the recent addition of ANGLE had. This manifests itself in symbols version usage These are the symbol versions required from libstdc++.so.6 on 3.6 (as given by objdump -p): And on 4.0: This means Firefox 4.0 builds from Mozilla need the GLIBCXX_3.4.9 symbol version, which was introduced with gcc 4.2. This means Firefox 4.0 builds don t work on systems with a libstdc++ older than that, while 3.6 builds would. It so happens that the system libstdc++ on the buildbots themselves is that old, which is why we set LD_LIBRARY_PATH to the appropriate location during tests. This shouldn t however be a big problem for users. Newer gcc, new problems As part of making Firefox faster, we re planning to switch to gcc 4.5, to benefit from better (as in working) profile guided optimization, and other compiler improvements. We actually attempted to switch to gcc 4.5 twice during the 4.0 development cycle. But various problems made us go back to gcc 4.3.3, the main contender being the use of even newer libstdc++ symbols: GLIBCXX_3.4.14 was added in gcc 4.5, making the build require a very recent libstdc++ installed on users systems. As this wouldn t work for Mozilla builds, we attempted to build with -static-libstdc++. This options makes the resulting binary effectively contain libstdc++ itself, which means not requiring a system one. This is the usual solution used for builds such as Mozilla s, that require to work properly on very different systems. The downside of -static-libstdc++ is that it makes the libxul.so binary larger (about 1MB larger). It looks like the linker doesn t try to eliminate the code from libstdc++ that isn t actually used. Taras has been fighting to try to get libstdc++ in a shape that would allow the linker to remove that code that is effectively dead weight for Firefox. Why do we need these symbols? The actual number of symbols required with the GLIBCXX_3.4.14 version is actually very low: With the addition of the following on debug builds only: The number of symbols required with the GLIBCXX_3.4.9 version is even lower: It however varies depending on the compiler version. I have seen other builds also require std::ostream& std::ostream::_M_insert(double). All these are actually internal implementation details of the libstdc++. We re never calling these functions directly. I m going to show two small examples triggering some of these requirements (that actually generalize to all of them). The case of templates
#include <iostream>
int main()  
    unsigned int i;
    std::cin >> i;
    return i;
 
This example, when built, requires std::istream& std::istream::_M_extract<double>(double&), but we are effectively calling std::istream& operator>>(unsigned int&). It is defined in /usr/include/c++/4.5/istream as:
template<typename _CharT, typename _Traits>
class basic_istream : virtual public basic_ios<_CharT, _Traits>  
    basic_istream<_CharT, _Traits>& operator>>(unsigned int& __n)  
        return _M_extract(__n);
     
 
And _M_extract is defined in /usr/include/c++/4.5/bits/istream.tcc as:
template<typename _CharT, typename _Traits> template<typename _ValueT>
        basic_istream<_CharT, _Traits>&
        basic_istream<_CharT, _Traits>::_M_extract(_ValueT& __v)  
            (...)
         
And later on in the same file:
extern template istream& istream::_M_extract(unsigned int&);
What this all means is that libstdc++ actually provides an implementation of an instance of the template for the istream (a.k.a. basic_istream<char>) class, with an unsigned int & parameter (and some more implementations). So, when building the example program, gcc decides, instead of instantiating the template, to use the libstdc++ function. This extern definition, however, is guarded by a #if _GLIBCXX_EXTERN_TEMPLATE, so if we build with -D_GLIBCXX_EXTERN_TEMPLATE=0, we actually get gcc to instantiate the template, thus getting rid of the GLIBCXX_3.4.9 dependency. The downside is that this doesn t work so well with bigger code, because other things are hidden behind #if _GLIBCXX_EXTERN_TEMPLATE. There is however another (obvious) way to for the template instantiation: instantiating it. So adding template std::istream& std::istream::_M_extract(unsigned int&); to our code is just enough to get rid of the GLIBCXX_3.4.9 dependency. Other template cases obviously can be worked around the same way. The case of renamed implementations
#include <list>
int main()  
    std::list<int> l;
    l.push_back(42);
    return 0;
 
Here, we get a dependency on std::_List_node_base::_M_hook(std::_List_node_base*) but we are effectively calling std::list<int>::push_back(int &). It is defined in /usr/include/c++/bits/stl_list.h as:
template<typename _Tp, typename _Alloc = std::allocator<_Tp> >
class list : protected _List_base<_Tp, _Alloc>  
    void push_back(const value_type& __x)  
        this->_M_insert(end(), __x);
     
 
_M_insert is defined in the same file:
template<typename ... _Args>
void _M_insert(iterator __position, _Args&&... __args)  
    _List_node<_Tp>* __tmp = _M_create_node(std::forward<_args>(__args)...);
    __tmp->_M_hook(__position._M_node);
 
Finally, _M_hook is defined as follows:
struct _List_node_base  
    void _M_hook(_List_node_base * const __position) throw ();
 
In gcc 4.4, however, push_back has the same definition, and while _M_insert is defined similarly, it calls __tmp->hook instead of __tmp->_M_hook. Interestingly, gcc 4.5 s libstdc++ exports symbols for both std::_List_node_base::_M_hook and std::_List_node_base::hook, and the code for both methods is the same. Considering the above, a work-around for this kind of dependency is to define the newer function in our code, and make it call the old function. In our case here, this would look like:
namespace std  
    struct _List_node_base  
        void hook(_List_node_base * const __position) throw ();
        void _M_hook(_List_node_base * const __position) throw ();
     ;
    void _List_node_base::_M_hook(_List_node_base * const __position) throw ()  
        hook(__position);
     
 
which you need to put in a separate source file, not including <list>. All in all, with a small hack, we are able to build Firefox with gcc 4.5 without requiring libstdc++ 4.5. Now, another reason to switch to gcc 4.5 was to use better optimization flags, but it turns out it makes the binaries 6MB bigger. But that s another story.

Colin Watson: Wubi bug 693671

I spent most of last week working on Ubuntu bug 693671 ("wubi install will not boot - phase 2 stops with: Try (hd0,0): NTFS5"), which was quite a challenge to debug since it involved digging into parts of the Wubi boot process I'd never really touched before. Since I don't think much of this is very well-documented, I'd like to spend a bit of time explaining what was involved, in the hope that it will help other developers in the future. Wubi is a system for installing Ubuntu into a file in a Windows filesystem, so that it doesn't require separate partitions and can be uninstalled like any other Windows application. The purpose of this is to make it easy for Windows users to try out Ubuntu without the need to worry about repartitioning, before they commit to a full installation. Wubi started out as an external project, and initially patched the installer on the fly to do all the rather unconventional things it needed to do; we integrated it into Ubuntu 8.04 LTS, which involved turning these patches into proper installer facilities that could be accessed using preseeding, so that Wubi only needs to handle the Windows user interface and other Windows-specific tasks. Anyone familiar with a GNU/Linux system's boot process will immediately see that this isn't as simple as it sounds. Of course, ntfs-3g is a pretty solid piece of software so we can handle the Windows filesystem without too much trouble, and loopback mounts are well-understood so we can just have the initramfs loop-mount the root filesystem. Where are you going to get the kernel and initramfs from, though? Well, we used to copy them out to the NTFS filesystem so that GRUB could read them, but this was overly complicated and error-prone. When we switched to GRUB 2, we could instead use its built-in loopback facilities, and we were able to simplify this. So all was more or less well, except for the elephant in the room. How are you going to load GRUB? In a Wubi installation, NTLDR (or BOOTMGR in Windows Vista and newer) still owns the boot process. Ubuntu is added as a boot menu option using BCDEdit. You might then think that you can just have the Windows boot loader chain-load GRUB. Unfortunately, NTLDR only loads 16 sectors - 8192 bytes - from disk. GRUB won't fit in that: the smallest core.img you can generate at the moment is over 18 kilobytes. Thus, you need something that is small enough to be loaded by NTLDR, but that is intelligent enough to understand NTFS to the point where it can find a particular file in the root directory of a filesystem, load boot loader code from it, and jump to that. The answer for this was GRUB4DOS. Most of GRUB4DOS is based on GRUB Legacy, which is not of much interest to us any more, but it includes an assembly-language program called GRLDR that supports doing this very thing for FAT, NTFS, and ext2. In Wubi, we build GRLDR as wubildr.mbr, and build a specially-configured GRUB core image as wubildr. Now, the messages shown in the bug report suggested a failure either within GRLDR or very early in GRUB. The first thing I did was to remember that GRLDR has been integrated into the grub-extras ntldr-img module suitable for use with GRUB 2, so I tried building wubildr.mbr from that; no change, but this gave me a modern baseline to work on. OK; now to try QEMU (you can use tricks like qemu -hda /dev/sda if you're very careful not to do anything that might involve writing to the host filesystem from within the guest, such as recursively booting your host OS ...). No go; it hung somewhere in the middle of NTLDR. Still, I could at least insert debug statements, copy the built wubildr.mbr over to my test machine, and reboot for each test, although it would be slow and tedious. Couldn't I? Well, yes, I mostly could, but that 8192-byte limit came back to bite me, along with an internal 2048-byte limit that GRLDR allocates for its NTFS bootstrap code. There were only a few spare bytes. Something like this would more or less fit, to print a single mark character at various points so that I could see how far it was getting:
	pushal
	xorw	%bx, %bx	/* video page 0 */
	movw	$0x0e4d, %ax	/* print 'M' */
	int	$0x10
	popal
In a few places, if I removed some code I didn't need on my test machine (say, CHS compatibility), I could even fit in cheap and nasty code to print a single register in hex (as long as you didn't mind 'A' to 'F' actually being ':' to '?' in ASCII; and note that this is real-mode code, so the loop counter is %cx not %ecx):
	/* print %edx in dumbed-down hex */
	pushal
	xorw	%bx, %bx
	movb	$0xe, %ah
	movw	$8, %cx
1:
	roll	$4, %edx
	movb	%dl, %al
	andb	$0xf, %al
	int	$0x10
	loop	1b
	popal
After a considerable amount of work tracking down problems by bisection like this, I also observed that GRLDR's NTFS code bears quite a bit of resemblance in its logical flow to GRUB 2's NTFS module, and indeed the same person wrote much of both. Since I knew that the latter worked, I could use it to relieve my brain of trying to understand assembly code logic directly, and could compare the two to look for discrepancies. I did find a few of these, and corrected a simple one. Testing at this point suggested that the boot process was getting as far as GRUB but still wasn't printing anything. I removed some Ubuntu patches which quieten down GRUB's startup: still nothing - so I switched my attentions to grub-core/kern/i386/pc/startup.S, which contains the first code executed from GRUB's core image. Code before the first call to real_to_prot (which switches the processor into protected mode) succeeded, while code after that point failed. Even more mysteriously, code added to real_to_prot before the actual switch to protected mode failed too. Now I was clearly getting somewhere interesting, but what was going on? What I really wanted was to be able to single-step, or at least see what was at the memory location it was supposed to be jumping to. Around this point I was venting on IRC, and somebody asked if it was reproducible in QEMU. Although I'd tried that already, I went back and tried again. Ubuntu's qemu is actually built from qemu-kvm, and if I used qemu -no-kvm then it worked much better. Excellent! Now I could use GDB:
(gdb) target remote   qemu -gdb stdio -no-kvm -hda /dev/sda
This let me run until the point when NTLDR was about to hand over control, then interrupt and set a breakpoint at 0x8200 (the entry point of startup.S). This revealed that the address that should have been real_to_prot was in fact garbage. I set a breakpoint at 0x7c00 (GRLDR's entry point) and stepped all the way through to ensure it was doing the right thing. In the process it was helpful to know that GDB and QEMU don't handle real mode very well between them. Useful tricks here were: Single-stepping showed that GRLDR was loading the entirety of wubildr correctly and jumping to it. The first instruction it jumped to wasn't in startup.S, though, and then I remembered that we prefix the core image with grub-core/boot/i386/pc/lnxboot.S. Stepping through this required a clear head since it copies itself around and changes segment registers a few times. The interesting part was at real_code_2, where it copies a sector of the kernel to the target load address, and then checks a known offset to find out whether the "kernel" is in fact GRUB rather than a Linux kernel. I checked that offset by hand, and there was the smoking gun. GRUB recently acquired Reed-Solomon error correction on its core image, to allow it to recover from other software writing over sectors in the boot track. This moved the magic number lnxboot.S was checking somewhat further into the core image, after the first sector. lnxboot.S couldn't find it because it hadn't copied it yet! A bit of adjustment and all was well again. The lesson for me from all of this has been to try hard to get an interactive debugger working. Really hard. It's worth quite a bit of up-front effort if it saves you from killing neurons stepping through pages of code by hand. I think the real-mode debugging tricks I picked up should be useful for working on GRUB in the future.

Julien Viard de Galbert: Triage X Bugs of the Week (TXBW18)

Better later than never, I restarted to triage last week, here is the report for it. In the mean time, Cyril has been triaging a lot of bugs see Debian XSF News #7.
But there are still 533 bugs to triage. Mike Hommey recently wrote about graphs for the Debian Bug Tracking System. In particular there is now a per maintainer graph, so here it the X Strike Force bug graph ! (Note: the graph does not filter out some bugs as we do on UDD. The X Strike Force (still) needs you ! You can have a look at the X Strike Force Bug Closing Procedure and check XSF unstable bugs sorted by date.

13 March 2011

Francois Marier: Setting up RAID on an existing Debian/Ubuntu installation

I run RAID1 on all of the machines I support. While such hard disk mirroring is not a replacement for having good working backups, it means that a single drive failure is not going to force me to have to spend lots of time rebuilding a machine.

The best possible time to set this up is of course when you first install the operating system. The Debian installer will set everything up for you if you choose that option and Ubuntu has alternate installation CDs which allow you to do the same.

This post documents the steps I followed to retrofit RAID1 into an existing Debian squeeze installation. Getting a mirrored setup after the fact.

OverviewBefore you start, make sure the following packages are installed:
apt-get install mdadm rsync initramfs-tools
Then go through these steps:
  1. Partition the new drive.
  2. Create new degraded RAID arrays.
  3. Install GRUB2 on both drives.
  4. Copy existing data onto the new drive.
  5. Reboot using the RAIDed drive and test system.
  6. Wipe the original drive by adding it to the RAID array.
  7. Test booting off of the original drive.
  8. Resync drives.
  9. Test booting off of the new drive.
  10. Reboot with the two drives and resync the array.
(My instructions are mostly based on this old tutorial but also on this more recent one.)

1- Partition the new driveOnce you have connected the new drive (/dev/sdb), boot into your system and use one of cfdisk or fdisk to display the partition information for the existing drive (/dev/sda on my system).

The idea is to create partitions of the same size on the new drive. (If the new drive is bigger, leave the rest of the drive unpartitioned.)

Partition types should all be: fd (or "linux raid autodetect").

2- Create new degraded RAID arraysThe newly partioned drive, consisting of a root and a swap partition, can be added to new RAID1 arrays using mdadm:
mdadm --create /dev/md0 --level=1 --raid-devices=2 missing /dev/sdb1
mdadm --create /dev/md1 --level=1 --raid-devices=2 missing /dev/sdb2
and formatted like this:
mkswap /dev/md1
mkfs.ext4 /dev/md0
Specify these devices explicitly in /etc/mdadm/mdadm.conf:
DEVICE /dev/sda* /dev/sdb*
and append the RAID arrays to the end of that file:
mdadm --detail --scan >> /etc/mdadm/mdadm.conf
dpkg-reconfigure mdadm
You can check the status of your RAID arrays at any time by running this command:
cat /proc/mdstat

3- Install GRUB2 on both drivesThe best way to ensure that GRUB2, the default bootloader in Debian and Ubuntu, is installed on both drives is to reconfigure its package:
dpkg-reconfigure grub-pc
and select both /dev/sda and /dev/sdb (but not /dev/md0) as installation targets.

This should cause the init ramdisk (/boot/initrd.img-2.6.32-5-amd64) and the grub menu (/boot/grub/grub.cfg) to be rebuilt with RAID support.

4- Copy existing data onto the new driveCopy everything that's on the existing drive onto the new one using rsync:
mkdir /tmp/mntroot
mount /dev/md0 /tmp/mntroot
rsync -auHxv --exclude=/proc/* --exclude=/sys/* --exclude=/tmp/* /* /tmp/mntroot/

5- Reboot using the RAIDed drive and test systemBefore rebooting, open /tmp/mntroot/etc/fstab, and change /dev/sda1 and /dev/sda2 to /dev/md0 and /dev/md1 respectively.

Then reboot and from within the GRUB menu, hit "e" to enter edit mode and make sure that you will be booting off of the new disk:
set root='(md/0)'
linux /boot/vmlinuz-2.6.32-5-amd64 root=/dev/md0 ro quiet
Once the system is up, you can check that the root partition is indeed using the RAID array by running mount and looking for something like:
/dev/md0 on / type ext4 (rw,noatime,errors=remount-ro)

6- Wipe the original drive by adding it to the RAID arrayOnce you have verified that everything is working on /dev/sdb, it's time to change the partition types on /dev/sda to fd and to add the original drive to the degraded RAID array:
mdadm /dev/md0 -a /dev/sda1
mdadm /dev/md1 -a /dev/sda2
You'll have to wait until the two partitions are fully synchronized but you can check the sync status using:
watch -n1 cat /proc/mdstat

7- Test booting off of the original driveOnce the sync is finished, update the boot loader menu:
update-grub
and shut the system down:
shutdown -h now
before physically disconnecting /dev/sdb and turning the machine back on to test booting with only /dev/sda present.

After a successful boot, shut the machine down and plug the second drive back in before powering it up again.

8- Resync drivesIf everything works, you should see the following after running cat /proc/mdstat:
md0 : active raid1 sda1[1]
280567040 blocks [2/1] [_U]
indicating that the RAID array is incomplete and that the second drive is not part of it.

To add the second drive back in and start the sync again:
mdadm /dev/md0 -a /dev/sdb1

9- Test booting off of the new driveTo complete the testing, shut the machine down, pull /dev/sda out and try booting with /dev/sdb only.

10- Reboot with the two drives and resync the arrayOnce you are satisfied that it works, reboot with both drives plugged in and re-add the first drive to the array:
mdadm /dev/md0 -a /dev/sda1
Your setup is now complete and fully tested.

Ongoing maintenanceI recommend making sure the two RAIDed drives stay in sync by enabling periodic RAID checks. The easiest way is to enable the checks that are built into the Debian package:
dpkg-reconfigure mdadm
but you can also create a weekly or monthly cronjob which does the following:
echo "check" > /sys/block/md0/md/sync_action
Something else you should seriously consider is to install the smartmontools package and run weekly SMART checks by putting something like this in your /etc/smartd.conf:
/dev/sda -a -d ata -o on -S on -s (S/../.././02 L/../../6/03)
/dev/sdb -a -d ata -o on -S on -s (S/../.././02 L/../../6/03)
These checks, performed by the hard disk controllers directly, could warn you of imminent failures ahead of time. Personally, when I start seeing errors in the SMART log (smartctl -a /dev/sda), I order a new drive straight away.

12 March 2011

Julien Blache: forked-daapd: v0.13

forked-daapd v0.13 is available! This release has been in the making for a long time, got delayed for a lot of reasons and had its content changed a few times along the way. Nonetheless, it s here now and if all goes to plan at least a couple releases should appear in the coming months, say before the summer. In this release: Thanks to all the contributors that sent bugs and patches for this release! I know development doesn t go quite as fast as some would like, but keep in mind that I m doing this in whatever free time I have and that the public git tree doesn t tell the whole story. There are several parallel feature branches you don t get to see, for instance. Hopefully 0.14 will appear in a few weeks. Tarballs available at http://alioth.debian.org/~jblache/forked-daapd/ ; GPG signatures made with my Debian key F5D65169.

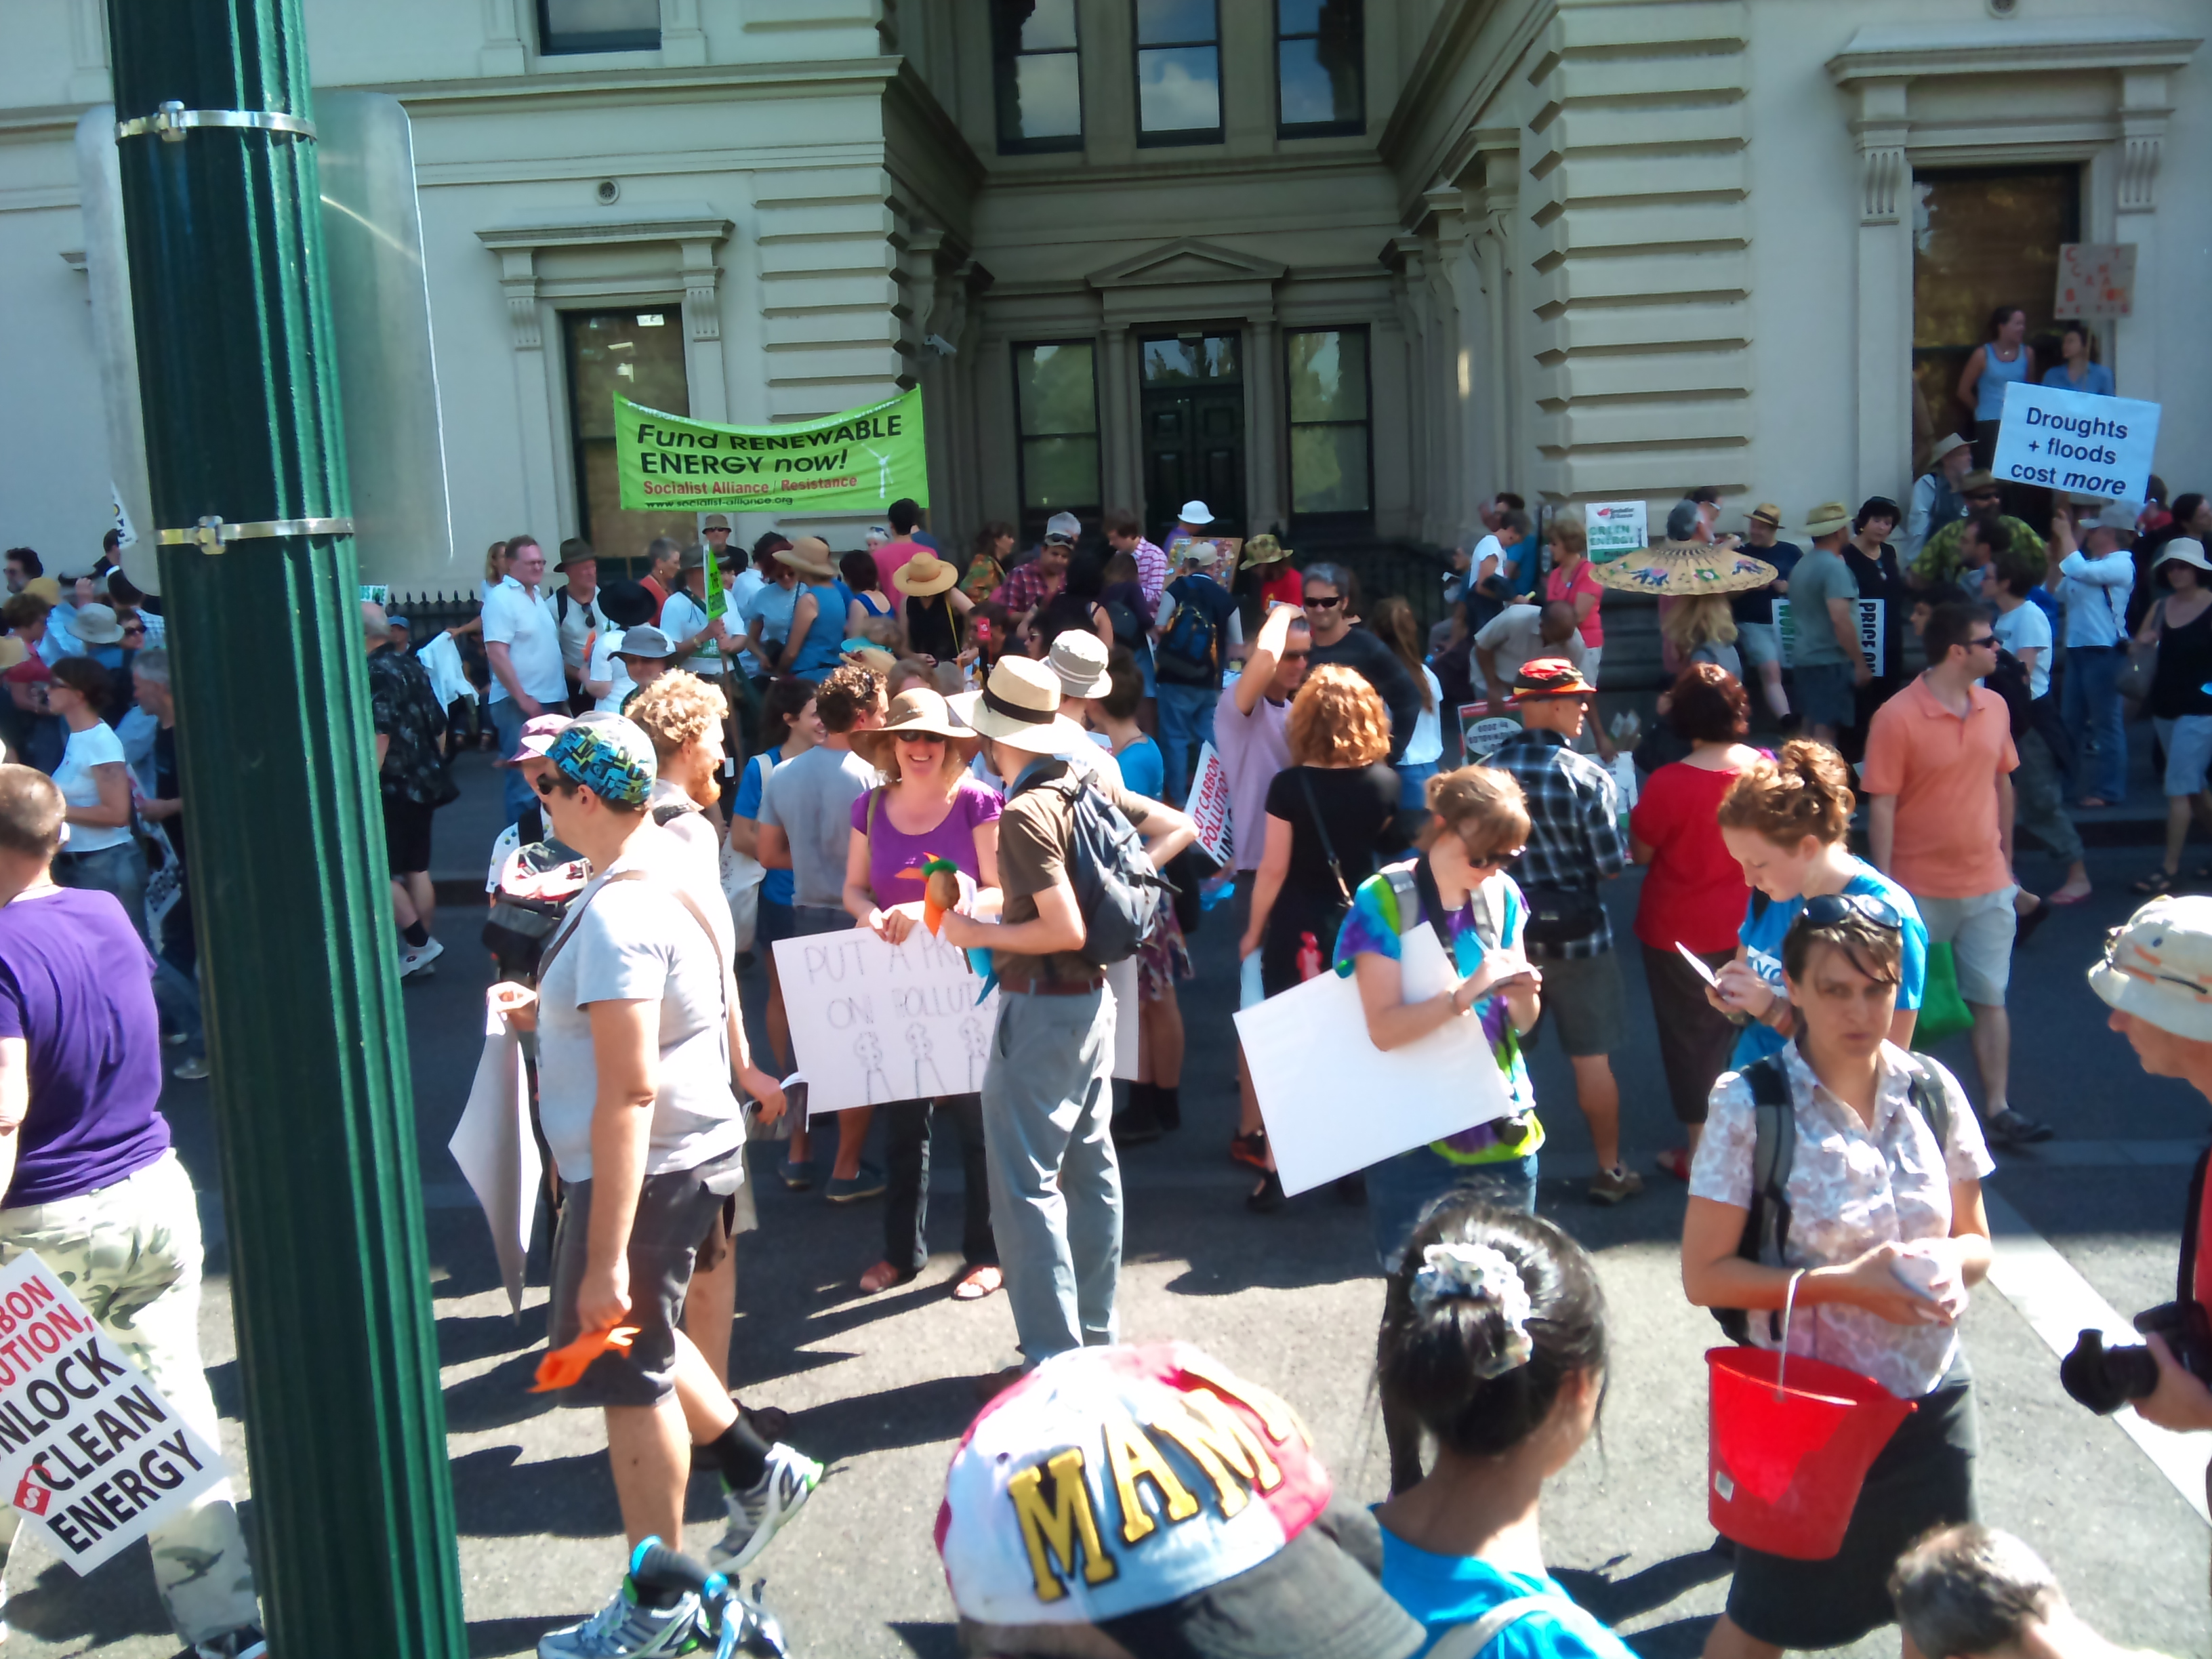
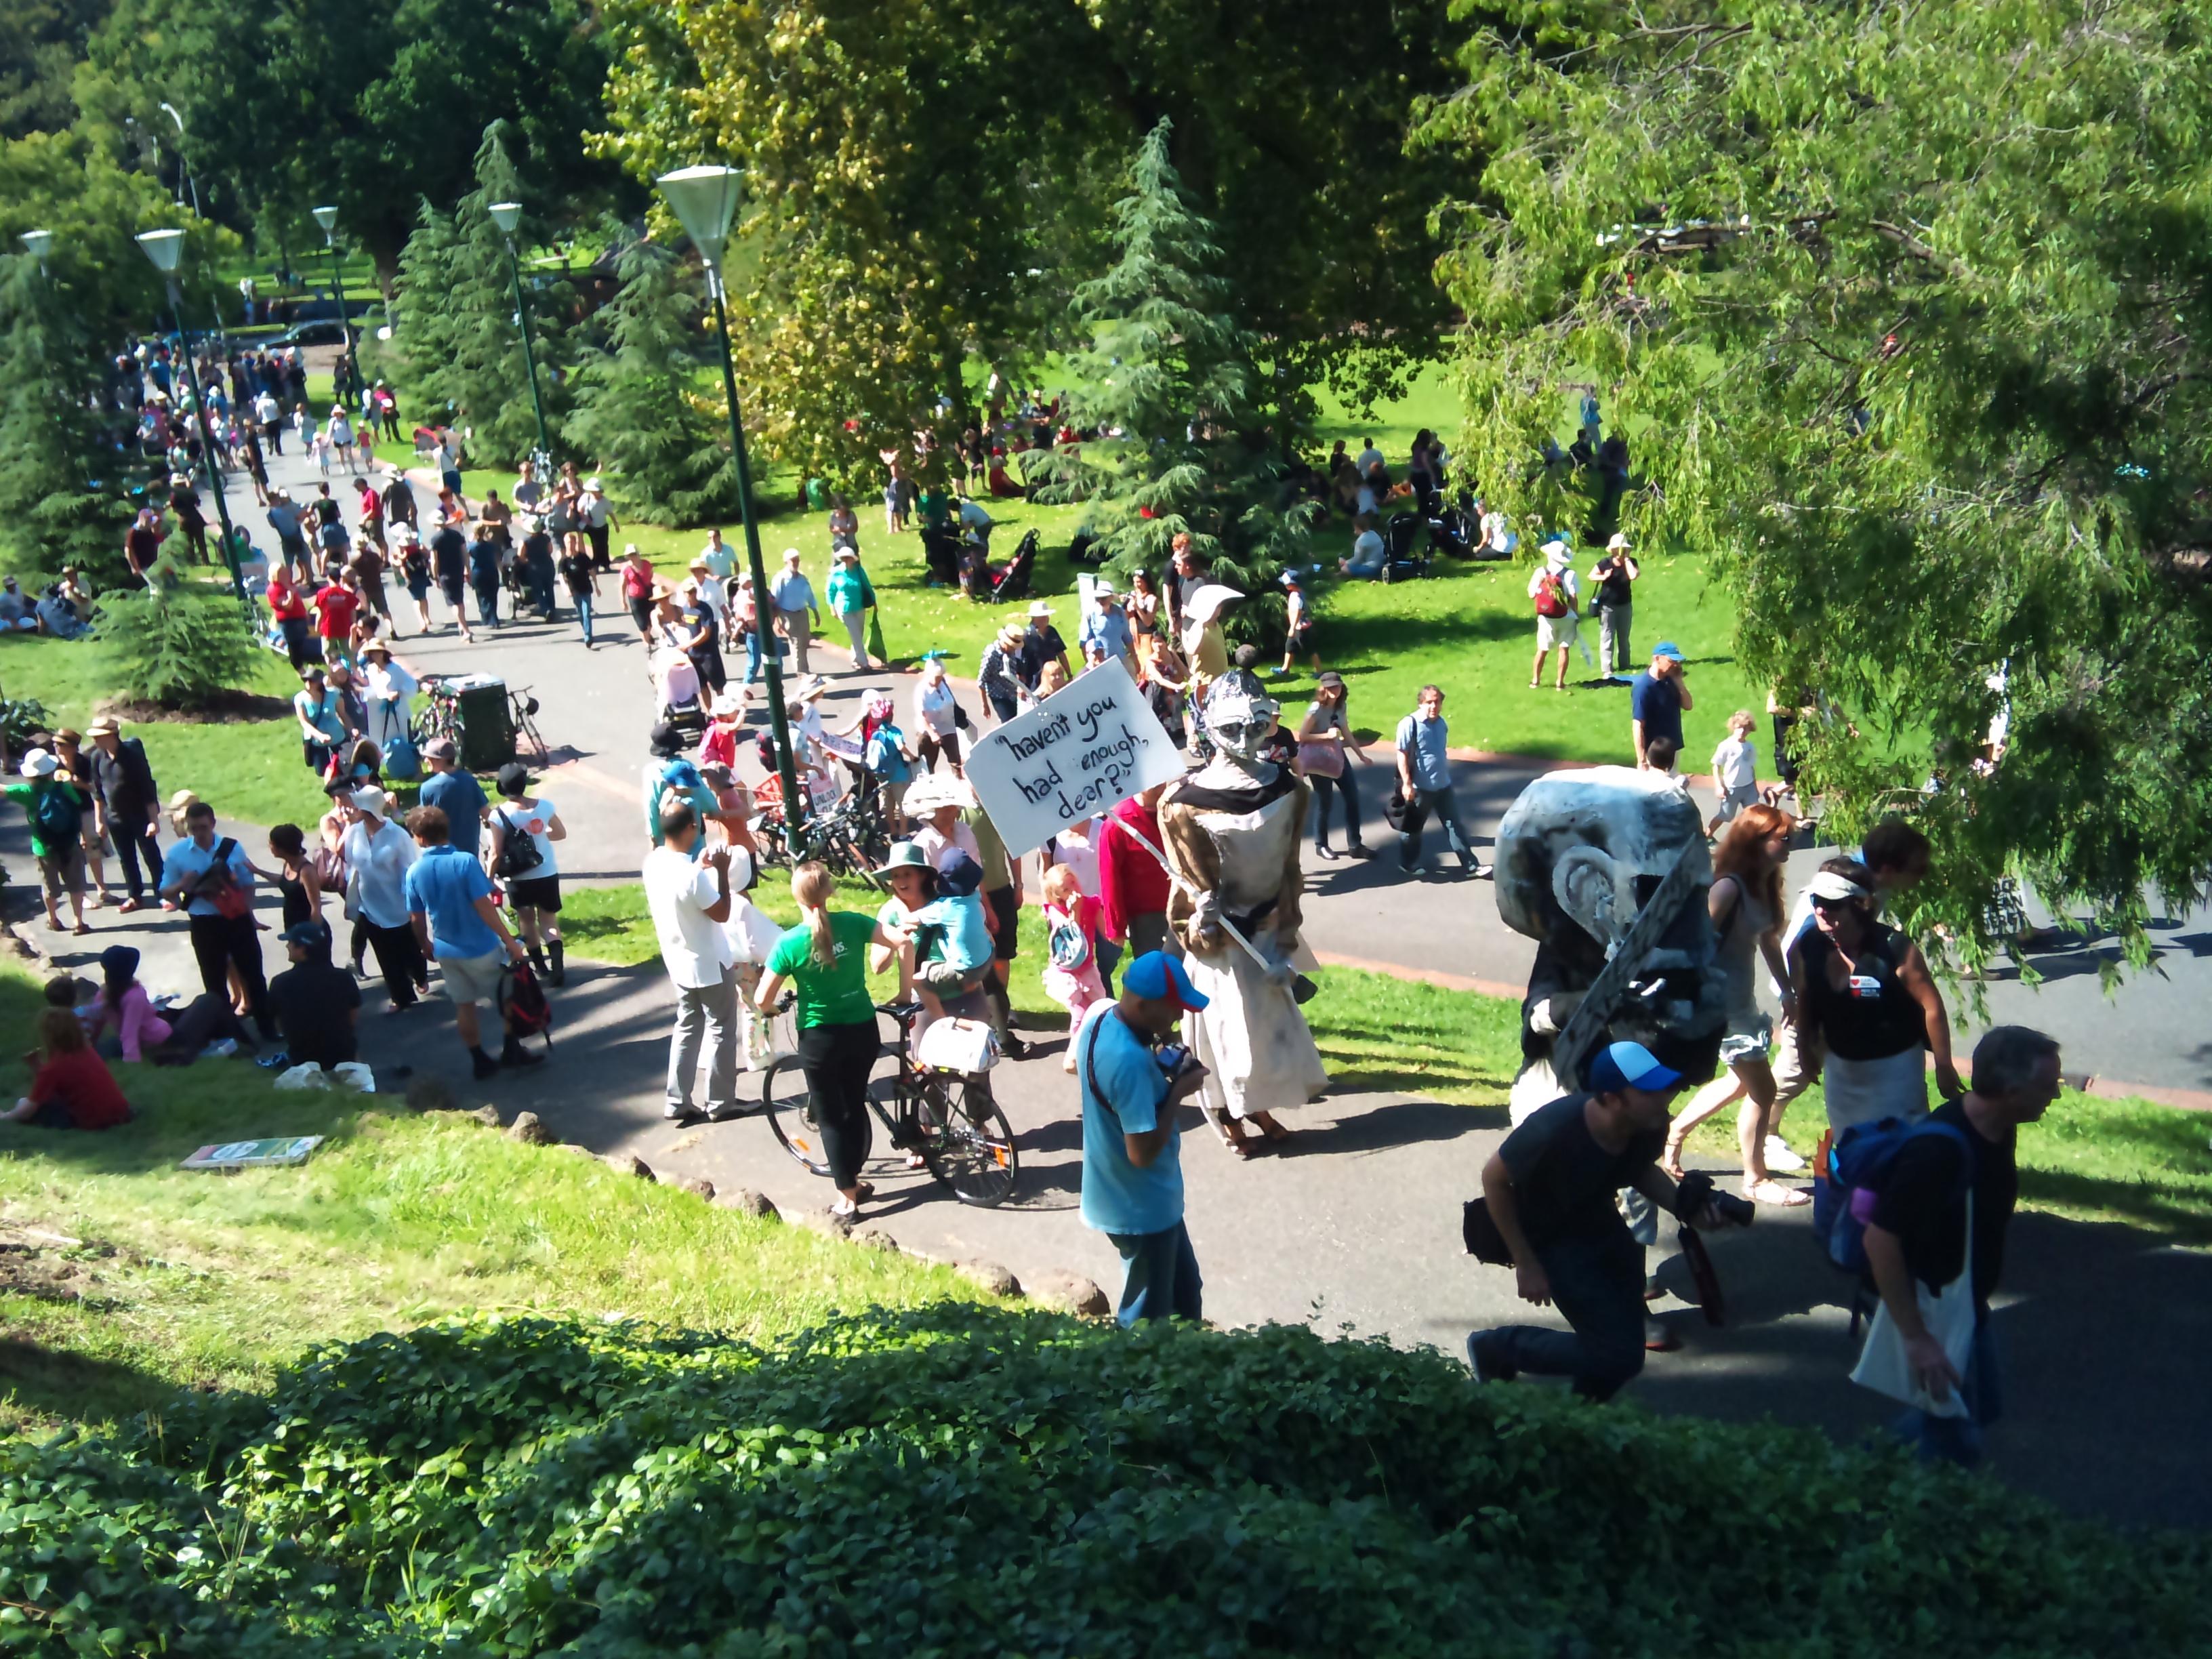
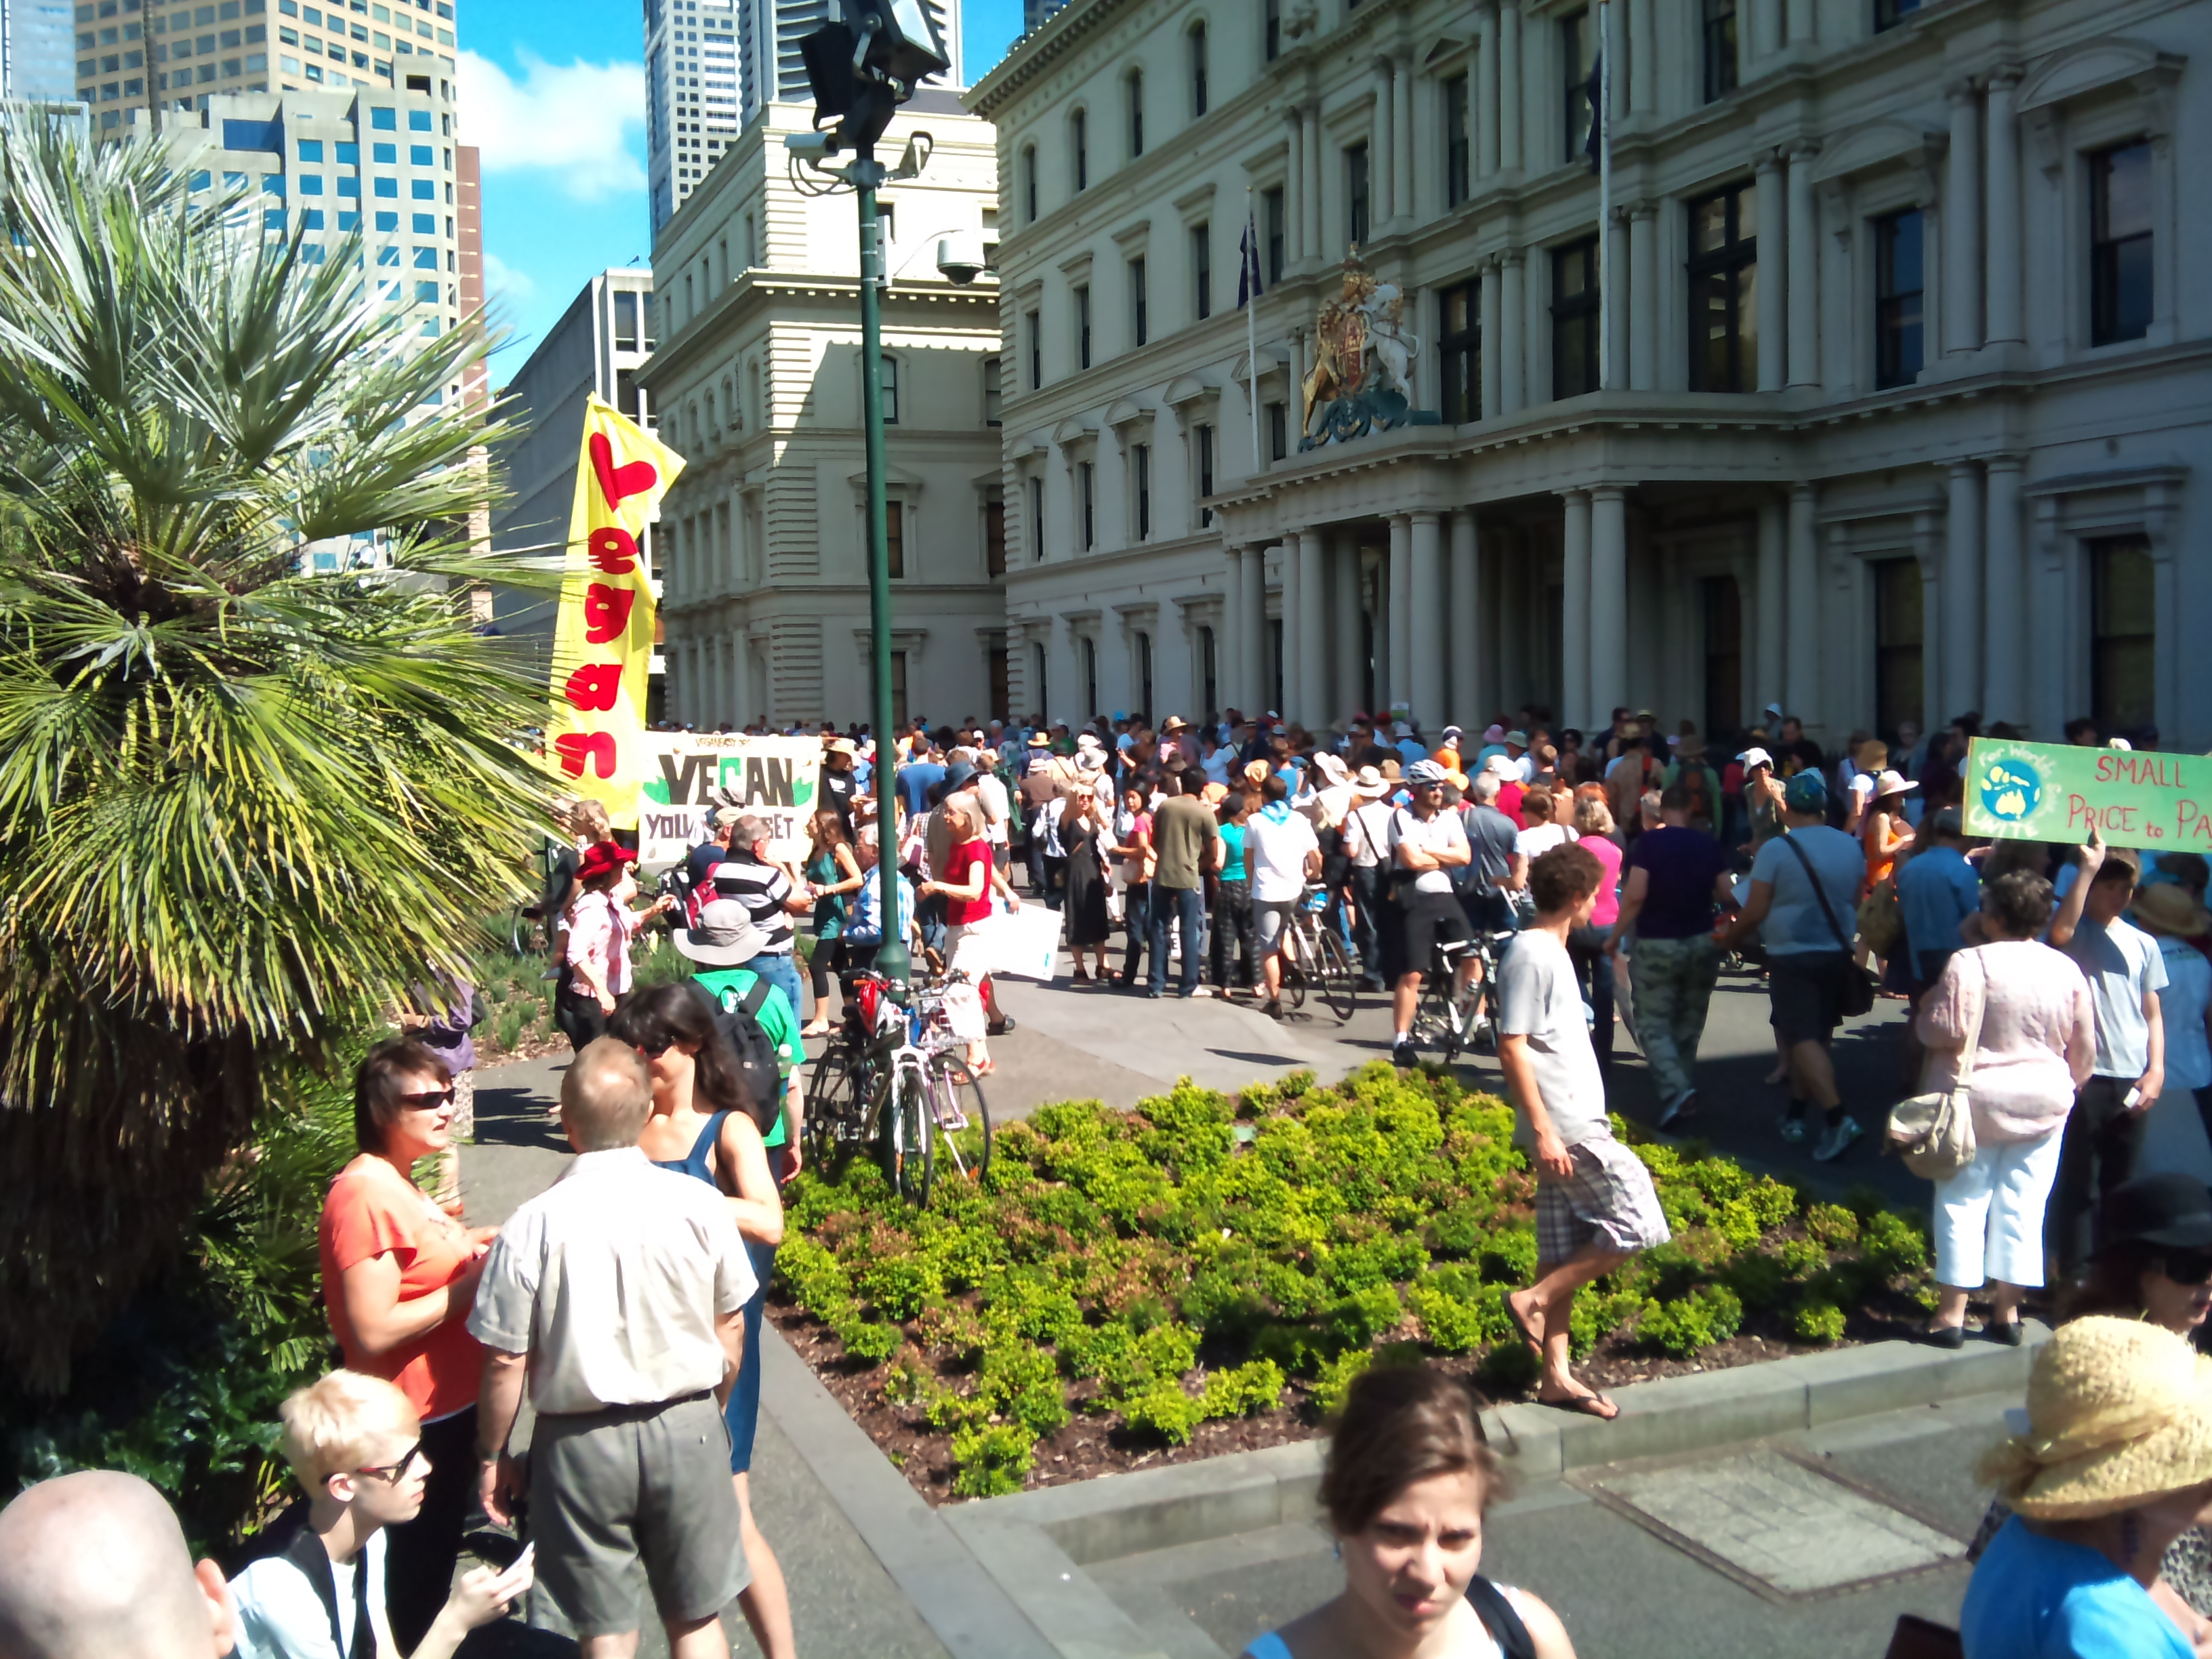
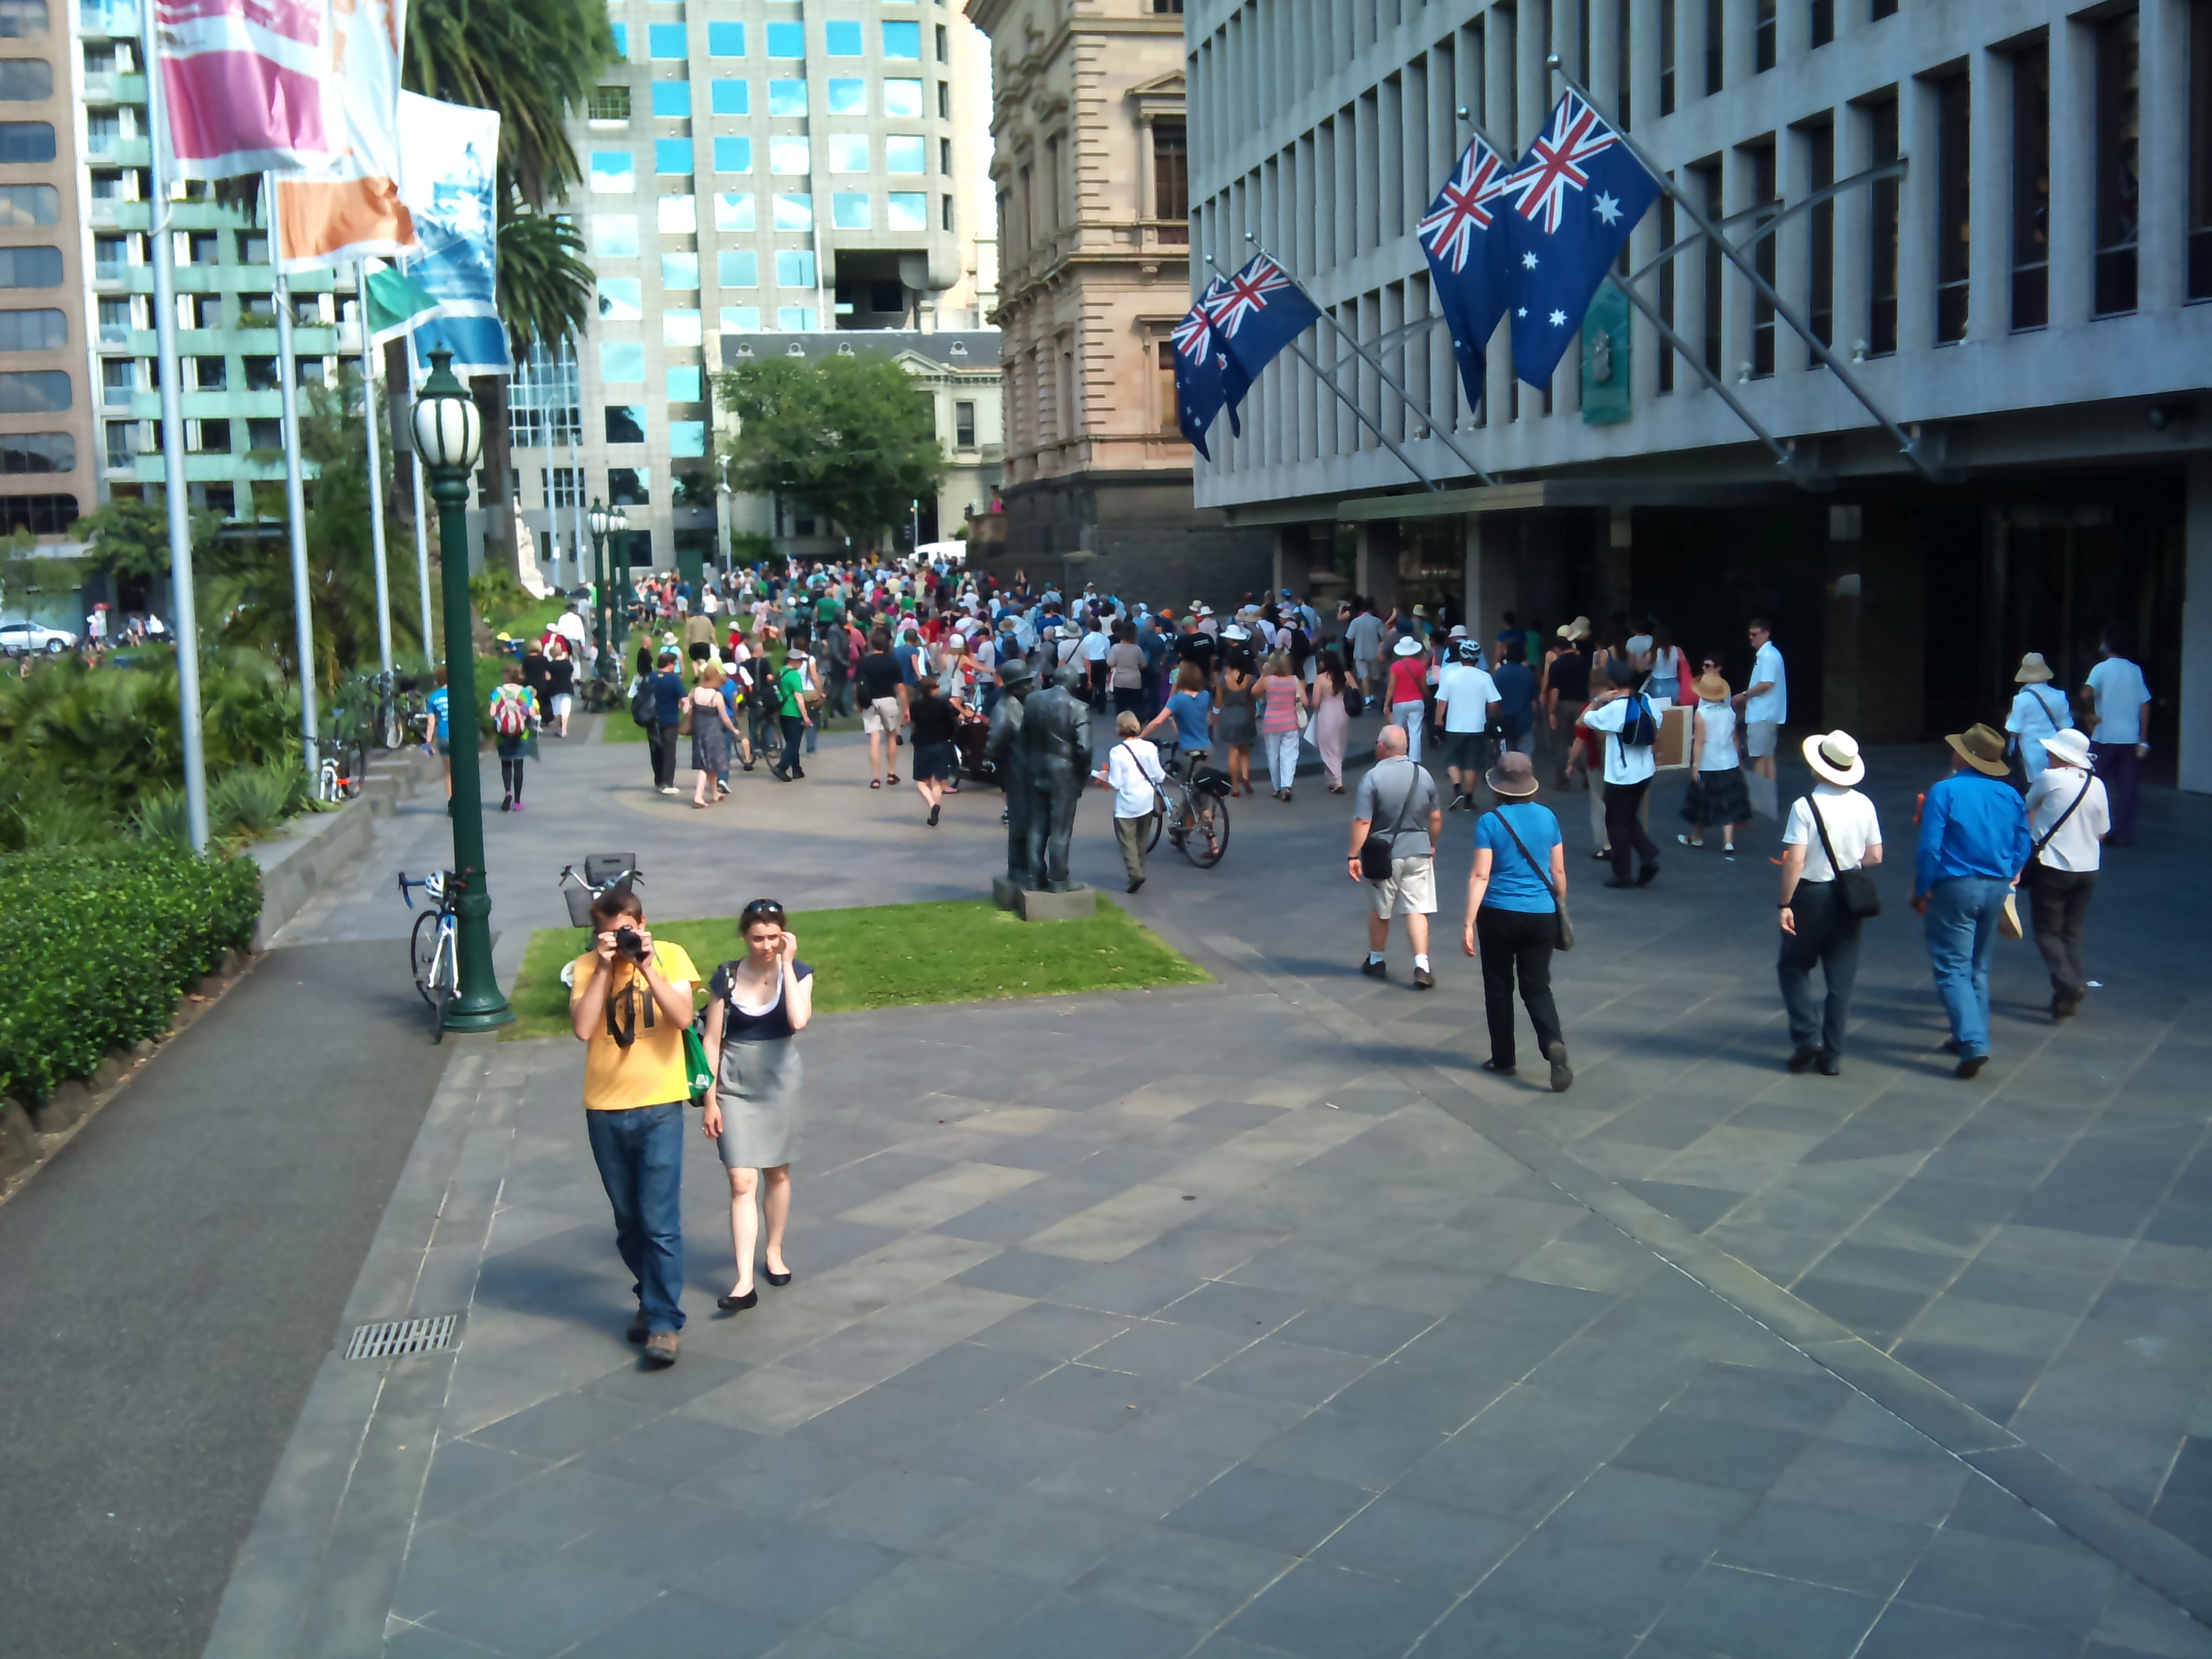
Russell Coker: Climate Action Now Rally Melbourne 12th March

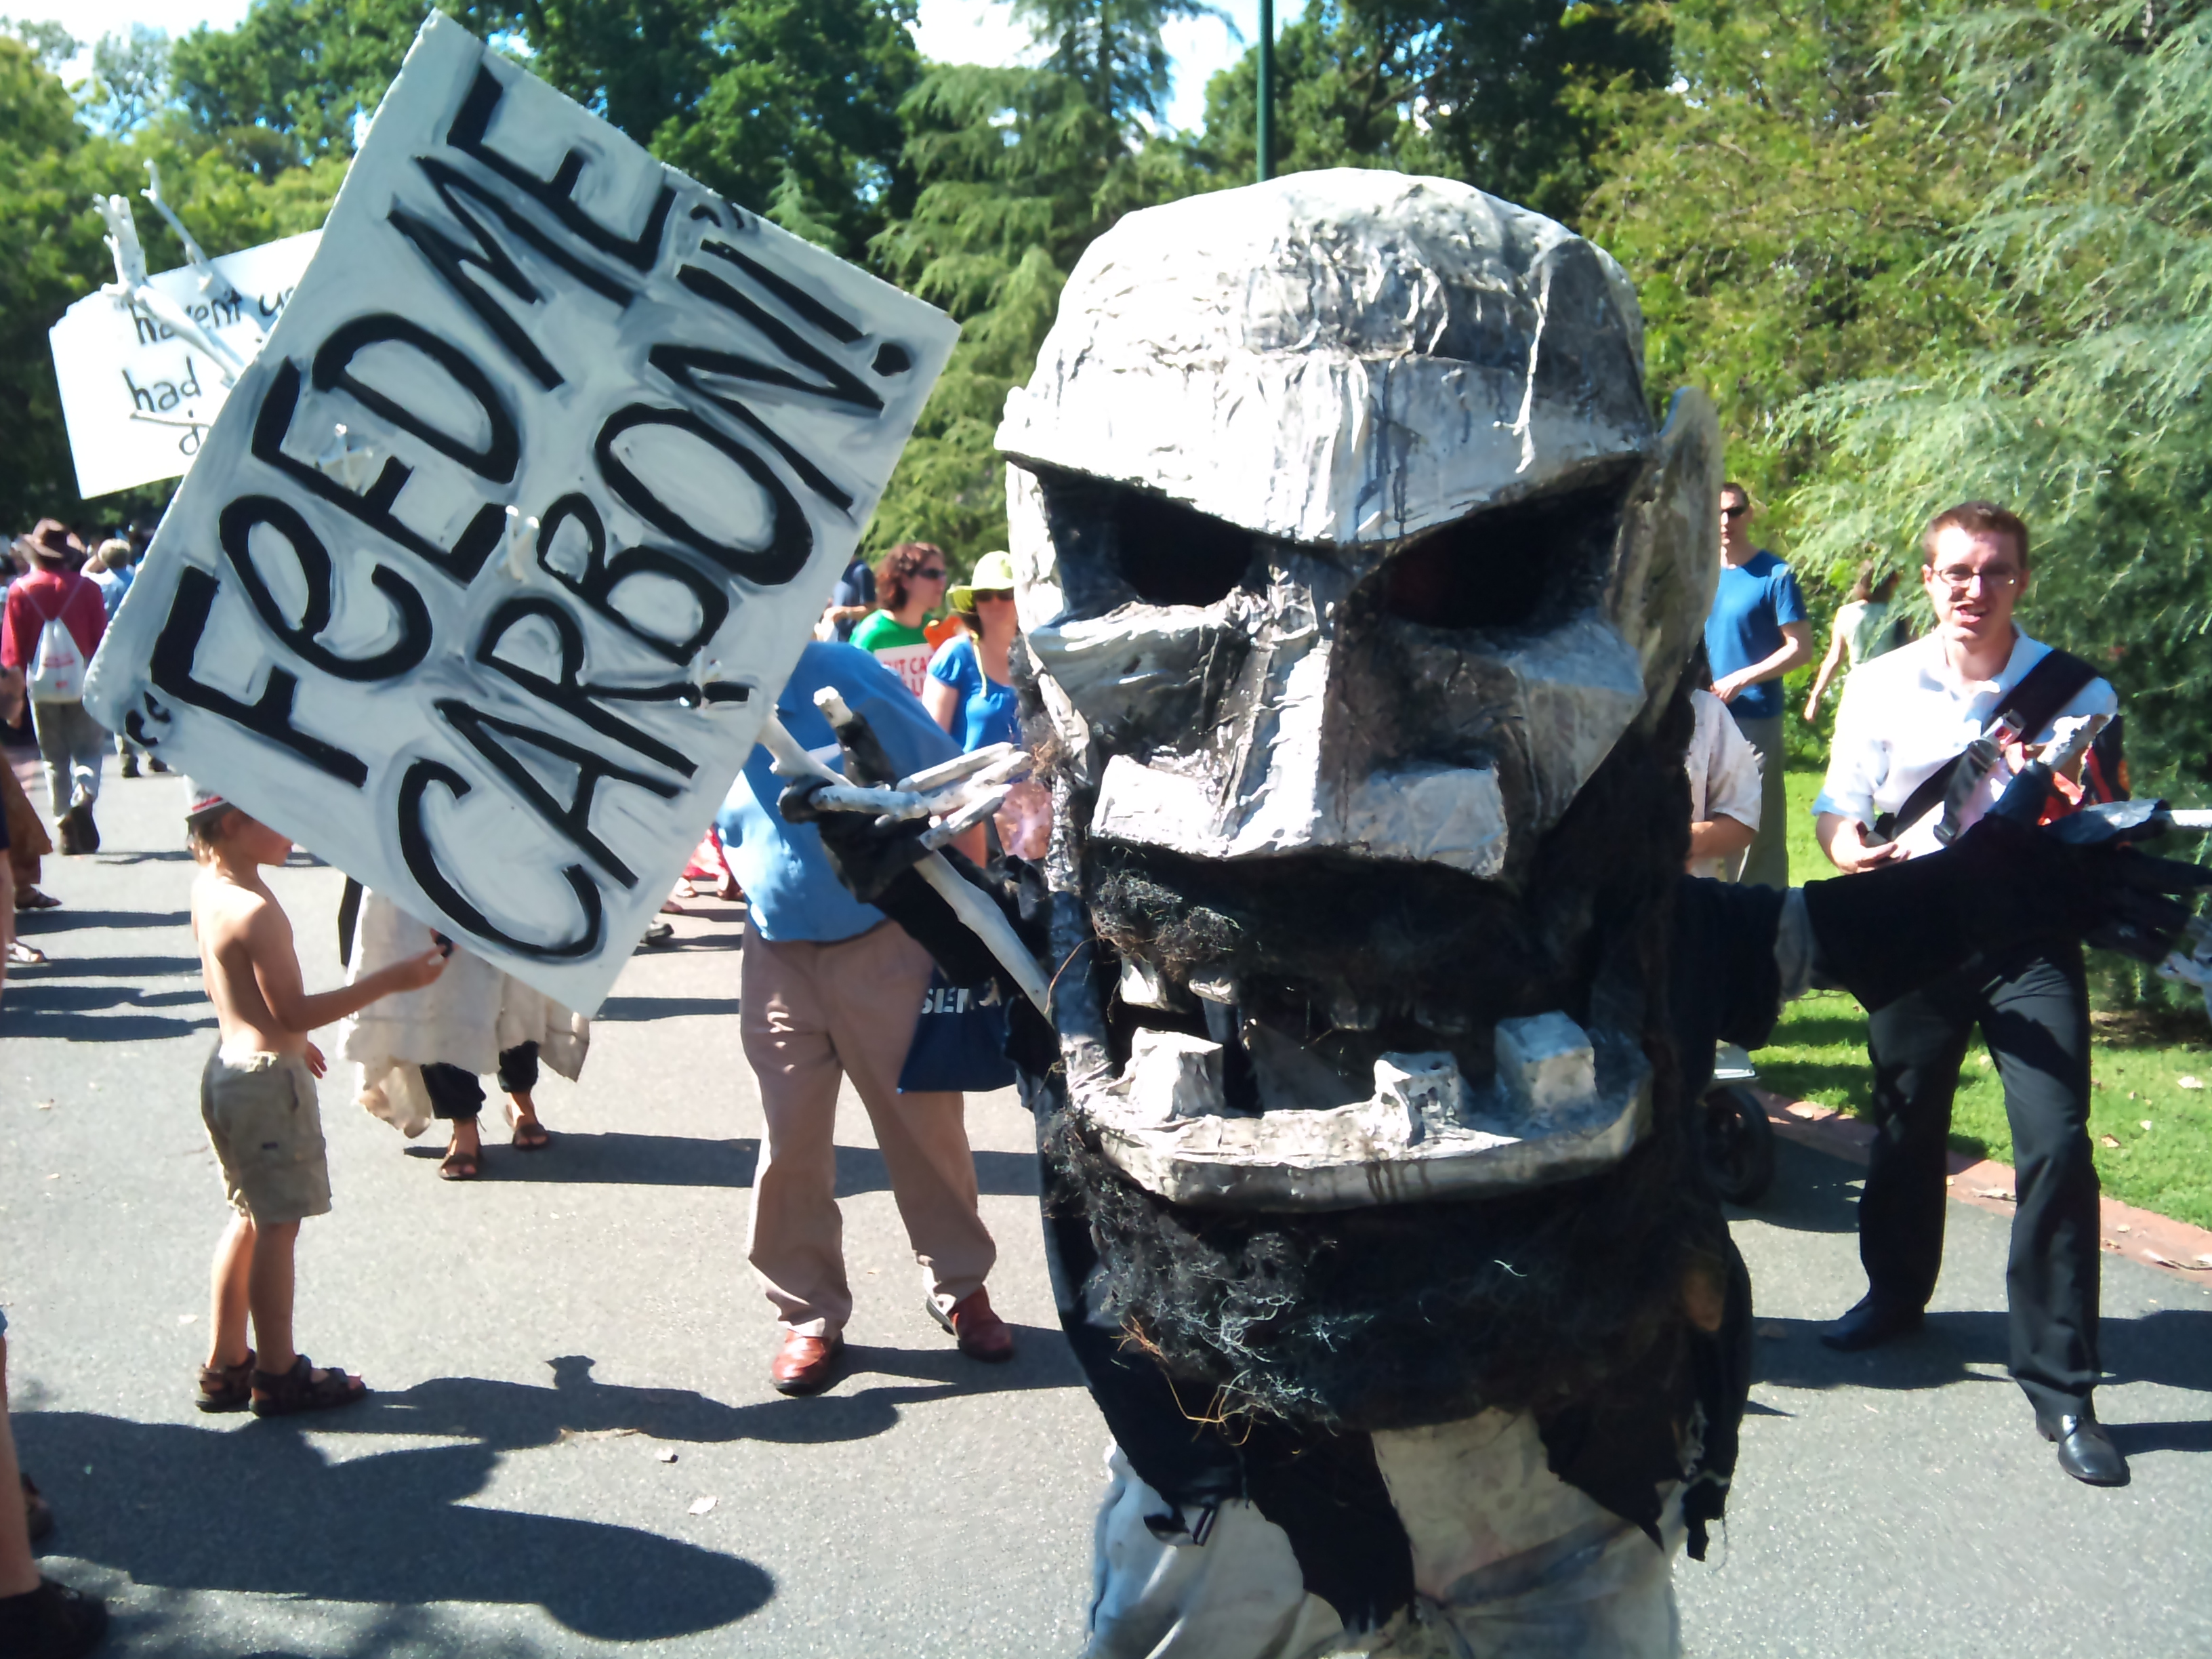
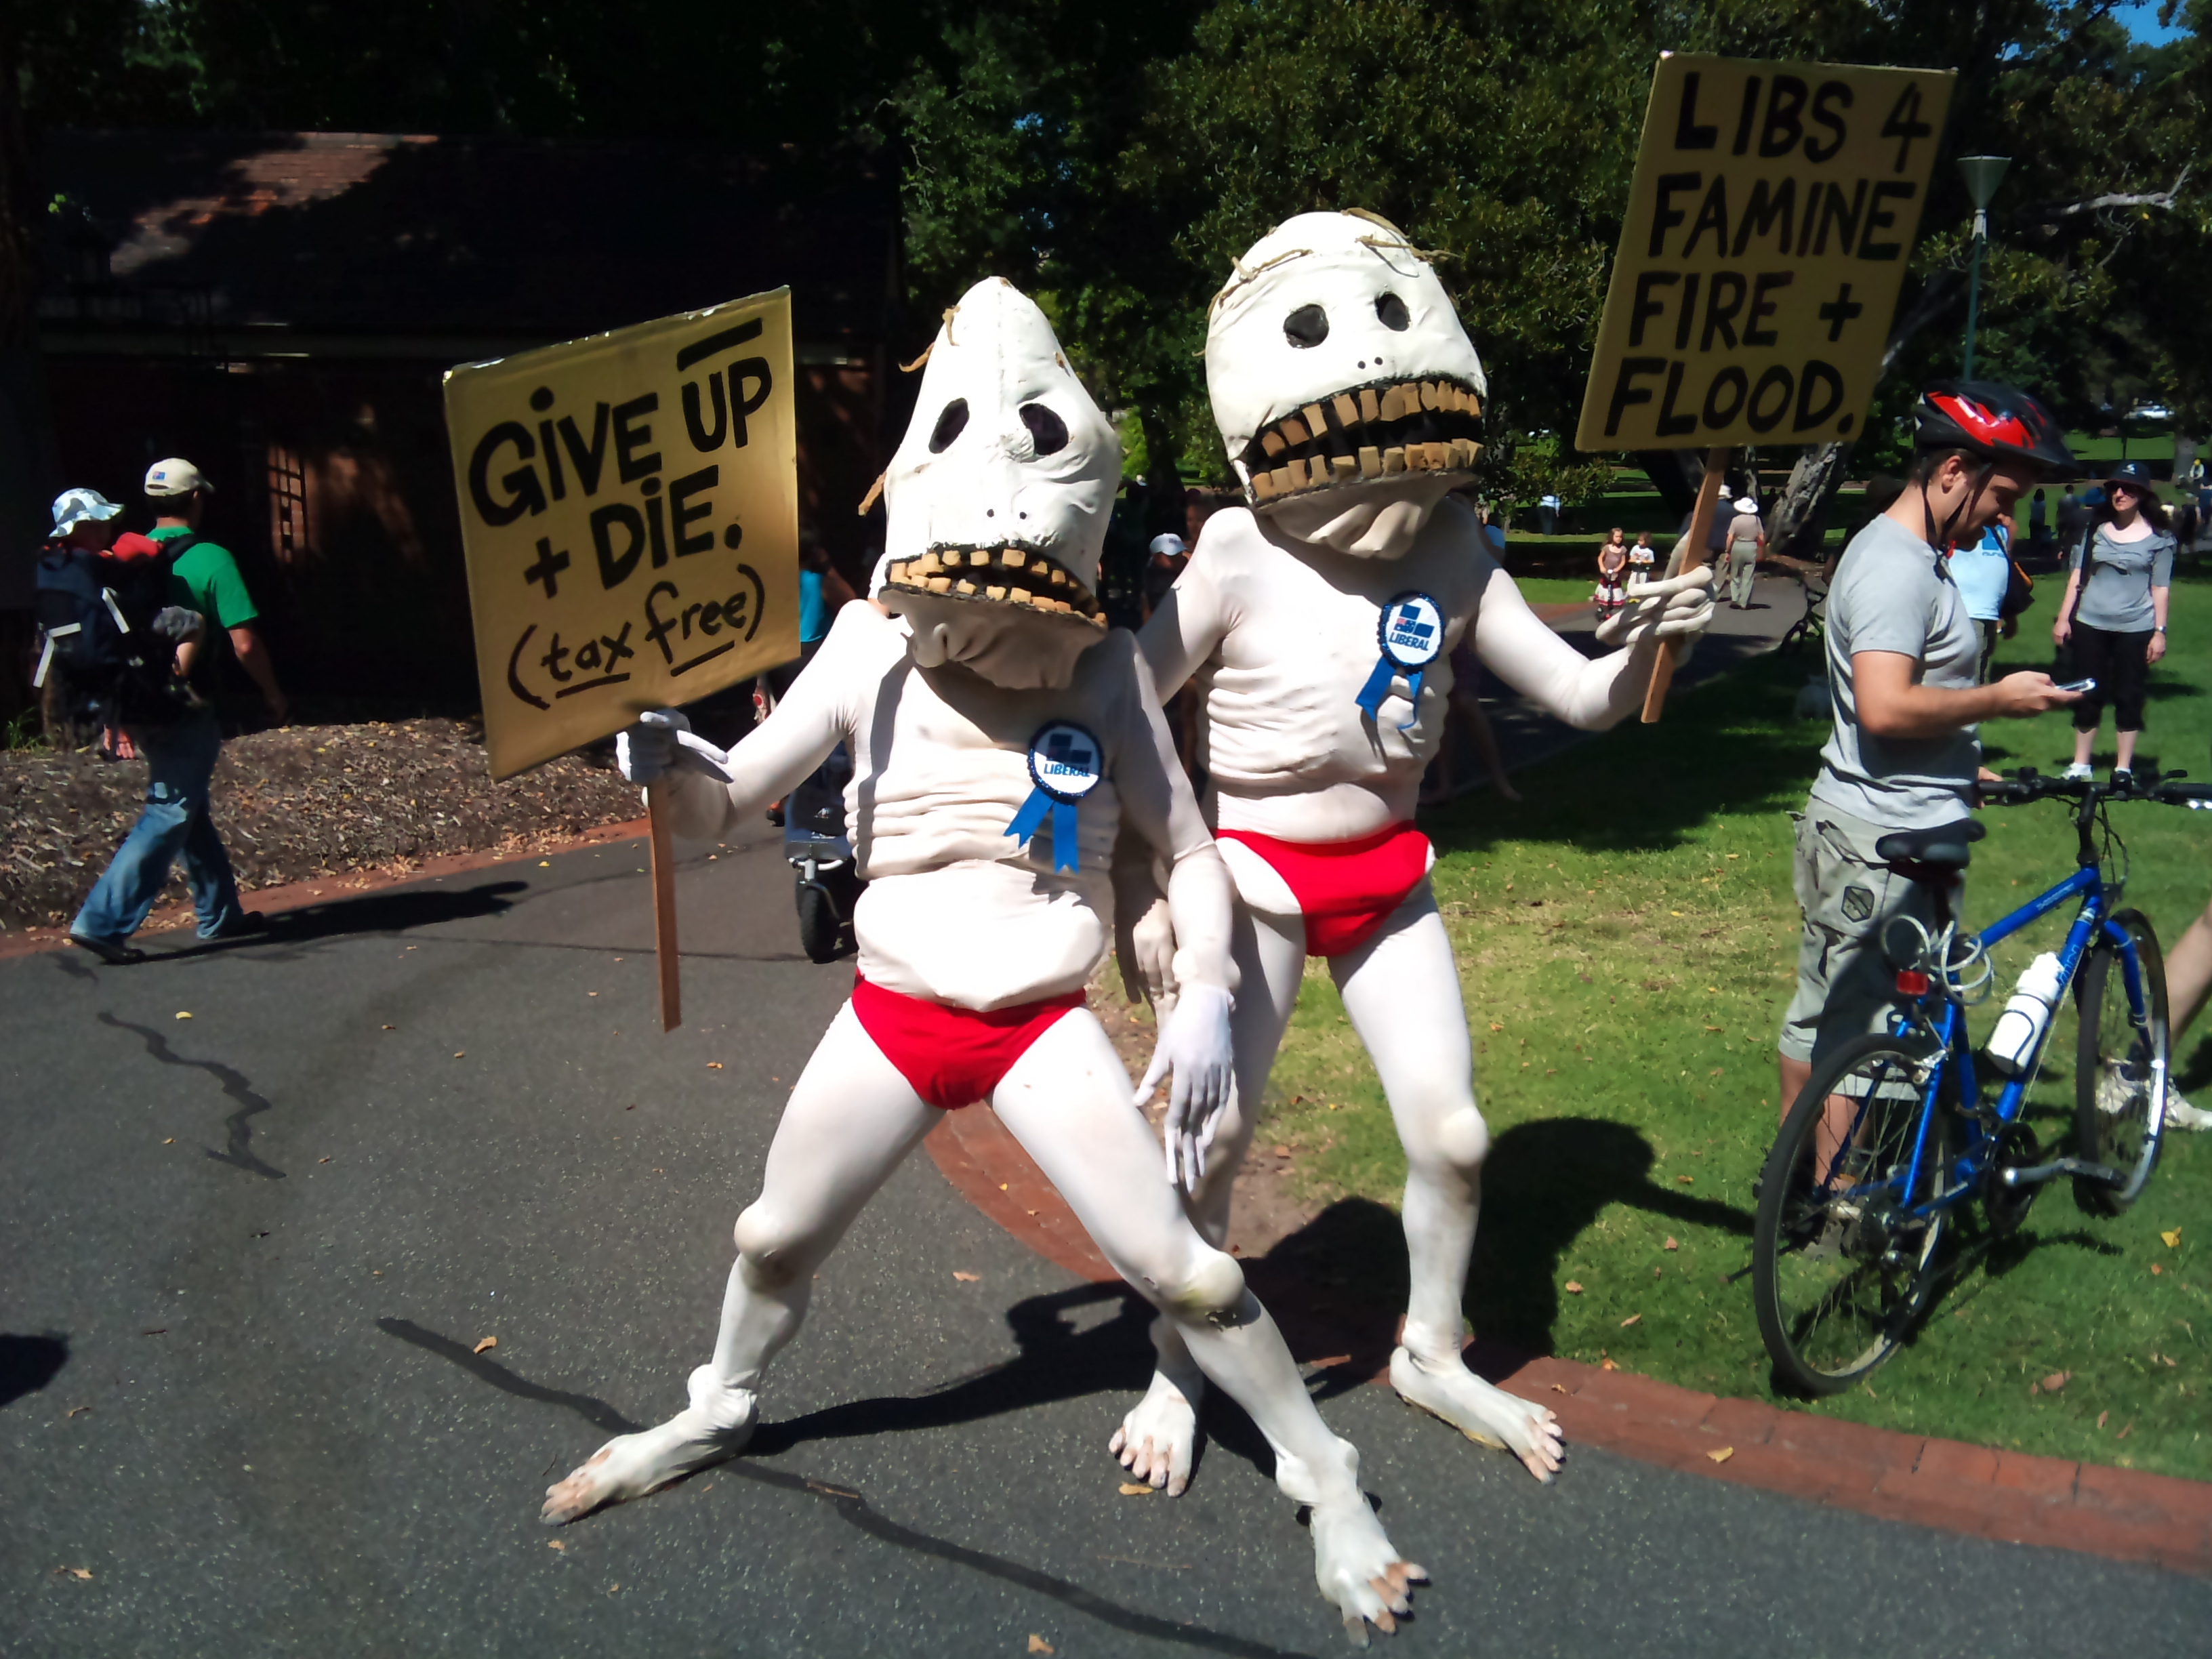
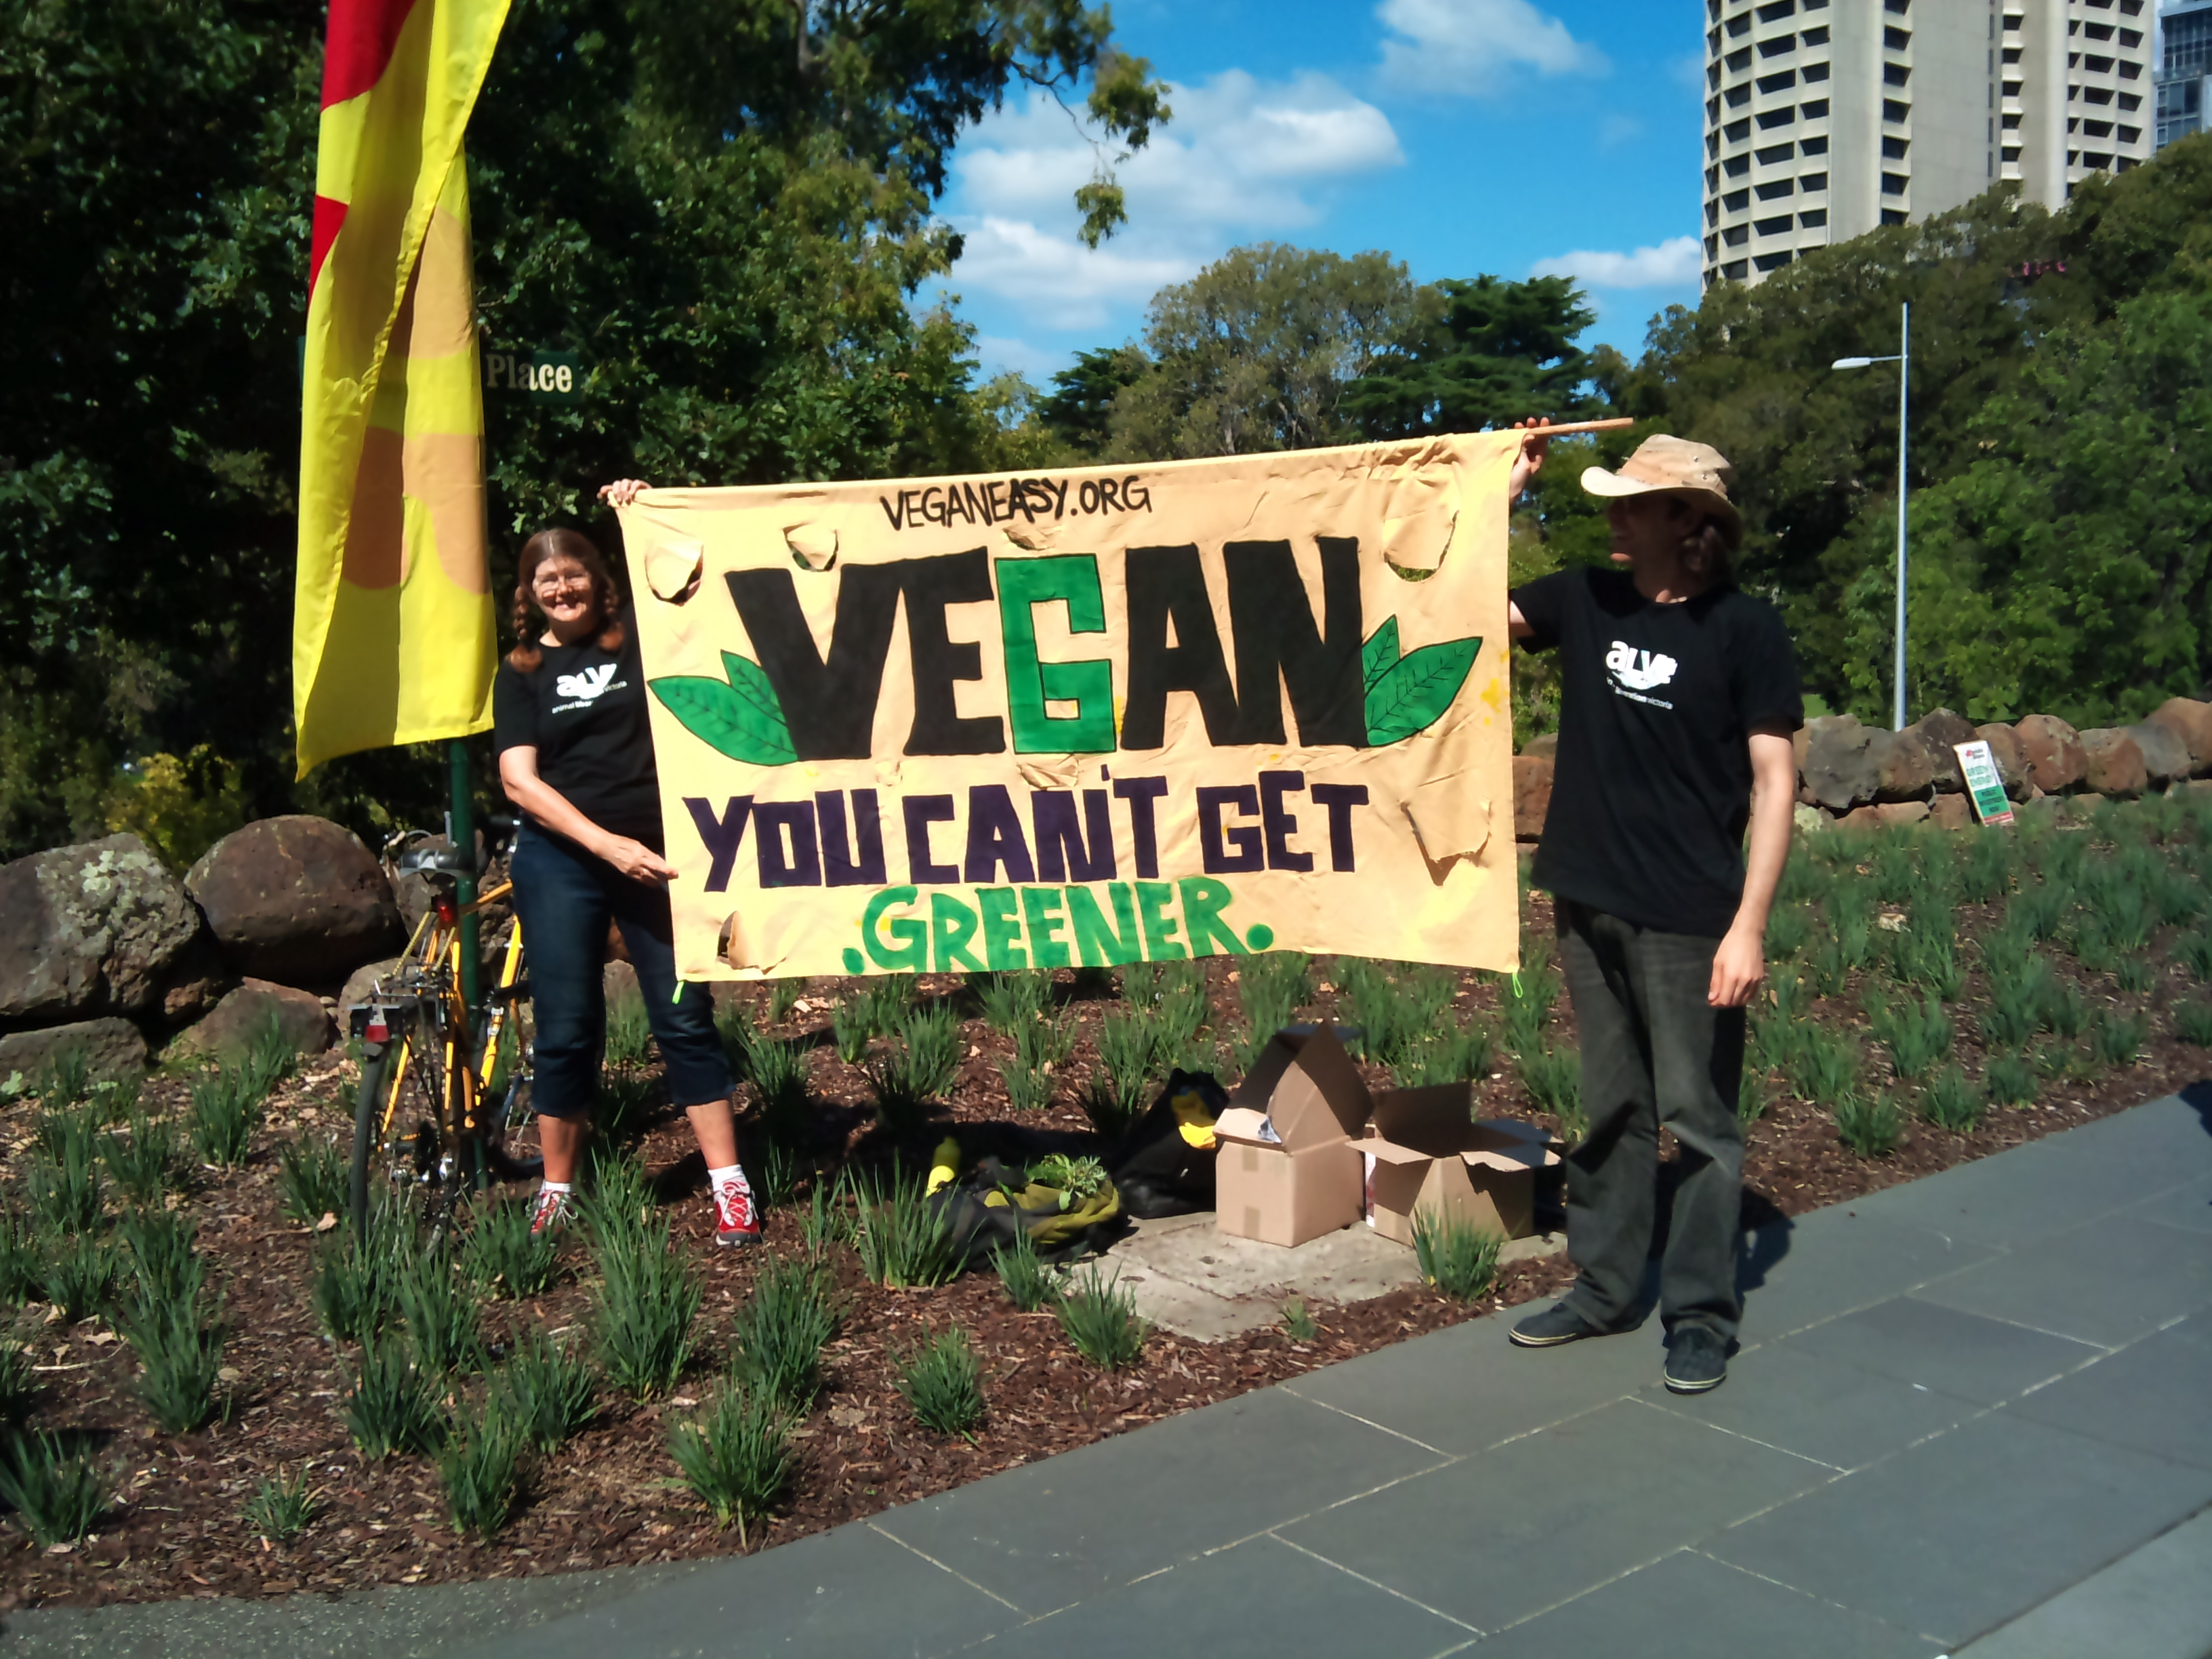
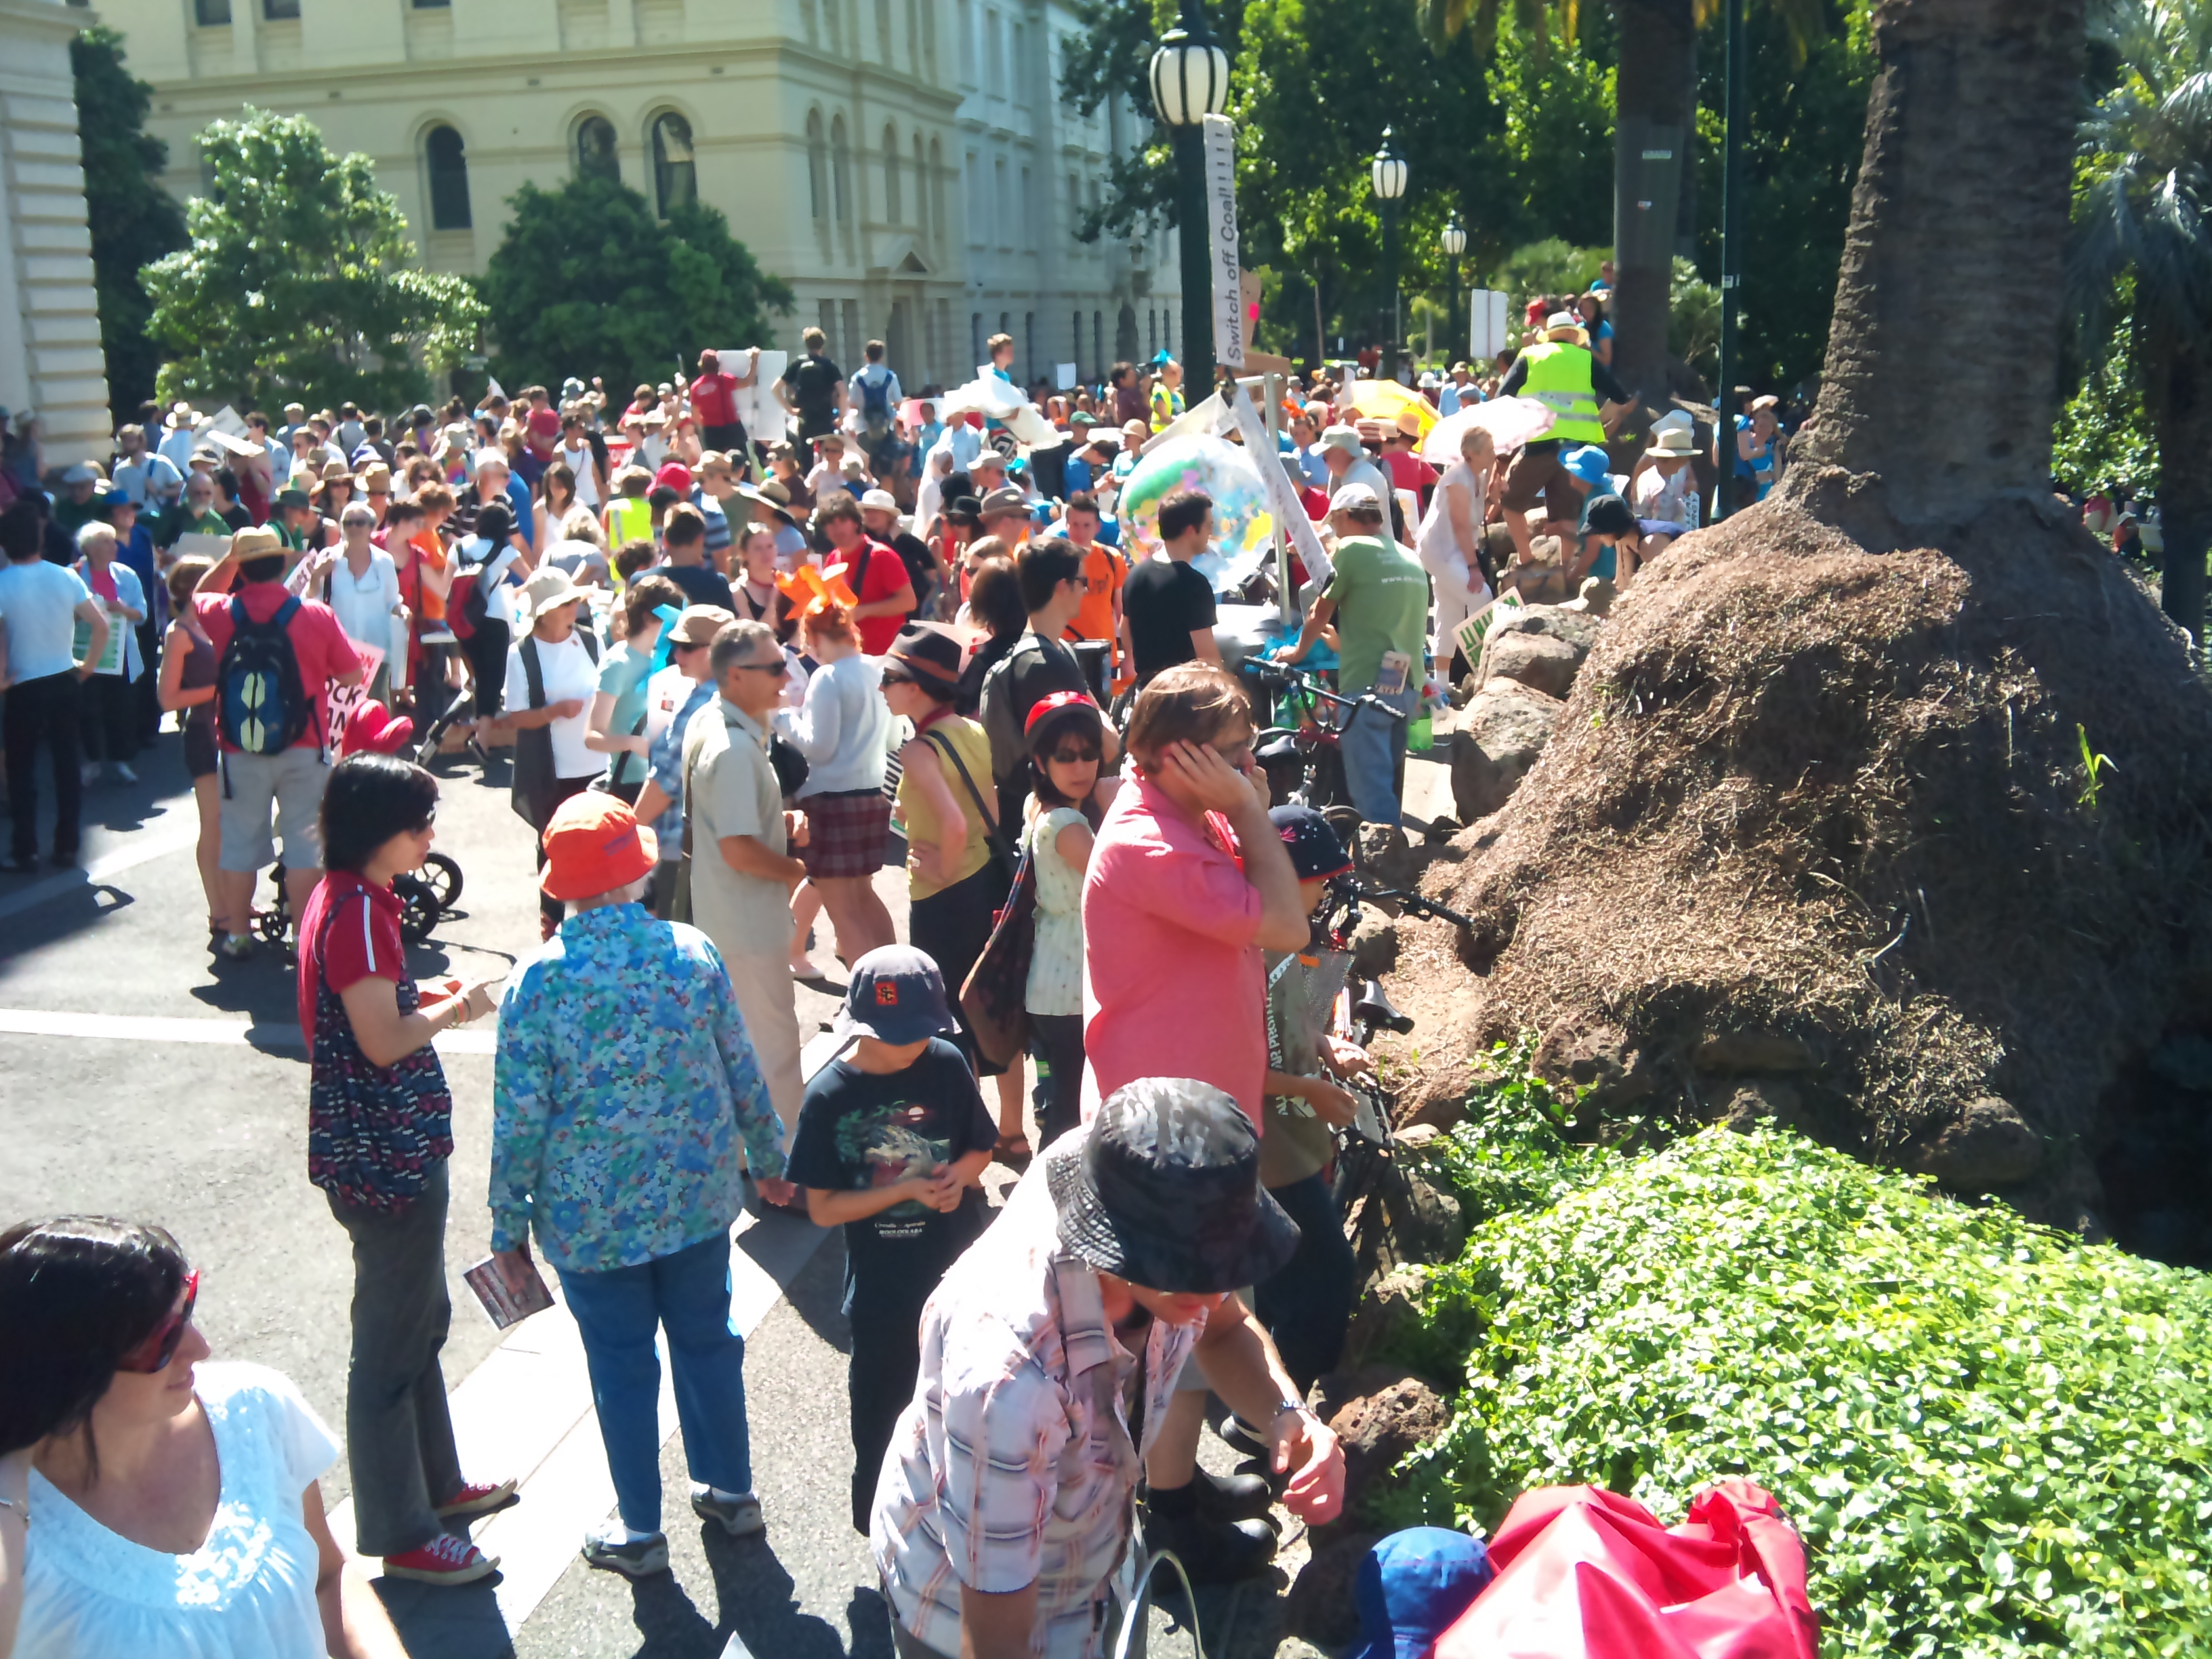
This morning I attended the Climate Action Now rally to support a pollution tax [1]. The event was well attended, my personal estimate of the number of people there was there there was definitely more than 3,000 people, and maybe as many as 8,000 or more.I spoke to an employee of the APS who was on guard duty, he described the event as big and said that they don t usually have events that are so well attended. He gave a personal estimate of 5,000 people. While he wasn t speaking on behalf of the APS he was presumably more skillful at making such estimations than most people. I expect that he also gave a conservative estimate, so it could have been a lot more than that.There were some people using comedy to make political points. Below is a picture of the carbon monster, what you can t see is the man who was handing out coal BBQ fuel for people to feed the monster, children appeared to enjoy that! Also there were three people dressed as Gollum representing the Liberal party (the Australian conservative party), I was unable to get all three in one picture.Carbon monster with sign saying feed me carbonTwo people dressed as Gollum with Liberal Party badges advocating that we die tax-free and that the Liberal party is for famine, fire, and floodSome vegans had a banner supporting the VeganEasy.org site [2]. Being vegetarian can make a significant impact on human environmental impact including on the amount of electricity used (from coal or other sources).Vegans waving a banner for VeganEasy.orgHere are pictures taken looking East over the main part of the rally, looking North towards the building at 3 Treasury place from the other side of the road, looking South over the lawns where people who didn t like being crowded gathered, and looking West over part of the main crowd. The picture looking South shows another view of the Carbon Monster and his accomplice with a sign haven t you had enough dear? .Looking East over the main rallyLooking North towards the building across Treasury PlaceLooking south over the lawnLooking west over the crowdWhen I first arrived there were two main sections to the rally. They weren t discrete (there was no empty space between them) but they acted separately because there was no PA system that could make enough noise to be heard in both sections. At one stage the West section was chanting while there were speeches in the East section. Below is a picture looking out over the West section as people had just turned to go home. This area was entirely packed when I first arrived.The rally was really a family event. There were some grey-haired people wearing t-shirts explaining that they wanted to create a better world for their grand-children and there were also some young children. At the end of the event some children used cardboard signs as toboggans to slide down a steep grassy bank near the main rally area recycling!!! I deliberately chose my photos to try and avoid including children, but even so you can see a few in the background of some of them.

11 March 2011

Julien Danjou: Second OrgCamp Paris

I'll be at the OrgCamp April 2011 in Paris next month. However, I'm not yet sure of what I'll talk about this time. Flattr this

Eddy Petri&#537;or: HOWTO: Making Windows usable and avoiding accidental sending of mails in Microsoft Outlook

I've changed jobs recently and after 5 years of not having to work with a Windows system I am having all sorts of adaptation-to-Windows problems at the new job.

First I just had to have the usual X-mouse behaviour and so I installed True X-Mouse Gizmo for Windows. This provides focus under mouse, middle click paste after select (not perfect, but it works), right click to push to bottom the window.

Second I had to have a virtual desktop, so I installed Microsoft's Virtual Desktop Manager from the PowerToys page. I tried another virtual desktop manager before using MSVDM, but I found it too clumsy so I switched to MSVDM which I knew from way back when I used Windows the last time. Good, now I can have my applications organised the way I am used to.

UPDATE:
I gave up on MSVDM in favour of Virtual Dimension since I wasn't able to send a particular window to the intended desktop unless I had in the taskbar all apps visible (Shared Desktop option). I might try other suggestions (Virtual Dimension does not have a way to send a window directly to a specific desktop, but just to the neighbours of the current one.)


Third, I had to make Caps Lock work as Ctrl. I just can't go back to an inferior setup. I found information on this page and ended up at this page from where I got a zip file with various registry keys which allow the deactivation of caps, or turning it into another Ctrl.

Fourth, I am used to write with diacritics in Romanian with the secondary layout of the standard (SR 13392:2004), so I rushed to Cristian Secar 's page for the keyboard driver since on XP the Romanian layout is retarded (some history in which some arbitrary German guy decided y and z had to be switched on Romanian keyboards and some other similarly weird stuff). Since the installation, my keyboard behaves according to this layout:


Things started to look well, but I soon was reminded that Outlook is an idiotic mailer since it doesn't require a confirmation on send, not even if you didn't set a subject. And this is problematic since sending the mail is done via Alt+S, so if the current layer is NOT Romanian, when I want to type (s with a comma below), a fairly common character in Romanian words, you end up looking like an idiot on the recipient side since they receive an incomplete mail. Remember, no confirmation AND no default spell checking before send. Yay!

At my second such accidental mail sending (of which the last two were sent to the same person), I decided to see if this can't be fixed. I initially looked for changing the short cut, but I couldn't find it (I might be inept at finding things in Windows, remember, I haven't touched Windows systems in the last 5 years) but I found another workaround and decided it's good enough to share with other people that might hit the problem.

Just setup a delay rule following these steps.
1. Go to Tools....Rules Wizard
2. Click 'New' Rule
3. Select "Check messages after sending"
4. Click Next on "Which conditions you want to Check?" dialog.
5. Press yes to "This Rule will be applied to every message" message box
6. In the "What do you want to do with message?" dialog, Select "Defer delivery by a number of minutes"
7. Select your favourite number of minutes.... I usually select 2 mins.
8. Select Finish. and close the Rules Wizard.

Now everytime you send an email it will sit in your outbox
for specified number of minutes. If you ever wanted to change it, delete it etc, You have sufficient time to do it :)


I used 3 minutes for the delay. At least now I can prevent looking retarded in front of people... more than necessary :D .


Oh, and Windows' clock display is retarded. It shows, by default, the hour and minutes, but there's no way to change that in a sane way. If you want the date, you must hover over the clock and it shows it, but the day of week is missing. Great job! You can see that information, too, but you have to drag the toolbar to be 2 or even 3 rows high (here it requires 2, but I've seen people saying they needed 3) to get that information, too. Great! One has to choose between wasting desktop real estate and having access to useful information. Or you could install an independent application for the clock... retarded. I am not making this shit up.

I hope this helped.

Guido G nther: git-buildpackage tip #4: creating remote repositories

In order to ease creation of remote repositories to publish your Debian packaging work git-buildpackage ships gbp-create-remote-repo: If you run
gbp-create-remote-repo --remote-url-pattern='ssh://git.debian.org/home/users/agx/public_git/%(pkg)s.git'
from inside a git repository it will create a remote repository on git.debian.org in the given directory, push your debian, upstream and pristine-tar branches into it and set up branch tracking so you can easily use gbp-pull or git pull to update your local repository from there. '%(pkg)s' will be replaced by the source packages name. If you want to be more explicit you can use:
gbp-create-remote-repo --remote-url-pattern='ssh://git.debian.org/home/users/agx/public_git/foo.git'
so no substitution will take place. In case you only want to push to that repository but not pull from there you can use the --no-track option so gbp-create-repo won't set up any branch tracking. If you specify the remote-url-pattern via gbp.conf calling:
gbp-create-remote-repo
is enough to create a repo on your favorite git server. The default is to create new repositories in the collab-maint repository on alioth.debian.org. This feature is available in your $PATH since 0.5.16 (it was shipped in examples/ before) and was inspired by the Debian OCaml Maintainers dom-new-git-repo work. This blog is flattr enabled.

10 March 2011

Adrian von Bidder: New Toy

Getting a birthday present is always nice, of course. This one made me itch to go outside and hunt for nice motifs, though ... Images are straight from the camera, just a bit cropped (look at the EXIF if you feel like it.) If you don't want to look at the EXIF: the beautiful new lens is the Canon Canon EF 70-200mm 1:2.8 L IS II USM (like all manufacturers, Canon likes to collect funny abbreviations at the end of their product names though I feel they're not as bad as some...), and I truly like what I'm seeing so far. That this lens has excellent sharpness goes without saying (especially on the 40D with modest 10MPixel on a crop sensor), see the comparison with the old EF 100-300mm f/4.5-5.6 USM (the piccolo picture.) Beyond sharpness, there's the 1:2.8 aperture, the IS really keeps what it promises (and is absolutely silent), and AF is quiet and ultra fast as well. I've only got it today, so I took only a few shots I'm confident that CA, flare resistance etc. will live up to reputation though. Now I'm really starting about a full frame camera with higher MP count to take full advantage of my lenses (you may remember that I quite like decent equipment; the wideangle is said to be usable for full frame down to ca. 14mm although it's really designed for crop sensor...) The obvious question is if I really can take better pictures just because I'm now lugging around a 6kg bag of stuff ... but honestly, having a telephoto lens without image stabilisation was a pain, so getting the old tele replaced was the obvious next step.Oh yes, and: see you in Banja Luka! :-)

Michal &#268;iha&#345;: Contributing to phpMyAdmin and GSoC 2011

It looks like questions about contributing to phpMyAdmin are more and more frequent with upcoming GSoC. The fact that is still time for organizations to apply and it's not yet decided whether we will be accepted or not does not change anything. But before asking, please try to look up existing resources. We have lot of information available on wiki, with entry point being contribution page on website. You should find there all basic information how project works. Should you specifically ask for GSoC, we have an applicant guide, which tells you what to do if you want to apply. After last year experiences, we will be even stricter on previous contributions, because it turned out to be good filter for people who would have problems with contributing during GSoC as well. In case you don't know where to start, there is list of junior jobs which should not be that complicated and then there is of course GSoC ideas list with things primarily targeted on GSoC.

Filed under: English Phpmyadmin 0 comments Flattr this!

Rapha&#235;l Hertzog: My Debian package maintainer pledge

When coming back from DebConf9, I wrote this pledge:

As a package maintainer, I will do my best to help the Debian project release a stable version of our operating system. In particular, I will work together with the release team and I will keep all packages associated to my name free of release critical bugs. To this effect, if I m not registered as being busy or in vacation, I will start working on my release critical bugs as soon as possible (in less than 1 week in common cases). If I can t deal with them in a timely fashion, I will state it clearly in the associated bug reports, tag them help and invite other contributors either to provide a patch or to do a non-maintainer upload. If I do not manage to handle release critical bugs in the above described way, or if I almost never deal with any of my RC bugs by myself, I will:
  • not refuse help and even propose co-maintenance to good contributors
  • recognize my failure and actively try to find a new maintainer and/or co-maintainers
  • not complain if the quality assurance team decides to orphan the package
I recognize that my work is not limited to unstable. I will also work with the stable release team and the security team to provide updated packages for the stable and/or testing distribution when some issues deserve it. I am aware of the limits of my skills and my available time and I will avoid packaging software that I would not be able to maintain properly.
It tries to sum up the minimal expectations that Debian should have towards the package maintainers. I tried first to get this pledge integrated into the NM/DM process but the discussion concluded that it would be best to document this in the developers-reference. There s already a chapter called Debian Developer s Duties where this can nicely fit. I submitted this as a wishlist request for the developers-reference soon after and it s still open. Now I went to the next step and prepared a patch that restructures the chapter about developer duties. See #548867 for details.
Follow me on Identi.ca, Twitter and Facebook. Or subscribe to this blog by RSS or by email.

4 comments Liked this article? Click here. My blog is Flattr-enabled.

7 March 2011

Ritesh Raj Sarraf: Microsoft, Nokia and Qt

Nokia has announced that it is selling off its Qt business. This needed to happen given the change in the company's strategy. Microsoft is a software vendor providing Mobile OS, with Nokia being one of its consumers. For Nokia, to have a tier 1 alliance with Microsoft, it would have been important for the company to show positive gesture. With this move, Microsoft and Nokia will strengthen their partnership. This move will focus on tighter integration in between the 2 company's portfolios. Nokia mentioned in the announcement that it'd further continue Qt core development. I don't see what value that has to bring to the company. It either has to do with the company making some money with whatever IP it acquired in Trolltech, or else, it'd be just a phased wise approach in selling off the Qt business. Also it could be Nokia's Plan B, in case the Micro-Noki team fails to build the ecosystem that it is aspiring for. As for Qt, we'll have to see. Given that it is GPL, we don't have too much to worry (hopefully).

Kai Wasserb ch: On building from Source

I've received a few requests to help with failing builds in the past, mainly for packages I maintain (either officially or unofficially). And most of those requests revolve around custom Wine builds. Because this is recurring, I'd like to take the opportunity to write down some general answers which solve most of the problems, so I can point people to this entry. Apart from that, you'll most likely find a lot of answers in the Developer's Reference and the New Maintainers' Guide. Nothing of this is news to Debian Maintainers, but I hope it helps people doing a build for themselves, when they're less experienced.

Gerfried Fuchs: Squeeze RCs

Alright, the stress of the release and its aftermath with respect to the New Website is getting lower. We even were explicitly mentioned for that during the introduction to the category Outstanding Contribution to Open Source/Linux/Free Software at this year's Linux New Media Awards. Given that the Webmaster Team is much more energetic and lively these days I will shift a bit of my efforts to stable RC squashing again. I came to the conclusion that working on lenny RCs doesn't gain much of appreciation or real turnaround, and given that my time is limited I started to switch over to work on squeeze RCs. This is the list of bugs that I squashed last week (actually, marked them as invalid/not affecting squeeze): I hope to be able to keep up that pace for a few weeks (currently there are 168 RC bugs in squeeze listed), and hopefully being able to motivate others to also support our stable release instead of only working on unstable.

/debian permanent link Comments: 0 Flattr this

Next.

Previous.