Search Results: "ed"

14 August 2025

Jonathan McDowell: Local Voice Assistant Step 4: openWakeWord

People keep asking me when I ll write the next instalment of my local voice assistant journey. I didn t mean for it to be so long since the last one, things have been busier than I d like. Anyway. Last time we d built Tensorflow, so now it s time to sort out openWakeWord. As a reminder we re trying to put a local voice satellite on my living room Debian media machine. The point of openWakeWord is to run on the machine the microphone is connected to, listening for the wake phrase ( Hey Jarvis in my case), and only then calling back to the central server to do a speech to text operation. It s wrapped up for Wyoming as wyoming-openwakeword. Of course I ve packaged it up - available at https://salsa.debian.org/noodles/wyoming-openwakeword. Trixie only released yesterday, so I m still running all of this on bookworm. That means you need python3-wyoming from Trixie - 1.6.0-1 will install fine without needing rebuilt - and the python3-tflite-runtime we built last time. Like the other pieces I m not sure about how this could land in Debian; it s unclear to me that the pre-trained models provided would be accepted in main. As usual I start it with with a systemd unit file dropped in /etc/systemd/service/wyoming-openwakeword.service:
[Unit]
Description=Wyoming OpenWakeWord server
After=network.target
[Service]
Type=simple
DynamicUser=yes
ExecStart=/usr/bin/wyoming-openwakeword --uri tcp://[::1]:10400/ --preload-model 'hey_jarvis' --threshold 0.8
MemoryDenyWriteExecute=false
ProtectControlGroups=true
PrivateDevices=false
ProtectKernelTunables=true
ProtectSystem=true
RestrictRealtime=true
RestrictNamespaces=true
[Install]
WantedBy=multi-user.target
I m still playing with the threshold level. It defaults to 0.5, but the device lives under the TV and seems to get a bit confused by it sometimes. There s some talk about using speex for noise suppression, but I haven t explored that yet (it s yet another Python module to bind to the C libraries I d have to look at). This is a short one; next post is actually building the local satellite on top to tie everything together.

13 August 2025

Sven Hoexter: Automated Browsing with Gemini and Chrome via BrowserMCP and gemini-cli

Brief dump so I don't forget how that worked in August 2025. Requires npm, npx and nodejs.
  1. Install Chrome
  2. Add the BrowserMCP extension
  3. Install gemini-cli npm install -g @google/gemini-cli
  4. Retrieve a Gemini API key via AI Studio
  5. Export API key for gemini-cli export GEMINI_API_KEY=2342
  6. Start BrowserMCP extension, see manual, an info box will appear that it's active with a cancel button.
  7. Add mcp server to gemini-cli gemini mcp add browsermcp npx @browsermcp/mcp@latest
  8. Start gemini-cli, let it use the mcp server and task it to open a website.

12 August 2025

Sergio Cipriano: Running Docker (OCI) Images in Incus

Running Docker (OCI) Images in Incus Incus 6.15 released with a lot of cool features, my favorite so far is the authentication support for OCI registries. Here's an example:
$ incus remote add docker https://docker.io --protocol=oci
$ incus launch docker:debian:sid sid
$ incus shell sid
root@sid:~# apt update && apt upgrade -y
root@sid:~# cat /etc/os-release 
PRETTY_NAME="Debian GNU/Linux forky/sid"
NAME="Debian GNU/Linux"
VERSION_CODENAME=forky
ID=debian
HOME_URL="https://www.debian.org/"
SUPPORT_URL="https://www.debian.org/support"
BUG_REPORT_URL="https://bugs.debian.org/"
This has been really useful for creating containers to test packages, much better than launching the official Debian stable Incus images and then manually changing the sources list.

Freexian Collaborators: Debian Contributions: DebConf 25, OpenSSH upgrades, Cross compilation collaboration and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-07 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 25, by Stefano Rivera and Santiago Ruano Rinc n In July, DebConf 25 was held in Brest, France. Freexian was a gold sponsor and most of the Freexian team attended the event. Many fruitful discussions were had amongst our team and within the Debian community. DebConf itself was organized by a local team in Brest, that included Santiago (who now lives in Uruguay). Stefano was also deeply involved in the organization, as a DebConf committee member, core video team, and the lead developer for the conference website. Running the conference took an enormous amount of work, consuming all of Stefano and Santiago s time for most of July. Lucas Kanashiro was active in the DebConf content team, reviewing talks and scheduling them. There were many last-minute changes to make during the event. Anupa Ann Joseph was part of the Debian publicity team doing live coverage of DebConf 25 and was part of the DebConf 25 content team reviewing the talks. She also assisted the local team to procure the lanyards. Recorded sessions presented by Freexian collaborators, often alongside other friends in Debian, included:

OpenSSH upgrades, by Colin Watson Towards the end of a release cycle, people tend to do more upgrade testing, and this sometimes results in interesting problems. Manfred Stock reported No new SSH connections possible during large part of upgrade to Debian Trixie , which would have affected many people upgrading from Debian 12 (bookworm), with potentially severe consequences for people upgrading remote systems. In fact, there were two independent problems that each led to much the same symptom:
  • As part of hardening the OpenSSH server, OpenSSH 9.8 split the monolithic sshd listener process into two pieces: a minimal network listener (still called sshd), and an sshd-session process dealing with each individual session. Before this change, when sshd received an incoming connection, it forked and re-executed itself with some special parameters to deal with it; after this change, it forks and executes sshd-session instead, and sshd no longer accepts the parameters it used to accept for this.

    Debian package upgrades happen (roughly) in two phases: first we unpack the new files onto disk, and then we run some configuration steps which usually include things like restarting services. Normally this is fine, because the old service keeps on working until it s restarted. In this case, unpacking the new files onto disk immediately stopped new SSH connections from working: the old sshd received the connection and tried to hand it off to a freshly-executed copy of the new sshd binary on disk, which no longer supports this. This wasn t much of a problem when upgrading OpenSSH on its own or with a small number of other packages, but in release upgrades it left a large gap when you can t SSH to the system any more, and if anything fails in that interval then you could be in trouble.

    After trying a couple of other approaches, Colin landed on the idea of having the openssh-server package divert /usr/sbin/sshd to /usr/sbin/sshd.session-split before the unpack step of an upgrade from before 9.8, then removing the diversion and moving the new file into place once it s ready to restart the service. This reduces the period when new connections fail to a minimum.
  • Most OpenSSH processes, including sshd, check for a compatible version of the OpenSSL library when they start up. This check used to be very picky, among other things requiring both the major and minor part of the version number to match. OpenSSL 3 has a better versioning policy, and so OpenSSH 9.4p1 relaxed this check.

    Unfortunately, bookworm shipped with OpenSSH 9.2p1, so as soon as you unpacked the new OpenSSL library during an upgrade, sshd stopped working. This couldn t be fixed by a change in trixie; we needed to change bookworm in advance of the upgrade so that it would tolerate newer versions of OpenSSL, and time was tight if we wanted this to be available before the release of Debian 13.

    Fortunately, there s a stable-updates mechanism for exactly this sort of thing, and the stable release managers kindly accepted Colin s proposal to fix this there.
The net result is that if you apply updates to bookworm (including stable-updates / bookworm-updates, which is enabled by default) before starting the upgrade to trixie, everything should be fine.

Cross compilation collaboration, by Helmut Grohne Supporting cross building in Debian packages touches lots of areas of the archive and quite some of these matters reside in shared responsibility between different teams. Hence, DebConf was an ideal opportunity to settle long-standing issues. The cross building bof sparked lively discussions as a significant fraction of developers employ cross builds to get their work done. In the trixie release, about two thirds of the packages can satisfy their cross Build-Depends and about half of the packages actually can be cross built.

Miscellaneous contributions
  • Rapha l Hertzog updated tracker.debian.org to remove references to Debian 10 which was moved to archive.debian.org, and had many fruitful discussions related to Debusine during DebConf 25.
  • Carles Pina prepared some data, questions and information for the DebConf 25 l10n and i18n BoF.
  • Carles Pina demoed and discussed possible next steps for po-debconf-manager with different teams in DebConf 25. He also reviewed Catalan translations and sent them to the packages.
  • Carles Pina started investigating a django-compressor bug: reproduced the bug consistently and prepared a PR for django-compressor upstream (likely more details next month). Looked at packaging frictionless-py.
  • Stefano Rivera triaged Python CVEs against pypy3.
  • Stefano prepared an upload of a new upstream release of pypy3 to Debian experimental (due to the freeze).
  • Stefano uploaded python3.14 RC1 to Debian experimental.
  • Thorsten Alteholz uploaded a new upstream version of sane-airscan to experimental. He also started to work on a new upstream version of hplip.
  • Colin backported fixes for CVE-2025-50181 and CVE-2025-50182 in python-urllib3, and fixed several other release-critical or important bugs in Python team packages.
  • Lucas uploaded ruby3.4 to experimental as a starting point for the ruby-defaults transition that will happen after Trixie release.
  • Lucas coordinated with the Release team the fix of the remaining RC bugs involving ruby packages, and got them all fixed.
  • Lucas, as part of the Debian Ruby team, kicked off discussions to improve internal process/tooling.
  • Lucas, as part of the Debian Outreach team, engaged in multiple discussions around internship programs we run and also what else we could do to improve outreach in the Debian project.
  • Lucas joined the Local groups BoF during DebConf 25 and shared all the good experiences from the Brazilian community and committed to help to document everything to try to support other groups.
  • Helmut spent significant time with Samuel Thibault on improving architecture cross bootstrap for hurd-any mostly reviewing Samuel s patches. He proposed a patch for improving bash s detection of its pipesize and a change to dpkg-shlibdeps to improve behavior for building cross toolchains.
  • Helmut reiterated the multiarch policy proposal with a lot of help from Nattie Mayer-Hutchings, Rhonda D Vine and Stuart Prescott.
  • Helmut finished his work on the process based unschroot prototype that was the main feature of his talk (see above).
  • Helmut analyzed a multiarch-related glibc upgrade failure induced by a /usr-move mitigation of systemd and sent a patch and regression fix both of which reached trixie in time. Thanks to Aurelien Jarno and the release team for their timely cooperation.
  • Helmut resurrected an earlier discussion about changing the semantics of Architecture: all packages in a multiarch context in order to improve the long-standing interpreter problem. With help from Tollef Fog Heen better semantics were discovered and agreement was reached with Guillem Jover and Julian Andres Klode to consider this change. The idea is to record a concrete architecture for every Architecture: all package in the dpkg database and enable choosing it as non-native.
  • Helmut implemented type hints for piuparts.
  • Helmut reviewed and improved a patch set of Jochen Sprickerhof for debvm.
  • Anupa was involved in discussions with the Debian Women team during DebConf 25.
  • Anupa started working for the trixie release coverage and started coordinating release parties.
  • Emilio helped coordinate the release of Debian 13 trixie.

11 August 2025

David Bremner: Hibernate on the pocket reform 11/n

Context

Update to latest rockchip-devel
  • rebase reform-patches on top of collabora/rockchip-devel
  • pci reset series has new conflicts
  • try dropping from rebase and re-applying
$ b4 am 20250715-pci-port-reset-v6-0-6f9cce94e7bb@oss.qualcomm.com
# follow hint from b4
$ git checkout -b v6_20250715_manivannan_sadhasivam_oss_qualcomm_com 19272b37aa4f83ca52bdf9c16d5d81bdd1354494
$ git am ./v6_20250715_manivannan_sadhasivam_pci_add_support_for_resetting_the_root_ports_in_a_platform_specifi.mbx
$ git rebase -i collabora/rockchip-devel
  • conflict in pcie-qcom.c: take new version
  • conflict in pcie-dw-rockchip.c resolved as in hibernate-pocket-8
  • rebase reform patches on top of pci reset, instead of vice versa.
  • rebuild as discussed in hibernate-pocket-8
$ cp /boot/config-6.16.0-rc7+ .config
$ make olddefconfig
# this generates a message about "reform2_lpc config not found!!"
# and "rockchip_vdec2 config not found!!"
# hopefully this is ok
$ yes ''   make localmodconfig
$ make KBUILD_IMAGE=arch/arm64/boot/Image bindeb-pkg -j$(nproc)
previous episode

10 August 2025

Jonathan Carter: Debian 13

Debian 13 has finally been released! One of the biggest and under-hyped features is support for HTTP Boot. This allows you to simply specify a URL (to any d-i or live image iso) in your computer s firmware setup and then you can boot to it directly over the Internet, so no need to download an image, write it to flash disk and then boot from the flash disk on computers made in the last ~5 years. This is also supported on the Tianocore free EFI firmware, which is useful if you d like to try it out on QEMU/KVM. More details about Debian 13 available on the official press release. The default theme for Debian 13 is Ceratopsian, designed by Elise Couper. I ll be honest, I wasn t 100% sure it was the best choice when it won the artwork vote, but it really grew on me over the last few months, and it looked great in combination with all kinds of other things during DebConf too, so it has certainly won me over.
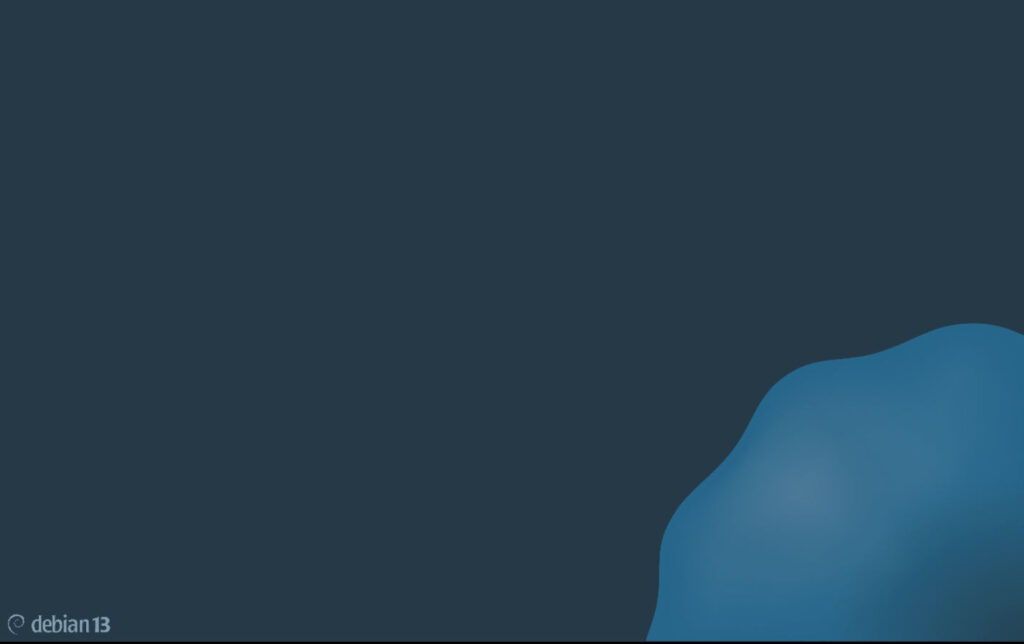
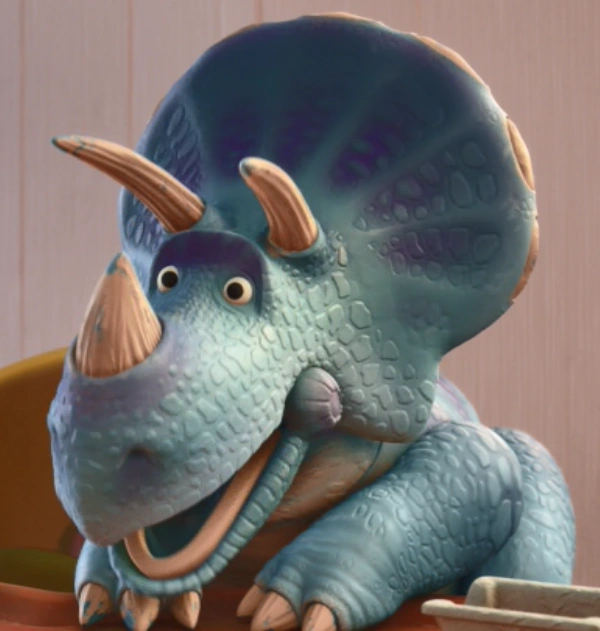
And I particularly like the Plymouth theme. It s very minimal, and it reminds me of the Toy Story Trixie character, it s almost like it helps explain the theme:

Plymouth (start-up/shutdown) theme.

Trixie, the character from Toy Story that was chosen as the codename for Debian 13.

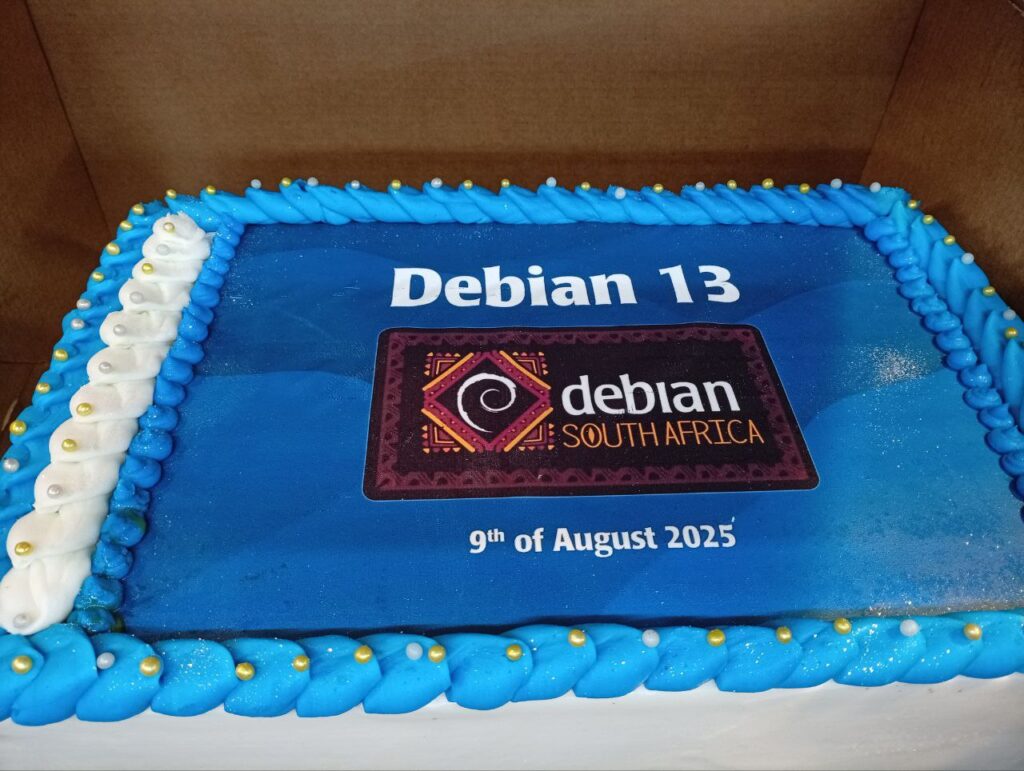
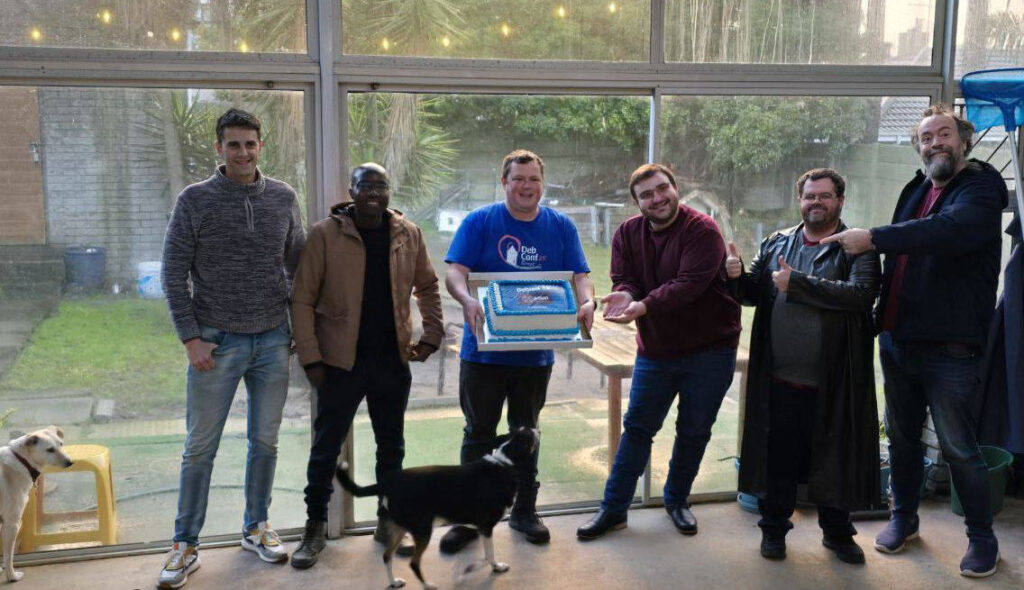
Debian Local Team ISO testing Yesterday we got some locals together for ISO testing and we got a cake with the wallpaper printed on it, along with our local team logo which has been a work in progress for the last 3 years, so hopefully we ll finalise it this year! (it will be ready when it s ready). It came out a lot bluer than the original wallpaper, but still tasted great.
For many releases, I ve been the only person from South Africa doing ISO smoke-testing, and this time was quite different, since everyone else in the photo below tested an image except for me. I basically just provided some support and helped out with getting salsa/wiki accounts and some troubleshooting. It went nice and fast, and it s always a big relief when there are no showstoppers for the release.

My dog was really wishing hard that the cake would slip off.

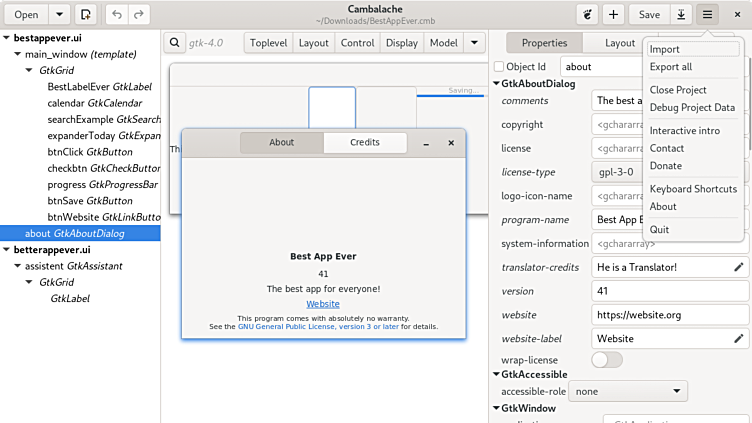
Packaging-wise, I only have one big new package for Trixie, and that s Cambalache, a rapid application design UI builder for GTK3/GTK4.
The version in trixie is 0.94.1-3 and version 1.0 was recently released, so I ll get that updated in forky and backport it if possible. I was originally considering using Cambalache for an installer UI, but ended up going with a web front-end instead. But that s moving firmly towards forky territory, so more on that another time! Thanks to everyone who was involved in this release, so far upgrades have been very smooth!

C.J. Collier: Upgrading Proxmox 7 to 8

Some variant of the following[1] worked for me. The first line is the start of a for loop that runs on each node in my cluster a command using ssh. The argument -t is passed to attach a controlling terminal to STDIN, STDERR and STDOUT of this session, since there will not be an intervening shell to do it for us. The argument to ssh is a workflow of bash commands. They upgrade the 7.x system to the most recent packages on the repository. We then update the sources.list entries for the system to point at bookworm sources instead of bullseye. The package cache is updated and the proxmox-ve package is installed. Packages which are installed are upgraded to the versions from bookworm, and the installer concludes. Dear reader, you might be surprised how many times I saw the word perl scroll by during the manual, serial scrolling of this install. It took hours. There were a few prompts, so stand by the keyboard! [1]
gpg: key 1140AF8F639E0C39: public key "Proxmox Bookworm Release Key " imported
# have your ssh agent keychain running and a key loaded that's installed at 
# ~root/.ssh/authorized_keys on each node 
apt-get install -y keychain
eval $(keychain --eval)
ssh-add ~/.ssh/id_rsa
# Replace the IP address prefix (100.64.79.) and  suffixes (64, 121-128)
# with the actual IPs of your cluster nodes.  Or use hostnames :-)
for o in 64 121 122 123 124 125 126 127 128 ; do   ssh -t root@100.64.79.$o '
  sed -i -e s/bullseye/bookworm/g /etc/apt/sources.list $(compgen -G "/etc/apt/sources.listd.d/*.list") \
  && echo "deb [signed-by=/usr/share/keyrings/proxmox-release.gpg] http://download.proxmox.com/debian/pve bookworm pve-no-subscription" \
      dd of=/etc/apt/sources.list.d/proxmox-release.list status=none \
  && echo "deb [signed-by=/usr/share/keyrings/proxmox-release.gpg] http://download.proxmox.com/debian/ceph-quincy bookworm main no-subscription" \
      dd of=/etc/apt/sources.list.d/ceph.list status=none \
  && proxmox_keyid="0xf4e136c67cdce41ae6de6fc81140af8f639e0c39" \
  && curl "https://keyserver.ubuntu.com/pks/lookup?op=get&search=$ proxmox_keyid " \
      gpg --dearmor -o /usr/share/keyrings/proxmox-release.gpg  \
  && apt-get -y -qq update \
  && apt-get -y -qq install proxmox-ve \
  && apt-get -y -qq full-upgrade \
  && echo "$(hostname) upgraded"'; done

9 August 2025

Bits from Debian: Debian stable is now Debian 13 "trixie"!

Alt trixie has been released We are pleased to announce the official release of Debian 13, codenamed trixie! What's New in Debian 13 Want to install it? Fresh installation ISOs are now available, including the final Debian Installer featuring kernel 6.12.38 and mirror improvements. Choose your favourite installation media and read the installation manual. You can also use an official cloud image directly on your cloud provider, or try Debian prior to installing it using our "live" images. Already a happy Debian user and you only want to upgrade? Full upgrade path from Debian 12 "bookworm" is supported and documented in the Release Notes. Upgrade notes cover APT source preparation, handling obsoletes, and ensuring system resilience. Additional Information For full details, including upgrade instructions, known issues, and contributors, see the official Release Notes for Debian 13 "trixie". Congratulations to all developers, QA testers, and volunteers who made Debian 13 "trixie" possible! Do you want to celebrate the release? To celebrate with us on this occassion find a release party near to you and if there isn't any, organize one!

Thorsten Alteholz: My Debian Activities in July 2025

Debian LTS This was my hundred-thirty-third month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on: I also continued my work on suricata, which turned out to be more challenging than expected. This month I also did a week of FD duties and attended the monthly LTS/ELTS meeting. Debian ELTS This month was the eighty-fourth ELTS month. Unfortunately my allocated hours were far less than expected, so I couldn t do as much work as planned. Most of the time I spent with FD tasks and I also attended the monthly LTS/ELTS meeting. I further listened to the debusine talks during debconf. On the one hand I would like to use debusine to prepare uploads for embargoed ELTS issues, on the other hand I would like to use debusine to run the version of lintian that is used in the different releases. At the moment some manual steps are involved here and I tried to automate things. Of course like for LTS, I also continued my work on suricata. Debian Printing This month I uploaded a new upstream version of: Guess what, I also started to work on a new version of hplip and intend to upload it in August. This work is generously funded by Freexian! Debian Astro This month I uploaded new upstream versions of: I also uploaded the new package boinor. This is a fork of poliastro, which was retired by upstream and removed from Debian some months ago. I adopted it and rebranded it at the desire of upstream. boinor is the abbreviation of BOdies IN ORbit and I hope this software is still useful. Debian Mobcom Unfortunately I didn t found any time to work on this topic. misc On my fight against outdated RFPs, I closed 31 of them in July. Their number is down to 3447 (how can you dare to open new RFPs? :-)). Don t be afraid of them, they don t bite and are happy to be released to a closed state. FTP master The peace will soon come to an end, so this month I accepted 87 and rejected 2 packages. The overall number of packages that got accepted was 100.

Valhalla's Things: MOAR Pattern Weights

Posted on August 9, 2025
Tags: madeof:atoms
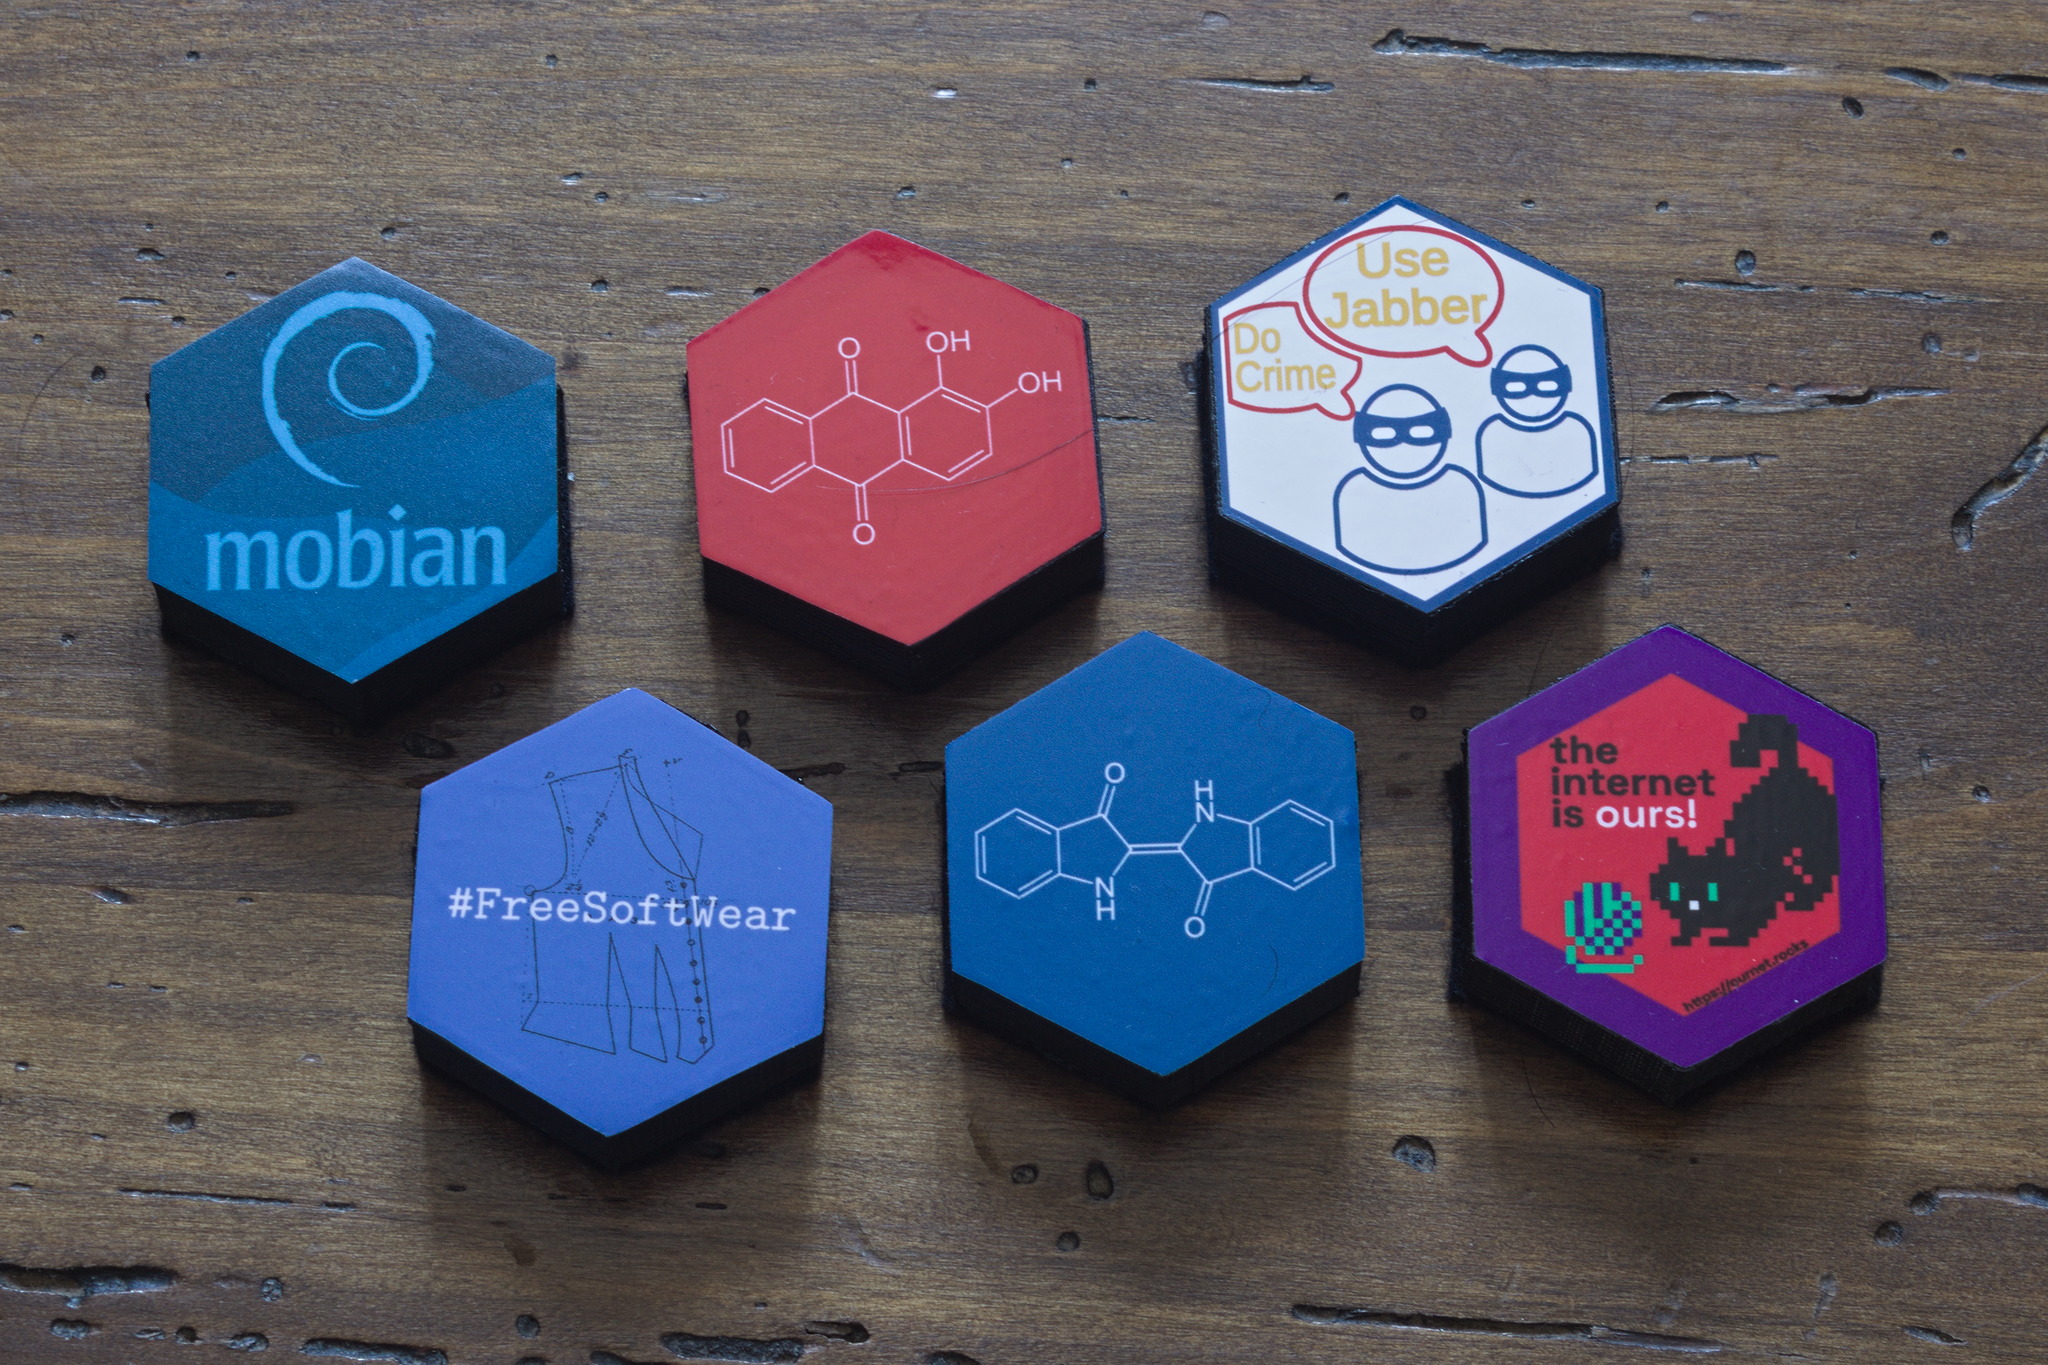
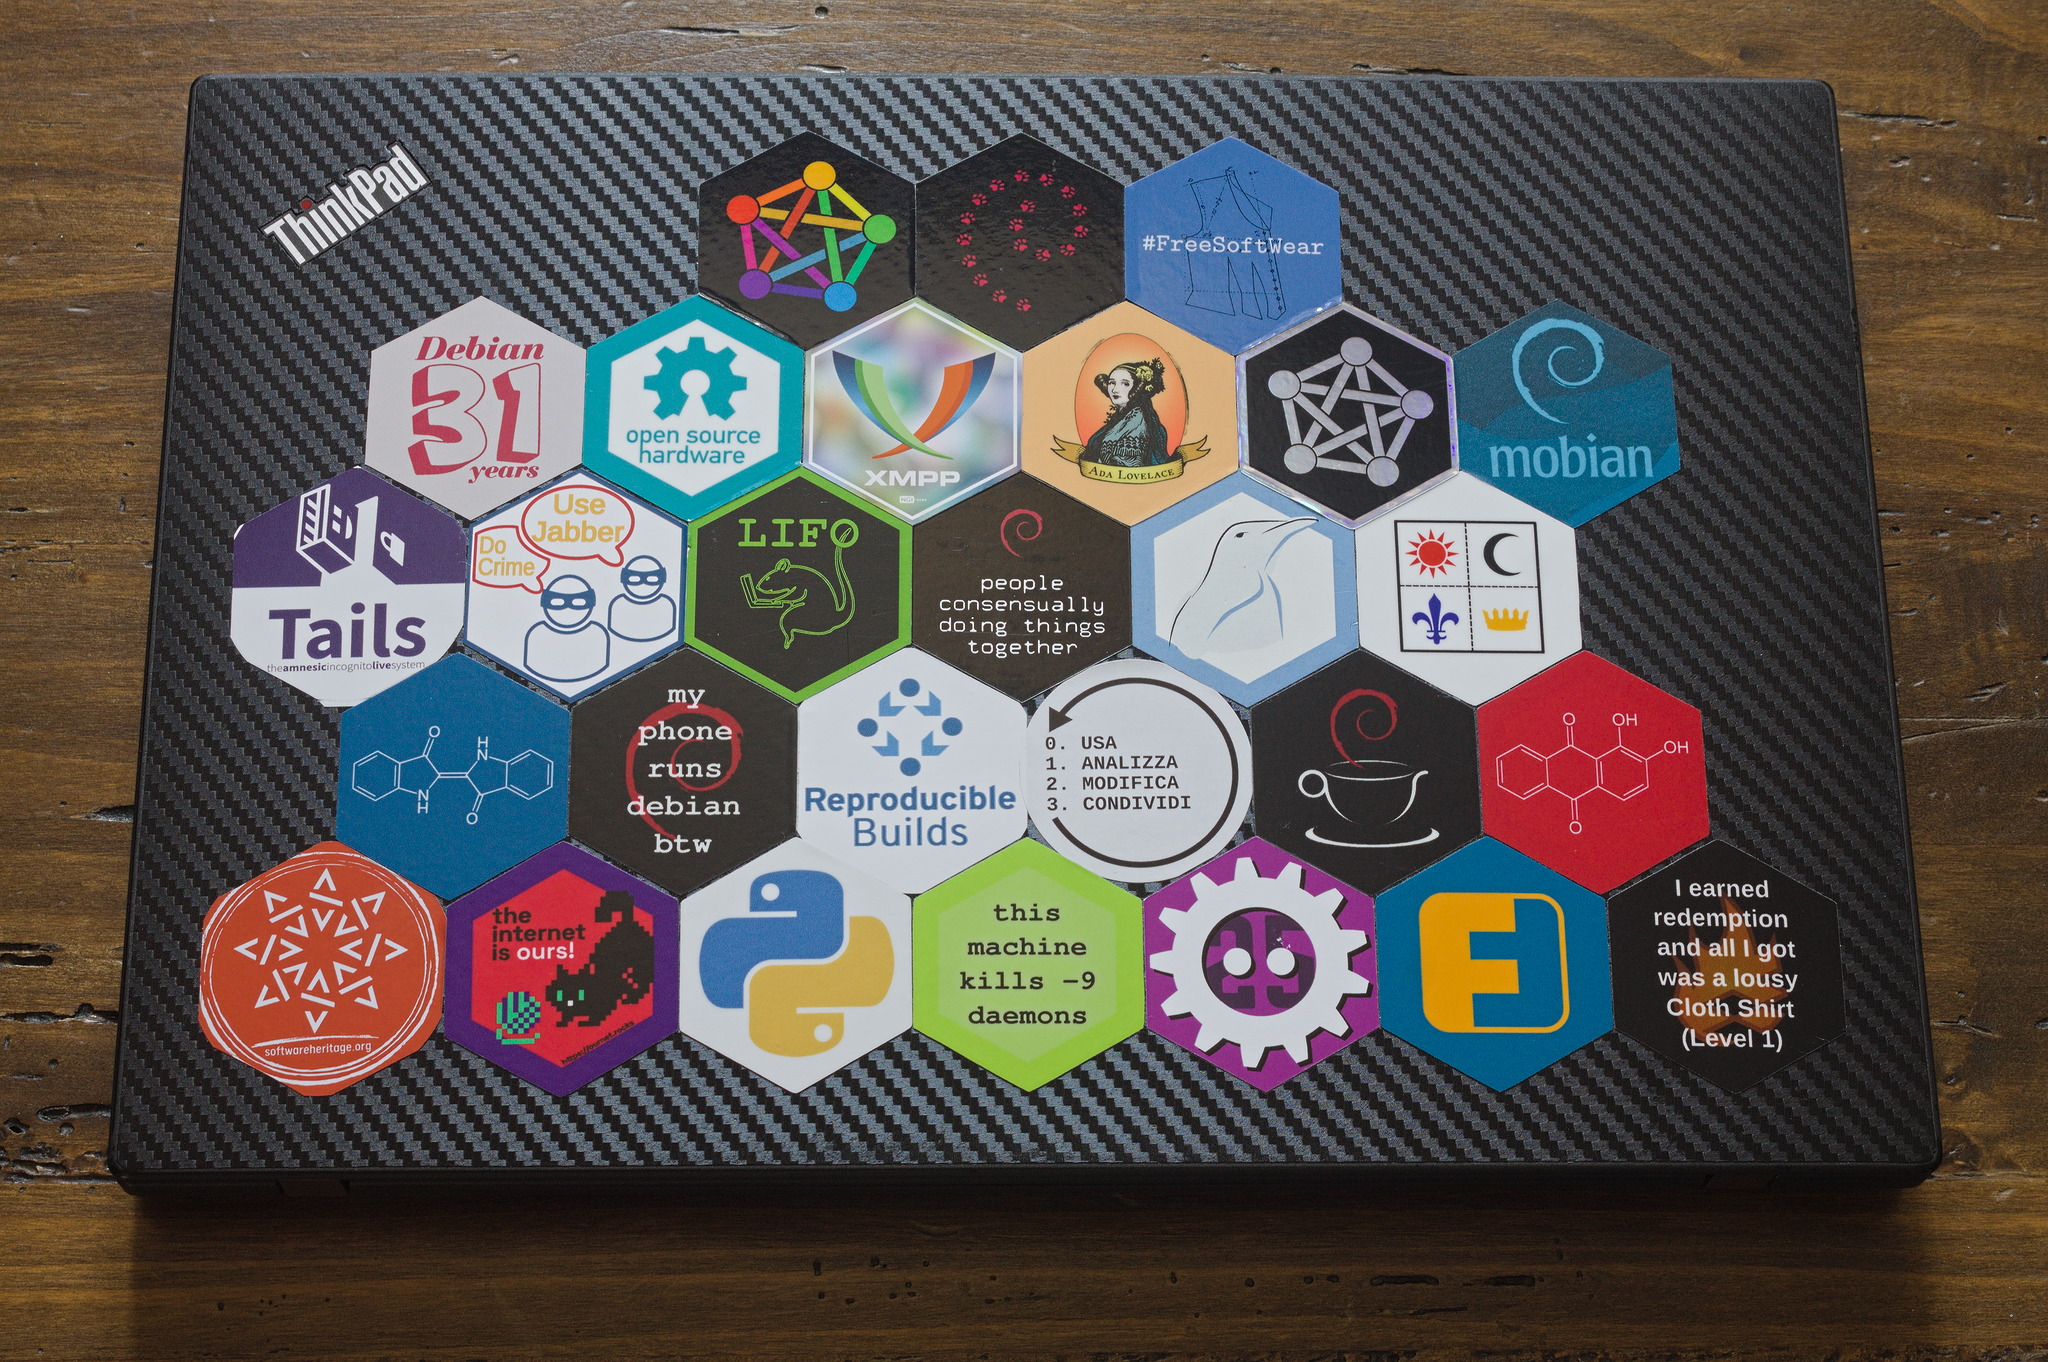
Six hexagonal blocks with a Standard Compliant sticker on top: mobian (blue variant), alizarin molecule, Use Jabber / Do Crime, #FreeSoftWear, indigotin molecule, The internet is ours with a cat that plays with yarn. I ve collected some more Standard Compliant stickers. A picture of the lid of my laptop: a relatively old thinkpad carpeted with hexagonal stickers: Fediverse, a Debian swirl made of cat paw prints, #FreeSoftWear, 31 years of Debian, Open Source Hardware, XMPP, Ada Lovelace, rainbow holographic Fediverse, mobian (blue sticker), tails (cut from a round one), Use Jabber / Do Crime, LIFO, people consensually doing things together (center piece), GL-Como, Piecepack, indigotin, my phone runs debian btw, reproducible builds (cut from round), 4 freedoms in Italian (cut from round), Debian tea, alizarin, Software Heritage (cut from round), ournet.rocks (the cat also seen above), Python, this machine kills -9 daemons, 25 years of FOSDEM, Friendica, Flare. There are only 5 full hexagonal slots free. Some went on my laptop, of course, but some were selected for another tool I use relatively often: more pattern weights like the ones I blogged about in February. And of course the sources: I have enough washers to make two more weights, and even more stickers, but the printer is currently not in use, so I guess they will happen a few months or so in the future.

6 August 2025

Reproducible Builds: Reproducible Builds in July 2025

Welcome to the seventh report from the Reproducible Builds project in 2025. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this report:
  1. Reproducible Builds Summit 2025
  2. Reproducible Builds an official goal for SUSE Enterprise Linux
  3. Reproducible Builds at FOSSY 2025
  4. New OSS Rebuild project from Google
  5. New extension of Python setuptools to support reproducible builds
  6. diffoscope
  7. New library to patch system functions for reproducibility
  8. Independently Reproducible Git Bundles
  9. Website updates
  10. Distribution work
  11. Reproducibility testing framework
  12. Upstream patches

Reproducible Builds Summit 2025 We are extremely pleased to announce the upcoming Reproducible Builds Summit, set to take place from October 28th 30th 2025 in Vienna, Austria! We are thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving. If you re interesting in joining us this year, please make sure to read the event page which has more details about the event and location. Registration is open until 20th September 2025, and we are very much looking forward to seeing many readers of these reports there!

Reproducible Builds an official goal for SUSE Enterprise Linux On our mailing list this month, Bernhard M. Wiedemann revealed the big news that reproducibility is now an official goal for SUSE Linux Enterprise Server (SLES) 16:
[Everything] changed earlier this year when reproducible-builds for SLES-16 became an official goal for the product. More people are talking about digital sovereignty and supply-chain security now. [ ] Today, only 9 of 3319 (source) packages have significant problems left (plus 7 with pending fixes), so 99.5% of packages have reproducible builds.

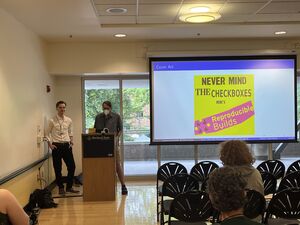
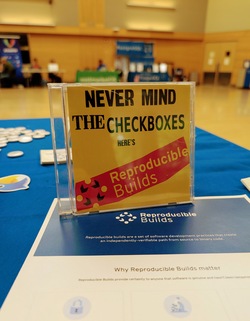
Reproducible Builds at FOSSY 2025 On Saturday 2nd August, Vagrant Cascadian and Chris Lamb presented at this year s FOSSY 2025. Their talk, titled Never Mind the Checkboxes, Here s Reproducible Builds!, was introduced as follows:
There are numerous policy compliance and regulatory processes being developed that target software development but do they solve actual problems? Does it improve the quality of software? Do Software Bill of Materials (SBOMs) actually give you the information necessary to verify how a given software artifact was built? What is the goal of all these compliance checklists anyways or more importantly, what should the goals be? If a software object is signed, who should be trusted to sign it, and can they be trusted forever?
Hosted by the Software Freedom Conservancy and taking place in Portland, Oregon, USA, FOSSY aims to be a community-focused event: Whether you are a long time contributing member of a free software project, a recent graduate of a coding bootcamp or university, or just have an interest in the possibilities that free and open source software bring, FOSSY will have something for you . More information on the event is available on the FOSSY 2025 website, including the full programme schedule. Vagrant and Chris also staffed a table, where they will be available to answer any questions about Reproducible Builds and discuss collaborations with other projects.

New OSS Rebuild project from Google The Google Open Source Security Team (GOSST) published an article this month announcing OSS Rebuild, a new project to strengthen trust in open source package ecosystems by reproducing upstream artifacts. As the post itself documents, the new project comprises four facets:
  • Automation to derive declarative build definitions for existing PyPI (Python), npm (JS/TS), and Crates.io (Rust) packages.
  • SLSA Provenance for thousands of packages across our supported ecosystems, meeting SLSA Build Level 3 requirements with no publisher intervention.
  • Build observability and verification tools that security teams can integrate into their existing vulnerability management workflows.
  • Infrastructure definitions to allow organizations to easily run their own instances of OSS Rebuild to rebuild, generate, sign, and distribute provenance.
One difference with most projects that aim for bit-for-bit reproducibility, OSS Rebuild aims for a kind of semantic reproducibility:
Through automation and heuristics, we determine a prospective build definition for a target package and rebuild it. We semantically compare the result with the existing upstream artifact, normalizing each one to remove instabilities that cause bit-for-bit comparisons to fail (e.g. archive compression).
The extensive post includes examples about how to access OSS Rebuild attestations using the Go-based command-line interface.

New extension of Python setuptools to support reproducible builds Wim Jeantine-Glenn has written a PEP 517 Build backend in order to enable reproducible builds when building Python projects that use setuptools. Called setuptools-reproducible, the project s README file contains the following:
Setuptools can create reproducible wheel archives (.whl) by setting SOURCE_DATE_EPOCH at build time, but setting the env var is insufficient for creating reproducible sdists (.tar.gz). setuptools-reproducible [therefore] wraps the hooks build_sdist build_wheel with some modifications to make reproducible builds by default.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 301, 302 and 303 to Debian:
  • Improvements:
    • Use Difference.from_operation in an attempt to pipeline the output of the extract-vmlinux script, potentially avoiding it all in memory. [ ]
    • Memoize a number of calls to --version, saving a very large number of external subprocess calls.
  • Bug fixes:
    • Don t check for PyPDF version 3 specifically, check for versions greater than 3. [ ]
    • Ensure that Java class files are named .class on the filesystem before passing them to javap(1). [ ]
    • Mask stderr from extract-vmlinux script. [ ][ ]
    • Avoid spurious differences in h5dump output caused by exposure of absolute internal extraction paths. (#1108690)
  • Misc:
    • Use our_check_output in the ODT comparator. [ ]
    • Update copyright years. [ ]
In addition: Lastly, Chris Lamb added a tmpfs to try.diffoscope.org so that diffoscope has a non-trivial temporary area to unpack archives, etc. [ ] Elsewhere in our tooling, however, reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.30 was uploaded to Debian unstable by Holger Levsen, chiefly including a change by Rebecca N. Palmer to not call sudo with the -h flag in order to fix Debian bug #1108550. [ ]

New library to patch system functions for reproducibility Nicolas Graves has written and published libfate, a simple collection of tiny libraries to patch system functions deterministically using LD_PRELOAD. According to the project s README:
libfate provides deterministic replacements for common non-deterministic system functions that can break reproducible builds. Instead of relying on complex build systems or apps or extensive patching, libfate uses the LD_PRELOAD trick to intercept system calls and return fixed, predictable values.
Describing why he wrote it, Nicolas writes:
I originally used the OpenSUSE dettrace approach to make Emacs reproducible in Guix. But when Guix switch to GCC@14, dettrace stopped working as expected. dettrace is a complex piece of software, my need was much less heavy: I don t need to systematically patch all sources of nondetermism, just the ones that make a process/binary unreproducible in a container/chroot.

Independently Reproducible Git Bundles Simon Josefsson has published another interesting article this month. Titled Independently Reproducible Git Bundles, the blog post describes the advantages of why you might a reproducible bundle, and the pitfalls that can arise when trying to create them:
One desirable property is that someone else should be able to reproduce the same git bundle, and not only that a single individual is able to reproduce things on one machine. It surprised me to see that when I ran the same set of commands on a different machine (started from a fresh git clone), I got a different checksum. The different checksums occurred even when nothing had been committed on the server side between the two runs.

Website updates Once again, there were a number of improvements made to our website this month including:

Distribution work In Debian this month:
Debian contributors have made significant progress toward ensuring package builds produce byte-for-byte reproducible results. You can check the status for packages installed on your system using the new package debian-repro-status, or visit reproduce.debian.net for Debian s overall statistics for trixie and later. You can contribute to these efforts by joining #debian-reproducible on IRC to discuss fixes, or verify the statistics by installing the new rebuilderd package and setting up your own instance.

The IzzyOnDroid Android APK repository made further progress in July, crossing the 50% reproducibility threshold congratulations. Furthermore, a new release of the Neo Store was released, which exposes the reproducible status directly next to the version of each app.
In GNU Guix, a series of patches intended to fix the reproducibility for the Mono programming language was merged, fixing reproducibility in Mono versions 1.9 [ ], 2.4 [ ] and 2.6 [ ].
Lastly, in addition to the news that openSUSE Enterprise Linux now [has an official goal of reproducibility]((https://lists.reproducible-builds.org/pipermail/rb-general/2025-July/003846.html), Bernhard M. Wiedemann posted another monthly update for their work there.

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In July, however, a number of changes were made by Holger Levsen, including:
  • Switch the URL for the Tails package set. [ ]
  • Make the dsa-check-packages output more useful. [ ]
  • Setup the ppc64el architecture again, has it has returned this time with a 2.7 GiB database instead of 72 GiB. [ ]
In addition, Jochen Sprickerhof improved the reproducibility statistics generation:
  • Enable caching of statistics. [ ][ ][ ]
  • Add some common non-reproducible patterns. [ ]
  • Change output to directory. [ ]
  • Add a page sorted by diffoscope size. [ ][ ]
  • Switch to Python s argparse module and separate output(). [ ]
Holger also submitted a number of Debian bugs against rebuilderd and rebuilderd-worker:
  • Config files and scripts for a simple one machine setup. [ ][ ]
  • Create a rebuilderd user. [ ]
  • Create rebuilderd-worker user with sbuild. [ ]
Lastly, Mattia Rizzolo added a scheduled job to renew some SSL certificates [ ] and Vagrant Cascadian performed some node maintenance [ ][ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: There were a number of other patches from openSUSE developers:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

David Bremner: Using git-annex for email and notmuch metadata

Introducing git-remote-notmuch Based on an idea and ruby implementation by Felipe Contreras, I have been developing a git remote helper for notmuch. I will soon post an updated version of the patchset to the notmuch mailing list (I wanted to refer to this post in my email). In this blog post I'll outline my experiments with using that tool, along with git-annex to store (and sync) a moderate sized email store along with its notmuch metadata.

WARNING The rest of this post describes some relatively complex operations using (at best) alpha level software (namely git-remote-notmuch). git-annex is good at not losing your files, but git-remote-notmuch can (and did several times during debugging) wipe out your notmuch database. If you have a backup (e.g. made with notmuch-dump), this is much less annoying, and in particular you can decide to walk away from this whole experiment and restore your database.

Why git-annex? I currently have about 31GiB of email, spread across more than 830,000 files. I want to maintain the ability to search and read my email offline, so I need to maintain a copy on several workstations and at least one server (which is backed up explicitly). I am somewhat commited to maintaining synchronization of tags to git since that is how the notmuch bug tracker works. Commiting the email files to git seems a bit wasteful: by design notmuch does not modify email files, and even with compression, the extra copy adds a fair amount of overhead (in my case, 17G of git objects, about 57% overhead). It is also notoriously difficult to completely delete files from a git repository. git-annex offers potential mitigation for these two issues, at the cost of a somewhat more complex mental model. The main idea is that instead of committing every version of a file to the git repository, git-annex tracks the filename and metadata, with the file content being stored in a key-value store outside git. Conceptually this is similar to git-lfs. From our current point, the important point is that instead of a second (compressed) copy of the file, we store one copy, along with a symlink and a couple of directory entries.

What to annex For sufficiently small files, the overhead of a symlink and couple of directory entries is greater than the cost of a compressed second copy. When this happens depends on several variables, and will probably depend on the file content in a particular collection of email. I did a few trials of different settings for annex.largefiles to come to a threshold of largerthan=32k 1. For the curious, my experimental results are below. One potentially surprising aspect is that annexing even a small fraction of the (largest) files yields a big drop in storage overhead.
Threshold fraction annexed overhead
0 100% 30%
8k 29% 13%
16k 12% 9.4%
32k 7% 8.9%
48k 6% 8.9%
100k 3% 9.1%
256k 2% 11%
(git) 0 % 57%
In the end I chose to err on the side of annexing more files (for the flexibility of deletion) rather than potentially faster operations with fewer annexed files at the same level of overhead. Summarizing the configuration settings for git-annex (some of these are actually defaults, but not in my environment).
$ git config annex.largefiles largerthan=32k
$ git config annex.dotfiles true
$ git config annex.synccontent true

Delivering mail To get new mail, I do something like
# compute a date based folder under $HOME/Maildir
$ dest = $(folder)
# deliver mail to $ dest  (somehow).
$ notmuch new
$ git -C $HOME/Maildir add $ folder 
$ git -C $HOME/Maildir diff-index --quiet HEAD $ folder    git -C $HOME/Maildir commit -m 'mail delivery'
The call to diff-index is just an optimization for the case when nothing was delivered. The default configuration of git-annex will automagically annex any files larger than my threshold. At this point the git-annex repo knows nothing about tags. There is some git configuration that can speed up the "git add" above, namely
$ git config core.untrackedCache true
$ git config core.fsmonitor true
See git-status(1) under "UNTRACKED FILES AND PERFORMANCE" Defining notmuch as a git remote Assuming git-remote-notmuch is somewhere in your path, you can define a remote to connect to the default notmuch database.
$ git remote add database notmuch::
$ git fetch database
$ git merge --allow-unrelated database
The --allow-unrelated should be needed only the first time. In my case the many small files used to represent the tags (one per message), use a noticeable amount of disk space (in my case about the same amount of space as the xapian database). Once you start merging from the database to the git repo, you will likely have some conflicts, and most conflict resolution tools leave junk lying around. I added the following .gitignore file to the top level of the repo
*.orig
*~
This prevents our cavalier use of git add from adding these files to our git history (and prevents pushing random junk to the notmuch database. To push the tags from git to notmuch, you can run
$ git push database master
You might need to run notmuch new first, so that the database knows about all of the messages (currently git-remote-notmuch can't index files, only update metadata). git annex sync should work with the new remote, but pushing back will be very slow 2. I disable automatic pushing as follows
$ git config remote.database.annex-push false
Unsticking the database remote If you are debugging git-remote-notmuch, or just unlucky, you may end up in a sitation where git thinks the database is ahead of your git remote. You can delete the database remote (and associated stuff) and re-create it. Although I cannot promise this will never cause problems (because, computers), it will not modify your local copy of the tags in the git repo, nor modify your notmuch database.
$ git remote rm database
$ git update-rf -d notmuch/master
$ rm -r .git/notmuch
Fine tuning notmuch config
  • In order to avoid dealing with file renames, I have
      notmuch config maildir.synchronize_flags false
    
  • I have added the following to new.ignore:
       .git;_notmuch_metadata;.gitignore
    

  1. I also had to set annex.dotfiles to true, as many of my maildirs follow the qmail style convention of starting with a .
  2. I'm not totally clear on why it so slow, but certainly git-annex tries to push several more branches, and these are ignored by git-remote-annex.

Colin Watson: Free software activity in July 2025

About 90% of my Debian contributions this month were sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. DebConf I attended DebConf for the first time in 11 years (my last one was DebConf 14 in Portland). It was great! For once I had a conference where I had a fairly light load of things I absolutely had to do, so I was able to spend time catching up with old friends, making some new friends, and doing some volunteering - a bit of Front Desk, and quite a lot of video team work where I got to play with sound desks and such. Apparently one of the BoFs ( birds of a feather , i.e. relatively open discussion sessions) where I was talkmeister managed to break the automatic video cutting system by starting and ending precisely on time, to the second, which I m told has never happened before. I ll take that. I gave a talk about Debusine, along with helping Enrico run a Debusine BoF. We still need to process some of the feedback from this, but are generally pretty thrilled about the reception. My personal highlight was getting a shout-out in a talk from CERN (in the slide starting at 32:55). Other highlights for me included a Python team BoF, Ian s tag2upload talk and some very useful follow-up discussions, a session on archive-wide testing, a somewhat brain-melting whiteboard session about the multiarch interpreter problem , several useful discussions about salsa.debian.org, Matthew s talk on how Wikimedia automates their Debian package builds, and many others. I hope I can start attending regularly again! OpenSSH Towards the end of a release cycle, people tend to do more upgrade testing, and this sometimes results in interesting problems. Manfred Stock reported No new SSH connections possible during large part of upgrade to Debian Trixie , and after a little testing in a container I confirmed that this was a reproducible problem that would have affected many people upgrading from Debian 12 (bookworm), with potentially severe consequences for people upgrading remote systems. In fact, there were two independent problems that each led to much the same symptom: The net result is that if you apply updates to bookworm (including stable-updates / bookworm-updates, which is enabled by default) before starting the upgrade to trixie, everything should be fine. Many thanks to Manfred for reporting this with just enough time to spare that we were able to fix it before Debian 13 is released in a few days! debmirror I did my twice-yearly refresh of debmirror s mirror_size documentation, and applied a patch from Christoph Goehre to improve mirroring of installer files. madison-lite I proposed renaming this project along with the rmadison tool in devscripts, although I m not yet sure what a good replacement name would be. Python team I upgraded python-expandvars, python-typing-extensions (in experimental), and webtest to new upstream versions. I backported fixes for some security vulnerabilities to unstable: I fixed or helped to fix a number of release-critical bugs: I fixed some other bugs, mostly Severity: important: I reinstated python3-mastodon s build-dependency on and recommendation of python3-blurhash, now that the latter has been fixed to use the correct upstream source.

Matthew Palmer: I'm trying an open source funding experiment

As I m currently somewhat underemployed, and could do with some extra income, I m starting an open source crowd-funding experiment. My hypothesis is that the open source community, and perhaps a community-minded company or two, really wants more open source code in the world, and is willing to put a few dollars my way to make that happen. To begin with, I m asking for contributions to implement a bunch of feature requests on action-validator, a Rust CLI tool I wrote to validate the syntax of GitHub actions and workflows. The premise is quite simple: for every AU$150 (about US$100) I receive in donations, I ll implement one of the nominated feature requests. If people want a particular feature implemented, they can nominate a feature in their donation message, otherwise when general donations get to AU$150, I ll just pick a feature that looks interesting. More details are on my code fund page. In the same spirit of simplicity, donations can be made through my Ko-fi page, and I ll keep track of the various totals in a hand-written HTML table. So, in short, if you want more open source code to exist, now would be a good time to visit my Ko-fi page and chip in a few dollars. If you re curious to know more, my code fund page has a list of Foreseeably Anticipated Questions that might address your curiosity. Otherwise, ask your questions in the comments or email me.

5 August 2025

Ravi Dwivedi: Tricked by a website while applying for Vietnam visa

In December 2024, Badri and I went to Vietnam. In this post, I ll document our experiences with the visa process of Vietnam. Vietnam requires an e-visa to enter the country. The official online portal for the e-visa application is evisa.xuatnhapcanh.gov.vn/. However, I submitted my visa application on the website vietnamvisa.govt.vn. It was only after submitting my application and making the payment that I realized that it s not the official e-visa website. The realization came from the tagline mentioned in the top left corner of the website - the best way to obtain a Vietnam visa. I was a bit upset that I got tricked by that website. I should have checked the top level domains of Vietnam s government websites. Anyways, it is pretty easy to confuse govt.vn with gov.vn. I also paid double the amount of the official visa fee. However, I wasn t asked to provide a flight reservation or hotel bookings - documents which are usually asked for most of the visas. But they did ask me for a photo. I was not even sure whether the website was legit or not. Badri learnt from my experience and applied through the official Vietnam government website. During the process, he had to provide a hotel booking as well as enter the hotel address into the submission form. Additionally, the official website asked to provide the exact points of entry to and exit from the country, which the non-official website did not ask for. On the other hand, he had to pay only 25 USD versus my 54 USD. It turned out that the website I registered on was also legit, as they informed me a week later that my visa has been approved, along with a copy of my visa. Further, I was not barred from entering and found to be holding a fake visa. It appears that the main scam is not about the visa being fake, but rather that you will be charged more than if you apply through the official website. I would still recommend you (the readers) to submit your visa application only through the official website and not on any of the other such websites. Our visa was valid for a month (my visa was valid from the 4th of December 2024 to the 4th of January 2025). We also had a nice time in Vietnam. Stay tuned for my Vietnam travel posts! Credits to Badri for proofreading and writing his part of the experience.

Thomas Lange: FAIme service new features: Linux Mint support and data storage for USB

Build your own customized Linux Mint ISO Using the FAIme service [1] you can now build your own customized installation ISO for Xfce edition of Linux Mint 22.1 'Xia'. You can select the language, add a list of additional packages, set the username and passwords. In the advanced settings you may add your ssh public key, some grub option and add a postinst script to be executed. Add writable data partition for USB sticks For all variants of ISOs (all live and all install ISOs) you can add a data partition to the ISO by just clicking a checkbox. This writable partition can be used when booting from USB stick. FAI will use it to search for a config space and to store the logs when this partition is detected. The logs will be stored in the subdirectory logs on this partition. For using a different config space than the one on the ISO (which is read only) create a subdirectory config and copy a FAI config space into that directory. Then set FAI_CONFIG_SRC=detect:// (which is the default) and FAI will search for a config space on the data partition and uses this. More info about this [2] You can also store some local packages in your config space, which will be installed automatically, without the need of recreating the ISO.

Matthew Garrett: Cordoomceps - replacing an Amiga's brain with Doom

There's a lovely device called a pistorm, an adapter board that glues a Raspberry Pi GPIO bus to a Motorola 68000 bus. The intended use case is that you plug it into a 68000 device and then run an emulator that reads instructions from hardware (ROM or RAM) and emulates them. You're still limited by the ~7MHz bus that the hardware is running at, but you can run the instructions as fast as you want.

These days you're supposed to run a custom built OS on the Pi that just does 68000 emulation, but initially it ran Linux on the Pi and a userland 68000 emulator process. And, well, that got me thinking. The emulator takes 68000 instructions, emulates them, and then talks to the hardware to implement the effects of those instructions. What if we, well, just don't? What if we just run all of our code in Linux on an ARM core and then talk to the Amiga hardware?

We're going to ignore x86 here, because it's weird - but most hardware that wants software to be able to communicate with it maps itself into the same address space that RAM is in. You can write to a byte of RAM, or you can write to a piece of hardware that's effectively pretending to be RAM[1]. The Amiga wasn't unusual in this respect in the 80s, and to talk to the graphics hardware you speak to a special address range that gets sent to that hardware instead of to RAM. The CPU knows nothing about this. It just indicates it wants to write to an address, and then sends the data.

So, if we are the CPU, we can just indicate that we want to write to an address, and provide the data. And those addresses can correspond to the hardware. So, we can write to the RAM that belongs to the Amiga, and we can write to the hardware that isn't RAM but pretends to be. And that means we can run whatever we want on the Pi and then access Amiga hardware.

And, obviously, the thing we want to run is Doom, because that's what everyone runs in fucked up hardware situations.

Doom was Amiga kryptonite. Its entire graphical model was based on memory directly representing the contents of your display, and being able to modify that by just moving pixels around. This worked because at the time VGA displays supported having a memory layout where each pixel on your screen was represented by a byte in memory containing an 8 bit value that corresponded to a lookup table containing the RGB value for that pixel.

The Amiga was, well, not good at this. Back in the 80s, when the Amiga hardware was developed, memory was expensive. Dedicating that much RAM to the video hardware was unthinkable - the Amiga 1000 initially shipped with only 256K of RAM, and you could fill all of that with a sufficiently colourful picture. So instead of having the idea of each pixel being associated with a specific area of memory, the Amiga used bitmaps. A bitmap is an area of memory that represents the screen, but only represents one bit of the colour depth. If you have a black and white display, you only need one bitmap. If you want to display four colours, you need two. More colours, more bitmaps. And each bitmap is stored in an independent area of RAM. You never use more memory than you need to display the number of colours you want to.

But that means that each bitplane contains packed information - every byte of data in a bitplane contains the bit value for 8 different pixels, because each bitplane contains one bit of information per pixel. To update one pixel on screen, you need to read from every bitmap, update one bit, and write it back, and that's a lot of additional memory accesses. Doom, but on the Amiga, was slow not just because the CPU was slow, but because there was a lot of manipulation of data to turn it into the format the Amiga wanted and then push that over a fairly slow memory bus to have it displayed.

The CDTV was an aesthetically pleasing piece of hardware that absolutely sucked. It was an Amiga 500 in a hi-fi box with a caddy-loading CD drive, and it ran software that was just awful. There's no path to remediation here. No compelling apps were ever released. It's a terrible device. I love it. I bought one in 1996 because a local computer store had one and I pointed out that the company selling it had gone bankrupt some years earlier and literally nobody in my farming town was ever going to have any interest in buying a CD player that made a whirring noise when you turned it on because it had a fan and eventually they just sold it to me for not much money, and ever since then I wanted to have a CD player that ran Linux and well spoiler 30 years later I'm nearly there. That CDTV is going to be our test subject. We're going to try to get Doom running on it without executing any 68000 instructions.

We're facing two main problems here. The first is that all Amigas have a firmware ROM called Kickstart that runs at powerup. No matter how little you care about using any OS functionality, you can't start running your code until Kickstart has run. This means even documentation describing bare metal Amiga programming assumes that the hardware is already in the state that Kickstart left it in. This will become important later. The second is that we're going to need to actually write the code to use the Amiga hardware.

First, let's talk about Amiga graphics. We've already covered bitmaps, but for anyone used to modern hardware that's not the weirdest thing about what we're dealing with here. The CDTV's chipset supports a maximum of 64 colours in a mode called "Extra Half-Brite", or EHB, where you have 32 colours arbitrarily chosen from a palette and then 32 more colours that are identical but with half the intensity. For 64 colours we need 6 bitplanes, each of which can be located arbitrarily in the region of RAM accessible to the chipset ("chip RAM", distinguished from "fast ram" that's only accessible to the CPU). We tell the chipset where our bitplanes are and it displays them. Or, well, it does for a frame - after that the registers that pointed at our bitplanes no longer do, because when the hardware was DMAing through the bitplanes to display them it was incrementing those registers to point at the next address to DMA from. Which means that every frame we need to set those registers back.

Making sure you have code that's called every frame just to make your graphics work sounds intensely irritating, so Commodore gave us a way to avoid doing that. The chipset includes a coprocessor called "copper". Copper doesn't have a large set of features - in fact, it only has three. The first is that it can program chipset registers. The second is that it can wait for a specific point in screen scanout. The third (which we don't care about here) is that it can optionally skip an instruction if a certain point in screen scanout has already been reached. We can write a program (a "copper list") for the copper that tells it to program the chipset registers with the locations of our bitplanes and then wait until the end of the frame, at which point it will repeat the process. Now our bitplane pointers are always valid at the start of a frame.

Ok! We know how to display stuff. Now we just need to deal with not having 256 colours, and the whole "Doom expects pixels" thing. For the first of these, I stole code from ADoom, the only Amiga doom port I could easily find source for. This looks at the 256 colour palette loaded by Doom and calculates the closest approximation it can within the constraints of EHB. ADoom also includes a bunch of CPU-specific assembly optimisation for converting the "chunky" Doom graphic buffer into the "planar" Amiga bitplanes, none of which I used because (a) it's all for 68000 series CPUs and we're running on ARM, and (b) I have a quad core CPU running at 1.4GHz and I'm going to be pushing all the graphics over a 7.14MHz bus, the graphics mode conversion is not going to be the bottleneck here. Instead I just wrote a series of nested for loops that iterate through each pixel and update each bitplane and called it a day. The set of bitplanes I'm operating on here is allocated on the Linux side so I can read and write to them without being restricted by the speed of the Amiga bus (remember, each byte in each bitplane is going to be updated 8 times per frame, because it holds bits associated with 8 pixels), and then copied over to the Amiga's RAM once the frame is complete.

And, kind of astonishingly, this works! Once I'd figured out where I was going wrong with RGB ordering and which order the bitplanes go in, I had a recognisable copy of Doom running. Unfortunately there were weird graphical glitches - sometimes blocks would be entirely the wrong colour. It took me a while to figure out what was going on and then I felt stupid. Recording the screen and watching in slow motion revealed that the glitches often showed parts of two frames displaying at once. The Amiga hardware is taking responsibility for scanning out the frames, and the code on the Linux side isn't synchronised with it at all. That means I could update the bitplanes while the Amiga was scanning them out, resulting in a mashup of planes from two different Doom frames being used as one Amiga frame. One approach to avoid this would be to tie the Doom event loop to the Amiga, blocking my writes until the end of scanout. The other is to use double-buffering - have two sets of bitplanes, one being displayed and the other being written to. This consumes more RAM but since I'm not using the Amiga RAM for anything else that's not a problem. With this approach I have two copper lists, one for each set of bitplanes, and switch between them on each frame. This improved things a lot but not entirely, and there's still glitches when the palette is being updated (because there's only one set of colour registers), something Doom does rather a lot, so I'm going to need to implement proper synchronisation.

Except. This was only working if I ran a 68K emulator first in order to run Kickstart. If I tried accessing the hardware without doing that, things were in a weird state. I could update the colour registers, but accessing RAM didn't work - I could read stuff out, but anything I wrote vanished. Some more digging cleared that up. When you turn on a CPU it needs to start executing code from somewhere. On modern x86 systems it starts from a hardcoded address of 0xFFFFFFF0, which was traditionally a long way any RAM. The 68000 family instead reads its start address from address 0x00000004, which overlaps with where the Amiga chip RAM is. We can't write anything to RAM until we're executing code, and we can't execute code until we tell the CPU where the code is, which seems like a problem. This is solved on the Amiga by powering up in a state where the Kickstart ROM is "overlayed" onto address 0. The CPU reads the start address from the ROM, which causes it to jump into the ROM and start executing code there. Early on, the code tells the hardware to stop overlaying the ROM onto the low addresses, and now the RAM is available. This is poorly documented because it's not something you need to care if you execute Kickstart which every actual Amiga does and I'm only in this position because I've made poor life choices, but ok that explained things. To turn off the overlay you write to a register in one of the Complex Interface Adaptor (CIA) chips, and things start working like you'd expect.

Except, they don't. Writing to that register did nothing for me. I assumed that there was some other register I needed to write to first, and went to the extent of tracing every register access that occurred when running the emulator and replaying those in my code. Nope, still broken. What I finally discovered is that you need to pulse the reset line on the board before some of the hardware starts working - powering it up doesn't put you in a well defined state, but resetting it does.

So, I now have a slightly graphically glitchy copy of Doom running without any sound, displaying on an Amiga whose brain has been replaced with a parasitic Linux. Further updates will likely make things even worse. Code is, of course, available.

[1] This is why we had trouble with late era 32 bit systems and 4GB of RAM - a bunch of your hardware wanted to be in the same address space and so you couldn't put RAM there so you ended up with less than 4GB of RAM

comment count unavailable comments

Michael Ablassmeier: PVE 9.0 - Snapshots for LVM

The new Proxmox release advertises a new feature for easier snapshot handling of virtual machines whose disks are stored on LVM volumes, I wondered.. whats the deal..? To be able to use the new feature, you need to enable a special flag for the LVM volume group. This example shows the general workflow for a fresh setup. 1) Create the volume group with the snapshot-as-volume-chain feature turned on:
 pvesm add lvm lvmthick --content images --vgname lvm --snapshot-as-volume-chain 1
2) From this point on, you can create virtual machines right away, BUT those virtual machines disks must use the QCOW image format for their disk volumes. If you use the RAW format, you wont be able to create snapshots, still.
 VMID=401
 qm create $VMID --name vm-lvmthick
 qm set $VMID -scsi1 lvmthick:2,format=qcow2
So, why would it make sense to format the LVM volume as QCOW? Snapshots on LVM thick provisioned devices are, as everybody knows, a very I/O intensive task. Besides each snapshot, a special -cow Device is created that tracks the changed block regions and the original block data for each change to the active volume. This will waste quite some space within your volume group for each snapshot. Formatting the LVM volume as QCOW image, makes it possible to use the QCOW backing-image option for these devices, this is the way PVE 9 handles these kind of snapshots. Creating a snapshot looks like this:
 qm snapshot $VMID id
 snapshotting 'drive-scsi1' (lvmthick3:vm-401-disk-0.qcow2)
 Renamed "vm-401-disk-0.qcow2" to "snap_vm-401-disk-0_id.qcow2" in volume group "lvm"
 Rounding up size to full physical extent 1.00 GiB
 Logical volume "vm-401-disk-0.qcow2" created.
 Formatting '/dev/lvm/vm-401-disk-0.qcow2', fmt=qcow2 cluster_size=131072 extended_l2=on preallocation=metadata compression_type=zlib size=1073741824 backing_file=snap_vm-401-disk-0_id.qcow2 backing_fmt=qcow2 lazy_refcounts=off refcount_bits=16
So it will rename the current active disk and create another QCOW formatted LVM volume, but pointing it to the snapshot image using the backing_file option. Neat.

4 August 2025

Scarlett Gately Moore: Fostering Constructive Communication in Open Source Communities

I write this in the wake of a personal attack against my work and a project that is near and dear to me. Instead of spreading vile rumors and hearsay, talk to me. I am not known to be hard to talk to and am wide open for productive communication. I am disheartened and would like to share some thoughts of the importance of communication. Thanks for listening. Open source development thrives on collaboration, shared knowledge, and mutual respect. Yet sometimes, the very passion that drives us to contribute can lead to misunderstandings and conflicts that harm both individuals and the projects we care about. As contributors, maintainers, and community members, we have a responsibility to foster environments where constructive dialogue flourishes.

The Foundation of Healthy Open Source Communities At its core, open source is about people coming together to build something greater than what any individual could create alone. This collaborative spirit requires more than just technical skills it demands emotional intelligence, empathy, and a commitment to treating one another with dignity and respect. When disagreements arise and they inevitably will the manner in which we handle them defines the character of our community. Technical debates should focus on the merits of ideas, implementations, and approaches, not on personal attacks or character assassinations conducted behind closed doors.

The Importance of Direct Communication One of the most damaging patterns in any community is when criticism travels through indirect channels while bypassing the person who could actually address the concerns. When we have legitimate technical disagreements or concerns about someone s work, the constructive path forward is always direct, respectful communication. Consider these approaches:
  • Address concerns directly: If you have technical objections to someone s work, engage with them directly through appropriate channels
  • Focus on specifics: Critique implementations, documentation, or processes not the person behind them
  • Assume good intentions: Most contributors are doing their best with the time and resources available to them
  • Offer solutions: Instead of just pointing out problems, suggest constructive alternatives

Supporting Contributors Through Challenges Open source contributors often juggle their community involvement with work, family, and personal challenges. Many are volunteers giving their time freely, while others may be going through difficult periods in their lives job searching, dealing with health issues, or facing other personal struggles. During these times, our response as a community matters enormously. A word of encouragement can sustain someone through tough periods, while harsh criticism delivered thoughtlessly can drive away valuable contributors permanently.

Building Resilient Communities Strong open source communities are built on several key principles: Transparency in Communication: Discussions about technical decisions should happen in public forums where all stakeholders can participate and learn from the discourse. Constructive Feedback Culture: Criticism should be specific, actionable, and delivered with the intent to improve rather than to tear down. Recognition of Contribution: Every contribution, whether it s code, documentation, bug reports, or community support, has value and deserves acknowledgment. Conflict Resolution Processes: Clear, fair procedures for handling disputes help prevent minor disagreements from escalating into community-damaging conflicts.

The Long View Many successful open source projects span decades, with contributors coming and going as their life circumstances change. The relationships we build and the culture we create today will determine whether these projects continue to attract and retain the diverse talent they need to thrive. When we invest in treating each other well even during disagreements we re investing in the long-term health of our projects and communities. We re creating spaces where innovation can flourish because people feel safe to experiment, learn from mistakes, and grow together.

Moving Forward Constructively If you find yourself in conflict with another community member, consider these steps:
  1. Take a breath: Strong emotions rarely lead to productive outcomes
  2. Seek to understand: What are the underlying concerns or motivations?
  3. Communicate directly: Reach out privately first, then publicly if necessary
  4. Focus on solutions: How can the situation be improved for everyone involved?
  5. Know when to step back: Sometimes the healthiest choice is to disengage from unproductive conflicts

A Call for Better Open source has given us incredible tools, technologies, and opportunities. The least we can do in return is treat each other with the respect and kindness that makes these collaborative achievements possible. Every contributor whether they re packaging software, writing documentation, fixing bugs, or supporting users is helping to build something remarkable. Let s make sure our communities are places where that work can continue to flourish, supported by constructive communication and mutual respect. The next time you encounter work you disagree with, ask yourself: How can I make this better? How can I help this contributor grow? How can I model the kind of community interaction I want to see? Our projects are only as strong as the communities that support them. Let s build communities worthy of the amazing software we create together. https://gofund.me/506c910c

Aigars Mahinovs: Snapshot mirroring in Debian (and Ubuntu)

Snapshot mirroring in Debian (and Ubuntu) The use of snapshots has been routine in both Debian and Ubuntu for several years now or more than 15 years for Debian, to be precise. Snapshots have become not only very reliable, but also an increasingly important part of the Debian package archive. This week, I encountered a problem at work that could be perfectly solved by correctly using the Snapshot service. However, while trying to figure it out, I ran into some shortcomings in the documentation. Until the docs are updated, I am publishing this blog post to make this information easier to find. Problem 1: Ensure fully reproducible creation of Docker containers with the exact same packages installed, even years after the original images were generated. Solution 1: Pin everything! Use a pinned source image in the FROM statement, such as debian:trixie-20250721-slim, and also pin the APT package sources to the "same" date - "20250722". Hint: The APT packages need to be newer than the Docker image base. If the APT packages are a bit newer, that's not a problem, as APT can upgrade packages without issues. However, if your Docker image has a newer package than your APT package sources, you will have a big problem. For example, if you have "libbearssl0" version 0.6-2 installed in the Docker image, but your package sources only have the older version 0.6-1, you will fail when trying to install the "libbearssl-dev" package. This is because you only have version 0.6-1 of the "-dev" package available, which hard-depends on exactly version 0.6-1 of "libbearssl0", and APT will refuse to downgrade an already installed package to satisfy that dependency. Problem 2: You are using a lot of images in a lot of executions and building tens of thousands of images per day. It would be a bad idea to put all this load on public Debian servers. Using local sources is also faster and adds extra security. Solution 2: Use local (transparently caching) mirrors for both the Docker Hub repository and the APT package source. At this point, I ran into another issue I could not easily figure out how to specify a local mirror for the snapshot part of the archive service. First of all, snapshot support in both Ubuntu and Debian accepts both syntaxes described in the Debian and Ubuntu documentation above. The documentation on both sites presents different approaches and syntax examples, but both work. The best approach nowadays is to use the "deb822" sources syntax. Remove /etc/apt/sources.list (if it still exists), delete all contents of the /etc/apt/sources.list.d directory, and instead create this file at /etc/apt/sources.list.d/debian.sources:
Types: deb
URIs: https://common.mirror-proxy.local/ftp.debian.org/debian/
Suites: trixie
Components: main non-free-firmware non-free contrib
Signed-By: /usr/share/keyrings/debian-archive-keyring.gpg
Snapshot: 20250722
Hint: This assumes you have a mirror service running at common.mirror-proxy.local that proxies requests (with caching) to whitelisted domains, based on the name of the first folder in the path. If you now run sudo apt update --print-uris, you will see that your configuration accesses your mirror, but does not actually use the snapshot. Next, add the following to /etc/apt/apt.conf.d/80snapshots:
APT::Snapshot "20250722";
That should work, right? Let's try sudo apt update --print-uris again. I've got good news and bad news! The good news is that we are now actually using the snapshot we specified (twice). The bad news is that we are completely ignoring the mirror and going directly to snapshots.debian.org instead. Finding the right information was a bit of a challenge, but after a few tries, this worked: to specify a custom local mirror of the Debian (or Ubuntu) snapshot service, simply add the following line to the same file, /etc/apt/apt.conf.d/80snapshots:
Acquire::Snapshots::URI::Override::Origin::debian "https://common.mirror-proxy.local/snapshot.debian.org/archive/debian/@SNAPSHOTID@/";
Now, if you check again with sudo apt update --print-uris, you will see that the requests go to your mirror and include the specified snapshot identifier. Success! Now you can install any packages you want, and everything will be completely local and fully reproducible, even years later!

Next.

Previous.