Search Results: "ag"

23 April 2015

Steve McIntyre: Ready for Jessie! (aka bits from the debian-cd team)

I'm happy with the progress we've made for debian-installer and related packages for the Jessie release. We're going to end up with a release that's better in a number of ways than what we've had before. 1. Big EFI enhancements I've already blogged a lot about the stuff I've worked on here, so I'll just summarise for now some of the improvements we've got over Wheezy.
  1. A fix for systems that (badly) dual-boot in EFI and BIOS mode such that after installing Debian you wouldn't get a sensible choice of which OS to boot (#763127).
  2. A workaround for broken EFI implementations: an option to install the grub-efi bootloader to the removable media path in case the system firmware does not load grub-efi from the correctly registered boot path. (#746662).
  3. Addition of 32-bit EFI to our i386 installation images, to support both some older systems and some brand new systems that need it. This has unfortunately stopped those i386 images from working on some of the oldest Intel-based Apple Mac machines, so we've added an extra Mac-only flavour of i386 netinst without EFI in case people need it.
  4. Significantly better support for Intel-based Apple Macs in general, to the point that installing Debian on lots of these machines should now be much easier and doesn't depend on extra third-party software such as rEFIt or rEFInd. I've massively updated the Debian wiki page at https://wiki.debian.org/MacMiniIntel with more details for specific models of Mac Mini. I'm hoping to provide similarly updated information for Mac laptops too - see below!
    Massive thanks to the lovely folks at Mythic Beasts for providing me with a range of machines to test with here!
  5. Support for mixed-mode EFI systems like the Intel Bay Trail: a 64-bit platform crippled with a 32-bit EFI firmware. I believe Jessie will be the first release of a Linux distribution to support these machines fully!
2. Openstack images In collaboration with Thomas Goirand, we now have amd64 Openstack Jessie image builds being produced every week, and there will be an official image made to go with the Jessie release too. See http://cdimage.debian.org/cdimage/openstack/testing/ for the current image. 3. Debian-live images As of a few weeks ago, we've also added started doing weekly builds of live Debian images for amd64 and i386, using software and configuration from the Live Systems Project. See http://cdimage.debian.org/cdimage/weekly-live-builds/ for the current weekly images. These will be produced in sync with the Jessie release too. 4. New architectures We've added installation media for the two new architectures added in Jessie: arm64 and ppc64el. I'm particularly proud of the arm64 images. With help from Ian Campbell, Leif Lindholm and Thomas Schmitt I've managed to make EFI-compatible CD images in an isohybrid design that means they should also work when copied directly to a USB stick. Hopefully this will help this new platform to become just as easy to install as any x86 PC is today. Hopefully post-Jessie we'll even be able to start providing live images and openstack images for more architectures too. More help needed yet! First of all, we're planning to release Jessie as Debian 8 this coming Saturday (25th April). Help with testing the installation and live images as they're produced would be lovely - please join us on the #debian-cd channel on irc.debian.org and we'll co-ordinate there. Secondly, there's an almost endless variety of machines out there. I've updated information about how Debian installation works on some of the more awkward Mac Mini machines, but we don't yet cover all the bases even there. It would be great to update the information about other machines such as the Macbook range as well - currently a lot of these pages are well out of date and won't be helpful for new users. Please test on machines if you have them, and help improve Debian's documentation here.

22 April 2015

Jonathan Wiltshire: Jessie Countdown: 3

Three is the new number for continuing oldstable security support: thanks to the efforts of those behind the Long-Term Support initiative, the full stable lifecycle of a release has therefore become five years (source: https://www.debian.org/News/2014/20140424). Where do those numbers come from? 2 years as stable, 1 year overlap support as oldstable, plus 2 new years under LTS = 5 years. Having been successful for Squeeze (6), LTS is widely anticipated to follow a similar pattern for Wheezy (7) and Jessie (8) for the same lifetimes. Some reduction in coverage is unavoidable (for example, Squeeze only covers the most popular amd64 and i386 architectures), but for a majority of users this reduces the need to follow a three-year upgrade cycle invaluable when you are managing hundreds or thousands of servers and can t achieve that in a single year.
Jessie Countdown: 3 is a post from: jwiltshire.org.uk Flattr

Lars Wirzenius: Jessie release part in Helsinki

There will be a gathering of Debian people to celebrate the release of jessie this Saturday in Helsinki. For details, see the wiki page. Welcome, everyone.

Riku Voipio: Fastest way to change running dtb

Tollef posted about using BeagleBone Black for temperature monitoring. There was a passage about patching the DTB (device tree) file:
... This needs to be compiled into a .dtb. I found the easiest way was just to drop the patched .dts into an unpacked kernel tree and then running make dtbs.
There are easier ways. For example, you can get the current device tree file generated from /proc:

apt-get install device-tree-compiler
dtc -I fs -O dts -o current.dts /proc/device-tree/
(Why /proc and not /sys ? because device tree predates /sys) Now you can just modify and build the dtb again, and install it back to where bootloader reads the dtb from:

vim current.dts
dtc -I dts -O dtb -o new.dtb current.dts
Alternative, of course, is to build a brand new mainline kernel and use the dynamic Device tree code now available.

Dirk Eddelbuettel: RcppArmadillo 0.5.000.0

A new major version 5.000 of Armadillo was released by Conrad a couple of days ago. Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. This version brings several new functions for sparse matrices, and automagically switches to 64-bit matrix indices in C++11 mode. See below for a short description of all the major changes based on the NEWS.Rd file. This version is now on CRAN, as well as in Debian. The integration into CRAN was delayed by a few days as my testing had a shortcoming. We run full reverse-dependency checks against all 115 CRAN package depending in RcppArmadillo, and we even made full pre-release 0.4.999.1 and 0.5.000.0 shipped to the drat repo of the RcppCore GitHub organization (which was described in the previous release post). But a minor flaw in my setup made it miss how the change in indexing affected packages dfcomb and dfmta. My thanks to its maintainer Marie-Karelle Riviere for providing updates to her packages permitting this release to get onto CRAN. The testing process has been tightened and this should not happen again.
Changes in RcppArmadillo version 0.5.000.0 (2015-04-12)
  • Upgraded to Armadillo release Version 5.000 ("Ankle Biter")
    • added spsolve() for solving sparse systems of linear equations
    • added svds() for singular value decomposition of sparse matrices
    • added nonzeros() for extracting non-zero values from matrices
    • added handling of diagonal views by sparse matrices
    • expanded repmat() to handle sparse matrices
    • expanded join_rows() and join_cols() to handle sparse matrices
    • sort_index() and stable_sort_index() have been placed in the delayed operations framework for increased efficiency
    • use of 64 bit integers is automatically enabled when using a C++11 compiler
    • workaround for a bug in recent releases of Apple Xcode
    • workaround for a bug in LAPACK 3.5
Changes in RcppArmadillo version 0.4.999.1.0 (2015-04-04)
  • Upgraded to Armadillo release preview 4.999.1
  • Non-CRAN test release
Courtesy of CRANberries, there is also a diffstat report for the most recent CRAN release. As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Tollef Fog Heen: Temperature monitoring using a Beaglebone Black and 1-wire

I've had a half-broken temperature monitoring setup at home for quite some time. It started out with a Atom-based NAS, a USB-serial adapter and a passive 1-wire adapter. It sometimes worked, then stopped working, then started when poked with a stick. Later, the NAS was moved under the stairs and I put a Beaglebone Black in its old place. The temperature monitoring thereafter never really worked, but I didn't have the time to fix it. Over the last few days, I've managed to get it working again, of course by replacing nearly all the existing components. I'm using the DS18B20 sensors. They're about USD 1 a piece on Ebay (when buying small quantities) and seems to work quite ok. My first task was to address the reliability problems: Dropouts and really poor performance. I thought the passive adapter was problematic, in particular with the wire lengths I'm using and I therefore wanted to replace it with something else. The BBB has GPIO support, and various blog posts suggested using that. However, I'm running Debian on my BBB which doesn't have support for DTB overrides, so I needed to patch the kernel DTB. (Apparently, DTB overrides are landing upstream, but obviously not in time for Jessie.) I've never even looked at Device Tree before, but the structure was reasonably simple and with a sample override from bonebrews it was easy enough to come up with my patch. This uses pin 11 (yes, 11, not 13, read the bonebrews article for explanation on the numbering) on the P8 block. This needs to be compiled into a .dtb. I found the easiest way was just to drop the patched .dts into an unpacked kernel tree and then running make dtbs. Once this works, you need to compile the w1-gpio kernel module, since Debian hasn't yet enabled that. Run make menuconfig, find it under "Device drivers", "1-wire", "1-wire bus master", build it as a module. I then had to build a full kernel to get the symversions right, then build the modules. I think there is or should be an easier way to do that, but as I cross-built it on a fast AMD64 machine, I didn't investigate too much. Insmod-ing w1-gpio then works, but for me, it failed to detect any sensors. Reading the data sheet, it looked like a pull-up resistor on the data line was needed. I had enabled the internal pull-up, but apparently that wasn't enough, so I added a 4.7kOhm resistor between pin 3 (VDD_3V3) on P9 and pin (GPIO_45) on P8. With that in place, my sensors showed up in /sys/bus/w1/devices and you can read the values using cat. In my case, I wanted the data to go into collectd and then to graphite. I first tried using an Exec plugin, but never got it to work properly. Using a [python plugin] worked much better and my graphite installation is now showing me temperatures. Now I just need to add more probes around the house. The most useful references were In addition, various searches for DS18B20 pinout and similar, of course.

John Goerzen: Today I FLEW A PLANE

DJI00694
For once you have tasted flight,
You will walk the earth with your eyes turned skyward;
For there you have been,
And there you long to return. Leonardo da Vinci
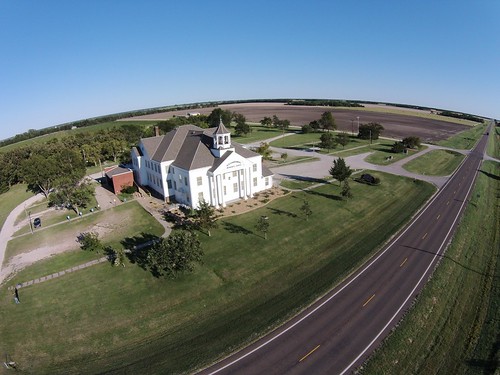
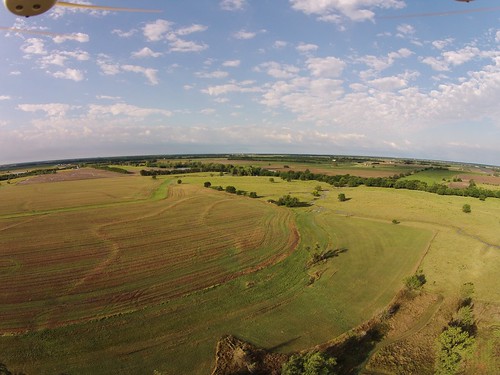
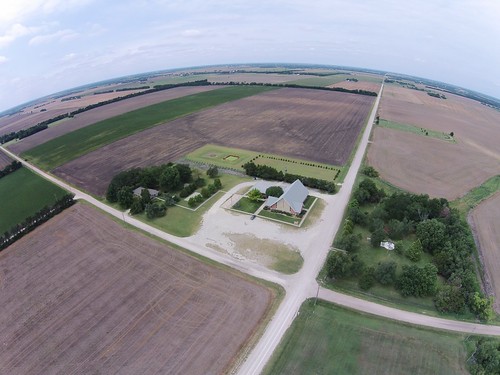
There is something of a magic to flight, to piloting. I remember the first flight I ever took, after years of dreaming of flying in a plane: my grandma had bought me a plane ticket. In one of the early morning flights, I witnessed a sunrise above cumulus clouds. Although I was just 10 or so at the time, that still is a most beautiful image seared into my memory. I have become meh about commercial flight over the years. The drive to the airport, the security lines, the lack of scenery at 35,000 feet. And yet, there is much more to flight than that. When I purchased what was essentially a flying camera, I saw a whole new dimension of the earth s amazing beauty. All the photos in this post, in fact, are ones I took. I then got a RC airplane, because flying the quadcopter was really way too easy. DJI00620
It s wonderful to climb the liquid mountains of the sky.
Behind me and before me is God, and I have no fears. Helen Keller
Start talking to pilots, and you notice a remarkable thing: this group of people that tends to be cool and logical, methodical and precise, suddenly finds themselves using language almost spiritual. Many have told me that being a pilot brings home how much all humans have in common, the unifying fact of sharing this beautiful planet together. Many volunteer with organizations such as Angel Flight. And having been up in small planes a few times, I start to glimpse this. Flying over my home at 1000 up, or from lake to lake in Seattle with a better view than the Space Needle, seeing places familiar and new, but from a new perspective, drives home again and again the beauty of our world, the sheer goodness of it, and the wonderful color of the humanity that inhabits it. DJI00120
The air up there in the clouds is very pure and fine, bracing and delicious. And why shouldn t it be? It is the same the angels breathe. Mark Twain
The view from 1000 feet, or 3000, is often so much more spectacular than the view from 35,000 ft as you get on a commercial flight. The flexibility is too; there are airports all over the country that smaller planes can use which the airlines never touch. Here is one incredible video from a guy that is slightly crazy but does ground-skimming, flying just a few feet off the ground: (try skipping to 9:36) So what comes next is something I blame slightly on my dad and younger brother. My dad helped get me interested in photography as a child, and that interest has stuck. It s what caused me to get into quadcopters ( a flying camera for less than the price of a nice lens! ). And my younger brother started mentioning airplanes to me last year for some reason, as if he was just trying to get me interested. Eventually, it worked. I started talking to the pilots I know (I know quite a few; there seems to be a substantial overlap between amateur radio and pilots). I started researching planes, flight, and especially safety the most important factor. And eventually I decided I wanted to be a pilot. I ve been studying feverishly, carrying around textbooks and notebooks in the car, around the house, and even on a plane. There is a lot to learn. And today, I took my first flight with a flight instructor. Today I actually flew a plane for awhile. Wow! There is nothing quite like that experience. Seeing a part of the world I am familiar with from a new perspective, and then actually controlling this amazing machine I really fail to find the words to describe it. I have put in many hours of study already, and there will be many more studying and flying, but it is absolutely worth it. Here is one final video about one of the most unique places you can fly to in Kansas. And a blog with lots of photos of a flight to Beaumont called Horse on the runway .

21 April 2015

Julien Danjou: Gnocchi 1.0: storing metrics and resources at scale

A few months ago, I wrote a long post about what I called back then the "Gnocchi experiment". Time passed and we me and the rest of the Gnocchi team continued to work on that project, finalizing it. It's with a great pleasure that we are going to release our first 1.0 version this month, roughly at the same time that the integrated OpenStack projects release their Kilo milestone. The first release candidate numbered 1.0.0rc1 has been released this morning! The problem to solve Before I dive into Gnocchi details, it's important to have a good view of what problems Gnocchi is trying to solve. Most of the IT infrastructures out there consists of a set of resources. These resources have properties: some of them are simple attributes whereas others might be measurable quantities (also known as metrics). And in this context, the cloud infrastructures make no exception. We talk about instances, volumes, networks which are all different kind of resources. The problems that are arising with the cloud trend is the scalability of storing all this data and being able to request them later, for whatever usage. What Gnocchi provides is a REST API that allows the user to manipulate resources (CRUD) and their attributes, while preserving the history of those resources and their attributes. Gnocchi is fully documented and the documentation is available online. We are the first OpenStack project to require patches to integrate the documentation. We want to raise the bar, so we took a stand on that. That's part of our policy, the same way it's part of the OpenStack policy to require unit tests. I'm not going to paraphrase the whole Gnocchi documentation, which covers things like installation (super easy), but I'll guide you through some basics of the features provided by the REST API. I will show you some example so you can have a better understanding of what you could leverage using Gnocchi! Handling metrics Gnocchi provides a full REST API to manipulate time-series that are called metrics. You can easily create a metric using a simple HTTP request:
POST /v1/metric HTTP/1.1
Content-Type: application/json


"archive_policy_name": "low"


HTTP/1.1 201 Created
Location: http://localhost/v1/metric/387101dc-e4b1-4602-8f40-e7be9f0ed46a
Content-Type: application/json; charset=UTF-8


"archive_policy":
"aggregation_methods": [
"std",
"sum",
"mean",
"count",
"max",
"median",
"min",
"95pct"
],
"back_window": 0,
"definition": [

"granularity": "0:00:01",
"points": 3600,
"timespan": "1:00:00"
,

"granularity": "0:30:00",
"points": 48,
"timespan": "1 day, 0:00:00"

],
"name": "low"
,
"created_by_project_id": "e8afeeb3-4ae6-4888-96f8-2fae69d24c01",
"created_by_user_id": "c10829c6-48e2-4d14-ac2b-bfba3b17216a",
"id": "387101dc-e4b1-4602-8f40-e7be9f0ed46a",
"name": null,
"resource_id": null


The archive_policy_name parameter defines how the measures that are being sent are going to be aggregated. You can also define archive policies using the API and specify what kind of aggregation period and granularity you want. In that case , the low archive policy keeps 1 hour of data aggregated over 1 second and 1 day of data aggregated to 30 minutes. The functions used for aggregations are the mathematical functions standard deviation, minimum, maximum, and even 95th percentile. All of that is obviously customizable and you can create your own archive policies. If you don't want to specify the archive policy manually for each metric, you can also create archive policy rule, that will apply a specific archive policy based on the metric name, e.g. metrics matching disk.* will be high resolution metrics so they will use the high archive policy. It's also worth noting Gnocchi is precise up to the nanosecond and is not tied to the current time. You can manipulate and inject measures that are years old and precise to the nanosecond. You can also inject points with old timestamps (i.e. old compared to the most recent one in the timeseries) with an archive policy allowing it (see back_window parameter). It's then possible to send measures to this metric:
POST /v1/metric/387101dc-e4b1-4602-8f40-e7be9f0ed46a/measures HTTP/1.1
Content-Type: application/json

[

"timestamp": "2014-10-06T14:33:57",
"value": 43.1
,

"timestamp": "2014-10-06T14:34:12",
"value": 12
,

"timestamp": "2014-10-06T14:34:20",
"value": 2

]

HTTP/1.1 204 No Content

These measures are synchronously aggregated and stored into the configured storage backend. Our most scalable storage drivers for now are either based on Swift or Ceph which are both scalable storage objects systems. It's then possible to retrieve these values:
GET /v1/metric/387101dc-e4b1-4602-8f40-e7be9f0ed46a/measures HTTP/1.1

HTTP/1.1 200 OK
Content-Type: application/json; charset=UTF-8

[
[
"2014-10-06T14:30:00.000000Z",
1800.0,
19.033333333333335
],
[
"2014-10-06T14:33:57.000000Z",
1.0,
43.1
],
[
"2014-10-06T14:34:12.000000Z",
1.0,
12.0
],
[
"2014-10-06T14:34:20.000000Z",
1.0,
2.0
]
]

As older Ceilometer users might notice here, metrics are only storing points and values, nothing fancy such as metadata anymore. By default, values eagerly aggregated using mean are returned for all supported granularities. You can obviously specify a time range or a different aggregation function using the aggregation, start and stop query parameter. Gnocchi also supports doing aggregation across aggregated metrics:
GET /v1/aggregation/metric?metric=65071775-52a8-4d2e-abb3-1377c2fe5c55&metric=9ccdd0d6-f56a-4bba-93dc-154980b6e69a&start=2014-10-06T14:34&aggregation=mean HTTP/1.1

HTTP/1.1 200 OK
Content-Type: application/json; charset=UTF-8

[
[
"2014-10-06T14:34:12.000000Z",
1.0,
12.25
],
[
"2014-10-06T14:34:20.000000Z",
1.0,
11.6
]
]

This computes the mean of mean for the metric 65071775-52a8-4d2e-abb3-1377c2fe5c55 and 9ccdd0d6-f56a-4bba-93dc-154980b6e69a starting on 6th October 2014 at 14:34 UTC. Indexing your resources Another object and concept that Gnocchi provides is the ability to manipulate resources. There is a basic type of resource, called generic, which has very few attributes. You can extend this type to specialize it, and that's what Gnocchi does by default by providing resource types known for OpenStack such as instance, volume, network or even image.
POST /v1/resource/generic HTTP/1.1

Content-Type: application/json


"id": "75C44741-CC60-4033-804E-2D3098C7D2E9",
"project_id": "BD3A1E52-1C62-44CB-BF04-660BD88CD74D",
"user_id": "BD3A1E52-1C62-44CB-BF04-660BD88CD74D"


HTTP/1.1 201 Created
Location: http://localhost/v1/resource/generic/75c44741-cc60-4033-804e-2d3098c7d2e9
ETag: "e3acd0681d73d85bfb8d180a7ecac75fce45a0dd"
Last-Modified: Fri, 17 Apr 2015 11:18:48 GMT
Content-Type: application/json; charset=UTF-8


"created_by_project_id": "ec181da1-25dd-4a55-aa18-109b19e7df3a",
"created_by_user_id": "4543aa2a-6ebf-4edd-9ee0-f81abe6bb742",
"ended_at": null,
"id": "75c44741-cc60-4033-804e-2d3098c7d2e9",
"metrics": ,
"project_id": "bd3a1e52-1c62-44cb-bf04-660bd88cd74d",
"revision_end": null,
"revision_start": "2015-04-17T11:18:48.696288Z",
"started_at": "2015-04-17T11:18:48.696275Z",
"type": "generic",
"user_id": "bd3a1e52-1c62-44cb-bf04-660bd88cd74d"


The resource is created with the UUID provided by the user. Gnocchi handles the history of the resource, and that's what the revision_start and revision_end fields are for. They indicates the lifetime of this revision of the resource. The ETag and Last-Modified headers are also unique to this resource revision and can be used in a subsequent request using If-Match or If-Not-Match header, for example:
GET /v1/resource/generic/75c44741-cc60-4033-804e-2d3098c7d2e9 HTTP/1.1
If-Not-Match: "e3acd0681d73d85bfb8d180a7ecac75fce45a0dd"

HTTP/1.1 304 Not Modified

Which is useful to synchronize and update any view of the resources you might have in your application. You can use the PATCH HTTP method to modify properties of the resource, which will create a new revision of the resource. The history of the resources are available via the REST API obviously. The metrics properties of the resource allow you to link metrics to a resource. You can link existing metrics or create new ones dynamically:
POST /v1/resource/generic HTTP/1.1
Content-Type: application/json


"id": "AB68DA77-FA82-4E67-ABA9-270C5A98CBCB",
"metrics":
"temperature":
"archive_policy_name": "low"

,
"project_id": "BD3A1E52-1C62-44CB-BF04-660BD88CD74D",
"user_id": "BD3A1E52-1C62-44CB-BF04-660BD88CD74D"


HTTP/1.1 201 Created
Location: http://localhost/v1/resource/generic/ab68da77-fa82-4e67-aba9-270c5a98cbcb
ETag: "9f64c8890989565514eb50c5517ff01816d12ff6"
Last-Modified: Fri, 17 Apr 2015 14:39:22 GMT
Content-Type: application/json; charset=UTF-8


"created_by_project_id": "cfa2ebb5-bbf9-448f-8b65-2087fbecf6ad",
"created_by_user_id": "6aadfc0a-da22-4e69-b614-4e1699d9e8eb",
"ended_at": null,
"id": "ab68da77-fa82-4e67-aba9-270c5a98cbcb",
"metrics":
"temperature": "ad53cf29-6d23-48c5-87c1-f3bf5e8bb4a0"
,
"project_id": "bd3a1e52-1c62-44cb-bf04-660bd88cd74d",
"revision_end": null,
"revision_start": "2015-04-17T14:39:22.181615Z",
"started_at": "2015-04-17T14:39:22.181601Z",
"type": "generic",
"user_id": "bd3a1e52-1c62-44cb-bf04-660bd88cd74d"


Haystack, needle? Find! With such a system, it becomes very easy to index all your resources, meter them and retrieve this data. What's even more interesting is to query the system to find and list the resources you are interested in! You can search for a resource based on any field, for example:
POST /v1/search/resource/instance HTTP/1.1
Content-Type: application/json


"=":
"user_id": "bd3a1e52-1c62-44cb-bf04-660bd88cd74d"


That query will return a list of all resources owned by the user_id bd3a1e52-1c62-44cb-bf04-660bd88cd74d. You can do fancier queries such as retrieving all the instances started by a user this month:
POST /v1/search/resource/instance HTTP/1.1
Content-Type: application/json
Content-Length: 113


"and": [

"=":
"user_id": "bd3a1e52-1c62-44cb-bf04-660bd88cd74d"

,

">=":
"started_at": "2015-04-01"


]


And you can even do fancier queries than the fancier ones (still following?). What if we wanted to retrieve all the instances that were on host foobar the 15th April and who had already 30 minutes of uptime? Let's ask Gnocchi to look in the history!
POST /v1/search/resource/instance?history=true HTTP/1.1
Content-Type: application/json
Content-Length: 113


"and": [

"=":
"host": "foobar"

,

">=":
"lifespan": "1 hour"

,

"<=":
"revision_start": "2015-04-15"


]


I could also mention the fact that you can search for value in metrics. One feature that I will very likely include in Gnocchi 1.1 is the ability to search for resource whose specific metrics matches some value. For example, having the ability to search for instances whose CPU consumption was over 80% during a month. Cherries on the cake While Gnocchi is well integrated and based on common OpenStack technology, please do note that it is completely able to function without any other OpenStack component and is pretty straight-forward to deploy. Gnocchi also implements a full RBAC system based on the OpenStack standard oslo.policy and which allows pretty fine grained control of permissions.
There is also some work ongoing to have HTML rendering when browsing the API using a Web browser. While still simple, we'd like to have a minimal Web interface served on top of the API for the same price! Ceilometer alarm subsystem supports Gnocchi with the Kilo release, meaning you can use it to trigger actions when a metric value crosses some threshold. And OpenStack Heat also supports auto-scaling your instances based on Ceilometer+Gnocchi alarms. And there are a few more API calls that I didn't talk about here, so don't hesitate to take a peek at the full documentation! Towards Gnocchi 1.1! Gnocchi is a different beast in the OpenStack community. It is under the umbrella of the Ceilometer program, but it's one of the first projects that is not part of the (old) integrated release. Therefore we decided to have a release schedule not directly linked to the OpenStack and we'll release more often that the rest of the old OpenStack components probably once every 2 months or the like. What's coming next is a close integration with Ceilometer (e.g. moving the dispatcher code from Gnocchi to Ceilometer) and probably more features as we have more requests from our users. We are also exploring different backends such as InfluxDB (storage) or MongoDB (indexer). Stay tuned, and happy hacking!

Dirk Eddelbuettel: Introducing ghrr: GitHub Hosted R Repository

ghrr logo

Background R relies on package repositories for initial installation of a package via install.packages(). A crucial second step is update.packages(): For all currently installed packages, a list of available updates is constructed or offered for either one-by-one or bulk updates. This keeps the local packages in sync with upstream, and provides for a very convenient way to obtain new features, bug fixes and other improvements. So by installing from a repository, we automatically have the ability to track the repository for updates.

Enter drat Fairly recently, the drat package was added to the R ecosystem. It makes both aspects of package distribution easy: providing a package (if you are an author) as well as installing it (if you are a user). Now, because drat is at the same time source code (as it is also a package providing the functionality), and a repository (using what drat provides ib features), the "namespace" becomes a little cluttered. But because a key feature of drat is the "one variable" unique identification via the GitHub, I opted to create a drat repository in the name of a new organisation: ghrr. This is a simple acronym for GitHub Hosted R Repository.

Use cases We can outline several use case for packages in ghrr:
  • packages not published in a repo by their authors: I already use two like that:
    • fasttime, an impeccably fast parser for ISO datetimes by Simon Urbanek which was however never released into a repo by Simon, and
    • RcppR6, a very nice extension to both R6 (by Winston) and Rcpp, by Rich FitzJohn; similarly never released beyond GitHub;
  • packages possibly unsuitable for mainline repos:
    • Rblpapi is a great package by Whit Armstong and John Laing to which I have been contributing quite a bit of late. As it requires a free-to-use but not open source library and headers from Bloomberg, it will never make it to the mainline repository for R, but hosting it in ghrr is perfect as I can easily update several machines at work once I cut a new development release;
    • winsorize is a small package I needed a few weeks ago; it is spun out of robustHD but does not yet contain new code so Andreas and I are content to keep it in this drat for now;
  • packages in pre-relase mode:
    • RcppArmadillo where I announced both a release candidate before Armadillo 5.000 came out, as well as the actual RcppArmadillo 0.500.0.0 which is not (yet) on the mainline repository as two affected packages need a small update first. Users, however, can get RcppArmadillo already from the sibling Rcpp drat repo.
    • RcppToml is a new package I am currently working on implementing a toml parser based on cpptoml. It works, but it not quite ready for public announcements yet, and hence perfect for ghrr.

Going forward ghrr is meant to be open. While anybody can open a drat repository, particularly on GitHub, it may be beneficial to somehow group packages. This is however not something that can be planned ex-ante: it may just happen if others who see similar benefits in this can in fact contribute. In that spirit, I strongly encourage pull requests. Early on, I made my commit messages conform to a pattern of package version sha1 repourl to make code provenance of every commit very clear. Ideally, subsequent commits would conform to such a scheme, or replace it with a better one.

Some Resources A few links to learn more about drat and ghrr: Comments and questions via email or issue tickets are more than welcome. We hope that others find ghrr to be a useful tool for easy repository management and use via GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Olivier Berger: How to publish an HTML5+RDFa Web site from org-mode

I m a big fan of org-mode (see previous posts), and I ve started maintaining (sic) my professional webpage(s) with it. But I ve also recently tried and publish some more Semantic/Linked Data aware documents too (again, previous posts). Ideally, I think my preferred workflow for publishing articles or documents of some importance, would be to author them in org-mode, and then publish them as HTML5 including RDFa meta-data and annotations. Instead, I ve more frequently been doing conversions of org-mode to LaTeX, in order to submit a printable version, and later-on decided to convert the LaTeX to HTML5+RDFa But one of the issues is how to properly embed the RDF meta-data inside the org-mode documents, so that the syntax is both compact and expressive enough. I doubt there s a universal solution, given that RDF tends to be complex, and graphs may not project easilly along a mainly linear structure of an org-mode document, but anyway, there seems to be possible middle grounds that are practically good enough. I ve tried and implement a solution, which reuses the principles set by John Kitchin in Extending the org-mode link syntax with attributes, i.e. implementing an HTML exporter for a particular custom link type, which will convert the plist-like syntax to some RDFa constructs. Here s a description of the whole solution : http://www-public.telecom-sudparis.eu/~berger_o/test-org-publishing-rdfa.html The nice thing about org-mode, and its litterate programming babel environment, is that it allows to embed the code of the links exporter inside the org document, avoiding to dissociate the converter from the document s source, making it auto-complete. Next step will probably be to author a paper (or convert back a preprint of mines) with org-mode, in order to provide Linked Research meta-data. Stay tuned for more details, and in the meantime, I welcome any improvement to the org/babel/elisp setup. Edit: I ve recorded a webcast to provide a bit more details, available on YouTube : https://youtu.be/OyI3DVqllx4

Manuel A. Fernandez Montecelo: About the Debian GNU/Linux port for OpenRISC or1k

In my previous post I mentioned my involvement with the OpenRISC or1k port. It was the technical activity in which I spent most time during 2014 (Debian and otherwise, day job aside). I thought that it would be nice to talk a bit about the port for people who don't know about it, and give an update for those who do know and care. So this post explains a bit how it came to be, details about its development, and finally the current status. It is going to be written as a rather personal account, for that matter, since I did not get involved enough in the OpenRISC community at large to learn much about its internal workings and aspects that I was not directly involved with. There is not much information about all of this elsewhere, only bits and pieces scattered here and there, but specially not much public information at all about the development of the Debian port. There is an OpenRISC entry in the Debian wiki, but it does not contain much information yet. Hopefully, this piece will help a bit to preserve history and give an insight for future porters. First Things First I imagine that most people reading this post will be familiar with the terminology, but just in case, to create a new Debian port means to get a Debian system (GNU/Linux variant, in this case) to run in the OpenRISC or1k computer architecture. Setting to one side all differences between hardware and software, and as described in their site:
The aim of the OpenRISC project is to create free and open source computing platforms
It is therefore a good match for the purposes of Debian and Free Software world in general. The processor has not been produced in silicon, or not available for the masses in any case. People with the necessary know-how can download the hardware description (Verilog) and synthesise it in a FPGA, or otherwise use simulators. It is not some piece of hardware that people can purchase yet, and there are no plans to mass-produce it in the near future either. The two people (including me) involved in this Debian port did not have the hardware, so we created the port entirely through cross-compiling from other architectures, and then compiling inside Qemu. In a sense, we were creating a Debian port for hardware that "does not [phisically] exist". The software that we built was tested by people who had hardware available in FPGA, though, so it was at least usable. I understand that people working in the arm64 port had to work similarly in the initial phases, working in the dark without access to real hardware to compile or test. The Spark The first time that I heard about the initiative to create the port was in late February of 2014, in a post which appeared in Linux Weekly News (sent by Paul Wise) and Slashdot. The original post announcing it was actually from late January, from Christian Svensson (blueCmd):
Some people know that I've been working on porting Glibc and doing some toolchain work. My evil master plan was to make a Debian port, and today I'm a happy hacker indeed! Below is a link to a screencast of me installing Debian for OpenRISC, installing python2.7 via apt-get (which you shouldn't do in or1ksim, it takes ages! (but it works!)) and running a small Python script. http://asciinema.org/a/7362
So, now, what can a Debian Hacker do when reading this? (Even if one's Hackery Level is not that high, as it is my case). And well, How Hard Can It Be? I mean, Really? Well, in my own defence, I knew that the answer to the last two questions would be a resounding Very . But for some reason the idea grabbed me and I couldn't help but think that it would be a Really Exciting Project, and that somehow I would like to get involved. So I wrote to Christian offering my help after considering it for a few days, around mid March, and he welcomed me aboard. The Ball Was Already Rolling Christian had already been in contact with the people behind DebianBootstrap, and he had already created the repository http://openrisc.debian.net/ with many packages of the base system and beyond (read: packages name_version_or1k.deb available to download and install). Still nowadays the packages are not signed with proper keys, though, so use your judgement if you want to try them. After a few weeks, I got up to speed with the status of the project and got my system working with the necessary tools. This meant basically sbuild/schroot to compile new packages, with the base system that Christian already got working, installed in a chroot, probably with the help of debootstrap, and qemu-system-or1k to simulate the system. Only a few of the packages were different from the version in Debian, like gcc, binutils or glibc -- they had not been upstreamed yet. sbuild ran through qemu-system-or1k, so the compilation of new packages could happen "natively" (running inside Qemu) rather than cross-compiling the packages, pulling _or1k.deb packages for dependencies from the repository that he had prepared, and _all.deb packages from snapshots.debian.org. I started by trying to get the packages that I [co-]maintain in Debian compiled for this architecture, creating the corresponding _or1k.deb. For most of them, though, I needed many dependencies compiled before I could even compile my packages. The GNU autotools / autoreconf Problem Since very early, many of the packages failed to build with messages such as:
Invalid configuration 'or1k-linux-gnu': machine 'or1k' not recognized
configure: error: /bin/bash ../config.sub or1k-linux-gnu failed
This means that software packages based on GNU autotools and using configure scripts need recent versions of the files config.sub and config.guess that they ship in their root directory, to be able to detect the architecture and generate the code accordingly. This is counter-intuitive, having into account that GNU autotools were designed to help with portability. Yet, in the case of creating new Debian ports, it meant that unless upstream had very recent versions of config. guess,sub , it would prevent the package to compile straight away in the new architectures -- even if invoking gcc without ado would have worked without problems in most cases for native compilation. Of course this did not only affect or1k, and there was already the autoreconf effort underway as a way to update these files automatically when building Debian packages, pushed by people porting Debian to the new architectures added in 2013/2014 (mips64el, arm64, ppc64el), which encountered the same roadblock. This affected around a thousand source packages in unstable. A Royal Pain. Also, all of their reverse dependencies (packages that depended on those to be built) could not be compiled straight away. The bugs were not Release Critical, though (none of these architectures were officially accepted at the time), so for people not concerned with the new ports there was no big incentive to get them fixed. This problem, which conceptually is easily solvable, prevented new ports to even attempt compile vast portions of the archive straight away (cleanly, without modifications to the package or to the host system), for weeks or months. The GNU autotools / autoreconf Solution We tackled this problem mainly in two ways. First, more useful for Debian in general, was to do as other porters were doing and submit bug reports and patches to Debian packages requesting them to use autoreconf, and NMUing packages (uploading changes to the archive without the official maintainers' intervention). A few NMUs were made for packages which had bug reports with patches available for a while, that were in the critical path to get many other packages compiled, and that were orphan or had almost no maintainer activity. The people working in the other new ports, and mainly Ubuntu people which helped with some of those ports and wanted to support them, had submitted a large amount of requests since late 2013, so there was no shortage of NMUs to be made. Some porters, not being Debian Developers, could not easily get the changes applied; so I also helped a bit the porters of other architectures, specially later on before the freeze of Jessie, to get as many packages compiled in those architectures as possible. The second way was to create dpkg-buildpackage hooks that updated unconditionally config. guess,sub before attempting to build the package in the local build system. This local and temporary solution allowed us in the or1k port to get many _or1k.deb packages in the experimental repository, which in turn would allow many more packages to compile. After a few weeks, I set up many sbuilds in a multi-core machine attempting to build uninterruptedly packages that were not previously built and which had their dependencies available. Every now and then (typically several times per day in peak times) I pushed the resulting _or1k.deb files to the repository, so more packages would have the necessary dependencies ready to attempt to build. Christian was doing something similar, and by April at peak times, among the two of us, we were compiling some days more than a hundred packages -- a huge amount of packages did not need any change other than up-to-date config. guess,sub files. At some point, late April, Christian set up wanna-build in a few hosts to do this more elegantly and smartly than my method, and more effectively as well. Ugly Hacks, Bugs and Shortcomings in the Toolchain and Qemu Some packages are extremely important because many other packages need them to compile (like cmake, Qt or GTK+), and they are themselves very complex and have dependency loops. They had deeper problems than the autoreconf issue and needed some seriously dirty hacking to get them built. To try to get as many packages compiled as possible, we sometimes compiled these important packages with some functionality disabled, disabling some binary packages (e.g. Java bindings) or specially disabling documentation (using DEB_BUILD_OPTIONS=nodoc when possible, and more aggressively when needed by removing chunks of debian/rules). I tried to use the more aggressive methods in as few packages as possible, though, about a dozen in total. We also used DEB_BUILD_OPTIONS=nocheck for speeding up compilation and avoiding build failures -- many packages' tests failed due to qemu-system-or1k not supporting multi-threading, which we could do nothing about at the time, but otherwise the packages mostly passed tests fine. Due to bugs and shortcomings in Qemu and the toolchain --like the compiler lacking atomics, missing functionality in glibc, Qemu entering in endless loops, or programs segfaulting (especially gettext, used by many packages and causing the packages failing to build)--, we had to resort to some very creative ways or time-consuming dull work to edit debian/rules, or to create wrappers of the real programs avoiding or forcing certain options (like gcc -O0, since -O2 made buggy binaries too often). To avoid having a mix of cleanly compiled and hacked packages in the same repository, Christian set up a two-tiered repository system -- the clean one and the dirty one. In the dirty one we dumped all of the packages that we got built, no matter how. The packages in the clean one could use packages from the dirty one to build, but they themselves were compiled without any hackery. Of course this was not a completely airtight solution, since they could contain code injected at build time from the "dirty repository" (e.g. by static linking), and perhaps other quirks. We hoped to get rid of these problems later by rebuilding all packages against clean builds of all their dependencies. In addition, Christian also spent significant amounts of time working inside the OpenRISC community, debugging problems, testing and recompiling special versions of the toolchain that we could use to advance in our compilation of the whole archive. There were other people in the OpenRISC community implementing the necessary bits in the toolchain, but I don't know the details. Good Progress Olof Kindgren wrote the OpenRISC health report April 2014 (actually posted in May), explaining the status at the time of projects in the broad OpenRISC community, and talking about the software side, Debian port included. Sadly, I think that there have been no more "health reports" since then. There was also a new post in Slashdot entitled OpenRISC Gains Atomic Operations and Multicore Support shortly thereafter. In the side of the Debian port, from time to time new versions of packages entered unstable and we started to use those newer versions. Some of them had nice fixes, like the autoreconf updates, so they did not require local modifications. In other cases, the new versions failed to build when old ones had worked (e.g. because the newer versions added support and dependencies of new versions of gnutls, systemd or other packages not yet available for or1k), and we had to repeat or create more nasty hacks to get the packages built again. But in general, progress was very good. There were about 10k arch-dependent packages in Debian at the time, and we got about half of them compiled by the beginning of May, counting clean and dirty. And, if I recall correctly, there were around the same number of arch=all (which can be installed in any architecture, after the package is built in one of them). Counting both, it meant that systems using or1k got about 15k packages available, or 75% of the whole Debian archive (at least "main", we excluded "contrib" and "non-free"). Not bad. By the middle to end of May, we had about 6k arch-dependent packages compiled, and 4k to go. The count of packages eventually reached ~6.6k at its peak (I think that in June/July). Many had been built with hacks and not rebuilt cleanly yet, but everything was fine until the amount of packages built plateaued. Plateauing There were multiple reasons for that. One of them is that after having fixed the autoreconf issue locally in some packages, new versions were uploaded to Debian without fixing that problem (in many cases there was no bug report or patch yet, so it was understandable; in other cases the requests were ignored). The wanna-build for the clean repository set up by Christian rightly considered the package out-of-date and prepared to build the more recent version, that failed. Then, other packages entering the unstable archive and build-depending on newer versions of those could not be built ("BD-Uninstallable"), until we built the newer versions of the dependencies in the dirty repository with local hacks. Consequently, the count of cleanly built packages went back-and-forth, when not backwards. More challenging was the fact that when creating a new port, language compilers which are written in that same language need to be built for that architecture first. Sometimes it is not the compiler, but compile-time or run-time support for modules of a language are not ported yet. Obviously, as with other dependencies, large amounts of packages written in those languages are bound to remain uncompiled for a long time. As Colin Watson explained in porting Haskell's GHC to arm64 and ppc64el, untangling some of the chicken-and-egg problems of language compilers for new ports is extremely challenging. Perl and Python are pretty much a pre-requisite of the base Debian system, and Christian got them working early on. But for example in May, 247 packages depended on r-base-dev (GNU R) for building, and 736 on ghc, and we did not have these dependencies compiled. Just counting those two, 1k source packages of the remaining 4k to 5k to be compiled for the new architecture would have to wait for a long time. Then there was Java, Mono, etc... Even more worrying problems were the pending issues with the toolchain, like atomics in glibc, or make check failing for some packages in the clean repository built with wanna-build. Christian continued to work on the toolchain and liasing with the rest of the OpenRISC community, I continued to request more changes to the Debian archive through a few requests to use autoreconf, and pushing a few more NMUs. Though many requests were attended, I soon got negative replies/reactions and backed off a bit. In the meantime, the porters of other new architectures at the time were mostly submitting requests to support them and not NMUing much either. Upstreaming Things continued more or less in the same state until the end of the summer. The new ports needed as many packages built as possible before the evaluation of which official ports to accept (in early September, I think, the final decision around the time of the freeze). Porters of the other new architectures (and maintainers, and other helpful Debian Developers) were by then more active in pushing for changes, specially remaining autoreconf issues, many of which benefited or1k. As I said before, I also kept pushing NMUs now and then, specially during summer, for packages which were not of immediate benefit for our port but helped the others (e.g. ppc64el needed updates to ltmain.sh for libtool which were not necessary for or1k, in addition to config. guess,sub ). In parallel in the or1k camp, there were patches that needed changes to be sent upstream, like for example Python's NumPy, that I submitted in May to the Debian package and upstream, and was uploaded to Debian in September with a new upstream release. Similar paths were followed between May and September for packages such as jemalloc, ocaml, gstreamer0.10, libgc, mesa, X.org's cf module and cmake (patch created by Christian). In April, Christian had reached the amazing milestone of tracking and getting all of the contributors of the port of GNU binutils to assign copyright to the Free Software Foundation (FSF), all of the work was refreshed and upstreamed. In July or August, he started to gather information about the contributors of the GCC port, which had started more than a decade ago. After that, nothing much happened (from the outside) until the end of the year, when Christian sent a message about the status of upstreaming GCC to the OpenRISC community. There was only one remaining person to assign the copyright to the FSF, but it was a blocker. In addition, there was the need to find one or more maintainers to liaise with upstream, review the patches, fix the remaining failures in the test suite and keeping the port in good shape. A few months after that and from what I could gather, the status remains the same. Current Status, and The Future? In terms of the Debian port, there have not been huge visible changes since the end of the summer, and not only because of the Jessie freeze. It seems that for this effort to keep going forward and be sustainable, sorting out the issues with GCC and Glibc is essential. That means having the toolchain completely pushed upstream and in good shape, and particularly completing the copyright assignment. Debian will not accept private forks of those essential packages without a very good reason even in unofficially supported ports; and from the point of view of porters, working in the remaining not-yet-built packages with continuing problems in the toolchain is very frustrating and time-consuming. Other than that, there is already a significant amount of software available that could run in an or1k system, so I think that overall the project has achieved a significant amount of success. Granted, KDE and LibreOffice are not available yet, neither are the tools depending on Haskell or Java. But a lot of software is available (including things high in the stack, like XFCE), and in many aspects it should provide a much more functional system that the one available in Linux (or other free software) systems in the late 1990s. If the blocking issues are sorted out in the near future, the effort needed to get a very functional port, on par with the unofficial Debian ports, should not be that big. In my opinion, and looking at the big picture, not bad at all for an architecture whose hardware implementation is not easy to come by, and in which the port was created almost solely with simulators. That it has been possible to get this far with such meagre resources, it's an amazing feat of Free Software and Debian in particular. As for the future, time will tell, as usual. I will try to keep you posted if there is any significant change in the future.

20 April 2015

Mark Brown: Flashing an AT91SAM9G20-EK from bare metal

Since I just had cause to do this and it was harder than it needed to be due to bitrot in the public documentation I could find I thought I d write up how to get a modern bootloader onto older Atmel boards. These instructions are written for the AT91SAM9G20-EK though they should also apply to other Atmel boards of a similar generation. These instructions are for booting from NAND since it s the default thing for the board, for this J34 should be fitted to enable the chip select and J33 disconnected to disable the dataflash. If there is something broken programmed into flash then booting while holding down BP4 should cause the second stage bootloader to trash itself and ensure the ROM bootloader puts itself into recovery mode, or just removing both J33 and J34 during power on will also ensure no second stage bootloader is found. There is a ROM bootloader but it just loads a small region from the boot media and jumps into it which isn t enough for u-boot so there is a second stage bootloader called AT91Bootstrap. Download sources for current versions from github. If it (or a more sensibly written equivalent) is not yet merged upstream you ll need to apply this patch to get it to build with a modern compiler, or you could use an old toolchain (which you ll need in the next step anyway):
diff --git a/board/at91sam9g20ek/board.mk b/board/at91sam9g20ek/board.mk
index 45f59b1822a6..b8251ca2fbad 100644
--- a/board/at91sam9g20ek/board.mk
+++ b/board/at91sam9g20ek/board.mk
@@ -1,7 +1,7 @@
 CPPFLAGS += \
        -DCONFIG_AT91SAM9G20EK \
-       -mcpu=arm926ej-s
+       -mcpu=arm926ej-s -mfloat-abi=soft
 
 ASFLAGS += \
        -DCONFIG_AT91SAM9G20EK \
-       -mcpu=arm926ej-s
+       -mcpu=arm926ej-s -mfloat-abi=soft
Once that s done you can build with:
make at91sam9g20eknf_uboot_defconfig
make CROSS_COMPILE=arm-linux-gnueabihf-
producing binaries/at91sam9g20ek-nandflashboot-uboot-$ VERSION .bin. This configuration will look for u-boot at 0x40000 in the flash so we need a u-boot binary. Unfortunately modern compilers seem to produce binaries that fail with no output. This is normally a sign that they need the ABI specifying more clearly as above but I got fed up trying to spot what was missing so I used an old CodeSourcery 2013.05 release instead, hopefully future versions of u-boot will be able to build for this target with older toolchains. Grab a recent release (I used 2015.01) and build with:
cd $ UBOOT 
make at91sam9g20ek_nandflash_defconfig
make CROSS_COMPILE=arm-linux-gnueabihf-
to get u-boot.bin. These can then be flashed using the Atmel flashing tool SAM-BA. Start it and connect to the target (there is a Linux version, though it appears to rely on old versions of TCL/TK so if you get trouble starting it the easiest thing is to use the sacrificial Windows laptop you ve obtained in order to run the entertaining flashing tools companies sometimes provide without risking a real system, or in my case your shiny new laptop that you ve not yet installed Linux on). Start it then:
  1. Connect SAM-BA to the device following the dialog on start.
  2. Make sure you ve selected NandFlash in the memory type tabs in the center of the window.
  3. Run the Enable NandFlash script.
  4. Run the Erase All script.
  5. Run the Send Boot File script and provide the at91bootstrap binary.
  6. Set Send File Name to be the u-boot binary you built earlier and Address to be 0x40000.
  7. Click Send File
  8. Press the reset button
which should result in at91bootstrap output followed by u-boot output on the serial console. A similar process works for the AT91SAM9263, there the jumper you need is J19 (sadly u-boot does not flash pictures of cute animals or forested shorelines on the screen as the default Basic LCD Project 1.4 firmware does, I m not sure this full operating system thing is really delivering improved functionality).

Daniel Pocock: WebRTC video from mini-DebConf Lyon, France

Thanks to the Debian France community for putting on another very successful mini-DebConf in Lyon recently. It was a great opportunity to meet more people for the first time and share ideas. On the first day, I gave a talk about the current status of WebRTC and the Debian WebRTC portal. You can now watch the video of the talk online. Unfortunately, we had some wifi problems that delayed the demonstration but we did eventually see it work successfully towards the end of the talk.

B lint R czey: Hot upgrading Erlang applications using tools in Debian

Erlang lets you write applications supporting zero downtime by switching one live system to another running a different application version converting the application s state on the fly to the new representation. Debian packages however can have only one installed version on a system which prevents using Erlang s hot-upgrade feature easily. Engineers at Yakaz (Jean-S bastien P dron) came up with a nice solution by creating separate directories for each application release and creating .deb packages for managing the transitions. I had to solve the same problem recently and found that the erlsvc Perl application they created needed a few patches to be usable with latest Erlang and other packages and with the changes it worked perfectly. Yakaz was not interested in accepting the patches and developing it further, but let me continue the maintenance. Please find the updated erlsvc application under my GitHub account and feel free to submit patches if you find something to fix in it. I have also packaged erlsvc as an official Debian package and it is waiting in the NEW queue for being accepted. When it enters unstable you will have to make very little effort to make your applications hot-upgradeable on Debian!

Russ Allbery: Review: The Girls from Alcyone

Review: The Girls from Alcyone, by Cary Caffrey
Series: Girls from Alcyone #1
Publisher: Tealy
Copyright: 2011
ISBN: 1-105-33727-8
Format: Kindle
Pages: 315
Sigrid is a very special genetic match born to not particularly special parents, deeply in debt in the slums of Earth. That's how she finds herself being purchased by a mercenary corporation at the age of nine, destined for a secret training program involving everything from physical conditioning to computer implants, designed to make her a weapon. Sigrid, her friend Suko, and the rest of their class are a special project of the leader of the Kimura corporation, one that's controversial even among the corporate board, and when the other mercenary companies unite against Kimura's plans, they become wanted contraband. This sounds like it could be a tense SF thriller, but I'll make my confession at the start of the review: I had great difficulty taking this book seriously. Initially, it had me wondering what horrible alterations and mind control Kimura was going to impose on the girls, but it very quickly turned into, well, boarding school drama, with little of the menace I was expecting. Not that bullying, or the adults who ignore it to see how the girls will handle it themselves, are light-hearted material, but it was very predictable. As was the teenage crush that grows into something deeper, the revenge on the nastiest bully that the protagonist manages to not be responsible for, and the conflict between unexpectedly competent girls and an invasion of hostile mercenaries. I'm not particularly well-read or informed about the genre, so I'm not the best person to make this comparison, but the main thing The Girls from Alcyone reminded me of was anime or manga. The mix of boarding-school interpersonal relationships, crushes and passionate love, and hypercompetent female action heroes who wear high heels and have constant narrative attention on their beauty had that feel to it. Add in the lesbian romance and the mechs (of sorts) that show up near the end of the story, and it's hard to shake the feeling that one is reading SF yuri as imagined by a North American author. The other reason why I had a hard time taking this seriously is that it's over-the-top action sequences (it's the Empire Strikes Back rescue scene!) mixed with rather superficial characterization, with one amusing twist: female characters almost always end up being on the side of the angels. Lady Kimura, when she appears, turns into exactly the sort of mentor figure that one would expect given the rest of the story (and the immediate deference she got felt like it was lifted from anime). The villains, meanwhile, are hissable and motivated by greed or control. While there's a board showdown, there's no subtle political maneuvering, just a variety of more or less effective temper tantrums. I found The Girls from Alcyon amusing, and even fun to read in places, but that was mostly from analyzing how closely it matched anime and laughing at how reliably it delivered characteristic tropes. It thoroughly embraces its action-hero story full of beautiful, deadly women, but it felt more like a novelization of a B-grade sci-fi TV show than serious drama. It's just not well-written or deep enough for me to enjoy it as a novel. None of the characters were particularly engaging, partly because they were so predictable. And the deeper we got into the politics behind the plot, the less believable I found any of it. I picked this up, along with several other SFF lesbian romances, because sometimes it's nice to read a story with SFF trappings, a positive ending, and a lack of traditional gender roles. The Girls from Alcyone does have most of those things (the gender roles are tweaked but still involve a lot of men looking at beautiful women). But unless you really love anime-style high-tech mercenary boarding-school yuri, want to read it in book form, and don't mind a lot of cliches, I can't recommend it. Followed by The Machines of Bellatrix. Rating: 3 out of 10

19 April 2015

Richard Hartmann: Release Critical Bug report for Week 16

The UDD bugs interface currently knows about the following release critical bugs: How do we compare to the Squeeze and Wheezy release cycles?
Week Squeeze Wheezy Jessie
43 284 (213+71) 468 (332+136) 319 (240+79)
44 261 (201+60) 408 (265+143) 274 (224+50)
45 261 (205+56) 425 (291+134) 295 (229+66)
46 271 (200+71) 401 (258+143) 427 (313+114)
47 283 (209+74) 366 (221+145) 342 (260+82)
48 256 (177+79) 378 (230+148) 274 (189+85)
49 256 (180+76) 360 (216+155) 226 (147+79)
50 204 (148+56) 339 (195+144) ???
51 178 (124+54) 323 (190+133) 189 (134+55)
52 115 (78+37) 289 (190+99) 147 (112+35)
1 93 (60+33) 287 (171+116) 140 (104+36)
2 82 (46+36) 271 (162+109) 157 (124+33)
3 25 (15+10) 249 (165+84) 172 (128+44)
4 14 (8+6) 244 (176+68) 187 (132+55)
5 2 (0+2) 224 (132+92) 175 (124+51)
6 release! 212 (129+83) 161 (109+52)
7 release+1 194 (128+66) 147 (106+41)
8 release+2 206 (144+62) 147 (96+51)
9 release+3 174 (105+69) 152 (101+51)
10 release+4 120 (72+48) 112 (82+30)
11 release+5 115 (74+41) 97 (68+29)
12 release+6 93 (47+46)
13 release+7 50 (24+26)
14 release+8 51 (32+19)
15 release+9 39 (32+7)
16 release+10 20 (12+8)
17 release+11 24 (19+5)
18 release+12 2 (2+0)
Graphical overview of bug stats thanks to azhag:

Patrick Schoenfeld: Resources about writing puppet types and providers

When doing a lot of devops stuff with Puppet, you might get to a point, where the existing types are not enough. That point is usually reached, when a task at hand becomes extraordinary complex when trying to achieve it with the Puppet DSL. One example of such a case could be if you need to interact with a system binary a lot. In this case, writing your own puppet type might be handy. Now where to start, if you want to write your own type? Overview: modeling and providing types First thing that you should know about puppet types (if you do not already): a puppet resource type consists of a type and one or more providers. The type is a model of the resource and describes which properties (e.g. the uid of a user resource) and parameters (like the managehome parameter) a resource has. It s a good idea to start with a rough idea of what properties you ll be manage with your resource and what values they will accept, since the type also does the job of validation. What actually needs to be done on the target system is what the provider is up to. There can be different providers for different implementations (e.g. a native ruby implementation or an implementation using a certain utility), different operating systems and other conditions. A combination of a type and a matching provider is what forms a (custom) resource type. Resources Next I ll show you some resources about puppet provider development, that I found useful: Official documentation: Actually types and resources is quiet well documented in the official documentation, although it might not get to much in the details: Blog posts:
A hands-on tutorial in multiple parts with good explanations are the blog posts by Gary Larizza: Books:
The probably most complete information, including explanations of the puppet resource model and it s resource abstraction layer (RAL), can be found in the book Puppet Types and providers by Dan Bode and Nan Liu. The puppet source:
Last but not least, it s always worth a peek at how others did it. The puppet source contains all providers of the official puppet release, as well as the base libraries for puppet types and providers with their api documentation: https://github.com/puppetlabs/puppet/

Wouter Verhelst: Youn Sun Nah 5tet: Light For The People

About a decade ago, I played in the (now defunct) "Jozef Pauly ensemble", a flute choir connected to the musical academy where I was taught to play the flute. At the time, this ensemble had the habit of goin on summer trips every year; sometimes these trips were large international concert tours (like our 2001 trip to Australia), but that wasn't always the case; there have also been smaller trips, like the 2002 one to the French Ardennes. While there, we went on a day trip to the city of Reims. As a city close to the front in the first world war, it has a museum dedicated to that subject that I remembered going to. But the fondest memory of that day was going to a park where a podium was set up, with a few stacks of fold-up chairs standing nearby. I took one and listened to the music. That was the day when I realized that I kindof like jazz. I had come into contact with Jazz before, but it had always been something to be used as a kind of musical wallpaper; something you put on, but don't consciously listen to. Watching this woman sing, however, was a different kind of experience altogether. I'm still very fond of her rendition of "Besame Mucho". After having listened to the concert for about two hours, they called it quits, but did tell us that there was a record which you could buy. Of course, after having enjoyed the afternoon so much, I couldn't imagine not buying it, so that happened. Fast forward several years, in the move from my apartment above my then-office to my current apartment (just around the corner), the record got put into the wrong box, and when I unpacked things again it got lost; permanently, I thought. Since I also hadn't digitized it yet at the time, I haven't listened to it anymore in quite a while. But that time came to an end today. The record which I thought I'd lost wasn't, it was just in a weird place, and while cleaning yesterday, I found it sitting among a bunch of old stuff that I was going to throw out. Putting on the record today made me realize again how good it really is, and I thought that I might want to see if she was still active, and if she might perhaps have made another album. It was great to find out that not only had she made six more albums since the one I bought, she'd also become a lot more known in the Jazz world (which I must admit I don't really follow all that well), and won a number of awards. At the time, Youn Sun Nah was just a (fairly) recent graduate from a particular Jazz school in Paris. Today, she appears to be so much more...

Laura Arjona: Six months selfhosting: my userop experiences

Note: In this post I mention some problems and ask questions (to myself, like thinking aloud ). The goal is not to get answers to those questions (I suppose that I will find them soon or later in the internet, manuals and so), but to show the kind of problems and questions that arise in my selfhosting adventures, which I suppose are common to other people trying to administer a home server with some web services. Am I an userop? Well I m something in the middle of (GNU/Linux) user and sysadmin: I have studied computer technical engineering but most of my experience has been in helpdesk, providing support for Windows users. I m running Debian in some LAMP boxes at work (without GUI) since 2008 or so, and in my desktops (with GUI) since 2010. I don t code nor package, but I don t mind trying to read code and understand it (or not). I know a bit of C, a bit of Python, of PHP, and enough Perl to open a Perl file and close it after two minutes, understanding that it s great, but too much for me :) I translate software, so I m not scared to clone a repository, edit files, commit or submit a patch. I m not scared of compiling a program (except if it s an Android app: I try to avoid setting up the development environment just to try some translation that I made but I built my Puma before it was the binary available for download or in F-Droid). In conclusion, I feel more like a GNU/Linux power user than a sysadmin . Sometimes just a user or even a newbie (for example, I don t know very well the Unix/Linux folder tree where are the wallpapers stored? Does it depend on the desktop that I use?). Anyway. I won t stop my free software + free networks digital life because I don t know many things. I bought a small server for home last September, and I wanted to try to selfhost some services, for me and for my family. I want to be a home sysadmin or something like that, so I joined the userops mailing list :) Here you have my experiences on selfhosting/being an userop until now. Mail I even didn t try to setup my mail server, because many people say it s a pain (although nice articles were published about how to do it, for example this series in ArsTechnica) and I need a static IP which is 14 /month more to my ISP, and Gandi, the place where I rented my domain name, provides mail, and they use Debian and Roundcube, and sponsor Debian too, so I decided to trust on them. So this is my strategy now, to try to keep mail under my control: MediaGoblin I ve setup two MediaGoblin instances (yes, two!). I managed to do it in Debian 7 stable (I think NodeJS npm was not needed then), but soon later I upgraded to Jessie so now it s even better. I installed Nginx and PostgreSQL via apt, to use them for both instances (and probably some more software later). One instance is public, and I use a Debian user, a PostgreSQL database, and it s running in http://media.larjona.net
I have requested an SSL cert to Gandi but I still didn t deployed it (lazy LArjona!!). The other instance is private, for family photos. I didn t know very well how much of my existing setup could reuse and how to keep both instances in case of downtimes or attack I know more or less the concept or chroot but I don t know how to deploy it in my machine. So I decided to use another Debian user, another PostgreSQL database, deploy MediaGoblin in a different folder, and create another virtual server in my Nginx to serve it. I managed to setup that virtual server to http-authenticate and to serve content via a different port, and use a self-signed SSL certificate (it s only for family, so it does not matter). I created another (unprivileged) Debian user with a password for the nginx authentication, and gave my family the URL in the form https://mediaprivate.larjona.net:PortNumber and the user and password (mediaprivate is a string, and PortNumber is a number). I think they don t use the instance too much, but at least I upload photos there from time to time and email the link instead of emailing the photos themselves (they don t use GPG either ). Upgrades I upgraded MediaGoblin from 0.7.1 to 0.8.0 successfully, I sent a report about how I did it to the mailing list. First I upgraded the public instance, when I figure out the process, I upgraded the second instance to test my instructions, and then, I sent the report with the instructions to the mailing list. Static site and LimeSurvey: the power of free software (with instructions) I wanted to act as a mirror of floss2013.libresoft.es and surveys.libresoft.es since they suffer a downtime and I participated in that project (not in the sysadmin part, but in the research and content creation). The static site floss2013.libresoft.es offered a zip with the whole website tree (since the website was licensed as AGPL), and I had access to the git repo holding the development copy of the website. So I just cloned the repository and setup another nginx virtual server in my machine, and tuned my DNS zone in Gandi website to serve floss2013.larjona.net from home. 10 minutes setup YAY! #inGitWeTrust #FreeSoftwareFTW :) For surveys.larjona.net I had to install a LimeSurvey instance. I knew how to do it because we use LimeSurvey at work, but at home I had Nginx instead of Apache, and PostgreSQL instead of MySQL. And no PHP I searched about how to install PHP in Nginx (I can use apt-get, nice!) and how to install LimeSurvey with Nginx and PostgreSQL (I had documentation about that, so I followed, and it worked). For making available the data (one survey and its results, so people can login as visitor to query and get statistics), I downloaded the LimeSurvey export dataset that we were providing in the static website, followed the replication instructions (hey, I wrote them!), and they worked #oleole! (And here, dear researchers, gets demonstrated that free software and free culture really empower your research and help spreading your results). Etherpad: not so easy, it seems! I m trying to install Etherpad-Lite, but I m suffering a bit. I think I did everything ok according to some guides but I get Bad Gateway and these kind of errors when trying to browse with Lynx in the host:
[error] 3615#0: *24 upstream timed out (110: Connection timed out) 
while reading response header from upstream, 
client: 127.0.0.1, 
server: pad.larjona.net, 
request: "GET / HTTP/1.0", 
upstream: "http://127.0.0.1:9001/", 
host: "pad.larjona.net"
2015/04/17 20:52:56 [error] 3615#0: *24 connect() failed 
(111: Connection refused) while connecting to upstream, 
client: 127.0.0.1, 
server: pad.larjona.net, 
request: "GET / HTTP/1.0", 
upstream: "http://[::1]:9001/", 
host: "pad.larjona.net"
I m not sure if I need to open some port in iptables, my router, or change my nginx configuration because the guides assume you re only serving one website in the port 80 (and I have several of them, now ), or what I ve spent three chunks of time (maybe ~2h each?) on this, in different days, and couldn t figure it out, so I decided to round-robin in my TODO list. Userops thoughts Debian brings peace of mind (for me) On one side, maintaining a Debian box it s quite easy, and the more software that it s packaged, the less time that I spend installing or upgrading. I like being in stable, I m in Jessie now (I migrated when it was frozen), but I ll stay in stable as much as I can. I like that I can use the software that I installed via apt-get for several services (nginx, PostgreSQL ). About the software that is not packaged (MediaGoblin, LimeSurvey, EtherPad, maybe others later), I wonder how dependencies and updates are handled. And maybe (probably) I have installed some components several times, one for each service (this sounds like a Windows box #grr). For example MediaGoblin uses PyPump. PyPump 0.5 is packaged in Debian Jessie. MediaGoblin uses PyPump 0.7+. What if PyPump 0.7+ gets, let s say, into Jessie-backports? Can I benefit from that? I know that MediaGoblin upgrade instructions includes upgrading the dependencies, but what about some security patch in one dependency? Should I upgrade the pip modules periodically? How to know if some upgrade is recommended because patches a vulnerability, or it s just new features (and maybe breaking my setup)? This kind of things are the peace of mind that Debian packaging brings to me: when some piece of software is packaged, I know maybe I need to care about proper setup and configuration, but later, it s kind-of-easy to maintain (since the Debian maintainers care about the rest). I don t mind about cloning a repo and compiling, I mind about later, or coexistance with other program/services. I trust in the MediaGoblin community and I m an active member (I m not developer, but hang on IRC, follow the mailing list, etc) but for example I don t know anything about the EtherPad project. And I don t feel like joining the community (I m already an active member in Debian, MediaGoblin, F-Droid, Pump.io, translator of LimeSurvey and many other small apps that I use, and in the future will use more services, like OwnCloud, XMPP ), joining the community of each software that I use is becoming not sustainable :s Free software is more than software I follow the userop mailing list, and it s becoming very technical. I mostly understand the problems (which are similar to the problems that I face: how to isolate different services, how to easily-configure them, how to make them installable by average user ) But I don t understand most of the solutions proposed, and I think that probably we need technical solutions, but in the meanwhile, some issues can be addressed not with software, but with other means: good documentation, community support, translations, beta-testers This is my conclusion until now. When a project is well documented, I think I can find my way to selfhost no matter if the software is packaged (or contained ) or not. MediaGoblin, and LimeSurvey, are well documented, and the user support channels are very responsive. I find lots of instructions that assume that you will use a whole machine for their service (and not for other things). And lots of documentation for the LAMP stack, but not for Nginx + PostgreSQL and Node instead of PHP So, for each particularity of my setup, I search the internet and try to pick good sources to help me do what I wanted to do. I m kind of privileged Some elements, not software related, to take into account as pre-requisites for succeed selfhosting services: These aspects are not present in a lot of people. If I look around to the computer users that I know (mostly Windows+Android, some GNU/Linux users, some Mac OSX users, some iOS users), I find that they search things like X does not work or they cannot write a proper search query in English. Or they trust some random person writing a recipe in their blog, without trying first to understand what the recipe does. Other people just say I m not a professional sysadmin, I ll just do what everybody does (aka use Google services or whatever). What if I try and I don t succeed? . Things like that. We may need some technical solutions (and hackers are thinking about that, and working on that). But I feel that we need (more) a huge group of beta-testers, dogfooding people, aventurers that try the half-cooked solutions and provide successful and unsuccessful experiences, to guide the research and make software technologies advance. I m not sure if I am an userop, but I feel part of that vanguard force , I want to be part of the future of free software and free networks. Comments? You can comment about this post on this pump.io thread.
Filed under: My experiences and opinion Tagged: Communities, Contributing to libre software, Debian, Developer motivations, English, free networks, Free Software, Freedom, innovation, MediaGoblin, Moving into free software, Project Management, selfhosting, sysadmin

18 April 2015

Gregor Herrmann: RC bugs 2015/11-16

only one week left until the jessie release. yay! in the last weeks I didn't find many RC bugs that I could fix; still, here's the short list; nice feature: I mostly help others or could build an work done by others.

Next.

Previous.