Search Results: "nate"

12 June 2023

Matthew Palmer: Private Key Redaction: Redux

[Note: the original version of this post named the author of the referenced blog post, and the tone of my writing could be construed to be mocking or otherwise belittling them. While that was not my intention, I recognise that was a possible interpretation, and I have revised this post to remove identifying information and try to neutralise the tone. On the other hand, I have kept the identifying details of the domain involved, as there are entirely legitimate security concerns that result from the issues discussed in this post.] I have spoken before about why it is tricky to redact private keys. Although that post demonstrated a real-world, presumably-used-in-the-wild private key, I ve been made aware of commentary along the lines of this representative sample:
I find it hard to believe that anyone would take their actual production key and redact it for documentation. Does the author have evidence of this in practice, or did they see example keys and assume they were redacted production keys?
Well, buckle up, because today s post is another real-world case study, with rather higher stakes than the previous example.

When Helping Hurts Today s case study begins with someone who attempted to do a very good thing: they wrote a blog post about using HashiCorp Vault to store certificates and their private keys. In his post, they included some test data, a certificate and a private key, which they redacted. Unfortunately, they did not redact these very well. Each base64 blob has had one line replaced with all xs. Based on the steps I explained previously, it is relatively straightforward to retrieve the entire, intact private key.

From Bad to OMFG Now, if this post author had, say, generated a fresh private key (after all, there s no shortage of possible keys), that would not be worthy of a blog post. As you may surmise, that is not what happened. After reconstructing the insufficiently-redacted private key, you end up with a key that has a SHA256 fingerprint (in hex) of: 72bef096997ec59a671d540d75bd1926363b2097eb9fe10220b2654b1f665b54 Searching for certificates which use that key fingerprint, we find one result: a certificate for hiltonhotels.jp (and a bunch of other, related, domains, as subjectAltNames). As of the time of writing, that certificate is not marked as revoked, and appears to be the same certificate that is currently presented to visitors of that site. This is, shall we say, not great. Anyone in possession of this private key which, I should emphasise, has presumably been public information since the post s publication date of February 2023 has the ability to completely transparently impersonate the sites listed in that certificate. That would provide an attacker with the ability to capture any data a user entered, such as personal information, passwords, or payment details, and also modify what the user s browser received, including injecting malware or other unpleasantness. In short, no good deed goes unpunished, and this attempt to educate the world at large about the benefits of secure key storage has instead published private key material. Remember, kids: friends don t let friends post redacted private keys to the Internet.

11 June 2023

Dirk Eddelbuettel: sanitizers 0.1.1 on CRAN: Updated and Expanded

bleach The second release of the sanitizers package is now on CRAN. sanitizers provides true positives for programming errors detected by Address Sanitizers and friends. This permits validation of the setup when chasing such bug reports: it allows us to ascertain that the compiler (and instrumented R version) are correctly set up and the errors we expect to be reported are in fact reported. Almost nine years (!!) since the first release, this update brings an added integer overflow sanitizer contributed by Greg Jeffries so long ago that I had thought it was part of the CRAN releases my bad for delaying this. It also updates programming practices by switching to symbol registration for the compiled functions. And of course several R packaging best practices have improved since the initial release so we updated a few small things throughout. A very good resources for all things sanitizers is the Google repo at GitHub and especially its wiki. The brief NEWS entry follows.

Changes in version 0.1.1 (2023-06-11)
  • Added integer overflow example kindly contributed by Greg Jeffries
  • Added continuous integration and badges
  • Updated package to use symbol registration for compiled code
  • Updated and edited DESCRIPTION, README and help pages for current packaging standards
  • Expanded README with usage example via r-devel-san Rocker container

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page, the github repo, and the package documentation for more details. If you like the open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

10 June 2023

Freexian Collaborators: Debian Contributions: /usr-merge updates, tox 4 transition, and more! (by Utkarsh Gupta, Stefano Rivera)

Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

/usr-merge, by Helmut Grohne, et al Towards the end of April, the discussion on DEP 17 on debian-devel@l.d.o initiated by Helmut Grohne took off, trying to deal with the fact that while Debian bookworm has a merged /usr, files are still being distributed to / and /usr in Debian binary packages, and moving them currently has some risk of breakage. Most participants of the discussion agreed that files should be moved, and there are several competing design ideas for doing it safely. Most of the time was spent understanding the practical implications of lifting the moratorium and moving all the files from / to /usr in a coordinated effort. With help from Emilio Pozuelo Monfort, Enrico Zini, and Raphael Hertzog, Helmut Grohne performed extensive analysis of the various aspects, including quantitative analysis of the original file move problem, analysis of effects on dpkg-divert, dpkg-statoverride, and update-alternatives, analysis of effects on filesystem bootstrapping tools. Most of the problematic cases spawned plausible workarounds, such as turning Breaks into Conflicts in selected cases or adding protective diversions for the symbolic links that enable aliasing. Towards the end of May, Andreas Beckmann reported a new failure scenario which may cause shared resources to inadvertently disappear, such as directories and even regular files in case of Multi-Arch packages, and our work on analyzing these problems and proposing mitigations is on-going. While the quantitative analysis is funded by Freexian, we wouldn t be here without the extensive feedback and ideas of many voluntary contributors from multiple areas of Debian, which are too many to name here. Thank you.

Preparing for the tox 4 transition, by Stefano Rivera While Debian was in freeze for the bookworm release, tox 4 has landed in Debian experimental, and some packages are starting to require it, upstream. It has some backwards-incompatible behavior that breaks many packages using tox through pybuild. So Stefano had to make some changes to pybuild and to many packages that run build-time tests with tox. The easy bits of this transition are now completed in git / experimental, but a few packages that integrate deeply into tox need upstream work.

Debian Printing, by Thorsten Alteholz Just before the release of Bookworm, lots of QA tools were used to inspect packages. One of these tools found a systemd service file in a wrong directory. So, Thorsten did another upload of package lprint to correct this. Thanks a lot to all the hardworking people who run such tools and file bugs. Thorsten also participated in discussions about the new Common Printing Dialog Backends (CPDB) that will be introduced in Trixie and hopefully can replace the current printing architecture in Forky.

Miscellaneous contributions
  • DebConf 23 preparations by Stefano Rivera. Some work on the website, video team planning, accounting, and team documentation.
  • Utkarsh Gupta started to prep the work on the bursary team s side for DC23.
  • Stefano spun up a website for the Hamburg mini-DebConf so that the video team could have a machine-readable schedule and a place to stream video from the event.
  • Santiago Ruano Rinc n reviewed and sponsored four python packages of a prospective Debian member.
  • Helmut Grohne supported Timo Roehling and Jochen Sprickerhof to improve cross building in 15 ROS packages.
  • Helmut Grohne supported Jochen Sprickerhof with diagnosing an e2fsprogs RC bug.
  • Helmut Grohne continued to maintain rebootstrap and located an issue with lto in gcc-13.
  • Anton Gladky fixed some RC-Bugs and uploaded a new stravalib python library.

9 June 2023

Wouter Verhelst: Planet Debian rendered with PtLink

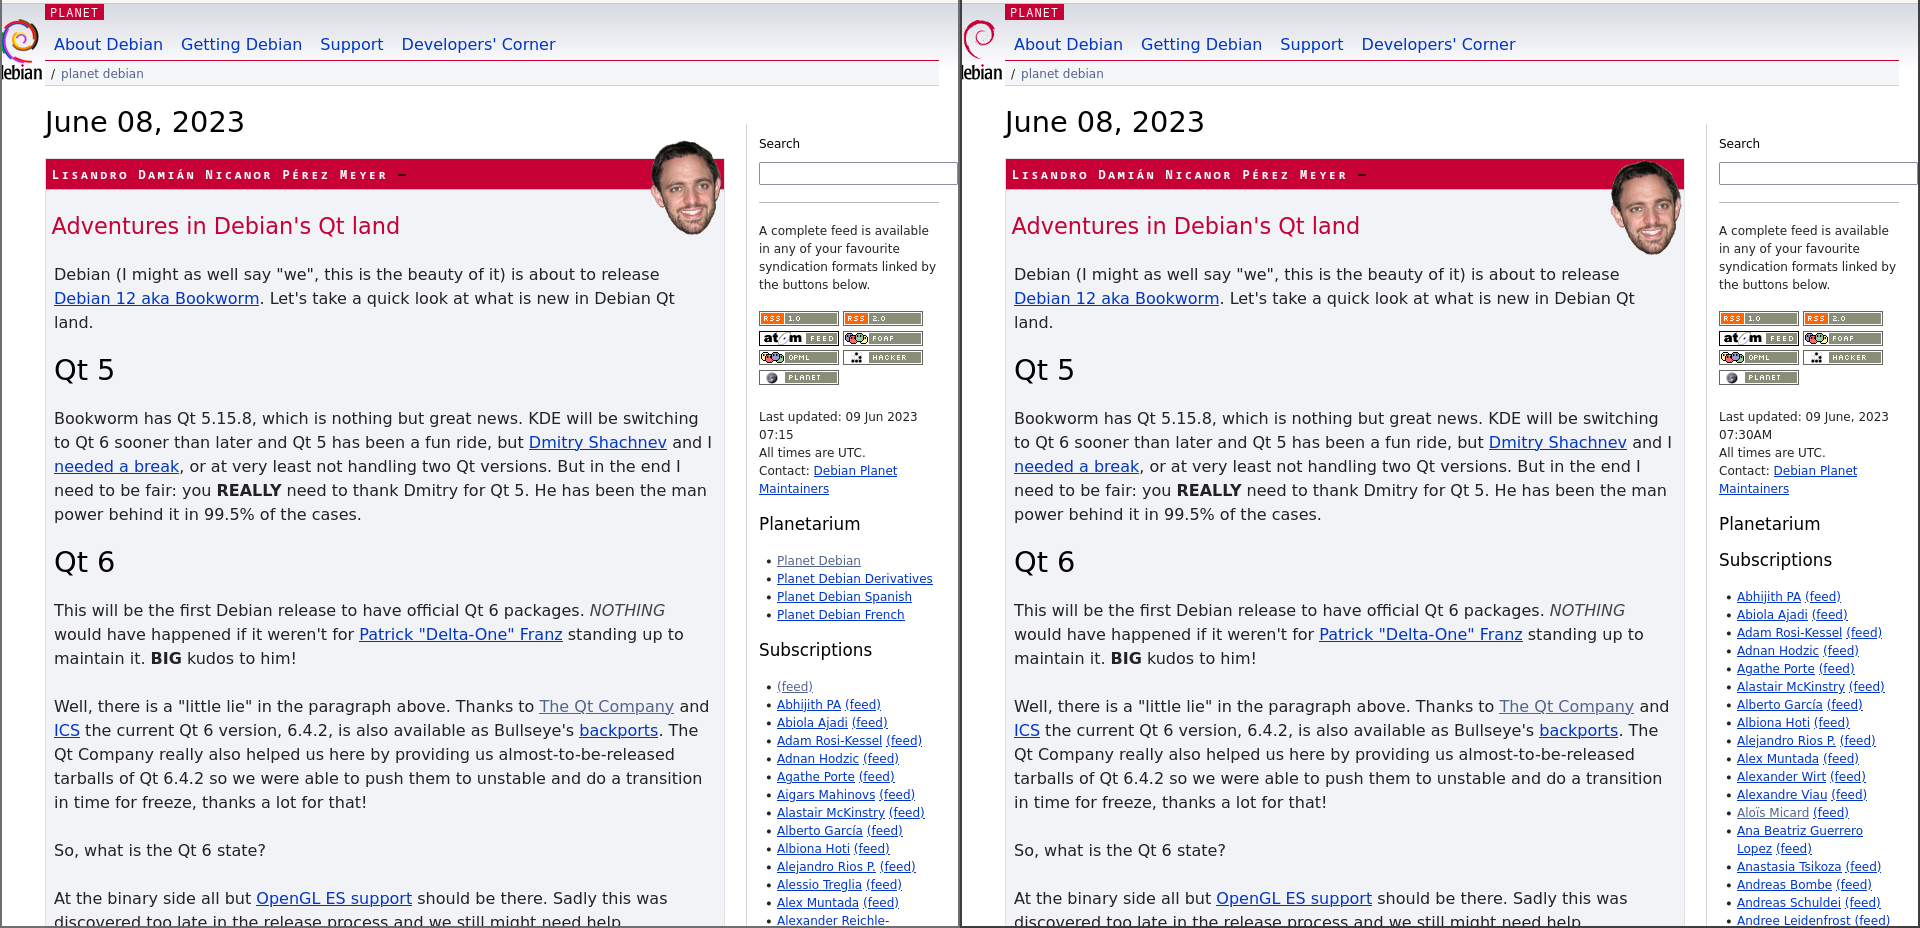
As I blogged before, I've been working on a Planet Venus replacement. This is necessary, because Planet Venus, unfortunately, has not been maintained for a long time, and is a Python 2 (only) application which has never been updated to Python 3. Python not being my language of choice, and my having plans to do far more than just the "render RSS streams" functionality that Planet Venus does, meant that I preferred to write "something else" (in Perl) rather than updating Planet Venus to modern Python. Planet Grep has been running PtLink for over a year now, and my plan had been to update the code so that Planet Debian could run it too, but that has been taking a bit longer. This month, I have finally been able to work on this, however. This screenshot shows two versions of Planet Debian: The rendering on the left is by Planet Venus, the one on the right is by PtLink. It's not quite ready yet, but getting there. Stay tuned.

6 June 2023

Russell Coker: PinePhonePro First Impression

Hardware I received my PinePhone Pro [1] on Thursday, it seems in many ways better than the Purism Librem 5 [2] that I have previously written about. The PinePhone is thinner, lighter, and yet has a much longer battery life. A friend described the Librem5 as the CyberTruck phone and not in a good way. In a test I had my PinePhone and my Librem5 fully charged, left them for 4.5 hours without doing anything much with them, and then the PinePhone was at 85% and the Librem5 was at 57%. So the Librem5 will run out of battery after about 10 hours of not being used while a PinePhonePro can be expected to last about 30 hours. The PinePhonePro isn t as good as some of the recent Android phones in this regard but it shows the potential to be quite usable. For this test both phones were connected to a 2.4GHz Wifi network (which uses less power than 5GHz) and doing nothing much with an out of the box configuration. A phone that is checking email, social networking, and a couple of IM services will use the battery faster. But even if the PinePhone has it s battery used twice as fast in a more realistic test that will still be usable. Here are the passmark results from the PinePhone Pro [3] which got a CPU score of 888 compared to 507 for the Librem 5 and 678 for one of the slower laptops I ve used. The results are excluded from the Passmark averages because they identified the CPU as only having 4 cores (expecting just 4*A72) while the PinePhonePro has 6 cores (2*A72+4*A53). This phone definitely has the CPU power for convergence [4]! Default OS By default the PinePhone has a KDE based GUI and the Librem5 has a GNOME based GUI. I don t like any iteration of GNOME (I have tried them all and disliked them all) and I like KDE so I will tend to like anything that is KDE based more than anything GNOME based. But in addition to that the PinePhone has an interface that looks a lot like Android with the three on-screen buttons at the bottom of the display and the way it has the slide up tray for installed apps. Android is the most popular phone OS and looking like the most common option is often a good idea for a new and different product, this seems like an objective criteria to determine that the default GUI on the PinePhone is a better choice (at least for the default). When I first booted it and connected it to Wifi the updates app said that there were 633 updates to apply, but never applied them (I tried clicking on the update button but to no avail) and didn t give any error message. For me not being Debian is enough reason to dislike Manjaro, but if that wasn t enough then the failure to update would be a good start. When I ran pacman in a terminal window it said that each package was corrupt and asked if I wanted to delete it. According to tar tvJf the packages weren t corrupt. After downloading them again it said that they were corrupt again so it seemed that pacman wasn t working correctly. When the screen is locked and a call comes in it gives a window with Accept and Reject buttons but neither of them works. The default country code for Spacebar (the SMS app) is +1 (US) even though I specified Australia on the initial login. It also doesn t get the APN unlike Android phones which seem to have some sort of list of APNs. Upgrading to Debian The Debian Wiki page about Installing on the PinePhone Pro has the basic information [5]. The first thing it covers is installing the TOW boot loader which is already installed by default in recent PinePhones (such as mine). You can recognise that TOW is installed by pressing the volume-up button in the early stages of boot up (described as before and during the second vibration ), then the LED will turn blue and the phone will act as a USB mass storage device which makes it easy to do other install/recovery tasks. The other TOW option is to press volume-down to boot from a MicroSD card (the default is to boot the OS on the eMMC). The images linked from the Debian wiki page are designed to be installed with bmaptool from the bmap-tools Debian package. After installing that package and downloading the pre-built Mobian image I installed it with the command bmaptool copy mobian-pinephonepro-phosh-bookworm-12.0-rc3.img.gz /dev/sdb where /dev/sdb is the device that the USB mapped PinePhone storage was located. That took 6 minutes and then I rebooted my PinePhone into Mobian! Unfortunately the default GUI for Mobian is GNOME/Phosh. Changing it to KDE is my next task.

5 June 2023

Reproducible Builds: Reproducible Builds in May 2023

Welcome to the May 2023 report from the Reproducible Builds project In our reports, we outline the most important things that we have been up to over the past month. As always, if you are interested in contributing to the project, please visit our Contribute page on our website.


Holger Levsen gave a talk at the 2023 edition of the Debian Reunion Hamburg, a semi-informal meetup of Debian-related people in northern Germany. The slides are available online.
In April, Holger Levsen gave a talk at foss-north 2023 titled Reproducible Builds, the first ten years. Last month, however, Holger s talk was covered in a round-up of the conference on the Free Software Foundation Europe (FSFE) blog.
Pronnoy Goswami, Saksham Gupta, Zhiyuan Li, Na Meng and Daphne Yao from Virginia Tech published a paper investigating the Reproducibility of NPM Packages. The abstract includes:
When using open-source NPM packages, most developers download prebuilt packages on npmjs.com instead of building those packages from available source, and implicitly trust the downloaded packages. However, it is unknown whether the blindly trusted prebuilt NPM packages are reproducible (i.e., whether there is always a verifiable path from source code to any published NPM package). [ ] We downloaded versions/releases of 226 most popularly used NPM packages and then built each version with the available source on GitHub. Next, we applied a differencing tool to compare the versions we built against versions downloaded from NPM, and further inspected any reported difference.
The paper reports that among the 3,390 versions of the 226 packages, only 2,087 versions are reproducible, and furthermore that multiple factors contribute to the non-reproducibility including flexible versioning information in package.json file and the divergent behaviors between distinct versions of tools used in the build process. The paper concludes with insights for future verifiable build procedures. Unfortunately, a PDF is not available publically yet, but a Digital Object Identifier (DOI) is available on the paper s IEEE page.
Elsewhere in academia, Betul Gokkaya, Leonardo Aniello and Basel Halak of the School of Electronics and Computer Science at the University of Southampton published a new paper containing a broad overview of attacks and comprehensive risk assessment for software supply chain security. Their paper, titled Software supply chain: review of attacks, risk assessment strategies and security controls, analyses the most common software supply-chain attacks by providing the latest trend of analyzed attack, and identifies the security risks for open-source and third-party software supply chains. Furthermore, their study introduces unique security controls to mitigate analyzed cyber-attacks and risks by linking them with real-life security incidence and attacks . (arXiv.org, PDF)
NixOS is now tracking two new reports at reproducible.nixos.org. Aside from the collection of build-time dependencies of the minimal and Gnome installation ISOs, this page now also contains reports that are restricted to the artifacts that make it into the image. The minimal ISO is currently reproducible except for Python 3.10, which hopefully will be resolved with the coming update to Python version 3.11.
On our rb-general mailing list this month: David A. Wheeler started a thread noting that the OSSGadget project s oss-reproducible tool was measuring something related to but not the same as reproducible builds. Initially they had adopted the term semantically reproducible build term for what it measured, which they defined as being if its build results can be either recreated exactly (a bit for bit reproducible build), or if the differences between the release package and a rebuilt package are not expected to produce functional differences in normal cases. This generated a significant number of replies, and several were concerned that people might confuse what they were measuring with reproducible builds . After discussion, the OSSGadget developers decided to switch to the term semantically equivalent for what they measured in order to reduce the risk of confusion. Vagrant Cascadian (vagrantc) posted an update about GCC, binutils, and Debian s build-essential set with some progress, some hope, and I daresay, some fears . Lastly, kpcyrd asked a question about building a reproducible Linux kernel package for Arch Linux (answered by Arnout Engelen). In the same, thread David A. Wheeler pointed out that the Linux Kernel documentation has a chapter about Reproducible kernel builds now as well.
In Debian this month, nine reviews of Debian packages were added, 20 were updated and 6 were removed this month, all adding to our knowledge about identified issues. In addition, Vagrant Cascadian added a link to the source code causing various ecbuild issues. [ ]
The F-Droid project updated its Inclusion How-To with a new section explaining why it considers reproducible builds to be best practice and hopes developers will support the team s efforts to make as many (new) apps reproducible as it reasonably can.
In diffoscope development this month, version 242 was uploaded to Debian unstable by Chris Lamb who also made the following changes: In addition, Mattia Rizzolo documented how to (re)-produce a binary blob in the code [ ] and Vagrant Cascadian updated the version of diffoscope in GNU Guix to 242 [ ].
reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, Holger Levsen uploaded versions 0.7.24 and 0.7.25 to Debian unstable which added support for Tox versions 3 and 4 with help from Vagrant Cascadian [ ][ ][ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including: In addition, Jason A. Donenfeld filed a bug (now fixed in the latest alpha version) in the Android issue tracker to report that generateLocaleConfig in Android Gradle Plugin version 8.1.0 generates XML files using non-deterministic ordering, breaking reproducible builds. [ ]

Testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In May, a number of changes were made by Holger Levsen:
  • Update the kernel configuration of arm64 nodes only put required modules in the initrd to save space in the /boot partition. [ ]
  • A huge number of changes to a new tool to document/track Jenkins node maintenance, including adding --fetch, --help, --no-future and --verbose options [ ][ ][ ][ ] as well as adding a suite of new actions, such as apt-upgrade, command, deploy-git, rmstamp, etc. [ ][ ][ ][ ] in addition a significant amount of refactoring [ ][ ][ ][ ].
  • Issue warnings if apt has updates to install. [ ]
  • Allow Jenkins to run apt get update in maintenance job. [ ]
  • Installed bind9-dnsutils on some Ubuntu 18.04 nodes. [ ][ ]
  • Fixed the Jenkins shell monitor to correctly deal with little-used directories. [ ]
  • Updated the node health check to warn when apt upgrades are available. [ ]
  • Performed some node maintenance. [ ]
In addition, Vagrant Cascadian added the nocheck, nopgo and nolto when building gcc-* and binutils packages [ ] as well as performed some node maintenance [ ][ ]. In addition, Roland Clobus updated the openQA configuration to specify longer timeouts and access to the developer mode [ ] and updated the URL used for reproducible Debian Live images [ ].

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

3 June 2023

Ben Hutchings: FOSS activity in May 2023

2 June 2023

Matt Brown: Calling time on DNSSEC: The costs exceed the benefits

I m calling time on DNSSEC. Last week, prompted by a change in my DNS hosting setup, I began removing it from the few personal zones I had signed. Then this Monday the .nz ccTLD experienced a multi-day availability incident triggered by the annual DNSSEC key rotation process. This incident broke several of my unsigned zones, which led me to say very unkind things about DNSSEC on Mastodon and now I feel compelled to more completely explain my thinking: For almost all domains and use-cases, the costs and risks of deploying DNSSEC outweigh the benefits it provides. Don t bother signing your zones. The .nz incident, while topical, is not the motivation or the trigger for this conclusion. Had it been a novel incident, it would still have been annoying, but novel incidents are how we learn so I have a small tolerance for them. The problem with DNSSEC is precisely that this incident was not novel, just the latest in a long and growing list. It s a clear pattern. DNSSEC is complex and risky to deploy. Choosing to sign your zone will almost inevitably mean that you will experience lower availability for your domain over time than if you leave it unsigned. Even if you have a team of DNS experts maintaining your zone and DNS infrastructure, the risk of routine operational tasks triggering a loss of availability (unrelated to any attempted attacks that DNSSEC may thwart) is very high - almost guaranteed to occur. Worse, because of the nature of DNS and DNSSEC these incidents will tend to be prolonged and out of your control to remediate in a timely fashion. The only benefit you get in return for accepting this almost certain reduction in availability is trust in the integrity of the DNS data a subset of your users (those who validate DNSSEC) receive. Trusted DNS data that is then used to communicate across an untrusted network layer. An untrusted network layer which you are almost certainly protecting with TLS which provides a more comprehensive and trustworthy set of security guarantees than DNSSEC is capable of, and provides those guarantees to all your users regardless of whether they are validating DNSSEC or not. In summary, in our modern world where TLS is ubiquitous, DNSSEC provides only a thin layer of redundant protection on top of the comprehensive guarantees provided by TLS, but adds significant operational complexity, cost and a high likelihood of lowered availability. In an ideal world, where the deployment cost of DNSSEC and the risk of DNSSEC-induced outages were both low, it would absolutely be desirable to have that redundancy in our layers of protection. In the real world, given the DNSSEC protocol we have today, the choice to avoid its complexity and rely on TLS alone is not at all painful or risky to make as the operator of an online service. In fact, it s the prudent choice that will result in better overall security outcomes for your users. Ignore DNSSEC and invest the time and resources you would have spent deploying it improving your TLS key and certificate management. Ironically, the one use-case where I think a valid counter-argument for this position can be made is TLDs (including ccTLDs such as .nz). Despite its many failings, DNSSEC is an Internet Standard, and as infrastructure providers, TLDs have an obligation to enable its use. Unfortunately this means that everyone has to bear the costs, complexities and availability risks that DNSSEC burdens these operators with. We can t avoid that fact, but we can avoid creating further costs, complexities and risks by choosing not to deploy DNSSEC on the rest of our non-TLD zones.

But DNSSEC will save us from the evil CA ecosystem! Historically, the strongest motivation for DNSSEC has not been the direct security benefits themselves (which as explained above are minimal compared to what TLS provides), but in the new capabilities and use-cases that could be enabled if DNS were able to provide integrity and trusted data to applications. Specifically, the promise of DNS-based Authentication of Named Entities (DANE) is that with DNSSEC we can be free of the X.509 certificate authority ecosystem and along with it the expensive certificate issuance racket and dubious trust properties that have long been its most distinguishing features. Ten years ago this was an extremely compelling proposition with significant potential to improve the Internet. That potential has gone unfulfilled. Instead of maturing as deployments progressed and associated operational experience was gained, DNSSEC has been beset by the discovery of issue after issue. Each of these has necessitated further changes and additions to the protocol, increasing complexity and deployment cost. For many zones, including significant zones like google.com (where I led the attempt to evaluate and deploy DNSSEC in the mid 2010s), it is simply infeasible to deploy the protocol at all, let alone in a reliable and dependable manner. While DNSSEC maturation and deployment has been languishing, the TLS ecosystem has been steadily and impressively improving. Thanks to the efforts of many individuals and companies, although still founded on the use of a set of root certificate authorities, the TLS and CA ecosystem today features transparency, validation and multi-party accountability that comprehensively build trust in the ability to depend and rely upon the security guarantees that TLS provides. When you use TLS today, you benefit from:
  • Free/cheap issuance from a number of different certificate authorities.
  • Regular, automated issuance/renewal via the ACME protocol.
  • Visibility into who has issued certificates for your domain and when through Certificate Transparency logs.
  • Confidence that certificates issued without certificate transparency (and therefore lacking an SCT) will not be accepted by the leading modern browsers.
  • The use of modern cryptographic protocols as a baseline, with a plausible and compelling story for how these can be steadily and promptly updated over time.
DNSSEC with DANE can match the TLS ecosystem on the first benefit (up front price) and perhaps makes the second benefit moot, but has no ability to match any of the other transparency and accountability measures that today s TLS ecosystem offers. If your ZSK is stolen, or a parent zone is compromised or coerced, validly signed TLSA records for a forged certificate can be produced and spoofed to users under attack with minimal chances of detection. Finally, in terms of overall trust in the roots of the system, the CA/Browser forum requirements continue to improve the accountability and transparency of TLS certificate authorities, significantly reducing the ability for any single actor (say a nefarious government) to subvert the system. The DNS root has a well established transparent multi-party system for establishing trust in the DNSSEC root itself, but at the TLD level, almost intentionally thanks to the hierarchical nature of DNS, DNSSEC has multiple single points of control (or coercion) which exist outside of any formal system of transparency or accountability. We ve moved from DANE being a potential improvement in security over TLS when it was first proposed, to being a definite regression from what TLS provides today. That s not to say that TLS is perfect, but given where we re at, we ll get a better security return from further investment and improvements in the TLS ecosystem than we will from trying to fix DNSSEC.

But TLS is not ubiquitous for non-HTTP applications The arguments above are most compelling when applied to the web-based HTTP-oriented ecosystem which has driven most of the TLS improvements we ve seen to date. Non-HTTP protocols are lagging in adoption of many of the improvements and best practices TLS has on the web. Some claim this need to provide a solution for non-HTTP, non-web applications provides a motivation to continue pushing DNSSEC deployment. I disagree, I think it provides a motivation to instead double-down on moving those applications to TLS. TLS as the new TCP. The problem is that costs of deploying and operating DNSSEC are largely fixed regardless of how many protocols you are intending to protect with it, and worse, the negative side-effects of DNSSEC deployment can and will easily spill over to affect zones and protocols that don t want or need DNSSEC s protection. To justify continued DNSSEC deployment and operation in this context means using a smaller set of benefits (just for the non-HTTP applications) to justify the already high costs of deploying DNSSEC itself, plus the cost of the risk that DNSSEC poses to the reliability to your websites. I don t see how that equation can ever balance, particularly when you evaluate it against the much lower costs of just turning on TLS for the rest of your non-HTTP protocols instead of deploying DNSSEC. MTA-STS is a worked example of how this can be achieved. If you re still not convinced, consider that even DNS itself is considering moving to TLS (via DoT and DoH) in order to add the confidentiality/privacy attributes the protocol currently lacks. I m not a huge fan of the latency implications of these approaches, but the ongoing discussion shows that clever solutions and mitigations for that may exist. DoT/DoH solve distinct problems from DNSSEC and in principle should be used in combination with it, but in a world where DNS itself is relying on TLS and therefore has eliminated the majority of spoofing and cache poisoning attacks through DoT/DoH deployment the benefit side of the DNSSEC equation gets smaller and smaller still while the costs remain the same.

OK, but better software or more careful operations can reduce DNSSEC s cost Some see the current DNSSEC costs simply as teething problems that will reduce as the software and tooling matures to provide more automation of the risky processes and operational teams learn from their mistakes or opt to simply transfer the risk by outsourcing the management and complexity to larger providers to take care of. I don t find these arguments compelling. We ve already had 15+ years to develop improved software for DNSSEC without success. What s changed that we should expect a better outcome this year or next? Nothing. Even if we did have better software or outsourced operations, the approach is still only hiding the costs behind automation or transferring the risk to another organisation. That may appear to work in the short-term, but eventually when the time comes to upgrade the software, migrate between providers or change registrars the debt will come due and incidents will occur. The problem is the complexity of the protocol itself. No amount of software improvement or outsourcing addresses that. After 15+ years of trying, I think it s worth considering that combining cryptography, caching and distributed consensus, some of the most fundamental and complex computer science problems, into a slow-moving and hard to evolve low-level infrastructure protocol while appropriately balancing security, performance and reliability appears to be beyond our collective ability. That doesn t have to be the end of the world, the improvements achieved in the TLS ecosystem over the same time frame provide a positive counter example - perhaps DNSSEC is simply focusing our attention at the wrong layer of the stack. Ideally secure DNS data would be something we could have, but if the complexity of DNSSEC is the price we have to pay to achieve it, I m out. I would rather opt to remain with the simpler yet insecure DNS protocol and compensate for its short comings at higher transport or application layers where experience shows we are able to more rapidly improve and develop our security capabilities.

Summing up For the vast majority of domains and use-cases there is simply no net benefit to deploying DNSSEC in 2023. I d even go so far as to say that if you ve already signed your zones, you should (carefully) move them back to being unsigned - you ll reduce the complexity of your operating environment and lower your risk of availability loss triggered by DNS. Your users will thank you. The threats that DNSSEC defends against are already amply defended by the now mature and still improving TLS ecosystem at the application layer, and investing in further improvements here carries far more return than deployment of DNSSEC. For TLDs, like .nz whose outage triggered this post, DNSSEC is not going anywhere and investment in mitigating its complexities and risks is an unfortunate burden that must be shouldered. While the full incident report of what went wrong with .nz is not yet available, the interim report already hints at some useful insights. It is important that InternetNZ publishes a full and comprehensive review so that the full set of learnings and improvements this incident can provide can be fully realised by .nz and other TLD operators stuck with the unenviable task of trying to safely operate DNSSEC.

Postscript After taking a few days to draft and edit this post, I ve just stumbled across a presentation from the well respected Geoff Huston at last weeks RIPE86 meeting. I ve only had time to skim the slides (video here) - they don t seem to disagree with my thinking regarding the futility of the current state of DNSSEC, but also contain some interesting ideas for what it might take for DNSSEC to become a compelling proposition. Probably worth a read/watch!

1 June 2023

Jamie McClelland: Enough about the AI Apocalypse Already

After watching Democracy Now s segment on artificial intelligence I started to wonder - am I out of step on this topic? When people claim artificial intelligence will surpass human intelligence and thus threaten humanity with extinction, they seem to be referring specifically to advances made with large language models. As I understand them, large language models are probability machines that have ingested massive amounts of text scraped from the Internet. They answer questions based on the probability of one series of words (their answer) following another series of words (the question). It seems like a stretch to call this intelligence, but if we accept that definition then it follows that this kind of intelligence is nothing remotely like human intelligence, which makes the claim that it will surpass human intelligence confusing. Hasn t this kind of machine learning surpassed us decades ago? Or when we say surpass does that simply refer to fooling people into thinking an AI machine is a human via conversation? That is an important milestone, but I m not ready to accept the turing test as proof of equal intelligence. Furthermore, large language models hallucinate and also reflect the biases of their training data. The word hallucinate seems like a euphemism, as if it could be corrected with the right medication when in fact it seems hard to avoid when your strategy is to correlate words based on probability. But even if you could solve the here is a completely wrong answer presented with sociopathic confidence problem, reflecting the biases of your data sources seems fairly intractable. In what world would a system with built-in bias be considered on the brink of surpassing human intelligence? The danger from LLMs seems to be their ability to convince people that their answers are correct, including their patently wrong and/or biased answers. Why do people think they are giving correct answers? Oh right terrifying right wing billionaires (with terrifying agendas have been claiming AI will exceed human intelligence and threaten humanity and every time they sign a hyperbolic statement they get front page mainstream coverage. And even progressive news outlets are spreading this narrative with minimal space for contrary opinions (thank you Tawana Petty from the Algorithmic Justice League for providing the only glimpse of reason in the segment). The belief that artificial intelligence is or will soon become omnipotent has real world harms today: specifically it creates the misperception that current LLMs are accurate, which paves the way for greater adoption among police forces, social service agencies, medical facilities and other places where racial and economic biases have life and death consequences. When the CEO of OpenAI calls the technology dangerous and in need of regulation, he gets both free advertising promoting the power and supposed accuracy of his product and the possibility of freezing further developments in the field that might challenge OpenAI s current dominance. The real threat to humanity is not AI, it s massive inequality and the use of tactics ranging from mundane bureaucracy to deadly force and incarceration to segregate the affluent from the growing number of people unable to make ends meet. We have spent decades training bureaucrats, judges and cops to robotically follow biased laws to maintain this order without compassion or empathy. Replacing them with AI would be make things worse and should be stopped. But, let s be clear, the narrative that AI is poised to surpass human intelligence and make humanity extinct is a dangerous distraction that runs counter to a much more important story about the very real and very present exploitative practices of the [companies building AI], who are rapidly centralizing power and increasing social inequities. . Maybe we should talk about that instead?

31 May 2023

Russell Coker: Links May 2023

Petter Reinholdtsen wrote an interesting blog post about their work on packaging speech to text for Debian [1]. The work of the Debian Deep Learning Team seems really interesting and I look forward to playing with this sort of thing after the release of Bookworm (the packages in question will NOT go in Bookworm but I ll run at least one system on Testing after Bookworm). It would be nice to get more information on the hardware used for running such programs, the minimum hardware needed for real-time speech to text would be interesting to know. Brian Krebs wrote an informative article about attacks involving supply chain compromise and fake LinkedIn profiles [2]. The attacks targetted Linux as well as Windows. Interesting video about the Illium cameras, a bit harsh though, they criticise Illium devices for being too low resolution, too expensive, and taking too much CPU time to process [3]. The Illium cameras still sell for decent prices on eBay, I wonder if it s because of curious people like me who would like to play with them and have money to spare or whether some other interesting things are being done. I wonder how a 4*4 array of the rectangular cameras secured together with duct tape would go. The ideas of Illium should work better if implemented for multi-core CPUs or GPUs. Bruce Schneier with Henry Farrell and Nathan Sanders wrote an insightful blog post about how AT Chatbots could improve democracy [4]. Wired has an interesting article about the way DJI drones transmit the location of the drone operator without encryption by design [5]. Apparently this has been used for targetting attacks on drone operators in Ukraine. This video about robot mice navigating mazes is interesting [6]. But I think it became less interesting when they got to the stage of milliseconds counting for the win, it s very optimised for one case just like F1. I think it would be interesting if they had a rally contest where they go across grass or sand, 3D mazes both in air and water, and contests where Tungsten weights have to be transported. They should push some of the other limits of engineering as completing a maze quickly has been solved. The Guardian has an interesting article about a blood test for sleepy driving [7]. Once they have an objective test they can punish people for it. This github repository listing public APIs is interesting [8]. Lots of fun ideas for phone apps there. Simon Josefsson wrote an insightful blog post about the threat model of security devices [9]. Unfortunately the security of most people is way below the level where this is an issue. But it s good to think about future steps needed for good security. Cory Doctorow wrote an interesting article The Swivel Eyed Loons have a Point [10] about the fact that some of the nuttiest people are protesting about real issues, just in the wrong way.

29 May 2023

John Goerzen: Recommendations for Tools for Backing Up and Archiving to Removable Media

I have several TB worth of family photos, videos, and other data. This needs to be backed up and archived. Backups and archives are often thought of as similar. And indeed, they may be done with the same tools at the same time. But the goals differ somewhat: Backups are designed to recover from a disaster that you can fairly rapidly detect. Archives are designed to survive for many years, protecting against disaster not only impacting the original equipment but also the original person that created them. Reflecting on this, it implies that while a nice ZFS snapshot-based scheme that supports twice-hourly backups may be fantastic for that purpose, if you think about things like family members being able to access it if you are incapacitated, or accessibility in a few decades time, it becomes much less appealing for archives. ZFS doesn t have the wide software support that NTFS, FAT, UDF, ISO-9660, etc. do. This post isn t about the pros and cons of the different storage media, nor is it about the pros and cons of cloud storage for archiving; these conversations can readily be found elsewhere. Let s assume, for the point of conversation, that we are considering BD-R optical discs as well as external HDDs, both of which are too small to hold the entire backup set. What would you use for archiving in these circumstances? Establishing goals The goals I have are: I would welcome your ideas for what to use. Below, I ll highlight different approaches I ve looked into and how they stack up. Basic copies of directories The initial approach might be one of simply copying directories across. This would work well if the data set to be archived is smaller than the archival media. In that case, you could just burn or rsync a new copy with every update and be done. Unfortunately, this is much less convenient with data of the size I m dealing with. rsync is unavailable in that case. With some datasets, you could manually design some rsyncs to store individual directories on individual devices, but that gets unwieldy fast and isn t scalable. You could use something like my datapacker program to split the data across multiple discs/drives efficiently. However, updates will be a problem; you d have to re-burn the entire set to get a consistent copy, or rely on external tools like mtree to reflect deletions. Not very convenient in any case. So I won t be using this. tar or zip While you can split tar and zip files across multiple media, they have a lot of issues. GNU tar s incremental mode is clunky and buggy; zip is even worse. tar files can t be read randomly, making it extremely time-consuming to extract just certain files out of a tar file. The only thing going for these formats (and especially zip) is the wide compatibility for restoration. dar Here we start to get into the more interesting tools. Dar is, in my opinion, one of the best Linux tools that few people know about. Since I first wrote about dar in 2008, it s added some interesting new features; among them, binary deltas and cloud storage support. So, dar has quite a few interesting features that I make use of in other ways, and could also be quite helpful here: Additionally, dar comes with a dar_manager program. dar_manager makes a database out of dar catalogs (or archives). This can then be used to identify the precise archive containing a particular version of a particular file. All this combines to make a useful system for archiving. Isolated catalogs are tiny, and it would be easy enough to include the isolated catalogs for the entire set of archives that came before (or even the dar_manager database file) with each new incremental archive. This would make restoration of a particular subset easy. The main thing to address with dar is that you do need dar to extract the archive. Every dar release comes with source code and a win64 build. dar also supports building a statically-linked Linux binary. It would therefore be easy to include win64 binary, Linux binary, and source with every archive run. dar is also a part of multiple Linux and BSD distributions, which are archived around the Internet. I think this provides a reasonable future-proofing to make sure dar archives will still be readable in the future. The other challenge is user ability. While dar is highly portable, it is fundamentally a CLI tool and will require CLI abilities on the part of users. I suspect, though, that I could write up a few pages of instructions to include and make that a reasonably easy process. Not everyone can use a CLI, but I would expect a person that could follow those instructions could be readily-enough found. One other benefit of dar is that it could easily be used with tapes. The LTO series is liked by various hobbyists, though it could pose formidable obstacles to non-hobbyists trying to aceess data in future decades. Additionally, since the archive is a big file, it lends itself to working with par2 to provide redundancy for certain amounts of data corruption. git-annex git-annex is an interesting program that is designed to facilitate managing large sets of data and moving it between repositories. git-annex has particular support for offline archive drives and tracks which drives contain which files. The idea would be to store the data to be archived in a git-annex repository. Then git-annex commands could generate filesystem trees on the external drives (or trees to br burned to read-only media). In a post about using git-annex for blu-ray backups, an earlier thread about DVD-Rs was mentioned. This has a few interesting properties. For one, with due care, the files can be stored on archival media as regular files. There are some different options for how to generate the archives; some of them would place the entire git-annex metadata on each drive/disc. With that arrangement, one could access the individual files without git-annex. With git-annex, one could reconstruct the final (or any intermediate) state of the archive appropriately, handling deltions, renames, etc. You would also easily be able to know where copies of your files are. The practice is somewhat more challenging. Hundreds of thousands of files what I would consider a medium-sized archive can pose some challenges, running into hours-long execution if used in conjunction with the directory special remote (but only minutes-long with a standard git-annex repo). Ruling out the directory special remote, I had thought I could maybe just work with my files in git-annex directly. However, I ran into some challenges with that approach as well. I am uncomfortable with git-annex mucking about with hard links in my source data. While it does try to preserve timestamps in the source data, these are lost on the clones. I wrote up my best effort to work around all this. In a forum post, the author of git-annex comments that I don t think that CDs/DVDs are a particularly good fit for git-annex, but it seems a couple of users have gotten something working. The page he references is Managing a large number of files archived on many pieces of read-only medium. Some of that discussion is a bit dated (for instance, the directory special remote has the importtree feature that implements what was being asked for there), but has some interesting tips. git-annex supplies win64 binaries, and git-annex is included with many distributions as well. So it should be nearly as accessible as dar in the future. Since git-annex would be required to restore a consistent recovery image, similar caveats as with dar apply; CLI experience would be needed, along with some written instructions. Bacula and BareOS Although primarily tape-based archivers, these do also also nominally support drives and optical media. However, they are much more tailored as backup tools, especially with the ability to pull from multiple machines. They require a database and extensive configuration, making them a poor fit for both the creation and future extractability of this project. Conclusions I m going to spend some more time with dar and git-annex, testing them out, and hope to write some future posts about my experiences.

27 May 2023

Dirk Eddelbuettel: RcppArmadillo 0.12.4.0.0 on CRAN: New Upstream Minor

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1074 other packages on CRAN, downloaded 29.3 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 535 times according to Google Scholar. This release brings a new upstream release 12.4.0 made by Conrad a day or so ago. I prepared the usual release candidate, tested on the over 1000 reverse depends (which sadly takes almost a day on old hardware), found no issues and sent it to CRAN. Where it got tested again and was once again auto-processed smoothly by CRAN within a few hours on a Friday night which is just marvelous. So this time I tweeted about it too. The releases actually has a relatively small set of changes as a second follow-up release in the 12.* series.

Changes in RcppArmadillo version 0.12.4.0.0 (2023-05-26)
  • Upgraded to Armadillo release 12.4.0 (Cortisol Profusion Redux)
    • Added norm2est() for finding fast estimates of matrix 2-norm (spectral norm)
    • Added vecnorm() for obtaining the vector norm of each row or column of a matrix

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like my open-source work, you may consider sponsoring me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

25 May 2023

Dirk Eddelbuettel: qlcal 0.0.6 on CRAN: More updates from QuantLib

The sixth release of the still new-ish qlcal package arrivied at CRAN today. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. This release brings updates to a few calendars which happened since the QuantLib 1.30 release, and also updates a several of the (few) non-calendaring functions.

Changes in version 0.0.6 (2023-05-24)
  • Several calendars (India, Singapore, South Africa, South Korea) updated with post-QuantLib 1.3.0 changes (Sebastian Schmidt in #6)
  • Three now-used scheduled files were removed (Dirk in #7))
  • A number of non-calendaring files used were synchronised with the current QuantLib repo (Dirk in #8)

Last release, we also added a quick little demo using xts to column-bind calendars produced from each of the different US sub-calendars. This is a slightly updated version of the sketch we tooted a few days ago. The output now is
> print(Reduce(cbind, Map(makeHol, cals)))
           LiborImpact NYSE GovernmentBond NERC FederalReserve
2023-01-02        TRUE TRUE           TRUE TRUE           TRUE
2023-01-16        TRUE TRUE           TRUE   NA           TRUE
2023-02-20        TRUE TRUE           TRUE   NA           TRUE
2023-04-07          NA TRUE             NA   NA             NA
2023-05-29        TRUE TRUE           TRUE TRUE           TRUE
2023-06-19        TRUE TRUE           TRUE   NA           TRUE
2023-07-04        TRUE TRUE           TRUE TRUE           TRUE
2023-09-04        TRUE TRUE           TRUE TRUE           TRUE
2023-10-09        TRUE   NA           TRUE   NA           TRUE
2023-11-10        TRUE   NA             NA   NA             NA
2023-11-23        TRUE TRUE           TRUE TRUE           TRUE
2023-12-25        TRUE TRUE           TRUE TRUE           TRUE
> 
Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

22 May 2023

Russ Allbery: Review: Tsalmoth

Review: Tsalmoth, by Steven Brust
Series: Vlad Taltos #16
Publisher: Tor
Copyright: 2023
ISBN: 1-4668-8970-5
Format: Kindle
Pages: 277
Tsalmoth is the sixteenth book in the Vlad Taltos series and (some fans of the series groan) yet another flashback novel to earlier in Vlad's life. It takes place between Yendi and the interludes in Dragon (or, perhaps more straightforwardly, between Yendi and Jhereg. Most of the books of this series stand alone to some extent, so you could read this book out of order and probably not be horribly confused, but I suspect it would also feel weirdly pointless outside of the context of the larger series. We're back to Vlad running a fairly small operation as a Jhereg, who are the Dragaeran version of organized crime. A Tsalmoth who owes Vlad eight hundred imperials has rudely gotten himself murdered, thoroughly enough that he can't be revived. That's a considerable amount of money, and Vlad would like it back, so he starts poking around. As you might expect if you've read any other book in this series, things then get a bit complicated. This time, they involve Jhereg politics, Tsalmoth house politics, and necromancy (which in this universe is more about dimensional travel than it is about resurrecting the dead). The main story is... fine. Kragar is around being unnoticeable as always, Vlad is being cocky and stubborn and bantering with everyone, and what appears to be a straightforward illegal business relationship turns out to involve Dragaeran magic and thus Vlad's highly-placed friends. As usual, they're intellectually curious about the magic and largely ambivalent to the rest of Vlad's endeavors. The most enjoyable part of the story is Vlad's insistence on getting his money back while everyone else in the story cannot believe he would be this persistent over eight hundred imperials and is certain he has some other motive. It's otherwise a fairly forgettable little adventure. The implications for the broader series, though, are significant, although essentially none of the payoff is here. Brust has been keeping a major secret about Vlad that's finally revealed here, one that has little impact on the plot of this book (although it causes Vlad a lot of angst) but which I suspect will become very important later in the series. That was intriguing but rather unsatisfying, since it stays only a future hook with an attached justification for why we're only finding out about it now. If one has read the rest of the series, it's also nice to see Vlad and Cawti working together, bantering with each other and playing off of each other's strengths. It's reminiscent of the best parts of Yendi. As with many of the books of this series, the chapter introductions tell a parallel story; this time, it's Vlad and Cawti's wedding. I think previous books already mentioned that Vlad is narrating this series into some sort of recording device, and a bit about why he's doing that, but this is made quite explicit here. We get as much of the surrounding frame as we've ever seen before. There are no obvious plot consequences from this it's still all hints and guesswork but I suspect this will also become important by the end of the series. If you've read this much of the series, you'll obviously want to read this one as well, but unfortunately don't get your hopes up for significant plot advancement. This is another station-keeping book, which is a bit of a disappointment. We haven't gotten major plot advancement since Hawk in 2014, and I'm getting impatient. Thankfully, Lyorn has a release date already (April 9, 2024), and assuming all goes according to the grand plan, there are only two books left after Lyorn (Chreotha and The Last Contract). I'm getting hopeful that we're going to get to see the entire series. Meanwhile, I am very tempted to do a complete re-read of the series to date, probably in series chronological order rather than in publication order (as much as that's possible given the fractured timelines of Dragon and Tiassa) so that I can see how the pieces fit together. The constant jumping back and forth and allusions to events that have already happened but that we haven't seen yet is hard to keep track of. I'm very glad the Lyorn Records exists. Followed by Lyorn. Rating: 7 out of 10

21 May 2023

Russ Allbery: Review: The Stone Canal

Review: The Stone Canal, by Ken MacLeod
Series: Fall Revolution #2
Publisher: Tor
Copyright: 1996
Printing: January 2001
ISBN: 0-8125-6864-8
Format: Mass market
Pages: 339
The Stone Canal is a sort of halfway sequel to The Star Fraction. They both take place in the same universe, but the characters are almost entirely disjoint. Half of The Stone Canal happens (mostly) well before the previous book and the other half happens well after it. This book does contain spoilers for the ending of The Star Fraction if one connects the events of the two books correctly (which was a bit harder than I thought it should be), so I would not read them out of order. At the start of The Stone Canal, Jon Wilde wakes up on New Mars beside the titular canal, in the middle of nowhere, accompanied only by a robot that says it made him. Wilde remembers dying on Earth; this new life is apparently some type of resurrection. It's a long walk to Ship City, the center of civilization of a place the robot tells him is New Mars. In Ship City, an android named Dee Model has escaped from her owner and is hiding in a bar. There, she meets an AI abolitionist named Tamara, who helps her flee out the back and down the canal on a boat when Wilde walks into the bar and immediately recognizes her. The abolitionists provide her protection and legal assistance to argue her case for freedom from her owner, a man named Reid. The third thread of the story, and about half the book, is Jon Wilde's life on Earth, starting in 1975 and leading up to the chaotic wars, political fracturing, and revolutions that formed the background and plot of The Star Fraction. Eventually that story turns into a full-fledged science fiction setting, but not until the last 60 pages of the book. I successfully read two books in a Ken MacLeod series! Sadly, I'm not sure I enjoyed the experience. I commented in my review of The Star Fraction that the appeal for me in MacLeod's writing was his reputation as a writer of political science fiction. Unfortunately that's been a bust. The characters are certainly political, in the sense that they profess to have strong political viewpoints and are usually members of some radical (often Trotskyite) organization. There are libertarian anarchist societies and lots of political conflict. But there is almost no meaningful political discussion in any of these books so far. The politics are all tactical or background, and often seem to be created by authorial fiat. For example, New Mars is a sort of libertarian anarchy that somehow doesn't have corporations or a strongman ruler, even though the history (when we finally learn it) would have naturally given rise to one or the other (and has, in numerous other SF novels with similar plots). There's a half-assed explanation for this towards the end of the book that I didn't find remotely believable. Another part of the book describes the formation of the libertarian microstate in The Star Fraction, but never answers a "why" or "how" question I had in the previous book in a satisfying way. Somehow people stop caring about control or predictability or stability or traditional hierarchy without any significant difficulties except external threats, in situations of chaos and disorder where historically humans turn to anyone promising firm structure. It's common to joke about MacLeod winning multiple libertarian Prometheus Awards for his fiction despite being a Scottish communist. I'm finding that much less surprising now that I've read more of his books. Whether or not he believes in it himself, he's got the cynical libertarian smugness and hand-waving down pat. What his characters do care deeply about is smoking, drinking, and having casual sex. (There's more political fire here around opposition to anti-smoking laws than there is about any of the society-changing political structures that somehow fall into place.) I have no objections to any of those activities from a moral standpoint, but reading about other people doing them is a snoozefest. The flashback scenes sketch out enough imagined history to satisfy some curiosity from the previous book, but they're mostly about the world's least interesting love triangle, involving two completely unlikable men and lots of tedious jealousy and posturing. The characters in The Stone Canal are, in general, a problem. One of those unlikable men is Wilde, the protagonist for most of the book. Not only did I never warm to him, I never figured out what motivates him or what he cares about. He's a supposedly highly political person who seems to engage in politics with all the enthusiasm of someone filling out tax forms, and is entirely uninterested in explaining to the reader any sort of coherent philosophical approach. The most interesting characters in this book are the women (Annette, Dee Model, Tamara, and, very late in the book, Meg), but other than Dee Model they rarely get much focus from the story. By far the best part of this book is the last 60 pages, where MacLeod finally explains the critical bridge events between Wilde's political history on earth and the New Mars society. I thought this was engrossing, fast-moving, and full of interesting ideas (at least for a 1990s book; many of them feel a bit stale now, 25 years later). It was also frustrating, because this was the book I wanted to have been reading for the previous 270 pages, instead of MacLeod playing coy with his invented history or showing us interminable scenes about Wilde's insecure jealousy over his wife. It's also the sort of book where at one point characters (apparently uniformly male as far as one could tell from the text of the book) get assigned sex slaves, and while MacLeod clearly doesn't approve of this, the plot is reminiscent of a Heinlein novel: the protagonist's sex slave becomes a very loyal permanent female companion who seems to have the same upside for the male character in question. This was unfortunately not the book I was hoping for. I did enjoy the last hundred pages, and it's somewhat satisfying to have the history come together after puzzling over what happened for 200 pages. But I found the characters tedious and annoying and the politics weirdly devoid of anything like sociology, philosophy, or political science. There is the core of a decent 1990s AI and singularity novel here, but the technology is now rather dated and a lot of other people have tackled the same idea with fewer irritating ticks. Not recommended, although I'll probably continue to The Cassini Division because the ending was a pretty great hook for another book. Followed by The Cassini Division. Rating: 5 out of 10

17 May 2023

Jamie McClelland: Cranky old timers should know perl

I act like an old timer (I ve been around linux for 25 years and I m cranky about new tech that is not easily maintained and upgraded) yet somehow I don t know perl. How did that happen? I discovered this state when I decided to move from the heroically packaged yet seemingly upstream un-maintained opendmarc package to authentication_milter. It s written in perl. And, alas, not in debian. How hard could this be? The instructions for installing seemed pretty straight forward: cpanm Mail::Milter::Authentication. Wah. I m glad I tried this out on a test virtual machine. It took forever! It ran tests! It compiled things! And, it installed a bunch of perl modules already packaged in Debian. I don t think I want to add this command to my ansible playbook. Next I spent an inordinate amount of time trying to figure out how to list the dependencies of a given CPAN module. I was looking for something like cpanm --list-dependencies Mail::Milter::Authentication but eventually ended up writing a perl script that output perl code, inserting a use " before each dependency and a semicolon and line break after them. Then, I could execute that script on a clean debian installation and see which perl modules I needed. For each error, I checked for the module in Debian (and installed it) or kept a list of modules I would have to build (and commented out the line). Once I had a list of modules to build, I used the handy cpan2deb command. It took some creative ordering but eventually I got it right. Since I will surely forget how to do this when it s time to upgrade, I wrote a script. In total it took me several days to figure this all out, so I once again find myself very appreciative of all the debian packagers out there - particularly the perl ones!! And also if I did this all wrong and there is an easier way I would love to hear about it in the comments.

15 May 2023

Dirk Eddelbuettel: RcppSimdJson 0.1.10 on CRAN: New Upstream

We are happy to share that the RcppSimdJson package has been updated to release 0.1.10. RcppSimdJson wraps the fantastic and genuinely impressive simdjson library by Daniel Lemire and collaborators. Via very clever algorithmic engineering to obtain largely branch-free code, coupled with modern C++ and newer compiler instructions, it results in parsing gigabytes of JSON parsed per second which is quite mindboggling. The best-case performance is faster than CPU speed as use of parallel SIMD instructions and careful branch avoidance can lead to less than one cpu cycle per byte parsed; see the video of the talk by Daniel Lemire at QCon. This release updates the underlying simdjson library to version 3.1.8 (also made today). Otherwise we only made a minor edit to the README and adjusted one tweek for code coverage. The (very short) NEWS entry for this release follows.

Changes in version 0.1.10 (2023-05-14)
  • simdjson was upgraded to version 3.1.8 (Dirk in #85).

Courtesy of my CRANberries, there is also a diffstat report for this release. For questions, suggestions, or issues please use the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

13 May 2023

Sergio Durigan Junior: Ubuntu debuginfod and source code indexing

You might remember that in my last post about the Ubuntu debuginfod service I talked about wanting to extend it and make it index and serve source code from packages. I m excited to announce that this is now a reality since the Ubuntu Lunar (23.04) release. The feature should work for a lot of packages from the archive, but not all of them. Keep reading to better understand why.

The problem While debugging a package in Ubuntu, one of the first steps you need to take is to install its source code. There are some problems with this:
  • apt-get source required dpkg-dev to be installed, which ends up pulling in a lot of other dependencies.
  • GDB needs to be taught how to find the source code for the package being debugged. This can usually be done by using the dir command, but finding the proper path to be is usually not trivial, and you find yourself having to use more complex commands like set substitute-path, for example.
  • You have to make sure that the version of the source package is the same as the version of the binary package(s) you want to debug.
  • If you want to debug the libraries that the package links against, you will face the same problems described above for each library.
So yeah, not a trivial/pleasant task after all.

The solution Debuginfod can index source code as well as debug symbols. It is smart enough to keep a relationship between the source package and the corresponding binary s Build-ID, which is what GDB will use when making a request for a specific source file. This means that, just like what happens for debug symbol files, the user does not need to keep track of the source package version. While indexing source code, debuginfod will also maintain a record of the relative pathname of each source file. No more fiddling with paths inside the debugger to get things working properly. Last, but not least, if there s a need for a library source file and if it s indexed by debuginfod, then it will get downloaded automatically as well.

but not a perfect one In order to make debuginfod happy when indexing source files, I had to patch dpkg and make it always use -fdebug-prefix-map when compiling stuff. This GCC option is used to remap pathnames inside the DWARF, which is needed because in Debian/Ubuntu we build our packages inside chroots and the build directories end up containing a bunch of random cruft (like /build/ayusd-ASDSEA/something/here). So we need to make sure the path prefix (the /build/ayusd-ASDSEA part) is uniform across all packages, and that s where -fdebug-prefix-map helps. This means that the package must honour dpkg-buildflags during its build process, otherwise the magic flag won t be passed and your DWARF will end up with bogus paths. This should not be a big problem, because most of our packages do honour dpkg-buildflags, and those who don t should be fixed anyway.

especially if you re using LTO Ubuntu enables LTO by default, and unfortunately we are affected by an annoying (and complex) bug that results in those bogus pathnames not being properly remapped. The bug doesn t affect all packages, but if you see GDB having trouble finding a source file whose full path starts without /usr/src/..., that is a good indication that you re being affected by this bug. Hopefully we should see some progress in the following weeks.

Your feedback is important to us If you have any comments, or if you found something strange that looks like a bug in the service, please reach out. You can either send an email to my public inbox (see below) or file a bug against the ubuntu-debuginfod project on Launchpad.

12 May 2023

Dirk Eddelbuettel: crc32c 0.0.2 on CRAN: Build Fixes

A first follow-up to the initial announcement just days ago of the new crc32c package. The package offers cyclical checksum with parity in hardware-accelerated form on (recent enough) intel cpus as well as on arm64. This follow-up was needed because I missed, when switching to a default static library build, that newest compilers would complain if -fPIC was not set. gcc-12 on my box was happy, gcc-13 on recent Fedora as used at CRAN was not. A second error was assuming that saying SystemRequirements: cmake would suffice. But hold on whippersnapper: macOS always has a surprise for you! As described at the end of the appropriate section in Writing R Extensions, on that OS you have to go the basement, open four cupboards, rearrange three shelves and then you get to use it. And then in doing so (from an added configure script) I failed to realize Windows needed a fallback. Gee. The NEWS entry for this (as well the initial release) follows.

Changes in version 0.0.2 (2023-05-11)
  • Explicitly set cmake property for position-independent code
  • Help macOS find its cmake binary as detailed also in WRE
  • Help Windows with a non-conditional Makevars.win pointing at cmake
  • Add more badges to README.md

Changes in version 0.0.1 (2023-05-07)
  • Initial release version and CRAN upload

If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 May 2023

Simon Josefsson: Streamlined NTRU Prime sntrup761 goes to IETF

The OpenSSH project added support for a hybrid Streamlined NTRU Prime post-quantum key encapsulation method sntrup761 to strengthen their X25519-based default in their version 8.5 released on 2021-03-03. While there has been a lot of talk about post-quantum crypto generally, my impression has been that there has been a slowdown in implementing and deploying them in the past two years. Why is that? Regardless of the answer, we can try to collaboratively change things, and one effort that appears strangely missing are IETF documents for these algorithms. Building on some earlier work that added X25519/X448 to SSH, writing a similar document was relatively straight-forward once I had spent a day reading OpenSSH and TinySSH source code to understand how it worked. While I am not perfectly happy with how the final key is derived from the sntrup761/X25519 secrets it is a SHA512 call on the concatenated secrets I think the construct deserves to be better documented, to pave the road for increased confidence or better designs. Also, reusing the RFC5656 4 structs makes for a worse specification (one unnecessary normative reference), but probably a simpler implementation. I have published draft-josefsson-ntruprime-ssh-00 here. Credit here goes to Jan Moj of TinySSH that designed the earlier sntrup4591761x25519-sha512@tinyssh.org in 2018, Markus Friedl who added it to OpenSSH in 2019, and Damien Miller that changed it to sntrup761 in 2020. Does anyone have more to add to the history of this work? Once I had sharpened my xml2rfc skills, preparing a document describing the hybrid construct between the sntrup761 key-encapsulation mechanism and the X25519 key agreement method in a non-SSH fashion was easy. I do not know if this work is useful, but it may serve as a reference for further study. I published draft-josefsson-ntruprime-hybrid-00 here. Finally, how about a IETF document on the base Streamlined NTRU Prime? Explaining all the details, and especially the math behind it would be a significant effort. I started doing that, but realized it is a subjective call when to stop explaining things. If we can t assume that the reader knows about lattice math, is a document like this the best place to teach it? I settled for the most minimal approach instead, merely giving an introduction to the algorithm, included SageMath and C reference implementations together with test vectors. The IETF audience rarely understands math, so I think it is better to focus on the bits on the wire and the algorithm interfaces. Everything here was created by the Streamlined NTRU Prime team, I merely modified it a bit hoping I didn t break too much. I have now published draft-josefsson-ntruprime-streamlined-00 here. I maintain the IETF documents on my ietf-ntruprime GitLab page, feel free to open merge requests or raise issues to help improve them. To have confidence in the code was working properly, I ended up preparing a branch with sntrup761 for the GNU-project Nettle and have submitted it upstream for review. I had the misfortune of having to understand and implement NIST s DRBG-CTR to compute the sntrup761 known-answer tests, and what a mess it is. Why does a deterministic random generator support re-seeding? Why does it support non-full entropy derivation? What s with the key size vs block size confusion? What s with the optional parameters? What s with having multiple algorithm descriptions? Luckily I was able to extract a minimal but working implementation that is easy to read. I can t locate DRBG-CTR test vectors, anyone? Does anyone have sntrup761 test vectors that doesn t use DRBG-CTR? One final reflection on publishing known-answer tests for an algorithm that uses random data: are the test vectors stable over different ways to implement the algorithm? Just consider of some optimization moved one randomness-extraction call before another, then wouldn t the output be different? Are there other ways to verify correctness of implementations? As always, happy hacking!

Next.

Previous.