Search Results: "ag"

14 August 2015

Wouter Verhelst: Multi-pass transcoding to WebM with normalisation

Transcoding video from one format to another seems to be a bit of a black art. There are many tools that allow doing this kind of stuff, but one issue that most seem to have is that they're not very well documented. I ran against this a few years ago, when I was first doing video work for FOSDEM and did not yet have proper tools to do the review and transcoding workflow. At the time, I just used mplayer to look at the .dv files, and wrote a text file with a simple structure to remember exactly what to do with it. That file was then fed to a perl script which wrote out a shell script that would use the avconv command to combine and extract the "interesting" data from the source DV files into a single DV file per talk, and which would then call a shell script which used gst-launch and sox to do a multi-pass transcode of those intermediate DV files into a WebM file. While all that worked properly, it was a rather ugly hack, never cleaned up, and therefore I never really documented it properly either. Recently, however, someone asked me to do so anyway, so here goes. Before you want to complain about how this ate the videos of your firstborn child, however, note the above. The perl script spent a somewhat large amount of code reading out the text file and parsing it into an array of hashes. I'm not going to reproduce that, since the actual format of the file isn't all that important anyway. However, here's the interesting bits:
foreach my $pfile(keys %parts)  
        my @files = @ $parts $pfile ;
        say "#" x (length($pfile) + 4);
        say "# " . $pfile . " #";
        say "#" x (length($pfile) + 4);
        foreach my $file(@files)  
                my $start = "";
                my $stop = "";
                if(defined($file-> start ))  
                        $start = "-ss " . $file-> start ;
                 
                if(defined($file-> stop ))  
                        $stop = "-t " . $file-> stop ;
                 
                if(defined($file-> start ) && defined($file-> stop ))  
                        my @itime = split /:/, $file-> start ;
                        my @otime = split /:/, $file-> stop ;
                        $otime[0]-=$itime[0];
                        $otime[1]-=$itime[1];
                        if($otime[1]<0)  
                                $otime[0]-=1;
                                $otime[1]+=60;
                         
                        $otime[2]-=$itime[2];
                        if($otime[2]<0)  
                                $otime[1]-=1;
                                $otime[2]+=60;
                         
                        $stop = "-t " . $otime[0] . ":" . $otime[1] .  ":" . $otime[2];
                 
                if(defined($file-> start )   defined($file-> stop ))  
                        say "ln " . $file-> name  . ".dv part-pre.dv";
                        say "avconv -i part-pre.dv $start $stop -y -acodec copy -vcodec copy part.dv";
                        say "rm -f part-pre.dv";
                  else  
                        say "ln " . $file-> name  . ".dv part.dv";
                 
                say "cat part.dv >> /tmp/" . $pfile . ".dv";
                say "rm -f part.dv";
         
        say "dv2webm /tmp/" . $pfile . ".dv";
        say "rm -f /tmp/" . $pfile . ".dv";
        say "scp /tmp/" . $pfile . ".webm video.fosdem.org:$uploadpath   true";
        say "mv /tmp/" . $pfile . ".webm .";
 
That script uses avconv to read one or more .dv files and transcode them into a single .dv file with all the start- or end-junk removed. It uses /tmp rather than the working directory, since the working directory was somewhere on the network, and if you're going to write several gigabytes of data to an intermediate file, it's usually a good idea to write them to a local filesystem rather than to a networked one. Pretty boring. It finally calls dv2webm on the resulting .dv file. That script looks like this:
#!/bin/bash
set -e
newfile=$(basename $1 .dv).webm
wavfile=$(basename $1 .dv).wav
wavfile=$(readlink -f $wavfile)
normalfile=$(basename $1 .dv)-normal.wav
normalfile=$(readlink -f $normalfile)
oldfile=$(readlink -f $1)
echo -e "\033]0;Pass 1: $newfile\007"
gst-launch-0.10 webmmux name=mux ! fakesink \
  uridecodebin uri=file://$oldfile name=demux \
  demux. ! ffmpegcolorspace ! deinterlace ! vp8enc multipass-cache-file=/tmp/vp8-multipass multipass-mode=1 threads=2 ! queue ! mux.video_0 \
  demux. ! progressreport ! audioconvert ! audiorate ! tee name=t ! queue ! vorbisenc ! queue ! mux.audio_0 \
  t. ! queue ! wavenc ! filesink location=$wavfile
echo -e "\033]0;Audio normalize: $newfile\007"
sox --norm $wavfile $normalfile
echo -e "\033]0;Pass 2: $newfile\007"
gst-launch-0.10 webmmux name=mux ! filesink location=$newfile \
  uridecodebin uri=file://$oldfile name=video \
  uridecodebin uri=file://$normalfile name=audio \
  video. ! ffmpegcolorspace ! deinterlace ! vp8enc multipass-cache-file=/tmp/vp8-multipass multipass-mode=2 threads=2 ! queue ! mux.video_0 \
  audio. ! progressreport ! audioconvert ! audiorate ! vorbisenc ! queue ! mux.audio_0
rm $wavfile $normalfile
... and is a bit more involved. Multi-pass encoding of video means that we ask the encoder to first encode the file but store some statistics into a temporary file (/tmp/vp8-multipass, in our script), which the second pass can then reuse to optimize the transcoding. Since DV uses different ways of encoding things than does VP8, we also need to do a color space conversion (ffmpegcolorspace) and deinterlacing (deinterlace), but beyond that the video line in the first gstreamer pipeline isn't very complicated. Since we're going over the file anyway and we need the audio data for sox, we add a tee plugin at an appropriate place in the audio line in the first gstreamer pipeline, so that we can later on pick up that same audio data an write it to a wav file containing linear PCM data. Beyond the tee, we go on and do a vorbis encoding, as is needed for the WebM format. This is not actually required for a first pass, but ah well. There's some more conversion plugins in the pipeline (specifically, audioconvert and audiorate), but those are not very important. We next run sox --norm on the .wav file, which does a fully automated audio normalisation on the input. Audio normalisation is the process of adjusting volume levels so that the audio is not too loud, but also not too quiet. Sox has pretty good support for this; the default settings of its --norm parameter make it adjust the volume levels so that the highest peak will just about reach the highest value that the output format can express. As such, you have no clipping anywhere in the file, but also have an audio level that is actually useful. Next, we run a second-pass encoding on the input file. This second pass uses the statistics gathered in the first pass to decide where to put its I- and P-frames so that they are placed at the most optimal position. In addition, rather than reading the audio from the original file, we now read the audio from the .wav file containing the normalized audio which we produced with sox, ensuring the audio can be understood. Finally, we remove the intermediate audio files we created; and the shell script which was generated by perl also contained an rm command for the intermediate .dv file. Some of this is pretty horrid, and I never managed to clean it up enough so it would be pretty (and now is not really the time). However, it Just Works(tm), and I am happy to report that it continues to work with gstreamer 1.0, provided you replace the ffmpegcolorspace by an equally simple videoconvert, which performs what ffmpegcolorspace used to perform in gstreamer 0.10.

Dirk Eddelbuettel: Rblpapi: Connecting R to Bloomberg

big deal Whit, John and I are thrilled to announce Rblapi, a new CRAN package which connects R to the Bloomberg backends. Rebuilt from scratch using only the Bloomberg C++ API and the Rcpp and BH packages, it offers efficient and direct access from R to a truly vast number of financial data series, pricing tools and more. The package has been tested on Windows, OS X and Linux. As is standard for CRAN packages, binaries for Windows and OS X are provided (or will be once the builders caught up). Needless to say, a working Bloomberg installation is required to use the package. Please see the Rblapi package page for more details, including a large part of the introductory vignette document. As a teaser, here are just three of the core functions:
## Bloomberg Data Point Query
bdp(c("ESA Index", "SPY US Equity"), c("PX_LAST", "VOLUME"))
## Bloomberg Data Set Query
bds("GOOG US Equity", "TOP_20_HOLDERS_PUBLIC_FILINGS")
## Bloomberg Data History Query
bdh("SPY US Equity", c("PX_LAST", "VOLUME"), start.date=Sys.Date()-31)
## Get OHLCV bars (by default hourly and just six of them)
getBars("ES1 Index")
## Get Tick Data (by default last hour)
getTicks("ES1 Index")
Source code for the package is at the Rblpapi GitHub repo where issue tickets can be filed as well. The sibbling blp GitHub repo contains the Bloomberg code required to build and link the package (which is automated during the build of the CRAN package). Last but not least the Rblpapi package page has more details about the package.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Tiago Bortoletto Vaz: c3video for debconf #5

This is a follow-up to my previous post related the DebConf videoteam using a new software stack for the next conferences: http://acaia.ca/~tiago/posts/c3video-for-dc-take-4/. This is about the encoding step from C3TT, mostly done by the script named D-encoding. We can have many different encoding templates in the system. They're XSLT files which will generate the XML needed to create the local encoding commands. We can have more than one encoding template assigned for a conference.
/images/c3tt_encoding.png

XSLT encoding templates

A general comment: each meta ticket (say, the original ticket with meta info about the talk) will generate two children tickets over time, a recording one and a encoding one, with their own states. If things go wrong, a ingest ticket is created. More details can be checked here.
/images/c3tt_children_tickets.png

Children tickets

So I've got the proper encoded files in my Processing.Path.Output directory. The ticket is marked as encoded by the script. There's also a postencoding step, executed by E-postencoding. As I could understand, it's intended to be a general post-processing hook for encoded files. For instance, it can produces an audio file and make it available on Auphonic service. As we won't use that, we may want to set the property Processing.Auphonic.Enable to no. The next step starts from the operator side. Just going to the Releasing tab in the web interface, choosing the ticket to check and doing a quick review in the encoded file:
/images/c3tt_releasing.png

Releasing tab

Then, if everything looks fine, click Everthing's fine:
/images/c3tt_check.png

Check encoded file

From this point the ticket will be marked as checked and the next script (F-postprocessing) will take care of pushing the video(s)/audio(s) to the target place, as defined by Publishing.UploadTarget. I had to set myself the encoding template property EncodingProfile.Extension. We can optionally set Publishing.UploadOptions. (keep that in mind, seems not documented elsewhere) So I have now the first DebCamp encoded video file uploaded to an external host, entirely processed using the C3TT software stack. We may also want to use a very last script to release the videos (eg. as torrents, to different mirrors and other onlive services) if needed. This is script-G-release.pl, which unlike others, won't be run by the screen UI in the sequence. It has some parameters hardcoded on it, although code is very clear and ready to be hacked. It'll also mark the ticket as Released.
/images/c3tt_released.png

Released!

That's all for now! In summary: I've been able to install and set C3TT up during a few days in DebCamp, and will be playing with it during DebConf. In case things go well we'll probably be using this system as our video processing environment for the next events. We can access most CCC VoC software from https://github.com/voc. By having a look at what they're developing I feel that we (DebConf and CCC) share quite the same technical needs. And most important, the same spirit of community work for bringing part of the conference to those unable to attend. DebCamp was warm!

Alberto Garc a: I/O limits for disk groups in QEMU 2.4

QEMU 2.4.0 has just been released, and among many other things it comes with some of the stuff I have been working on lately. In this blog post I am going to talk about disk I/O limits and the new feature to group several disks together. Disk I/O limits Disk I/O limits allow us to control the amount of I/O that a guest can perform. This is useful for example if we have several VMs in the same host and we want to reduce the impact they have on each other if the disk usage is very high. The I/O limits can be set using the QMP command block_set_io_throttle, or with the command line using the throttling.* options for the -drive parameter (in brackets in the examples below). Both the throughput and the number of I/O operations can be limited. For a more fine-grained control, the limits of each one of them can be set on read operations, write operations, or the combination of both: Example:
-drive if=virtio,file=hd1.qcow2,throttling.bps-write=52428800,throttling.iops-total=6000
In addition to that, it is also possible to configure the maximum burst size, which defines a pool of I/O that the guest can perform without being limited: One additional parameter named iops_size allows us to deal with the case where big I/O operations can be used to bypass the limits we have set. In this case, if a particular I/O operation is bigger than iops_size then it is counted several times when it comes to calculating the I/O limits. So a 128KB request will be counted as 4 requests if iops_size is 32KB. Group throttling All of these parameters I ve just described operate on individual disk drives and have been available for a while. Since QEMU 2.4 however, it is also possible to have several drives share the same limits. This is configured using the new group parameter. The way it works is that each disk with I/O limits is member of a throttle group, and the limits apply to the combined I/O of all group members using a round-robin algorithm. The way to put several disks together is just to use the group parameter with all of them using the same group name. Once the group is set, there s no need to pass the parameter to block_set_io_throttle anymore unless we want to move the drive to a different group. Since the I/O limits apply to all group members, it is enough to use block_set_io_throttle in just one of them. Here s an example of how to set groups using the command line:
-drive if=virtio,file=hd1.qcow2,throttling.iops-total=6000,throttling.group=foo
-drive if=virtio,file=hd2.qcow2,throttling.iops-total=6000,throttling.group=foo
-drive if=virtio,file=hd3.qcow2,throttling.iops-total=3000,throttling.group=bar
-drive if=virtio,file=hd4.qcow2,throttling.iops-total=6000,throttling.group=foo
-drive if=virtio,file=hd5.qcow2,throttling.iops-total=3000,throttling.group=bar
-drive if=virtio,file=hd6.qcow2,throttling.iops-total=5000
In this example, hd1, hd2 and hd4 are all members of a group named foo with a combined IOPS limit of 6000, and hd3 and hd5 are members of bar. hd6 is left alone (technically it is part of a 1-member group). Next steps I am currently working on providing more I/O statistics for disk drives, including latencies and average queue depth on a user-defined interval. The code is almost ready. Next week I will be in Seattle for the KVM Forum where I will hopefully be able to finish the remaining bits.
I will also attend LinuxCon North America. Igalia is sponsoring the event and we have a booth there. Come if you want to talk to us or see our latest demos with WebKit for Wayland. See you in Seattle!

Neil Williams: The problem of SD mux

I keep being asked about automated bootloader testing and the phrase which crops up is SD mux hardware to multiplex SD card access (typically microSD). Each time, the questioner comes up with a simple solution which can be built over a weekend, so I ve decided to write out the actual objective, requirements and constraints to hopefully illustrate that this is not a simple problem and the solution needs to be designed to a fully scalable, reliable and maintainable standard. The objective Support bootloader testing by allowing fully automated tests to write a custom, patched, bootloader to the principal boot media of a test device, hard reset the board and automatically recover if the bootloader fails to boot the device by switching the media from the test device to a known working support device with full write access to overwrite everything on the card and write a known working bootloader. The environment 100 test devices, one SD mux each (potentially), in a single lab with support for all or any to be switched simultaneously and repeatedly (maybe a hundred times a day to and fro) with 99.99% reliability. The history First attempt was a simplistic solution which failed to operate reliably. Next attempt was a complex solution (LMP) which failed to operate as designed in a production environment (partially due to a reliance on USB) and has since suffered from a lack of maintenance. The most recent attempt was another simplistic solution which delivered three devices for test with only one usable and even that became unreliable in testing. The requirements (None of these are negotiable and all are born from real bugs or real failures of previous solutions in the above environment.)
  1. Ethernet yes, really. Physical, cat5/6 RJ45 big, bulky, ugly gigabit ethernet port. No wifi. This is not about design elegance, this is about scalability, maintenance and reliability. Must have a fully working TCP/IP stack with stable and reliable DHCP client. Stable, predictable, unique MAC addresses for every single board guaranteed. No dynamic MAC addresses, no hard coded MAC addresses which cannot be modified. Once modified, retain permanence of the required MAC address across reboots.
  2. No USB involement yes, really. The server writing to the media to recover a bricked device usually has only 2 USB ports but supports 20 devices. Powered hubs are not sufficiently reliable.
  3. Removable media only eMMC sounds useful but these are prototype development boards and some are already known to intermittently fry SD card controller chips causing permanent and irreversible damage to the SD card. If that happened to eMMC, the entire device would have to be discarded.
  4. Cable connections to the test device. This is a solved problem, the cables already exist due to the second attempt at a fix for this problem which resulted in a serviceable design for just the required cables. Do not consider any fixed connection, the height of the connector will never match all test device requirements and will be a constant source of errors when devices are moved around within the rack.
  5. Guaranteed unique, permanent and stable serial numbers for every device. With 100 devices in a lab, it is absolutely necessary that every single one is uniquely addressable.
  6. Interrogation there must be an interface for the control device to query the status of the SD mux and be assured that the results reflect reality at all times. The device must allow the control device to read and write to the media without requiring the test device to acknowledge the switch or even be powered on.
  7. No feature creep. There is no need to make this be able to switch ethernet or HDMI or GPIO as well as SD. Follow the software principle of pick one job and do it properly.
  8. Design for scalability this is not a hobbyist project, this is a serious task requiring genuine design. The problem is not simple, it is not acceptable to make a simple solution.
  9. Power the device must boot directly from power-on without requiring manual intervention of any kind and boot into a default safe mode where the media is only accessible to the control device. 5V power with a barrel connector is preferable definitely not power over USB. Device must raise the TCP/IP control interface automatically and be prepared to react to commands immediately that the interface is available.
  10. Software: some logic to prevent queued requests from causing repeated switching without any interval in between, e.g. if the device had to be power cycled.
  11. Ongoing support and maintenance of hardware, firmware and software. Test devices continue to develop and will require further changes or fixes as time goes on.
  12. Mounting holes sounds obvious but the board needs to be mounted in a sensible manner. Dangling off the end of a cat5 cable is not acceptable.
If any of those seem insurmountable or awkward or unappealing, please go back to the drawing board or leave well alone. Beyond the absolutes, there are other elements. The device is likely to need some kind of CPU and something ARM would be preferable, Cortex-M or Cortex-A if relevant, but creating a cape for a beaglebone-black is likely to be overkill. The available cables are short and the device will need to sit quite close to the test device. Test devices never put the SD card slot in the same place twice or in any location which is particularly accessible. Wherever possible, the components on the device should be commodity parts, replaceable and serviceable. The device would be best not densely populated there is no need for the device to be any particular size and overly small boards tend to be awkward to position correctly once cables are connected. There are limits, of course, so boards which end up bigger than typical test devices would seem excessive. So these are the reasons why we don t have automated bootloader testing and won t have it any time soon. If you ve got this far, maybe there is a design which meets all the criteria so contact me and let s see if this is a fixable problem after all.

Norbert Preining: QMapShack GPS and Maps on Linux

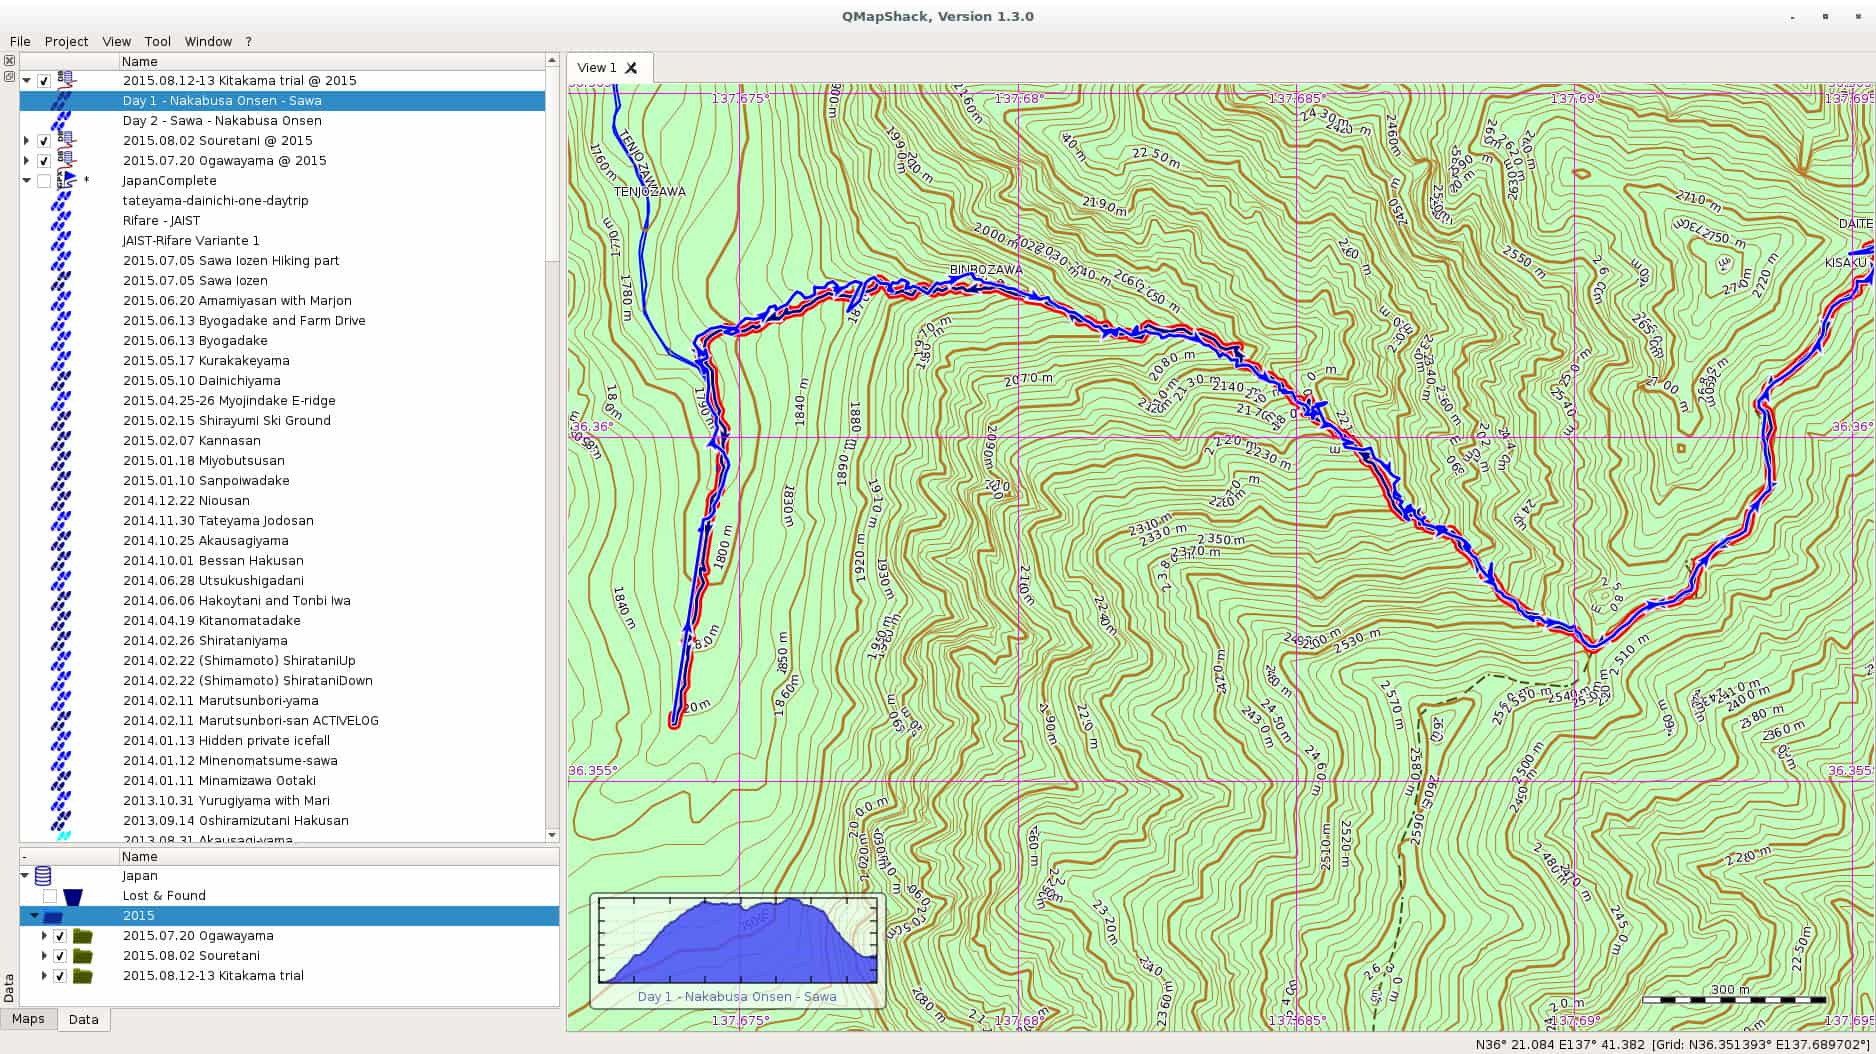
In one of the comments on my last post on Windows 10, a friendly reader from my home country pointed me at QMapShack as a replacement for QuoVadis. I have been using QuoVadis now for many many years, and it contains my mountaineering history all the way back. All the guiding work, all the track. QuoVadis is a great program, able to work with various commercial digital maps as well as GPS receivers. It only has one disadvantage, it doesn t work on Linux. QMapShack is very similar in the target audience, but very different in usage. The one big difference is of course the set of maps one can use with QMapShack. Fortunately, Garmin Maps are supported, and since all my maps regarding Japan are Garmin maps, I am now in the process to converting to QMapShack at least for my Japan GPS data. qmapshack Let us start with the program I was using since ages, and still are using, QuoVadis. QuoVadis is a great program, there is nothing to complain. It is extremely feature-rich, and above all it can work with many different maps. While working as mountain guide in Europe it was an essential tool for me. I could use the digital raster maps of Austria, Switzerland (SwissTOPO), Germany, France, Italy, as well as Garmin vector maps. For serious work as a professional it was indispensable for me. Unfortunately, it never worked on Linux. For some time I had a VirtualBox installation of Windows, but that was more a clutch than anything else. So for most of the GPS work I had to reboot my laptop to Windows, do my stuff there, and then switch back to Linux. QMapShack is far from as feature rich as QuoVadis, but as far as I see now, it does have enough features for me and my mountaineering in Japan. Dealing with GPS units is not a problem, this is the easy part. The difficult part are the digital maps. Fortunately, QMapShack supports Garmin vector maps, the only maps that are (as far as I know) available digitally for Japan. Getting used to QMapShack is a bit a challenge coming from QuoVadis, but the Wiki help pages allowed a quick start. Within short time I had maps set up. Next step was to download a data from my last weekend trip to Yarigadake, Kitakama-ridge (unfortunately we had to turn back due to rain). Connecting the unit and mounting it was already enough to show up in QMapShack, and allowed me to copy the tracks to my local database. Next I switched to Windows and exported some tracks from my Japan folder to a gpx file. After rebooting to Linux, I loaded the gpx file into QMapShack and without failure all the tracks and routes showed up, as it can be seen in the above screenshot (click on it to get a bigger version). Also the display of the Garmin map worked perfectly. Update: Please see the comment section for explanation of the necessary functions. QMapShack does provide similar functionality. Thanks to Oliver for pointing me at it! After some time of working there are a few functions from QuoVadis I am missing for now at QMapShack: Although these two functionalities are missing, all in all I am very happy for now with QMapShack. My next steps are: Finally, above all, I see a future where I do not need to reboot into Windows for doing my GPS work. For now I will import all the data into both applications, but if QMapShack holds its promises from the first day of usage, I am confident that this will not be necessary in future. Enjoy.

13 August 2015

Julien Danjou: Reading LWN.net with Pocket

I've started to use Pocket a few months ago to store my backlog of things to read. It's especially useful as I can use it to read content offline since we still don't have any Internet access in places such as airplanes or the Paris metro. It's only 2015 after all. I am also a LWN.net subscriber for years now, and I really like their articles from the weekly edition. Unfortunately, as the access is restricted to subscribers, you need to login: it makes it impossible to add these articles to Pocket directly. Sad. Yesterday, I thought about that and decided to start hacking on it. LWN provides a feature called "Subscriber Link" that allows you to share an article with a friend. I managed to use that feature to share the articles with my friend Pocket! As doing that every week is tedious, I wrote a small Python program called lwn2pocket that I published on GitHub. Feel free to use it, hack it and send pull requests.

Tiago Bortoletto Vaz: c3video for debconf #4

This is a follow-up to my previous post related the DebConf videoteam using a new software stack for the next conferences: http://acaia.ca/~tiago/posts/c3video-for-dc-take-3/. As mentioned before, C3TT provides a set of scripts which will work in background for most reviewing and video processing tasks. The first will just check if the talk is done and mark the related ticket as recorded. The second script, B-mount4cut, does a nice job by mounting a custom fuse filesystem providing the following files (more detailed explanation here: uncut.dv: full original dv file used as input file for the final trimming. project.kdenlive: Kdenlive project file for the operator. Once it's saved with the trim marks, fuse-vdv will do a parse on it and use the marks for cutting. cut.dv: contains only the frames between the trim marks extracted from project.kdenlive. cut-complete.dv: contains the frames between the trim marks extracted from project.kdenlive, plus a prepended intro and an appended video. Paths for these files should be previously set in the web interface as properties Processing.Path.Outro and Processing.Path.Intros. The outro file can be, for instance, an appended video file with a common thanks for sponsors. The intro files is usually an individual frame for each talk, being a colorful presentation poster. We can also set the intro duration in the Processing.Duration.Intro property. cut.wav: demuxed audio from cut.dv Note: in fact, fuse-vdv provides virtual video files as a concatenation of original input files, so avoiding copying large and redundant data. Ideally, these fuse mountpoints will be shared over the network for operators via glusterFS, but I'll skip that for now. After adding the trimming marks and saving the project using Kdenlive, the operator should go to the web interface and mark the ticket as cut:
/images/c3tt_cut.png

Mark ticket as cut

Note: I've been able to do the marks in Kdenlive using double-click in the video, then editing the crop start/end options. The buttons "[" and "]" didn't work in my Kdenlive version for some unknown reason. In the current DebConf video environment I had to make a link builder for translating the path/file names to the C3TT format. So, for the Amsterdam/2015-08-13/09:57:02.dv we should have a amsterdam-2015.08.13-09_57_02.dv symlink. From now the system will delivery the next tasks to C-cut-postprocessor script. This script will just check the marks from the Kdenlive project file and do the cutting job. So far it has worked perfectly here for the first video sessions in DebCamp, with zero hack in the original code, wow! Next post will be about the encoding script, named D-encoding.

Steve Kemp: Making an old android phone useful again

I've got an HTC Desire, running Android 2.2. It is old enough that installing applications such as thsoe from my bank, etc, fails. The process of upgrading the stock ROM/firmware seems to be: All in all .. not ideal .. in any sense. I wish there were a more "official" way to go. For the moment I guess I'll ignore the problem for another year. My nokia phone does look pretty good ..

Matthew Palmer: Your "Infrastructure as Code" is still code!

Whether you re a TDD zealot, or you just occasionally write a quick script to reproduce some bug, it s a rare coder who doesn t see value in some sort of automated testing. Yet, somehow, in all of the new-age Infrastructure as Code mania, we appear to have forgotten this, and the tools that are commonly used for implementing Infrastructure as Code have absolutely woeful support for developing your Infrastructure Code. I believe this has to change. At present, the state of the art in testing system automation code appears to be, spin up a test system, run the manifest/state/whatever, and then use something like serverspec or testinfra to SSH in and make sure everything looks OK . It s automated, at least, but it isn t exactly a quick process. Many people don t even apply that degree of rigour to their system config systems, and rely on manual testing, or even just doing it live! , to shake out the bugs they ve introduced. Speed in testing is essential. As the edit-build-test-debug cycle gets longer, frustration grows exponentially. If it takes two minutes to get a something went wrong report out of my tests, I m not going to run them very often. If I m not running my tests very often, then I m not likely to write tests much, and suddenly oops. Everything s on fire. In traditional software development, the unit tests are the backbone of the fast feedback cycle. You re running thousands of tests per second, ideally, and an entire test run might take 5-10 seconds. That s the sweet spot, where you can code and test in a rapid cycle of ever-increasing awesomeness. Interestingly, when I ask the users of most infrastructure management systems about unit testing, they either get a blank look on their face, or, at best, point me in the direction of the likes of Test Kitchen, which is described quite clearly as an integration platform, not a unit testing platform. Puppet has rspec-puppet, which is a pretty solid unit testing framework for Puppet manifests although it isn t widely used. Others, though nobody seems to have any ideas. The blank look is near-universal. If infrastructure developers want to be taken seriously, we need to learn a little about what s involved in the development part of the title we ve bestowed upon ourselves. This means knowing what the various types of testing are, and having tools which enable and encourage that testing. It also means things like release management, documentation, modularity and reusability, and considering backwards compatibility. All of this needs to apply to everything that is within the remit of the infrastructure developer. You don t get to hand-wave away any of this just because it s just configuration! . This goes double when your just configuration! is a hundred lines of YAML interspersed with templating directives (SaltStack, I m looking at you).

12 August 2015

Tiago Bortoletto Vaz: c3video for debconf #3

This is a follow-up to my previous post related the DebConf videoteam using a new software stack for the next conferences: http://acaia.ca/~tiago/posts/c3video-for-dc-take-2/. An outdated documentation for current subject is available at https://wiki.fem.tu-ilmenau.de/streaming/projekte/c3/28c3/crs/pipeline. Although the system may work differently nowadays, the basic idea remains the same. A newer, but incomplete documentation can be found in https://repository.fem.tu-ilmenau.de/trac/c3tt/wiki. Btw, CCC people from #voc at hackint.eu have been very kind and supportive. I've set an instance of C3TT for DebConf15 in http://c3tt.acaia.ca/. If you want to play with it just ping me in #debconf-video at oftc. As you can see, we can keep a single external C3TT server for all Debian events, without much work left to the local side, doesn't it sound amazing?
Setting a new conference Go to Projects, then Create. In the project area we'll need to import the Tickets. Tickets will come from the schedule file, which is a XML as generated from frab. With a minor hack we've been able to make the schedule XML from DebConf Summit quite compatible to it (kudos cate!):
/images/import_tickets.png

Importing tickets

By importing the schedule from https://summit.debconf.org/debconf15.xml we'll be asked from which rooms we want to import the events. Usually those that have video coverage will be selected:
/images/chosing_rooms.png

Choosing rooms

Then, we may want to exclude some talks that we won't provide video:
/images/chosing_talks.png

Choosing talks

We're also required to adjust some Properties for a given conference. An example with some explanation of these properties is availabe at https://c3voc.de/wiki/c3tracker. For my initial tests the ones below seem to be enough:
/images/c3tt_properties.png

Setting properties

The backend: basic understand The screen UI mentioned above will run a set of scripts in background which will automate most of the tasks, preparing videos for cutting to deploying them in different online services. Tab 0: A-recording-scheduler Each 30 seconds it will check if there's any ticket in the state scheduled or recording. It's based in the start/end datetime of the talk, so the ticket will be kept as scheduled (current < talk start), or marked as recording (start => current =< end) or recorded (current > end). Tab 1: B-mount4cut Each 30 seconds it will check if there's any ticket in the state recorded. That means the talk is already finished, and the raw video file is available in the path which has previously been set as a property (Path.Capture) in the web interface. For each ticket marked as recorded it will try to find the related video file in the capture path. The file format should be <room>-YYYY-MM-DD_HH-MM-SS.<extension>. The script will then use fuse-vdv to create a custom filesystem with some needed files for human interaction (fancy stuff!). Here's an example of talks in a room called Heidelberg, after being recorded and auto-mounted by the B-mount4cut script:
/images/c3tt_fuse.png

Mounting custom fuse FS

The human interaction is just a short review process using Kdenlive. The reviewers will access these files via a glusterFS network share. There's even a Debian Virtualbox image provided for that, including all the necessary tools. I'm going into this right now and will report what I get in the next hours. Hopefully the following scripts will also be covered, very soon-ish :) Tab 2: C-cut-postprocessor Tab 3: D-encoding Tab 4: E-postencoding (auphonic) Tab 5: F-postprocessing(upload) DebCamp is fun.

Elena 'valhalla' Grandi: Printing a 2965 lines text file

Printing a 2965 lines text file

Let us image I have a reason https://people.debian.org/~anibal/ksp-dc15/ksp-dc15.html to print a text file that is 2965 lines long, is encoded in utf-8 (so a2ps and enscript don't work) and I don't want to destroy a whole forest for it.

I've started by using xelatex to get a nicely typeset A5 page with my file in a monospaced font: partecipants.tex

\documentclass[a5paper] article
\usepackage fontspec
\usepackage[left=1cm,right=1cm,top=0.8cm,bottom=1cm,foot=0.2cm] geometry
\usepackage listings

\lstset %
basicstyle=\ttfamily\scriptsize,
frame=none,
keepspaces=true,


\begin document
\lstinputlisting ksp-dc15.txt
\end document


This gets compiled into partecipants.pdf with


$ xelatex partecipants.tex


And resulted in 44 pages, 4 less than the 48 needed by a2ps, and printable on just 11 A4 sheets.

I wanted it to be easily manageable while walking around, taking notes into it while standing, so I decided to arrange it in booklet form:


$ pdfbook partecipants.pdf


The result, partecipants-book.pdf was printed (two sided, of course) folded and stitched in the middle.

I could have arranged it into signatures, but this would have required an additional sheet to bring the number of pages to a multiple of 16.

I know that there are electronic alternatives around, and I've also considered just carrying around the file and adding notes (to a copy?) with vim, but I'd trust a paper copy more.

Daniel Pocock: Recording live events like a pro (part 2: video)

In the first blog in this series, we looked at how to capture audio effectively for a range of different events. While recording audio appears less complicated than video, it remains fundamental to a good recording. For some types of event, like a speech or a debate, you can have quite a bad video with poor lighting and other defects but people will still be able to watch it if the audio is good. Therefore, if you haven't already looked at the previous blog, please do so now. As mentioned in the earlier blog, many people now have high quality equipment for recording both audio and video and a wide range of opportunities to use it, whether it is a talk at a conference, a wedding or making a Kickstarter video. The right camera for video recording The fundamental piece of equipment is the camera itself. You may have a DSLR camera that can record video or maybe you have a proper handheld video camera. The leading DSLR cameras, combined with a good lens, make higher quality recordings than many handheld video cameras. Unfortunately, although you pay good money to buy a very well engineered DSLR that could easily record many hours of video, most DSLRs are crippled to record a maximum of 30 minutes in one recording. This issue and some workarounds are discussed later in this blog. If you don't have any camera at all you need to think carefully about which type to buy. If you are only going to use it once you may want to consider renting or borrowing or asking for other people attending the event to bring whatever cameras they have to help make multiple recordings (the crowdsourcing solution). If you are a very keen photographer then you will probably have a preference for a DSLR. Accessories Don't just look at the cost of your camera and conclude that is all the budget you need. For professional quality video recording, you will almost certainly need some accessories. You may find they are overpriced at the retail store where you bought your camera, but you still need some of them, so have a look online.
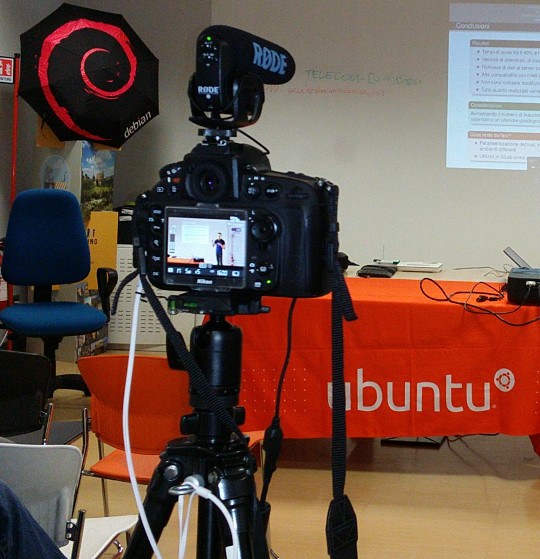
Recording a talk at a free software event with a Nikon D800 on a very basic tripod with Rode VideoMic Pro, headphones (white cable) and external power (black cable) If you want to capture audio with the camera and record it in the video file (discussed in more detail below), you will need to purchase a microphone that mounts on the camera. The built-in microphones on cameras are often quite bad, even on the most expensive cameras. If you are just using the built-in microphone for reference audio (to help with time synchronization when you combine different audio files with the video later) then the built-in microphone may be acceptable. Camera audio is discussed in more detail below. If your camera has a headphone socket, get some headphones for listening to the audio. Make sure you have multiple memory cards. Look carefully at the speed of the memory cards, slow ones are cheaper but they can't keep up with the speed of writing 1080p video. At a minimum, you should aim to buy memory cards that can handle one or two days worth of data for whatever it is you do. A tripod is essential for most types of video. If you use a particularly heavy camera or lens or if you are outdoors and it may be windy you will need a heavier tripod for stability. For video, it is very useful to have a tripod with a handle for panning left and right but if the camera will be stationary for the whole recording then the handle is not essential. Carrying at least one spare battery is another smart move. On one visit to the Inca Trail in Peru, we observed another member of our group hiking up and down the Andes with a brand new DSLR that they couldn't use because the battery was flat. For extended periods of recording, batteries will not be sufficient and you will need to purchase a mains power supply (PSU). These are available for most types of DSLR and video camera. The camera vendors typically design cameras with unusual power sockets so that you can only use a very specific and heavily overpriced PSU from the same company. Don't forget a surge protector too. There are various smartphone apps that allow you to remotely control the camera from the screen of your phone, such as the qDslrDashboard app. These often give a better preview than the screen built-in to the camera and may even allow you to use the touch screen to focus more quickly on a specific part of the picture. A regular USB cable is not suitable for this type of app, you need to buy a USB On-The-Go (OTG) cable.
Screenshot of qDslrDashboard app on a smartphone, controlling a DSLR camera If you plan to copy the video from the camera to a computer at the event, you will need to make sure you have a fast memory card reader. The memory card readers in some laptops are quite slow and others can be quite fast so you may not need to buy an extra card reader. Camera audio Most cameras, including DSLRs, have a built-in microphone and a socket for connecting an external microphone. The built-in microphones obtain very poor quality sound. For many events, it is much better to have independent microphones, such as a lapel microphone attached to a smartphone or wireless transmitter. Those solutions are described in part one of this blog series. Nonetheless, there are still some benefits of capturing audio in the camera. The biggest benefit is the time synchronization: if you have audio recordings in other devices, you will need to align them with the video using post-production software. If the camera recorded an audio stream too, even if the quality is not very good, you can visualize the waveform on screen and use it to align the other audio recordings much more easily and precisely. If the camera will be very close to the people speaking then it may be acceptable to use a microphone mounted on the camera. This will be convenient for post-production because the audio will be synchronized with the video. It may still not be as good as a lapel microphone though, but the quality of these camera-mounted microphones is still far higher than the built-in microphones. I've been trying the Rode VideoMic Pro, it is definitely better than recording with the built-in microphone on the camera and also better than the built-in microphone on my phone. One problem that most people encounter is the sound of the lens autofocus mechanism being detected by the microphone. This occurs with both the built-in microphone and any other microphone you mount on the camera. A microphone mounted on top of the camera doesn't detect this noise with the same intensity as the built-in microphone but it is still present in the recordings. If using a camera-mounted microphone to detect the audio from an audience, you may need to have an omnidirectional microphone. Many camera-mounted microphones are directional and will not detect very much sound from the sides or behind the camera. When using any type of external microphone with the camera, it is recommend to disable automatic gain control (AGC) in the camera settings and then manually adjust the microphone sensitivity/volume level. Use headphones A final word on audio - most good cameras have an audio output socket. Connect headphones and wear them, to make sure you are always capturing audio. Otherwise, if the microphone's battery goes flat or if a wireless microphone goes out of range you may not notice. Choosing a lens The more light you get, the better. Bigger and more expensive lenses allow more light into the camera. Many of the normal lenses sold with a DSLR camera are acceptable but if it is a special occasion you may want to rent a more expensive lens for the day. If you already have a lens, it is a very good idea to test it in conditions similar to those you expect for the event you want to record. Recording duration limits Most DSLR cameras with video capability impose a 30 minute maximum recording duration This is basically the result of a friendly arrangement between movie studios and politicians to charge an extra tax on video recording technology and potentially make the movie studio bosses richer, supposedly justified by the fact that a tiny but exaggerated number of people use their cameras to record movies at the cinema. As a consequence, most DSLR manufacturers limit the duration of video recording so their product won't be subject to the tax, ensuring the retail price is lower and more attractive. On top of this, many DSLR cameras also have a 4GB file size limit if they use the FAT filesystem. Recording 1080p video at a high frame rate may hit the file size limit in 10 minutes, well before you encounter the 30 minute maximum recording duration. To deal with the file size issue, you can record at 720p instead of 1080p and use the frame rate 24fps. For events longer than 30 minutes or where you really want 1080p or a higher frame rate, there are some other options you can consider:
  • Buy or rent a proper video camera instead of using a DSLR camera
  • Using multiple cameras that can stop and be restarted at different times.
  • Manually stopping and restarting the camera if there are breaks in the event where it is safe to do so.
  • Use an app to control the camera and program it to immediately restart the recording each time it stops
  • Extract the raw output from the camera's HDMI socket and record into some other device or computer. There are several purpose-built devices
    that can be used this way with an embedded SSD for storage.
  • There are also some people distributing unofficial/alternative firmware images that remove the artificial 30 minute recording limit.
Camera settings There are many online tutorials and demonstration videos on YouTube that will help you optimize the camera settings for video. You may have already made recordings using the automatic mode. Adjusting some or all of the settings manually may help you create a more optimal recording. You will need to spend some time familiarizing yourself with the settings first. The first thing to check is white balance. This tells the camera the type of lighting in the location. If you set this incorrectly then the colours will be distorted. Many cameras have the ability to automatically set the white balance. For video, you may be able to change one or more settings that control the recording quality. These settings control the file compression ratio and image size. Typical image size settings are 720p and 1080p. Compression ratio may be controlled by a high/medium/low quality setting. Choosing the highest quality and biggest picture requires more space on the memory card and also means you reach the 4GB file size limit more quickly. A higher quality setting also implies a faster memory card is required, because the rate of megabytes per second written to the memory card is higher. Next you need to think about the frame rate. Events that involve fast moving subjects, such as sports, typically benefit from a higher frame rate. For other events it is quite acceptable to use 24 frames per second (fps). Higher frame rates also imply bigger file size and a requirement for a faster memory card. Once you have decided on the frame rate, the next thing to do is set the shutter speed. Use a shutter speed that is double the frame rate. For example, if using 24fps or 25fps, use a 1/50 shutter speed. The final two settings you need to adjust are the ISO and aperture. Set these based on the lighting conditions and extent to which the subjects are moving. For example, if the setting is dark or if you are trying to record fast moving subjects like athletes, vehicles or animals, use an ISO value of 800 or higher. Once you have chosen ISO, adjust the aperture to ensure the picture is sufficiently illuminated. Aperture also has a significant impact on the depth of field. Operating the camera: zoom and focus Many people use zoom lenses. It is not always necessary to change the zoom while recording a video, you can use software to zoom in and out on individual parts of the picture when editing it in post-production. If you do change the zoom while recording, it may be more difficult to maintain focus. Almost all lenses support manual focus (turning the focus ring by hand) and many support automatic focus. When shooting photographs with a DSLR, the mirror is down and the camera can use dedicated sensors for focus and light sensing. When shooting video, the mirror is up and the camera can not use the same focus sensors that are used in photography. Video recording uses a digital focussing algorithm based on contrast in the picture. If you take a lot of photos you are probably quite accustomed to the fast and precise autofocus for photography and you will notice that keeping a video in focus is more challenging. As mentioned already, one of the first things you can do to keep focus simple is to avoid zooming while recording. Record in a higher resolution than you require and then zoom with software later. Some people record using 4k resolution even when they only want to produce a 720p video, as they can digitally zoom in to different parts of the 4k recording without losing detail. If the subject is very stationary (people sitting at a desk for an interview is a typical example), you may be able to set the camera to manual focus and not change it at all while recording. If you choose to enable autofocus while recording, any built-in camera microphone or microphone mounted on the camera is likely to detect sounds from the motorized focus system. Ultimately, the autofocus mechanism is not accurate for all subjects and you may be unable to stop them moving around so you will need to change the focus manually while recording. It requires some practice to be able to do this quickly without overshooting the right focus. To make life more tricky, Nikon and Canon focus rings rotate in the opposite direction, so if you are proficient using one brand you may feel awkward if you ever have to use the other. A good way to practice this skill is to practice while in the car or on the train, pointing at different subjects outside the window and trying to stay in focus as you move from one subject to the next. Make a trial run Many events, from weddings right up to the Olympic Games opening ceremony, have a trial run the day before. One reason for that is to test the locations and settings of all the recording and broadcasting equipment. If a trial run isn't possible for your event, you may find some similar event to practice recording and test your equipment. For example, if you are planning to record a wedding, you could try and record a Sunday mass in the same church. Backup and duplicate the recordings before leaving the event If you only have one copy of the recordings and the equipment is stolen or damaged you may be very disappointed. Before your event, make a plan to duplicate the raw audio and video recordings so that several people can take copies away with them. Decide in advance who will be responsible for this, ensure there will be several portable hard disks and estimate how much time it will take to prepare the copies and factor this into the schedule. Conclusion All the products described can be easily purchased from online retailers. You may not need every accessory that is mentioned as it depends on the type of event you record. The total cost of buying or renting the necessary accessories may be as much as the cost of the camera itself so if you are new to this you may need to think carefully about making a budget with a spreadsheet to do it correctly. Becoming familiar with the camera controls and practicing the techniques for manual focus and zoom can take weeks or months. If you enjoy photography this can be time well spent but if you don't enjoy it then you may not want to commit the time necessary to make good quality video. Don't rule out options like renting equipment instead of buying it or crowdsourcing, asking several participants or friends to help make recordings with their own equipment. For many events, audio is far more indispensable than video and as emphasizing at the beginning of this article, it is recommended that you should be one hundred percent confident in your strategy for recording audio before you start planning to record video.

Daniel Pocock: UK wakes up to airport tax and data grab

The UK has just woken up to the fact that retailers at airports have been playing the VAT system. The focus of the media coverage has been on the VAT money, failing to give much emphasis to the fact this is also a sophisticated and coordinated attack on personal privacy. This situation has been obvious to me for years and it doesn't just occur in the UK. Whenever one of these retailers asks me for a boarding pass, I always refuse. Sometimes they lie to me and tell me that it is mandatory to let them scan my boarding pass: I tell them that a travel companion has the boarding passes and at this point they usually find some way to complete the transaction without further comment. It is only necessary to pay the correct amount With the rise of payment cards, people seem to be forgetting that you can pay for things in cash. If I have the right change to pay for something in this scenario, I typically put it on the counter and walk away. Why should I have to waste my time helping a poorly trained cashier understand VAT? I already deal with enough computer problems in the job I'm paid to do, why should I lose my time when on vacation explaining to a cashier that their computer is failing to correctly deduct 20% VAT? Whenever showing a boarding pass or passport It is far too common for people to try and scan or copy documents these days. When somebody in an airport shop or hotel asks to see a document, I don't let it out of my hands. It is not hard to cover the barcode with your fingers too. This prevents them making an unauthorized copy or using a barcode scanner to extract personal data. Some of these staff literally try to snatch the documents out of people's hands and drop them onto a scanner next to their till. In some countries hotels are obliged to look at your passport and make a record of the name but they often have no obligation to photocopy or scan it and it is often a huge risk if they do. If the airports are genuinely concerned about the security of passengers, they would be just as thorough in protecting data as they are in the hunt for terrorists. For example, they could give VAT-free passengers colour-coded boarding passes or some other vouchers without any personal information on them. VAT diversion funds customer data grab Shops pocket an extra 20% of the price of a product and they condition everybody, staff and customers, to having all customer data expropriated from the boarding pass at the point of sale, even the customers not eligible for a tax refund are unnecessarily having their data hoovered up in this way. The VAT money diverted away from both the tax man and the customer is rolled back into the system to fund the data grab. UK law promises customers significant protection from unlawful use of personal data, so how can these retailers lie to passengers and tell them that scanning the boarding pass is mandatory? Why not ask the Information Commission's Office to check up on this? Paying the correct amount and walking away It is not hard for people to add up the amount of VAT included in a price, deduct it themselves, give the correct and exact amount of cash to the cashier and walk away. Just type the price into your smart phone, divide by 1.2 and you can see the amount to pay. For example, if a product costs 24.95, just type 24.95 1.2 into the calculator on your phone and you find that you have to pay 20.79. It may only be necessary to show a boarding pass or ID for purchasing duty-free alcohol or tobacco. Not just for airports Carrying a correct amount of cash doesn't just help navigate the data grab in airports. Consider some of the other scenarios:
  • A long queue at the cashier in a petrol station, typically on a Sunday afternoon. Did you ever notice somebody who just walks past the queue and puts the exact change (or a cheque) on the counter and drives away while everybody else is waiting to pay with some payment card and scan their loyalty card?
  • Restaurant in a tourist spot, you receive a bill and notice they have added VAT and service charges or something you didn't ask for like bread. In European countries and Australia, the price next to each dish on the menu is the only price you have to pay, just like the price on the shelf in a shop or the price on a web page. If you have the right change you can just pay that amount and walk away without a discussion. In the US the taxes are added later and some tourist hot spots in Europe try this with English speaking customers, thinking that if they are American they won't complain.
  • Hotel tries to insist on a currency conversion when charging your credit card. Maybe you've already realized that dynamic currency conversion (DCC) used by retailers often adds at least 3% to a purchase but some hotels try to go way beyond this. The booking confirmation page you printed from their web site gives you a total price in one currency, perhaps USD or EUR and they use some arbitrary exchange rate, with a whopping 30% margin or more, to convert to the local currency and ask you to insert your PIN number or sign a credit card authorization. The best answer to this practice is usually to carry banknotes in the currency used for the booking, paying that exact amount in cash and if they try to argue, just keep counting out the bank notes to prove it matches the confirmation page. Hotels only get away with this trick because few people check the rate, even fewer carry sufficient cash and you may not be able to use local cash machines to get the currency specified in your booking. This is a situation I've encountered in eastern Europe and South America where it is common to quote in EUR and USD even if that isn't the domestic currency.

11 August 2015

Tiago Bortoletto Vaz: c3video for debconf #2

This is a follow-up to my previous post related the DebConf videoteam using a new software stack for the next conferences: http://acaia.ca/~tiago/posts/c3video-for-dc-take-1/.
Installing C3TT scripts There's a video (in German) which gives an idea about how the C3TT works: https://www.youtube.com/watch?v=K-KHbAcTo9I It basically gives the volunteers a web interface to cut and review the recordings, wich communicates with a set of scripts running in background which will automate some tasks. "Installing" the set of scripts is just a matter of placing them in a common directory and installing some Perl dependencies, mostly which are already packaged for Debian. First check it out from the svn repository (fun fact: the web interface is coded in php in a git repository, the scripts are mostly written in perl with a little of bash, in a subversion repository. Both the conference and media system is are in ruby :)
$ svn co https://subversion.fem.tu-ilmenau.de/repository/cccongress
$ mkdir /opt/crs; mv cccongress/trunk/tools /opt/crs/
A few libraries required:
$ apt-get install libboolean-perl libmath-round-perl libdatetime-perl libwww-curl-perl libconfig-inifiles-perl libxml-simple-perl
$ perl -MCPAN -e 'install XML::RPC::Fast'
In the web tracker create a project, go to all projects => workers and create a worker (I'll try to explain it later). Go edit the worker and we'll see the token and secret that should be used in the scripts to talk to the interface.
cd  /opt/crs/tools/tracker3.0
Create a file tracker-profile.sh with the follow lines (using our correct values):
export CRS_TRACKER=http://localhost/rpc
export CRS_TOKEN=2q24M7LW4Rk31YNW4tWKv8koNvyM3V4s
export CRS_SECRET=5j8SyCS35W2SBk2XIM4IWeDUqF9agG1x
We also need to build and install the fuse-vdv package from trunk/tools (if working with dv files, otherwise fuse-ts package). Next step is run the scripts. Fortunatelly a nice UI has been done using screen with multiple tabs, which can be alternated using a <Ctrl+a> <number> combination.
cd  /opt/crs/tools/tracker3.0 && /start-screenrc-dv.sh
We'll get the following:
/images/screen-c3tt-dv.png

Screen tabs from C3TT

In a next post I'll try to explain a bit of how the web system work together with the scripts and how to do a basic setup for a real conference. I hope to get there soon!

Jonathan McDowell: Programming the FST-01 (gnuk) with a Bus Pirate + OpenOCD

Last year at DebConf14 Lucas authorized the purchase of a handful of gnuk devices, one of which I obtained. At the time it only supported 2048 bit RSA keys. I took a look at what might be involved in adding 4096 bit support during DebConf and managed to brick my device several times in doing so. Thankfully gniibe was on hand with his STLinkV2 to help me recover. However subsequently I was loathe to experiment further at home until I had a suitable programmer. As it is this year has been busy and the 1.1.x release train is supposed to have 4K RSA (as well as ECC) support. DebConf15 is coming up and I felt I should finally sort out playing with the device properly. I still didn t have a suitable programmer. Or did I? Could my trusty Bus Pirate help? The FST-01 has an STM32F103TB on it. There is an exposed SWD port. I found a few projects that claimed to do SWD with a Bus Pirate - Will Donnelly has a much cloned Python project, the MC HCK project have a programmer in Ruby and there s LibSWD though that s targeted to smarter programmers. None of them worked for me; I could get the Python bits as far as correctly doing the ID of the device, but not reading the option bytes or successfully flashing (though I did manage an erase). Enter the old favourite, OpenOCD. This already has SWD support and there s an outstanding commit request to add Bus Pirate support. NodoNogard has a post on using the ST-Link/V2 with OpenOCD and the FST-01 which provided some useful pointers. I grabbed the patch from Gerrit, applied it to OpenOCD git and built an openocd.cfg that contained:
source [find interface/buspirate.cfg]
buspirate_port /dev/ttyUSB0
buspirate_vreg 1
buspirate_mode normal
transport select swd
source [find target/stm32f1x.cfg]
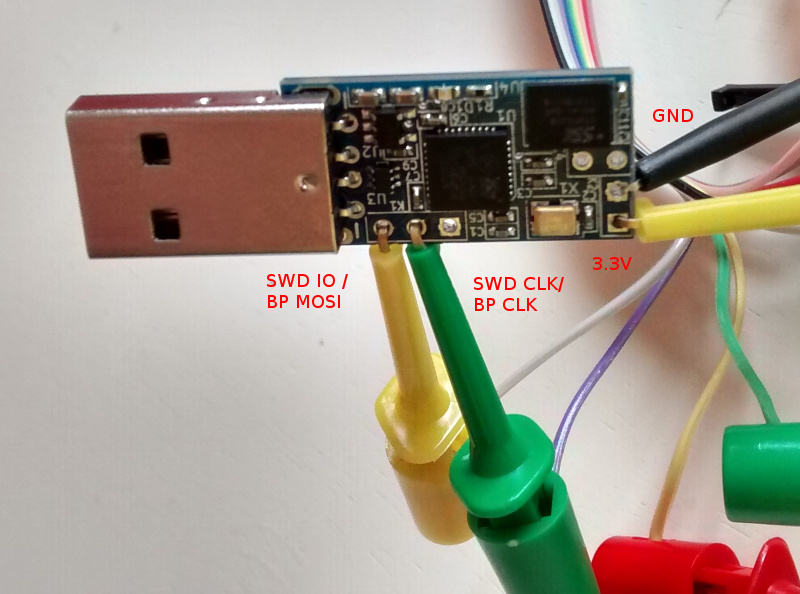
My BP has the Seeed Studio probe cable, so my hookups look like this: Bus Pirate + FST-01 SWD connection That s BP MOSI (grey) to SWD IO, BP CLK (purple) to SWD CLK, BP 3.3V (red) to FST-01 PWR and BP GND (brown) to FST-01 GND. Once that was done I fired up OpenOCD in one terminal and did the following in another:
$ telnet localhost 4444
Trying ::1...
Trying 127.0.0.1...
Connected to localhost.
Escape character is '^]'.
Open On-Chip Debugger
> reset halt
target state: halted
target halted due to debug-request, current mode: Thread
xPSR: 0x01000000 pc: 0xfffffffe msp: 0xfffffffc
Info : device id = 0x20036410
Info : SWD IDCODE 0x1ba01477
Error: Failed to read memory at 0x1ffff7e2
Warn : STM32 flash size failed, probe inaccurate - assuming 128k flash
Info : flash size = 128kbytes
> stm32f1x unlock 0
Device Security Bit Set
stm32x unlocked.
INFO: a reset or power cycle is required for the new settings to take effect.
> reset halt
target state: halted
target halted due to debug-request, current mode: Thread
xPSR: 0x01000000 pc: 0xfffffffe msp: 0xfffffffc
> flash write_image erase /home/noodles/checkouts/gnuk/src/build/gnuk.elf
auto erase enabled
wrote 109568 bytes from file /home/noodles/checkouts/gnuk/src/build/gnuk.elf in 95.055603s (1.126 KiB/s)
> stm32f1x lock 0
stm32x locked
> reset halt
target state: halted
target halted due to debug-request, current mode: Thread 
xPSR: 0x01000000 pc: 0x08000280 msp: 0x20005000
Then it was a matter of disconnecting the gnuk from the BP, plugging it into my USB port and seeing it come up successfully:
usb 1-2: new full-speed USB device number 11 using xhci_hcd
usb 1-2: New USB device found, idVendor=234b, idProduct=0000
usb 1-2: New USB device strings: Mfr=1, Product=2, SerialNumber=3
usb 1-2: Product: Gnuk Token
usb 1-2: Manufacturer: Free Software Initiative of Japan
usb 1-2: SerialNumber: FSIJ-1.1.7-87063020
usb 1-2: ep 0x82 - rounding interval to 1024 microframes, ep desc says 2040 microframes
More once I actually have a 4K key loaded on it.

Tiago Bortoletto Vaz: c3video for debconf #1

Some context DebConf has provided live streaming and recordings from talks since 2004. We used to work with a set of scripts which worked together with Pentabarf for most of videoteam tasks, including volunteer shifts coordination, reviewing process, encoding and deployment. Things has changed since DebConf14, when Pentabarf was replaced by Summit as the conference management system. Without those old Pentabarf features and hacks we had to invent new ways of dealing with the video workflow in DebConf. We gave veyepar a try in 2014, and we will probably do it again in DebConf15. However, for a long term solution we are considering the software stack from CCC Video Operation Center, which so far I see as a free, solid and community-oriented mix of Debian-friendly tools. I will be reporting the progress on setting up and testing the CCC software strucutre for DebConf. Having the opportunity of being in DebCamp together with other videoteam folks will certainly make things easier :)
Setting up the CCC Ticket Tracker C3TT is a ticket/tracker system used by CCC for reviewing/encoding process. The web side of C3TT is written in PHP and can be cloned from http://git.fem.tu-ilmenau.de/cccongress.git. Some documentation is available at https://repository.fem.tu-ilmenau.de/trac/c3tt/wiki and from https://c3voc.de/wiki/c3tracker. What I've done so far to get it working: Installing some dependencies:
$ apt-get install postgresql-9.4 php5-pgsql php5-xsl postgresql-contrib-9.4 php5-xmlrpc php5 php5-curl
Creating database and users:
$ su -s /bin/bash postgres
$ createuser -DRS dc15
$ createdb -O dc15 c3tt
$ psql
postgres=# ALTER ROLE dc15 WITH PASSWORD 'xxx';
Basic site config using lighttpd:
$HTTP["host"] =~ "c3tt\.your\.host"  
  server.document-root = "/var/www/c3tt/Public/"
  alias.url = ("/javascript/" => "/var/www/js/")
  url.rewrite-once = ( ".*\.(js ico gif jpg png css)$" => "$0", "^(.*?)$" => "index.php/$1",)
   
Running the installer script:
$ php -q Install/install.php
This will ask you some questions, then will create the config file and populate the database. At this point you should be able to access the ticket track system from your browser. The set of scripts from C3TT doesn't need to be installed in the same host as the web side, they communicate via XML/RPC. In a next post I will report the installation and initial setup for these scripts.

Matthias Klumpp: AppStream/DEP-11 for everyone! (beta!)

One of the things we discussed at this year s Akademy conference is making AppStream work on Kubuntu.appstream-logo On Debian-based systems, we use a YAML-based implementation of AppStream, called DEP-11 . DEP-11 exists for historical reasons (the DEP-11 YAML format was a superset of AppStream once) and because YAML, unlike XML, is one accepted file format by the Debian FTPMasters team, who we want to have on board when adding support for AppStream. So I ve spent the last few days on setting up the DEP-11 generator for Kubuntu, as well as improving it greatly to produce more meaningful error messages and to generate better output. It became a bit slower in the process, but the greatly improved diagnostics data is worth it. For example, maintainers of Debian packages will now get a more verbose explanation of issues found with metadata in their packages, making them easier to fix for people who didn t get in contact with AppStream yet. At time, we generate AppStream metadata for Tanglu, Kubuntu and Debian, but so far only Tanglu makes real use of it by shipping it in a .deb package. Shipping the data as package is only a workaround though, for a proper implementation, the data will be downloaded by Apt. To achieve that, the data needs to reach the archive first, which is something that I can hopefully discuss and implement with the FTPMasters team of Debian at this year s Debconf. When this is done, the new metadata will automatically become available in tools like GNOME-Software or Muon Discover. How can I see if there are issues with my package? The dep11-generator tool will return HTML pages to show both the extracted metadata, as well as issues with it. You can find the information for the respective distribution here: Each issue tag will contain a detailed explanation of what went wrong. Errors generally lead to ignoring the metadata, so it will not be processed. Warnings usually concern things which might reduce the amount of metadata or make it less useful, while Info-type hints contain information on how to improve the metadata or make it more useful. Can I use the data already? Yes, you can. You just need to place the compressed YAML files in /var/cache/app-info/yaml and the icons in /var/cache/app-info/icons/<suite>-<component>/<size>, for example: /var/cache/app-info/icons/jessie-amd64/64 64 I think I found a bug in the generator In that case, please report the issue against the appstream-dep11 package at Debian, or file an issue at Github.. The only reason why I announce this feature now is to find remaining generator bugs, before officially announcing the feature on debian-devel-announce. When will this be officially announced? I want to give this feature a little bit more testing, and ideally have the integration into the archive ready, so people can see how the metadata looks like when rendered in GNOME-Software/Discover. I also want to write a bit more documentation to help Debian developers and upstreams to improve their metadata. Ideally, I also want to incorporate some feedback at Debconf when announcing full AppStream support in Debian. So take all the stuff you ve read above as a little sneak peek  Debconf15goingI will also give a talk at Debconf, titled AppStream, Limba, XdgApp Where we are going. The aim of this talk is to give an insight i tnto the new developments happening in the software distribution area, and what the goal of these different projects is (the talk should give an overview of what s in the oven and how it will impact Debian). So if you are interested, please drop by :-) Maybe setting up a BOF would also be a good idea.
10 August 2015

Norbert Preining: Updating my dual-boot Linux laptop to Windows 10

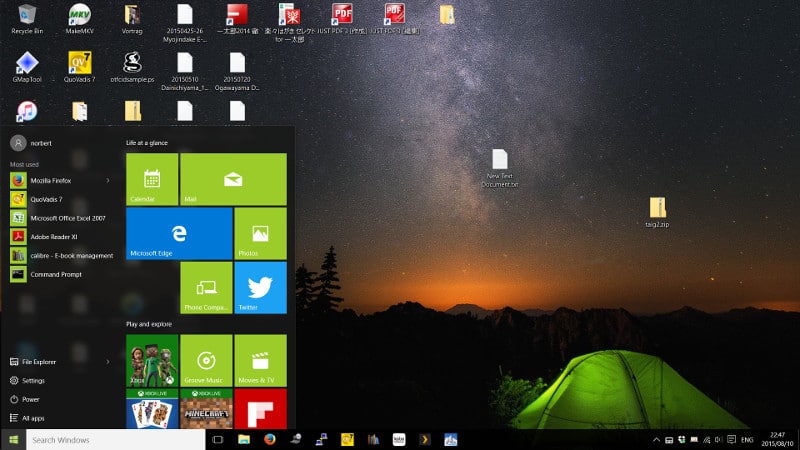
Ok, I have to admit, I still have Windows on my laptop. I do about 90% of my work on the Linux (Debian) side, but there are some applications where I don t have an alternative: Word (yes, I know LibreOffice, but it is still not capable enough to handle Japanese forms without breaking the layout), and much more, QuoVadis, a GPS and digital map program where I do have my whole history of moutaineering and bundled knowledge as mountain guide. So for the time being, I cannot switch away from Windows. Not to mention some of the Steam games that only work on Windows, unfortunately. So the other day I went ahead and accepted the upgrade offer and let Windows do its part win10 The machine is a Sony Vaio I have reported already many times, see the posts of the tag Vaio. All in all, it was a very smooth upgrade, to my complete suprise: On the other hand, as it is well documented, Windows 10 is a beast when it comes to collecting all kinds of data. There are a lot of settings to be turned off just to make sure not all your details down to your shoe size and the x-ray of your grandparents are transmitted to Microsoft. I used the German Computer News page heise where I found this article. All in all for now I am happy with the current situation, I could boot back into my comfy Linux and know that if it is necessary, I can switch to Windows (10) for some dirty work.

Carl Chenet: Retweet, a simple bot to retweet tweets from a user

Follow me on Identi.ca or Twitter or Diaspora*diaspora-banner For a small project related to the french-speaking Hacker News-style website le Journal du hacker, I needed to retweet every tweets from a Twitter account to another one. So here it is : Retweet I wanted to keep it simple, stupid, and coded in Python if I needed to extend it myself for the projet Le Journal du hacker. logo-journal-du-hacker It was quite easy to reach these goals, but the project is also well documented and should be quite simple to install, configure and use. What about you? Do you also have this kind of needs? Don t hesitate to fork the project, report bugs, ask for feature requests and let us know in the comments of this post ;)

Next.

Previous.