Search Results: "cts"

31 October 2023

Iustin Pop: Raspberry PI OS: upgrading and cross-grading

One of the downsides of running Raspberry PI OS is the fact that - not having the resources of pure Debian - upgrades are not recommended, and cross-grades (migrating between armhf and arm64) is not even mentioned. Is this really true? It is, after all a Debian-based system, so it should in theory be doable. Let s try!

Upgrading The recently announced release based on Debian Bookworm here says:
We have always said that for a major version upgrade, you should re-image your SD card and start again with a clean image. In the past, we have suggested procedures for updating an existing image to the new version, but always with the caveat that we do not recommend it, and you do this at your own risk. This time, because the changes to the underlying architecture are so significant, we are not suggesting any procedure for upgrading a Bullseye image to Bookworm; any attempt to do this will almost certainly end up with a non-booting desktop and data loss. The only way to get Bookworm is either to create an SD card using Raspberry Pi Imager, or to download and flash a Bookworm image from here with your tool of choice.
Which means, it s time to actually try it turns out it s actually trivial, if you use RPIs as headless servers. I had only three issues:
  • if using an initrd, the new initrd-building scripts/hooks are looking for some binaries in /usr/bin, and not in /bin; solution: install manually the usrmerge package, and then re-run dpkg --configure -a;
  • also if using an initrd, the scripts are looking for the kernel config file in /boot/config-$(uname -r), and the raspberry pi kernel package doesn t provide this; workaround: modprobe configs && zcat /proc/config.gz > /boot/config-$(uname -r);
  • and finally, on normal RPI systems, that don t use manual configurations of interfaces in /etc/network/interface, migrating from the previous dhcpcd to NetworkManager will break network connectivity, and require you to log in locally and fix things.
I expect most people to hit only the 3rd, and almost no-one to use initrd on raspberry pi. But, overall, aside from these two issues and a couple of cosmetic ones (login.defs being rewritten from scratch and showing a baffling diff, for example), it was easy. Is it worth doing? Definitely. Had no data loss, and no non-booting system.

Cross-grading (32 bit to 64 bit userland) This one is actually painful. Internet searches go from it s possible, I think to it s definitely not worth trying . Examples: Aside from these, there are a gazillion other posts about switching the kernel to 64 bit. And that s worth doing on its own, but it s only half the way. So, armed with two different systems - a RPI4 4GB and a RPI Zero W2 - I tried to do this. And while it can be done, it takes many hours - first system was about 6 hours, second the same, and a third RPI4 probably took ~3 hours only since I knew the problematic issues. So, what are the steps? Basically:
  • install devscripts, since you will need dget
  • enable new architecture in dpkg: dpkg --add-architecture arm64
  • switch over apt sources to include the 64 bit repos, which are different than the 32 bit ones (Raspberry PI OS did a migration here; normally a single repository has all architectures, of course)
  • downgrade all custom rpi packages/libraries to the standard bookworm/bullseye version, since dpkg won t usually allow a single library package to have different versions (I think it s possible to override, but I didn t bother)
  • install libc for the arm64 arch (this takes some effort, it s actually a set of 3-4 packages)
  • once the above is done, install whiptail:amd64 and rejoice at running a 64-bit binary!
  • then painfully go through sets of packages and migrate the set to arm64:
    • sometimes this work via apt, sometimes you ll need to use dget and dpkg -i
    • make sure you download both the armhf and arm64 versions before doing dpkg -i, since you ll need to rollback some installs
  • at one point, you ll be able to switch over dpkg and apt to arm64, at which point the default architecture flips over; from here, if you ve done it at the right moment, it becomes very easy; you ll probably need an apt install --fix-broken, though, at first
  • and then, finish by replacing all packages with arm64 versions
  • and then, dpkg --remove-architecture armhf, reboot, and profit!
But it s tears and blood to get to that point

Pain point 1: RPI custom versions of packages Since the 32bit armhf architecture is a bit weird - having many variations - it turns out that raspberry pi OS has many packages that are very slightly tweaked to disable a compilation flag or work around build/test failures, or whatnot. Since we talk here about 64-bit capable processors, almost none of these are needed, but they do make life harder since the 64 bit version doesn t have those overrides. So what is needed would be to say downgrade all armhf packages to the version in debian upstream repo , but I couldn t find the right apt pinning incantation to do that. So what I did was to remove the 32bit repos, then use apt-show-versions to see which packages have versions that are no longer in any repo, then downgrade them. There s a further, minor, complication that there were about 3-4 packages with same version but different hash (!), which simply needed apt install --reinstall, I think.

Pain point 2: architecture independent packages There is one very big issue with dpkg in all this story, and the one that makes things very problematic: while you can have a library package installed multiple times for different architectures, as the files live in different paths, a non-library package can only be installed once (usually). For binary packages (arch:any), that is fine. But architecture-independent packages (arch:all) are problematic since usually they depend on a binary package, but they always depend on the default architecture version! Hrmm, and I just realise I don t have logs from this, so I m only ~80% confident. But basically:
  • vim-solarized (arch:all) depends on vim (arch:any)
  • if you replace vim armhf with vim arm64, this will break vim-solarized, until the default architecture becomes arm64
So you need to keep track of which packages apt will de-install, for later re-installation. It is possible that Multi-Arch: foreign solves this, per the debian wiki which says:
Note that even though Architecture: all and Multi-Arch: foreign may look like similar concepts, they are not. The former means that the same binary package can be installed on different architectures. Yet, after installation such packages are treated as if they were native architecture (by definition the architecture of the dpkg package) packages. Thus Architecture: all packages cannot satisfy dependencies from other architectures without being marked Multi-Arch foreign.
It also has warnings about how to properly use this. But, in general, not many packages have it, so it is a problem.

Pain point 3: remove + install vs overwrite It seems that depending on how the solver computes a solution, when migrating a package from 32 to 64 bit, it can choose either to:
  • overwrite in place the package (akin to dpkg -i)
  • remove + install later
The former is OK, the later is not. Or, actually, it might be that apt never can do this, for example (edited for brevity):
# apt install systemd:arm64 --no-install-recommends
The following packages will be REMOVED:
  systemd
The following NEW packages will be installed:
  systemd:arm64
0 upgraded, 1 newly installed, 1 to remove and 35 not upgraded.
Do you want to continue? [Y/n] y
dpkg: systemd: dependency problems, but removing anyway as you requested:
 systemd-sysv depends on systemd.
Removing systemd (247.3-7+deb11u2) ...
systemd is the active init system, please switch to another before removing systemd.
dpkg: error processing package systemd (--remove):
 installed systemd package pre-removal script subprocess returned error exit status 1
dpkg: too many errors, stopping
Errors were encountered while processing:
 systemd
Processing was halted because there were too many errors.
But at the same time, overwrite in place is all good - via dpkg -i from /var/cache/apt/archives. In this case it manifested via a prerm script, in other cases is manifests via dependencies that are no longer satisfied for packages that can t be removed, etc. etc. So you will have to resort to dpkg -i a lot.

Pain point 4: lib- packages that are not lib During the whole process, it is very tempting to just go ahead and install the corresponding arm64 package for all armhf lib package, in one go, since these can coexist. Well, this simple plan is complicated by the fact that some packages are named libfoo-bar, but are actual holding (e.g.) the bar binary for the libfoo package. Examples:
  • libmagic-mgc contains /usr/lib/file/magic.mgc, which conflicts between the 32 and 64 bit versions; of course, it s the exact same file, so this should be an arch:all package, but
  • libpam-modules-bin and liblockfile-bin actually contain binaries (per the -bin suffix)
It s possible to work around all this, but it changes a 1 minute:
# apt install $(dpkg -i   grep ^ii   awk ' print $2 ' grep :amrhf sed -e 's/:armhf/:arm64')

into a 10-20 minutes fight with packages (like most other steps).

Is it worth doing? Compared to the simple bullseye bookworm upgrade, I m not sure about this. The result? Yes, definitely, the system feels - weirdly - much more responsive, logged in over SSH. I guess the arm64 base architecture has some more efficient ops than the lowest denominator armhf , so to say (e.g. there was in the 32 bit version some rpi-custom package with string ops), and thus migrating to 64 bit makes more things faster , but this is subjective so it might be actually not true. But from the point of view of the effort? Unless you like to play with dpkg and apt, and understand how these work and break, I d rather say, migrate to ansible and automate the deployment. It s doable, sure, and by the third system, I got this nailed down pretty well, but it was a lot of time spent. The good aspect is that I did 3 migrations:
  • rpi zero w2: bullseye 32 bit to 64 bit, then bullseye to bookworm
  • rpi 4: bullseye to bookworm, then bookworm 32bit to 64 bit
  • same, again, for a more important system
And all three worked well and no data loss. But I m really glad I have this behind me, I probably wouldn t do a fourth system, even if forced And now, waiting for the RPI 5 to be available See you!

Russell Coker: Links October 2023

The Daily Kos has an interesting article about a new more effective method of desalination [1]. Here is a video of a crazy guy zapping things with 100 car batteries [2]. This is sonmething you should avoid if you want to die of natural causes. Does dying while making a science video count for a Darwin Award? A Hacker News comment has an interesting explanation of Unix signals [3]. Interesting documentary on the rise of mega corporations [4]. We need to split up Google, Facebook, and Amazon ASAP. Also every phone platform should have competing app stores. Dave Taht gave an interesting LCA lecture about Internet congestion control [5]. He also referenced a web site about projects to alleviate the buffer bloat problem [6]. This tiny event based sensor is an interesting product [7]. It could lead to some interesting (but possibly invasive) technological developments in phones. Tara Barnett s Everything Open lecture Swiss Army GLAM had some interesting ideas for community software development [8]. Having lots of small programs communicating with APIs is an interesting way to get people into development. Actually Hardcore Overclocking has an interesting youtube video about the differences between x8 and x14 DDR4 DIMMs [9]. Interesting YouTube video from someone who helped the Kurds defend against Turkey about how war tunnels work [10]. He makes a strong case that the Israeli invasion of the Gaza Strip won t be easy or pleasant.

29 October 2023

Aigars Mahinovs: Figuring out finances part 4

At the end of the last part of this, we got a Home Assistant OS installation that contains in itself a Firefly III instance and that contains all the current financial information. Now I will try to connect the two. While it could be nice to create a fully-featured integration for Firefly III to Home Assistant to communicate all interesting values and events, I have an interest on programming a more advanced data point calculation for my budget needs, so a less generic, but more flexible approch is a better one for me. So I was quite interested when among the addons in the Home Assistant Addon Store I saw AppDaemon - a way to simply integrate arbitrary Python processing with Home Assistant. Let's see if that can do what I want. For start, after reading the tutorial , I wanted to create a simple script that would use Firefly III REST API to read the current balance of my main account and then send that to Home Assistant as a sensor value, which then can be displayed on a dashboard. As a quick try I modified the provided hello_world.py that is included in the default AppDaemon installation:
import requests
from datetime import datetime
import appdaemon.plugins.hass.hassapi as hass
app_token = "<FIREFLY_PERSONAL_ACCESS_TOKEN>"
firefly_url = "<FIREFLY_URL>"
class HelloWorld(hass.Hass):
    def initialize(self):
        self.run_every(self.set_asset, "now", 60 * 60)
    def set_asset(self, kwargs):
        ent = self.get_entity("sensor.firefly3_asset_sparkasse_main")
        if not ent.exists():
            ent.add(
                state=0.0,
                attributes= 
                    "native_value": 0.0,
                    "native_unit_of_measurement": "EUR",
                    "state_class": "measurement",
                    "device_class": "monetary",
                    "current_balance_date": datetime.now(),
                 )
        r = requests.get(
            firefly_url + "/api/v1/accounts?type=asset",
            headers= 
                "Authorization": "Bearer " + app_token,
                "Accept": "application/vnd.api+json",
                "Content-Type": "application/json",
         )
        data = r.json()
        for account in data["data"]:
            if not "attributes" in account or "name" not in account["attributes"]:
                continue
            if account["attributes"]["name"] != "Sparkasse giro":
                continue
            self.log("Account :" + str(account["attributes"]))
            ent.set_state(
                state=account["attributes"]["current_balance"],
                attributes= 
                    "native_value": account["attributes"]["current_balance"],
                    "current_balance_date": datetime.fromisoformat(account["attributes"]["current_balance_date"]),
                 )
            self.log("Entity updated")
It uses a URL and personal access token to access Firefly III API, gets the asset accounts information, then extracts info about current balance and balance date of my main account and then creates and/or updates a "sensor" value into Home Assistant. This sensor is with metadata marked as a monetary value and as a measurement. This makes Home Assistant track this value in the database as a graphable changing value. I modified the file using the File Editor addon to edit the /config/appdaemon/apps/hello.py file. Each time the file is saved it is reloaded and logs can be seen in the AppDaemon Logs section - main_log for logging messages or error_log if there is a crash. Useful to know that requests library is included, but it hard to see in the docks what else is included or if there is an easy way to install extra Python packages. This is already a very nice basis for custom value insertion into Home Assistant - whatever you can with a Python script extract or calculate, you can also inject into Home Assistant. With even this simple approach you can monitor balances, budgets, piggy-banks, bill payment status and even sum of transactions in particular catories in a particular time window. Especially interesting data can be found in the insight section of the Firefly III API. The script above uses a trigger like self.run_every(self.set_asset, "now", 60 * 60) to simply run once per hour. The data in Firefly will not be updated too often anyway, at least not until we figure out how to make bank connection run automatically without user interaction and not screw up already existing transactions along the way. In theory a webhook API of the Firefly III could be used to trigger the data update instantly when any transaction is created or updated. Possibly even using Home Assistant webhook integration. Hmmm. Maybe. Who am I kiddind? I am going to make that work, for sure! :D But first - how about figuring out the future? So what I want to do? In short, I want to predict what will be the balance on my main account just before the next months salary comes in. To do this I would:
  • take the current balance of the main account
  • if this months salary is not paid out yet, then add that into the balance
  • deduct all still unpaid bills that are due between now and the target date
  • if the credit card account has not yet been reset to the main account, deduct current amount on the cards
  • if credit card account has been reset, but not from main account deducted yet, deduct the reset amount
To do that I need to use the Firefly API to read: current account info, status of all bills including next due date and amount, transfer transactions between credit cards and main account and something that would store the expected salary date and amount. Ideally I'd use a recurring transaction or a income bill for this, but Firefly is not really cooperating with that. The easiest would be just to hardcode that in the script itself. And this is what I have come up with so far. To make the development process easier, I separated put the params for the API key and salary info and app params for the month to predict for, and predict both this and next months balances at the same time. I edited the script locally with Neovim and also ran it locally with a few mocks, uploading to Home Assistant via the SSH addon when the local executions looked good. So what's next? Well, need to somewhat automate the sync with the bank (if at all possible). And for sure take a regular database and config backup :D

Valhalla's Things: Forgotten Yeast Bread or Pan Sbagliato

Posted on October 29, 2023
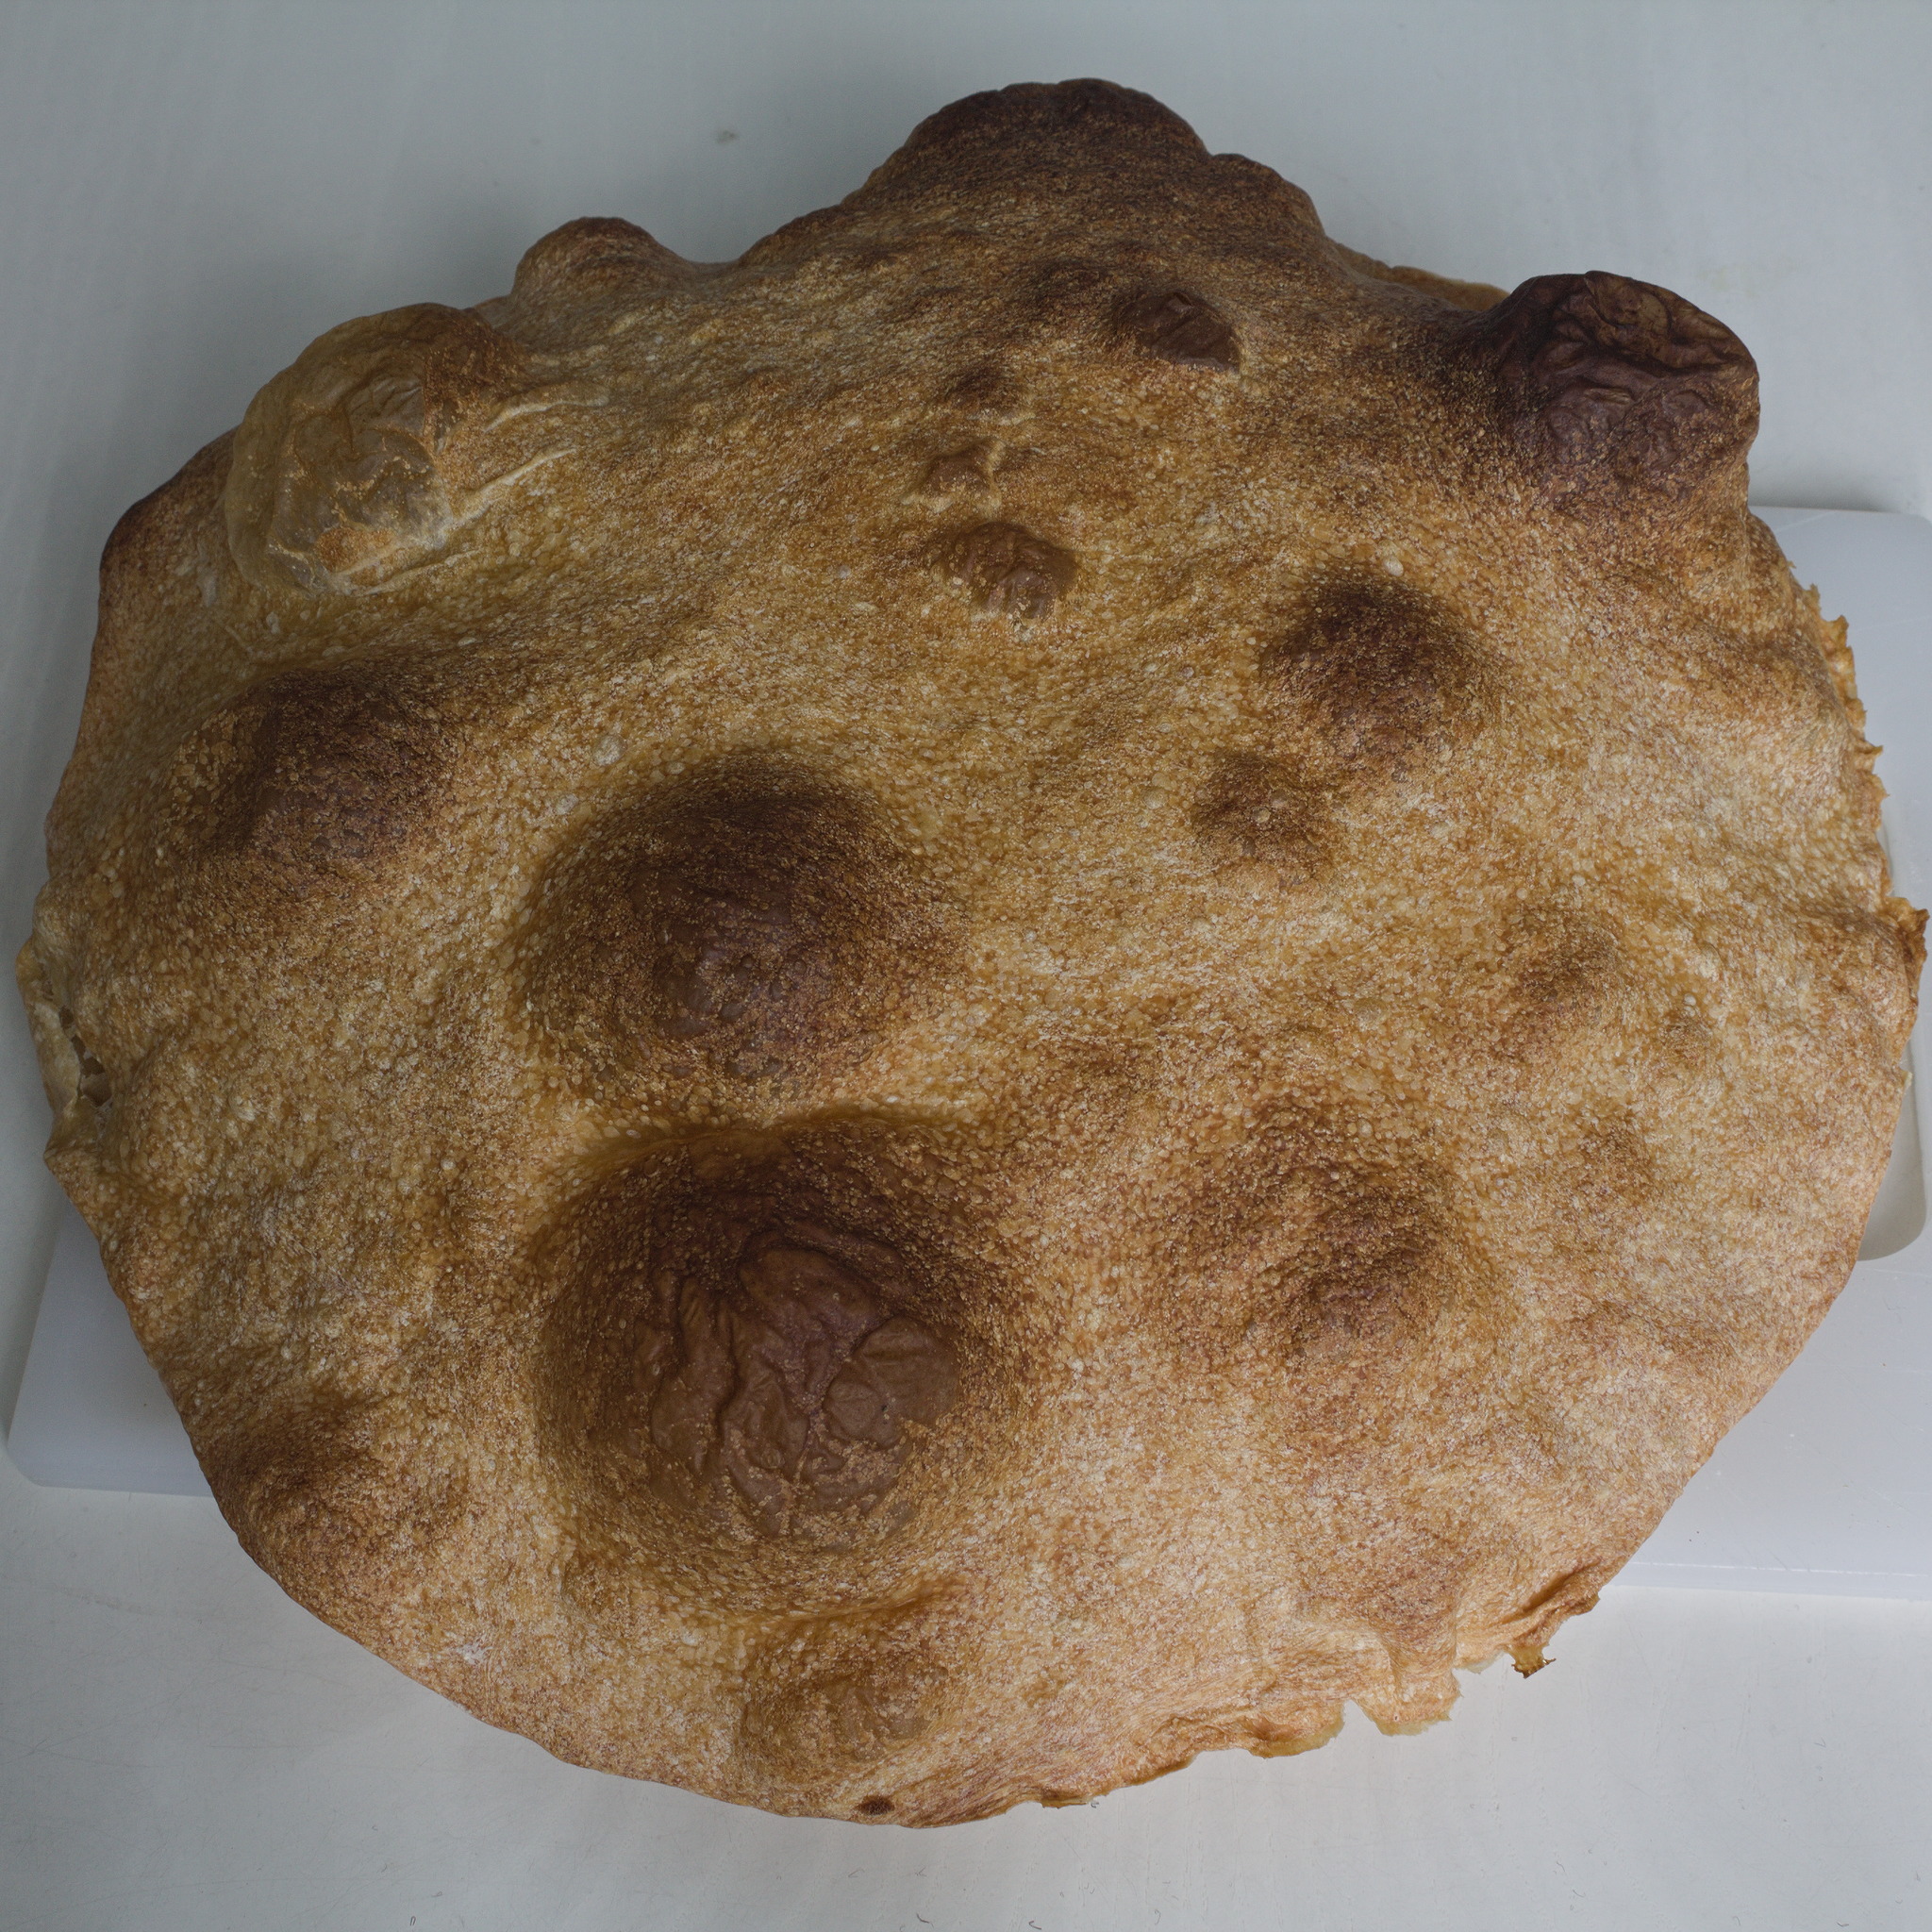
a wide and flat round loaf of bread with a well cooked crust I ve made it again. And again. And a few more times, and now it has an official household name, Pan Sbagliato , or Wrong Bread . And this is the procedure I ve mostly settled on; starting on the day before (here called Saturday) and baking it so that it s ready for lunch time (on what here is called Sunday). Saturday: around 13:00
In a bowl, mix together and work well:
  • 250 g water;
  • 400 g flour;
  • 8 g salt;
cover to rise.
Saturday: around 18:00
In a small bowl, mix together:
  • 2-3 g yeast;
  • 10 g water;
  • 10 g flour.
Saturday: around 21:00
In the bowl with the original dough, add the contents of the small bowl plus:
  • 100 g flour;
  • 100 g water;
and work well; cover to rise overnight.
Sunday: around 8:00
Pour the dough on a lined oven tray, leave in the cold oven to rise.
Sunday: around 11:00
Remove the tray from the oven, preheat the oven to 240 C, bake for 10 minutes, then lower the temperature to 160 C and bake for 20 more minutes. Waiting until it has cooled down a bit will make it easier to cut, but is not strictly necessary.
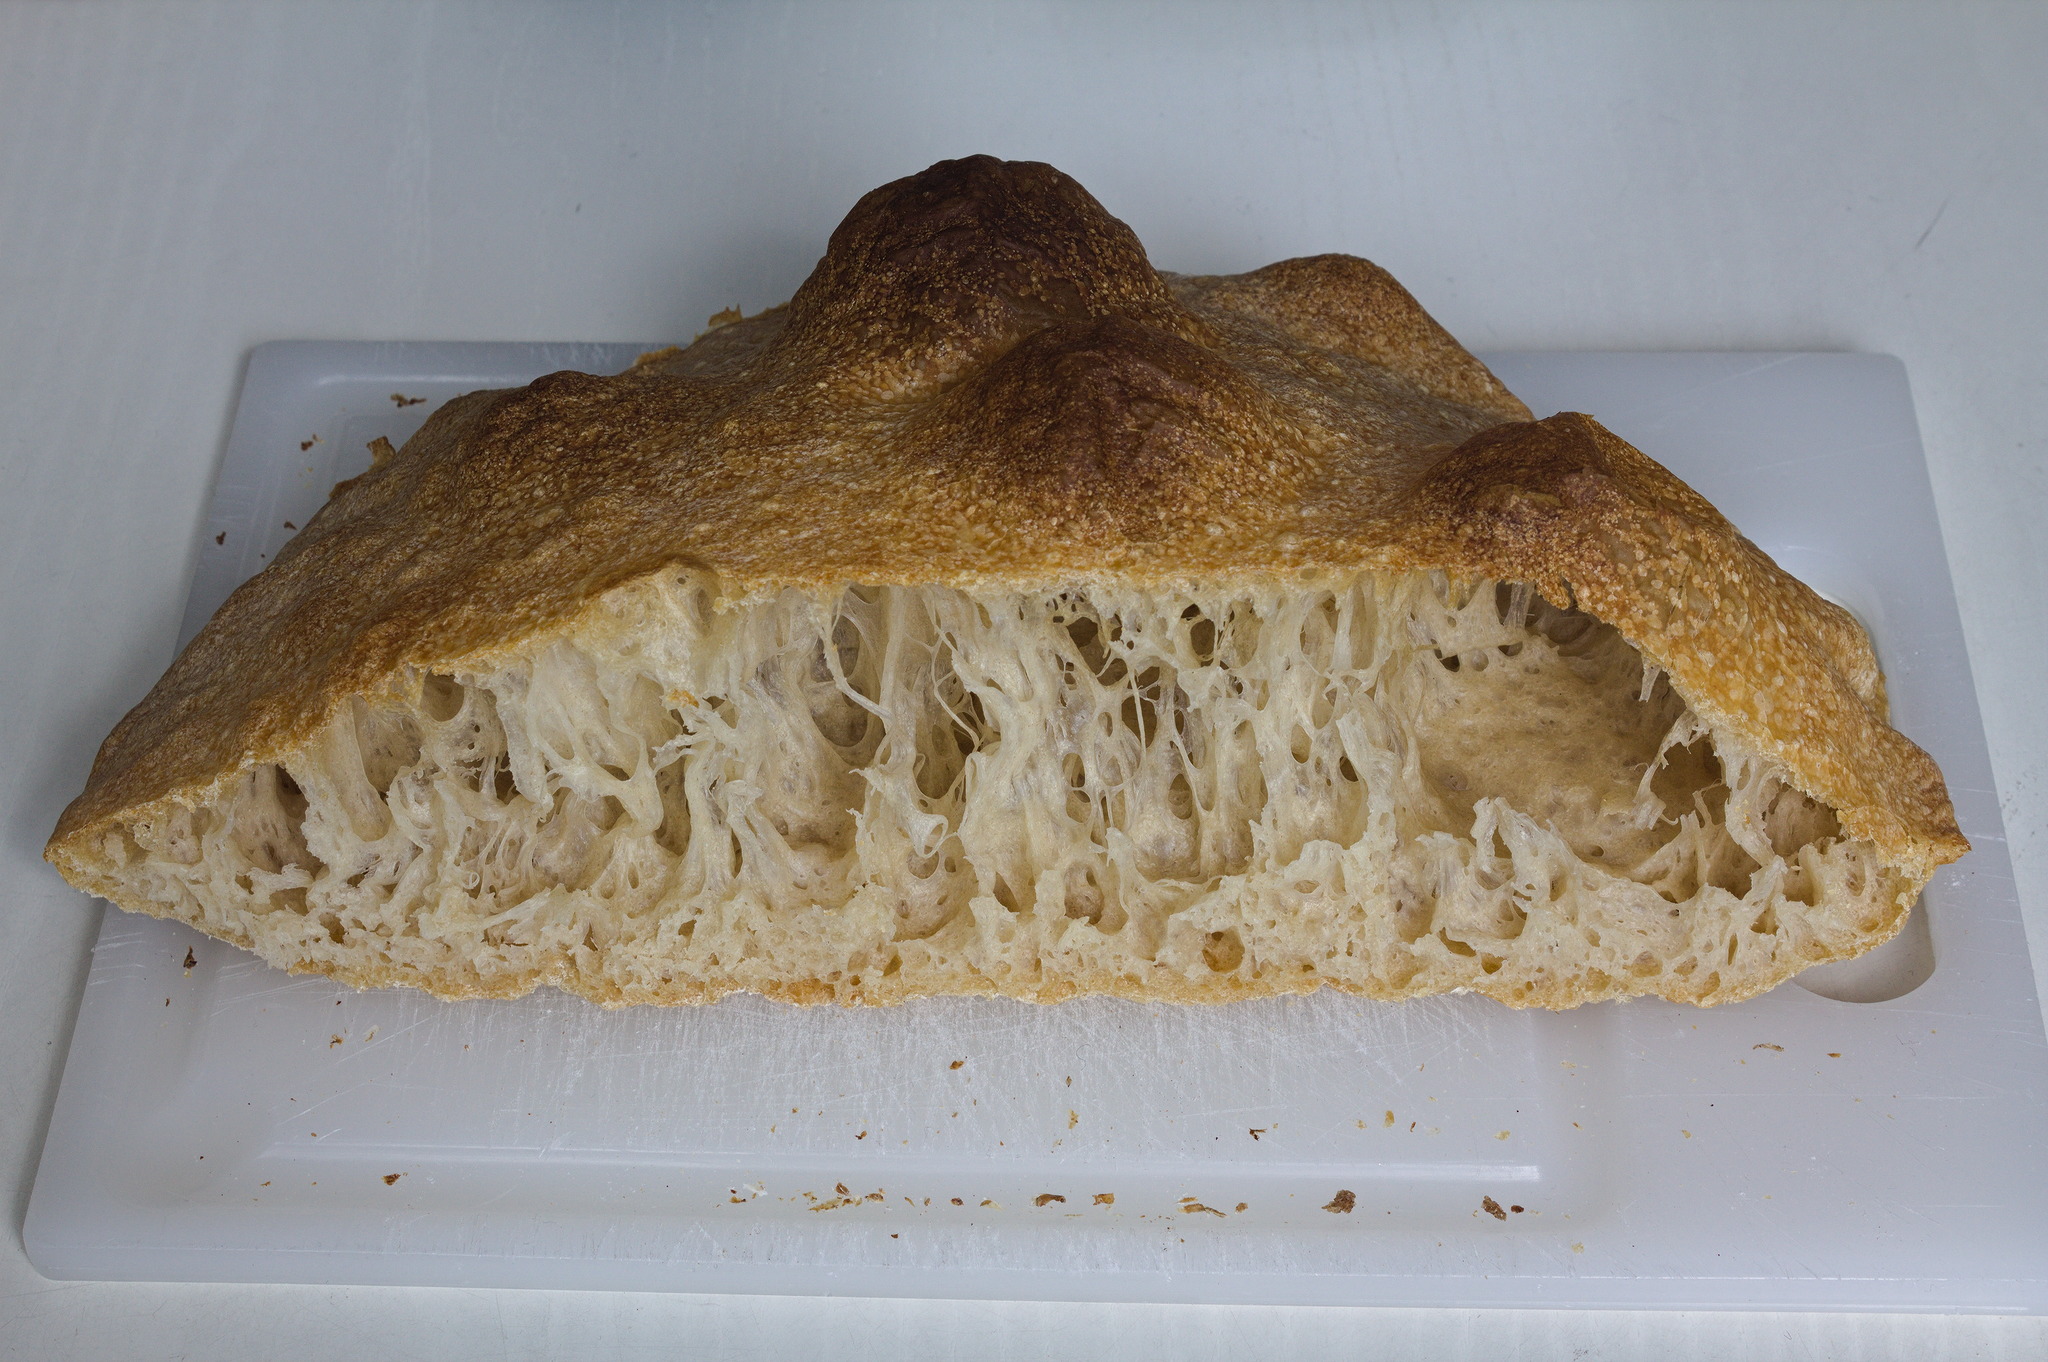
the loaf cut in half, to show thin stripes of crumb from the high hydration. I ve had up to a couple of hours variations in the times listed, with no ill effects.
26 October 2023

Dima Kogan: Talking to ROS from outside a LAN

The problem
This is about ROS version 1. Version 2 is different, and maybe they fixed stuff. But I kinda doubt it since this thing is heinous in a million ways. Alright so let's say we have have some machines in a LAN doing ROS stuff and we have another machine outside the LAN that wants to listen in (like to get a realtime visualization, say). This is an extremely common scenario, but they created enough hoops to make this not work. Let's say we have 3 computers:
  • router: the bridge between the two networks. This has two NICs. The inner IP is 10.0.1.1 and the outer IP is 12.34.56.78
  • inner: a machine in the LAN that's doing ROS stuff. IP 10.0.1.99
  • outer: a machine outside that LAN that wants to listen in. IP 12.34.56.99
Let's say the router is doing ROS stuff. It's running the ROS master and some nodes like this:
ROS_IP=10.0.1.1 roslaunch whatever
If you omit the ROS_IP it'll pick router, which may or may not work, depending on how the DNS is set up. Here we set it to 10.0.1.1 to make it possible for the inner machine to communicate (we'll see why in a bit). An aside: ROS should use the IP by default instead of the name because the IP will work even if the DNS isn't set up. If there are multiple extant IPs, it should throw an error. But all that would be way too user-friendly. OK. So we have a ROS master on 10.0.1.1 on the default port: 11311. The inner machine can rostopic echo and all that. Great. What if I try to listen in from outer? I say
ROS_MASTER_URI=http://12.34.56.78:11311 rostopic list
This connects to the router on that port, and it works well: I get the list of available topics. Here this works because the router is the router. If inner was running the ROS master then we'd need to do a forward for port 11311. In any case, this works and we understand it. So clearly we can talk to the ROS master. Right? Wrong! Let's actually listen in on a specific topic on outer:
ROS_MASTER_URI=http://12.34.56.78:11311 rostopic echo /some/topic
This does not work. No errors are reported. It just sits there, which looks like no data is coming in on that topic. But this is a lie: it's actually broken.

The diagnosis
So this is our problem. It's a very common use case, and there are plenty of internet people asking about it, with no specific solutions. I debugged it, and the details are here. To figure out what's going on, I made a syscall log on a machine inside the LAN, where a simple rostopic echo does work:
sysdig -A proc.name=rostopic and fd.type contains ipv -s 2000
This shows us all the communication between inner running rostopic and the server. It's really chatty. It's all TCP. There are multiple connections to the router on port 11311. It also starts up multiple TCP servers on the client that listen to connections; these are likely to be broken if we were running the client on outer and a machine inside the LAN tried to talk to them; but thankfully in my limited testing nothing actually tried to talk to them. The conversations on port 11311 are really long, but here's the punchline. inner tells the router:
POST /RPC2 HTTP/1.1                                                                                                                 
Host: 10.0.1.1:11311                                                                                                          
Accept-Encoding: gzip                                                                                                               
Content-Type: text/xml                                                                                                              
User-Agent: Python-xmlrpc/3.11                                                                                                      
Content-Length: 390                                                                                                                 
<?xml version='1.0'?>
<methodCall>
<methodName>registerSubscriber</methodName>
<params>
<param>
<value><string>/rostopic_2447878_1698362157834</string></value>
</param>
<param>
<value><string>/some/topic</string></value>
</param>
<param>
<value><string>*</string></value>
</param>
<param>
<value><string>http://inner:38229/</string></value>
</param>
</params>
</methodCall>
Yes. It's laughably chatty. Then the router replies:
HTTP/1.1 200 OK
Server: BaseHTTP/0.6 Python/3.8.10
Date: Thu, 26 Oct 2023 23:15:28 GMT
Content-type: text/xml
Content-length: 342
<?xml version='1.0'?>
<methodResponse>
<params>
<param>
<value><array><data>
<value><int>1</int></value>
<value><string>Subscribed to [/some/topic]</string></value>
<value><array><data>
<value><string>http://10.0.1.1:45517/</string></value>
</data></array></value>
</param>
</params>
</methodResponse>
Then this sequence of system calls happens in the rostopic process (an excerpt from the sysdig log):
> connect fd=10(<4>) addr=10.0.1.1:45517
< connect res=-115(EINPROGRESS) tuple=10.0.1.99:47428->10.0.1.1:45517 fd=10(<4t>10.0.1.99:47428->10.0.1.1:45517)
< getsockopt res=0 fd=10(<4t>10.0.1.99:47428->10.0.1.1:45517) level=1(SOL_SOCKET) optname=4(SO_ERROR) val=0 optlen=4
So the inner client makes an outgoing TCP connection on the address given to it by the ROS master above: 10.0.1.1:45517. This IP is only accessible from within the LAN, which works fine when talking to it from inner, but would be a problem from the outside. Furthermore, some sort of single-port-forwarding scheme wouldn't fix connecting from outer either, since the port number is dynamic. To confirm what we think is happening, the sequence of syscalls when trying to rostopic echo from outer does indeed fail:
connect fd=10(<4>) addr=10.0.1.1:45517 
connect res=-115(EINPROGRESS) tuple=10.0.1.1:46204->10.0.1.1:45517 fd=10(<4t>10.0.1.1:46204->10.0.1.1:45517)
getsockopt res=0 fd=10(<4t>10.0.1.1:46204->10.0.1.1:45517) level=1(SOL_SOCKET) optname=4(SO_ERROR) val=-111(ECONNREFUSED) optlen=4
That's the breakage mechanism: the ROS master asks us to communicate on an address we can't talk to. Debugging this is easy with sysdig:
sudo sysdig -A -s 400 evt.buffer contains '"Subscribed to"' and proc.name=rostopic
This prints out all syscalls seen by the rostopic command that contain the string Subscribed to, so you can see that different addresses the ROS master gives us in response to different commands. OK. So can we get the ROS master to give us an address that we can actually talk to? Sorta. Remember that we invoked the master with
ROS_IP=10.0.1.1 roslaunch whatever
The ROS_IP environment variable is exactly the address that the master gives out. So in this case, we can fix it by doing this instead:
ROS_IP=12.34.56.78 roslaunch whatever
Then the outer machine will be asked to talk to 12.34.56.78:45517, which works. Unfortunately, if we do that, then the inner machine won't be able to communicate. So some sort of ssh port forward cannot fix this: we need a lower-level tunnel, like a VPN or something. And another rant. Here rostopic tried to connect to an unreachable address, which failed. But rostopic knows the connection failed! It should throw an error message to the user. Something like this would be wonderful:
ERROR! Tried to connect to 10.0.1.1:45517 ($ROS_IP:dynamicport), but connect() returned ECONNREFUSED
That would be immensely helpful. It would tell the user that something went wrong (instead of no data being sent), and it would give a strong indication of the problem and how to fix it. But that would be asking too much.

The solution
So we need a VPN-like thing. I just tried sshuttle, and it just works. Start the ROS node in the way that makes connections from within the LAN work:
ROS_IP=10.0.1.1 roslaunch whatever
Then on the outer client:
sshuttle -r router 10.0.1.0/24
This connects to the router over ssh and does some hackery to make all connections from outer to 10.0.1.x transparently route into the LAN. On all ports. rostopic echo then works. I haven't done any thorough testing, but hopefully it's reliable and has low overhead; I don't know. I haven't tried it but almost certainly this would work even with the ROS master running on inner. This would be accomplished like this:
  1. Tell ssh how to connect to inner. Dropping this into ~/.ssh/config should do it:
    Host inner
    HostName 10.0.1.99
    ProxyJump router
    
  2. Do the magic thing:
    sshuttle -r inner 10.0.1.0/24
    
I'm sure any other VPN-like thing would work also.

25 October 2023

Russ Allbery: Review: Going Infinite

Review: Going Infinite, by Michael Lewis
Publisher: W.W. Norton & Company
Copyright: 2023
ISBN: 1-324-07434-5
Format: Kindle
Pages: 255
My first reaction when I heard that Michael Lewis had been embedded with Sam Bankman-Fried working on a book when Bankman-Fried's cryptocurrency exchange FTX collapsed into bankruptcy after losing billions of dollars of customer deposits was "holy shit, why would you talk to Michael Lewis about your dodgy cryptocurrency company?" Followed immediately by "I have to read this book." This is that book. I wasn't sure how Lewis would approach this topic. His normal (although not exclusive) area of interest is financial systems and crises, and there is lots of room for multiple books about cryptocurrency fiascoes using someone like Bankman-Fried as a pivot. But Going Infinite is not like The Big Short or Lewis's other financial industry books. It's a nearly straight biography of Sam Bankman-Fried, with just enough context for the reader to follow his life. To understand what you're getting in Going Infinite, I think it's important to understand what sort of book Lewis likes to write. Lewis is not exactly a reporter, although he does explain complicated things for a mass audience. He's primarily a storyteller who collects people he finds fascinating. This book was therefore never going to be like, say, Carreyrou's Bad Blood or Isaac's Super Pumped. Lewis's interest is not in a forensic account of how FTX or Alameda Research were structured. His interest is in what makes Sam Bankman-Fried tick, what's going on inside his head. That's not a question Lewis directly answers, though. Instead, he shows you Bankman-Fried as Lewis saw him and was able to reconstruct from interviews and sources and lets you draw your own conclusions. Boy did I ever draw a lot of conclusions, most of which were highly unflattering. However, one conclusion I didn't draw, and had been dubious about even before reading this book, was that Sam Bankman-Fried was some sort of criminal mastermind who intentionally plotted to steal customer money. Lewis clearly doesn't believe this is the case, and with the caveat that my study of the evidence outside of this book has been spotty and intermittent, I think Lewis has the better of the argument. I am utterly fascinated by this, and I'm afraid this review is going to turn into a long summary of my take on the argument, so here's the capsule review before you get bored and wander off: This is a highly entertaining book written by an excellent storyteller. I am also inclined to believe most of it is true, but given that I'm not on the jury, I'm not that invested in whether Lewis is too credulous towards the explanations of the people involved. What I do know is that it's a fantastic yarn with characters who are too wild to put in fiction, and I thoroughly enjoyed it. There are a few things that everyone involved appears to agree on, and therefore I think we can take as settled. One is that Bankman-Fried, and most of the rest of FTX and Alameda Research, never clearly distinguished between customer money and all of the other money. It's not obvious that their home-grown accounting software (written entirely by one person! who never spoke to other people! in code that no one else could understand!) was even capable of clearly delineating between their piles of money. Another is that FTX and Alameda Research were thoroughly intermingled. There was no official reporting structure and possibly not even a coherent list of employees. The environment was so chaotic that lots of people, including Bankman-Fried, could have stolen millions of dollars without anyone noticing. But it was also so chaotic that they could, and did, literally misplace millions of dollars by accident, or because Bankman-Fried had problems with object permanence. Something that was previously less obvious from news coverage but that comes through very clearly in this book is that Bankman-Fried seriously struggled with normal interpersonal and societal interactions. We know from multiple sources that he was diagnosed with ADHD and depression (Lewis describes it specifically as anhedonia, the inability to feel pleasure). The ADHD in Lewis's account is quite severe and does not sound controlled, despite medication; for example, Bankman-Fried routinely played timed video games while he was having important meetings, forgot things the moment he stopped dealing with them, was constantly on his phone or seeking out some other distraction, and often stimmed (by bouncing his leg) to a degree that other people found it distracting. Perhaps more tellingly, Bankman-Fried repeatedly describes himself in diary entries and correspondence to other people (particularly Caroline Ellison, his employee and on-and-off secret girlfriend) as being devoid of empathy and unable to access his own emotions, which Lewis supports with stories from former co-workers. I'm very hesitant to diagnose someone via a book, but, at least in Lewis's account, Bankman-Fried nearly walks down the symptom list of antisocial personality disorder in his own description of himself to other people. (The one exception is around physical violence; there is nothing in this book or in any of the other reporting that I've seen to indicate that Bankman-Fried was violent or physically abusive.) One of the recurrent themes of this book is that Bankman-Fried never saw the point in following rules that didn't make sense to him or worrying about things he thought weren't important, and therefore simply didn't. By about a third of the way into this book, before FTX is even properly started, very little about its eventual downfall will seem that surprising. There was no way that Sam Bankman-Fried was going to be able to run a successful business over time. He was extremely good at probabilistic trading and spotting exploitable market inefficiencies, and extremely bad at essentially every other aspect of living in a society with other people, other than a hit-or-miss ability to charm that worked much better with large audiences than one-on-one. The real question was why anyone would ever entrust this man with millions of dollars or decide to work for him for longer than two weeks. The answer to those questions changes over the course of this story. Later on, it was timing. Sam Bankman-Fried took the techniques of high frequency trading he learned at Jane Street Capital and applied them to exploiting cryptocurrency markets at precisely the right time in the cryptocurrency bubble. There was far more money than sense, the most ruthless financial players were still too leery to get involved, and a rising tide was lifting all boats, even the ones that were piles of driftwood. When cryptocurrency inevitably collapsed, so did his businesses. In retrospect, that seems inevitable. The early answer, though, was effective altruism. A full discussion of effective altruism is beyond the scope of this review, although Lewis offers a decent introduction in the book. The short version is that a sensible and defensible desire to use stronger standards of evidence in evaluating charitable giving turned into a bizarre navel-gazing exercise in making up statistical risks to hypothetical future people and treating those made-up numbers as if they should be the bedrock of one's personal ethics. One of the people most responsible for this turn is an Oxford philosopher named Will MacAskill. Sam Bankman-Fried was already obsessed with utilitarianism, in part due to his parents' philosophical beliefs, and it was a presentation by Will MacAskill that converted him to the effective altruism variant of extreme utilitarianism. In Lewis's presentation, this was like joining a cult. The impression I came away with feels like something out of a science fiction novel: Bankman-Fried knew there was some serious gap in his thought processes where most people had empathy, was deeply troubled by this, and latched on to effective altruism as the ethical framework to plug into that hole. So much of effective altruism sounds like a con game that it's easy to think the participants are lying, but Lewis clearly believes Bankman-Fried is a true believer. He appeared to be sincerely trying to make money in order to use it to solve existential threats to society, he does not appear to be motivated by money apart from that goal, and he was following through (in bizarre and mostly ineffective ways). I find this particularly believable because effective altruism as a belief system seems designed to fit Bankman-Fried's personality and justify the things he wanted to do anyway. Effective altruism says that empathy is meaningless, emotion is meaningless, and ethical decisions should be made solely on the basis of expected value: how much return (usually in safety) does society get for your investment. Effective altruism says that all the things that Sam Bankman-Fried was bad at were useless and unimportant, so he could stop feeling bad about his apparent lack of normal human morality. The only thing that mattered was the thing that he was exceptionally good at: probabilistic reasoning under uncertainty. And, critically to the foundation of his business career, effective altruism gave him access to investors and a recruiting pool of employees, things he was entirely unsuited to acquiring the normal way. There's a ton more of this book that I haven't touched on, but this review is already quite long, so I'll leave you with one more point. I don't know how true Lewis's portrayal is in all the details. He took the approach of getting very close to most of the major players in this drama and largely believing what they said happened, supplemented by startling access to sources like Bankman-Fried's personal diary and Caroline Ellis's personal diary. (He also seems to have gotten extensive information from the personal psychiatrist of most of the people involved; I'm not sure if there's some reasonable explanation for this, but based solely on the material in this book, it seems to be a shocking breach of medical ethics.) But Lewis is a storyteller more than he's a reporter, and his bias is for telling a great story. It's entirely possible that the events related here are not entirely true, or are skewed in favor of making a better story. It's certainly true that they're not the complete story. But, that said, I think a book like this is a useful counterweight to the human tendency to believe in moral villains. This is, frustratingly, a counterweight extended almost exclusively to higher-class white people like Bankman-Fried. This is infuriating, but that doesn't make it wrong. It means we should extend that analysis to more people. Once FTX collapsed, a lot of people became very invested in the idea that Bankman-Fried was a straightforward embezzler. Either he intended from the start to steal everyone's money or, more likely, he started losing money, panicked, and stole customer money to cover the hole. Lots of people in history have done exactly that, and lots of people involved in cryptocurrency have tenuous attachments to ethics, so this is a believable story. But people are complicated, and there's also truth in the maxim that every villain is the hero of their own story. Lewis is after a less boring story than "the crook stole everyone's money," and that leads to some bias. But sometimes the less boring story is also true. Here's the thing: even if Sam Bankman-Fried never intended to take any money, he clearly did intend to mix customer money with Alameda Research funds. In Lewis's account, he never truly believed in them as separate things. He didn't care about following accounting or reporting rules; he thought they were boring nonsense that got in his way. There is obvious criminal intent here in any reading of the story, so I don't think Lewis's more complex story would let him escape prosecution. He refused to follow the rules, and as a result a lot of people lost a lot of money. I think it's a useful exercise to leave mental space for the possibility that he had far less obvious reasons for those actions than that he was a simple thief, while still enforcing the laws that he quite obviously violated. This book was great. If you like Lewis's style, this was some of the best entertainment I've read in a while. Highly recommended; if you are at all interested in this saga, I think this is a must-read. Rating: 9 out of 10

23 October 2023

Russ Allbery: Review: Going Postal

Review: Going Postal, by Terry Pratchett
Series: Discworld #33
Publisher: Harper
Copyright: October 2004
Printing: November 2014
ISBN: 0-06-233497-2
Format: Mass market
Pages: 471
Going Postal is the 33rd Discworld novel. You could probably start here if you wanted to; there are relatively few references to previous books, and the primary connection (to Feet of Clay) is fully re-explained. I suspect that's why Going Postal garnered another round of award nominations. There are arguable spoilers for Feet of Clay, however. Moist von Lipwig is a con artist. Under a wide variety of names, he's swindled and forged his way around the Disc, always confident that he can run away from or talk his way out of any trouble. As Going Postal begins, however, it appears his luck has run out. He's about to be hanged. Much to his surprise, he wakes up after his carefully performed hanging in Lord Vetinari's office, where he's offered a choice. He can either take over the Ankh-Morpork post office, or he can die. Moist, of course, immediately agrees to run the post office, and then leaves town at the earliest opportunity, only to be carried back into Vetinari's office by a relentlessly persistent golem named Mr. Pump. He apparently has a parole officer. The clacks, Discworld's telegraph system first seen in The Fifth Elephant, has taken over most communications. The city is now dotted with towers, and the Grand Trunk can take them at unprecedented speed to even far-distant cities like Genua. The post office, meanwhile, is essentially defunct, as Moist quickly discovers. There are two remaining employees, the highly eccentric Junior Postman Groat who is still Junior because no postmaster has lasted long enough to promote him, and the disturbingly intense Apprentice Postman Stanley, who collects pins. Other than them, the contents of the massive post office headquarters are a disturbing mail sorting machine designed by Bloody Stupid Johnson that is not picky about which dimension or timeline the sorted mail comes from, and undelivered mail. A lot of undelivered mail. Enough undelivered mail that there may be magical consequences. All Moist has to do is get the postal system running again. Somehow. And not die in mysterious accidents like the previous five postmasters. Going Postal is a con artist story, but it's also a startup and capitalism story. Vetinari is, as always, solving a specific problem in his inimitable indirect way. The clacks were created by engineers obsessed with machinery and encodings and maintenance, but it's been acquired by... well, let's say private equity, because that's who they are, although Discworld doesn't have that term. They immediately did what private equity always did: cut out everything that didn't extract profit, without regard for either the service or the employees. Since the clacks are an effective monopoly and the new owners are ruthless about eliminating any possible competition, there isn't much to stop them. Vetinari's chosen tool is Moist. There are some parts of this setup that I love and one part that I'm grumbly about. A lot of the fun of this book is seeing Moist pulled into the mission of resurrecting the post office despite himself. He starts out trying to wriggle out of his assigned task, but, after a few early successes and a supernatural encounter with the mail, he can't help but start to care. Reformed con men often make good protagonists because one can enjoy the charisma without disliking the ethics. Pratchett adds the delightfully sharp-witted and cynical Adora Belle Dearheart as a partial reader stand-in, which makes the process of Moist becoming worthy of his protagonist role even more fun. I think that a properly functioning postal service is one of the truly monumental achievements of human society and doesn't get nearly enough celebration (or support, or pay, or good working conditions). Give me a story about reviving a postal service by someone who appreciates the tradition and social role as much as Pratchett clearly does and I'm there. The only frustration is that Going Postal is focused more on an immediate plot, so we don't get to see the larger infrastructure recovery that is clearly needed. (Maybe in later books?) That leads to my grumble, though. Going Postal and specifically the takeover of the clacks is obviously inspired by corporate structures in the later Industrial Revolution, but this book was written in 2004, so it's also a book about private equity and startups. When Vetinari puts a con man in charge of the post office, he runs it like a startup: do lots of splashy things to draw attention, promise big and then promise even bigger, stumble across a revenue source that may or may not be sustainable, hire like mad, and hope it all works out. This makes for a great story in the same way that watching trapeze artists or tightrope walkers is entertaining. You know it's going to work because that's the sort of book you're reading, so you can enjoy the audacity and wonder how Moist will manage to stay ahead of his promises. But it is still a con game applied to a public service, and the part of me that loves the concept of the postal service couldn't stop feeling like this is part of the problem. The dilemma that Vetinari is solving is a bit too realistic, down to the requirement that the post office be self-funding and not depend on city funds and, well, this is repugnant to me. Public services aren't businesses. Societies spend money to build things that they need to maintain society, and postal service is just as much one of those things as roads are. The ability of anyone to send a letter to anyone else, no matter how rural the address is, provides infrastructure on which a lot of important societal structure is built. Pratchett made me care a great deal about Ankh-Morpork's post office (not hard to do), and now I want to see it rebuilt properly, on firm foundations, without splashy promises and without a requirement that it pay for itself. Which I realize is not the point of Discworld at all, but the concept of running a postal service like a startup hits maybe a bit too close to home. Apart from that grumble, this is a great book if you're in the mood for a reformed con man story. I thought the gold suit was a bit over the top, but I otherwise thought Moist's slow conversion to truly caring about his job was deeply satisfying. The descriptions of the clacks are full of askew Discworld parodies of computer networking and encoding that I enjoyed more than I thought I would. This is also the book that introduced the now-famous (among Pratchett fans at least) GNU instruction for the clacks, and I think that scene is the most emotionally moving bit of Pratchett outside of Night Watch. Going Postal is one of the better books in the Discworld series to this point (and I'm sadly getting near the end). If you have less strongly held opinions about management and funding models for public services, or at least are better at putting them aside when reading fantasy novels, you're likely to like it even more than I did. Recommended. Followed by Thud!. The thematic sequel is Making Money. Rating: 8 out of 10

22 October 2023

Ravi Dwivedi: Software Freedom Day at sflc.in

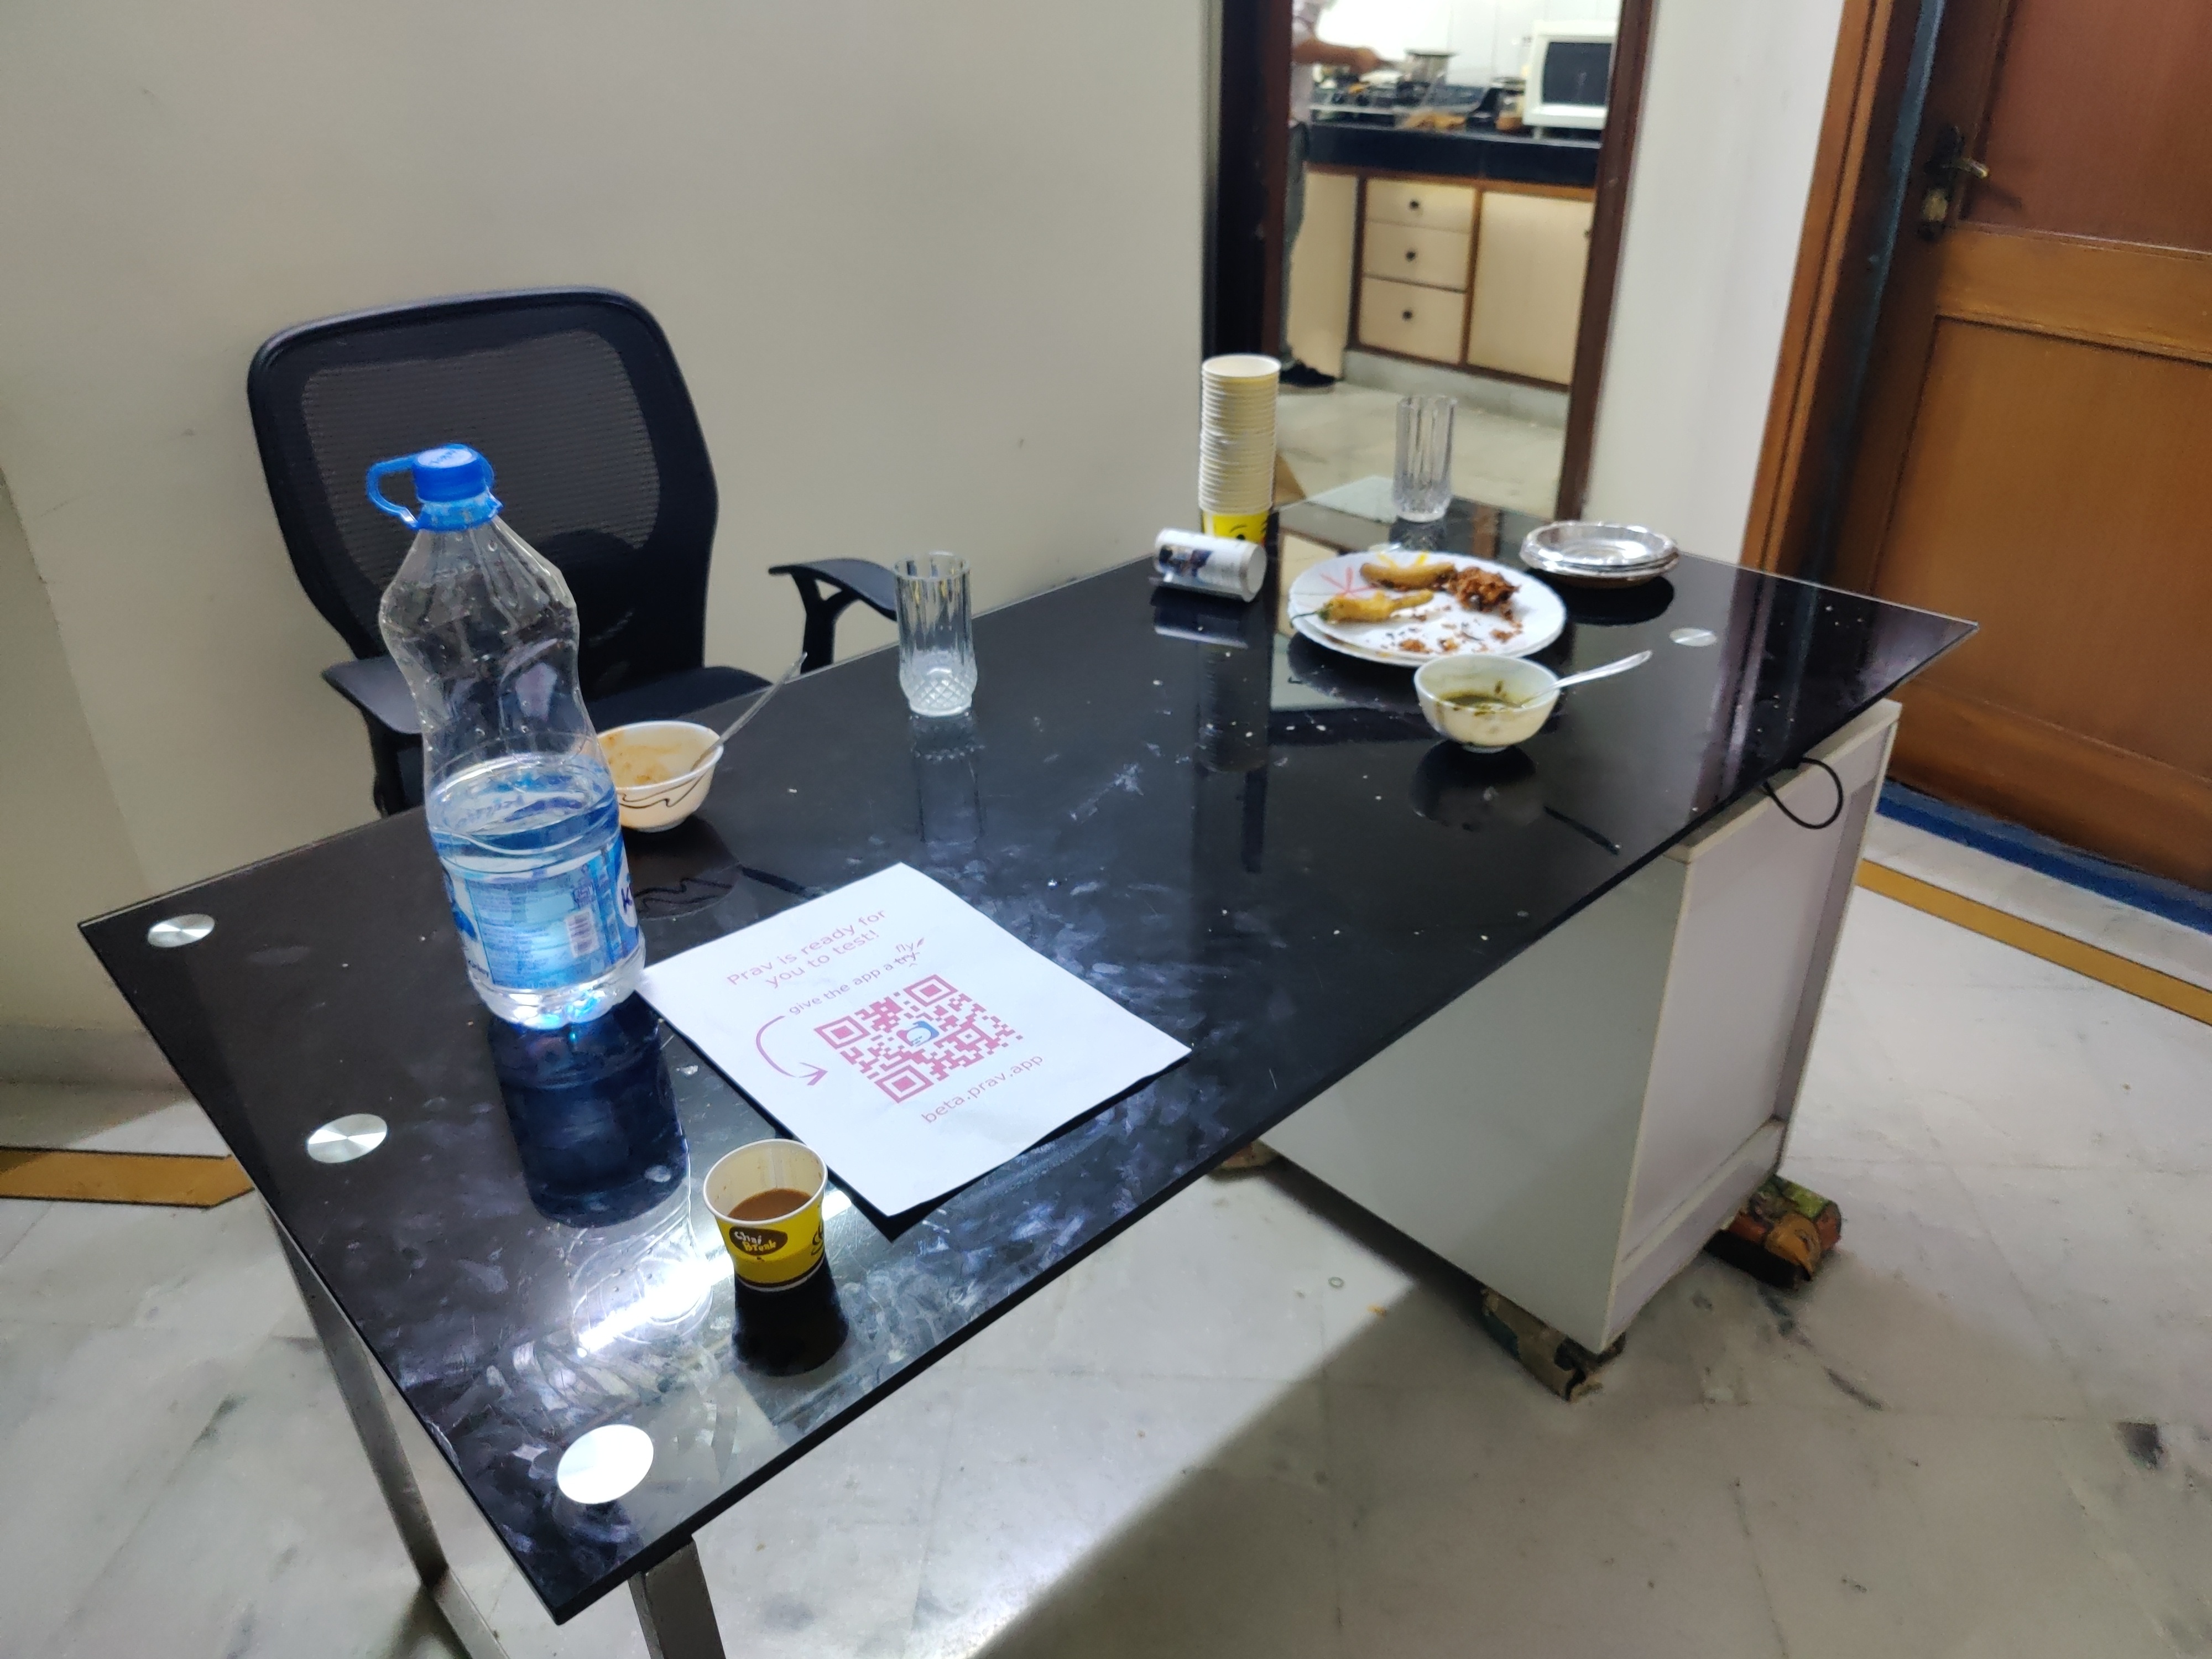
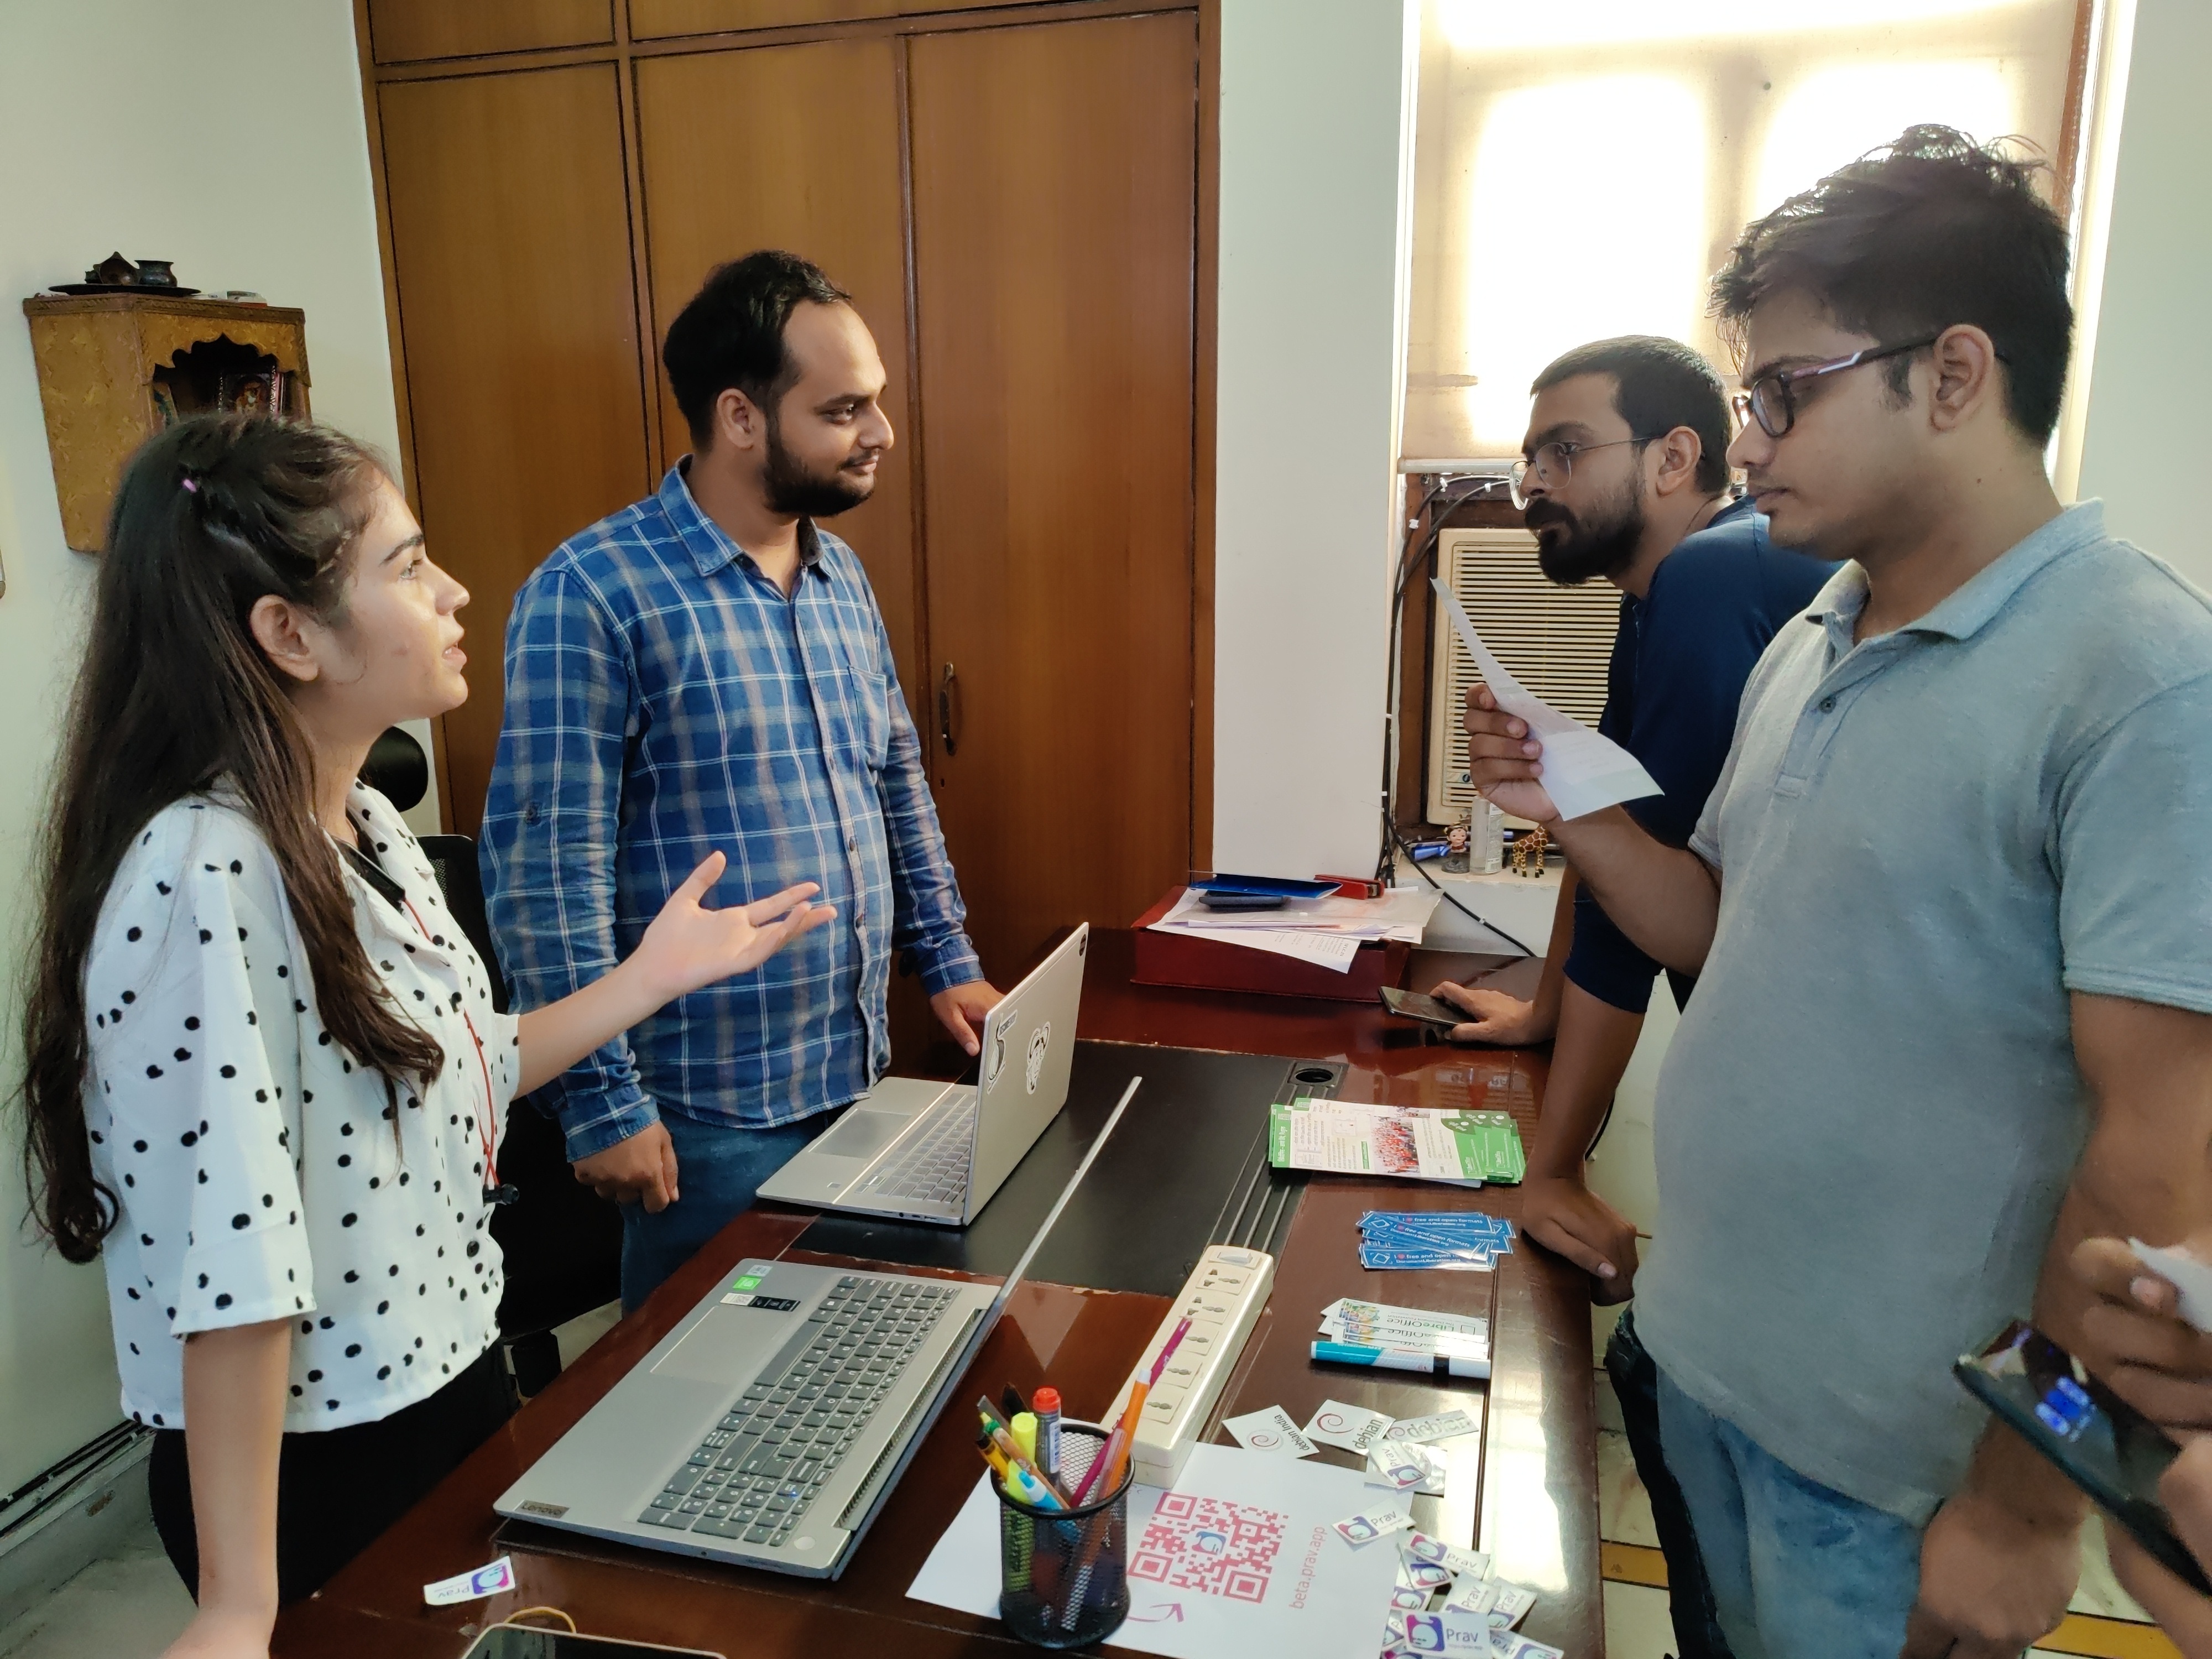
Software Freedom Law Center, India, also known as sflc.in, organized an event to celebrate the Software Freedom Day on 30th September 2023. Me, Sahil, Contrapunctus and Suresh joined. The venue was at the SFLC India office in Delhi. The sflc.in office was on the second floor of what looked like someone s apartment:). I also met Chirag, Orendra, Surbhi and others. My plan was to have a stall on LibreOffice and Prav app to raise awareness about these projects. I didn t have QR code for downloading prav app printed already, so I asked the people at sflc.in if they can get it printed for me. They were very kind and helped me in getting a color printout for me. So, I got a stall in their main room. Surbhi was having an Inkscape stall next to mine and gave me company. People came and asked about the prav project and then I realized I was still too tired to explain the idea behind the prav project and about LibreOffice (after a long Kerala trip). We got a few prav app installs during the event, which is cool.
My stall. Photo credits: Tejaswini.
Sahil had Debian stall and contrapunctus had OpenStreetMap stall. After about an hour, Revolution OS was screened for all of us to watch, along with popcorn. The documentary gave an overview of history of Free Software Movement. The office had a kitchen where fresh chai was being made and served to us. The organizers ordered a lot of good snacks for us.
Snacks and tea at the front desk. CC-BY-SA 4.0 by Ravi Dwivedi.
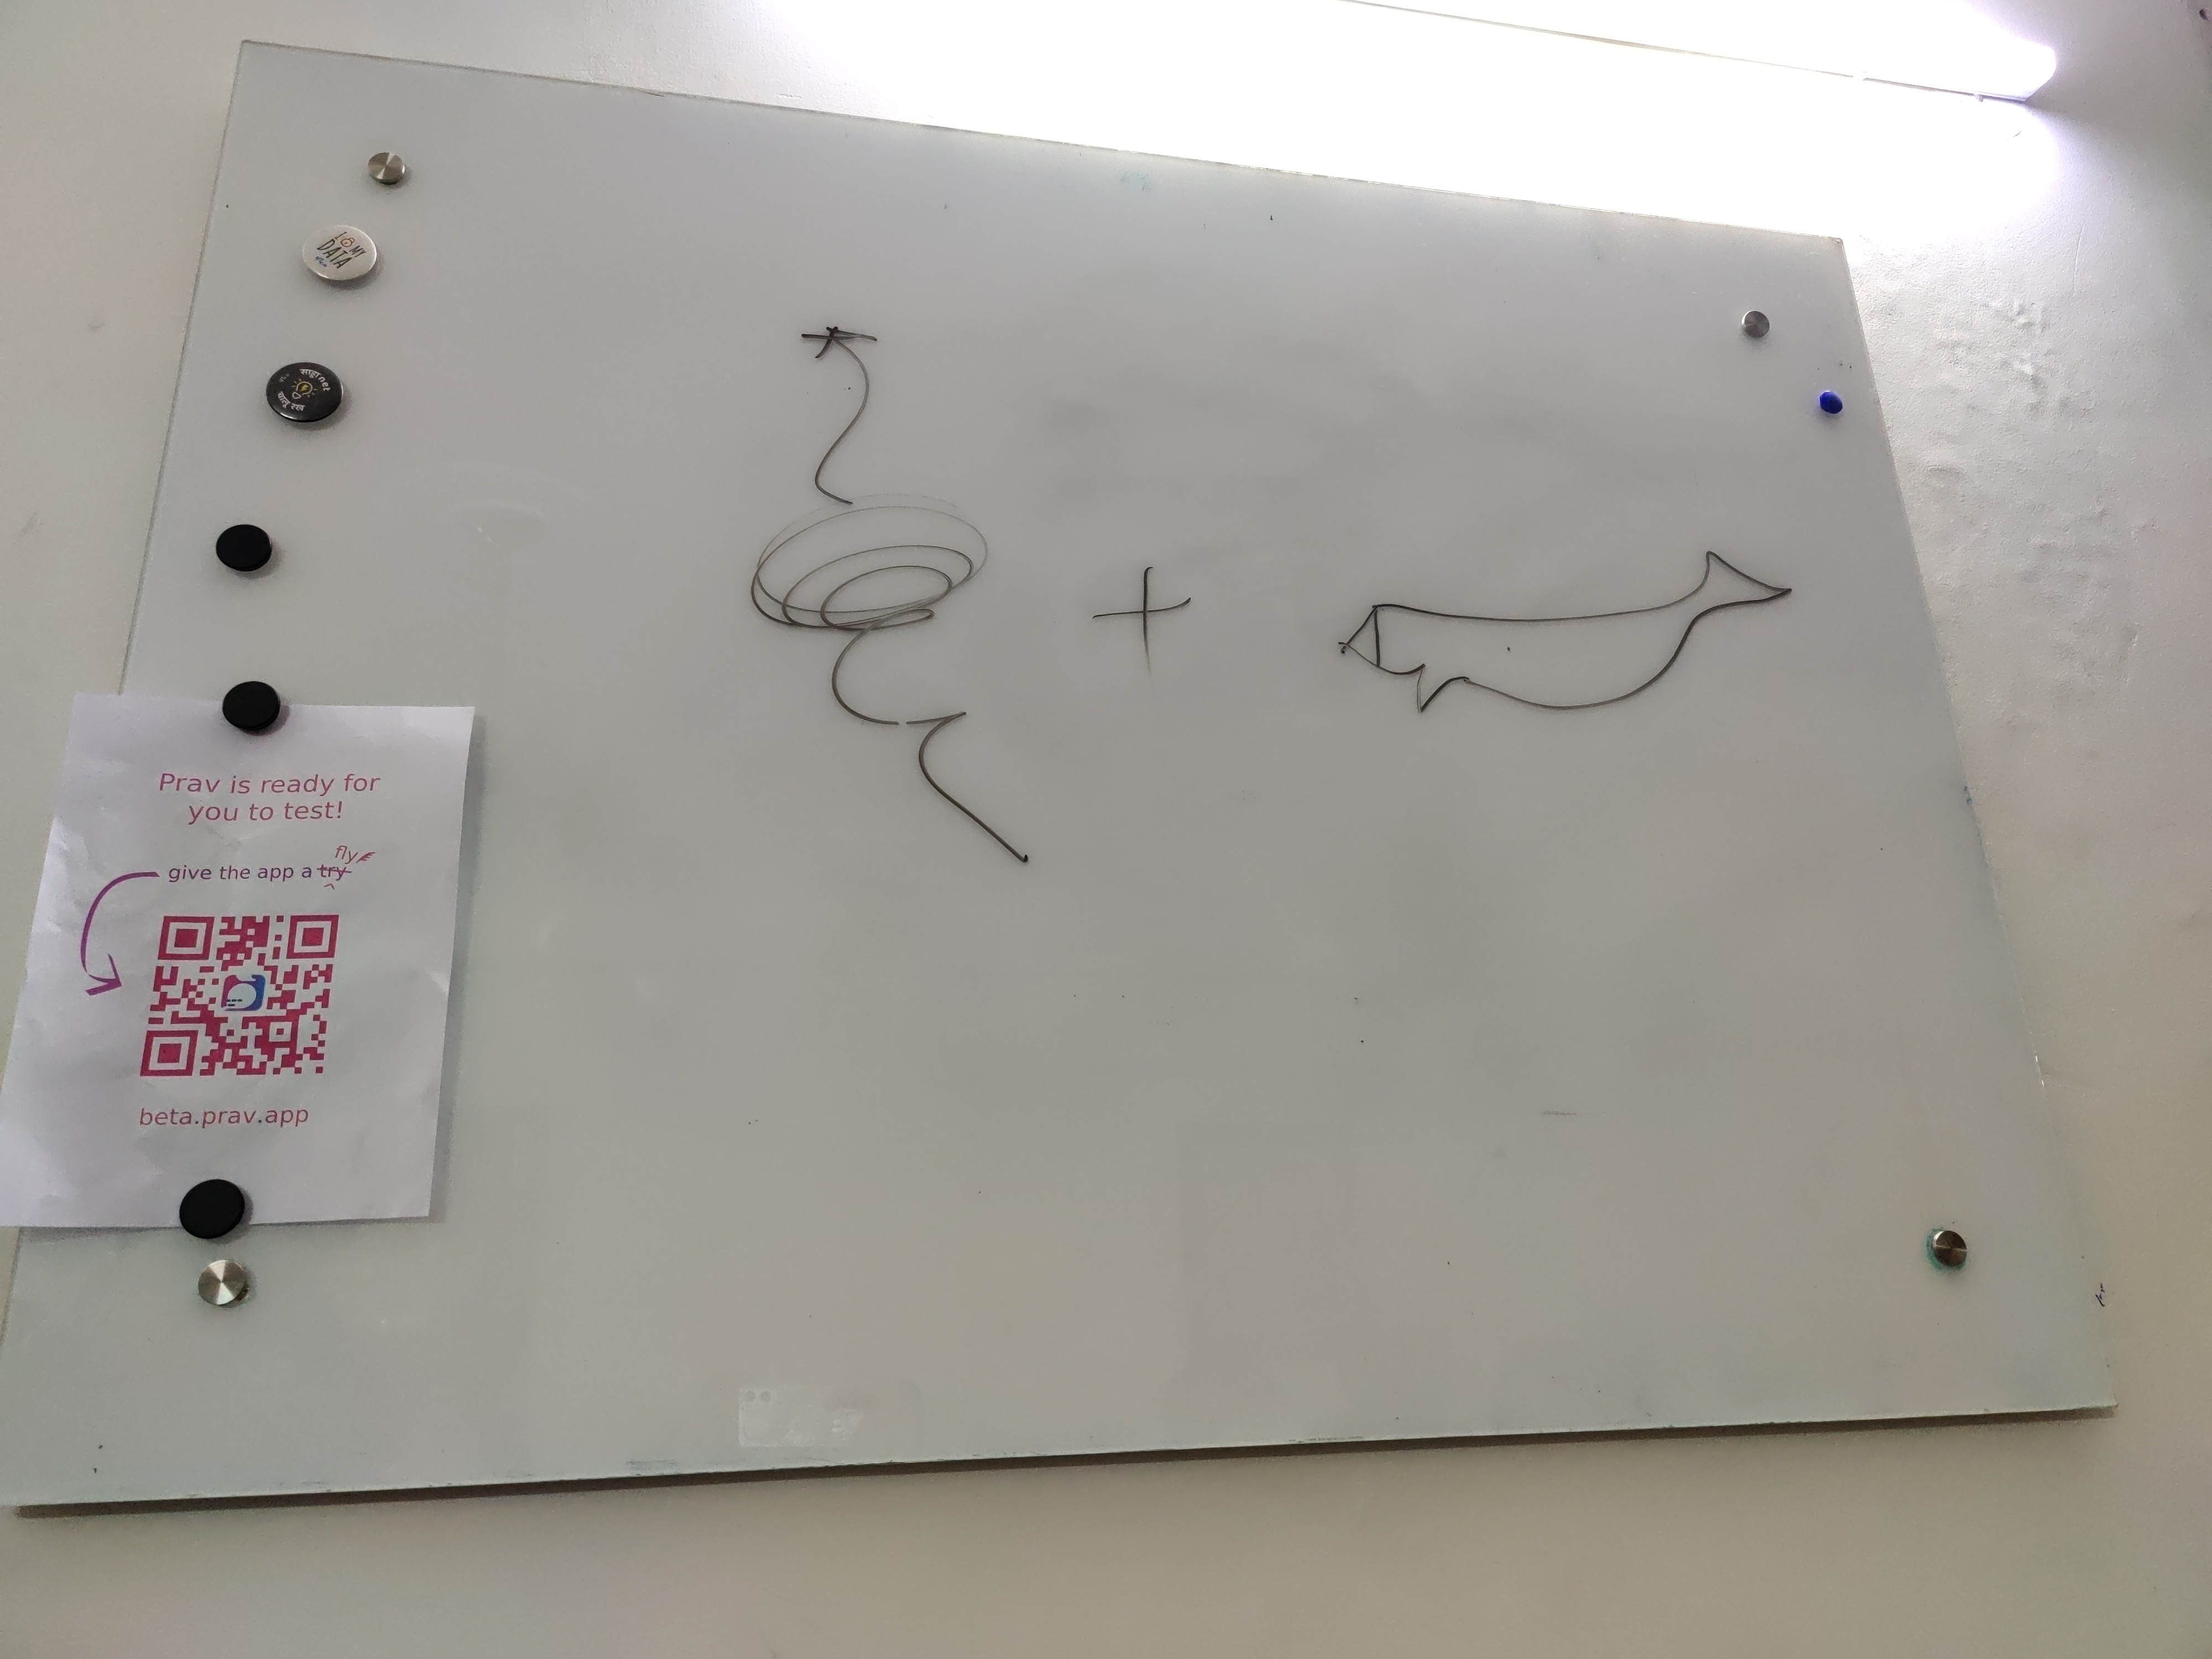
I came out of the movie hall to take more tea and snacks from the front desk. I saw a beautiful painting was hanging at the wall opposite to the front desk and Tejaswini (from sflc.in) revealed that she had made it. The tea was really good as it was freshly made in the kitchen. After the movie, we played a game of pictionary. We were divided into two teams. The game goes as follows: A person from a team is selected and given a term related to freedom respecting software written on a piece of paper, but concealed from other participants. Then that person draws something on the board (no logo, no alphabets) without speaking. If the team from which the person belongs correctly guesses the term, the team gets one step ahead on the leader board. The team who reaches the finish line wins. I recall some fun pictionaries. Like, the one in the picture below seems far from the word Wireguard and even then someone from the team guessed that word. Our team won in the end \o/.
Pictionary drawing nowhere close to the intended word Wireguard :), which was guessed. Photo by Ravi Dwivedi, CC-BY-SA 4.0.
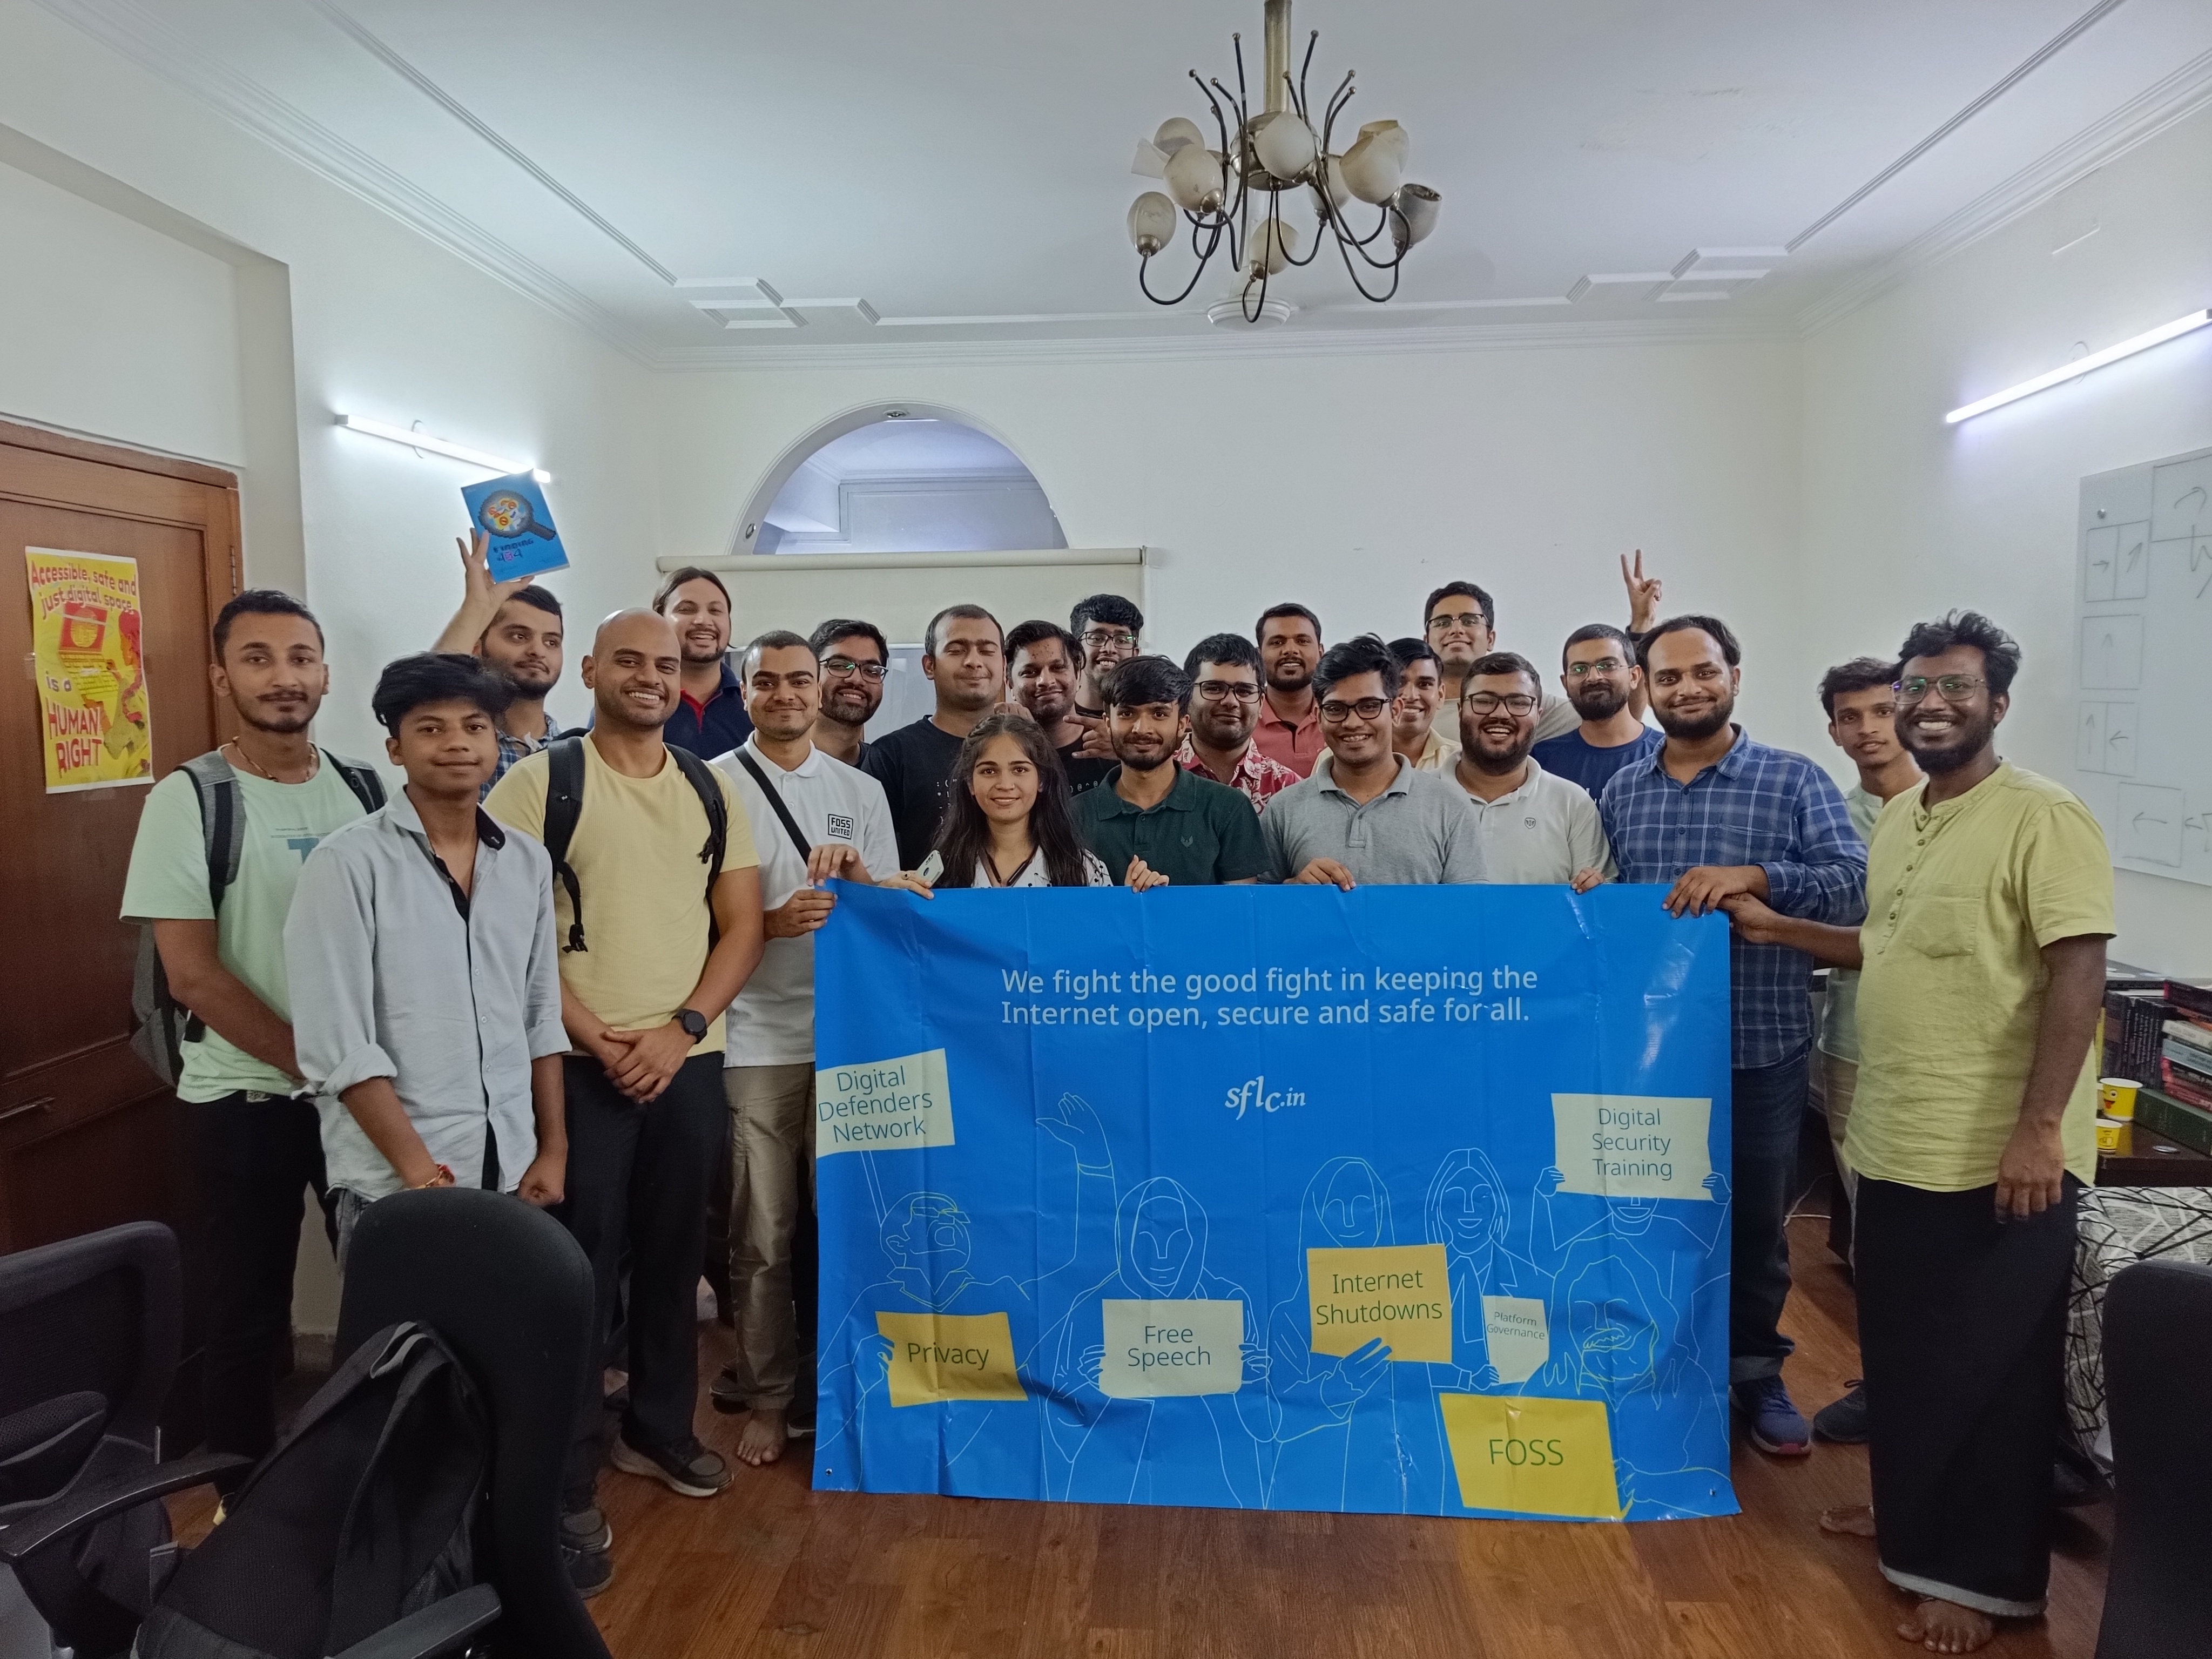
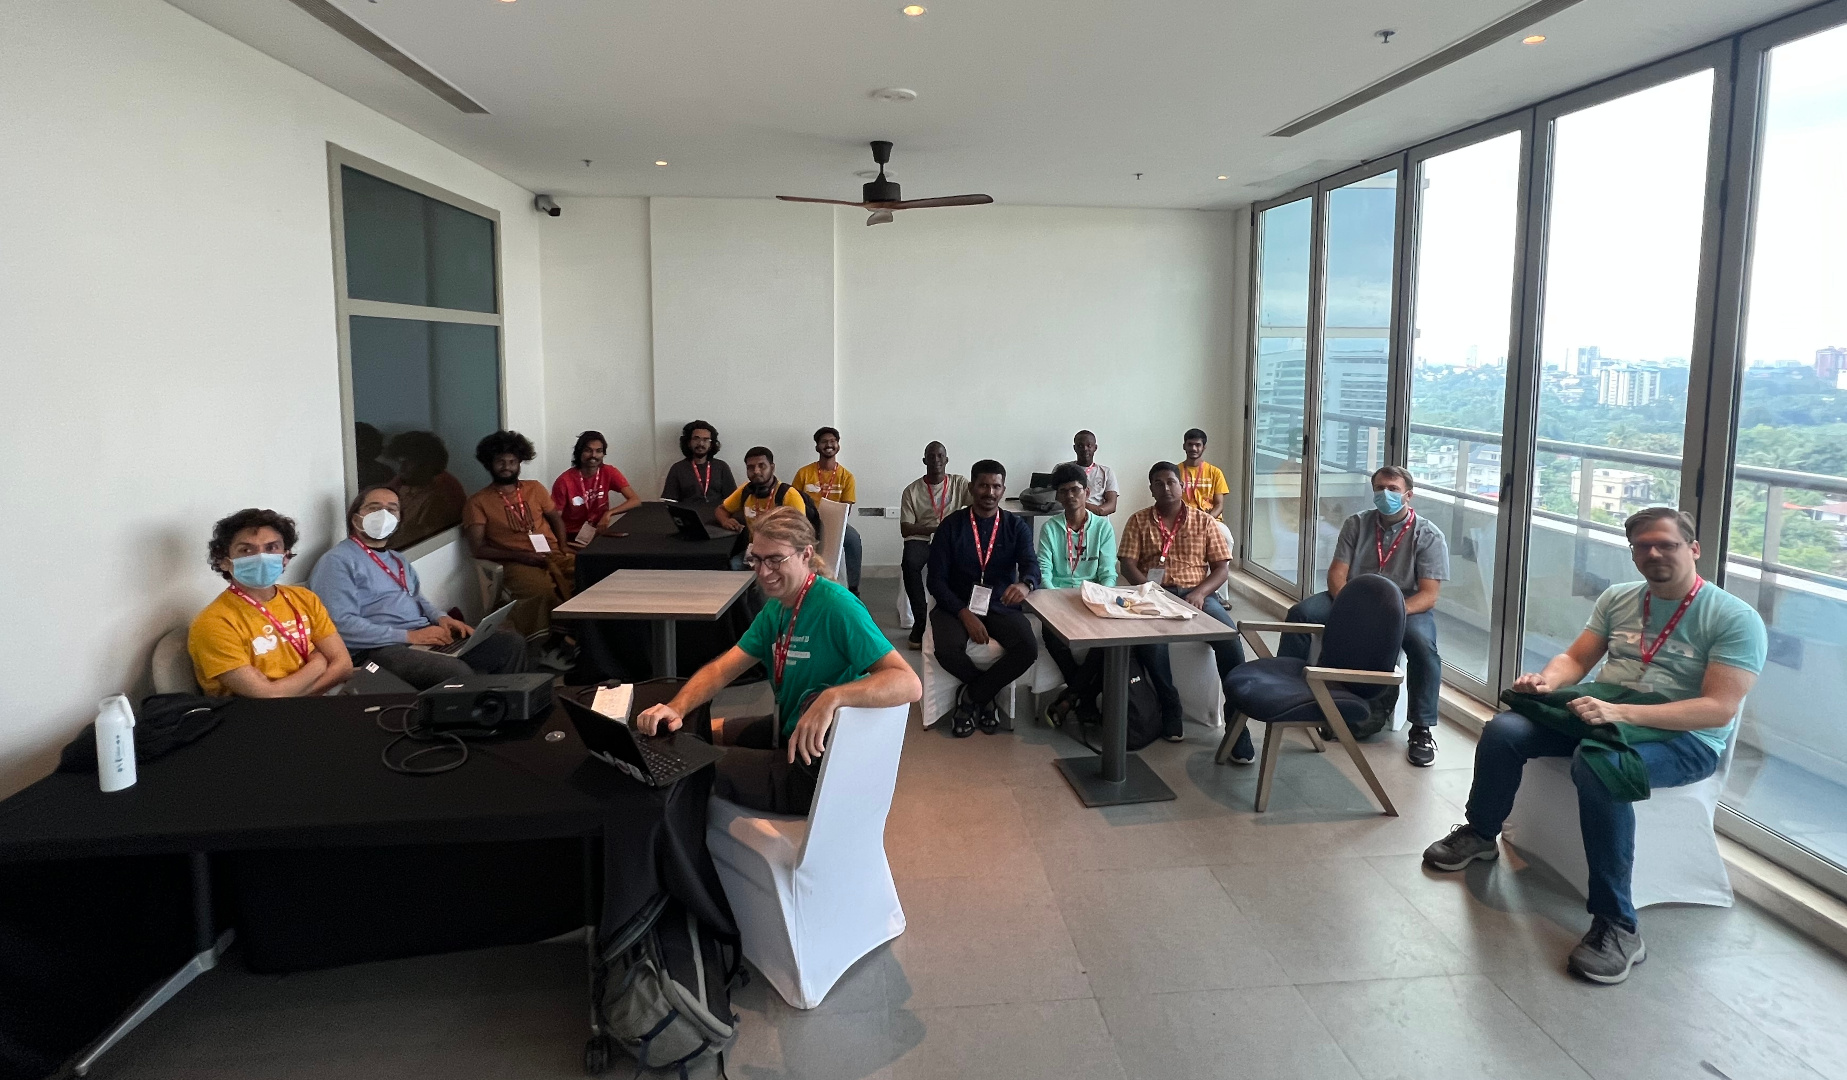
Then, we posed for a group picture. At the end, SFLC.in had a delicious cake in store for us. They had some merchandise - handbags, T-shirts, etc. which we could take if we donate some amount to SFLC.in. I bought a handbag with Ban Plastic, not Internet written on it in exchange for donation. I hope that gives people around me a powerful message :) .
Group photo. Photo credits: Tejaswini.
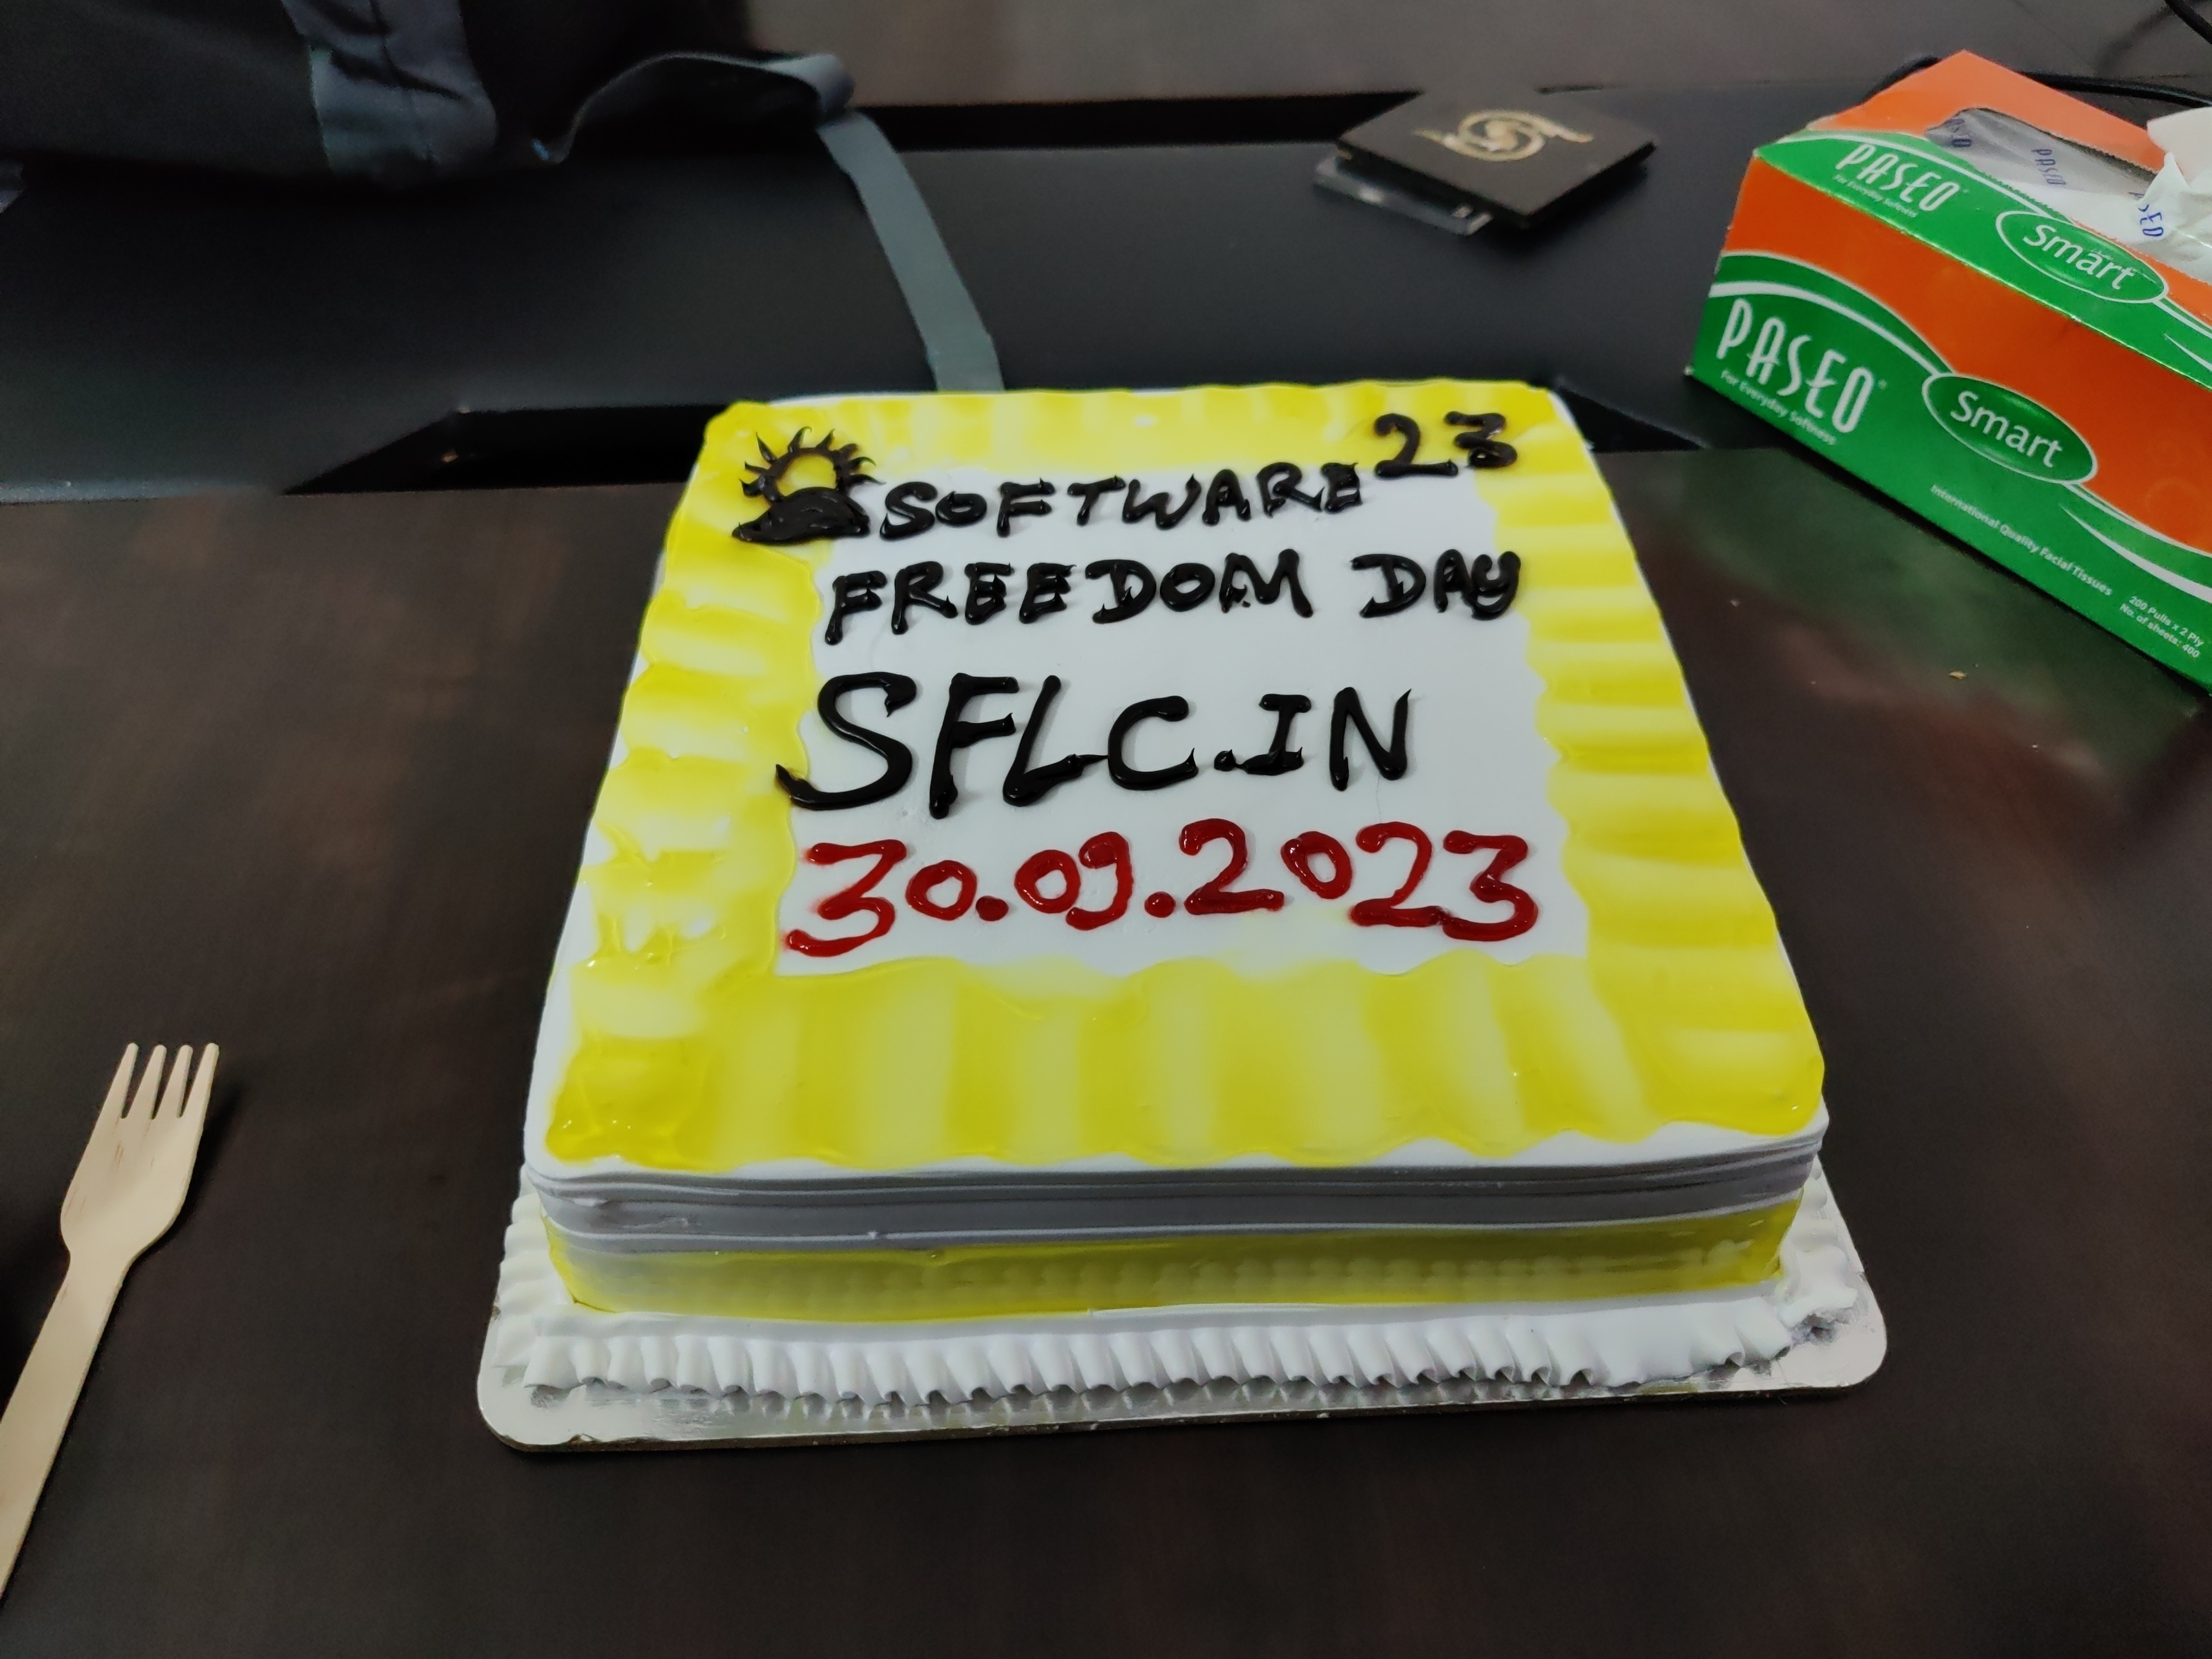
Tasty cake. CC-BY-SA 4.0 by Ravi Dwivedi.
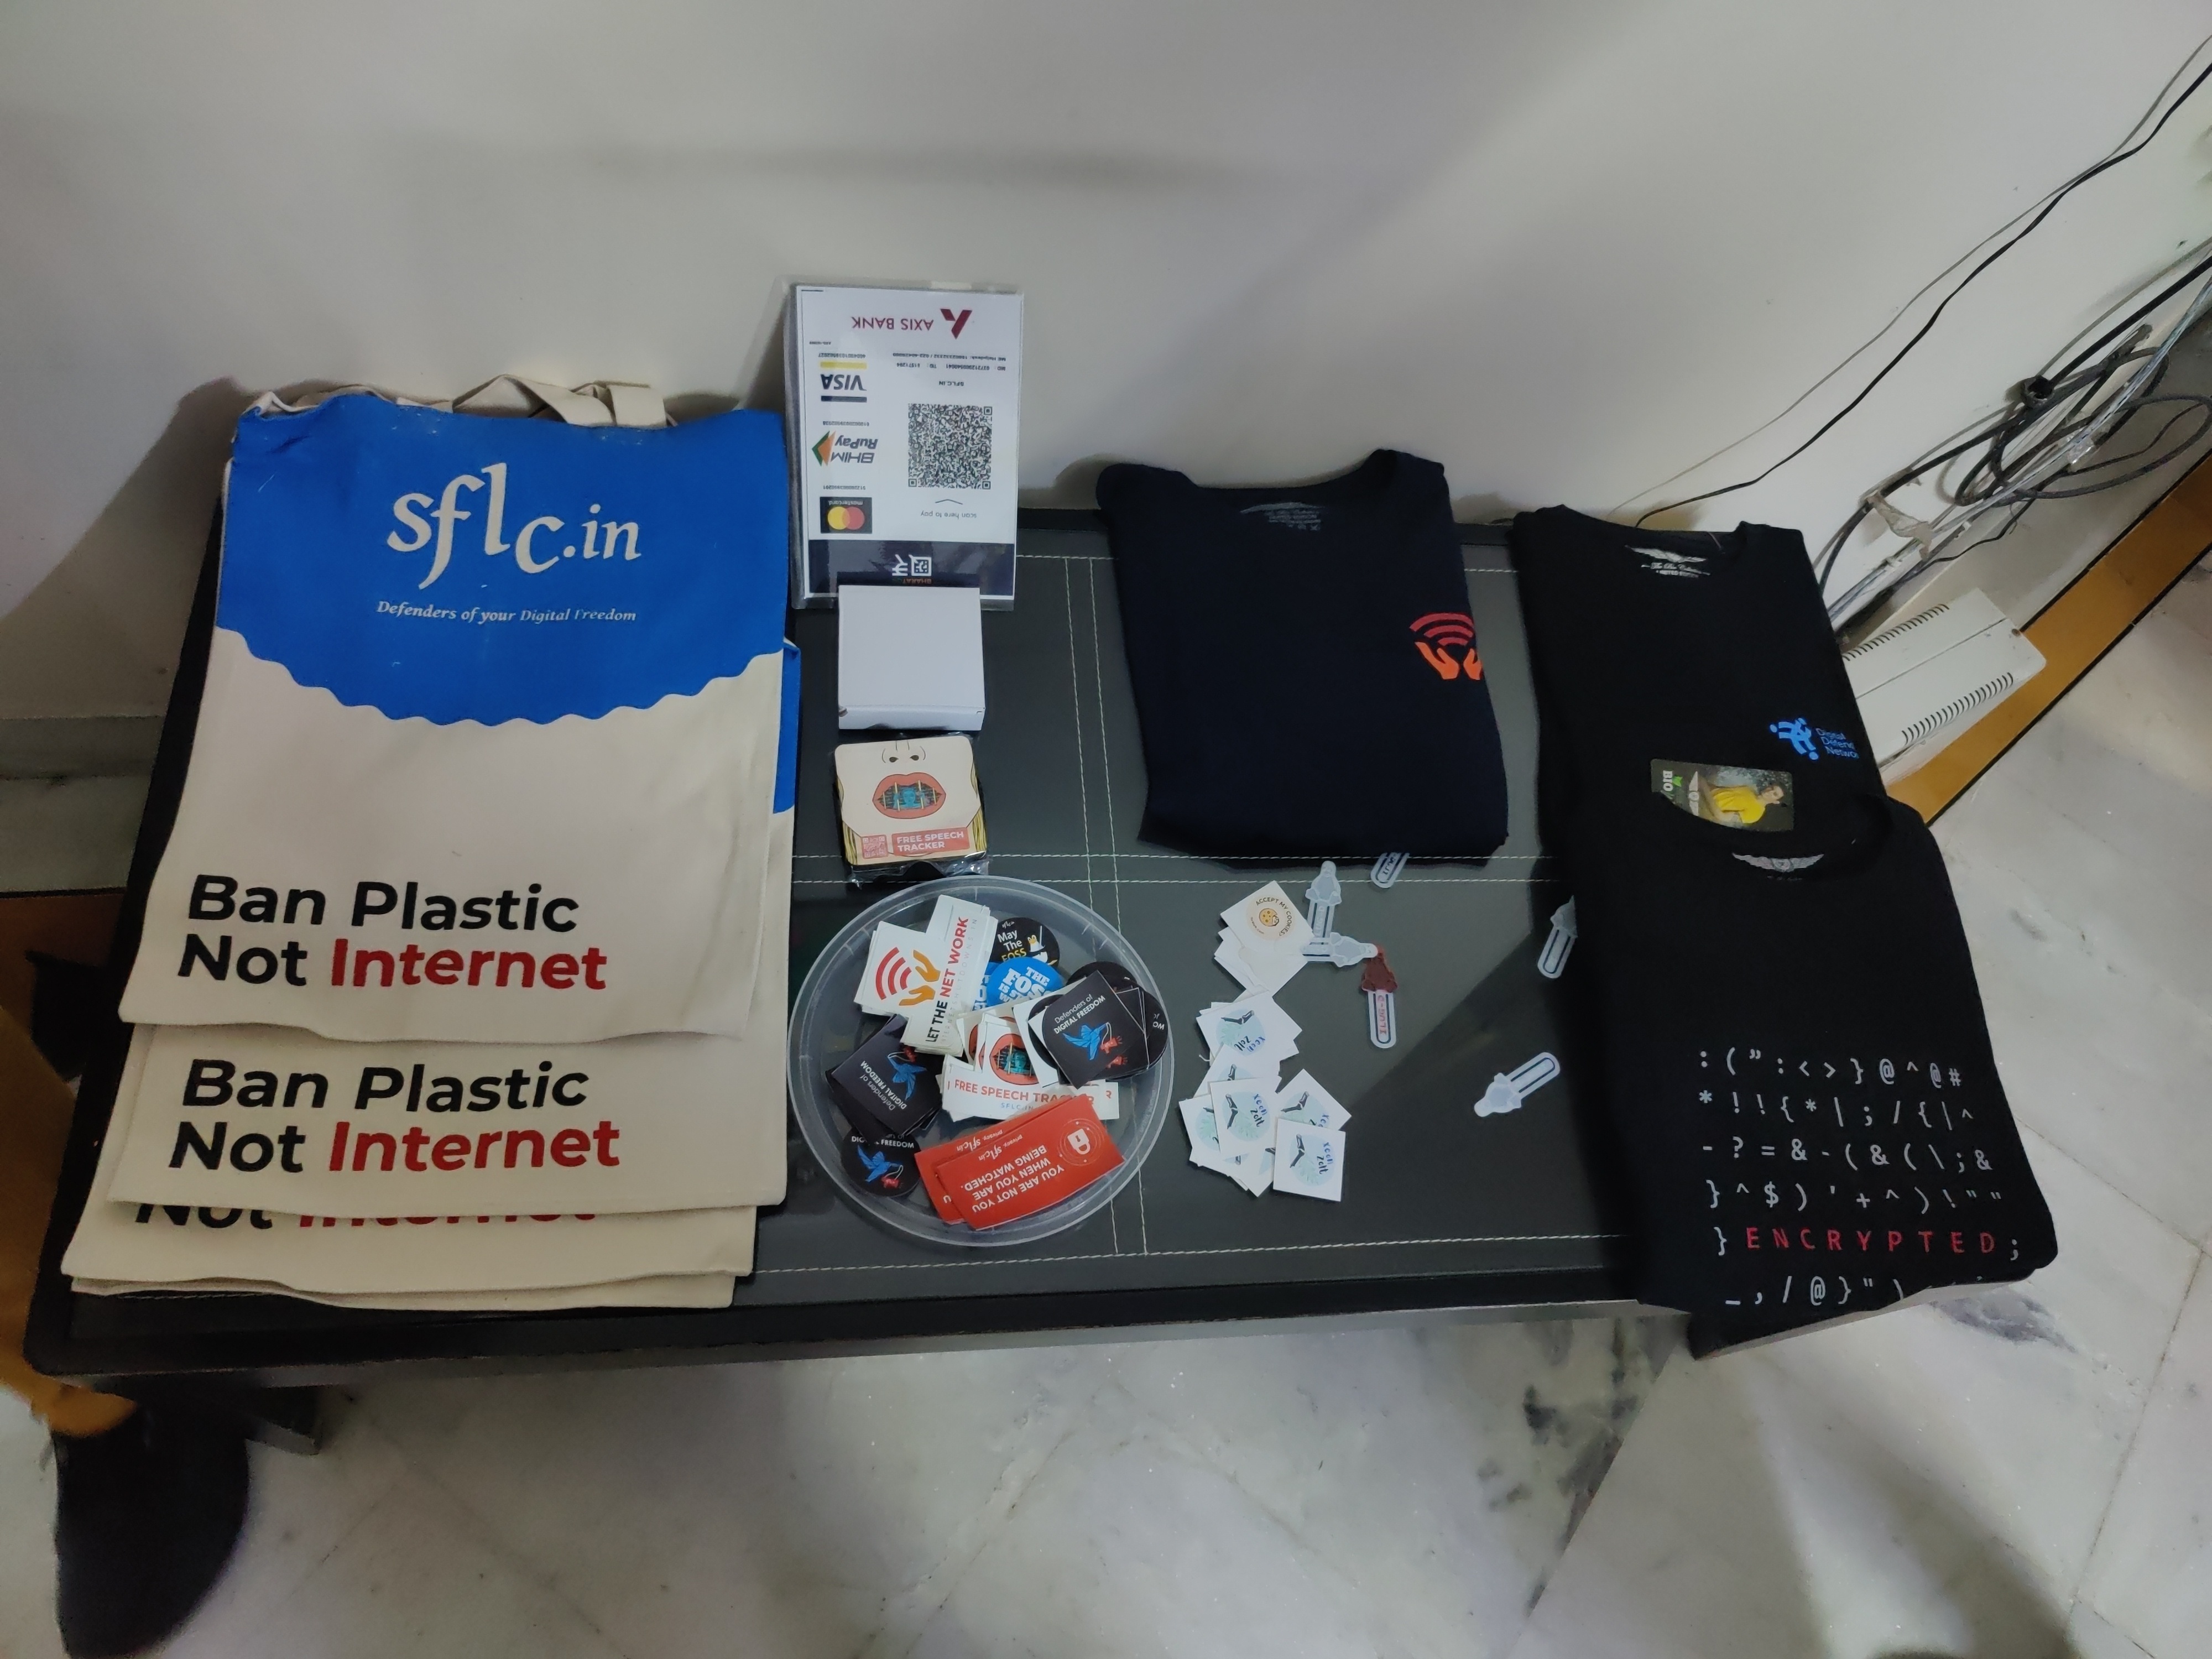
Merchandise by sflc.in. CC-BY-SA 4.0 by Ravi Dwivedi.

All in all, a nice event by sflc.in :)

Aigars Mahinovs: Figuring out finances part 3

So now that I have something that looks very much like a budgeting setup going, I am going to .. delete it! Why? Well, at the end of the last part of this, the Firefly III instance was running on a tiny Debian server in a Docker container right next to another Docker container that is running the main user of this server - a Home Assistant instance that has been managing my home for several years already. So why change that? See, there is one bit of knowledge that is very crucial to your Home Assistant experience, which is not really emphasised enough in the Home Assistant documentation. In fact back when I was getting into the Home Assistant both the main documentation and basically all the guides around were just coming off the hype of Docker disrupting everything and that is a big reason why everyone suggested to install and use Home Assistant as a Docker container on top of any kind of stable OS. In fact I used to run it for years on my TerraMaster NAS, just so that I don't have a separate home server running 24/7 at home and just have everything inside the very compact NAS case. So here is the thing you NEED to know - Home Assistant Container is DEMO version of Home Assistant! If you want to have a full Home Assistant experience and use the knowledge of the huge community around the HA space, you have to use the Home Assistant OS. Ideally on dedicated hardware. Ideally on HA Green box, but any tiny PC would also work great. Raspberry Pi 4+ is common, but quite weak as the network size grows and especially the SD card for storage gets old very fast. Get a real small x86 PC with at least 4Gb RAM and a NVME SSD (eMMC is fine too). You want to have an Ethernet port and a few free USB ports. I would also suggest immediately getting HA SkyConnect adapter that can do Zigbee networking and will do Matter soon (tm). I am making do with a SonOff Zigbee gateway, but it is quite hacky to get working and your whole Zigbee communication breaks down if the WiFi goes down - suboptimal. So I took a backup of the Home Assistant instance using it's build-in tools. I took an export of my fully configured Firefly III instance and proceeded to wipe the drive of the NUC. That was not a smart idea. :D On the Home Assitant side I was really frustrated by the documentation that was really focused on users that are (likely) using Windows and are using an SD card in something like Raspberry Pi to get Home Assistant OS running. It recommended downloading Etcher to write the image to the boot medium. That is a really weird piece of software that managed to actually crash consistently when I was trying to run it from Debian Live or Ubuntu Live on my NUC. It took me way too long to give up and try something much simpler - dd. xzcat haos_generic-x86-64-11.0.img.xz dd of=/dev/mmcblk0 bs=1M That just worked, prefectly and really fast. If you want to use a GUI in a live environment, then just using the gnome-disk-utility ("Disks" in Gnome menu) and using the "Restore Disk Image ..." on a partition would work just as well. It even supports decompressing the XZ images directly while writing. But that image is small, will it not have a ton of unused disk space behind the fixed install partition? Yes, it will ... until first boot. The HA OS takes over the empty space after its install partition on the first boot-up and just grows its main partition to take up all the remaining space. Smart. After first boot is completed, the first boot wizard can be accessed via your web browser and one of the prominent buttons there is restoring from backup. So you just give it the backup file and wait. Sadly the restore does not actually give any kind of progress, so your only way to figure out when it is done is opening the same web adress in another browser tab and refresh periodically - after restoring from backup it just boots into the same config at it had before - all the settings, all the devices, all the history is preserved. Even authentification tokens are preserved so if yu had a Home Assitant Mobile installed on your phone (both for remote access and to send location info and phone state, like charging, to HA to trigger automations) then it will just suddenly start working again without further actions needed from your side. That is an almost perfect backup/restore experience. The first thing you get for using the OS version of HA is easy automatic update that also automatically takes a backup before upgrade, so if anything breaks you can roll back with one click. There is also a command-line tool that allows to upgrade, but also downgrade ha-core and other modules. I had to use it today as HA version 23.10.4 actually broke support for the Sonoff bridge that I am using to control Zigbee devices, which are like 90% of all smart devices in my home. Really helpful stuff, but not a must have. What is a must have and that you can (really) only get with Home Assistant Operating System are Addons. Some addons are just normal servers you can run alongside HA on the same HA OS server, like MariaDB or Plex or a file server. That is not the most important bit, but even there the software comes pre-configured to use in a home server configuration and has a very simple config UI to pre-configure key settings, like users, passwords and database accesses for MariaDB - you can litereally in a few clicks and few strings make serveral users each with its own access to its own database. Couple more clicks and the DB is running and will be kept restarted in case of failures. But the real gems in the Home Assistant Addon Store are modules that extend Home Assitant core functionality in way that would be really hard or near impossible to configure in Home Assitant Container manually, especially because no documentation has ever existed for such manual config - everyone just tells you to install the addon from HA Addon store or from HACS. Or you can read the addon metadata in various repos and figure out what containers it actually runs with what settings and configs and what hooks it puts into the HA Core to make them cooperate. And then do it all over again when a new version breaks everything 6 months later when you have already forgotten everything. In the Addons that show up immediately after installation are addons to install the new Matter server, a MariaDB and MQTT server (that other addons can use for data storage and message exchange), Z-Wave support and ESPHome integration and very handy File manager that includes editors to edit Home Assitant configs directly in brower and SSH/Terminal addon that boht allows SSH connection and also a web based terminal that gives access to the OS itself and also to a comand line interface, for example, to do package downgrades if needed or see detailed logs. And also there is where you can get the features that are the focus this year for HA developers - voice enablers. However that is only a beginning. Like in Debian you can add additional repositories to expand your list of available addons. Unlike Debian most of the amazing software that is available for Home Assistant is outside the main, official addon store. For now I have added the most popular addon repository - HACS (Home Assistant Community Store) and repository maintained by Alexbelgium. The first includes things like NodeRED (a workflow based automation programming UI), Tailscale/Wirescale for VPN servers, motionEye for CCTV control, Plex for home streaming. HACS also includes a lot of HA UI enhacement modules, like themes, custom UI control panels like Mushroom or mini-graph-card and integrations that provide more advanced functions, but also require more knowledge to use, like Local Tuya - that is harder to set up, but allows fully local control of (normally) cloud-based devices. And it has AppDaemon - basically a Python based automation framework where you put in Python scrips that get run in a special environment where they get fed events from Home Assistant and can trigger back events that can control everything HA can and also do anything Python can do. This I will need to explore later. And the repository by Alex includes the thing that is actually the focus of this blog post (I know :D) - Firefly III addon and Firefly Importer addon that you can then add to your Home Assistant OS with a few clicks. It also has all kinds of addons for NAS management, photo/video server, book servers and Portainer that lets us setup and run any Docker container inside the HA OS structure. HA OS will detect this and warn you about unsupported processes running on your HA OS instance (nice security feature!), but you can just dismiss that. This will be very helpful very soon. This whole environment of OS and containers and apps really made me think - what was missing in Debian that made the talented developers behind all of that to spend the immense time and effor to setup a completely new OS and app infrastructure and develop a completel paraller developer community for Home Assistant apps, interfaces and configurations. Is there anything that can still be done to make HA community and the general open source and Debian community closer together? HA devs are not doing anything wrong: they are using the best open source can provide, they bring it to people whould could not install and use it otherwise, they are contributing fixes and improvements as well. But there must be some way to do this better, together. So I installed MariaDB, create a user and database for Firefly. I installed Firefly III and configured it to use the MariaDB with the web config UI. When I went into the Firefly III web UI I was confronted with the normal wizard to setup a new instance. And no reference to any backup restore. Hmm, ok. Maybe that goes via the Importer? So I make an access token again, configured the Importer to use that, configured the Nordlinger bank connection settings. Then I tried to import the export that I downloaded from Firefly III before. The importer did not auto-recognose the format. Turns out it is just a list of transactions ... It can only be barely useful if you first manually create all the asset accounts with the same names as before and even then you'll again have to deal with resolving the problem of transfers showing up twice. And all of your categories (that have not been used yet) are gone, your automation rules and bills are gone, your budgets and piggy banks are gone. Boooo. It will be easier for me to recreate my account data from bank exports again than to resolve data in that transaction export. Turns out that Firefly III documenation explicitly recommends making a mysqldump of your own and not rely on anything in the app itself for backup purposes. Kind of sad this was not mentioned in the export page that sure looked a lot like a backup :D After doing all that work all over again I needed to make something new not to feel like I wasted days of work for no real gain. So I started solving a problem I had for a while already - how do I add cash transations to the system when I am out of the house with just my phone in the hand? So far my workaround has been just sending myself messages in WhatsApp with the amount and description of any cash expenses. Two solutions are possible: app and bot. There are actually multiple Android-based phone apps that work with Firefly III API to do full financial management from the phone. However, after trying it out, that is not what I will be using most of the time. First of all this requires your Firefly III instance to be accessible from the Internet. Either via direct API access using some port forwarding and secured with HTTPS and good access tokens, or via a VPN server redirect that is installed on both HA and your phone. Tailscale was really easy to get working. But the power has its drawbacks - adding a new cash transaction requires opening the app, choosing new transaction view, entering descriptio, amount, choosing "Cash" as source account and optionally choosing destination expense account, choosing category and budget and then submitting the form to the server. Sadly none of that really works if you have no Internet or bad Internet at the place where you are using cash. And it's just too many steps. Annoying. An easier alternative is setting up a Telegram bot - it is running in a custom Docker container right next to your Firefly (via Portainer) and you talk to it via a custom Telegram chat channel that you create very easily and quickly. And then you can just tell it "Coffee 5" and it will create a transaction from the (default) cash account in 5 amount with description "Coffee". This part also works if you are offline at the moment - the bot will receive the message once you get back online. You can use Telegram bot menu system to edit the transaction to add categories or expense accounts, but this part only work if you are online. And the Firefly instance does not have to be online at all. Really nifty. So next week I will need to write up all the regular payments as bills in Firefly (again) and then I can start writing a Python script to predict my (financial) future!

Ian Jackson: DigiSpark (ATTiny85) - Arduino, C, Rust, build systems

Recently I completed a small project, including an embedded microcontroller. For me, using the popular Arduino IDE, and C, was a mistake. The experience with Rust was better, but still very exciting, and not in a good way. Here follows the rant. Introduction In a recent project (I ll write about the purpose, and the hardware in another post) I chose to use a DigiSpark board. This is a small board with a USB-A tongue (but not a proper plug), and an ATTiny85 microcontroller, This chip has 8 pins and is quite small really, but it was plenty for my application. By choosing something popular, I hoped for convenient hardware, and an uncomplicated experience. Convenient hardware, I got. Arduino IDE The usual way to program these boards is via an IDE. I thought I d go with the flow and try that. I knew these were closely related to actual Arduinos and saw that the IDE package arduino was in Debian. But it turns out that the Debian package s version doesn t support the DigiSpark. (AFAICT from the list it offered me, I m not sure it supports any ATTiny85 board.) Also, disturbingly, its board manager seemed to be offering to install board support, suggesting it would download stuff from the internet and run it. That wouldn t be acceptable for my main laptop. I didn t expect to be doing much programming or debugging, and the project didn t have significant security requirements: the chip, in my circuit, has only a very narrow ability do anything to the real world, and no network connection of any kind. So I thought it would be tolerable to do the project on my low-security video laptop . That s the machine where I m prepared to say yes to installing random software off the internet. So I went to the upstream Arduino site and downloaded a tarball containing the Arduino IDE. After unpacking that in /opt it ran and produced a pointy-clicky IDE, as expected. I had already found a 3rd-party tutorial saying I needed to add a magic URL (from the DigiSpark s vendor) in the preferences. That indeed allowed it to download a whole pile of stuff. Compilers, bootloader clients, god knows what. However, my tiny test program didn t make it to the board. Half-buried in a too-small window was an error message about the board s bootloader ( Micronucleus ) being too new. The boards I had came pre-flashed with micronucleus 2.2. Which is hardly new, But even so the official Arduino IDE (or maybe the DigiSpark s board package?) still contains an old version. So now we have all the downsides of curl bash-ware, but we re lacking the it s up to date and it just works upsides. Further digging found some random forum posts which suggested simply downloading a newer micronucleus and manually stuffing it into the right place: one overwrites a specific file, in the middle the heaps of stuff that the Arduino IDE s board support downloader squirrels away in your home directory. (In my case, the home directory of the untrusted shared user on the video laptop,) So, whatever . I did that. And it worked! Having demo d my ability to run code on the board, I set about writing my program. Writing C again The programming language offered via the Arduino IDE is C. It s been a little while since I started a new thing in C. After having spent so much of the last several years writing Rust. C s primitiveness quickly started to grate, and the program couldn t easily be as DRY as I wanted (Don t Repeat Yourself, see Wilson et al, 2012, 4, p.6). But, I carried on; after all, this was going to be quite a small job. Soon enough I had a program that looked right and compiled. Before testing it in circuit, I wanted to do some QA. So I wrote a simulator harness that #included my Arduino source file, and provided imitations of the few Arduino library calls my program used. As an side advantage, I could build and run the simulation on my main machine, in my normal development environment (Emacs, make, etc.). The simulator runs confirmed the correct behaviour. (Perhaps there would have been some more faithful simulation tool, but the Arduino IDE didn t seem to offer it, and I wasn t inclined to go further down that kind of path.) So I got the video laptop out, and used the Arduino IDE to flash the program. It didn t run properly. It hung almost immediately. Some very ad-hoc debugging via led-blinking (like printf debugging, only much worse) convinced me that my problem was as follows: Arduino C has 16-bit ints. My test harness was on my 64-bit Linux machine. C was autoconverting things (when building for the micrcocontroller). The way the Arduino IDE ran the compiler didn t pass the warning options necessary to spot narrowing implicit conversions. Those warnings aren t the default in C in general because C compilers hate us all for compatibility reasons. I don t know why those warnings are not the default in the Arduino IDE, but my guess is that they didn t want to bother poor novice programmers with messages from the compiler explaining how their program is quite possibly wrong. After all, users don t like error messages so we shouldn t report errors. And novice programmers are especially fazed by error messages so it s better to just let them struggle themselves with the arcane mysteries of undefined behaviour in C? The Arduino IDE does offer a dropdown for compiler warnings . The default is None. Setting it to All didn t produce anything about my integer overflow bugs. And, the output was very hard to find anyway because the log window has a constant stream of strange messages from javax.jmdns, with hex DNS packet dumps. WTF. Other things that were vexing about the Arduino IDE: it has fairly fixed notions (which don t seem to be documented) about how your files and directories ought to be laid out, and magical machinery for finding things you put nearby its sketch (as it calls them) and sticking them in its ear, causing lossage. It has a tendency to become confused if you edit files under its feet (e.g. with git checkout). It wasn t really very suited to a workflow where principal development occurs elsewhere. And, important settings such as the project s clock speed, or even the target board, or the compiler warning settings to use weren t stored in the project directory along with the actual code. I didn t look too hard, but I presume they must be in a dotfile somewhere. This is madness. Apparently there is an Arduino CLI too. But I was already quite exasperated, and I didn t like the idea of going so far off the beaten path, when the whole point of using all this was to stay with popular tooling and share fate with others. (How do these others cope? I have no idea.) As for the integer overflow bug: I didn t seriously consider trying to figure out how to control in detail the C compiler options passed by the Arduino IDE. (Perhaps this is possible, but not really documented?) I did consider trying to run a cross-compiler myself from the command line, with appropriate warning options, but that would have involved providing (or stubbing, again) the Arduino/DigiSpark libraries (and bugs could easily lurk at that interface). Instead, I thought, if only I had written the thing in Rust . But that wasn t possible, was it? Does Rust even support this board? Rust on the DigiSpark I did a cursory web search and found a very useful blog post by Dylan Garrett. This encouraged me to think it might be a workable strategy. I looked at the instructions there. It seemed like I could run them via the privsep arrangement I use to protect myself when developing using upstream cargo packages from crates.io. I got surprisingly far surprisingly quickly. It did, rather startlingly, cause my rustup to download a random recent Nightly Rust, but I have six of those already for other Reasons. Very quickly I got the trinket LED blink example, referenced by Dylan s blog post, to compile. Manually copying the file to the video laptop allowed me to run the previously-downloaded micronucleus executable and successfully run the blink example on my board! I thought a more principled approach to the bootloader client might allow a more convenient workflow. I found the upstream Micronucleus git releases and tags, and had a look over its source code, release dates, etc. It seemed plausible, so I compiled v2.6 from source. That was a success: now I could build and install a Rust program onto my board, from the command line, on my main machine. No more pratting about with the video laptop. I had got further, more quickly, with Rust, than with the Arduino IDE, and the outcome and workflow was superior. So, basking in my success, I copied the directory containing the example into my own project, renamed it, and adjusted the path references. That didn t work. Now it didn t build. Even after I copied about .cargo/config.toml and rust-toolchain.toml it didn t build, producing a variety of exciting messages, depending what precisely I tried. I don t have detailed logs of my flailing: the instructions say to build it by cd ing to the subdirectory, and, given that what I was trying to do was to not follow those instructions, it didn t seem sensible to try to prepare a proper repro so I could file a ticket. I wasn t optimistic about investigating it more deeply myself: I have some experience of fighting cargo, and it s not usually fun. Looking at some of the build control files, things seemed quite complicated. Additionally, not all of the crates are on crates.io. I have no idea why not. So, I would need to supply local copies of them anyway. I decided to just git subtree add the avr-hal git tree. (That seemed better than the approach taken by the avr-hal project s cargo template, since that template involve a cargo dependency on a foreign git repository. Perhaps it would be possible to turn them into path dependencies, but given that I had evidence of file-location-sensitive behaviour, which I didn t feel like I wanted to spend time investigating, using that seems like it would possibly have invited more trouble. Also, I don t like package templates very much. They re a form of clone-and-hack: you end up stuck with whatever bugs or oddities exist in the version of the template which was current when you started.) Since I couldn t get things to build outside avr-hal, I edited the example, within avr-hal, to refer to my (one) program.rs file outside avr-hal, with a #[path] instruction. That s not pretty, but it worked. I also had to write a nasty shell script to work around the lack of good support in my nailing-cargo privsep tool for builds where cargo must be invoked in a deep subdirectory, and/or Cargo.lock isn t where it expects, and/or the target directory containing build products is in a weird place. It also has to filter the output from cargo to adjust the pathnames in the error messages. Otherwise, running both cd A; cargo build and cd B; cargo build from a Makefile produces confusing sets of error messages, some of which contain filenames relative to A and some relative to B, making it impossible for my Emacs to reliably find the right file. RIIR (Rewrite It In Rust) Having got my build tooling sorted out I could go back to my actual program. I translated the main program, and the simulator, from C to Rust, more or less line-by-line. I made the Rust version of the simulator produce the same output format as the C one. That let me check that the two programs had the same (simulated) behaviour. Which they did (after fixing a few glitches in the simulator log formatting). Emboldened, I flashed the Rust version of my program to the DigiSpark. It worked right away! RIIR had caused the bug to vanish. Of course, to rewrite the program in Rust, and get it to compile, it was necessary to be careful about the types of all the various integers, so that s not so surprising. Indeed, it was the point. I was then able to refactor the program to be a bit more natural and DRY, and improve some internal interfaces. Rust s greater power, compared to C, made those cleanups easier, so making them worthwhile. However, when doing real-world testing I found a weird problem: my timings were off. Measured, the real program was too fast by a factor of slightly more than 2. A bit of searching (and searching my memory) revealed the cause: I was using a board template for an Adafruit Trinket. The Trinket has a clock speed of 8MHz. But the DigiSpark runs at 16.5MHz. (This is discussed in a ticket against one of the C/C++ libraries supporting the ATTiny85 chip.) The Arduino IDE had offered me a choice of clock speeds. I have no idea how that dropdown menu took effect; I suspect it was adding prelude code to adjust the clock prescaler. But my attempts to mess with the CPU clock prescaler register by hand at the start of my Rust program didn t bear fruit. So instead, I adopted a bodge: since my code has (for code structure reasons, amongst others) only one place where it dealt with the underlying hardware s notion of time, I simply changed my delay function to adjust the passed-in delay values, compensating for the wrong clock speed. There was probably a more principled way. For example I could have (re)based my work on either of the two unmerged open MRs which added proper support for the DigiSpark board, rather than abusing the Adafruit Trinket definition. But, having a nearly-working setup, and an explanation for the behaviour, I preferred the narrower fix to reopening any cans of worms. An offer of help As will be obvious from this posting, I m not an expert in dev tools for embedded systems. Far from it. This area seems like quite a deep swamp, and I m probably not the person to help drain it. (Frankly, much of the improvement work ought to be done, and paid for, by hardware vendors.) But, as a full Member of the Debian Project, I have considerable gatekeeping authority there. I also have much experience of software packaging, build systems, and release management. If anyone wants to try to improve the situation with embedded tooling in Debian, and is willing to do the actual packaging work. I would be happy to advise, and to review and sponsor your contributions. An obvious candidate: it seems to me that micronucleus could easily be in Debian. Possibly a DigiSpark board definition could be provided to go with the arduino package. Unfortunately, IMO Debian s Rust packaging tooling and workflows are very poor, and the first of my suggestions for improvement wasn t well received. So if you need help with improving Rust packages in Debian, please talk to the Debian Rust Team yourself. Conclusions Embedded programming is still rather a mess and probably always will be. Embedded build systems can be bizarre. Documentation is scant. You re often expected to download board support packages full of mystery binaries, from the board vendor (or others). Dev tooling is maddening, especially if aimed at novice programmers. You want version control? Hermetic tracking of your project s build and install configuration? Actually to be told by the compiler when you write obvious bugs? You re way off the beaten track. As ever, Free Software is under-resourced and the maintainers are often busy, or (reasonably) have other things to do with their lives. All is not lost Rust can be a significantly better bet than C for embedded software: The Rust compiler will catch a good proportion of programming errors, and an experienced Rust programmer can arrange (by suitable internal architecture) to catch nearly all of them. When writing for a chip in the middle of some circuit, where debugging involves staring an LED or a multimeter, that s precisely what you want. Rust embedded dev tooling was, in this case, considerably better. Still quite chaotic and strange, and less mature, perhaps. But: significantly fewer mystery downloads, and significantly less crazy deviations from the language s normal build system. Overall, less bad software supply chain integrity. The ATTiny85 chip, and the DigiSpark board, served my hardware needs very well. (More about the hardware aspects of this project in a future posting.)

comment count unavailable comments

21 October 2023

Russell Coker: More About the PineTime

Since my initial review of the PineTime 10 days ago [1] I ve used it in more situations. My initial tests were done connecting to a Huawei Nova 7i [2], I am now using it with a Huawei Mate 10 Pro. I ve also upgraded the PineTime from version 1.11 (from memory) of the Infinitime software that runs on the watch to version 1.13 [3]. To upgrade it I had to download the file pinetime-mcuboot-app-dfu-1.13.0.zip to the Android phone and then use the File Installer option of the GadgetBridge Android app to upload it. The zip file does NOT need to be extracted first, I don t know if GadgetBridge extracts it before upload or if the PineTime firmware has a copy of unzip, but it just works. Version 1.13 is purported to take less battery, I haven t directly verified this as I turned on the new feature of measuring my pulse 24*7 which significantly increases battery use. The end result is that the battery is being used up at about the same rate as before, overall adding a new battery-hungry feature while reducing battery use for other things to compensate is a good thing and strongly suggests that battery use has decreased overall. I have noticed that now with a different phone and different version of the firmware it doesn t reconnect as reliably. Sometimes I need to turn bluetooth on the watch off and on before it works (which indicates an issue with the firmware) and sometimes I need to turn bluetooth off and on on the phone which indicates a phone issue. Also I often unlock my phone to find the GadgetBridge notification saying that it s disconnected and it usually connects fine, but I get the impression it s often disconnected. Does the Mate 10 Pro have a problem that triggers a bug in the PineTime? Does the 1.13 version of InfiniTime have a problem that triggers a bug in the Mate 10 Pro? Are they both independently buggy? Is the new version of InfiniTime just disconnecting when it s not doing stuff to save battery and triggering bugs that weren t obvious before? I ve tested the media control which basically works, sometimes it gets out of sync and displays the name of the previous track which is annoying. The PineTime is IP67 rated and there are reports on Reddit of people wearing it in the shower and swimming pool. I wouldn t recommend those things although it should work OK. It might be an option for controlling music when in the bath or when having a pool party. When the watch is running normally and displays a new notification it s not possible to swipe it away. You have to go to the notifications menu afterwards to swipe them which I find annoying. Also the notification of an inbound call remains in the notification list indefinitely while I think a more appropriate action is to have it disappear in an amount of time where it s already been answered or gone to voicemail. Voicemail timeouts are as low as 15 seconds so having the notification disappear after 1 minute would be reasonable. I have configured my PineTime to take 2 taps on the screen to wake up. I previously had it set to 1 tap and had problems with accidentally doing something it registered as a tap while in bed and waking me up. Also I found that if I want to turn the screen on when my hands are dirty so I don t want to touch it with a finger then tapping it on my nose works well. Apparently it is programmed to ignore taps on large areas so I can t wake it with my elbow. I ve setup a PineTime for an elderly relative who is greatly enjoying it. I don t expect them to flash new firmware or do any other complex things, but they are doing well with using the device. They are considering getting a different band as they don t like rubber. I m sure their local jeweler has some leather and metal bands that could fit. There is a design on Thiniverse for a PineTime case [4], this could be used for making an adaptor to fit a PineTime to a greatly different type of band, an instrument console, etc. Generally I think the PineTime is an OK smart watch for someone who s not into FOSS for it s own sake. My relative could have been happy with a slightly cheaper watch, but it s still significantly cheaper than the Samsung and Apple options so it s not particularly expensive. A benefit for them is that having the same type of SmartWatch as me they will get better tech support.

20 October 2023

Freexian Collaborators: Debian Contributions: Freexian meetup, debusine updates, lpr/lpd in Debian, and more! (by Utkarsh Gupta, Stefano Rivera)

Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Freexian Meetup, by Stefano Rivera, Utkarsh Gupta, et al. During DebConf, Freexian organized a meetup for its collaborators and those interested in learning more about Freexian and its services. It was well received and many people interested in Freexian showed up. Some developers who were interested in contributing to LTS came to get more details about joining the project. And some prospective customers came to get to know us and ask questions. Sadly, the tragic loss of Abraham shook DebConf, both individually and structurally. The meetup got rescheduled to a small room without video coverage. With that, we still had a wholesome interaction and here s a quick picture from the meetup taken by Utkarsh (which is also why he s missing!).

Debusine, by Rapha l Hertzog, et al. Freexian has been investing into debusine for a while, but development speed is about to increase dramatically thanks to funding from SovereignTechFund.de. Rapha l laid out the 5 milestones of the funding contract, and filed the issues for the first milestone. Together with Enrico and Stefano, they established a workflow for the expanded team. Among the first steps of this milestone, Enrico started to work on a developer-friendly description of debusine that we can use when we reach out to the many Debian contributors that we will have to interact with. And Rapha l started the design work of the autopkgtest and lintian tasks, i.e. what s the interface to schedule such tasks, what behavior and what associated options do we support? At this point you might wonder what debusine is supposed to be let us try to answer this: Debusine manages scheduling and distribution of Debian-related build and QA tasks to a network of worker machines. It also manages the resulting artifacts and provides the results in an easy to consume way. We want to make it easy for Debian contributors to leverage all the great QA tools that Debian provides. We want to build the next generation of Debian s build infrastructure, one that will continue to reliably do what it already does, but that will also enable distribution-wide experiments, custom package repositories and custom workflows with advanced package reviews. If this all sounds interesting to you, don t hesitate to watch the project on salsa.debian.org and to contribute.

lpr/lpd in Debian, by Thorsten Alteholz During Debconf23, Till Kamppeter presented CPDB (Common Print Dialog Backend), a new way to handle print queues. After this talk it was discussed whether the old lpr/lpd based printing system could be abandoned in Debian or whether there is still demand for it. So Thorsten asked on the debian-devel email list whether anybody uses it. Oddly enough, these old packages are still useful:
  • Within a small network it is easier to distribute a printcap file, than to properly configure cups clients.
  • One of the biggest manufacturers of WLAN router and DSL boxes only supports raw queues when attaching an USB printer to their hardware. Admittedly the CPDB still has problems with such raw queues.
  • The Pharos printing system at MIT is still lpd-based.
As a result, the lpr/lpd stuff is not yet ready to be abandoned and Thorsten will adopt the relevant packages (or rather move them under the umbrella of the debian-printing team). Though it is not planned to develop new features, those packages should at least have a maintainer. This month Thorsten adopted rlpr, an utility for lpd printing without using /etc/printcap. The next one he is working on is lprng, a lpr/lpd printer spooling system. If you know of any other package that is also needed and still maintained by the QA team, please tell Thorsten.

/usr-merge, by Helmut Grohne Discussion about lifting the file move moratorium has been initiated with the CTTE and the release team. A formal lift is dependent on updating debootstrap in older suites though. A significant number of packages can automatically move their systemd unit files if dh_installsystemd and systemd.pc change their installation targets. Unfortunately, doing so makes some packages FTBFS and therefore patches have been filed. The analysis tool, dumat, has been enhanced to better understand which upgrade scenarios are considered supported to reduce false positive bug filings and gained a mode for local operation on a .changes file meant for inclusion in salsa-ci. The filing of bugs from dumat is still manual to improve the quality of reports. Since September, the moratorium has been lifted.

Miscellaneous contributions
  • Rapha l updated Django s backport in bullseye-backports to match the latest security release that was published in bookworm. Tracker.debian.org is still using that backport.
  • Helmut Grohne sent 13 patches for cross build failures.
  • Helmut Grohne performed a maintenance upload of debvm enabling its use in autopkgtests.
  • Helmut Grohne wrote an API-compatible reimplementation of autopkgtest-build-qemu. It is powered by mmdebstrap, therefore unprivileged, EFI-only and will soon be included in mmdebstrap.
  • Santiago continued the work regarding how to make it easier to (automatically) test reverse dependencies. An example of the ongoing work was presented during the Salsa CI BoF at DebConf 23.
    In fact, omniorb-dfsg test pipelines as the above were used for the omniorb-dfsg 4.3.0 transition, verifying how the reverse dependencies (tango, pytango and omnievents) were built and how their autopkgtest jobs run with the to-be-uploaded omniorb-dfsg new release.
  • Utkarsh and Stefano attended and helped run DebConf 23. Also continued winding up DebConf 22 accounting.
  • Anton Gladky did some science team uploads to fix RC bugs.

17 October 2023

Russ Allbery: Review: A Hat Full of Sky

Review: A Hat Full of Sky, by Terry Pratchett
Series: Discworld #32
Publisher: HarperTrophy
Copyright: 2004
Printing: 2005
ISBN: 0-06-058662-1
Format: Mass market
Pages: 407
A Hat Full of Sky is the 32nd Discworld novel and the second Tiffany Aching young adult novel. You should not start here, but you could start with The Wee Free Men. As with that book, some parts of the story carry more weight if you are already familiar with Granny Weatherwax. Tiffany is a witch, but she needs to be trained. This is normally done by apprenticeship, and in Tiffany's case it seemed wise to give her exposure to more types of witching. Thus, Tiffany, complete with new boots and a going-away present from the still-somewhat-annoying Roland, is off on an apprenticeship to the sensible Miss Level. (The new boots feel wrong and get swapped out for her concealed old boots at the first opportunity.) Unbeknownst to Tiffany, her precocious experiments with leaving her body as a convenient substitute for a mirror have attracted something very bad, something none of the witches are expecting. The Nac Mac Feegle know a hiver as soon as they feel it, but they have a new kelda now, and she's not sure she wants them racing off after their old kelda. Terry Pratchett is very good at a lot of things, but I don't think villains are one of his strengths. He manages an occasional memorable one (the Auditors, for example, at least before the whole chocolate thing), but I find most of them a bit boring. The hiver is one of the boring ones. It serves mostly as a concretized metaphor about the temptations of magical power, but those temptations felt so unlike the tendencies of Tiffany's personality that I didn't think the metaphor worked in the story. The interesting heart of this book to me is the conflict between Tiffany's impatience with nonsense and Miss Level's arguably excessive willingness to help everyone regardless of how demanding they get. There's something deeper in here about female socialization and how that interacts with Pratchett's conception of witches that got me thinking, although I don't think Pratchett landed the point with full force. Miss Level is clearly a good witch to her village and seems comfortable with how she lives her life, so perhaps they're not taking advantage of her, but she thoroughly slots herself into the helper role. If Tiffany attempted the same role, people would be taking advantage of her, because the role doesn't fit her. And yet, there's a lesson here she needs to learn about seeing other people as people, even if it wouldn't be healthy for her to move all the way to Miss Level's mindset. Tiffany is a precocious kid who is used to being underestimated, and who has reacted by becoming independent and somewhat judgmental. She's also had a taste of real magical power, which creates a risk of her getting too far into her own head. Miss Level is a fount of empathy and understanding for the normal people around her, which Tiffany resists and needed to learn. I think Granny Weatherwax is too much like Tiffany to teach her that. She also has no patience for fools, but she's older and wiser and knows Tiffany needs a push in that direction. Miss Level isn't a destination, but more of a counterbalance. That emotional journey, a conclusion that again focuses on the role of witches in questions of life and death, and Tiffany's fascinatingly spiky mutual respect with Granny Weatherwax were the best parts of this book for me. The middle section with the hiver was rather tedious and forgettable, and the Nac Mac Feegle were entertaining but not more than that. It felt like the story went in a few different directions and only some of them worked, in part because the villain intended to tie those pieces together was more of a force of nature than a piece of Tiffany's emotional puzzle. If the hiver had resonated with the darker parts of Tiffany's natural personality, the plot would have worked better. Pratchett was gesturing in that direction, but he never convinced me it was consistent with what we'd already seen of her. Like a lot of the Discworld novels, the good moments in A Hat Full of Sky are astonishing, but the plot is somewhat forgettable. It's still solidly entertaining, though, and if you enjoyed The Wee Free Men, I think this is slightly better. Followed by Going Postal in publication order. The next Tiffany Aching novel is Wintersmith. Rating: 8 out of 10

15 October 2023

Russ Allbery: Review: A Killing Frost

Review: A Killing Frost, by Seanan McGuire
Series: October Daye #14
Publisher: DAW
Copyright: 2020
ISBN: 0-7564-1253-6
Format: Kindle
Pages: 351
A Killing Frost is the 14th book in the October Daye urban fantasy series and a direct plot sequel to the events of The Brightest Fell. You definitely cannot start here. This review has some relationship spoilers here for things that you would be expecting after the first five or six books, but which you wouldn't know when reading the first few books of the series. If you haven't started the series yet but plan to, consider skipping this review; if you haven't started reading this series, it will probably be meaningless anyway. Finally, events seem to have slowed, enough trauma has been healed, and Toby is able to seriously consider getting married. However, no sooner is the thought voiced than fae politics injects itself yet again. In order to get married without creating potentially substantial future problems for herself and her family, Toby will have to tie up some loose ends. Since one of those loose ends is a price from the Luidaeg that has been haunting her family for decades, this is easier said than done. The Brightest Fell had a very unsatisfying ending. This, after a two book interlude, is the proper end to that story. I picked this up when I had a bunch of stressful things going on and I wanted to be entertained without having to do much work as a reader. Once again, this series delivered exactly that. The writing is repetitive and a bit clunky, McGuire hammers the same emotional points into the ground, and one does wonder about Toby's tendency to emulate a half-human battering ram, but every book has me engrossed and turning the pages. Everyone should have at least one book series on the go that offers reliable, low-effort entertainment. The initial lever that McGuire uses to push Toby into this plot (fae marriage requirements that had never previously been mentioned) felt rather strained and arbitrary, and I spent the first part of the book grumbling a bit about it. However, there is a better reason for this complication that is revealed with time, and which implies some interesting things about how the fae see heroes and how they use them to solve problems. Now I'm wondering if McGuire will explore that some more in later books. This is the "all is revealed" book about Simon Torquill. As we get later into the series, these "all is revealed" books are coming more frequently. So far, I'm finding the revelations satisfying, which is a lot harder than it looks with a series this long and with this many hidden details. There are a few directions the series is taking that aren't my favorite (the Daoine Sidhe obsession with being the Best Fae is getting a bit boring, for example), but none of them seem egregiously off, and I'm deeply invested in the answers to the remaining questions. Toby hits a personal record here for not explaining the dangerous things she's doing because people might talk her out of it. It makes for a tense and gripping climax, but wow I felt for her friends and family, and substantial parts of that risk seemed unnecessary. This is pointed out to her in no uncertain terms, and I'm wondering if it will finally stick. Toby's tendency to solve complicated problems by bleeding on them is part of what gives this series its charm, but I wouldn't mind her giving other people more of a chance to come up with better plans. I did not like this one as well as the previous two books, mostly because I prefer the Luidaeg-centric stories to the Daoine-Sidhe-centric stories, but if you're enjoying the series to this point, this won't be an exception. It's a substantial improvement on The Brightest Fell and did a lot to salvage that story for me, although there are still some aspects of it that need better explanations. Followed by When Sorrows Come. As usual, there is a novella included in at least the Kindle edition. "Shine in Pearl": I was again hoping for more Gillian, but alas. Instead, and breaking with the tendency for the novellas to be side stories unrelated to the main novel, this fleshes out Simon's past and the other primary relationship driving the novel's plot. It's... fine? The best parts by far are the scenes from Dianda's viewpoint, which are just as refreshingly blunt as Dianda is elsewhere. Neither of the other two characters are favorites of mine, and since the point of the story is to describe the tragedy that is resolved in the plot of the main novel, it's somewhat depressing. Not my favorite of the novellas; not the worst of them. (6) Rating: 7 out of 10

13 October 2023

Scarlett Gately Moore: KDE: Snaps move, KDE neon unstable broken OMG! Fixed, and Debian updates

Kitties keeping warm!
It s that time of year already! We have hit our first freeze of the year. While the kitties keep warm by the wood burning stove, I have been busy with many updates and fixes in a variety of projects. KDE neon: It s true, Neon unstable has been very unstable. Due to a few factors including a builder being out of space, timed with a new Qt release. There is a cost with living in unstable land with bleeding edge releases. It takes time and finesse to get everything happy, especially with major transitions such as Qt. The drive issue was just bad timing. We worked night and day ( quite literally with people spanning from the US, Europe and Australia ) to get everything happy again. I know it s frustrating when things are broken, but please keep in mind, most of us are volunteers. I am happy to report, it is once again stable. If you continue to experience issues please report them on https://bugs.kde.org there have been a few cases where there were rogue apt sources lists creating issues. We also have the User edition which is much more stable!
KDE Snaps: The big move to snapcraft files per repo continues. With that comes a new version 23.08.2. This big win this week was Audiotube! I have finally got this snap working. With a combination of snappy-debug and snap run gdb audiotube I was able to find all the hidden dependencies such as yt-dlp needed to be built with ffmpeg support and it needed a newer ytmusicapi as the version it called for was broken with gettext translations. I also had to fix the dbus name as it was not the standard org.kde.app. The final fix was it required the alsa plug and layouts adjusted to point to the snap alsa libraries ( which fixed the very important sound feature ). Who says you can t teach an old dog new tricks. Unfortunately, it still requires devmode to run, as it has one last network issue even with all the network plugs. I have to set it aside for now, as I have many more snaps to migrate. However, if you want to enjoy youtube music with this super awesome app you can, just append devmode when installing. Enjoy! The following apps have now migrated to their respective KDE repos and have the snap recipes in launchpad for automated builds: A new content pack with the latest Frameworks 5.110 and Qt 5.15.11 is complete and the neon extension update will follow after the required global autoconnect is approved from the store. Debian: I have caught up on my dashboard with new releases, fixed test failures, and FTBFS on the more obscure arches. The following debian packages have been uploaded to unstable:
description
umbrello
squashfuse
golang-github-muesli-mango
golang-github-muesli-roff
speechpy-fast
lingua-franca
If you have made it this far, thank you! As you can see I am quite busy and there is still much to do. If you can possibly spare a donation so I can continue my efforts in KDE neon / KDE Snaps / and Debian, it would be so appreciated. I enjoy doing this work and I hope it benefits someone out there. Have a lovely day and thanks for stopping by. Donate https://gofund.me/b8b69e54

12 October 2023

Jonathan McDowell: Installing Debian on the BananaPi M2 Zero

My previously mentioned C.H.I.P. repurposing has been partly successful; I ve found a use for it (which I still need to write up), but unfortunately it s too useful and the fact it s still a bit flaky has become a problem. I spent a while trying to isolate exactly what the problem is (I m still seeing occasional hard hangs with no obvious debug output in the logs or on the serial console), then realised I should just buy one of the cheap ARM SBC boards currently available. The C.H.I.P. is based on an Allwinner R8, which is a single ARM v7 core (an A8). So it s fairly low power by today s standards and it seemed pretty much any board would probably do. I considered a Pi 2 Zero, but couldn t be bothered trying to find one in stock at a reasonable price (I ve had one on backorder from CPC since May 2022, and yes, I know other places have had them in stock since but I don t need one enough to chase and I m now mostly curious about whether it will ever ship). As the title of this post gives away, I settled on a Banana Pi BPI-M2 Zero, which is based on an Allwinner H3. That s a quad-core ARM v7 (an A7), so a bit more oompfh than the C.H.I.P. All in all it set me back 25, including a set of heatsinks that form a case around it. I started with the vendor provided Debian SD card image, which is based on Debian 9 (stretch) and so somewhat old. I was able to dist-upgrade my way through buster and bullseye, and end up on bookworm. I then discovered the bookworm 6.1 kernel worked just fine out of the box, and even included a suitable DTB. Which got me thinking about whether I could do a completely fresh Debian install with minimal tweaking. First thing, a boot loader. The Allwinner chips are nice in that they ll boot off SD, so I just needed a suitable u-boot image. Rather than go with the vendor image I had a look at mainline and discovered it had support! So let s build a clean image:
noodles@buildhost:~$ mkdir ~/BPI
noodles@buildhost:~$ cd ~/BPI
noodles@buildhost:~/BPI$ ls
noodles@buildhost:~/BPI$ git clone https://source.denx.de/u-boot/u-boot.git
Cloning into 'u-boot'...
remote: Enumerating objects: 935825, done.
remote: Counting objects: 100% (5777/5777), done.
remote: Compressing objects: 100% (1967/1967), done.
remote: Total 935825 (delta 3799), reused 5716 (delta 3769), pack-reused 930048
Receiving objects: 100% (935825/935825), 186.15 MiB   2.21 MiB/s, done.
Resolving deltas: 100% (785671/785671), done.
noodles@buildhost:~/BPI$ mkdir u-boot-build
noodles@buildhost:~/BPI$ cd u-boot
noodles@buildhost:~/BPI/u-boot$ git checkout v2023.07.02
...
HEAD is now at 83cdab8b2c Prepare v2023.07.02
noodles@buildhost:~/BPI/u-boot$ make O=../u-boot-build bananapi_m2_zero_defconfig
  HOSTCC  scripts/basic/fixdep
  GEN     Makefile
  HOSTCC  scripts/kconfig/conf.o
  YACC    scripts/kconfig/zconf.tab.c
  LEX     scripts/kconfig/zconf.lex.c
  HOSTCC  scripts/kconfig/zconf.tab.o
  HOSTLD  scripts/kconfig/conf
#
# configuration written to .config
#
make[1]: Leaving directory '/home/noodles/BPI/u-boot-build'
noodles@buildhost:~/BPI/u-boot$ cd ../u-boot-build/
noodles@buildhost:~/BPI/u-boot-build$ make CROSS_COMPILE=arm-linux-gnueabihf-
  GEN     Makefile
scripts/kconfig/conf  --syncconfig Kconfig
...
  LD      spl/u-boot-spl
  OBJCOPY spl/u-boot-spl-nodtb.bin
  COPY    spl/u-boot-spl.bin
  SYM     spl/u-boot-spl.sym
  MKIMAGE spl/sunxi-spl.bin
  MKIMAGE u-boot.img
  COPY    u-boot.dtb
  MKIMAGE u-boot-dtb.img
  BINMAN  .binman_stamp
  OFCHK   .config
noodles@buildhost:~/BPI/u-boot-build$ ls -l u-boot-sunxi-with-spl.bin
-rw-r--r-- 1 noodles noodles 494900 Aug  8 08:06 u-boot-sunxi-with-spl.bin
I had the advantage here of already having a host setup to cross build armhf binaries, but this was all done on a Debian bookworm host with packages from main. I ve put my build up here in case it s useful to someone - everything else below can be done on a normal x86_64 host. Next I needed a Debian installer. I went for the netboot variant - although I was writing it to SD rather than TFTP booting I wanted as much as possible to come over the network.
noodles@buildhost:~/BPI$ wget https://deb.debian.org/debian/dists/bookworm/main/installer-armhf/20230607%2Bdeb12u1/images/netboot/netboot.tar.gz
...
2023-08-08 10:15:03 (34.5 MB/s) -  netboot.tar.gz  saved [37851404/37851404]
noodles@buildhost:~/BPI$ tar -axf netboot.tar.gz
Then I took a suitable microSD card and set it up with a 500M primary VFAT partition, leaving the rest for Linux proper. I could have got away with a smaller VFAT partition but I d initially thought I might need to put some more installation files on it.
noodles@buildhost:~/BPI$ sudo fdisk /dev/sdb
Welcome to fdisk (util-linux 2.38.1).
Changes will remain in memory only, until you decide to write them.
Be careful before using the write command.
Command (m for help): o
Created a new DOS (MBR) disklabel with disk identifier 0x793729b3.
Command (m for help): n
Partition type
   p   primary (0 primary, 0 extended, 4 free)
   e   extended (container for logical partitions)
Select (default p):
Using default response p.
Partition number (1-4, default 1):
First sector (2048-60440575, default 2048):
Last sector, +/-sectors or +/-size K,M,G,T,P  (2048-60440575, default 60440575): +500M
Created a new partition 1 of type 'Linux' and of size 500 MiB.
Command (m for help): t
Selected partition 1
Hex code or alias (type L to list all): c
Changed type of partition 'Linux' to 'W95 FAT32 (LBA)'.
Command (m for help): n
Partition type
   p   primary (1 primary, 0 extended, 3 free)
   e   extended (container for logical partitions)
Select (default p):
Using default response p.
Partition number (2-4, default 2):
First sector (1026048-60440575, default 1026048):
Last sector, +/-sectors or +/-size K,M,G,T,P  (534528-60440575, default 60440575):
Created a new partition 2 of type 'Linux' and of size 28.3 GiB.
Command (m for help): w
The partition table has been altered.
Calling ioctl() to re-read partition table.
Syncing disks.
$ sudo mkfs -t vfat -n BPI-UBOOT /dev/sdb1
mkfs.fat 4.2 (2021-01-31)
The bootloader image gets written 8k into the SD card (our first partition starts at sector 2048, i.e. 1M into the device, so there s plenty of space here):
noodles@buildhost:~/BPI$ sudo dd if=u-boot-build/u-boot-sunxi-with-spl.bin of=/dev/sdb bs=1024 seek=8
483+1 records in
483+1 records out
494900 bytes (495 kB, 483 KiB) copied, 0.0282234 s, 17.5 MB/s
Copy the Debian installer files onto the VFAT partition:
noodles@buildhost:~/BPI$ cp -r debian-installer/ /media/noodles/BPI-UBOOT/
Unmount the SD from the build host, pop it into the M2 Zero, boot it up while connected to the serial console, hit a key to stop autoboot and tell it to boot the installer:
U-Boot SPL 2023.07.02 (Aug 08 2023 - 09:05:44 +0100)
DRAM: 512 MiB
Trying to boot from MMC1
U-Boot 2023.07.02 (Aug 08 2023 - 09:05:44 +0100) Allwinner Technology
CPU:   Allwinner H3 (SUN8I 1680)
Model: Banana Pi BPI-M2-Zero
DRAM:  512 MiB
Core:  60 devices, 17 uclasses, devicetree: separate
WDT:   Not starting watchdog@1c20ca0
MMC:   mmc@1c0f000: 0, mmc@1c10000: 1
Loading Environment from FAT... Unable to read "uboot.env" from mmc0:1...
In:    serial
Out:   serial
Err:   serial
Net:   No ethernet found.
Hit any key to stop autoboot:  0
=> setenv dibase /debian-installer/armhf
=> fatload mmc 0:1 $ kernel_addr_r  $ dibase /vmlinuz
5333504 bytes read in 225 ms (22.6 MiB/s)
=> setenv bootargs "console=ttyS0,115200n8"
=> fatload mmc 0:1 $ fdt_addr_r  $ dibase /dtbs/sun8i-h2-plus-bananapi-m2-zero.dtb
25254 bytes read in 7 ms (3.4 MiB/s)
=> fdt addr $ fdt_addr_r  0x40000
Working FDT set to 43000000
=> fatload mmc 0:1 $ ramdisk_addr_r  $ dibase /initrd.gz
31693887 bytes read in 1312 ms (23 MiB/s)
=> bootz $ kernel_addr_r  $ ramdisk_addr_r :$ filesize  $ fdt_addr_r 
Kernel image @ 0x42000000 [ 0x000000 - 0x516200 ]
## Flattened Device Tree blob at 43000000
   Booting using the fdt blob at 0x43000000
Working FDT set to 43000000
   Loading Ramdisk to 481c6000, end 49fffc3f ... OK
   Loading Device Tree to 48183000, end 481c5fff ... OK
Working FDT set to 48183000
Starting kernel ...
At this point the installer runs and you can do a normal install. Well, except the wifi wasn t detected, I think because the netinst images don t include firmware. I spent a bit of time trying to figure out how to include it but ultimately ended up installing over a USB ethernet dongle, which Just Worked and was less faff. Installing firmware-brcm80211 once installation completed allowed the built-in wifi to work fine. After install you need to configure u-boot to boot without intervention. At the u-boot prompt (i.e. after hitting a key to stop autoboot):
=> setenv bootargs "console=ttyS0,115200n8 root=LABEL=BPI-ROOT ro"
=> setenv bootcmd 'ext4load mmc 0:2 $ fdt_addr_r  /boot/sun8i-h2-plus-bananapi-m2-zero.dtb ; fdt addr $ fdt_addr_r  0x40000 ; ext4load mmc 0:2 $ kernel_addr_r  /boot/vmlinuz ; ext4load mmc 0:2 $ ramdisk_addr_r  /boot/initrd.img ; bootz $ kernel_addr_r  $ ramdisk_addr_r :$ filesize  $ fdt_addr_r '
=> saveenv
Saving Environment to FAT... OK
=> reset
This is assuming you have /boot on partition 2 on the SD - I left the first partition as VFAT (that s where the u-boot environment will be saved) and just used all of the rest as a single ext4 partition. I did have to do an e2label /dev/sdb2 BPI-ROOT to label / appropriately; otherwise I occasionally saw the SD card appear as mmc1 for Linux (I m guessing due to asynchronous boot order with the wifi). You should now find the device boots without intervention.

Reproducible Builds: Reproducible Builds in September 2023

Welcome to the September 2023 report from the Reproducible Builds project In these reports, we outline the most important things that we have been up to over the past month. As a quick recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries.
Andreas Herrmann gave a talk at All Systems Go 2023 titled Fast, correct, reproducible builds with Nix and Bazel . Quoting from the talk description:

You will be introduced to Google s open source build system Bazel, and will learn how it provides fast builds, how correctness and reproducibility is relevant, and how Bazel tries to ensure correctness. But, we will also see where Bazel falls short in ensuring correctness and reproducibility. You will [also] learn about the purely functional package manager Nix and how it approaches correctness and build isolation. And we will see where Bazel has an advantage over Nix when it comes to providing fast feedback during development.
Andreas also shows how you can get the best of both worlds and combine Nix and Bazel, too. A video of the talk is available.
diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb fixed compatibility with file(1) version 5.45 [ ] and updated some documentation [ ]. In addition, Vagrant Cascadian extended support for GNU Guix [ ][ ] and updated the version in that distribution as well. [ ].
Yet another reminder that our upcoming Reproducible Builds Summit is set to take place from October 31st November 2nd 2023 in Hamburg, Germany. If you haven t been before, our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. If you re interested in joining us this year, please make sure to read the event page, the news item, or the invitation email that Mattia Rizzolo sent out recently, all of which have more details about the event and location. We are also still looking for sponsors to support the event, so please reach out to the organising team if you are able to help. Also note that PackagingCon 2023 is taking place in Berlin just before our summit.
On the Reproducible Builds website, Greg Chabala updated the JVM-related documentation to update a link to the BUILDSPEC.md file. [ ] And Fay Stegerman fixed the builds failing because of a YAML syntax error.

Distribution work In Debian, this month: September saw F-Droid add ten new reproducible apps, and one existing app switched to reproducible builds. In addition, two reproducible apps were archived and one was disabled for a current total of 199 apps published with Reproducible Builds and using the upstream developer s signature. [ ] In addition, an extensive blog post was posted on f-droid.org titled Reproducible builds, signing keys, and binary repos .

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In August, a number of changes were made by Holger Levsen:
  • Disable armhf and i386 builds due to Debian bug #1052257. [ ][ ][ ][ ]
  • Run diffoscope with a lower ionice priority. [ ]
  • Log every build in a simple text file [ ] and create persistent stamp files when running diffoscope to ease debugging [ ].
  • Run schedulers one hour after dinstall again. [ ]
  • Temporarily use diffoscope from the host, and not from a schroot running the tested suite. [ ][ ]
  • Fail the diffoscope distribution test if the diffoscope version cannot be determined. [ ]
  • Fix a spelling error in the email to IRC gateway. [ ]
  • Force (and document) the reconfiguration of all jobs, due to the recent rise of zombies. [ ][ ][ ][ ]
  • Deal with a rare condition when killing processes which should not be there. [ ]
  • Install the Debian backports kernel in an attempt to address Debian bug #1052257. [ ][ ]
In addition, Mattia Rizzolo fixed a call to diffoscope --version (as suggested by Fay Stegerman on our mailing list) [ ], worked on an openQA credential issue [ ] and also made some changes to the machine-readable reproducible metadata, reproducible-tracker.json [ ]. Lastly, Roland Clobus added instructions for manual configuration of the openQA secrets [ ].

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

11 October 2023

Russell Coker: The PineTime

I have just got a PineTime smart watch [1] from Pine64. They cost $US27 each which ended up as $144.63 Australian for three including postage when I ordered on the 16th of September, it s annoying that you can t order more than 3 at a time to reduce postage costs. The Australian online store Kogan has smart watches starting at about $15 [2] with Bluetooth and support for phone notifications so the $48.21 for a PineTime doesn t compare well on just price and features. The watches Kogan sells start getting into high resolution at around the $25 price and many of them have features like 24*7 heart monitoring that the PineTime lacks (it just measures when you request it). No-one would order a PineTime for being cheap or having lots of features, you order it because you want open hardware that allows you to do things your way. Also the PineTime isn t going to be orphaned while it s likely that in a few years most of the cheap watches sold by Kogan etc won t support the new phones running the latest version of Android. The screen of the PineTime is 240*240 resolution (about 260dpi) with 64k colors. The screen resolution is lower than some high-end smart watches but higher than most phones and almost all monitors. I doubt that much benefit could be gained from higher resolution. Even on minimum brightness the screen is easy to read on all but the brightest sunny days. The compute capabilities are 4.5MB of flash storage, 64k of RAM, and a 64MHz CPU this can t run Linux and nothing like it will run Linux for a long time. I ve had the PineTime for 6 days now, I charged it once and it s now at 55% battery. It looks like it will last close to 2 weeks on a single charge and it s claimed that a newer firmware will make the battery last longer. Software The main Android app for using with the PineTime is GadgetBridge which I installed from the f-droid repository. It had lots of click-through menus for allowing access to various Android features (contacts, bluetooth, draw over foreground, location, and more) but after that it was easy to setup. It was the first bluetooth device I ve used which had a 6 digit PIN for connecting to a phone. Initially I used the PineTime with my Huawei Nova 7i [3]. The aim is to eventually have it run from my PinePhonePro but my test of the PinePhonePro didn t go as well as hoped [4]. Now I m using it on my Huawei Mate 10 Pro. It comes with InfiniTime [5] installed as the default firmware, mine had 1.11.0 which is a fairly recent version. I will probably upgrade it soon to get the better power optimisation and weather alerts in the watch face. I don t have any plans to use different watch firmware and I don t have any plans to contribute to firmware development I just can t hack on every FOSS project around it s better to do big contributions to a small number of projects. For people who don t want the default firmware the Wasp-OS project seems interesting as it s written in Python [6], I don t like Python but it s very popular. Python is particularly popular in ML development, it will be interesting to see if Wasp-OS becomes a preferred platform for smart watches that talk to GPT servers. Generally the software works well, one annoyance is that when a notification goes away on the phone it remains on the PineTime and has to be manually dismissed. It would be nice if clearing notifications on the phone would clear them on the PineTime too. The music control works with RocketPlayer on Android, it displays the track name and has options for pause/play and skipping forward and backward one track. Annoyingly the current firmware doesn t allow configuring the main screens, from the primary screen you swipe down for notifications, right for settings, up for menus, and there s nothing defined for swipe left. I d like to make swipe left the command to get to music control. Hardware It has a detachable band that appears to be within the common range of watch bands. According to the PineTime Wiki page [7] there are a selection of alternate bands that will fit it, but some don t because the band is recessed into the watch. It is IP67 rated which means you can probably wear it while swimming. The charging contacts are exposed on the bottom of the case which means that any chemicals left by pool water can be cleaned off and also as they are apparently not expected to be harmed by sweat and skin oil there shouldn t be a problem charging it. I have significant experience using a Samsung Galaxy S5 Mini which is rated at IP67 in swimming pools. I had two problems with the S5 Mini when getting out of the pool, firstly water in the headphone socket made the phone consider that it was in headphone mode and turn off the speakers and secondly it took hours to become dry enough to charge and after many swims the charge rate dropped presumably due to oxide on the contacts. There are reports of success when swimming with a PineTime. Generally it feels well made and appears more solid than the cheapest Kogan devices appear to be. Conclusion If I wanted monitoring for medical reasons then I would choose a different smart watch. I ve read about people doing things like tracking their body stats 24*7 and trying to discover useful things, the PineTime is not a good option for BioHacking type use. However if I did have a need for such things I d probably just buy a second smart watch and have one on each wrist. The PineTime generally works well. It s a pity it has fewer hardware features than closed devices that are cheaper. But having a firmware that can be continually improved by the community is good. The continually expanding use of mobile phone technology devices for custom use in corporations (such as mobile phone in custom case for scanning prices etc in a supermarket) has some potential for use with this. I can imagine someone adding some custom features to a PineTime for such use. When a supermarket chain has 200,000 employees (as Woolworths in Australia does) then paying for a few months of software development work to make a smart watch do specific things for that company could provide significant value. There are probably some business opportunities for FOSS developers to hack on extra hardware on a PineTime and write software to support it. I recommend that everyone who s into FOSS buy one of these. Preferably make a deal with two friends to get the minimum postage cost.

Russell Coker: PinePhone Status

4 months ago I got my PinePhonePro [1]. Since then I have got SE Linux working on it to the stage of allowing it to boot correctly with Debian/Unstable, login with the user_t domain (minimum privilege for the graphical user) and make and receive calls. I finished getting SE Linux working reasonably well 3 days ago and most (but not all) of the SE Linux policy is in Debian now. I ve been getting good at Github PRs and I m sending a lot of policy upstream, so the next version of Debian will have a much smaller diff from the upstream Refpolicy. I have been running the PinePhone with Plasma Mobile because I prefer KDE, I would run GNOME/Phoc if it gave significantly better functionality. 3 days ago I moved my main SIM (the one with the number that people call about work etc) to my PinePhone and tried running it as my main phone. Today I gave up on that. My Android History The last phone I had that did everything I needed was a Huawei Mate 10 Pro that I bought refurbished in June 2019 for $389. The Mate 10 Pro runs Android with the Google Play store and has been quite unremarkable which is presumably why I forgot to blog about it when I got it, it was a slight upgrade over the Huawei Mate 9 [2] that I had used for 2 years before that. In April 2022 I tried using a Huawei Nova 7i as my main phone without Google Play programs or services [3]. That experiment was a failure as I couldn t get NextCloud to work for Calendaring and Contacts. It could be that I stuffed something up when trying that, but I put more skill and effort into trying to get it to work than most people ever would. The Nova 7i is a very slick phone, faster and nicer than the Mate 10 Pro (as expected being 2 years newer) while also having ridiculously long battery life. The Nova 7i when always on running the SchildiChat Matrix client and the Conversations Jabber client it will use less than 10% battery in a 8 hour work day. As nice as the Nova 7i is for the core functions I still need to have Play Store apps for LinkedIn, Twitter, Facebook, Zoom, etc. Which meant connecting the Mate 10 Pro via Wifi. As slick as the Nova 7i is for non-Google stuff running it and the Mate 10 Pro is a medium amount of pain for a small amount of freedom. So now I have for the moment abandoned the Nova 7i and gone back to the Mate 10 Pro. What I will try to do is to either forcibly install Google Play on the Nova 7i to make it my proprietary phone or to install an open distribution of Linux (IE not Android) to make it at least a small tablet which incidentally is much more powerful than a PinePhonePro. Issues With the PinePhonePro The battery charges very slowly (as much as 50 hours estimated charge time) and discharges fast. When used in a typical way in Caffeine mode to stop suspend so I can ssh to it etc it won t come close to lasting an 8 hour day. Also it will only take 5V charging and ideally wants 5V 3A charging which most chargers won t do. The charging speed over regular USB ports is very slow, sometimes stating it will take as much as 50 hours to charge. A phone that gets below 50% charge in less than 4 hours and can t be charged at a reasonable speed from a USB port on a laptop or monitor is going to be a major pain to use in the office. I don t think this can be fixed in software, we can alleviate it by making software more CPU efficient and by enabling various hardware sleep modes more effectively but the slow charging is a hardware issue that can t be fixed. The phone call quality is poor. Usually when on a call I hear static and sometimes the person at the other end appears to hear nothing. Also the UI for calls is different from Android which makes it take longer to answer a call and gives more missed calls. The UI issue is a combination of software and habits, both of which can be changed. But the call quality may be a hardware issue. I don t know if it s a hardware issue specific to my phone or something related to the PinePhonePro on the Telstra network. Clicking on notification in the drop-down doesn t take me to the app. I don t know if this is regarded as a bug by the Plasma-Mobile developers. Also notifications aren t displayed on the lock screen and there doesn t seem to be a configuration option to enable this. The Plasma-Mobile configuration for the wifi hotspot is difficult. There is no button for it in the drop-down menu (called Quicksettings in Plasma-Mobile) and no way of easily determining whether it s in hotspot or wifi client mode. This isn t an insurmountable problem and the worst-case is that I could write a script to do it, but it s still annoying. There is apparent support in the desktop version of KDE for syncing contacts from Google and I could probably get that working (although I failed last time I tried on the desktop), but it is a pain. Conclusion Most of the problems are software related and therefore I can get involved in solving them. I plan to keep working on these things. If all the software had worked in an ideal manner then I would have spent more time investigating the hardware issues of battery life and charge time and the quality of calls. I now have my Librem5 [4] running Debian so I will be able to compare call quality with the PinePhonePro. If I m unable to get the PinePhonePro working adequately then maybe making the Librem5 my main phone will be an option. I hope that by early next year I will be able to make another test at using a FOSS phone my main phone. In the mean time I can still work on convergence and other things.

10 October 2023

Julian Andres Klode: Divergence - A case for different upgrade approaches

APT currently knows about three types of upgrades: All of these upgrade types are necessary to deal with upgrades within a distribution release. Yes, sometimes even removals may be needed because bug fixes require adding a Conflicts somewhere. In Ubuntu we have a third type of upgrades, handled by a separate tool: release upgrades. ubuntu-release-upgrader changes your sources.list, and applies various quirks to the upgrade. In this post, I want to look not at the quirk aspects but discuss how dependency solving should differ between intra-release and inter-release upgrades. Previous solver projects (such as Mancoosi) operated under the assumption that minimizing the number of changes performed should ultimately be the main goal of a solver. This makes sense as every change causes risks. However it ignores a different risk, which especially applies when upgrading from one distribution release to a newer one: Increasing divergence from the norm. Consider a person installs foo in Debian 12. foo depends on a b, so a will be automatically installed to satisfy the dependency. A release later, a has some known issues and b is prefered, the dependency now reads: b a. A classic solver would continue to keep a installed because it was installed before, leading upgraded installs to have foo, a installed whereas new systems have foo, b installed. As systems get upgraded over and over, they continue to diverge further and further from new installs to the point that it adds substantial support effort. My proposal for the new APT solver is that when we perform release upgrades, we forget which packages where previously automatically installed. We effectively perform a normalization: All systems with the same set of manually installed packages will end up with the same set of automatically installed packages. Consider the solving starting with an empty set and then installing the latest version of each previously manually installed package: It will see now that foo depends b a and install b (and a will be removed later on as its not part of the solution). Another case of divergence is Suggests handling. Consider that foo also Suggests s. You now install another package bar that depends s, hence s gets installed. Upon removing bar, s is not being removed automatically because foo still suggests it (and you may have grown used to foo s integration of s). This is because apt considers Suggests to be important - they won t be automatically installed, but will not be automatically removed. In Ubuntu, we unset that policy on release upgrades to normalize the systems. The reasoning for that is simple: While you may have grown to use s as part of foo during the release, an upgrade to the next release already is big enough that removing s is going to have less of an impact - breakage of workflows is expected between release upgrades. I believe that apt release-upgrade will benefit from both of these design choices, and in the end it boils down to a simple mantra:

Next.

Previous.