Search Results: "will"

7 January 2012

Stefano Zacchiroli: debian donations-fu

The end of the year is a period of time during which many people sit down and decide to donate some money to initiatives that pursue the public good. I have that habit myself. At the end of 2011 I've decided to donate to Wikipedia, as I consider Wikipedia to be one of the greatest achievements of humanity and I see a lot of value in keeping it running on a purely non-profit basis. (Not to mention that it's already quite annoying to see Jimbo's banners one month per year, go figure what would happen if those banners would suddenly turn into permanent advertisement banners!) You may wonder why I haven't donated to Debian, given my involvement in the project. In fact, that involvement is precisely why I didn't donate to Debian: there is some sort of sanity in keeping a distinction between causes to which I donate my spare time (the case of Debian) and those to which I donate money (the case of Wikipedia), and I like to keep that distinction. As DPL, I've the luxury of being cc:-ed on Debian donation notifications that flow through SPI, and I can also check the flow of donations to other Debian trusted organizations. This year, I've been particularly impressed by the high flow of Debian donations during the end of the year. Thank you, donors, it is thanks to your generosity that we keep many Debian activities going. Using the money people like you regularly donate to Debian we: On a more political note, I'm happy to observe that Debian incomes come almost entirely from private citizens. We do have big corporate sponsors, but their contributions tend to be concentrated as specifically earmarked donations for our annual conference. This is good for them, because they get the fancy banners on the DebConf website and at the conference. But it is also good for Debian, because a donation-based economy (as Debian's, with DebConf exception) is less likely to be influenced by the whims of a few big donors. But with (great) donations comes (great) responsibility. In particular, it comes the need of budget transparency. You can't go out soliciting donations and simply say "thanks, your contribution is appreciated". You need to show donors how their money are used, so that they can judge whether they made the right choice in donating to you or not. Whether they will donate again in the future or not granting long term sustainability to your project usually depends on that. So, if you have donated to Debian or are considering doing so in the future, here are a few of places where you can check what we have been doing with donated money: Albeit quite detailed, the above is not enough: we should do better on the transparency of Debian budget. For one thing, the above is too scattered: budget transparency should not depend on (potential) donors mixing and matching too many sources of information. Further more, the above is not even complete: SPI is not the only Debian trusted organization, and the accessibility of information about Debian budgets hosted at other organizations varies quite a bit. We've been working on improving this for the past year or so: we're not there yet, but I'm positive we can have detailed and comprehensive budgets encompassing all Debian trusted organizations published in the coming months . Why has it taken so long and what could possibly be so difficult about it? I think the cause of the delay is twofold:
  1. The disperse nature of Debian adds some difficulties to regular accounting challenges. Contrary to other FOSS projects I'm aware of, we've many different trusted organizations, each one with its own different way of reporting things. The advantage of such a setup is that we can often avoid the costs of money transfers around the world, costs in which we'd incur had we a single organization holding our assets, say, in the US. Still, having too many organizations is counterproductive. This is why for the past 1.5 years I've been working on consolidating our money assets into as few budgets as possible (avoiding, for instance, to use more than one organization per currency).
  2. We tend to be good at recruiting packaging geeks, but not so good at recruiting other kinds of geeks: budget geeks, artwork geeks, journalist geeks, management geeks, etc. But it is upon those other kinds of "geekness" that many activities of "standard" Debian geeks depend. For example: if you want to have a steady flow of new project members, you need to communicate effectively Debian values and make some buzz around them, so that you could hope they get to the right ears. If you want to organize sprints for maintainers to work together you need money donations, and to solicit donations you need a transparent budget. Etc. In the specific case of accounting, we're now lucky enough to have found "standard" Debian geeks who also have a passion for accounting and auditing; but that appaears to be, essentially, a coincidence. If we don't fix the more general problem, I believe our difficulties in recruiting "non-standard" Debian geeks might hurt us quite a bit in the long run.

Steve Kemp: Review of the Panasonic Lumix FS-16 camera

Recently I've been wanting to replace my old point and shoot camera, a Canon PowerShot A620. I've got a pair of DLSR cameras and I do frequently carry one of them out with me, but there are undoubtedly occasions where I'd rather not bother, or where I find myself wanting to take a picture without having one to hand. Unfortunately the PowerShot is pretty large itself, although significantly less so than the DSLRS I possess. (I cannot remember the last time I used the PowerShot outside my flat, that is how rarely it goes outdoors). The PowerShot has been a good camera to me for many years and the three features I liked the most: Picking a replacement camera, even with the help of fine comparison websites like snapsort.com is hard. Cameras have moved on and "improved" a lot over the last few years - to the extent that finding one with a built-in viewfinder is hard. Finding one with a built-in viewfinder and running on easily replaceable batteries was virtually impossible. Eventually I settled on the Panasonic Lumix FS16, which omits both: The way that you use the LCD or viewfinder differs pretty significantly, but the LCD wasn't as bad as I'd feared:

ViewFinder
You hold the camera to your eye, and press the appropriate buttons.
LCD
You typically hold the camera at arms length, which means you're prone to shaking your hands/arms and getting blurry shots. Because you're holding the camera relatively far away from your eyes if you have the sun at your back you're liable to need to squint.
The LCD on the Lumix FS-16 isn't amazing, but neither is it horrific and it is better than expected in dark locations. So after a week what do I think? On the whole it is a fine camera, better than the PowerShot in many ways, and while it has draw-backs none are deal-breakers:
Size
The best camera is one you have with you; on that basis this camera is a clear win being smaller, lighter, and more compact than the Canon. I've taken this camera with me, randomly, to several places and returned with useful and interesting images.
Low Light
Low light performance is pretty poor. With only one manual control you see noise if you're shooting in gloomy pubs, and outdoors. With the flash you can get acceptable pictures if you're careful - but its a tricky thing to get right. (To update this a little: Outdoors at night? No. In a pub with poor lighting you'll be alright.)
Manual Controls
The camera features precisely two manual controls:
  • "Flash on" vs. "Flash off".
  • ISO can be changed from: Auto, 100, 200, 400, 800, 1200 and 1600.
There is no notion of shutter speed, nor is there any ability to change the aperture size. (Though both these values are displayed on the screen as you take a picture I wonder why? As you can't change anything you can't use the information in any useful fashion, and presumably a non-camera-person wouldn't understand what these numbers represent.) The lack of these two controls is a little galling, but pretty common for the low-end P&S cameras.
Video Recording
There is no external MIC so sounds aren't great, but they're not horrible either. Video recordings are limited to the smaller of 8 minutes or 2Gb. So no long films, but short ones look fine. Just be aware that once you start recording focus won't change, nor will zooming work. Compared to the canon the quality is improved; but the Canon allowed you to (optically) zoom whilst recording. Here you can only zoom with your feet.
Recharging Time
When I received the camera it took about an hour to charge. The battery life seems reasonable - the level is 2/3 a week later and I've been shooting, reviewing, and deleting regularly. (Note: I never use USB to transfer pictures, I always remove the card and plug it into my PC. Whether this makes a difference to battery life I don't know.)
Controls
Physical controls are reasonable. There is a mechanical slide-switch to turn on/off. I like that, as it is less prone to being knocked by keys, change, etc. There is also a physical slide-switch to change from "shoot" to "review current images/videos". (Same as my Canon) I think this is a mistake, and don't see why it can't be a soft-button.
Full Auto
There are several modes available in the camera (remember the caveat about lack of aperture/shutter speed) I've been using both full-auto and manual modes, and both are good. Full auto would suit most people - it has clever face-tracking.
Focusing Speed
As expected this is not stellar. Walking to the corner shop the other lunchtime I found a cat in the road, I talked to her and she rubbed herself against my ankles. Could I focus fast enough to catch her looking up at me? No. For static scenes, and candid shots of people it'll suffice. For fast action and moving children probably not a chance.
On balance, the upgrade was worthwhile. ObQuote: "I don't mean to lecture and I don't mean to preach. And I know I'm not your father..." - Spider-Man

Christian Perrier: [life] [running] 2011 summary

That time of the year comes where I summarize my running activities. It's now 4.5 years that I resumed running, after nearly 10 years without active sports. Apparently, things continue to improve, though I'm logically reaching my limits in some way. I finally missed the 2500km mark by 14 kilometers, mostly because of a cold I had during the last 2 days of the year. The grand total is thus 2486 kilometers run, in 237 hours (9 days 21hours), at about 10.5km/h. The climbed height difference is 27700 meters, so about three times the altitude of Mount Sagarmatha..:-) This was achieved in 294 "activities". That seems to be a lot (nearly 1 activity per day): indeed, there are days where I have up to 4 activities, when I run to/back work, which means two runs in the morning (3+4km) and two in the evening. If I count the number of days where I had at least one running activity, this lowers to 181. In short, I ran about every 2 days. Indeed, along the year, the biggest timeframe between two runs has been 7 days. In short, I ran at least once every week during this year. The most active month was July with 272km and the less active was September with 163.5. When counted by distance, this summarizes to: When it comes at results, I ran 8 official races during the year : two "ultra" races (70km Le Puy-Firminy in November, by night and 55km Paris Ecotrail), two marathons (Paris, two weeks after Ecotrail, and Berlin in September), one 35km trail race (Trail des Cerfs in May), two half-marathons and one 12km cross-country race in my hometown. The seasons "peaks" were clearly the Ecotrail+Paris Marathon succession in March/April, the Berlin marathon in September and my longest race ever in November. Most were as successful as I expected, except maybe Berlin marathon, were I was secretly hoping to break my record (indeed, I can still be proud of running in the same race than Patrick Makau breaking the world record in 2h03'38"). An injured ankle unfortunately prevented me to prepare it as serously as I was hoping. This year was indeed the first year where I was trying to go beyond the marathon distance as another challenge. And, believe me, ultra distances are really fun (yes, running 9 hours by night *is* fun!). Indeed, I only regret not breaking one of my best times (either half-marathon or marathon). I'll try to do that in 2012. How about next^W this year? Well, my goals are currently being secured: Busy program....I cross fingers for no injury to come and disturb all this.

Christian Perrier: Towards 100% in wheezy for debconf translations

This article could become one of my recurring "let's make noise about translators work" articles. You've been warned. In Squeeze, a few languages reached full completion of debconf strings, those "questions" that are asked during packages installation or upgrades. This can be followed here (for unstable: we don't have an online status page for testing).. Many of you, particularly those who aren't bored at reading me, know that I like pushing this friendly "competition" as a good way to encourage progress in localization of that part of Debian. As of now, we have really good and active teams that are able to maintain a great completion in this. Several of them are likely to reach full 100% completion for wheezy. Let's look at the current status: I hope this maybe gave you the idea of joining these efforts. Please pop up on one of the i18n mailing lists if you're interested, and if you don't know where to start, then debian-i18n< is what you're looking for. See you soon!

Craig Small: rpath bites me again

Debian OpenLogo

Image via Wikipedia

It s funny, in bad way, when certain sorts of bugs come back to bite you. People may remember the fun debian had with rpath issues around in the late 90s where some binaries wanted to set the path of where their libraries were located. After much contraversy the consensus was at least in Debian (with some specific exceptions) RPATH is bad and don t use it. I lived through that fun and remember hacking libtool or autoconf or some such file. The horror of those times came back to haunt me today while working on procps 3.3.2 packages. lintian was suddenly complaining that binary-or-shlib-defines-rpath for all my binaries. I ve not seen rpath set for many years and as I m also part of the upstream and never saw it set there it took me a while to work out what was going on. Certainly, my binaries were setting the RPATH, it wasn t lintian getting the wrong idea. You can see this with objdump myfile grep RPATH. If you get a hit, you got RPATH set, an empty result means no RPATH. libtool was definitely setting the rpath, with
cc -Iproc -g -O2 -o \$progdir/\$file pmap.o  ./proc/.libs/libprocps.so \
 -Wl,-rpath -Wl,/home/csmall/debian/procps/procps/proc/.libs \
 -Wl,-rpath -Wl,//usr/lib/x86_64-linux-gnu
That s not one rpath setting but two, for double insult. Configure flags such as disable-rpath wouldn t work. I flicked back to a pure upstream archive and there was no rpath there in either the compile flags or objdump. There was obviously some sort of side-effect going on. The problem, after much testing, was in the debian/rules file:
        ./configure \
          --build=$(DEB_BUILD_GNU_TYPE) \
          --enable-watch8bit --enable-w-from \
          --prefix=/ \
          --mandir=\$$ prefix /usr/share/man  \
          --libdir=\$$ prefix /usr/lib/$(DEB_HOST_MULTIARCH)
The problem is above, and all it was was a / . libtool does some checking to see if the library directory exists and if it doesn t silently turns on rpath. It s not smart enough to know that //usr/lib/x86_64-linux-gnu is the same as /usr/lib/x86_64-linux-gnu and so it enables rpath. Removing the slash before the usr fixed the problem. I d say this is bad behavour on libtools part. It should know that / is // or all the other alternative ways of specifying paths. Hopefully this post will stop someone else wasting their time like I did.

Paul Wise: apt-get purge defoma

Debian is finally transitioning from the unmaintained and Debian-specific font manager called defoma. The replacement is called fontconfig and it is maintained upstream and in Debian (by upstream) and is cross-distribution with wide support from our upstreams and other distributions. With the upload of libwmf 0.2.8.4-9 (thanks Lo c!) the last package in Debian sid declaring a strict dependency on defoma has removed this dependency. There is still more to do, some more bugs to file and some lenny->squeeze->wheezy upgrade testing to do. Thanks go to Christian PERRIER for slogging through and providing encouragement, bug reports and NMUs. The transition is unfortunately not without loss of functionality; TeX uses a different directory for fonts to the rest of the system. Fonts used by TeX cannot be used by the rest of the system and vice versa. This issue has always existed in Debian and other distributions and is unrelated to the removal of defoma. If your software doesn't use one of the text renderers (such as Pango, Qt or QuesoGLC) that find fonts on their own and fall back on other fonts where needed (due to missing fonts or glyphs), please switch text rendering systems. If you are unable to switch, please use fontconfig to search for font filenames rather than hard-coding them at build time. This message brought to you by the Debian Fonts Task Force. We welcome people who want to help us maintain font packages or improve support and quality assurance for fonts and font related software.

6 January 2012

Mark Brown: regmap updates in 3.2

Version 3.1 of the Linux kernel was the first release to include regmap support and only included a bare minimum of features in order to ease review so version 3.2 has been a pretty big one for regmap development with some pretty major features being built on top of the core code.

Steve Kemp: Tonight I've mostly been using Sinatra

This evening I've mostly been using Sinatra to build a little file storage service which uses a REST API. That means I can upload a file:
skx@birthday:~/hg/sinatra$ curl -X PUT -F file=@/etc/fstab http://localhost:4567/
 "id":"dbd1bdc11b5a1a8e80588a135648b4c2edffb49a","path":"/" 
Download that same file:
skx@birthday:~/hg/sinatra$ curl -X GET -F id=dbd1bdc11b5a1a8e80588a135648b4c2edffb49a  \
   http://localhost:4567/
# /etc/fstab: static file system information.
..
/dev/cdrom        /media/cdrom0   udf,iso9660 user,noauto     0       0
Get an index of files:
skx@birthday:~/hg/sinatra$ curl http://localhost:4567/
[ "id":"dbd1bdc11b5a1a8e80588a135648b4c2edffb49a","type":"file" ]
And finally we can delete a file:
skx@birthday:~/hg/sinatra$ curl -X DELETE -F "id=dbd1bdc11b5a1a8e80588a135648b4c2edffb49a" \
  http://localhost:4567/
Removed
We can also upload to different paths so we can replicate a file-system if we wanted to. (I added in "type" to hold either "file" or "directory", though I guess if we were to code up a FUSE client we'd want to store things like ctime, UID, GID, etc. THe list operation will show both files and sub-directories) The code was trivial once I got the hang of Sinatra, and I'm pretty pleased with it so far. I don't yet need to use it for anything, but I'm thinking of unifying the way that I store images on a couple of sites - and fetching them via JSON and Javascript might be an option this was an experiment in that direction. (Though I'd probably want to hook in rsync so we replicated the eventual upload location for safety.) In other news I've been all organized and upgraded the kernel on my guest:
steve@steve:~$ uptime
 22:00:28 up  4:18,  1 user,  load average: 0.14, 0.05, 0.05
steve@steve:~$ uname -r
3.2.0-kvm-hosting.org-i386-20120106
So for once I'm up to date with a cutting edge kernel. Happy times. ObQuote: "How you expect to run with the wolves come night when you spend all day sparring with the puppies? " - The Wire (Omar)

Matthew Garrett: Firmware bugs considered enraging

Part of our work to make it possible to use UEFI Secure Boot on Linux has been to improve our EFI variable support code. Right now this has a hardcoded assumption that variables are 1024 bytes or smaller, which was true in pre-1.0 versions of the EFI spec. Modern implementations allow the maximum variable size to be determined by the hardware, and with implementations using large key sizes and hashes 1024 bytes isn't really going to cut it. My first attempt at this was a little ugly but also fell foul of the fact that sysfs only allows writes of up to the size of a page - so 4KB on most of the platforms we're caring about. So I've now reimplemented it as a filesystem[1], which is trickier but avoids this problem nicely.
Things were almost working fine - I could read variables of arbitrary sizes, and I could write to existing variables. I was just finishing hooking up new variable creation, but in the process accidentally set the contents of the Boot0002 variable to 0xffffffff 0xffffffff 0x00000000. Boot* variables provide the UEFI firmware with the different configured boot devices on the system - they can point either at a raw device or at a bootloader on a device, and they can do so using various different namespaces. They have a defined format, as documented in chapter 9 of the UEFI spec. At boot time the boot manager reads the variables and attempts to boot from them in a configured order as found in the BootOrder variable.

Now, obviously, 0xffffffff 0x00000000 is unlikely to conform to the specification. And when I rebooted the machine, it gave me a flashing cursor and did nothing. Fair enough - I should be able to choose another boot path from the boot manager. Except the boot manager behaves identically, and I get a flashing cursor and nothing else.

I reported this to the EDK2 development list, and Andrew Fish (who invented EFI back in the 90s) pointed me at the code that's probably responsible. It's in the BDS (Boot Device Selection) library that's part of the UEFI reference implementation from Intel, and you can find it here. The relevant function is BdsLibVariableToOption, which is as follows (with irrelevant bits elided):
BdsLibVariableToOption (
  IN OUT LIST_ENTRY                   *BdsCommonOptionList,
  IN  CHAR16                          *VariableName
  )
 
  UINT16                    FilePathSize;
  UINT8                     *Variable;
  UINT8                     *TempPtr;
  UINTN                     VariableSize;
  VOID                      *LoadOptions;
  UINT32                    LoadOptionsSize;
  CHAR16                    *Description;
  //
  // Read the variable. We will never free this data.
  //
  Variable = BdsLibGetVariableAndSize (
              VariableName,
              &gEfiGlobalVariableGuid,
              &VariableSize
              );
  if (Variable == NULL)  
    return NULL;
   
So so far so good - we read the variable from flash and put it in Variable, Variable is now 0xffffffff 0xffffffff 0x00000000. If it hadn't existed we'd have skipped over and continued. VariableSize is 12.
  //
  // Get the option attribute
  //
  TempPtr   =  Variable;
  Attribute =  *(UINT32 *) Variable;
  TempPtr   += sizeof (UINT32);
Attribute is now 0xffffffff and TempPtr points to Variable + 4.
  //
  // Get the option's device path size
  //
  FilePathSize =  *(UINT16 *) TempPtr;
  TempPtr      += sizeof (UINT16);
FilePathSize is 0xffff, TempPtr points to Variable + 6.
  //
  // Get the option's description string size
  //
  TempPtr     += StrSize ((CHAR16 *) TempPtr);
TempPtr points to 0xffff 0x0000, so StrSize (which is basically strlen) will be 4. TempPtr now points to Variable + 10.
  //
  // Get the option's device path
  //
  DevicePath =  (EFI_DEVICE_PATH_PROTOCOL *) TempPtr;
  TempPtr    += FilePathSize;
TempPtr now points to Variable + 65545 (FilePathSize is 0xffff).
  LoadOptions     = TempPtr;
  LoadOptionsSize = (UINT32) (VariableSize - (UINTN) (TempPtr - Variable));
LoadOptionsSize is now 12 - (Variable + 65545 - Variable), or 12 - 65545, or -65533. But it's cast to an unsigned 32 bit integer, so it's actually 4294901763.
  Option->LoadOptions = AllocateZeroPool (LoadOptionsSize);
  ASSERT(Option->LoadOptions != NULL);
We attempt to allocate just under 4GB of RAM. This probably fails - if it does the boot manager exits. This probably means game over. But if it somehow succeeds:
CopyMem (Option->LoadOptions, LoadOptions, LoadOptionsSize);
we then proceed to read almost 4GB of content from uninitialised addresses, and since Variable was probably allocated below 4GB that almost certainly includes all of your PCI space (which is typically still below 4GB) and bits of your hardware probably generate very unhappy signals on the bus and you lose anyway.

So now I have a machine that won't boot, and the clear CMOS jumper doesn't clear the flash contents so I have no idea how to recover from it. And because this code is present in the Intel reference implementation, doing the same thing on most other UEFI machines would probably have the same outcome. Thankfully, it's not something people are likely to do by accident - using any of the standard interfaces will always generate a valid entry, so you could only trigger this when modifying variables by hand. But now I need to set up another test machine.

[1] All code in Linux will evolve until the point where it's implemented as a filesystem.

comment count unavailable comments

Mirco Bauer: Smuxi 0.8.9 "One Giant Leap" Release

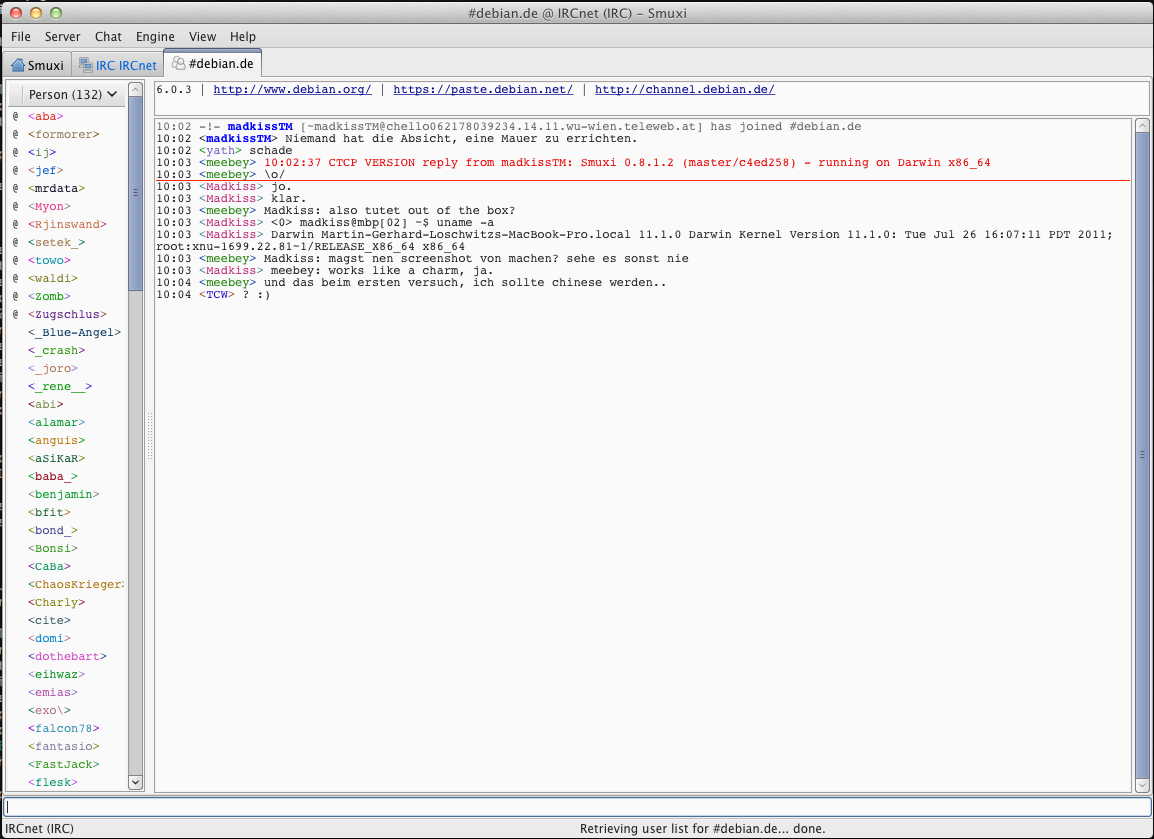
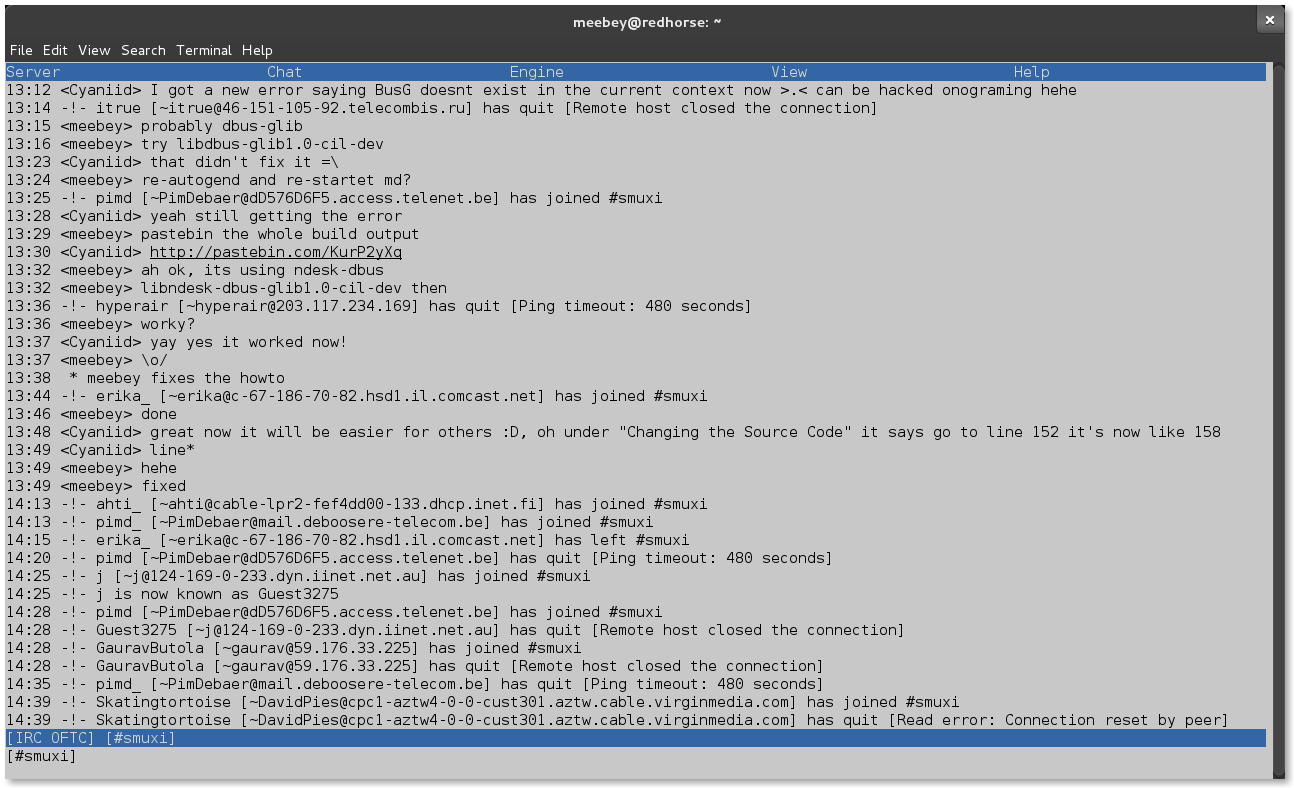
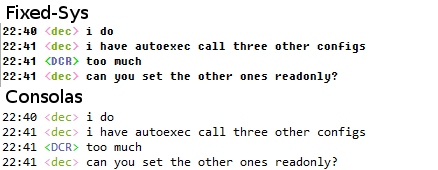
Just in time for 2012 I am very pleased to announce Smuxi 0.8.9 codenamed "One Giant Leap". During the development 56 bug reports and 33 feature requests in 593 commits were worked on making this release a major milestone of the Smuxi project. At the Chaos Communication Congress (28C3) in Berlin I was doing the final development sprint to get 0.8.9 done, which was a very intensive and refreshing experience. Here are the highlights of this release: Development Builds / Rolling Releases After the 0.8 release it became clear that a continious and short development -> test cycle is important to keep the project going quickly. At some point I have received requests if the project is dead while it was more active than ever. The lack of new releases (for about 15 months) lead to this wrong impression. Thus Smuxi can be obtained from development builds now. This includes daily builds for Debian (Squeeze, Wheezy, Sid), Ubuntu (Lucid, Maverick, Natty, Oneiric, Precise) and Windows. Thanks goes to Hannes Tismer for providing the Windows autobuilder and to Canonical for the PPA autobuilder. We invite everyone to use these daily builds to keep track of the latest development of Smuxi. Issues and regressions are fixed in a very short period (usually the same day). Thanks to our users who ran development builds and reported issues which led to many bug fixes prior to this release. On the other hand one of my New Year's resolutions are to "release early, release often" So there should be no nerd left behind... Screenshot of Smuxi 0.8.9 on Mac OS X Mac OS X support With the help of Steven McGrath (Steve[cug]) who created the initial Mac OS X installer for Smuxi we now have official support for Mac OS X. The download page contains the instructions how to obtain and install Smuxi on Mac OS X. This makes the 4th platform where Smuxi can be used on besides Windows, Linux and *BSD. For now Smuxi 0.8.9 doesn't feel as native as it could as it relies on the GTK+ port. We are looking into enhancing the experience though, just stay tuned. Chat History on Disk (Beta) The most exciting feature in this release I think are the "persistent message buffers". With this feature I could solve one of the biggest drawbacks IRC ever had: IRC does not retain any messages you have sent or received. All messages are only relayed to all users. The issue is that if you close your IRC client or even just leave a channel, all your received messages are gone. One workaround in most clients was to create text log files which then contains the chat history, but it is annoying and not user-friendly to open some text file somewhere from your disk to read the history outside of your IRC client. Now with Smuxi 0.8.9 you no longer have this issue, all chat history gets automatically written and read to a message database when you start Smuxi, join channels or open queries! As this feature is not fully stable yet it is not enabled by default. If you want to try it go to: File -> Preferences -> Interface and change "Persistency Type" from "Volatile" to "Persistent", hit OK and restart Smuxi. Now all messages are saved into the database and will automatically be shown. Click here for a screencast of this feature Jabber / XMPP Support (Beta) You probably have friends not on IRC and Twitter, say on Jabber, gTalk or Facebook? This is where the new XMPP engine of Smuxi comes into play. You can send and receive messages to/from them now! The implementation is far from complete, though. It has no buddy list for example and needs only to be treated as a technical preview of what will be coming in future Smuxi releases. Click here for a screencast of this feature Screenshot of Smuxi's Text Interface Text Interface (Alpha) This is the first release that contains a text frontend based on the STFL library. STFL is a library that uses ncurses to draw text based user interface using a markup language (like Glade for GTK+). This frontend is in early alpha state and lacks a lot of interface features and likes to crash. It is still included to attract potential developers who want to enhance this frontend. The frontend can be enabled by passing --enable-frontend-stfl to the configure script and then by executing smuxi-frontend-stfl. NetworkManager Support Everyone with a laptop knows how annoying it can be to suspend and resume when network based applications suddenly go crazy because they have lost the connection and either spew errors or take forever to get back in shape. Smuxi will now detect the network state right away with the help of the new Network Manager support. It automatically reconnects when needed right away for you. Next Generation Internet Support You can now connect to IRC servers using the IPv6 protocol Enhanced Find Group Chat Support Users had real issues to find out how to search for channels, thus Bianca Mix added a neat feature. The /list command will now simply open the Find Group Chat dialog for you. This way everyone used to IRC will find it in no time. Searching for channels on freenode wasn't working correctly, this is now fixed. Smuxi also supports the SAFELIST feature of the IRC protocol now which allows to retrieve a full channel list and do client side search which makes consecutive searches much faster. Enhanced Windows Experience For a long time you could not use Smuxi with the latest GTK# version of 2.12.10 on Windows. The issue was that Smuxi relied on SVG support which 2.12.10 no longer had. Smuxi is no longer using SVG instead it uses pre-scaled PNG images thus it works just fine with GTK# 2.12.10 on Windows now. At the same time the issue that the maximized state of the main window was left when restoring from task bar is fixed with GTK# 2.12.10. Screenshot of Fixed-Sys vs Consolas font Smuxi used by default the FixedSys font on Windows to give it the typical IRC look most people are used to. Since Windows Vista there is a better console-like font available called Consolas. Smuxi will now use the Consolas font instead on Windows Vista or later. Another important enhancement is that Smuxi no longer has issues with multiple GTK+ installs on the same computer, which was getting more common with more popular ported GTK+ applications such as GIMP or Pidgin. SSL for IRC fixed IRC with SSL was only working with the default port of 6697. Thanks to Jo Shields now any port can be used with SSL. Crash Related Issues Desktop notifications could crash Smuxi in case of errors related to the notification system or an absent notification daemon. There was a chance that the crash dialog simply disappeared which made reporting bugs more difficult no longer happens. Rapid use of ctrl+w, /window close (Jimmie Elvenmark) and opening the Find Group Chat dialog on the Smuxi tab do no longer crash. Also number-only network names, /network switch freenode and GTK+ install without SVG support no longer lead into a crash. Enhanced Notice Handling Notices will no longer open query tabs for you instead it will show them on tabs you share with the person who sent it with the server tab as fallback. This also avoids ChanServ, NickServ and spammy IRCop tabs. Twitter fixes Twitter made some changes to their API which broke the Twitter support of Smuxi 0.8. This was taken care of and also a few other issues were solved allowing Smuxi 0.8.9 to work smoothly with Twitter again. Extended Keybindings Smuxi allows now to use the ctrl+tab / ctrl+shift+tab and ctrl+n / ctrl+p keys to switch tabs. The keybindings still work even with a hidden menu bar now. Smuxi Server specific highlights More interactive and much faster synchronization When connecting to a smuxi-server you had to wait till Smuxi finished the synchronization before you could use the interface. Also you could not tell how far the synchronization was and just had to wait till it was completed. With Smuxi 0.8.9 the connect just takes a few seconds and all chats are synchronized in the background with a progress bar so you can use the interface from the first moment on and know how far it is. The speed how much it takes to synchronize all chats also reduced drastictly by 400%! Click here for a screencast of this feature More background communication When using a smuxi-server the interface sometimes had load times like when opening the preferences or when using the nickname completion (Andrew Kannan). These operations are done in the background and no longer blocks the interface. Also when the communication is lost to the smuxi-server the frontend will now automatically reconnect to it in the background. Low Bandwidth Mode When it comes to mobile internet connectivity such as UMTS/HSDPA, Edge and GRPS it can be a real pain to connect to the smuxi-server as it has to transfer all the messages over that. If you just want to ask someone you know then you don't need any old messages to do that. With the "Low Bandwidth Mode" you can now connect to the smuxi-server without loading old messages which makes the connect very quick. You find this option in the engine connect dialog. Stable Protocol Initially I didn't plan to make the protocol of Smuxi stable before the 0.9 release, but as it turned out the 0.8 protocol was good enough to still use it and for that reason Smuxi 0.8.9 is still compatible with 0.8. The 0.8 protocol will see no breakages, instead the next protocol will be on-top or opt-in of the current one. This means future Smuxi versions stay compatible with it. Shutdown Command You can now shutdown the smuxi-server if you like using the /shutdown command. It it safe to use the command, it will do a clean shutdown sequence for you. For example it makes sure all messages are written to disk in the case of enabled persistent message buffers. If you have your smuxi-server daemon monitored (e.g. with runit) it can also automatically be restarted and upgraded this way. Built-in SSH Keyfile Support It is no longer needed to fiddle with the .ssh/config file or pagent to get SSH key authorization working. You can now simply tell Smuxi which SSH keyfile you want to use to connect to your smuxi-server. Updated Translations
  • Catalan (Siegfried-Angel Gevatter Pujals)
  • Danish (Joe Hansen)
  • Finnish (Kalle Kaitala)
  • French (Cl ment Bourgeois)
  • German (Bianca Mix)
  • Italian (Vincenzo Campanella)
  • Portuguese (Americo Monteiro)
  • Spanish (Castilian) (Ricardo A. Hermosilla Carrillo)
New Translations
  • Chinese Simp (Dean Lee)
  • Slovak (Tom Vadina)
  • Swedish (Jimmie Elvenmark)
  • partially Russian (Aleksandr P)
  • partially Turkish (Umut Albayrak)
  • partially Urdu (makki)
Contributors Contributors to this release are the following people:
  • Mirco Bauer (497 commits)
  • Tuukka Hastrup (10 commits)
  • Bianca Mix (10 commits, translations)
  • Cl ment Bourgeois (8 commits, translations)
  • Andrius Bentkus (5 commits)
  • Carlos Mart n Nieto (3 commits)
  • Jimmie Elvenmark (3 commits, translations)
  • Hannes Tismer (1 commit)
  • Jonathan Pryor (1 commit)
  • Jo Shields (1 commit)
  • Siegfried-Angel Gevatter Pujals (translations)
  • Dean Lee (translations)
  • Aleksandr P (translations)
  • Americo Monteiro (translations)
  • Andrew Kannan (translations)
  • Joe Hansen (translations)
  • Kalle Kaitala (translations)
  • makki (translations)
  • Ricardo A. Hermosilla Carrillo (translations)
  • Tom Vadina (translations)
  • Umut Albayrak (translations)
  • Vincenzo Campanella (translations)
Thank you very much for your contributions to Smuxi! After reading this whole pile of text, head over here and grab this smexy stuff!
Posted Sun Jan 1 22:58:29 2012

Vincent Fourmond: Graphical connection to a Mac from Linux

For my lab work, I have developed an (almost) cross-platform program based on Qt4 that help us analyze our data. One of the motivations to use Qt was the ability to port the program to other platforms, and in particular MacOSX (half of my team uses them). After installing the required development tools using MacPorts (mind you, the MacOS version of the development tools, not the X11 one), I was able to compile and run the program without a single code change on my bosses' Mac. But here come problems: several things do not work the same way in Mac and in Linux (whereas it should, I think), so additional tweaking and debugging will be necessary.This is where the problem comes in: I don't own a Mac and don't intend to, so I need to connect to my bosses' Mac in order to perform testing. How can I connect to a Mac display ? X11 connection won't work, since my application is a Mac application and not a X11 one. I had him turn on screen sharing (the most basic tick box), which sets up a VNC server on the Mac. Unfortunately, when I connect using the command-line VNC clients available for debian, ie vncviewer (from the packages xvnc4viewer or xtightvncviewer), I get the following problems:

~ vncviewer chrismac
VNC Viewer Free Edition 4.1.1 for X - built Mar 10 2010 22:31:05
Copyright (C) 2002-2005 RealVNC Ltd.
See http://www.realvnc.com for information on VNC.
Wed Dec  7 10:40:41 2011
 CConn:       connected to host chrismac port 5900
 CConnection: Server supports RFB protocol version 3.889
 CConnection: Using RFB protocol version 3.8
 CConnection: No matching security types
 main:        No matching security types

The good news is that remmina is able to connect graphically, although for me it required that I set the display depth to 24 bits (else it seems to connect, but the connection dies immediately). Great, I'll be able to debug, then...
Edit: after a while, I found out that remmina had some drawbacks when connecting to a Mac, such as, at least in my case, a weird problem with Shift: once I hit Shift, I'm never able again to type in lowercase characters, which is quite painful. I tried also Vinagre, who handled that better (but had some quite painful freezing moment), so I must say that I finally found a client I'm happy with: gtkvncviewer.

Timo Jyrinki: I have a new GPG key


-----BEGIN PGP SIGNED MESSAGE-----
Hash: SHA1,SHA512

Hello,

I'm transitioning from my 2003 GPG key to a new one.

The old key will continue to be valid for some time, but I eventually
plan to revoke it, so please use the new one from now on. I would also
like this new key to be re-integrated into the web of trust. This message
is signed by both keys to certify the transition.

The old key was:

pub 1024D/FC7F6D0F 2003-07-10
Key fingerprint = E6A8 8BA0 D28A 3629 30A9 899F 82D7 DF6D FC7F 6D0F

The new key is:

pub 4096R/90BDD207 2012-01-06
Key fingerprint = 6B85 4D46 E843 3CD7 CDC0 3630 E0F7 59F7 90BD D207

To fetch my new key from a public key server, you can simply do:

gpg --keyserver pgp.mit.edu --recv-key 90BDD207

If you already know my old key, you can now verify that the new key is
signed by the old one:

gpg --check-sigs 90BDD207

If you don't already know my old key, or you just want to be double
extra paranoid, you can check the fingerprint against the one above:

gpg --fingerprint 90BDD207

If you are satisfied that you've got the right key, and the UIDs match
what you expect, I'd appreciate it if you would sign my key:

gpg --sign-key 90BDD207

Lastly, if you could send me these signatures, i would appreciate it.
You can either send me an e-mail with the new signatures by attaching
the following file:

gpg --armor --export 90BDD207 > timojyrinki.asc

Or you can just upload the signatures to a public keyserver directly:

gpg --keyserver pgp.mit.edu --send-key 90BDD207

Please let me know if there is any trouble, and sorry for the inconvenience.

(this post has been modified from the example at
http://www.debian-administration.org/users/dkg/weblog/48)

-----BEGIN PGP SIGNATURE-----
Version: GnuPG v1.4.11 (GNU/Linux)

iEYEARECAAYFAk8GuZoACgkQgtffbfx/bQ9nqACglWyHnDTFQfdKmz8OCd3oL6iR
hcEAmgKJ7RZsgwxwkRGPhygy5y1Ztb+3iQIcBAEBCgAGBQJPBrmaAAoJEOD3WfeQ
vdIHdVQQAMT1yvIogzbtK6sUnWqwbrXI9pDEFk7AzJTb80R+wzxsw7gu9gcBDk8G
BL2O26GKUqKWA3ytuApSl42FJam/Lusi9npT3XNkmHs6FaBMNuLYrqEXmCwXwWr/
OrLyeeLiF4yxgbNWbv+600BqAWqFlo6NeTgQKsJWtCjR3RVMxX3R8nzjDnKJuF+z
c6+2JKBWyx/HVUKcJpJrFDDR36HRFvVJomTuma2JCQ/RAl9vzAguqNYOi1QkuuQv
EF1gXH7gLifukGuwquP1DHP6SWWkj77jtRWr5ewC0xymbrArzAwKbvMQl3VpKBHh
MmpJjYP3ECyL14AKi/TY2Lidi0Sf6yqFMcPcreoih01N0OU0NXmD4IrHMT24/ssb
okDUe1o3YImjGq1jTACvlzC8s54EfLsqDgSP98SGVpuoDqPJUwVk4nuHj8q0vDSs
qZox26gVwB2FAOUi1BFiZbIzM5rsyYfCGyWUGiAwBFf54lYRAeCDCt8iAOOL1Ov/
TumIGYdLoXnDuOJq1VjXLGx2OFDrpyU8SPGoa3zNEVz39tgxQ48ASJEqcqt7HvBy
IW+TTsMLdJ1Ait9aCM3mzzr1iwP8TrL0qUsdRLOE6AKdAqocIfqXY8OeDKhbUiOJ
CXWk5q3xheK3sDWUXX7J63bAAUH4jFnpQEOVMJKBUNMKsWa0iXDS
=mklN
-----END PGP SIGNATURE-----

Craig Small: procps-ng version 3.3.2 released

procps-ng version 3.3.2 was released today. This version fixes some bugs introduced in version 3.3.1 as well as a number of enhancements. Below is the most significant set of changes that 3.3.2 brings. NLS The most visible change is that procps-ng is now international. The NLS changes took a long windy path but we got there in the end. This means all procps-ng programs can now use standard gettext PO files to output in any supported language. While the programs have been enabled for translations, there are no po files as yet but we expect them to follow soon. Library Changes procps always had a closed library, meaning that it wasn t supposed to be used for other non-procps programs. This meant the library was always called libprocps-(version) rather than using a SONAME. Procps 3.3.2 now uses a SONAME of version 0.0.0 The API hasn t changed but it will be in subsequent versions. Patch Backporting Due to the stagnant natute of procps development in the past, there have been a large number of patches each distribution carries for procps. A significant number of patches have been incorportated into procps-ng, giving a more consistent look across the distributions and meaning any subsquent fixes or enhancements are done in one place. A major goal of procps-ng was to reduce the number of distribution specific patches which this change has helped greatly. debian Packages The Debian packages will be worked on soon and will clear up some confusion about the procps binaries and library packages as this will now be split into two. It also means that some programs that depend on libprocps will break, but going on from this point will be able to use the normal shlibs process to manage that, rather than the ugly crunch we will have now.

Robert Collins: Public service announcement: signals implies reentrant code even in Python

This is a tiny PSA prompted by my digging into a deadlock condition in the Launchpad application servers. We were observing a small number of servers stopping cold when we did log rotation, with no particularly rhyme or reason. tl;dr: do not call any non-reentrant code from a Python signal handler. This includes the signal handler itself, queueing tools, multiprocessing, anything with locks (including RLock). Tracking this down I found we were using an RLock from within the signal handler (via a library ) so I filed a bug upstream: http://bugs.python.org/issue13697 Some quick background: when a signal is received by Python, the VM sets a status flag saying that signal X has been received and returns. The next chance that thread 0 gets to run bytecode, (and its always thread 0) the signal handler in Python itself runs. For builtin handlers this is pretty safe e.g. for SIGINT a KeyboardInterrupt is raised. For custom signal handlers, the current frame is pushed and a new stack frame created, which is used to execute the signal handler. Now this means that the previous frame has been interrupted without regard for your code: it might be part way through evaluating a multi-condition if statement, or between receiving the result of a function and storing it in a variable. Its just suspended. If the code you call somehow ends up calling that suspended function (or other methods on the same object, or variations on this theme), there is no guarantee about the state of the object; it becomes very hard to reason about. Consider, for instance, a writelines() call, which you might think is safe. If the internal implementation is for line in lines: foo.write(line) , then a signal handler which also calls writelines, could have what it outputs appear between any two of the lines in writelines. True reentrancy is a step up from multithreading in terms of nastiness, primarily because guarding against it is very hard: a non-reentrant lock around the area needing guarding will force either a deadlock, or an exception from your reentered code; a reentrant lock around it will provide no protection. Both of these things apply because the reentering occurs within the same thread kindof like a generator but without any control or influence on what happens. Safe things to do are: In Launchpad s case, we will be setting a flag variable unconditionally from the signal handler, and the next log write that occurs will lock out other writers, consult the flag, and if needed do a rotation, resetting the flag. Writes after the rotation signal, which don t see the new flag, would be ok. This is the only possible race, if a write to the variable isn t seen by an in-progress or other-thread log write. That is all.

5 January 2012

Michal &#268;iha&#345;: ColorHug client in unstable

It took me much more uploads than I expected, but ColorHug client is finally in unstable. I was fighting with various bugs, which I could not reproduce locally and of course with my own stupidity in configuring pbuilder. Anyway the buildds overview now shows mostly green, so this is good. The remaining ones mostly wait for libgusb, which needs build on armhf and needs to be ported to non Linux (or rather libusb needs to exist there). One of things I've learned on the way is that docbook-utils is not enough to convert docbook to man pages, you need docbook package as well. Still I don't understand why this did locally work for me... The one outstanding issue is that client code assumes it runs on little endian host (or rather same endianity as the ColorHug device) and thus will break on PPC and other big endian machines. The upstream is aware of that an I even managed to produce patch which should fix it, though I have no means to test it (lack of big endian hardware and lack of the ColorHug device itself).

Filed under: Debian English 4 comments Flattr this!

Patrick Schoenfeld: Bringing GVFS to a good use

One of the GNOME features I really liked since the beginning of my GNOME usage is the ability to mount various network file system by a few clicks and keystrokes. It enables me to quickly access NFS shares or files via SFTP. But so far these mounts weren't actually mounts in a classical sense, so they were only rudimentary useful.

As a user who often works with terminals I was always halfway happy with that feature and halfway not:

- Applications have to be aware and enabled to make use of that feature, so its often neccessary to workaround problems (e.g. movie players not able to open a file on a share)
- No shell access to files

Previously this GNOME feature was realised with an abstraction layer called GNOME VFS, which all applications needed to use if they wanted to provide access to the "virtual mounts". It did no efforts to actually re-use common mechanisms of Un*x-like systems, like mount points. So it were doomed to fail at certain degrees.

Today GNOME uses a new mechanism, called GVFS. Its realized by a shared library and daemon components communicating over DBUS. At first glance it does not seem to change anything, so I was rather disappointed. But then I heard rumors, that Ubuntu was actually making these mounts available in a special mount point in ~/.gvfs.
My Debian GNOME installation were not.

So I investigated a bit and found evidence about a daemon called gvfs-fuse-daemon, which eventually is handling that. After that I figured this daemon to be in a package called gvfs-fuse and learned that installing it and restarting my GNOME session is actually all needed to do.
Now getting shell access to my GNOME "Connect to server" mounts is actually possible, which makes these mounts really useful after all. Only thing to find out is, if e.g. the video player example now works from Nautilus. But if it doesn't I'm still able to use it via a shell.

The solution is quiet obvious, on the one side. But totally non-obvious on the other.

A common user eventually will not find that solutin without aid. After all the package name does not really suggest what the package is used for, since its referring to technologies instead of the problem it solves. Which is understandable. What I don't understand is, why this package is not a dependency of the gnome meta package. But I haven't yet asked the maintainer, so I cannot really blame anybody.

However: Now GVFS is actually useful.

Russell Coker: DRBD Benchmarking

I ve got some performance problems with a mail server that s using DRBD so I ve done some benchmark tests to try and improve things. I used Postal for testing delivery to an LMTP server [1]. The version of Postal I released a few days ago had a bug that made LMTP not work, I ll release a new version to fix that next time I work on Postal or when someone sends me a request for LMTP support (so far no-one has asked for LMTP support so I presume that most users don t mind that it s not yet working). The local spool on my test server is managed by Dovecot, the Dovecot delivery agent stores the mail and the Dovecot POP and IMAP servers provide user access. For delivery I m using the LMTP server I wrote which has been almost ready for GPL release for a couple of years. All I need to write is a command-line parser to support delivery options for different local delivery agents. Currently my LMTP server is hard-coded to run /usr/lib/dovecot/deliver and has it s parameters hard-coded too. As an aside if someone would like to contribute some GPL C/C++ code to convert a string like /usr/lib/dovecot/deliver -e -f %from% -d %to% -n into something that will populate an argv array for execvp() then that would be really appreciated. Authentication is to a MySQL server running on a fast P4 system. The MySQL server was never at any fraction of it s CPU or disk IO capacity so using a different authentication system probably wouldn t have given different results. I used MySQL because it s what I m using in production. Apart from my LMTP server and the new version of Postal all software involved in the testing is from Debian/Squeeze. The Tests All tests were done on a 20G IDE disk. I started testing with a Pentium-4 1.5GHz system with 768M of RAM but then moved to a Pentium-4 2.8GHz system with 1G of RAM when I found CPU time to be a bottleneck with barrier=0. All test results are for the average number of messages delivered per minute for a 19 minute test run where the first minute s results are discarded. The delivery process used 12 threads to deliver mail.
P4-1.5 p4-2.8
Default Ext4 1468 1663
Ext4 max_batch_time=30000 1385 1656
Ext4 barrier=0 1997 2875
Ext4 on DRBD no secondary 1810 2409
When doing the above tests the 1.5GHz system was using 100% CPU time when the filesystem was mounted with barrier=0, about half of that was for system (although I didn t make notes at the time). So the testing on the 1.5GHz system showed that increasing the Ext4 max_batch_time number doesn t give a benefit for a single disk, that mounting with barrier=0 gives a significant performance benefit, and that using DRBD in disconnected mode gives a good performance benefit through forcing barrier=0. As an aside I wonder why they didn t support barriers on DRBD given all the other features that they have for preserving data integrity. The tests with the 2.8GHz system demonstrate the performance benefits of having adequate CPU power, as an aside I hope that Ext4 is optimised for multi-core CPUs because if a 20G IDE disk needs a 2.8GHz P4 then modern RAID arrays probably require more CPU power than a single core can provide. It s also interesting to note that a degraded DRBD device (where the secondary has never been enabled) only gives 84% of the performance of /dev/sda4 when mounted with barrier=0.
p4-2.8
Default Ext4 1663
Ext4 max_batch_time=30000 1656
Ext4 min_batch_time=15000,max_batch_time=30000 1626
Ext4 max_batch_time=0 1625
Ext4 barrier=0 2875
Ext4 on DRBD no secondary 2409
Ext4 on DRBD connected C 1575
Ext4 on DRBD connected B 1428
Ext4 on DRBD connected A 1284
Of all the options for batch times that I tried it seemed that every change decreased the performance slightly but as the greatest decrease in performance was only slightly more than 2% it doesn t matter much. One thing that really surprised me was the test results from different replication protocols. The DRBD replication protocols are documented here [2]. Protocol C is fully synchronous a write request doesn t complete until the remote node has it on disk. Protocol B is memory synchronous, the write is complete when it s on a local disk and in RAM on the other node. Protocol A is fully asynchronous, a write is complete when it s on a local disk. I had expected protocol A to give the best performance as it has lower latency for critical write operations and for protocol C to be the worst. My theory is that DRBD has a performance bug for the protocols that the developers don t recommend. One other thing I can t explain is that according to iostat the data partition on the secondary DRBD node had almost 1% more sectors written than the primary and the number of writes was more than 1% greater on the secondary. I had hoped that with protocol A the writes would be combined on the secondary node to give a lower disk IO load. I filed Debian bug report #654206 about the kernel not exposing the correct value for max_batch_time. The fact that no-one else has reported that bug (which is in kernels from at least 2.6.32 to 3.1.0) is an indication that not many people have found it useful. Conclusions When using DRBD use protocol C as it gives better integrity and better performance. Significant CPU power is apparently required for modern filesystems. The fact that a Maxtor 20G 7200rpm IDE disk [3] can t be driven at full speed by a 1.5GHz P4 was a surprise to me. DRBD significantly reduces performance when compared to a plain disk mounted with barrier=0 (for a fair comparison). The best that DRBD could do in my tests was 55% of native performance when connected and 84% of native performance when disconnected. When comparing a cluster of cheap machines running DRBD on RAID-1 arrays to a single system running RAID-6 with redundant PSUs etc the performance loss from DRBD is a serious problem that can push the economic benefit back towards the single system. Next I will benchmark DRBD on RAID-1 and test the performance hit of using bitmaps with Linux software RAID-1. If anyone knows how to make a HTML table look good then please let me know. It seems that the new blog theme that I m using prevents borders. Update: I mentioned my Debian bug report about the mount option and the fact that it s all on Debian/Squeeze. Related posts:
  1. I need an LMTP server I am working on a system where a front-end mail...
  2. Some Notes on DRBD DRBD is a system for replicating a block device across...
  3. paper about ZCAV This paper by Rodney Van Meter about ZCAV (Zoned Constant...

Michal &#268;iha&#345;: PostgreSQL setup for SMSD testing

This is mostly note to myself, when I will set this up for next time. Every time I set up test environment for Gammu SMSD, I'm lost in PostgreSQL configuration. Simple reason is that I do not use it at all for any other reason. Adding user and creating a database:
# su - postgres
postgres@rincewind:~> psql template1
psql (9.1.1)
Type "help" for help.
template1=# CREATE USER smsd WITH PASSWORD 'smsd';
CREATE ROLE
template1=# CREATE DATABASE smsd OWNER = smsd;
CREATE DATABASE
template1=# GRANT ALL PRIVILEGES ON DATABASE smsd TO smsd;
GRANT
template1=# \q
Next stem is to allow anybody to connect as smsd user. There might be better ways to do that, however I've chosen the simplest one - to trust any local connection - as testing of Gammu SMSD is anyway the only thing this database server does. Edit /var/lib/pgsql/data/pg_hba.conf:
# "local" is for Unix domain socket connections only
local   all             all                                     trust
# IPv4 local connections:
host    all             all             127.0.0.1/32            trust
# IPv6 local connections:
host    all             all             ::1/128                 trust

Filed under: English Gammu 1 comments Flattr this!

Jaldhar Vyas: Jeopardy!: The Post-Mortem

By now hopefully you got a chance to see my Jeopardy! episode so it won't be much of a spoiler to mention that I didn't win. It went like this. I flew into LA on the night of October 31st. The taping was to take place on the next two days. Jeopardy! tapes two weeks of shows, two days a week for a total of 10 episodes. Contestants are randomly chosen for one of those 10 episodes but you don't find out which one you will be on until the last minute. Randomness and secrecy have become become a big part of the production process in games since the quiz show scandals of the 1950s. (Interesting fact: it is a Federal felony to tamper with a TV game show.) There were a group of just under 20 0f us altogether waiting to go on. All very nice people. Here in the New York area one tends to equate very intelligent people with "Type A" personalities but we got on well together. Interspersed between the tapings, we had short practice sessions to familiarize ourselves with the studio setup and this is where I first started getting a little apprehensive. Jeopardy! is not just about general knowledge, there is a physical element too in that you have to buzz in by pressing a button on a stick which is wired up to some producers console. You can't buzz in before Alex has finished reading the question and obviously you can't buzz in if someone is already answering the question. If you buzz at the wrong time, your buzzer locks for 0.75 seconds so just jamming your finger on the button. I didn't even get that far as on the entire first day I failed to buzz in at all despite changing hands, changing grip different ways and other strategies. I was pretty despondent by the second day but then miraculously I managed to get the hang of it. So when I was finally selected (for the 3rd game of that day.) I was back to my usual cool self. I was up against Dave Leach and Nicholas Campiz who were returning after having tied in the previous game. And the game did start well enough. Oh one thing you may notice is that Alex mispronounces my name Jaldhal. I knew he did that once or twice and even mentioned it to a producer but it was only viewing the episode right now that I see he does it consistently. I assumed such things would be fixed up in post-editting but I guess not. Oh well, after living in this country for so many years I've learned to be happy whenever two consonants are more or less in the right place. This particular mispronunciation is actually fairly common, even Indian people have been known to make it. The alternative theory is that Alex couldn't read my horrible handwriting which is also plausible. Anyway, I digress. I started off fairly well. My first mistake was in a category about alcoholic drinks. I answered vermouth when the correct response was gin. In my defense I'm a strict teetoler so none of these words mean anything to me. I also earned the disapproval of my superhero fan son by mistaking Dr. Strange for Dr. Doom. I did get the one about Spiderman villain Dr. Octopus so that mollified him somewhat. The highlight of my evening was strangely enough in a category about books of the Bible. I got a Daily Double. It was a risky move but I have always wanted to make a "true" daily double so I threw caution to the winds and wagered everything I had. To my surprise as much as anyones, got the answer right doubling my score. I was in a pretty good position for the Double Jeopardy but thats when Dave started dominating. If you haven't been watching previous games, Dave Leach is arguably the best player this season. Not only is he smart but he is almost supernaturally fast on the buzzer. You can't see because I kept my hands behind the podium but I again and again I would desperately try to ring in on a question I knew the answer to only to be beaten to the punch by Dave. This caused me to start getting a bit reckless and answering questions where I was less than certain which cost me dearly. One particularly dumb mistake was in a category where all the answers were supposed to start with the letter g. I said compass when I should said gyrocompass but actually I should have left that category alone entirely. By the time Final Jeopardy came around winning was no longer an option as Dave was too far in the lead. I was slightly ahead of Nicholas in 2nd place. This is where I again made a strategic error. My original plan to bet nothing in Final Jeopardy but the category was "1930s Novels" and I liked my chances. The clue was read out and it involved an anti-war novel whose author was blacklisted. I was elated. It had to be "All Quiet on the Western Front" right? The blacklist bit gave me pause as the author Erich Maria Remarque was German and this was obviously a reference to the anti-Communist blacklist in the 1950s USA. But somehow I remembered that he had spent the end of his life in Hollywood or maybe I just convinced myself that it was plausible. Evidently my thought process wasn't too crazy because all three of us came up with the same answer. All three of us were wrong. The correct answer was "Johnny Got His Gun" by Daltan Trumbo. In hindsight I knew this but it illustrates the strange ways the mind works. I knew because the video for Metallicas song "One" from "...And Justice for All" is based on the film adaptation of this book. However in a previous orientation session the lady who is the contestant coordinator for Jeopardy! had mentioned AQOTHWF as anexample of something and this got stuck in my brain crowding out the previously known fact. So when all was said and done I ended up in 3rd place. (I bet big whereas Nicholas was more conservative.) Oh well. Despite not winning I had a blast. I fulfilled my dream of appearing on Jeopardy! I met Alex Trebek. (And I should be receiving an autographed picture of us together soon.) My witty banter was sufficiently witty. I made enough money to cover my travel expenses and still have a nice amount left. And I got to meet lots of interesting and wonderful people. So I'm satisfied.
4 January 2012

Bartosz Fe&#324;ski: Brute force attack against Wifi Protected Setup

Probably most of you already heard about weakness in Wifi Protected Setup discovered recently.
Using it you can reduce PIN authentication probes from 100000000 to only 11000 making brute force attack possible and reveal password to network in about 4 hours (usually even sooner). Most AccessPoints are vulnerable thus with this attack you can brute-force almost any network around. Doesn t matter if it uses WPA/WPA2 nor which method PSK/Radius. It only needs to be WPS enabled and most of APs are. I ve just packaged reaver-wps tool for Debian (I m also an author of its ArchLinux PKGBUILD) and it s now waiting in new queue. If you want to try it before it enters unstable I put it also on my people.debian.org account.
After installing it all you have to do is enable monitor mode in your wifi card (you need aircrack-ng package for that):
airmon-ng start wlan0
Then start attack:
reaver -i mon0 -b xx:xx:xx:xx:xx:xx -vv
Of course name of interfaces may differ as their depend on your wifi driver. After -b switch you have to enter BSSID of the target AP. That s all. Happy ha^Wcracking ;) I wonder if it really enter Debian archive, cause it s shipped with several libraries already included in Debian. Mainly Linux Wireless Extensions library, and some part of wpa-supplicant package (this are at least slightly modified). In fact there are chances that reaver will became the part of the aircrack-ng suite (they discuss it already), but that won t happen soon, so it still would be great to have this package in Debian.

Next.

Previous.