Search Results: "ed"

1 April 2016

Norbert Preining: Searching for a job

Yesterday my contract with my university JAIST ended. I was working there as Associate Professor for 6.5 years, but the university decided not to extend my contract (financial problems, foreigner in Japan). That means, I am now out on the job market again not the greatest fun for an academic at my age. Thanks to JAIST for circumventing the ominous 5-year clause of permanent employment.
shuushoku My prime interests are academic work, that is research and teaching, where research is in a variety of fields, mostly mathematical logic, theoretical computer science, and formal methods. Recently I am working on an extension of the Curry-Howard correspondence to cover different calculi, in particular Hyper Sequent Calculi, and relate them to some kind of process algebra. For more details see the logic dedicated page. My other focal point is programming and software development, where I have contributed to many open source projects, and act as main developer of the TeX Live infrastructure and distribution system (tlmgr). Main languages are Perl, PHP, C, but also Python, Vala, Lisp, CafeOBJ, and whatever comes around. For more details see the software page. I recently became father, so I would prefer either an academic position in Hokuriku, Japan, or a software developer position where I can work (most of the time) remotely. In case one of the readers here has some hints, please drop me a line. In the meantime I enjoy my unemployed life with my baby!

Francois Marier: How Safe Browsing works in Firefox

Firefox has had support for Google's Safe Browsing since 2005 when it started as a stand-alone Firefox extension. At first it was only available in the USA, but it was opened up to the rest of the world in 2006 and moved to the Google Toolbar. It then got integrated directly into Firefox 2.0 before the public launch of the service in 2007. Many people seem confused by this phishing and malware protection system and while there is a pretty good explanation of how it works on our support site, it doesn't go into technical details. This will hopefully be of interest to those who have more questions about it.

Browsing Protection The main part of the Safe Browsing system is the one that watches for bad URLs as you're browsing. Browsing protection currently protects users from: If a Firefox user attempts to visit one of these sites, a warning page will show up instead, which you can see for yourself here: The first two warnings can be toggled using the browser.safebrowsing.malware.enabled preference (in about:config) whereas the last one is controlled by browser.safebrowsing.enabled.

List updates It would be too slow (and privacy-invasive) to contact a trusted server every time the browser wants to establish a connection with a web server. Instead, Firefox downloads a list of bad URLs every 30 minutes from the server (browser.safebrowsing.provider.google.updateURL) and does a lookup against its local database before displaying a page to the user. Downloading the entire list of sites flagged by Safe Browsing would be impractical due to its size so the following transformations are applied:
  1. each URL on the list is canonicalized,
  2. then hashed,
  3. of which only the first 32 bits of the hash are kept.
The lists that are requested from the Safe Browsing server and used to flag pages as malware/unwanted or phishing can be found in urlclassifier.malwareTable and urlclassifier.phishTable respectively. If you want to see some debugging information in your terminal while Firefox is downloading updated lists, turn on browser.safebrowsing.debug. Once downloaded, the lists can be found in the cache directory:
  • ~/.cache/mozilla/firefox/XXXX/safebrowsing/ on Linux
  • ~/Library/Caches/Firefox/Profiles/XXXX/safebrowsing/ on Mac
  • C:\Users\XXXX\AppData\Local\mozilla\firefox\profiles\XXXX\safebrowsing\ on Windows

Resolving partial hash conflicts Because the Safe Browsing database only contains partial hashes, it is possible for a safe page to share the same 32-bit hash prefix as a bad page. Therefore when a URL matches the local list, the browser needs to know whether or not the rest of the hash matches the entry on the Safe Browsing list. In order resolve such conflicts, Firefox requests from the Safe Browsing server (browser.safebrowsing.provider.mozilla.gethashURL) all of the hashes that start with the affected 32-bit prefix and adds these full-length hashes to its local database. Turn on browser.safebrowsing.debug to see some debugging information on the terminal while these "completion" requests are made. If the current URL doesn't match any of these full hashes, the load proceeds as normal. If it does match one of them, a warning interstitial page is shown and the load is canceled.

Download Protection The second part of the Safe Browsing system protects users against malicious downloads. It was launched in 2011, implemented in Firefox 31 on Windows and enabled in Firefox 39 on Mac and Linux. It roughly works like this:
  1. Download the file.
  2. Check the main URL, referrer and redirect chain against a local blocklist (urlclassifier.downloadBlockTable) and block the download in case of a match.
  3. On Windows, if the binary is signed, check the signature against a local whitelist (urlclassifier.downloadAllowTable) of known good publishers and release the download if a match is found.
  4. If the file is not a binary file then release the download.
  5. Otherwise, send the binary file's metadata to the remote application reputation server (browser.safebrowsing.downloads.remote.url) and block the download if the server indicates that the file isn't safe.
Blocked downloads can be unblocked by right-clicking on them in the download manager and selecting "Unblock". While the download protection feature is automatically disabled when malware protection (browser.safebrowsing.malware.enabled) is turned off, it can also be disabled independently via the browser.safebrowsing.downloads.enabled preference. Note that Step 5 is the only point at which any information about the download is shared with Google. That remote lookup can be suppressed via the browser.safebrowsing.downloads.remote.enabled preference for those users concerned about sending that metadata to a third party.

Types of malware The original application reputation service would protect users against "dangerous" downloads, but it has recently been expanded to also warn users about unwanted software as well as software that's not commonly downloaded. These various warnings can be turned on and off in Firefox through the following preferences:
  • browser.safebrowsing.downloads.remote.block_dangerous
  • browser.safebrowsing.downloads.remote.block_dangerous_host
  • browser.safebrowsing.downloads.remote.block_potentially_unwanted
  • browser.safebrowsing.downloads.remote.block_uncommon
and tested using Google's test page. If you want to see how often each "verdict" is returned by the server, you can have a look at the telemetry results for Firefox Beta.

Privacy One of the most persistent misunderstandings about Safe Browsing is the idea that the browser needs to send all visited URLs to Google in order to verify whether or not they are safe. While this was an option in version 1 of the Safe Browsing protocol (as disclosed in their privacy policy at the time), support for this "enhanced mode" was removed in Firefox 3 and the version 1 server was decommissioned in late 2011 in favor of version 2 of the Safe Browsing API which doesn't offer this type of real-time lookup. Google explicitly states that the information collected as part of operating the Safe Browsing service "is only used to flag malicious activity and is never used anywhere else at Google" and that "Safe Browsing requests won't be associated with your Google Account". In addition, Firefox adds a few privacy protections:
  • Query string parameters are stripped from URLs we check as part of the download protection feature.
  • Cookies set by the Safe Browsing servers to protect the service from abuse are stored in a separate cookie jar so that they are not mixed with regular browsing/session cookies.
  • When requesting complete hashes for a 32-bit prefix, Firefox throws in a number of extra "noise" entries to obfuscate the original URL further.
On balance, we believe that most users will want to keep Safe Browsing enabled, but we also make it easy for users with particular needs to turn it off.

Learn More If you want to learn more about how Safe Browsing works in Firefox, you can find all of the technical details on the Safe Browsing and Application Reputation pages of the Mozilla wiki or you can ask questions on our mailing list. Google provides some interesting statistics about what their systems detect in their transparency report and offers a tool to find out why a particular page has been blocked. Some information on how phishing sites are detected is also available on the Google Security blog, but for more detailed information about all parts of the Safe Browsing system, see the following papers:

Bits from Debian: Debian announces partnership to sub-contract publicity and press to an outside marketing agency

Last year we started to push more of Debian news and information away the single news source of the DPN into other media services. Debian has been more active than ever on our many IRC channels, free software based social networks, and unofficial Twitter and Facebook feeds. Today we have decided to announce the next stage in keeping Debian at the forefront of media by sub-contracting publicity and press to an outside marketing agency. The marketing agency (name will be disclosed soon) has provided an AI system (running entirely with free software) which will be fed with all the content of Debian mailing lists and sources.debian.net to understand the character of the Debian community and then better customize future articles, interviews, and event news. However, some bits of personal information are also needed. Please install the "publicity" package and you'll be presented a form to fill in your data: name, surname, phone, snail mail address, place of birth, names of family members, employers or employees. Each person providing their data to the agency will receive coupon for a 20% discount in the download (purchase) of next Debian release (valid only for downloads from the official site www.debian.org). We kindly ask every Debian community member to sign up in, at least, one of theses services: Twitter, Whatsapp, Slack or Facebook (IRC, mailing lists, and free software based RTC are allegedly not so 'cool'). Users need not be concerned with losing the features that the IRC bots provide (so long KGB!) as they will be replaced by Tay-like AI systems. The most visible change will be that MeetBot will no longer log the meetings anymore, but we have bribed an NSA employee so they pass the relevant messages to us. "If this 'centralization, outsourcing and pay-and-forget' approach goes well with publicity, I'm considering running for DPL in 2017 to extend this model to other areas of Debian" said Laura Arjona Reina, (now) former publicity delegate. A new logo and mascot has been designed too, as a symbol of this new era embracing the standards of branding and corporate messaging. Please consider voting in favor of it, in the General Resolution that will be proposed soon: Mascot and Logo

Junichi Uekawa: It feels great when I write code in the plane.

It feels great when I write code in the plane. I wonder if it's the speed I am travelling at or the restricted environment that I feel I am limited in what I can do.

31 March 2016

Antoine Beaupr : My free software activities, march 2016

Debian Long Term Support (LTS) This is my 4th month working on Debian LTS, started by Raphael Hertzog at Freexian. I spent half of the month away on a vacation so little work was done, especially since I tried to tackle rather large uploads like NSS and Xen. I also worked on the frontdesk shift last week.

Frontdesk That work mainly consisted of figuring out how to best help the security team with the last uploads to the Wheezy release. For those who don't know, Debian 7 Wheezy, or "oldstable", is going to be unsupported by the security team starting end of april, and the Debian 6 Squeeze (the previous LTS) is now unsupported. The PGP signatures on the archived release have started yielding expiration errors which can be ignored but that are really a strong reminder that it is really time to upgrade. So the LTS team is now working towards backporting a few security issues from squeeze to wheezy, and this is what I focused on during triage work. I have identified the following high priority packages I will work on after I complete my work on the Xen and NSS packages (detailed below):
  • libidn
  • icu
  • phpmyadmin
  • tomcat6
  • optipng
  • srtp
  • dhcpcd
  • python-tornado

Updates to NSS and Xen I have spent a lot of time testing and building packages for NSS and Xen. To be fair, Brian May did most of the work on the Xen packages, and I merely did some work to test the packages on Koumbit's infrastructure, something which I will continue doing in the next month. For NSS, wheezy and jessie are in this weird state where patches were provided to the security team all the way back in November yet were never tested. Since then, yet more issues came up and I worked hard to review and port patches for those new security issues to wheezy. I'll followup on both packages in the following month.

Other free software work

Android TL;DR: there's an even longer version of this with the step-by-step procedures and that I will update as time goes on in my wiki. I somehow inherited an Android phone recently, on a loan from a friend because the phone broke one too many times and she got a new one from her provider. This phone is a HTC One S "Ville", which is fairly old, but good enough to play with and give me a mobile computing platform to listen to podcasts, play music, access maps and create GPS traces. I was previously doing this with my N900, but that device is really showing its age: very little development is happening on it, the SDK is closed source and the device itself is fairly big, compared to the "Ville". Plus, the SIM card actually works on the Ville so, even though I do not have an actual contract with a cell phone provider (too expensive, too invasive on my privacy), I can still make emergency phone calls (911)! Plus, since there is good wifi on the machine, I can use it to connect to the phone system with the built-in SIP client, send text messages through SMS (thanks to VoIP.ms SMS support) or Jabber. I have also played around with LibreSignal, the free software replacement for Signal, which uses proprietary google services. Yes, the VoIP.ms SMS app also uses GCM, but hopefully that can be fixed. (While I was writing this, another Debian Developer wrote a good review of Signal so I am happy to skip that step. Go read that.)
See also my apps list for a more complete list of the apps I have installed on the phone. I welcome recommendations on cool free software apps I should use!
I have replaced the stock firmware on the phone with Cyanogenmod 12.1, which was a fairly painful experience, partly because of the difficult ambiance on the #cyanogenmod channel on Freenode, where I had extreme experiences: a brave soul helped me through the first flashing process for around 2 hours, nicely holding my hand at every step. Other times, I have seen flames and obtuse comments from people being vulgar, brutal, obnoxious, if not sometimes downright homophobic and sexist from other users. It is clearly a community that needs to fix their attitude. I have documented everything I could in details in this wiki page, in case others want to resuscitate their old phones, but also because I ended up reinstalling the freaking phone about 4 times, and was getting tired of forgetting how to do it every time. I am somewhat fascinated by Android: here is the Linux-based device that should save us all from the proprietary Apple nightmares of fenced in gardens and censorship. Yet, public Android downloads are hidden behind license agreements, even though the code itself is free, which has led fellow Debian developers to work on making libre rebuilds of Androids to workaround this insanity. But worse: all phones are basically proprietary devices down to the core. You need custom firmware to be loaded on the machine for it to boot at all, from the bootloader all the way down to the GSM baseband and Wifi drivers. It is a minefield of closed source software, and trying to run free software on there is a bit of a delusion, especially since the baseband has so much power over the phone. Still, I think it is really interesting to run free software on those machines, and help people that are stuck with cell phones get familiar with software freedom. It seems especially important to me to make Android developers aware of software freedom considering how many apps are available for free yet on which it is not possible to contribute significantly because the source code is not published at all, or published only on the Google Store, instead of the more open and public F-Droid repository which publishes only free software. So I did contribute. This month, I am happy to announce that I contributed to the following free software projects on Android: I have also reviewed the literature surrounding Telegram, a popular messaging app rival to Signal and Whatsapp. Oddly enough, my contributions to Wikipedia on that subject were promptly reverted which made me bring up the subject on the page's Talk page. This lead to an interesting response from the article's main editors which at least added that the "its security features have been contested by security researchers and cryptography experts". Considering the history of Telegram, I would keep people away from it and direct people to use Signal instead, even though Signal has similar metadata issues, mostly because Telegram's lack of response to the security issues that were outlined by fellow security researchers. Both systems suffer from a lack of federation as well, which is a shame in this era of increasing centralization. I am not sure I will put much more work in developing for Android for now. It seems like a fairly hostile platform to work on, and unless I have specific pain points I want to fix, it feels so much better to work on my own stuff in Debian. Which brings me to my usual plethora of free software projects I got stuck in this month.

IRC projects irssi-plugin-otr had a bunch of idiotic bugs lying around, and I had a patch that I hadn't submitted upstream from the Debian package, which needed a rebuild because the irssi version changed, which is a major annoyance. The version in sid is now a snapshot because upstream needs to make a new release but at least it should fix things for my friends running unstable and testing. Hopefully those silly uploads won't be necessary in the future. That's for the client side. On the server side, I have worked on updating the Atheme-services package to the latest version, which actually failed because the upstream libmowgli is missing release tags, which means the Debian package for it is not up-to-date either. Still, it is nice to have a somewhat newer version, even though it is not the latest and some bugs were fixed. I have also looked at making atheme reproducible but was surprised at the hostility of the upstream. In the end, it looks like they are still interested in patches, but they will be a little harder to deploy than for Charybdis, so this could take some time. Hopefully I will find time in the coming weeks to test the new atheme services daemon on the IRC network I operate.

Syncthing I have also re-discovered Syncthing, a file synchronization software. Amazingly, I was having trouble transferring a single file between two phones. I couldn't use Bluetooth (not sure why), the "Wifi sharing" app was available only on one phone (and is proprietary, and has a limit of 4MB files), and everything else requires an account, the cloud, or cabling. So. Just heading to f-droid, install syncthing, flash a few qr-codes around and voil : files are copied over! Pretty amazing: the files were actually copied over the local network, using IPv6 link-local addresses, encryption and the DHT. Which is a real geeky way of saying it's completely fast, secure and fast. Now, I found a few usability issues, so much that I wrote a whole usability story for the developers, which were really appreciative of my review. Some of the issues were already fixed, others were pretty minor. Syncthing has a great community, and it seems like a great project I encourage everyone to get familiar with.

Battery stats The battery-status project I mentionned previously has been merged with the battery-stats project (yes, the names are almost the same, which is confusing) and so I had to do some work to fix my Python graph script, which was accepted upstream and will be part of Debian officially from now on, which is cool. The previous package was unofficial. I have also noticed that my battery has a significantly than when I wrote the script. Whereas it was basically full back then, it seems now it has lost almost 15% of its capacity in about 6 months. According to the calculations of the script:
this battery will reach end of life (5%) in 935 days, 19:07:58.336480, on 2018-10-23 12:06:07.270290
Which is, to be fair, a good life: it will somewhat work for about three more years.

Playlist, git-annex and MPD in Python On top of my previously mentioned photos-import script, I have worked on two more small programs. One is called get-playlist and is an extension to git-annex to easily copy to the local git-annex repository all files present in a given M3U playlist. This is useful for me because my phone cannot possibly fit my whole MP3 collection, and I use playlists in GMPC to tag certain files, particularly the Favorites list which is populated by the "star" button in the UI. I had a lot of fun writing this script. I started using elpy as an IDE in Emacs. (Notice how Emacs got a new webpage, which is a huge improvement was had been basically unchanged since the original version, now almost 20 years old, and probably written by RMS himself.) I wonder how I managed to stay away from Elpy for so long, as it glues together key components of Emacs in an elegant and functional bundle:
  • Company: the "vim-like" completion mode i had been waiting for forever
  • Jedi: context-sensitive autocompletion for Python
  • Flymake: to outline style and syntax errors (unfortunately not the more modern Flycheck)
  • inline documentation...
In short, it's amazing and makes everything so much easier to work with that I wrote another script. The first program wouldn't work very well because some songs in the playlists had been moved, so I made another program, this time to repair playlists which refer to missing files. The script is simply called fix-playlists, and can operate transparently on multiple playlists. It has a bunch of heuristics to find files and uses a MPD server as a directory to search into. It can edit files in place or just act as a filter.

Useful snippets Writing so many scripts, so often, I figured I needed to stop wasting time always writing the same boilerplate stuff on top of every file, so I started publishing Yasnippet-compatible file snippets, in my snippets repository. For example, this report is based on the humble lts snippet. I also have a base license snippet which slaps the AGPLv3 license on top of a Python file. But the most interesting snippet, for me, is this simple script snippet which is a basic scaffolding for a commandline script that includes argument processing, logging and filtering of files, something which I was always copy-pasting around.

Other projects And finally, a list of interesting issues en vrac:
  • there's a new Bootstrap 4 theme for Ikiwiki. It was delivering content over CDNs, which is bad for privacy issues, so I filed an issue which was almost immediately fixed by the author!
  • I found out about BitHub, a tool to make payments with Bitcoins for patches submitted on OWS projects. It wasn't clear to me where to find the demo, but when I did, I quickly filed a PR to fix the documentation. Given the number of open PRs there and the lack of activity, I wonder if the model is working at all...
  • a fellow Debian Developer shared his photos workflow, which was interesting to me because I have my own peculiar script, which I never mentionned here, but which I ended up sharing with the author

Steinar H. Gunderson: Signal

Signal is a pretty amazing app; it manages to combine great security with great simplicity. (It literally takes two minutes, even for an unskilled user, to set it up.) I looked at the Wikipedia article, and the list of properties the protocol provides is impressive; I had hardly any idea you would even want all of these. But I've tried to decode what they actually mean: (There are more guarantees and features for group chat.) Again, it's really impressive. Modern cryptography at its finest. My only two concerns is that it's too bound to telephone numbers (you can't have the same account on two devices, for instance it very closely mimics the SMS/MMS/POTS model in that regard), and that it's too clumsy to verify public keys for the IM part. It can show them as hex or do a two-way QR code scan, but there's no NFC support, and there's no way to read e.g. a series of plaintext words instead of the fingerprint. (There's no web of trust, but probably that's actually for the better.) I hear WhatsApp is currently integrating the Signal protocol (or might be done already it's a bit unclear), but for now, my bet is on Signal. Install it now and frustrate NSA. And get free SMS/MMS to other Signal users (which are growing in surprising numbers) while you're at it. :-)

Chris Lamb: Free software activities in March 2016

Here is my monthly update covering a large part of what I have been doing in the free software world (previously):
Debian
  • Presented Reproducible Builds - fulfilling the original promise of free software at FOSSASIA '16.
  • Uploaded libfiu (0.94-4), adding a patch from Logan Rose to fix a FTBFS with ld --as-needed.
My work in the Reproducible Builds project was also covered in more depth in Lunar's weekly reports (#44, #45, #46, #47).
LTS

This month I have been paid to work 7 hours on Debian Long Term Support (LTS). Whilst the LTS team will take over support from the Security Team on April 26, 2016, in the meantime I did the following:
  • Archived the squeeze distribution (via the FTPteam).
  • Assisted in preparing updates for python-django.
  • Helping end-users migrate to wheezy now that squeeze LTS has reached end-of-life.


FTP Team

As a Debian FTP assistant I ACCEPTed 143 packages: acme-tiny, berkshelf-api, circlator, cloud-utils, corsix-th, cronic, diaspora-installer, dub, dumb-init, firehol, firetools, flask-bcrypt, flask-oldsessions, flycheck, ganeti, geany-plugins, git-build-recipe, git-phab, gnome-shell-extension-caffeine, gnome-shell-extension-mediaplayer, golang-github-cheggaaa-pb, golang-github-coreos-ioprogress, golang-github-cyberdelia-go-metrics-graphite, golang-github-cznic-ql, golang-github-elazarl-goproxy, golang-github-hashicorp-hil, golang-github-mitchellh-go-wordwrap, golang-github-mvdan-xurls, golang-github-paulrosania-go-charset, golang-github-xeipuuv-gojsonreference, golang-github-xeipuuv-gojsonschema, grilo-plugins, gtk3-nocsd, herisvm, identity4c, lemonldap-ng, libisal, libmath-gsl-perl, libmemcached-libmemcached-perl, libplack-middleware-logany-perl, libplack-middleware-logwarn-perl, libpng1.6, libqmi, librdf-generator-http-perl, libtime-moment-perl, libvirt-php, libxml-compile-soap-perl, libxml-compile-wsdl11-perl, linux, linux-tools, mdk-doc, mesa, mpdecimal, msi-keyboard, nauty, node-addressparser, node-ansi-regex, node-argparse, node-array-find-index, node-base62, node-co, node-component-consoler, node-crypto-cacerts, node-decamelize, node-delve, node-for-in, node-function-bind, node-generator-supported, node-invert-kv, node-json-localizer, node-normalize-git-url, node-nth-check, node-obj-util, node-read-file, node-require-dir, node-require-main-filename, node-seq, node-starttls, node-through, node-uid-number, node-uri-path, node-url-join, node-xmlhttprequest-ssl, ocrmypdf, octave-netcdf, open-infrastructure-container-tools, osmose-emulator, pdal, pep8, pg-backup-ctl, php-guzzle, printrun, pydocstyle, pysynphot, python-antlr3, python-biom-format, python-brainstorm, python-django-adminsortable, python-feather-format, python-gevent, python-lxc, python-mongoengine, python-nameparser, python-pdal, python-pefile, python-phabricator, python-pika-pool, python-pynlpl, python-qtawesome, python-requests-unixsocket, python-saharaclient, python-stringtemplate3, r-cran-adegraphics, r-cran-assertthat, r-cran-bold, r-cran-curl, r-cran-data.table, r-cran-htmltools, r-cran-httr, r-cran-lazyeval, r-cran-mcmc, r-cran-openssl, r-cran-pbdzmq, r-cran-rncl, r-cran-uuid, rawtran, reel, ruby-certificate-authority, ruby-rspec-pending-for, ruby-ruby-engine, ruby-ruby-version, scribus-ng, specutils, symfony, tandem-mass, tdb, thrift, udfclient, vala, why3, wmaker, xdg-app & xiccd.

Lars Wirzenius: New job: QvarnLabs

Today was my last day at Suomen Tilaajavastuu, where I worked on Qvarn. Tomorrow is my first day at my new job. The new job is for a new company, tentatively named QvarnLabs (registration is in process), to further develop and support Qvarn. The new company starts operation tomorrow, so you'll have to excuse me that there isn't a website yet. Qvarn provides a secure, RESTful JSON HTTP API for storing and retrieving data, with detailed access control (and I can provide more buzzwords if necessary). If you operate in the EU, and store information about people, you might want to read up about the General Data Protection Regulation, and Qvarn may be a possible part of a solution you want to look into, once we have the website up.

Michael Prokop: Event: OSDC 2016

* Open Source Data Center Conference (OSDC) is a conference on open source software in data centers and huge IT environments and will take place in Berlin/Germany in April 2016. I will give a talk titled Continuous Integration in Data Centers Further 3 Years Later there. I gave a talk titled Continuous Integration in data centers at OSDC in 2013, presenting ways how to realize continuous integration/delivery with Jenkins and related tools. Three years later we gained new tools in our continuous delivery pipeline, including Docker, Gerrit and Goss. Over the years we also had to deal with different problems caused by faster release cycles, a growing team and gaining new projects. We therefore established code review in our pipeline, improved our test infrastructure and invested in our infrastructure automation. In this talk I will discuss the lessons we learned over the last years, demonstrate how a proper continuous delivery pipeline can improve your life and how open source tools like Jenkins, Docker and Gerrit can be leveraged for setting up such an environment. Hope to see you there!

30 March 2016

Ian Wienand: Durable photo workflow

Ever since my kids were born I have accumulated thousands of digital happy-snaps and I have finally gotten to a point where I'm quite happy with my work-flow. I have always been extremely dubious of using any sort of external all-in-one solution to managing my photos; so many things seem to shut-down, cease development or disappear, all leaving you to have to figure out how to migrate to the next latest thing (e.g. Picasa shutting down). So while there is nothing complicated or even generic about them, there are a few things in my photo-scripts repo that might help others who like to keep a self-contained archive. Firstly I have a simple script to copy the latest photos from the SD card (i.e. those new since the last copy -- this is obviously very camera specific). I then split by date so I have a simple flat directory layout with each week's photos in it. With the price of SD cards and my rate of filling them up, I don't even bother wiping them at this point, but just keep them in the safe as a backup. For some reason I have a bit of a thing about geotagging all the photos so I know where I took them. Certainly some cameras do this today, but mine does not. I have a two-progned approach; I have a geotag script and then a small website easygeotag.info which quickly lets met translate a point on Google maps to exiv2 command-line syntax. Since I take a lot of photos in the same place, the script can store points by name in a small file sourced by the script. Adding comments to the photos is done with perhaps the lesser-known cousin of EXIF -- IPTC. Some time ago I wrote python bindings for libiptcdata and it has been working just fine ever since. Debian's python-iptcdata comes with a inbuilt script to set title and caption, which is easily wrapped. What I like about this is that my photos are in a simple directory layout, with all metadata embedded within the actual image files in very standarised formats that should be readable by anywhere I choose to host them. For sharing, I then upload to Flickr. I used to have a command-line script for this, but have found the web uploader works even better these days. It reads the IPTC data for titles and comments, and gets the geotag info for nice map displays. I manually coralle them into albums, and the Flickr "guest pass" is perfect for then sharing albums to friends and family without making them jump through hoops to register on a site to get access to the photos, or worse, host them myself. I consider Flickr a cache, because (even though I pay) I expect it to shut-down or turn evil at any time. Interestingly, their AI tagging is often quite accurate, and I imagine will only get better. This is nice extra metadata that you don't have to spend time on yourself. The last piece has always been the "hit by a bus" component of all this. Can anyone figure out access to all these photos if I suddenly disappear? I've tried many things here -- at one point I was using rdiff-backup to sync encrypted bundles up to AWS for example; but I very clearly found the problem in that when I forgot the keep the key safe and couldn't unencrypt any of my backups (let alone anyone else figuring all this out). Finally Google Nearline seems to be just what I want. It's off-site, redundant and the price is right; but more importantly I can very easily give access to the backup bucket to anyone with a Google address, who can then just hit a website to download the originals from the bucket (I left the link with my other "hit by a bus" bits and pieces). Of course what they then do with this data is their problem, but at least I feel like they have a chance. This even has an rsync like interface in the client, so I can quickly upload the new stuff from my home NAS (where I keep the photos in a RAID0). I've been doing this now for 350 weeks and have worked through some 25,000 photos. I used to get an album up every week, but as the kids get older and we're closer to family I now do it in batches about once a month. I do wonder if my kids will ever be interested in tagged and commented photos with pretty much their exact location from their childhood ... I doubt it, but it's nice to feel like I have a good chance of still having them if they do.

Niels Thykier: Easter patching of Britney

I decided to take a couple of days of vacation next to Easter and obviously ended up with tons of time. I ended up channelling most of the (productive) time into improving Britney. In raw results: The most exciting items in the patch series are probably: Once reviewed, these will be merged into master and we will have versioned provides support (in Britney).:)
Filed under: Debian, Release-Team

Mike Gabriel: Pushing X.org Git repos to Github et al.

TL;DR; If you want to know why cloning several of the X.org repositories to Github or GitLab instances fails and how this can be worked around, you may want to continue reading. Why we stumbled over this issue... As a joint effort of the Arctica Project, TheQVD and X2Go, Ulrich Sibiller and I are currently preparing a build workflow for the nxagent X-server (version 3) [1] that allows building nxagent against the modular X.org 7.0 (using autoconf and automake) rather than the monolithic build workflow of X.org 6.9 (using ancient imake). Our goal is to rewind all X.org components required for building nxagent back to a state where nxagent successfully builds and runs. Then we will go through various, (probably) monthly cycles of Our first hurdle... After Ulrich now has a functioning nxagent-against-X.org-7.0-workflow locally, we want to get everything into the Arctica Project's Github namespace. Which fails...
[mike@minobo xorg.upstream]$ git clone https://anongit.freedesktop.org/git/xorg/lib/libX11.git
Cloning into 'libX11'...
remote: Counting objects: 18520, done.
remote: Compressing objects: 100% (3441/3441), done.
remote: Total 18520 (delta 15094), reused 18325 (delta 14954)
Receiving objects: 100% (18520/18520), 5.98 MiB   549.00 KiB/s, done.
Resolving deltas: 100% (15094/15094), done.
Checking connectivity... done.
[mike@minobo xorg.upstream]$ cd libX11/
[mike@minobo libX11 (master)]$ git remote rename origin upstream 
[mike@minobo libX11 (master)]$ git remote add origin git@github.com:ArcticaProject/libX11.git
[mike@minobo libX11 (master)]$ git push --mirror origin 
Counting objects: 18520, done.
Delta compression using up to 4 threads.
Compressing objects: 100% (3301/3301), done.
remote: error: object 70d5e4d45dd7bf1e05b099cb5a4dd529344084f0: missingSpaceBeforeDate: invalid author/committer line - missing space before date
remote: fatal: Error in object
error: pack-objects died of signal 13
error: failed to push some refs to 'git@github.com:ArcticaProject/libX11.git'
This issue should be a known issue at X.org / Mesa upstream [2]. The underlying problem occurs with Git 2.5 and above... If you run git-fsck from Git (>= 2.5) against several of the X.org Git repositories, you will stumble over the above issue. For libX11.git, we see these errors reported when running git-fsck from current Debian unstable:
mike@sid:~/xorg/libX11.git$ git fsck 
Checking object directories: 100% (256/256), done.
error in tag 70d5e4d45dd7bf1e05b099cb5a4dd529344084f0: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag a3bfe698090a5d41f1e9acb1b57a049085d6b04e: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag c1fc8c9aec1bc92d03d08d5e986dd40b194a7a3e: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag d4c27f7e7d8e2ea32418f341ad85c33f3b76862d: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 79780379aee21bf4d4bcb046a3b54774893ea6b1: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag a638de80ec20dc1de625cd323ed19a6646fecf2e: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag f6a6414e4e52a971a35fd118c350567e2383d034: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag b5c6810e21be2e7ccfac8f0539d46bf75dbe50a0: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 86cec9d20428cc190ec7278a0abe481b180288ac: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag ac912988091574790c7cffbbc2c60b8c59f8fcef: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 2d01674092951cd3284b3b099978b2436ea468ad: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 922d0534154668918eaa09a36cc5cd53fc6b71b7: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 8ef91b9cc0a4a7b0361f6b40b3f735221c8272cb: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 1516173727005a87aa501e1ad708d72e6ae6e753: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 77c9e63a3abff1593ccbed249b2c3ae7f68e1833: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 58044c7087137ce2b521297dbb31934ccaedc94e: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 2e0d061c6830891dcc856a04aac900e5bb6d0779: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 2f58c7cc4cbf3d30927f6301039b6bf018ed38fd: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 77fc2e1e26019c3ba92275d249fe1979570255d2: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 9b2e06fa262f23dbcbbccd42be6477e08a452268: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 7f99410bb9cc9f7cbbc2d43d8ad044771a6eec0a: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 99b59b83f126b4abb9da89f577a5b8147d543c25: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 97170c33f99761acd932f968e21d6d7664e7ba80: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag b39966d452127c992987d082f69321f950ae4c39: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 05e20c3bd8ac6b7e873607db73894486a4ac0519: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag f478497b5a3e9d6b92237e0f408c9f0f18108f52: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag c5ed936f28ce70c8932e33d67a6e06d140e35ba8: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 2b6beba295a6ff997dfe15a732c95ae6577fa735: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 32edbb1e9c5b7d1c6f8639dab85e5368d303df7f: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 490fbe2afb9ffc7057c0eb150f7cdd4d4fa8686c: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag fc605ac48bd7d675d6d04162a0f3bfebe27f2037: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 6289ecc26d1d505f395c59da744a9354d7aad2a2: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 8c9c30dac72aebd1a2c31a55a47c0ac11bc328db: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 3b7aa57994924be0dad693e837559d9ee900299c: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag b02ad9a8ec96e3c1027ca71289aeef5b8748e17e: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 4402ab1a86226a9cd0ce84fb8147b1c4958c684d: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag bb02b4fbde316644c771d28d5edeeb9b213a6d6a: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 95b6462c70213b562c9d2b8726eda706edc9c456: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag a99fea43ad53907623f269942c55237c238645e0: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 0c417ce98a6cf927ce7a1359b198b2bb746c707e: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag ce3ff6b102f360fc9dcd3a85361f44da054de0b1: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 2fb7b16b38a365c5009bd170d4463634c1f3de26: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 95570f484bfde5fc2ed8548cb17b87d8114a2866: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag d6e5895c104cfe0d135494a605013dd2910a93a1: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 49be7144523c4a56afcb389a9aa021d167710d2c: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 020353d1b982ac938d229039ca13bfea5793fcd9: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 991792d4f8477ab65ad4d8a0245c9a3bbb1f0294: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag e8037555efe299a7143370b485f754f6b08ffac7: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 4fdc8e36a5022f3e32d5567305d8e9cde4011f1a: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 9c93a19a76163328e30a7306bb0babe3175fb9a2: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 9f90bf4424250f80340b3e2803d343c74d2adb0b: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 2e7a8c7974777e3e869de9013025dc3f61633e1e: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 59b7c06da2a64d72668394e9239e3dfe8a5cff59: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 0263c4f684faa9a5126a0db524d5d35be7277e52: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 1514e654c1a9b346cbfca5a81f6d331f106242aa: missingSpaceBeforeDate: invalid author/committer line - missing space before date
error in tag 6aa83ec3d1d82ee332cedcf4e99d3cbd56e73edd: missingSpaceBeforeDate: invalid author/committer line - missing space before date
Checking objects: 100% (18523/18523), done.
What actually is going wrong here... When looking at one of those tags (luckily, only tags are affected), we see that something's not ok with the date string of the tag (I am not a Git plumber, so sorry for being superficial here):
mike@sid:~/xorg/libX11.git$ git show 2fb7b16b38a365c5009bd170d4463634c1f3de26
tag XORG-RELEASE-1-TM-MERGE
Tagger: Alan Coopersmith 
Date:   Thu Jan 1 00:00:00 1970 +0000
        ^^^^^^^^^^^^^^^^^^^^^^^^^^^^^
commit 84adc60cae8e944777563501dd633622a28bdb3b
Author: Alan Coopersmith 
Date:   Sat Mar 27 07:08:16 2004 +0000
    Fix typo (IsModiferKey should be IsModifierKey)
[... not quoting the diff for the above commit ...]
How to work around that issue... We then got the idea that we could redo those tags with the date string derived from the commit that this tag points at. This can be scripted (credits go to an unnamed person in Ulrich's surrounding!!!):
mike@sid:~/xorg/libX11$ cat repair.sh
#!/bin/bash
set -x
git fsck 2>&1   tee git-fsck.log   grep "error in tag"   sed -r -e 's/error in tag ([0-9a-f]+):.*/\1/p'   while read broken; do
         echo $broken
         commit=$(git rev-parse $ broken ^ commit )
         tag=$(git cat-file tag $broken   sed -n 's/^tag //p')
         tag_msg=$(git cat-file tag $broken   sed -n '/^$/,$p'   tail -n +2)
         export GIT_COMMITTER_NAME="$(git log -1 --format='%cn' $commit)"
         export GIT_COMMITTER_EMAIL="$(git log -1 --format='%ce' $commit)"
         export GIT_COMMITTER_DATE="$(git log -1 --format='%cD' $commit)"
         git tag -a -f -m "$tag_msg" $tag $commit
done
# drop all old content...
git reflog expire --expire=all --all
git gc --prune=all
# no more errors should be reported...
git fsck
Copy this repair.sh into the Git repo itself and let the script walk over your tags. After this script has been applied you can push the X.org Git repo with broken tags redone to Git hosters like Github or GitLab. light+love,
Mike [1] https://github.com/ArcticaProject/nx-libs
[2] https://lists.freedesktop.org/archives/mesa-dev/2016-February/106268.html

Bits from Debian: DebConf16 welcomes its first nine sponsors!

DebConf16 logo DebConf16 will take place in Cape Town, South Africa in July 2016. We strive to provide an intense working environment and enable good progress for Debian and for Free Software in general. We extend an invitation to everyone to join us and to support this event. As a volunteer-run non-profit conference, we depend on our sponsors. Nine companies have already committed to sponsor DebConf16! Let's introduce them: Our first Platinum sponsor is Hewlett Packard Enterprise (HPE). HPE is one of the largest computer companies in the world, providing a wide range of products and services, such as servers, storage, networking, consulting and support, software, and financial services. HPE is also a development partner of Debian, and provides hardware for port development, Debian mirrors, and other Debian services (hardware donations are listed in the Debian machines page). Our first Gold sponsor is Valve, a company developing games, social entertainment platform, and game engine technologies. Our second Gold sponsor is Google, the technology company specialized in Internet-related services as online advertising and search engine. Rusbitech (developers of the Astra Linux Debian derivative), credativ (a service-oriented company focusing on open-source software and also a Debian development partner), Catalyst (a company offering IT solutions using open source software), the Bern University of Applied Sciences (with over 7,000 students enrolled, located in the Swiss capital), and Texas Instruments (the global semiconductor company) are our four Silver sponsors. And last but not least, the open source company Univention has agreed to support us as Bronze-level. Become a sponsor too! Would you like to become a sponsor? Do you know of or work in a company or organization that may consider sponsorship? Please have a look at our sponsorship brochure (or a summarized flyer), in which we outline all the details and describe the sponsor benefits. For further details, feel free to contact us through sponsors@debconf.org, and visit the DebConf16 website at https://debconf16.debconf.org.

Julien Danjou: The OpenStack Schizophrenia

When I started contributing to OpenStack, almost five years ago, it was a small ecosystem. There were no foundation, a handful of projects and you could understand the code base in a few days. Fast forward 2016, and it is a totally different beast. The project grew to no less than 54 teams, each team providing one or more deliverable. For example, the Nova and Swift team each one produces one service and its client, whereas the Telemetry team produces 3 services and 3 different clients. In 5 years, OpenStack went to a few IaaS projects, to 54 different teams tackling different areas related to cloud computing. Once upon a time, OpenStack was all about starting some virtual machines on a network, backed by images and volumes. Nowadays, it's also about orchestrating your network deployment over containers, while managing your application life-cycle using a database service, everything being metered and billed for. This exponential growth has been made possible with the decision of the OpenStack Technical Committee to open the gates with the project structure reform voted at the end of 2014. This amendment suppresses the old OpenStack model of "integrated projects" (i.e. Nova, Glance, Swift ). The big tent, as it's called, allowed OpenStack to land new projects every month, growing from the 20 project teams of December 2014 to the 54 we have today multiplying the number of projects by 2.7 in a little more than a year. Amazing growth, right? And this was clearly a good change. I sat at the Technical Committee in 2013, when projects were trying to apply to be "integrated", after Ceilometer and Heat were. It was painful to see how the Technical Committee was trying to assess whether new projects should be brought in or not. But what I notice these days, is how OpenStack is still stuck between its old and new models. On one side, it accepted a lot of new teams, but on the other side, many are considered as second-class citizens. Efforts are made to continue to build an OpenStack project that does not exist anymore. For example, there is a team trying to define what's OpenStack core, named DefCore. That is looking to define which projects are, somehow, actually OpenStack. This leads to weird situations, such as having non-DefCore projects seeing their doc rejected from installation guides. Again, I reiterated my proposal to publish documentation as part of each project code to solve that dishonest situation and put everything on a level playing field Some cross-projects specs are also pushed without implication of all OpenStack projects. For example, The deprecate-cli spec which proposes to deprecate command-line interface tools proposed by each project had a lot of sense in the old OpenStack sense, where the goal was to build a unified and ubiquitous cloud platform. But when you now have tens of projects with largely different scopes, this start making less sense. Still, this spec was merged by the OpenStack Technical Committee this cycle. Keystone is the first project to proudly force users to rely on openstack-client, removing its old keystone command line tool. I find it odd to push that specs when it's pretty clear that some projects (e.g. Swift, Gnocchi ) have no intention to go down that path. Unfortunately, most specs pushed by the Technical Committee are in the realm of wishful thinking. It somehow makes sense, since only a few of the members are actively contributing to OpenStack projects, and they can't by themselves implement all of that magically. But OpenStack is no exception in the free software world and remains a do-ocracy. There is good cross-project content in OpenStack, such as the API working group. While the work done should probably not be OpenStack specific, there's a lot that teams have learned by building various HTTP REST API with different frameworks. Compiling this knowledge and offering it as a guidance to various teams is a great help. My fellow developer Chris Dent wrote a post about what he would do on the Technical Committee. In this article, he points to a lot of the shortcomings I described here, and his confusion between OpenStack being a product or being a kit is quite understandable. Indeed, the message broadcasted by OpenStack is still very confusing after the big tent openness. There's no enough user experience improvement being done. The OpenStack Technical Committee election is opened for April 2016, and from what I read so far, many candidates are proposing to now clean up the big tent, kicking out projects that do not match certain criteria anymore. This is probably a good idea, there is some inactive project laying around. But I don't think that will be enough to solve the identity crisis that OpenStack is experiencing. So this is why, once again this cycle, I will throw my hat in the ring and submit my candidacy for OpenStack Technical Committee.

Colin Watson: Re-signing PPAs

Julian has written about their efforts to strengthen security in APT, and shortly before that notified us that Launchpad s signatures on PPAs use weak SHA-1 digests. Unfortunately we hadn t noticed that before; GnuPG s defaults tend to result in weak digests unless carefully tweaked, which is a shame. I started on the necessary fixes for this immediately we heard of the problem, but it s taken a little while to get everything in place, and I thought I d explain why since some of the problems uncovered are interesting in their own right. Firstly, there was the relatively trivial matter of using SHA-512 digests on new signatures. This was mostly a matter of adjusting our configuration, although writing the test was a bit tricky since PyGPGME isn t as helpful as it could be. (Simpler repository implementations that call gpg from the command line should probably just add the --digest-algo SHA512 option instead of imitating this.) After getting that in place, any change to a suite in a PPA will result in it being re-signed with SHA-512, which is good as far as it goes, but we also want to re-sign PPAs that haven t been modified. Launchpad hosts more than 50000 active PPAs, though, a significant percentage of which include packages for sufficiently recent Ubuntu releases that we d want to re-sign them for this. We can t expect everyone to push new uploads, and we need to run this through at least some part of our usual publication machinery rather than just writing a hacky shell script to do the job (which would have no idea which keys to sign with, to start with); but forcing full reprocessing of all those PPAs would take a prohibitively long time, and at the moment we need to interrupt normal PPA publication to do this kind of work. I therefore had to spend some quality time working out how to make things go fast enough. The first couple of changes (1, 2) were to add options to our publisher script to let us run just the one step we need in careful mode: that is, forcibly re-run the Release file processing step even if it thinks nothing has changed, and entirely disable the other steps such as generating Packages and Sources files. Then last week I finally got around to timing things on one of our staging systems so that we could estimate how long a full run would take. It was taking a little over two seconds per archive, which meant that if we were to re-sign all published PPAs then that would take more than 33 hours! Obviously this wasn t viable; even just re-signing xenial would be prohibitively slow. The next question was where all that time was going. I thought perhaps that the actual signing might be slow for some reason, but it was taking about half a second per archive: not great, but not enough to account for most of the slowness. The main part of the delay was in fact when we committed the database transaction after processing each archive, but not in the actual PostgreSQL commit, rather in the ORM invalidate method called to prepare for a commit. Launchpad uses the excellent Storm for all of its database interactions. One property of this ORM (and possibly of others; I ll cheerfully admit to not having spent much time with other ORMs) is that it uses a WeakValueDictionary to keep track of the objects it s populated with database results. Before it commits a transaction, it iterates over all those alive objects to note that if they re used in future then information needs to be reloaded from the database first. Usually this is a very good thing: it saves us from having to think too hard about data consistency at the application layer. But in this case, one of the things we did at the start of the publisher script was:
def getPPAs(self, distribution):
    """Find private package archives for the selected distribution."""
    if (self.isCareful(self.options.careful_publishing) or
            self.options.include_non_pending):
        return distribution.getAllPPAs()
    else:
        return distribution.getPendingPublicationPPAs()
def getTargetArchives(self, distribution):
    """Find the archive(s) selected by the script's options."""
    if self.options.partner:
        return [distribution.getArchiveByComponent('partner')]
    elif self.options.ppa:
        return filter(is_ppa_public, self.getPPAs(distribution))
    elif self.options.private_ppa:
        return filter(is_ppa_private, self.getPPAs(distribution))
    elif self.options.copy_archive:
        return self.getCopyArchives(distribution)
    else:
        return [distribution.main_archive]
That innocuous-looking filter means that we do all the public/private filtering of PPAs up-front and return a list of all the PPAs we intend to operate on. This means that all those objects are alive as far as Storm is concerned and need to be considered for invalidation on every commit, and the time required for that stacks up when many thousands of objects are involved: this is essentially accidentally quadratic behaviour, because all archives are considered when committing changes to each archive in turn. Normally this isn t too bad because only a few hundred PPAs need to be processed in any given run; but if we re running in a mode where we re processing all PPAs rather than just ones that are pending publication, then suddenly this balloons to the point where it takes a couple of seconds. The fix is very simple, using an iterator instead so that we don t need to keep all the objects alive:
from itertools import ifilter
def getTargetArchives(self, distribution):
    """Find the archive(s) selected by the script's options."""
    if self.options.partner:
        return [distribution.getArchiveByComponent('partner')]
    elif self.options.ppa:
        return ifilter(is_ppa_public, self.getPPAs(distribution))
    elif self.options.private_ppa:
        return ifilter(is_ppa_private, self.getPPAs(distribution))
    elif self.options.copy_archive:
        return self.getCopyArchives(distribution)
    else:
        return [distribution.main_archive]
After that, I turned to that half a second for signing. A good chunk of that was accounted for by the signContent method taking a fingerprint rather than a key, despite the fact that we normally already had the key in hand; this caused us to have to ask GPGME to reload the key, which requires two subprocess calls. Converting this to take a key rather than a fingerprint gets the per-archive time down to about a quarter of a second on our staging system, about eight times faster than where we started. Using this, we ve now re-signed all xenial Release files in PPAs using SHA-512 digests. On production, this took about 80 minutes to iterate over around 70000 archives, of which 1761 were modified. Most of the time appears to have been spent skipping over unmodified archives; even a few hundredths of a second per archive adds up quickly there. The remaining time comes out to around 0.4 seconds per modified archive. There s certainly still room for speeding this up a bit. We wouldn t want to do this procedure every day, but it s acceptable for occasional tasks like this. I expect that we ll similarly re-sign wily, vivid, and trusty Release files soon in the same way.

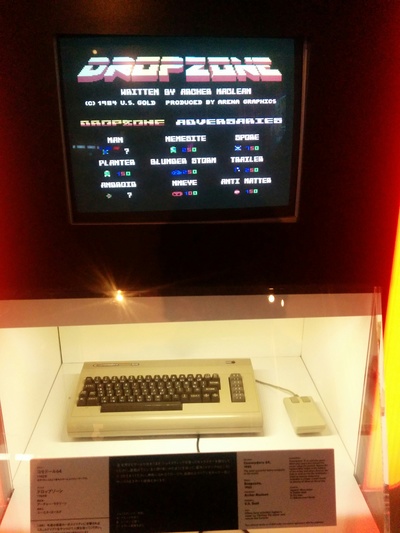
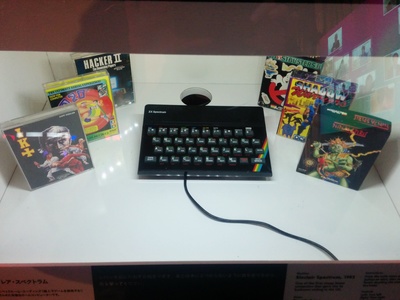
NOKUBI Takatsugu: GAME-ON the historical videogame exhibition

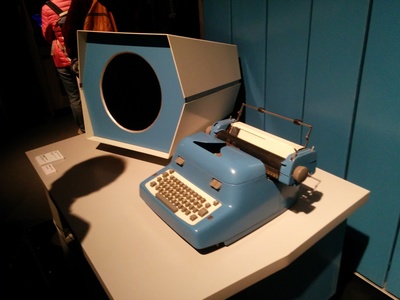
I attended GAME-ON last weedkend at Miraikan, The National Museum of Emerging Science and Innovation in Tokyo. There are many historical videogame hardware and software, and the bland-new PSVR exibition. DEC PDP-1 DisplayI can see the real DEC PDP-1 hardware. Unfortunately it is only haredware, not worked. And also PONG is exibited.
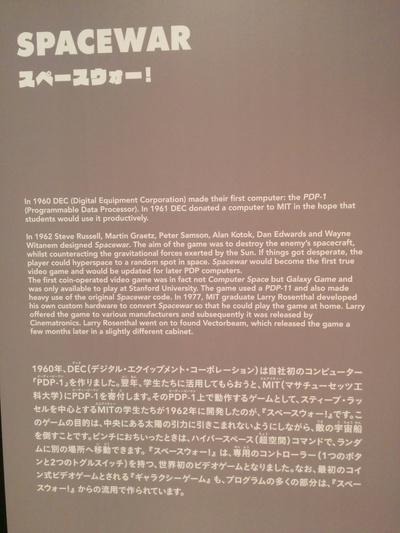
SPACEWAR description

SPACEWAR description

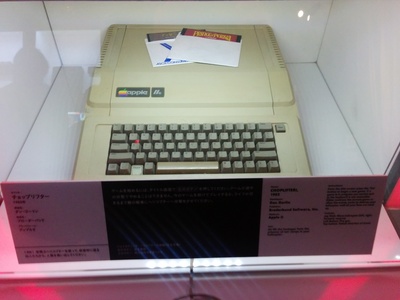
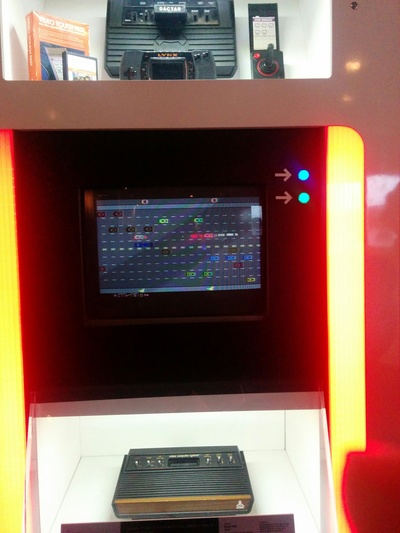
There are many old hardware Atari 2600, Commodore 64, Spectrum, and so on. Apple IIe Atari 2600/VCS Commodore 64 Spectrum Almost exhibition with English description, and officials can talk English, if you feel interested, go Miraikan until 30th May.

Patrick Matth i: Current jessie-backports packaging work in march

Hey, I have uploaded some new already accepted packages to jessie-backports: I hope you enjoy the current versions in Debian 8. :-)

29 March 2016

Vincent Fourmond: Release 0.14.1 of ctioga2

With the (relatively, sorry) recent switch to ruby2.3 as default Ruby version, I realized that my plotting program ctioga2 crashed with ruby 2.3 (due to a rather ugly lazy hack). I have just fixed this in release 0.14.1. Update as usual with:
~ gem update ctioga2
If you're not using Ruby 2.3, you probably don't need to update soon, though. Enjoy !

Michal Čihař: Weekly phpMyAdmin contributions 2016-W12

Last week we've finally released phpMyAdmin 4.6.0. That also means that 4.5.5 is out of maintenance now (however 4.4.15 and 4.0.10 are still supported if you're stuck with older PHP or MySQL versions for some reason). The biggest focus was spent on handling incoming issues and checking if they are still present in 4.6.0 what in most cases proven not to be true. Handled issues:

Filed under: English phpMyAdmin 0 comments

Rog rio Brito: Partially switching to Chromium

In the interest of being as brief as possible (just ask for details if you want to know more or if you think that it would help), I have started, against my preferences, to start using chromium from Debian instead of Firefox (aka, Iceweasel). The reason? I have a slow computer (a Core 2 Duo T7250). My main computer. My workhorse. There are some sites that even with an empty profile and a vanilla Firefox build right from Mozilla Foundation cause Firefox to generate a very heavy CPU load. I briefly reported this via Twitter to one (but not the only!) of the sites in question and to Firefox Site Compatibility. What do I see? Many CSS and redraw events (thanks to Firefox's profiling tools). In fact, as many events that Firefox alone is able to completely take over 1 (of the 2) cores that I have, with just that single tab open. I don't see those problems with Chromium, unfortunately (or, at least, they are not that perceptible to my computer's CPU). So, before I go on and formally file a bug report, I would love to confirm if other people see the same problems that I am seeing. Do you also see something similar? Your input is highly welcome!

Next.

Previous.