Search Results: "ron"

9 November 2008

Adam Rosi-Kessel: Roslindale Scoop: Himalayan Bistro Coming to the Neighborhood

I have it on very good authority* that our favorite Indian/Nepali restaurant, Himalayan Bistro, is coming to Roslindale (from West Roxbury), into the oft-turned-over location last assigned to NuVo, and Gusto before that. Perhaps the third “-o” restaurant will be a charm. Assuming they serve up the same superlative food and atmosphere as the West Roxbury location, I’m sure this one will be a keeper. (My only concern is that having the two restaurants so close to each other may result in self-competition.) *Authority = Himalayan Bistro delivery guy. You don’t get much more authoritative than that. In other Roslindale Restaurant news, we heard via RVMS recently that Robyn’s Bar and Grill has changed hands to the owners of the Halfway Cafe in Dedham, which could be a change for the better. Roslindale did not need another pizza/sports-bar, and still does not need one, although maybe that’s all the Robyn’s location will ever be. Even more recently, however, we heard an unconfirmed rumor from a neighbor that the sale fell through and Robyn’s is not changing owners. In other potentially disappointing news, the Roslindale Emac and Bolio’s has changed owners again, this time to a co-owner of the Blue Star Restaurant. I want to like Blue Star, but they can’t seem to get the most basic short-order cooking tasks right. A diner must, first and foremost, deliver greasy food fast, hot, and at the same time for the entire group. At worst, serve the kids first. It also helps for the food to be consistent. Blue Star in our experience (many visits) only occasionally satisfies the basic diner requirements, much less delivers any sort of creative urban-chic reinterpretation of the classic retro diner. (By contrast, Deluxe Town Diner in Watertown is our current Greater Boston favorite — it’s always a good sign when a greasy spoon also actively caters to vegans.) Which brings me to Emac and Bolio’s, which apparently will be renamed “Select Caf .” First, why give up the goodwill associated with the Emac’s trademark? Second, the initial signs of the change-over are not promising. A handwritten sign posted in the window announces that the cafe is under new management, and (1) no credit or debit cards will be accepted and (2) no Emac and Bolio’s gift certificates will be honored. I’d love to be proved wrong about this, but I’m pessimistic that this is going to be the Change We Need in Roslindale — namely, a top rate artisanale snobby espresso shop. We can only hope that Simon’s, Flatblack, Cafe Nation, Diesel, or another of their ilk will come occupy one of the vacant storefronts on the courtyard. That we have any vacancies at all in the square, much less several, is a crime against humanity. Technorati Tags: ,

Andrew Pollock: [tech] Keeping hard drives cool

I've had this crazy ATA over Ethernet SAN for my MythTV setup for as long as I've been running MythTV. I'm using minotaur, an old Pentium III 1RU VA Linux server as the "head". Originally, I had 4 IDE hard drives, attached to minotaur via IDE-USB adapters. This worked perfectly fine, but I missed the ability to query SMART information, and do other low-level drive tweaking with hddparm So a while ago, NewEgg had a sale on 750Gb SATA drives, and I bought a 4 port eSATA card, and took the plunge with SATA. That all went fine. The entire time, I've had the 4 hard drives themselves just sitting on top of minotaur, on cork trivets. The whole arrangement is in the bottom of our linen closet, as this is where the patch panel for the apartment is. I've graphed the temperature of linen closet for some time now, but the benefit of having hard drives connected via SATA was that I could easily graph the temperature of them as well, which I started doing recently. The catalyst for wanting to do this was that I had a drive fail, and I was concerned that they were getting too hot, just sitting in the closet with no airflow. Matt Bottrell's recent reminder of Google's research into hard drive failures also helped bring this concern to forefront. Seagate's product documentation for the Barracuda 7200.10 claims that ambient operating temperature must be between 0 C and 60 C. I'm assuming that's the environment the hard drive is in, and not the temperature of the drive itself as reported by something like hddtemp. The closet is typically in the high 30's. If you believe what SMART reports, it seems to imply that anything over 45 C is a Bad Thingtm. So after I had a drive fail, I figured I should probably try to do something about the temperature situation, and started looking around for an external enclosure. I'd previously had problems with the IEC-to-Molex power supplies I was using to power the disks, and think that they'd been the cause of some failures of my IDE disks, so was quite eager to stop using them as well, which was something else an external enclosure would give me. I had trouble finding an enclosure that presented 4 separate eSATA ports, and I was talking to Marc about SATA port multipliers, when he mentioned he had a brand-new unused full-height SCSI enclosure, for four disks, which was surplus to his requirements. Since all I really needed was external power and cooling, I thought I could cannibalise this to my needs. Sure enough, I could just remove the SCSI cables and their Centronics connectors, and feed the eSATA cables out the gap they left, and use the molex-SATA power splitters I already had. Because the enclosure was intended for full-height 3.5" hard drives, there was plenty of air space between each disk. The enclosure included two fans. The results? Well the graph speaks for itself:

Graph of hard drive temperatures (I'm not entirely sure why minotaur's internal disk occasionally reports a very low temperature) The added bonus is I've cleaned up the rats nest of cables in the linen closet. So thanks very much, Marc!

Christine Spang: Switching to Colemak

Way back in mid-late May, I switched keyboard layouts from standard US QWERTY to Colemak. I’d played around with the layout a bit before that and thought it seemed pretty solid, but it hadn’t been a good time to switch then. (I did, however, snag the idea of remapping Caps Lock to Backspace from that early trial though, and to this day that’s probably the most annoying thing about typing on QWERTY, because I associate Caps Lock with Backspace on both layouts now. Anyway.) This time, however, I strategically timed it to coincide with the end of classes, so I had no assignments due and could make a fool out of myself during the first few days of my summer job. Smashing success. It only took a couple days to get past the point of extremely frustrating slowness. Two weeks in I was up to 40wpm, which was about the point where I stopped noticing that I’d taken a backwards step in typing speed, as it didn’t really hinder anything I did on a regular basis. By the end of the summer I was back up to the same speed as I’d been prior to switching (around 75wpm). I didn’t really do any typing lessons after the first few days, as I found just doing whatever I would normally do on a computer much more interesting. The biggest hurdle after the initial adaptation of actually being able to type on the layout was, for a command-line lover like myself, dealing with “hjkl” not being a convenient way of navigating around in console apps like mutt, vim, aptitude, and less. After a bit of experimentation, I stole an idea from this page and started adapting my dotfiles to make these programs use ne for jk and st for hl, and that seems to be working out well. The worst key that this clobbers in general is n, but it’s pretty easy to remap that to QWERTY’s n, which is easy to remember and is the hardly-used k on the Colemak layout. For any interested others, I’ve thrown the relevant dotfile snippets up here. I’d been putting off blogging this because I wanted to finish setting up dotfiles/homedirs-in-git la Joey Hess beforehand, but I figure I’ll never actually get it done if I keep using that excuse. For mutt, the given snippet goes in your .muttrc (or whatever you source keybindings into your muttrc from). The same goes for vim. Aptitude keybindings go in .aptitude/config. For less, it’s a little more arcane: first you stick your keybindings in .lesskey, and then you run the command lesskey. I also remapped screen’s escape key to ctrl-t. Why not Dvorak? Dvorak seems to be the most well-known QWERTY alternative around, so why didn’t I switch to that if I wanted something better? I did try Dvorak first, but the incredibly uncomfortable combination of ls on the right pinky was a complete deal-breaker. I also found it very slow-going to try to adapt to Dvorak after typing on QWERTY for years. The Colemak FAQ has some more notes on Dvorak deficiencies that it addresses. Overall, I’ve found typing on Colemak to be remarkably lacking in anything that particularly bothers me. I still type on QWERTY a little, but mostly just for login prompts on Athena workstations and the desktop machine in my room which my roommate sometimes uses. I have to glance down at the keyboard when typing on QWERTY to get it back in my head, but generally I only need it for a few minutes anyway and it’s no big deal. As long as I glance down occasionally I can still maintain a speed level well above that of frustration. On the plus side, this means that if I look at the keyboard when typing normally in Colemak, I get screwed up because I start thinking in QWERTY. So it’s good touch-typing reinforcement in general.

Simon McVittie: Spec-writing On A Plane

(Written on Friday 16th, posted on Monday)

As I write this, I'm on a plane off the coast of the Netherlands, on the way back from a couple of days designing APIs with Rob McQueen and the RTCom people at NRC Helsinki (who we work with on the chat and VoIP functionality for Nokia internet tablets).

We've had a very useful couple of days, mainly designing the next-generation channel requesting and dispatch API for Telepathy (the same APIs I've been doing preparatory work for on the Telepathy mailing list in the last couple of weeks). API sketches for review and comment are either on are on Merge Monkey or on the way there.

Before even reaching Nokia, Rob and I did a lot of design on the plane over to Helsinki, and I took some notes: here they are, by way of a glimpse at how the Telepathy design process works when we don't have a whiteboard[1] :-)

  • Geoloc looks good in principle, needs some more work
    • add more docstrings
    • add a way to ask people for uncached info (RequestLocations)
    • move access control to Co.I.Presence, call it RichPresenceAccessControl?
  • DeliveryReporting looks good, ish
    • improve wording of delivery-echo and rationale
    • when sending a delivery report, add a reason for the status (using Channel_Text_Send_Error?)
  • Uniqueness requirement for (channel, handle_type != 0, handle) is in the way - let's drop it
  • MSN should use "authentic" 1-1 chats, and use Ch.I.UpgradeableToRoom (name tbd) to migrate the underlying switchboard to be a room
  • XMPP should use Ch.I.UpgradeableToRoom too, but the 1-1 channel may also stay open
  • Mutable handle => handle 0 must stay (for requestotron's benefit)
  • bundles ftw
  • renaming: we want SelfHandleChanged in the core
  • TpC* - add ability to subscribe to ifaces ay construct time (blocks Ready) or later
  • Dispatching: when registering a c'handler, specify everything it can handle
  • If a new bundle can be handled in its entirety by the same handler (call it 'the bundle handler'), do it. Otherwise split it up completely (there is no 'bundle handler').
  • If a channel in an existing bundle can be handled by the bundle handler, send it there, else send to the default handler.
  • Group - add SelfHandleChanged, maybe? Also Connection
  • Add HandleOwners: prop a uu , HandleOwnersChanged(a uu , au)
  • Use TargetHandleType, TargetHandle
  • Stringified initiator handle as a separate property
  • Maybe even a FirstMessage property, although this stretches the definition of "immutable"
  • org.freedesktop.Telepathy.Client interface

Nokia's Mikhail Zabaluev kindly took notes for some further discussion we had with him and Alberto Mardegan about the dispatch API, which he already posted to the mailing list.

We hope this API will make it possible to integrate Telepathy into the desktop better - it should make it a lot easier to share connections between processes in a useful way and hand out incoming channels to the appropriate handlers, which was always a major goal for Telepathy. It should also let us and others implement exciting new notification mechanisms (hi to the people on IRC and the mailing list wanting to patch their media players to integrate with Telepathy! :-)
[1]When we do have a whiteboard, the design process is: "Robot101 scribbles on a whiteboard, smcv writes down <tp:rationale> elements"

Simon McVittie: Implementing D-Bus services with telepathy-glib

(Part 1 of an ongoing series: shiny things in telepathy-glib)
16:46 < epmf> tp-glib is made of magic

—#telepathy, 2008-04-15

Rob pointed out today that I'd been promising to blog about telepathy-glib for several months and still haven't done so. I think there's too much to cover in one blog post, so I'll start with the oldest part - implementing a service (typically a Telepathy connection manager).

While telepathy-glib is (obviously) intended for Telepathy implementors, I think the ideas we've been implementing are likely to be useful for any D-Bus API, particularly flexible/complex APIs where an object implements many interfaces.

Introduction to telepathy-glib telepathy-glib started out as a collection of code extracted from our XMPP connection manager, telepathy-gabble, but at some point it grew beyond that into a wrapper around/partial replacement for dbus-glib. We've been quite pleased with it, really :-) My first major round of work on telepathy-glib, during the first half of 2007, was to split it out from telepathy-gabble (versions up to 0.5.9 were released as part of Gabble 0.5.x tarballs, in fact), leading to the release of the 0.6.x stable branch in late September. This was very helpful for implementing connection managers - Salut, Idle and telepathy-sofiasip (our connection managers for link-local XMPP, IRC and SIP) all started off by forking/cargo-culting from Gabble, and achieved huge code reductions by porting to telepathy-glib. Also, Will Thompson used it in his Summer of Code project, telepathy-haze, to go from nothing to a working and useful Telepathy implementation based on libpurple in a matter of a few months. The second major round of work, which I'll discuss in a later article, added client code to telepathy-glib, obsoleting the older/worse libtelepathy and allowing client programs like Empathy and telepathy-stream-engine to be written using telepathy-glib. In the process, I accidentally reinvented DBusGProxy :-) More details to come later!
Some background: service-side code generation
The secret Collabora code-generation process

(credit: daf)

Supporting D-Bus in the GObject world has always involved quite a lot of code generation. The core API of dbus-glib is heavily reliant on varargs functions, which aren't type-safe and are easy to get wrong. dbus-glib contains a program called dbus-binding-tool, which is meant to generate reasonably sane GObject APIs for D-Bus objects. Unfortunately, it seems to be intended to generate a whole GObject at a time. Early versions of telepathy-gabble used dbus-binding-tool plus a script called gengobject.py to generate API stubs for the exported objects; developers then filled in the blanks, and hey presto, we had a GObject on D-Bus. This was fine up to a point, but had a couple of major drawbacks. Whenever we changed the D-Bus API (quite common during the early development of Telepathy), there was a very laborious and error-prone merging process. We ended up with the following process:
  • copy the D-Bus introspection XML from the telepathy-spec repository into a directory xml/pristine (actually, the canonical form for the spec was Python for a while, and we had a script that exported a contrived object onto D-Bus and introspected itself to get the XML - but that's another story!)
  • preprocess the introspection XML to add the dbus-glib CFunctionName annotation, resulting in a directory xml/modified
  • run dbus-binding-tool and a Python script gengobject.py to generate C source in xml/src
  • three-way-diff the old version of xml/src, the new version of xml/src, and the real C code in src to create a new version of src
  • pray that the diff process hadn't randomly exchanged functions' implementations
  • update the resulting code in src so it worked
  • check the whole mess back into darcs
  • hope that nobody else had made changes that would result in darcs conflicts
If you haven't yet gathered, this was a bit of a nightmare. Also, it was very easy to return the wrong thing from a method without noticing - because all the APIs were varargs, the compiler didn't notice, and the first we'd know about it was a mysterious segfault under certain circumstances.
How telepathy-glib fixes code generation telepathy-glib improves on this by taking advantage of this innocuous-looking feature in dbus-glib:
commit 355ef78d98d6fc65715845d56232199162cab12a
Author: Steve Fr cinaux <steve istique net>
Date:   Thu Aug 17 11:48:20 2006 +0200
    Interface support for bindings.
Instead of running dbus-binding-tool or creating GObjects with D-Bus interfaces, we put the entire Telepathy spec through glib-ginterface-gen.py, a distant descendant of Gabble's gengobject.py. For each interface in the spec, we generate a GInterface that mirrors the D-Bus interface. Any GObject that implements the GInterface automatically gets the D-Bus interface if it's exported onto D-Bus. There are a few non-obvious refinements, though:
  • The signature of the method implementation is always in the mode that dbus-glib calls "asynchronous", where the method implementation can either send a reply message before or after it returns. For "slow" methods, this is the only thing you can do. For instance, many Telepathy D-Bus methods can't return anything until some TCP round-trips to the server have happened. This is also the only thing you can do if you want to extract extra information, like the sender's unique name, from the method-call message (dbus-glib's "synchronous" API doesn't allow this to be done). For "fast" methods, sending a reply message before returning is just as easy as using the "synchronous" API (it's just a difference of syntax), and has an API consistent with that of the "slow" methods, making it easier for service authors.

  • The layout of the GInterface vtable is private, and (auto-generated) accessor functions are used to fill in implementations. This means our ABI doesn't change just because we re-ordered functions in the spec.

  • If no implementation is provided for a method, we just raise an appropriate error (org.freedesktop.Telepathy.Errors.NotImplemented), rather than suffering an assertion failure. This means we can safely add methods to an interface.

  • While we're generating code anyway, we generate some static inline wrapper functions which wrap dbus_g_method_return(), to have type-safe method returns. You can easily check that a method replies with correct types, by checking that the implementation of Foo() replies by calling tp_svc_some_interface_return_from_foo().

  • Similarly, we generate wrapper functions to emit signals, to get type-safe signal emission.

Not all interfaces are stable enough to be included in telepathy-glib's stable API and ABI, so some of our other projects include a copy of the telepathy-glib code-generation tools, and generate their own "mini-telepathy-glib" (traditionally in a /extensions/ directory) for their implementation-specific (drafts of) interfaces. This isn't yet as polished as it ought to be (mainly because we don't want to freeze the augmented-introspection-XML format that we write the Telepathy spec in, because it's rather ad-hoc and hackish in places) but it works quite well in practice. To see what this looks like in practice, have a look at the examples in telepathy-glib, or at a Telepathy connection manager like telepathy-gabble.
Mixins and base classes Another feature of telepathy-glib which makes life easier for connection manager authors is that it provides "mixins" and base classes which implement some of the GInterfaces. There's absolutely nothing magic about the base classes - they don't have any access to private implementation details of the GInterfaces, they just implement them like everyone else does. The "mixins" are only slightly more magical - they store some extra state inside the structures representing GObjects and their classes, and use it to provide default implementations of some or all of the methods on a particular interface (or two interfaces, in the case of the new TpMessageMixin). I'll leave it up to Rob to explain those in greater detail, since I seem to remember that he invented them :-P The examples and regression tests in telepathy-glib are quite good examples of how these work in practice.

Simon McVittie: Encrypted root filesystem on a Debian laptop

I've been meaning to document this for ages... My laptop is set up with an encrypted root filesystem using LVM and dmcrypt. It also has a small Debian stable system for recovery purposes (I don't have a CD drive, so if everything goes horribly wrong, I can't just boot from a live CD). Here's how to set up something similar:

Step 1. Set up the recovery system Start the Debian lenny (beta) installer as usual. (I originally used etch, but these instructions are for lenny - either should work.) When you get to "Partition disks", choose "Manual". Here's the partitioning scheme to use:
  • main partition for LVM, taking up the whole disk minus 1GB or so. select "Do not use", for now
  • 1GB recovery partition at the end of the disk (this will also be the main system's /boot, since /boot needs to be unencrypted anyway). Use the defaults: ext3 mounted at /.
Finish partitioning and write changes to disk, and wait for the base system to install. Say yes to installing Grub to the MBR for now (it might be possible to do the install more cleanly by installing Grub to the recovery partition's boot sector instead - I haven't tested that). Reboot into the freshly installed recovery system and satisfy yourself that it works.

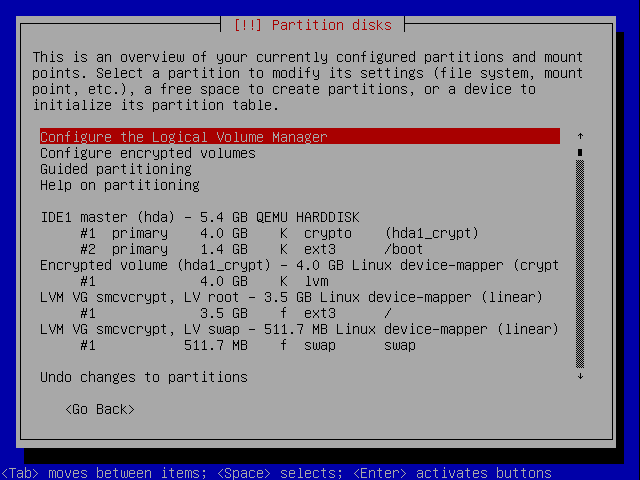
Step 2. Set up the main system Now boot the Debian installer again. This time it's for your installed system. At the "Partition disks" stage, choose "Manual" again. Select the main partition and choose "Use as: physical volume for encryption". Next select "Configure encrypted volumes". Your main partition will now be randomized - this is slow - and some time later you'll be asked for a passphrase. You'll have to type this in at each boot. Select the contents of the "disk" Encrypted volume (hda1_crypt) and choose Use as: physical volume for LVM. Now "Configure the Logical Volume Manager" and create a Volume Group. I always use the laptop's hostname as the VG name (this reduces confusion if you ever plug the disk into another machine for disaster recovery). Create a Logical Volume called swap, the size you want your swap space to be. If you plan to use suspend-to-disk, this needs to be at least as large as your RAM. Create a Logical Volume called root, for the root filesystem. If you want separate "partitions" for things like /home, now is a good time to create them too; if you want to use my schroot howto, leave some unallocated space in the VG for that. Set your swap LV to be used as a swap area, and your root LV to be used as ext3 mounted at /. If you wanted extra LVs, set them up too. Also set your recovery partition to be used as ext3, mounted on /boot, and not reformatted. It should now look something like this (smcvcrypt is the name of a KVM virtual machine in which I've been testing these instructions, normally you'd have the laptop's hostname there). Screenshot from d-i Proceed with the installation. Install Grub to the MBR - this will temporarily make the recovery system unbootable, but shrug never mind. Finish the installation and reboot into your new main system.

Step 3. Make them dual-boot Within the main system your recovery system is also visible, at /boot. Bind-mount /dev onto /boot/dev, chroot into /boot, and run "update-grub /dev/hda2", where hda2 is the partition where the recovery partition is. Leave the chroot. Edit /boot/grub/menu.lst and put this right at the end:
title Go to recovery system
root (hd0,1)
chainloader +1
(Replace (hd0,1) with what Grub thinks the recovery partition is - the second number is the partition number starting from 0, so /dev/hda5 would be (hd0,4) and so on.) Also edit /boot/boot/grub/menu.lst and put this right at the end:
title Back to main system
root (hd0)
chainloader +1
Also, still in /boot/boot/grub/menu.lst, go to the top of the file and change the colour scheme to something else (I used a red background) to indicate that this boot menu is for the recovery system. Reboot and try it out. You should now have an extra boot menu option, "Recovery system". Selecting it will switch to the recovery system's boot menu, which has an option to switch back, and so on. Each boot menu also has some entries for kernels, any of which will boot with the appropriate root filesystem (encrypted root for the main system, unencrypted for the recovery system). Success!

Simon McVittie: Integrating Enemies of Carlotta with Postfix

From the "doing sysadmin over wobbly 3G while waiting for our plane to be allowed to take off" department comes this bit of mailing list setup. By his own admission, Rob is better at configuring Postfix than he is at making blog posts, so I get to be the one posting this...
09:58 <@Robot101> my postfix -> eoc integration is basically ninja, if I might 
                  say so myself
09:58 <@Robot101> so, an eoc transport in master.cf:
09:58 <@Robot101> eoc       unix  -       n       n       -       10      pipe 
                  user=list argv=/usr/bin/enemies-of-carlotta --quiet 
                  --incoming --sender=$ sender  --recipient=$ recipient 
09:59 <@Robot101> then in main.cf:
09:59 <@Robot101> eoc_destination_recipient_limit = 1
09:59 <@Robot101> virtual_mailbox_domains = lists.collabora.co.uk
09:59 <@Robot101> virtual_mailbox_maps = pcre:/etc/postfix/list_transports
09:59 <@Robot101> transport_maps = pcre:/etc/postfix/list_transports
09:59 <@Robot101> then a script/cron:
09:59 <@Robot101> su -c "enemies-of-carlotta --show-lists" list   sed 
                  's,\(.*\)@\(.*\),/^\1(-[^@]*)?@\2$/ eoc,' 
                  >/etc/postfix/list_transports
09:59 <@Robot101> giving list_transports like this:
09:59 <@Robot101> /^test(-[^@]*)?@lists.collabora.co.uk$/ eoc
09:59 <@Robot101> (thanks to smcv for assistance with regexp-generation regexp)
...
10:01 <@wjt> ten points for using the best -named mlm
10:01 <@Robot101> 2000 points for not having a mailing list system held 
                  together with procmail, shell, duct tape, gash and string

Martin Michlmayr: GCC 4.4 and better preprocessor checks

GCC 4.4 will show more preprocessor errors when compiling code, partly because some new checks have been added and partly because the full preprocessor directives are now checked. So let's review some common problems. Let's take some code like this:
#ifdef A
#elif
#endif
This will now give:
t.c:2:6: error: #elif with no expression
The reason is that an #elif always needs an argument. Looking at the code, it's obvious that a #else should be used. Another common issue is this one:
#define B
#ifdef A
#elif B
#endif
The problem here is that you're trying to check whether B is defined, so the third line has to be:
#elif defined(B)
Finally, the following code:
#ifdef A
#elif define(B)
#endif
will give:
t.c:2:13: error: missing binary operator before token "("
It took me a minute to see what was wrong with the code... but define is a typo and what you really want is defined.

8 November 2008

Joerg Jaspert: Debian mirror scripts

With a small mail to our mirrors-announce list, I just opened the work of more than one month to the public. Even better, I strongly encourage every mirror admin to use my scripts, or at least scripts that follow a minimal set of rules I wrote down… Some long time (somewhere in April or May this year) I got added to the Debian mirroradm group. First it was only to get some problems with packages.debian.org solved, but later on I started doing more. This group is basically the one that handles the archvsync user on .debian.org machines and also manages the official Debian mirrors listing. As the archvsync user exists on multiple .debian.org machines, and many of them do mirror a copy of our archive for various reasons, all of them had some version of a mirroring script, and sometimes also a version of a pushmirror script. Unfortunately, as they all had been maintained mostly on their own per machine - they sometimes had evolved a bit different. Additionally all of them had a few problems which could leave us with a broken mirror behind, despite it looking all well. So on Sept. 26 I decided to trash it all and rewrite the script and put it all in a VCS (and selected git). For that I set myself a few goals, like (in no particular order) Now, 109 commits and more than a month later, I was finally able to open the scripts to the wide public. (Had multiple people test them before this, but thats always different than a real “release”). The scripts are in use on all .debian.org machines and some other mirrors already, so I’m fairly sure they work.
As I already wrote, Debian mirror admins are strongly encouraged to use this scriptset and not to invent their own. In case you miss a feature either send me a mail describing it, or better, a patch implementing it. I’m happy to implement as much as possible (and sensible :) ) And while it is discouraged to use own scripts, sometimes people have reasons to have their own, so there is now a minimal set of functionality that such a script MUST support. All of those requirements are easy to fulfill. Well, at least the MUST ones. The first one is basically a given, all scripts I know are doing this already. The second one sounds more complicated, but actually might just be about 4 lines of actual code changes. Just touch an extra file before you gain a lockfile (to avoid two scripts running at the same time) and then rerun rsync as long as that extra file is around. (It helps to rm this trigger file right before you call rsync :) ). The should directive is actually a little more work to implement correctly. I won’t show source here, read the ftpsync script if you want to see it, but I try some small explanation. Background: Debian mirror synchronisation is usually done by scripts that get started via ssh. As mirror operators (understandably) do not like their upstream mirror to be able to login, this is done using “ssh triggers”, a feature I wrote about earlier. Those are sshkeys using a forced command, so nothing else than this command will be run, ever. SSH, if used with such forced commands, has the helpful feature that it sets the environment variable SSH_ORIGINAL_COMMAND containing the original arguments. Which means that, if the mirror pushes you with “ssh yourhost -l mirror sleep 1” you will see *sleep 1 in that variable. It is what many mirror operators currently use when pushing their downstreams. Now, we can use that to tell the receiving end all things we want it to know. If you look in my script you will see that I defined a little more than the minimal arguments. But none of the additional ones are a requirement, they only make life much easier. My script currently understands, additional to the 3 minimal ones:
As if that wasn’t enough, I also had to rewrite the runmirrors script. The old 10-line one just didn’t cope with the more general approach. This script is used to “push” your downstream mirrors, telling them that they need to update. (Which is the only sane way to run a mirror. cron is just not made for mirrors that can update at random times!). One nice new feature of it is the ability to update multiple mirrors nearly at the same time. This is extremely helpful in case of DNS Round Robin entries like security.debian.org (multiple hosts offering the same archive under one hostname). You do not want to have such hosts out of sync. Not even for a minute, if you can avoid that. So we now push the mirrors with sync:stage1 as argument. Then we wait until all of them have finished the stage1 sync before we push them all again, this time with sync:stage2 as argument. This will erase any update delays thanks to network latency / low bandwidth one of the security mirrors might have, as the large transfers (all the binary and source packages) are done in stage1. They can take time, a normal user won’t notice it - the Package and Source indices are not transferred yet. They arevery small and as such transfered pretty fast whenever stage1 is done everywhere and we tell mirrors to do stage2.
All in all it was a pretty nice exercise writing those scripts. Comments: 0

7 November 2008

Axel Beckert: e-mail.is-not-s.ms

When I first read http://two.sentenc.es/ in (if I remember correctly) madduck’s signature, I thought something like “This can’t be! Why are people castrating themself?” Although I really understand that the inventor has good reasons for such a personal policy, I notice how much time I waste by trying to fit all the information I want to transmit in the 160 characters a short messages allows — or, even worse, into the 140 characters microblogging services like identi.ca or Twitter allow. So I had to oppose something to this, but even to only reach the coolness level of the domain “sentenc.es” is hard, you probably can’t top it at all. For luck, I’m not alone and Venty had the right idea for a hostname which has at least some geeky niveau. So here it is, our pleading for e-mails as long and detailed as necessary:

http://e-mail.is-not-s.ms/ A German version will be available soon at http://e-mail.ist-nicht-s.ms/. Feel free to add either URL to your e-mail signature. :-) Oh, and thanks to the Government of Montserrat which allows strangers to register .ms domains without any hassles. :-) Update / FAQ Seems to be necessary to make a few things clear…

  1. No, I do not think that everyone using two.sentenc.es has neither style nor knows anything about grammar or punctuation. What I say is that the site two.sentenc.es itself with its comparision to short messages (and especially without reading the author’s blog post about the site’s background) indirectly suggests to drop grammar, punctuation and style by cramming all information into a limit number of characters as often done with short messages or microblogging. And the limitation in senctences leads to tapeworm sentences which I try to avoid since they’re considered bad style, too.
  2. And yes, it’s consciously written and designed to be the opposite of two.sentenc.es — even the colors and the font — and therefore is of course very close to the original. See it as it parody or satire if the closeness makes you angry.
  3. And no, I currently don’t care if the site makes less sense if you don’t know two.sentenc.es — people usually can follow hyperlinks on websites.
  4. We weren’t the first ones who noticed that e-mail is not SMS. An example of the problem described above from 2001.

John Goerzen: Search for Backup Tools

Since the last time I went looking for backup software, I've still be using rdiff-backup.

It's nice, except for one thing: it always keeps an uncompressed copy of your current state on the disk. This is becoming increasingly annoying.

I did some tests with dar and BackupPC, and both saved considerable disk space over rdiff-backup. The problem with dar, or compressed full/incrementals with tar, is that eventually you have to make a new full backup. You have to do that, *then* delete all your old fulls and incrementals, so there will be times when you have to store a full backup twice.

The hardlinking approach sounds good. It's got a few problems, too. One is that it can lose metadata about, ironically enough, hard links. Another is that few of the hard linking programs offer a compressed on-disk format. Here's what I've been looking at:

BackupPC

Nice on the service. I'm a bit annoyed that it's web-driven rather than commandline-driven, but I can look past that. I can also look past that it won't let me clamp down on ssh access as much as I'd like.

BackupPC writes metadata to disk alongside files, so it can restore hard links, symlinks, device entries, and the like. It also has the nice feature of being able to hard link identical files across machines, so if you're backing up /usr on a bunch of machines and have the same files installed, you save space. Nice.

BackupPC also can compress the files on your disk. It uses pre-compression md5sums for identifying files to hard link, which is nice.

Here's where I get nervous.

BackupPC doesn't just use regular compression, from say gzip or bzip2. It uses its own low-level algorithm centered around the Perl deflate library. And it does it in a nonstandard way owing to a supposed memory issue with zlib. Why they don't just pipe it through gzip or equivalent is beyond me.

This means that, first off, it's using a nonstandard compression format, which makes me nervous to begin with. If that weren't annoying enough, you have to install Perl plus a bunch of modules to extract the thing. This makes me nervous too.

Dirvish

Doesn't support compression.

faubackup

Doesn't support compression.

rdup

Supports compression and encryption. Does not preserve ownership of things unless the destination filesystem does (meaning you must run as root to store your backups.)

Killer lack of feature: it does not preserve knowledge about what was hardlinked on the source system, so when you restore your backup, all hardlinks are lost. Epic fail.

rsnapshot

Doesn't support compression.

StoreBackup

Does support compression, appears to restore metadata in a sane way. Supports backing up to a different machine on the LAN, but only if you set up NFS. Looks inappropriate for doing backups over VPN. Comprehensive, though confusing, manual. Looks like an oddball design with an oddball manual.

So, any suggestions?

John Goerzen: Wow

People often talk about "memorable moments" -- times where pretty much everybody in the country remembers where they were at that exact time.

There are probably only two of those moments I can remember: the 1989 earthquake during the World Series and the time 9/11 happened. My car was in for service that day, and I was sitting in the lobby of the mechanics watching it on TV.

So now I have a third: watching Barack Obama win the presidency.

We were installing some new blinds in the kitchen while listening to the coverage on NPR, periodically going over to the office to watch the TV coverage on the computer. (Our TV is upstairs right now, so that was more convenient.)

A few minutes before the election was called, I remember Brian Williams saying something like "We're going to go to local stations now, but you better not walk away. We'll have some amazing news at the top of the hour."

We watched that announcement, then saw McCain's speech, and finally Obama's speech (missed the first minute or two of it actually). What an amazing evening.

Then seeing the stories of people celebrating all around the country and around the world: the impromptu party in front of the White House Tuesday night, the small gathering at the Lincoln Memorial Wednesday morning, the Obama parties all around the world. And we watched it on TV in our house while Jacob slept. I feel like I missed out somehow.

Ian Wienand: Spot the bug!

See if you can spot the bug in this code!
#include <stdio.h>
#include <stdlib.h>
int main(void)
 
	union  
		unsigned char raw[8];
		struct  
			char one;
			int two;
			char three;
			char four;
			char five;
		  formatted __attribute__((packed));
	  test;
	printf("one   : %d\n", (int)&test.formatted.one - (int)&test);
	printf("two   : %d\n", (int)&test.formatted.two - (int)&test);
	printf("three : %d\n", (int)&test.formatted.three - (int)&test);
	printf("four  : %d\n", (int)&test.formatted.four - (int)&test);
	printf("five  : %d\n", (int)&test.formatted.five - (int)&test);
	return 0;
 
$ gcc -Wall  -o packing packing.c
$ ./packing
one   : 0
two   : 4
three : 8
four  : 9
five  : 10
Here's the relevant bit from the gcc manual:
For an enum, struct or union type, you may specify attributes either between the enum, struct or union tag and the name of the type, or just past the closing curly brace of the definition. The former syntax is preferred.
By getting the packed attribute in the wrong place (if it's not clear, it should be before formatted), it is applied to the variable rather than the type. The compiler (both gcc and icc do this) has already laid out the structure, so misses the packing directive, and unfortunately doesn't warn (that may be a bug?). I can tell you from experience this can be hard to track down!

6 November 2008

Pablo Lorenzzoni: Bash prompts: the essential

Bash is probably the most common command-line shell in the GNU/Linux world. Although a lot of people use alternate shells (such as Zsh), Bash is still shipped with most mainstream distros as the default. Once you have a lot of different remote machines, all running Bash as the shell, it becomes increasingly difficult to pay attention to the prompt, and typing reboot in a machine different from the one you wanted becomes more likely. I deal with that problem by changing Bash prompts First of all, the basics: Bash prompts are just environment variables with special characters you can set and export. Bash has four of these variables: PS1 to PS4, but usually only the first two matters (actually, just PS1 for a reference on the others, check the manpage). The most common PS1 string is:

spectra@home:~$ echo $PS1
\u@\h:\w\$
spectra@home:~$
This has 4 special characters, escaped with a backslash: \u informing us the username; \h informing us the hostname; \w, informing us the working directory; and \$, which gives us the $ in the end of the prompt (more on this later). So, essentially, one can change that string to anything else

spectra@home:~$ PS1="my_shell_prompt\$ " 
my_shell_prompt$
Pretty easy. You can check a complete reference of the special characters at the section PROMPTING of bash manpage, but the most useful IMHO are the following: Also, as part of the prompt string, one can use ANSI Colors enclosed as non-printing characters (that is between \[ and \]). ANSI sequences always begin with an ESC[ and end with an m . (Yes Really arbitrary but that s the way it is ). ESC can be represented as \e Here is a list of the most common colors in ANSI sequences: Now, notice that there are two numbers separated by a semi-colon the first is always 0 (zero) in the colors I pointed above, but it actually refers to an ANSI attribute called Select Graphic Rendition You can use 0 (zero) to normal colors, 1 for bold, 2 to faint, etc. So \e[0;30m refers to BLACK, \e[1;30m refers to DARK GREY. The Wikipedia has a good article on these escape sequences. Once you re satisfied with something printed in a color, to go back to the default (to reset), you issue the \e[0m escape sequence. So, back to my problem Each different machine gets a different color for the hostname. On hospital machine, for instance, my PS1 looks like:

spectra@hospital:~$ PS1="\[\e[1;33m\]\u\[\e[0m\]@\[\e[0;35m\]\h\[\e[0m\]:\[\e[0;32m\]\w\[\e[0m\]\$ " 
spectra@hospital:~$
With \e[0;35m (Purple) for the hostname. On home machine, it may be \e[0;34m (Blue)... On server , it may be \e[0;36m (Cyan), and so on After a while, you get used to the color and end up linking the color to the machine so that typing reboot on a machine with the wrong color gets harder than before. To make the changes permanent, put export PS1 in one of the config script of bash (.bashrc, .bash_profile, etc). On some systems, /etc/environment holds lots of environment variables definitions. I just scratched the surface That s just what works for me The Bash-Prompt-HOWTO has some interesting examples, and I actually have a friend who uses more esoterical stuff, such as fancybash or bashish, but I ll leave this up to you

Mike Hommey: Emptying a deleted file

Yesterday, at work, we had the typical case where df would say there is (almost) no space left on some device, while du doesn’t see as much data present as you would expect from this situation. This happens when you delete a file that another process has opened (and, obviously, not yet closed). In typical UNIX filesystems, files are actually only entries in a directory, pointing (linking) to the real information about the content, the inode. The inode contains the information about how many such links exist on the filesystem, the link count. When you create a hard link (ln without -s), you create another file entry in some directory, linking to the same inode as the “original” file. You also increase the link count for the inode. Likewise, when removing a file, the entry in the directory is removed (though most of the time, really only skipped, but that’s another story), and the link count decreased. When the link count is zero, usually, the inode is marked as deleted. Except when the usage count is not zero. When a process opens a file, the kernel keeps a usage count for the corresponding inode in memory. When some process is reading from a file, it doesn’t really expect it to disappear suddenly. So, as long as the usage count is not null, even when the link count in the inode is zero, the content is kept on the disk and still takes space on the filesystem. On the other hand, since there is no entry left in any directory linking to the inode, the size for this content can’t be added to du’s total. Back to our problem, the origin was that someone had to free some space on a 1GB filesystem, and thought a good idea would be to delete that 860MB log file that nobody cares about. Except that it didn’t really remove it, but he didn’t really check. Later, the “filesystem full” problem came back at someone else, who came to ask me what files from a small list he could remove. But the files were pretty small, and that wouldn’t have freed enough space. That gave me the feeling that we probably were in this typical case I introduced this post with, which du -sk confirmed: 970MB used on the filesystem according to df, but only 110MB worth of data… Just in case you would need to find the pid of the process having the deleted file still opened, or even better, get access to the file itself, you can use the following command:
find -L /proc/*/fd -type f -links 0
(this works on Linux ; remove -L on recent Solaris ; on other OSes, you can find the pid with lsof) Each path this command returns can be opened and its content accessed with a program, such as cat. That will give access to the deleted content. I already adressed how to re-link such a file, which somehow works under Linux, but in my case, all that mattered was to really remove the file, this time. But we didn’t know if it was safe to stop the process still holding the file, nor how to properly restart it. We were left without a possible resolution, but still needed to come up with something before the filesystem gets really full while waiting to be able to deal with the root of the problem. The first crazy idea I had was to attach a debugger to the process, and use it to close the file descriptor and open a new file instead (I think you can find some examples with google). But there was no debugger installed. So, I had this other crazy idea: would truncate() work on these /proc/$pid/fd files? You know what? It does work. So I bought us some time by running:
perl -e 'truncate("/proc/$pid/fd/$fd", 0);'
(somehow, there is no standard executable to do a truncate(), so I always resort to perl) Afterwards, I also verified the same works under Linux (where you wouldn’t really know what it’d do with these files that are symbolic links to somewhere that doesn’t exist). The even simpler following command works, too.
> /proc/$pid/fd/$fd
It doesn’t truncate() but open() with O_WRONLY O_CREAT O_TRUNC, and close() right after (to simplify), which has the same effect. Good to know, isn’t it?

Martin-&#201;ric Racine: Available for a new job

A couple of years ago, I started what has probably been the best job I've held so far, as a Business Development Manager for Artec Group where I focused on marketing and selling the ThinCan LTSP client. During that time, I used a combination of Guerrilla Marketing techniques to spread the word about this cool Estonian embedded platform in its LTSP client configuration and defined an extremely tight market-oriented focus that saw this relatively obscure electronic design start-up rise to the forefront of the LTSP hardware market and also brought the company commendable notoriety in the Coreboot community, thanks to its Programmable LPC Dongle, a low-cost ROM emulator that can be used to bootstrap various embedded hardware and test firmware images. Looking back at close to 3 years with Artec (if we include the stint I did at Linutop), I most fondly remember how I managed to bring the Estonian and Turkish nations closer together in collaborating on Innovation. On my first visit to Turkey, I had noticed that very little is know about Estonia in Turkey, even though both countries have a collaboration that dates back to the 1920's, so my tactic was to introduce Estonia's achievements as a whole, to establish confidence in Artec's offering. It worked: Among other things, my idea to organize an Estonian ICT Conference during the visit of Estonian PM Andrus Ansip in Turkey created a lot of extremely positive buzz that resulted in Estonia being mentioned as a trendy country in a prime time Turkish TV series. During this time, I've also made a lot of contacts among the Estonian and Turkish business communities and, more surprisingly, among the Estonian diplomacy who, much to my amazement, welcomed my ideas for better promoting Estonian interests abroad with great enthusiasm. Come December 2008, my time at Artec will become a page in my employment history. While the Thincan remains one of Artec's key products, current marketing and sales resources are focused on new markets and new technologies that completely fall outside my core expertise, which is why the company decided to let me go. I thus welcome offers from interested parties in Coreboot or LTSP markets. Other refreshing offers from outside the box - such as in business diplomacy - are equally welcome, as I've been pondering a career change for a long time.

Russell Coker: EC2 and IP Addresses

One of the exciting things about having a cloud computing service is how to talk to the rest of the world. It’s all very well to have a varying number of machines in various locations, but you need constant DNS names at least (and sometimes constant IP addresses) to do most useful things. I have previously described how to start an EC2 instance and login to it - which includes discovering it’s IP address [1]. It would not be difficult (in theory at least) to use nsupdate to change DNS records after an instance is started or terminated. One problem is that there is no way of knowing when an instance is undesirably terminated (IE killed by hardware failure) apart from polling ec2-describe-instances so it seems impossible to remove a DNS name before some other EC2 customer gets a dynamic IP address. So it seems that in most cases you will want a constant IP address (which Amazon calls an Elastic IP address) if you care about this possibility. For the case of an orderly shutdown you could have a script remove the DNS record, wait for the timeout period specified by the DNS server (so that all correctly operating DNS caches have purged the record) and then terminate the instance. One thing that interests me is the possibility of running front-end mail servers on EC2. Mail servers that receive mail from the net can take significant amounts of CPU time and RAM for spam and virus filters. Instead of having the expense of running enough MX servers to sustain the highest possible load even while one of the servers has experienced a hardware failure there is a possibility of running an extra EC2 instance at peak times with the possibility of running a large instance for a peak time when one of the dedicated servers has experienced a problem. The idea of having a mail server die and have someone else’s server take the IP address and receive the mail is too horrible to contemplate, so an Elastic IP address is required. It is quite OK to have a set of mail servers of which not all servers run all the time (this is why the MX record was introduced to the DNS) so having a server run periodically at periods of high load (one of the benefits of the EC2 service) will not require changes to the DNS. I think it’s reasonably important to minimise the amount of changes to the DNS due to the possibility of accidentally breaking it (which is a real catastrophe) and the possibility of servers caching DNS data for longer than they should. The alternative is to change the MX record to not point to the hostname of the server when the instance is terminated. I will be interested to read comments on this issue. The command ec2-allocate-address will allocate a public IP address for your use. Once the address is allocated it will cost $0.01 per hour whenever it is unused. There are also commands ec2-describe-addresses (to list all addresses allocated to you), ec2-release-address (to release an allocated address), ec2-associate-address to associate an IP address with a running instance, and ec2-disassociate-address to remove such an association. The command “ec2-associate-address -i INSTANCE ADDRESS” will associate an IP address with the specified instance (replace INSTANCE with the instance ID - a code starting with “i-” that is returned from ec2-describe-instances. The command “ec2-describe-instances grep ^INSTANCE cut -f2” will give you a list of all instance IDs in use - this is handy if your use of EC2 involves only one active instance at a time (all the EC2 API commands give output in tab-separated lists and can be easily manipulated with grep and cut). Associating an IP address with an instance is documented as taking several minutes, while Amazon provides no guarantees or precise figures as to how long the various operations take it seems that assigning an IP address is one of the slower operations. I expect that is due to the requirement for reconfiguring a firewall device (which services dozens or maybe hundreds of nodes) while creating or terminating an instance is an operation that is limited in scope to a single Xen host. One result that I didn’t expect was that associating an elastic address is that the original address that was assigned to the instance is removed. I had a ssh connection open to an instance when I assigned an elastic address and my connection was broken. It makes sense to remove addresses that aren’t needed (IPv4 addresses are a precious commodity) and further reading of the documentation revealed that this is the documented behavior. One thing I have not yet investigated is whether assigning an IP address from one instance to another is atomic. Taking a few minutes to assign an IP address is usually no big deal, but having an IP address be unusable for a few minutes while in the process of transitioning between servers would be quite inconvenient. It seems that a reasonably common desire would be to have a small instance running and to then transition the IP address to a large (or high-CPU) instance if the load gets high, having this happen without the users noticing would be a good thing.

5 November 2008

Neil Williams: Componentisation of Debian/Emdebian

OK, I know I've been very quiet on the blog for weeks now but I have my reasons and all will become clear, eventually. I'm principally waiting for the Lenny release before being able to start full discussions about certain ideas that have been consuming a lot of my time recently. I continue to do what I can to get Lenny out of the door because the wait is driving me nuts. (Fixed another RC bug yesterday, yippee!)

Anyway, something I can talk about is Emdebian Grip. Emdebian has always wanted to support "in-between" devices that don't need the full-on cross-build everything approach of the current Emdebian packages for ARM but don't quite have room for a full Debian install either. Until I had at least a basic package set available via the cross-building system, I didn't want to start working on an intermediate system, for reasons of simplicity mainly, but also because I knew that getting a cross-building package set would involve changes to the tools needed for the intermediary set.

Bah, I'm waffling again. For the background, see Emdebian, Squeeze, Grip and Crush.

The good news is that Emdebian Grip, once running, will take far, far less time (for everyone) than the full-on cross-building malarkey of Emdebian Crush. Grip can be 99.9% automated by breaking Debian into discrete package sets or 'components'.
Componentising Debian for Emdebian
Emdebian Grip is about a smaller Debian, nothing more. No changes in functionality, no changes in dependencies; only changes in final installation size and Packages.gz size. It means using the code from dpkg-cross to unpack packages, remove unwanted files and repack the .deb. Yes, yes, this can be done one package at a time at a trivial level. Emdebian Grip seeks to bring a standard method for this operation that will work for all packages on any architecture for any architecture from any suite, creating and maintaining repositories of "gripped" packages for use in devices like my Acer Aspire1 where you just don't need documentation, manpages and the rest. Squeeze is the obvious target release but any release supported by the current version of dpkg could be "gripped" too, like oldstable.

The componentisation comes in at the level of the Packages.gz file. If the device cannot realistically be expected to run CAD software or has no fancy graphics or other power-hungry hardware, why should packages that need such resources clutter up the apt-cache list? This data isn't just slowing down searching for packages you do want, it slows down every installation process (that bit about 'Reading database . . . . . '), it slows down the process of getting the updated cache data in the first place because there is more of it, it wastes space on your device in several different places when the whole point of Emdebian is that disc space is not cheap and it wastes your precious battery power if you need to do simple package management stuff away from the mains. What is needed is a mini-repository, a mini-mirror that just contains the parts of Debian that your machine needs - a "well-trimmed" mirror with sources and all dependencies satisfied, a mirror that can be automatically updated but which doesn't keep getting NEW packages that you won't use. New dependencies will be added, yes. New packages unrelated to what you currently use? Absolutely not. You could even keep a mini-mirror on your home network, updating and "gripping" while you sleep, because a mini-mirror should be a lot, lot smaller than a standard Debian mirror.

I now have a script that will do the work, what I've lacked is the idea on how to "feed" packages to the Gripper. :-)

So, I'm going to be exploring this method:
  1. An arbitrary package set - say the output of 'dpkg -l' from the target machine setup by an expert, or 'dpkg --get-selections' or just the packages from a normal debootstrap - the basic idea is to start with only the packages you absolutely must have for your target device.

  2. A very small wrapper for some debootstrap code that downloads those .debs from the Debian mirrors - debootstrap can cope with choosing the mirror, the architecture, the suite etc. (already written, landing in Emdebian SVN soon).

  3. Parse the list of packages (.debs) and use 'apt-cache showsrc' to convert into a list of source packages. (Script done).

  4. 'apt-get source' to match the source package to the binary. At this point, we have what amounts to a partial mirror but with very well defined limits. There are other ways of doing the same thing so anything that gets you to this point is as equal as the steps above, as long as the .debs exist alongside the .dsc and all associated source package files. What you need is full control over the list of packages at this stage, we'll worry about dependencies later.

  5. Simple scripting parses the .dsc to create suitable debian/files content (done).

  6. dpkg-genchanges regenerates the .changes file - critical for keeping the Gripped packages with the correct source packages in the final Grip repository

  7. Now run 'emgrip' against the .changes file to convert the .debs, update the .changes file with the new, smaller, .deb details and copy everything into a suitable incoming/ directory.

  8. point your repository software (tested with reprepro) at the incoming/ directory and generate your Gripped repository - which only contains the packages you listed at the start, just smaller. reprepro has a neat way of allowing foobar-1.2.3-2 to be included even if foobar-1.2.3-1 does not exist in the repository, as long as foobar_1.2.3.orig.tar.gz exists somewhere that reprepro can find and even though foobar-1.2.3-2.dsc does not mention the .orig.tar.gz. Neat! (Tested and working.)

  9. Run 'edos-debcheck' against the repository and "catch-up" with whatever packages are needed to make the repository as a whole "trimmed" (no unresolved dependencies).

  10. Keep the update script running as a cron task to pull updated packages from incoming.debian.org, run the .changes through emgrip and update your repository.

  11. Clean out the .debs, leave the source packages and restart the process for another architecture. (Crafty!)

  12. Possibly, to support those who can afford to do a small amount of compilation on their Emdebian Grip device, add a second repository that provides the Build-Depends that may be missing from the initial package set - stuff like automake and pkgconfig. Depending on how that works out, it might not be many packages and it may be easier to fold them into the mini-mirror anyway.

  13. Instead of 20,000 packages, I'm expecting something closer to 2,000, per mini-mirror.

  14. The process of "gripping" a package also drops numerous control fields (like Homepage and VCS*), as well as Recommends, Suggests and Enhances as well as truncating the long description at a maximum of four lines - all in the name of reduced package data sizes.

  15. The end result is that each mini-mirror contains a component package set for Emdebian Grip, using Debian packages. Mini-mirrors are still "well-trimmed" (no unresolved dependencies) because you get to choose which packages you include and if a particular package tries to bring in both Gtk and KDE dependencies, you can choose to omit that package and use a different one.

  16. Whether Emdebian Grip will or should support dropping certain binary packages from the repository is a difficult issue - Emdebian Crush is probably the preferred route if you need to start optimising an Emdebian Grip mini-mirror that harshly.

  17. Another wrapper will be needed to clean out cruft (old dependencies, outdated packages etc.) - that one may be harder to achieve by automation.


The first Emdebian Grip repositories will be for ARM, armel and i386, based on an XFCE environment package set.

"Gripping" all the packages in my /var/cache/apt/archives (about 1Gb) took about 30 minutes on a fast laptop that was doing other things at the time - the real packages will be "gripped" on the Emdebian server and for multiple architectures in sequence. It's certainly conceivable that any number of mini-mirrors can exist with any number of package sets (components), all with "gripped" packages. You can choose to "grip" .debs upon download from a normal Debian mirror but that wastes time if there is more than one device, it wastes space in /var/lib/apt/lists and /var/lib/dpkg/ and wastes bandwidth. For portable devices that you want to be using, not updating, I think that a mini-mirror is a worthwhile bonus.

Expect a 20% reduction in installation size (for more, you'll need the cross-building, functionality-modifying Emdebian Crush shebang) but a large decrease in the size of all the apt-cache data and dpkg status data. I'm hoping to push towards 30% reductions but most of these figures are guesswork right now.

And beyond the mini-mirrors? Debian-Installer, of course. I really need to set some time aside to prepare an Emdebian Grip installer using current D-I. Simple things like:

It really, really annoys me that I have to spend ages getting devices like the Acer Aspire1 working properly under Debian and that I have to take particular care during the installer to change the Debian default to something more sane for that kind of device. For Debian to be The Universal Operating System, the installer needs to be as smooth on an NSLU2* as on a standard desktop, a fast server and a cluster. This isn't just an architecture thing, there are big and small devices in all architectures, it needs to be a machine:variant thing. Mini-mirrors of single components are a start and part of the bigger answer is to support machine-specific configuration packages in these mini-mirrors. Packages that only exist in a specific mini-mirror and are specifically designed to setup a host of machine-specific settings, blacklist certain modules and enable others, set sensible settings in /etc/fstab and other places based on results from things like powertop, turning off features for some devices and turning them on for others. The whole point of such packages is that what they do would be insane on what would currently be considered a "typical Debian machine".

*(I'm not talking about an NSLU2 with an external hard drive here, I'm talking about fitting Emdebian Crush into the 6.4Mb of space on the NSLU2 itself so that external hard drives can be hot-plugged, as well as devices like the OpenMoko and iPAQs etc.)

Don't get me wrong, D-I does a fantastic job for the kinds of devices Debian currently supports but there are a host of other devices out there that need customised solutions where a mini-mirror and a machine-specific configuration package can remove huge amounts of hassle from the actual installation process. Emdebian Crush already uses machine:variant specific packages and the current Emdebian packages repository is, itself, a mini-mirror, albeit not well trimmed.

Let's make the most of "Debian Squeeze" - let's squeeze it onto more devices and make it even easier to get Debian onto anything.

Francois Marier: Converting any video to a podcast

If you don't always have time to sit down in front of your computer to watch long video presentations (lectures, talks, etc.), then you might find this simple script useful. That's what I use to convert any video file to a podcast that I can listen to on the go.

First, dump the audio using mplayer to a file called audiodump.wav:
mplayer -vo null -ao pcm:fast input_video_file
Then, if you want, you can downsample that wave file (using sox) since voice doesn't need the same quality as music:
sox audiodump.wav --rate 32000 -1 --channels 1 audiodump_small.wav vol 0.9 dither
Finally, encode the file as in the SPEEX format (if your music player supports it):
speexenc --denoise --vbr --dtx audiodump_small.wav output.spx
You could also use the OGG Vorbis format:
oggenc --downmix --output=output.ogg audiodump.wav
or create an MP3 using lame:
lame -mm audiodump.wav output.mp3
It works very well with Youtube videos, but you have to download the video first using youtube-dl or clive.

4 November 2008

Ross Burton: OfflineIMAP, ConsoleKit, GNOME Keyring

Over the weekend I finally got fed up with Evolution struggling to connect to work's "IMAP" server (Exchange 2007), and switched to using OfflineIMAP to sync the mail to a local Maildir. This as expected worked pretty well, and I'm now hidden from the nasty lag on the server. However, I've had to write my top secret Intel password into .offlineimaprc, which sucks. Then I had a cunning plan... GNOME Keyring will store passwords in a pretty secure manner, so somehow I need to fetch the password from there. A quick look at the OfflineIMAP manual revealed that I can write Python functions which return the password, so I should be abe to hook into the keyring from OfflineIMAP. This should be fairly simple:
import gobject, gnomekeyring
# The keyring needs to know the application name
if gobject.get_application_name() is None:
  gobject.set_application_name("offlineimap")
def keyring(user, host):
  keys = gnomekeyring.find_network_password_sync(user=user, server=host, protocol="imap")
  # First one will do nicely thanks
  return keys[0]["password"]
...
remotepasseval = keyring("rburton", "imapmail.intel.com")
After writing a small tool to add the key to the keyring, to my surprise this worked first time. I bounced with glee, but ten minutes later I had error messages from OfflineIMAP running from cron in my inbox... GNOME Keyring uses an environment variable to find the daemon, which isn't set in a cron environment. GNOME Keyring will fall back to using DBus to find the daemon, but the DBus session bus environment variable isn't set. DBus will fall back to reading the session bus address from the X root window, but DISPLAY isn't set so that doesn't work either... EPIC FAIL. But, I thought, I upgraded to Network Manager 0.7 last week which bought in ConsoleKit. If I ask ConsoleKit for my sessions I should be able to find a session with has an X connection, then I can set DISPLAY appropriately and then the chain described above will work, and I'll have my password. Shockingly, this worked first time too:
import dbus, os
if not os.getenv("DISPLAY"):
  # Get the ConsoleKit manager
  bus = dbus.SystemBus()
  manager_obj = bus.get_object('org.freedesktop.ConsoleKit', '/org/freedesktop/ConsoleKit/Manager')
  manager = dbus.Interface(manager_obj, 'org.freedesktop.ConsoleKit.Manager')
  
  # For each of my sessions..
  for ssid in manager.GetSessionsForUnixUser(os.getuid()):
    obj = bus.get_object('org.freedesktop.ConsoleKit', ssid)
    session = dbus.Interface(obj, 'org.freedesktop.ConsoleKit.Session')
    # Get the X11 display name
    dpy = session.GetX11Display()
    if dpy:
      # If we have a display, set the environment variable
      os.putenv("DISPLAY", dpy);
      break
(man, I really with python-dbus had a better syntax for getting objects with a specific interface) So there you go, integrating OfflineIMAP with the GNOME Keyring via ConsoleKit and DBus. Surprisingly this was pretty easy to do, thanks to DBus and the magic provided by ConsoleKit it is 100% hack free.

Next.

Previous.