Search Results: "ron"

16 November 2008

Bdale Garbee: Level 3!

I wrote last month about my failed first attempt to achieve a "level 3" high power rocketry certification. Last week, I learned that one of the commercial altimeters I flew for control of the ejection sequence has a firmware bug, which can cause premature ejection of the main parachute on flights above 10k feet! So it may in fact be the case that everything I did was perfect and I was simply the victim of a bug in software... how ironic! Yesterday, on my second certification attempt, I was successful! The rocket I flew this time was based on a Polecat Aerospace ten inch Goblin kit. I incorporated several modifications in my build, including additional fiberglass and carbon fiber reinforcement, and a payload bay in the nose cone. Once again, my wife Karen graced me with a parachute sewn from the Team Vatsaas design, this time a slightly larger one in burgundy and black rip-stop nylon. She incorporated several design tweaks based on her experiences sewing the first one which we'll try to write up at some point, that allowed her to sew this one in less time. The motor selected was again an Aerotech M1297W reload. The launch went perfectly, and the ascent was impressive. At apogee, the nose cone separated as planned and the drogue parachute deployed. Unfortunately, when the backup charge fired two seconds later, the main parachute also deployed. That wasn't intended... the main was supposed to deploy much lower, at 1300 feet. Luckily, the winds were light enough that the rocket touched down only about a mile downrange from the launch rail, well within the waiver distance, and was easily recovered without damage. There are three things I'll consider changing before flying this rocket again. First, the chute size calculator used to design the main parachute seems way off. The actual descent rate was around 32 feet per second, while our goal was 20. Other than that, the parachute performed admirably! Second, the premature deployment of the main at apogee could be cured by replacing the paper taped over that parachute bay with another piston capping the bay and held in with a pair of shear pins. Finally, the hard touch down snapped some of the nylon wire ties holding the batteries in place in the avionics bay. While no damage was done, and reducing the descent rate might prevent it happening again, improving the battery mounting would be an easy upgrade. For more information, see my project page for this rocket. James Russell took some pictures at the launch, including a great one of the rocket under boost just leaving the launch rail. And Jeff Lane captured video of the ascent and descent. It was a great flight and a great day, and represents a major milestone in our hobby rocket activities!

15 November 2008

Matthew Garrett: Adventures in PCI hotplug

I played with an Eee for a bit last time I was in Boston, culminating in a patch to make the eeepc-laptop driver use standard interfaces rather than just having random files in /sys that people need to write custom scripts to use. The world became a better place.

However. Asus implemented the rfkill control on the Eee in a slightly odd way. Disabling the wifi actually causes the entire card to drop off the bus, similar to how Bluetooth is normally handled. The difference is that the Bluetooth dongles are almost exclusively USB, while the Eee's wifi is PCI. Linux supports hotplugging of PCI devices, but nothing seemed to work out of the box on the Eee. Another case of this was the SD reader in the Acer Aspire One. Unless a card was present in the slot during boot, it simply wouldn't appear on the PCI bus. It turned out that Acer have implemented things in such a way that removing the card results in the entire chip being unplugged. This was when I started looking more closely into how this functionality is implemented.

The two common cases of PCI hotplug are native PCIe hotplug and ACPI mediated hotplug. In the former case, the chipset generates an interrupt when a hotplug event occurs and the OS then rescans the bus. This is a mildly complicated operation, requiring enabling the slot, checking whether there's a card there, powering the card and all its functions up, waiting for the PCIe link to settle and then announcing the new PCI device to the rest of the OS. ACPI-mediated hotplugging puts more of the load on the firmware rather than the OS - the hotplug event generates a notify message that is caught by the ACPI interpreter in the OS, allowing the OS to check for device presence by calling another ACPI method. If the device is present it's then a simple matter of telling the PCI layer about it.

Native PCIe hotplug has the advantage that there's much less vendor code involved. ACPI is still involved to an extent - an _OSC method on the PCIe bridge is called to allow the OS to tell the firmware that it supports handling hotplug events. This allows the firmware to stop sending any ACPI notifications. ACPI hotplugging requires more support in the firmware, but can work for PCI as well as PCIe.

The general approach taken to getting the Eee's wifi hotplugging to work has been to load the pciehp driver with the pciehp_force=1 argument. This tells the driver to listen for hotplugging events even when there's no _OSC method to tell the firmware that the OS is handling things now. Since the hardware will generate the event anyway, things work. However, this is non-ideal. Some hardware exists where ACPI hotplugging will work, but due to quirks in the hardware design native PCIe hotplugging control will fail. This has been handled in their firmware by having the _OSC method fail, signalling to the pciehp driver that it shouldn't bind to the port. Using pciehp_force overrides that, leading to a situation where hardware could potentially be removed from a port that's powered up. Unfortunate.

My first approach was to add a new argument to pciehp called pciehp_passive. This would indicate to the pciehp driver that it should only listen for notifications from the hardware. User-triggered events would not be supported, avoiding the situation where anyone could remove the card by accident. This worked on my test machine (an Eee 901 somewhere in Ottawa, since I don't actually have one myself...) but was reported to work less well on a 700. Since the 700 didn't claim to have any support for power control, the code was forced to wait a second on every operation to see whether the link powered up or not. This resulted in long pauses during boot and suspend/resume operations.

The final issue that convinced me that this was the wrong approach was reading a document on Microsoft's site on how PCIe hotplugging is implemented in Windows. It turns out that XP doesn't support native PCIe hotplugging at all - that feature was added in Vista. Both the Eee and the Aspire One are available with XP, but things work there. So PCIe native hotplugging was clearly not the right answer. Time to look further.

Armed with a disassembly of the Aspire One's DSDT, I figured out why the ACPI hotplug driver didn't work on it. The first thing the driver does is walk the list of ACPI devices, looking for any that are removable. That was being implemented by looking for an _EJ0 method. _EJ0 indicates that the device can be ejected under the control of the OS. The Aspire One doesn't have an _EJ0 method on its SD readers. However, it did have an _RMV method. This can be used to indicate that a device is removable but not ejectable - that is, the device can be removed (by physically pulling it out or by the hardware taking it away itself), but there's no standard way to ask the OS to logically disconnect it. A quick patch to acpiphp later and the Aspire One now worked without any forcing or spec contravention. This also has the nice side effect of making expresscard hotplug work on a bunch of machines where it otherwise wouldn't.

But back to the Eee. acpiphp still wasn't binding, and a closer examination revealed why. There's nothing to indicate that the Eee's ports are hotpluggable, and there's no topological data in the ACPI tables that ties the wifi function to the PCIe root bridges. However, the Eee firmware was sending an ACPI notification on wifi hotplug. But it was only sending this to the PCIe root bridges, and there's no way to then tell which device had potentially appeared or vanished.

In the end, I gave up on trying to solve this generically. Instead I've got a patch that implements the hotplugging entirely in eeepc-laptop. In an ideal world nobody else will have implemented this in the same way as Asus and we can all be happy.

Stefano Zacchiroli: from Vim to Emacs - part 2

One month with Emacs and counting - Part 2
Other posts in the from Vim to Emacs series: part 1
A while ago I've blogged about my switch from Vim to Emacs, promising a blog post series, quite a mouthful :-) nevertheless, it's time to continue the series. The first part was about why I think that nowadays Emacs is ready to be switching to. This second part is about flawed Vim design choices which substantially contributed to my choice. (Of course all this post is under a IMO-/rant-disclaimer, it can't be otherwise, so take it cum grano salis) Flawed Vim design choices Vim started as a wonderful editor, following the path of Vi, which in turn has got right a good deal of design choices. One is the often debated modality. In spite of being a HCI PITA in general, modality is not a problem at all for software you are using every single day (and the editor is the 2nd program I use the most, with the terminal being the 1st), because you learn it as a habit. In the case of Vim, modality is good because it let you use powerful yet simple motions in command mode, which can be easily combined with operator-pending commands. This can be considered yet another incarnation of the UNIX philosophy, casted inside the editor itself. ... which brings us to the good old joke which describes Emacs as a great operating system, lacking only a decent editor. In fact, Vim is no longer the nice Unix philosophy player which it used to be, and Emacs plays much more nicely with external tools than Vim. As arguments, let's consider a few (not so) recent Vim evolutions: Well, I acknowledge that Emacs got this choice right, and that it's an important one: Emacs supports interaction with external processes, and plugin authors have been happy to exploit it to create really cool stuff (sticking to the UNIX philosophy). Please welcome: Flyspell, M-x grep (shameless smartass plug: same number of keystroke of :grep), Grand Unified Debugger, a sampling of language-specific major modes with top-level support. (But I recommend having a look at least once at the coolness of other stuff built-on top of external process support, like Flymake, mentioned by dancer not a long ago.) Even in this respect, I acknowledge that Emacs got this right. It has chosen a single, now full-fledged, programming language (Elisp), which is offered both to the final user (fact: the average Emacs user knows much better how to program her own editor than the average Vim user) and to extensions developer. The standard library of the language is organized with a consistent naming (even though not always intuitive) and documented in an organized manner. You might not like the language, but at least is has been taken seriously and managed as such. Finally, being a Lisp dialect, you might need what you learn with Elisp elsewhere. Vim script is too committing: it is useful only inside Vim. I believe that contributed significantly in its scarce diffusion among Vim users. The fact that Elisp was born together with Emacs and that it is also used internally for the editor implementation is not relevant here: I do care about what is offered to me as an user and as an extension developer. What I see on the Emacs side in this respect is much better that what I see on the Vim side. Moreover, from the point of view of the users, is the difference between what is inside the editor and what is outside (i.e., the extensions) that relevant? I think it is not, and that brings me to the final Vim choice which I consider flawed and which has the potential of seriously limit its future evolutions: Where to from here in this blog post series? For sure some tips on how to migrate for hard-core Vim users, then we'll see ... If you did enjoy the read please let me know commenting in the discussion page (as you did in the last post, thanks!).

14 November 2008

John Goerzen: Education

One of the speakers at OSCon this year — I forget which one — made a point that ran something like this, heavily paraphrased:
Education used to be an end in itself, not a means. It wasn’t about having a high-paying career. It was about knowing the world, about having knowledge and wisdom for its own sake. It was, quite bluntly, the accumulation of useless knowledge by the elite — those that could afford to spend time on such things, knowing that useless knowledge has a way of becoming useful in the most unexpected of ways. How fortunate we are to live in an age where the accumulation of useless knowledge is available to so many, and how sad it is that so few take advantage of it.
What a powerful statement, and it rings true to me. I remember in high school, when people from the local liberal arts college would come and talk. They’d talk about the value throughout a lifetime of knowledge in a broad range of disciplines: English, history, political science, religion, science, and the arts. They’d talk about how their graduates went on to lead distinguished lives, how this broad core of knowledge serves a person well through life. I guess I didn’t believe them, because due to their lack of a computer science major, I went elsewhere. That local school may not have been the best choice for me for other reasons, but as I look back on it, I think they had a much stronger message than I realized back then. Here I am, just two math classes, one computer science class, and one biology class away from a degree. Yet I have had not one class covering the history of east Asia, not one class on different world cultures or religions, and only a very basic understanding of one foreign language (German). This hits me in the face almost every day. Yesterday I was wondering about the history of slavery and racism in Europe. Today I’m curious about China’s history as an economic powerhouse. Last week I was curious about Roman law and daily life. The fact is, everything from philosophy to calculus is screamingly relevant to daily, modern life. We hear talk of “an American revolution” in Washington, of a shift of power in the Senate. It seems we forget that the notion of a Senate is considerably older than the United States is — and that we have such a thing because our founders were aware of this. Macroeconomic theory is thrust in our faces on an almost daily basis these days, yet I’ve never had a class on economics at all. We might feel fear of terrorist attacks, or see our fellow citizens lash out at “the Arabs.” Our own short memories fail to remind us of the light in which we are seen, fail to put the really quite minor terrorist threat in context of what London or Dresden endured in World War II. We demand our government to make us safer, and our government responds by making us less safe but making us *feel* safer at airports. In my own field, I see some universities buckling to pressure from Business to turn out large numbers of mediocre programmers that know the Java or .NET standard library well, but have no sense of the theory behind computer science, and would be utterly lost if asked to, say, write a recursive QuickSort. I find myself almost completely baffled that some companies that want to hire the world’s best programmers are only looking for people that are already fluent in $LANGUAGE — not ones that are good programmers, and so well-versed in computer science that they can easily pick up any language. I think there is a lot to the argument that a good, broad, classical education can serve a person well in any career. I wish I had realized that a little earlier.

Eddy Petrișor: If you own/have access to a Nokia E71 made for Romania, please contact me

I am trying to contact an owner of a Nokia E71 who is able to input Romanian diacritics on this type of phone. This person shouldn't worry, there is nothing destructive/dangerous involving his/her phone, should he/she contact me.

(Skip up to the "second approach" paragraph, if you don't care for the technical details or my story.)


Some time ago, during my latest blog silence period, I bought a white Nokia E71 phone from a Cosmote dealer.

I am really satisfied with it, except for two or three small issues[0], but the most annoying is that my phone was not made for the Romanian market, so I can't type Romanian diacritics[1].


Why does this matter? Because since I bought this phone I managed to do some translation work on the E71, on the daily commute to work. Still, the lack of diacritics forces me to go through another hop to add diacritics to my .po files when I get home.


So I was thinking on ways to fix this issue. After some google-ing I came up with the following possible fixes:
Since my phone was made for Singapore and I want to change to a Romanian product code, I have to wait for an update to be visible for Romania. Although the firmware update arrived for Singapore products, for phones made for Romania the firmware update is unavailable, so I am stuck on the first front.


Enter the second approach and my request for help.

I have looked into the files of my phone and I think I have found the files which define the keyboard layouts available on my phone. I haven't made out the details of the files, but, as a first step, I thought that I should try to replace one of those layout files I don't need with a Romanian layout file.

The problem is that I don't have a copy of such a file, but on a phone that works this file should be present and should be easily accessible. For short, I would need a copy of the firmware that is running on the phone, so I can try to replace on my phone the relevant files.


If you own a Nokia E71 and you're able to input Romanian diacritics on it, please contact me via a comment on my blog, or an email at eddy.petrisor+e71@gmail.com. Thanks in advance!


[0] the phone is really close to perfection on my scoreboard
[1] the correct "s comma" and "t comma" are not visible in any font present in the phone, but as long as they are correctly encoded I am fine with that. Surely with a proper font and an external editor I can fix that problem.

Gintautas Miliauskas: Non-native LCD resolutions

Now that LCD monitors have spread, I keep noticing one thing: lots of public places with computers have the resolution set to some non-native value. Blur in cafes, libraries, everywhere! It seems that people just do not notice the blurriness, and I do not really blame them how could they know that there's a better resolution? This makes me think that it would be a good idea to warn the user on the desktop environment configuration level about reduced quality whenever the screen is an LCD and they are trying to switch to a non-native resolution. A non-intrusive, but informative message could do the trick, I think.

MJ Ray: Spammers Silenced by Service Suppliers

Maybe, like me, you’ve noticed that you’ve had less junk email this week and you’ve been wondering why. News sites are reporting that a large spammer-friendly hosting service in California has been disconnected by its service providers after they were sent evidence about its activities. (Check out the “Next” links on the report to see how the story develops.) For the technically-minded, Changes in Spam Levels this week Posted by simonw illustrates the level of disruption and may grow an interesting discussion from server managers - it seems the reduction is less than the 75% reported in some news services, but still significant. This is great news for all good internet users. It’s disappointing if the spam hosting service won’t have to pay any of the costs they’ve inflicted on other computer users in some way. The only practical negative that I’ve noticed so far is that much of the stopped spam was pretty easy to identify and filter out, so the reduction in spam reaching my “unsure” mailbox hasn’t been anything like 50%. Still, less spam hitting the filters means less computer power used, which means less electricity and network data transfer used, which means lower costs for us. Yippee! And finally, I smiled at this comment over on the WebmasterWorld discussion:-
“Our spam email has dropped so much in the past 2 days that I was beginning to wonder if there was something wrong with our email accounts.”

13 November 2008

David Welton: Ubuntu Intrepid Regression: Beware of Wireless and WPA

A lot of people, myself included as of the upgrade I did last night, seem to be having trouble using certain wireless chipsets with WPA: https://bugs.edge.launchpad.net/ubuntu/intrepid/+source/wpasupplicant/+bug/272185 There are a lot of people following this one, and you have to think that for every person who looked it up, googled it, and dug around to find that page, registered with the site, and so on, there are several more who simply gave up and went back to Windows or something. I thought a couple of weeks was probably a good amount of time for the bugs to be shaken out of Intrepid, but I thought wrong. Here is a set of search terms that can be used to look through "regression-potential" bugs, which if I'm not mistaken, ought to mean those things that worked in previous versions of Ubuntu but now no longer work. In my case, there's an extra little bit of annoyance because I am running on a Dell laptop that I bought with Ubuntu preinstalled, and you'd think the Ubuntu guys would have a few sitting around to do some testing with prior to release. I spent some time digging around in the code for the network manager, wpasupplicant, and a brief look at the kernel code, but there was nothing that made much sense, so I guess I'll just have to wait for the fix like everyone else... wish I could help, somehow, though.

Lucas Nussbaum: Living in France? Not an April member? You are WRONG.

I’ve been a member of April, the french association for promotion and defense of Free Software, for a bit more than a year, and I often regret not becoming a member earlier. (I was feeling so guilty and shameful about not being a member that I actually postponed becoming a member.) Stop feeling guilty and shameful, become an April member today! Why Is becoming an April member so important? Some of the things they worked on recently (from the top of my head): So, really, become a member today. It’s only 10 EUR, and you already know they will be well used. April is trying to reach 5000 members by the end of 2008. (Apparently, if you use that address, April will now that you came from me. No benefit for me at all.)

Tore S. Bekkedal: Following memes for fun and prophets.

Cute meme du jour: Well, OK. Page 56, fifth sentence:
“The functions of other software interrupt service routines are quite variable; The I/O postprocessing interrupt service routine has a specific function to perform but is data-driven by the I/O request packets (IRPs) in its work queue.”
I know at least one of the slightly more than one people (I count too, right?) who read my blog (Hi, Ian!) might well realize what book this came from: VAX/VMS Internals and Data Structures, by Ruth Goldenberg and Lawrence Kenah. Yes, the book really was the closest to me - I have an overdesk shelf, and it was the furthest out. The book, by the way, is a fascinating read; I don’t know of any other book that lays out the design of an entire OS kernel in the really quite elegant way that this book does. I got mine signed by Ruth, too, which is pretty damn cool. :) One highlight of this book are the quotes at the beginning of each chapter - sometimes funny, sometimes profound, frequently both. I decided to list those from the first part here, for the enjoyment of both my readers.
Part I
Chapter 1, System Overview:
For the fashion of Minas Tirith was such that it was built on seven levels, each delved into a hill, and about each was set a wall, and in each wall was a gate.
- J. R. R. Tolkien, The Return of the King
Chapter 2, VAX Interrupts and Exceptions
“By indirections find directions out.”
- Shakespeare, Hamlet, 2, i
3, Hardware Interrupts
While I nodded, nearly napping, suddenly there came a tapping,
As of someone gently rapping, rapping at my chamber door.
Edgar Allan Poe, The Raven
4. Software Interrupts
And now I see with eye serene
The very pulse of the machine.
William Wordsworth, She Was A Phantom Of Delight
5. Condition Handling
“Would you tell me, please, which way I ought to go from here?”
“That depends a good deal on where you want to get to,” said the Cat.
Lewis Carroll, Alice’s Adventures in Wonderland
6. System Service Dispatching
Between the idea
And the reality
Between the motion
And the act
Falls the Shadow
T. S. Eliot, The Hollow Men
7. ASTs (Asynchronous Software Traps, ed.)
What you want, what you’re hanging around in the world
waiting for, is for something to occur to you.
Robert Frost
8. Synchronization Techniques
“Time,” said George, “why I can give you a definition of time. It’s what keeps everything from happening at once.”
Ray Cummings, The Man Who Mastered Time
9. Event Flags
I claim not to have controlled events, but confess plainly that events have controlled me.
Abraham Lincoln, Letter to A. G. Hodges, April 4, 1864
10. Lock Management
‘Tis in my memory lock’d
And you yourself shall keep the key of it.
Shakespeare, Hamlet, 1, iii
11. Time Support
Love, all alike, no season knows, nor clime,
Nor hours, days, months, which are the rags of time.
John Donne, The Sun Rising
12. Scheduling
It is equally bad when one speeds on the guest unwilling to go, and when he holds back one who is hastening. Rather one should befriend the guest who is there, but speed him when he wishes.
Homer, The Oddysey
13. Process Control and Communication
I was alone and unable to comunicate with anyone. I did not know the names of anything. I did not even know things had names. Then one day, after she had tried a number of approaches, my teacher held my hand under the water pump on our farm. As the cool water ran over my hand and arm, she spelled the word water in my other hand. She spelled it over and over, and suddenly I knew there was a name for things and that I would never be completely alone again.
Helen Keller

12 November 2008

MJ Ray: Webmaster Jargon for Website Owners

I wrote to a site owner last week and I thought I was writing to a webmaster. The site owner complained about some of the jargon and, while explaining who I thought I was writing for, I explained some of it because I think more website owners might benefit from these three explanations:- “Expat-like terms” - made available in a way that is freely sharable, modifiable and redistributable, similar to the Expat software package, whose terms are published at http://www.jclark.com/xml/copying.txt - this is often used as a clear, simple example for encouraging wide distribution of electronic resources (software). “clandestine Google Analytics” - Google Analytics is a service from Google, Inc for tracking users through a website in various ways. I believe the Data Protection Act means that English websites should obtain informed consent from users by publishing a Privacy Policy on their site which discloses what the GA service will be used for and linking through to GA’s own Privacy Policy. Some websites attempt to run Google Analytics on users’ computers without explaining why and without any Privacy Policy. That is what I mean by “clandestine”. “valid xhtml” - validating against the eXtensible HyperText Markup Language standards published by the World Wide Web Consortium (W3C) - the underlying language of the web. There is a test service provided at http://validator.w3.org/ and passing it is a key stepping stone towards making an accessible website. There’s not really such a thing as “invalid xhtml” - if it doesn’t pass validation, it’s not xhtml. So I guess I’m guilty of using a tautology sometimes - sorry about that. Is it worthwhile knowing those three phrases? Are there other key technical phrases which you think site owners should know?

Jaldhar Vyas: Diwali: The Aftermath

Shailu with no front teeth I HAVE NO FRONT TEETH. YOUR ARGUMENT IS INVALID.

Joachim Breitner: My very first font

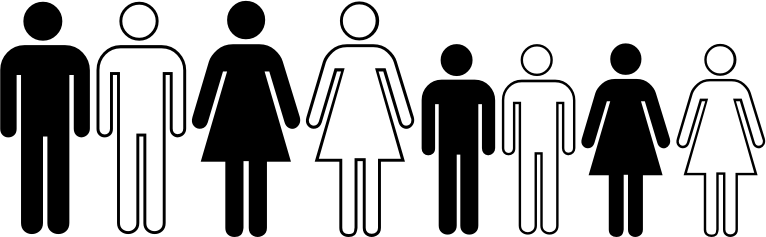
For a project of mine I needed the pictograms for man and woman (as also known from toilette doors), in two different sizes, once filled and once as an outline. I coud not find these as a LaTeX symbol nor as a defined unicode character, so I searched the internet. I found some material as vector graphics (EPS), which I was using first, imported into my LaTeX document as images. But it felt wrong to use images for something that s a symbol in the text.So I installed fontforge, the apparently usual tool for that, imported the EPS files and with surprisingly reasonable effort created a TrueType font with these nice eight glyphs:
Quite a while ago I wrote here how to use single glyphs from a TrueType font in LaTeX. Based on that I created the neccessary files to use these in LaTex with these commands, in the order of the picture: \Mansym, \mansym, \Womansym, \womansym, \Boysym, \boysym, \Girlsym, \girlsym. Here are the files: ManPictograms.ttf T1ManPictograms.fd ManPictograms.tfm ManPictograms.enc ManPictograms.sty. If anyone feels like turning them into a more proper LaTeX font package, they are welcome.

Obey Arthur Liu: Aptitude 0.5.0 (aka Aptitude-gtk) released

Long time no post. Anyway, I have some good news. The Gtk code for Aptitude has been merged some time ago into the main development trunk and we now have a release in Experimental. aptitude-gtk-050-dashboard For those that don’t know about it, here’s what it’s all about : “The new frontend is is an effort to bring some of the design principles of the curses frontend to a GUI environment, while also exploiting the unique features a GUI gives us and exploring ways to deal with changes in the environment in the nine years since aptitude was first designed.” I had a very good time this summer working on Aptitude with Daniel Burrows in the Google Summer of Code program and I’m very glad we now have a real release. This version is by no means final or perfect but it’s a good start. Head for the blog post from Daniel for some other informations : [Daniel Burrows]

11 November 2008

Daniel Burrows: aptitude 0.5.0 released

I've released version 0.5.0 of the aptitude package manager (release notes). Once the mirrors have synced, you should be able to download it from Debian's experimental distribution, or manually from the aptitude package page.
[Edit] This release was uploaded to experimental because it is not a final release. aptitude follows the Linux version numbering scheme in which an odd second digit indicates an unstable development version. DO NOT INSTALL THIS VERSION IF YOU WANT STABLE SOFTWARE; IT IS INCOMPLETE, INADEQUATE, AND PROBABLY INCORRECT. To reply to some questions that several people have asked me:
  1. The final release of aptitude 0.6.0 will be split into two packages, one containing only the traditional text interface and named aptitude-curses, and one containing the GUI binary named aptitude-gtk, with both of them providing the aptitude binary through Debian's alternatives mechanism. This release wasn't split because the code to drop GTK+ support was buggy and I discovered this fact halfway through assembling the release. It's fixed now.
  2. To run the traditional curses interface, pass the --no-gui command-line parameter or set the option Aptitude::Start-Gui to false in /etc/apt/apt.conf. Unless you want to test that the curses frontend isn't broken, though, there won't be much for you in this release: the only change affecting it is Xapian support, and that currently breaks incremental search. (see the note above about this being an unstable release)
Also, another feature that I suspect might be bothersome is the behavior of updating the package lists and downloading changelogs on startup. There's no switch for changelogs yet, but you can disable the package list update by setting Aptitude::Update-On-Startup to false.
The main change in this release is the new GTK+ frontend, designed and implemented by Obey Arthur Liu with funding from the 2008 edition of Google's Summer of Code. aptitude 0.5.0 screenshot The new frontend is is an effort to bring some of the design principles of the curses frontend to a GUI environment, while also exploiting the unique features a GUI gives us and exploring ways to deal with changes in the environment in the nine years since aptitude was first designed. For instance, it is no longer reasonable for the user to actually read the entire package list (when I first installed Debian, you could read through the whole package list in a single sitting). So instead of basing the interface around a list of all the packages, we based it around the ability to search for the packages you're interested in. This version of aptitude also introduces Xapian searching:
daniel@emurlahn:~$ aptitude search "apt package manager"
i   apt                                  - Advanced front-end for dpkg
p   apt-dater                            - terminal-based remote package update manager
p   apt-dater-dbg                        - terminal-based remote package update manager (d
i   aptitude                             - terminal-based package manager
i   aptitude-dbg                         - Debug symbols for the aptitude package manager
p   createrepo                           - generates the metadata necessary for a RPM pack
p   gnome-apt                            - graphical package manager
p   smartpm                              - An alternative package manager that works with
p   smartpm-core                         - An alternative package manager that works with
i   synaptic                             - Graphical package manager
i A update-manager-core                  - APT update manager core functionality
You might ask why I didn't search for just package manager. The reason is simple: aptitude doesn't yet sort by relevance, and that second search gave me screenfuls of packages whose description contains both package and manager, including addressmanager.app (a PIM for GNUstep), compiz-gtk (a piece of eye candy), and wterm (an X terminal emulator). However, it is worth noting that Xapian searches are fully integrated into the aptitude search language, so they can be combined with non-Xapian search terms in just the way you would expect:
daniel@emurlahn:~$ aptitude search "?installed apt package manager"
i   apt                                  - Advanced front-end for dpkg
i   aptitude                             - terminal-based package manager
i   aptitude-dbg                         - Debug symbols for the aptitude package manager
i   synaptic                             - Graphical package manager
i A update-manager-core                  - APT update manager core functionality
So, all the basic functionality that the GUI version needs is in place; the next step is to start polishing it and filling in the gaps that are left. And, of course, suggestions and bug reports are welcome, so we know where the rough spots and the gaps are. Please send your comments to aptitude-devel@lists.alioth.debian.org so that they are part of the public record and so that people besides me can read them. :-) Happy package managing!

Ross Burton: Asynchronous Flickr Library, version 0.3

Finally, Flickrpc 0.3 is released. Some nice features that we all know and love from Postr here: Grab a tarball here or the Bazaar tree here.

Joey Hess: spelling policy

Effective immediatly -- If you're annoyed by the spelling of something I've written, I will accept a patch -- preferably generated by git-format-patch, but diff -u is also acceptable. Any other communication about spelling mistakes will be ignored, unless the mistake has ramifications that will cause undue pain and suffering to people who are not English majors. Furthermore, if the spelling "mistake" is that I spelled "-ize" as "-ise", it's not a mistake -- I prefer to use the latter form for obscure reasons, with a few exceptions. PS, I realise that these are entirely arbitrary rules forced upon you willy-nilly. Teh irony..

10 November 2008

Kurt Roeckx: Finding which sector belongs to which file on a RAID device.

I got this nice message (and some others) in my log today:
smartd: Device: /dev/sdd, 2 Currently unreadable (pending) sectors After running a smartctl -t long /dev/sdd smartctl now reports:
ID# ATTRIBUTE_NAME          FLAG     VALUE WORST THRESH TYPE      UPDATED  WHEN_FAILED RAW_VALUE
  5 Reallocated_Sector_Ct   0x0033   200   200   140    Pre-fail  Always       -       0
  9 Power_On_Hours          0x0032   089   089   000    Old_age   Always       -       8719
196 Reallocated_Event_Count 0x0032   200   200   000    Old_age   Always       -       0
197 Current_Pending_Sector  0x0012   200   200   000    Old_age   Always       -       2
198 Offline_Uncorrectable   0x0010   200   200   000    Old_age   Offline      -       0
[...]
SMART Error Log Version: 1
ATA Error Count: 10 (device log contains only the most recent five errors)
[...]
Error 10 occurred at disk power-on lifetime: 8692 hours (362 days + 4 hours)
  When the command that caused the error occurred, the device was active or idle.
  After command completion occurred, registers were:
  ER ST SC SN CL CH DH
  -- -- -- -- -- -- --
  40 51 08 78 e5 89 e0  Error: UNC 8 sectors at LBA = 0x0089e578 = 9037176
  Commands leading to the command that caused the error were:
  CR FR SC SN CL CH DH DC   Powered_Up_Time  Command/Feature_Name
  -- -- -- -- -- -- -- --  ----------------  --------------------
  25 00 08 78 e5 89 2f 00  45d+06:36:27.880  READ DMA EXT
  25 00 08 70 e5 89 2f 00  45d+06:36:27.798  READ DMA EXT
  25 00 08 68 e5 89 2f 00  45d+06:36:27.308  READ DMA EXT
  25 00 08 e0 77 e5 35 00  45d+06:36:27.295  READ DMA EXT
  25 00 08 60 e5 89 2f 00  45d+06:36:26.653  READ DMA EXT
[...]
Error 9 occurred at disk power-on lifetime: 8692 hours (362 days + 4 hours)
  When the command that caused the error occurred, the device was active or idle.
  After command completion occurred, registers were:
  ER ST SC SN CL CH DH
  -- -- -- -- -- -- --
  40 51 08 60 e5 89 e0  Error: UNC 8 sectors at LBA = 0x0089e560 = 9037152
SMART Self-test log structure revision number 1
Num  Test_Description    Status                  Remaining  LifeTime(hours)  LBA_of_first_error
# 1  Extended offline    Completed: read failure       90%      8715         797566305
# 2  Extended offline    Completed without error       00%      8198         -
Notice that 197 Current_Pending_Sector indicates that there are 2 sectors with a problem. Note that the SMART error log shows LBA sectors 9037176 (0x89e578) and 9037152 (0x89e560) but it's limited to 0xffffff. The self test logs shows us the proper LBA error at 797566305 (0x2f89e561) which has a 0x2f in front, and also shows us that it's the second sector in the block of 8 we tried to read. The kernel log also shows:
ata4.00: exception Emask 0x0 SAct 0x0 SErr 0x0 action 0x0
ata4.00: (BMDMA2 stat 0xc0009)
ata4.00: cmd 25/00:08:60:e5:89/00:00:2f:00:00/e0 tag 0 cdb 0x0 data 4096 in
         res 51/40:00:61:e5:89/00:00:2f:00:00/f0 Emask 0x9 (media error)
So I've tried to reproduce the error with:
# dd if=/dev/sdd of=797566305 skip=797566305 bs=512 count=1 iflag=direct
1+0 records in
1+0 records out
512 bytes (512 B) copied, 1.27727 s, 0.4 kB/s
Notice that it can actually read that block, it just seems to take a while. And the error log now contains:
  After command completion occurred, registers were:
  ER ST SC SN CL CH DH
  -- -- -- -- -- -- --
  40 51 01 61 e5 89 e0  Error: UNC 1 sectors at LBA = 0x0089e561 = 9037153
Because it's part of a RAID device I could just let the whole disk resync, but I was a little curious which files were in it. So I found this document that explains on how to find which files has the problem. But it only has examples covering ext2/ext3 on a partition and LVM and nothing about RAID device. So it looks like someone using RAID 0 will have a hard time finding the file that's having a problem. So following the document we start with:
# fdisk -lu /dev/sdd
Disk /dev/sdd: 500.1 GB, 500107862016 bytes
255 heads, 63 sectors/track, 60801 cylinders, total 976773168 sectors
Units = sectors of 1 * 512 = 512 bytes
Disk identifier: 0x000578f9
   Device Boot      Start         End      Blocks   Id  System
/dev/sdd1   *          63      385559      192748+  fd  Linux raid autodetect
/dev/sdd2       972864270   976768064     1951897+  fd  Linux raid autodetect
/dev/sdd3          385560   972864269   486239355   fd  Linux raid autodetect
Partition table entries are not in disk order
In /proc/mdstat we see:
md1 : active raid5 sda3[0] sdd3[3] sdc3[2] sdb3[1]
      1458717696 blocks level 5, 64k chunk, algorithm 2 [4/4] [UUUU]
So sdd3 is part of md1 and I have an ext3 filesytsem on that. Tune2fs -l grep Block gives:
Block count:              364679424
Block size:               4096
Blocks per group:         32768
mdadm tells me:
# mdadm -QE /dev/sdd3
/dev/sdd3:
          Magic : a92b4efc
        Version : 00.90.00
           UUID : 747b071a:a70f723b:c3a9ed44:15845cbf
  Creation Time : Mon Nov 12 20:13:51 2007
     Raid Level : raid5
  Used Dev Size : 486239232 (463.71 GiB 497.91 GB)
     Array Size : 1458717696 (1391.14 GiB 1493.73 GB)
   Raid Devices : 4
  Total Devices : 4
Preferred Minor : 1
    Update Time : Mon Nov 10 10:57:28 2008
          State : clean
 Active Devices : 4
Working Devices : 4
 Failed Devices : 0
  Spare Devices : 0
       Checksum : 4b3147f4 - correct
         Events : 78
         Layout : left-symmetric
     Chunk Size : 64K
      Number   Major   Minor   RaidDevice State
this     3       8       51        3      active sync   /dev/sdd3
   0     0       8        3        0      active sync   /dev/sda3
   1     1       8       19        1      active sync   /dev/sdb3
   2     2       8       35        2      active sync   /dev/sdc3
   3     3       8       51        3      active sync   /dev/sdd3
I've been told that 0.90 stores the superblock at the end of the device, so that makes it a little easier. And this seems to agree:
# cat /sys/block/md1/md/dev-sdd3/offset
0
We have a left-symmetric layout, so in raid5_compute_sector() we see
	stripe = chunk_number / data_disks;
	*dd_idx = chunk_number % data_disks;
[...]
	case ALGORITHM_LEFT_SYMMETRIC:
		*pd_idx = data_disks - stripe % raid_disks;
		*dd_idx = (*pd_idx + 1 + *dd_idx) % raid_disks;
So it looks like the chunks are located on the disk like:
stripesdasdbsdcsdd
0D 0D 1D 2P 0-2
1D 4D 5P 3-5D 3
2D 8P 6-8D 6D 7
3P 9-11D 9D 10D 11
4D 12D 13D 14P 12-14
With each of those 64K. The problem is at 797566305 and the partition started at 385560. So that's at sector 797180745 inside partition sdd3. Each sector is 512 bytes and a chunk is 65536 bytes which gets us 128 sectors per chunk. If we want to know which the stride the sector is on we do: 797180745/128=6227974.5703125 This means that the stripe is number 6227974 and that it's sector 0.5703125*128=73 on sdd3 within that chunk. The parity is on disk: pd_idx = 3 - 6227974 % 4 = 1, being sdb. To get the chunk we need to multiply with the number of data disks (3) and since it's the forth disk and the parity is on the second disk we need to add 1 and get: 6227974*3+1=18683923 So calculating that back to sectors we multiply it with the number of sectors per chunk again and add our offset in the chunk: 18683923*128+73=2391542217 To test that our math is any good we try:
# dd if=/dev/md1 of=797566305.2 skip=2391542217 bs=512 count=1 iflag=direct
1+0 records in
1+0 records out
512 bytes (512 B) copied, 5.99103 s, 0.1 kB/s
We see an error message in the kernel log, there are 2 new errors in the error log, so it seems that everything is calculated correctly. The files are also identical. The file system is in blocks of 4096 bytes, so for the file system this is block 2391542217*512/4096=298942777.125 Then we use debugfs:
# debugfs
debugfs 1.41.2 (02-Oct-2008)
debugfs:  open /dev/md1
debugfs:  icheck 298942777
Block   Inode number
298942777       <block not found>
Which isn't making any sense to me, since I get that error about every 2 hour when a certain cronjob runs. 298942777 / 32768 (Blocks per group) = 9123.00955. So I wonder if ext3 is keeping some meta data there and debugfs doesn't tell that? Anyway, at some point I was running a smartctl -t long /dev/sdd again because I couldn't reproduce the error anymore, the cronjob started, and I then found alot of errors in my log again and now it included:
raid5:md1: read error corrected (8 sectors at 797180744 on sdd3)
It's so much fun that disks always behaves the same trying to read the same sector. Smartctl now reports:
  5 Reallocated_Sector_Ct   0x0033   200   200   140    Pre-fail  Always       -       0
196 Reallocated_Event_Count 0x0032   200   200   000    Old_age   Always       -       0
197 Current_Pending_Sector  0x0012   200   200   000    Old_age   Always       -       0
198 Offline_Uncorrectable   0x0010   200   200   000    Old_age   Offline      -       0
I assume the kernel removed the pending sector by writing to it. The other pending error was already gone for some time, I assume new data got written to that one.

David Welton: Generating Rails Fixtures From Large Datasets

I've been working with Tomaso Minelli doing some Rails work, and one thing we needed to do was set up some tests. The situation we are in is that we already have a large set of data to work with in our development environment, but getting that data into .yml files is no easy task. Since we have a fairly large number of interdependent tables, dumping one of them alone is pretty useless, unless you manage to get the other tables it links to, and so on and so forth. Dumping all the data would make testing quite slow, and really is too much to be useful. Here's the rough solution we arrived at:

@fixtures =  
@seen =  
# Do something with a fixture.  In this case, we store it for later.
def handle_fixture(record)
  @fixtures[record.class.table_name]  = []
  @fixtures[record.class.table_name] << record
end
# Get some sort of unique way of identifiying a record - class name and id.
def unique_record(record)
  return record.class.to_s + " " + record.id.to_s
end
# Grab all the relations of a class and add them to the queue.
def add_fixture(record)
  ur = unique_record(record)
  if @seen[ur]
    puts "LOOP!"
    return
  end
  @seen[ur] = true
  puts "Fixture for # record.class.name  - ID # record.id "
  handle_fixture(record)
  record.class.reflections.each do  k, r 
    begin
      if r.macro == :has_many  
          r.macro == :has_and_belongs_to_many
        related = record.send(r.name).send('find', :all, :limit => STARTING_LIMIT)
      else
        related = record.send(r.name)
      end
      related = [related] unless related.is_a?(Array)
      related.each do  related_record 
        if related_record
          puts "    New Record # related_record.class.name  # related_record.id "
          @todo << related_record
        end
      end
    rescue => e
      puts "    ERROR: # e :\n# e.backtrace.inspect "
    end
  end
end
@todo = []
namespace :db do
  namespace :fixtures do
    desc 'Create YAML test fixtures starting from a single model using reflections'
    task :modelbase => :environment do
      STARTING_CLASS = Foobar
      STARTING_FIND  = :all
      STARTING_LIMIT = 1
      tmp = 0
      totale = STARTING_CLASS.find(STARTING_FIND, :limit => STARTING_LIMIT).size
      STARTING_CLASS.find(STARTING_FIND, :limit => STARTING_LIMIT).each do  m 
        tmp += 1
        puts "# tmp  su # totale : # m.id "
        @todo << m
      end
      while true
        if @todo.length == 0
          break
        end
        add_fixture(@todo.pop)
      end
      puts "\n\n# '='*80 \nScan Finished\n# '='*80 \n\n"
      @fixtures.each do  name, fixture 
        if fixture.size > 0
          i = "000"
          filename = "# RAILS_ROOT /test/fixtures/# name .yml"
          puts "Create # filename  for class # fixture.class.name "
          FileUtils.mkdir(File.dirname(filename)) unless Dir[File.dirname(filename)].size > 0
          File.open("# RAILS_ROOT /test/fixtures/# name .yml", 'w') do  file 
            file.write fixture.inject( )    hash, record 
              hash["# record.class.table_name _# i.succ! "] = record.attributes
              hash
             .to_yaml
          end
        else
          puts "Fixture for # name  is EMPTY"
        end
      end
    end
  end
end
It's written in a somewhat quick and dirty way, but it gets the job done. What it does: It takes a single class - hopefully a well connected one - fetches a few of them, and goes from there, exploring all the other objects that the initial ones are connected to, and then dumping them in .yml files in the fixtures/ directory. It could certainly use more work:
  • Additional starter classes, for ones that aren't connected to others.
  • Intelligent examination of data and data sets...
  • For example you could check to see what classes aren't connected to the others and use them as starter classes.
  • If you wanted to waste a lot of cycles, you could also try and aim for a representative set of examples. For an object that has_many something elses, you could try and find one with zero, one with one, and one with a lot, to cover various cases. That could quickly get out of hand for largish data sets though.
  • I'm sure there are various other tweaks, knobs, and levers that could be added to work more efficiently. I'd love to see them!

Julien Blache: pommed v1.22: various improvements, Late 2008 laptops

I’ve just released pommed v1.22, which has been collecting improvements and reworks over the past few weeks; this release also adds partial support for the Late 2008 laptops. Partial support means the LCD backlight is not supported yet. The method for controlling the backlight has to be figured out; if you hear of anything, let me know. You’ll need a recent kernel for full support on these machines, which means either a late 2.6.28-rc or possibly an early 2.6.29-rc. It all depends on how fast the patches get applied to mainline. Patches are needed for the keyboard quirks, trackpad support, applesmc support and sound support, as usual. On the improvements front, wmpomme has become event-driven, eliminating the fixed-rate update and associated wakeups and visual ugliness in some configurations; pommed has got some code fixes, though nothing major; gpomme has got a new Japanese translation. Hopefully the next release will bring full Late 2008 support.

Next.

Previous.