Search Results: "spa"

20 April 2008

David Moreno Garza: GMail and Sup, the smart way

I m a person who isn t satisfied with a lot of things. This both affects me and helps me on several circumstances in life, such it is. The latter also affects my way to deal with mail, mail serving and MUAs. For years, I was a strong Novell Evolution user, mainly because it was quite easy to use, it was pretty and it used to understand the needs that people like me, involved in a lot of things (some of the worthwhile, some of them shitty), required. But in the last couple of years, it began to bloat, to handle connections Bayesian filters and SpamAssassin in a way that was utterly broken and decomposed. I took a break years ago, and tried Mutt, as many free software folks and Debian developers use them on a daily basis to deal with even more incoming mail. I actually liked it, but I was just unable to deal with spam too. My local config was probably broken, fixing it was an obscure fart of Benedict XVI and hidden folders for mailing lists were just a way to forget that I actually was subscribed to mailing lists and focused only on the incoming mail on the inbox. I then tried KMail, since I started usign KDE. It was good enough for it was sometimes slow when trying to load or search on about 100 000 mails and it just didn t fulfill me. I also tried Thunderbird which only made me hate its very closed format to display its ugly UI. Besides, a lot of things on it were getting my angry, like the message filters, etc. So I just didn t give a damn and moved my whole personal mail accounts to Google Apps, giving an opportunity to a totally different approach on mail handling. So I started using the Web interface of GMail. At first I was shocked watching me dealing with a Webmail but after a while I started getting used to it and liking it. Its way to put all conversations threaded on a central inbox was sweet (i was able to filter, tag and take out of inbox too). So I liked it. Some things have never liked me whatsoever: It will always use your default mail address to reply to all messages, even if they are delivered to another recipient, which I consider retarded; its way to let users to top-post, etc, (you should also see how debian-private is seen on GMail and how the google sponsored links propose products based on all its threads xD). The good thing here also was that while not being a total purist, I loved that most spam has automatically handled for me, oh thank Lord I m a lazy bastard. Then I found Sup, which I think is like GMail but on mutt. It is written in Ruby and distributed as a gem (I d prefer it to be in C/C++, but I ll always give the benefit of doubt). Its main feature? A console mail client featuring GMail s features, such as, one inbox, one big archive and labels all over the place, which is exactly what I was (probably) looking for. As the time of writing,Sup can only connect to IMAPs remote servers or read a number of local file formats. So, I undusted fetchmail and set it up. Since all my mail accounts now are forwarded to the main GMail account, I only need to handle one fetchmail config to get messages with POP (and some procmail recipes salting touch). Here comes the sweetest thing from all this setup, by enabling GMail s POP support, you can also specify if you want it to delete the GMail copy or store it. Since I ve used 2% of all my storage, the best thing to do right now is to store and archive, which means that while i download all my email everyday and several times a day, all downloaded copies are also being stored on GMail, so in case I don t have access to my machine, I can still find messages on the web interface. GMail also works nicely when you are sending an email from your remote mail client and using GMail s SMTP, then also the mail you are sending gets stored on your GMail web interface, which is totally cool. So I think I m mildly content now with what I have. This also leads me to another awesome feature for me: Spam gets processed by GMail before I fetch it, so most of my downloaded POP mail is ham. In case I want to see some spam, the web interface will have it as usual for 30 days before being deleted. I like to improve my time for productivity, to get more things done in less time, I do like learning about it, and the proof of concept for GMail handling being used by Sup and the free facilities that Google offers to dudes like me is just a great of avoiding procrastination. It s a hell nice bag of features for me, and probably for you, why not try it?

Julian Andres Klode: Fedora 9 & Kernel Mode Setting


Today, I decided to try out the new kernel mode setting feature in Fedora 9, which moves some stuff about video from userspace into the kernel. I tested this on my notebook, a HP Compaq 6720s with Intel X3100 (GM965) graphics controller. I downloaded the preview live image for x86_64 and booted with the i915.modeset=1 option. The boot was almost normal, except that it was flicker-free. After the system booted I switched the virtual terminal from Xorg to tty1 and back, and it was extremely fast. The terminals all had the same resolution. This does not mean that everything is perfect. There are a lot of things which do not work. For example, running glxgears and moving the window does not “look good”. Also, speed was a bit low. Normally, in Ubuntu Hardy, I get about 1000 FPS, in Fedora I only got 230 FPS. But the difference was not visible. Another thing which did not work was suspend & resume, because the graphics card seemed to be not correctly re-initialized. This is worse than Ubuntu & Debian. In Ubuntu, suspend & resume works almost every time. In Debian, it works except that the backlight is disabled in X. If these problems can be fixed, it would be very interesting to get this feature into Ubuntu Intrepid, maybe not as the default, but as an option for people who want to test it. Fedora 9 seems to be a fast and stable distribution, with experimental features for experienced users and developers. It also provides a nice application for configuring PulseAudio, like per-application volume settings, a functionality I miss in Ubuntu.

Steve Kemp: On the other side of the screen, it all looks so easy

I've updated the IMAP utility that I mentioned previously, which has now been given the name sift. It will accept, and process, a much simpler configuration file format keeping state as it goes. Here's my updated sample file:
username: blah.bah
password: pas.word
#
#  Comments are fine.
#
folder:livejournal status:new subject:temp mark:read exec:~/bin/notify
folder:foo status:new mark:read
folder:bar status:old exec:/usr/local/bin/record delete
Each line consists of a set of tokens, split by whitespace, which is "executed" in order. So the first line selects the folder "livejournal", finds messages which are "new", then each message containing "temp" in the subject is marked as read, and the program "notify" is executed once for each match. Essentially we keep a list of messages as "current" as we process each line, that list of messages is then refined as we move through the line. (When a folder is opened all messages are selected by default.) As a simple example to delete all the messages contained in a folder we'd use this:
folder:foo delete
To refine that to only delete messages from "fred" we'd say:
folder:foo from:fred delete
(If there were no matches the "delete" action wouldn't occur.) Consider each line of input a collection of filters each operating on the previous result. Simple to understand, simple to extend with more operations, and simple for me to code! TODO: Add a "move:xxx" to move a message to folder "xxx", and a bit more polish, then release. ObQuote: Tron.

19 April 2008

Chris Lawrence: Principals, agents, and Debian

I’ve noted in the past that Debian has deliberately enshrined in its constitution some rather serious principal-agent problems. By and large this isn’t a bad thing, since there isn’t the consensus within the Debian community to support the “benevolent dictator for life” model of decision-making—if you want that, well that’s what Ubuntu and Daddy Warbucks is for. But it does mean that sometimes the caca hits the fan when a Debian project leader does exercise his powers, as our now-former DPL did earlier this week just before the end of his term of office (by my estimate, just over one hour and 27 minutes before). John Adams would be proud. So we have three related issues in my mind: In any event, congratulations to all the new Debian developers—and I’ll avoid pondering for too long why one person’s appointment to an unrelated group would suddenly break the logjam of developer application approvals.

Theodore Ts'o: What Sun was trying to do with Open Solaris

I was recently checking to see what, if any follow-up there had been from Sun’s ham-handed handling of the Open Solaris Trademark, and I ran across this very interesting comment from Jon Plocher’s Candidate Statement for the Open Solaris Governing Board:
“I also think there was a misunderstanding about what Sun desired when it launched the community (in part) to encourage developers to adopt and use Solaris. My take is that, while there *is* value in getting more kernel, driver and utility developers contributing to and porting the (open) Solaris operating system, there is significantly *more* value in having a whole undivided ecosystem based on a compatible set of distributions, where application developers, university students, custom distro builders and users are all able to take advantage of each other’s work. Put these two things together, and you can see Sun’s predicament. Sun *wanted* a community that empowered application developers, but *got* a community aimed squarely at kernel hackers. Whether you see this as the “kernel.org -vs- Ubuntu” fight, or the “fully open -vs- MySQL model” argument, in my opinion, it all is simply a reflection of the above mismatched expectations.”
So that explains why it’s take three long years to try to get basic open source development tools (such as putting Open Solaris source code in a distributed SCM located outside of the Sun firewall) for Open Solaris. It was never was Sun’s intention to try to promote a kernel engineering community, or at least, it was certainly not a high priority for them to do so. This can be shown by the fact that as of this writing they still are using the incredibly clunky requester/sponsor system for getting patches into Solaris; setting up a git or mercurial server is not rocket science. This lack explains why Linus gets more contributions while brushing his teeth than Open Solaris gets in a week. So if you run into a Sun salescritter or a Sun CEO claiming that OpenSolaris is just like Linux, it’s not. Fundamentally, Open Solaris has been released under a Open Source license, but it is not an Open Source development community. Maybe it will be someday, as some Sun executives have claimed, but it’s definitely not a priority by Sun; if it was, it would have been done before now. And why not? After all, they are getting all of the marketing benefit of claiming that Solaris is “just like Linux”, without having to deal with any of the messy costs of working with an outside community. As a tactical measure, astroturfing is certainly a valid marketing trick. But after three years, the excuse of “just you wait a little longer, we’re just trying to figure this open source community stuff out”, is starting to wear a little thin. Furthermore, if (as Jon Ploncher claims) this was about “empowering application programmers”, why was it that Sun’s first act was to trumpet how wonderful it was to release the Solaris source code under a Open Source license? This only seems to make sense if the Open Solaris initiative was really a cynical marketing tactic to try to save Solaris from being viewed as irrelevant. If that was Sun’s intention, I think it is fair to say that from a marketing point of view, the tactic has been at least partially successful — although as Jon has admitted, the goal of creating a full community with application developers, university students, and so on, hasn’t materialized for Open Solaris. Sun has the dream; the Linux community is living it. However, from business standpoint, I wonder if Sun will really be able to sustain their Solaris engineering team if they will really be doing all of the work themselves, and outside contributions continue at the rate of 0.6 patches per day. After all, the margins when you are selling low-cost AMD servers are much lower than when you are selling ber-expensive SPARC servers. With Linux, we have a major advantage in that kernel improvements are coming from multiple companies in the ecosystem, instead of being paid for by a single company. And given that 70-80% of Sun’s AMD servers are running Linux, not Solaris, it’s not clear how Sun justifies their Solaris engineering costs to their shareholders. Furthermore, if Solaris on x86_64 were to actually take off, there’s nothing to stop competitors from selling Solaris support — except the competitors won’t have to pay the engineering costs to maintain and improve Solaris, so they would be able to provide the support much more cheaply than Sun could. So while Sun’s marketing tactics have kept Solaris alive in some verticals, I have to question how successful Sun will be in the long-term.

18 April 2008

Pablo Lorenzzoni: fisl9.0: 2nd day

They ve came down with a participant number for fisl9.0: 7417. That s it over SEVEN THOUSAND! I was told it s still an estimate, since they haven t merged the databases yet (anyway, that s the official number so far). This fisl is huge! One more picture of the crowd, just for the record: Now everything is fine. TVSL went online with no problems (once the network was fixed) and remained broadcasting the event the whole day long. All was so fine that one can think it s even boring! I spent half the day attending our company booth and the other half trying to help the organizing committee. While walking around, two linux-driven home-made robots called my attention. The first one serves water to the guy in front of it: The other one just walks around: On the Debian side of the trench , I met Jo o Eriberto Mota Filho, Debian Developer wannabe who asked me to sign his key. I ve seem he before, since he s a frequent speaker at fisl and welcome him as a future developer. Meanwhile I was reminded by faw that I still owe him my signature since DebConf4!! I signed so many keys in the KSP we held then, that one or two might have been missed I intend to fix that RSN ;-)

Jaldhar Vyas: L'affaire Fucktard

Hi, Julien, I agree that Debian is not dying and it was a bad PR move for Lucas to suggest it is, but what makes you think your response is any better from the PR perspective? I too have represented Debian at trade shows, LUGs etc. and I've had to deal with this topic before. My response is not to berate the holders of misinformation (and while I believe you when you say you were only aiming at Lucas, you used the plural so it would be easy for readers to be misled into thinking you meant multiple people.) but to emphasize that Debian is unique. Noone has conducted a social experiment of this type on this scale before and it is only natural for experiments to occasionally result in explosions and bad smells. Adopting this angle does not make us look bad and steers the questioner away from negative lines of thinking without belittling him. Much better PR don't you think?

Gintautas Miliauskas: Calibrating the keyboard autorepeat setting

The default keyboard autorepeat setting on most systems is boringly slow. Even worse, the delay before autorepeat kicks in is so long. This is great for novice users, but we programmers deserve better. Here's a calibration procedure that I use: For me an autorepeat delay of ~250ms and 80 char/s rate works well. To get your numbers, you can use the command xset q grep 'repeat rate' . This tweak make the standard direction keys (and particularly the backspace & delete keys) much more useful: you can frequently get away without using special editor commands or, say, having to select things to delete them and thus resetting the X buffer. It makes things a little faster and more responsive. Try reverting to the standard setting after a few weeks of fast repeat to feel the difference.

Axel Beckert: Harddisk prices gone mad

Cut and paste from Brack’s SATA harddisk pricelist:
Samsung SpinPoint S166,  HDD,  80GB, 7200rpm, 8.9ms,  8MB Cache, SATA II NCQ, OEM, 3.5'', SAH-HD082GJ   CHF  53.00
Samsung SpinPoint S250,  HDD, 250GB, 7200rpm, 8.9ms,  8MB Cache, SATA-II NCQ, OEM, 3.5'', SAH-HD250HJ   CHF  64.00
[...]
Samsung SpinPoint T166s, HDD, 400GB, 7200rpm, 8.9ms, 16MB Cache, SATA-II NCQ, OEM, 3.5'', SAH-HD403LJ   CHF 109.00
Samsung SpinPoint T166s, HDD, 500GB, 7200rpm, 8.9ms, 16MB Cache, SATA-II NCQ, OEM, 3.5'', SAH-HD501LJ   CHF 101.00
So from 80 GB to 250 GB the price difference is less than CHF 10 and 500 GB harddisks are cheaper than 400 GB harddisks of the same type? We live in a strange world. And no, none of this harddisks is marked as special price or promotion. Oh and for all those not having CHF as your daily currency:
CHFEURUSD
1.00€0.626417$0.997506
1.59638€1.00$1.5924
1.0025€0.627983$1.00
(Rates from x-rates.com.)

David Welton: "Open Source" Akismet or Defensio?

I have a bad habit of getting caught up in side projects - I love to build stuff, and open see opportunities to engage in this hobby. A site I've run for a while is the Linux Incompatibility List, which also led me to create my own Rails based wiki for it, DedaWiki, which is of course open source (and could use some more attention). However, things are getting badly on the spam front, and it's time to find a better solution than hacking at my own anti-spam code. Two systems that look good are Akismet, which I use successfully for this journal, and Defensio. However, being the impractical guy that I am, I am also curious if there are what we might call 'open source' efforts in this area. I'm not sure what that would look like, since there's probably strength in numbers, and a hosted solution is certainly easier. Also, it seems the incentives in an arms race like anti-spam are in favor of the quick turnaround that a small, smart, dedicated team can provide. Also... a bit of security through obscurity in an arms race type situation probably doesn't hurt, since there's often going to be a way around anything that's not locked down (and part of the value of a journal like this is in the comments), and letting people see exactly what numbers and ratios and metrics are being used is going to help the bad guys. Anyone able to point me to something that proves me wrong?

Julien Danjou: Updating my .plan

I've been on holidays for one week now, breaking my usual workflow. Well, that allowed me to rest and to think about what I'd like to do and things I need to handle during next weeks. The urgent things this next days will be my primary server replacement. It is currently dying, and I already had to change its power supply twice in a month. Unfortunately, I'm now at a point where I do not have any spare piece so if things go wrong again, I'm screwed. I need to collect some money and buy a new server, or maybe get a server if someone have an old or spare one to give me, I do not know yet. On the awesome front, I'm about to release awesome 2.3, which will be the final minor release of the major branch 2. This will lead me to work on awesome 3 at a slower rate and a cooler pace. Then, the thing I do not have to hurry for is awesome 3. There's no big problems in awesome 2, and the xcb-util stuff are not stabilized yet. After my gentle yelling on XCB mailing list, it seems that things will move but will slowly. So I do have time to make things right and do what I want on that branch, making bugfix release on awesome 2 if needed. You can read more about futur on my last post about awesome. All this should give me some more spare time to work on the upcoming Debian release, lenny, which I'd like to work on. Two years ago (my god, time flies), we've done good work with the french cabal squashing critical bugs and I'd like to go back on this and squash asses again.

17 April 2008

Pablo Lorenzzoni: Wow! Fisl exploded!

I have never seem so many people at fisl. Seriously! All the rooms were crowded, all the time same as the expo and the user-group area. Our official counter were stopped at 6667 participants, but that is just because we ve taken the registration database off-line in order to process new registrations on-site. By the end of fisl all the numbers will be summed up, but I heard rumors of 7 thousand people! Awesome! I spent this first day mostly in the TVSL room. We ve had problems with the network all day long. PUCRS technicians and our link providers personnel were trying to figure out where the problem seems to be. Being stuck with a non-functioning stuff, to me this day was mostly a sequence of frustrating attempts to get over the blockage. By the end of the day I was told that they were close to a solution It reminded me of our second year trying to stream fisl, as was best told by Fluendo s Thomas ... This just leads me to an unavoidable conclusion: our network sucks! I had to hear from a Brazilian friend who lives in Europe how wonderful her Gigabit network is grrrrrrr Bored as I was, I went walking around. That, surely, were the best part of fisl so far: meeting old friends. I had the most pleasant chat (yet quick) with Otavio Salvador and Felipe van de Wiel, both friends of long time. I took some pictures of the crowd: And, since I was not available in the morning, when the huge crowd was arriving, I took a picture of a picture taken by Marlon of this initial moments: (It is not really clear in this picture, but beyond the red gates there were as many people as inside)

Jaldhar Vyas: Bitter New Maintainers Cling to Guns and Religion

For the second year in a row, I didn't vote in the DPL election. Not because I have lost interest in Debian affairs but because nothing is really going on that demands my attention. All three of the candidates who ran this year were eminently capable of representing of Debian and its ideals, all three had more or less the same vision for the role of DPL (IMO. See here for platforms,) and all three are, as far as I know, nice people. Organizational and social problems that previously existed have been fixed. The only problem I have with Debian these days is a lack of time but I can hardly expect the DPL to do anything about that. However, a recent post from Lucas reminded me that there is one group for which all is not fine and dandy. Given that this is the same complaint that has been made for atleast five years nows, one has to wonder why it remains singularly unfixable? Well I don't know but this delegation makes me confident that we will finally see the end of this last bottleneck too. Joerg is the one who sped up NEW package processing and I am sure he will have account creation humming along in no time. I sympathize with the frustration people stuck in NM feel, but I would like to remind them that Debian acts the way Winston Churchill observed the United States does:
"Americans can always be depended upon to do the right thing—after they've tried everything else."

Neil Williams: Data Centric programming - a new start at Alioth.

It's time for me to stop complaining about the commercialisation of SourceForge and vote with my code. I'm leaving for brighter, bluer pastures at Alioth.

Query Object Framework is first (libqof1). The others will follow. I'm leaving because of unusable mailing list archives, impossibly slow web pages and wiki and the general amount of work involved in the SF interface. I'm gaining sane mailing lists, a friendly and usable ikiwiki and a simpler (although very similar) interface.

I'm also migrating most of those packages to subversion. With so many other changes, it's not exactly a problem to add cvs2svn into the mix.

Now, of course, this does not mean that these upstream packages suddenly become Debian-only or Debian-native. It does mean that I have a chance of encouraging new developers to join the team by providing the kinds of services and support that people need when starting off with a new project. (I suppose the one thing I don't yet have is an IRC channel. Not sure if it is worthwhile but I'll see what happens.)

QOF will form the basis of the support available for each of the other projects - all will share the same low-volume QOF-devel mailing list and QOF Wiki as provided by Alioth. I'll also migrate QuickList because I'm looking at restarting development on a stalled project allied to QOF and which could provide missing functionality in QuickList. I did look at Gaby in this mix but a botched Gtk1->Gtk2 transition that ended up with two incompatible forks running different parts of the original codebase put me off completely (and neither of the forks actually worked). (Some packages deserve to be dead upstream.)

I'm looking for new blood, fresh faces and a new desire to take these projects forwards. The driving force is data freedom - creating data-driven applications that are completely agnostic to where and how the data happens to be stored. It is user data, it should be as free as the source code that wrote it. Who cares what format it is in? Let's get it into a format that some other program can use and make use of the existing data instead of duplicating it all the time. (The observant will note that my old haunt of GnuCash is stubbornly ignorant of the merits of a decent import/export implementation that actually covers more than 50% of the data in the application. No wonder I took the chance to sponsor homebank.)

DWI Data With Interaction (aka DUI -- Data Under the Interface) is what can provide the missing interfaces. It'll take a while to get it back up to date and available in Debian but it can provide the link between data and interfaces. GNU/Linux users should be able to design an interface purely on the basis of the data that it needs to handle and not care one jot about how that data comes from one free software app and goes on to the next free software app. QOF is gaining a connection to libgda which means that data can go to and fro between a whole range of databases and file formats. Homebank and pilot-qof can gain new data inputs (and possibly outputs) by utilising the existing import/export support in new ways via DWI/QOF (as libqof2). That can give a complete interface for all PIM and financial data for a typical SOHO user and all based on SQL-type queries so that every stage of the process can be tweaked and optimised according to user requirements at runtime.

(Where does Emdebian come into this? Well, many people like me need to record and process PIM/financial data on the move so Emdebian means that those users can have the same data processing on their handhelds as on the desktop. Smaller apps to capture the data quickly and efficiently whilst on the move; larger apps to refine, optimise and filter the data on the desktop entirely under user control but with a simple, scriptable, interface based on runtime queries so that the user can do exactly the same conversions tomorrow with new data but none of the configuration. Easy!)

Is this groupware ? No - it is personal, ultimately flexible and entirely customised for particular users by the users themselves. It's about small niche markets, about independent business people with bespoke and highly specialised requirements. No one is going to spend time writing their reports in Scheme or Haskell, because they are the only people who need that particular report. Instead, that individual user needs to be empowered through a simple and intuitive interface to take a piece of data from one source, correlate it with a static piece of data from individual configuration sources, calculate a result according to a third piece of data from a completely separate source and combine them all into a new set of objects that can be used in other queries. It's about preparing invoices from Palm data, it's about handling customer accounts for a one-man company or handling a stocks and shares portfolio for a partnership. Ultimately customised, ultimately flexible and completely format-agnostic.

These are the kind of applications that hold people back from GNU/Linux migrations - bespoke applications that are developed for just a few small companies or just a few situations. Free software finds it hard to provide those apps because free software depends (currently) on someone else being motivated to write a bespoke program and that person rarely understands the niche. This is a chance to put the development into the hands of those with the motivation to do the work, by making the development process more WYSIWYG.

The question is: Can we come up with a better name for DWI, dear lazyweb?

"DWI is a fairly simple environment for quickly creating data-driven applications, that is, graphical applications that manipulate and show info from a database. This environment differs from others in that it is focused on native GTK/Gnome support through the Glade GUI designer, and thus allows you to build user interfaces as elegant as you can make them in Glade."
http://dwi.sourceforge.net/

The big appeal is that DWI is database-agnostic - it only cares about the data structure, not the file format. Ally that with QOF which provides data-centric SQL-based queries and conversions between objects (including combining elements from one object into one or more other objects without having to hardcode the connection between the objects at compile time) and we have an interesting and powerful combination of engines, frontends and backends that are all data-centric.

Please, if this sparks your interest, join the QOF-devel mailing list, have a play with the ikiwiki at http://qof.alioth.debian.org/ and have a go with the code. This whole area is begging for development but it is just so far from being usable by the target audience at this stage. There is a lot of programming to be done by current developers before the principles can be let loose on the masses.
:-)

This is about working between existing projects and between distributions - no longer dedicated to a single application, platform or file format, no more tunnel vision. Work on the edges of existing applications (and indeed projects), remove the sharp edges of applications that should work together but can't. The majority of the code in these libraries and applications is already stable and mature. Like so many parts of free software, it is time, IMHO, to put aside our egotistical devotion to the one-true-executable and come up with an actual solution.

Bah! I'm beginning to sound like a PR exec instead of a dedicated geek. What does it take to motivate people and get things done around here?
:-)

Matthew Garrett

This week I'm in Mountain View for the X Developers' Conference, where I gave a presentation on things graphics drivers have to care about in order to make suspend/resume work reliably. Various people suggested that I write up an explanation of the current situation, along with some best practices for manufacturers.

One of the major differences between the ACPI specification and the older APM specification is that saving and restoring hardware state is generally left up to the operating system, with the firmware playing a much more passive role. Linux is now able to handle this state restoration for the majority of hardware, but we still have issues with graphics. Modern graphics hardware can be hugely complicated, which to a large extent we've been able to ignore because the platform will initialise it on boot. Many X drivers know how to switch a card from text mode to graphics mode (and vice-versa), but that's not adequate.

What can make this situation even more awkward is that the ACPI specification makes no guarantees about what state the hardware comes up in. It may still be in PCI D3. It may be powered up, but the registers may all be zeroed. It's even valid for the hardware to come up in text mode. A driver has to be able to deal with all of these situations.

So far, we've mostly tried to deal with this situation by running chunks of the video BIOS with applications like vbetool. This is hacky and often works badly - in some cases, it won't work at all (nvidia rewrite the entry point to their video BIOS after boot, in order to prevent situations where someone attempts to POST the card and it tries to jump to bits of the system BIOS that no longer exist). The only long-term option is for the kernel to handle the graphics suspend/resume. There's several levels at which this can be supported:
Since 2.6.25, i915 and later Intel hardware can manage basic mode reprogramming without requiring any external assistance. The radeon kernel modesetting code is also heading in this direction, and we ought to be able to manage something there before too long. The nouveau developers are heading towards the stage of being able to do native mode programming, so there's some hope of progress there as well.

It's not all plain sailing, though. Vendors can wire up hardware in different ways. AMD and Nvidia hardware provides scripts in the ROM that, in theory, abstract this away. The downside to this is that we'll have to put the interpreters for these scripts in kernel space, though this is probably needed for kernel modesetting work anyway. Even then, it's possible that we'll need workarounds for specific pieces of hardware that don't quite behave as we expect them to.

As far as making graphics work over suspend/resume, we have a pretty good idea where we are now (failing on anything other than modern Intel hardware), where we need to be in the future (triumph, huge success, cake) and how to get there (?). However, hardware manufacturers can still help.
Chipset vendors:Tell us how to reinitialise your hardware. If that involves parsing BIOS tables, then please let us know how to do that. Expecting us to jump into your ROM and execute x86 code is ok if that's genuinely the only way to do it, but for any modern hardware that's clearly not the case.
System vendors:Try not to alter your system behaviour too wildly. Requiring magic register writes in order to light up the VGA output does not classify as value add. Please don't have your firmware program text mode directly - we're trying to get away from that. And do not attempt to detect that you're running on Linux and alter your system behaviour. If it's possible for you to tell that you're not running on Windows, that's a bug in Linux. If you rely on that bug, you will break. I'm not joking here in the slightest. The closest thing to a "standard" interface between an OS and the hardware is whatever Windows does, and we're basically aiming for bug-for-bug compatibility there.

Biella Coleman: Chiki-Chiki Precario,Euromayday 08

It is not the case that “copyleft” is paired with issues such as sexual freedom and immigrant rights all that often. But there are times when they are bundled together as in this video, which is advertising a Pan-Europe set of May 1st events. And even if you don’t know Spanish, you will get something out of the video given its zany aesthetics (and note that “El Copyleft” is number 1 on their list :-) )

Russell Coker: Making Linux DVDs

Anthony Towns writes about using an improved version of jigdo to download CD/DVD images [1]. His improvement is basically to pipeline operation for better performance. Jigdo (the Jigsaw download) is a tool to download a set of files and then use them to create a CD or DVD image [2]. The idea is that most web sites that have CD or DVD images also have a collection of files which comprise the DVD image available. This removes the need to store the data twice (wasting disk space on mirrors and in some situations breaking web caching). I have never used jigdo, and for all Debian installations in recent times (the last few years at least) I download a small net-inst CD image and then have it download the other files from the net. I have Squid set up to cache large objects so this doesn’t waste too much of my precious network bandwidth (which is limited and expensive in Australia). Now I’m thinking about what the optimum method for doing installs might be. One thing that would be good would be to support multiple repositories, the packages have unique file names and checksums so it should be possible to check one repository and then check another if it’s not working. I don’t mean multiple “deb” lines in the APT configuration. What I would like to do is to have an NFS file server or web server with an archive of downloaded packages and have APT check there first before downloading a file. So APT could get a list of packages from the net and then get the actual files locally if they are available. The next thing that would be good is the ability to create a CD or DVD image dynamically and to store all temporary files. So I could download files from the repository and create a DVD image with just the packages that I need. Every time I create a DVD image my sub-set of the Debian archives would increase and the number of files actually downloaded in the creation process would be reduced. The effect would be to incrementally create a local mirror of the Debian repository. Then I would like to see a two-stage DVD install process. I would like to boot from a CD or DVD and start the install and then have it give a list of files needed (which could be stored on a USB device or floppy) to create further CDs or DVDs for installation. One situation where this could have been beneficial was when I was doing an emergency install of CentOS. I did the first part of the install (selecting packages etc) to determine which CDs were needed. It turned out that almost all CDs were needed even though some of the CDs had only a few files that I was installing. If the installer could have written a list of packages to a USB device then I could have downloaded just those packages and got the install working a lot sooner. It seems to me that it’s fairly common to do one test install and then do some dozens of other installs with the same settings. So the ability to create a DVD of exactly the needed files for the other dozens of installs would be a great benefit. Now this is just random commentary, unfortunately don’t have time to do any coding on this. But it seems obvious that something has to be done to improve the situation for developers and IT staff who need some degree of mirroring of the Debian package pool but who can’t do a full mirror. Back in 1996 I was able to mirror Debian over a 28K8 modem link and fit it on what was a reasonable hard drive by the standards of the day (incredibly tiny by today’s standards). Now I can’t practically mirror Debian over an Australian cable broadband connection and even by the standards of about 4 years ago (the age of most of my hard disks) the space requirements are significant. I hope this post helps inspire some interest in developing these features. As delays in joining Debian [3] is the topic of the day it should be noted that work on preparing DVD images can easily be done by people who are not DDs. Such software should work from Debian archives without requiring any changes to them, and thus nothing special is needed from the Debian project to start work.

16 April 2008

Jeff Bailey: Physio, T-shirts, and the end of the contest!

Updates of the moment:

* I can put a t-shirt on now! About 3 days ago, I got brave and decided to give it a try. So, yay, no more zip up sweaters!

* Had my 6-week checkup yesterday, and everything is looking good. The incision is still a bit red and since my skin is so sensitive, the surgeon doesn't want me in the hottub for another 2 weeks. *pout*

* I started physiotherapy today. I can only give it a mixed review. The therapist was absolutely wonderful, it turns out that I got the clinic director. However, she doesn't actually have time to see me 3 days a week. Her schedule is so booked up that I'd be lucky to see her once a week. On top of that, the receptionists and assistants were not terribly professional (tending not to articulate, getting flustered, sort of tossing sheets of paper at me expecting me to know what to do with them), and the place was not clean. It was also in one big room, so the therapy is done in front of everyone else. Blech. So I have an appointment with a different clinic on Friday. Hopefully this one will go better.

* I don't think I've mentioned Leif recently. He's walking, can open the doors in the house now, and can clearly say "All Done". He also climbed onto my lap the other day and cuddled with me. So cute!

* Lastly, this is the end of the contest of "Guess the cost!" And the final total for the bill was.... $199,849.24. Our running total is of all things combined at UCSF is now somewhere around $280k, so I'm guessing the final total for everything will be around $300k when we're all said and done. Crazy. The closest guess was by [info]runasand at $192,000, whoever you are. Linked-in says the winner is in Norway. So finding that vegan restaurant might be interesting. I still remember Debconf 3 in Norway when the caterer told me "In Norway, we have a special way of preparing vegetables... We feed them to the animals." And the meat-eaters begging the vegetarians who were going elsewhere for food for their meals so that they had something other than slabs of meat to eat.

I think because of this, I'm going to have to award the prize to [info]mmmmtino in the meantime, who came in second place at $185k. That way I can pay it out hopefully within the next year. I'll still keep the other as a raincheque in case I happen to wind up in Norway sometime again. =)

Further on the OMG-This-medical-system-is-barbaric, It looks like the insurance company negotiates the hospital down in price, because they're in network. I've only seen the payout information for that one day overnight stay, but the insurance company will only be paying 10% of the cost. So if I didn't have insurance, I'd have to pay $67k. But the insurance company gets to pay around $7k. Do they charge so much because they don't make enough money when someone is insured? How does that all work?

Simon McVittie: Implementing D-Bus services with telepathy-glib

16:46 < epmf> tp-glib is made of magic

—#telepathy, 2008-04-15

Rob pointed out today that I'd been promising to blog about telepathy-glib for several months and still haven't done so. I think there's too much to cover in one blog post, so I'll start with the oldest part - implementing a service (typically a Telepathy connection manager).

While telepathy-glib is (obviously) intended for Telepathy implementors, I think the ideas we've been implementing are likely to be useful for any D-Bus API, particularly flexible/complex APIs where an object implements many interfaces.

Introduction to telepathy-glib telepathy-glib started out as a collection of code extracted from our XMPP connection manager, telepathy-gabble, but at some point it grew beyond that into a wrapper around/partial replacement for dbus-glib. We've been quite pleased with it, really :-) My first major round of work on telepathy-glib, during the first half of 2007, was to split it out from telepathy-gabble (versions up to 0.5.9 were released as part of Gabble 0.5.x tarballs, in fact), leading to the release of the 0.6.x stable branch in late September. This was very helpful for implementing connection managers - Salut, Idle and telepathy-sofiasip (our connection managers for link-local XMPP, IRC and SIP) all started off by forking/cargo-culting from Gabble, and achieved huge code reductions by porting to telepathy-glib. Also, Will Thompson used it in his Summer of Code project, telepathy-haze, to go from nothing to a working and useful Telepathy implementation based on libpurple in a matter of a few months. The second major round of work, which I'll discuss in a later article, added client code to telepathy-glib, obsoleting the older/worse libtelepathy and allowing client programs like Empathy and telepathy-stream-engine to be written using telepathy-glib. In the process, I accidentally reinvented DBusGProxy :-) More details to come later!
Some background: service-side code generation
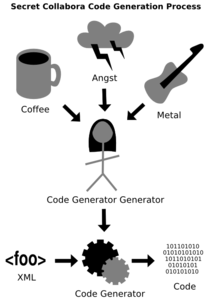
The secret Collabora code-generation process

(credit: daf)

Supporting D-Bus in the GObject world has always involved quite a lot of code generation. The core API of dbus-glib is heavily reliant on varargs functions, which aren't type-safe and are easy to get wrong. dbus-glib contains a program called dbus-binding-tool, which is meant to generate reasonably sane GObject APIs for D-Bus objects. Unfortunately, it seems to be intended to generate a whole GObject at a time. Early versions of telepathy-gabble used dbus-binding-tool plus a script called gengobject.py to generate API stubs for the exported objects; developers then filled in the blanks, and hey presto, we had a GObject on D-Bus. This was fine up to a point, but had a couple of major drawbacks. Whenever we changed the D-Bus API (quite common during the early development of Telepathy), there was a very laborious and error-prone merging process. We ended up with the following process:
  • copy the D-Bus introspection XML from the telepathy-spec repository into a directory xml/pristine (actually, the canonical form for the spec was Python for a while, and we had a script that exported a contrived object onto D-Bus and introspected itself to get the XML - but that's another story!)
  • preprocess the introspection XML to add the dbus-glib CFunctionName annotation, resulting in a directory xml/modified
  • run dbus-binding-tool and a Python script gengobject.py to generate C source in xml/src
  • three-way-diff the old version of xml/src, the new version of xml/src, and the real C code in src to create a new version of src
  • pray that the diff process hadn't randomly exchanged functions' implementations
  • update the resulting code in src so it worked
  • check the whole mess back into darcs
  • hope that nobody else had made changes that would result in darcs conflicts
If you haven't yet gathered, this was a bit of a nightmare. Also, it was very easy to return the wrong thing from a method without noticing - because all the APIs were varargs, the compiler didn't notice, and the first we'd know about it was a mysterious segfault under certain circumstances.
How telepathy-glib fixes code generation telepathy-glib improves on this by taking advantage of this innocuous-looking feature in dbus-glib:
commit 355ef78d98d6fc65715845d56232199162cab12a
Author: Steve Frécinaux <steve istique net>
Date:   Thu Aug 17 11:48:20 2006 +0200
    Interface support for bindings.
Instead of running dbus-binding-tool or creating GObjects with D-Bus interfaces, we put the entire Telepathy spec through glib-ginterface-gen.py, a distant descendant of Gabble's gengobject.py. For each interface in the spec, we generate a GInterface that mirrors the D-Bus interface. Any GObject that implements the GInterface automatically gets the D-Bus interface if it's exported onto D-Bus. There are a few non-obvious refinements, though:
  • The signature of the method implementation is always in the mode that dbus-glib calls "asynchronous", where the method implementation can either send a reply message before or after it returns. For "slow" methods, this is the only thing you can do. For instance, many Telepathy D-Bus methods can't return anything until some TCP round-trips to the server have happened. This is also the only thing you can do if you want to extract extra information, like the sender's unique name, from the method-call message (dbus-glib's "synchronous" API doesn't allow this to be done). For "fast" methods, sending a reply message before returning is just as easy as using the "synchronous" API (it's just a difference of syntax), and has an API consistent with that of the "slow" methods, making it easier for service authors.

  • The layout of the GInterface vtable is private, and (auto-generated) accessor functions are used to fill in implementations. This means our ABI doesn't change just because we re-ordered functions in the spec.

  • If no implementation is provided for a method, we just raise an appropriate error (org.freedesktop.Telepathy.Errors.NotImplemented), rather than suffering an assertion failure. This means we can safely add methods to an interface.

  • While we're generating code anyway, we generate some static inline wrapper functions which wrap dbus_g_method_return(), to have type-safe method returns. You can easily check that a method replies with correct types, by checking that the implementation of Foo() replies by calling tp_svc_some_interface_return_from_foo().

  • Similarly, we generate wrapper functions to emit signals, to get type-safe signal emission.

Not all interfaces are stable enough to be included in telepathy-glib's stable API and ABI, so some of our other projects include a copy of the telepathy-glib code-generation tools, and generate their own "mini-telepathy-glib" (traditionally in a /extensions/ directory) for their implementation-specific (drafts of) interfaces. This isn't yet as polished as it ought to be (mainly because we don't want to freeze the augmented-introspection-XML format that we write the Telepathy spec in, because it's rather ad-hoc and hackish in places) but it works quite well in practice. To see what this looks like in practice, have a look at the examples in telepathy-glib, or at a Telepathy connection manager like telepathy-gabble.
Mixins and base classes Another feature of telepathy-glib which makes life easier for connection manager authors is that it provides "mixins" and base classes which implement some of the GInterfaces. There's absolutely nothing magic about the base classes - they don't have any access to private implementation details of the GInterfaces, they just implement them like everyone else does. The "mixins" are only slightly more magical - they store some extra state inside the structures representing GObjects and their classes, and use it to provide default implementations of some or all of the methods on a particular interface (or two interfaces, in the case of the new TpMessageMixin). I'll leave it up to Rob to explain those in greater detail, since I seem to remember that he invented them :-P The examples and regression tests in telepathy-glib are quite good examples of how these work in practice.

Russell Coker: Resizing the Root Filesystem

Uwe Hermann has described how to resize a root filesystem after booting from a live-cd or recovery disk [1]. He makes some good points about resizing an LVM PV (which I hadn’t even realised was possible). The following paragraph is outdated, see the update at the end:
Incidentally it should be noted that if your root filesystem is an LVM logical volume then it can’t be resized without booting from a different device because the way LVM appears to work is that the LV in question is locked, then files under /etc/lvm/ are written, and then the LV is unlocked. If the LV in question contains /etc/lvm then you deadlock your root filesystem and need to press reset. Of course if your root filesystem is on an LV which has been encrypted via cryptsetup (the LV is encrypted not the PV) then a live resize of the root filesystem can work as locking the LV merely means that write-backs from the encryption layer don’t get committed. I’m not sure if this means that data written to an encrypted device is less stable (testing this is on my todo list). If your root filesystem is on a partition of a hard drive (such as /dev/hda2) then it is possible to extend it without booting from different media. There is nothing stopping you from running fdisk and deleting the partition of your root filesystem and recreating it. When you exit fdisk it will call an ioctl() to re-read the partition table, the kernel code counts the number of open file handles related to the device and if the number is greater than 1 (fdisk has one open handle) then it refuses to re-read the table. So you can use fdisk to change the root partition and then reboot to have the change be noticed. After that ext2online can be used to take advantage of the extra space (if the filesystem has a recent enough version of the ext3 disk format). One thing he didn’t mention is that if you do need to boot from another device to manipulate your root filesystem (which should be quite rare if you are bold and know the tricks) then you can always use your swap space. To do this you simply run swapoff and then run mkfs on the device that had been used for swap (incidentally there is nothing really special about the swap space, but it does tend to often be used for such recovery operations simply because it has no data that persists across a reboot). The minimum set of files that need to be copied to a temporary filesystem is usually /bin, /sbin, /dev, /lib (excluding all directories under /lib/modules apart from the one related to the kernel you are using), and /etc. Also you should make directories /proc, /sys, and /selinux (if the machine in question runs SE Linux). The aim is not to copy enough files for the machine to run in a regular manner, merely enough to allow manipulating all filesystems and logical volumes. Often for such recovery I boot with init=/bin/bash as a kernel parameter to skip the regular init and just start with a shell. Note that when you use init=/bin/bash you end up with a shell that has no job control and ^C is not enabled, if you want to run a command that might not terminate of it’s own accord then the command “openvt /bin/bash” can be used to start another session with reasonable terminal settings. I recommend that anyone who wants to work as a sys-admin experiment with such procedures on a test machine. There are lots of interesting things that you can learn and interesting ways that you can break your system when performing such operations. Update: Wouter points out that the LVM bug of deadlocking the root filesystem has been fixed and that you can also use ext2online to resize the mounted filesystem [2].

Next.

Previous.