Search Results: "ron"

8 March 2009

Martin Michlmayr: D-Link DNS-323 and Conceptronic CH3SNAS support integrated in installer

I finally had a chance today to test the patches Matt Palmer created to add D-Link DNS-323 support to the Debian installer. I tested the patches on a Conceptronic CH3SNAS which, from a hardware perspective, is a D-Link DNS-323 (rev B1). I noticed that the firmware image specifies a number for the vendor, so we have to generate different installer images for the D-Link DNS-323 and Conceptronic CH3SNAS. That was easy enough to do and I was able to install Debian without any problems. The next steps are to write an installation guide and other documentation, and to improve the kernel (the power LED is blinking and cannot be changed, and fan control is missing).

Stefano Zacchiroli: zack for DPL

/me for DPL Given that it is now widespread news, I guess it's time to blog about it: I'm running for DPL in this year elections, i.e.: zack for DPL!. Am I out of my mind?
Possibly :-) It started as a joke at last DebConf, with my (naked or dressed ...) room mates spreading that rumor. Then the idea grows into me ... and now here I am. (IOW: I'm pretending I'm not entirely guilty of inflicting another platform to be read.) Apparently we are just two candidates: me and the "ticket" Steve-Luk. For the moment I've to spare a page where I will collect material about the election, and a couple of feelings: Version 1.0 of my platform has been submitted to the secretary, and is now available from my homepage. If you have questions, for me or the other candidates, just post them on -vote: campaigning has just started, I'm confident it will be fun! Update the platform is now available from the vote page

Russell Coker: The FAIL Meme

One of the recent poor trends in mailing list discussions is to reply to a message with a comment such as FAIL or EPIC FAIL . The FAIL meme has been around for a while and actually does some in some situations, slate has a good article about it [1]. The first example cited in that article is that when Ben Bernanke and Henry Paulson testified before the Senate banking committee last month about Paulson s proposed bailout bill, a demonstrator in the audience held up an 8.5-by-11 piece of paper with one word scrawled on it in block letters: FAIL. . This is an effective form of political demonstration, short words generally work well on placards (if only because the letters can be larger and therefore read from a greater distance) and anyone can understand the meaning of FAIL in that context. There are some blogs dedicated to publicising supposed failures, failblog.org and ShipmentOfFail.com are two examples. I cite these as supposed failures because some of the pictures that they contain are obviously staged. It s basically an Internet equivalent of the Funniest Home Videos shows that I never watched because they were not particularly funny. So using the word FAIL on it s own can be an effective form of political protest and can be used for mildly amusing web sites. But where it falls down is when it s applied to a discussion that involves people who are from different cultures or have different levels of background knowledge - which covers most mailing list discussions. Something that might be obviously wrong to some people is often not obvious at all to others. For example being forced to reboot a computer for any reason other than a kernel upgrade seems obviously wrong to me (and to most people who use Linux or other Unix systems) but Windows users seem happy to reboot machines after applying patches or upgrades. So writing a message with FAIL as the only word in a discussion with Windows users would not be productive. It could however be reasonable to forward a link to a page on a Microsoft web site to Linux people for their amusement with FAIL as the only comment - anyone who would find the link in question amusing would require no more explanation. Sometimes when in a debate someone will write a message that only says FAIL , this is a very unconvincing argument that will not convince the opposition or any onlookers. Generally it seems that using FAIL in a discussion with other like-minded people when talking about someone outside your group for the purpose of amusement can be effective. But any other use is going to be a FAIL . As a more general rule single-word messages seem to have little value apart from certain limited situations. I have identified the following seven scenarios where a single word message is useful. Can anyone think of any others?

  1. Code review - someone posts code (or design for code) and people who like it will write ACK or something similar.

  2. Arranging a meeting - the question who wants to meet for lunch tomorrow has me as a valid answer.

  3. Voting - yes and no are valid answers for a poll, but a mailing list or forum probably isn t the best place for it.

  4. Citing an example to refute a claim - often a single word won t be a great response but may be adequate to prove a point.

  5. Answering a request for a recommendation - if asked to recommend a laptop I might say Thinkpad or if asked to recommend a server I might say HP . Both those answers are poor (I recommend EeePC for netbooks and Dell for small/cheap servers), so while such an answer would be useful it would be below my usual quality standards for email (I prefer to write at least two paragraphs explaining why I recommend something).

  6. Informing people that something has been done by replying to a request with the word Done .

  7. Agreeing to a contract or proposal with OK or Yes .

Update: I added another two reasonable uses of single word messages,

Axel Beckert: How to make identi.ca talk

The listeners of yesterday s episode of Venty s Hackerfunk radio show on Radio LoRa already know and heard it: We made identi.ca talk. And we did it with help of other microbloggers. (The podcast version of this Hackerfunk episode will be online in a few days, too. Will link it here and either Venty or me will post it on identi.ca, too, as soon as it s published.) A few weeks ago we thought about how we could show microblogging on the radio. With identi.ca s Jabber (XMPP) interface we have real time access, and so the idea was born to pipe all incoming dents into a speech synthesis system. Then we tried to figure out which tools would be appropriate. Quite fast, people on identi.ca as well as on the LUGS IRC (e.g. bones0) pointed us to festival and espeak. We found no support for German in festival, so we went for espeak although festival would have had the advantage of the existence of a festival plugin for the popular multiprotocol messenger Pidgin. Next step was more difficult than expected: How to make a tail -f of XMPP incoming messages? Something like rsstail, just for XMPP. Although using the IM to IRC gateway Bitlbee (as I use it myself) and using tail -f (or better inotail -f ) on the IRC client s log file (ii comes to my mind for such purposes) would have been an option, nobody had the idea at that time. And since @deepspawn conjured xmpptail in less than two hours we happily took it. xmpptail (tar.gz) is written in Python and uses Twisted Words (Debian package python-twisted-words) as XMPP libraries. I had to patch xmpptail slightly for unbuffered I/O, Unicode support and for removing things we don t want to hear on the radio as follows, but it worked more or less out of the box.
--- xmmptail.py 2009-02-25 20:47:48.000000000 +0100
+++ xmpptail.py 2009-03-07 18:48:57.000000000 +0100
@@ -1,4 +1,4 @@
-#!/usr/bin/python
+#!/usr/bin/python -u
 # -*- coding: utf-8 -*-
 # author: Carlos A. Perilla 
 # This file is part of Jance bot.
@@ -65,7 +65,8 @@
          body = unicode(e.__str__())
          break
 
-    print("%s: %s" % (from_id,body))
+#    print("%s: %s" % (from_id,body))
+    print("%s" % (body.encode('utf-8')))
 
 
 def authfailedEvent(xmlstream):
@@ -80,9 +81,9 @@
   dprint('Got something: %s -> %s' % (el.name, str(el.attributes)))
 
 if __name__ == '__main__':
-    print "Starting"
+    #print "Starting"
     execfile('tailconf')
-    print USER_HANDLE
+    #print USER_HANDLE
     me = USER_HANDLE + "/xmpptail"
     myJid = jid.JID(me)
     server = USER_HANDLE[USER_HANDLE.find('@')+1:]
So after configuring xmpptail to use the hackerfunk Jabber account, we successfully ran the following script during the radio show:
./xmpptail.py   while read LINE; do
        if [ "$LINE" = "empty" ]; then
                continue;
        fi;
        echo $LINE
        echo $LINE   tee -a xmpp-espeak.log   espeak --stdin -v de;
done
At the end of the show, @rebugger found this howto which describes very detailed how to get festival working together with the non-free ( non-free as in DFSG) MBROLA project which offers also the appropriate files for German. But because of how much work this would be to get it running, I currently prefer to stay with espeak for German speech synthesis . Next step would be to use mnoGosearch s mguesser to detect the language of a dent and run espeak (or whatever text-to-speech system is appropriate for the guessed language) with the appropiate options for that language, because otherwise many dents sound really funny. ;-) Update, 15:02: Venty gave the whole system the name Identibla .

6 March 2009

Russell Coker: Case Sensitivity and Published Passwords

When I first started running a SE Linux Play Machine [1] I used passwords such as 123456 . Then for a while I had selinux but when I created a T-shirt design (see the main Play Machine page for details) I changed the password to SELINUX because that is easier to read on a shirt. Unfortunately the last time I rebuilt the Play Machine I used a password of selinux , some people worked this out and still logged in so I didn t realise that anything was wrong until a comment was placed on my blog yesterday. So for the past three weeks or so some people have been finding themselves unable to login. The password is now SELINUX again, sorry for any inconvenience. It s a pity that I can t make sshd a little less case sensitive for passwords. A PAM module to implement a caps-lock mode where the opposite case is tried would be useful for this case and some others too.

Robert McQueen: This is a local mail for local people, we ll have no trouble here!

all programs that interact with e-mail are broken in one way or another. Please be careful. - Lars Wirzenius
I seem to have a cunning knack of finding problems with configuring server software, particularly involving e-mail, where a) I can t find answers in Google, b) most people I go and ask for help say they d usually ask me such things, and c) if I go onto IRC or mailing lists I end up helping other people and not getting any help with my problem. It s quite likely this is just because I m something of a perfectionist, so the ridiculous crappy hacks people come up with and seem content to entrust their mail to are unacceptable to me for one reason or another. Anyway, in my ongoing quest for the perfect mail system, I ve painted myself into a corner again. (I m currently running with postfix, postgrey, clamav-milter, dspam, dovecot using LDA, managesieve and the cmusieve & antispam plugins. If I can get the current incarnation working, I ve had enough requests to write up a full HOWTO, and seen enough around with pretty questionable content, that I ll probably do it before too long.) I ve got postfix s local transport configured to hand mail to dspam over LMTP, using mailbox_transport = lmtp:unix:/dspam/dspam.sock. dspam is configured to listen here, add X-DSPAM-Result and signature headers, and then deliver the mail with dovecot s deliver LDA (which I ve set to 4750 root:dspam). From dspam.conf: ServerParameters "--deliver=innocent,spam -d %u"
ServerDomainSocketPath "/var/spool/postfix/dspam/dspam.sock"
...
Preference "spamAction=tag"
Preference "signatureLocation=headers"
...
TrustedDeliveryAgent "/usr/lib/dovecot/deliver"
My dovecot configuration is pretty standard, using PAM for both passdb and userdb, and provides the auth-master socket that deliver needs. The problem I have is that postfix s local transport is qualifying the local username with the FQDN of the machine before delivering it to dspam with LMTP (the local mail transfer protocol), even for locally-originated mail which was only addressed with a bare username! dspam doesn t mangle it or care if the user is local or not, and then cheerfully invokes deliver -d robot101@omega.example.co.uk, which returns EX_NOUSER (addressee unknown) because my username is just robot101. From mail robot101: Mar 6 02:25:40 omega postfix/pickup[13607]: DAA4942F41F: uid=1000 from=<robot101>
Mar 6 02:25:40 omega postfix/cleanup[13637]: DAA4942F41F: message-id=<20090306022540.DAA4942F41F@omega.example.co.uk>
Mar 6 02:25:40 omega postfix/qmgr[12552]: DAA4942F41F: from=<robot101@omega.example.co.uk>, size=339, nrcpt=1 (queue active)
Mar 6 02:25:40 omega dovecot: auth(default): passwd(robot101@omega.example.co.uk): unknown user
Mar 6 02:25:40 omega dspam[13527]: Delivery agent returned exit code 67: /usr/lib/dovecot/deliver -d robot101@omega.example.co.uk
Mar 6 02:25:40 omega postfix/lmtp[13640]: DAA4942F41F: to=<robot101@omega.example.co.uk>, orig_to=<robot101>, relay=omega.example.co.uk[/dspam/dspam.sock], delay=0.08, delays=0.05/0.01/0.01/0.03, dsn=4.3.0, status=deferred (host omega.example.co.uk[/dspam/dspam.sock] said: 421 4.3.0 <robot101@omega.example.co.uk> Delivered (in reply to end of DATA command))
So, no e-mail for me. Dearest lazyweb, which of the three components is behaving wrongly, and how can I fix it? (And no, I m not just going to switch to GMail. I store my data on hard drives, which are sometimes in servers, not in the cloud . Until about a month ago, most people I knew spoke about clouds which were made of particles of water in the sky, rather than as a data storage media. What if it rains? ;)

Robert McQueen: This is a local mail for local people, we ll have no trouble here!

all programs that interact with e-mail are broken in one way or another. Please be careful. - Lars Wirzenius
I seem to have a cunning knack of finding problems with configuring server software, particularly involving e-mail, where a) I can t find answers in Google, b) most people I go and ask for help say they d usually ask me such things, and c) if I go onto IRC or mailing lists I end up helping other people and not getting any help with my problem. It s quite likely this is just because I m something of a perfectionist, so the ridiculous crappy hacks people come up with and seem content to entrust their mail to are unacceptable to me for one reason or another. Anyway, in my ongoing quest for the perfect mail system, I ve painted myself into a corner again. (I m currently running with postfix, postgrey, clamav-milter, dspam, dovecot using LDA, managesieve and the cmusieve & antispam plugins. If I can get the current incarnation working, I ve had enough requests to write up a full HOWTO, and seen enough around with pretty questionable content, that I ll probably do it before too long.) I ve got postfix s local transport configured to hand mail to dspam over LMTP, using mailbox_transport = lmtp:unix:/dspam/dspam.sock. dspam is configured to listen here, add X-DSPAM-Result and signature headers, and then deliver the mail with dovecot s deliver LDA (which I ve set to 4750 root:dspam). From dspam.conf: ServerParameters "--deliver=innocent,spam -d %u"
ServerDomainSocketPath "/var/spool/postfix/dspam/dspam.sock"
...
Preference "spamAction=tag"
Preference "signatureLocation=headers"
...
TrustedDeliveryAgent "/usr/lib/dovecot/deliver"
My dovecot configuration is pretty standard, using PAM for both passdb and userdb, and provides the auth-master socket that deliver needs. The problem I have is that postfix s local transport is qualifying the local username with the FQDN of the machine before delivering it to dspam with LMTP (the local mail transfer protocol), even for locally-originated mail which was only addressed with a bare username! dspam doesn t mangle it or care if the user is local or not, and then cheerfully invokes deliver -d robot101@omega.example.co.uk, which returns EX_NOUSER (addressee unknown) because my username is just robot101. From mail robot101: Mar 6 02:25:40 omega postfix/pickup[13607]: DAA4942F41F: uid=1000 from=<robot101>
Mar 6 02:25:40 omega postfix/cleanup[13637]: DAA4942F41F: message-id=<20090306022540.DAA4942F41F@omega.example.co.uk>
Mar 6 02:25:40 omega postfix/qmgr[12552]: DAA4942F41F: from=<robot101@omega.example.co.uk>, size=339, nrcpt=1 (queue active)
Mar 6 02:25:40 omega dovecot: auth(default): passwd(robot101@omega.example.co.uk): unknown user
Mar 6 02:25:40 omega dspam[13527]: Delivery agent returned exit code 67: /usr/lib/dovecot/deliver -d robot101@omega.example.co.uk
Mar 6 02:25:40 omega postfix/lmtp[13640]: DAA4942F41F: to=<robot101@omega.example.co.uk>, orig_to=<robot101>, relay=omega.example.co.uk[/dspam/dspam.sock], delay=0.08, delays=0.05/0.01/0.01/0.03, dsn=4.3.0, status=deferred (host omega.example.co.uk[/dspam/dspam.sock] said: 421 4.3.0 <robot101@omega.example.co.uk> Delivered (in reply to end of DATA command))
So, no e-mail for me. Dearest lazyweb, which of the three components is behaving wrongly, and how can I fix it? (And no, I m not just going to switch to GMail. I store my data on hard drives, which are sometimes in servers, not in the cloud . Until about a month ago, most people I knew spoke about clouds which were made of particles of water in the sky, rather than as a data storage media. What if it rains? ;) Update: The problem is fixed! Even though arguably the problem is dspam s for not knowing which users are local or not, it s fixable in dovecot 1.1.x using the auth_username_format = %n option. Thanks so much to Angel Marin for helping me out. Update 2: There s also a patch for dspam floating around which adds a StripRcptDomain option, which makes the LMTP server truncate the e-mail address at the @, so essentially assumes everyone to be a local user. The problem with both of these fixes is that they re both blunt instruments which will break virtual users on the same host. I think the real fix would be something more like a LocalDomains option in dspam, to choose which domains should be considered local and truncated from the e-mail addresses for delivery purposes.

5 March 2009

Matt Brubeck: 5 Mar 2009

Async Map and Fold in JavaScript My latest experiment is an implementation of asynchronous/parallel "map" (and other array functions) in JavaScript and Oni. Oni is a "structured concurrency language" embedded in JavaScript. For my source code and commentary, see oni-map at GitHub. You can leave comments at GitHub too. All this time reading Real World Haskell must really have warped my brain if a simple testing framework for a JavaScript program has got me thinking about higher-order functions and concurrency semantics...

Sami Haahtinen: Debian Xen dom0 Upgrade woes

I finally decided that it's time for me to upgrade my Xen installation. It used to run etch with backported Xen, because the etch version was increasingly difficult to work with. I also acknowledge that some of the issues I've been having are simply caused by yours truly, but even still the Debian Xen installation is way too fragile to my taste. I've already considered installing XenServer Express locally and running the hosts on it. The big drawback has been that XenCenter (the tool that is used to manage XenServer) is windows only and it doesn't work with wine. So you can imagine my desperation... Anyway, the latest upgrade from etch to lenny was painful as usual. The first part went smoothly, bit of sed magic on sources.list and a few upgrade commands (carefully picking the Xen packages out of the upgrade set). So in the end I had a working lenny installation with backported Xen. Next I made sure that there was nothing major going on in my network (one of the virtual machines acts as my local firewall) and took a deep breath before upgrading the rest of the packages. I knew to be careful about xendomains -script which has reliably restored my virtual machines after reboot to a broken host so I had always ended up restarting my virtual machines after reboot. I carefully cleared XENDOMAINS_AUTO and set XENDOMAINS_RESTORE to false in /etc/default/xendomains so that the virtual machines would be saved but not restored or restarted on reboot. After the normal pre-boot checks I went for it. Oddly enough everything worked normally and the system came up after a bit of waiting. I checked the bridges and everything appeared normal, so it was time to try and restore a single domain to see that everything actually did work as planned.
Hydrogen:~# xm restore /var/lib/xen/save/Aluminium
Error: Device 0 (vif) could not be connected. Hotplug scripts not working.

Oof, Googling for the issue revealed that there were others that had suffered from the same problem on various different platforms the problems were caused by different things. One would assume that the problem is in the vif-bridge script that is mentioned in the xend-config.sxp file as the script that brings up the vif, but after many hours of tial and error and pointless googling (over gprs connection), I couldn't find any solution to the problem. It was time to call it a day (it was almost 3 am already...) During the night I had a new idea about the possible cause. What if the problem isn't in xend, but somewhere else. I fired up udevadm monitor to see what udev saw and it wasn't much. I'm not an expert with udev, but from previous encounters I had a vague feeling that there was supposed to be more events flying around. I wasn't able to pinpoint what was wrong so I decided to purge xen-utils, of which I had 2 versions installed: 3.2-1 and 3.0.2. I also removed everything related to xenstore. After reinstalling the current versions and restoring my configuration files the first host came up just fine. I still had problems resuming the virtual machines and I ended up rebooting them again, which was nothing new, but at least they were running again. In the end I don't know what was the actual cause for udev not handling the devices properly, but I'm happy to have them all running again. And I learned a valuable lesson of all this: udev is an important part of Xen, make sure it works properly.

Eddy Petri&#537;or: Glest: how upstream can be a real dick

At some point in the past, when I was still thinking that Glest can be packaged in a sane way, I had a conversation with upstream developer martinho on the Glest forum (they call it board) about them integrating a patch in order to support big endian machines.

After some messages on their board, it was clear that they don't want to integrate any patches and started to throw out random fake arguments against the integration of my patch and other patches.

When he figured out that I replied and debunked all of his fake arguments, he went on and actually removed my posts from the forum. It was so weird since I have never seen that kind of behaviour before and some of his posts and other people's posts were replies to my posts and things didn't made any sense after the deletion.

At that moment I have managed to save one small bit of the conversation via Google's cache, but now I have finally decided to make it public.


Note: Back then, I kept this post private in the hope that I was maybe too involved in the conversation at that moment to make a rational decision about it, and hoped things would get better in time. They didn't. Meanwhile they migrated to another forum software and they said they lost most/all(?) of the previous content from the old forum.


Here is the conversation bit I managed to save.
Original text is in italic font. Regular font is for my current comments for clearing up the context of the discussion. The text retains the BB syntax and [quote]-d text is martinho's own words.


[quote="martinho"]thebohemian, eddyd,

I think you guys are missing the point, this is not the place for any [/quote]

Congrats, you are avoiding to answer the points I have raised.

[quote]
- The Glest project is made by a bunch of friends for fun, we ask for nothing, we answer to no one. So I beg you not co complain, because it is out of order.
[/quote]

In that case I don't see the point of the "development" forum. care to explain?
And, from my PoV, these are your users you're arrogantly dismissing.


The following was a reply to my request to add big endian support through a patch I provided at that time. The patch wasn't complete to actually make glest work on BE machines, but it didn't broke little endian support at all. He was trying to argue that there were no valid big endian machines on which the game would run. Integrating the patch would have made my life a lot easier in continuing the work on the patch.

[quote]
- Our target plarforms are PCs running Windows (I'm responsible for this) or Linux (matze is the boss here). We don't care if Glest doesn't run in a big endian dishwasher with Solaris.
[/quote]

Linux on PowerPC is a viable platform. So is Mac OS X on PowerPC.


I made the mistake of saying that some parts of the code where not that clean and could be improved. More on that below.

[quote]
- One of the keys of Glest success is how extremely clean our code is. Bringing random people in would break this, and we are not going to do it. [/quote]

So you are the only keepers of true knowledge of clean code? Hahahaha!

There were at least 3 patches that provided this through word/double-word swapping. I don't see how embedding the patch can affect the unity of the code.

BTW, you are aware you can "carve" people into coding in your style before accepting in, aren't you?


I suggested using int8, uint8, int16, uint16 in order to make sure that the parameters are of the expected fixed size since plain char, int, long, long long have different sizes depending on the architecture. The usage of int and int16 was inconsistent and I also suggested using always the numbered variants.

I said the approach that was then taken in code was not portable and that was the reason for the proposed change.

[quote]
- Glest has been coded with portability in mind, some of your comments about portability are really naive (compilers don't care if you declare function parameters with fixed byte length, they just use whatever is the fastest int in the platform). Fixed length data types are used when needed,
[/quote]

What? When did I say anything about that? I said the code uses inconsistently "int" and "int16" and should use the later always because the code assumes the sizes on i386, which are not always applicable - see long on amd64.


If you mean that I can't enforce the width of the parameter, then you should know better, those types are defined in a platform dependent way to be platform independent. Yes, there are cases where [b]on the stack[/b] the size of the passed data is bigger (they might be padded), but that is transparent to the functions and, in spite of that, the functions will see the proper values for the parameters.

Also, the packing behaviour is compiler and architecture dependent, and some compilers produce the weirdest packing (if you are allowed access to such docs, look for Green Hills compilers' for V850 and you'll be stunned).


Please, don't make a fool of yourself by trying to discredit me, just not to loose face.

Later he just removed my posts not to loose face.


As a sane programmer, I made my patch to do the swapping only on big endian platforms, and the code was enabled in through the precompiler, so there was no performance hit on the little endian arches.

Of course, any more-than-newbie programmer would agree that having two data sets for a single game is stupid and is better to do the swapping in the application itself to avoid space wastage and maintaing an alternate big endian data set.

[quote]
no more, no less. About endianness, we don't care. If we wanted to fix the problem anyway, the right way is to do the byte swap in the data, this is how it is done in commercial games, since it is more efficient.
[/quote]

You just proved how much bullshit you can deliver in one phrase just for the sake of winning an argument. All portable games and all applications that have data files prefer to do swapping on the spot just because swapping the data on the disk (or providing BE and LE data) is plain stupid and inefficient from a disk and bandwidth PoV.

For Glest, swapping the data after reading from disk is not even affecting performance in a manner that could be significant or noticed, not even for a processor running at 500MHz, since that would be done only on load, once, and just for the bits of data which are relevant; these are mostly headers, since the actual data, in most cases, is just a long byte vector. This translates in not more than 3 or 4 instructions in assembler (an init, an exchange, an increment and/or a loop instruction), and that would happen before starting a game, which is dead time anyway and wouldn't be noticed unless the data would be huge (order of hundreds of MB or GB) and the whole data set would need swapping.

Even if the data itself (not headers) represents data which needs to be swapped, that is still irrelevant in terms of speed.


BTW, the reason that in commercial games it might be done like that is because there the games are distributed in a package per platform anyway and having two data sets is not an issue since they are using the same amount of CDs/DVDs, but doing the same for a game like Glest would mean doubling the storage used and it would increase the complexity for a release, not to count the confusion of the users.

I still doubt commercial games do this, but I might be wrong.

Colin Watson: Bug triage, redux

I've been a bit surprised by the strong positive response to my previous post. People generally seemed to think it was quite non-ranty; maybe I should clean the rust off my flamethrower. :-) My hope was that I'd be able to persuade people to change some practices, so I guess that's a good thing. Of course, there are many very smart people doing bug triage very well, and I don't want to impugn their fine work. Like its medical namesake, bug triage is a skilled discipline. While it's often repetitive, and there are lots of people showing up with similar symptoms, a triage nurse can really make a difference by spotting urgent cases, cleaning up some of the initial blood, and referring the patient quickly to a doctor for attention. Or, if a pattern of cases suddenly appears, a triage nurse might be able to warn of an incipient epidemic. [Note: I have no medical experience, so please excuse me if I'm talking crap here. :-)] The bug triagers who do this well are an absolute godsend; especially when they respond to repetitive tasks with tremendously useful pieces of automation like bughelper. The cases I have trouble with are more like somebody showing up untrained, going through everyone in the waiting room, and telling each of them that they just need to go home, get some rest, and stop complaining so much. Sometimes of course they'll be right, but without taking the time to understand the problem they're probably going to do more harm than good. Ian Jackson reminded me that it's worth mentioning the purpose of bug reports on free software: namely, to improve the software. The GNU Project has some advice to maintainers on this. I think sometimes we stray into regarding bug reports more like support tickets. In that case it would be appropriate to focus on resolving each case as quickly as possible, if necessary by means of a workaround rather than by a software change, and only bother the developers when necessary. This is the wrong way to look at bug reports, though. The reason that we needed to set up a bug triage community in Ubuntu was that we had a relatively low developer-to-package ratio and a very high user-to-developer ratio, and we were getting a lot of bug reports that weren't fleshed out enough for a developer to investigate them without spending a lot of time in back-and-forth with the reporter, so a number of people volunteered to take care of the initial back-and-forth so that good clear bug reports could be handed over to developers. This is all well and good, and indeed I encouraged it because I was personally finding myself unable to keep up with incoming bugs and actually fix anything at the same time. Somewhere along the way, though, some people got the impression that what we wanted was a first-line support firewall to try to defend developers from users, which of course naturally leads to ideas such as closing wishlist bugs containing ideas because obviously those important developers wouldn't want to be bothered by them, and closing old bugs because clearly they must just be getting in developers' way. Let me be clear about this now: I absolutely appreciate help getting bug reports into a state where I can deal with them efficiently, but I do not want to be defended from my users! I don't have a basis from which to state that all developers feel the same way, but my guess is that most do. Antti-Juhani Kaijanaho said he'd experienced most of these problems in Debian. I hadn't actually intended my post to go to Planet Debian - I'd forgotten that the "ubuntu" category on my blog goes there too, which generally I see as a feature, but if I'd remembered that I would have been a little clearer that I was talking about Ubuntu bug triage. If I had been talking about Debian bug triage I'd probably have emphasised different things. Nevertheless, it's interesting that at least one Debian (and non-Ubuntu) developer had experienced similar problems. Justin Dugger mentions a practice of marking duplicate bugs invalid that he has problems with. I agree that this is suboptimal and try not to do it myself. That said, this is not something I object to to the same extent. Given that the purpose of bugs is to improve the software, the real goal is to be able to spend more time fixing bugs, not to get bugs into the ideal state when the underlying problem has already been solved. If it's a choice between somebody having to spend time tracking down the exact duplicate bug number versus fixing another bug, I know which I'd take. Obviously, when doing this, it's worth apologising that you weren't able to find the original bug number, and explaining what the user can do if they believe that you're mistaken (particularly if it's a bug that's believed to be fixed); the stock text people often use for this doesn't seem informative enough to me. Sebastien Bacher commented that preferred bug triage practices differ among teams: for instance, the Ubuntu desktop team deals with packages that are very much to the forefront of users' attention and so get a lot of duplicate bugs. Indeed - and bug triagers who are working closely with the desktop team on this are almost certainly doing things the way the developers on the desktop team prefer, so I have no problem with that. The best advice I can give bug triagers is that their ultimate aim is to help developers, and so they should figure out which developers they need to work with and go and talk to them! That way, rather than duplicating work or being counterproductive, they can tailor their work to be most effective. Everybody wins.

4 March 2009

Uwe Hermann: Building an ARM cross-toolchain with binutils, gcc, newlib, and gdb from source

I've been planning to write about building custom ARM toolchains for a while (I used stuff from gnuarm.com in the past, but I switched to the lastest and greatest upstream versions at some point). Among other things, recent upstream versions now have ARM Cortex support. First you will need a few base utilities and libs:
  $ apt-get install flex bison libgmp3-dev libmpfr-dev autoconf texinfo build-essential
Then you can use my tiny build-arm-toolchain script, which will download, build, and install the whole toolchain:
  $ cat build-arm-toolchain
  #!/bin/sh
  # Written by Uwe Hermann <uwe@hermann-uwe.de>, released as public domain.
  TARGET=arm-elf                         # Or: TARGET=arm-none-eabi
  PREFIX=/tmp/arm-cortex-toolchain       # Install location of your final toolchain
  PARALLEL="-j 2"                        # Or: PARALLEL=""
  BINUTILS=binutils-2.19.1
  GCC=gcc-4.3.3
  NEWLIB=newlib-1.17.0
  GDB=gdb-6.8
  export PATH="$PATH:$PREFIX/bin"
  mkdir build
  wget -c http://ftp.gnu.org/gnu/binutils/$BINUTILS.tar.bz2
  tar xfvj $BINUTILS.tar.bz2
  cd build
  ../$BINUTILS/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib \
    --with-gnu-as --with-gnu-ld --disable-nls
  make $PARALLEL
  make install
  cd ..
  rm -rf build/* $BINUTILS $BINUTILS.tar.bz2
  wget -c ftp://ftp.gnu.org/gnu/gcc/$GCC/$GCC.tar.bz2
  tar xfvj $GCC.tar.bz2
  cd build
  ../$GCC/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib \
    --enable-languages="c" --with-newlib --without-headers --disable-shared --with-gnu-as --with-gnu-ld
  make $PARALLEL all-gcc
  make install-gcc
  cd ..
  rm -rf build/* $GCC.tar.bz2
  wget -c ftp://sources.redhat.com/pub/newlib/$NEWLIB.tar.gz
  tar xfvz $NEWLIB.tar.gz
  cd build
  ../$NEWLIB/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib \
    --with-gnu-as --with-gnu-ld --disable-nls
  make $PARALLEL
  make install
  cd ..
  rm -rf build/* $NEWLIB $NEWLIB.tar.gz
  # Yes, you need to build gcc again!
  cd build
  ../$GCC/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib \
    --enable-languages="c,c++" --with-newlib --disable-shared --with-gnu-as --with-gnu-ld
  make $PARALLEL
  make install
  cd ..
  rm -rf build/* $GCC
  wget -c ftp://ftp.gnu.org/gnu/gdb/$GDB.tar.bz2
  tar xfvj $GDB.tar.bz2
  cd build
  ../$GDB/configure --target=$TARGET --prefix=$PREFIX --enable-interwork --enable-multilib
  make $PARALLEL
  make install
  cd ..
  rm -rf build $GDB $GDB.tar.bz2
The final toolchain is located in /tmp/arm-cortex-toolchain per default, and is ca. 170 MB in size. I explicitly created the build script in such a way that it minimizes the amount of disk space used during the build (ca. 1.2 GB or so, compared to more than 3 GB in the "naive" approach). Using the "-j 2" option for make (see script) you can speed up the build quite a bit on multi-core machines (ca. 30 minutes vs. 60 minutes on an AMD X2 dual-core box). Also, you can change the script to build for other target variants if you want to (arm-elf or arm-none-eabi, for example). Checkout the blog entry How to build arm gnu gcc toolchain for Mac OS X by Piotr Esden-Tempski for similar instructions for Mac OS X users. Oh, and while I'm at it does anybody have any idea why there are no pre-built toolchains for embedded (microcontroller) ARM targets in Debian? There are some toolchains for other microcontroller architectures (avr, m68hc1x, h8300, z80) but not too much other stuff. Is there some specific reason for the missing ARM toolchains (other than "nobody cared enough yet")? I have heard about Emdebian, but from a quick look that seems to be more intended for toolchains with Linux/libc, not for microcontroller firmware (i.e. no MMU, no Linux, no libc etc.), but maybe I'm wrong?

Jose Carlos Garcia Sogo: Innovation in netbooks

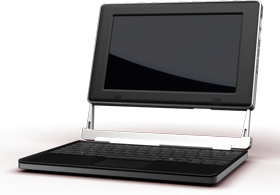
After the release of Asus Eee PC and the discovery of the market that was eager to buy cheap and wearable computers every laptop manufacturer has jumped into the hype and released their own versions of netbooks, with different success.
But somehow it was a cloning phase. Vendors were just cloning what Asus did, with more or less changes, but without innovating. Now, it seems that the path has opened again, from the open source and open hardware front, and it has been released AlwaysInnovating s touchbook. It is a netbook with a detachable keyboard (it is even sold separated) and built upon an ARM processor from Texas Instruments, and a 8GB microSD card. Thus they claim the battery last from 10 to 15h with the keyboard, and 3 to 5h in touchscreen mode.
As is said above, the whole machine is open source based. Software is based upon OpenEmbedded, and hardware schematics of the board are released under GPL on Beagleboard project. They say that you can also install Ubuntu, Android or even Windows CE on it. Update: Just discovered that AlwaysInnovating is a Gr goire Gentil startup. Gr gory is a Civil Engineer from cole des ponts et Chauss es. We know how to build things :-D

3 March 2009

Steve Kemp: Nobody likes a perky goth

Debian project leader elections are coming up soon. My vote will go to the candidate that: Thats all. I guess most people don't really care about being a DPL per-se, instead they stand for election to accomplish a pet project, or two. (Not that there is anything wrong with that. If your platform says "Elect me and I'll do $foo" then you've got implicit support.) A recurring theme in platforms has been communication, and I think that over time it has got a lot better. Regardless, if theres one thing I want to see from the DPL in 2009 it is even more communication. In other news, depending on your timezone, todays date is 3/3/9 - enjoy it while it lasts. The next similar date is 4/4/16 - which is seven years in the future. ObTitle: Blood Ties

Uwe Hermann: How to use the full size of your (x)term when connecting to some other box serially with minicom

minicom terminal size 1 Just as a reminder for myself, as I'll probably need this more often in the future (and maybe it's helpful for others): Per default, if you use a big xterm (232x74 in my case) where you start minicom, the $COLUMNS and $LINES environment variables will be 80x24 nevertheless, and those applications which honor them (vim, for example) will be too small and not use the full xterm size of 232x74.
  $ minicom
  $ echo $COLUMNS; echo $LINES
  80
  24
minicom terminal size 2 You can fix that like this:
  $ eval  resize 
  $ echo $COLUMNS; echo $LINES
  232
  74
After you do eval resize the variables are updated and vim will use the full xterm size. That's all.

Jon Dowland: sorting out backups

I'm busy re-working how I handle backups of my personal files. A very useful recent discussion on some available features and technologies is at Theodore T'so's blog: http://thunk.org/tytso/blog/2009/01/12/wanted-incremental-backup-solutions-that-use-a-database/. From that post I discovered a package 'archfs' which provides a FUSE-powered filesystem view of an rdiff-backup history. I found a stale ITP for this package and have adopted it, so keep your eyes out for that. Looking at how I am going to approach things, I think the Debian package of anacron might need some work. I'm planning on looking at the issues there a bit more closely and feeding back to the maintainer when I do.

Wouter Verhelst: DVswitch tally lights

So you do computer stuff for work, and what do you do in the weekend? Right, more computer stuff. Not that I dislike it, obviously. But, well. The computer stuff that I did this weekend was situated mainly around dvswitch. During their talk at the Debian devroom at FOSDEM, Ben and Holger mentioned that one of the things they'd still like to see implemented in DVswitch is the ability to do tally lights. Such lights are useful, not only for the benefit of those in front of the camera, but also for the benefit of those behind the camera allowing them to know when they're free to roam about in order to find something interesting to show, or when they should keep the camera somewhat stead because they're live. Since I was planning on using dvswitch to record the concert (dutch only) of the choir group that I'm part of, and since a concert has different requirements than does a talk, I set about implementing tally light functionality. For now, the actual tally light is just a laptop screen which turns red when you're live, or green when you're not but there's nothing stopping anyone from changing that into, say, a USB-controlled light or some such. In any case, it works now. It's not entirely pretty (involving two processes working with the same socket) and not entirely finished yet, either (it only works for primary sources, not secondary sources), but it gets the job done. It did require me to refresh knowledge that I hadn't used in literally 10 years, however. I had some C++ at school, but haven't used it since my final exam on that course, and while the code is still readable, it did require me to refresh my memory at some levels. Oh my... Anyway, that was yesterday, for the most part. Today, a friend came over with a DV camera (since I don't have any), and we ran some tests. Most of it worked immediately, but there were a few bugs, which I ironed out today. Right now, it works correctly the parts that are implemented, at least. This video stuff is rather fun to play with.

Marco d'Itri: The files in /etc/modprobe.d/

The module-init-tools upstream maintainers decided that in the future the files in /etc/modprobe.d/ will be processed only if they have a .conf suffix. The latest module-init-tool release complains loudly for each one and still processes them, but this will change.

Please update your packages and remember that the files in this directory are opened and parsed every time modprobe is run (and it is run very often at boot time!), so try to look at the big picture and install a file there only if it is really needed. Do not install a file if it only contains comments, if it is only useful for some unusual environment or if it not needed by the kernel currently in the archive (nowadays most drivers have their own aliases built in, check /lib/modules/$KVER/modules.alias and submit a kernel patch if they are missing).

2 March 2009

Ingo Juergensmann: HowTo: Migrate RAID1 to RAID5

As I wrote last week (German), I had the plan to make a RAID5 out of my existing RAID1 after I received my third 1 TB harddisk. Migrating to RAID5 doesn't work online yet, because mdadm doesn't support the use of --grow and --level together, as you can read in the man page when looking for "-l, --level":


-l, --level=
Set raid level. When used with --create, options are: linear, raid0, 0, stripe, raid1, 1, mirror, raid4,
4, raid5, 5, raid6, 6, raid10, 10, multipath, mp, faulty. Obviously some of these are synonymous.

When used with --build, only linear, stripe, raid0, 0, raid1, multipath, mp, and faulty are valid.

Not yet supported with --grow.


But there's always a way to obtain your goal. If you're brave enough you can find the solution by a quick internet search. Ok, I'm not that brave to try this without a backup, but you shouldn't do that kind of work without having a good backup anyway.

But before I describe the way how to do it, as usual a strong disclaimer: use this howto on your own risk! There's no warranty that this will work for you and you should take care to have a backup of your data. Whoever is doing this migration without having a backup risks the loss of all the data!

I'll describe the migration using an example... there are three logical volumes (LVs) with 1 GB in size each. This is enough for testing purposes and demonstrates how the migration works. You can use real partitions like swap partitions if you want. The LVs are r1, r2, and r3 and are within the Volume Group (VG) /dev/vg:


r1 vg -wi-a- 1.00G
r2 vg -wi-a- 1.00G
r3 vg -wi-a- 1.00G


Two of these LVs are being setup for a RAID1 /dev/md5:

CODE:
muaddib:/home/ij# mdadm --create /dev/md5 -l 1 -n 2 /dev/vg/r[12]
mdadm: /dev/vg/r1 appears to be part of a raid array:
level=raid1 devices=2 ctime=Thu Feb 26 16:16:59 2009
mdadm: /dev/vg/r2 appears to be part of a raid array:
level=raid1 devices=2 ctime=Thu Feb 26 16:16:59 2009
Continue creating array? yes
mdadm: array /dev/md5 started.


The warning to be a part of another raid array can be ignored. It's just a testing array. The result should look similar to:


md5 : active raid1 dm-12[1] dm-11[0]
1048512 blocks [2/2] [UU]
[========>............] resync = 40.2% (422900/1048512) finish=0.7min speed=14096K/sec


Now a filesystem can be created on the raid array and some data can be stored there:

CODE:
muaddib:/home/ij# mkfs.xfs -f /dev/md5
meta-data=/dev/md5 isize=256 agcount=4, agsize=65532 blks
= sectsz=512 attr=2
data = bsize=4096 blocks=262128, imaxpct=25
= sunit=0 swidth=0 blks
naming =version 2 bsize=4096 ascii-ci=0
log =internal log bsize=4096 blocks=1200, version=2
= sectsz=512 sunit=0 blks, lazy-count=0
realtime =none extsz=4096 blocks=0, rtextents=0
muaddib:/home/ij# mount /dev/md5 /mnt
muaddib:/home/ij# cp pics/backdrops/*.jpg /mnt/
muaddib:/home/ij# dir /mnt/
amigager_back1.jpg Dansk-Dunes14.jpg Dansk-Nature-2.jpg
CapeCod_085.jpg Dansk-Dunes15.jpg Dansk-Priel.jpg
ct-1-p1600.jpg Dansk-Dunes16.jpg Dansk-Woods-1.jpg
ct-2-p1600.jpg Dansk-Dunes17.jpg earth_lights_lrg.jpg
Dansk-Beach1.jpg Dansk-Dunes18.jpg HanseSail-AlterStrom2.jpg
Dansk-Beach2.jpg Dansk-Dunes2.jpg HanseSail-AlterStrom.jpg
Dansk-Beach3.jpg Dansk-Dunes3.jpg HanseSail-Mast.jpg
Dansk-Beach4.jpg Dansk-Dunes4.jpg HanseSail-Warnemuende.jpg
Dansk-Beach5.jpg Dansk-Dunes5.jpg LinuxInside_p1600.jpg
Dansk-Beachstones.jpg Dansk-Dunes6.jpg prerow.jpg
Dansk-Cliffs.jpg Dansk-Dunes7.jpg sgi-1440.jpg
Dansk-Dunes10.jpg Dansk-Dunes8.jpg sgi.jpg
Dansk-Dunes11.jpg Dansk-Dunes9.jpg Sonnenuntergang-2.jpg
Dansk-Dunes12.jpg Dansk-Dunes.jpg Sonnenuntergang.jpg
Dansk-Dunes13.jpg Dansk-Nature-1.jpg
muaddib:/home/ij# umount /mnt


After umounting the real challenge arise: creation of a RAID5 label! Normally this is no issue, but I guess you like your data and think twice before proceeding... but hey! You have a backup anyway, don't you?!

CODE:
muaddib:/home/ij# mdadm --create /dev/md5 --level=5 --raid-devices=2 /dev/vg/r[12]
mdadm: /dev/vg/r1 appears to be part of a raid array:
level=raid1 devices=2 ctime=Mon Mar 2 18:18:09 2009
mdadm: /dev/vg/r2 appears to be part of a raid array:
level=raid1 devices=2 ctime=Mon Mar 2 18:18:09 2009
Continue creating array? yes
mdadm: array /dev/md5 started.
muaddib:/home/ij# cat /proc/mdstat
md5 : active (auto-read-only) raid5 dm-12[2](S) dm-11[0]
1048512 blocks level 5, 64k chunk, algorithm 2 [2/1] [U_]
muaddib:/home/ij# cat /proc/mdstat
Personalities : [linear] [multipath] [raid0] [raid1] [raid6] [raid5] [raid4] [raid10]
md5 : active raid5 dm-12[2] dm-11[0]
1048512 blocks level 5, 64k chunk, algorithm 2 [2/1] [U_]
[>....................] recovery = 3.1% (33152/1048512) finish=0.5min speed=33152K/sec


After stopping /dev/md5 the new RAID5 label can be written. The data ought to be safe because of the RAID5 algorithm when running with 2 disks. To verify the theory you can mount /dev/md5 again. The next steps can be done with the array online.


muaddib:/home/ij# mount /dev/md5 /mnt
muaddib:/home/ij# dir /mnt/
amigager_back1.jpg Dansk-Dunes14.jpg Dansk-Nature-2.jpg
CapeCod_085.jpg Dansk-Dunes15.jpg Dansk-Priel.jpg
ct-1-p1600.jpg Dansk-Dunes16.jpg Dansk-Woods-1.jpg
ct-2-p1600.jpg Dansk-Dunes17.jpg earth_lights_lrg.jpg
Dansk-Beach1.jpg Dansk-Dunes18.jpg HanseSail-AlterStrom2.jpg
Dansk-Beach2.jpg Dansk-Dunes2.jpg HanseSail-AlterStrom.jpg
Dansk-Beach3.jpg Dansk-Dunes3.jpg HanseSail-Mast.jpg
Dansk-Beach4.jpg Dansk-Dunes4.jpg HanseSail-Warnemuende.jpg
Dansk-Beach5.jpg Dansk-Dunes5.jpg LinuxInside_p1600.jpg
Dansk-Beachstones.jpg Dansk-Dunes6.jpg prerow.jpg
Dansk-Cliffs.jpg Dansk-Dunes7.jpg sgi-1440.jpg
Dansk-Dunes10.jpg Dansk-Dunes8.jpg sgi.jpg
Dansk-Dunes11.jpg Dansk-Dunes9.jpg Sonnenuntergang-2.jpg
Dansk-Dunes12.jpg Dansk-Dunes.jpg Sonnenuntergang.jpg
Dansk-Dunes13.jpg Dansk-Nature-1.jpg


The next step is to add the third "disk":

CODE:
muaddib:/home/ij# mdadm --add /dev/md5 /dev/vg/r3
mdadm: added /dev/vg/r3
muaddib:/home/ij# cat /proc/mdstat
md5 : active raid5 dm-13[2](S) dm-12[1] dm-11[0]
1048512 blocks level 5, 64k chunk, algorithm 2 [2/2] [UU]


That was the first step. As you can see the third "disk" has been added as a spare device. Because we don't want a spare but a RAID5 we need to expand the number of disks to 3 and tell the RAID to grow it's capacity:

CODE:
muaddib:/home/ij# mdadm --grow /dev/md5 --raid-devices=3
mdadm: Need to backup 128K of critical section..
mdadm: ... critical section passed.
muaddib:/home/ij# cat /proc/mdstat
Personalities : [linear] [multipath] [raid0] [raid1] [raid6] [raid5] [raid4] [raid10]
md5 : active raid5 dm-13[2] dm-12[1] dm-11[0]
1048512 blocks super 0.91 level 5, 64k chunk, algorithm 2 [3/3] [UUU]
[>....................] reshape = 3.1% (33472/1048512) finish=3.0min speed=5578K/sec


The last two commands were made with the mounted filesystem that just needs to get enlarged. With XFS you make this happen by invoking xfs_growfs:

CODE:
muaddib:/home/ij# df -h /mnt
Filesystem Size Used Avail Use% Mounted on
/dev/md5 1020M 21M 1000M 2% /mnt
muaddib:/home/ij# xfs_growfs /mnt
meta-data=/dev/md5 isize=256 agcount=4, agsize=65532 blks
= sectsz=512 attr=2
data = bsize=4096 blocks=262128, imaxpct=25
= sunit=0 swidth=0 blks
naming =version 2 bsize=4096 ascii-ci=0
log =internal bsize=4096 blocks=1200, version=2
= sectsz=512 sunit=0 blks, lazy-count=0
realtime =none extsz=4096 blocks=0, rtextents=0
data blocks changed from 262128 to 524256
muaddib:/home/ij# df -h /mnt
Filesystem Size Used Avail Use% Mounted on
/dev/md5 2.0G 21M 2.0G 1% /mnt


Done!

If you have an LVM on your RAID you'll need to use the appropriate LVM tools to enlarge the PVs and VGs as well. But the hardest work is already done. The reshaping can take a lot of time, as you can see here:


md4 : active raid5 sda6[0] sdc6[2] sdb6[1]
969161152 blocks super 0.91 level 5, 64k chunk, algorithm 2 [3/3] [UUU]
[>....................] reshape = 2.8% (27990592/969161152) finish=1485.0min speed=10562K/sec


There might be other fallpits if you change your setup from 2-disk arrays to 3-disk arrays. For example you'll need to adopt the changes to your configuration files like /etc/mdadm/mdadm.conf. But this has not much to do with the migration from RAID1 to RAID5 itself.

Many thanks to Goswin Brederlow for his advice and writing a wishlist bug: #517731

Julian Andres Klode: debian-cd, dependencies, debimg, comments


Looking at the amd64 CD images of Lenny, I just saw that there is the package gnome on disk 1, while some of its dependencies are on disk 2. I don t think that this is good. Same also applies to K3B on disk 3, and openoffice.org-kde on KDE-disk 1. In my opinion, all packages which are located on a disk X, should only depend on a disk N (N<X). This means that the package gnome would be moved to disk 2, or its dependencies to disk 1. This is exactly the way debimg works. Debimg uses so-called package groups, which simply represents a set of packages with cyclic dependencies. These package groups are returned in a specific order, so that a group N only requires a group <N. This order is kept when the groups are added to the disk. Furthermore, we treat the groups as one when adding them to the disk, ie. we check whether the whole group fits on the disk (and add it) or not (create a new disk). This way, we ensure that all dependencies can be satisfied. Today, I decided to try it out and therefore wrote a small script reading the debian-cd task files and comparing the file list (of the packages added to the disk) with the file list of the official KDE disk. The results look very good, debimg adds 11 packages and removes 26 which is not that much, and mostly caused by wrong size limits, etc. You can look at the results your self, and regenerate them using: Anyway, debimg still needs real configuration and handling of the debian installer and source packages, but this should give you an idea of how debimg works. And a tarball, for those who don t want to use git all the time. BTW, I have now enabled comment threading here, a new WordPress feature. I hope that it works, as I have not tried it out yet. Posted in Debian, debimg

Next.

Previous.