Search Results: "ema"

14 December 2023

Russell Coker: Fat Finger Shell

I ve been trying out the Fat Finger Shell which is a terminal emulator for Linux on touch screen devices where the keyboard is overlayed with the terminal output. This means that instead of having a tiny keyboard and a tiny terminal output you have the full screen for both. There is a YouTube video showing how the Fat Finger Shell works [1]. Here is a link to the Github page [2], which hasn t changed much in the last 11 years. Currently the shell is hard-coded to a 80*24 terminal and a 640*480 screen which doesn t match any modern hardware. Some parts of this are easy to change but then there s the comment I ran once XGetGeometry and I am harcoded (bad) values for x, y, etc.. which is followed by some magic numbers that are not easy to change which are hacked into the source of xvt. The configuration of this is almost great. It has a plain text file where each line has 4 numbers representing the X and Y coordinates of opposite corners of a rectangle and additional information on what the key is, which is relatively easy to edit. But then it has an image which has to match that, the obvious improvement would be to not have an image but to just display rectangles for each pair of corner coordinates and display the glyph of the character in question inside it. I think there is a real need for a terminal like this for use on devices like the PinePhonePro, it won t be to everyone s taste but the people who like it will really like it. The features that such a shell needs for modern use are being based on Wayland, supporting a variety of screen resolutions and particularly the commonly used ones like 720*1440 and 1920*1080 (with terminal resolution matching the combination of screen resolution and font), and having code derived from a newer terminal emulator. As a final note it would be good for such a terminal to also take input from a regular keyboard so when you plug your Linux phone into a dock you don t need to close your existing terminal sessions. There is a Debian RFP/ITP bug for this [3] which I think should be closed due to nothing happening for 11 years and the fact that so much work is required to make this usable. The current Fat Finger Shell code is a good demonstration of the concept, but I don t think it makes sense to move on with this code base. One of the many possible ways of addressing this with modern graphics technology might be to have a semi transparent window overlaying the screen and generating virtual keyboard events for whichever window happens to be below it so instead of being limited to one terminal program by the choice of input method have that input work for any terminal that the user may choose as well as any other text based program (email, IM, etc).

13 December 2023

Jonathan Dowland: equivalence problems with StreamGraph

I've been tackling an equivalence problem with rewritten programs in StrIoT, our proof-of-concept stream-processing system. The StrIoT Logical Optimiser applies a set of rewrite rules to a stream-processing program, generating a set of variants that can be reasoned about, ranked, and deployed. The problem I've been tackling is that a variant may appear to be semantically equivalent to another, but compare (with ==) as distinct. The issue relates to the design of our data-type representing programs, in particular, a consequence of our choice to outsource the structural aspect to a 3rd-party library (Algebra.Graph). The Graph library deems nodes that compare as equivalent (again with ==) to be the same. Since a stream-processing program may contain many operators which are equivalent, but distinct, we needed to add a field to our payload type to differentiate them: so we opted for an Integer field, vertexId (something I've described as a "wart" elsewhere) Here's a simplified example of our existing payload type, StreamVertex:
data StreamVertex = StreamVertex
      vertexId   :: Int
    , operator   :: StreamOperator
    , parameters :: [ExpQ]
    , intype     :: String
    , outtype    :: String
     
A rewrite rule might introduce or eliminate operators from a stream-processing program. For example, consider the rule which "hoists" a filter upstream from a merge operator. In pseudo-Haskell,
streamFilter p . streamMerge [a , b, ...]
=>
streamMerge [ streamFilter p a
            , streamFilter p b
            , ...]
The original streamFilter is removed, and new streamFilters are introduced, one per stream arriving at streamMerge. In general, rules may need to synthesise new operators, and thus new vertexIds. Another rewrite rule might perform the reverse operation. But the individual rules operate in isolation: and so, the program variant that results after applying a rule and then applying an inverse rule may not have the same vertexIds, or the same order of vertexIds, as the original program. I thought of the outline of two possible solutions to this. "well-numbered" StreamGraphs The first was to encode (and enforce) some rules about how vertexIds are used. If they always began from (say) 1, and were strictly-ascending from the source operator(s), and rewrite rules guaranteed that a "well numbered" input would be "well numbered" after rewriting, this would be sufficient to rule out a rewritten-but-semantically-equivalent program being considered distinct. The trouble with this approach is using properties of a numerical system built around vertexId as a stand-in for the real structural problem. I was not sure I could prove both that the stand-in system was sound and that it was a proper analogue for the underlying structural issue. It feels to me more that the choice to use an external library to encode the structure of a stream-processing program was the issue: the structure itself is a fundamental part of the semantics of the program. What if we had encoded the structure of programs within the same data-type? alternative data-type StrIoT programs are trees. The root is the sink node: there is always exactly one. There can be multiple source (leaf nodes), but they always converge. Operators can have multiple inputs (including zero). The root node has no output, but all other operators have exactly one. I explored transforming StreamVertex into a tree by adding a field representing incoming streams, and dispensing with Graph and vertexId. Something like this
data StreamProg = StreamProg StreamOperator [Exp] String String [StreamProg]
A uni-directional transformation from Graph StreamVertex to StreamProg is all that's needed to implement something like ==, so we don't need to keep track of vertexId mappings. Unfortunately, we can't fix the actual Eq (Graph StreamVertex) implementation this way: it delegates to Eq StreamVertex, and we just don't have enough information to fix the problem at that level. But, we can write a separate graphEq and use that instead where we need to. could I go further? Spoiler: I haven't. But I've been sorely tempted. We still have a separate StreamOperator type, which it would be nice to fold in; and we still have to use a list around the incoming nodes, since different operators accept different numbers of incoming streams. It would be better to encode the correct valences in the type. In 2020 I explored iteratively reducing the StreamVertex data-type to try and get it as close as possible to the ideal end-user API: simple functions. I wrote about one step along that path in Template Haskell and Stream-processing programs, but concluded that, since this was not my main PhD focus, I wouldn't go further. But it was nagging at my subconcious ever since. I allowed myself a couple of days exploring some advanced concepts including typed Template Haskell (that has had some developments since 2020), generalised abstract data types (GADTs) and more generic programming to see what could be achieved. I'll summarise all that in the next blog post.

Melissa Wen: 15 Tips for Debugging Issues in the AMD Display Kernel Driver

A self-help guide for examining and debugging the AMD display driver within the Linux kernel/DRM subsystem. It s based on my experience as an external developer working on the driver, and are shared with the goal of helping others navigate the driver code. Acknowledgments: These tips were gathered thanks to the countless help received from AMD developers during the driver development process. The list below was obtained by examining open source code, reviewing public documentation, playing with tools, asking in public forums and also with the help of my former GSoC mentor, Rodrigo Siqueira.

Pre-Debugging Steps: Before diving into an issue, it s crucial to perform two essential steps: 1) Check the latest changes: Ensure you re working with the latest AMD driver modifications located in the amd-staging-drm-next branch maintained by Alex Deucher. You may also find bug fixes for newer kernel versions on branches that have the name pattern drm-fixes-<date>. 2) Examine the issue tracker: Confirm that your issue isn t already documented and addressed in the AMD display driver issue tracker. If you find a similar issue, you can team up with others and speed up the debugging process.

Understanding the issue: Do you really need to change this? Where should you start looking for changes? 3) Is the issue in the AMD kernel driver or in the userspace?: Identifying the source of the issue is essential regardless of the GPU vendor. Sometimes this can be challenging so here are some helpful tips:
  • Record the screen: Capture the screen using a recording app while experiencing the issue. If the bug appears in the capture, it s likely a userspace issue, not the kernel display driver.
  • Analyze the dmesg log: Look for error messages related to the display driver in the dmesg log. If the error message appears before the message [drm] Display Core v... , it s not likely a display driver issue. If this message doesn t appear in your log, the display driver wasn t fully loaded and you will see a notification that something went wrong here.
4) AMD Display Manager vs. AMD Display Core: The AMD display driver consists of two components:
  • Display Manager (DM): This component interacts directly with the Linux DRM infrastructure. Occasionally, issues can arise from misinterpretations of DRM properties or features. If the issue doesn t occur on other platforms with the same AMD hardware - for example, only happens on Linux but not on Windows - it s more likely related to the AMD DM code.
  • Display Core (DC): This is the platform-agnostic part responsible for setting and programming hardware features. Modifications to the DC usually require validation on other platforms, like Windows, to avoid regressions.
5) Identify the DC HW family: Each AMD GPU has variations in its hardware architecture. Features and helpers differ between families, so determining the relevant code for your specific hardware is crucial.
  • Find GPU product information in Linux/AMD GPU documentation
  • Check the dmesg log for the Display Core version (since this commit in Linux kernel 6.3v). For example:
    • [drm] Display Core v3.2.241 initialized on DCN 2.1
    • [drm] Display Core v3.2.237 initialized on DCN 3.0.1

Investigating the relevant driver code: Keep from letting unrelated driver code to affect your investigation. 6) Narrow the code inspection down to one DC HW family: the relevant code resides in a directory named after the DC number. For example, the DCN 3.0.1 driver code is located at drivers/gpu/drm/amd/display/dc/dcn301. We all know that the AMD s shared code is huge and you can use these boundaries to rule out codes unrelated to your issue. 7) Newer families may inherit code from older ones: you can find dcn301 using code from dcn30, dcn20, dcn10 files. It s crucial to verify which hooks and helpers your driver utilizes to investigate the right portion. You can leverage ftrace for supplemental validation. To give an example, it was useful when I was updating DCN3 color mapping to correctly use their new post-blending color capabilities, such as: Additionally, you can use two different HW families to compare behaviours. If you see the issue in one but not in the other, you can compare the code and understand what has changed and if the implementation from a previous family doesn t fit well the new HW resources or design. You can also count on the help of the community on the Linux AMD issue tracker to validate your code on other hardware and/or systems. This approach helped me debug a 2-year-old issue where the cursor gamma adjustment was incorrect in DCN3 hardware, but working correctly for DCN2 family. I solved the issue in two steps, thanks for community feedback and validation: 8) Check the hardware capability screening in the driver: You can currently find a list of display hardware capabilities in the drivers/gpu/drm/amd/display/dc/dcn*/dcn*_resource.c file. More precisely in the dcn*_resource_construct() function. Using DCN301 for illustration, here is the list of its hardware caps:
	/*************************************************
	 *  Resource + asic cap harcoding                *
	 *************************************************/
	pool->base.underlay_pipe_index = NO_UNDERLAY_PIPE;
	pool->base.pipe_count = pool->base.res_cap->num_timing_generator;
	pool->base.mpcc_count = pool->base.res_cap->num_timing_generator;
	dc->caps.max_downscale_ratio = 600;
	dc->caps.i2c_speed_in_khz = 100;
	dc->caps.i2c_speed_in_khz_hdcp = 5; /*1.4 w/a enabled by default*/
	dc->caps.max_cursor_size = 256;
	dc->caps.min_horizontal_blanking_period = 80;
	dc->caps.dmdata_alloc_size = 2048;
	dc->caps.max_slave_planes = 2;
	dc->caps.max_slave_yuv_planes = 2;
	dc->caps.max_slave_rgb_planes = 2;
	dc->caps.is_apu = true;
	dc->caps.post_blend_color_processing = true;
	dc->caps.force_dp_tps4_for_cp2520 = true;
	dc->caps.extended_aux_timeout_support = true;
	dc->caps.dmcub_support = true;
	/* Color pipeline capabilities */
	dc->caps.color.dpp.dcn_arch = 1;
	dc->caps.color.dpp.input_lut_shared = 0;
	dc->caps.color.dpp.icsc = 1;
	dc->caps.color.dpp.dgam_ram = 0; // must use gamma_corr
	dc->caps.color.dpp.dgam_rom_caps.srgb = 1;
	dc->caps.color.dpp.dgam_rom_caps.bt2020 = 1;
	dc->caps.color.dpp.dgam_rom_caps.gamma2_2 = 1;
	dc->caps.color.dpp.dgam_rom_caps.pq = 1;
	dc->caps.color.dpp.dgam_rom_caps.hlg = 1;
	dc->caps.color.dpp.post_csc = 1;
	dc->caps.color.dpp.gamma_corr = 1;
	dc->caps.color.dpp.dgam_rom_for_yuv = 0;
	dc->caps.color.dpp.hw_3d_lut = 1;
	dc->caps.color.dpp.ogam_ram = 1;
	// no OGAM ROM on DCN301
	dc->caps.color.dpp.ogam_rom_caps.srgb = 0;
	dc->caps.color.dpp.ogam_rom_caps.bt2020 = 0;
	dc->caps.color.dpp.ogam_rom_caps.gamma2_2 = 0;
	dc->caps.color.dpp.ogam_rom_caps.pq = 0;
	dc->caps.color.dpp.ogam_rom_caps.hlg = 0;
	dc->caps.color.dpp.ocsc = 0;
	dc->caps.color.mpc.gamut_remap = 1;
	dc->caps.color.mpc.num_3dluts = pool->base.res_cap->num_mpc_3dlut; //2
	dc->caps.color.mpc.ogam_ram = 1;
	dc->caps.color.mpc.ogam_rom_caps.srgb = 0;
	dc->caps.color.mpc.ogam_rom_caps.bt2020 = 0;
	dc->caps.color.mpc.ogam_rom_caps.gamma2_2 = 0;
	dc->caps.color.mpc.ogam_rom_caps.pq = 0;
	dc->caps.color.mpc.ogam_rom_caps.hlg = 0;
	dc->caps.color.mpc.ocsc = 1;
	dc->caps.dp_hdmi21_pcon_support = true;
	/* read VBIOS LTTPR caps */
	if (ctx->dc_bios->funcs->get_lttpr_caps)  
		enum bp_result bp_query_result;
		uint8_t is_vbios_lttpr_enable = 0;
		bp_query_result = ctx->dc_bios->funcs->get_lttpr_caps(ctx->dc_bios, &is_vbios_lttpr_enable);
		dc->caps.vbios_lttpr_enable = (bp_query_result == BP_RESULT_OK) && !!is_vbios_lttpr_enable;
	 
	if (ctx->dc_bios->funcs->get_lttpr_interop)  
		enum bp_result bp_query_result;
		uint8_t is_vbios_interop_enabled = 0;
		bp_query_result = ctx->dc_bios->funcs->get_lttpr_interop(ctx->dc_bios, &is_vbios_interop_enabled);
		dc->caps.vbios_lttpr_aware = (bp_query_result == BP_RESULT_OK) && !!is_vbios_interop_enabled;
	 
Keep in mind that the documentation of color capabilities are available at the Linux kernel Documentation.

Understanding the development history: What has brought us to the current state? 9) Pinpoint relevant commits: Use git log and git blame to identify commits targeting the code section you re interested in. 10) Track regressions: If you re examining the amd-staging-drm-next branch, check for regressions between DC release versions. These are defined by DC_VER in the drivers/gpu/drm/amd/display/dc/dc.h file. Alternatively, find a commit with this format drm/amd/display: 3.2.221 that determines a display release. It s useful for bisecting. This information helps you understand how outdated your branch is and identify potential regressions. You can consider each DC_VER takes around one week to be bumped. Finally, check testing log of each release in the report provided on the amd-gfx mailing list, such as this one Tested-by: Daniel Wheeler:

Reducing the inspection area: Focus on what really matters. 11) Identify involved HW blocks: This helps isolate the issue. You can find more information about DCN HW blocks in the DCN Overview documentation. In summary:
  • Plane issues are closer to HUBP and DPP.
  • Blending/Stream issues are closer to MPC, OPP and OPTC. They are related to DRM CRTC subjects.
This information was useful when debugging a hardware rotation issue where the cursor plane got clipped off in the middle of the screen. Finally, the issue was addressed by two patches: 12) Issues around bandwidth (glitches) and clocks: May be affected by calculations done in these HW blocks and HW specific values. The recalculation equations are found in the DML folder. DML stands for Display Mode Library. It s in charge of all required configuration parameters supported by the hardware for multiple scenarios. See more in the AMD DC Overview kernel docs. It s a math library that optimally configures hardware to find the best balance between power efficiency and performance in a given scenario. Finding some clk variables that affect device behavior may be a sign of it. It s hard for a external developer to debug this part, since it involves information from HW specs and firmware programming that we don t have access. The best option is to provide all relevant debugging information you have and ask AMD developers to check the values from your suspicions.
  • Do a trick: If you suspect the power setup is degrading performance, try setting the amount of power supplied to the GPU to the maximum and see if it affects the system behavior with this command: sudo bash -c "echo high > /sys/class/drm/card0/device/power_dpm_force_performance_level"
I learned it when debugging glitches with hardware cursor rotation on Steam Deck. My first attempt was changing the clock calculation. In the end, Rodrigo Siqueira proposed the right solution targeting bandwidth in two steps:

Checking implicit programming and hardware limitations: Bring implicit programming to the level of consciousness and recognize hardware limitations. 13) Implicit update types: Check if the selected type for atomic update may affect your issue. The update type depends on the mode settings, since programming some modes demands more time for hardware processing. More details in the source code:
/* Surface update type is used by dc_update_surfaces_and_stream
 * The update type is determined at the very beginning of the function based
 * on parameters passed in and decides how much programming (or updating) is
 * going to be done during the call.
 *
 * UPDATE_TYPE_FAST is used for really fast updates that do not require much
 * logical calculations or hardware register programming. This update MUST be
 * ISR safe on windows. Currently fast update will only be used to flip surface
 * address.
 *
 * UPDATE_TYPE_MED is used for slower updates which require significant hw
 * re-programming however do not affect bandwidth consumption or clock
 * requirements. At present, this is the level at which front end updates
 * that do not require us to run bw_calcs happen. These are in/out transfer func
 * updates, viewport offset changes, recout size changes and pixel
depth changes.
 * This update can be done at ISR, but we want to minimize how often
this happens.
 *
 * UPDATE_TYPE_FULL is slow. Really slow. This requires us to recalculate our
 * bandwidth and clocks, possibly rearrange some pipes and reprogram
anything front
 * end related. Any time viewport dimensions, recout dimensions,
scaling ratios or
 * gamma need to be adjusted or pipe needs to be turned on (or
disconnected) we do
 * a full update. This cannot be done at ISR level and should be a rare event.
 * Unless someone is stress testing mpo enter/exit, playing with
colour or adjusting
 * underscan we don't expect to see this call at all.
 */
enum surface_update_type  
UPDATE_TYPE_FAST, /* super fast, safe to execute in isr */
UPDATE_TYPE_MED,  /* ISR safe, most of programming needed, no bw/clk change*/
UPDATE_TYPE_FULL, /* may need to shuffle resources */
 ;

Using tools: Observe the current state, validate your findings, continue improvements. 14) Use AMD tools to check hardware state and driver programming: help on understanding your driver settings and checking the behavior when changing those settings.
  • DC Visual confirmation: Check multiple planes and pipe split policy.
  • DTN logs: Check display hardware state, including rotation, size, format, underflow, blocks in use, color block values, etc.
  • UMR: Check ASIC info, register values, KMS state - links and elements (framebuffers, planes, CRTCs, connectors). Source: UMR project documentation
15) Use generic DRM/KMS tools:
  • IGT test tools: Use generic KMS tests or develop your own to isolate the issue in the kernel space. Compare results across different GPU vendors to understand their implementations and find potential solutions. Here AMD also has specific IGT tests for its GPUs that is expect to work without failures on any AMD GPU. You can check results of HW-specific tests using different display hardware families or you can compare expected differences between the generic workflow and AMD workflow.
  • drm_info: This tool summarizes the current state of a display driver (capabilities, properties and formats) per element of the DRM/KMS workflow. Output can be helpful when reporting bugs.

Don t give up! Debugging issues in the AMD display driver can be challenging, but by following these tips and leveraging available resources, you can significantly improve your chances of success. Worth mentioning: This blog post builds upon my talk, I m not an AMD expert, but presented at the 2022 XDC. It shares guidelines that helped me debug AMD display issues as an external developer of the driver. Open Source Display Driver: The Linux kernel/AMD display driver is open source, allowing you to actively contribute by addressing issues listed in the official tracker. Tackling existing issues or resolving your own can be a rewarding learning experience and a valuable contribution to the community. Additionally, the tracker serves as a valuable resource for finding similar bugs, troubleshooting tips, and suggestions from AMD developers. Finally, it s a platform for seeking help when needed. Remember, contributing to the open source community through issue resolution and collaboration is mutually beneficial for everyone involved.

12 December 2023

Raju Devidas: Nextcloud AIO install with docker-compose and nginx reverse proxy

Nextcloud AIO install with docker-compose and nginx reverse proxyNextcloud is a popular self-hosted solution for file sync and share as well as cloud apps such as document editing, chat and talk, calendar, photo gallery etc. This guide will walk you through setting up Nextcloud AIO using Docker Compose. This blog post would not be possible without immense help from Sahil Dhiman a.k.a. sahilisterThere are various ways in which the installation could be done, in our setup here are the pre-requisites.
Step 1 : The docker-compose file for nextcloud AIOThe original compose.yml file is present in nextcloud AIO&aposs git repo here . By taking a reference of that file, we have own compose.yml here.
services:
  nextcloud-aio-mastercontainer:
    image: nextcloud/all-in-one:latest
    init: true
    restart: always
    container_name: nextcloud-aio-mastercontainer # This line is not allowed to be changed as otherwise AIO will not work correctly
    volumes:
      - nextcloud_aio_mastercontainer:/mnt/docker-aio-config # This line is not allowed to be changed as otherwise the built-in backup solution will not work
      - /var/run/docker.sock:/var/run/docker.sock:ro # May be changed on macOS, Windows or docker rootless. See the applicable documentation. If adjusting, don&apost forget to also set &aposWATCHTOWER_DOCKER_SOCKET_PATH&apos!
    ports:
      - 8080:8080
    environment: # Is needed when using any of the options below
      # - AIO_DISABLE_BACKUP_SECTION=false # Setting this to true allows to hide the backup section in the AIO interface. See https://github.com/nextcloud/all-in-one#how-to-disable-the-backup-section
      - APACHE_PORT=32323 # Is needed when running behind a web server or reverse proxy (like Apache, Nginx, Cloudflare Tunnel and else). See https://github.com/nextcloud/all-in-one/blob/main/reverse-proxy.md
      - APACHE_IP_BINDING=127.0.0.1 # Should be set when running behind a web server or reverse proxy (like Apache, Nginx, Cloudflare Tunnel and else) that is running on the same host. See https://github.com/nextcloud/all-in-one/blob/main/reverse-proxy.md
      # - BORG_RETENTION_POLICY=--keep-within=7d --keep-weekly=4 --keep-monthly=6 # Allows to adjust borgs retention policy. See https://github.com/nextcloud/all-in-one#how-to-adjust-borgs-retention-policy
      # - COLLABORA_SECCOMP_DISABLED=false # Setting this to true allows to disable Collabora&aposs Seccomp feature. See https://github.com/nextcloud/all-in-one#how-to-disable-collaboras-seccomp-feature
      - NEXTCLOUD_DATADIR=/opt/docker/cloud.raju.dev/nextcloud # Allows to set the host directory for Nextcloud&aposs datadir.   Warning: do not set or adjust this value after the initial Nextcloud installation is done! See https://github.com/nextcloud/all-in-one#how-to-change-the-default-location-of-nextclouds-datadir
      # - NEXTCLOUD_MOUNT=/mnt/ # Allows the Nextcloud container to access the chosen directory on the host. See https://github.com/nextcloud/all-in-one#how-to-allow-the-nextcloud-container-to-access-directories-on-the-host
      # - NEXTCLOUD_UPLOAD_LIMIT=10G # Can be adjusted if you need more. See https://github.com/nextcloud/all-in-one#how-to-adjust-the-upload-limit-for-nextcloud
      # - NEXTCLOUD_MAX_TIME=3600 # Can be adjusted if you need more. See https://github.com/nextcloud/all-in-one#how-to-adjust-the-max-execution-time-for-nextcloud
      # - NEXTCLOUD_MEMORY_LIMIT=512M # Can be adjusted if you need more. See https://github.com/nextcloud/all-in-one#how-to-adjust-the-php-memory-limit-for-nextcloud
      # - NEXTCLOUD_TRUSTED_CACERTS_DIR=/path/to/my/cacerts # CA certificates in this directory will be trusted by the OS of the nexcloud container (Useful e.g. for LDAPS) See See https://github.com/nextcloud/all-in-one#how-to-trust-user-defined-certification-authorities-ca
      # - NEXTCLOUD_STARTUP_APPS=deck twofactor_totp tasks calendar contacts notes # Allows to modify the Nextcloud apps that are installed on starting AIO the first time. See https://github.com/nextcloud/all-in-one#how-to-change-the-nextcloud-apps-that-are-installed-on-the-first-startup
      # - NEXTCLOUD_ADDITIONAL_APKS=imagemagick # This allows to add additional packages to the Nextcloud container permanently. Default is imagemagick but can be overwritten by modifying this value. See https://github.com/nextcloud/all-in-one#how-to-add-os-packages-permanently-to-the-nextcloud-container
      # - NEXTCLOUD_ADDITIONAL_PHP_EXTENSIONS=imagick # This allows to add additional php extensions to the Nextcloud container permanently. Default is imagick but can be overwritten by modifying this value. See https://github.com/nextcloud/all-in-one#how-to-add-php-extensions-permanently-to-the-nextcloud-container
      # - NEXTCLOUD_ENABLE_DRI_DEVICE=true # This allows to enable the /dev/dri device in the Nextcloud container.   Warning: this only works if the &apos/dev/dri&apos device is present on the host! If it should not exist on your host, don&apost set this to true as otherwise the Nextcloud container will fail to start! See https://github.com/nextcloud/all-in-one#how-to-enable-hardware-transcoding-for-nextcloud
      # - NEXTCLOUD_KEEP_DISABLED_APPS=false # Setting this to true will keep Nextcloud apps that are disabled in the AIO interface and not uninstall them if they should be installed. See https://github.com/nextcloud/all-in-one#how-to-keep-disabled-apps
      # - TALK_PORT=3478 # This allows to adjust the port that the talk container is using. See https://github.com/nextcloud/all-in-one#how-to-adjust-the-talk-port
      # - WATCHTOWER_DOCKER_SOCKET_PATH=/var/run/docker.sock # Needs to be specified if the docker socket on the host is not located in the default &apos/var/run/docker.sock&apos. Otherwise mastercontainer updates will fail. For macos it needs to be &apos/var/run/docker.sock&apos
    # networks: # Is needed when you want to create the nextcloud-aio network with ipv6-support using this file, see the network config at the bottom of the file
      # - nextcloud-aio # Is needed when you want to create the nextcloud-aio network with ipv6-support using this file, see the network config at the bottom of the file
      # - SKIP_DOMAIN_VALIDATION=true
    # # Uncomment the following line when using SELinux
    # security_opt: ["label:disable"]
volumes: # If you want to store the data on a different drive, see https://github.com/nextcloud/all-in-one#how-to-store-the-filesinstallation-on-a-separate-drive
  nextcloud_aio_mastercontainer:
    name: nextcloud_aio_mastercontainer # This line is not allowed to be changed as otherwise the built-in backup solution will not work
I have not removed many of the commented options in the compose file, for a possibility of me using them in the future.If you want a smaller cleaner compose with the extra options, you can refer to
services:
  nextcloud-aio-mastercontainer:
    image: nextcloud/all-in-one:latest
    init: true
    restart: always
    container_name: nextcloud-aio-mastercontainer
    volumes:
      - nextcloud_aio_mastercontainer:/mnt/docker-aio-config
      - /var/run/docker.sock:/var/run/docker.sock:ro
    ports:
      - 8080:8080
    environment:
      - APACHE_PORT=32323
      - APACHE_IP_BINDING=127.0.0.1
      - NEXTCLOUD_DATADIR=/opt/docker/nextcloud
volumes:
  nextcloud_aio_mastercontainer:
    name: nextcloud_aio_mastercontainer
I am using a separate directory to store nextcloud data. As per nextcloud documentation you should be using a separate partition if you want to use this feature, however I did not have that option on my server, so I used a separate directory instead. Also we use a custom port on which nextcloud listens for operations, we have set it up as 32323 above, but you can use any in the permissible port range. The 8080 port is used the setup the AIO management interface. Both 8080 and the APACHE_PORT do not need to be open on the host machine, as we will be using reverse proxy setup with nginx to direct requests. once you have your preferred compose.yml file, you can start the containers using
$ docker-compose -f compose.yml up -d 
Creating network "clouddev_default" with the default driver
Creating volume "nextcloud_aio_mastercontainer" with default driver
Creating nextcloud-aio-mastercontainer ... done
once your container&aposs are running, we can do the nginx setup.

Step 2: Configuring nginx reverse proxy for our domain on host. A reference nginx configuration for nextcloud AIO is given in the nextcloud git repository here . You can modify the configuration file according to your needs and setup. Here is configuration that we are using

map $http_upgrade $connection_upgrade  
    default upgrade;
    &apos&apos close;
 
server  
    listen 80;
    #listen [::]:80;            # comment to disable IPv6
    if ($scheme = "http")  
        return 301 https://$host$request_uri;
     
    listen 443 ssl http2;      # for nginx versions below v1.25.1
    #listen [::]:443 ssl http2; # for nginx versions below v1.25.1 - comment to disable IPv6
    # listen 443 ssl;      # for nginx v1.25.1+
    # listen [::]:443 ssl; # for nginx v1.25.1+ - keep comment to disable IPv6
    # http2 on;                                 # uncomment to enable HTTP/2        - supported on nginx v1.25.1+
    # http3 on;                                 # uncomment to enable HTTP/3 / QUIC - supported on nginx v1.25.0+
    # quic_retry on;                            # uncomment to enable HTTP/3 / QUIC - supported on nginx v1.25.0+
    # add_header Alt-Svc &aposh3=":443"; ma=86400&apos; # uncomment to enable HTTP/3 / QUIC - supported on nginx v1.25.0+
    # listen 443 quic reuseport;       # uncomment to enable HTTP/3 / QUIC - supported on nginx v1.25.0+ - please remove "reuseport" if there is already another quic listener on port 443 with enabled reuseport
    # listen [::]:443 quic reuseport;  # uncomment to enable HTTP/3 / QUIC - supported on nginx v1.25.0+ - please remove "reuseport" if there is already another quic listener on port 443 with enabled reuseport - keep comment to disable IPv6
    server_name cloud.example.com;
    location /  
        proxy_pass http://127.0.0.1:32323$request_uri;
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header X-Forwarded-Port $server_port;
        proxy_set_header X-Forwarded-Scheme $scheme;
        proxy_set_header X-Forwarded-Proto $scheme;
        proxy_set_header X-Real-IP $remote_addr;
        proxy_set_header Accept-Encoding "";
        proxy_set_header Host $host;
    
        client_body_buffer_size 512k;
        proxy_read_timeout 86400s;
        client_max_body_size 0;
        # Websocket
        proxy_http_version 1.1;
        proxy_set_header Upgrade $http_upgrade;
        proxy_set_header Connection $connection_upgrade;
     
    ssl_certificate /etc/letsencrypt/live/cloud.example.com/fullchain.pem; # managed by Certbot
    ssl_certificate_key /etc/letsencrypt/live/cloud.example.com/privkey.pem; # managed by Certbot
    ssl_session_timeout 1d;
    ssl_session_cache shared:MozSSL:10m; # about 40000 sessions
    ssl_session_tickets off;
    ssl_protocols TLSv1.2 TLSv1.3;
    ssl_ciphers ECDHE-ECDSA-AES128-GCM-SHA256:ECDHE-RSA-AES128-GCM-SHA256:ECDHE-ECDSA-AES256-GCM-SHA384:ECDHE-RSA-AES256-GCM-SHA384:ECDHE-ECDSA-CHACHA20-POLY1305:ECDHE-RSA-CHACHA20-POLY1305:DHE-RSA-AES128-GCM-SHA256:DHE-RSA-AES256-GCM-SHA384:DHE-RSA-CHACHA20-POLY1305;
    ssl_prefer_server_ciphers on;
    # Optional settings:
    # OCSP stapling
    # ssl_stapling on;
    # ssl_stapling_verify on;
    # ssl_trusted_certificate /etc/letsencrypt/live/<your-nc-domain>/chain.pem;
    # replace with the IP address of your resolver
    # resolver 127.0.0.1; # needed for oscp stapling: e.g. use 94.140.15.15 for adguard / 1.1.1.1 for cloudflared or 8.8.8.8 for google - you can use the same nameserver as listed in your /etc/resolv.conf file
 
Please note that you need to have valid SSL certificates for your domain for this configuration to work. Steps on getting valid SSL certificates for your domain are beyond the scope of this article. You can give a web search on getting SSL certificates with letsencrypt and you will get several resources on that, or may write a blog post on it separately in the future.once your configuration for nginx is done, you can test the nginx configuration using
$ sudo nginx -t 
nginx: the configuration file /etc/nginx/nginx.conf syntax is ok
nginx: configuration file /etc/nginx/nginx.conf test is successful
and then reload nginx with
$ sudo nginx -s reload

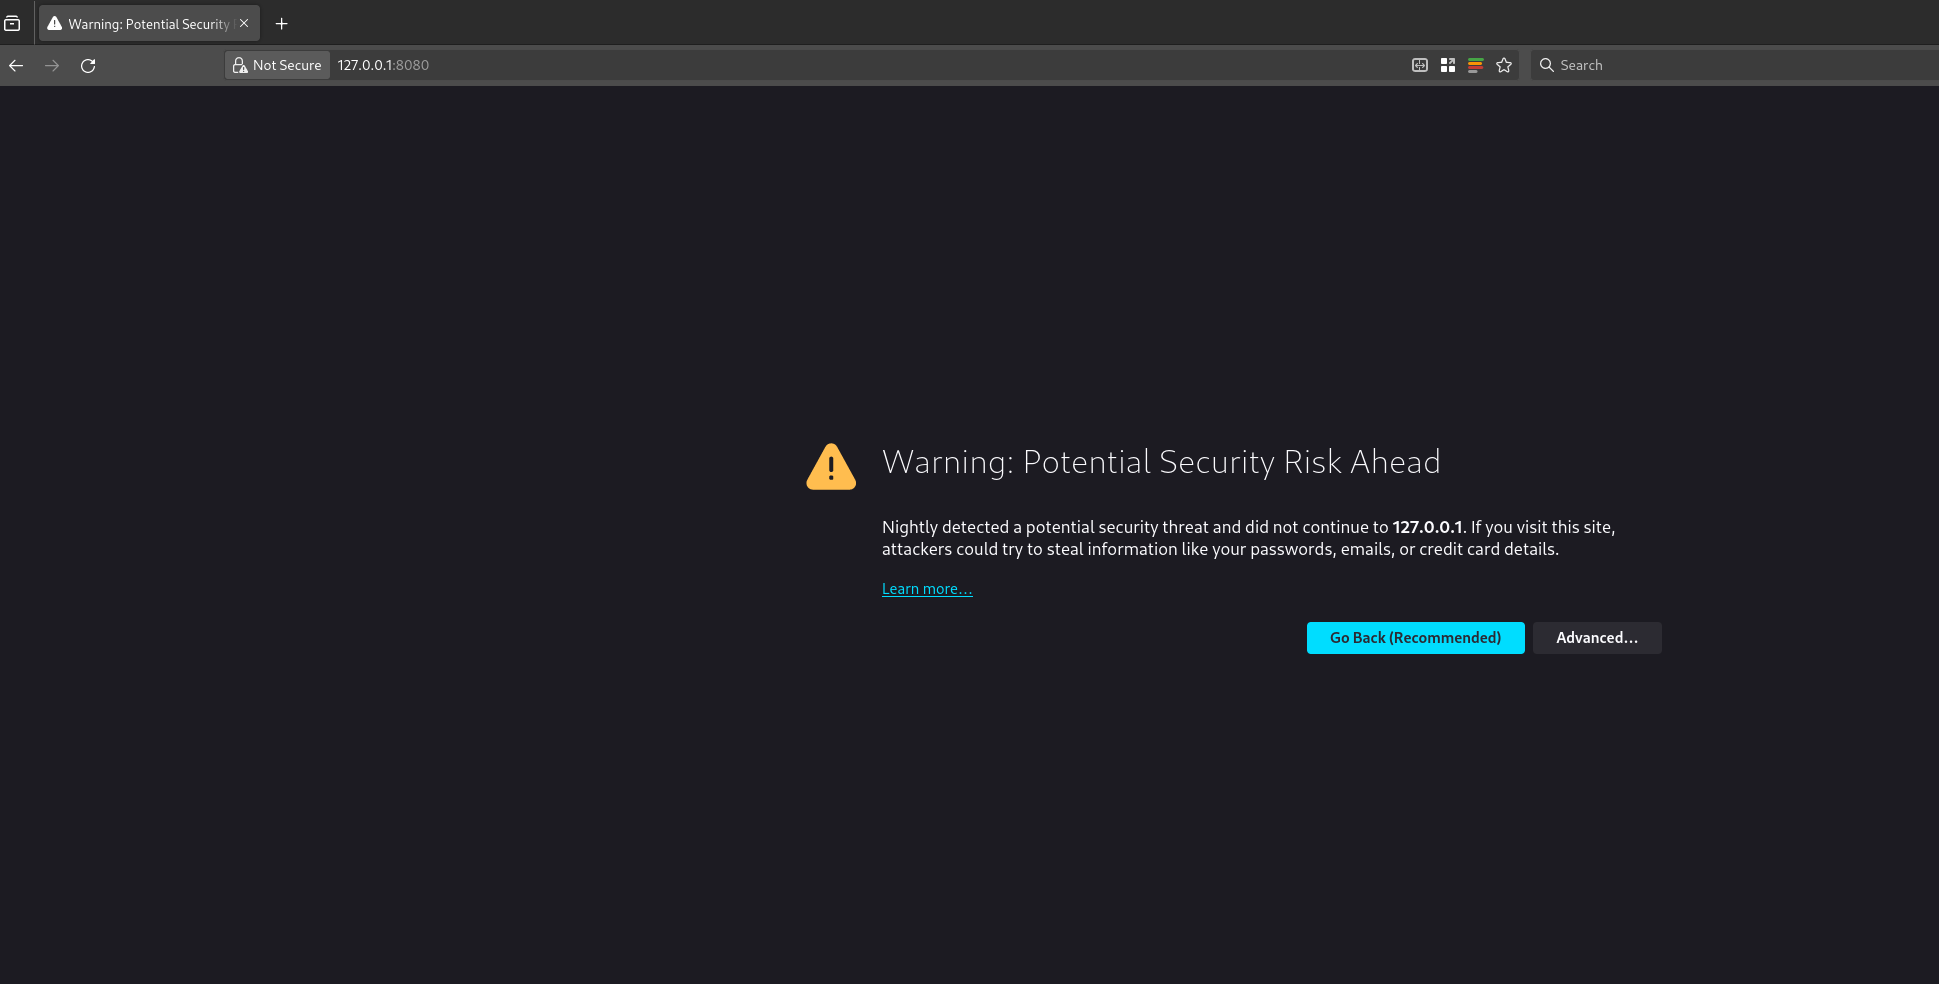
Step 3: Setup of Nextcloud AIO from the browser.To setup nextcloud AIO, we need to access it using the web browser on URL of our domain.tld:8080, however we do not want to open the 8080 port publicly to do this, so to complete the setup, here is a neat hack from sahilister
ssh -L 8080:127.0.0.1:8080 username:<server-ip>
you can bind the 8080 port of your server to the 8080 of your localhost using Unix socket forwarding over SSH.The port forwarding only last for the duration of your SSH session, if the SSH session breaks, your port forwarding will to. So, once you have the port forwarded, you can open the nextcloud AIO instance in your web browser at 127.0.0.1:8080
Nextcloud AIO install with docker-compose and nginx reverse proxy
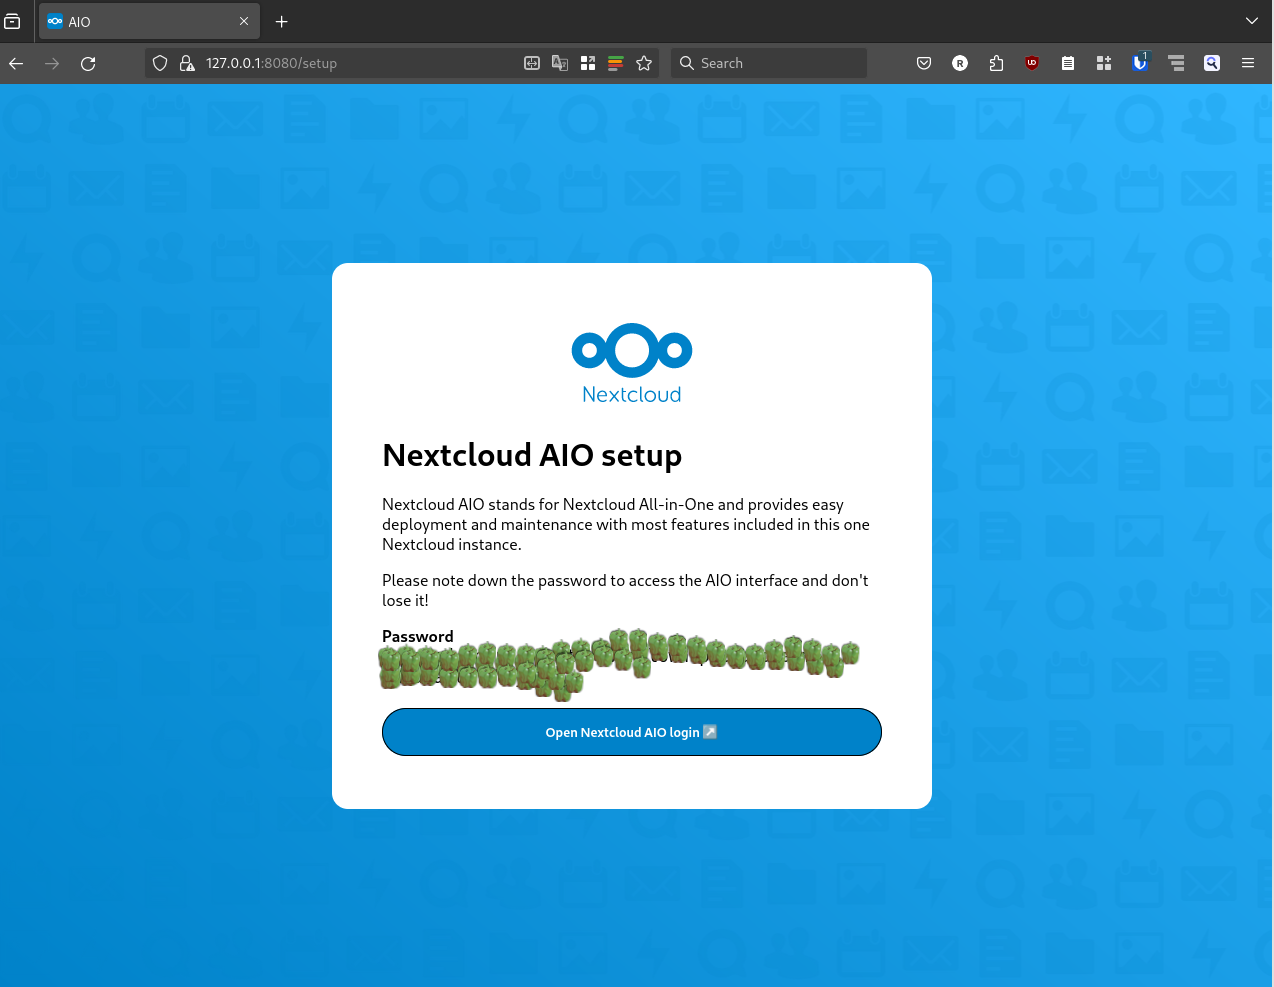
you will get this error because you are trying to access a page on localhost over HTTPS. You can click on advanced and then continue to proceed to the next page. Your data is encrypted over SSH for this session as we are binding the port over SSH. Depending on your choice of browser, the above page might look different.once you have proceeded, the nextcloud AIO interface will open and will look something like this.
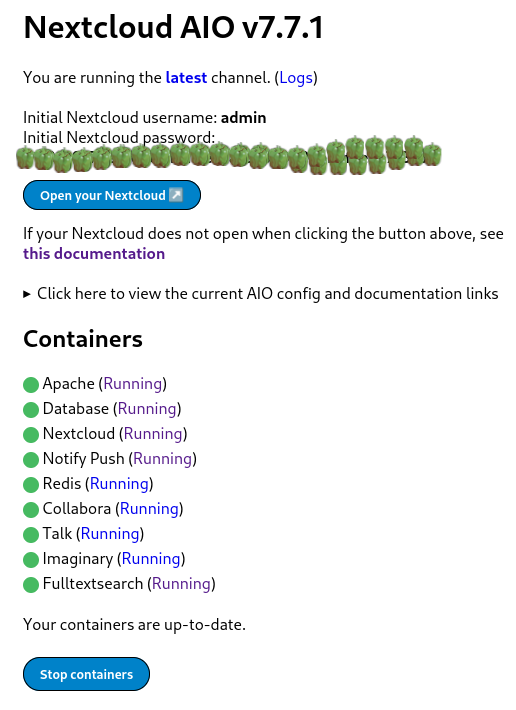
Nextcloud AIO install with docker-compose and nginx reverse proxynextcloud AIO initial screen with capsicums as password
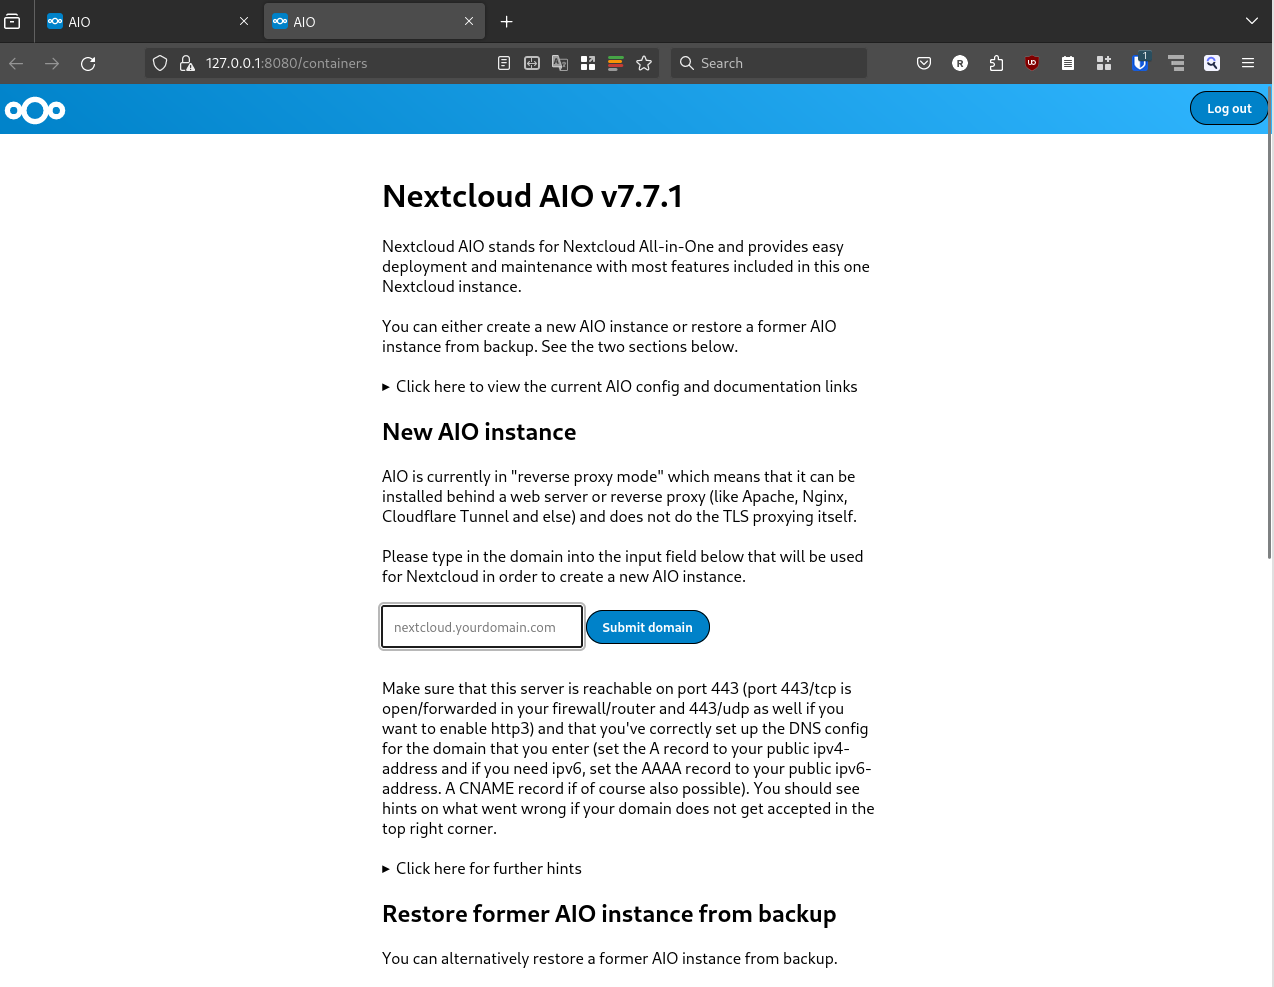
It will show an auto generated passphrase, you need to save this passphrase and make sure to not loose it. For the purposes of security, I have masked the passwords with capsicums. once you have noted down your password, you can proceed to the Nextcloud AIO login, enter your password and then login. After login you will be greeted with a screen like this.
Nextcloud AIO install with docker-compose and nginx reverse proxy
now you can put the domain that you want to use in the Submit domain field. Once the domain check is done, you will proceed to the next step and see another screen like this
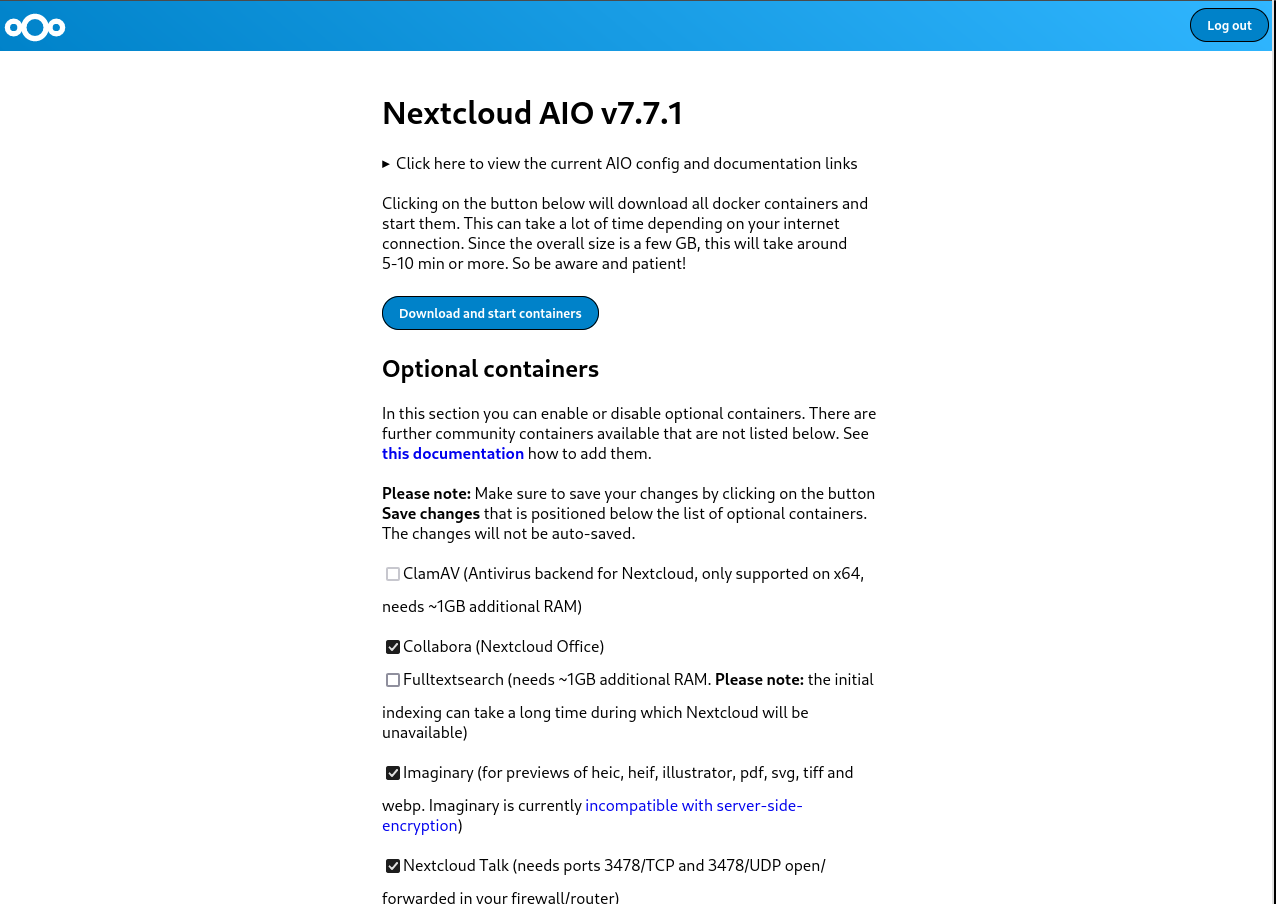
Nextcloud AIO install with docker-compose and nginx reverse proxy
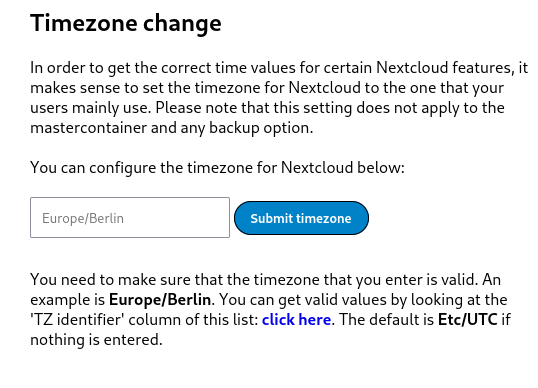
here you can select any optional containers for the features that you might want. IMPORTANT: Please make sure to also change the time zone at the bottom of the page according to the time zone you wish to operate in.
Nextcloud AIO install with docker-compose and nginx reverse proxy
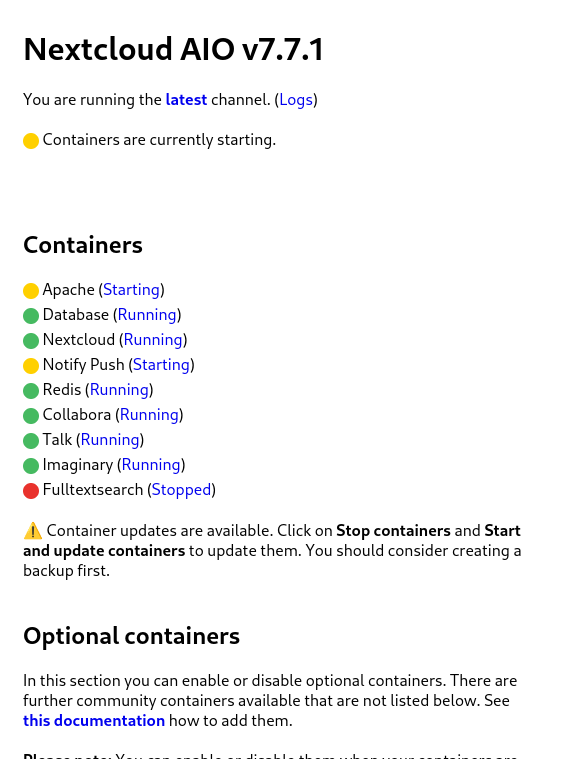
The timezone setup is also important because the data base will get initialized according to the set time zone. This could result in wrong initialization of database and you ending up in a startup loop for nextcloud. I faced this issue and could only resolve it after getting help from sahilister . Once you are done changing the timezone, and selecting any additional features you want, you can click on Download and start the containersIt will take some time for this process to finish, take a break and look at the farthest object in your room and take a sip of water. Once you are done, and the process has finished you will see a page similar to the following one.
Nextcloud AIO install with docker-compose and nginx reverse proxy
wait patiently for everything to turn green.
Nextcloud AIO install with docker-compose and nginx reverse proxy
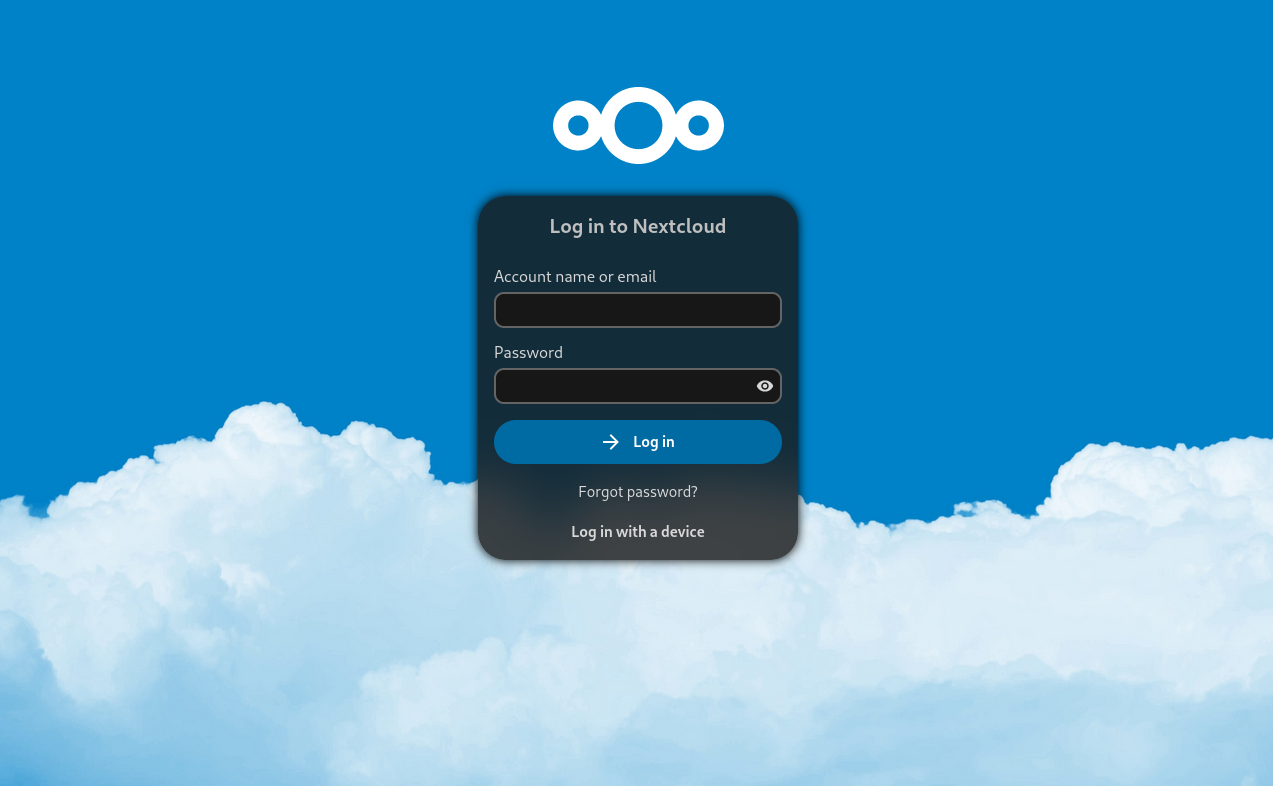
once all the containers have started properly, you can open the nextcloud login interface on your configured domain, the initial login details are auto generated as you can see from the above screenshot. Again you will see a password that you need to note down or save to enter the nextcloud interface. Capsicums will not work as passwords. I have masked the auto generated passwords using capsicums.Now you can click on Open your Nextcloud button or go to your configured domain to access the login screen.
Nextcloud AIO install with docker-compose and nginx reverse proxy
You can use the login details from the previous step to login to the administrator account of your Nextcloud instance. There you have it, your very own cloud!

Additional Notes:

How to properly reset Nextcloud setup?While following the above steps, or while following steps from some other tutorial, you may have made a mistake, and want to start everything again from scratch. The instructions for it are present in the Nextcloud documentation here . Here is the TLDR for a docker-compose setup. These steps will delete all data, do not use these steps on an existing nextcloud setup unless you know what you are doing.
  • Stop your master container.
docker-compose -f compose.yml down -v
The above command will also remove the volume associated with the master container
  • Stop all the child containers that has been started by the master container.
docker stop nextcloud-aio-apache nextcloud-aio-notify-push nextcloud-aio-nextcloud nextcloud-aio-imaginary nextcloud-aio-fulltextsearch nextcloud-aio-redis nextcloud-aio-database nextcloud-aio-talk nextcloud-aio-collabora
  • Remove all the child containers that has been started by the master container
docker rm nextcloud-aio-apache nextcloud-aio-notify-push nextcloud-aio-nextcloud nextcloud-aio-imaginary nextcloud-aio-fulltextsearch nextcloud-aio-redis nextcloud-aio-database nextcloud-aio-talk nextcloud-aio-collabora
  • If you also wish to remove all images associated with nextcloud you can do it with
docker rmi $(docker images --filter "reference=nextcloud/*" -q)
  • remove all volumes associated with child containers
docker volume rm <volume-name>
  • remove the network associated with nextcloud
docker network rm nextcloud-aio

Additional references.
  1. Nextcloud Github
  2. Nextcloud reverse proxy documentation
  3. Nextcloud Administration Guide
  4. Nextcloud User Manual
  5. Nextcloud Developer&aposs manual

Freexian Collaborators: Monthly report about Debian Long Term Support, November 2023 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering. Some notable fixes which were made in LTS during the month of November include the gnutls28 cryptographic library and the freerdp2 Remote Desktop Protocol client/server implementation. The gnutls28 update was prepared by LTS contributor Markus Koschany and dealt with a timing attack which could be used to compromise a cryptographic system, while the freerdp2 update was prepared by LTS contributor Tobias Frost and is the result of work spanning 3 months to deal with dozens of vulnerabilities. In addition to the many ordinary LTS tasks which were completed (CVE triage, patch backports, package updates, etc), there were several contributions by LTS contributors for the benefit of Debian stable and old-stable releases, as well as for the benefit of upstream projects. LTS contributor Abhijith PA uploaded an update of the puma package to unstable in order to fix a vulnerability in that package while LTS contributor Thosten Alteholz sponsored an upload to unstable of libde265 and himself made corresponding uploads of libde265 to Debian stable and old-stable. LTS contributor Bastien Roucari s developed patches for vulnerabilities in zbar and audiofile which were then provided to the respective upstream projects. Updates to packages in Debian stable were made by Markus Koschany to deal with security vulnerabilities and by Chris Lamb to deal with some non-security bugs. As always, the LTS strives to provide high quality updates to packages under the direct purview of the LTS team while also rendering assistance to maintainers, the stable security team, and upstream developers whenever practical.
Debian LTS contributors In November, 18 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 7.0h (out of 0h assigned and 14.0h from previous period), thus carrying over 7.0h to the next month.
  • Adrian Bunk did 15.0h (out of 14.0h assigned and 9.75h from previous period), thus carrying over 8.75h to the next month.
  • Anton Gladky did 10.0h (out of 9.5h assigned and 5.5h from previous period), thus carrying over 5.0h to the next month.
  • Bastien Roucari s did 16.0h (out of 18.25h assigned and 1.75h from previous period), thus carrying over 4.0h to the next month.
  • Ben Hutchings did 12.0h (out of 16.5h assigned and 12.25h from previous period), thus carrying over 16.75h to the next month.
  • Chris Lamb did 18.0h (out of 17.25h assigned and 0.75h from previous period).
  • Emilio Pozuelo Monfort did 15.5h (out of 23.5h assigned and 0.25h from previous period), thus carrying over 8.25h to the next month.
  • Guilhem Moulin did 13.0h (out of 12.0h assigned and 8.0h from previous period), thus carrying over 7.0h to the next month.
  • Lee Garrett did 14.5h (out of 16.75h assigned and 7.0h from previous period), thus carrying over 9.25h to the next month.
  • Markus Koschany did 30.0h (out of 30.0h assigned).
  • Ola Lundqvist did 6.5h (out of 8.25h assigned and 15.5h from previous period), thus carrying over 17.25h to the next month.
  • Roberto C. S nchez did 5.5h (out of 12.0h assigned), thus carrying over 6.5h to the next month.
  • Santiago Ruano Rinc n did 3.25h (out of 13.62h assigned and 2.375h from previous period), thus carrying over 12.745h to the next month.
  • Sean Whitton did 3.25h (out of 10.0h assigned), thus carrying over 6.75h to the next month.
  • Sylvain Beucler did 10.0h (out of 13.5h assigned and 10.25h from previous period), thus carrying over 13.75h to the next month.
  • Thorsten Alteholz did 14.0h (out of 14.0h assigned).
  • Tobias Frost did 12.0h (out of 12.0h assigned).
  • Utkarsh Gupta did 0.0h (out of 6.0h assigned and 17.75h from previous period), thus carrying over 23.75h to the next month.

Evolution of the situation In November, we have released 35 DLAs.

Thanks to our sponsors Sponsors that joined recently are in bold.

10 December 2023

Scarlett Gately Moore: KDE: KDE Snaps 23.08.4, PIM! KDE neon, Debian

KDE PIM Kaddressbook snapKDE PIM Kaddressbook snap
KDE Snaps: This weeks big accomplishment is KDE PIM snaps! I have successfully added akonadi as a service via an akonadi content snap and running it as a service. Kaddressbook is our first PIM snap with this setup and it works flawlessly! It is available in the snap store. I have a pile of MRs awaiting approvals, so keep your eye out for the rest of PIM in the next day. KDE Applications 23.08.4 has been released and available in the snap store. Krita 5.2.2 has been released. I have created a new kde-qt6 snap as the qt-framework snap has not been updated and the maintainer is unreachable. It is in edge and I will be rebuilding our kf6 snap with this one. I am debugging an issue with the latest Labplot release. KDE neon: This week I helped with frameworks release 5.113 and KDE applications 23.08.4. I also worked on the ongoing Unstable turning red into green builds as the porting to qt6 continues. Debian: With my on going learning packaging for all the programming languages, Rust packaging: I started on Rustic https://github.com/rustic-rs/rustic unfortunately, it was a bit of wasted time as it depends on a feature of tracing-subcriber that depends on matchers which has a grave bug, so it remains disabled. Personal: I do have an interview tomorrow! And it looks like the project may go through after the new year. So things are looking up, unfortunately I must still ask, if you have any spare change please consider a donation. The phone company decided to take an extra $200.00 I didn t have to spare and while I resolved it, they refused a refund, but gave me a credit to next months bill, which doesn t help me now. Thank you for your consideration. https://gofund.me/b74e4c6f

Freexian Collaborators: Debian Contributions: Python 3.12 preparations, debian-printing, merged-/usr tranisition updates, and more! (by Utkarsh Gupta)

Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Preparing for Python 3.12 by Stefano Rivera Stefano uploaded a few packages in preparation for Python 3.12, including pycxx and cython. Cython has a major new version (Cython 3), adding support for 3.12, but also bringing changes that many packages in Debian aren t ready to build with, yet. Stefano uploaded it to Debian experimental and did an archive rebuild of affected packages, and some analysis of the result. Matthias Klose has since filed bugs for all of these issues.

debian-printing, by Thorsten Alteholz This month Thorsten invested some of the previously obtained money to build his own printlab. At the moment it only consists of a dedicated computer with an USB printer attached. Due to its 64GB RAM and an SSD, building of debian-printing packages is much faster now. Over time other printers will be added and understanding bugs should be a lot easier now. Also Thorsten again adopted two packages, namely mink and ink, and moved them to the debian-printing team.

Merged-/usr transition by Helmut Grohne, et al The dumat analysis tool has been improved in quite some aspects. Beyond fixing false negative diagnostics, it now recognizes protective diversions used for mitigating Multi-Arch: same file loss. It was found that the proposed mitigation for ineffective diversions does not work as expected. Trying to fix it up resulted in more problems, some of which remain unsolved as of this writing. Initial work on moving shared libraries in the essential set has been done. Meanwhile, the wider Debian community worked on fixing all known Multi-Arch: same file loss scenarios. This work is now being driven by Christian Hofstaedler and during the Mini DebConf in Cambridge, Chris Boot, tienne Mollier, Miguel Landaeta, Samuel Henrique, and Utkarsh Gupta sent the other half of the necessary patches.

Miscellaneous contributions
  • Stefano merged patches to support loong64 and hurd-amd64 in re2.
  • For the Cambridge mini-conf, Stefano added a web player to the DebConf video streaming frontend, as the Cambridge miniconf didn t have its own website to host the player.
  • Rapha l helped the upstream developers of hamster-time-tracker to prepare a new upstream release (the first in multiple years) and packaged that new release in Debian unstable.
  • Enrico joined Hemut in brainstorming some /usr-merge solutions.
  • Thorsten took care of RM-bugs to remove no longer needed packages from the Debian archive and closed about 50 of them.
  • Helmut ported the feature of mounting a fuse connection via /dev/fd/N from fuse3 to fuse2.
  • Helmut sent a number of patches simplifying unprivileged use of piuparts.
  • Roberto worked with Helmut to prepare the Shorewall package for the ongoing /usr-move transition.
  • Utkarsh also helped with the ongoing /usr-merge work by preparing patches for gitlab, libnfc, and net-tools.
  • Utkarsh, along with Helmut, brainstormed on fixing #961138, as this affects the whole archive and all the suites and not just R packages. Utkarsh intends to follow up on the bug in December.
  • Santiago organized a MiniDebConf in Uruguay. In total, nine people attended, including most of DDs in the surrounding area. Here s a nicely written blog by Gunnar Wolf.
  • Santiago also worked on some issues on Salsa CI, fixed with some merge requests: #462, #463, and #466.

7 December 2023

Daniel Kahn Gillmor: New OpenPGP certificate for dkg, December 2023

dkg's New OpenPGP certificate in December 2023 In December of 2023, I'm moving to a new OpenPGP certificate. You might know my old OpenPGP certificate, which had an fingerprint of C29F8A0C01F35E34D816AA5CE092EB3A5CA10DBA. My new OpenPGP certificate has a fingerprint of: D477040C70C2156A5C298549BB7E9101495E6BF7. Both certificates have the same set of User IDs:
  • Daniel Kahn Gillmor
  • <dkg@debian.org>
  • <dkg@fifthhorseman.net>
You can find a version of this transition statement signed by both the old and new certificates at: https://dkg.fifthhorseman.net/2023-dkg-openpgp-transition.txt The new OpenPGP certificate is:
-----BEGIN PGP PUBLIC KEY BLOCK-----
xjMEZXEJyxYJKwYBBAHaRw8BAQdA5BpbW0bpl5qCng/RiqwhQINrplDMSS5JsO/Y
O+5Zi7HCwAsEHxYKAH0FgmVxCcsDCwkHCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0
QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmfUAgfN9tyTSxpxhmHA1r63GiI4v6NQ
mrrWVLOBRJYuhQMVCggCmwECHgEWIQTUdwQMcMIValwphUm7fpEBSV5r9wAAmaEA
/3MvYJMxQdLhIG4UDNMVd2bsovwdcTrReJhLYyFulBrwAQD/j/RS+AXQIVtkcO9b
l6zZTAO9x6yfkOZbv0g3eNyrAs0QPGRrZ0BkZWJpYW4ub3JnPsLACwQTFgoAfQWC
ZXEJywMLCQcJELt+kQFJXmv3RxQAAAAAAB4AIHNhbHRAbm90YXRpb25zLnNlcXVv
aWEtcGdwLm9yZ4l+Z3i19Uwjw3CfTNFCDjRsoufMoPOM7vM8HoOEdn/vAxUKCAKb
AQIeARYhBNR3BAxwwhVqXCmFSbt+kQFJXmv3AAALZQEAhJsgouepQVV98BHUH6Sv
WvcKrb8dQEZOvHFbZQQPNWgA/A/DHkjYKnUkCg8Zc+FonqOS/35sHhNA8CwqSQFr
tN4KzRc8ZGtnQGZpZnRoaG9yc2VtYW4ubmV0PsLACgQTFgoAfQWCZXEJywMLCQcJ
ELt+kQFJXmv3RxQAAAAAAB4AIHNhbHRAbm90YXRpb25zLnNlcXVvaWEtcGdwLm9y
ZxLvwkgnslsAuo+IoSa9rv8+nXpbBdab2Ft7n4H9S+d/AxUKCAKbAQIeARYhBNR3
BAxwwhVqXCmFSbt+kQFJXmv3AAAtFgD4wqcUfQl7nGLQOcAEHhx8V0Bg8v9ov8Gs
Y1ei1BEFwAD/cxmxmDSO0/tA+x4pd5yIvzgfGYHSTxKS0Ww3hzjuZA7NE0Rhbmll
bCBLYWhuIEdpbGxtb3LCwA4EExYKAIAFgmVxCcsDCwkHCRC7fpEBSV5r90cUAAAA
AAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBncC5vcmd7X4TgiINwnzh4jar0
Pf/b5hgxFPngCFxJSmtr/f0YiQMVCggCmQECmwECHgEWIQTUdwQMcMIValwphUm7
fpEBSV5r9wAAMuwBAPtMonKbhGOhOy+8miAb/knJ1cIPBjLupJbjM+NUE1WyAQD1
nyGW+XwwMrprMwc320mdJH9B0jdokJZBiN7++0NoBM4zBGVxCcsWCSsGAQQB2kcP
AQEHQI19uRatkPSFBXh8usgciEDwZxTnnRZYrhIgiFMybBDQwsC/BBgWCgExBYJl
cQnLCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lhLXBn
cC5vcmfCopazDnq6hZUsgVyztl5wmDCmxI169YLNu+IpDzJEtQKbAr6gBBkWCgBv
BYJlcQnLCRB3LRYeNc1LgUcUAAAAAAAeACBzYWx0QG5vdGF0aW9ucy5zZXF1b2lh
LXBncC5vcmcQglI7G7DbL9QmaDkzcEuk3QliM4NmleIRUW7VvIBHMxYhBHS8BMQ9
hghL6GcsBnctFh41zUuBAACwfwEAqDULksr8PulKRcIP6N9NI/4KoznyIcuOHi8q
Gk4qxMkBAIeV20SPEnWSw9MWAb0eKEcfupzr/C+8vDvsRMynCWsDFiEE1HcEDHDC
FWpcKYVJu36RAUlea/cAAFD1AP0YsE3Eeig1tkWaeyrvvMf5Kl1tt2LekTNWDnB+
FUG9SgD+Ka8vfPR8wuV8D3y5Y9Qq9xGO+QkEBCW0U1qNypg65QHOOARlcQnLEgor
BgEEAZdVAQUBAQdAWTLEa0WmnhUmDBdWXX0ZlYAa4g1CK/fXg0NPOQSteA4DAQgH
wsAABBgWCgByBYJlcQnLCRC7fpEBSV5r90cUAAAAAAAeACBzYWx0QG5vdGF0aW9u
cy5zZXF1b2lhLXBncC5vcmexrMBZe0QdQ+ZJOZxFkAiwCw2I7yTSF2Ox9GVFWKmA
mAKbDBYhBNR3BAxwwhVqXCmFSbt+kQFJXmv3AABcJQD/f4ltpSvLBOBEh/C2dIYa
dgSuqkCqq0B4WOhFRkWJZlcA/AxqLWG4o8UrrmwrmM42FhgxKtEXwCSHE00u8wR4
Up8G
=9Yc8
-----END PGP PUBLIC KEY BLOCK-----
When I have some reasonable number of certifications, i'll update the certificate associated with my e-mail addresses on https://keys.openpgp.org, in DANE, and in WKD. Until then, those lookups should continue to provide the old certificate.

6 December 2023

Tim Retout: Nostalgia for my attention span

This post was possibly inspired by my daughter s homework assignment to interview an old person about technology change. Guess who s old now? Sometimes I look back at how life used to be, and remember what it was like. There are two key nostalgia points for me: before internet, and before smartphones.

Before the internet Before the internet, there were computers. There were always computers in my life, they were just less fancy, with mainly text and fewer graphics at first. These days we adapt our user interfaces to look more like DOS and call it retro , although claiming it s more efficient that way. Sometimes it is. The written word is a fundamental mode of human communication it resonates. Some of my earliest programming memories were typing lines of BASIC code into some sort of BBC Micro, usually not successfully. Most of my computer learning was largely theoretical, through Usborne books (now available online! Thanks internet for reducing the marginal cost of publishing to approximately zero) but without the benefit of a computer of my own. I went for a walk this morning, with a slight bite to the air, and bought a newspaper, like the old person I am (I m leaning in). Imagine that - a physical paper full of news. When I was an inquisitive sixth-former, TheGuardian cost 50 pence today it was 2.80. This increase far outstrips the rate of inflation, which would bring it to around 90 pence. No, this must surely reflect the drop in circulation of the physical edition, and the rise in advertisement-filled web content.

Before smartphones As the internet became mainstream, I remember dial-up, and Freeserve, and even the tail end of USENET, and IRC. This was still a time when email was a thing you had to be at your desk to check. Feature phones were very useful, but it was still possible to get lost. My university halls had a shared land-line phone on each floor. And I wrote on the internet. I remember commenting on blogs, and I think my writing was better back then; more free, less inhibited. I do find myself giving less attention to news squeezed into the small form-factor of a mobile phone. Chat messages and notification pings. I m not convinced this is great progress for humanity.

Reproducible Builds: Reproducible Builds in November 2023

Welcome to the November 2023 report from the Reproducible Builds project! In these reports we outline the most important things that we have been up to over the past month. As a rather rapid recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries (more).

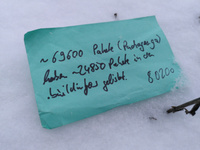
Reproducible Builds Summit 2023 Between October 31st and November 2nd, we held our seventh Reproducible Builds Summit in Hamburg, Germany! Amazingly, the agenda and all notes from all sessions are all online many thanks to everyone who wrote notes from the sessions. As a followup on one idea, started at the summit, Alexander Couzens and Holger Levsen started work on a cache (or tailored front-end) for the snapshot.debian.org service. The general idea is that, when rebuilding Debian, you do not actually need the whole ~140TB of data from snapshot.debian.org; rather, only a very small subset of the packages are ever used for for building. It turns out, for amd64, arm64, armhf, i386, ppc64el, riscv64 and s390 for Debian trixie, unstable and experimental, this is only around 500GB ie. less than 1%. Although the new service not yet ready for usage, it has already provided a promising outlook in this regard. More information is available on https://rebuilder-snapshot.debian.net and we hope that this service becomes usable in the coming weeks. The adjacent picture shows a sticky note authored by Jan-Benedict Glaw at the summit in Hamburg, confirming Holger Levsen s theory that rebuilding all Debian packages needs a very small subset of packages, the text states that 69,200 packages (in Debian sid) list 24,850 packages in their .buildinfo files, in 8,0200 variations. This little piece of paper was the beginning of rebuilder-snapshot and is a direct outcome of the summit! The Reproducible Builds team would like to thank our event sponsors who include Mullvad VPN, openSUSE, Debian, Software Freedom Conservancy, Allotropia and Aspiration Tech.

Beyond Trusting FOSS presentation at SeaGL On November 4th, Vagrant Cascadian presented Beyond Trusting FOSS at SeaGL in Seattle, WA in the United States. Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture. The summary of Vagrant s talk mentions that it will:
[ ] introduce the concepts of Reproducible Builds, including best practices for developing and releasing software, the tools available to help diagnose issues, and touch on progress towards solving decades-old deeply pervasive fundamental security issues Learn how to verify and demonstrate trust, rather than simply hoping everything is OK!
Germane to the contents of the talk, the slides for Vagrant s talk can be built reproducibly, resulting in a PDF with a SHA1 of cfde2f8a0b7e6ec9b85377eeac0661d728b70f34 when built on Debian bookworm and c21fab273232c550ce822c4b0d9988e6c49aa2c3 on Debian sid at the time of writing.

Human Factors in Software Supply Chain Security Marcel Fourn , Dominik Wermke, Sascha Fahl and Yasemin Acar have published an article in a Special Issue of the IEEE s Security & Privacy magazine. Entitled A Viewpoint on Human Factors in Software Supply Chain Security: A Research Agenda, the paper justifies the need for reproducible builds to reach developers and end-users specifically, and furthermore points out some under-researched topics that we have seen mentioned in interviews. An author pre-print of the article is available in PDF form.

Community updates On our mailing list this month:

openSUSE updates Bernhard M. Wiedemann has created a wiki page outlining an proposal to create a general-purpose Linux distribution which consists of 100% bit-reproducible packages albeit minus the embedded signature within RPM files. It would be based on openSUSE Tumbleweed or, if available, its Slowroll-variant. In addition, Bernhard posted another monthly update for his work elsewhere in openSUSE.

Ubuntu Launchpad now supports .buildinfo files Back in 2017, Steve Langasek filed a bug against Ubuntu s Launchpad code hosting platform to report that .changes files (artifacts of building Ubuntu and Debian packages) reference .buildinfo files that aren t actually exposed by Launchpad itself. This was causing issues when attempting to process .changes files with tools such as Lintian. However, it was noticed last month that, in early August of this year, Simon Quigley had resolved this issue, and .buildinfo files are now available from the Launchpad system.

PHP reproducibility updates There have been two updates from the PHP programming language this month. Firstly, the widely-deployed PHPUnit framework for the PHP programming language have recently released version 10.5.0, which introduces the inclusion of a composer.lock file, ensuring total reproducibility of the shipped binary file. Further details and the discussion that went into their particular implementation can be found on the associated GitHub pull request. In addition, the presentation Leveraging Nix in the PHP ecosystem has been given in late October at the PHP International Conference in Munich by Pol Dellaiera. While the video replay is not yet available, the (reproducible) presentation slides and speaker notes are available.

diffoscope changes diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including:
  • Improving DOS/MBR extraction by adding support for 7z. [ ]
  • Adding a missing RequiredToolNotFound import. [ ]
  • As a UI/UX improvement, try and avoid printing an extended traceback if diffoscope runs out of memory. [ ]
  • Mark diffoscope as stable on PyPI.org. [ ]
  • Uploading version 252 to Debian unstable. [ ]

Website updates A huge number of notes were added to our website that were taken at our recent Reproducible Builds Summit held between October 31st and November 2nd in Hamburg, Germany. In particular, a big thanks to Arnout Engelen, Bernhard M. Wiedemann, Daan De Meyer, Evangelos Ribeiro Tzaras, Holger Levsen and Orhun Parmaks z. In addition to this, a number of other changes were made, including:

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In October, a number of changes were made by Holger Levsen:
  • Debian-related changes:
    • Track packages marked as Priority: important in a new package set. [ ][ ]
    • Stop scheduling packages that fail to build from source in bookworm [ ] and bullseye. [ ].
    • Add old releases dashboard link in web navigation. [ ]
    • Permit re-run of the pool_buildinfos script to be re-run for a specific year. [ ]
    • Grant jbglaw access to the osuosl4 node [ ][ ] along with lynxis [ ].
    • Increase RAM on the amd64 Ionos builders from 48 GiB to 64 GiB; thanks IONOS! [ ]
    • Move buster to archived suites. [ ][ ]
    • Reduce the number of arm64 architecture workers from 24 to 16 in order to improve stability [ ], reduce the workers for amd64 from 32 to 28 and, for i386, reduce from 12 down to 8 [ ].
    • Show the entire build history of each Debian package. [ ]
    • Stop scheduling already tested package/version combinations in Debian bookworm. [ ]
  • Snapshot service for rebuilders
    • Add an HTTP-based API endpoint. [ ][ ]
    • Add a Gunicorn instance to serve the HTTP API. [ ]
    • Add an NGINX config [ ][ ][ ][ ]
  • System-health:
    • Detect failures due to HTTP 503 Service Unavailable errors. [ ]
    • Detect failures to update package sets. [ ]
    • Detect unmet dependencies. (This usually occurs with builds of Debian live-build.) [ ]
  • Misc-related changes:
    • do install systemd-ommd on jenkins. [ ]
    • fix harmless typo in squid.conf for codethink04. [ ]
    • fixup: reproducible Debian: add gunicorn service to serve /api for rebuilder-snapshot.d.o. [ ]
    • Increase codethink04 s Squid cache_dir size setting to 16 GiB. [ ]
    • Don t install systemd-oomd as it unfortunately kills sshd [ ]
    • Use debootstrap from backports when commisioning nodes. [ ]
    • Add the live_build_debian_stretch_gnome, debsums-tests_buster and debsums-tests_buster jobs to the zombie list. [ ][ ]
    • Run jekyll build with the --watch argument when building the Reproducible Builds website. [ ]
    • Misc node maintenance. [ ][ ][ ]
Other changes were made as well, however, including Mattia Rizzolo fixing rc.local s Bash syntax so it can actually run [ ], commenting away some file cleanup code that is (potentially) deleting too much [ ] and fixing the html_brekages page for Debian package builds [ ]. Finally, diagnosed and submitted a patch to add a AddEncoding gzip .gz line to the tests.reproducible-builds.org Apache configuration so that Gzip files aren t re-compressed as Gzip which some clients can t deal with (as well as being a waste of time). [ ]

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

5 December 2023

Dirk Eddelbuettel: RcppArmadillo 0.12.6.6.1 on CRAN: No More Deprecation

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1126 other packages on CRAN, downloaded 31.7 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 569 times according to Google Scholar. This release ends the practice on asking Armadillo to suppress deprecation warnings. RcppArmadillo, as noted, has a large user base. Sometimes Conrad sometimes made changes without too much of a heads-up so at times it was opportune to not bring those warnings to dozens (or maybe hundreds) of packages at CRAN. Yet we need to balance this with the demonstrable need to call out older deprecated code use. So sixteen months ago, with GitHub issue #391, we started to alert author of 30+ affected packages and supplied either pull requests or emailed patches to all. Eleven months ago GitHub issues #402 was added for a second deprecation. And the time of making the switch has come. Release 0.12.6.6.1 no longer defines ARMA_IGNORE_DEPRECATED_MARKER. So among the over 1100 packages using RcppArmadillo at CRAN, around a good dozen or so were flagged in the upload but CRAN concurred and let the package migrate to CRAN. If you maintain an affected package, consider applying the patch or pull request now. A simple stop-gap measure also exists by adding -DARMA_IGNORE_DEPRECATED_MARKER to src/Makevars as either PKG_CPPFLAGS or PKG_CXXFLAGS to reactivate it. But a proper code update, which is generally simple, may be better. If you are unsure, do not hesitate to get in touch. The set of changes since the last CRAN release follows.

Changes in RcppArmadillo version 0.12.6.6.1 (2023-12-03)
  • Following the extendeded transition in #391 and #402, this release no longer sets ARMA_IGNORE_DEPRECATED_MARKER. Maintainers of affected packages have received pull requests or patches and can set -DARMA_IGNORE_DEPRECATED_MARKER as PKG_CPPFLAGS.

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

30 November 2023

Bits from Debian: New Debian Developers and Maintainers (September and October 2023)

The following contributors got their Debian Developer accounts in the last two months: The following contributors were added as Debian Maintainers in the last two months: Congratulations!
Dirk Eddelbuettel: qlcal 0.0.9 on CRAN: Maintenance

The ninth release of the qlcal package arrivied at CRAN today. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. This releases updates the code to address warning now shown under R-devel when -Wformat -Wformat-security are enabled. This amounted to re-generating RcppExports.cpp under an updated Rcpp version. We also no longer set C++14 explicitly as a compilation standard but rather determine at build time if it is needed or not.

Changes in version 0.0.9 (2023-11-29)
  • configure now uses a new helper script to only set a compilation standard when needed for R versions older than 4.2.0
  • The file RcppExports.cpp was regenerated to avoid a string format warning from R-devel

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

27 November 2023

Fran ois Marier: Automatically rebooting for kernel updates

I use reboot-notifier on most of my servers to let me know when I need to reboot them for kernel updates since I want to decide exactly when those machines go down. On the other hand, my home backup server has very predictable usage patterns and so I decided to go one step further there and automate these necessary reboots. To do that, I first installed reboot-notifier which puts the following script in /etc/kernel/postinst.d/reboot-notifier to detect when a new kernel was installed:
#!/bin/sh
if [ "$0" = "/etc/kernel/postinst.d/reboot-notifier" ]; then
    DPKG_MAINTSCRIPT_PACKAGE=linux-base
fi
echo "*** System restart required ***" > /var/run/reboot-required
echo "$DPKG_MAINTSCRIPT_PACKAGE" >> /var/run/reboot-required.pkgs
Note that unattended-upgrades puts a similar script in /etc/kernel/postinst.d/unattended-upgrades:
#!/bin/sh
case "$DPKG_MAINTSCRIPT_PACKAGE::$DPKG_MAINTSCRIPT_NAME" in
   linux-image-extra*::postrm)
      exit 0;;
esac
if [ -d /var/run ]; then
    touch /var/run/reboot-required
    if ! grep -q "^$DPKG_MAINTSCRIPT_PACKAGE$" /var/run/reboot-required.pkgs 2> /dev/null ; then
        echo "$DPKG_MAINTSCRIPT_PACKAGE" >> /var/run/reboot-required.pkgs
    fi
fi
and so you only need one of them to be installed since they both write to /var/run/reboot-required. It doesn't hurt to have both of them though. Then I created the following cron job (/etc/cron.daily/reboot-local) to actually reboot the server:
#!/bin/bash
REBOOT_REQUIRED=/var/run/reboot-required
if [ -s $REBOOT_REQUIRED ] ; then
    cat "$REBOOT_REQUIRED"   /usr/bin/mail -s "Rebooting $HOSTNAME" root
    /bin/systemctl reboot
fi
With that in place, my server will send me an email and then automatically reboot itself. This is a work in progress because I'd like to add some checks later on to make sure that no backup is in progress during that time (maybe by looking for active ssh connections?), but it works well enough for now. Feel free to leave a comment if you've got a smarter script you'd like to share.

26 November 2023

Dirk Eddelbuettel: RQuantLib 0.4.20 on CRAN: More Maintenance

A new release 0.4.20 of RQuantLib arrived at CRAN earlier today, and has already been uploaded to Debian as well. QuantLib is a rather comprehensice free/open-source library for quantitative finance. RQuantLib connects (some parts of) it to the R environment and language, and has been part of CRAN for more than twenty years (!!) as it was one of the first packages I uploaded there. This release of RQuantLib brings a few more updates for nags triggered by recent changes in the upcoming R release (aka r-devel , usually due in April). The Rd parser now identifies curly braces that lack a preceding macro, usually a typo as it was here which affected three files. The printf (or alike) format checker found two more small issues. The run-time checker for examples was unhappy with the callable bond example so we only run it in interactive mode now. Lastly I had alread commented-out the setting for a C++14 compilation (required by the remaining Boost headers) as C++14 has been the default since R 4.2.0 (with suitable compilers, at least). Those who need it explicitly will have to uncomment the line in src/Makevars.in. Lastly, the expand printf format strings also found a need for a small change in Rcpp so the development version (now 1.0.11.5) has that addressed; the change will be part of Rcpp 1.0.12 in January.

Changes in RQuantLib version 0.4.20 (2023-11-26)
  • Correct three help pages with stray curly braces
  • Correct two printf format strings
  • Comment-out explicit selection of C++14
  • Wrap one example inside 'if (interactive())' to not exceed total running time limit at CRAN checks

Courtesy of my CRANberries, there is also a diffstat report for the this release 0.4.20. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Niels Thykier: Providing online reference documentation for debputy

I do not think seasoned Debian contributors quite appreciate how much knowledge we have picked up and internalized. As an example, when I need to look up documentation for debhelper, I generally know which manpage to look in. I suspect most long time contributors would be able to a similar thing (maybe down 2-3 manpages). But new contributors does not have the luxury of years of experience. This problem is by no means unique to debhelper. One thing that debhelper does very well, is that it is hard for users to tell where a addon "starts" and debhelper "ends". It is clear you use addons, but the transition in and out of third party provided tools is generally smooth. This is a sign that things "just work(tm)". Except when it comes to documentation. Here, debhelper's static documentation does not include documentation for third party tooling. If you think from a debhelper maintainer's perspective, this seems obvious. Embedding documentation for all the third-party code would be very hard work, a layer-violation, etc.. But from a user perspective, we should not have to care "who" provides "what". As as user, I want to understand how this works and the more hoops I have to jump through to get that understanding, the more frustrated I will be with the toolstack. With this, I came to the conclusion that the best way to help users and solve the problem of finding the documentation was to provide "online documentation". It should be possible to ask debputy, "What attributes can I use in install-man?" or "What does path-metadata do?". Additionally, the lookup should work the same no matter if debputy provided the feature or some third-party plugin did. In the future, perhaps also other types of documentation such as tutorials or how-to guides. Below, I have some tentative results of my work so far. There are some improvements to be done. Notably, the commands for these documentation features are still treated a "plugin" subcommand features and should probably have its own top level "ask-me-anything" subcommand in the future.
Automatic discard rules Since the introduction of install rules, debputy has included an automatic filter mechanism that prunes out unwanted content. In 0.1.9, these filters have been named "Automatic discard rules" and you can now ask debputy to list them.
$ debputy plugin list automatic-discard-rules
+-----------------------+-------------+
  Name                    Provided By  
+-----------------------+-------------+
  python-cache-files      debputy      
  la-files                debputy      
  backup-files            debputy      
  version-control-paths   debputy      
  gnu-info-dir-file       debputy      
  debian-dir              debputy      
  doxygen-cruft-files     debputy      
+-----------------------+-------------+
For these rules, the provider can both provide a description but also an example of their usage.
$ debputy plugin show automatic-discard-rules la-files
Automatic Discard Rule: la-files
================================
Documentation: Discards any .la files beneath /usr/lib
Example
-------
    /usr/lib/libfoo.la        << Discarded (directly by the rule)
    /usr/lib/libfoo.so.1.0.0
The example is a live example. That is, the provider will provide debputy with a scenario and the expected outcome of that scenario. Here is the concrete code in debputy that registers this example:
api.automatic_discard_rule(
    "la-files",
    _debputy_prune_la_files,
    rule_reference_documentation="Discards any .la files beneath /usr/lib",
    examples=automatic_discard_rule_example(
        "usr/lib/libfoo.la",
        ("usr/lib/libfoo.so.1.0.0", False),
    ),
)
When showing the example, debputy will validate the example matches what the plugin provider intended. Lets say I was to introduce a bug in the code, so that the discard rule no longer worked. Then debputy would start to show the following:
# Output if the code or example is broken
$ debputy plugin show automatic-discard-rules la-files
[...]
Automatic Discard Rule: la-files
================================
Documentation: Discards any .la files beneath /usr/lib
Example
-------
    /usr/lib/libfoo.la        !! INCONSISTENT (code: keep, example: discard)
    /usr/lib/libfoo.so.1.0.0
debputy: warning: The example was inconsistent. Please file a bug against the plugin debputy
Obviously, it would be better if this validation could be added directly as a plugin test, so the CI pipeline would catch it. That is one my personal TODO list. :) One final remark about automatic discard rules before moving on. In 0.1.9, debputy will also list any path automatically discarded by one of these rules in the build output to make sure that the automatic discard rule feature is more discoverable.
Plugable manifest rules like the install rule In the manifest, there are several places where rules can be provided by plugins. To make life easier for users, debputy can now since 0.1.8 list all provided rules:
$ debputy plugin list plugable-manifest-rules
+-------------------------------+------------------------------+-------------+
  Rule Name                       Rule Type                      Provided By  
+-------------------------------+------------------------------+-------------+
  install                         InstallRule                    debputy      
  install-docs                    InstallRule                    debputy      
  install-examples                InstallRule                    debputy      
  install-doc                     InstallRule                    debputy      
  install-example                 InstallRule                    debputy      
  install-man                     InstallRule                    debputy      
  discard                         InstallRule                    debputy      
  move                            TransformationRule             debputy      
  remove                          TransformationRule             debputy      
  [...]                           [...]                          [...]        
  remove                          DpkgMaintscriptHelperCommand   debputy      
  rename                          DpkgMaintscriptHelperCommand   debputy      
  cross-compiling                 ManifestCondition              debputy      
  can-execute-compiled-binaries   ManifestCondition              debputy      
  run-build-time-tests            ManifestCondition              debputy      
  [...]                           [...]                          [...]        
+-------------------------------+------------------------------+-------------+
(Output trimmed a bit for space reasons) And you can then ask debputy to describe any of these rules:
$ debputy plugin show plugable-manifest-rules install
Generic install ( install )
===========================
The generic  install  rule can be used to install arbitrary paths into packages
and is *similar* to how  dh_install  from debhelper works.  It is a two "primary" uses.
  1) The classic "install into directory" similar to the standard  dh_install 
  2) The "install as" similar to  dh-exec 's  foo => bar  feature.
Attributes:
 -  source  (conditional): string
    sources  (conditional): List of string
   A path match ( source ) or a list of path matches ( sources ) defining the
   source path(s) to be installed. [...]
 -  dest-dir  (optional): string
   A path defining the destination *directory*. [...]
 -  into  (optional): string or a list of string
   A path defining the destination *directory*. [...]
 -  as  (optional): string
   A path defining the path to install the source as. [...]
 -  when  (optional): manifest condition (string or mapping of string)
   A condition as defined in [Conditional rules](https://salsa.debian.org/debian/debputy/-/blob/main/MANIFEST-FORMAT.md#Conditional rules).
This rule enforces the following restrictions:
 - The rule must use exactly one of:  source ,  sources 
 - The attribute  as  cannot be used with any of:  dest-dir ,  sources 
[...]
(Output trimmed a bit for space reasons) All the attributes and restrictions are auto-computed by debputy from information provided by the plugin. The associated documentation for each attribute is supplied by the plugin itself, The debputy API validates that all attributes are covered and the documentation does not describe non-existing fields. This ensures that you as a plugin provider never forget to document new attributes when you add them later. The debputy API for manifest rules are not quite stable yet. So currently only debputy provides rules here. However, it is my intention to lift that restriction in the future. I got the idea of supporting online validated examples when I was building this feature. However, sadly, I have not gotten around to supporting it yet.
Manifest variables like PACKAGE I also added a similar documentation feature for manifest variables such as PACKAGE . When I implemented this, I realized listing all manifest variables by default would probably be counter productive to new users. As an example, if you list all variables by default it would include DEB_HOST_MULTIARCH (the most common case) side-by-side with the the much less used DEB_BUILD_MULTIARCH and the even lessor used DEB_TARGET_MULTIARCH variable. Having them side-by-side implies they are of equal importance, which they are not. As an example, the ballpark number of unique packages for which DEB_TARGET_MULTIARCH is useful can be counted on two hands (and maybe two feet if you consider gcc-X distinct from gcc-Y). This is one of the cases, where experience makes us blind. Many of us probably have the "show me everything and I will find what I need" mentality. But that requires experience to be able to pull that off - especially if all alternatives are presented as equals. The cross-building terminology has proven to notoriously match poorly to people's expectation. Therefore, I took a deliberate choice to reduce the list of shown variables by default and in the output explicitly list what filters were active. In the current version of debputy (0.1.9), the listing of manifest-variables look something like this:
$ debputy plugin list manifest-variables
+----------------------------------+----------------------------------------+------+-------------+
  Variable (use via:   NAME  )   Value                                    Flag   Provided by  
+----------------------------------+----------------------------------------+------+-------------+
  DEB_HOST_ARCH                      amd64                                           debputy      
  [... other DEB_HOST_* vars ...]    [...]                                           debputy      
  DEB_HOST_MULTIARCH                 x86_64-linux-gnu                                debputy      
  DEB_SOURCE                         debputy                                         debputy      
  DEB_VERSION                        0.1.8                                           debputy      
  DEB_VERSION_EPOCH_UPSTREAM         0.1.8                                           debputy      
  DEB_VERSION_UPSTREAM               0.1.8                                           debputy      
  DEB_VERSION_UPSTREAM_REVISION      0.1.8                                           debputy      
  PACKAGE                            <package-name>                                  debputy      
  path:BASH_COMPLETION_DIR           /usr/share/bash-completion/completions          debputy      
+----------------------------------+----------------------------------------+------+-------------+
+-----------------------+--------+-------------------------------------------------------+
  Variable type           Value    Option                                                 
+-----------------------+--------+-------------------------------------------------------+
  Token variables         hidden   --show-token-variables OR --show-all-variables         
  Special use variables   hidden   --show-special-case-variables OR --show-all-variables  
+-----------------------+--------+-------------------------------------------------------+
I will probably tweak the concrete listing in the future. Personally, I am considering to provide short-hands variables for some of the DEB_HOST_* variables and then hide the DEB_HOST_* group from the default view as well. Maybe something like ARCH and MULTIARCH, which would default to their DEB_HOST_* counter part. This variable could then have extended documentation that high lights DEB_HOST_<X> as its source and imply that there are special cases for cross-building where you might need DEB_BUILD_<X> or DEB_TARGET_<X>. Speaking of variable documentation, you can also lookup the documentation for a given manifest variable:
$ debputy plugin show manifest-variables path:BASH_COMPLETION_DIR
Variable: path:BASH_COMPLETION_DIR
==================================
Documentation: Directory to install bash completions into
Resolved: /usr/share/bash-completion/completions
Plugin: debputy
This was my update on online reference documentation for debputy. I hope you found it useful. :)
Thanks On a closing note, I would like to thanks Jochen Sprickerhof, Andres Salomon, Paul Gevers for their recent contributions to debputy. Jochen and Paul provided a number of real world cases where debputy would crash or not work, which have now been fixed. Andres and Paul also provided corrections to the documentation.

Ian Jackson: Hacking my filter coffee machine

I hacked my coffee machine to let me turn it on from upstairs in bed :-). Read on for explanation, circuit diagrams, 3D models, firmware source code, and pictures. Background: the Morphy Richards filter coffee machine I have a Morphy Richards filter coffee machine. It makes very good coffee. But the display and firmware are quite annoying: Also, I m lazy and wanted to be able to cause coffee to exist from upstairs in bed, without having to make a special trip down just to turn the machine on. Planning My original feeling was I can t be bothered dealing with the coffee machine innards so I thought I would make a mechanical contraption to physically press the coffee machine s on button. I could have my contraption press the button to turn the machine on (timed, or triggered remotely), and then periodically in pairs to reset the 25-minute keep-warm timer. But a friend pointed me at a blog post by Andy Bradford, where Andy recounts modifying his coffee machine, adding an ESP8266 and connecting it to his MQTT-based Home Assistant setup. I looked at the pictures and they looked very similar to my machine. I decided to take a look inside. Inside the Morphy Richards filter coffee machine My coffee machine seemed to be very similar to Andy s. His disassembly report was very helpful. Inside I found the high-voltage parts with the heating elements, and the front panel with the display and buttons. I spent a while poking about, masuring things, and so on. Unexpected electrical hazard At one point I wanted to use my storage oscilloscope to capture the duration and amplitude of the beep signal. I needed to connect the scope ground to the UI board s ground plane, but then when I switched the coffee machine on at the wall socket, it tripped the house s RCD. It turns out that the low voltage UI board is coupled to the mains. In my setting, there s an offset of about 8V between the UI board ground plane, and true earth. (In my house the neutral is about 2-3V away from true earth.) This alarmed me rather. To me, this means that my modifications needed to still properly electrically isolate everything connected to the UI board from anything external to the coffee machine s housing. In Andy s design, I think the internal UI board ground plane is directly brought out to an external USB-A connector. This means that if there were a neutral fault, the USB-A connector would be at live potential, possibly creating an electrocution or fire hazard. I made a comment in Andy Bradford s blog, reporting this issue, but it doesn t seem to have appeared. This is all quite alarming. I hope Andy is OK! Design approach I don t have an MQTT setup at home, or an installation of Home Assistant. I didn t feel like adding a lot of complicated software to my life, if I could avoid it. Nor did I feel like writing a web UI myself. I ve done that before, but I m lazy and in this case my requirements were quite modest. Also, the need for electrical isolation would further complicate any attempt to do something sophisticated (that could, for example, sense the state of the coffee machine). I already had a Tasmota-based cloud-free smart plug, which controls the fairy lights on our gazebo. We just operate that through its web UI. So, I decided I would add a small and stupid microcontroller. The microcontroller would be powered via a smart plug and an off-the-shelf USB power supply. The microcontroller would have no inputs. It would simply simulate an on button press once at startup, and thereafter two presses every 24 minutes. After the 4th double press the microcontroller would stop, leaving the coffee machine to time out itself, after a total period of about 2h. Implementation - hardware I used a DigiSpark board with an ATTiny85. One of the GPIOs is connected to an optoisolator, whose output transistor is wired across the UI board s on button. circuit diagram; board layout diagram; (click for diagram scans as pdfs). The DigiSpark has just a USB tongue, which is very wobbly in a normal USB socket. I designed a 3D printed case which also had an approximation of the rest of the USB A plug. The plug is out of spec; our printer won t go fine enough - and anyway, the shield is supposed to be metal, not fragile plastic. But it fit in the USB PSU I was using, satisfactorily if a bit stiffly, and also into the connector for programming via my laptop. Inside the coffee machine, there s the boundary between the original, coupled to mains, UI board, and the isolated low voltage of the microcontroller. I used a reasonably substantial cable to bring out the low voltage connection, past all the other hazardous innards, to make sure it stays isolated. I added a drain power supply resistor on another of the GPIOs. This is enabled, with a draw of about 30mA, when the microcontroller is soon going to off / on cycle the coffee machine. That reduces the risk that the user will turn off the smart plug, and turn off the machine, but that the microcontroller turns the coffee machine back on again using the remaining power from USB PSU. Empirically in my setup it reduces the time from smart plug off to microcontroller stops from about 2-3s to more like 1s. Optoisolator board (inside coffee machine) pictures (Click through for full size images.) optoisolator board, front; optoisolator board, rear; optoisolator board, fitted. Microcontroller board (in USB-plug-ish housing) pictures microcontroller board, component side; microcontroller board, wiring side, part fitted; microcontroller in USB-plug-ish housing. Implementation - software I originally used the Arduino IDE, writing my program in C. I had a bad time with that and rewrote it in Rust. The firmware is in a repository on Debian s gitlab Results I can now cause the coffee to start, from my phone. It can be programmed more than 12h in advance. And it stays warm until we ve drunk it. UI is worse There s one aspect of the original Morphy Richards machine that I haven t improved: the user interface is still poor. Indeed, it s now even worse: To turn the machine on, you probably want to turn on the smart plug instead. Unhappily, the power button for that is invisible in its installed location. In particular, in the usual case, if you want to turn it off, you should ideally turn off both the smart plug (which can be done with the button on it) and the coffee machine itself. If you forget to turn off the smart plug, the machine can end up being turned on, very briefly, a handful of times, over the next hour or two. Epilogue We had used the new features a handful of times when one morning the coffee machine just wouldn t make coffee. The UI showed it turning on, but it wouldn t get hot, so no coffee. I thought oh no, I ve broken it! But, on investigation, I found that the machine s heating element was open circuit (ie, completely broken). I didn t mess with that part. So, hooray! Not my fault. Probably, just being inverted a number of times and generally lightly jostled, had precipitated a latent fault. The machine was a number of years old. Happily I found a replacement, identical, machine, online. I ve transplanted my modification and now it all works well. Bonus pictures (Click through for full size images.) probing the innards; machine base showing new cable route.
edited 2023-11-26 14:59 UTC in an attempt to fix TOC links


comment count unavailable comments

25 November 2023

Andrew Cater: Laptop with ARM, mobile phone BoF - MiniDebConf Cambridge day 1

So following Emanuele's talk on a Lenovo X13s, we're now at the Debian on Mobile BoF (Birds of a feather) discussion session from Arnaud Ferraris
Discussion and questions on how best to support many variants of mobile phones: the short answer seems to be "it's still *hard* - too many devices around to add individual tweaks for every phone and manufacturer.One thing that may not have been audible in the video soundtrack - lots of laughter in the room prompted as someone's device said, audibly "You are not allowed to do that without unlocking your device"Upstream and downstream packages for hardware enablement are also hard: basic support is sometimes easy but that might even include non-support for charging, for example.Much discussion around the numbers of kernels and kernel image proliferation there could be. Debian tends to prefer *one* way of doing things with kernels.Abstracting hardware is the hardest thing but leads to huge kernels - there's no easy trade-off. Simple/feasible in multiple end user devices/supportable - pick one

23 November 2023

Bits from Debian: archive.debian.org rsync address change

The proposed and previously announced changes to the rsync service have become effective with the rsync://archive.debian.org address now being discontinued. The worldwide Debian mirrors network has served archive.debian.org via both HTTP and rsync. As part of improving the reliability of the service for users, the Debian mirrors team is separating the access methods to different host names: rsync service on archive.debian.org has stopped, and we encourage anyone using the service to migrate to the new host name as soon as possible. If you are currently using rsync to the debian-archive from a debian.org server that forms part of the archive.debian.org rotation, we also encourage Administrators to move to the new service name. This will allow us to better manage which back-end servers offer rsync service in future. Note that due to its nature the content of archive.debian.org does not change frequently - generally there will be several months, possibly more than a year, between updates - so checking for updates more than once a day is unnecessary. For additional information please reach out to the Debian Mirrors Team maillist.

Freexian Collaborators: Debian Contributions: Preparing for Python 3.12, /usr-merge updates, invalid PEP-440 versions, and more! (by Utkarsh Gupta)

Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

urllib3 s old security patch by Stefano Rivera Stefano ran into a test-suite failure in a new Debian package (python-truststore), caused by Debian s patch to urllib3 from a decade ago, making it enable TLS verification by default (remember those days!). Some analysis confirmed that this patch isn t useful any more, and could be removed. While working on the package, Stefano investigated the scope of the urllib3 2.x transition. It looks ready to start, not many packages are affected.

Preparing for Python 3.12 in dh-python by Stefano Rivera We are preparing to start the Python 3.12 transition in Debian. Two of the upstream changes that are going to cause a lot of packages to break could be worked-around in dh-python, so we did:
  • Distutils is no longer shipped in the Python stdlib. Packages need to Build-Depend on python3-setuptools to get a (compatibility shim) distutils. Until that happens, dh-python will Depend on setuptools.
  • A failure to find any tests to execute will now make the unittest runner exit 5, like pytest does. This was our change, to test-suites that have failed to be automatically discovered. It will cause many packages to fail to build, so until they explicitly skip running test suites, dh-python will ignore these failures.

/usr-merge by Helmut Grohne It has become clear that the planned changes to debhelper and systemd.pc cause more rc-bugs. Helmut researched these systematically and filed another stack of patches. At the time of this writing, the uploads would still cause about 40 rc-bugs. A new opt-in helper dh_movetousr has been developed and added to debhelper in trixie and unstable.

debian-printing, by Thorsten Alteholz This month Thorsten adopted two packages, namely rlpr and lprng, and moved them to the debian-printing team. As part of this Thorsten could close eight bugs in the BTS. Thorsten also uploaded a new upstream version of cups, which also meant that eleven bugs could be closed. As package hannah-foo2zjs still depended on the deprecated policykit-1 package, Thorsten changed the dependency list accordingly and could close one RC bug by the following upload.

Invalid PEP-440 Versions in Python Packages by Stefano Rivera Stefano investigated how many packages in Debian (typically Debian-native packages) recorded versions in their packaging metadata (egg-info directories) that weren t valid PEP-440 Python versions. pip is starting to enforce that all versions on the system are valid.

Miscellaneous contributions
  • distro-info-data updates in Debian, due to the new Ubuntu release, by Stefano.
  • DebConf 23 bookkeeping continues, but is winding down. Stefano still spends a little time on it.
  • Utkarsh continues to monitor and help with reimbursements.
  • Helmut continues to maintain architecture bootstrap and accidentally broke pam briefly
  • Anton uploaded boost1.83 and started to prepare a transition to make boost1.83 as a default boost version.
  • Rejuntada Debian UY 2023, a MiniDebConf that will be held in Montevideo, from 9 to 11 November, mainly organized by Santiago.

Next.

Previous.