Search Results: "ed"

20 October 2025

Dirk Eddelbuettel: RcppArmadillo 15.2.0-0 on GitHub: New Upstream, Simpler OpenMP

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1270 other packages on CRAN, downloaded 42 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 650 times according to Google Scholar. This versions updates to the 15.2.0 upstream release made today. It brings a few changes over Armadillo 15.0 (see below for more). It follows the most recent RcppArmadillo 15.0.2-2 release and the Armadillo 15 upstream transition with its dual focus on moving on from C++11 and deprecation of a number of API access points. As we had a few releases last month to manage the transition, we will sit this upgrade out and not upload to CRAN in order to normalize our update cadence towards the desired about six in six months (that the CRAN Policy asks for). One can of course install as usual directly from the GitHub repository as well as from r-universe which also offers binaries for all CRAN platforms. The transition to Armadillo 15 appears to be going slowly but steadily. We had well over 300 packages with either a need to relax the C++11 setting and/or update away from now-deprecated API access points. That number has been cut in half thanks to a lot of work from a lot of package maintainers which is really appreciated! Of course, a lot remains to be done. Issues #489 and #491 contain the over sixty PRs and patches I prepared for all packages with at least one reverse dependency. Most (but not all) have aided in CRAN updates, some packages are still outstanding in terms of updates. As before meta-issue #475 regroups all the resources for the transition. If you, dear reader, have a package that is affected and I could be of assistance please do reach out. The other change we made is to greatly simplify the detection and setup of OpenMP. As before, we rely on configure to attempt compilation of a minimal OpenMP-using program in order to pass the success or failure onto Armadillo as a can-or-cannot use OpenMP. In the year 2025 one of the leading consumer brands still cannot ship an OS where this works out of the box, so we try to aide there. For all others systems, R actually covers this pretty well and has a reliable configuration variable that we rely upon. Just as we recommend for downstream users of the package. This setup should be robust, but is a change so by all means if you knowingly rely on OpenMP please test and report back. The detailed changes since the last CRAN release follow.

Changes in RcppArmadillo version 15.2.0-0 (2025-10-20) (GitHub Only)
  • Upgraded to Armadillo release 15.2.0 (Medium Roast Deluxe)
    • Added rande() for generating matrices with elements from exponential distributions
    • shift() has been deprecated in favour of circshift(), for consistency with Matlab/Octave
    • Reworked detection of aliasing, leading to more efficient compiled code
  • OpenMP detection in configure has been simplified

More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Birger Schacht: A plea for <dialog>

A couple of weeks ago there was an article on the Freexian blog about Using JavaScript in Debusine without depending on JavaScript. It describes how JavaScript is used in the Debusine Django app, namely for progressive enhancement rather than core functionality . This is an approach I also follow when implementing web interfaces and I think developments in web technologies and standardization in recent years have made this a lot easier. One of the examples described in the post, the Bootstrap toast messages, was something that I implemented myself recently, in a similar but slightly different way. In the main app I develop for my day job we also use the Bootstrap framework. I have also used it for different personal projects (for example the GSOC project I did for Debian in 2018, was also a Django app that used Bootstrap). Bootstrap is still primarily a CSS framework, but it also comes with a JavaScript library for some functionality. Previous versions of Bootstrap depended on jQuery, but since version 5 of Bootstrap, you don t need jQuery anymore. In my experience, two of the more commonly used JavaScript utilities of Bootstrap are modals (also called lightbox or popup, they are elements that are displayed above the main content of a website) and toasts (also called alerts, they are little notification windows that often disappear after a timeout). The thing is, Bootstrap 5 was released in 2021 and a lot has happened since then regarding web technologies. I believe that both these UI components can nowadays be implemented using standard HTML5 elements. An eye opening talk I watched was Stop using JS for that from last years JSConf(!). In this talk the speaker argues that the Rule of least power is one of the core principles of web development, which means we should use HTML over CSS and CSS over JavaScript. And the speaker also presents some CSS rules and HTML elements that added recently and that help to make that happen, one of them being the dialog element:
The <dialog> HTML element represents a modal or non-modal dialog box or other interactive component, such as a dismissible alert, inspector, or subwindow. The Dialog element at MDN
The baseline for this element is widely available :
This feature is well established and works across many devices and browser versions. It s been available across browsers since March 2022. The Dialog element at MDN
This means there is an HTML element that does what a modal Bootstrap does! Once I had watched that talk I removed all my Bootstrap modals and replaced them with HTML <dialog> elements (JavaScript is still needed to .show() and .close() the elements, though, but those are two methods instead of a full library). This meant not only that I replaced code that depended on an external library, I m now also a lot more flexible regarding the styling of the elements. When I started implementing notifications for our app, my first approach was to use Bootstrap toasts, similar to how it is implemented in Debusine. But looking at the amount of HTML code I had to write for a simple toast message, I thought that it might be possible to also implement toasts with the <dialog> element. I mean, basically it is the same, only the styling is a bit different. So what I did was that I added a #snackbar area to the DOM of the app. This would be the container for the toast messages. All the toast messages are simply <dialog> elements with the open attribute, which means that they are visible right away when the page loads.
<div id="snackbar">
   % for message in messages % 
    <dialog class="mytoast alert alert-  message.tags  " role="alert" open>
        message  
    </dialog>
   % endfor % 
</div>
This looks a lot simpler than the Bootstrap toasts would have. To make the <dialog> elements a little bit more fancy, I added some CSS to make them fade in and out:
.mytoast  
    z-index: 1;
    animation: fadein 0.5s, fadeout 0.5s 2.6s;
 
@keyframes fadein  
    from  
        opacity: 0;
     
    to  
        opacity: 1;
     
 
@keyframes fadeout  
    from  
        opacity: 1;
     
    to  
        opacity: 0;
     
 
To close a <dialog> element once it has faded away, I had to add one JavaScript event listener:
window.addEventListener('load', () =>  
    document.querySelectorAll(".mytoast").forEach((element) =>  
        element.addEventListener('animationend', function(e)  
            e.animationName == "fadeout" && element.close();
         );
     );
 );
(If one would want to use the same HTML code for both script and noscript users, then the CSS should probably adapted: it fades away and if there is no JavaScript to close the element, it stays visible after the animation is over. A solution would for example be to use a close button and for noscript users simply let it stay visible - this is also what happens with the noscript messages in Debusine). So there are many new elements in HTML and a lot of new features of CSS. It makes sense to sometimes ask ourselves if instead of the solutions we know (or what a web search / some AI shows us as the most common solution) there might be some newer solution that was not there when the first choice was created. Using standardized solutions instead of custom libraries makes the software more maintainable. In web development I also prefer standardized elements over a third party library because they have usually better accessibility and UX. In How Functional Programming Shaped (and Twisted) Frontend Development the author writes:
Consider the humble modal dialog. The web has <dialog>, a native element with built-in functionality: it manages focus trapping, handles Escape key dismissal, provides a backdrop, controls scroll-locking on the body, and integrates with the accessibility tree. It exists in the DOM but remains hidden until opened. No JavaScript mounting required. [ ] you ve trained developers to not even look for native solutions. The platform becomes invisible. When someone asks how do I build a modal? , the answer is install a library or here s my custom hook, never use <dialog>. Ahmad Alfy

19 October 2025

Colin Watson: Mistaken dichotomies about dgit

In Could the XZ backdoor have been detected with better Git and Debian packaging practices? , Otto contrasts git-buildpackage managed git repositories with dgit managed repositories , saying that the dgit managed repositories cannot incorporate the upstream git history and are thus less useful for auditing the full software supply-chain in git . Otto does qualify this earlier with a package that has not had the history recorded in dgit earlier , but the last sentence of the section is a misleading oversimplification. It s true for repositories that have been synthesized by dgit (which indeed was the focus of that section of Otto s article), but it s not true in general for repositories that are managed by dgit. I suspect this was just slightly unclear writing, so I don t want to nitpick here, but rather to take the opportunity to try to clear up some misconceptions around dgit that I ve often heard at conferences and seen on mailing lists. I m not a dgit developer, although I m a happy user of it and I ve tried to help out in various design discussions over the years.
dgit and git-buildpackage sit at different layers It seems very common for people to think of git-buildpackage and dgit as alternatives, as the example I quoted at the start of this article suggests. It s really better to think of dgit as a separate and orthogonal layer. You can use dgit together with tools such as git-buildpackage. In that case, git-buildpackage handles the general shape of your git history, such as helping you to import new upstream versions, and dgit handles gatewaying between the archive and git. The advantages become evident when you start using tag2upload, in which case you can just use git debpush to push a tag and the tag2upload service deals with building the source package and uploading it to the archive for you. This is true regardless of how you put your package s git history together. (There s currently a wrinkle around pristine-tar support, so at the moment I personally tend to use dgit push-source for new upstream versions and git debpush for new Debian revisions, since I haven t yet convinced myself that I see no remaining value in pristine upstream tarballs.)
dgit supports complete history If the maintainer has never used dgit, and so dgit clone synthesizes a repository based on the current contents of the Debian archive, then there s indeed no useful history there; in that situation it doesn t go back and import everything from the snapshot archive the way that gbp import-dscs --debsnap does. However, if the maintainer uses dgit, then dgit s view will include more history, and it s absolutely possible for that to include complete upstream git history as well. Try this:
$ dgit clone man-db
canonical suite name for unstable is sid
fetching existing git history
last upload to archive: specified git info (debian)
downloading http://ftp.debian.org/debian//pool/main/m/man-db/man-db_2.13.1.orig.tar.xz...
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                                 Dload  Upload   Total   Spent    Left  Speed
100 2060k  100 2060k    0     0  4643k      0 --:--:-- --:--:-- --:--:-- 4652k
downloading http://ftp.debian.org/debian//pool/main/m/man-db/man-db_2.13.1.orig.tar.xz.asc...
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                                 Dload  Upload   Total   Spent    Left  Speed
100   833  100   833    0     0  16322      0 --:--:-- --:--:-- --:--:-- 16660
HEAD is now at 167835b0 releasing package man-db version 2.13.1-1
dgit ok: ready for work in man-db
$ git -C man-db log --graph --oneline   head
* 167835b0 releasing package man-db version 2.13.1-1
*   f7910493 New upstream release (2.13.1)
 \
  *   3073b72e Import man-db_2.13.1.orig.tar.xz
   \
    * 349ce503 Release man-db 2.13.1
    * 0d6635c1 Update Russian manual page translation
    * cbf87caf Update Italian translation
    * fb5c5017 Update German manual page translation
    * dae2057b Update Brazilian Portuguese manual page translation
That package uses git-dpm, since I prefer the way it represents patches. But it works fine with git-buildpackage too:
$ dgit clone isort
canonical suite name for unstable is sid
fetching existing git history
last upload to archive: specified git info (debian)
downloading http://ftp.debian.org/debian//pool/main/i/isort/isort_7.0.0.orig.tar.gz...
  % Total    % Received % Xferd  Average Speed   Time    Time     Time  Current
                                 Dload  Upload   Total   Spent    Left  Speed
100  786k  100  786k    0     0  1772k      0 --:--:-- --:--:-- --:--:-- 1774k
HEAD is now at f812aae releasing package isort version 7.0.0-1
dgit ok: ready for work in isort
$ git -C isort log --graph --oneline   head
* f812aae releasing package isort version 7.0.0-1
*   efde62f Update upstream source from tag 'upstream/7.0.0'
 \
  * 9694f3d New upstream version 7.0.0
*   9cbfe0b releasing package isort version 6.1.0-1
*   5423ffe Mark isort and python3-isort Multi-Arch: foreign
*   5eaf5bf Update upstream source from tag 'upstream/6.1.0'
 \ 
  * edafbfc New upstream version 6.1.0
*     aedfd25 Merge branch 'debian/master' into fix992793
If you look closely you ll see another difference here: the second only includes one commit representing the new upstream release, and doesn t have complete upstream history. This doesn t represent a difference between git-dpm and git-buildpackage. Both tools can operate in both ways: for example, git-dpm import-new-upstream --parent and gbp import-orig --upstream-vcs-tag do broadly similar things, and something like gbp import-dscs --debsnap --upstream-vcs-tag='%(version)s' can be used to do a bulk import provided that upstream s tags are named consistently enough. This is not generally the default because adding complete upstream history requires extra setup: the maintainer has to add an extra git remote pointing to upstream and select the correct tag when importing a new version, and some upstreams forget to push git tags or don t have the sort of consistency you might want. The Debian Python team s policy says that Complete upstream Git history should be avoided in the upstream branch , which is why the isort history above looks the way it does. I don t love this because I think the results are less useful, but I understand why it s there: in a moderately large team maintaining thousands of packages, getting everyone to have the right git remotes set up would be a recipe for frustrating inconsistency. However, in packages I maintain myself, I strongly value having complete upstream history in order to make it easier to debug problems, and I think it makes things a bit more transparent to auditors too, so I m willing to go to a little extra work to make that happen. Doing that is completely compatible with using dgit.

Otto Kek l inen: Could the XZ backdoor have been detected with better Git and Debian packaging practices?

Featured image of post Could the XZ backdoor have been detected with better Git and Debian packaging practices?The discovery of a backdoor in XZ Utils in the spring of 2024 shocked the open source community, raising critical questions about software supply chain security. This post explores whether better Debian packaging practices could have detected this threat, offering a guide to auditing packages and suggesting future improvements. The XZ backdoor in versions 5.6.0/5.6.1 made its way briefly into many major Linux distributions such as Debian and Fedora, but luckily didn t reach that many actual users, as the backdoored releases were quickly removed thanks to the heroic diligence of Andres Freund. We are all extremely lucky that he detected a half a second performance regression in SSH, cared enough to trace it down, discovered malicious code in the XZ library loaded by SSH, and reported promtly to various security teams for quick coordinated actions. This episode makes software engineers pondering the following questions: As a Debian Developer, I decided to audit the xz package in Debian, share my methodology and findings in this post, and also suggest some improvements on how the software supply-chain security could be tightened in Debian specifically. Note that the scope here is only to inspect how Debian imports software from its upstreams, and how they are distributed to Debian s users. This excludes the whole story of how to assess if an upstream project is following software development security best practices. This post doesn t discuss how to operate an individual computer running Debian to ensure it remains untampered as there are plenty of guides on that already.
Downloading Debian and upstream source packages Let s start by working backwards from what the Debian package repositories offer for download. As auditing binaries is extremely complicated, we skip that, and assume the Debian build hosts are trustworthy and reliably building binaries from the source packages, and the focus should be on auditing the source code packages. As with everything in Debian, there are multiple tools and ways to do the same thing, but in this post only one (and hopefully the best) way to do something is presented for brevity. The first step is to download the latest version and some past versions of the package from the Debian archive, which is easiest done with debsnap. The following command will download all Debian source packages of xz-utils from Debian release 5.2.4-1 onwards:
$ debsnap --verbose --first 5.2.4-1 xz-utils
Getting json https://snapshot.debian.org/mr/package/xz-utils/
...
Getting dsc file xz-utils_5.2.4-1.dsc: https://snapshot.debian.org/file/a98271e4291bed8df795ce04d9dc8e4ce959462d
Getting file xz-utils_5.2.4.orig.tar.xz.asc: https://snapshot.debian.org/file/59ccbfb2405abe510999afef4b374cad30c09275
Getting file xz-utils_5.2.4-1.debian.tar.xz: https://snapshot.debian.org/file/667c14fd9409ca54c397b07d2d70140d6297393f
source-xz-utils/xz-utils_5.2.4-1.dsc:
Good signature found
validating xz-utils_5.2.4.orig.tar.xz
validating xz-utils_5.2.4.orig.tar.xz.asc
validating xz-utils_5.2.4-1.debian.tar.xz
All files validated successfully.
Once debsnap completes there will be a subfolder source-<package name> with the following types of files:
  • *.orig.tar.xz: source code from upstream
  • *.orig.tar.xz.asc: detached signature (if upstream signs their releases)
  • *.debian.tar.xz: Debian packaging source, i.e. the debian/ subdirectory contents
  • *.dsc: Debian source control file, including signature by Debian Developer/Maintainer
Example:
$ ls -1 source-xz-utils/
...
xz-utils_5.6.4.orig.tar.xz
xz-utils_5.6.4.orig.tar.xz.asc
xz-utils_5.6.4-1.debian.tar.xz
xz-utils_5.6.4-1.dsc
xz-utils_5.8.0.orig.tar.xz
xz-utils_5.8.0.orig.tar.xz.asc
xz-utils_5.8.0-1.debian.tar.xz
xz-utils_5.8.0-1.dsc
xz-utils_5.8.1.orig.tar.xz
xz-utils_5.8.1.orig.tar.xz.asc
xz-utils_5.8.1-1.1.debian.tar.xz
xz-utils_5.8.1-1.1.dsc
xz-utils_5.8.1-1.debian.tar.xz
xz-utils_5.8.1-1.dsc
xz-utils_5.8.1-2.debian.tar.xz
xz-utils_5.8.1-2.dsc

Verifying authenticity of upstream and Debian sources using OpenPGP signatures As seen in the output of debsnap, it already automatically verifies that the downloaded files match the OpenPGP signatures. To have full clarity on what files were authenticated with what keys, we should verify the Debian packagers signature with:
$ gpg --verify --auto-key-retrieve --keyserver hkps://keyring.debian.org xz-utils_5.8.1-2.dsc
gpg: Signature made Fri Oct 3 22:04:44 2025 UTC
gpg: using RSA key 57892E705233051337F6FDD105641F175712FA5B
gpg: requesting key 05641F175712FA5B from hkps://keyring.debian.org
gpg: key 7B96E8162A8CF5D1: public key "Sebastian Andrzej Siewior" imported
gpg: Total number processed: 1
gpg: imported: 1
gpg: Good signature from "Sebastian Andrzej Siewior" [unknown]
gpg: aka "Sebastian Andrzej Siewior <bigeasy@linutronix.de>" [unknown]
gpg: aka "Sebastian Andrzej Siewior <sebastian@breakpoint.cc>" [unknown]
gpg: WARNING: This key is not certified with a trusted signature!
gpg: There is no indication that the signature belongs to the owner.
Primary key fingerprint: 6425 4695 FFF0 AA44 66CC 19E6 7B96 E816 2A8C F5D1
Subkey fingerprint: 5789 2E70 5233 0513 37F6 FDD1 0564 1F17 5712 FA5B
The upstream tarball signature (if available) can be verified with:
$ gpg --verify --auto-key-retrieve xz-utils_5.8.1.orig.tar.xz.asc
gpg: assuming signed data in 'xz-utils_5.8.1.orig.tar.xz'
gpg: Signature made Thu Apr 3 11:38:23 2025 UTC
gpg: using RSA key 3690C240CE51B4670D30AD1C38EE757D69184620
gpg: key 38EE757D69184620: public key "Lasse Collin <lasse.collin@tukaani.org>" imported
gpg: Total number processed: 1
gpg: imported: 1
gpg: Good signature from "Lasse Collin <lasse.collin@tukaani.org>" [unknown]
gpg: WARNING: This key is not certified with a trusted signature!
gpg: There is no indication that the signature belongs to the owner.
Primary key fingerprint: 3690 C240 CE51 B467 0D30 AD1C 38EE 757D 6918 4620
Note that this only proves that there is a key that created a valid signature for this content. The authenticity of the keys themselves need to be validated separately before trusting they in fact are the keys of these people. That can be done by checking e.g. the upstream website for what key fingerprints they published, or the Debian keyring for Debian Developers and Maintainers, or by relying on the OpenPGP web-of-trust .

Verifying authenticity of upstream sources by comparing checksums In case the upstream in question does not publish release signatures, the second best way to verify the authenticity of the sources used in Debian is to download the sources directly from upstream and compare that the sha256 checksums match. This should be done using the debian/watch file inside the Debian packaging, which defines where the upstream source is downloaded from. Continuing on the example situation above, we can unpack the latest Debian sources, enter and then run uscan to download:
$ tar xvf xz-utils_5.8.1-2.debian.tar.xz
...
debian/rules
debian/source/format
debian/source.lintian-overrides
debian/symbols
debian/tests/control
debian/tests/testsuite
debian/upstream/signing-key.asc
debian/watch
...
$ uscan --download-current-version --destdir /tmp
Newest version of xz-utils on remote site is 5.8.1, specified download version is 5.8.1
gpgv: Signature made Thu Apr 3 11:38:23 2025 UTC
gpgv: using RSA key 3690C240CE51B4670D30AD1C38EE757D69184620
gpgv: Good signature from "Lasse Collin <lasse.collin@tukaani.org>"
Successfully symlinked /tmp/xz-5.8.1.tar.xz to /tmp/xz-utils_5.8.1.orig.tar.xz.
The original files downloaded from upstream are now in /tmp along with the files renamed to follow Debian conventions. Using everything downloaded so far the sha256 checksums can be compared across the files and also to what the .dsc file advertised:
$ ls -1 /tmp/
xz-5.8.1.tar.xz
xz-5.8.1.tar.xz.sig
xz-utils_5.8.1.orig.tar.xz
xz-utils_5.8.1.orig.tar.xz.asc
$ sha256sum xz-utils_5.8.1.orig.tar.xz /tmp/xz-5.8.1.tar.xz
0b54f79df85912504de0b14aec7971e3f964491af1812d83447005807513cd9e xz-utils_5.8.1.orig.tar.xz
0b54f79df85912504de0b14aec7971e3f964491af1812d83447005807513cd9e /tmp/xz-5.8.1.tar.xz
$ grep -A 3 Sha256 xz-utils_5.8.1-2.dsc
Checksums-Sha256:
0b54f79df85912504de0b14aec7971e3f964491af1812d83447005807513cd9e 1461872 xz-utils_5.8.1.orig.tar.xz
4138f4ceca1aa7fd2085fb15a23f6d495d27bca6d3c49c429a8520ea622c27ae 833 xz-utils_5.8.1.orig.tar.xz.asc
3ed458da17e4023ec45b2c398480ed4fe6a7bfc1d108675ec837b5ca9a4b5ccb 24648 xz-utils_5.8.1-2.debian.tar.xz
In the example above the checksum 0b54f79df85... is the same across the files, so it is a match.

Repackaged upstream sources can t be verified as easily Note that uscan may in rare cases repackage some upstream sources, for example to exclude files that don t adhere to Debian s copyright and licensing requirements. Those files and paths would be listed under the Files-Excluded section in the debian/copyright file. There are also other situations where the file that represents the upstream sources in Debian isn t bit-by-bit the same as what upstream published. If checksums don t match, an experienced Debian Developer should review all package settings (e.g. debian/source/options) to see if there was a valid and intentional reason for divergence.

Reviewing changes between two source packages using diffoscope Diffoscope is an incredibly capable and handy tool to compare arbitrary files. For example, to view a report in HTML format of the differences between two XZ releases, run:
diffoscope --html-dir xz-utils-5.6.4_vs_5.8.0 xz-utils_5.6.4.orig.tar.xz xz-utils_5.8.0.orig.tar.xz
browse xz-utils-5.6.4_vs_5.8.0/index.html
Inspecting diffoscope output of differences between two XZ Utils releases If the changes are extensive, and you want to use a LLM to help spot potential security issues, generate the report of both the upstream and Debian packaging differences in Markdown with:
diffoscope --markdown diffoscope-debian.md xz-utils_5.6.4-1.debian.tar.xz xz-utils_5.8.1-2.debian.tar.xz
diffoscope --markdown diffoscope.md xz-utils_5.6.4.orig.tar.xz xz-utils_5.8.0.orig.tar.xz
The Markdown files created above can then be passed to your favorite LLM, along with a prompt such as:
Based on the attached diffoscope output for a new Debian package version compared with the previous one, list all suspicious changes that might have introduced a backdoor, followed by other potential security issues. If there are none, list a short summary of changes as the conclusion.

Reviewing Debian source packages in version control As of today only 93% of all Debian source packages are tracked in git on Debian s GitLab instance at salsa.debian.org. Some key packages such as Coreutils and Bash are not using version control at all, as their maintainers apparently don t see value in using git for Debian packaging, and the Debian Policy does not require it. Thus, the only reliable and consistent way to audit changes in Debian packages is to compare the full versions from the archive as shown above. However, for packages that are hosted on Salsa, one can view the git history to gain additional insight into what exactly changed, when and why. For packages that are using version control, their location can be found in the Git-Vcs header in the debian/control file. For xz-utils the location is salsa.debian.org/debian/xz-utils. Note that the Debian policy does not state anything about how Salsa should be used, or what git repository layout or development practices to follow. In practice most packages follow the DEP-14 proposal, and use git-buildpackage as the tool for managing changes and pushing and pulling them between upstream and salsa.debian.org. To get the XZ Utils source, run:
$ gbp clone https://salsa.debian.org/debian/xz-utils.git
gbp:info: Cloning from 'https://salsa.debian.org/debian/xz-utils.git'
At the time of writing this post the git history shows:
$ git log --graph --oneline
* bb787585 (HEAD -> debian/unstable, origin/debian/unstable, origin/HEAD) Prepare 5.8.1-2
* 4b769547 d: Remove the symlinks from -dev package.
* a39f3428 Correct the nocheck build profile
* 1b806b8d Import Debian changes 5.8.1-1.1
* b1cad34b Prepare 5.8.1-1
* a8646015 Import 5.8.1
* 2808ec2d Update upstream source from tag 'upstream/5.8.1'
 \
  * fa1e8796 (origin/upstream/v5.8, upstream/v5.8) New upstream version 5.8.1
  * a522a226 Bump version and soname for 5.8.1
  * 1c462c2a Add NEWS for 5.8.1
  * 513cabcf Tests: Call lzma_code() in smaller chunks in fuzz_common.h
  * 48440e24 Tests: Add a fuzzing target for the multithreaded .xz decoder
  * 0c80045a liblzma: mt dec: Fix lack of parallelization in single-shot decoding
  * 81880488 liblzma: mt dec: Don't modify thr->in_size in the worker thread
  * d5a2ffe4 liblzma: mt dec: Don't free the input buffer too early (CVE-2025-31115)
  * c0c83596 liblzma: mt dec: Simplify by removing the THR_STOP state
  * 831b55b9 liblzma: mt dec: Fix a comment
  * b9d168ee liblzma: Add assertions to lzma_bufcpy()
  * c8e0a489 DOS: Update Makefile to fix the build
  * 307c02ed sysdefs.h: Avoid <stdalign.h> even with C11 compilers
  * 7ce38b31 Update THANKS
  * 688e51bd Translations: Update the Croatian translation
*   a6b54dde Prepare 5.8.0-1.
*   77d9470f Add 5.8 symbols.
*   9268eb66 Import 5.8.0
*   6f85ef4f Update upstream source from tag 'upstream/5.8.0'
 \ \
  *   afba662b New upstream version 5.8.0
   /
  * 173fb5c6 doc/SHA256SUMS: Add 5.8.0
  * db9258e8 Bump version and soname for 5.8.0
  * bfb752a3 Add NEWS for 5.8.0
  * 6ccbb904 Translations: Run "make -C po update-po"
  * 891a5f05 Translations: Run po4a/update-po
  * 4f52e738 Translations: Partially fix overtranslation in Serbian man pages
  * ff5d9447 liblzma: Count the extra bytes in LZMA/LZMA2 decoder memory usage
  * 943b012d liblzma: Use SSE2 intrinsics instead of memcpy() in dict_repeat()
This shows both the changes on the debian/unstable branch as well as the intermediate upstream import branch, and the actual real upstream development branch. See my Debian source packages in git explainer for details of what these branches are used for. To only view changes on the Debian branch, run git log --graph --oneline --first-parent or git log --graph --oneline -- debian. The Debian branch should only have changes inside the debian/ subdirectory, which is easy to check with:
$ git diff --stat upstream/v5.8
debian/README.source   16 +++
debian/autogen.sh   32 +++++
debian/changelog   949 ++++++++++++++++++++++++++
...
debian/upstream/signing-key.asc   52 +++++++++
debian/watch   4 +
debian/xz-utils.README.Debian   47 ++++++++
debian/xz-utils.docs   6 +
debian/xz-utils.install   28 +++++
debian/xz-utils.postinst   19 +++
debian/xz-utils.prerm   10 ++
debian/xzdec.docs   6 +
debian/xzdec.install   4 +
33 files changed, 2014 insertions(+)
All the files outside the debian/ directory originate from upstream, and for example running git blame on them should show only upstream commits:
$ git blame CMakeLists.txt
22af94128 (Lasse Collin 2024-02-12 17:09:10 +0200 1) # SPDX-License-Identifier: 0BSD
22af94128 (Lasse Collin 2024-02-12 17:09:10 +0200 2)
7e3493d40 (Lasse Collin 2020-02-24 23:38:16 +0200 3) ###############
7e3493d40 (Lasse Collin 2020-02-24 23:38:16 +0200 4) #
426bdc709 (Lasse Collin 2024-02-17 21:45:07 +0200 5) # CMake support for building XZ Utils
If the upstream in question signs commits or tags, they can be verified with e.g.:
$ git verify-tag v5.6.2
gpg: Signature made Wed 29 May 2024 09:39:42 AM PDT
gpg: using RSA key 3690C240CE51B4670D30AD1C38EE757D69184620
gpg: issuer "lasse.collin@tukaani.org"
gpg: Good signature from "Lasse Collin <lasse.collin@tukaani.org>" [expired]
gpg: Note: This key has expired!
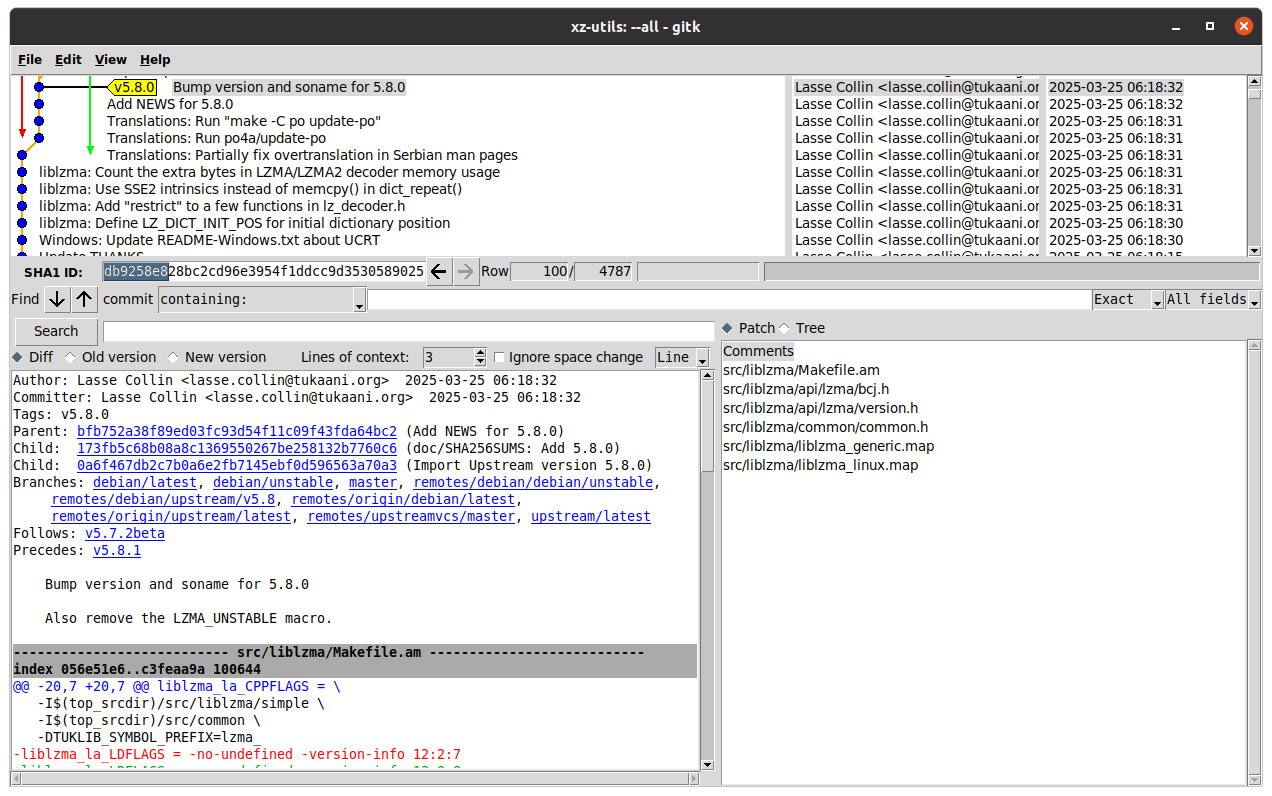
The main benefit of reviewing changes in git is the ability to see detailed information about each individual change, instead of just staring at a massive list of changes without any explanations. In this example, to view all the upstream commits since the previous import to Debian, one would view the commit range from afba662b New upstream version 5.8.0 to fa1e8796 New upstream version 5.8.1 with git log --reverse -p afba662b...fa1e8796. However, a far superior way to review changes would be to browse this range using a visual git history viewer, such as gitk. Either way, looking at one code change at a time and reading the git commit message makes the review much easier. Browsing git history in gitk --all

Comparing Debian source packages to git contents As stated in the beginning of the previous section, and worth repeating, there is no guarantee that the contents in the Debian packaging git repository matches what was actually uploaded to Debian. While the tag2upload project in Debian is getting more and more popular, Debian is still far from having any system to enforce that the git repository would be in sync with the Debian archive contents. To detect such differences we can run diff across the Debian source packages downloaded with debsnap earlier (path source-xz-utils/xz-utils_5.8.1-2.debian) and the git repository cloned in the previous section (path xz-utils):
diff
$ diff -u source-xz-utils/xz-utils_5.8.1-2.debian/ xz-utils/debian/
diff -u source-xz-utils/xz-utils_5.8.1-2.debian/changelog xz-utils/debian/changelog
--- debsnap/source-xz-utils/xz-utils_5.8.1-2.debian/changelog 2025-10-03 09:32:16.000000000 -0700
+++ xz-utils/debian/changelog 2025-10-12 12:18:04.623054758 -0700
@@ -5,7 +5,7 @@
 * Remove the symlinks from -dev, pointing to the lib package.
 (Closes: #1109354)

- -- Sebastian Andrzej Siewior <sebastian@breakpoint.cc> Fri, 03 Oct 2025 18:32:16 +0200
+ -- Sebastian Andrzej Siewior <sebastian@breakpoint.cc> Fri, 03 Oct 2025 18:36:59 +0200
In the case above diff revealed that the timestamp in the changelog in the version uploaded to Debian is different from what was committed to git. This is not malicious, just a mistake by the maintainer who probably didn t run gbp tag immediately after upload, but instead some dch command and ended up with having a different timestamps in the git compared to what was actually uploaded to Debian.

Creating syntetic Debian packaging git repositories If no Debian packaging git repository exists, or if it is lagging behind what was uploaded to Debian s archive, one can use git-buildpackage s import-dscs feature to create synthetic git commits based on the files downloaded by debsnap, ensuring the git contents fully matches what was uploaded to the archive. To import a single version there is gbp import-dsc (no s at the end), of which an example invocation would be:
$ gbp import-dsc --verbose ../source-xz-utils/xz-utils_5.8.1-2.dsc
Version '5.8.1-2' imported under '/home/otto/debian/xz-utils-2025-09-29'
Example commit history from a repository with commits added with gbp import-dsc:
$ git log --graph --oneline
* 86aed07b (HEAD -> debian/unstable, tag: debian/5.8.1-2, origin/debian/unstable) Import Debian changes 5.8.1-2
* f111d93b (tag: debian/5.8.1-1.1) Import Debian changes 5.8.1-1.1
* 1106e19b (tag: debian/5.8.1-1) Import Debian changes 5.8.1-1
 \
  * 08edbe38 (tag: upstream/5.8.1, origin/upstream/v5.8, upstream/v5.8) Import Upstream version 5.8.1
   \
    * a522a226 (tag: v5.8.1) Bump version and soname for 5.8.1
    * 1c462c2a Add NEWS for 5.8.1
    * 513cabcf Tests: Call lzma_code() in smaller chunks in fuzz_common.h
An online example repository with only a few missing uploads added using gbp import-dsc can be viewed at salsa.debian.org/otto/xz-utils-2025-09-29/-/network/debian%2Funstable An example repository that was fully crafted using gbp import-dscs can be viewed at salsa.debian.org/otto/xz-utils-gbp-import-dscs-debsnap-generated/-/network/debian%2Flatest. There exists also dgit, which in a similar way creates a synthetic git history to allow viewing the Debian archive contents via git tools. However, its focus is on producing new package versions, so fetching a package with dgit that has not had the history recorded in dgit earlier will only show the latest versions:
$ dgit clone xz-utils
canonical suite name for unstable is sid
starting new git history
last upload to archive: NO git hash
downloading http://ftp.debian.org/debian//pool/main/x/xz-utils/xz-utils_5.8.1.orig.tar.xz...
downloading http://ftp.debian.org/debian//pool/main/x/xz-utils/xz-utils_5.8.1.orig.tar.xz.asc...
downloading http://ftp.debian.org/debian//pool/main/x/xz-utils/xz-utils_5.8.1-2.debian.tar.xz...
dpkg-source: info: extracting xz-utils in unpacked
dpkg-source: info: unpacking xz-utils_5.8.1.orig.tar.xz
dpkg-source: info: unpacking xz-utils_5.8.1-2.debian.tar.xz
synthesised git commit from .dsc 5.8.1-2
HEAD is now at f9bcaf7 xz-utils (5.8.1-2) unstable; urgency=medium
dgit ok: ready for work in xz-utils
$ dgit/sid   git log --graph --oneline
* f9bcaf7 xz-utils (5.8.1-2) unstable; urgency=medium 9 days ago (HEAD -> dgit/sid, dgit/dgit/sid)
 \
  * 11d3a62 Import xz-utils_5.8.1-2.debian.tar.xz 9 days ago
* 15dcd95 Import xz-utils_5.8.1.orig.tar.xz 6 months ago
Unlike git-buildpackage managed git repositories, the dgit managed repositories cannot incorporate the upstream git history and are thus less useful for auditing the full software supply-chain in git.

Comparing upstream source packages to git contents Equally important to the note in the beginning of the previous section, one must also keep in mind that the upstream release source packages, often called release tarballs, are not guaranteed to have the exact same contents as the upstream git repository. Projects might strip out test data or extra development files from their release tarballs to avoid shipping unnecessary files to users, or projects might add documentation files or versioning information into the tarball that isn t stored in git. While a small minority, there are also upstreams that don t use git at all, so the plain files in a release tarball is still the lowest common denominator for all open source software projects, and exporting and importing source code needs to interface with it. In the case of XZ, the release tarball has additional version info and also a sizeable amount of pregenerated compiler configuration files. Detecting and comparing differences between git contents and tarballs can of course be done manually by running diff across an unpacked tarball and a checked out git repository. If using git-buildpackage, the difference between the git contents and tarball contents can be made visible directly in the import commit. In this XZ example, consider this git history:
* b1cad34b Prepare 5.8.1-1
* a8646015 Import 5.8.1
* 2808ec2d Update upstream source from tag 'upstream/5.8.1'
 \
  * fa1e8796 (debian/upstream/v5.8, upstream/v5.8) New upstream version 5.8.1
  * a522a226 (tag: v5.8.1) Bump version and soname for 5.8.1
  * 1c462c2a Add NEWS for 5.8.1
The commit a522a226 was the upstream release commit, which upstream also tagged v5.8.1. The merge commit 2808ec2d applied the new upstream import branch contents on the Debian branch. Between these is the special commit fa1e8796 New upstream version 5.8.1 tagged upstream/v5.8. This commit and tag exists only in the Debian packaging repository, and they show what is the contents imported into Debian. This is generated automatically by git-buildpackage when running git import-orig --uscan for Debian packages with the correct settings in debian/gbp.conf. By viewing this commit one can see exactly how the upstream release tarball differs from the upstream git contents (if at all). In the case of XZ, the difference is substantial, and shown below in full as it is very interesting:
$ git show --stat fa1e8796
commit fa1e8796dabd91a0f667b9e90f9841825225413a
(debian/upstream/v5.8, upstream/v5.8)
Author: Sebastian Andrzej Siewior <sebastian@breakpoint.cc>
Date: Thu Apr 3 22:58:39 2025 +0200
New upstream version 5.8.1
.codespellrc   30 -
.gitattributes   8 -
.github/workflows/ci.yml   163 -
.github/workflows/freebsd.yml   32 -
.github/workflows/netbsd.yml   32 -
.github/workflows/openbsd.yml   35 -
.github/workflows/solaris.yml   32 -
.github/workflows/windows-ci.yml   124 -
.gitignore   113 -
ABOUT-NLS   1 +
ChangeLog   17392 +++++++++++++++++++++
Makefile.in   1097 +++++++
aclocal.m4   1353 ++++++++
build-aux/ci_build.bash   286 --
build-aux/compile   351 ++
build-aux/config.guess   1815 ++++++++++
build-aux/config.rpath   751 +++++
build-aux/config.sub   2354 +++++++++++++
build-aux/depcomp   792 +++++
build-aux/install-sh   541 +++
build-aux/ltmain.sh   11524 ++++++++++++++++++++++
build-aux/missing   236 ++
build-aux/test-driver   160 +
config.h.in   634 ++++
configure   26434 ++++++++++++++++++++++
debug/Makefile.in   756 +++++
doc/SHA256SUMS   236 --
doc/man/txt/lzmainfo.txt   36 +
doc/man/txt/xz.txt   1708 ++++++++++
doc/man/txt/xzdec.txt   76 +
doc/man/txt/xzdiff.txt   39 +
doc/man/txt/xzgrep.txt   70 +
doc/man/txt/xzless.txt   36 +
doc/man/txt/xzmore.txt   31 +
lib/Makefile.in   623 ++++
m4/.gitignore   40 -
m4/build-to-host.m4   274 ++
m4/gettext.m4   392 +++
m4/host-cpu-c-abi.m4   529 +++
m4/iconv.m4   324 ++
m4/intlmacosx.m4   71 +
m4/lib-ld.m4   170 +
m4/lib-link.m4   815 +++++
m4/lib-prefix.m4   334 ++
m4/libtool.m4   8488 +++++++++++++++++++++
m4/ltoptions.m4   467 +++
m4/ltsugar.m4   124 +
m4/ltversion.m4   24 +
m4/lt~obsolete.m4   99 +
m4/nls.m4   33 +
m4/po.m4   456 +++
m4/progtest.m4   92 +
po/.gitignore   31 -
po/Makefile.in.in   517 +++
po/Rules-quot   66 +
po/boldquot.sed   21 +
po/ca.gmo   Bin 0 -> 15587 bytes
po/cs.gmo   Bin 0 -> 7983 bytes
po/da.gmo   Bin 0 -> 9040 bytes
po/de.gmo   Bin 0 -> 29882 bytes
po/en@boldquot.header   35 +
po/en@quot.header   32 +
po/eo.gmo   Bin 0 -> 15060 bytes
po/es.gmo   Bin 0 -> 29228 bytes
po/fi.gmo   Bin 0 -> 28225 bytes
po/fr.gmo   Bin 0 -> 10232 bytes
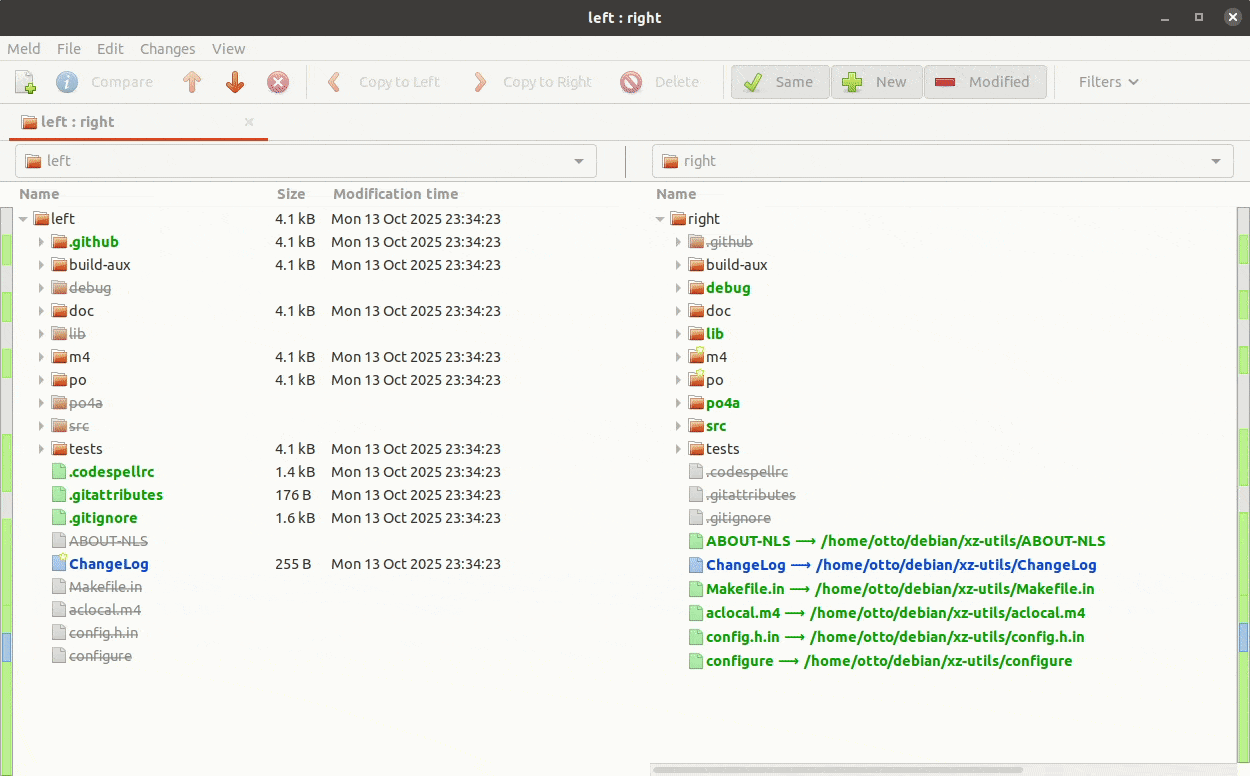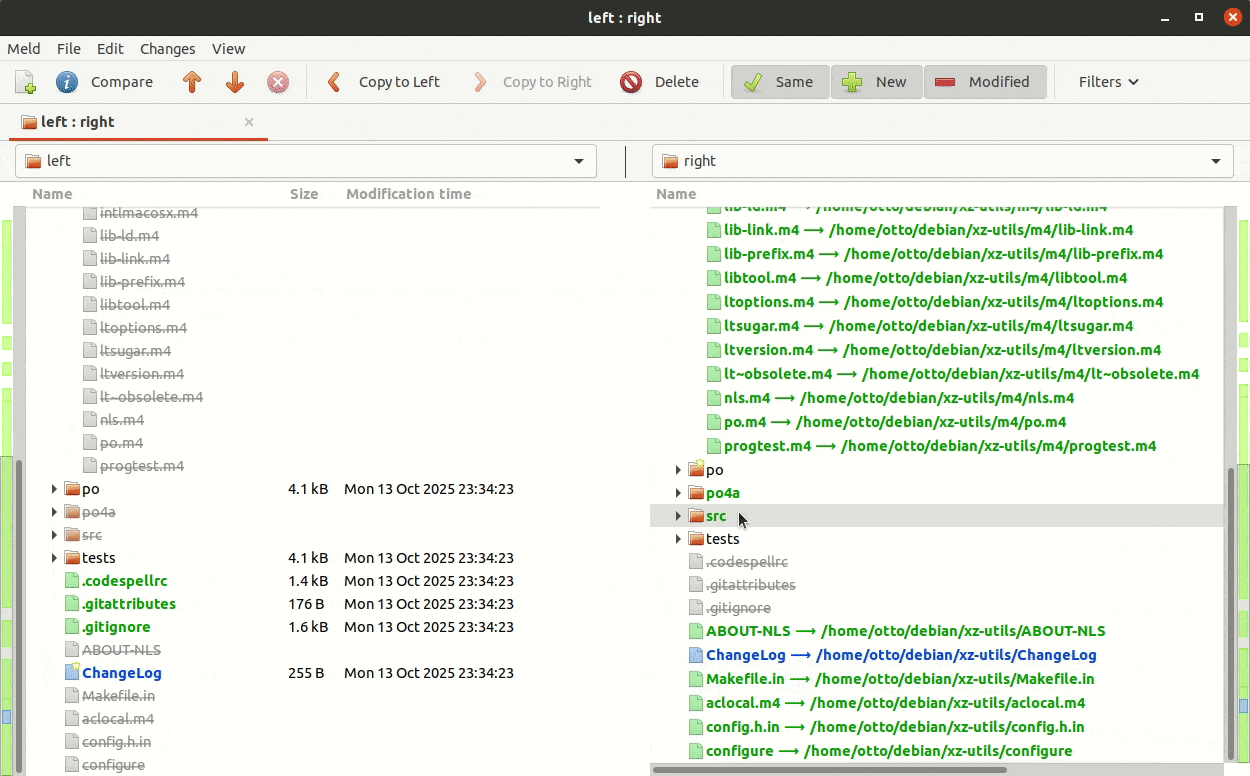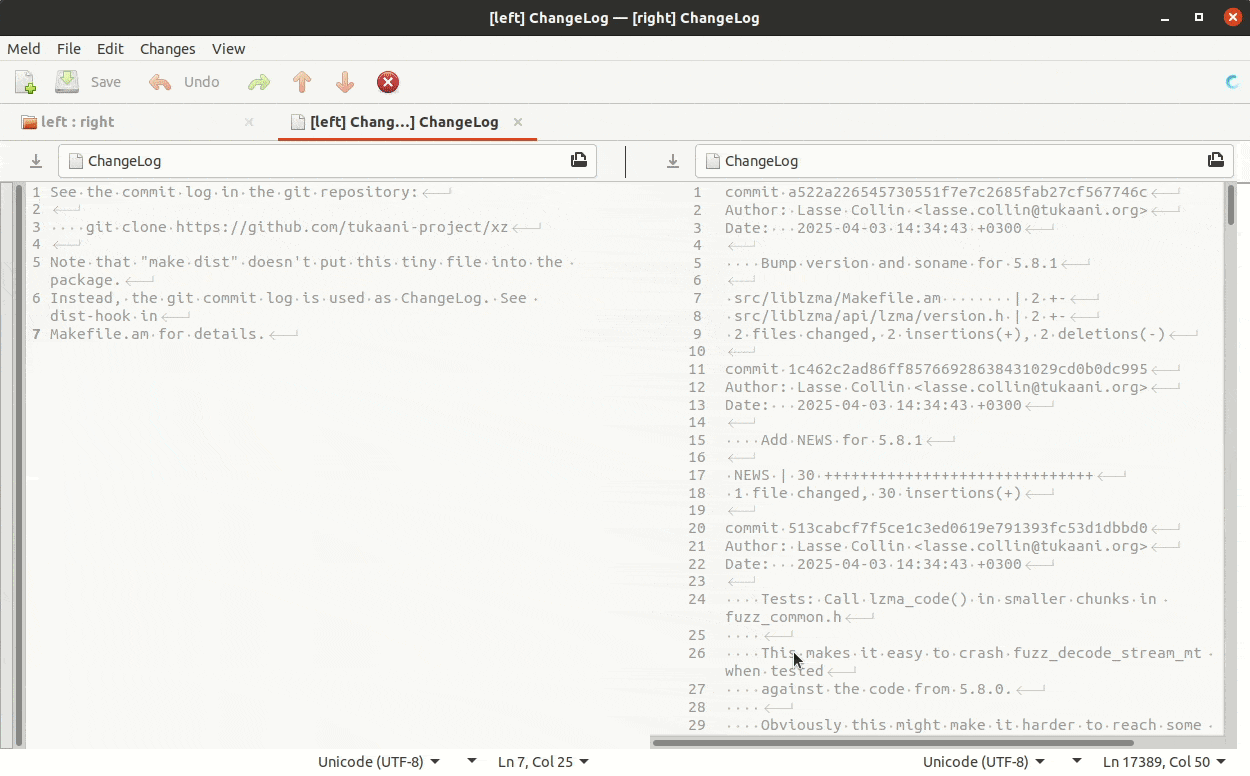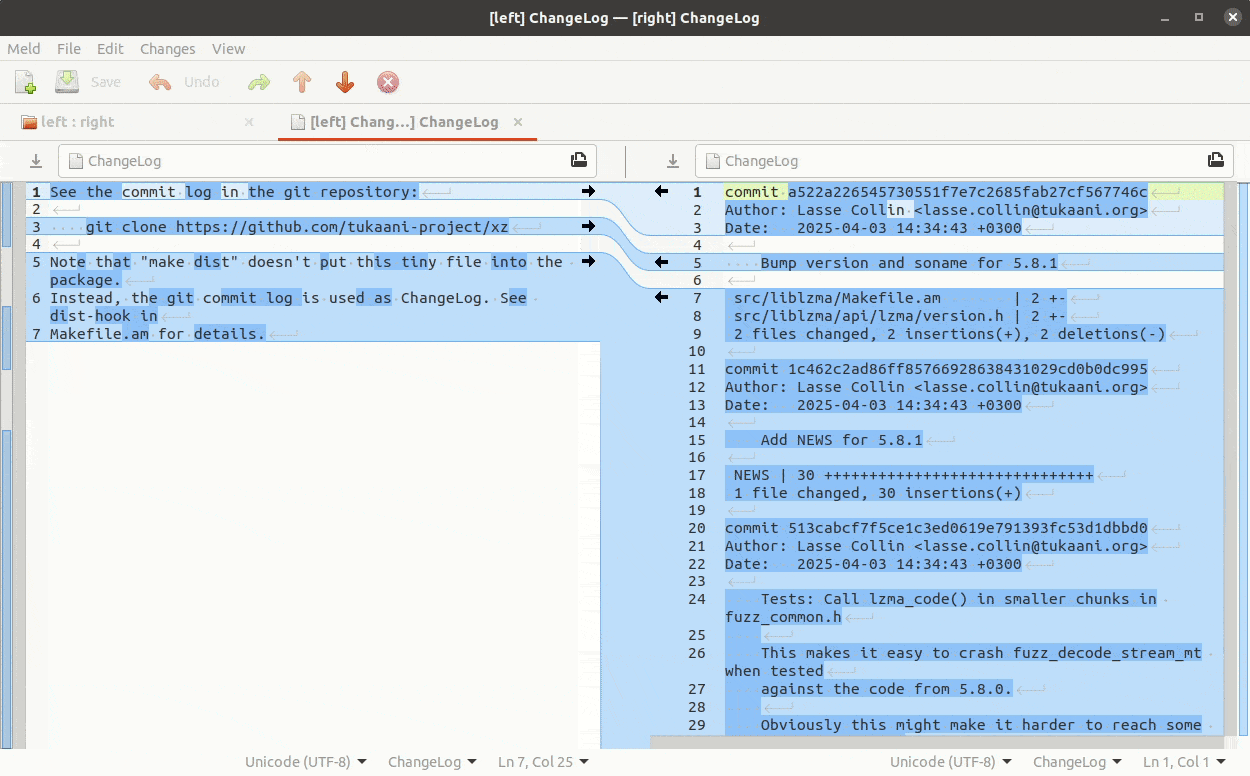
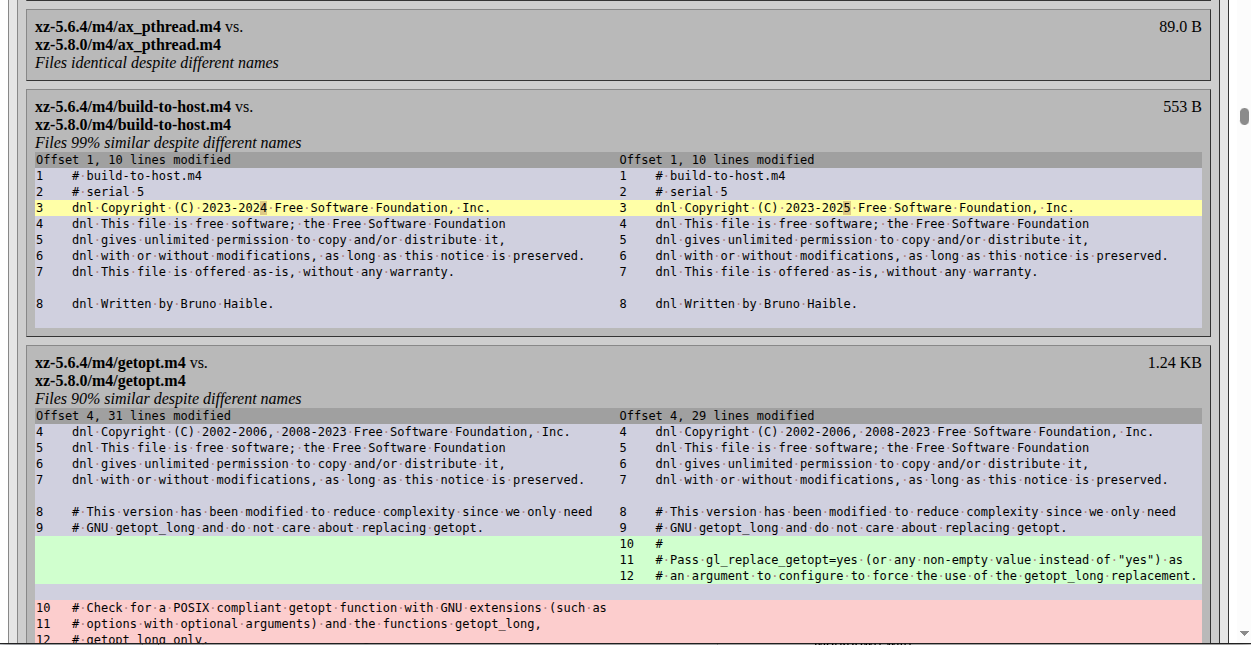
To be able to easily inspect exactly what changed in the release tarball compared to git release tag contents, the best tool for the job is Meld, invoked via git difftool --dir-diff fa1e8796^..fa1e8796. Meld invoked by git difftool --dir-diff afba662b..fa1e8796 to show differences between git release tag and release tarball contents To compare changes across the new and old upstream tarball, one would need to compare commits afba662b New upstream version 5.8.0 and fa1e8796 New upstream version 5.8.1 by running git difftool --dir-diff afba662b..fa1e8796. Meld invoked by git difftool --dir-diff afba662b..fa1e8796 to show differences between to upstream release tarball contents With all the above tips you can now go and try to audit your own favorite package in Debian and see if it is identical with upstream, and if not, how it differs.
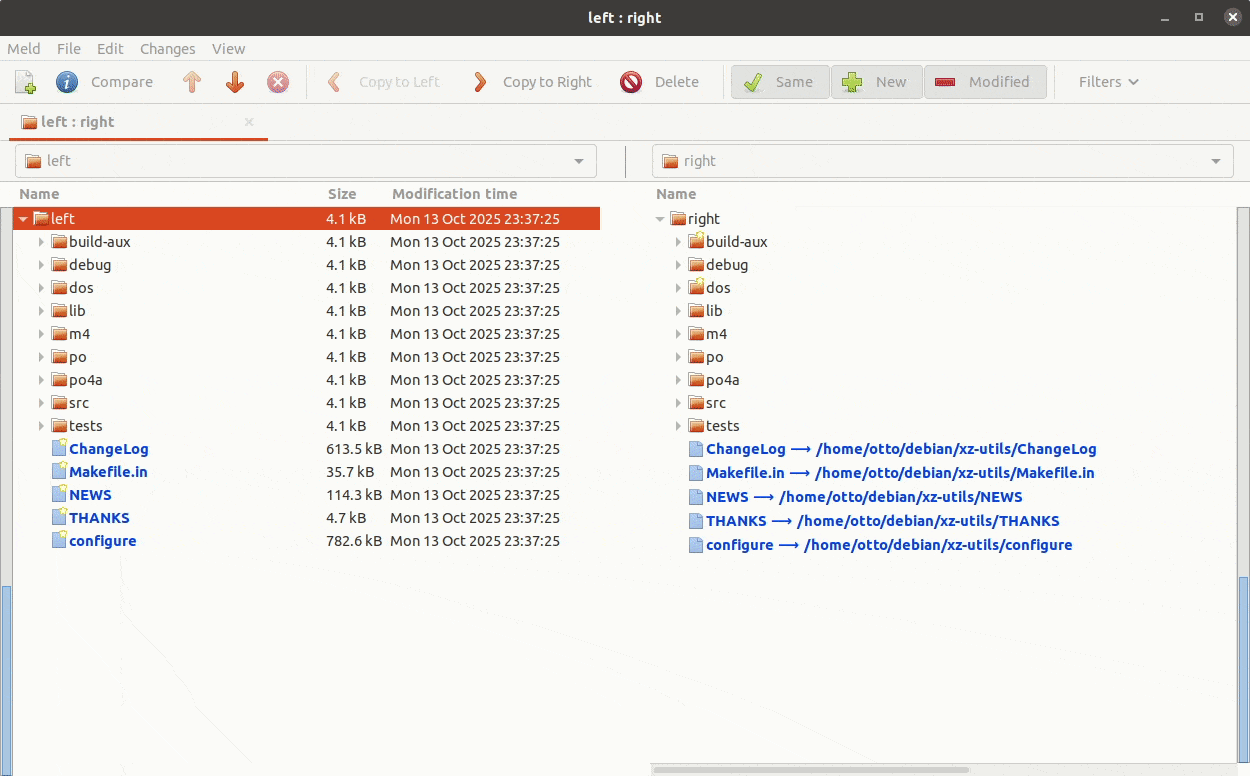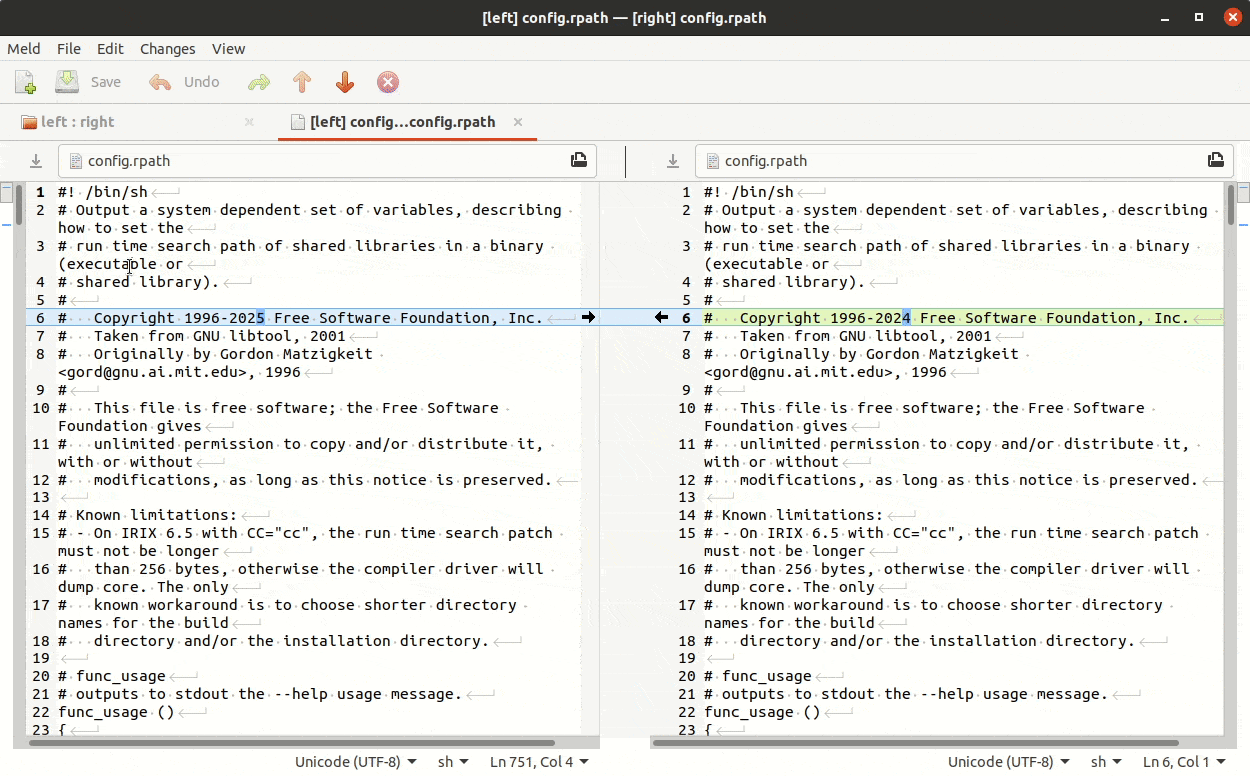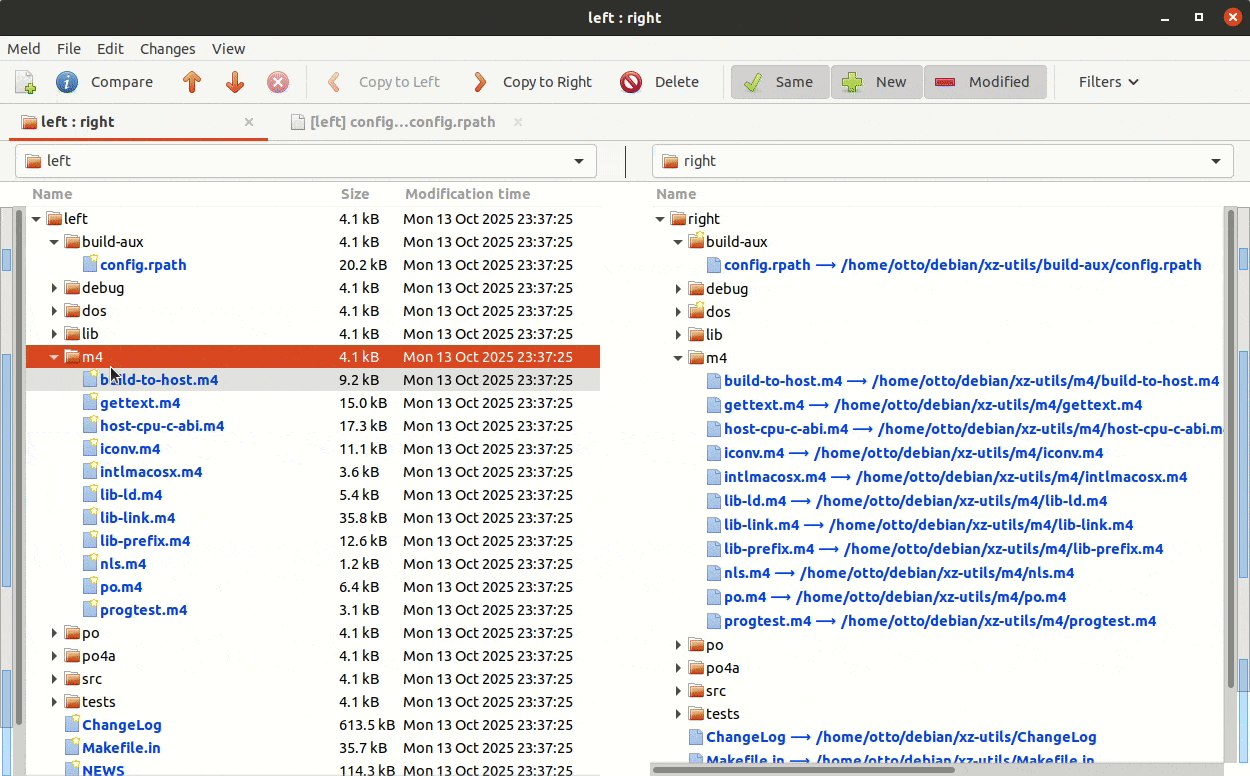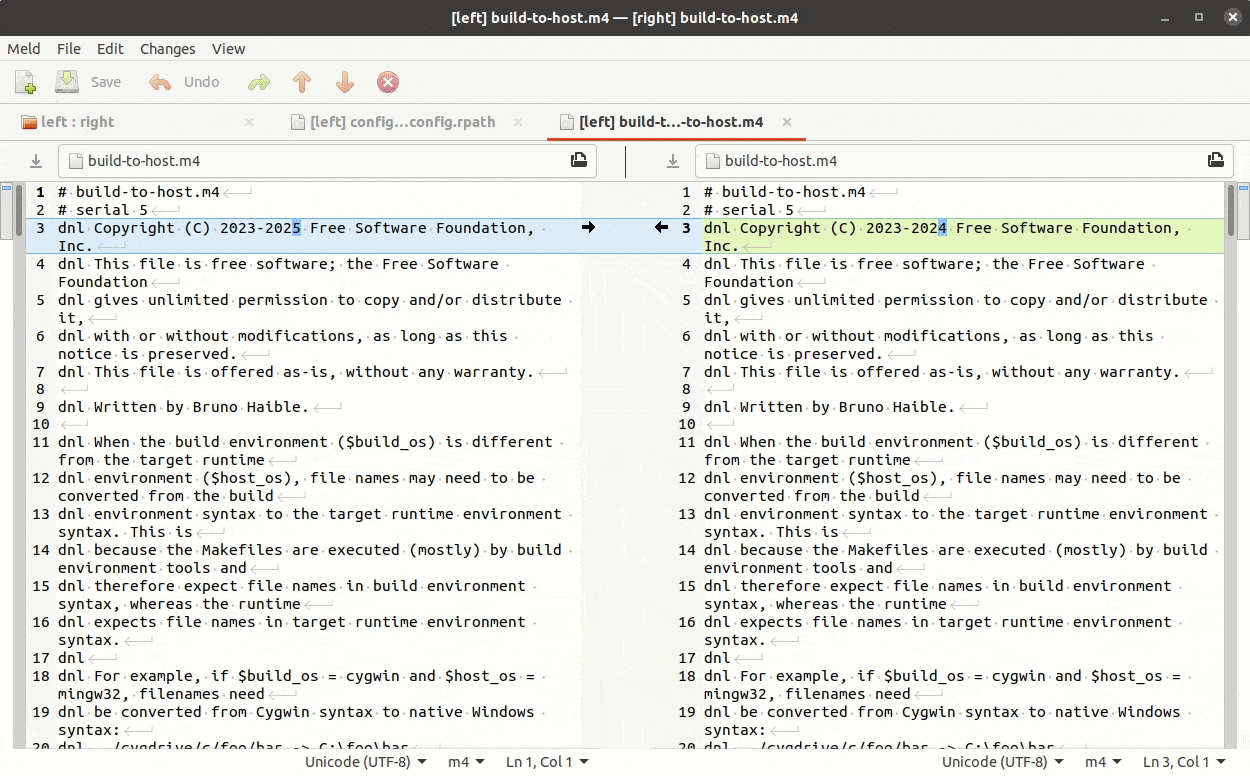
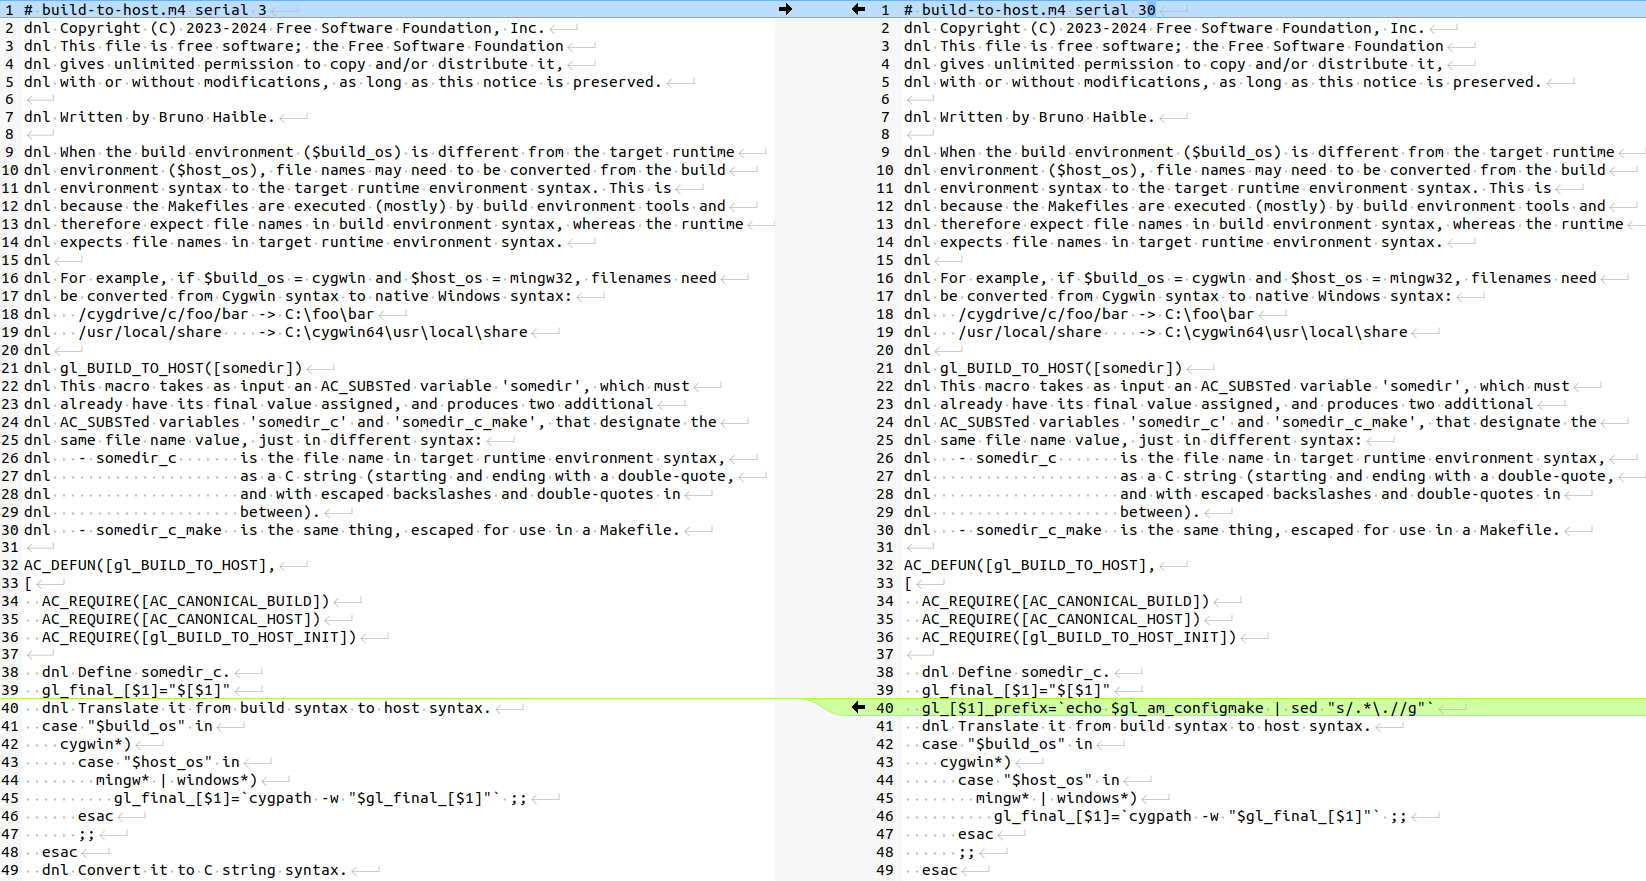
Should the XZ backdoor have been detected using these tools? The famous XZ Utils backdoor (CVE-2024-3094) consisted of two parts: the actual backdoor inside two binary blobs masqueraded as a test files (tests/files/bad-3-corrupt_lzma2.xz, tests/files/good-large_compressed.lzma), and a small modification in the build scripts (m4/build-to-host.m4) to extract the backdoor and plant it into the built binary. The build script was not tracked in version control, but generated with GNU Autotools at release time and only shipped as additional files in the release tarball. The entire reason for me to write this post was to ponder if a diligent engineer using git-buildpackage best practices could have reasonably spotted this while importing the new upstream release into Debian. The short answer is no . The malicious actor here clearly anticipated all the typical ways anyone might inspect both git commits, and release tarball contents, and masqueraded the changes very well and over a long timespan. First of all, XZ has for legitimate reasons for several carefully crafted .xz files as test data to help catch regressions in the decompression code path. The test files are shipped in the release so users can run the test suite and validate that the binary is built correctly and xz works properly. Debian famously runs massive amounts of testing in its CI and autopkgtest system across tens of thousands of packages to uphold high quality despite frequent upgrades of the build toolchain and while supporting more CPU architectures than any other distro. Test data is useful and should stay. When git-buildpackage is used correctly, the upstream commits are visible in the Debian packaging for easy review, but the commit cf44e4b that introduced the test files does not deviate enough from regular sloppy coding practices to really stand out. It is unfortunately very common for git commit to lack a message body explaining why the change was done, and to not be properly atomic with test code and test data together in the same commit, and for commits to be pushed directly to mainline without using code reviews (the commit was not part of any PR in this case). Only another upstream developer could have spotted that this change is not on par to what the project expects, and that the test code was never added, only test data, and thus that this commit was not just a sloppy one but potentially malicious. Secondly, the fact that a new Autotools file appeared (m4/build-to-host.m4) in the XZ Utils 5.6.0 is not suspicious. This is perfectly normal for Autotools. In fact, starting from XZ Utils version 5.8.1 it is now shipping a m4/build-to-host.m4 file that it actually uses now. Spotting that there is anything fishy is practically impossible by simply reading the code, as Autotools files are full custom m4 syntax interwoven with shell script, and there are plenty of backticks ( ) that spawn subshells and evals that execute variable contents further, which is just normal for Autotools. Russ Cox s XZ post explains how exactly the Autotools code fetched the actual backdoor from the test files and injected it into the build. Inspecting the m4/build-to-host.m4 changes in Meld launched via git difftool There is only one tiny thing that maybe a very experienced Autotools user could potentially have noticed: the serial 30 in the version header is way too high. In theory one could also have noticed this Autotools file deviates from what other packages in Debian ship with the same filename, such as e.g. the serial 3, serial 5a or 5b versions. That would however require and an insane amount extra checking work, and is not something we should plan to start doing. A much simpler solution would be to simply strongly recommend all open source projects to stop using Autotools to eventually get rid of it entirely.

Not detectable with reasonable effort While planting backdoors is evil, it is hard not to feel some respect to the level of skill and dedication of the people behind this. I ve been involved in a bunch of security breach investigations during my IT career, and never have I seen anything this well executed. If it hadn t slowed down SSH by ~500 milliseconds and been discovered due to that, it would most likely have stayed undetected for months or years. Hiding backdoors in closed source software is relatively trivial, but hiding backdoors in plain sight in a popular open source project requires some unusual amount of expertise and creativity as shown above.

Is the software supply-chain in Debian easy to audit? While maintaining a Debian package source using git-buildpackage can make the package history a lot easier to inspect, most packages have incomplete configurations in their debian/gbp.conf, and thus their package development histories are not always correctly constructed or uniform and easy to compare. The Debian Policy does not mandate git usage at all, and there are many important packages that are not using git at all. Additionally the Debian Policy also allows for non-maintainers to upload new versions to Debian without committing anything in git even for packages where the original maintainer wanted to use git. Uploads that bypass git unfortunately happen surpisingly often. Because of the situation, I am afraid that we could have multiple similar backdoors lurking that simply haven t been detected yet. More audits, that hopefully also get published openly, would be welcome! More people auditing the contents of the Debian archives would probably also help surface what tools and policies Debian might be missing to make the work easier, and thus help improve the security of Debian s users, and improve trust in Debian.

Is Debian currently missing some software that could help detect similar things? To my knowledge there is currently no system in place as part of Debian s QA or security infrastructure to verify that the upstream source packages in Debian are actually from upstream. I ve come across a lot of packages where the debian/watch or other configs are incorrect and even cases where maintainers have manually created upstream tarballs as it was easier than configuring automation to work. It is obvious that for those packages the source tarball now in Debian is not at all the same as upstream. I am not aware of any malicious cases though (if I was, I would report them of course). I am also aware of packages in the Debian repository that are misconfigured to be of type 1.0 (native) packages, mixing the upstream files and debian/ contents and having patches applied, while they actually should be configured as 3.0 (quilt), and not hide what is the true upstream sources. Debian should extend the QA tools to scan for such things. If I find a sponsor, I might build it myself as my next major contribution to Debian. In addition to better tooling for finding mismatches in the source code, Debian could also have better tooling for tracking in built binaries what their source files were, but solutions like Fraunhofer-AISEC s supply-graph or Sony s ESSTRA are not practical yet. Julien Malka s post about NixOS discusses the role of reproducible builds, which may help in some cases across all distros.

Or, is Debian missing some policies or practices to mitigate this? Perhaps more importantly than more security scanning, the Debian Developer community should switch the general mindset from anyone is free to do anything to valuing having more shared workflows. The ability to audit anything is severely hampered by the fact that there are so many ways to do the same thing, and distinguishing what is a normal deviation from a malicious deviation is too hard, as the normal can basically be almost anything. Also, as there is no documented and recommended default workflow, both those who are old and new to Debian packaging might never learn any one optimal workflow, and end up doing many steps in the packaging process in a way that kind of works, but is actually wrong or unnecessary, causing process deviations that look malicious, but turn out to just be a result of not fully understanding what would have been the right way to do something. In the long run, once individual developers workflows are more aligned, doing code reviews will become a lot easier and smoother as the excess noise of workflow differences diminishes and reviews will feel much more productive to all participants. Debian fostering a culture of code reviews would allow us to slowly move from the current practice of mainly solo packaging work towards true collaboration forming around those code reviews. I have been promoting increased use of Merge Requests in Debian already for some time, for example by proposing DEP-18: Encourage Continuous Integration and Merge Request based Collaboration for Debian packages. If you are involved in Debian development, please give a thumbs up in dep-team/deps!21 if you want me to continue promoting it.

Can we trust open source software? Yes and I would argue that we can only trust open source software. There is no way to audit closed source software, and anyone using e.g. Windows or MacOS just have to trust the vendor s word when they say they have no intentional or accidental backdoors in their software. Or, when the news gets out that the systems of a closed source vendor was compromised, like Crowdstrike some weeks ago, we can t audit anything, and time after time we simply need to take their word when they say they have properly cleaned up their code base. In theory, a vendor could give some kind of contractual or financial guarantee to its customer that there are no preventable security issues, but in practice that never happens. I am not aware of a single case of e.g. Microsoft or Oracle would have paid damages to their customers after a security flaw was found in their software. In theory you could also pay a vendor more to have them focus more effort in security, but since there is no way to verify what they did, or to get compensation when they didn t, any increased fees are likely just pocketed as increased profit. Open source is clearly better overall. You can, if you are an individual with the time and skills, audit every step in the supply-chain, or you could as an organization make investments in open source security improvements and actually verify what changes were made and how security improved. If your organisation is using Debian (or derivatives, such as Ubuntu) and you are interested in sponsoring my work to improve Debian, please reach out.

18 October 2025

Julian Andres Klode: Sound Removals

Problem statement Currently if you have an automatically installed package A (= 1) where
  • A (= 1) Depends B (= 1)
  • A (= 2) Depends B (= 2)
and you upgrade B from 1 to 2; then you can:
  1. Remove A (= 1)
  2. Upgrade A to version 2
If A was installed by a chain initiated by Recommends (say X Rec Y, Y Depends A), the solver sometimes preferred removing A (and anything depending on it until it got). I have a fix pending to introduce eager Recommends which fixes the practical case, but this is still not sound. In fact we can show that the solver produces the wrong result for small minimal test cases, as well as the right result for some others without the fix (hooray?). Ensuring sound removals is more complex, and first of all it begs the question: When is a removal sound? This, of course, is on us to define. An easy case can be found in the Debian policy, 7.6.2 Replacing whole packages, forcing their removal : If B (= 2) declares a Conflicts: A (= 1) and Replaces: A (= 1), then the removal is valid. However this is incomplete as well, consider it declares Conflicts: A (< 1) and Replaces: A (< 1); the solution to remove A rather than upgrade it would still be wrong. This indicates that we should only allow removing A if the conflicts could not be solved by upgrading it. The other case to explore is package removals. If B is removed, A should be removed as well; however it there is another package X that Provides: B (= 1) and it is marked for install, A should not be removed. That said, the solver is not allowed to install X to satisfy the depends B (= 1) - only to satisfy other dependencies [we do not want to get into endless loops where we switch between alternatives to keep reverse dependencies installed].

Proposed solution To solve this, I propose the following definition: Definition (sound removal): A removal of package P is sound if either:
  1. A version v is installed that package-conflicts with B.
  2. A package Q is removed and the installable versions of P package-depends on Q.
where the other definitions are: Definition (installable version): A version v is installable if either it is installed, or it is newer than an installed version of the same package (you may wish to change this to accomodate downgrades, or require strict pinning, but here be dragons). Definition (package-depends): A version v package-depends on a package B if either:
  1. there exists a dependency in v that can be solved by any version of B, or
  2. there exists a package C where v package-depends C and any (c in C) package-depends B (transitivity)
Definition (package-conflicts): A version v package-conflicts with an installed package B if either:
  1. it declares a conflicts against an installable version of B; or
  2. there exists a package C where v package-conflicts C, and b package-depends C for installable versions b.

Translating this into a (modified) SAT solver One approach may be to implement the logic in the conflict analysis that drives backtracking, i.e. we assume a package A and when we reach not A, we analyse if the implication graph for not A constitutes a sound removal, and then replace the assumption A with the assumption A or "learned reason. However, while this seems a plausible mechanism for a DPLL solver, for a modern CDCL solver, it s not immediately evident how to analyse whether not A is sound if the reason for it is a learned clause, rather than a problem clause. Instead we propose a static encoding of the rules into a slightly modified SAT solver: Given c1, , cn that transitive-conflicts A and D1, , Dn that A package-depends on, introduce the rule: A unless c1 or c2 or ... cn ... or not D1 or not D2 ... or not Dn Rules of the form A... unless B... - where A... and B... are CNF - are intuitively the same as A... or B..., however the semantic here is different: We are not allowed to select B... to satisfy this clause. This requires a SAT solver that tracks a reason for each literal being assigned, such as solver3, rather than a SAT solver like MiniSAT that only tracks reasons across propagation (solver3 may track A depends B or C as the reason for B without evaluating C, whereas MiniSAT would only track it as the reason given not C).

Is it actually sound? The proposed definition of a sound removal may still proof unsound as I either missed something in the conclusion of the proposed definition that violates my goal I set out to achieve, or I missed some of the goals. I challenge you to find cases that cause removals that look wrong :D

17 October 2025

Dirk Eddelbuettel: ML quacks: Combining duckdb and mlpack

A side project I have been working on a little since last winter and which explores extending duckdb with mlpack is now public at the duckdb-mlpack repo. duckdb is an excellent small (as in runs as a self-contained binary ) database engine with both a focus on analytical payloads (OLAP rather than OLTP) and an impressive number of already bolted-on extensions (for example for cloud data access) delivered as a single-build C++ executable (or of course as a library used from other front-ends). mlpack is an excellent C++ library containing many/most machine learning algorithms, also built in a self-contained manner (or library) making it possible to build compact yet powerful binaries, or to embed (as opposed to other ML framework accessed from powerful but not lightweight run-times such as Python or R). The compact build aspect as well as the common build tools (C++, cmake) make these two a natural candidate for combining them. Moreover, duckdb is a champion of data access, management and control and the complementary machine learning insights and predictions offered by mlpack are fully complementary and hence fit this rather well. duckdb also has a very robust and active extension system. To use it, one starts from a template repository and its use this template button, runs a script and can then start experimenting. I have now grouped my initial start and test functions into a separate repository duckdb-example-extension to keep the duckdb-mlpack one focused on the extend to mlpack aspect. duckdb-mlpack is right an MVP , i.e. a minimally viable product (or demo). It just runs the adaboost classifier but does so on any dataset fitting the rectangular setup with columns of features (real valued) and a final column (integer valued) of labels. I had hope to use two select queries for both features and then labels but it turns a table function (returning a table of data from a query) can only run one select *. So the basic demo, also on the repo README is now to run the following script (where the SELECT * FROM mlpack_adaboost((SELECT * FROM D)); is the key invocation of the added functionality):
#!/bin/bash

cat <<EOF   build/release/duckdb
SET autoinstall_known_extensions=1;
SET autoload_known_extensions=1; # for httpfs

CREATE TEMP TABLE Xd AS SELECT * FROM read_csv("https://mlpack.org/datasets/iris.csv");
CREATE TEMP TABLE X AS SELECT row_number() OVER () AS id, * FROM Xd;
CREATE TEMP TABLE Yd AS SELECT * FROM read_csv("https://mlpack.org/datasets/iris_labels.csv");
CREATE TEMP TABLE Y AS SELECT row_number() OVER () AS id, CAST(column0 AS double) as label FROM Yd;
CREATE TEMP TABLE D AS SELECT * FROM X INNER JOIN Y ON X.id = Y.id;
ALTER TABLE D DROP id;
ALTER TABLE D DROP id_1;
CREATE TEMP TABLE A AS SELECT * FROM mlpack_adaboost((SELECT * FROM D));

SELECT COUNT(*) as n, predicted FROM A GROUP BY predicted;
EOF
to produce the following tabulation / group by:
./sampleCallRemote.sh
Misclassified: 1
 
    n     predicted  
  int64     int32    
 
     50           0  
     49           1  
     51           2  
 
$
(Note that this requires the httpfs extension. So when you build from a freshly created extension repository you may be ahead of the most recent release of duckdb by a few commits. It is easy to check out the most recent release tag (or maybe the one you are running for your local duckdb binary) to take advantage of the extensions you likely already have for that version. So here, and in the middle of October 2025, I picked v1.4.1 as I run duckdb version 1.4.1 on my box.) There are many other neat duckdb extensions. The core ones are regrouped here while a list of community extensions is here and here. For this (still more minimal) extension, I added a few TODO items to the README.md: Please reach out if you are interested in working on any of this.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

David Bremner: Hibernate on the pocket reform 13/n

Context

Some progress upstream Recently Sebastian Reichel at Collabora [1] has made a few related commits, apparently inspired in part by my kvetching on this blog.

Disconnecting and reconnecting PCI busses At some point I noticed error message about the nvme device on resume. I then learned how to disconnect and reconnect PCI buses in Linux. I ended up with something like the following. At least the PCI management seems to work. I can manually disconnect all the PCI busses and rescan to connect them again on a running system. It presumably helps that I am not using the nvme device in this system.
set -x
echo platform >  /sys/power/pm_test
echo reboot > /sys/power/disk
rmmod mt76x2u
sleep 2
echo 1   tee /sys/bus/pci/devices/0003:30:00.0/remove
sleep 2
echo 1   tee /sys/bus/pci/devices/0004:41:00.0/remove
sleep 2
echo 1   tee /sys/bus/pci/devices/0004:40:00.0/remove
sleep 2
echo LSPCI:
lspci -t
sleep 2
echo disk >  /sys/power/state
sleep 2
echo 1   tee /sys/bus/pci/rescan
sleep 2
modprobe mt76x2u

Minimal changes to upstream With the ongoing work at collabora I decided to try a minimal patch stack to get the pocket reform to boot. I added the following 3 commits (available from [3]).
09868a4f2eb (HEAD -> reform-patches) copy pocket-reform dts from reform-debian-packages
152e2ae8a193 pocket/panel: sleep fix v3
18f65da9681c add-multi-display-panel-driver
It does indeed boot and seems stable.
$ uname -a
Linux anthia 6.18.0-rc1+ #19 SMP Thu Oct 16 11:32:04 ADT 2025 aarch64 GNU/Linux
Running the hibernation script above I get no output from the lspci, but seemingly issues with PCI coming back from hibernate:
[  424.645109] PM: hibernation: Allocated 361823 pages for snapshot
[  424.647216] PM: hibernation: Allocated 1447292 kbytes in 3.23 seconds (448.07 MB/s)
[  424.649321] Freezing remaining freezable tasks
[  424.654767] Freezing remaining freezable tasks completed (elapsed 0.003 seconds)
[  424.661070] rk_gmac-dwmac fe1b0000.ethernet end0: Link is Down
[  424.740716] rockchip-dw-pcie a40c00000.pcie: Failed to receive PME_TO_Ack
[  424.742041] PM: hibernation: hibernation debug: Waiting for 5 second(s).
[  430.074757] pci 0004:40:00.0: [1d87:3588] type 01 class 0x060400 PCIe Root Port
F F & Zn [  watchdog: CPU4: Watchdog detected hard LOCKUP on cpu 5
[  456.039004] Modules linked in: xt_CHECKSUM xt_tcpudp nft_chain_nat xt_MASQUERADE nf_nat nf_conntrack nf_defrag_ipv6 nf_defrag_ipv4 nft_compat x_tables bridge stp llc nf_tables aes_neon_bs aes_neon_blk ccm dwmac_rk binfmt_misc mt76x2_common mt76x02_usb mt76_usb mt76x02_lib mt76 mac80211 rk805_pwrkey snd_soc_tlv320aic31xx snd_soc_simple_card reform2_lpc(OE) libarc4 rockchip_saradc industrialio_triggered_buffer kfifo_buf industrialio cfg80211 rockchip_thermal rockchip_rng hantro_vpu cdc_acm v4l2_vp9 v4l2_jpeg rockchip_rga rfkill snd_soc_rockchip_i2s_tdm videobuf2_dma_sg v4l2_h264 panthor snd_soc_audio_graph_card drm_gpuvm snd_soc_simple_card_utils drm_exec evdev joydev dm_mod nvme_fabrics efi_pstore configfs nfnetlink autofs4 ext4 crc16 mbcache jbd2 btrfs blake2b_generic xor xor_neon raid6_pq mali_dp snd_soc_meson_axg_toddr snd_soc_meson_axg_fifo snd_soc_meson_codec_glue panfrost drm_shmem_helper gpu_sched ao_cec_g12a meson_vdec(C) videobuf2_dma_contig videobuf2_memops v4l2_mem2mem videobuf2_v4l2 videodev
[  456.039060]  videobuf2_common mc dw_hdmi_i2s_audio meson_drm meson_canvas meson_dw_mipi_dsi meson_dw_hdmi mxsfb mux_mmio panel_edp imx_dcss ti_sn65dsi86 nwl_dsi mux_core pwm_imx27 hid_generic usbhid hid xhci_plat_hcd onboard_usb_dev xhci_hcd nvme nvme_core snd_soc_hdmi_codec snd_soc_core nvme_keyring nvme_auth hkdf snd_pcm_dmaengine snd_pcm snd_timer snd soundcore fan53555 rtc_pcf8523 micrel phy_package stmmac_platform stmmac pcs_xpcs rk808_regulator phylink sdhci_of_dwcmshc mdio_devres dw_mmc_rockchip of_mdio sdhci_pltfm phy_rockchip_usbdp fixed_phy dw_mmc_pltfm fwnode_mdio typec phy_rockchip_naneng_combphy phy_rockchip_samsung_hdptx pwm_rockchip sdhci dwc3 libphy dw_wdt dw_mmc ehci_platform rockchip_dfi mdio_bus cqhci ulpi ohci_platform ehci_hcd udc_core ohci_hcd rockchipdrm phy_rockchip_inno_usb2 usbcore dw_hdmi_qp analogix_dp dw_mipi_dsi cpufreq_dt dw_mipi_dsi2 i2c_rk3x usb_common drm_dp_aux_bus [last unloaded: mt76x2u]
[  456.039111] Sending NMI from CPU 4 to CPUs 5:
[  471.942262] page_pool_release_retry() stalled pool shutdown: id 9, 2 inflight 60 sec
[  532.989611] page_pool_release_retry() stalled pool shutdown: id 9, 2 inflight 121 sec
This does look like some progress, probably thanks to Sebastien. Comparing with the logs in hibernate-pocket-12, the resume process is not bailing out complaining about PHY.

Attempt to reapply PCI reset patches Following the procedure in hibernate-pocket-12, I attempted to re-apply the pci reset patches [2]. In particular I followed the hints output by b4. Unfortunately there are too many conflicts now for me to sensibly resolve.
  1. https://gitlab.collabora.com/hardware-enablement/rockchip-3588/linux.git#rockchip-devel
  2. https://lore.kernel.org/all/20250715-pci-port-reset-v6-0-6f9cce94e7bb@oss.qualcomm.com/#r
  3. https://salsa.debian.org/bremner/collabora-rockchip-3588#reform-patches

14 October 2025

Gunnar Wolf: Can a server be just too stable?

One of my servers at work leads a very light life: it is our main backups server (so it has a I/O spike at night, with little CPU involvement) and has some minor services running (i.e. a couple of Tor relays and my personal email server yes, I have the authorization for it ). It is a very stable machine But today I was surprised: As I am about to migrate it to Debian 13 (Trixie), naturally, I am set to reboot it. But before doing so:
$ w
 12:21:54 up 1048 days, 0 min,  1 user,  load average: 0.22, 0.17, 0.17
USER     TTY      FROM             LOGIN@   IDLE   JCPU   PCPU  WHAT
gwolf             192.168.10.3     12:21           0.00s  0.02s sshd-session: gwolf [priv]
Wow. Did I really last reboot this server on December 1 2022? (Yes, I know this might speak bad of my security practices, as there are several kernel updates I never applied, even having installed the relevant packages. Still, it got me impressed ) Debian. Rock solid. Debian Rocks

Dirk Eddelbuettel: qlcal 0.0.17 on CRAN: Regular Update

The seventeenth release of the qlcal package arrivied at CRAN today, once again following a QuantLib release as 1.40 came out this morning. qlcal delivers the calendaring parts of QuantLib. It is provided (for the R package) as a set of included files, so the package is self-contained and does not depend on an external QuantLib library (which can be demanding to build). qlcal covers over sixty country / market calendars and can compute holiday lists, its complement (i.e. business day lists) and much more. Examples are in the README at the repository, the package page, and course at the CRAN package page. This releases mainly synchronizes qlcal with the QuantLib release 1.40. Only one country calendar got updated; the diffstat looks larger as the URL part of the copyright got updated throughout. We also updated the URL for the GPL-2 badge: when CRAN checks this, they always hit a timeout as the FSF server possibly keeps track of incoming requests; we now link to version from the R Licenses page to avoid this.

Changes in version 0.0.17 (2025-07-14)
  • Synchronized with QuantLib 1.40 released today
  • Calendar updates for Singapore
  • URL update in README.md

Courtesy of my CRANberries, there is a diffstat report for this release. See the project page and package documentation for more details, and more examples.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Freexian Collaborators: Debian Contributions: Old Debian Printing software and C23, Work to decommission packages.qa.debian.org, rebootstrap uses *-for-host and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-09 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Updating old Debian Printing software to meet C23 requirements, by Thorsten Alteholz The work of Thorsten fell under the motto gcc15 . Due to the introduction of gcc15 in Debian, the default language version was changed to C23. This means that for example, function declarations without parameters are no longer allowed. As old software, which was created with ANSI C (or C89) syntax, made use of such function declarations, it was a busy month. One could have used something like -std=c17 as compile flags, but this would have just postponed the tasks. As a result Thorsten uploaded modernized versions of ink, nm2ppa and rlpr for the Debian printing team.

Work done to decommission packages.qa.debian.org, by Rapha l Hertzog Rapha l worked to decommission the old package tracking system (packages.qa.debian.org). After figuring out that it was still receiving emails from the bug tracking system (bugs.debian.org), from multiple debian lists and from some release team tools, he reached out to the respective teams to either drop those emails or adjust them so that they are sent to the current Debian Package Tracker (tracker.debian.org).

rebootstrap uses *-for-host, by Helmut Grohne Architecture cross bootstrapping is an ongoing effort that has shaped Debian in various ways over the years. A longer effort to express toolchain dependencies now bears fruit. When cross compiling, it becomes important to express what architecture one is compiling for in Build-Depends. As these packages have become available in trixie , more and more packages add this extra information and in August, the libtool package gained a gfortran-for-host dependency. It was the first package in the essential build closure to adopt this and required putting the pieces together in rebootstrap that now has to build gcc-defaults early on. There still are hundreds of packages whose dependencies need to be updated though.

Miscellaneous contributions
  • Rapha l dropped the Build Log Scan integration in tracker.debian.org since it was showing stale data for a while as the underlying service has been discontinued.
  • Emilio updated pixman to 0.46.4.
  • Emilio coordinated several transitions, and NMUed guestfs-tools to unblock one.
  • Stefano uploaded Python 3.14rc3 to Debian unstable. It s not yet used by any packages, but it allows testing the level of support in packages to begin.
  • Stefano upgraded almost all of the debian-social infrastructure to Debian trixie .
  • Stefano published the sponsorship brochures for DebConf 26.
  • Stefano attended the Debian Technical Committee meeting.
  • Stefano uploaded routine upstream updates for a handful of Python packages (pycparser, beautifulsoup4, platformdirs, pycparser, python-authlib, python-cffi, python-mitogen, python-resolvelib, python-super-collections, twine).
  • Stefano reviewed and responded to DebConf 25 feedback.
  • Stefano investigated and fixed a request visibility bug in debian-reimbursements (for admin-altered requests).
  • Lucas reviewed a couple of merge requests from external contributors for Go and Ruby packages.
  • Lucas updated some ruby packages to its latest upstream version (thin, passenger, and puma is still WIP).
  • Lucas set up the build environment to run rebuilds of reverse dependencies of ruby using ruby3.4. As an alternative, he is looking for personal repositories provided by Debusine to perform this task more easily. This is the preparation for the transition to ruby3.4 as the default in Debian.
  • Lucas helped on the next round of the Outreachy internship program.
  • Helmut sent patches for 30 cross build failures and responded to cross building support questions on the mailing list.
  • Helmut continued to maintain rebootstrap. As gcc version 15 became the default, test jobs for version 14 had to be dropped. A fair number of patches were applied to packages and could be dropped.
  • Helmut resumed removing RC-buggy packages from unstable and sponsored a termrec upload to avoid its deletion. This work was paused to give packages some time to migrate to forky .
  • Santiago reviewed different merge requests created by different contributors. Those MRs include a new test to build reverse dependencies, created by Aquila Macedo as part of his GSoC internship; restore how lintian was used in experimental, thanks Otto Kek l inen; and the fix by Christian Bayle to support again extra repositories in deb822-style sources, whose support was broken with the move to sbuild+unshare last month.
  • While doing some new upstream release updates, thanks to Debusine s reverse dependencies autopkgtest checks, Santiago discovered that paramiko 4.0 will introduce a regression in libcloud by the drop of support for the obsolete DSA keys. Santiago finally uploaded to unstable both paramiko 4.0, and a regression fix for libcloud.
  • Santiago has taken part in different discussions and meetings for the preparation of DebConf 26. The DebConf 26 local team aims to prepare for the conference with enough time in advance.
  • Carles kept working on the missing-package-relations and reporting missing Recommends. He improved the tooling to detect and report bugs creating 269 bugs and followed up comments. 37 bugs have been resolved, others acknowledged. The missing Recommends are a mixture of packages that are gone from Debian, packages that changed name, typos and also packages that were recommended but are not packaged in Debian.
  • Carles improved the missing-package-relations to report broken Suggests only for packages that used to be in Debian but are removed from it now. No bugs have been created yet for this case but identified 1320 of them.
  • Colin spent much of the month chasing down build/test regressions in various Python packages due to other upgrades, particularly relating to pydantic, python-pytest-asyncio, and rust-pyo3.
  • Colin optimized some code in ubuntu-dev-tools (affecting e.g. pull-debian-source) that made O(n) HTTP requests when it could instead make O(1).
  • Anupa published Micronews as part of Debian Publicity team work.

13 October 2025

Jonathan McDowell: onak 0.6.4 released

A bit delayed in terms of an announcement, but last month I tagged a new version of onak, my OpenPGP compatible keyserver. It s been 2 years since the last release, and this is largely a bunch of minor fixes to make compilation under Debian trixie with more recent CMake + GCC versions happy. OpenPGP v6 support, RFC9580, hasn t made it. I ve got a branch which adds it, but a lack of keys to do any proper testing with, and no X448 support implemented, mean I m not ready to include it in a release yet. The plan is that ll land for 0.7.0 (along with some backend work), but no idea when that might be. Available locally or via GitHub.
0.6.4 - 7th September 2025
  • Fix building with CMake 4.0
  • Fixes for building with GCC 15
  • Rename keyd(ctl) to onak-keyd(ctl)

Wouter Verhelst: RPM and ECDSA GPG keys

Dear lazyweb, At work, we are trying to rotate the GPG signing keys for the Linux packages of the eID middleware We created new keys, and they will be installed on all Linux machines that have the eid-archive package installed soon (they were already supposed to be, but we made a mistake). Running some tests, however, I have a bit of a problem:

[wouter@rhel rpm-gpg]$ sudo rpm --import RPM-GPG-KEY-BEID-RELEASE
[wouter@rhel rpm-gpg]$ sudo rpm --import RPM-GPG-KEY-BEID-RELEASE-2025
fout: RPM-GPG-KEY-BEID-RELEASE-2025: key 1 import failed.
[wouter@rhel rpm-gpg]$ sudo rpm --import RPM-GPG-KEY-BEID-CONTINUOUS
This is on RHEL9. The only difference between the old keys and the new one, apart of course from the fact that the old one is, well, old, is that the old one uses the RSA algorithm whereas the new one uses ECDSA on the NIST P-384 curve (the same algorithm as the one used by the eID card). Does RPM not support ECDSA keys? Does anyone know where this is documented? (Yes, I probably should have tested this before publishing the new key, but this is where we are)

Russell Coker: WordPress Spam Users

Just over a year ago I configured my blog to only allow signed in users to comment to reduce spam [1]. This has stopped all spam comments, it was even more successful than expected but spammers keep registering accounts. I ve now got almost 5000 spam accounts, an average of more than 10 per day. I don t know why they keep creating them without trying to enter comments. At first I thought that they were trying to assemble a lot of accounts for a deluge of comment spam but that hasn t happened. There are some WordPress plugins for bulk deletion of users but I couldn t find one with support for delete all users who haven t submitted a comment . So I do it a page at a time, but of course I don t want to do it 100 at a time so I used the below SQL to change it to 400 at a time. I initially tried larger numbers like 2000 but got Chrome timeouts when trying to click the check-box to select all users. From experimenting it seems that the time taken to check that is worse than linear. Doing it for 2000 users is obviously much more than 5* the duration of doing it for 400. 800 users was one attempt which resulted in it being possible to select them all but then it gave an error about the URL being too long when it came to actually delete them. After a binary search I found that 450 was too many but 400 worked. So now it s 12 operations to delete all the spam accounts. Each bulk delete operation is 5 GUI operations so it s 60 operations to delete 15 months of spam users. This is annoying, but less than the other problems of spam.
UPDATE  wp_usermeta  SET  meta_value  = 400 WHERE  user_id  = 2 AND  meta_key  = 'users_per_page';
Deleting the spam users reduced the size of the backup (zstd -9 of a mysql dump) for my blog by 6.5%. Then changing from zstd -9 to -19 reduced it by another 13%. After realising this difference I configured all my mysql backups to be compressed with zstd -19, this will make a difference on the system with over 30G of zstd compressed mysql backups.

Freexian Collaborators: Monthly report about Debian Long Term Support, September 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In September, 20 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 10.0h (out of 10.0h assigned and 4.0h from previous period), thus carrying over 4.0h to the next month.
  • Andreas Henriksson did 1.0h (out of 0.0h assigned and 20.0h from previous period), thus carrying over 19.0h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 20.0h (out of 21.0h assigned), thus carrying over 1.0h to the next month.
  • Carlos Henrique Lima Melara did 10.0h (out of 12.0h assigned), thus carrying over 2.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 21.0h (out of 21.0h assigned).
  • Emilio Pozuelo Monfort did 39.75h (out of 40.0h assigned), thus carrying over 0.25h to the next month.
  • Guilhem Moulin did 15.0h (out of 15.0h assigned).
  • Jochen Sprickerhof did 12.0h (out of 9.25h assigned and 11.75h from previous period), thus carrying over 9.0h to the next month.
  • Lee Garrett did 13.5h (out of 21.0h assigned), thus carrying over 7.5h to the next month.
  • Lucas Kanashiro did 8.0h (out of 20.0h assigned), thus carrying over 12.0h to the next month.
  • Markus Koschany did 15.0h (out of 3.25h assigned and 17.75h from previous period), thus carrying over 6.0h to the next month.
  • Paride Legovini did 6.0h (out of 8.0h assigned), thus carrying over 2.0h to the next month.
  • Roberto C. S nchez did 7.25h (out of 7.75h assigned and 13.25h from previous period), thus carrying over 13.75h to the next month.
  • Santiago Ruano Rinc n did 13.25h (out of 13.5h assigned and 1.5h from previous period), thus carrying over 1.75h to the next month.
  • Sylvain Beucler did 17.0h (out of 7.75h assigned and 13.25h from previous period), thus carrying over 4.0h to the next month.
  • Thorsten Alteholz did 21.0h (out of 21.0h assigned).
  • Tobias Frost did 5.0h (out of 0.0h assigned and 8.0h from previous period), thus carrying over 3.0h to the next month.
  • Utkarsh Gupta did 16.5h (out of 14.25h assigned and 6.75h from previous period), thus carrying over 4.5h to the next month.

Evolution of the situation In September, we released 38 DLAs.
  • Notable security updates:
    • modsecurity-apache prepared by Adrian Bunk, fixes a cross-site scripting vulnerability
    • cups, prepared by Thorsten Alteholz, fixes authentication bypass and denial of service vulnerabilities
    • jetty9, prepared by Adrian Bunk, fixes the MadeYouReset vulnerability (a recent, well-known denial of service vulnerability)
    • python-django, prepared by Chris Lamb, fixes a SQL injection vulnerability
    • firefox-esr and thunderbird, prepared by Emilio Pozuelo Monfort, were updated from the 128.x ESR series to the 140.x ESR series, fixing a number of vulnerabilities as well
  • Notable non-security updates:
    • wireless-regdb prepared by Ben Hutchings, updates information reflecting changes to radio regulations in many countries
There was one package update contributed by a Debian Developer outside of the LTS Team: an update of node-tar-fs, prepared by Xavier Guimard (a member of the Node packaging team). Finally, LTS Team members also contributed updates of the following packages:
  • libxslt (to stable and oldstable), prepared by Guilhem Moulin, to address a regression introduced in a previous security update
  • libphp-adodb (to stable and oldstable), prepared by Abhijith PA
  • cups (to stable and oldstable), prepared by Thorsten Alteholz
  • u-boot (to oldstable), prepared by Daniel Leidert and Jochen Sprickerhof
  • libcommongs-lang3-java (to stable and oldstable), prepared by Daniel Leidert
  • python-internetarchive (to oldstable), prepared by Daniel Leidert
One other notable contribution by a member of the LTS Team is that Sylvain Beucler proposed a fix upstream for CVE-2025-2760 in gimp2. Upstream no longer supports gimp2, but it is still present in Debian LTS, and so proposing this fix upstream is of benefit to other distros which may still be supporting the older gimp2 packages.

Thanks to our sponsors Sponsors that joined recently are in bold.

12 October 2025

Dirk Eddelbuettel: RcppSpdlog 0.0.23 on CRAN: New Upstream

Version 0.0.23 of RcppSpdlog arrived on CRAN today (after a slight delay) and has been uploaded to Debian. RcppSpdlog bundles spdlog, a wonderful header-only C++ logging library with all the bells and whistles you would want that was written by Gabi Melman, and also includes fmt by Victor Zverovich. You can learn more at the nice package documention site. This release updates the code to the version 1.16.0 of spdlog which was released yesterday morning, and includes version 1.12.0 of fmt. We also converted the documentation site to now using mkdocs-material to altdoc (plus local style and production tweaks) rather than directly. I updated the package yesterday morning when spdlog was updated. But the passage was delayed for a day at CRAN as their machines still times out hitting the GPL-2 URL from the README.md badge, leading to a human to manually check the log assert the nothingburgerness of it. This timeout does not happen to me locally using the corresponding URL checker package. I pondered this in a r-package-devel thread and may just have to switch to using the R Project URL for the GPL-2 as this is in fact recurrning. The NEWS entry for this release follows.

Changes in RcppSpdlog version 0.0.23 (2025-10-11)
  • Upgraded to upstream release spdlog 1.16.0 (including fmt 12.0)
  • The mkdocs-material documentation site is now generated via altdoc

Courtesy of my CRANberries, there is also a diffstat report detailing changes. More detailed information is on the RcppSpdlog page, or the package documention site.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

11 October 2025

John Goerzen: A Mail Delivery Mystery: Exim, systemd, setuid, and Docker, oh my!

On mail.quux, a node of NNCPNET (the NNCP-based peer-to-peer email network), I started noticing emails not being delivered. They were all in the queue, frozen, and Exim s log had entries like:
unable to set gid=5001 or uid=5001 (euid=100): local delivery to [redacted] transport=nncp
Weird. Stranger still, when I manually ran the queue with sendmail -qff -v, they all delivered fine. Huh. Well, I thought, it was a one-off weird thing. But then it happened again. Upon investigating, I observed that this issue was happening only on messages submitted by SMTP. Which, on these systems, aren t that many. While trying different things, I tried submitting a message to myself using SMTP. Nothing to do with NNCP at all. But look at this:
 jgoerzen@[redacted] R=userforward defer (-1): require_files: error for /home/jgoerzen/.forward: Permission denied
Strraaannnge . All the information I could find about this, even a FAQ entry, said that the problem is that Exim isn t setuid root. But it is:
-rwsr-xr-x 1 root root 1533496 Mar 29  2025 /usr/sbin/exim4
This problem started when I upgraded to Debian Trixie. So what changed there? There are a lot of possibilities; this is running in Docker using my docker-debian-base system, which runs a regular Debian in Docker, including systemd. I eventually tracked it down to Exim migrating from init.d to systemd in trixie, and putting a bunch of lockdowns in its service file. After a bunch of trial and error, I determined that I needed to override this set of lockdowns to make it work. These overrides did the trick:
ProtectClock=false
PrivateDevices=false
RestrictRealtime=false
ProtectKernelModules=false
ProtectKernelTunables=false
ProtectKernelLogs=false
ProtectHostname=false
I don t know for sure if the issue is related to setuid. But if it is, there s nothing that immediately jumps out at me about any of these that would indicate a problem with setuid. I also don t know if running in Docker makes any difference. Anyhow, problem fixed, but mystery not solved!

10 October 2025

Louis-Philippe V ronneau: Montreal's Debian & Stuff - September 2025

Our Debian User Group met on September 27th for our first meeting since our summer hiatus. As always, it was fun and productive! Here's what we did: pollo: sergiodj: LeLutin: tvaz: viashimo: tassia: Pictures This time again, we were hosted at La Balise (formely ATS ). It's nice to see this community project continuing to improve: the social housing apartments on the top floors should be opening this month! Lots of construction work was also ongoing to make the Espace des Possibles more accessible from the street level. Group photo Some of us ended up grabbing a drink after the event at l'Isle de Garde, a pub right next to the venue, but I didn't take any pictures.
Reproducible Builds: Reproducible Builds in September 2025

Welcome to the September 2025 report from the Reproducible Builds project! Welcome to the very latest report from the Reproducible Builds project. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this report:

  1. Reproducible Builds Summit 2025
  2. Can t we have nice things?
  3. Distribution work
  4. Tool development
  5. Reproducibility testing framework
  6. Upstream patches

Reproducible Builds Summit 2025 Please join us at the upcoming Reproducible Builds Summit, set to take place from October 28th 30th 2025 in Vienna, Austria! We are thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving. If you re interesting in joining us this year, please make sure to read the event page which has more details about the event and location. Registration is open until 20th September 2025, and we are very much looking forward to seeing many readers of these reports there!

Can t we have nice things? Debian Developer Gunnar Wolf blogged that George V. Neville-Neil s Kode Vicious column in Communications of the ACM in which reproducible builds is mentioned without needing to introduce it (assuming familiarity across the computing industry and academia) . Titled, Can t we have nice things?, the article mentions:
Once the proper measurement points are known, we want to constrain the system such that what it does is simple enough to understand and easy to repeat. It is quite telling that the push for software that enables reproducible builds only really took off after an embarrassing widespread security issue ended up affecting the entire Internet. That there had already been 50 years of software development before anyone thought that introducing a few constraints might be a good idea is, well, let s just say it generates many emotions, none of them happy, fuzzy ones. [ ]

Distribution work In Debian this month, Johannes Starosta filed a bug against the debian-repro-status package, reporting that it does not work on Debian trixie. (An upstream bug report was also filed.) Furthermore, 17 reviews of Debian packages were added, 10 were updated and 14 were removed this month adding to our knowledge about identified issues. In March s report, we included the news that Fedora would aim for 99% package reproducibility. This change has now been deferred to Fedora 44 according to Phoronix. Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their work there.

Tool development diffoscope version 306 was uploaded to Debian unstable by Chris Lamb. It included contributions already covered in previous months as well as some changes by Zbigniew J drzejewski-Szmek to address issues with the fdtump support [ ] and to move away from the deprecated codes.open method. [ ][ ] strip-nondeterminism version 1.15.0-1 was uploaded to Debian unstable by Chris Lamb. It included a contribution by Matwey Kornilov to add support for inline archive files for Erlang s escript [ ]. kpcyrd has released a new version of rebuilderd. As a quick recap, rebuilderd is an automatic build scheduler that tracks binary packages available in a Linux distribution and attempts to compile the official binary packages from their (purported) source code and dependencies. The code for in-toto attestations has been reworked, and the instances now feature a new endpoint that can be queried to fetch the list of public-keys an instance currently identifies itself by. [ ] Lastly, Holger Levsen bumped the Standards-Version field of disorderfs, with no changes needed. [ ][ ]

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In August, however, a number of changes were made by Holger Levsen, including:
  • Setting up six new rebuilderd workers with 16 cores and 16 GB RAM each.
  • reproduce.debian.net-related:
    • Do not expose pending jobs; they are confusing without explaination. [ ]
    • Add a link to v1 API specification. [ ]
    • Drop rebuilderd-worker.conf on a node. [ ]
    • Allow manual scheduling for any architectures. [ ]
    • Update path to trixie graphs. [ ]
    • Use the same rebuilder-debian.sh script for all hosts. [ ]
    • Add all other suites to all other archs. [ ][ ][ ][ ]
    • Update SSH host keys for new hosts. [ ]
    • Move to the pull184 branch. [ ][ ][ ][ ][ ]
    • Only allow 20 GB cache for workers. [ ]
  • OpenWrt-related:
    • Grant developer aparcar full sudo control on the ionos30 node. [ ][ ]
  • Jenkins nodes:
    • Add a number of new nodes. [ ][ ][ ][ ][ ]
    • Dont expect /srv/workspace to exist on OSUOSL nodes. [ ]
    • Stop hardcoding IP addresses in munin.conf. [ ]
    • Add maintenance and health check jobs for new nodes. [ ]
    • Document slight changes in IONOS resources usage. [ ]
  • Misc:
    • Drop disabled Alpine Linux tests for good. [ ]
    • Move Debian live builds and some other Debian builds to the ionos10 node. [ ]
    • Cleanup some legacy support from releases before Debian trixie. [ ]
In addition, Jochen Sprickerhof made the following changes relating to reproduce.debian.net:
  • Do not expose pending jobs on the main site. [ ]
  • Switch the frontpage to reference Debian forky [ ], but do not attempt to build Debian forky on the armel architecture [ ].
  • Use consistent and up to date rebuilder-debian.sh script. [ ]
  • Fix supported worker architectures. [ ]
  • Add a basic excuses page. [ ]
  • Move to the pull184 branch. [ ][ ][ ][ ]
  • Fix a typo in the JavaScript. [ ]
  • Update front page for the new v1 API. [ ][ ]
Lastly, Roland Clobus did some maintenance relating to the reproducibility testing of the Debian Live images. [ ][ ][ ][ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Sergio Cipriano: Avoiding 5XX errors by adjusting Load Balancer Idle Timeout

Avoiding 5XX errors by adjusting Load Balancer Idle Timeout Recently I faced a problem in production where a client was running a RabbitMQ server behind the Load Balancers we provisioned and the TCP connections were closed every minute. My team is responsible for the LBaaS (Load Balancer as a Service) product and this Load Balancer was an Envoy proxy provisioned by our control plane. The error was similar to this:
[2025-10-03 12:37:17,525 - pika.adapters.utils.connection_workflow - ERROR] AMQPConnector - reporting failure: AMQPConnectorSocketConnectError: timeout("TCP connection attempt timed out: ''/(<AddressFamily.AF_INET: 2>, <SocketKind.SOCK_STREAM: 1>, 6, '', ('<IP>', 5672))")
[2025-10-03 12:37:17,526 - pika.adapters.utils.connection_workflow - ERROR] AMQP connection workflow failed: AMQPConnectionWorkflowFailed: 1 exceptions in all; last exception - AMQPConnectorSocketConnectError: timeout("TCP connection attempt timed out: ''/(<AddressFamily.AF_INET: 2>, <SocketKind.SOCK_STREAM: 1>, 6, '', ('<IP>', 5672))"); first exception - None.
[2025-10-03 12:37:17,526 - pika.adapters.utils.connection_workflow - ERROR] AMQPConnectionWorkflow - reporting failure: AMQPConnectionWorkflowFailed: 1 exceptions in all; last exception - AMQPConnectorSocketConnectError: timeout("TCP connection attempt timed out: ''/(<AddressFamily.AF_INET: 2>, <SocketKind.SOCK_STREAM: 1>, 6, '', ('<IP>', 5672))"); first exception - None
At first glance, the issue is simple: the Load Balancer's idle timeout is shorter than the RabbitMQ heartbeat interval. The idle timeout is the time at which a downstream or upstream connection will be terminated if there are no active streams. Heartbeats generate periodic network traffic to prevent idle TCP connections from closing prematurely. Adjusting these timeout settings to align properly solved the issue. However, what I want to explore in this post are other similar scenarios where it's not so obvious that the idle timeout is the problem. Introducing an extra network layer, such as an Envoy proxy, can introduce unpredictable behavior across your services, like intermittent 5XX errors. To make this issue more concrete, let's look at a minimal, reproducible setup that demonstrates how adding an Envoy proxy can lead to sporadic errors.

Reproducible setup I'll be using the following tools: This setup is based on what Kai Burjack presented in his article. Setting up Envoy with Docker is straightforward:
$ docker run \
    --name envoy --rm \
    --network host \
    -v $(pwd)/envoy.yaml:/etc/envoy/envoy.yaml \
    envoyproxy/envoy:v1.33-latest
I'll be running experiments with two different envoy.yaml configurations: one that uses Envoy's TCP proxy, and another that uses Envoy's HTTP connection manager. Here's the simplest Envoy TCP proxy setup: a listener on port 8000 forwarding traffic to a backend running on port 8080.
static_resources:
  listeners:
  - name: go_server_listener
    address:
      socket_address:
        address: 0.0.0.0
        port_value: 8000
    filter_chains:
    - filters:
      - name: envoy.filters.network.tcp_proxy
        typed_config:
          "@type": type.googleapis.com/envoy.extensions.filters.network.tcp_proxy.v3.TcpProxy
          stat_prefix: go_server_tcp
          cluster: go_server_cluster
  clusters:
  - name: go_server_cluster
    connect_timeout: 1s
    type: static
    load_assignment:
      cluster_name: go_server_cluster
      endpoints:
      - lb_endpoints:
        - endpoint:
            address:
              socket_address:
                address: 127.0.0.1
                port_value: 8080
The default idle timeout if not otherwise specified is 1 hour, which is the case here. The backend setup is simple as well:
package main

import (
    "fmt"
    "net/http"
    "time"
)

func helloHandler(w http.ResponseWriter, r *http.Request)  
  w.Write([]byte("Hello from Go!"))
 

func main()  
    http.HandleFunc("/", helloHandler)

    server := http.Server 
        Addr:        ":8080",
        IdleTimeout: 3 * time.Second,
     

    fmt.Println("Starting server on :8080")
    panic(server.ListenAndServe())
 
The IdleTimeout is set to 3 seconds to make it easier to test. Now, oha is the perfect tool to generate the HTTP requests for this test. The Load test is not meant to stress this setup, the idea is to wait long enough so that some requests are closed. The burst-delay feature will help with that:
$ oha -z 30s -w --burst-delay 3s --burst-rate 100 http://localhost:8000
I'm running the Load test for 30 seconds, sending 100 requests at three-second intervals. I also use the -w option to wait for ongoing requests when the duration is reached. The result looks like this: oha test report tcp fail We had 886 responses with status code 200 and 64 connections closed. The backend terminated 64 connections while the load balancer still had active requests directed to it. Let's change the Load Balancer idle_timeout to two seconds.
filter_chains:
- filters:
  - name: envoy.filters.network.tcp_proxy
    typed_config:
      "@type": type.googleapis.com/envoy.extensions.filters.network.tcp_proxy.v3.TcpProxy
      stat_prefix: go_server_tcp
      cluster: go_server_cluster
      idle_timeout: 2s # <--- NEW LINE
Run the same test again. oha test report tcp success Great! Now all the requests worked. This is a common issue, not specific to Envoy Proxy or the setup shown earlier. Major cloud providers have all documented it. AWS troubleshoot guide for Application Load Balancers says this: The target closed the connection with a TCP RST or a TCP FIN while the load balancer had an outstanding request to the target. Check whether the keep-alive duration of the target is shorter than the idle timeout value of the load balancer. Google troubleshoot guide for Application Load Balancers mention this as well: Verify that the keepalive configuration parameter for the HTTP server software running on the backend instance is not less than the keepalive timeout of the load balancer, whose value is fixed at 10 minutes (600 seconds) and is not configurable. The load balancer generates an HTTP 5XX response code when the connection to the backend has unexpectedly closed while sending the HTTP request or before the complete HTTP response has been received. This can happen because the keepalive configuration parameter for the web server software running on the backend instance is less than the fixed keepalive timeout of the load balancer. Ensure that the keepalive timeout configuration for HTTP server software on each backend is set to slightly greater than 10 minutes (the recommended value is 620 seconds). RabbitMQ docs also warn about this: Certain networking tools (HAproxy, AWS ELB) and equipment (hardware load balancers) may terminate "idle" TCP connections when there is no activity on them for a certain period of time. Most of the time it is not desirable. Most of them are talking about Application Load Balancers and the test I did was using a Network Load Balancer. For the sake of completeness, I will do the same test but using Envoy's HTTP connection manager. The updated envoy.yaml:
static_resources:
  listeners:
  - name: listener
    address:
      socket_address:
        address: 0.0.0.0
        port_value: 8000
    filter_chains:
    - filters:
      - name: envoy.filters.network.http_connection_manager
        typed_config:
          "@type": type.googleapis.com/envoy.extensions.filters.network.http_connection_manager.v3.HttpConnectionManager
          stat_prefix: go_server_http
          access_log:
          - name: envoy.access_loggers.stdout
            typed_config:
              "@type": type.googleapis.com/envoy.extensions.access_loggers.stream.v3.StdoutAccessLog
          http_filters:
          - name: envoy.filters.http.router
            typed_config:
              "@type": type.googleapis.com/envoy.extensions.filters.http.router.v3.Router
          route_config:
            name: http_route
            virtual_hosts:
            - name: local_service
              domains: ["*"]
              routes:
              - match:
                  prefix: "/"
                route:
                  cluster: go_server_cluster
  clusters:
  - name: go_server_cluster
    type: STATIC
    load_assignment:
      cluster_name: go_server_cluster
      endpoints:
      - lb_endpoints:
        - endpoint:
            address:
              socket_address:
                address: 0.0.0.0
                port_value: 8080
The yaml above is an example of a service proxying HTTP from 0.0.0.0:8000 to 0.0.0.0:8080. The only difference from a minimal configuration is that I enabled access logs. Let's run the same tests with oha. oha test report http fail Even thought the success rate is 100%, the status code distribution show some responses with status code 503. This is the case where is not that obvious that the problem is related to idle timeout. However, it's clear when we look the Envoy access logs:
[2025-10-10T13:32:26.617Z] "GET / HTTP/1.1" 503 UC 0 95 0 - "-" "oha/1.10.0" "9b1cb963-449b-41d7-b614-f851ced92c3b" "localhost:8000" "0.0.0.0:8080"
UC is the short name for UpstreamConnectionTermination. This means the upstream, which is the golang server, terminated the connection. To fix this once again, the Load Balancer idle timeout needs to change:
  clusters:
  - name: go_server_cluster
    type: STATIC
    typed_extension_protocol_options: # <--- NEW BLOCK
      envoy.extensions.upstreams.http.v3.HttpProtocolOptions:
        "@type": type.googleapis.com/envoy.extensions.upstreams.http.v3.HttpProtocolOptions
        common_http_protocol_options:
          idle_timeout: 2s # <--- NEW VALUE
        explicit_http_config:
          http_protocol_options:  
Finally, the sporadic 503 errors are over: oha test report http success

To Sum Up Here's an example of the values my team recommends to our clients: recap drawing Key Takeaways:
  1. The Load Balancer idle timeout should be less than the backend (upstream) idle/keepalive timeout.
  2. When we are working with long lived connections, the client (downstream) should use a keepalive smaller than the LB idle timeout.

Dirk Eddelbuettel: RcppArmadillo 15 CRAN Transition: Offering Office Hours

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1273 other packages on CRAN, downloaded 41.8 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 651 times according to Google Scholar. Armadillo 15 brought changes. We mentioned these in the 15.0.2-1 and 15.0.2-1 release blog posts: (The second point is a consequence of the first. Prior to C++14, deprecation notes were issue via a macro, and the macro was set up by Conrad in the common way of allowing an override, which we took advantage of in RcppArmadillo effectively shielding downstream package. In C++14 this is now an attribute, and those cannot be suppressed.) We tested this then-upcoming change extensively: Thirteen reverse dependency runs expoloring different settings and leading to the current package setup where an automatic fallback to the last Armadillo 14 release offers fallback for hardwired C++11 use and Armadillo 15 others. Given the 1200+ reverse deoendencies, this took considerable time. All this was also quite extensively discussed with CRAN (especially Kurt Hornik) and documented / controlled via a series of issue tickets starting with overall issue #475 covering the subissues: The sixty pull requests (or emailed patches) followed a suggestion by CRAN to rank-order packages affected by their reverse dependencies sorted in descending package count. Now, while this change from Armadillo 14 to 15 was happening, CRAN also tightened the C++11 requirement for packages and imposed a deadline for changes. In discussion, CRAN also convinced me that a deadline for the deprecation warning, now unmasked, was viable (and is in fairness commensurate with similar, earlier changes triggered by changes in the behaviour of either gcc/g++ or clang/clang++). So we now have two larger deadline campaigns affecting the package (and as always there are some others). These deadlines are coming close: October 17 for the C++11 transition, and October 23 for the deprecation warning. Now, as became clear preparing the sixty pull requests and patches, these changes are often relatively straightforward. For the former, remove the C++11 enforcement and the package will likely build without changes. For the latter, make the often simple (e.g. swith from arma::is_finite to std::isfinite) change. I did not encounter anything much more complicated yet. The number of affected packages approximated by looking at all packages with a reverse dependency on RcppArmadillo and having a deadline can be computed as
suppressMessages(library(data.table))
D <- setDT(tools::CRAN_package_db())
P <- data.table(Package=tools::package_dependencies("RcppArmadillo", reverse=TRUE, db=D)[[1]])
W <- merge(P, D, all.x=TRUE)[is.na(Deadline)==FALSE,c(1:2,38,68)]
W

W[, nrevdep := length(tools::package_dependencies(Package, reverse=TRUE, recursive=TRUE, db=D)[[1]]), by=Package]
W[order(-nrevdep)]
and has been declining steadily from over 350 to now under 200. For that a big and heartfelt Thank You! to all the maintainers who already addressed their package and uploaded updated packages to CRAN. That rocks, and is truly appreciated. Yet the number is still large. And while issues #489 and #491 show a number of pending packages that have merged but not uploaded (yet?) there are also all the other packages I have not been able to look at in detail. While preparing sixty PRs / patches was viable over a period of a good week, I cannot create these for all packages. So with that said, here is a different suggestion for help: All of next week, I will be holding open door open source office hours online two times each day (11:00h to 13:00h Central, 16:00h to 18:00h Central) which can be booked via this booking link for Monday to Friday next week in either fifteen or thirty minutes slots you can book. This should offer Google Meet video conferencing (with jitsi as an alternate, you should be able to control that) which should allow for screen sharing. (I cannot hookup Zoom as my default account has organization settings with a different calendar integration.) If you are reading this and have a package that still needs helps, I hope to see you in the Open Source Office Hours to aid in the RcppArmadillo package updates for your package. Please book a slot!

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Next.

Previous.