Search Results: "tar"

24 August 2026

David Bremner: Reproducing Org mode configuration

Context Recently I was trying to reproduce a bug with citeproc.el and org-mode in emacs. I thought I could use package-vc-install to install a set of upstream emacs packages at fixed versions, and thereby let citeproc upstream test in the same environment as I have. It turns out that getting emacs to load the non-builtin version of org via package-vc-install did not work because
  • org-mode needs to run make after cloning
  • once package.el was initialized, I always seemed to end up with the built in org-mode (yeah, I realize that isn't an explanation).

Recipe part 1: get org Here you can replace 9.8.7 with any other tagged release
  EMACSHOME=$(mktemp -d)
  git clone https://git.sr.ht/~bzg/org-mode $ EMACSHOME /org
  git -C $ EMACSHOME /org reset --hard release_9.8.7 
  make -C $ EMACSHOME /org autoloads
  emacs -Q --batch -L $ EMACSHOME /org/lisp --eval "(progn (require 'org) (message (org-version)))"
This should print 9.8.7, not the version of built in org-mode.

Recipe part 2: add-on packages Now to test some add-on packages, run
    emacs -Q --init-directory $ EMACSHOME  -L $ EMACSHOME /org/lisp
  (progn
    (require 'org)
    (package-initialize)
    (package-vc-install "https://github.com/emacs-straight/queue")
    (package-vc-install "https://github.com/joostkremers/parsebib" "6.7")
    (package-vc-install "https://github.com/rejeep/f.el" "0.21.0")
    (package-vc-install "https://github.com/magnars/s.el" "1.13.0")
    (package-vc-install "https://github.com/akicho8/string-inflection" "1.0.16")
    (package-vc-install "https://github.com/andras-simonyi/citeproc-el" "0.9.5"))
You can then run your tests in that emacs right away, or restart the environment with
  emacs -Q --init-directory $ EMACSHOME  -L $ EMACSHOME /org/lisp

Freexian Collaborators: Monthly report about Debian Long Term Support, July 2026 (by Santiago Ruano Rinc n)

The Debian LTS Team, funded by Freexian s Debian LTS offering, is pleased to report its activities for July.

Activity summary During the month of July, 23 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 52 DLAs fixing 2159 CVEs. In July, the Debian Stable Release Managers published the last point release of Debian 12 ( bookworm ), after which the Debian LTS team took full responsibility of Debian 12. This completes the handover from the Security Team, that took place in June. This also marks the second month in a row where the Debian LTS has been focusing on two simultaneous Debian releases. Other than Debian 12, the team is maintaining Debian 11 ( bullseye ), which will reach the end of its Long Term Support on 31 August 2026. After that date, Freexian will continue the security support under the Extended LTS offer. The team published several notable updates:
  • jq (DLA 4662-1 and DLA 4661-1) prepared by Andreas Henriksson in collaboration with Jochen Sprickerhof, addressing multiple vulnerabilities.
  • Several updates for the different linux supported versions prepared by Ben Hutchings, in collaboration with Emilio Pozuelo Monfort. Other than the regular security advisories: DLA 4664-1, DLA 4665-1, DLA 4671-1, DLA 4688-1, and DLA 4700-1, Ben started preparing packages of 6.12 via bookworm-backports.
  • nginx (DLA 4667-1), updated for bookworm by Carlos Henrique Lima Melara, as a follow up of the bullseye update (DLA 4660-1), that was prepared in June.
  • grub2/bullseye (DLA 4685-1), prepared by Emilio. Other than addressing several security issues, this DLA was needed for being able to update the shim boot loader.
  • samba (DLA 4692-1), uploaded by Markus Koschany, to fix several security flaws in bullseye, including issues that could yield to remote code execution.
  • imagemagick (DLA 4680-1 and DLA 4696-1), prepared by Bastien Roucari s, addressing several issues that could lead to denial of service, information disclosure or potentially arbitrary code execution in some scenarios.
  • poppler (DLA 4709-1), by Guilhem Moulin, fixing several vulnerabilities.
  • nss (DLA-4694-1), by Jochen, fixing flaws that may result in or denial of service or potentially the execution of arbitrary code.
Contributions from outside the LTS Team: The LTS Team has also contributed with updates to the latest Debian releases:
  • Bastien also proposed two updates for imagemagick. The first one released as DSA 6383-1, and the second as a trixie point update proposal (#1142554).
  • python-httplib2 by Emmanuel Arias, and released by the security team as DSA 6441-1 in August.
  • hplip (DSA 6402-1), prepared by Thorsten Alteholz, to address privilege escalation and arbitrary code execution related flaws.
  • libnfs trixie update (#1142351), by Thorsten
  • patool update for trixie #1141607, by Abhijith PA
Other contributions: Besides the work on security updates, different documentation and tooling changes were needed, especially in the context of the Debian 12 handover. This work was mainly done by Sylvain Beucler.

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

23 August 2026

Russ Allbery: Long delayed haul

I haven't made a new book haul post in I don't know how long, so a lot of books have piled up and many have already been reviewed. Here's the overdue catch-up in case anyone is curious what books I am finding interesting before the reviews get posted. Ilona Andrews Magic Bites (sff)
Elizabeth Bear In the House of Aryaman, a Lonely Signal Burns (sff)
Oliver Burkeman Four Thousand Weeks (non-fiction)
Miles Cameron Whalesong (sff)
Lee Child Killing Floor (thriller)
august clarke The Felicity Complex (sff)
Alison Cochrun Here We Go Again (romance)
Dan Davies The Unaccountability Machine (non-fiction)
Linzi Day Midlife in Gretna Green (sff)
Linzi Day Painting the Blues in Gretna Green (sff)
Linzi Day Ties that Bond in Gretna Green (sff)
Linzi Day Spilling the Tea in Gretna Green (sff)
Michelle Diener Dark Ambitions (sff)
Michelle Diener Dark Class (sff)
Michelle Diener Collision Course (sff)
Michelle Diener Crash Course (sff)
Henry Farrell Underground Empire (non-fiction)
Kathleen A. Flynn The Jane Austen Project (sff)
Victoria Goddard The Hands of the Emperor (sff)
James Herriot All Creatures Great and Small (mainstream)
James Herriot All Things Bright and Beautiful (mainstream)
James Herriot All Things Wise and Wonderful (mainstream)
James Herriot The Lord God Made Them All (mainstream)
James Herriot Every Living Thing (mainstream)
Lauren Hough Monster of a Land (non-fiction collection)
Bethany Jacobs This Brutal Moon (sff)
Guy Gavriel Kay Written on the Dark (sff)
Mary Robinette Kowal The Martian Contingency (sff)
Ann Leckie Radiant Star (sff)
C.B. Lee Coffeeshop in an Alternate Universe (sff)
Fonda Lee The Last Contract of Isako (sff)
Julie Leong The Teller of Small Fortunes (sff)
Julie Leong The Keeper of Magical Things (sff)
R.Z. Nicolet The Cloak and Its Wizard (sff)
Claire North Slow Gods (sff)
Rebecca Ore Writing's Writing (non-fiction collection)
Suzanne Palmer Ode to the Half-Broken (sff)
Gareth L. Powell Fleet of Knives (sff)
Cameron Reed What We Are Seeking (sff)
Beth Revis Full Speed to a Crash landing (sff)
Beth Revis How to Steal a Galaxy (sff)
Beth Revis Last Chance to Save the World (sff)
Natalie Zina Walschots Villain (sff)
Jo Walton Everybody's Perfect (sff)
Martha Wells Platform Decay (sff)
James White The Galactic Gourmet (sff)
James White Final Diagnosis (sff)
The James Herriot books were ones my parents were getting rid of. I have them marked as mainstream fiction as a short-hand since "fictionalized autobiography" seemed like too much of a mouthful.

Sergio Cipriano: Two Debian Days in one week

Two Debian Days in one week The Debian Project was officially founded by Ian Murdock on August 16, 1993. The Debian community celebrates its birthday, Debian Day, on or around this date every year. This year, I had the chance to attend two of them: one in Jo o Pessoa, Para ba, and another in Bras lia, the capital of Brazil.

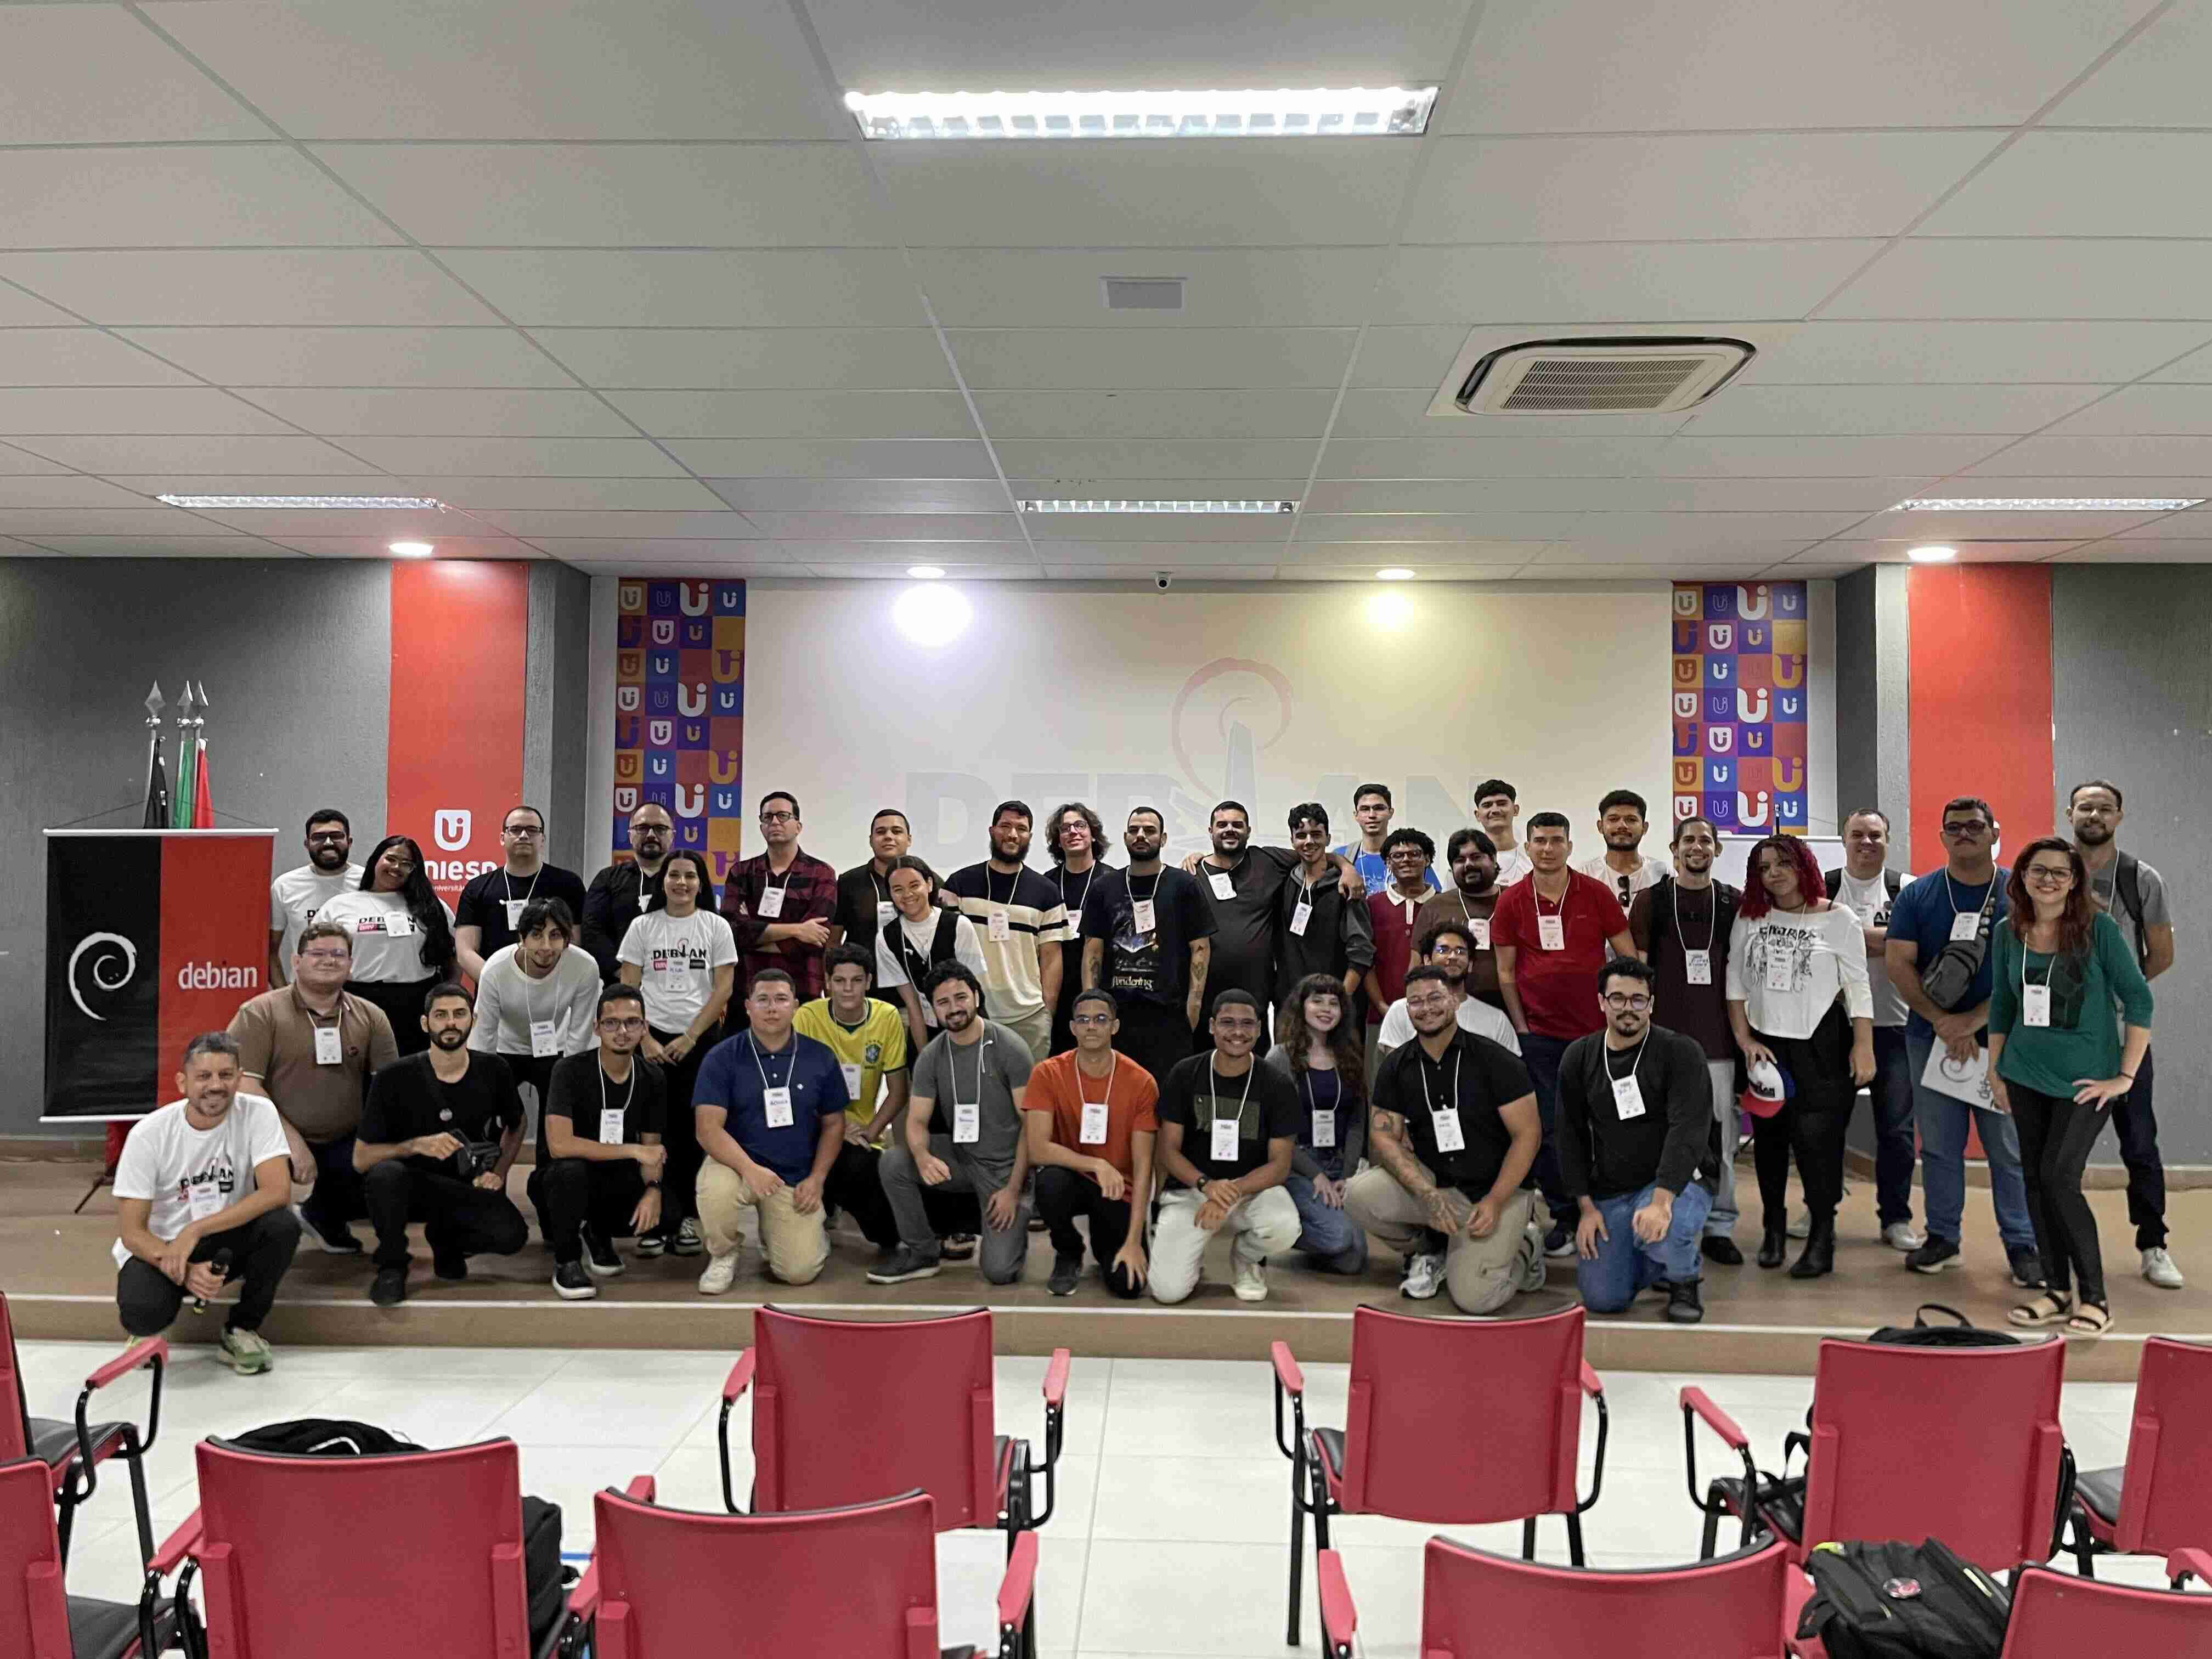
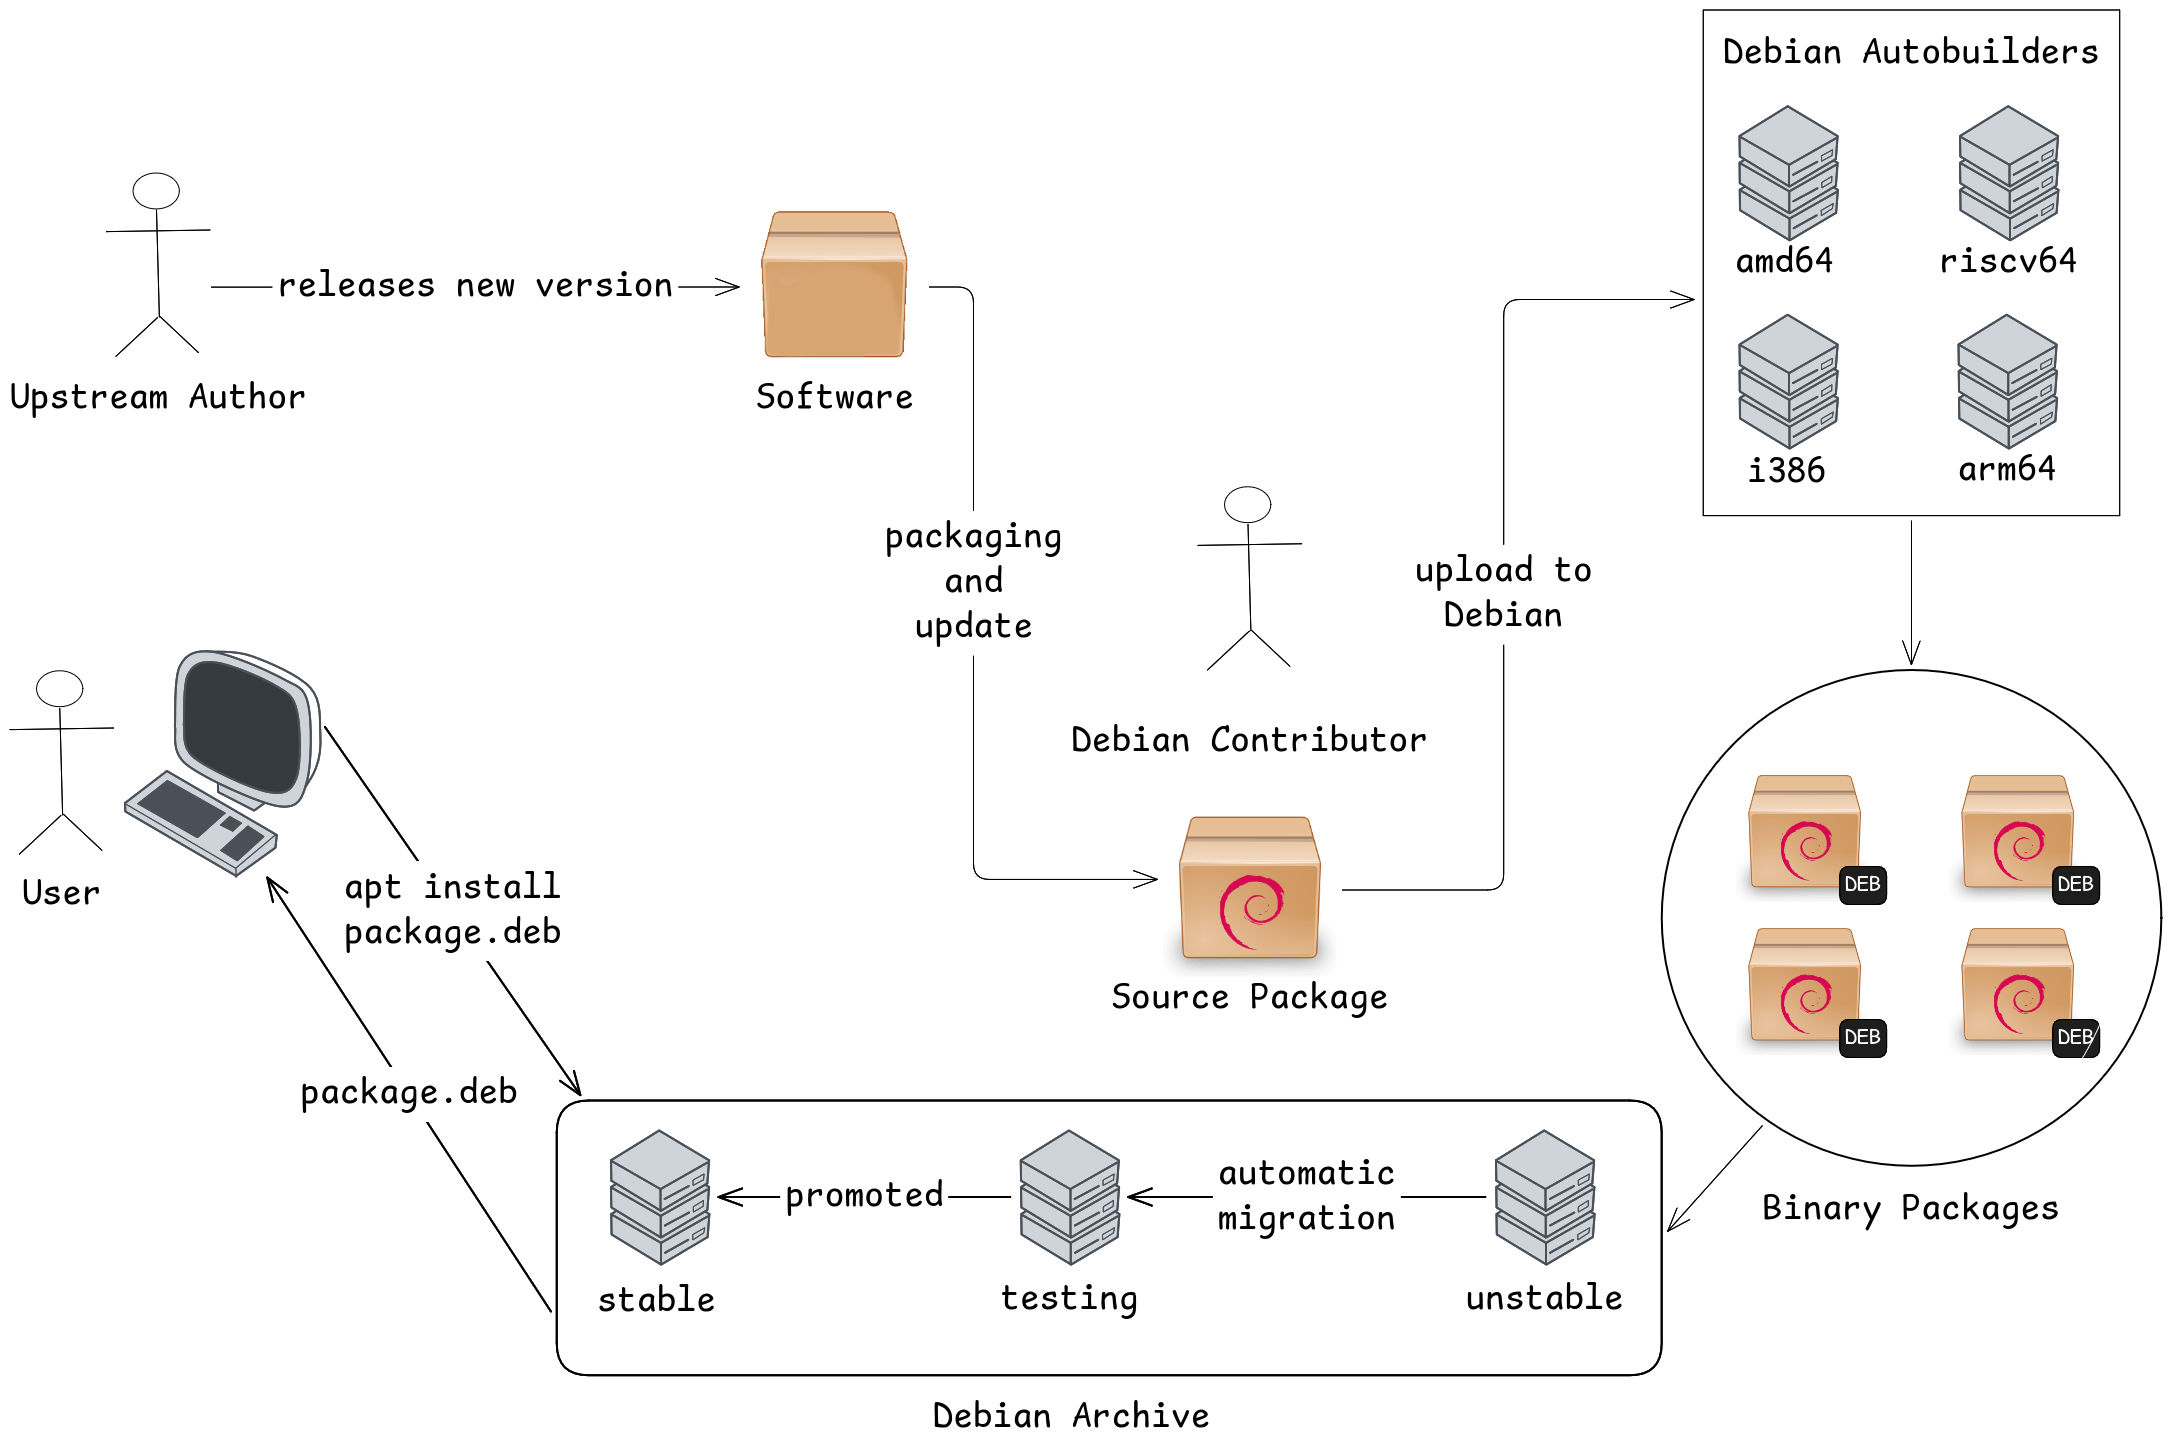
Jo o Pessoa Debian Day Jo o Pessoa Group Photo In Jo o Pessoa, we had a two-day event. The first day was dedicated entirely to workshops, and I ran a packaging workshop for newcomers. It was the first time I had been responsible for a workshop, and it was a great experience. We didn't have a lot of time, so I decided to start with a 30-minute talk explaining a few things about Debian. For example, I made this image to explain the packaging workflow: Debian upload workflow This image was based on The Debian Administrator's Handbook, and I think the participants really enjoyed learning about this workflow. When I showed the slide with this image, it was the moment when I received the most questions. After the talk, I explained my way of working and what they were going to do. The hardest part was setting up the environment, since my approach uses sbuild + gbp. They were running different Debian releases and, because of my inexperience with workshops, I had some of them configure sbuild with unshare, even though it is only available in stable through backports. Some of them even managed to learn how to use backports, while others decided to start again using the "old" way. One thing that helped a lot was the Debian Brasil Wiki. It has all the instructions for configuring sbuild in Portuguese, along with great examples. The Brazilian wiki is an opinionated version of the Debian Wiki. We generally prefer to use it for the convenience of having the exact workflow we follow, as well as an up-to-date Portuguese version of our process. If you want to learn more about the Brazilian community, you can find more details in the schedules from previous DebConfs. We almost always had a talk about the community and its activities. In the end, everyone successfully set up their development environment, and all six participants made their first contribution to Debian. If you take a look at my upload tracking page, you will see that every upload made on August 15, 2026 was a sponsored upload from this event. One of them appear twice in the list because I sponsored the upload and also made some other changes. I also asked all of them to put this in their changelog:
* My first contribution!
The idea was to make it clear to other people that they were only working on small Lintian issues as a way of learning and understanding the process. By the way, I made a UDD query to find packages with the following Lintian tag: redundant-rules-requires-root-no-field. To fix this issue, they only had to remove one line from the debian/control file. It is obvious that these uploads are not particularly useful. I call them "motivational uploads" because my goal is to help newcomers understand the process and immediately give them the reward of having made a contribution to Debian. I'll try to keep in touch with them. My plan is to hold another session, this time remotetly, to help them continue contributing to Debian. In fact, I already have another package prepared by one of them waiting for my review. The second day was a full-day event featuring a bunch of talks from the local community. I gave a talk explaining the new members process. I was the only Debian Developer at the event, and I think having a DD there made a real difference. Being there to answer questions, and simply being present, makes Debian feel more tangible and accessible to people. A big shout-out to Rafael Rocha, who put in a lot of work to make this event happen, with the help of many volunteers who contributed along the way.

Bras lia Debian Day talk in Bras lia One thing I really like about Debian Days is that each place has its own way of doing things. In Jo o Pessoa, we had a MiniDebConf-like event, while in Bras lia, we had something smaller but still very valuable. We decided to keep things simple: talk to a few students at the University of Bras lia (UnB) and then go somewhere to eat and have a few drinks.

A bit of history For those who don't know, the DebConf 19 was held in Curitiba, Brazil. After the event, Arthur Diniz got really excited about Debian and decided to go back to his University, UnB, to share his experience and encourage more people to contribute to Debian. I attended one of his talks, thanks to Joenio Costa, who invited Arthur to give the talk. Joenio was also my professor at the time and a Debian contributor. I really liked what Arthur had to say about free software, and he did a great job of presenting the Debian community as a friendly and welcoming place. So I decided to attend local meetings of the Debian Bras lia community, which had been inactive for a long time. Lucas Kanashiro was the Debian Developer who answered our questions and, as I mentioned earlier, simply being there made Debian feel more tangible. Everything stopped when the pandemic began. Then, towards the end of 2020, I saw a message in the Debian Bras lia channel saying that the meetings were back, this time remotely. I was hesitant to join because, back in 2019, I hadn't managed to make a packaging contribution, even with their help. I had eventually given up on the process. So this time, I decided to join the meeting with something already prepared for review. I watched all of Eriberto's packaging videos, picked a random package, and joined the meeting. I remember Kanashiro being excited that someone had just shown up with something ready for review. At the time, it was only the second meeting since Debian Bras lia had come back online, and none of the newcomers had started working on contributions yet. During the same meeting, he also convinced us, the newcomers, to give a talk about Debian just three days later. The MiniDebConf Online Brazil 2020 was happening on Sunday, and the meeting was on the Thursday before it. Since he has great convincing skills, I went along with the idea and prepared the talk with Francisco Ferreira. That was the rebirth of the Debian Bras lia community. Since then, we have maintained a close connection with the University of Bras lia, and today, at least seven Debian Developers are from UnB, whether as former students or former professors. The reason I told this story is that, even though the Debian Day we held in Bras lia was smaller, it is part of something that has been working for us for several years: staying close to an University. We've managed to attract and retain many people who share the same values and interests. I've hope you all had a great Debian Day. If you're reading this and aren't part of the Debian community but would like to join, get in touch!

22 August 2026

Aigars Mahinovs: Optimistic take on AI

As I am writing this, there is a vote ongoing in the Debian project on how to deal with AI in general and AI-assisted contributions to Debian specifically. Massive discussions have happened in debian-vote and other locations. I have also asked questions there and offered my perspective. IMHO now is the time to summarize that, after all the discussions that I've had with people on multiple sides of this debate both online and offline, and explain how I will be voting and why. Hopefully that will be helpful to someone else as well. None of this has been compiled with AI assistance, but only because I think that forming opinions is not something where AI can really be helpful. Spellcheck was used though. So, first I will describe how I see each of the 8 proposals, then what my vote will be, and then a bit more detail on the reasoning and thinking behind this. WARNING - this went long. With all the above considered I will vote like this (earlier options are preferred over later options): Details on rationale Hypocrisy - I find any proposal that would ban AI-assisted contributions to Debian, but at the same time not ban including AI-assisted contributions from upstream projects to be inherently hypocritical. If LLMs and AI are the very incarnation of evil (a puppy-killing machine, as the analogy went in some emails), then any rational proposal would involve excluding any and ALL code contaminated by this evil from the project. What does it matter if puppies were killed in writing the debian subfolder of the source code or the src subfolder? No proposals went there because everyone knows that such a ban would be the death of the relevance of the project for the future. Debian would be frozen on some old version of the Linux kernel forever and other software would be falling to the same problem too, for example as projects on GitHub start enabling AI-supported reviews with patch suggestions. Soon the "development" of Debian could just be stopped as there is nothing to develop without any upstreams. Assumptions - a lot of proposals mention various "concerns" with at most one word, like "practical" or "community" without an explanation of what exactly they mean by that. The proposers assumed that everyone lives in the same info bubble as they do and already know everything that they mean and already agree to that. That is false. Proposal A was a positive stand-out in this area. Debian has contributors all over the world with very different exposure to different information sources and very different world views. If you want to convince the project as a whole that LLMs are bad because of "ethics", then you do really need to explain what you mean by that and give links to sources, at least as well as Proposal A did. All other proposals were really weak in this area. Copyright - the question on how copyright law interacts with training LLMs and their outputs is still not settled law. The closest legal statements we have so far are that - just because an LLM is trained on copyrighted material does not make that LLM itself be a derivative work of the training data (you, however, cannot just create and distribute a "library" of copyrighted materials just because you plan to train LLMs on it). The output of the LLM might not be subject to copyright law at all, like a photo taken by a monkey. It would then be public domain and thus can be modified and then licensed by the user of the LLM. It might also be a derived work of the context of the inference (so for software - if you refactor a GPL project, the refactoring itself is likely GPL too). Any stricter interpretations would break a lot of existing copyright doctrine, such as raising questions like: "does the output of any programmer now become a derived work of the programming manual books they read in college?". In any case it is really not up to Debian to legislate the nuances of copyright law. And I strongly disagree with the concept that an author can tell me how I am allowed to use the learnings that I gained by reading their work. That is not how either copyright or society works. I can look at 10 pictures of a sunset and draw my own, inspired by the ones I saw. No one can forbid me that expression. The same must be true for a machine learning and replicating patterns. Ethics - I've re-read all proposals and emails and the only real specifically ethical concern I could find was the complaint that some LLMs (or their training farms) are running their web scrapers too aggressively and that causes extra load on services. Like that is not an LLM problem. Scraping the web is not an inherent part of the LLM training or inference process. It's just a few misconfigured scripts. We saw the exact same thing in the early days of web search engine proliferation. Then we banned/blocked the misconfigured engines and the survivors learned that obeying robots.txt is one of the rules for surviving. Literally the exact same problem and it will be solved the same way. Did we ban all search engines back then just because some of them were misconfigured? No. Some claims (like in Proposal C) are just bombastic hyperbole ("hazards to users' mental health", "fraud", ...) and on top of that have zero relevance to the topic at hand - AI-assisted contributions to Debian. What "hazard to users' mental health" is created when a Coderabbit spots that a lock is not taken before accessing a resource in a particular function and suggests an AI-generated patch to fix it? What "fraud" is committed by this? There is no sane answer. I get that some people are very busy fighting some culture wars and sometimes, some AI-bros happen to be on the other side of one such war, so it is useful to label everything coming from the AI sphere as "bad" in all possible and impossible ways. You do you. In private. Why pull Debian into that? Why force your position on everyone else in the project? Why deny everyone in the project access to useful tooling, just because you have strong feelings about some of the people promoting some of those tools? This seems to me a repeating pattern here - blaming the technology as a whole or blaming all providers of this type of technology for failings (ethical or technical) of some of those providers. Like refusing to wear all shoes and condemning all shoemakers and sellers, just because some American billionaires figured out a way to make and sell cheap shoes by killing puppies. Not refusing and condemning those providers, but condemning all for the actions of a few. Resource usage - this is a big topic for many and it has reasonable points to it. The LLM and AI technology has no inherent need to be damaging to the environment in any way for it to function. It does not need to burn oil or dig up cobalt. It does not need to sacrifice a ton of water to the Gods. It is perfectly possible to run AI (both inference and training) purely from green, electrical energy and cool data centers in equally sustainable ways, like with simple air-source heat pumps (also known as air conditioning) or even use it beneficially (many data centers are used for heating surrounding buildings via district heating). However, some AI companies do use non-green power for their data centers, some do use locally-limited fresh water for evaporative cooling (evaporated water still rains down as rain, it is not really lost, but that may happen in another location so lack of water can still happen locally). Some even run unlicensed natural gas turbines in their data centers to provide them with power. And those specific providers can and should be shunned and condemned. Not the other ones, who are doing the right things. Not the technology or its users or its outputs. There is a very wide spectrum of options on how an AI system could be powered: starting from local execution on already existing private hardware powered by one's own local solar power (good), to a data center stuffed with borrowed AI-only cards powered by a gas turbine or coal power station that operates solely to supply this data center (bad). Proposals that talk about ecological impact, but do not even consider where on that (very wide) spectrum to draw the line between "good", "acceptable", "discouraged" and "bad" well, I cannot see those proposals being actually serious about the environment to begin with. It feels like they just refer to it for points. And if we go into the power question deeper, well the grid dynamics and economics become very, very complex and often also non-intuitive. Like, all large software companies with data centers (that also happen to provide AI services), like Google, Meta, Apple, Microsoft and others do actually care about sustainability (in part because their customers care and vote with their wallets) and so all of them use 100% green energy for their data centers (including AI data centers) .... "on an annual scale". Wait, what does that mean? Well, the electrical grid is special - the amount of electricity produced and consumed on the whole electrical grid together has to match almost exactly every second. If there is just a single second where there is significantly more energy consumed from the grid than is produced, the frequency will plummet and you get a brownout and risk a grid collapse. The same is true in reverse - that causes a voltage swell. So grid operators manage energy flows every second and command power stations to increase and decrease generation all the time. Some power stations are easier to regulate dynamically than others. In the end, all that means is that even if your data center has a contract for 100% green energy with your power company, at some seconds across the year there might not be enough green energy in the grid to fully supply ALL people and companies that have 100% green energy contracts. This gets compensated in other seconds, so that across the year ("on an annual scale") for each kWh that your data center pulled from the grid, the same amount of kWh of 100% green energy flows into the grid. But it might not happen at the exact same second. Pedantic companies, like Google, take that discrepancy and count that as CO2 emissions for themselves. And then they and the power companies (they have contracts with) invest billions into new green energy projects, better grids and better batteries so that eventually this discrepancy goes down to zero. In this way green AI data centers with their increasing consumption of green energy are actually doing a lot of good work in making our electrical grid more green. They are making more resources than they are consuming. And that is just the tip of the iceberg. This is a deep topic that really abhors generalizations like "more consumption = bad". I've heard similar discussions in the context of electric cars - "so you got an electric car? you'd have fewer emissions if you drove no car at all!". That might be so. And I would also reduce my emissions to zero if I stopped breathing, but I really do not want that kind of thinking to be propagated further, especially when impressionable young people are around who may take it to its logical (but wrong!) conclusion. Instead I talk about how early adopters use electric cars to gather experience and achieve volume to start the network effects working. Once network effects of many electric cars on the roads are sufficient, it becomes an economically logical choice to get an electric car. People who cannot avoid having a car start to switch over. And at the point of mass switchover the reduction of emissions is so massive that those early adopters failing to go all the way to riding a bicycle becomes a rounding error. But surely that does not apply to LLMs? They are only increasing consumption and bring no benefit? Benefit - and here we have to actually talk about benefits. Because you cannot make any cost-benefit analysis if you do not actually fully investigate the benefits. Are there environmental benefits from running those AI models? Yes, in a lot of very diverse ways. Hard to measure, however. There are projects that are easy to quantify - like that Google AI project on contrail avoidance. An advanced, special model trained and executed in Google AI data centers was able to predict where in the air contrails would be produced and could generate proposed course adjustments to commercial flights to avoid specific heights in specific locations at specific times. This stopped these aircraft from creating contrails and those contrails did not make a further contribution to global warming. That benefit in a year was many times higher than the environmental cost of training and running that AI model. And it can keep running for many years accumulating further benefits. On a personal scale, I've had problems that I bashed my head (and computer and CI resources) against without much success years ago solved with a few minutes of compute. Having a good enough candidate solution quickly is much cheaper from a resource perspective than spending days trying different things, running my PC for it, trying different patches on CI executions, doing different rebuilds. I've seen very significant benefits in AI-assisted development in enterprise environments where code way more complex than what is in Debian (especially in Debian tools and packaging) gets analysed, reviewed, modified or even refactored or rewritten in another language with AI assistance. And it generally works. The commonly mentioned "hallucinations" are a thing of last year in the coding context. Nowadays the AIs work in special coding harnesses and use real tools as foundational facts. You cannot "hallucinate" an API call or parameter if you have to run and pass the unit tests and integration tests by your harness before you can return "success" to the caller. I've personally seen high-level AI models read very complex software projects across multiple repositories and point out a very specific design consideration that was encoded in the code logic, but never mentioned in comments or documentation. It was so obscure that even I did not immediately know what it was talking about (and I wrote that code). Only on close inspection of code interaction across three repos did I remember that there was indeed that bug 2 years ago that I fixed by doing the change that this AI picked up (it wasn't in the history of this git repo due to repo migration). It mentioned this because it was very relevant to the task I initially gave it to review. These LLMs in a proper harness with proper system instructions and usage approach are not just fancy spell checkers or auto-complete. They function more like very advanced pattern matchers. They have learned millions of patterns from training data. When they look at the code, they see hundreds or thousands of overlapping patterns. When you ask them to make or change something, they pull out a pattern (or ten) from their training and apply those patterns to the context of your program. You get something that looks just like the surrounding code, same style choices, same language, same comment voice, but it implements something new there, based on other patterns learned. If you've studied design patterns in your CS class, this will be familiar. But people can learn and remember maybe 20-30 patterns, while an LLM can have a million patterns and can combine them when needed. So it takes a pattern of Python code, pattern of standalone script, pattern of parsing command line parameters, pattern of classes, pattern for background threads, pattern for file tree traversing, pattern for pipes, ... and squishes them together to make a solution for your query. And then tries to debug it with compilation, tests and execution until it works as expected. Even if there is zero LLM development going forward, it will take many years to fully appreciate the benefits we can extract from the already trained models. They don't even have to be retrained - for existing languages they just keep working. For new language variations, like a new Python version, you can feed the changelog into context and they will be able to work with a Python version that they never saw in training. And patterns are mostly abstract, so not really specific to any language - human or programming. This is another big enabler that LLMs have created that we have not really explored yet. LLMs have created really free software. People can actually create software that is perfectly suited just for them and no one else. They don't even have to know how to program and don't even need to speak English. I've seen people writing prompts in their native language and LLMs creating and then adjusting web apps or Android/iPhone apps and deploying them to the user's own phone. It was too buggy to work last year, but this year it is actually very functional for simpler use-cases. And the code looks just fine too - I've seen external contractors in a business setting deliver far worse. If you start with a good initial system prompt, the project will have architecture documentation, use-case documentation, unit tests, integration tests, deployment harness, testing and production deployments, audit logs, monitoring, clear git commits, CI validation on commit, ... Modern AI systems have the capabilty to deliver software freedom to people who are not coders. I really can not overstate the consequences this may have on the world. Community - I find the concerns that new people will be using LLMs so much that they will no longer be understanding the actual code they are contributing a bit regressive. I don't see any significant difference between this and people relying on compilers, on high-level languages or on debhelper. Writing modern debhelper packaging feels more like writing configuration and not writing code. It takes really significant effort to dig down through layers of abstraction to find what actually is being executed in debian/rules. AI does not really make this worse. In fact, I find that AI can make it much easier to understand arcane syntax because you can ask an LLM to explain what is happening in any part of the code and it will do a pretty good job of it, digging down through the layers of abstraction for you. All the pro-AI proposals include the requirement that each human contributor needs to understand and stand behind their AI-assisted contribution and I believe that is a good requirement and also a sufficient requirement. Modern LLMs not only produce clear and concise code, but they are also capable of producing good comments explaining why the code is how it is, good commit messages explaining the change and reason behind it and also making corresponding changes to test suites and documentation. You know - the housekeeping stuff that is often skipped because it slows down the actual feature development, but then its lack becomes a problem for future contributors. Responsible use of AI assistance is a great chance to actually strengthen our community and make our software easier to maintain. That said, I have no qualms about flat-out rejecting contributions that do not make sense. And it does not matter if they are made with or without AI assistance. If the contributor will not explain their patch, it might be they do not understand what their AI produced or it could be that the contribution is deliberately hiding a backdoor being planted. It is also quite common for a contribution of a new feature to be rejected because the author/maintainer does not believe that it is a good fit for the project. Featuritis is a real disease. AI or not. There have always been drive-by contributions to various projects. They will continue to exist. Each of them should be evaluated on its merits - is this feature valuable to our users and is the added complexity (if any) worth the functionality? A lot of security bug reports are "drive-by" contributions as well. And many of them nowadays are discovered, exploited and patched with AI assistance. We could reject them, but that just leaves us holding the bag on the now-known exploits. And the New Maintainer process should be able to figure out if an upcoming Developer has actually understood the nuances of Debian packaging or not. A contributor with upload rights to the archive has to be able to create a basic package with no support tooling (maybe even without using debhelper?) and be able to understand and modify more complex packages (possibly with tooling support). IMHO that is a separate discussion that is worth having, involving experts from the educational sector. Conclusion IMHO the Debian project should not restrict what tooling individual contributors use to contribute. Expecting high-quality contributions and that contributors understand what they are contributing (as a first level of review) is enough. However, Debian should provide its contributors (internal or external) with guidance on how to contribute in the best way possible. That could include: In addition to that it would be helpful for Debian, as a project, to reach out to AI service providers to: Questions? Feedback? Just ask here or here.

Russell Coker: Links August 2026

This YouTube video about the Cashier Girl Meme is interesting in the context of AI systems that generate images of people and can communicate with people, hotter than any real human is an achievable goal [1]. Stand Up Maths has an interesting Youtube video about LLMs solving maths problems which I highly recommend watching (it does not require any real knowledge of maths), I think this opens the door to attacks on well established cryptologic systems [2]. Adam Conover made an insightful YouTube video about how and why Hollywood is now unable to make good sitcoms and why this is bad for society [3]. Sky Croeser wrote an interesting and insightful blog post about topics covered at the Digital and sexual citizenship in an age of social media bans: Interrogating the rights of children and young people conference [4]. Zane wrote a very informative blog post about reverse engineering a trojaned Android projector with Claude Code [5]. We need much better security on home networks to break the business model for this sort of thing. Renee Stonebraker s article Puritans Wouldn t Eat Pussy, So They Invented the Western has a lot of interesting information about early days of colonising the US, and not much about eating pussy [6]. IFLScience has an interesting article about brinicles, icicles of brine that form under sea ice [7]. Nautilus has an interesting article about the Silurian Hypothesis [8]. The Conversation has an intersting article about the pros and cons of no-till farming [9]. Cold War is a 365tomorrows story about bio-warfare which raises several disturbing possibilities we need to guard against [10]. Scott Santens wrote an insightful article describing how a land value tax would reduce rent and solve the housing shortages [11]. Positive News has an interesting article about using OnlyFans to teach people about climate change [12]. The Conversation has an interesting article about cultural safety in healthcare, sounds good, and while we are at it lets deal with sexism [13]. Doctoreww has an interesting web page about ways of displaying different strings to humans and machines, this could result in you running a different command to what you thought you copied from a web site or defeating tools designed to block hostile content [14]. Cory Doctorow wrote an insightful article Commentary Hell is Other People about the way rich people want to use AI to replace all people [15]. Also psychologists who help rich people accept being greedy are worthy of a Luigi The research article Worship me at the office altar: Why narcissistic leaders resist remote work is interesting, yet another reason to get rid of narcissistic executives [16]. Renew Economy has an interesting article about clean up costs for mining (which is usually left for the government to pay) and how this could impact renewable energy production facilities [17]. Elvira Bary wrote an insightful article on the Russian financial collapse that is happening now [18]. The Guardian has an interesting article about Afro-American women who travel to South Korea for healthcare because of problems with racism and sexism in American hospitals [19]. The Conversation has an interesting article about the potential for disabled people to be more productive in space than non-disabled people [20]. Krebs has an interesting article about LG banning residential proxy code from apps after the LG store was found to have such code in 42% of it s apps [21]. Robert B Shpiner wrote an insightful article for The Guardian about the death of democracy in the US [22].

Emmanuel Kasper: Create a development VM using Debian cloud images

Following on the rationale of the previous post, here is how I create a development VM based on ready to use disk images made by the debian cloud team. I could as well install the VM myself using an ISO, but why download a collection of packages in a ISO only to copy them right onto a disk image ? From the list of images available at https://cloud.debian.org/images/cloud/ we will start with the generic qcow2 disk image, it has cloud-init, which allows initial automatic configuration, and snapshots of the VM via the qcow2 disk format. As for the virtualization, I am using virsh virt-install and virt-manager, which are part of the libvirt framework. Libvirt offers an excellent API accessible over qemu/KVM via shell (virsh), GUI (virt-manager) and Web (cockpit) . To use libvirt, properly you need to make sure your standard user is member of the libvirt group, and the libvirt default network is started via virsh net-autostart default. Also make sure you set export LIBVIRT_DEFAULT_URI=qemu:///system to use the system wide instance of libvirt, which is needed for the default bridged networking. Download the debian cloud image:
$ wget https://cloud.debian.org/images/cloud/trixie/daily/latest/debian-13-generic-amd64-daily.qcow2
Add the disk image as a libvirt volume:
$ export SIZE=$(stat -Lc%s debian-13-generic-amd64-daily.qcow2)
$ virsh vol-create-as default dev-vm $SIZE --format qcow2
$ virsh vol-upload --pool default dev-vm debian-13-generic-amd64-daily.qcow2
Create a VM with the root password set to root :
$ echo root > password.txt
$ virt-install --name dev-vm --memory 4096 --noreboot \
	--os-variant detect=on,name=linux2024 \
	--disk vol=default/dev-vm \
	--import \
	--boot uefi \
	--cloud-init root-password-file=password.txt,clouduser-ssh-key=$HOME/.ssh/.ssh/id_ed25519,disable=on
At the point libvirt will create a VM (a domain in libvirt parlance) and start it.
Starting install...
Allocating 'virtinst-ns9oa7_i-cloudinit.iso'                  368 kB  00:00     
Transferring 'virtinst-ns9oa7_i-cloudinit.iso'                368 kB  00:00     
Creating domain...                                                    00:00     
Connected to domain 'dev-vm'
BdsDxe: starting Boot0001 "UEFI Misc Device" from PciRoot(0x0)/Pci(0x2,0x3)/Pci(0x0,0x0)
Booting  Debian GNU/Linux'
Loading Linux 6.12.101+deb13-amd64 ...
Loading initial ramdisk ...
EFI stub: Loaded initrd from LINUX_EFI_INITRD_MEDIA_GUID device path
EFI stub: UEFI Secure Boot is enabled.
[    0.000000] Linux version 6.12.101+deb13-amd64 (debian-kernel@lists.debian.org) (x86_64-linux-gnu-gcc-14 (Debian 14.2.0-19) 14.2.0, GNU ld (GNU Binutils for Debian) 2.44) #1 SMP PREEMPT_DYNAMIC Debian 6.12.101-1 (2026-08-05)
[    0.000000] Command line: BOOT_IMAGE=/boot/vmlinuz-6.12.101+deb13-amd64 root=PARTUUID=2b4578e2-9d2e-4b32-b6a4-b5b2ca607ef6 ro console=tty0 console=ttyS0,115200 earlyprintk=ttyS0,115200 consoleblank=0
...
Once the VM is created you have now three ways to access it:
# open a serial console to the VM
$ virsh console dev-vm
# access the graphical console
$ virt-manager
# Access the VM via SSH with the precreated cloud user "debian"
$ virsh domifaddr dev-vm
 Name       MAC address          Protocol     Address
-------------------------------------------------------------------------------
 vnet7      52:54:00:23:e6:61    ipv4         192.168.122.225/24
$ ssh debian@192.168.122.225
In the next blog post we will see how to configure the IDE (vscodium) to run confortably in the VM.

19 August 2026

Sergio Cipriano: My experience at DebConf 2026 in Santa F

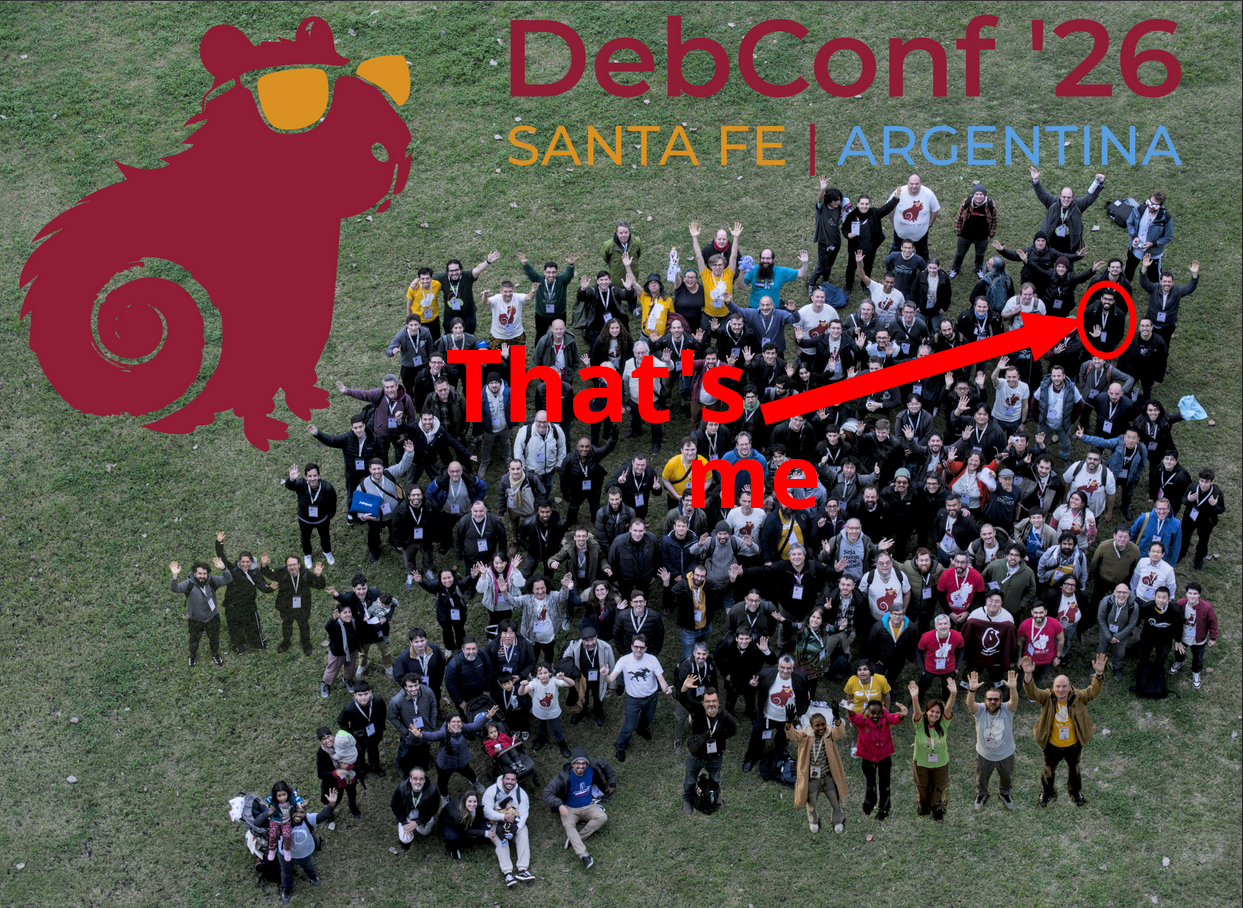
My experience at DebConf 2026 in Santa F The Official DebConf26 Group Photo Last month, I attended DebConf 2026 in Santa F , which was my 5th DebConf. As always, it was an amazing experience, and I met a lot of great people there. For those unfamiliar with the event, it takes place over the course of two weeks. The first week is called DebCamp and is geared more towards hacking and organizing the event itself, while also offering a great opportunity to discuss ideas with others. The second week is the DebConf. We still have the hacklabs, but the talks and workshops are the main focus.

My Activities during DebCamp My main activity was working on the python-click transition that I started in May. There were only a few packages left, and with the help of Guilherme Puida, we managed to work through all the remaining bugs. I plan to talk in details about this transition in another blog post, where I will focus on the tools I used and my experience with mass rebuilds and mass bug filing. I also helped with de Golang Sprint. I worked on a few packages and experimented with the dak API to generate a list of packages that needed manual action. There was a lot of manual, repetitive work and false positives, so I eventually moved on to some other, more fun stuff. I also learned a few thinks about kernel live patching while talking to David Tadokoro. I had to work on the Ubuntu Kernel package recently as part of my job, so we exchanged some ideas, and the conversation was really helpful. He also taught me two commands that I wasn't familiar with, since I'm a newbie in kernel development. Here are the commands:
$ b4 am https://lore.kernel.org/lkml/20240730071904.1047-1-sergiosacj@riseup.net/
$ b4 diff *mbox
By the way, this is the first and only patch I have submitted to the Linux Kernel. I worked on it during DebConf 2024, when I attended the workshop Helen Koike runs to help newcomers submit their first patch to the Linux Kernel. Another great interaction was with Marcos Talau. He showed me his remote access setup, which he is using to help students make contributions to Debian without the struggle of setting up the development environment. Another cool thing is that Puida showed me the command:
$ gbp clone vcs-git:typer
After that, I decided to read the gbp manpage because these little details really improve the overall experience. I also had many other amazing interactions. I just decided to write down the ones that I felt made the most sense for this kind of "blog report" post.

My Activities during DebConf I gave a talk about dh-make-vim, a tool I have been working on sporadically. An interesting detail is that one of the video team volunteers for the talk, Piotr, spoke to me about his tool, pypi2deb, which is similar but aimed at the Python ecosystem. There are many tools of this kind in Debian, and they are all interesting pieces of software. I plan to write more about them in the future. I attended several talks and participated in a few BoF sessions, and they were all great. But something that really stood out to me was the workshop on the Debian Installer, led by Alper Nebi Yasak. I didn't know anything about the Debian Installer, and I liked the way he approached the subject and showed the specific details. I'll take some time to read the Debian Installer internals documentation. I was not familiar with udebs or with the fact that the Debian Installer uses debconf under the hood.

Wrap up It was an amazing event. Unfortunatly, a lot of people I know were not able to attend for different reasons, and they were missed. There were many other things that I enjoyed during this trip. Here are a few more highlights:
  • World Cup matches
  • A day trip around Santa F
  • The Cheese & Wine party
  • Empanadas!!

Antoine Beaupr : The people vs the AI overlords

Also in this series:
In a post to oss-security, my (Debian) co-developer Russ Allbery stated that "open source software [OSS] is coming face to face with a motivation crisis that has been building for a long time". His point is essentially that large language models (LLMs1) are making the existing OSS community crisis worse. For him, it's the flood of code reviews, but he argues that varies according to people's desires, for others it's security issues and so on. I think Russ is right, but I would argue there's something much bigger than our open communities going on here, and it's about the entire field of computing. This pressure is on all of us, regardless of whether we work on open source software or not.

How people use models People using LLMs in their workflow have radically changed how programming works, even for people who claim to avoid vibe-coding. And I'm sorry to single out one poor maintainer here: it's not you, Brian, you're just one example among many. But this is typical use of those models nowadays:
Once it s done, I ll use /code-review and let Claude spawn sub-agents to do a full review of the new code. This usually finds some problems, even problems that the main Claude instance didn t find during its validation. I usually keep running /code-review again and again after finding and fixing issues, until there aren t any left.
Think about what that means for a minute. This is automation built to fire up dozens of agents crunching at a problem for minutes if not hours of GPU compute time, in parallel. This is essentially a couple of shelves in a datacenter rack, totally maxed out on power and cooling, abstracted behind a cute little /code-review command. The author, here, is rightly concerned that "Anthropic could pull the rug out and require API pricing", which is perhaps a code word for "charging something closer to actual costs". Brian also pays lip service to environmental and societal costs but those are largely abstracted away, so let's keep that conversation aside here as well, as we have discussed it before anyways. But clearly, this way of working has an (externalized) cost, to say the least.

Paying for non-free tools For decades my work has been focused on free and open source software. I've long stopped using proprietary operating systems like Windows or Mac, and even before that switch, I was mostly using free software on those platforms, partly out of principle, but also because I was too poor. So the tools of my trade are free, and I build free tools with them. It feels like we're going backwards: when I was in school, a millennia ago, my classmates didn't have access to a compiler and were wondering how they would scrape the money to buy a compiler like Borland's or Microsoft's. I had a compiler built into my operating system (FreeBSD at the time), so that wasn't a problem for me. For them, it was a significant expense, but at least those expenses (or more shady sourcing of programs) were a one-shot deal. Fast forward 30 years, and software is rented: you pay monthly for Adobe's Photoshop and Microsoft's office suite just like you pay for Netflix, Disney+ or Spotify2. And now you need to add dozens (if not hundreds of dollars) of monthly credits to access LLMs on top of that. So, now we have to pay to get anything done? This is peak enshitification of our job: first they steal our work to train their models, and then they sell it back to us at a profit.

Attacking the engineers AI is coming for our jobs, as engineers, if not everyone, according to the narrative. For a while now, our job market has deteriorated: less jobs, for less pay. Lots of skilled engineers looking for work and finding crap jobs then still looking while working. This is not by accident.3 We engineers have a lot of power, it is not organized, but that's just a couple of unions away (easy!). Tech overlords know this, so they are attacking our profession, directly, by forcing us to train and use models that they can control. Even in environments where programmers are not forced to use LLMs, the mere pressure of other people's LLM-generated work is huge. One can be forced to review LLM outputs, or just peer pressured you into producing more. We're now supposed to accelerate delivery, because models can presumably do things so much better and faster. With supply chain security becoming such a large vector that we now have worms crawling around developers accounts on NPM, increasing the delivery cadence seems like a really bad idea.4 The LLM hype is part of the larger wave of cyberwar against workers, against water, against the Earth, against all the people. This is not a matter of individually "adapting to the reality" or personal choice, but a political, social, hard problem we need to address collectively.

  1. I again prefer the term LLM to "AI" because models do not possess intelligence. I did use it in the title because click baiting is apparently important, but I stopped short of calling this one "Rage Against the Machines" because that would be the title of every blog post I have ever made.
  2. Yes, I know that Visual Studio is kind of free now, but I wouldn't be surprised if they turn that into a rental as well, because why not.
  3. Beyond sabotaging the job market, Sam Altman event wants to sell "intelligence as a utility" something that is just a really bad idea but especially shows how megalomaniac those people are.
  4. This brings back memories of another era, walking us back decades in terms of computer security.

18 August 2026

Andy Simpkins: My first go at tracking down a kernel bug

A couple of weekends back, I upgraded my home sever. It failed to restart after running apt dist-upgrade The only update that was performed was to the kernel, it went from 6.12.88+deb13-amd64 to 6.12.100+deb13-amd64. I had previously performed an apt-get upgrade, and rebooted the machine, so I was pretty sure that this was to blame. This blog entry (is a late) attempt to document how I went about finding a fix for this issue so that next time I don t need as much hand holding as I did this time around :-) (1)
Having my machine not boot following an upgrade is pretty rare, but has happened before. Usually it is because I have done something wrong so as always confirming I haven t broken something by accident is always my first step I plugged in a keyboard an monitor to the machine and watched it boot. Being a server this takes a long time (I guess because at this stage of system initialisation we want to test things sequentially) Watching the system boot I see the usual BIOS/UEFI stages for this machine, followed by the grub menu and the the local screen showed:
            Loading Linux 6.12.100+deb13-amd64 ...
            Loading initial ramdisk ...
Nothing else. That was it. OK that looks like I have a broken system all right, and at very early stage of the boot process process. (2)
Breaking into the grub menu and removing the quiet option yields a little more information (but not much):
            Loading Linux 6.12.100+deb13-amd64  
            Loading initial ramdisk ...
            
            	EFI stub: Loaded initrd from LINUX_EFI_INITRD_MEDIA_GUID d
            	evice path
            		EFI stub: Measured initrd data into PCR 9
and nothing else. (3) Initial debugging (4) Triage Start looking for where the fault first occurred. At this point I needed help, and given that Sledge was visiting I asked if he would sanity check what I was doing. His initial thoughts were that that /boot had run out of space, but replaying my step (3) with him acting as a rubber duck showed that this was something other than PBKAC Sledge had a quick look, then informed me that between kernel images 6.12.88+deb13 and 6.12.100+deb13 Debian stable has only had shipped .90 .94 .95 and .96 kernels. We could easily try them all: OK I now have the first kernel image that doesn t boot on my system, time to raise a bug

Up until now I have been walking to my garage where the server is located and standing in front of a rack
with a monitor and keyboard plugged into the machine. However this machine supports IPMI so I spent a little time getting that up and running so that I can continue from the relative comfort of my desk (with lights, a chair and not needing to hold the keyboard with one hand)
Great I can now grab screen shots from the confort of my desk (unfortunatly they are only screen shots not text files, but at least we can seen the early stage of boot, Post, grub menu and then initramfs before system log happens) (5) Collating information for the initial bug report Sledge had mentioned my problem in irc/#debain-kernal where iam_tj suggested that we try appending
debug earlycon=efifb to the kernal command line. This yielded 15 seconds worth of messages before the system locked up the last few messages being (vmlinuz-6.12.96+deb13-amd64):

[ 14.663477] RCU Tasks: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.750474] RCU Tasks Rude: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.838024] RCU Tasks Trace: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
[ 14.929752] NR_IRQS: 524544, nr_irqs: 584, preallocated irqs: 16
[ 15.016814] rcu: srcu_init: Setting srcu_struct sizes based on contention.
[ 15.104011] Console: colour dummy device 80 25
[ 15.191236] printk: legacy console [tty0] enabled
[ 15.278249] printk: legacy bootconsole [efifb0] disabled Booting the working kernel with the same kernel options yields the SAME messages with slightly differing times, but then continues to login prompt:

 [   14.697466] RCU Tasks: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.784936] RCU Tasks Rude: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.872067] RCU Tasks Trace: Setting shift to 5 and lim to 1 rcu_task_cb_adjust=1 rcu_task_cpu_ids=20.
 [   14.964000] NR_IRQS: 524544, nr_irqs: 584, preallocated irqs: 16
 [   15.051482] rcu: srcu_init: Setting srcu_struct sizes based on contention.
 [   15.226079] printk: legacy console [tty0] enabled
 [   15.313751] printk: legacy bootconsole [efifb0] disabled
 [   15.400831] ACPI: Core revision 20240827
 [   15.401415] clocksource: hpet: mask: 0xffffffff max_cycles: 0xffffffff, max_idle_ns: 79635855245 ns
 [   15.401464] APIC: Switch to symmetric I/O mode setup
 
... and so on
iam_tj also suggested adding keep_bootcon with debug earlycon=efifb keep_bootcon on vmlinuz-6.12.96+deb13-amd64:
We get a LOT further and we see a crash / trace-back:
[ 34.285342] BUG: kernel NULL pointer dereference, address: 0000000000000000
I raised bug #1143721 and followed it up with screen captures of the boot sequence (captured from the IPMI client) and files containing the output of dmidecode, lscpu and lspci to kive the kernel team as much information as possible:
[6.12.96+deb13-amd64 debug earlycon=efifb keep_bootcon.tar.gz (application/gzip, attachment)]
[dmidecode.txt (text/plain, attachment)]
[lscpu.txt (text/plain, attachment)]
[lspci.txt (text/plain, attachment)]
(6) Tracking down the bug Git Bisect The problem with this type of bug is that it is hardware (class) specific, whilst the kernel doesn t boot on my system, it clearly has worked on machines used by the kernel team, the Debian test and build infrastructure, (otherwise this kernel would never have been released) and everyone else who has upgraded to the newer kernel before I did (otherwise we would be drowning in fails to boot bug reports). Carnil s excellent response to my bug: Message #15 (and help in IRC) provided me with a detailed step by step guide in how to track down the individual git commit that fails on my system. I had already (with Sledge s suggestion) made a clone of the stable branch, but was struggling to follow the steps in the Debian Linux Kernel Handbook to re-build a duplicate kernel because I didn t understand how to obtain the same configuration that Debian used to build the kernel; Carnil s email provided me the missing steps (Highlighted).
git clone --single-branch -b linux-6.12.y https://git.kernel.org/pub/scm/linux/kernel/git/stable/linux-stable.git
cd linux-stable
git checkout v6.12.95
cp /boot/config-$(uname -r) .config
yes ''   make localmodconfig
make savedefconfig
mv defconfig arch/x86/configs/my_def
test 6.12.96 to ensure this is "bad"
git checkout v6.12.96
make my_defconfig
make -j $(nproc) bindeb-pkg
  install the resulting .deb package and confirm it fails to boot and triggers the NULL pointer dereference.
Right I can now start to Bisect the problem:
git bisect start
git bisect good v6.12.95
git bisect bad v6.12.96
Rather than use the half step point s git bisect suggested I was advised in irc to jump straight to the a given commit that from the git log was suspected as the culprit:

git checkout 977855894bca4b87afa50d21e3f3e85a5a0e901f
build and install .
fails
git bisect bad

git checkout 977855894bca4b87afa50d21e3f3e85a5a0e901f~1 ## ~1 is the commit beforehand
build and install .
fails
git bisect good The entire test tree can shown with git bisect log and this was submitted as an email to the bug report, we have found our smoking gun :-) Finally I would like to thank Carnil, Iam_tj for their time patience and fantastic support in guiding me through finding this regression. Right now kernel bugs are coming in thick and fast with a lot of AI assisted bug hunting, the increased numbers of bugs mean that the kernel team are especially busy. Hopefully our paths will cross and I ll be able to buy you some beers (or whatever) soon. thank you. Sledge also deserves thanks for putting up with me and pointing me in the right direction (as ever). Lucky for me that he lives nearby so I can provide beers on a regular basis :-)

John Goerzen: AI in Debian: The Vote, Proposals, and Nuance

Let me start with a hypothesis:
For human developers, using coding LLMs magnifies their difference in skill levels.
I am one that rarely thinks things are always black and white. Back in March, I wrote Artifial Intelligence: Shades of Gray. Since then, I ve had more of a chance to experiment with LLMs myself. I also happen to work for an employer that is taking a very pragmatic approach to LLMs: teams and individuals use it as they see fit, but if they are causing considerable expense, they have to justify it. In various settings, I have seen the egregious examples of AI slop we all know about. As I wrote in March, I have seen it both waste more time than it saves, and save a ton of time. I have come to see that, as a tool, it is most valuable when it is running under the supervision of an experienced engineer. It is at its worst when it has no such supervision; the vibe coding and other low-quality slop we see. A coding agent is like a junior developer or research assistant. When properly supervised, they help projects move along more quickly by letting a senior developer focus on the more difficult, less mundane aspects of the project. But one couldn t expect a junior developer to consistently deliver high-quality code and architecture on their own. Let s put a pin in this idea and look at the story in Debian. LLM use in Debian There is a vote happening in Debian around the use of LLMs. In typical Debian fashion, there are 8 options to choose from, many of them similar. Most of these proposals acknowledge there are different types of tasks done in Debian, but the proposals don t differentiate between them well. Let me do so here. These are some of the LLM-relevant tasks people in Debian perform: I m going to focus my remarks here on packaging upstream software for Debian, since this is by far the most time-consuming developer task project-wide. It matters to our users that we get this right, and packaging quality is one of the things that sets Debian apart from other distros. Packaging things for Debian requires knowledge of some specific tools, such as debhelper, that aren t widely used anywhere else. In most cases, it is fairly rote time-consuming work. In other words, by its design, it requires people with senior-level skills to do grunt work. I can t overstate how massive a burden this grunt work is. I maintain some packages for Go and Rust. By Debian policy, all of those packages dependencies must also exist as Debian packages, and be used to build against. When upstream adopts a newer version of some library, it can unleash cascading dependencies that can take hours to sort out. Worse, the Rust team and the Go team use entirely different ways of managing packages (Go uses one Git repo per package, while Rust has a monorepo with specialized scripts to import Cargo packages and generate Debian ones). On top of that, we can t just modify things like usual; we have to use quilt. And on top of that, I m also a backports maintainer, so all the work (and usually even more) has to be done there also. Now let s pull on that pin from the earlier conversation. This is exactly the kind of scenario that a well-supervised coding LLM is most effective in. I could see a seasoned developer saving hours, maybe even days, by turning over the mundane tasks of managing trees of cascading dependencies over to a coding tool and verifying and directing the process. (Yes, I have been using em-dashes for years; LLMs have copied people like me, not the other way around! This post was not written with any AI assistance.) Actually, this is almost a dream scenario for a coding assistant. The result is time-consuming to formulate but easy to review, which is the opposite of the way these things often go. I can assure you with 100% certainty that humans aren t adding a lot of value in this process. It would be wrong to believe that a human is carefully reading every line of code in dozens of updated or new library packages. The problem set is too big, the time too short, and the code too varied and complex. Coding agents seem to be most effective when there are strong test suites that they can test changes against. Debian builds, especially of modern packages, tend to have this property. Many packages have test suites that are run during build. And, if the package builds in an isolated environment (and especially if its downstream dependencies do also), then there is a decent chance that it s fairly correct. Maybe needing some manual tweaking here and there, but generally a successful build is a reasonable indicator. You can argue that it would make more sense for Debian to just include dependencies in source packages, along with some version information to support security rebuilds, and I d tend to agree with you. But we are where we are. This would be one of the more significant leaps forward in developer productivity, but it complicates things like copyright reviews. Where are LLMs run? What is the environmental impact? Most of the proposals seem to make the assumption that LLMs must always run in some large, hosted datacenter. As I noted in my March article, I have had credible results on even an older GPU running on solar power. That said, it is undeniable that LLMs are fueling a datacenter boom, and this in turn is producing a significant new demand for resources. Most notably for the global scale: electricity, which is sometimes generated using carbon-emitting technologies. Bill McKibben, who has been a leading voice in the fight against climate change since the 1980s, has made some interesting points recently: he s noted that solar power is the fastest kind of generation we can build, and a number of large AI companies are investing heavily in solar, even to the point of fully offsetting new datacenter s needs. On the other hand, he s also noted that some companies are buying inefficient and dirty gas turbines. It is decidedly a mixed bag. The heavy investment in solar can have knock-on positive effects for infrastructure. Obviously, not every picture here is rosy. This analysis doesn t touch on the real land and water use situation, either. On the other hand, if an LLM allows me to do in an hour what I would have done in a day, that s a day of not heating or cooling the work area generally not sustaining a human for the purpose of writing code for Debian. HVAC energy consumption dwarfs my GPU, and I d imagine probably also the slice of LLM energy used. Holistically, I would have to conclude the picture is mixed. It is possible to use LLMs in a pretty green way, and also in a pretty dirty way. Assuming Conditions Never Change A flaw in most of these proposals is they assume that the conditions at this present moment will always hold. In fact, that the conditions at the present moment will not continue is something both AI cheerleaders and AI skeptics agree on. For instance: Ed Zitron has done a ton of research into the financing side of AI, and has concluded that the current model is unsustainable and headed for a significant bubble burst. I m not positioned to personally evaluate those claims, but if that happens, what is the result? Perhaps it is a steeply increasing cost of inference for the frontier models, slower pace of training/evolution for them, etc. In a recent episode of Oxide and Friends, Simon Willison discussed the open weight models that are now available. They have been making remarkable strides in efficiency and capabilities, to the point where $50,000 of hardware can now run high-end open weight models with capabilities that are at least in the same ballpark as the American frontier models. This puts running high-end models locally squarely within reach of universities and small- to medium-sized businesses, with power requirements that can be met with standard commercial solar and wind installations. The lack of nuance in the more restrictive proposals is particularly concerning. Proposal A doesn t allow the use or assitance of LLMs . So it bans my solar-powered GPU. It bans using LLMs to find security issues. It bans all sorts of things that don t seem to be ban-worthy, alongside the things that do. And it codifies it in the very hard-to-change social contract. That proposal, and some like it, seem to imply that all LLM output is bad. I grant you that AI slop is a real and legitimate concern, and many Open Source projects have to deal with it. On the other hand, we have all seen first-hand how the security of the Linux kernel has benefited dramatically from AI analysis. It is certain that black hats are using these tools. If we refuse to use modern security tools, our security will be compromised (and what is the environmental and social impact of THAT?) I find the statement Generative AI is characterized by producing output of a nature that would ordinarily be produced and consumed by humans to be particularly interesting. The same was once said of compilers. The Real Concerns You might think from reading this that I am some AI cheerleader. I m not. I share the ethics of the FLOSS movement, and have for decades. I abhor the power and lack of ethics that many big names in the field are running with at the moment. I ve had to put up Anubis on this blog, for instance. I have personally experienced the effects of AI slop, especially at review time. This is a real problem, though I don t think the more draconian policies are likely to help (the looser you must disclose stand a fighting chance, but I m not sure they would help, either.) Done poorly, AI threatens developer burnout by overwhelming them with poor code and verbose but useless explanations. Done well, AI can help prevent developer burnout by automating tedious and low-value tasks. Shouldn t our goal be that humans submit work to Debian, using tools they prefer, and take responsibility for it? Does it matter if someone uses ed, vim, emacs, or vscode? If they use LSP or just run gcc manually? I d say we benefit from the diversity. Wouldn t we be better off to benefit from the diversity here, and judge work as we always have: on its merits, not what tools were used to create it? Fundamentally, a GR is a long and arduous process. It s not easy to reverse later. Amending the Social Contract is even longer and more arduous (I should know; I may have been the first one to try). The LLM landscape is fast-moving. None of us can really predict where it will be in a year. Will the current market leading companies even still exist? Will it be at all credible to refuse to use AI-assisted security tools? What is the most effective way to deal with AI slop? What level of utility will we be able to achieve with models run locally? Some of these proposals would make sense if drafted in some way short of a GR, which would allow more maneuverability as the landscape changes. Brief analysis of the options Considering the proposals: In favor of nuance I find that black-and-white thinking is almost always something to be avoided. I see it too often. I see it in politics, I see it in our software, I see it in discussions around AI. Are there deeply unethical things happening in AI? Absolutely. Are they doing some impressive things? Also yes. We have accepted this nuance in other areas. For instance, almost all the hardware Debian runs on has closed-source hardware, and has components manufactured or assembled in countries with some of the worst human rights records on the planet. I m not saying this is a great state of affairs. It is something we should speak up about and act upon. But the worse state of affairs would be no Debian because the hardware is impure .

16 August 2026

Bits from Debian: Debian turns 33!

It has now been thirty-three years since the Debian project was announced to the world by Ian Murdock, on August 16, 1993. This anniversary is an opportunity to reaffirm the goals, characteristics, and qualities of the Debian project: it s an association of individuals who have made common cause to create a free operating system. Our distribution is characterized by a commitment to software freedom, as enshrined in the Debian Social Contract and the Debian Free Software Guidelines. It focuses on security and stability. This stability is crucial to Debian position in the free software ecosystem. With our users as our priority, Debian makes special efforts regarding accessibility with Debian-Accessibility and diversity with our Outreach Programs. Debian Day is a great opportunity to get together, whether for a local meetup, or simply to grab a coffee with other members of the Debian community. Check out the Debian Day wiki to see if there is a celebration near you. And if there isn't, maybe you can organize it next year! Today is also an opportunity for you to start or resume your contributions to Debian. For example, you can install the how-can-i-help package and see if there is a bug in any of the software that you use that you can help to fix, contribute small tips on how to install Debian on your machines to our wiki pages, or put a Debian live image in an USB memory and give it to some person near you, who still didn't discover Debian. Thanks to everybody who has contributed to develop our beloved operating system in these 33 years, and Happy birthday Debian!

Vasudev Kamath: Releasing debvulns-exporter and debvulns CLI 0.2.2

I made another minor release with several enhancements: handling non-Debian origin vulnerabilities, improving data caching, and sharing the cache between the debvulns CLI and the exporter. Additionally, there are a few improvements on the dashboard front. Here is a breakdown of what changed.
Handling Vulnerabilities in Non-Debian Origin Packages During the previous release, I noticed that the grafana package which is not in Debian and was installed via an upstream repository was reported as vulnerable with multiple issues. Looking into why this happened, I found that all the CVEs reported in the dashboard were indeed listed on security-tracker.debian.org, but without a fixed version or status description. The logic assumed no fix was available and marked the package as vulnerable on the dashboard.
How Did I Solve This? Google maintains a distributed vulnerability database for open-source projects called osv.dev. I checked the generic vulnerability data for those CVEs on OSV (unbound to any specific distribution) and found that the issues were already fixed in the upstream version I was running. What I needed was a way to differentiate native Debian packages from non-Debian packages, which corresponds to the Origin field in APT metadata.
Pitfall The AI-generated code initially attempted to differentiate package origin using apt_pkg.PackageRecords and its origin field. However, many native Debian packages were incorrectly flagged as non-Debian. On closer inspection, when an upgrade is available for a package, the installed version's origin field can be unset. I had to resolve this by detecting available upgrades and inspecting the candidate version's origin instead, which was implemented in this patch. This solution was proudly crafted by me ;-) (partly because I ran out of API limits and had to wait 6 hours for the next reset).
Caching OSV Data Initially, the AI implemented the exporter to re-download the entire OSV dataset on every run, which was unnecessary. Since vulnerability data does not change rapidly once published, caching it on disk for longer than the standard 24-hour Debian/EPSS cache makes sense. OSV vulnerability data is now cached for 7 days before a refresh is triggered. All cache expiration thresholds remain configurable via CLI flags.
Catch One caveat with this approach: I have not yet verified whether every upstream CVE is tracked on security-tracker.debian.org. In the case of grafana, the entries existed. This feature operates on the assumption that security-tracker.debian.org indexes CVE metadata regardless of whether the package is native to Debian. I plan to re-evaluate this and add fallback handling if that assumption fails.
Unified Cache Directory for CLI and Exporter Another issue was cache segregation: the debvulns CLI utility defaulted to /var/cache/debvulns, while the Prometheus exporter used /var/cache/debvulns-exporter. While harmless when running only one tool, installing both led to duplicated cache storage and redundant network requests. Since the core evaluation logic is identical across both tools, they now share a unified cache directory to eliminate duplicate downloads.
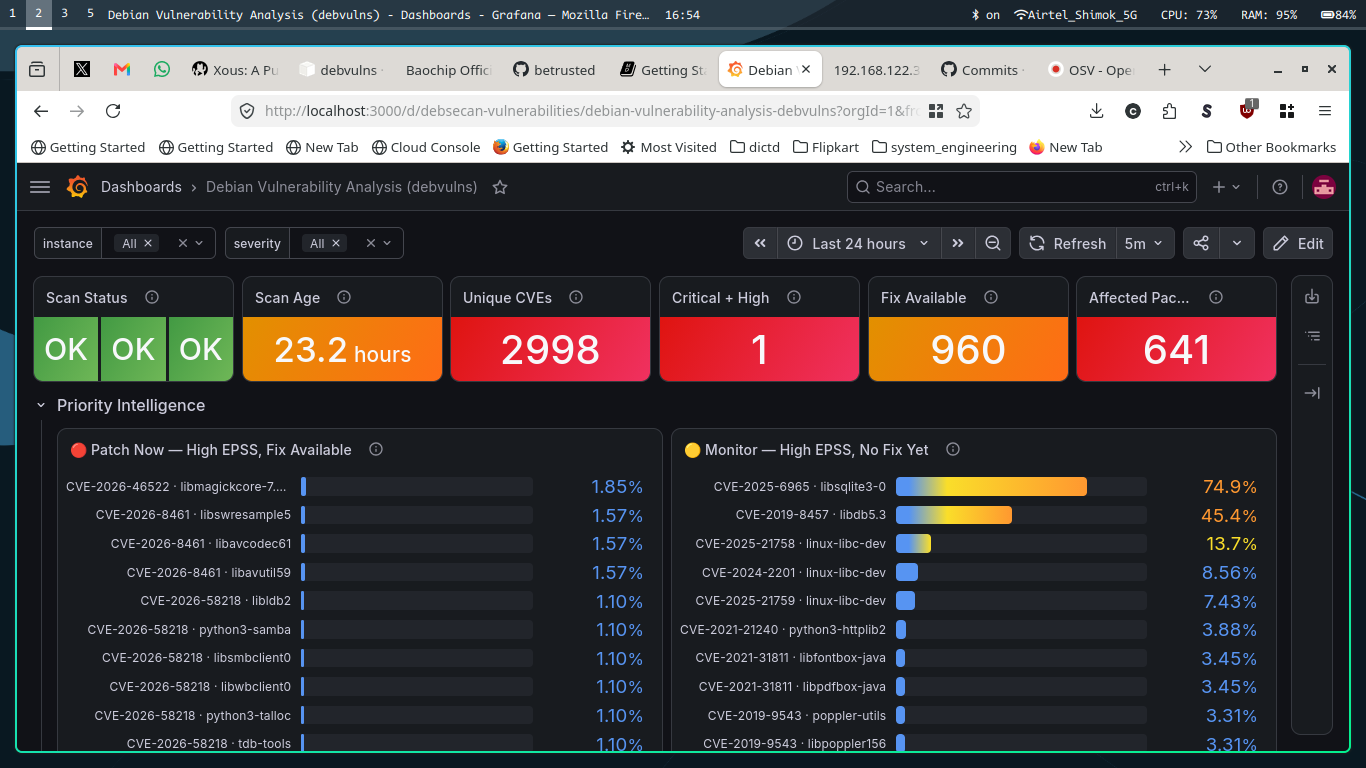
Dashboard Changes During the initial dashboard rollout, my test environment (my laptop alongside Debian 11 and Debian 12 VMs) reported a high aggregated vulnerability count. It was not immediately obvious whether these were distinct vulnerabilities or the same CVEs replicated across all three machines. This mirrors common questions raised during vulnerability reviews:
  • How many unique vulnerabilities are present across the fleet?
  • Which unique packages are affected?
The dashboard has been redesigned to surface unique vulnerability counts alongside affected package lists. The updated dashboard is shown below:
What's Next? A few planned items remain to make debvulns a comprehensive vulnerability reporting toolkit for Debian systems:
  1. Kernel Vulnerability Handling: Currently, installing a patched kernel marks the vulnerability as resolved, even if the system has not rebooted into it. The system remains exposed while the vulnerable kernel is executing in memory. Factoring in running kernel versions is crucial.
  2. Reboot and Service Restart Tracking: Similar to kernel upgrades requiring a reboot, userland library and binary fixes require running services to be restarted. This is typically detected via needrestart. Integrating this behavior directly into debvulns will provide complete visibility in a single dashboard metric.
  3. Debian Packaging: Once the above features are stable, the final step is packaging debvulns for Debian so it can be installed directly from the archive.
Until then, happy hacking.

13 August 2026

Gunnar Wolf: File recovery in process...

Ohai, I have some pending, encrypted mails to answer. And some of my answers for the next few days (particularly to what pertains to the current in-discussion vote on LLM usage in Debian) will be unsigned, even though I d like otherwise. My desktop system at work is showing some data corruption, and I m slowly backing up my data. Fortunately, it seems I haven t lost any data, but still, given I m letting rsync run until it starts spewing I/O errors, then power down and let the machine cool a bit, and start again it is a potentially long process. And yes, this makes me somewhat angry. Why angry? Because I m working on a brand-new computer (well, have used it for slightly over six months), custom-built to specs requested by my workplace. Specs that I don t really need, this machine is an utter luxury (i.e. an AMD Ryzen 9 9950X processor with 16 real cores / 32 threads; 128GB RAM in this day and age of RAM shortage, quite recent 32GB GPU, and lots of shiny lights seen in its huge fishbowl cabinet, liquid-based cooling ). The specs came not from me, but from people who had no idea what we would use them for. And yes, I expect the little fortune spent on this machine to be good for my use for probably a decade, as my previous computer was, but the amount paid was exorbitant. But still, what I learned recently is that the 4TB nVME SSD it has (a T-Force TM8FFJX34T) is a very cheap brand, bought because it was close to half the price of other offerings similar in capacity. According to smartctl s output, th SSD operates with a Warning Comp. Temp. Threshold: 90 Celsius and Critical Comp. Temp. Threshold: 110 Celsius, which sounds sensible, even too high for my standards (my last two laptops have been fanless yes, an ARM system is very different from a high-end gaming machine). I m right now typing from my laptop, which shows 78 C and 82 C for warning/critical thresholds. And as expected, under heavy sustained reads (backing up to my NFS server), the desktop s smartctl shows Temperature: 83 Celsius and, further down, Temperature Sensor 1: 107 Celsius and Temperature Sensor 2: 82 Celsius (don t know which of these would make the threshold jump). The SSD has sustained Media and Data Integrity Errors: 20 and Warning Comp. Temperature Time: 21 (although Critical Comp. Temperature Time: 0). At least one of my colleagues have shrugged and installed a SATA SSD, laying the huge nVME basically to waste. Anyway I also learned I am not the first, but the fourth person to notice this kind of issues in this system (out of ten similar purchased systems AIUI). It is completely unacceptable, and I ll be pushing our Institute s authorities to demand the provider to provide either good component quality for this very expensive system that has many luxury items, or to fix the system s build in a way the nVME does not heat as much as it currently does. Anyway, sigh, I only wanted to say, please excuse me for not using my cryptographic keys for a couple of days PS- I m also currently not connected to IRC and Jabber (and some similar technologies), as my bouncer runs from my usual workstation.

11 August 2026

Colin Watson: Free software activity in July 2026

About 95% of my Debian contributions this month were sponsored by Freexian. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH Now that Ubuntu 26.04 LTS has been released, I ve been getting back to the GSS-API key exchange package split in our OpenSSH packaging. Once I started testing my draft openssh-gssapi source package, I realized that I needed to make some changes in the main openssh source package first in order to support it. The dependency from openssh-server to openssh-client was awkward, as was the (related) fact that openssh-client contained shared documentation for other OpenSSH binary packages. After some thought, I created a new openssh-common binary package, moved shared documentation and the ssh-keygen program to that, and dropped dependencies on openssh-client which were no longer necessary (fixing #699473 and #1070098 in the process). This caused a couple of regressions (#1141420 and #1141550) that I had to fix, and more subtly it also caused a number of autopkgtest regressions in other packages because openssh-client is no longer in base images as a result of a dependency from openssh-server. I believe I have fixes for all of these either pending review or merged (one of which I did in August rather than July): I upgraded from 10.3p1 to 10.4p1, and in the process contributed a GSS-API option handling fix upstream. I made openssh-ssh1 s package description more accurately describe the package, thanks to suggestions from Matthias Lang. Installer team With support from a Freexian customer, I reviewed, tested, edited, and merged a patch to add VLAN support. I described the details of what I did in a comment. This has been vaguely on my to-do list since, er, about 2014, so it was very satisfying to get it sorted out. Python packaging New upstream versions: Other build/test failures: I fixed some other bugs: I adopted transaction for the Python team. I attended the Python BoF at DebConf remotely, although a badly-timed fibre outage in the village I live in really didn t help. Code reviews Other bits and pieces Dan Poltawski pointed out in a Fediverse post that the project history didn t list Sruthi as the current DPL. I fixed that, although it doesn t look as though the fix is in the published version yet. I upgraded yubihsm-shell to 2.8.0.
Freexian Collaborators: Debian Contributions: DebConf 26 organization, d-i VLAN support and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-07 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf 26 organization, by Lucas Kanashiro, Santiago Ruano Rinc n, Stefano Rivera and Antonio Terceiro The 27th Annual Debian Conference was held in Santa Fe, Argentina, and several Freexian fellows were quite busy by being involved in the organization team.
  • Santiago continued helping with duties related to the local team, e.g. preparing or proof-reading some announcements, reviewing the proposed food and the menus for the different diet required.
  • During the conference, Kanashiro and Santiago also carried over tasks related to the content of the conference, including updating the schedule as it became necessary during the event.
  • Stefano worked within the core video team, setting up equipment in talk rooms and coordinating the live video streaming. Stefano also supported the front desk and local organisers as a website developer and conference book-keeper.
  • Antonio kept working on website maintenance, specially in support of the content team. During DebConf he also ran a hands-on workshop to help interested contributors get started with developing the DebConf websites.

d-i VLAN support, by Colin Watson In environments that use IEEE 802.1Q VLANs, some hosts (such as routers attached to trunk ports) may need to apply VLAN tags themselves rather than relying on switches to do so. There has been a long-running request to add support for these to the Debian installer with a proposed patch set put together by several people over the years, and a Freexian customer asked us to help get this over the line. Colin reviewed the latest version of the patch set, applied a number of corrections, added Netplan support, spent some time testing a variety of possible paths through the installer, and landed this. There s also now documentation for this in the next version of the installation guide.

Miscellaneous contributions
  • Carles wrote documentation for installing Mailman3 and migrating from Mailman2. Added it into Mailman3 upstream documentation.
  • Carles, using po-debconf-manager: reviewed 2 packages, submitted 2 packages
  • Carles organized Catalan translation update. Created a Debian Wiki page to have an overview of the work / coordination during next months. Reviewed and submitted some pages.
  • Carles improved the documentation for building the debian.org Web in MR 1154 and MR 1557. Fixed debian-reference documentation. Added sections on Mutt Wiki page (handling of mailto, viewing HTML parts web browser), update and improve bash-completion Wiki page. Added a troubleshooting section in Signal Wiki.
  • Thorsten did another upload of hplip to fix RC bugs. He also spent some time taking care of older bugs. Most of the time such bugs had been fixed in a previous upload but haven t been closed in the BTS. He also uploaded a new upstream version of foomatic-db. Last but not least, he gave some user support with the package epson-inkjet-printer-escpr. There seems to be a new software available for Epson printers. Unfortunately the license is not compatible with DFSG and so this software will never make it into Debian.
  • During DebCamp 26, the Golang team had a dedicated Sprint to transition the Golang toolchain (namely on dh-golang) to make builds aware of the module defined upstream with the aim of solving important issues. To help in these efforts, Santiago made changes in the Salsa CI pipeline and documented on how to use it to check if a package requires adjustments after the toolchain update.
  • Santiago continued co-mentoring Aryan Karamtoth on the Linux livepatching project, specifically providing feedback about the implementation of dlp-tools.
  • Stefano reviewed and merged a migration of Debian reimbursements from wkhtmltopdf to weasyprint, unblocking an upgrade to Debian trixie.
  • Stefano s cPython upstream merge request adding multiarch tags to stable ABI extensions was finally merged.
  • Stefano iterated on his upstream cPython merge request to add CI coverage for Debian s multi-arch expectations.
  • Stefano uploaded Python 3.15.0 beta 4 to Debian experimental.
  • Stefano uploaded Python 3.13 to trixie, fixing a regression in a previous trixie point update he made.
  • Helmut continued to report undeclared file conflicts.
  • Helmut sent patches for three cross build failures.
  • Helmut proposed a MR to port piuparts to pathlib.
  • Antonio has done quite some work on Debian CI, including rebuilding the Debian CI armhf/armel worker VMs, and releasing debci 4.2, implementing a backup scheme, and several improvements to the codebase such as improving the incus-lxc backend in preparation for switching to the upcoming switch to using it by default as announced in the latest bits from the ci.debian.net operators.
  • Emilio helped with transitions, particularly with Python 3.14 as default and Perl 5.42. During the Perl transition, an issue was identified with how britney schedules autopkgtests for binNMUs, and that testing was reverted for the time being.
  • Colin restructured openssh-* binary packages to better support the upcoming GSS-API package split. This caused several autopkgtest regressions in other packages because openssh-server no longer depends on openssh-client, all of which have fixes either pending review or merged now.
  • Lucas started a discussion around the creation of a Debian packaging video course for newcomers in the context of the Outreach team.
  • Lucas reviewed some contributions to ruby3.4 and provided feedback.
  • Anupa worked with Jean-Pierre Giraud on the point release announcements for Debian 13.6 and Debian 12.15.
  • Anupa joined Jean-Pierre Giraud to prepare the Micronews for DebConf 26 press coverage.

9 August 2026

Elana Hashman: Managing virtualenvs with a little bash

When you need to install something directly from PyPI, Python virtualenvs have been my go-to for over a decade. A quick virtualenv intro Most of my readers are probably already familiar with virtualenvs, but for completeness, I'll give you a brief introduction. A virtualenv (short for "virtual environment") is an isolated distribution of Python packages, where you can independently install packages without disturbing your system packages or other virtualenvs. You can set one up like this, assuming you are using Python 3.3 or higher:
python3 -m venv ~/.venv/my-virtualenv
The directory specified here is just a convention. I keep all my virtualenvs in the .venv folder in my home directory, but you can pick whatever location you like. To use the virtualenv, you must activate it:
source ~/.venv/my-virtualenv/bin/activate
This activation script is a special shell script that configures your current shell, pointing at all the right paths in order to use the virtual environment. source runs this script in your current shell session to set it up. You will notice that this adds (my-virtualenv) to the beginning of your shell prompt, reminding you that the "my-virtualenv" virtualenv is active. Now when you pip install amazing-package, the software will only be available in this virtual environment. When you're done, you can deactivate it like so:
deactivate
Wonderful! Managing many virtualenvs gets annoying Over time, I end up accumulating many virtualenvs, which can become harder to manage. Maybe something like this:
$ ls ~/.venv/
my-virtualenv cool-project snakes-ahoy
I also don't want to type source ~/.venv/my-virtualenv/bin/activate every time I use the virtualenv, because it gets very repetitive only the name of the venv is really needed. But luckily, we can write a little bit of bash to make managing this less annoying. (Or you can use one of many Python developer tools that are designed to manage this, like pipx, but when I merely want to consume Python software, I might not have a development environment set up. So that's beyond the scope of this post!) If you add the following shell function to your ~/.bashrc or ~/.bash_aliases file, it will nicely wrap our activation command:
setup-venv()  
        source "$HOME/.venv/$1/bin/activate"
 
Now all we need to run is
setup-venv my-virtualenv
So much quicker! Spicing it up with tab completion The first thing I noticed after writing this wrapper was that I started hitting tab on the virtual environment name, but... nothing happened. Wouldn't it be nice to know what virtualenvs I had available, and to not have to type out the whole long thing? Well, we can write it ourselves If for some reason you don't already have bash completion installed, on a Debian-based system, you will need to install it with
apt install bash-completion
In order to configure our bash completion, we will create a new file, /etc/bash_completion.d/venv, with the following contents:
_list_venvs()
 
    local cur prev opts
    COMPREPLY=()
    cur="$ COMP_WORDS[COMP_CWORD] "
    prev="$ COMP_WORDS[COMP_CWORD-1] "
    opts=$(find $HOME/.venv/ -mindepth 1 -maxdepth 1 -type d -printf "%f ")
    COMPREPLY=( $(compgen -W "$ opts " -- $ cur ) )
    return 0
 
complete -F _list_venvs setup-venv
This file defines another shell function order to determine how to autocomplete the options for our setup-venv function. $opts is where we define the options for our function. We generate it with a find command looking at the .venv folder in the current user's home directory, then only including child folders (excluding the current directory itself, .venv, in our results) by using the min/max depth and type arguments, and printing just the individual directory names, deliminated by spaces using our print formatter. Everything else is the standard scaffolding required to use bash completions. Once you save this file and reload your shell, you'll see that you are able to use completions as expected!
setup-venv <tab>
my-virtualenv cool-project snakes-ahoy
setup-venv s<tab>
setup-venv snakes-ahoy
Complaints, comments, questions? Hope this was helpful! If it wasn't, that's too bad. But don't worry you can safely ignore this post.

Reproducible Builds: Reproducible Builds in July 2026

Welcome to the July 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. If you are interested in contributing to the project, please visit the Contribute page on our website. In this month s report, we cover:

  1. Tool development
  2. Distribution work
  3. Three new scholarly papers
  4. Patches
  5. Misc news

Tool development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 324, 325 and 326 to Debian:
  • Fix tests to work with zipdetails 4.0008. (#1141359)
  • Bump debhelper compatibility level to 13. [ ]
  • Update copyright years. [ ]
In addition, Paul Spooren made changes to allow trailing garbage in Gzip files [ ] and Vagrant Cascadian added an external tool reference for the pedump binary to use the mono package under GNU Guix. [ ]
disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues. This month, Christelle Gloor added the option to sort by ctime as returned by the lstat(2) syscall. [ ], which Chris Lamb uploaded whilst bumping the Standards-Version to version 4.7.4 [ ]. Bernhard Wiedemann also updated disorderfs to version 0.7.0 in openSUSE.
Yet again, there were a number of improvements made to our website this month as well. For example, Chris Lamb, by request of Digital Ocean, changed the target of a referral link so that they can manage incoming referrers [ ] and pushed a number of changes to the Tools page [ ].

Distribution work In Debian this month, 32 reviews of Debian packages were added, 26 were updated and a total of 21 were removed this month, adding to our extensive knowledge about identified issues. A number of issue types were added by Chris Lamb, including:
  • python_towncrier_build_date [ ][ ]
  • log_files_installed_in_package [ ]
  • fontforge_varies_by_timezone [ ][ ]
Chris also added a further note for the build_date_in_manpage_generated_by_spf13_cobra issue. [ ]
In addition, there is a new page showing verification rebuilds of OpenWrt APK packages and firmware images, powered by rebuilderd:

Three new scholarly papers Yan Li, Nan Jiang, Qihang Zhou, Shaowen Xu, Yamin Xie and Xiaoqi Jia of the Chinese Academy of Sciences published a paper titled VCAligner: Aligning Source Distribution Versions with Upstream Git Commits to Secure Supply Chain:
We present VCAligner, a content-based alignment methodology that constructs inverted indexes over VCS histories to precisely map released artifacts to their originating commits, independent of fragile version tags. We evaluated VCAligner on a dataset of 2,984 verifiable PyPI packages derived from the 4,000 most-downloaded projects linked to public GitHub upstreams. Our results reveal a critical weakness in conventional tag-based heuristics: while they appear effective on 85% of the dataset, the residual 15% failure rate generates a catastrophic downstream audit workload of over 10.3 million commits. In contrast, VCAligner reduces this burden by two orders of magnitude ( 158 ), bounding the total workload to under 65,000 commits. Furthermore, we provide the large-scale characterization of Packaging Noise, classifying artifact divergence into structural additions (Path Phantoms) and content mutations (Blob Phantoms), thereby isolating the distinct attack surfaces of malicious injection and code tampering.

Jens Dietrich and Spencer Sun from the Victoria University of Wellington together with Tim W. White and Behnaz Hassanshahi from Oracle Inc pre-published their paper No Snake Oil: Verifying Python Package Builds (PDF):
Python has become the default language for interacting with AI, with packages being distributed through registries like the Python Package Index (PyPI). This creates a need to analyse supply chains comprising such packages. One such analysis is to rebuild packages in order to identify compromised builds injecting malware. Independent rebuilds in hardened environments have the added advantage that they can generate and record provenance in order to increase the trustworthiness of packages. Two tools that are designed to automate such rebuilds and run them at scale are macaron and oss-rebuild. We study 12,180 popular releases from PyPI and find that the byte-for-byte equivalence rate is generally low. We analyse the reasons why they produce different wheels, and find that equivalence between the original and rebuilt wheels can often still be established, preserving most of the guarantees users expect from rebuildable releases. We present and evaluate daleq4py, a tool to establish the equivalence of Python wheels through the kernel of a normalisation function that is based on provenance-preserving datalog rules. Experimental results show that daleq4py substantially expands the set of rebuilds that can be accepted as equivalent. Although only 15.4% of macaron rebuilds and 19.1% of oss-rebuild rebuilds are byte-for-byte identical to the published PyPI wheels, daleq4py establishes wheel equivalence for 60.2% and 78.9% of source-equivalent rebuilds, respectively.

Denise Nanni, Julien Malka, Stefano Zacchiroli and Th o Zimmermann from T l com Paris together with Gabriele D Angelo from the University of Bologna pre-published their paper Understanding Build Reproducibility in the F-Droid Ecosystem (PDF), which was accepted at the 2026 ACM Conference on Reproducibility and Replicability:
The security of open source applications benefits considerably from the possibility of rebuilding their source and verifying the output. F-Droid, a prominent distribution for open source Android applications, systematically rebuilds them from source and tests their bitwise reproducibility at app publishing time. However, F-Droid offers no guarantee that app reproducibility will continue to hold in the future. As software ecosystems evolve, reproducibility may degrade, with potential negative consequences for software preservation and security. We present the first empirical study of build reproducibility in the F-Droid app ecosystem. Analyzing historical reproducibility logs, we find that the overall bitwise reproducibility rate has been steadily increasing over time (as new versions of apps are published). We then evaluate how reproducibility holds in time for fixed app versions, by attempting to rebuild 18 904 app versions that F-Droid had previously confirmed bitwise reproducible, published between September 2018 and February 2026, achieving an 83% rebuild success rate, and identify missing dependencies as the dominant cause of failure, accounting for 76% of non-rebuildable cases. Among successfully rebuilt apps, 94% are also bitwise reproducible-i.e., they still yield bitwise identical artifacts upon rebuild. Together, these results show that while bitwise reproducibility largely holds for apps that can be rebuilt, rebuildability itself is highly sensitive to temporal decay.

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Misc news On our mailing list this month, Colin Winter of Markovian Protocol wrote to our mailing list on the topic of Reproducible verification for retained logs:
Reproducible builds remove trust in the builder: anyone re-derives the same artifact from the same source, byte for byte. The same shape applies one layer over, to a retained record. Most record-keeping regimes (the EU AI Act s Article 12 logging is the current example) require that events be recorded and logs retained, but not that a retained log be verifiable, by a party who was not present, as unaltered and existing when claimed. That leaves an integrity obligation resting on trusting the party being audited.
(Full thread)

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

7 August 2026

Thorsten Alteholz: My Debian Activities in July 2026

Debian LTS/ELTS This was my hundred-forty-fifth month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on: Unfortunately the number of assigned hours was rather low this month. So besides doing some days of FD at the end of the month, where I also had to process a new package list for ELTS, and a review of the rsync package (prepared by Sylvain), not much happened here. Debian Printing This month I uploaded a new upstream versions: Besides the package upload, I also took care of some older bugs of hplip. This work is generously funded by Freexian! Debian Lomiri This month I continued the upload of lomiri packages with new upstream versions. Thanks to the help of my other colleagues, this project could be finished now. This work is generously funded by Fre(i)e Software GmbH! Debian Astro This month I uploaded a new upstream version or a bugfix version of: Debian IoT Unfortunately I had no time to work in this category this month. Debian Mobcom This month I uploaded a new upstream version or a bugfix version of: Next month I intend to upload new upstream versions of all Osmocom packages. As far as I can tell, these uploads will happen without soname changes. I like that :-). misc This month I uploaded a new upstream version or a bugfix version of:

6 August 2026

Bits from Debian: DebConf26 closes in Santa Fe and DebConf27 announced

DebConf26 group photo - click to enlarge On Saturday 25 July 2026, the annual Debian Developers and Contributors Conference came to a close. Over 270 attendees representing 35 countries from around the world came together for a combined 90 events (including some which took place during the DebCamp) including more than 27 Talks, 21 Short Talks, 29 Birds of a Feather sessions ("BoF" informal meeting between developers and users), 8 workshops, and activities in support of furthering our distribution and free software, learning from our mentors and peers, building our community, and having a bit of fun. The conference was preceded by the annual DebCamp hacking session held 13 through 19 July where Debian Developers and Contributors convened to focus on their individual Debian-related projects or work in team sprints geared toward in-person collaboration in developing Debian. As has been the case for several years, a special effort has been made to welcome newcomers and help them become familiar with Debian and DebConf by organizing a sprint "New Contributors Onboarding" every day of Debcamp, followed more informally by mentorship during DebConf. Half a dozen new contributors joined the sessions and learned about Debian, free software, packaging and much more. This year, a week-long DebCamp session was dedicated to auditing, patching, and modernizing the Go ecosystem in Debian and enable the transition triggered by the recent upload of dh-golang enabling GO111MODULE=on by default in Experimental. In order to make the conference more accessible for local participants, a local language track was included in the schedule for talks in Spanish, as was done at DebConf19 in Brazil. The actual Debian Developers Conference started on Monday 20 July 2026. In addition to the traditional "Bits from the DPL" talk, the continuous key-signing party, lightning talks, and the announcement of next year's DebConf27, there were several update sessions shared by internal projects and teams. Many of the hosted discussion sessions were presented by our technical core teams with the usual and useful "Meet the Technical Committee", three talks about Linux Kernel, early boot and improving Debian s kernel and installer support for Chromebooks, and about twenty BoFs and talks about Debian packaging policy, Debian infrastructure, security and privacy. This year, and echoing ongoing discussions within the Free Software community, Artificial Intelligence and Age Verification have been the subject of several talks. The Python, Perl, Ruby, Go, and Rust programming language teams also shared updates on their work and efforts. More than 17 BoFs and talks about community, diversity, and local outreach highlighted the work of various teams involved in not just the technical but also the social aspect of our community The schedule was updated each day with planned and ad hoc activities introduced by attendees over the course of the conference. Several traditional activities took place: a poetry performance, the traditional Cheese and Wine party, the Group Photos, and the Day Trip. For those who were not able to attend, most of the talks and sessions were broadcasted live and recorded. One can find the seventy hours of recorded videos available via the conference schedule, or alternatively through this link. Almost all of the sessions facilitated remote participation via IRC and Matrix messaging apps or online collaborative text documents which allowed remote attendees to "be in the room" and ask questions or share comments with the speaker or assembled audience. DebConf26 saw over 341 T-shirts, a day trip, and up to 130 meals planned per day. All of these events, activities, conversations, and streams coupled with our love, interest, and participation in Debian and F/OSS certainly made this conference an overall success both here in Santa Fe, Argentina and online around the world. The DebConf26 website will remain active for archival purposes and will continue to offer links to the presentations and videos of talks and events. Next year, DebConf27 will be held in Asahikawa, Hokkaido, Japan, from Sunday September 5th to Saturday September 11th, 2027. As tradition follows before the next DebConf the local organizers in Japan will start the conference activities with DebCamp with a particular focus on individual and team work towards improving the distribution. DebConf is committed to a safe and welcome environment for all participants. See the web page about the Code of Conduct on the DebConf26 website for more details on this. Debian thanks the commitment of numerous sponsors to support DebConf26, particularly our Platinum Sponsors: Infomaniak, and Proxmox, and our Gold Sponsors : Freexian, and Viridien. We also wish to thank our Video and Infrastructure teams, the DebConf26 and DebConf committees, our host nation of Argentina, and each and every person who helped contribute to this event and to Debian overall. Thank you all for your work in helping Debian continue to be "The Universal Operating System". See you next year! About Debian The Debian Project was founded in 1993 by Ian Murdock to be a truly free community project. Since then the project has grown to be one of the largest and most influential Open Source projects. Thousands of volunteers from all over the world work together to create and maintain Debian software. Available in 70 languages, and supporting a huge range of computer types, Debian calls itself the universal operating system. About DebConf DebConf is the Debian Project's developer conference. In addition to a full schedule of technical, social and policy talks, DebConf provides an opportunity for developers, contributors and other interested people to meet in person and work together more closely. It has taken place annually since 2000 in locations as varied as Scotland, Bosnia and Herzegovina, India, Korea, France. More information about DebConf is available from https://debconf.org/. About Infomaniak Infomaniak is an independent, employee-owned Swiss technology company that designs, develops, and operates its own cloud infrastructure and digital services entirely in Switzerland. With over 300 employees more than 70% engineers and developers the company reinvests all profits into R&D. Its public cloud is built on OpenStack, with managed Kubernetes, Database as a Service, object storage, and sovereign AI services accessible via OpenAI-compatible APIs, all running on its own Swiss infrastructure. Infomaniak also develops a sovereign collaborative suite messaging, email, storage, online office tools, videoconferencing, and a built-in AI assistant developed in-house and as a privacy-respecting solution to proprietary platforms. Open source is central to how Infomaniak operates. Its latest data center (D4) runs on 100% renewable energy and uses no traditional cooling: all the heat generated by its servers is captured and fed into Geneva's district heating network, supplying up to 6,000 homes in winter and hot water year-round. The entire project has been documented and open-sourced at d4project.org. About Proxmox Proxmox develops powerful, yet easy-to-use open-source server solutions. The comprehensive open-source ecosystem is designed to manage divers IT landscapes, from single servers to large-scale distributed data centers. Our unified platform integrates server virtualization, easy backup, and rock-solid email security ensuring seamless interoperability across the entire portfolio. With the Proxmox Datacenter Manager, the ecosystem also offers a "single pane of glass" for centralized management across different locations. Since 2005, all Proxmox solutions have been built on the rock-solid Debian platform. We are proud to return to DebConf26 as a sponsor because the Debian community provides the foundation that makes our work possible. We believe in keeping IT simple, open, and under your control. Contact Information For further information, please visit the DebConf26 web page at https://debconf26.debconf.org/ or send mail to press@debian.org.

Next.

Previous.