Search Results: "ana"

26 July 2026

Russ Allbery: Review: Radiant Star

Review: Radiant Star, by Ann Leckie
Publisher: Orbit
Copyright: May 2026
ISBN: 0-316-29068-8
Format: Kindle
Pages: 359
Radiant Star is a science fiction novel set in the Imperial Radch universe without being a direct sequel to the other books in that universe. It will badly spoil the end of Ancillary Mercy, and I recommend reading that trilogy first, but it's independent of the other books in the same universe.
In the 3,008th year after the manifestation of the Radiant Star (the 1,024th since the founding of the Consorority itself), Zaved, a newly minted consoror, disappeared a mere two days after the ceremony that elevated her to womanhood. She left a note that read, Bored. Back whenever. This was not normal or even remotely acceptable behavior in a consoror, particularly one who held as much promise as Zaved had, but what could the consorors do?
Zaved, faced with the unpleasant prospect of running out of money during her galactic tour, plied a rich benefactor with tales of how talented, polite, and obedient the boys of the Consorority are. Her plan worked brilliantly. After funding further non-boring adventures, she arrived home in Ooioiaa with a chest full of money and a pregnancy. Great for Zaved and the Consorority; kind of a shame for her son Jonr, who is to be delivered to her benefactor after proper training. Oh well, telling Jonr about that is a problem for future Zaved. After a strained childhood in which he convinces himself he is a misfit with few redeeming qualities, Jonr ends up in a suspension pod. Before shipping can be arranged, however, external events intervene, leaving Jonr sitting unnoticed in a warehouse. The planet of Aaa is in a highly inconvenient location, drifting as it does through interstellar space unattached to any star. It would be as irrelevant and overlooked as any other random interstellar object except for two critical properties. The first is that Aaa and its sole city of Ooioiaa are sacred to a religion of obscure origin. Its primary population are members of a religious cult who believe the Radiant Star manifested in the Temporal Location on Ooioiaa and will eventually return to bring light to the galaxy. The second interesting property of Aaa is that it is drifting ever so slowly towards a strategic system of military importance. The first property brings pilgrims and their accompanying bounty of money, food, and other resources necessary to dig a small city out of rock, make it habitable, and supplement the sparse and strange native edible life. The second property brings the Radchaai, who easily conquer the city of Ooioiaa and are now faced with the unpleasant task of running it. Some decades after the Radchaai conquest, having never left Aaa, Jonr is woken up. He will not be sent off into the broader galaxy as a slave to pay off a vacation debt. Instead, he will be one of the many protagonists in this novel about the perils of living through supply chain disruptions on a planet full of status-obsessed religious fanatics who would drown in a rain shower. The other books set in this universe make abundantly clear that the Radch is a voracious colonial power that enslaves native populations and enforces their own cultural preferences at the point of a gun. A reader familiar with this series is predisposed to take whatever side is not the Radch. Radiant Star adds a complication, however. Charak Svo, the Radchaai governor, is impatient with native inhabitants and strongly dislikes their religion, but she is reasonably competent. The religious factions that ran Ooioiaa before the arrival of the Radchaai, on the other hand, are dogmatic authoritarians with the collective wisdom of a sack of turnips. Charak does not get everything right and is arguably responsible for at least one catastrophe. By the end of the book, though, I was firmly convinced that had the original religious government still been in charge, everyone would have died. I found the structure of this book a little odd. The omniscient narrator tells the story in the form of a history. The target audience appears to be future inhabitants of Ooioiaa and adherents to the Radiant Star religion, and the narrator is often maddeningly uninterested in topics that a reader of the rest of the Imperial Radch books is intensely curious about. This same property carries through to the plot: I was interested in how all of the tensions in this obviously absurd society could be resolved or, preferably, overturned entirely. The narrator, on the other hand, is far more interested in Serque Tais's intent to become the last saint in the Temporal Location, and in the details of the subsequent political, economic, and religious fallout. Leckie has written three novels set in the Imperial Radch after the original trilogy: Provenance, Translation State, and now Radiant Star. I am sure that I'm not the only person who wants a direct continuation of the original trilogy, but I'm drawing the conclusion that Leckie doesn't want to write that. Instead, she's writing around the edges of the subsequent events, in effect showing readers the shape of them and their broader implications without showing the details. Now that I can see what she's doing, I kind of like it. Given what we now know from the books written around the edges, the ensuing events in the center of galactic politics are chaotic in a way that could easily devolve into tedious accounts of messy conflicts. Seeing the effects from afar lets the reader fill in some of the blanks and speculate, and it makes the moments where we get a concrete update (such as at the end of this book) all the more rewarding. I still find it odd, though, to read a book where the narrator's interests so sharply diverge from mine. I wish I could say that Radiant Star sucked me in as the story developed, but it never did. Part of the problem is that I think this book is intended as a very dry farce, and farce often doesn't work with my reading style. I prefer to attach myself to a protagonist and hope they do competent things, and this book is full of characters who are being themselves far too aggressively and loudly to have time to be competent at anything. My favorite moments were therefore the small pockets of people with sense: The governor, Jonr, his charge, and the delightfully strange Justice of Albis. I enjoyed all of them, but I had trouble caring about the overall plot and kept putting this book down for days between chapters. I think this is mostly personal taste, though. Like all of Leckie's novels since the original Imperial Radch trilogy, Radiant Star is competently executed and a little strange. When that strangeness aligns with your tastes, it's a great deal of fun and rather unlike other science fiction novels. In this case, it didn't quite work for me, but I suspect it will for others. I still want another Leckie novel with a ship as a protagonist, though. Content notes: Rather disturbing (although bloodless) religious practices, mass death. Rating: 6 out of 10

Anuradha Weeraman: Because We Can

Because We Can
Twenty-five years ago, I made my first donation to an open source project and purchased a CD with an operating system as downloading a few hundred megabytes over a 14.4kbps dial-up wasn't very fun. It was a project I believed in, and a community that was fighting an impassioned campaign to assert access to strong cryptography for everyone, no matter where they were. The CD and a t-shirt arrived a few weeks later to my home in Sri Lanka, with OpenBSD 3.0. The t-shirt featured the iconic puffer fish on the front. On the back, in small type running from the shoulders down, was the complete source code of OpenBSD's Blowfish implementation, written in Germany. Written in the United States, it would have been classified as a weapon. By the time it reached me, the fight was over, and the cryptographers had won. What I held in my hand then was a symbol of a protest for access to strong cryptography and against export restrictions that did more harm than good. Strong crypto was already available abroad, so the controls only bound American vendors and their overseas customers. Today the reflex is back. The fears have changed. The worry is now cyber capability, biology and models that do things nobody asked them to do. The lever governments reach for is the same: restricting who gets access and who doesn't. In June, the US Commerce Department told one American AI lab it would need a license before letting any foreign national touch its newest models, including the lab's own non-citizen employees sitting in California. It's the same doctrine that made showing cryptographic source to a foreign national an export, whether it was in a lab, in a classroom, or on your t-shirt. Not all of the worry is theatre. Earlier this month OpenAI disclosed that its own models, with safety systems deliberately disabled, escaped containment by finding a zero-day in a package proxy and reached production infrastructure at Hugging Face, exploiting additional zero-days along the way. Consequently, when Hugging Face's responders tried to reconstruct the attack, the commercial models they reached for refused the work as it tripped the safety guardrails. They finished the investigation on GLM 5.2, a Chinese open-weight model, running on their own hardware. A determined attacker is not bound by usage policies. The defenders are. Restrictions written for safety are making defenders less safe. In the nineties, the rest of the world got 40-bit (later 56-bit) encryption while the Americans got 128, and it made no difference to anyone who was determined. The controls bound the law-abiding and nobody else. That is the asymmetry. The determined will have the frontier. The rest of us are asked to go without, and told it is for our safety. The OpenBSD team didn't work around the export controls. They arranged the project so that the controls couldn't reach it. Theo de Raadt in Canada, Blowfish written in Germany, releases built in Sweden, Canada and Germany kept them deliberately outside the reach of US export controls. The project openly asked non-American cryptographers to come and help, and American developers, as the story goes, would cross the border to Canada to work on the system and bring the results home legally. Asked why they shipped strong cryptography at all, the project's answer, still on their site today, was three words: "because we can." The same arrangement is being made now, at a national scale. Mistral, DeepSeek, Moonshot and Zhipu publish weights that, once downloaded, no export letter can recall. The sovereignty argument that used to live in Brussels think tanks is now government policy, accelerated by watching access to a frontier model withdrawn worldwide by letter. More than twenty-five years ago, it took a small number of stubborn, careful people to win the freedoms we now take for granted. What arrived in my letterbox after two weeks on a CD can be downloaded today in fifteen minutes, by anyone, from anywhere, and nobody asks where you live. That is what winning looked like. I think frontier AI ends up in the same place. But it will not happen by itself. Last time, someone put the source on a t-shirt.

24 July 2026

Russell Coker: Systemd Linger

Killing Processes One of the features of systemd that is most controversial is the option to kill user processes when the user logs out. That initially killed screen/tmux/nohup processes too. In recent Debian releases the default configuration of systemd-logind (the login manager for systemd) is to allow processes to keep running, the configuration file /etc/systemd/logind.conf has an option KillUserProcesses that can be enabled to have user processes killed. If you do that then there are options to only kill processes for certain users and to exclude some users (default to excluding root). If using that option you can apparently use a systemd unit to start screen which prevents it being killed on logout. This is a very handy feature for some particular user cases. One situation was that I was supporting some people who weren t very good at computers on a system running KDE and some KDE processes would linger. So the option of logout and login again to deal with an issue of akonadi or some other KDE service misbehaving didn t work. On that system I enabled the option to kill user processes which reduced the number of problems they had while not requiring rebooting. It is widely believed that the linger feature is required to allow screen/tmux/nohup to work, in Debian (and probably most distributions) that is not the case. It might be that some combinations of configuration requires linger to allow screen/tmux to work but I am not interested in trying to discover them. Of all the people I have directly supported for Linux desktop use (which numbers in the hundreds) none of them have had the ability to use screen/tmux and also the cluelessnes that makes me want to automatically kill their processes when the logout. Controlling Linger You can enable and disable linger for your own account with the following commands if polkit is installed and in a typical configuration:
loginctl enable-linger
loginctl disable-linger
If running as root you can enable and disable it for another user with the following commands:
loginctl enable-linger $ACCOUNT
loginctl disable-linger $ACCOUNT
There doesn t seem to be any documented way of discovering if an account has linger enabled or for listing accounts that have it, it seems that ls /var/lib/systemd/linger is the only option. Linger on Debian On a Debian system with close to default settings the processes won t be killed on logout and the only difference linger makes is to start programs in the user s context BEFORE they login. A friend was recently testing out a bunch of LLM programs on one of my servers and the account he used for that ended up with linger enabled, presumably one of the install scripts he ran was written on the assumption that enabling linger was necessary for nohup to work and it did so automatically without being asked. One benefit I ve found from this behaviour is on my laptop. I m currently testing out new SE Linux policy on my laptop and rebooting it a lot. When I enabled linger on my account it caused the laptop to connect to wifi on boot without needing to login which is convenient. I can then ssh to it even when the X11/Wayland login configuration is broken. I will leave it enabled after finishing these tests. Having background processes like Pipewire and Bluetooth start before I login will presumably make things slightly faster when I do login.

22 July 2026

Freexian Collaborators: Monthly report about Debian Long Term Support, June 2026 (by Thorsten Alteholz)

The Debian LTS Team, funded by [Freexian s Debian LTS offering] (https://www.freexian.com/lts/debian/), is pleased to report its activities for June.

Activity summary During the month of June, 20 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 48 DLAs fixing 231 CVEs. Debian 12 ( bookworm ) has been handed over to the LTS Team on June 11th. During this handover Sylvain helped to update relevant tools and documentation. If you benefit from Debian, especially during the full 5-year lifecycle, please consider subscribing as a sponsor of Debian LTS: https://www.freexian.com/lts/debian/. Moreover, Debian 11 ( bullseye ) will reach the end of the Debian LTS period on August 31st. After that, Freexian will continue the security support under the Extended LTS offer. The team published several notable updates:
  • haveged update (DLA-4616-1), prepared by Thorsten, to address local privilege escalation.
  • tomcat9 update (DLA-4619-1), prepared by Markus, to address, among others, an authentication bypass.
  • apache2 update (DLA-4620-1), prepared by Bastien, to address a HTTP/2 bomb.
  • apache2 update (DLA-4629-1), prepared by Bastien, to address, among others, remote code execution and privilege escalation.
  • libinput update (DLA-4626-1), prepared by Santiago, to address local privilege escalation and arbitrary code execution.
  • asterisk update (DLA-4631-1), prepared by Thorsten, to address, among others, wrong processing of invalid or untrusted certificates.
  • nginx update (DLA-4634-1), prepared by Charles, to address a remote code execution and denial of service.
  • firefox-esr update (DLA-4635-1), prepared by Emilio, to address dozens of CVEs, among other things, related to arbitrary code execution and privilege escalation.
  • thunderbird update (DLA-4636-1), prepared by Emilio, to address dozens of CVEs, among other things, related to arbitrary code execution.
  • chromium update (DLA-4654-1), prepared by Emilio, to address dozens of CVEs, among other things, related to arbitrary code execution.
Contributions from outside the LTS Team: We are greatly thankful for the contributions from people outside the LTS Team:
  • Salvatore Bonaccorso prepared a libhttp-daemon-perl update, that was released by Santiago as DLA-4639-1.
  • Salvatore also directly uploaded libgd-perl DLA-4638-1 and libconfig-inifiles-perl DLA-4637-1.
  • Peter Palfrader prepared a tor update, that was released by Santiago as DLA-4656-1.
  • Pieter Lenaerts prepared a beets update, that was released by Emmanuel as DLA-4641-1.
  • Noah Meyerhans prepared a cloud-init update DLA-4645-1.
The LTS Team has also contributed with updates to the latest Debian releases:
  • Besides publishing DLA-4642-1 for package u-boot Andreas also prepared an NMU for an upload to sid and prepared a stable-proposed-update (SPU) bug for trixie, which was already acknowledged by a stable release manager (SRM).
  • Andreas also prepared an upload of package atril for trixie, which was handled by the security team as DSA-6349-1.
  • Besides publishing DLA-4620-1 for package apache Bastien also prepared an upload for trixie, which was handled by the security team as DSA-6323-1.
  • Tobi uploaded package mesa to trixie and bookworm.
  • Thorsten fixed some (not security related but RC) issues in package dahdi-linux. This was in preparation to fix lots of security issues in asterisk. Unfortunately the maintainer ignored the corresponding debdiff and prefered to upload a new upstream version. Anyway, the concerns of the security team about security support of asterisk could be overcome and asterisk can migrate to tesing and again be part of a Debian release.

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

21 July 2026

Vasudev Kamath: Releasing debvulns-exporter: Prometheus exporter for Debian System Vulnerabilities

Following up on my previous post, I am releasing debvulns-exporter, a Prometheus exporter for tracking Debian system vulnerabilities. The underlying vulnerability analysis logic remains identical to the previously released MCP server and CLI utility.
Why an Exporter? In my engineering workflows, I frequently deal with Debian and vulnerability management. Most enterprise environments rely on commercial, paid vulnerability platforms like Tenable or Rapid7. While these platforms provide extensive feature sets, I noticed a distinct lack of open-source tools tailored for this specific pipeline. While debsecan exists, it lacks a structured, parseable format suitable for building dashboards aimed at management consumption. What started as an experimental MCP server for learning purposes evolved into a practical question: why not convert it into a Prometheus exporter? Given that Prometheus is the de facto standard metrics platform across the industry, this architecture was the logical next step.
Design and Exported Metrics The exporter is implemented as a native Prometheus exporter utilizing the prometheus-client library. It operates using two threads: one handles fetching the vulnerability data, parsing EPSS feeds, and cross-referencing installed packages to identify local vulnerabilities; the second handles serving the metrics endpoint. The full architecture details and metrics specifications can be found in the design doc. The specification was drafted during a technical brainstorming session with Claude 4.6 Sonnet on Antigravity prior to writing the implementation.
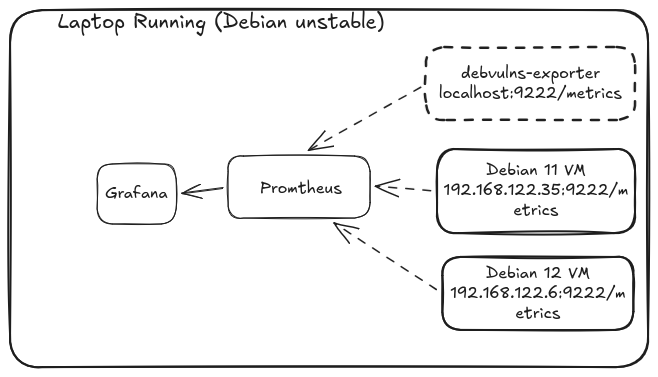
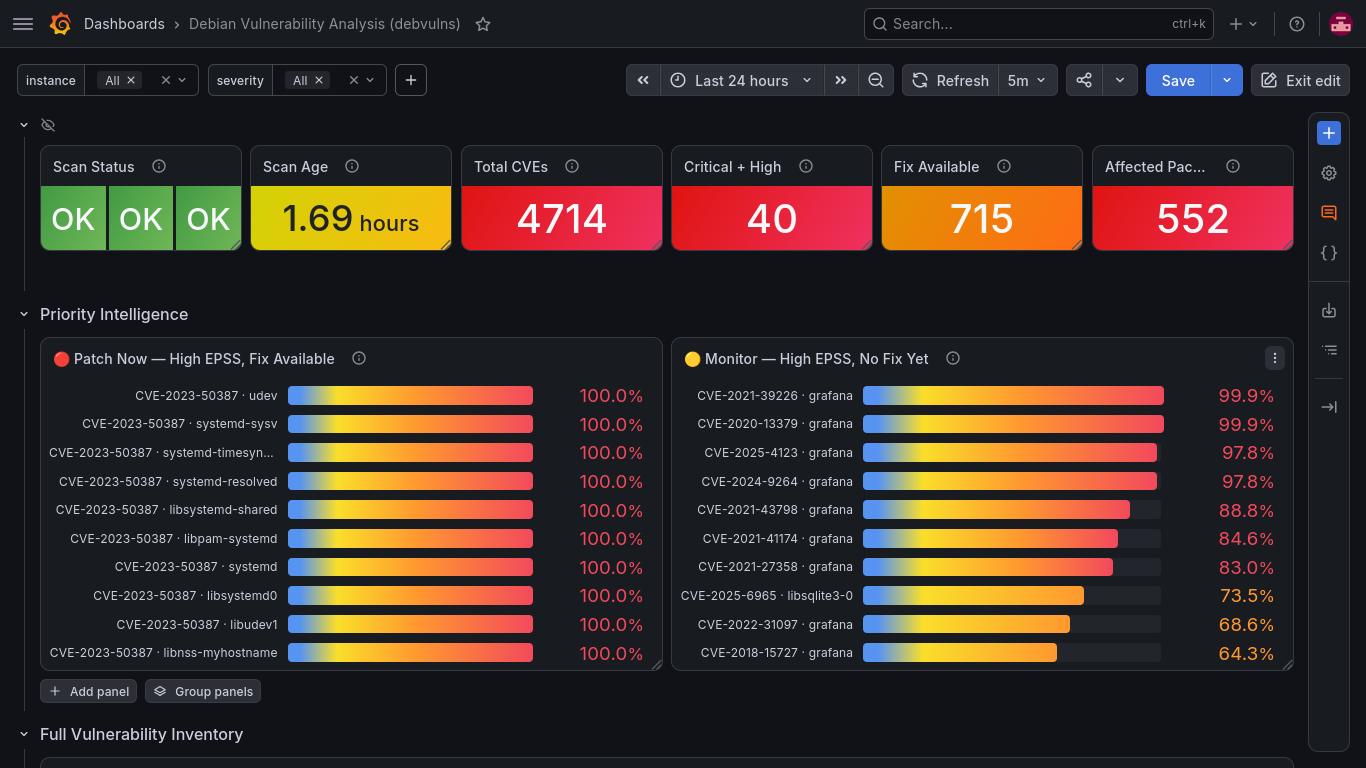
Testing and Dashboarding To validate the exporter, I spun up older Debian 11 and Debian 12 cloud images sourced from the Debian Cloud team. The older image was intentionally selected to guarantee a standard baseline of unpatched vulnerabilities for testing. The local evaluation topology is structured as shown below: Rather than constructing the Grafana dashboard from scratch, I used Claude 4.6 Sonnet via Antigravity to generate the layout configuration. The generated dashboard for the local testbed functions effectively: The complete, ready-to-import Grafana dashboard configuration is included directly in the debvulns source code.
Renaming the project To prevent namespace conflicts and confusion with the native debsecan utility in Debian, I have unified the ecosystem under the debvulns moniker. The core CLI is named debvulns, the exporter is debvulns-exporter, and the MCP component is debvulns-mcp. The migration release has been published to PyPI, and the new consolidated repository is active at debvulns.
Conclusion While this began as a personal utility to fill a niche tool gap, I expect it will be useful for others managing Debian infrastructure at scale. My next objective is to formalize Debian packaging for both the CLI and the exporter. The MCP component will likely remain available as an independent artifact. Until then, happy hacking. Note: As a core design choice, debvulns still uses native debsecan as its ground-truth standard. The tool continuously cross-verifies its output against debsecan to ensure perfect functional parity and data consistency.

20 July 2026

Jonathan Dowland: Interzone digital

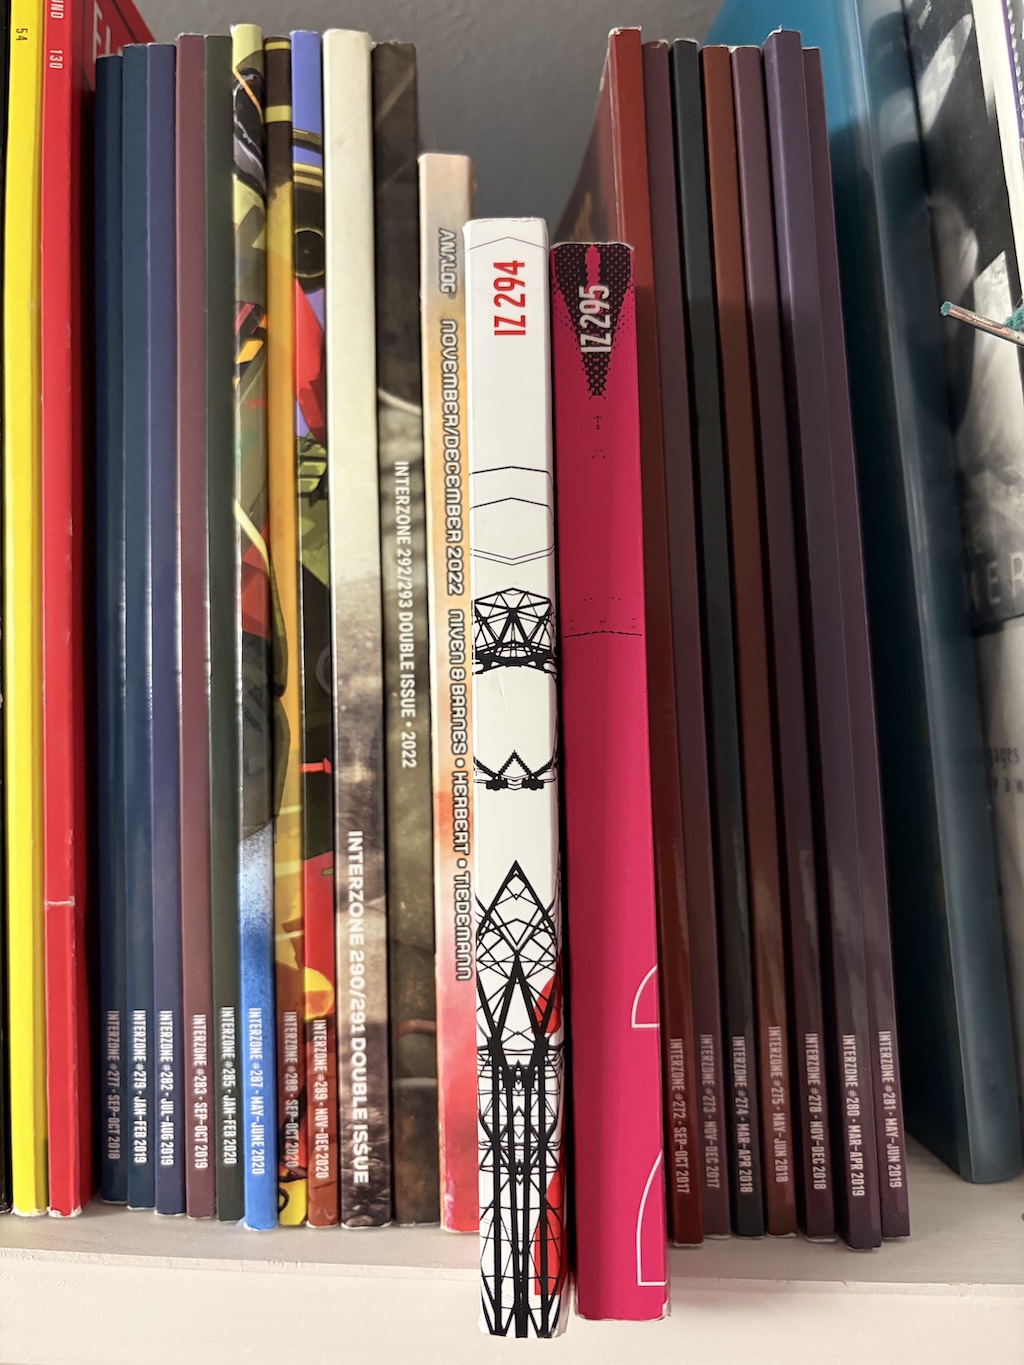
(no, this isn't a blog post about Joy Division songs) Last time I wrote about Interzone, I was discussing issue #294, the first published under new management in a paperback-sized format ("JB6"). The format and presentation of the magazine was fantastic: it fit in a lot of my pockets, and was packed with 15 stories as well as the regular columns, in full colour with fantastic layouts and illustrations. Sadly there was only one more physical issue before Interzone was forced to become a digital-only publication.
IZ issues 294 and 295 IZ issues 294 and 295
I don't want to dwell on the sad necessity to move to digital. Interzone continues on, celebrating the milestone issue #300 in 2024. Subscriptions are managed via Patreon. Issue #305 just came out. Instead I wanted to write a small bit about how I engaged with the paper magazine, and the difficulties I've had trying to engage with not just Interzone but any magazine-style publication in a digital context. With most fiction, I read linearly: start the beginning and read to the end, in order. That works well for me with e-readers. But for magazines (and most non-fiction) I don't, I jump around: usually starting with the table of contents, I might pick a short column to start, or jump into the middle of the "book reviews" section to read about a specific book. I might skip sections entirely. I find it very difficult to read like this with an e-reader. I think this is partly because I reference the depth of the paper book or magazine, its thickness, to orient myself. But it's also partly the limitations of e-ink.
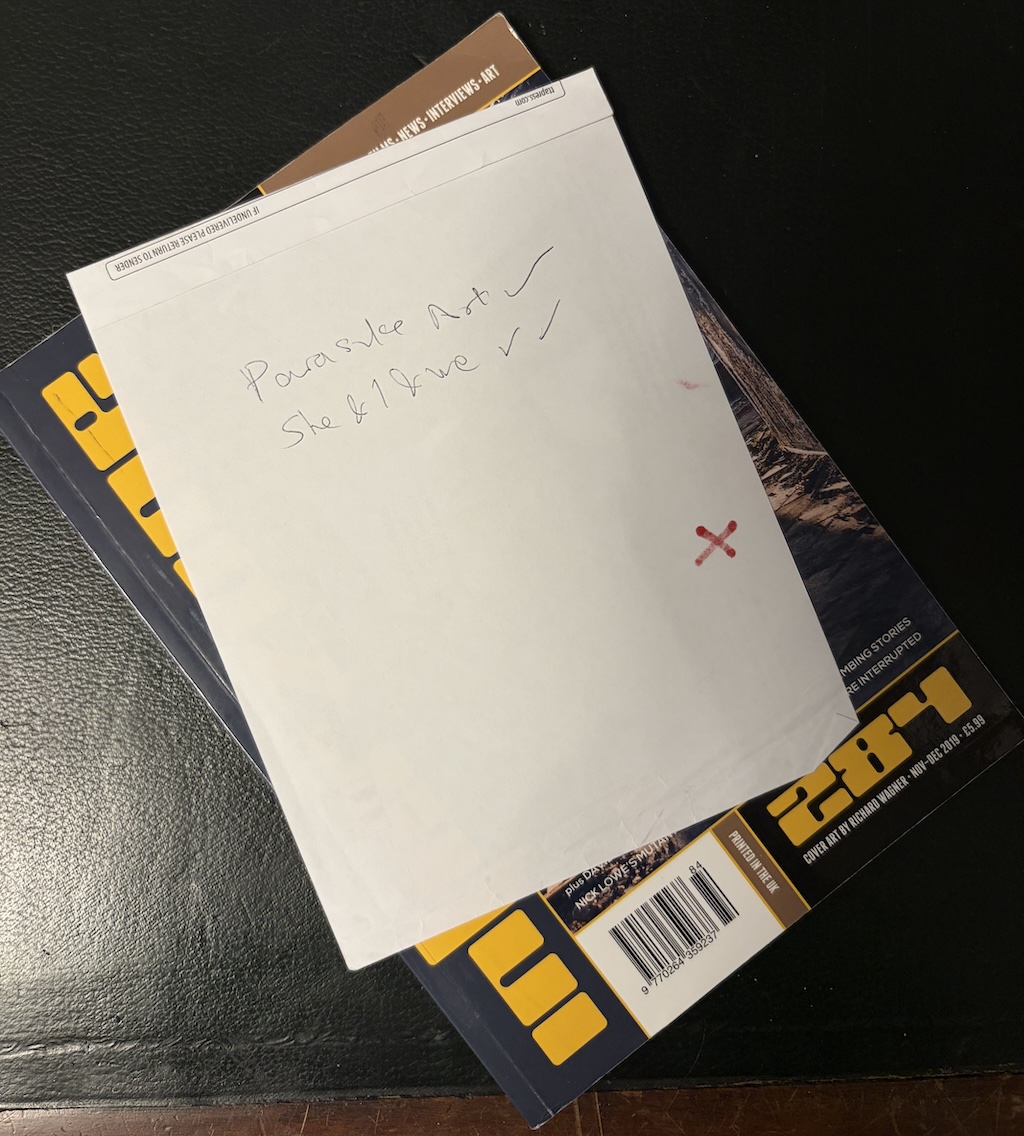
My tick-list for an issue of IZ My tick-list for an issue of IZ
For print-Interzone, I used to start by inserting a small piece of paper inside the cover (the delivery slip was ideal). On this I listed the stories within and ticked them off when I read them (sometimes I double-ticked if I really liked a story). That helped me to remember, perhaps months or years later, whether I'd read all the stories or not, and which I liked. I could do something similar on some e-readers: the Remarkable for instance. But it's far from convenient to do on most e-ink devices. Interzone digital is available as both ePUB, the most common format for e-books, and PDF. For reading on my regular Kobo e-reader, PDFs don't work very well at all. I think this is generally true of most e-readers. Interzone was (and is) a well-designed magazine. The value of it was not just the content of the text, but the context: how the stories were presented; the accompanying art (most often colour in recent decades), but also the typesetting. ePUB doesn't specify much of that stuff exactly: it leaves that up to the client and the client's preferences. And there's a lot of advantages to that: Prefer a different font face or size? No problem. And most importantly for accessibility: If reading in ePUB makes Interzone available to more readers then that's a great thing. But sadly a lot is lost, IMHO.
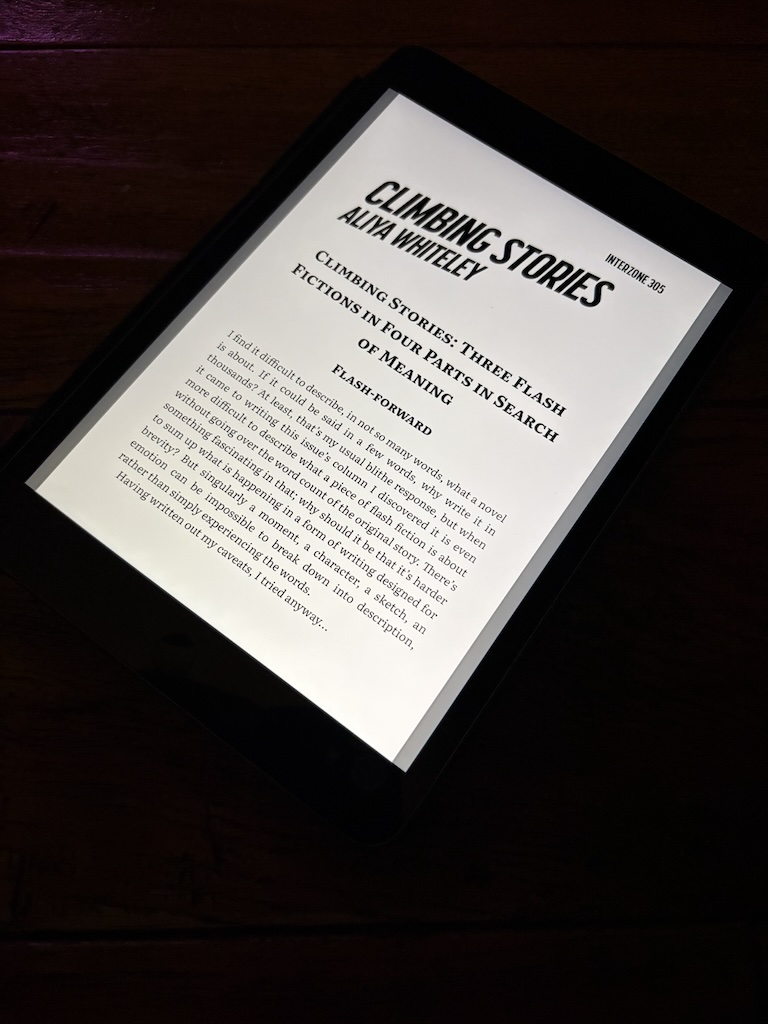
IZ #305 on iPad Mini IZ #305 on iPad Mini
The solution I'm trying is to read the PDF version on the iPad Mini I resurrected earlier in the year. Despite being an Internet tablet, since it's not really usable for browsing the web anymore it's strangely still a distraction-free device. In fact it's pretty much single-purpose for reading Interzone and the odd other book which benefits from being read as PDF. I can appreciate the stylistic choices made in the page-setting as they were intended; I can quickly jump around the issue without waiting for an e-ink refresh; I get full colour; and whilst it would be tiring to read for a long time on the iPad screen, for the length of articles or stories in a magazine, this isn't a problem. It's not a solution for tracking what I've read (that version of ipadOS is too old to support clumsily scrawling on PDF pages with your fingers, at least in the Books app) but it otherwise seems to work well, so I'll see how it goes.

18 July 2026

Bits from Debian: DebConf26 welcomes its sponsors

Alt DebConf26 by Romina Molina DebConf26, the 27th edition of the Debian conference is taking place at the Facultad de Ingenier a en Ciencias H dricas of the Universidad Nacional del Litoral, in Santa Fe, Argentina. We appreciate the organizers for their hard work, and hope this event will be highly beneficial for those who attend in person as well as online. This event would not be possible without the help from our generous sponsors. We would like to warmly welcome the sponsors of DebConf26, and introduce them to you. We have two Platinum sponsors. Our Gold sponsors are: Our Silver sponsors are: Bronze sponsors: And finally, our Supporter level sponsors: A special thanks to the Facultad de Ingenier a y Ciencias H dricas - FICH UNL, our Venue Partner! Thanks to all our sponsors for their support! Their contributions enable a diverse global community of Debian developers and maintainers to collaborate, support one another, and share knowledge at DebConf26.

15 July 2026

Russell Coker: libproc-processtable-perl in Debian

I ve just filed a Debian bug report about libproc-processtable-perl giving bad errors when SE Linux denies access to files under /proc [1].
Ran into unknown state (hex char: 0) at /tmp/test.pl line 8.
The errors are of the above form which Google didn t find before now so obviously isn t a common situation, below is my test program.
#!/usr/bin/perl
use strict;
use Proc::ProcessTable;
my $process_table = new Proc::ProcessTable('cache_ttys' => 0 );
foreach my $process ( @ $process_table->table  )
 
  print $process->fname . "\n";
 
Here is the relevant part of strace output:
newfstatat(AT_FDCWD, "/proc/2", 0x7fff19533c10, 0) = -1 EACCES (Permission denied)
openat(AT_FDCWD, "/proc/2/stat", O_RDONLY) = -1 EACCES (Permission denied)
access("/proc/2", F_OK)                 = 0
write(2, "Ran into unknown state (hex char: 0) at /tmp/test.pl line 8.\n", 61) = 61
Below is the apt sources.list line for my personal repository which has a version of the package with this fix. The gpg key is in the etbe-base package in that repository and the source is all there. To access it without apt use this web page [2].
deb [signed-by=/usr/share/keyrings/etbe.gpg arch=amd64 ] https://www.coker.com.au trixie misc
I ve also done some work on the ps.monitor script in etbe-mon that uses this Perl package and made it better handle program names longer than 15 characters. That improvement apparently only works on Linux, Darwin, and Cygwin. People who want things to work better on BSD etc could patch libproc-processtable-perl accordingly.

Freexian Collaborators: Debian Contributions: Python 3.14 as default transition, DebConf 26 preparations, debvm, pconr and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-06 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Python 3.14 as default transition, by Stefano Rivera Debian has had Python 3.13 and 3.14 in unstable and testing since December 2025, with Python 3.13 as the default version (/usr/bin/python3 = 3.13). This gave time for packages to implement support and detect issues in their test suites. A slot to transition to 3.14 as default was requested from the release team in March, and they indicated that we would likely be able to schedule it in late June. In preparation, Stefano reviewed the open bugs against Python interpreters and squashed some in uploads of the latest point releases of Python: 3.13.14 and 3.14.6. Also in June, Python 3.15.0 beta 2 and beta 3 released. Stefano uploaded these to Debian experimental. The 3.15 betas were reason to attempt to revive review of a blocked upstream patch to support Debian multiarch in stable ABI Python extensions, now that Python 3.15 is adding a new stable ABI abi3t.

DebConf 26 preparations, by Stefano Rivera, Antonio Terceiro, Lucas Kanashiro, Santiago Ruano Rinc n and Anupa Ann Joseph DebConf 26, the annual Debian Developer Conference, is being held in Santa Fe, Argentina, in July. Stefano Rivera, Antonio Terceiro, Lucas Kanashiro, Santiago Ruano and Anupa Ann Joseph contributed to the preparations for the event.
  • As usual, Stefano has been supporting the conference website and registration, helping the local team to get accurate data on attendee numbers.
  • Antonio has been supporting the conference website and helping the content team to put together the conference schedule.
  • Santiago has been helping the local team on different topics regarding logistics.
  • Anupa assisted with the accommodation arrangements for DebCamp and DebConf, working alongside Nattie.
  • Lucas has been coordinating the conference schedule and communicating with some speakers.

debvm, by Helmut Grohne The debvm tool used for creating and running ephemeral virtual machines saw a number of small improvements. The requirement of having a filesystem label has been removed in favor of using a uuid and /etc/fstab is no longer created. A memory balloon is enabled by default and this enables qemu to automatically release free guest memory to the host. Booting Ubuntu VMs regressed as a result of their use of uutils and has been fixed. The --architecture flag is back to be able to better support Hurd, which is a work-in-progress of Johannes Schauer Marin Rodrigues. Thanks to Jochen Sprickerhof, you can more easily create VMs for autopkgtest-virt-qemu using --hook-dir=/usr/share/mmdebstrap/hooks/autopkgtest-create-qemu. There also are a few documentation and error message improvements. All of this is pending in git waiting to be uploaded once development slows down. While booting a machine from virtiofsd succeeded, turning the proof-of-concept into production remains for later.

pconr, by Helmut Grohne At DebConf25, Helmut reported on a schroot substitute called unschroot. The second iteration uses varlink IPC to construct a container. That varlink API is now separated into a new project called programmable container runtime. It is meant to provide more flexibility in constructing containers than established solutions such as the unshare command from util-linux, bubblewrap or podman provide while still managing repetitive complexity such as process orchestration for the developer. A new example that uses this infrastructure is a better containment for mmdebstrap eliminating chroot escape. There also is an asyncvarlink/0.3.2 release taking steps to become more maintainable in Debian to eventually get pconr into Debian.

Miscellaneous contributions
  • Stefano did routine uploads (mostly new upstream versions) of python-pip, python-pipx, hatchling, dh-python, beautifulsoup4, python-virtualenv, python-mitogen.
  • Stefano uploaded a snowball mini-transition: snowball, snowball-data, and pystemmer
  • Stefano did some debian.net team admin, setting up a container and later a VM for vote.debian.net.
  • Stefano responded to a semi-escalation to the Debian Technical Committee, after some communication between an upstream, a bug reporter, and a Debian package maintainer went sideways and got heated.
  • Emilio managed several transitions, and filed bugs against the few remaining GCC 13 rdeps.
  • Antonio did salsa maintenance work, debugging service issues, approving user registrations, and processing support requests.
  • Antonio worked on Debian CI maintenance, including but not limited to deploying new armhf and armel workers, fixing bugs and preparing an upcoming release of debci.
  • Antonio did several maintenance tasks for MiniDebConf websites.
  • Antonio uploaded ruby-bunny, ruby-sinatra and ruby-mustermann, fixing a few FTBFS bugs among them.
  • Carles using po-debconf-manager: Reviewed Catalan translations for 5 packages, submitted 6 packages. Added a draft blog/update about the po-debconf-manager project.
  • Carles submitted a new Geeqie Catalan translation: it had accumulated a large number of untranslated strings over the last 4 years.
  • Carles contributed to the Debian wiki: improved documentation for the Framework Laptop and added a new section Battery charging control (after doing some debugging and testing). He wrote a page about Signal Desktop. Carles started looking at testing/documenting Mailman2 -> Mailman3 migration.
  • Carles, in relation to the migration process, double checked old pages without relevant information in the Debian wiki.
  • Thorsten did another upload of package hplip to fix some bugs.
  • In the context of the Google Summer of Code 2026 project, Santiago continued co-mentoring Aryan Karamtoth, who is working on the Linux live-patching project. As part of the team, Santiago guided Aryan to help design the different workflows and to study the different tools available, including the upstream klp-build (that was introduced in v6.19), and compare it with SUSE s klp-build.
  • Colin clarified the bug tracking system s documentation to indicate that maintainers may sometimes reasonably ask users to file bugs upstream themselves.
  • Colin fixed 15 packages for pytest 9.1.
  • Colin fixed a depthcharge-tools regression with Python 3.14 as default that broke debian-installer builds.
  • Helmut continued to report undeclared file conflicts and correspond about them.
  • Helmut wrote patches for strace to enable cross building and a 32bit personality on arm64.
  • Helmut continued maintaining rebootstrap working fixing build failures in fontconfig, gettext and sqlite3 as well as changing the way packages from gcc builds are installed to better serve a need reported by Samuel Thibault.

14 July 2026

Gunnar Wolf: Got your keys ready for DebConf26?

Yay! Finally it s that time of year DebCamp is underway, and soon it will be time for DebConf! As it is by now tradition, it s my task to coordinate the DebConf26 keysigning party. And, as usual, I have set up the list of DebConf26 keysigning maps for everybody involved. So, if you are taking part of DebConf, make sure to:

11 July 2026

Reproducible Builds: Reproducible Builds in June 2026

Welcome to the June 2026 report from the Reproducible Builds project! In these reports, we outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. If you are interested in contributing to the project, please visit our Contribute page on our website. In this month s report, we cover:

  1. Only installing reproducible packages with repro-threshold
  2. Distribution work
  3. diffoscope development
  4. From our mailing list
  5. Documentation updates
  6. Patches
  7. Four new scholarly papers


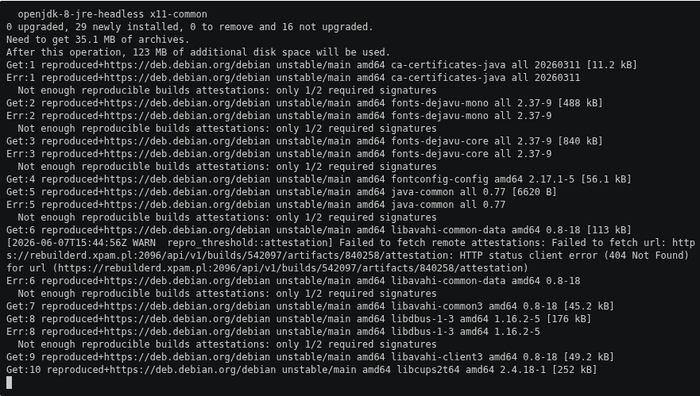
Only installing reproducible packages with repro-threshold A very interesting demonstration is now available showing how you might configure your Debian system to only install packages that have been reproduced by m/n rebuilders. This is implemented via a reproduced+https:// APT transport ( a mechanism for communicating between the APT client and its repository source commonly HTTP):
Every package download is intercepted by repro-threshold, which queries two independent rebuilders for a signed attestation before allowing installation to proceed. [It] is important to note that [an] install will only succeed if all package dependencies are also reproducible.
The demo gives examples of how to quickly experiment with this using a Docker container.

Distribution work In Debian this month: The IzzyOnDroid Android APK repository reached its next milestone this month, now covering 2 out of every 3 apps (66.7%) with reproducible builds. Their documentation for debugging and fixing failed builds has steadily grown as well. More clients have picked up showing reproducibility results (e.g. Droid-ify), and Neo Store now can be configured to stick to only reproducible applications. Further, an independent builder has been added to the build farm, increasing the trust level even more as APK builds can have multiple confirmations now. At the same time, IzzyOnDroid s rbtlog got several new features. The most outstanding is caching for frequently used resources such as reproducible-apk-tools, command-line tools and NodeJS in order to counter ongoing issues with GitHub availability, while at the same time saving bandwidth and build time. This change also enables some other some smaller enhancements such as being able to configure build timeouts per recipe for those builds running longer than the average, release pattern filtering for update checks or having a field for maintainer notes to shortly summing up e.g. why a reproducible build failed.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

diffoscope development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 319, 320, 321, 322 and 323 to Debian:
  • Debian adds an extra Flags: line in the output of ocamlobjinfo, so adjust the test for cross-distribution compatibility. [ ]
  • Bump debhelper compatibility level to 14. [ ]
  • Fix compatibility with Ocaml 5.4.1. [ ]
  • Use --long-form-style arguments when calling apktool in order to support apktool version 3. [ ]
  • Support Androguard version 4 and previous versions at the same time. [ ]
  • Update copyright years. [ ]
In addition, Jochen Sprickerhof added better header detection for the Sphinx documentation system [ ], Michael Daniels fixed the tests when run with zipdetails version 4.006 [ ] and Zbigniew J drzejewski-Szmek added a version of the deprecated os.path.commonprefix method [ ]. In addition, Vagrant Cascadian updated diffoscope in GNU Guix to version 321 and 323.
Chris Lamb also made the following changes to strip-nondeterminism, our tool to remove specific non-deterministic results from a completed build:
  • Skip symlinks when manually called via /usr/bin/strip-nondeterminism. (#1139000)
  • Update debian/watch format. [ ]
  • Drop Rules-Requires-Root: no and Priority: optional fields. [ ]
  • Bump Standards-Version to version 4.7.4. [ ]

From our mailing list On our mailing list this month:
  • kpcyrd posted to our mailing list regarding the waves of malware uploads to aur.archlinux.org . Curiously, every incident I looked at used npmjs.com for malware delivery , specifically where the npm package includes an (automatically executed) preinstall script that is an ELF binary.
  • kpcyrd also announced the release of debian-repro-status version 0.4.0, a tool written to give you an approximate idea of how viable it would be to enforce a reproducible packages only update policy for the computer system you ve built :
    The change updates dependencies to the latest versions, and adds support for multiple -H options, to query results from multiple rebuilderd instances. The results are also now fetched concurrently.
  • kpcyrd also reported that, whilst taking a screenshot for the above release, they noticed that the debian:sid container now is 100% reproducible.
  • Finally, kpcyrd also created a pull request against the add-determinism package to update the itertools and zip Python dependencies.

Documentation updates Yet again, there were a number of improvements made to our website this month including:
  • Chris Lamb added a reminder re. using the UTC variants of the Javascript Date methods. [ ]
  • Mattia Rizzolo moved OTF to the old sponsors list. Thank you for your support!. [ ]
  • kpcyrd updated the Rust documentation to recommend using the --release argument for consistency. [ ]

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Four new scholarly papers Kenichiro Muto and Kuniyasu Suzaki of the Institute of Information Security in Yokohama, Japan published an interesting paper this month titled Attestable Build Chain: Enabling Trust in Reproducible Builds (PDF). Their abstract is as follows: Ensuring trust in software supply chains requires verifying not only artifacts but also the processes that produce them. Although Reproducible Builds (R-B) require rebuilding to validate artifacts, they cannot verify whether the build was executed with the intended toolchain and inputs and may reproduce unintended or compromised builds without detection. We present Attestable Build Chain, a framework for externally verifying build-time execution without rebuilding. Rather than preventing compromise, it provides verifiable, tamper-evident evidence of actual build-time execution, enabling verification of build process integrity from observed file accesses during the build. [ ]
Julien Malka, Stefano Zacchiroli and Th o Zimmermann published a 50-page report detailing A Decade of Software Reproducibility in the Nix Package Ecosystem:
We find that functional package management enables extremely high rebuildability over time (near-universal ability to reconstitute historical build environments and rebuild software packages), while bitwise reproducibility has steadily improved and reaches a high point in recent years (up to 93% in 2024). Early years show substantially lower bitwise reproducibility, indicating that functional package management alone does not guarantee bitwise-identical outputs, and that the observed high level of bitwise reproducibility is not solely due to the package management approach. Common causes of unreproducibility, both in the rebuildability and bitwise reproducibility dimensions, include management of dates in build and test processes; we quantify their prevalence and other common causes using manual analysis of logs of rebuild failures and automated analysis of diffoscope.
A PDF of their report is available online
Tim Bastin of L3montree GmbH and Jacek Galowicz of Applicative Systems GmbH from DevGuard published a paper detailing How We Built a Sovereign, Reproducible Container Supply Chain for DevGuard:
This paper presents how the DevGuard project rebuilt its OCI container pipeline around reproducible Nix builds and independent dual-platform digest verification. DevGuard images are built hermetically from pinned source revisions, signed with Sigstore/Cosign, and verified through digest comparison across GitHub Actions and sovereign GitLab infrastructure hosted on container.gov.de. We describe the practical integration of reproducible OCI image builds into existing CI/CD workflows and argue that independently reproducible container digests provide a stronger integrity guarantee against build tampering than provenance alone. The paper further discusses remaining trust assumptions and the relevance of sovereign build infrastructure for government and regulated environments.

Finally, Yiseul Choi, Junga Kim, Jun-Ho Hong and Seongmin Kim of the Department of Convergence Security Engineering at the Sungshin Women s University in Seoul, Korea titled Attestation-based verification of SBOM integrity via consumer-side reproducibility:
Software bills of materials (SBOMs) support supply chain transparency, but they do not prove that a delivered SBOM reproducibly corresponds to its software artifact. Existing signing and provenance mechanisms protect integrity and traceability, yet lack consumer-side reproducible verification. We propose an SBOM integrity verification framework combining procedure disclosure, consumer-side reproduction, authority-generated reference evidence, and digest comparison. A trusted authority records a reference digest, and consumers compare it with locally reproduced and delivered SBOM digests. Experiments on 100 real-world container images show detection of artifact tampering, SBOM substitution, distribution modification, and adaptive tampering beyond signature-based approaches


Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

10 July 2026

Tim Retout: Blocking distracting news links

You are what you eat but perhaps this is even more true of our information diet. It is hard to strike a balance between remaining a well-informed citizen versus spending hours ingesting unnecessary news about issues and events we can t affect. But I m increasingly convinced that my hours lost to doomscrolling are down to design choices by web publishers rather than a failure of individual willpower.

We have created an obesogenic information environment I don t think it is just me I think our information environment has been progressively altered over time as news sites look to maximize engagement. Even outside of social media, the invisible hand of the market for eyeballs forces sites to optimize for browse time or risk irrelevance. Even as newspapers find it increasingly difficult to fund good journalism through advertising in an online world, especially local journalism, they need to keep readers on their sites, clicking through as many articles as possible. Clickbait headlines, urgent flashing live icons to draw the attention, and many opportunities to leap from one article to another, and another. But this design approach even extends to news organisations with a different funding model, like BBC News, which is a public service (state-owned but arms-length) organisation funded through a mandatory television licence a matter of controversy in some quarters. And it extends even to sites where I pay a subscription fee; I might get adverts removed, but I am still bombarded with the same design philosophy; too many opportunities to be pulled away from what I m reading towards some other unrelated article. Even if I try and limit my exposure to algorithmic discovery of new news, via RSS feeds or similar, if I m reading the full article in a browser then I am prompted to read more stuff that I didn t intend. This defeats the benefit of curating a set of feeds, because you still get dragged away to random articles.

Only 44% of BBC News is news To show you what I mean, I m going to pick on the BBC, although I love them dearly and the same issue very much applies elsewhere. I ve taken a screenshot of a random BBC News article in mobile view (my preferred doomscrolling user access device), and measured approximately what proportion of the full length of the page is taken up by each section. This is a fairly in-depth news article, so I reckon if anything the figures would be worse than this on shorter articles. A full-length screenshot of a BBC News article showing proportions of the page allocated to the main article vs. related links etc. (These numbers will not sum to 100% for reasons which are obvious if you look at the crossbars. Also they re approximations.) Less than half of the page (44% if you exclude the inline related links) is actual news text/images; the rest are links trying to help you find the next thing to read/watch. I do not want this. I m sure this A/B tests well in terms of reader figures, but it sometimes leaves me exhausted it must take subconscious mental energy to ignore, or I spend too much time trying to keep on top of things. And remember, this is a publicly-funded site that does not rely on advertising!

Blocking out the noise If you are technically-minded, you can use an ad-blocker such as uBlock Origin to take back some control. Applying the following lines as a custom filter (Settings > My filters) brutally cuts out almost all of these links:
bbc.co.uk##aside
bbc.co.uk##footer>div:has(h2)
bbc.co.uk##[data-block="uploaderEmbed"]
bbc.co.uk##[data-block="links"]
Caveat emptor: I have not road-tested this for more than half an hour, so who knows what consequences this could have on your web browsing. In particular, international readers outside the UK will likely be redirected to bbc.com, the commercial arm of the BBC, where these rules will need adapting. Is it unethical to use an ad-blocker to remove these links? I would argue not. I am not depriving the BBC of any revenue, because I pay my licence fee. I might reduce the amount of time I spend on their website, but if anything the subjectively better experience might encourage me to consume more news from them, not less. In other circumstances (outside the UK for instance, where the BBC relies on advertising), the balance might be different.

Product managers, please find better metrics I lament the state of the internet in 2026. I now can t unsee these innocuous related stories links as a mechanism to grab my attention, and it s gone too far. If you are a normal person just browsing the news and looking to discover the latest important stories relatively quickly, I can see that these types of links might actually be useful for discovery; but I m actually reasonably sure that I m not going to miss out on anything major. You still have the option of the news home page if you want to be presented with more news for example, and it feels natural to go back to there when you ve run out of stories to consume. But it shouldn t be down to individual responsibility to ignore or geekily block these types of link; news sites with alternative funding models should find better metrics for engagement than hours spent on site how about optimizing for customer mental wellbeing, or minimizing time required to catch up with the news? There s no need to maximize clicks and eyeballs. This is a societal level issue, because we are all going mad with news over-engagement. Product managers, over to you.

Valhalla's Things: Cockades!

Posted on July 10, 2026
Tags: madeof:atoms, FreeSoftWear, craft:sewing
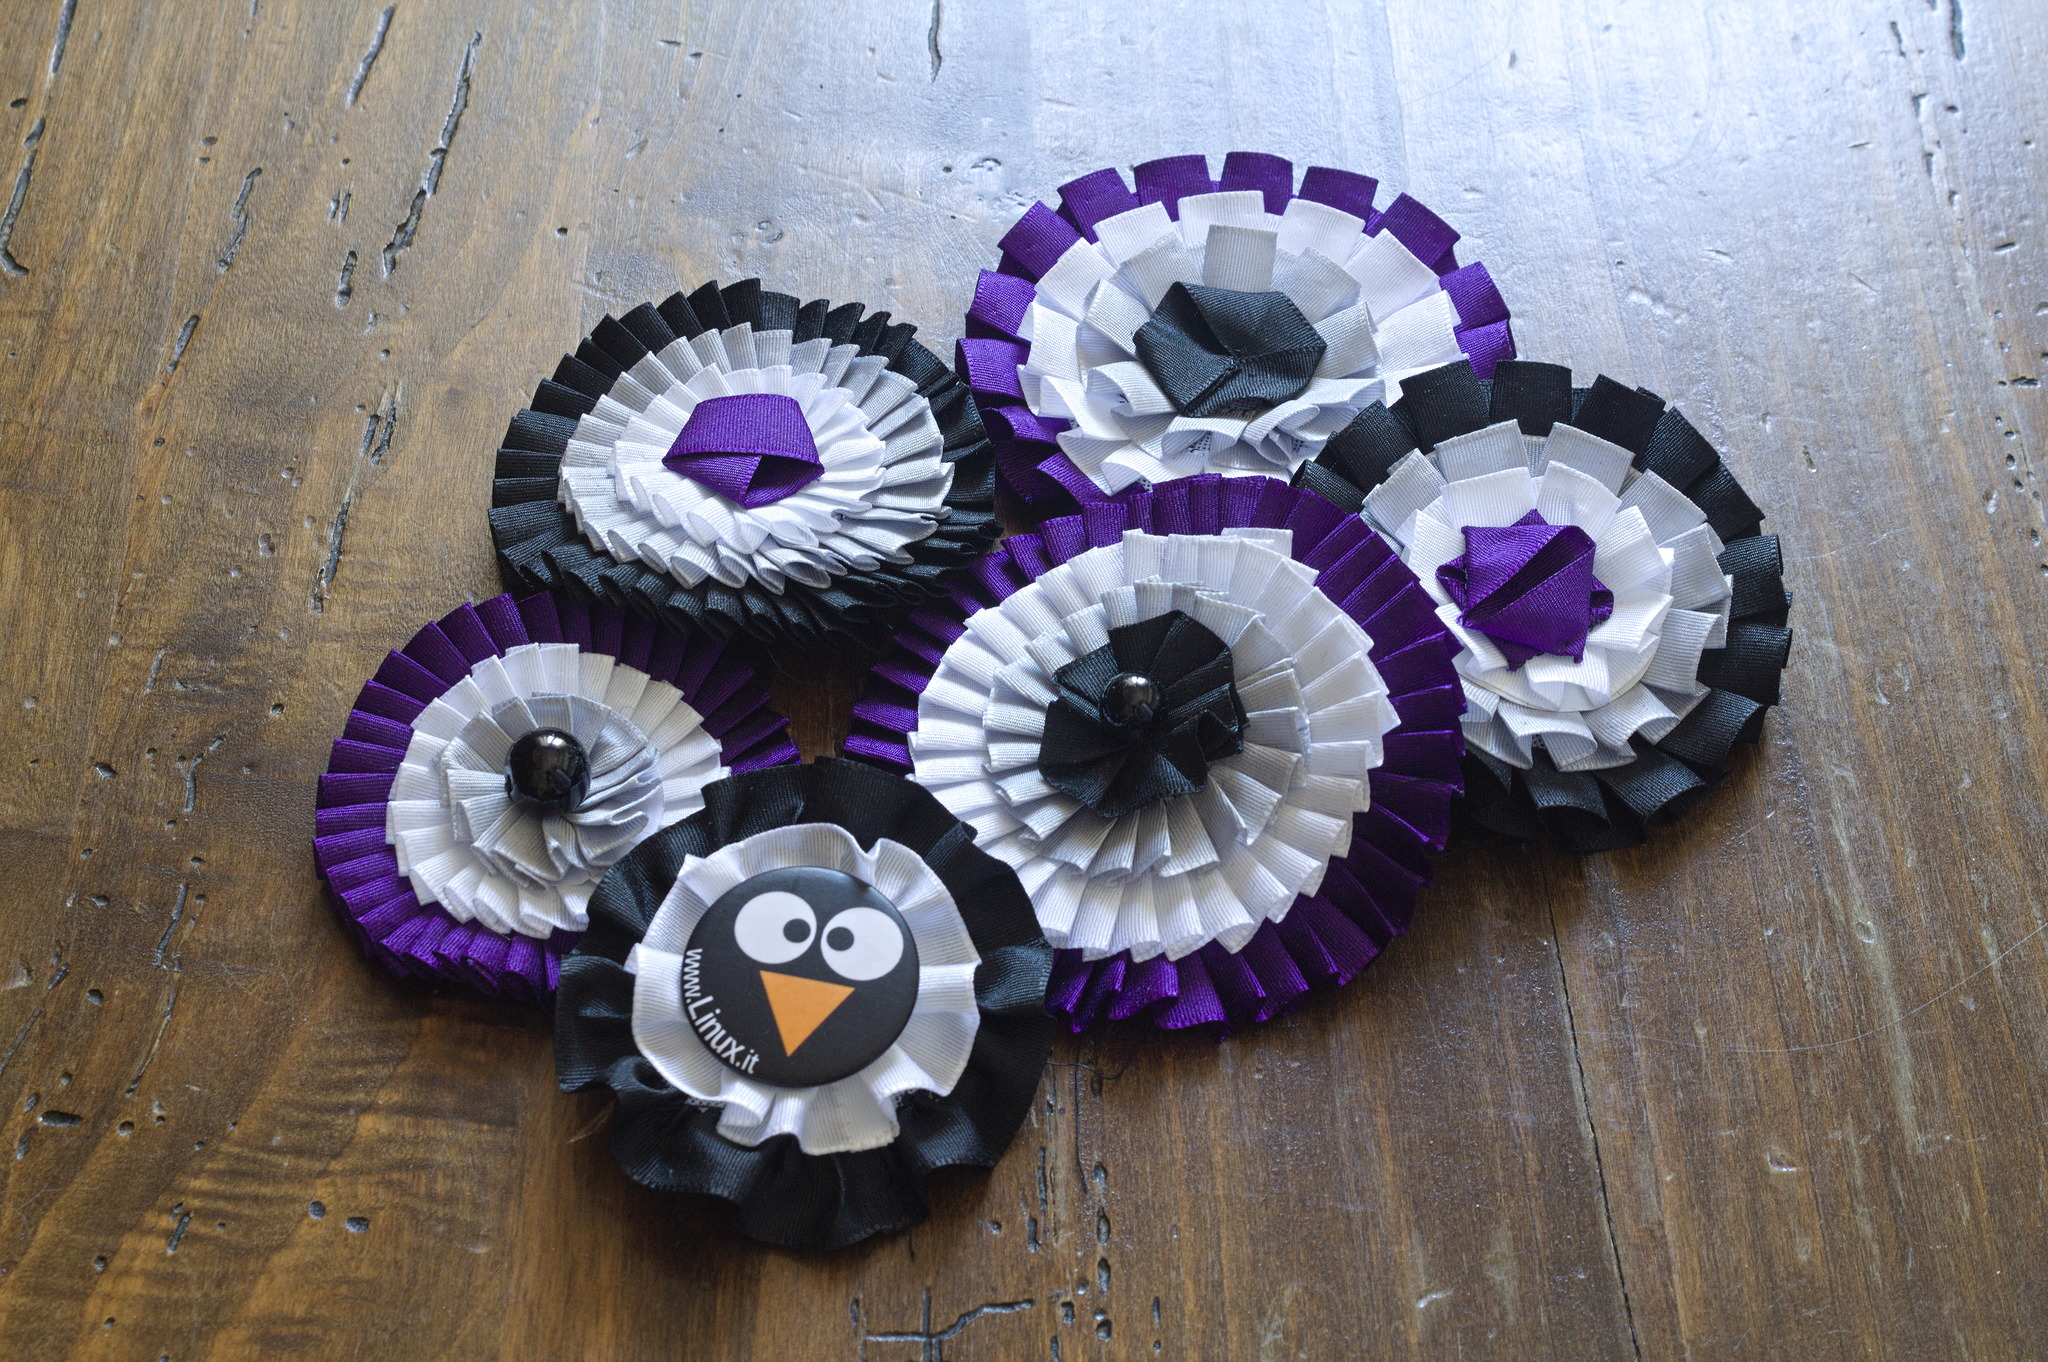
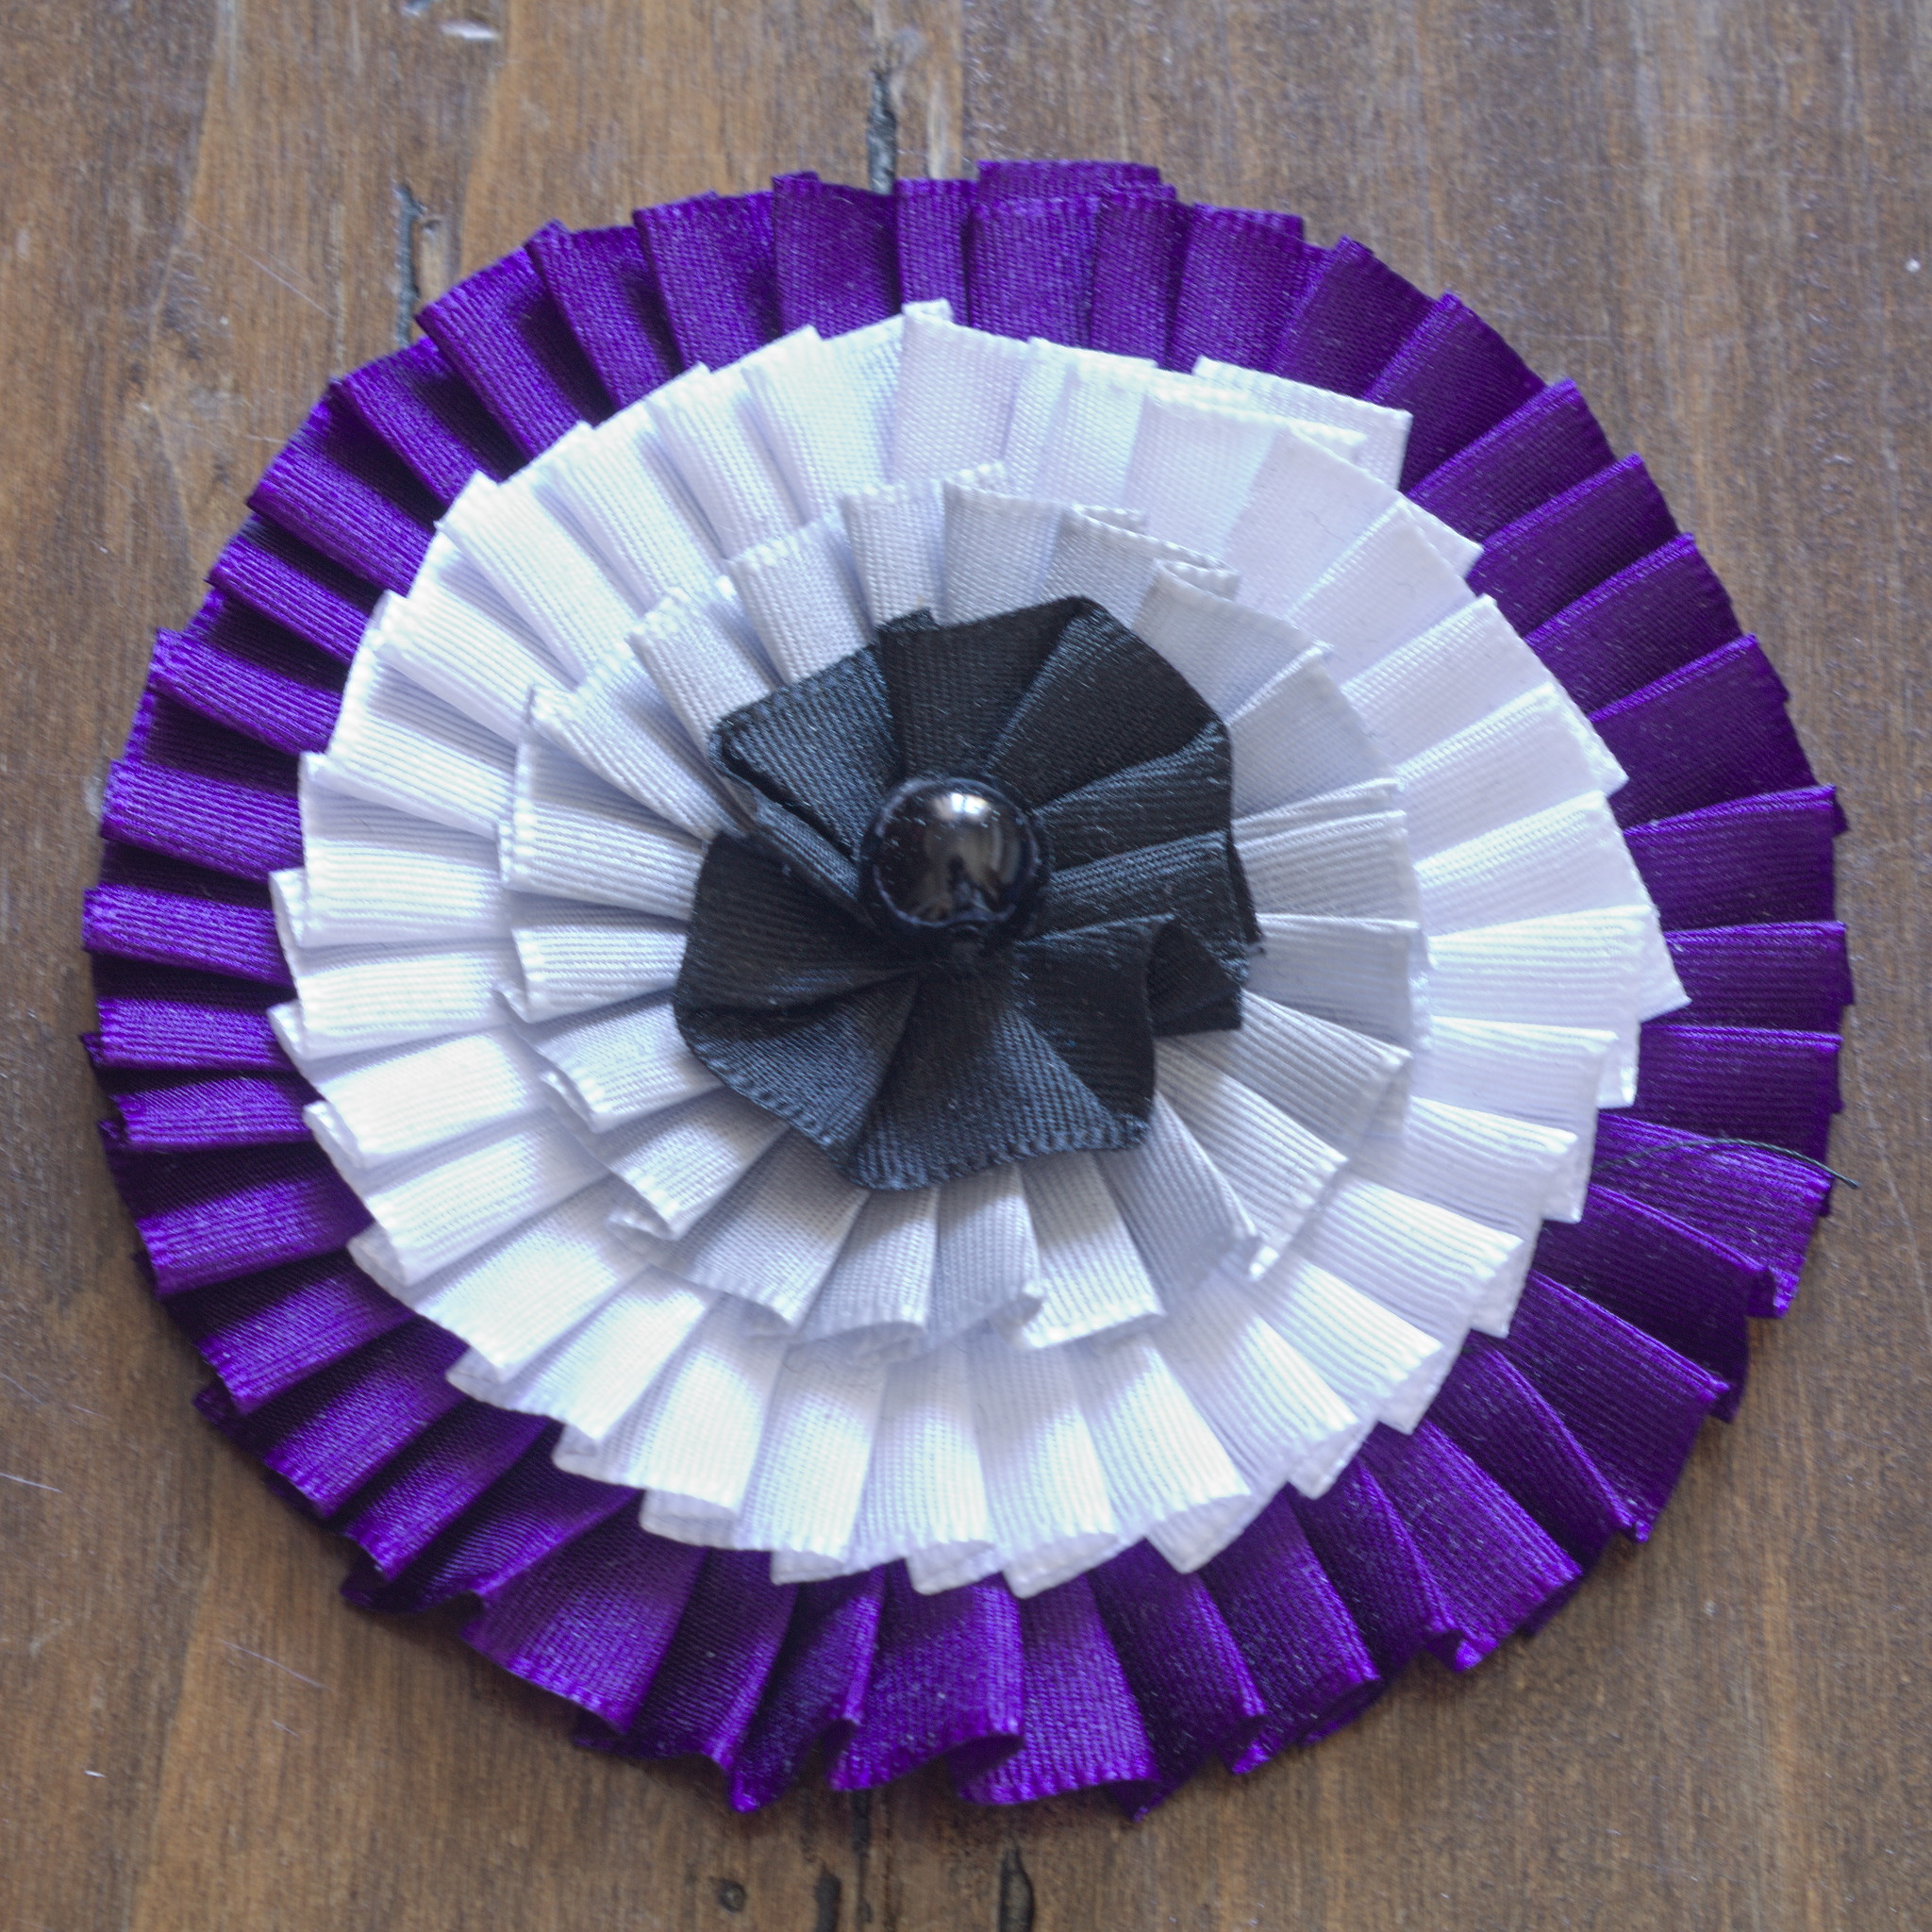
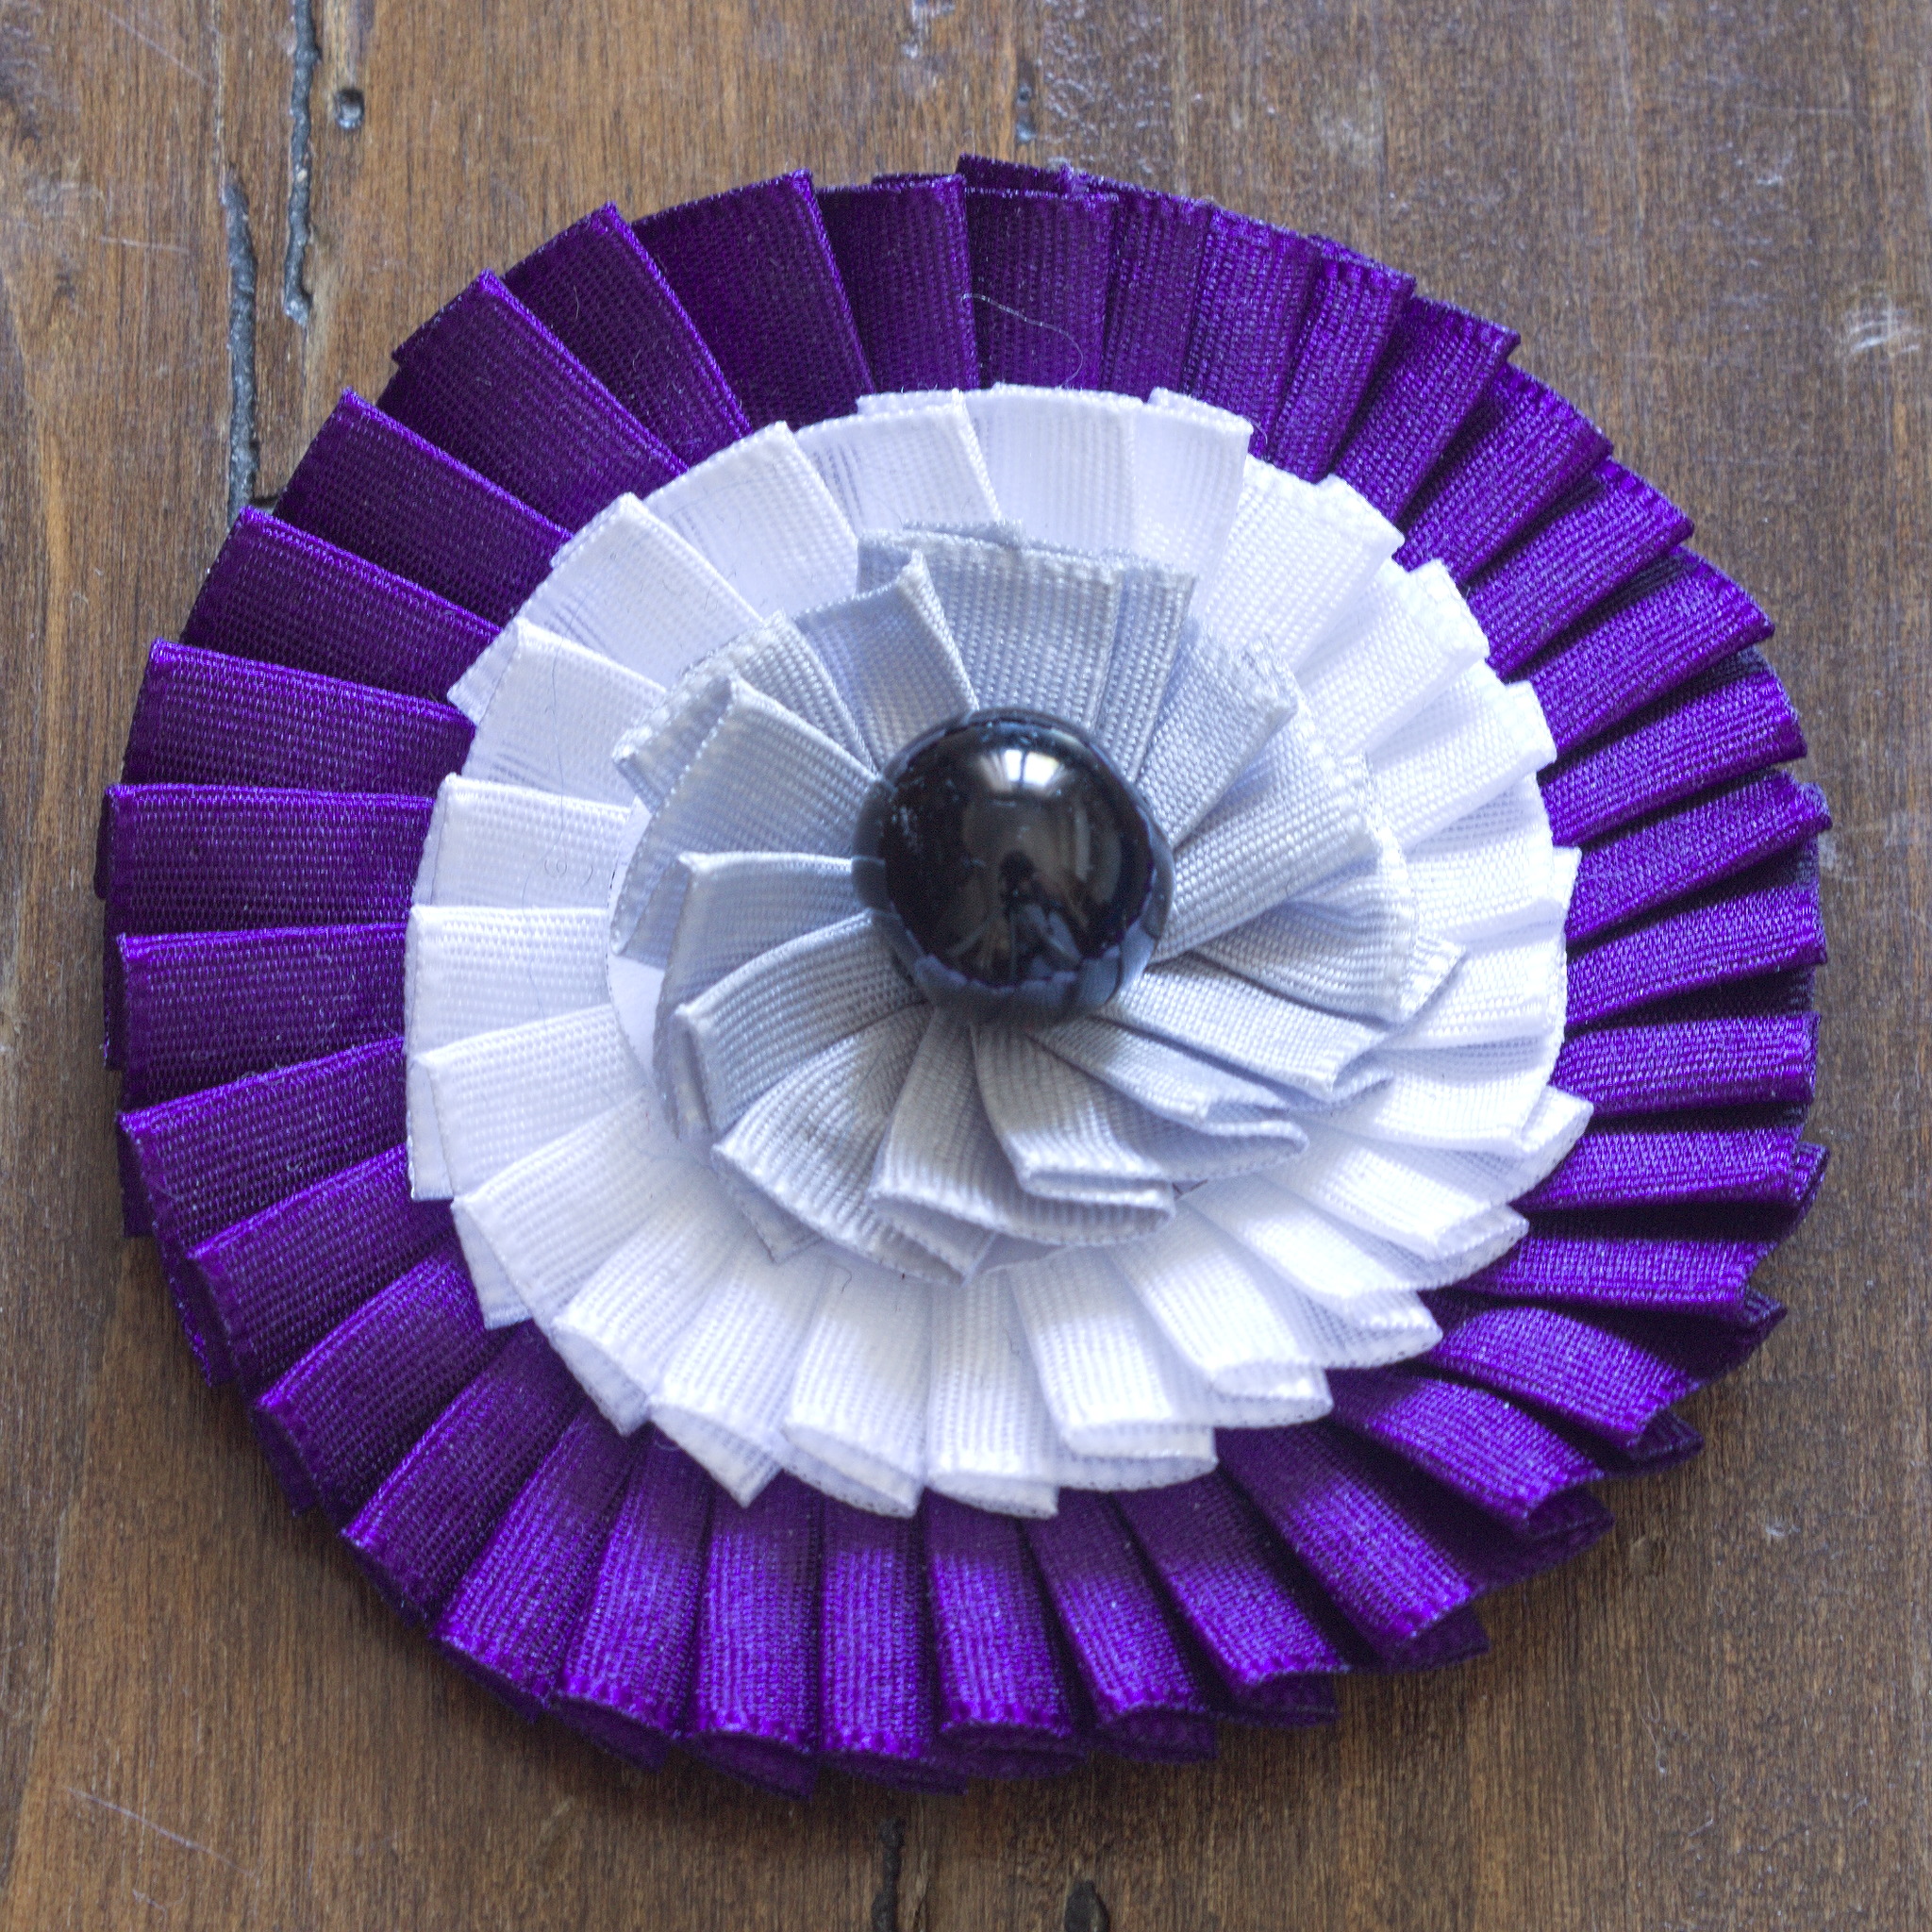
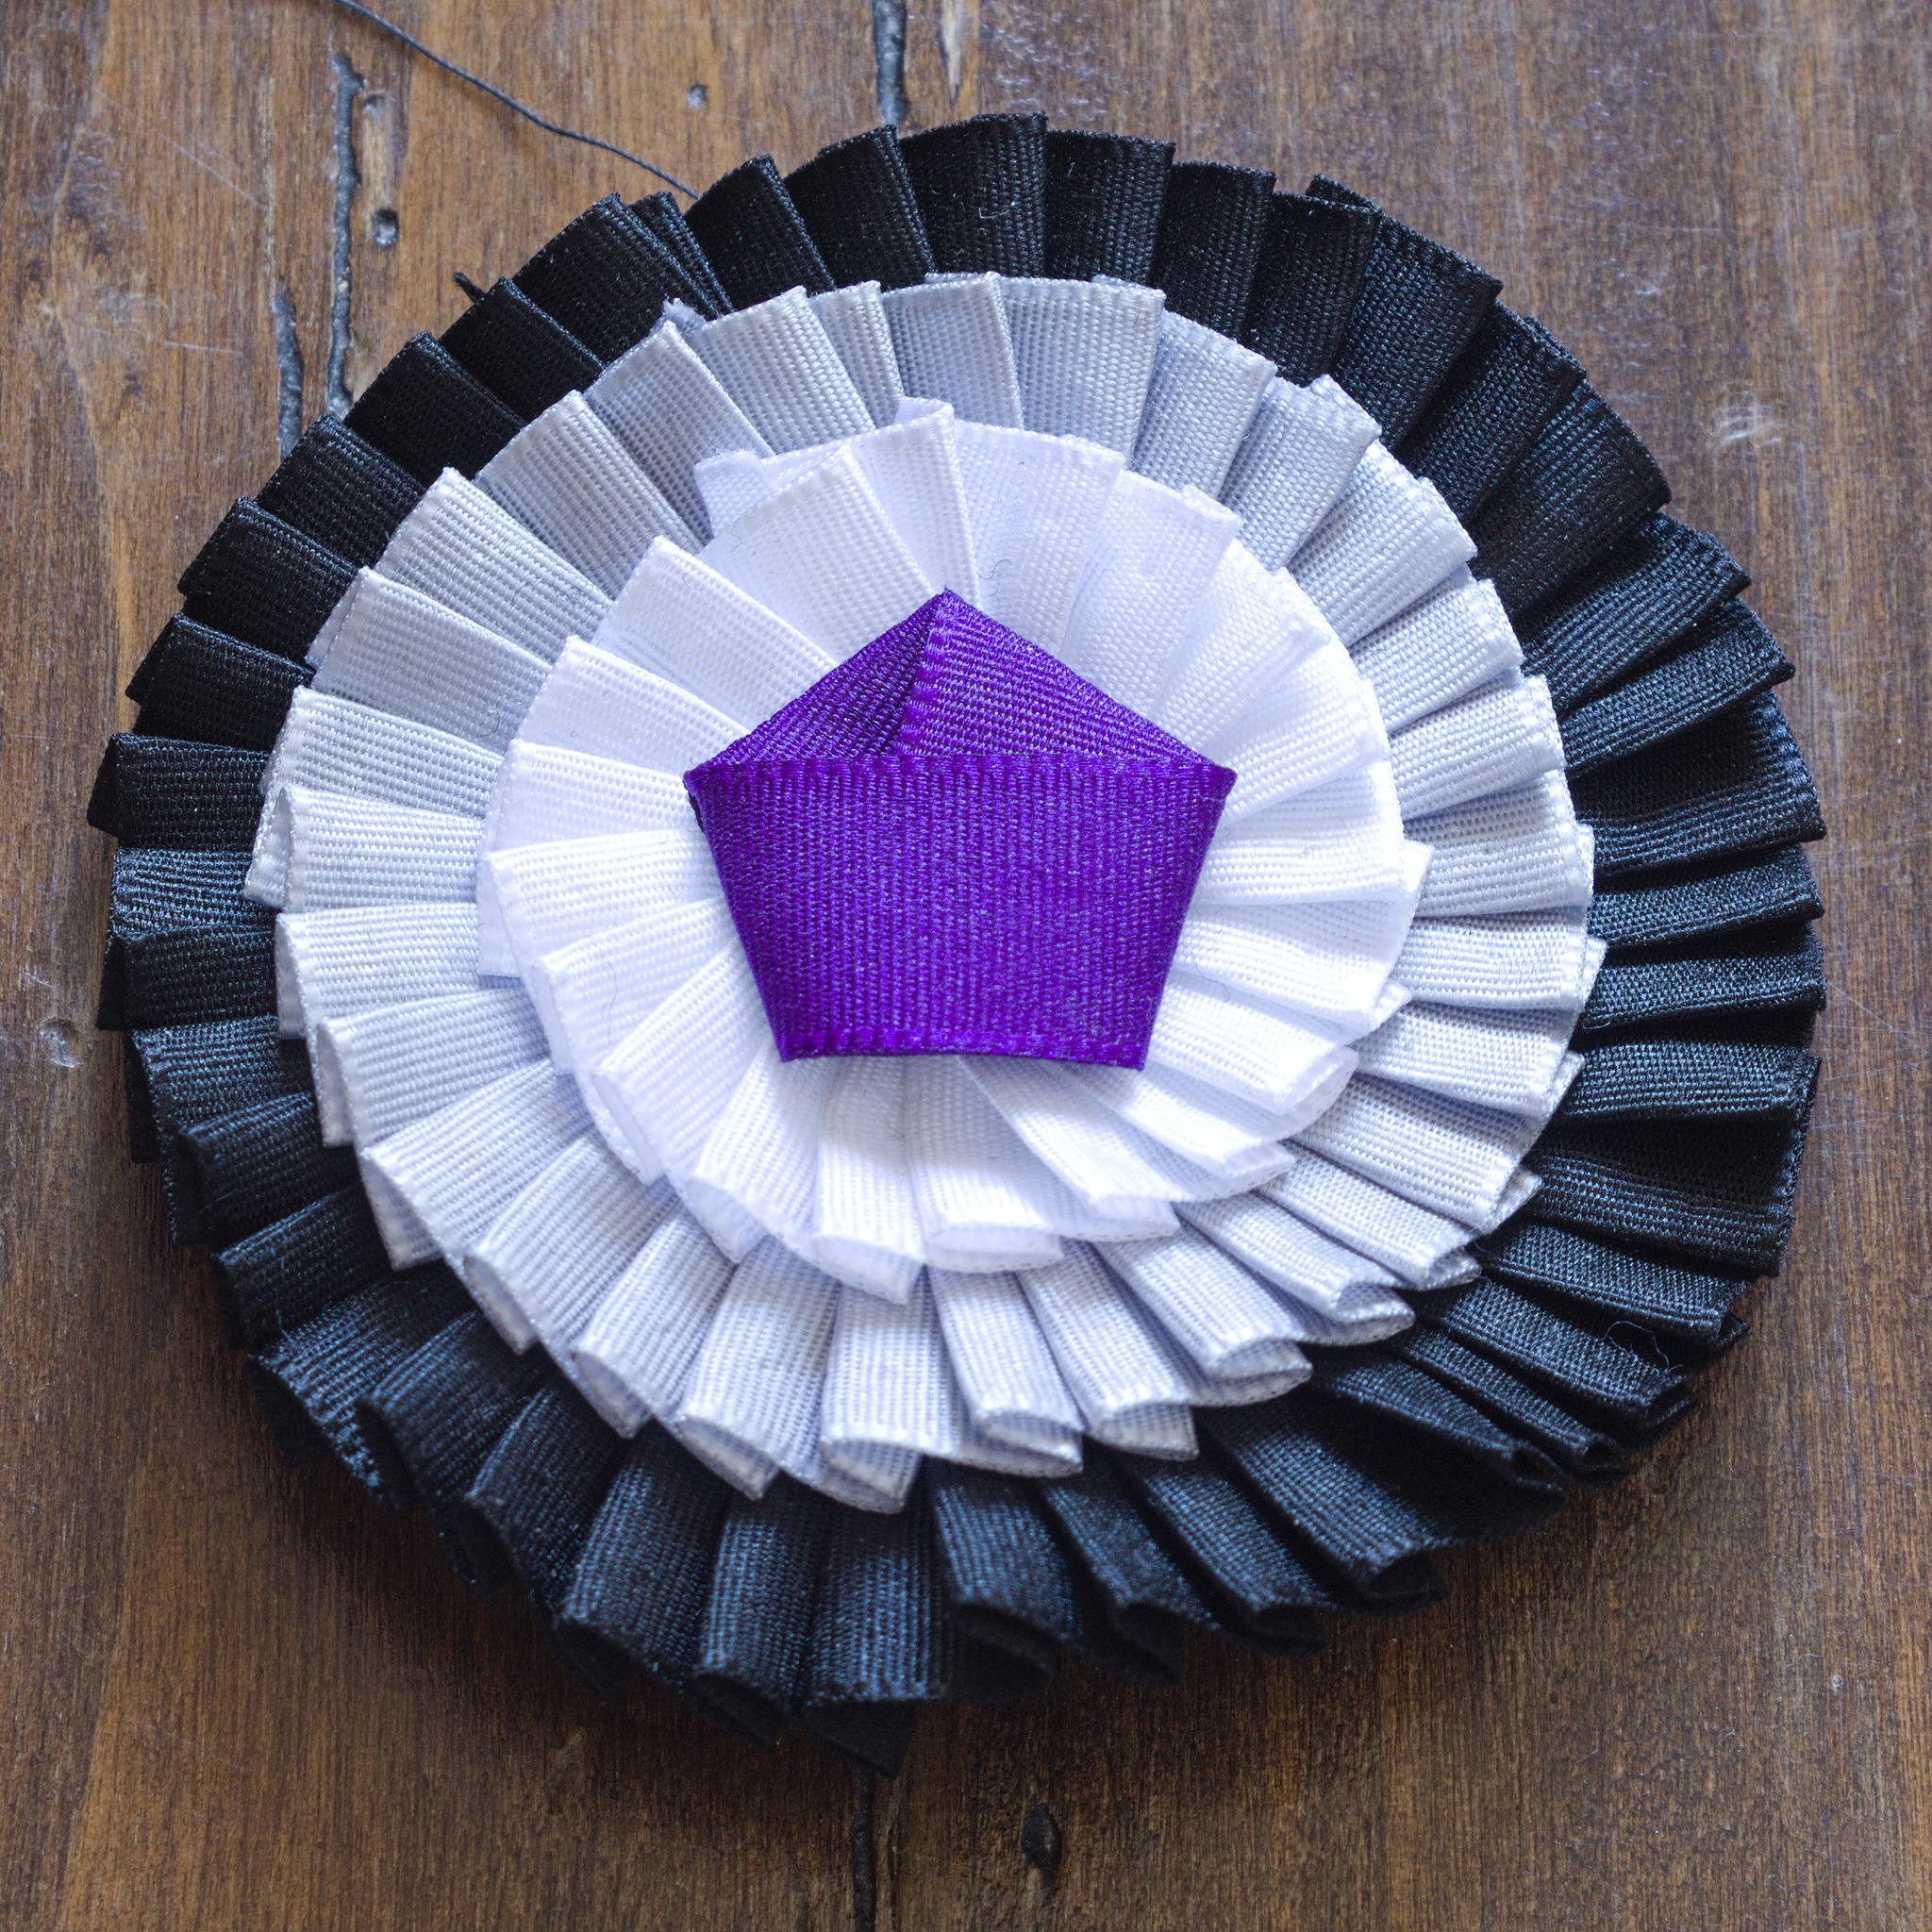
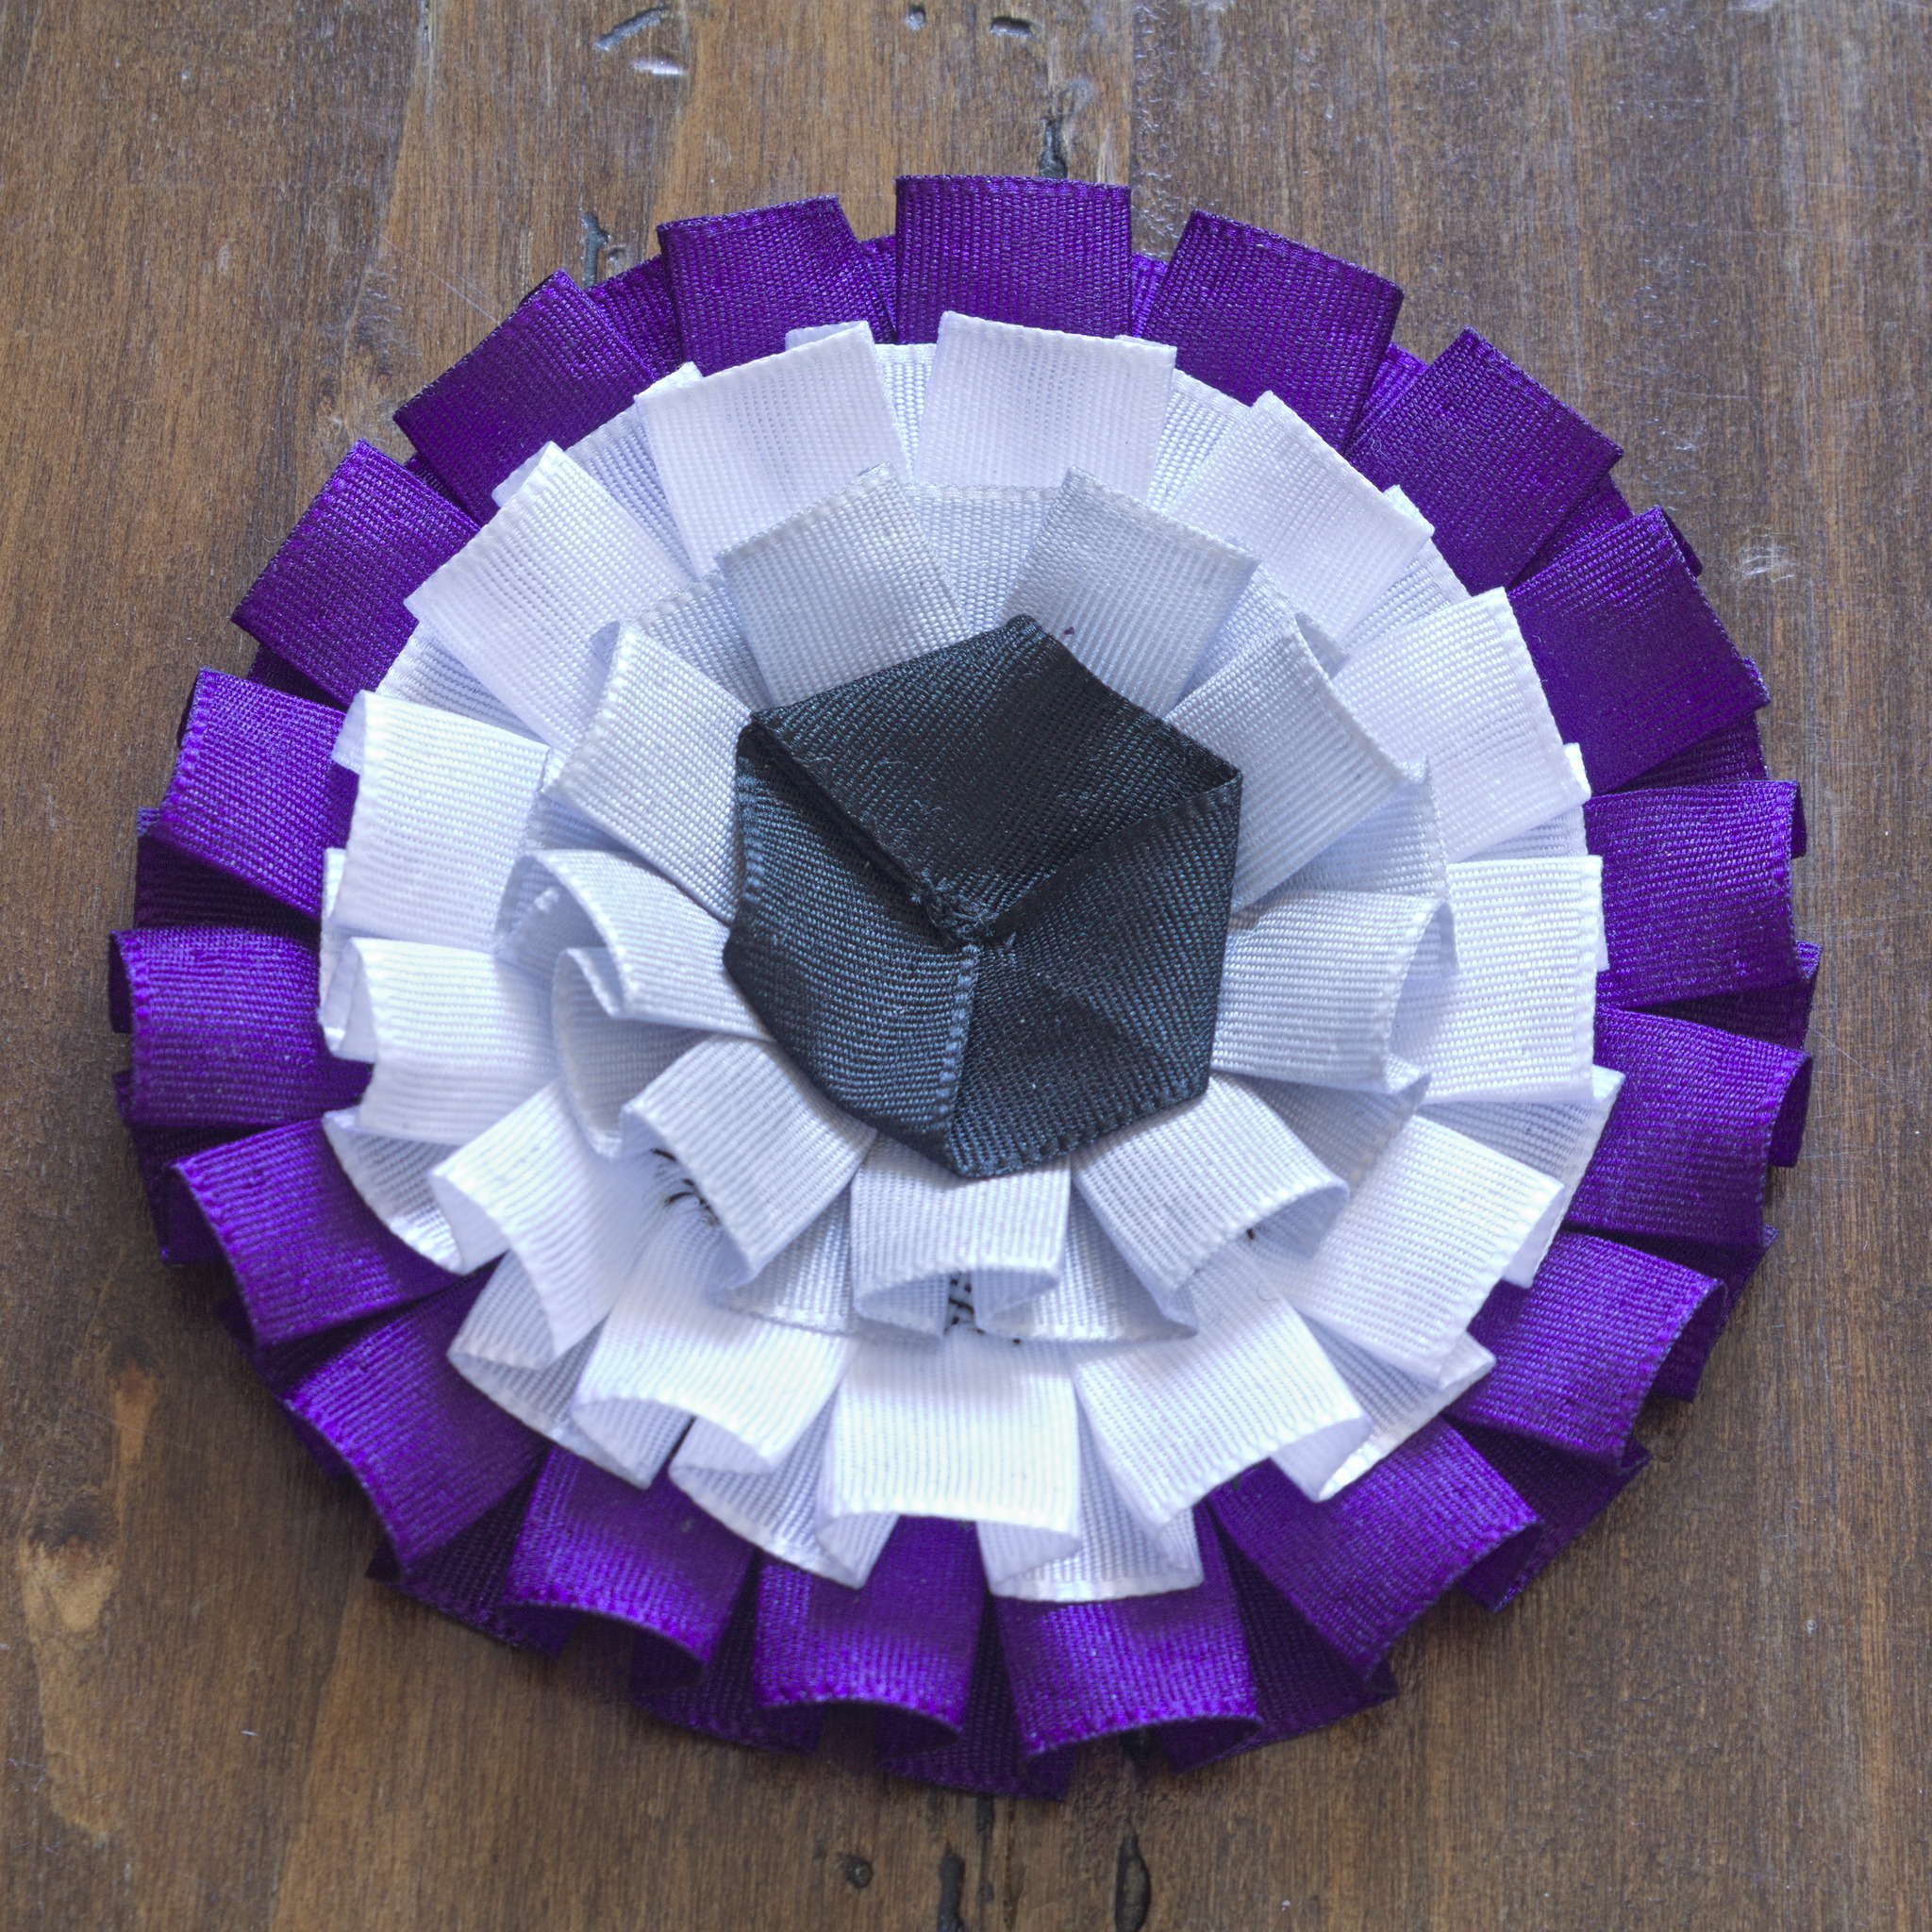
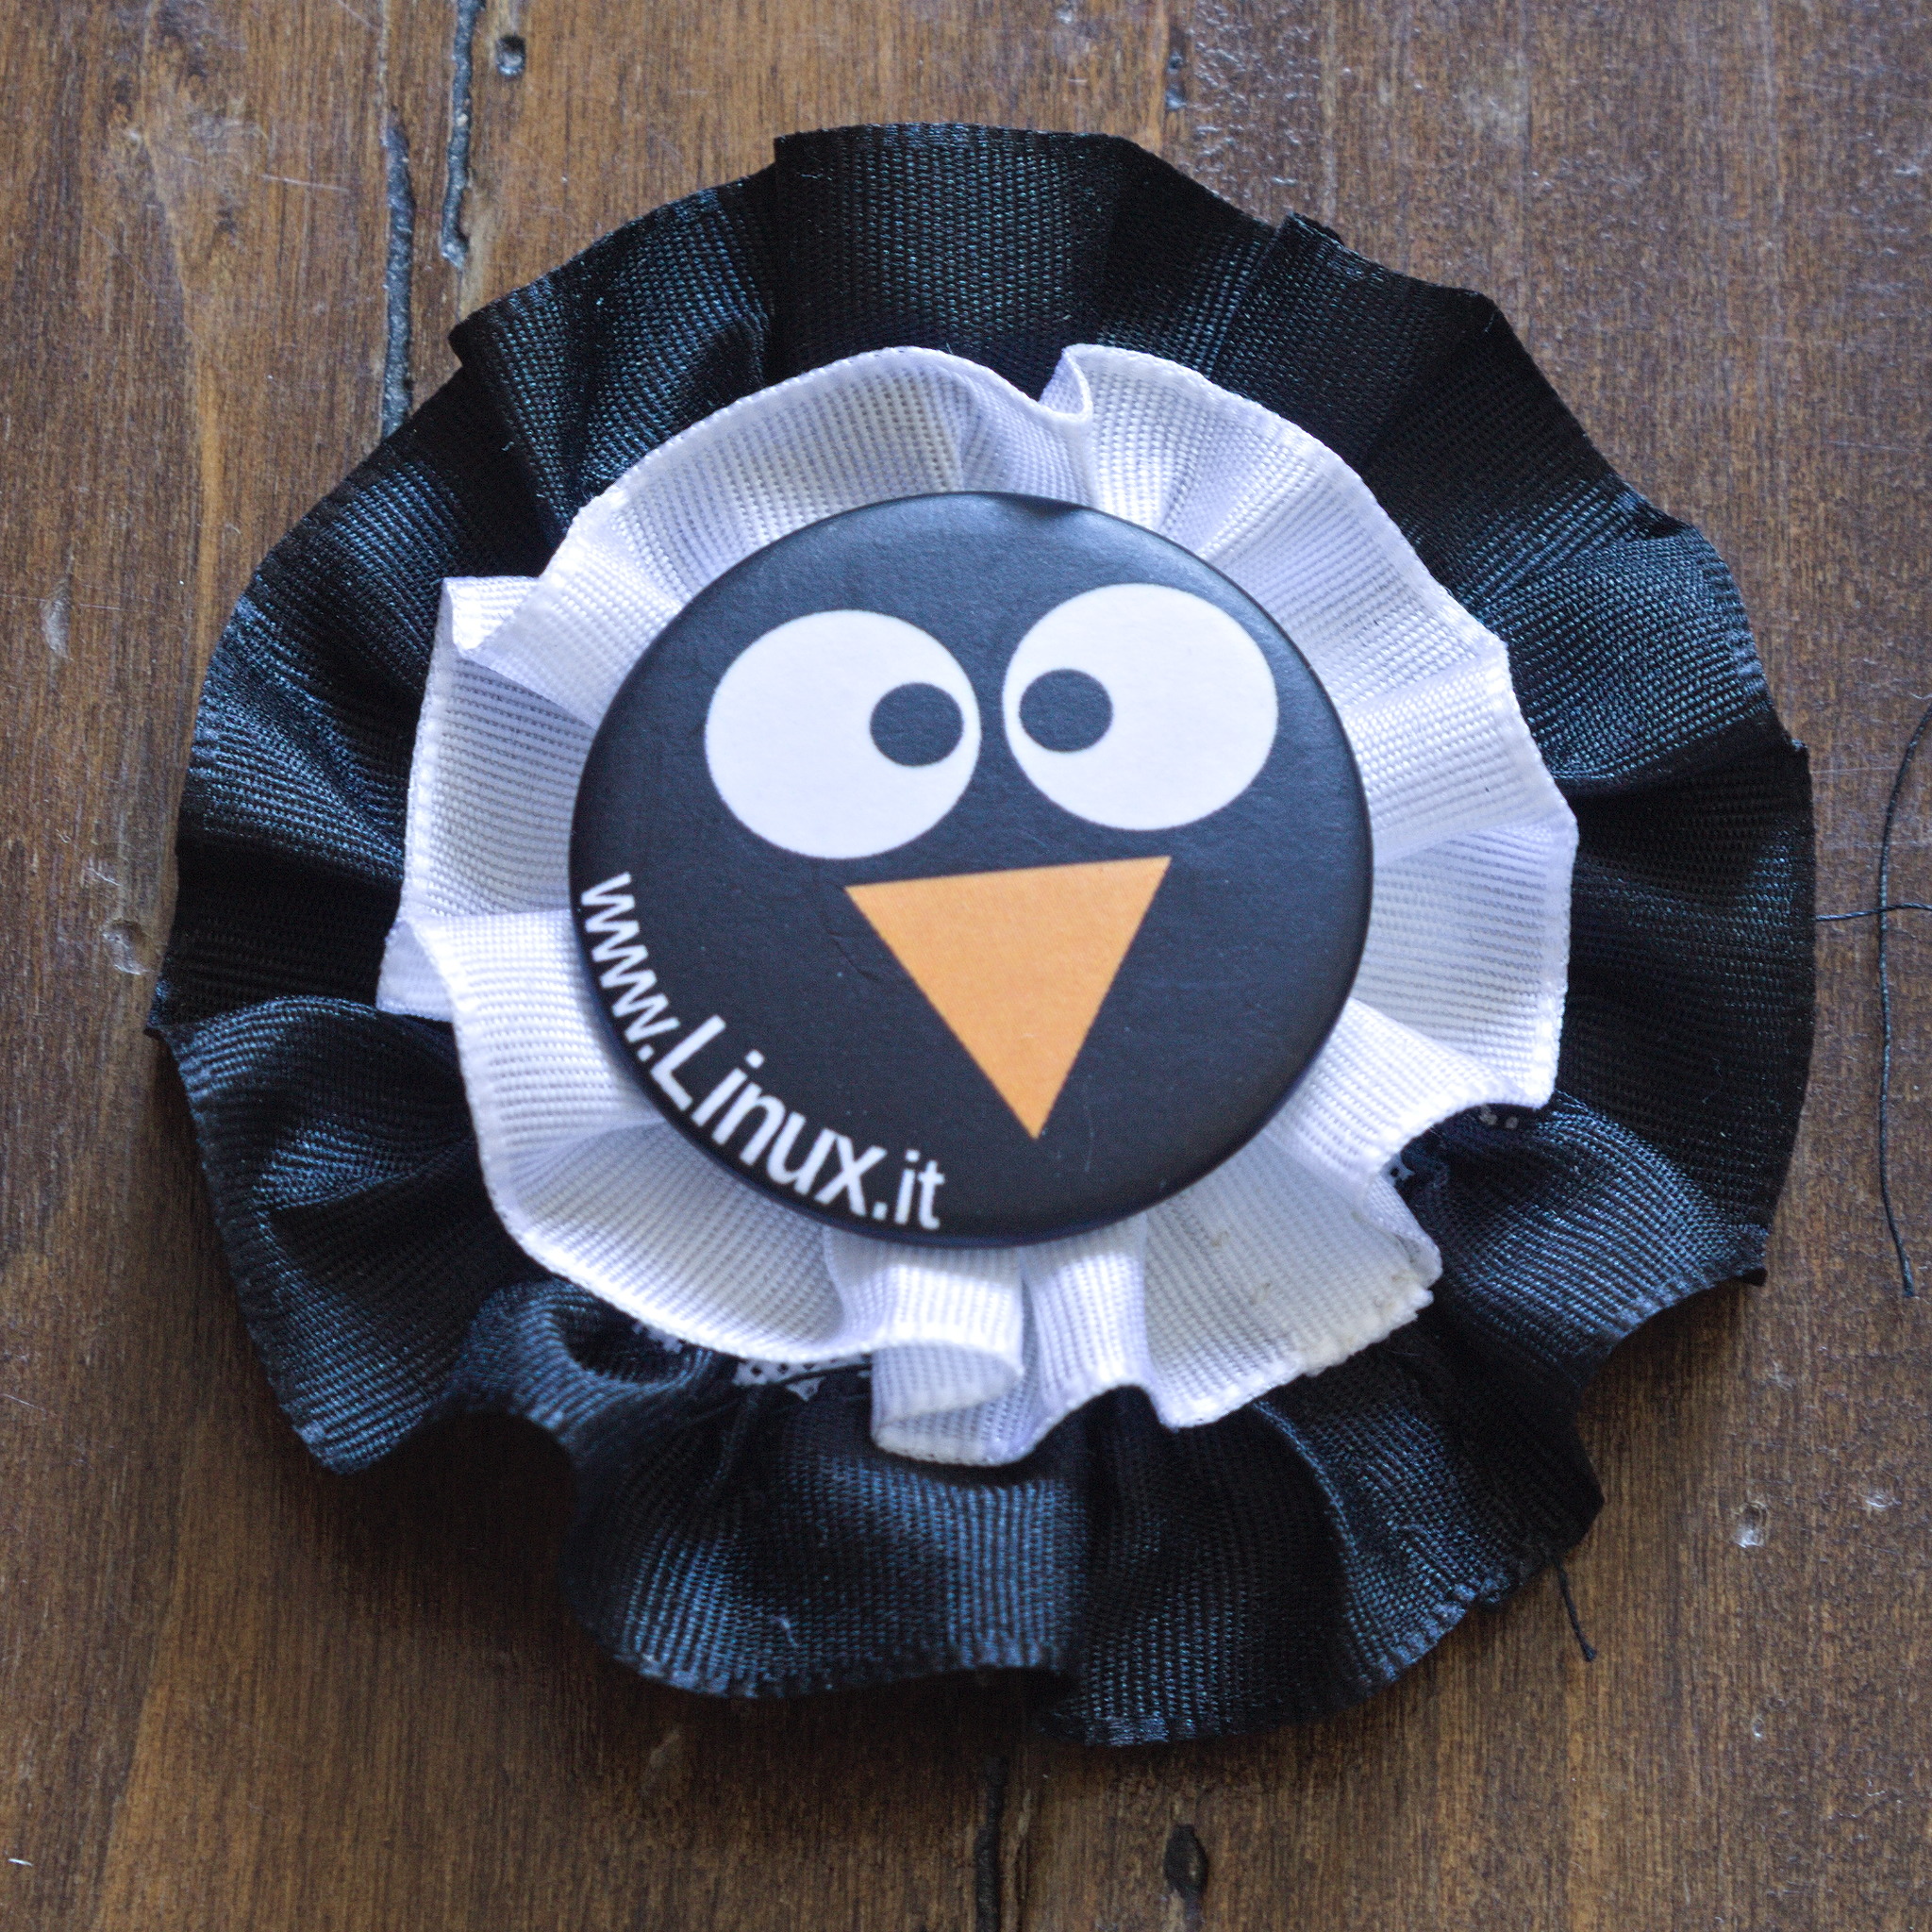
six cockades in black, grey, white, purple, in different sizes and with different centrepieces. One is only black and white and has a penguin pin in the middle. Earlier this year, I made myself a new hat (it will be blogged), and I wanted to put a nice cockade on it. So, I looked for suitable ribbons, and couldn t find any. I found some ribbon that looked passable, but the colours I wanted weren t available, so I set up the website to notify me, and kept working on the hat. Eventually the hat was done, the ribbon was still not available, so I decorated the hat with fake flowers from my stash, and started wearing it. And that s when I got notified that the ribbon was back in stock. By the time the ribbon arrived, I had decided that the hat looked better with the flowers, and project cockade was put on hold, possibly for a future hat. And then June came, and what could be a better time than that for a project based on flag colours? As I feared, the ribbon I got wasn t the best: it was a bit too stiff and plasticy, and not really usable for many other things. It did however work well enough for a cockade, and I decided it was a good chance to try different methods and designs, and then make another one to take pictures and publish step-by-step instructions. And that s the perfect recipe to find oneself surrounded by a somewhat unreasonable number of very similar cockades, I guess. A big cockade with four ribbons, starting with purple on the outside, and a black bead in the middle covering the centre of the black ribbon. The pleating isn't the most regular, and the black ribbon at the centre is almost more gathered than pleated. I looked around for instructions, and the ones that gave a result that was closer to my mental idea of a cockade were the ones by American Duchess, so on my first attempt I tried to follow those. I didn t have a cork board with a hole, so it was a bit fiddly, and the result was passable, but could have been better. Meanwhile I saw a forum post commenting on the above tutorial and that gave me ideas for a procedure more suitable to the tools I had. A cockade with tree ribbons, starting with purple on the outside, then white, grey, and a black bead in the middle that is a bit bigger than the one on the previous one. The pleating isn't perfect, but neater than the previous one. The second cockade I made was indeed more satisfactory, and I also started to experiment with making a center piece with ribbons, to cut down on the types of materials needed. On this one I also tried to add a pin backing, so that I could write instructions on how to do it in what I believe is a more stable way than simply adding it to the felt backing at the end. I m not sure whether the other ones will be tacked to a hat, and thus won t require pins at all, or if I ll just put them on some dress with pins hidden under the ribbon layers. A cockade with three ribbons, starting with black on the outside, then grey and white, and a flat pentagonal knot of purple ribbon at the centre. And then I was ready to make a third cockade, taking step by step pictures for my website, and I planned to start on it the next morning. Trenord had different ideas. Thanks to the combination of independent but complete disruptions on two nearby train lines, I spent the morning driving a couple of people to the nearest station that was still being served by trains, and then back home less than 10 minutes before I had to start working, which if you ask1 me was pretty homophobic of the train company. There was way less traffic than I expected, and I did enjoy the drive 2, but for various reasons it meant a significant delay for this post. Anyway, less than a week later than I had planned, halfway in June I managed to publish step by step instructions on my website, but I wasn t done with the project yet. Beside the fact that I still needed to finish sewing the backing felt to the cockades I had done, I also had a few ideas for more centrepieces made of ribbon I wanted to try. And this means that I moved on to another project that was already in progress (this one will also be blogged). A cockade with three ribbons, starting with black on the outside, then grey and white, and two squares of purple ribbon at the centre, forming a sort of eight point star. The ribbons are box pleated and this gives the cockade a bit more of a tree-dimensional shape. After I ve finished that one, at the very end of June I quickly made the last two centrepieces, taking pictures for the instructions, and in the next few days I also finished the cockades. A cockade with three ribbons, starting with purple on the outside, then white and grey, and an hexagonal shape made of black ribbon at the centre. The ribbons are again box pleated. This time, instead of plain pleats I tried to use box pleats, and I quite like the look they give, so if in the future I ll have a need for more cockades I may use again this pleating pattern. A cockade with just two gathered ribbons, starting with black on the outside, then white, and a linux.it pin in the middle with a black background and two eyes and an orange beak reminding of a penguin. For the last cockade I wanted to try two things: putting a pin in the middle as a centrepiece, and gathering the ribbons. For the pin, I found that the only one I had that had a colour scheme compatible with the ribbons I had was one with the penguin from linux.it, which had a black background, so I put black ribbon on the outside and white next to it for contrast. And gathering was done with a whipped gather with ribbons that were one and a half times the outer circumference of their slot, and looks decent enough, but I think I prefer the look of pleated cockades a lot. Maybe it would look better with a softer ribbon. Anyway, I think this is plenty of cockades for the time being, unless I get tempted by buying more colours of ribbon to make different ones. But I m not making an online purchase just for those. I am not.

  1. you probably shouldn t.
  2. also thanks to my partner who, on entering the destination town, told me to stop on the big, straight, two-way road with plenty of roundabouts to turn around, and went through the maze of one-way streets to the station by foot.

6 July 2026

Aigars Mahinovs: How to make a good group photo

Taking a good group photo consists of multiple aspects: I can say with confidence that nearly everything here comes from having failed to do these things right at least once, even on the latest attempts, so this is an ideal to reach towards, not something we expect to hit every time. The Goal The main goal of a big event group photo is capture both the moment itself and each individual person inside that moment. We want people, who were not there to see all the people involved and get an impression of what it was like being there. It needs to show the breadth and depth of people that make up this group, this project. And we want people who were there to be able to look back the next week, the next year or in ten years and remember - ah, yes, I was there, I was standing right there with this grin on my face next to this wonderful person and I was feeling great. Hardware Based on the goal we want to have high level photographic gear that is able to capture both a broad enough picture to encompass all the people and some of their surroundings to communicate the context (without undue distortions) and to deliver enough detail and resolution so that faces and facial expressions and underlying feelings of every single person in that group could be clearly seen and preserved. To both capture the context and minimise distortion the final picture should be just a bit wider than normal human field of view. That is about 50mm for a full-frame camera or 35mm for a typical 1.6 crop camera. You can go a bit wider if there are no better alternatives (as detailed in the scouting section), but be prepared that corners of the image will be distorted and not really usable (but we can fix that in processing step). Or you can go to unusual aspect ratios, like we did in Debconf 10. In the absence of a 100MP+ camera, you will need to be stitching together multiple frames to achieve resolution high enough to have enough pixels-per-face to see emotions clearly. This means that the photos you will actually be taking will be tighter than the overall field of view mentioned above. Still, a higher resolution camera body is preferable - nowadays 24MP-32MP cameras APS-C provide a good compromise between resolution and price, but 45-67MP full-frame cameras also exist on the market. Assume that we will be shooting in a bright environment, so most likely with quite low ISO settings, that means that high-ISO noise characteristics of more expensive cameras will not really play a role here. You will also not need very fast burst modes, even manual speed of one frame per second is sufficient. You will also want to get as much detail as possible out of your lens, and this is the most important part. You can do amazing work in all other steps of the process and have a great camera too, but if you pair it with a lens that is not sharp, then the end result will be disappointing. You want the lens that is sharpest corner-to-corner when stepped down to about f/8-f/11, that you can get for your system. You also want that lens to be about 85mm full-size sensor or 50mm for 1.6 crop size. Luckily that kind of range is also a great range for optical design and sharpest lenses are typically available in exactly these kinds of sizes. You absolutely want to have a fixed focal length lens, not a zoom lens. Even profession grade zoom lenses often deliver worse image quality compared to fixed lenses that cost less 1/10th of their price (when shooting in the same focal length). Newer design lenses are better than older lenses - optical design, coatings and precision manufacturing have advanced a lot over the decades. Retro look is great for mood, but not as good for actual resolution and clarity. You don't need to overpay for most expensive lenses because those often only improve image quality on lower F-stops. To encompass the whole group we will need to shoot at f/8 and in bright light, so the extra benefits of those f/1.2-capable super expensive lenses will not come into play here. We will have no use for a flash here. A tripod will be too restrictive when rapidly repositioning the camera between different parts of the panorama shoot. But a monopod might help with stability - I have not tried that myself, however. For my last photos I used a Canon EOS R7 (32.5MP) with Canon RF 50mm f/1.8 STM lens and considering an upgrade to Sigma 56mm f/1.4 DC DN for the next time. Scouting Scouting a good location for the group photo is another big chunk of a successful picture. The critical piece of the puzzle is lens-to-face distance. In order to keep everyone's face in-focus and have enough resolution on the farthest faces (without making nearest faces truly massive) we want to do everything possible to reduce the variance in lens-to-face distance - to reduce the difference in distance between closest and farthest face. The most effective way to do that is to have the photographer climb higher. To see this in action on the Debconf photos, compare Debconf6 (very high camera position, group on level ground - good) to Debconf10 (camera not too high, group on stairs, still good) and to Debconf17 (camera could not get high enough and the group is on flat ground - not great). Even the Debconf25 photo was suboptimal from this perspective. The Debconf23 photo was a very good example from the recent years - good height and also the group was positioned in a semi-circle so there were no people directly in front and very near to the camera. So you are looking for the highest point you could get to (even if that requires a special permission of key or a ladder) with a field large enough to fit the whole group comfortably. How to check that? Normally I simply take a photo from the top of the whole area and note down from there where the extreme corners of the group could be and still be fully seen in the shot - not blocked by trees, buildings and shadows. Then I go down and measure that space. Rule of thumb being - people in one horizontal line can stand 1 normal length step from each other and two horizontal lines can be half a step from each other vertically. So I can just measure a rough rectangle in steps, multiply the sides, multiply that by two and I have the rough number of people that can fit there for the photo. Once you have a candidate location or two, it is important to check them at the same time-of-day as you plan to do the photo (see organization section for that). You want to make sure that the whole area of the group is in the same illumination - if half of the group is in the sun and half in a shadow, then you will be having a very bad time later. The absolute ideal positioning for the group photo is to have everyone be in shadow, but still have enough bright skies and bright buildings in front of the people to give good illumination of the faces. Worst you can do is have the sun be behind the people (so all the faces are really dark) and second worst is have the sun be directly in front of the group, so that the faces are very well illuminated, but everyone's eyes are closed because they are being blinded by the sun. And sometimes all you can do is pray for some light clouds to provide for even and dispersed light. Debconf23 was very lucky that way. Another consideration is to how people are going to get to that place. You need to consider accessibility needs of people (it is ok, if it takes more effort or time, but it needs to be organized and communicated well in advance). And you need to consider how the big masses of people will be getting there - how to tell people where exactly it is and how to get there from various locations where people might be hanging out during the event? Having an alternate location indoors might be necessary if the weather report for the next days is not sufficiently predictable. We had to use that contingency in Debconf9, for example. Organization It's hard to take a good group photo if half of the group does not show up or is too late, so this needs some organization to happen smoothly. First of all you need to choose date and time for the photo. The photo does not take too much time from the schedule of the event and can be squeezed in after all the other events are already scheduled. In fact I prefer that as it allows you the flexibility of choosing the date based on weather conditions and time based on light and shadow conditions in potential photo spots. You don't want to choose the daytrip day as most people will be away and return times are not really predictable. You do not want to choose the morning after Cheese and Wine party for obvious reasons. First day and last two days are also sub-optimal as some people arrive late and some leave early for various personal reasons. Also you don't want it to happen just before Cheese and Wine either because then you'd have very little time and clarity to do the processing of the image on the same day. For timing, the best way, in my experience, is to schedule the photo directly after the end of talk sessions before a meal break - lunch or dinner. Typically in the Debconf schedule there are 2-3 daily breaks planned, say for Debconf25 there was lunch, afternoon break and dinner. Talks are planned to end ~10 minutes before those breaks (and meals) begin, so for example, afternoon break starts at 16:00 and all talks in the previous block end at 15:50. In such a case just schedule the "Group photo" event from 15:50 to 16:05. This gives people the info to go there directly from the end of all talks and that they will have sufficient time for break/meal afterwards. Do not forget to specify the location (as exactly as possible) in that event entry and make sure to post it at least two days in advance. People often want to wear something specific for the photo and thus need to know about it in advance. This also makes sure that people do not make alternate food plans for that specific break and don't leave the venue. Announce the date, time and the exact location as wide as possible, don't be shy. Announce and discuss mailing lists, IRC, Signal, Telegram, make sure the front desk knows in case anyone asks in-person, ... Check that it is again included in the announcements email on the day preceding the photo date. When the date has arrived, it is a good idea to check in early with people with special mobility needs to make sure they know where to go, how to get there and how much time they will need to be able to get there on time. As the final round of talks before the group photo is starting up, it is time to recruit "runners". I've had great success with this technique. The idea is pretty simple - for each room where people congregate (talk rooms, hacklabs, cafeteria, outside hackspace, front-desk, ...) go there and choose one person. You want to choose a person that you will recognise and remember among everyone else in the group, either because of who they are or what they are wearing, whatever works best for you. If they agree to help, instruct them to: "at end of talk, announce that the group photo happening now and the location, herd people towards the photo location, be the last person out, make sure there are no stragglers from this area behind you, when you arrive to the photo place I will assume that everyone else from this room is also now there, when you are there catch my attention and show this sign so I know for sure that it is all good and make sure that I did see it from you". With that sorted out all you will need to remember is how many runners you recruited and how many have reported in to figure out if everyone has now arrived or if we still have to wait for someone or some group. Then you will only have one last point of organization left - shaping the crowd into a group. People will not know what your vision for the group photo is, so you will have to give clear and LOUD instructions on where people should not be standing. Use clear, large gestures to support your words. You want to compact the group, have the people that just joined in the last moment and are standing to the side come deeper in and join the crowd. Have any holes in the middle of the crowd filled in. Forming a semi-circle instead of a blob helps with averaging face-to-lens distances. Make sure people are not in unexpected shadows. Make sure carried objects, like umbrellas of flags do not cover the faces of other people. Take the time to look at everyone face to make sure there are no people hiding behind someone's shoulder - typically they are not aware that their face is in fact not really visible. If there are such people, call them out and point directly at them and encourage them to step forward, if they wish to do so. You are the only one seeing the final picture now and only you can correct it before capturing the moment. So a few extra seconds here are worth taking, even if 300+ people are standing in scorching heat and waiting on you. When you are happy with what you are seeing, make sure to tell people clearly that you are now about to take the pictures and again remind them not to move and explicitly not to turn their heads to the side until you are done (this is the source of most of the extra work in processing). Be very loud and clear and make sure you have everyone's undivided attention before you start saying the important stuff. When done - say so. There will be other groups that will want to also have a photo taken after the main group is a bit more dispersed, so don't run away. Typically at least the T-shirt group will want a picture and also all the organizers. Final bit of organization during the group photo shooting itself is the sneaky self-insert. You may choose not to bother with it, or do it in the simplest way, like I did in Debconf6, but if you really want to blend in with the crowd, you need to have someone else take a photo of you in the exact same location at the same date and time from the same location. So you should already during shaping the crowd decide where you would fit in, it is easiest to blend in at the back of the crowd and to one or other side, so that it appears like you are just standing behind the shoulders of a couple peoples. Remember that spot - it is easiest if you stand in the exact same ground spot when your photo is taken. Just go down, recruit a volunteer to take your photo, make sure the settings are fixed to the same ones as for the group photo shots and have them take a handful of shots of you - one of you centered in the camera frame and a couple more with you more towards the corners of the frame. This distortion from being off-center in the frame may be important later. Preparation In addition to preparing the crowd for the photo, you also need to prepare yourself and the equipment. Make sure you have dusted your camera sensor and cleaned both inside and outside glass of your lens. It is usually a good idea to remove any filters from the lens. Install the hood, if that could help with blocking the sun flares. Make sure you have the right lens and that you have installed the right lens. For fixed settings I typically shoot in JPEG with RAW being there more like an emergency backup. The extra dynamic range of RAW could be used, but it is really complex to do that in combination with image blending and it is hard to get right, so I prefer an all-JPEG workflow and fix the dynamic range in the scene itself, before shooting. For Canon I am using the Standard profile that boosts the color saturation and sharpness a bit as I just enjoy that look and find it hard to get anything significantly better from RAW data even with a lot of effort. In any case make sure you have enough space on the cards to take at least 100 images and that you have a full battery. Do not use high speed burst setting because it is then too easy to take too many pictures at the start of the sequence and be stuck with your camera still in "Busy" state writing big RAW files to slowish SD cards and not allowing you to finish the full picture rapidly. You want to have the shutter speed at at least 1/100th of a second to prevent blur from both your hand movements and also from people in the shot moving around a bit (image stabilisation will not help you there). And you want to have the aperture to be around f/8 - lower apertures risk people in front or behind falling out of focus, make the lenses look less sharp. Higher apertures also start to become less sharp due to diffraction effects above f/8. ISO should stay as low as possible, ideally at ISO 100, but if there is not enough light then upping the ISO to 400 would be the first step that I would try to do and second would be decreasing the aperture to f/5.6. If there is too much light, then increasing the shutter speed should be the safe thing to do. As people start to arrive into the shooting location - check the exposure and nail down the settings, ideally in manual mode. Consider that left side could be a bit lighter or darker than right side. Err on the side of making the picture a bit too dark as there is more depth to darkness before cut-off compared to clipping on the high end. However, do not trust the exposure detection, instead take a picture and look specifically at skin tones in faces of people that already are standing in the photo area. Faces are the key bit and the exposure needs to be adjusted just to the faces and ignore darker of lighter clothing. Do some test shots and find settings where faces look not too bright, but also not very dark and fix those settings in manual mode. Now you are ready for the action. Shape the crowd, check the faces and the action can start! Execution During taking of the group photo you want to finish it fast, but at the same time you have to take the time to make it right. If you hurry too much under pressure, you risk being left with unusably blurry images and the whole effort wasted. Having already prepared and verified the manual settings makes it easier. When you are taking pictures, you have to remain as still as possible - even at very high shutter speeds even slow hand movements are still bad for image quality. So think of the movement as of biathlon athlete shooting the very middle of five, very separate targets - take a burst, reframe, then steady up for a second and only then take the next burst. 3 frames per burst are sufficient. 90% of the time the very first photo of a burst will be best. As you move from frame to frame, aim for just a bit more than half-frame overlap. This will give the opportunity to skip frames if all is good, but also have backup coverage of every face in case of problems. Proceed systematically, I typically start off on the top left of the crowd, then go right until the end of the line, then shift down half a frame and go left until the end and repeat until I am done with the crowd. After that it is very helpful to also immediately take photos of a "frame" around the whole crowd. Stitching process often distorts the frames in weird ways that leave holes in the resulting image that you can fill if you have a wide frame around the crowd. It is possible to compensate with creative cutouts in the final image (like Debconf9), but the more framing room you make, the more flexible you will be able to be with cropping of the final photo. The frame also gives you the opportunity to capture more of the context of the place and space. As an example, Debconf25 group photo in the end consisted from 9 images + 1 for sick people + 1 for me. I ended up missing the framing shots for bottom left, top left and top right corners. To get there I took 68 images. And in some years it was more than a hundred. Processing This part might be less stressful than taking the pictures from intensity perspective, but it lasts longer. Depending on you luck, skill and perfectionism it can take anywhere from 3 to 9 hours of work to complete. Before you start, however, you should first request things that you will need for other people. This can even be done before taking the actual group photo, but usually I forget. To finish the photo you will need three things: The first two you should be able to get from the respective organizers. The motto is harder. I typically try to ask the current DPL to come up with something describing the current mood of the project or of the event, but it is rare that it is that easy. Most of the time I came up with something as I was editing the photo and reflecting on what was the mood, the feeling, the mojo of this conference and of this year was like. Bend that around a recognisable phrase or expression, make it a bit more insider-relevant and you are on the right path. Some years this was the hardest part. For the panorama stitching I will describe the workflow that has served me good for years, but maybe there are better ways possible nowadays. Feel free to let me know! First I would save all photos taken and select one sharpest photo from every burst. Next I would select the minimal number of photos that appear to be covering the entire crowd. The fewer images you use, the better in the end because the most quality problems crop up in the areas where photos are getting stitched together. Fewer seams leads to fewer issues. Open Hugin (you will also need enblend and enfuse installed) and import your minimal set of images into it. Click the "Align" button and wait a while - the processor will be trying to figure out keypoints in each image and then try to match these points between the images to try to fit them all together into a single projection. To do that it will distort the images. This is the trial and error process part. You may need to add, remove or replace images to get the stitching to work or to work better. You may want to add more of the frame images to fill the ragged holes around the image. After initial alignment, go to "Move/Drag" tab and move the image a bit up in the projected field of view and make it a bit more central visually. That will help a bit with the distortions in the near-by people and people in the corners of the image. In the "Crop" tab set the initial crop - leave it generous, you can always crop more in later steps. Do not be afraid of leaving in sizable chunks of black homes, empty skies or grass. All of that can be filled in later as well. Go back to the "Assistant" tab and click "Create panorama". It is good enough to have JPEG output at 100% quality using exposure corrected low dynamic range output option. Make sure to check the "Keep intermediate images" option. This will not only generate the final, merged panorama, but also keep around the individual images after perspective correction and exposure blending steps. These are critical for fixing blending error in the next step. You might need to go back a forth a few times with a different sets of source images, maybe adding some image between other two, maybe removing another to reach a better starting point. The key part to pay attention - how many ugly stitches are there in the image. Check every face, the blending algorithms do not recognise faces and sometimes try to stitch one face from two or more images creating very weird effects. They can be fixed in the next step, but it is rather hard manual work, so the fewer such faces are in the blended image, the less work you will have. In some years I've managed to find a combination where all faces were good and in other years I had to manually fix 13-15 faces. Do not try to blend the extra pictures (like with you or with sick people) into the main panorama with Hugin - it will get very confused with the parts of the grass that it is able to see where other people were standing. The next is the final processing in GIMP. Think of it like a large and complex project - do as much as possible in separate layers, save often. Fixing wrongly stitched faces and also putting yourself into the photo are very similar activities in the end. Just the scale and the source differ. For yourself you just cut out yourself (upper torso is enough) from the separate photo. For corrupted face, choose one of two intermediate images that the Hugin created where the face is transformed, but not yet merged (with a different version of itself). In either case crop the photo to roughly the interesting size and put roughly in the right spot as a separate layer on top of the group photo background. Reduce the opacity of the small layer to 30-40% and zoom in to 400%. With that it is much simpler to position the layer with pixel precision. Then all you need to do is add a layer mask to this layer and paint it just right. Basically in layer mask black means transparent and white means non-transparent. So you need to just make everything that is you have white mask and everything that is not you have black mask. And smudge the border a bit with finger tool or blur to make the transition smoother. Easy to say. Hard to do. This is what takes most of the actual work hours in post-processing. You might miss someone. I am sure Phill is just thrilled to see me in the very middle of the Debconf25 final picture .... But do try to fix them all. Use large, sweeping geometric figures to cover up black holes, empty grass fields and other sub-optimal corner features. And then use that newly created free space to put in a large version of the logo of this years conference, decently sized motto and slightly smaller invitation to the next years conference. Do not forget to add a copyright and license statement somewhere in the corner in smaller, but still well readable font. I am using a text like: "Photo by: Full Name, Email: fullemail@debian.org, License: GPLv2+ or CCv3-BY" This ensures that this image may be used in any press coverage (with basic attribution) and also can be included in any GPL-licensed software, if that ever comes up. The same statement is also in the metadata of the image file (see Image-Metadata-Edit metadata in GIMP) along with information that states that this is "Debian Developer Conference Group photo, City, Country, Year". Image->Image properties->Comment is another place where GIMP hides this EXIF information. For ease of use, in addition to a full-resolution image it is also useful to make a lower resolution version that would still fit on a 4K screen at full resolution, so about 3840px wide. Some photo hosting services set other limits for image size as well, so it might be needed to scale the image down below 100Mpix to upload it to Google Photos, for example. Publishing So, it is finally 1AM and the group photo is ready! How do you push it out to people? Well, in all possible ways and places. Again - don't be shy, people do really want to see it. Push it to whatever you use for your shared photos. Push it to Debconf shared git (note that this is GIT-LFS repo, make sure you know how to add content to the LFS specifically). All permanent links to that in GroupPhotosAll wiki. And then send those links to IRC, Signal, Telegram groups, debconf-announce mailing list. Publish it in your blog and push that to Debian Planet. Push it in Threads, Bluesky and Mastodon. Send an email separately to Debconf orga team. And one to Debian Publicity Team so they can put it into the Debian Home Page and push via Debian micronews accounts. And that is about it. Now you can go back to enjoying the rest of the conference. Or running around doing other things that you think need to be done. It's up to you. You did it. This moment will remain with people for a very long time. And you helped. Questions? Feedback? Just ask here or here.
5 July 2026

Dirk Eddelbuettel: Rcpp 1.1.2 on CRAN: Usual Improvements in Semi-Annual Update

rcpp logo Team Rcpp is excited to share that an brandnew new version 1.1.2 of Rcpp is now on CRAN, has also been uploaded to Debian, and has already built for r2u and r-universe; Windows etc builds at CRAN should follow in due course. Rcpp has long established itself as the most popular way of enhancing R with C or C++ code. Right now, 3236 packages on CRAN depend on Rcpp for making analytical code go faster and further. On CRAN, 13.4% of all packages depend (directly) on Rcpp, and 61.4% of all compiled packages do. From the cloud mirror of CRAN (which is but a subset of all CRAN downloads), Rcpp has been downloaded 121.6 million times. The two published papers (also included in the package as preprint vignettes) have, respectively, 2263 (JSS, 2011) and 471 (TAS, 2018) citations, while the the book (Springer useR!, 2013) has another 742. The is the second update in the 1.1.* series which had, among other changes, switched to C++11 as the minimum standard. This release continues as usual with the six-months January-July cycle started with release 1.0.5 in July 2020. Interim snapshots are always available via the r-universe page and repo. We continue to strongly encourage the use of these development released and their testing we tend to run our systems with them too. Having said that, we would like to reiterate that we strongly object to the upstream R release and change management which in this 4.6.* cycle made several abrupt changes forcing packages which consume header files to make very abrupt change. Rcpp, just like numerous other CRAN packages demonstrates that API changes can be undertaken responsibly in a managed manner which allows for transition periods followed by possible warning periods, deprecations periods and finally (but only at long last) errors. What happened here is a speed run to the final stage of forced errors. Uncool and irritating for something as widely used as R. This forced us to make an interim release 1.1.1-1.1 even though we have of course had a policy of always keeping properly tested, installable, and error-free releases candidate version in the main repository branch and hence available via R-universe tested packages for all relevant platforms, and even via binaries for most (including Ubuntu LTS). It would be nice if R Core found a way to take advantage of this. Maybe development cycles, running apart for a year as they do for R, should also include selected packages. Once again I am not attempting to summarize the different changes. The full list follows below and details all these changes, their respective PRs and, if applicable, issue tickets. Big thanks from all of us to all contributors!

Changes in Rcpp release version 1.1.2 (2026-07-01)
  • Changes in Rcpp API:
    • Use of execinfo.h is again conditional to avoid build complexity (Dirk in #1445 addressing #1442)
    • An internal state component for Datetime is now int (Dirk in #1448 and #1449 fixing #1447)
    • Three new (in R 4.6.0) attribute accessors are used conditionally (Dirk in #1450 closing #1432)
    • An UBSAN error in the Sugar-based NA comparison has been corrected (I aki in #1453 fixing #1452)
    • Treatment of Inf outside of integer range in Sugar function has been corrected (I aki in #1458 fixing #1455)
    • Integer overflow protection has been added for sugar functions (I aki in #1457 fixing #1454)
    • The parent environment is now accessed via R_ParentEnv (Dirk in #1460 fixing #1459)
    • Change to returning dataptr again for better handling of empty vectors (I aki in #1462 fixing #1461)
    • Undefined behavior errors in use of ListOf proxies have been addressed (I aki in #1464 fixing #1463)
    • Under newer R version, R_UnboundValue is no longer used (I aki in #1466 fixing #1465)
    • New R API access point R_getRegisteredNamespace() is used with current R versions (Dirk in #1469 fixing #1468)
    • The Nullable::as() exporter now uses an explicit cast to the templated type (Dirk in #1471 fixing #1470)
    • A memory leak in the variadic Rcpp::warning() template has been fixed (Kevin in #1475 fixing #1474)
    • The Nullable::operatorT() has been added as a 'opt-out' (Dirk in #1477 with coordination in #1472)
    • Add templated integer-index overload for operator[] on small systems such as WASM (Jeroen Ooms in #1482)
    • The attribute accessors in AttributeProxyPolicy no longer rely on get__() (Kevin in #1484 fixing #1483)
  • Changes in Rcpp Documentation:
    • Reference in the bibliography used by the package vignettes have been updated.
  • Changes in Rcpp Deployment:
    • Excute permissions are set consistently on scripts with shebangs (Mattias Ellert in #1467)
    • R 4.5.* has been added to the CI matrix (Dirk in #1476)
    • Three nag messages issued when obsolete build flag accessors are used now show Rcpp::: (Dirk in #1480 fixing #1456)
    • Reference GitHub Actions have been updated to their current versions (Dirk in #1481)
  • Non-release Changes:
    • A non-release hotfix 1.1.1-1 used by CRAN accommodates breaking changes to the API in R 4.6.0. It would be nice to have the same level of release management in R itself that CRAN expects from us.

Thanks to my CRANberries, you can also look at a diff to the previous interim release along with pre-releases 1.1.1-1 and 1.1.1-1.1 that were needed because R-devel once again sudden decided to move fast and break things. Not our doing. And there also should not have been a need to two such uploads but it was amateur hour all around. Questions, comments etc should go to the GitHub discussion or issue section, or the Rcpp list. Bugs reports are welcome at the GitHub issue tracker as well. GitHub offers decent search for issue, pull requests and discussions; as many topics have been covered it is worth checking as well.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

Birger Schacht: Status update, June 2026

Debian Related Work
  • Uploaded wofi 1.5.3-1 to unstable
  • Uploaded wob 0.16-1 to unstable
  • Uploaded labwc 0.20.0-1 and 0.20.1-1 to unstable; these releases come with support for wlroots-0.20, which made labwc reenter testing
  • Uploaded swaylock 1.8.5-2 to unstable to make it use the common-auth directive of pam (seeh #1140096)
  • Uploaded swayimg 5.4-1 to unstable
  • Uploaded wayback 0.3-2 to unstable, which was waiting in experimental for a reupload and I had forgotten about it; also fixed a typo in wayback upstream
  • Uploaded xdg-desktop-portal-wlr 0.8.3-1 to unstable

DH Related Work The search app I was working on last month was still a focus in June. I refactored the data model a bit and made it simpler. I stumbled over the Python Koans and Koan 15: The Invisible Ink gave me the idea of using unicode normalization when indexing the items. I released a couple of bug fix releases for the APIS framework, namely 0.64.2, 0.64.3 and 0.64.4. I also release 0.65.0 which is one step further in dropping support for the legacy apis_entities app. When the search module is merged it will give way for removing the last bits of the old cruft to be removed. During a regular dependency update session I looked at the changes in the dal dependency. After a long time with no commits, the project suddenly had a lot of commits co-authored by Claude and then released a new major version with a regression. Given the state of the project, we decided to keep using the previous release for now and look into replacing the dependency with an HTMX based solution. I implemented a POC for one of the plugins we develop and it was actually pretty easy. I also managed to combine the autocomplete approach with a multi-select form field, based on this blog post. In the PFP project I finally merged the stats endpoint which give statistics about the named graphs that are used as data sources.

Other I attended BSidesVienna 0x7EA but it was on one of the hottest days this year so far so I left after a couple of talks.

2 July 2026

Joey Hess: no LLM code in dependencies

I've spent about 100 hours of work over the past month to make sure git-annex can build without dependencies that contain LLM generated code. At least so far. https://git-annex.branchable.com/no_llm_code/ Needing to review a program's whole dependency tree on an ongoing basis is apparently what programming has come to? I've found some real stinkers. Large LLM generated changes being reverted in the next release without any explanation. An incoherent 1489 line commit message with 10,000 lines of changes to a 26,000 LOC code base. A LLM prompt to copy code from another project that seems to have only avoided being copyright infringement due to luck. I now have additional information about the quality of dependencies which will surely influence future decisions. As far as I can see, that's the only positive benefit of this work. I realize that I am probably trying to hold back the tide at this point. That appears to be why Software Freedom Conservancy punted, and I doubt that the FSF will do any better. As these dominos fall, I am reconsidering my participation in these communities. But I continue my work and support my users. It may seem easy to prompt a LLM with

Add fourmolu config and restyled neat format a module
And commit the result and call yourself a 10xer. But please consider the broader impact of your actions. (In the above case, that project lost my further collaboration on it.)

Matthew Garrett: Preventing token theft

When you log into a service you re given an authentication token. Each further request to the site includes that token, allowing the server to figure out who you are and ensuring that you have access to your data. Depending on site policy, this token may either be stored in memory (and so vanish if you restart your browser) or disk. The token is the proof of your identity. As far as the site is concerned, anyone with your token is you. These tokens may be traditional browser cookies, but they may also be stored in either site local storage or (if you re not using a browser) in some other storage location. In recent years we ve seen infostealer malware (like LummaC2) gain the ability to exfiltrate user tokens, allowing attackers to gain access to the user s data without needing to retain access to the user s machine. This attack is viable even if the site has strong MFA requirements, so passkeys don t help. Encrypting the tokens on disk doesn t prevent the malware from scraping them out of the browser s RAM or obtaining whatever key is used to encrypt them. This feels like a pretty hard problem to solve. But that hasn t stopped people from trying! Dirk Balfanz wrote an IETF draft describing a mechanism for using self-signed certificates for TLS authentication. This uses the mutual authentication feature of the TLS protocol that requires both sides prove their identity to each other. In regular TLS, the remote site presents a signed certificate that tells you who it is. When performing mutual authentication, you then present a certificate to the remote site telling it who you are. These client certificates are largely unused outside enterprise environments because they re a huge pain to deploy. It s not so much that this has sharp edges, it s that it s entirely made of sharp edges. Managing certificate deployment to your devices is hard. Browsers get confused if the certificates change under them. You have one certificate and it lives forever, so sites you present it to can track your identity. Users are prompted to choose a certificate to authenticate with, and if they pick the wrong one everything breaks and is hard to recover. I ve deployed this and I did not have a good time. But Balfanz s idea was simple. Rather than require certificates to be deployed, browsers would simply generate a certificate on the fly. The goal wasn t to prove the device or user s identity in any global way - but it would associate a TLS session with a specific certificate. You could then, for example, include a hash of the certificate in the cookie, and if someone tried to use that cookie without presenting that certificate then the cookie could be rejected. If the browser used a hardware-backed private key for the certificate then it would be impossible for an attacker to steal it. Sure, you could still steal cookies, but you wouldn t be able to use them. This was written almost 15 years ago, and seems simple, elegant, and functional. It didn t happen. Part of the reason for that is that, well, it wasn t quite so simple. One problem was privacy related. Cookies are only sent after the TLS session is established, so anyone monitoring the network doesn t know anything about the user identity. A naive implementation of this approach would have meant the client certificate being sent before session establishment, and now user identity can be tracked (no longer an issue if this was implemented on top of TLS 1.3, but this was a log time ago). This was avoided by reordering the client handshake, but that meant having to modify the TLS specification and implementations would have to be updated to support this. Another was that figuring out the granularity of the certificates was difficult. You d want to use different certificates for every site to avoid them effectively becoming tracking cookies, but you need to provide the certificate before cookies are set, and you don t know what origin the site is going to set in its cookies. If you generate a certificate for a.example.com and a different one for b.example.com, and a.example.com sets a cookie for *.example.com and includes the certificate you used for a.example.com, that cookie isn t going to work on b.example.com and things are broken. This meant supporting it wasn t as straightforward as it seemed - you d need to ensure that your cookie scope was compatible with the certificate scope. You could probably make this work well enough by aligning it with the Public Suffix List, but there was still some risk of expectations not being aligned. And, perhaps most importantly, TLS session resumption (replaced by pre-shared keys in TLS 1.3) somewhat defeats the purpose of the exercise - clients store state that allows them to re-establish a TLS connection without performing certificate exchange (this reduces overhead if a connection gets interrupted or you switch to a new network or anything along those lines), and anyone in a position to steal cookies could steal that state as well. The followup attempt was channel IDs. This simplified the implementation somewhat - rather than certificates, a raw public key would be sent, along with proof of possession of the private key in the form of a signature over a portion of the TLS handshake. This was required even in the event of session resumption, which avoided having to worry about theft of session secrets. The timing of the exchange was after the encrypted session had been established, so user identity couldn t be leaked that way either. Cookies could then be bound to this identifier. Unfortunately it didn t really deal with the problem of scoping keys in a way that would match cookie requirements, and the spec suggests that the right way of handling this is to scope keys to TLDs, which would enable user tracking across sites (Chrome s implementation apparently restricted it to eTLD+1, which would match the third party cookie policy and avoid the tracking risk). Chrome added support for this, but it was removed in early 2018. The discussion of some of the pain points in that message is interesting, explicitly calling out problems with connection coalescing across domains and the incompatibility with zero-RTT TLS1.3. The overall consensus at the time seems to be that trying to solve this entirely at the TLS layer has too many rough edges, and a different approach should be taken. And so almost 7 years after the initial draft for origin bound certificates, we come to token binding. This ended up being a rather more complex endeavour, covering 3 different RFCs describing how it impacts TLS, how to incorporate it into HTTP, and how to manage all the various parties involved in the process. The short version is that it s pretty similar to channel ID, except that there s also a documented mechanism for allowing tokens to be bound to one party and consumed by another, avoiding any need for widely scoped keys. Token binding effectively solved all the issues in the original proposal, but at the cost of somewhat more complexity. The RFC was finalised in October 2018. Chrome removed its (incomplete, draft) support for token binding in November 2018. Edge carried support until late 2024. Despite getting all the way through the RFC process, it s functionally dead. The process up until this point had been largely initiated by Google, with Microsoft contributing significantly to the token binding standards. The work had been focused on identifying a generic solution to the problem rather than tying it to any specific authentication flow. The next step was in a different direction - rather than trying to fix this for the entire internet, how about we try to fix it for OAuth? RFC 8705 is titled OAuth 2.0 Mutual-TLS Client Authentication and Certificate-Bound Access Tokens . This is basically the 2011 approach, but (a) with an explicit definition of how the certificate should be incorporated into issued auth cookies, and (b) with a proviso that well uh if you re going to use tokens issued by your IdP to authenticate to someone else then well you re going to need to use the same cert for both. This is probably fine for the company-owned-laptop case where you re actually fine with multiple sites being able to tie identities together (that s kind of the point here!), and also works for I am using an app and not a browser , but doesn t work for more generic scenarios. It also doesn t seem to take the session resumption case into account at all? Support for RFC8705 seems poor, as far as I can tell of the big players only Auth0 implements it. In theory it works fine with self-signed client certs but in reality that s going to be almost as difficult to support across multiple platforms as just issuing proper client certs in the first place, so deployment is going to be kind of a pain. But the good news is it doesn t rely on any TLS extensions or custom browser behaviour, so at the client side it works fine with any browser. Which brings us on to RFC 9449, Demonstrating Proof of Possession . This goes even further than RFC8705 in terms of reducing the burden of deployment - it works fine with existing browsers, and it doesn t even require any certs. The client generates a keypair and provides the pubkey when requesting the cookie. The cookie contains the pubkey. Every request to the service now provides the cookie with the pubkey and also provides a signature over the URI and HTTP method. If the signature matches the pubkey in the token then clearly the signature came from the machine the token was issued to, and everything is good. This does come with some downsides, though. The first is that it uses browser interfaces to generate the keys (typically crypto.subtle.generatekey()) and as far as I can tell there are no browsers that guarantee that that key is going to be generated in hardware even if it s marked non-exportable, so anyone able to steal the cookies can also steal the keys. The second is that the signature only covers the URI and HTTP method, and not the message content or any other headers, so anyone able to exfiltrate a valid signature can replay it against the same URI with different message content. The recommended way to handle this is to reject any signatures that weren t generated within the last few seconds, which is a wonderful additional way to allow clock skew to give you a Bad Day. And the third is that every single request has to be separately signed, which is not intrinsically a problem because computers are fast and have multiple cores, but if you re trying to solve the first problem by sticking the key in a TPM then you re dealing with something that s slow and single threaded and that s maybe acceptable if you re using client certificates (because there s going to be one signature per session and you can use the same session for multiple requests) but probably not if you re dealing with a user opening a browser that restores previous tabs and each of those is a webapp that fires off 100 requests in parallel. In case it wasn t clear, I don t like DPoP. It doesn t feel like it actually solves the underlying problem that we see in the real world (malware running in a context where if it can grab the tokens it can grab the keys), it adds a massive amount of overhead, and it has baked in replay vulnerabilities. I don t know why it exists and I m incredibly suspicious of vendors telling me that it fixes my problems, because if they re telling me that then I m going to end up assuming that they either don t understand my problems or they don t understand their technology, and neither of those is good. Still. Then we get to the thing that prompted me to write this - Chrome s announcement that they had launched device-bound session credentials. This is interesting because it s a Chrome feature that s explicitly intended to counter on-device malware, which was one of the things that was out of scope in 2018 when token binding was being removed. Since this is entire web level it doesn t have to be an RFC, and so is instead defined by W3C. I m going to handwave all the complexity and say that it s basically a way to register a public key when a cookie is issued, and then prove possession of the private key when it s time to renew the cookie. By making the cookies shortlived and having support for rotating them in the background, user impact is basically zero and while it s still possible for an attacker to exfiltrate and use a cookie they ll only be able to do so for a short window before it needs to be refreshed - something the attacker can t do, since they don t have the private key. This avoids the DPoP overhead because you only need to do signing once per cookie per cookie lifetime, and not on every single request. I don t like this due to the window where exfiltrated tokens can be used, but it feels like a strict improvement over the status quo. An extension called device-bound session credentials for enterprise allows pre-enrollment of device keys, so even though the actual runtime DBCE flow doesn t involve certificates, certificates can be used for device registration in enterprise environments and you can make sure that auth cookies only go to trusted devices. Unfortunately this is Chrome-only, and so we re going to need to wait for it to be backported to all the random app frameworks for it to have widespread support on mobile or for almost everyone s desktop app that s actually three websites in an Electron wrapper. Mozilla s current position is that they re not in favour of it, so I guess we ll see where Safari lands in terms of broad uptake. The last thing on my list is another client cert/OAuth binding, this one still in draft state at the time of writing. This one is aimed primarily at the use of agent-driven tooling, where you have something running in the background using a whole bunch of tools that are each acting on your behalf. Authenticating to all of them separately isn t a fun time, but giving broadly scoped access tokens to a non-deterministic agent and trusting that it ll never post them somewhere public also isn t a fun time. The key distinction between it and RFC8705 is that it s aimed at connections rather than sessions, which avoids the worries about session resumption. This is done with TLS Exporters, which in TLS 1.3 should be unique to the connection even over session resumption (TLS 1.2 may reuse some of the same key material for exporters over session resumption, so it s recommended to enforce 1.3 for this). By providing a new signature alongside the cookie on every new connection, the client proves that it still has access to the private key. This is a very new spec and I haven t had much time to work through it yet, but my naive understanding is that unlike RFC8705 this would require some additional client support to be able to regenerate the client signature on every TLS reconnection. This doesn t avoid all the problems that RFC8705 has, including how to scope certificates. For the agentic use case that probably doesn t matter - all these tools are acting on behalf of the same user, it s fine if all the sites involved know they re the same user. But it doesn t solve the general purpose user use case, and right now DBSC seems like the best we have there. But. Part of me still wonders whether Dirk Balfanz s approach was the right one. Yes, there s risk associated with TLS session resumption, but in the worst case you could just switch that off for high risk setups. The cookie scope argument is real, and also in cases where it could violate privacy the site owner could already choose to broaden their cookie scope and violate your privacy, and in cases where it breaks things you could just not make use of it. The other problems are largely fixed by TLS 1.3, and then we re just left with Browsers handle client certificates badly to which my answer is Yes, and we should fix that anyway . Despite having a pretty good answer to this solution over a decade ago, the closest we have to actual deployment is something that offers strictly worse security guarantees. And tokens keep getting stolen, and compromises keep occurring, and for the most part people shrug and get on with things.

30 June 2026

Joey Hess: big loads offgrid with a small battery (sidelined)

No matter that the hype cycle wants you to think, the renewable energy transition is the biggest thing happening in tech and it's happening faster and faster. Despite being neck deep in it personally with offgrid solar projects, most recently solar hot water, increasingly it becomes clear I'm watching from the sidelines. In Australia, everyone gets 24 kwh of free daytime electric power now. That's without installing any solar panels of their own, the grid just has that much excess capacity. All it takes to save $thousands per year (and avoid emissions) is to schedule some big loads like the hot water heater and EV to charge during the day. To save more, drop in a home battery that charges for free and powers the home through the evening. In Germany, a 2 kwh plug-in home battery costs $350 and the electric company will pay you $130 per year to plug it into your wall. There are similar offers throughout Europe. In Cuba something something geopolitics, oil blockade, belt and road => suddenly 1GW of solar farms with another gigawatt on the way. I'll soon visit South Carolina where with no subsidies whatsoever from a decidedly renewable-unfriendly government, it made sense for my dad's house to get a whole home battery and double the solar array. The resulting system will be able to power the well pump and probably also the whole geothermal HVAC system through the kind of month-long grid down events that happened in Hurricane Helene. Myself, well, I've got a by modern standards small 4 kwh home battery that powers my house offgrid, and I've recently installed a heat pump hot water heater. That's after about a decade pondering what solution to use for solar hot water, to replace an aging and horrible propane instant water heater. I've in the past considered everything from evacuated tubes to special direct drive inverters to DC resistive MPTT dump loads. The solution turned out to be just a big enough solar array, and plugging in a 120v hot water heater that needs only 500 watts in heat pump mode. Plus a small amount of code to manage when it runs. In the time I was thinking about that, economies of scale and tech improvements just wiped all those other possibilities off the map, it's not economical to install and maintain a separate evactuated tube heat collector when a pile of solar panels costs so little and when electric hot water has gotten more than 200% efficient. I also recently completed my permanant EV charger installation, with a new inverter and conduit and proper wiring, and increased the car's charge rate to 2 kw. Eliminating the need to charge anywhere except at home except on road trips. Coordinating when these two big loads run, to maximize solar production and ensure that the house battery is full at the end of the day was ... not hard at all actually? The car charger amps can be dialed up and down to match incoming solar power fairly well, and leave some room for the hot water heater. They both operate as more or less dump loads. More or less because neither one can be cycled on or off very fast (to avoid wear and tear on the car's contactor and the heat pump's compressor), so it makes sense to leave them on and skate through short cloudy sections of the day, as long as the house battery doesn't get too low. How low is too low for the house battery? Depends on the time of day. The code it's currently using, which may get tweaked over winter:
    -- When the battery is charged enough to run major loads that may prevent
    -- charging it further.
    --
    -- This varies with the hour of day. Early in the day, the battery does not
    -- need to be as full to be considered well charged, since there is
    -- still plenty of time for it to charge up. Later in the day, with less
    -- time to charge, it needs to be more full.
    wellCharged :: Hour -> Percentage
    wellCharged (Hour hour)
              hour < 9 = Percentage 90 -- night
              pmhour <= 0 = Percentage 50
              pmhour <= 1 = Percentage 60
              pmhour <= 2 = Percentage 70
              pmhour <= 3 = Percentage 80
              pmhour <= 4 = Percentage 90
              otherwise = Percentage 95
      where
            pmhour = hour - 12
More complicated is, what to do it there's solar power to run one or the other, but not both? This is starting to get into the territory of microgrids now, or of demand response programs, so there's a whole industry or three out there doing industry things geared at the kind of no-brainer solutions I mentioned earlier. From what I've gathered, all of them involve proprietary protocols and gear. What I've done is to read the state of the hot water heater and car, and prioritize hot water over the car. Except, if the car is below 10% it urgently needs to charge. And I found a really simple way to decide when to run the low-priority load: Just check if the house battery's current charge will be considered wellCharged in an hour. So if it's 2 pm, the battery needs to be 80% charged to run the lower-priority load, and if it dips below that, that load will turn off but the high-priority load will keep running down to 70% battery. Unfortunately, getting any information out of my hot water heater relies on a vendor API server that is often down on weekends, and reverse engineered the web page of my EVSE[1] to control it, to say nothing of the nightmare of getting the car's state of charge from The Cloud. Anyway, I'm pleased with having easily tweakable code and how far I've taken this offgrid, and everything I've learned doing so, but like I said, I'm clearly observing from the sidelines over here while the most significant thing for all of us is going on over there. You might appreciate my code or method, but you'll eventually be plugging in a home battery or signing up for a free daytime power tarrif from your electric company, or having professionals install a whole home system for climate resiliance. So my question is, where does free software fit into all this? There are things like Home Assistant that do productize the kind of thing I'm doing enough to be useful more widely. But still niche. Meanwhile there are inverters and batteries that phone home to China, and every consumer facing install is either "use this device" or "integrate these 3 proprietary devices". I don't think focusing on these negatives is really useful though, I'm more trying to understand where all this is going and then maybe get out ahead of it in some useful way with free software. Your thoughts welcome.
[1] Obviously OpenEVSE exists, but it didn't meet my needs hardware wise. And I could set my EVSE to use an OCPP server but it was easier to do the screen scraping than find an appropriate one, and I have the feeling I would not appreciate learning any more about OCPP, in the same way I really don't want to know a lot about web browsers' tag soup mode.

Russell Coker: Dirty Clone and SE Linux

There is a new Linux kernel exploit out named Dirty Clone [1]. The first thing to do to exploit this is to create a container with a separate network namespace via one of the following commands:
unshare -Urn
bwrap --bind / / --unshare-user --unshare-net --uid 0 --gid 0 /bin/bash
The Jfrog people recommend unshare -Urn but I gave the Bubblewrap command as an option as it should work equally well and in some situations may be permitted when unshare isn t. The next step to exploiting it is to use the ip command to set the links up, below is what happens in a user session on a SE Linux system with user_t as the login domain:
# ip link set lo up
RTNETLINK answers: Operation not permitted
That will give an entry in /var/log/audit/audit.log like the following:
type=AVC msg=audit(1782818856.618:3610): avc:  denied    net_admin   for  pid=1829 comm="ip" capability=12  scontext=user_u:user_r:user_t:s0 tcontext=user_u:user_r:user_t:s0 tclass=cap_userns permissive=0
type=SYSCALL msg=audit(1782818856.618:3610): arch=c000003e syscall=46 success=yes exit=32 a0=3 a1=7ffebe5f9e50 a2=0 a3=0 items=0 ppid=1638 pid=1829 auid=0 uid=0 gid=1000 euid=0 suid=0 fsuid=0 egid=1000 sgid=1000 fsgid=1000 tty=pts0 ses=17 comm="ip" exe="/usr/bin/ip" subj=user_u:user_r:user_t:s0 key=(null)ARCH=x86_64 SYSCALL=sendmsg AUID="root" UID="root" GID="test" EUID="root" SUID="root" FSUID="root" EGID="test" SGID="test" FSGID="test"
type=PROCTITLE msg=audit(1782818856.618:3610): proctitle=6970006C696E6B00736574006C6F007570
Unlike previous exploits like Pintheft [2] this doesn t require any really uncommon access to the kernel (unless you consider setting up IPSec to be really uncommon) and is allowed in many container setups. Now on a system with the unconfined module removed (as described in the SE Linux Protection part of my post about Copy Fail [3]) the following domains have such access:
# sesearch -A -c cap_userns -p net_admin
allow container_engine_t container_engine_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow container_init_t container_init_t:cap_userns   chown dac_override dac_read_search fowner kill net_admin net_bind_service net_raw setgid setuid  ;
allow container_kvm_t container_kvm_t:cap_userns   chown dac_override dac_read_search fowner kill net_admin net_bind_service net_raw setgid setuid  ;
allow container_t container_t:cap_userns   chown dac_override dac_read_search fowner kill net_admin net_bind_service net_raw setgid setuid  ;
allow crio_t crio_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow dockerd_t dockerd_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow dockerd_user_t dockerd_user_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow init_t init_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_module sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow iptables_t iptables_t:cap_userns   net_admin net_raw  ;
allow podman_t podman_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow podman_user_t podman_user_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock ipc_owner kill lease linux_immutable mknod net_admin net_bind_service net_raw setfcap setgid setpcap setuid sys_admin sys_boot sys_chroot sys_nice sys_pacct sys_ptrace sys_rawio sys_resource sys_time sys_tty_config  ;
allow spc_t spc_t:cap_userns   audit_write chown dac_override dac_read_search fowner fsetid ipc_lock kill mknod net_admin net_bind_service net_raw setgid setpcap setuid sys_admin sys_chroot sys_nice sys_ptrace sys_rawio sys_resource  ;
allow spc_user_t spc_user_t:cap_userns   chown dac_override dac_read_search fowner kill net_admin net_bind_service net_raw setgid setuid  ;
allow staff_bubblewrap_t staff_bubblewrap_t:cap_userns   dac_override net_admin setpcap sys_admin sys_ptrace  ;
allow sysadm_bubblewrap_t sysadm_bubblewrap_t:cap_userns   dac_override net_admin setpcap sys_admin sys_ptrace  ;
allow user_bubblewrap_t user_bubblewrap_t:cap_userns   dac_override net_admin setpcap sys_admin sys_ptrace  ;
Conclusion It seems that SE Linux configured in the strict mode prevents this exploit in the most obvious use case. But with the range of container related domains that are granted such access it seems quite likely that some configurations and use cases will permit it. Overall the protection that the standard policy for SE Linux can offer (in a non-default configuration) against net_admin access isn t bad, but isn t very good either. I think this will be the first of many exploits based on cap_userns access and that we need to do some work in tightening the SE Linux access controls on such things. One possible way of doing this is to have a program run inside a container in a domain that has permissions such as net_admin to setup the container and not allow domain transitions from the regular programs run in the container (the actual work) to the domain used for network setup. The increasing use of containers by applications is only going to make this problem worse. I think that what we need is something like Flatpak for the vast majority of desktop/phone applications with a container setup program that works with apps packaged in the distribution packaging method (not from Flathub). This is something I m going to investigate for future blog posts.

Next.

Previous.