Search Results: "ron"

12 May 2009

Michal Čihař: Gammu test version 1.24.90

I finally find time to make another release of Gammu. This time it is really just bug fixing and I will stay in this mode for some time, because I have simply too much things to do in real life. Full list of changes follows: You can download from usual place: http://cihar.com/gammu/, Debian users will find packages in experimental soon, SUSE, Fedora and Mandriva users can check experimental repository in OpenSuse Build Service.

Erich Schubert: Dropbox experiences?

Has anyone experience with Dropbox?It seems to be an interesting web storage service, with 2 GB of free storage.However, the Linux client seems to be closed source (which is understandable, it seems to have a lot of neat features) - so I intend to use the web interface only (at least for now).Update #2: There is a RFP bug for Debian, some Source is on the download site. And while this sort (except the images) is GPL, it's just the nautilus integration part, not the daemon you also need.Did you try Dropbox? Does it work well? I know some people (especially Windows users) who could benefit a lot from a service like that, so I wonder if I should recommend them Dropbox. Or is there some better alternative (it should allow sharing of files though - synchronization is not as essential, it is a lot about exchanging files too large for usual email in small user groups; still synchronization probably is a comfortable way of transferring the files without having to think about it yourself)?No comments in this blog - email me via erich AT debian ORG.P.S. I know there is some referral program to get more storage, feel free to send me your referral link - I'll remove this PS once I've signed up.P.P.S. There also is Ubuntu one, but as far as I can tell Ubuntu only so far. Looks very similar.P.P.P.S. So far, I've received a lot of praise for DropBox.P^4.S. My own referral link, feel free to use this to sign up (+256 MB for you, too!) and "upgrade" my account.

11 May 2009

Fabio Tranchitella: Are you looking for a job?

I tried hard, but it seems impossible to find Python programmers for our start-up. I know, living in Pecs (Hungary) limits the choices, but I also tried in Budapest and I was unable to find anybody with a good knowledge of Python and Zope. For this reason, we finally decided with my business partner to experiment with telecommuting.

We are looking for talented Python programmers to join our team, based in Pecs and Budapest (Hungary) with a satellite office in Turin (Italy). You will be able to work from home, planning your time based on your schedule and goals. You will work on the development of a free (as in speech) CRM and marketing platform built on the Zope Toolkit (aka Zope 3).

About you:

Requirements:

Nice-to-haves:

If you are interested, drop me a line at kobold@debian.org.

Wouter Verhelst: Console-setup sucks

I have a few reasons for this:
  1. It wants to change the framebuffer font without asking. I seriously dislike the font it sets up.
  2. I have a habit of writing my own Xkb keymap. With xorg <= 7.3, that meant creating a file /usr/share/X11/xkb/symbols/wouter and having something like Option "XkbLayout" "wouter" in xorg.conf. Console-setup doesn't pick that up, though, and loads a default keymap that somehow looks closely similar to what I'm using.
  3. What's worse, the default keymap it picks up on my Apple Powerbook (which isn't my primary laptop anymore, but considering how my actual primary laptop is in for repairs, is what I need to use for now) is a PC Belgian AZERTY keymap, rather than the Apple AZERTY. This is *wrong*.
I might understand why they did this kind of thing, but the current implementation of autodetection is horribly broken.

10 May 2009

Ond&#345;ej &#268;ert&iacute;k: My experience with running an opensource project

Nir Aides, the author of the excellent winpdb debugger, sent me the following email on September 21, 2008, so I asked him if I can copy his email and reply in form of a blog post (so that other people can comment and join the discussion) and he agreed. It took me almost a year to reply, but I made it. :)

Hi Ondrej,

How are you?

I am about to publish a new free software project, a new simple PHP framework, and I am interested in your advice.

You started SymPy and were able to make other people join you and develop it with you.
How did you do it?
How did it happen?
Did you actively call for other people or they spontaneously showed interest and joined you?
Are the other major contributor people who were your friends before you started the project?
Did you need to create or manage the project in a particular way to make it attractive to other people?
Are there things you are aware of that promote collaboration or demote it?

I was never successful in doing the same with Winpdb, which while it became reasonably popular, no one has ever joined me to develop it, except for a notable tutorial contribution by Chris Lasher which was developed independently.

Now with the new project, I am wondering what are my chances of making other people try it and take it on. On the one hand it is a new and fresh code base in an interesting field, on the other hand, why would anyone bother to spend their energy on this new project when they have Symfony or Drupal?

What do you think?

BTW, Ohloh believes you have a median of 19,000 lines of changed code per month since the start of their log. Can this be true? Is this humanly possible? According to it SymPy has over 1,000,000 lines of code? I can't understand these numbers. Winpdb has about 25,000 lines after 3 years of development. And from my experience 1,000,000 lines of code projects need about 20-50 full time developers to work on for 2-5 years which is about 40-250 man years. And as if this is not enough you are listed as owner in a dozen other projects in Google code and have enough time to become an awarded scientist. How is this possible?

http://www.ohloh.net/p/sympy/contributors/

BTW2, do you still use Winpdb? If you find yourself using it less, can you say what are the reasons, or what it would take to make it more useful?

BTW3, How is SymPy doing?

Cheers,
Nir


So my most honest answer how to run a successful opensource project is: I don't know.

But nevertheless I tried to summarize some of my ideas and experience and some guidelines that I try to follow, maybe it will be useful to you Nir, or anyone else.

First of all, there has to be a public mailinglist (easily accessible), public bug tracker, nice webpage, easy to find downloads, frequent releases (once a month is good, but in the worst case at least 4 times a year) and a set of guidelines to follow in order to contribute. So that's a must, if the project doesn't have the above, it's almost impossible to become successful. However, that is just a start, just a playground. There are still many projects that have the above and yet they totally fail to attract developers.

So I think the most important principle is that I always think how to employ other people in what I do. If I have some plan in my head how to do something, e.g. how to move some things forward, I always create exact steps and put it to issues, or our mailinglist, so that each step can be done by someone who is completely new to sympy. So I try to look at things from other people's perspective and think -- ok, I quite like this SymPy project and I'd like to get this done (for example a new release, or something fixed, or implemented), but I have no idea how to start and what exactly needs to be done.

So what I try to do if someone comes to our list and asks for something, is that I create a new issue for it and think how I would fix it if I had time. Then write the necessary steps in the issue and invite the submitter to fix it and I offer help with explaining anything and guiding. Now there are two things that can happen. Either the submitter has time and a will to go forward and in this case he starts wrestling with it and whenever he has some code or a question, I need to find time, review it and offer some way out. Or the submitter is too busy, in which case the instructions simply rest in the issues and the next time someone asks for the feature, the instructions are already there. I don't have estimates how frequent either case is.

When I am working on something myself, I try not to code privately, but also put up issues first and put the steps needed in the issues, so that it's easy for other people to join in.

In general, the most precious value for me is the fact that someone else had to sit down at his computer and wrote the patch. So I do everything possible to get new (or more) people interested in the development. Some people think that only super programmers can do a decent job and it's useless to invest time in people that may just have started with Python. They are wrong. Among the SymPy developers (around 65 people total have contributed patches so far at the time of writing this post), we have all kinds of people. We have people from high school, we have a retired US army engineer, we have physicists, mathematicians, biologists, engineers, teachers, or just hobbyists, who do it for fun. Unfortunately, we do not have many women (I think no patch that made it into sympy was contributed by a woman, but I may be wrong), so if anyone has any ideas how to get more women involved, let me know (I know we have several women fans, so that's a good start:). We have people whose first open source project they ever contributed to was sympy and people who are new to Python.

Many times the first patch that a new potential developer submits is not perfect, usually it's faster for me to write it myself, than to help with the first patch, however my rule is to always help the submitter do that. Sometimes he sends a second patch, or a third, and usually it needs less and less work on my side and it already pays off, because he is then able to fix things himself, if he discovers a bug and sympy has just won a one more contributor.

So I came to the conclusion that all that is needed is an enthusiasm. You don't even have to know Python (as you can learn all these things on the way) and you can still do useful things for us and really spare our time.

To answer another question from Nir's email, SymPy has about 130000 lines of code and another about 20000 lines of tests, so I think those stats are wrong. Also the changed lines of code is in my opinion wrong, we usually have about 250 new patches per release (this depends how often we release and other things).

Yes, I am involved in couple other projects, e.g. Debian, Sage, ipython, scipy, hpfem.org (and couple more), basically everything that has to do with numeric simulation and Python, but my activity there varies. The most time consuming thing in the last couple years was definitely school, I was finishing my master in Theoretical Physics in Prague and then moved to the Nevada/Reno and I just finished my first semester here at PhD in Chemical Physics, and sometimes it was just crazy, e.g. I finished teaching at 7pm and instead of going home and sleep, I stayed in my office, fixed 10 sympy issues that were holding off a release, finished at 1am, went home (by bike, since I don't have a car yet), slept couple hours and then did just school again for a week, other people reviewed the issues in the meantime, and then I made the release (instead of sleeping again). In the last semester it was not unusual that I got home at 1am every week day, then slept most of Saturday to catch up, on Sunday I did some laundry and shopping, and the rest of time I did grading and homeworks for all my classes and teaching, no time for anything else (e.g. no friends, no girls, no rest, no hobby, no opensource stuff, nothing). So sometimes one has to work pretty hard to get through it, but fortunately it's behind me finally, if all goes well, I should be just doing research from now on and have a real life too. Also I am sorry I didn't manage to reply sooner. :)

To answer the other questions:
Are the other major contributor people who were your friends before you started the project?
No, not a single major contributor was my friend before I started the project. Every single one of them become a developer using the procedure I described above, e.g. first showed on the list or in the issues, and maybe even the very first patch was not a high quality one (and if I was stupid and arrogant, or didn't see the big potential, I would just ignore them). But when given a chance, they became extremely good developers and sympy would simply just not be here without them.

Did you actively call for other people or they spontaneously showed interest and joined you?
I very much encourage everyone to contribute, but the initial interest must be in them, e.g. they at least have to show around the mailinglist/issues, so that I know about them. But once I know they are interested in some issue, yes, I try to invite them to fix it, with my help.

One observation I made is that I have to always think in the spirit "how to earn new money, not how to spare the money I already have", e.g. when applied to sympy, how to get new developers, how to develop the new great things etc. Even if I am super busy as I was, I still have to think this way. Once I start thinking how to conserve and preserve what we already have, I am done, finished and that's the road to hell.

If I am open, positive, full of energy, I can see people joining me and we can do great things together. It probably sounds obvious, but it was not for me, when for example some people I worked with, started their own projects, when I got busy, and started to compete, instead of helping sympy out. And I felt betrayed, after so much work that I invested into it and started to become protective. And then I realised that's wrong. I can never stop other people do what they want to do. If they want to have their own project, they will have it. If they don't want to help sympy out, they won't (and what is more important, there is nothing wrong with either of that). It's that simple and being protective only makes things worse.

There is also a question of the license that you use for the project, e.g. one should basically only choose between BSD (maybe also MIT or Apache), LGPL and GPL (there are also several versions of the GPL licenses). Unfortunately the fact is, that there are people who will never contribute a code under a permissive BSD license (because it's not protecting their work enough) and there are also other people who really want to code to be BSD (or other permissive license) so they can sell it and they don't need to consult with lawyers what they are or aren't allowed to do and also so that they can combine it with any other code (opensource or not). It also depends if one wants to combine (and distribute) other codes together. So choosing a license is also important. I believe that for sympy BSD is the best and for other projects (like Sage) GPL is the best and one has to decide on a case by case basis. For Winpdb, I would make it BSD too, since you can get more people using it.

To conclude, SymPy is a little more than 2 years old, and it has been a great ride so far and more things are coming, e.g. this summer we have 5 Google Summer of Code students and people are starting it to use in their research and we plan to use it in our codes at our group here in Reno too, so things look promising. I am really glad, we managed to build such a community, so that when I am busy, as I was the last semester, other people help out with patches, reviews and other things, so that the project doesn't stall and when I got rid of my school duties now, we can move things forward a lot.

So maybe you can get inspired by some of the ideas above. I am also interested in any discussion about this (feel free to post a comment below, or send me an email, or just write to a sympy list about what you think).

9 May 2009

Andrew Pollock: [life] A few days in British Columbia

We got back from our brief visit to Canada last night. We had a great time, Vancouver and Victoria were both very nice. YVR (Vancouver Airport) This airport has to win the award for nicest airport I've seen. Clearly they pulled out all the stops in preparation for the Winter Olympics next year. The airport is very bright, airy and open. Before you even hit the immigration line, you pass through a couple of water features, some indigenous art, all of that jazz. Immigration is done in the open in a huge hall, instead of in the dark bowels of the airport, which was a pleasant change from the usual US airport immigration experience. (That said, Houston airport had a pretty nice immigration experience). Oh, and it was blanketed with free WiFi, which was a nice touch. Ferry to Victoria The brief geography lesson I got was that Victoria is on Vancouver Island, and Vancouver (the city) is not on Vancouver (the island). Go figure. Getting to Victoria from the airport via BC Ferries was a very seamless experience. You board a bus from the side of the airport terminal, and it drives to Tsawwassen, drives onto the ferry, and then you get off the bus and go sit on one of the passenger levels of the ferry. BC Ferries BC Ferries deserves special mention. The ferry itself is huge - 7 decks (three of them for vehicles). It's a veritable shopping mall on water. It's got some stores, buffets, exclusive $10 entry lounges, video arcades, cellular payphones, the works. The trip to Victoria The ferry ride took about 1.5 hours, and was very scenic. We passed by a few smaller islands, and I had an instant flashback to the TV show The Beachcombers that I used to watch as a kid, particularly the opening sequence. Victoria Victoria is a beautiful city. It's the capital of the province of British Columbia, and I likened it to Canberra in a lot of ways. It had more modern conveniences than a town with a population of its size would otherwise normally have. It was a government and university town. Nice houses, very green in general, and being an island, there was water everywhere. It seemed to have lots of bays, and harbours and rivers. It was very nice. Flight back to Vancouver We took a Harbour Air seaplane back to Vancouver on Sunday afternoon. That was fun. I've never been on a seaplane before. It took about 35 minutes. Vancouver First order of business in Vancouver was the purpose of the whole trip: renewing our visas. That went fine, I'll write a separate post about the process. Afterwards, we bought tickets for the Big Bus, and toured the city for the remainder of Monday and Tuesday. Drive to Whistler For Wednesday and Thursday, we hired a car, and went a bit further afield. On Wednesday, we drove up to Whistler to check it out. The drive up took about 5 hours, because we stopped at every scenic spot we came by. Waterfalls abounded. There was a lot of work being done on the roads between Vancouver and Whistler, upgrading them for the Olympics. Whistler itself was pretty spectacular. Some crazy looking ski runs. The village looked like Squaw Village on steroids. The drive back only took about 2 hours. Cleveland Dam, Lynn Canyon suspension bridge For the last day, we drove to Cleveland Dam, where there was a salmon hatchery, and checked out the dam, hatchery and surrounding area. It was lovely and green. After that, we drove to Lynn Canyon to check out the suspension bridge there (unlike the Capilano Suspension Bridge, which costs $26 a pop, the Lynn Canyon one is free). That was all we had time for really. The weather wasn't fantastic during our stay, but it didn't really prevent us from doing anything either. I'd have liked to have checked out Stanley Park if we had more time, and Sarah wanted to go to Grouse Mountain. We had a near-100% success rate at being picked as Australians, unlike when we're in the US, where more often than not, people ask us if we're British. Apparently this is mainly attributed to the fact that Australians run all of the ski lifts at Whistler. We certainly heard a lot of Australian accents while we were getting around. I'd also never seen such a saturation of Starbucks before. In Vancouver, there were literally Starbucks across the road from Starbucks, and around the corner from another one. Whistler village had two. The Canadian accent is cute. They really do tack "eh?" on the end of everything, although it's phonetically more like "ay?". "House" and "about" are also pronounced distinctively differently. Overall, Vancouver wasn't what I'd call bursting at the seams with tourist attractions, but seemed like a nice city. It was fairly flat. The beggars were well dressed. Everyone was very friendly. A lot of the taxis were Priuses. It seemed pretty clean. I could handle living there. Not sure how bad it gets in winter.

8 May 2009

Biella Coleman: Capital Punishment

Check out the one comment

Biella Coleman: Capital Punishment

Check out the one comment

Christoph Haas: Thanks for the great time, KDE

After years of being a dedicated KDE user it seems like it s finally time for me to go back to Gnome. I once tried KDE 4.x from the Debian experimental branch knowing that it s probably unstable and will require a lot of patience. But I was willing to report bugs and dive into new things. It didn t take long though to find out that graphics were extraordinarily slow with the new desktop effects . The worst was resizing a konsole (KDE terminal window). It took 25 seconds until the window was resized and redrawn! On the interweb I found KDE developers rant about NVidia who didn t support some special extension they needed. They suggested to get an ATI card instead. (No, thanks, I was struggling with the crappy radeon and fglrx drivers on my new work laptop and am sick of ATI for Xorg.) Or I could use a bare XTerm instead. Yeah, right. So I couldn t use the desktop effects. After all I used the non-free NVidia driver for years and it never let me down. I don t mind doing without eye candy. But the desktop effects were about the only serious way to switch between virtual desktops. Point the mouse into a corner or edge of the screen and get a zoom-out bird s view of the virtual desktops. Nice but quickly annoying. Besides you had to push the mouse pointer a few pixels into the edge (it s not sufficient to just hit the edge) which means that after 10 desktop switches I had to lift the mouse and set it back on the mousepad. Another annoying issue is that up to now I can t assign functionality to every key on my keyboard any more. I had a neat trick by having 3 3=9 virtual desktops and use my numpad keys 1 to 9 to page through them. 0 on the numpad opened a new shell window. + on the numpad maximized a window. But now I couldn t assign any of those numpad keys. I pressed the 1 but KDE didn t detect Numpad_1 but just 1 . Guess how useful it is to not be able to type the 1 any more. There is a low-priority bug report for KDE from users who want this fixed but it will likely not happen any time soon. So the only way to switch desktops was to poke on the tiny pager widget in my panel. Yuk. Not to mention that I couldn t put icons on the desktop any longer. There was just a sissy widget that I could use for that purpose but it didn t work like a conqueror or dolphin at all. It was pretty amusing when in KDE 4.2 there was suddenly a feature to re-enable the old behavior. Let me guess, KDE developers - I wasn t the only user you couldn t persuade of the new paradigm? Next evil thing was performance. KDE 4 takes ages to load. Simple window managers get me started within seconds. Even Gnome. But KDE takes 30 seconds until it s loaded plus some disk grinding in the background. And memory usage wasn t nice either. And what finally made me mad was stabilty - or rather lack thereof. Everytime the screen saver ran my kbluetooth module crashed. kmail crashed even more frequently than before. (I loved kmail for it s great customizability and feature set.) plasma (the actual window manager) died at least twice a day. Suddenly the panels were looking ugly or crashing. As a Debian developer I have to follow the unstable branch on my workstation. And there is no distinction between KDE 3 and KDE 4 any more so a dist-uprade inevitably gets all of my applications upgraded to KDE 4 (plus an hour of manual engineering in aptitude because half of my applications weren t upgraded automatically due to different application names and I had a mixed environment). So there I was with KDE 4.2. I really worked with it for a month. I tried hard to get acquainted to its bloatedness and instability. It s really a nice technological preview of what might be possible in the future. Everything is really automatic. Mounting external media. New ways to find programs (although I m not happy with the new K start menu). Funny effects and nice eye candy. But it s far from the rock solid desktop environment that I was used from KDE 3.5.8. So there I am on Gnome now. I was switching back and forth. One day working on KDE 4.2 and the other day using Gnome 2.26. And although it makes me feel sad I think it s finally time to say goodbye to KDE 4. I have invested a good amount of time and energy into it - even just from a user perspective. But it s not ready. And I finally need to get some work done. A number of projects suffered from my playfulness (my ispmail tutorial, screenshots.debian.net, debexpo, my kids) and it s time to get back to work. And Gnome was pretty surprising. With compiz I have the KDE desktop effects working (here they really do) and they are all customizable. I can assign keys properly again (even the numpad). Everything is pretty fast and stable. I have replaced kmail and its buggy shared calendar feature by Icedove (aka Thunderbird) with the Lightning plugin. Worked from the first minute and hasn t crashed in a week (just have to remember next time to install libstdc++5 to be able to use Lightning). With enigmail I finally have a proper simple working PGP key management that doesn t die and is buggy like hell like in kgpg. And there s the nice Nostalgy add-on that allows me to file emails into IMAP folder quickly again - a feature that just kmail seemed to support so far. Oh, and I see new mail instantly because Icedove supports the IDLE command while kmail has never learned that neat little trick. The Gnome file manager isn t really great for my taste but it s doing its job (dolphin is just much nicer). It s not as nice as KDE but I had to learn that working and stable weighs more than nice. The hard way. And many things I liked about KDE 4 (like starting a new program with Alt-F2 and having a smart application finder and simple calculator in one) are built into Gnome, too. So why bother. Thanks, KDE, for the years of fun and service. I ll surely miss you. Get back to me should you grow up one day.

David Welton: Ruby, Soap4R, WSSE Authentication

I've been doing some work for a client, where we have to interact with a web service front end for Oracle (which also means that everything reflects Oracle's "delightful" shortened table names, like UsrAddrsPhn...). I didn't find a lot out there to do this in Ruby, except this helpful post: http://willcannings.wordpress.com/2008/07/06/wsse-authentication-in-ruby-soap4r/ However, it wasn't quite enough for what we're doing, as we have to deal with a nonce parameter as well. Here's the snippet of code I created:
require 'rubygems'
gem 'soap4r'
require 'base64'
require 'soap/rpc/driver'
require 'soap/wsdlDriver'
wsdl_url = ARGV.shift
proxy    = SOAP::WSDLDriverFactory.new(wsdl_url).create_rpc_driver
# run ruby with -d to see SOAP wiredumps.
proxy.wiredump_dev = STDERR if $DEBUG
require 'soap/header/simplehandler'
require 'soap/element'
require 'xsd/datatypes'
class WsseAuthHeader < SOAP::Header::Handler
  NAMESPACE= 'http://docs.oasis-open.org/wss/2004/01/oasis-200401-wss-wssecurity-secext-1.0.xsd'
  USERNAME  = 'Not really the username'
  PASSWORD  = 'Put your own password here'
  def initialize()
    super(XSD::QName.new(NAMESPACE, 'Security'))
  end
  def on_outbound
    security = SOAP::SOAPElement.new('wsse:Security')
    security.extraattr['xmlns:wsse'] =
      'http://docs.oasis-open.org/wss/2004/01/oasis-200401-wss-wssecurity-secext-1.0.xsd'
    unt = SOAP::SOAPElement.new('wsse:UsernameToken')
    unt.extraattr['xmlns:wsu'] =
      'http://docs.oasis-open.org/wss/2004/01/oasis-200401-wss-wssecurity-utility-1.0.xsd'
    un = SOAP::SOAPElement.new('wsse:Username', USERNAME)
    unt.add(un)
    pw = SOAP::SOAPElement.new('wsse:Password', PASSWORD)
    pw.extraattr['Type'] =
      'http://docs.oasis-open.org/wss/2004/01/oasis-200401-wss-username-token-profile-1.0#PasswordText'
    unt.add(pw)
    # Create a nonce...
    nonce = SOAP::SOAPElement.new('wsse:Nonce', Base64.encode64((rand() * 1000000000).to_i.to_s))
    nonce.extraattr['EncodingType'] =
      'http://docs.oasis-open.org/wss/2004/01/oasis-200401-wss-soap-message-security-1.0#Base64Binary'
    unt.add(nonce)
    # The time format returned by XSDDateTime isn't quite right, so we
    # fiddle with it a bit.
    unt.add(SOAP::SOAPElement.new('wsu:Created',
                                  XSD::XSDDateTime.new(Time.now.utc - 30).to_s.gsub(/..*/, "") + "Z"))
    security.add(unt)
    return SOAP::SOAPHeaderItem.new(security, true)
  end
end
proxy.headerhandler << WsseAuthHeader.new()
... call proxy methods to interact with web service ...
The key thing is to dress up the outgoing header with all the right XML, including Nonce and Created parameters. This code was created by matching the XML generated by the Java code used to interact with this "JAX-WS" web service. All in all, it's a bit of a mess compared to a nice REST style web service. Hopefully the above code will be useful to others who are in a similar situation.

Asheesh Laroia: What is open source (and Free Software) missing? / Moving to Atlanta

Tim and my mother are both neonatologists at the Golisano Children's Hospital inside the University of Rochester. Earlier today, they had this conversation:

My mother: My son Asheesh is moving to Atlanta.
Tim: Is it for a girl?
My mother: I don't really know what the kids are doing as far as girls, but no....
In fact, I'm moving to Atlanta because Shotput Ventures funded me, Nelson Pavlosky, and my friend Raphael Krut-Landau to start a company to improve interactions in the open source / free software world. We get enough money to live in Atlanta from May 18 to August 6, and after that, we have to seek more funding. This has led to a series of ironies. The first is that I am working on a startup. The second is that I left San Francisco to do it. But I have already moved out of San Franisco, and I have left my job at Creative Commons. (Feel free to get in touch with me (outside my website's comments) about filling my shoes there.) Thanks, Nathan and Mike, for giving me the chance to contribute to CC, an organization and project that I have always had a great passion for. For a while, I may seem vague about the project I am about to undertake; it's because I still want to nail down some details between the three of us. When Nelson, Raphael, and I arrive in person, we're going to kick into gear. I've been chatting with a few of you over the past few months about ideas, and I do want to especially thank Karl Fogel and Mako Hill for helping the three of us think through what could be done. Some questions for readers: Feel free to email me (asheesh at asheesh.org) if you'd rather not comment publicly. I have a few ideas of my own, and I hope to be tossing them up for everyone to bat at soon! P.S. Noisebridge, I will miss you!

7 May 2009

Steve Kemp: I'm fireproof, you're not

I've mostly been avoiding the computer this evening, but I did spend the last hour working on attempt #2 at distributed monitoring. The more I plot, plan & ponder the more appealing the notion becomes. Too many ideas to discuss, but in brief:
My previous idea of running tests every few minutes on each node scaled badly when the number of host+service pairs to be tested grew. This lead to the realisation that as long as some node tests each host+service pair you're OK. Every node need not check each host on every run - this was something I knew, and had discussed, but I assumed that would be a nice optimisation later rather than something which is almost mandatory. My previous idea of testing for failures on other nodes after seeing a local failure was similarly flawed. It introduces too many delays:
  • Node 1 starts all tests - notices a failure. Records it
    • Fetches current results from all neighbour nodes.
    • Sees they are OK - the remote server only just crashed. Oops.
  • Node 2 starts all tests - notices a failure. Records it.
    • Fetches current results from all neighbour nodes.
    • Sees they are OK - the remote server only just crashed. Oops.
In short you have a synchronisation problem which coupled with the delay of making a large number of tests soon grows. Given a testing period of five minutes, ten testing nodes, and 150 monitored hosts+services, you're looking at delays of 8-15 minutes. On average. (Largely depends on where in the cycle the failing host is, and how many nodes must see a failure prior to alerting.) So round two has each node picking tests at "random" (making sure no host+service was tested more than 5 minutes ago) and at the point a failure is detected the neighbour nodes are immediately instructed to test and report their results (via XML::RPC). The new code is simpler, more reliable, and scales better. Plus it doesn't need Apache/CGI.
Anyway bored now. Hellish day. MySQL blows goats. ObFilm: Hellboy

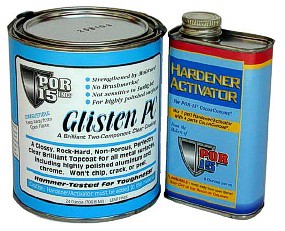
Biella Coleman: Make our words glisten


glisten vs hardened words, originally uploaded by the biella.
Now that I am (thankfully) done teaching until September, I have time to devour two small mountains of readings that I need to finish before I return to my manuscript, which I will be working on, I hope uber-productively, all summer long. One pile of readings deals with coding, open source, and the commons, such as Scott Rosenberg s Dreaming in Code and David Bollier s Viral Spiral. Another pile of reading edges toward the theoretical side of things, having to do with craft, pleasure, and humor, since it is pleasure in its many many many guises from from the calm feeling of self-satisfaction that underlies pride in one s craft, to the more sublime feeling of ecstatic bliss that powers many creative sprints. If one entertains pleasure, one must also entertain its darker side, for all of this feel good stuff is nonetheless often springs forth from a deep sea of passionate frustration. This seems to be the driving theme of Dreaming in Code and it is also what animates Ellen Ullman s fictional account of pure frustration, The Bug. I am quite fond of native expressions of geek frustration and recently was provided with an exquisite example a rant against the Adobe PSD format. The author of Xee, A light-weight, fast and convenient image viewer for Mac OS X explained his utter contempt for the Adobe PSD in the following way:
At this point, I d like to take a moment to speak to you about the Adobe PSD format. PSD is not a good format. PSD is not even a bad format. Calling it such would be an insult to other bad formats, such as PCX or JPEG. No, PSD is an abysmal format. Having worked on this code for several weeks now, my hate for PSD has grown to a raging fire that burns with the fierce passion of a million suns. If there are two different ways of doing something, PSD will do both, in different places. It will then make up three more ways no sane human would think of, and do those too. PSD makes inconsistency an art form. Why, for instance, did it suddenly decide that *these* particular chunks should be aligned to four bytes, and that this alignement should *not* be included in the size? Other chunks in other places are either unaligned, or aligned with the alignment included in the size. Here, though, it is not included. Were it within my power, I would gather every single copy of those specs, and launch them on a spaceship directly into the sun.
Even if this account represents unadulterated irritation, he leaves us, the reader, with nothing of the irritation, only pleasure. This aftermath of frustration is delivered through the vehicle of humor, which within the hacker context, is the cultural container that best captures the spirit of hacker pleasure or so I will be arguing. Like many humorous rants from the world of hacking (and please send me any others you know of), this text dances with liveliness; it exudes its own rhythm; it glistens to use Ronald Barthes apt phrasing from his short book The Pleasure of Text, which I just finished as part of my theoretical escape into the pleasure-dome. Although there are parts of his book which are to be frank, *really* *not* *pleasurable*, partly due to obscure references to High French Theory, which elide even an academic pair of eyes, the book generally pleases. And one of the most pleasing chunks is his definition of a stereotype:
The stereotype is the word repeated without any magic, any enthusiasm, as though it were natural, as though by some miracle this recurring words were adequate on each occasion for different reasons, as though to imitate could no longer be sensed as an imitation: an unconstrained word that claims consistency and is unaware of its own insistence
In contrast to the stereotype, a string of words that enchants does so by slipping off the page to hit you squarely in the heart or the gut. Unfortunately, while academic writing steers clear of stereotypes, often trying to present the detailed singularity of a phenomena (even when conditioned by social forces), it does not exactly glisten, though there are a handful of exceptions. I think we need more texts that glisten, even if only during sections or parts of our books and articles (much like the rant helped enliven the more staid technical document). In recent years, in large part due to the influence of free software, there has been an explosion, a move toward going open access. All of this is laudable and I fully embrace it (and have gotten into some small battles over it). But without an aesthetic politics that values pleasure in reading and writing we are doomed to obscurity anyway. A move toward making our knowledge public also required a move toward thinking about the literary aesthetics of pleasure.

Biella Coleman: Make our words glisten


glisten vs hardened words, originally uploaded by the biella.
Now that I am (thankfully) done teaching until September, I have time to devour two small mountains of readings that I need to finish before I return to my manuscript, which I will be working on, I hope uber-productively, all summer long. One pile of readings deals with coding, open source, and the commons, such as Scott Rosenberg s Dreaming in Code and David Bollier s Viral Spiral. Another pile of reading edges toward the theoretical side of things, having to do with craft, pleasure, and humor, since it is pleasure in its many many many guises from from the calm feeling of self-satisfaction that underlies pride in one s craft, to the more sublime feeling of ecstatic bliss that powers many creative sprints. If one entertains pleasure, one must also entertain its darker side, for all of this feel good stuff is nonetheless often springs forth from a deep sea of passionate frustration. This seems to be the driving theme of Dreaming in Code and it is also what animates Ellen Ullman s fictional account of pure frustration, The Bug. I am quite fond of native expressions of geek frustration and recently was provided with an exquisite example a rant against the Adobe PSD format. The author of Xee, A light-weight, fast and convenient image viewer for Mac OS X explained his utter contempt for the Adobe PSD in the following way:
At this point, I d like to take a moment to speak to you about the Adobe PSD format. PSD is not a good format. PSD is not even a bad format. Calling it such would be an insult to other bad formats, such as PCX or JPEG. No, PSD is an abysmal format. Having worked on this code for several weeks now, my hate for PSD has grown to a raging fire that burns with the fierce passion of a million suns. If there are two different ways of doing something, PSD will do both, in different places. It will then make up three more ways no sane human would think of, and do those too. PSD makes inconsistency an art form. Why, for instance, did it suddenly decide that *these* particular chunks should be aligned to four bytes, and that this alignement should *not* be included in the size? Other chunks in other places are either unaligned, or aligned with the alignment included in the size. Here, though, it is not included. Were it within my power, I would gather every single copy of those specs, and launch them on a spaceship directly into the sun.
Even if this account represents unadulterated irritation, he leaves us, the reader, with nothing of the irritation, only pleasure. This aftermath of frustration is delivered through the vehicle of humor, which within the hacker context, is the cultural container that best captures the spirit of hacker pleasure or so I will be arguing. Like many humorous rants from the world of hacking (and please send me any others you know of), this text dances with liveliness; it exudes its own rhythm; it glistens to use Ronald Barthes apt phrasing from his short book The Pleasure of Text, which I just finished as part of my theoretical escape into the pleasure-dome. Although there are parts of his book which are to be frank, *really* *not* *pleasurable*, partly due to obscure references to High French Theory, which elide even an academic pair of eyes, the book generally pleases. And one of the most pleasing chunks is his definition of a stereotype:
The stereotype is the word repeated without any magic, any enthusiasm, as though it were natural, as though by some miracle this recurring words were adequate on each occasion for different reasons, as though to imitate could no longer be sensed as an imitation: an unconstrained word that claims consistency and is unaware of its own insistence
In contrast to the stereotype, a string of words that enchants does so by slipping off the page to hit you squarely in the heart or the gut. Unfortunately, while academic writing steers clear of stereotypes, often trying to present the detailed singularity of a phenomena (even when conditioned by social forces), it does not exactly glisten, though there are a handful of exceptions. I think we need more texts that glisten, even if only during sections or parts of our books and articles (much like the rant helped enliven the more staid technical document). In recent years, in large part due to the influence of free software, there has been an explosion, a move toward going open access. All of this is laudable and I fully embrace it (and have gotten into some small battles over it). But without an aesthetic politics that values pleasure in reading and writing we are doomed to obscurity anyway. A move toward making our knowledge public also required a move toward thinking about the literary aesthetics of pleasure.

Adrian von Bidder: Why Public Health-Care is Difficult

A reply to Tore, who is probably partly wrong. I don't claim the U.S. system is good or bad, I don't know it. But I don't think public (which he seems to imply means free) health care is as easy as he suggests. I'm starting at his assertion that
Very few people break their legs intentionally to stay at a nice hospital. [Health care] is not a resource likely to be wasted once people are given free access to it.
The case of a broken leg is easy. What about chronic illnesses, especially those difficult to diagnose (some kinds of back pain, psychological problems, ...)? What about bored old people who spend their days talking to doctors about how bad getting older is? Easily available (cheap or free) health care has lead to hospitals being swamped with people with minor issues to the point where people with serious problems died because hospital staff didn't get to them in time. And, because the state's budget is not infinite, hospitals become badly run institutions with always-overworked staff leading to even fewer people wanting to work there etc. This has happened in the UK, for example (I think the system I have been reading about ages ago has since been replaced by a different one.) Switzerland doesn't have this problem (to this extent) because we really care about (this means, here: throw money at) our health system, but the result is that the mandatory health insurance becomes insanely expensive. There is talk about half the population needing state subsidies to pay for their health insurance within the next few years. Which, of course, will just move the cost from the whole population (via mandatory health insurance) to the whole population (via taxes) so I don't quite see the point... You'll note I don't propose solutions either. But I think it's important to acknowledge that health care is a difficult topic because, in the end, it always comes down to the question How much money should be spent on this person's illness? which is a very, very bad question. We try to sidestep it by only taking about statistics etc., but no matter how you look at it, you either do 20'000 per week medications for 80 year old patients who will die soon anyway and get a system society can't pay, or you don't and you get a system where the rich are better off than the poor. Or you delegate the decision to the doctor or the insurance or ... and try to minimize the number of people who deserve (can you see it, the hard question didn't get away!) treatment but don't get it. Update 20090508 - Response to comments I'd like to thank you for commenting. I didn't know (and sorry about that didn't care to research) that the U.S. system is even more expensive than ours, since my main message is just that health care is about hard decisions. Some people always will be left out. Elaborating a bit on the 20'000 a week medication: partly, I agree with Adrian and Tore: patent-supported monopolies on medication plays a part. Partly, because I stipulate there will always be rare illnesses where a few cases per year worldwide will have to pay for all the research and production of the medication. Of course, the cost can be distributed so that the patient (or his insurance) doesn't have to pay it, but society as a whole will still pay. So the hard question won't go away easily, now it's just become Do we fund research for this rare illness with fewer than five cases per year worldwide? Of course, now we're not speaking of people anymore, but already just of cases, and we're not cutting treatment for an actual person but we're just cutting budget on research, so it may be easier on the conscience, but it's still fundamentally the same question. Conclusion? Health-care will always be a difficult topic, and it will never be free. The cost can just be distributed in different ways.

6 May 2009

Tore S. Bekkedal: Why public health care is a no-brainer to me

I m a social democrat/democratic socialist, and I m baffled by the health care system in the United States. I thought I d jot down/brain dump my main arguments for public health care: Everyone needs health care, but nobody seeks it out
Health care is a necessity in unpleasant circumstances. When you break your leg, you need health care. Very few people break their legs intentionally to stay at a nice hospital. Therefore, it is not a resource likely to be wasted once people are given free access to it. Given that everyone needs it when they need it and don t when they don t, paying it via the state budget is unlikely to cause waste.
Hospitals become badly run when run for profit
I think the point of motivation from the objective self-interest is overstated and harmfully over-emphasized, but the point bears making. For-profit hospitals are run for profit. Fancy that. A for-profit institution has an interest in your using their services as much as possible, at the expense of who-ever is paying the bill, be it your health insurance, or your fifth mortgage. A public institution wants to get you out of the system as soon as possible - by curing you. So the self-interest of the patient aligns much better with a public hospital. Although a certain measure of inefficiency is added when run by a governmental organization, I believe the inefficiency induced by the hospital s profit motive is probably much greater, perhaps more so in countries without a corporate culture in the government that seems to accept ineptitude. Close enough for government work is *not* a phrase used in Norway - for a reason. (Nevertheless, it bears mentioning that the most efficently-run hospital in the United States is the government-run Veteran s Aid.)
Denying health care to people who need it is not nice
The justification that a system has to be that way for the greater good is dangerous and bad and wrong. People needing health care should have it under all circumstances, and I consider it a matter of elementary respect for the dignity of human life that health care should be a right of citizenship. What kind of society measures the worth of a human being by the size of their wallet?
Healthy people are more productive
If you re the bean-counter sort, this point may appeal to you. I don t think it very relevant, but it seems quite plausible. The societal cost of people calling in sick is probably greater than any potential cost in efficiency from nationalization.
One point specific to the US: The current implementation in the US is, AFAICT, deeply flawed and needs Change (WCBI) anyway.
The US health care system is insanely flawed. It needs to change anyway - why not do so with a bang rather than a whimper. I think that the Democratic resurgency has given the party a mandate for quite a lot of bang. When a president wins on a single word, change , then go change things.
Got any more points? Disagree? I d love a conversation in the comments.

MJ Ray: Koha IRC General Meeting

There will be a general meeting on the #koha IRC channel on Wednesday, 6 May 2009 at 19:00 UTC with a nominal finish time of 21:00. To convert to your timezone, try date -d @1241636400 (thanks to SPI (Joerg?) for that idea). The meeting will include Koha 3.2/tip status and timeline, Koha 3.0.x status, Koha bugs database, KohaCon 2009 report. The full agenda is on the wiki. Connection details are shown on the wiki front page but are basically irc://irc.katipo.co.nz:6667/#koha Hope to see you there, or a summary should be linked from the comments here later.

Daniel Kahn Gillmor: HOWTO prep for migration off of SHA-1 in OpenPGP

Last week at eurocrypt, a small group of researchers announced a fairly serious attack against the SHA-1 digest algorithm, which is used in many cryptosystems, including OpenPGP. The general consensus is that we should be moving in an orderly fashion toward the theater exits, deprecating SHA-1 where possible with an eye toward abandoning it soon (one point of reference: US gov't federal agencies have been directed to cease all reliance on SHA-1 by the end of 2010, and this directive was issued before the latest results). Since Debian relies heavily on OpenPGP and other cryptographic infrastructure, i'll be blogging about how Debian users can responsibly and carefully migrate toward better digests. This post focuses on some first steps for users of gpg, and for Debian Developers and Debian Maintainers in particular. The good news is that gpg and gpg2 both support digest algorithms from the stronger SHA-2 family: SHA512, SHA384, SHA256, and SHA224. By using these stronger digest algorithms some of your signatures may be un-readable by users of older software. However, gpg and PGP (a proprietary implementation) have both had support for at least SHA256 for well over 5 years. Debian's gnupg packages have supported the full SHA-2 family since sarge. However, most existing signatures in today's Web of Trust were made over the SHA-1 digest algorithm, which means that abandoning it immediately would cause the Web of Trust as we know it to evaporate. So we need to rely on SHA-1-based signatures until a reasonably-fleshed-out Web of Trust based on stronger digests is in place. Since we don't want to have to rely on SHA-1 for too much longer, we need to collectively start the transition now. So what can you do to help facilitate the move away from SHA-1? I'll outline three steps that current gpg users can do today, and then i'll walk through how to do each one: The first two are simple, quick, and painless actions. You'll be done with them in minutes! The third is tougher, and while you can start it today, key transitions take a little bit of time to complete. Read on for a HOWTO! This entry has been truncated read the full entry.Tags: cryptography, openpgp, security, sha1, tip

5 May 2009

Manoj Srivastava: Manoj: Debian list spam reporting the Gnus way

So, recently our email overlords graciously provided means for us minions to help them in their toils and help clean up the spammish clutter in the mailing lists by helping report the spam. And the provided us with a dead simple means of reporting such spam to them. Now, us folks who knoweth that there is but one editor, the true editor, and its, err, proponent is RMS, use Gnus to follow the emacs mailing lists, either directly, or through gmane. There are plenty of examples out there showing how to automate reporting spam to gmane, so I won t bore y all with the details. Here I only show how one serves our list overlords, and smite the spam at the same time. Some background, from the Gnus info page. I ll try to keep it brief. There is far more functionality present if you read the documentation, but you can see that for yourself.
The Spam package provides Gnus with a centralized mechanism for detecting and filtering spam. It filters new mail, and processes messages according to whether they are spam or ham. There are two contact points between the Spam package and the rest of Gnus: checking new mail for spam, and leaving a group. Checking new mail for spam is done in one of two ways: while splitting incoming mail, or when you enter a group. Identifying spam messages is only half of the Spam package s job. The second half comes into play whenever you exit a group buffer. At this point, the Spam package does several things: it can add the contents of the ham or spam message to the dictionary of the filtering software, and it can report mail to various places using different protocols.
All this is very plugin and modular. The advantage is, that you can use various plugin front ends to identify spam and ham, or mark messages as you go through a group, and when you exit the group, spam is reported, ham and spam messages are copied to special destinations for future training of your filter. Since you inspect the marks put into the group buffer as you read the messages, there is a human involved in the processing, but as much as possible can be automated away. Do read the info page on the Spam package in Gnus, it is edifying. Anyway, here is a snippet from my etc/emacs/news/gnusrc.el file, which can help automate the tedium of reporting spam. This is perhaps more like how Gnus does things than having to press a special key for every spam, and which does nothing to help train your filter.
    1  (add-to-list
    2   'gnus-parameters
    3   '("^nnml:\\(debian-.*\\)$"
    4           (to-address . "\\1@lists.debian.org")
    5           (to-list . "\\1@lists.debian.org")
    6           (admin-address . "\\1-request@lists.debian.org")
    7           (spam-autodetect . t)
    8           (spam-autodetect-methods spam-use-gmane-xref spam-use-hashcash spam-use-BBDB)
    9           (spam-process '(spam spam-use-resend))
   10           (spam-report-resend-to . "report-listspam@lists.debian.org")
   11           (subscribed . t)
   12           (total-expire . t)
   13           ))

4 May 2009

Eugene V. Lyubimkin: cupt: let me introduce it

Cupt is experimental re-implementation of APT suite from scratch using Perl .
It consists of Perl modules and console front-end to them.

Why?

- to finally avoid some bugs in APT design;
- to introduce some useful features;
- to make an extensible and readable codebase;


What infrastructure does Cupt use?

It uses the same APT infrastructure, e.g. index files, deb cache archive
files, configuration files. It understands some of widely used APT options.


What useful features has Cupt already?

- full-case strict dependency problem resolver;
- command-line and APT-like option name checker;
- case-sensitive search;
- pinning by source package name;
- pinning by package groups using shell-like patterns;
- configurable 'depends' and 'rdepends' subcommands;
- 'satisfy' subcommand.

What features will Cupt have in future?

See incomplete roadmap.


Why is it 'experimental'?

Because not all important functionality is implemented yet:
- 'update' action;
- cooperating with debconf;
- working with source packages;
- translated package descriptions;


Why Perl?

- I like Perl
- code conciseness
- code extensibility
- several useful libraries available


Can I use Cupt along with APT?

Yes, you can mix apt-get/apt-cache/aptitude/etc. with cupt without bad consequences.


Can I build a Debian package for Cupt?

Yes, go to repository, checkout it and build the Debian package as usual.


What's the status of Cupt in Debian?

It's currently in the NEW queue, but don't rush to try root-required actions because it's still experimental.


Who am I?

The man who had been contributing to the APT.

Next.

Previous.

