Search Results: "tar"

13 October 2012

Guido G nther: Preseeding Debian virtual machines with virt-install

Interactively installing Debian virtual machines with virt-install without having to download anything in advance can already be done by pointing it to a Debian mirror via --location. But you can also add files to the initrd after downloading using --initrd-inject. Upstreams intended use is for kickstart files but we can also feed it a preseed.cfg to automate the whole installation:
virt-install --connect=qemu:///system \
             --location=http://ftp.us.debian.org/debian/dists/stable/main/installer\-i386 \
             --initrd-inject=/path/to/preseed.cfg \
             --extra-args="auto" \
             --name d-i --ram=512 \
             --disk=pool=default,size=5,format=qcow2,bus=virtio
preseed.cfg is a regular preseed file (as described in the Debian Wiki) in your local filesystem. I'm using this one for Squeeze and Wheezy VMs. It must be named preseed.cfg in order for d-i to pick it up from the initrd. This also works for URLs like qemu+ssh://<remotehost>/system/ since virt-install uses libvirt's streaming API to upload the kernel and modified initrd to the remote host. In case you're running this on an i386 you'll need this fix which already sits in experimental. This blog is flattr enabled.

Russell Coker: Creating WordPress Packages

deb http://www.coker.com.au wheezy wordpress I maintain Debian packages of a number of WordPress themes and plugins for my personal use which I am not planning to upload to Debian due to the maintenance and security issues. Generally the way things work with WordPress packages (and apparently most things in PHP) is that new versions are released whenever the author feels like it with little documentation and often now way of determining whether it s a security issue. When there is a security issue it s often fixed in a new version that includes new features giving no good option for someone who was happy with the old functionality and just wants a secure system. This isn t the way we like to do things in Debian. The result of this is that I maintain a number of packages for my personal use (and for the benefit of any interested people on the Internet) that often get new updates. I ve written the below script to create a new version of a Debian package. It searches my repository for the most recent .debian.tar.gz file for the package, applies that, runs dch -i to update the changelog, and then builds the package. So far this has only been tested on one package, I expect that I ll have to put a sed command in there to cover the case where the zip file name doesn t match what I want as the package name and I ll probably find other bugs in future, but I think it s good enough to publish now. #!/bin/bash
set -e
REPOSITORY=/home/whatever
unzip $1
FILE=$(basename $1)
PACKAGE=$(echo $FILE sed -e "s/\..*$//")
LEN=$(($(echo $PACKAGE wc -c)+1))
VER=$(echo $FILE cut -c $ LEN -200 sed -e s/.zip//)
DIRNAME=wordpress-$ PACKAGE -$ VER
mv $PACKAGE $DIRNAME
tar czf wordpress-$ PACKAGE _$ VER .orig.tar.gz $ DIRNAME
cd $DIRNAME
tar xzf $(ls -tr $ REPOSITORY /wordpress-$ PACKAGE _*.debian.tar.gz tail -1)
dch -i
dpkg-buildpackage Any suggestions for improvement will be welcome, I don t claim to be the world s greatest shell scripter. But please note that I generally aim to write shell scripts that can be understood by people who aren t experts. So if you can replace the program with a single line of Perl I will be impressed but I won t implement your solution. Related posts:
  1. WordPress Maintainability For a while I ve been maintaining my own WordPress packages....
  2. permalinks in wordpress, Apache redirection, and other blog stuff When I first put my new blog online I didn t...
  3. WordPress Plugins I ve just added the WordPress Minify [1] plugin to my...

12 October 2012

Johannes Schauer: analyzing Packages and Sources from snapshot.debian.org

When I wanted to use my dependency graph analysis tools to analyze earlier states of Debian Sid, I naturally used snapshot.debian.org to retrieve the Packages and Sources files from which my tools retrieve the dependency information. The problem is, that many of those Packages and Sources files contain syntax errors that make the dose3 parser choke. This leads to my tools being unable to parse the affected files. The following script does not only download all Packages and Sources files in a five day interval (4460 MB from 2005/03/12 to 2012/10/11) but also cleans all the syntax errors that were not parsable by dose3. This includes invalid version naming, architecture lists separated by commas, disjunctions in Conflict fields and incorrect braces/bracket usage. Maybe this helps others who also want to profit from Packages and Sources files from the past. Fun fact #1: starting from June 2010, there were no more syntax errors in the Packages and Sources files of Debian Sid. Fun fact #2: starting from December 2009, there are no more mismatches between versions of binary packages in the Packages file and the versions of the corresponding source packages in the Sources file. <script src="https://gist.github.com/3880904.js"> </script>

Russell Coker: Cheap Bulk Storage

The Problem Some of my clients need systems that store reasonable amounts of data. This is enough data that we can expect some data corruption on disk such that traditional RAID doesn t work, that old fashioned filesystems like Ext3/4 will have unreasonable fsck fimes, and that the number of disks in a small server isn t enough. NetApp is a really good option for bulk reliable storage, but their products are very expensive. BTRFS has a lot of potential, but the currently released versions (as supported in distributions such as Debian/Wheezy) lack significant features. One significant lack in current BTRFS releases is something equivalent to the ZFS send/receive functionality for remote backups, this was a major factor when I analysed the options for hard drive based backup [1], and you should always think about backup before deploying a new system. Currently ZFS is the best choice for bulk storage which is reliable if you can t afford NetApp. Any storage system needs a minimum level of reliability if only to protect it s own metadata and a basic RAID array doesn t protect against media corruption with current data volumes. The combination of performance, lack of fsck (which is a performance feature), large storage support, backup, and significant real-world use makes ZFS a really good option. Now I need to get some servers for more than 8.1TiB of storage (the capacity of a RAID-Z array of 4*3TB disks). One of my clients needs significantly more, probably at least 10 disks in a RAID-Z array so none of the cheaper servers will do. Basically the issue that some of my clients are dealing with (and which I have to solve) is how to provide a relatively cheap ZFS system for storing reasonable amounts of data. For some systems I need to start with about 10 disks and be able to scale to 24 disks or more without excessive expense. Also to make things a little easier and cheaper 24*7 operation is not required, so instead of paying for hot-swap disks we can just schedule down-time outside business hours. The Problem with Dell Dell is really good for small systems, the PowerEdge tower servers that support 2*3.5 or 4*3.5 disks and which have space for an SSD or two are really affordable and easy to order. But even in the mid-size Dell tower servers (which are small by server standards) you have problems with just getting a few disks operating outside a RAID array [2]. The Dell online store is really great for small servers, any time I m buying a server for less than $2500 I check the Dell online store first and usually their price is good enough that there is no need to get a quote from another company. Unfortunately all the servers with bigger storage involve disks that are unreasonably expensive (it seems that Dell makes their profit on the parts) and prices are not available online. I gave my email address and phone number to the Dell web site on Wednesday and they haven t cared to get back to me yet. This is the type of service that makes me avoid IBM and HP for any server deployment where the Dell online store sells something suitable! BackBlaze For some time BackBlaze have been getting interest by describing how they store lots of data in a small amount of space by tightly stacking SATA disks. They don t think that ZFS on Linux is ready for production, but their hardware ideas are useful. They have recently described their latest architecture [3]. They describe it as 135TB for $7,384. Of course the 135TB number is based on the idea of getting the full 3TB capacity out of each disk which they can do as they have redundancy over multiple storage pods. But anyone who wants a single fileserver needs some internal redundancy to cover disk failure. One option might be to have three RAID-Z2 arrays of 15 disks which gives a usable capacity of 42*3TB==126TB==113TiB. Note that while the ZFS documentation recommends between 3 and 9 disks per zpool for performance I don t expect performance problems, when you only have a gigabit Ethernet connection there shouldn t be a problem with three ZFS zpools making the network the bottleneck. For this option the way to go would be to start with an array of 15 disks and then buy a second set of 15 disks when the first storage pool becomes full. It seems likely that 4TB disks will become cheap before a 35TiB array is filled so we can get more efficiency by delaying purchases. The BackBlaze pod isn t cheap, they are sold as a complete system without storage disks for $US5,395 by Protocase [4]. That gives a markup of $US3,411 over the BackBlaze cost which isn t too bad given that BackBlaze are quoting the insane bulk discount hardware prices that I could never get. Protocase also offer the case on it s own for anyone who wants to build a system around it. It seems like the better option is to buy the system from Protocase, but that would end up being over $6,000 when Australian import duty is added and probably close to $7,000 when shipping etc is included. Norco Norco offers a case that takes 24 hot-swap SATA/SAS disks and a regular PC motherboard for $US399 [5]. It s similar to the BackBlaze pod but smaller, cheaper, and there s no obvious option to buy a configured and tested system. 24 disks would allow two RAID-Z2 arrays of 12 disks, the first array could provide 27TiB and the second array could provide something bigger when new disks are released. SuperMicro SuperMicro has a range of storage servers that support from 12 to 36 disks [6]. They seem good, but I d have to deal with a reseller to buy them which would involve pain at best and at worst they wouldn t bother getting me a quote because I only want one server at a time. Conclusion Does anyone know of any other options for affordable systems suitable for running ZFS on SATA disks? Preferably ones that don t involve dealing with resellers. At the moment it seems that the best option is to get a Norco case and build my own system as I don t think that any of my clients needs the capacity of a BackBlaze pod at the moment. Supermicro seems good but I d have to deal with a reseller. In my experience the difference between the resellers of such computer systems and used car dealers is that used car dealers are happy to sell one car at a time and that every used car dealer at least knows how to drive. Also if you are an Australian reader of my blog and you want to build such storage servers to sell to my clients in Melbourne then I d be interested to see an offer. But please make sure that any such offer includes a reference to your contributions to the Linux community if you think I won t recognise your name. If you don t contribute then I probably don t want to do business with you. As an aside, I was recently at a camera store helping a client test a new DSLR when one of the store employees started telling me how good ZFS is for storing RAW images. I totally agree that ZFS is the best filesystem for storing large RAW files and this is what I am working on right now. But it s not the sort of advice I expect to receive at a camera store, not even one that caters to professional photographers. Related posts:
  1. Cheap SATA Disks in a Dell PowerEdge T410 A non-profit organisation I support has just bought a Dell...
  2. ZFS vs BTRFS on Cheap Dell Servers I previously wrote about my first experiences with BTRFS [1]....
  3. Flash Storage and Servers In the comments on my post about the Dell PowerEdge...

11 October 2012

Eddy Petri&#537;or: A shitstorm is comming

It has been brought to my attention that a company selling some so-called colon cleansing product wanted to threat with a law suit a Romanian skeptical blogger because he wrote some articles showing that any such products (the one produced by the said company is the most known/popular in Romania) are pure quackery and there is no scientific basis for the claim they make in order to promote their products.

In his articles he also explained how, in fact, the mucoid plaque, the thing that supposedly proves the efficiency of the product, it is a result of taking the product due to its ingredients, and how no such mucoid plaque was ever observed in any colonoscopy, colon surgery or any other situation where you'd expect it to be seen. He also quoted specialists and lots of other scientific references, showing an honest approach to the issue.

As a response to the initial take-down message from the company doing business with people's crap, the blogger said would like to see scientific proof for the claims made for the product, and when that was to happen, he would take down the articles and publish a correction.

The company decided that the best way to continue this was to try to make a legal threat and ask 100.000 euros (one hundred thousands Euros) as damage in a country where, according to the latest data from the National Statistics Institute, the total average monthly personal income is about 180 Euros.

The blogger, as a reply, decided the threat should be made public and wrote another article which probably made the company very unhappy, because they decided to sue Wordpress so they would take down the blog.

And that's exactly what they did, they sued Wordpress, and sent some documents to Wordpress who sent them to the blogger. Among the documents there were 4 pdf files containing each an original article (in Romanian) from the blog and only 3 pdf containg English translation for only 3 of them. The one missing was the one where the blogger himself showed there wasn't any legal basis for the threats they made initially against him.

Here are the translations (ironically, made on the company's own expense):

Initial article entitled "ColonHelp doesn't help the colon. But it empties your wallet!" (original here)
Initial Article.en<iframe class="scribd_iframe_embed" data-aspect-ratio="0.701030927835051" data-auto-height="true" frameborder="0" height="600" id="doc_83859" scrolling="no" src="http://www.scribd.com/embeds/109756494/content?start_page=1&amp;view_mode=scroll&amp;access_key=key-19l4sbejfk4l4na4feoe" width="100%"></iframe>


The second article entitled "Again about ColonHelp and intestinal cleansers" (original here)
Follow Up.en<iframe class="scribd_iframe_embed" data-aspect-ratio="0.70264064293915" data-auto-height="true" frameborder="0" height="600" id="doc_46722" scrolling="no" src="http://www.scribd.com/embeds/109757646/content?start_page=1&amp;view_mode=scroll&amp;access_key=key-1d0z2779liaialmv90r5" width="100%"></iframe>


** Missing translation of the first reply to threats (original Romanian text here)


The second article about the threats entitled "People who clean the colon have filled the fan with shit" (original here)
Threats 2<iframe class="scribd_iframe_embed" data-aspect-ratio="0.705069124423963" data-auto-height="true" frameborder="0" height="600" id="doc_72956" scrolling="no" src="http://www.scribd.com/embeds/109758037/content?start_page=1&amp;view_mode=scroll&amp;access_key=key-2d3c3eq1d6lo313fogho" width="100%"></iframe>


The Romanian blogger explains himself more of the details on this issue in his latest article on his blog.

The company is called Zenyth Pharmaceuticals and Wordpress will probably lose the lawsuit by not presenting themselves in any way in the Romanian courts, but I think some Streisand effect would really help the asses of this company to get them kicked in their rightful place, at the top of the hall of shame.

The product name is called ColonHelp.

Please spread this information as wide as possible.
Do NOT link to the company's site (it would raise its search engine rank), but link to the blogger' article or the translations.


If any Romanian speaker cares to translate the untranslated article and publish it somewhere on the web, I would be more than glad to update this article and add a link to that translation.

Simon Josefsson: Portable Symmetric Key Container (PSKC) Library

For the past weeks I have been working on implementing RFC 6030, also known as Portable Symmetric Key Container (PSKC). So what is PSKC? The Portable Symmetric Key Container (PSKC) format is used to transport and provision symmetric keys to cryptographic devices or software. My PSKC Library allows you to parse, validate and generate PSKC data. The PSKC Library is written in C, uses LibXML, and is licensed under LGPLv2+. In practice, PSKC is most commonly used to transport secret keys for OATH HOTP/TOTP devices (and other OTP devices) between the personalization machine and the OTP validation server. Yesterday I released version 2.0.0 of OATH Toolkit with the new PSKC Library. See my earlier introduction to OATH Toolkit for background. OATH Toolkit is packaged for Debian/Ubuntu and I hope to refresh the package to include libpskc/pskctool soon. To get a feeling for the PSKC data format, consider the most minimal valid PSKC data:
<?xml version="1.0"?>
<KeyContainer xmlns="urn:ietf:params:xml:ns:keyprov:pskc" Version="1.0">
  <KeyPackage/>
</KeyContainer>
The library can easily be used to export PSKC data into a comma-separated value (CSV) format, in fact the PSKC library tutorial concludes with that as an example. There is complete API documentation for the library. The command line tool is more useful for end-users and allows you to parse and inspect PSKC data. Below is an illustration of how you would use it to parse some PSKC data, first we show the content of a file pskc-figure2.xml :
<?xml version="1.0" encoding="UTF-8"?>
<KeyContainer Version="1.0"
	      Id="exampleID1"
	      xmlns="urn:ietf:params:xml:ns:keyprov:pskc">
  <KeyPackage>
    <Key Id="12345678"
         Algorithm="urn:ietf:params:xml:ns:keyprov:pskc:hotp">
      <Issuer>Issuer-A</Issuer>
      <Data>
        <Secret>
          <PlainValue>MTIzNA==
          </PlainValue>
        </Secret>
      </Data>
    </Key>
  </KeyPackage>
</KeyContainer>
Here is how you would parse and pretty print that PSKC data:
jas@latte:~$ pskctool -c pskc-figure2.xml 
Portable Symmetric Key Container (PSKC):
	Version: 1.0
	Id: exampleID1
	KeyPackage 0:
		DeviceInfo:
		Key:
			Id: 12345678
			Issuer: Issuer-A
			Algorithm: urn:ietf:params:xml:ns:keyprov:pskc:hotp
			Key Secret (base64): MTIzNA==
jas@latte:~$
For more information, see the OATH Toolkit website and the PSKC Library Manual. flattr this!

Paul Tagliamonte: Stuff that's bothering me about Ubuntu right now

As many of you know, I love Ubuntu. I ve given years of my life for Ubuntu. I ve served as much as anyone s expected to, and long upheld the ideology and technical motivations behind Ubuntu as second to none. Until recently. Now, with advertisements in the default DE (and don t tell me they re not, when I search for term and get The Terminator on DVD, it s a ad if you care so much about whatever binding to search applications, why not disable ads by default, and let super-s do your shopping ), and now, begging for a handout when people Download Ubuntu without an option to donate to Debian, which composes over 70% of the Desktop, I get upset. I feel cheated, and I m not even involved on a day-to-day anymore. I m ashamed of what s going on now, and I hope we find a better way to serve our users.

10 October 2012

Jonathan Carter: LTSP By The Sea 2012


Last weekend I was in Southwest Harbour, Maine again for the annual LTSP hackfest (called By The Sea). It s a fun and productive event and as always it s been good catching up with LTSP folk, even though we were missing Oliver, Alkis and Vagrant. Here is a summary of what I can recall from the discussions of the weekend Recent Happenings in LTSP Going Forward
  • Libpamssh - This has been ongoing work in the LTSP project that will allow you to authenticate against another machine using SSH with local PAM. This will make it somewhat trivial to adapt LightDM (Light Display Manager) as a remote login manager and we can then do away with LDM (LTSP Display Manager) which currently has several big limitations. Scott Balneaves and St phane Graber made big progress on this over the weekend and it s close to an initial release.
  • New LTSP Cluster Control Center - Simon Poirier has been working on a new LTSP Cluster Control Center, the old one has been rusting away and other attempts at rewriting it didn t quite work out. He did a demonstration of the proof-of-concept code and it s looking quite nice already.
  • Squashed Bugs - Marc Gari py took some time to squash some bugs: LP: #996533, LP: #1048689 and LP: #1062947
  • Documentation - I m taking it upon myself to fix some problems we have with documentation. The lts.conf documentation is incomplete and difficult to maintain, so I will be going through the client/server code and tag all the possible settings that there are so that we can auto-generate documentation from it. David Trask will be helping out there and will be writing some nice descriptions for the config settings.
  • LTSP 6.0 and the Future of LTSP - There was a good opening discussion about the future of LTSP. The combination of all the recent partial rewrites that Alkis has been doing combined with the deprecation of LDM will culminate in what will be called LTSP 6.0. There was also some interest in having an LTSP standalone distribution again (that can be installed on none-integrated distributions) and things like an LTSP live client disc. We were also wondering about the future of pure thin clients, many upstreams are writing software that aren t at all thin client friendly (Clutter-based software like Gnome Shell and Totem, Unity, etc) and at the same time, thin client hardware is becoming increasingly powerful. It s possible that there may be a focus on making diskless fat clients working even better with LTSP and make it easier to use remote-apps for running only certain applications the application servers. We re also quite interested in projects like FreeRDP for users who would still require pure thin clients.
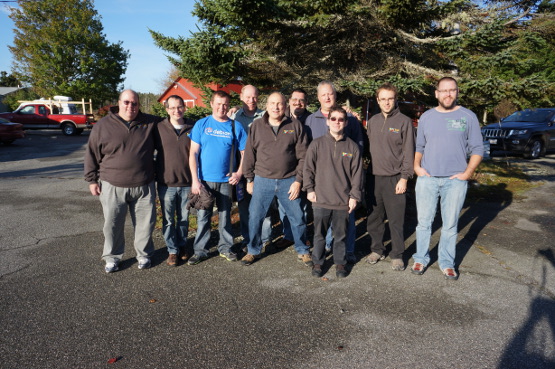
Social It was great seeing everyone again. I first started using LTSP around 9 years ago and never imagined back then that I d get to meet the people behind it. Ron Colcernian sourced us some really cool LTSP tops that you can see us wearing in the group photo. I hope to get to BTS again next year!

9 October 2012

David Welton: Fast, Light and Asynchronous

I am a big fan of Ruby on Rails: it does a lot of things, and it does most of them pretty well. When starting a new web project, it's the first thing I would reach for: most of the time, your problem is going to be figuring out a good product/market fit, or whipping up some internal tool without wasting a lot of programmer time. Once you've got a firm grasp of the problem, then maybe you can consider optimizing. Who cares if you do something that no one wants really really fast? However, Ruby on Rails is not beautiful in terms of being particularly fast or lightweight. No complaints from me: most of the time, I'm happy to have something that does so much for me, leaving me to work on the actual problem at hand. Once in a while, though, you do need fast and relatively lightweight, and that space has been getting more interesting over the past few years, at least in terms of the web. First of all, technologies like "Comet", utilizing web sockets or some other always-on connection are becoming more common, where a socket with the server remains open in order to quickly exchange data from the server to the client - and back. That seems to be a poor fit for something like Rails, where it can tie up a lot of resources if one isn't careful. And while computing costs continue to decline, no one minds getting more for less in terms of what their server can do. Furthermore, with frameworks like Backbone.js, pushing more and more code to the client, the server can afford to be a bit simpler and do less, so it may as well be snappy to boot. Java has long been fairly popular for "heavy lifting" types of applications, partially because it does end up being reasonably fast. But it's not something I've ever had much fun using and is usually kind of wordy, and makes you feel like you need a crew of people in Palo Alto, one in Bangalore, and one in Stockholm just to churn out all the code. And it certainly is no lightweight in terms of memory either. So... while it can certainly do pretty much anything you need, I don't see it as being the strongest player when someone needs "real time web" code, and needs it to be reasonably light weight. Ruby, outside of standard Rails stuff like Passenger, seems to offer some interesting possibilities for this kind of work, like Reel but they don't seem to have the traction other solutions do. Python is in a similar situation: the Twisted framework has been around for a while, and while it has some success stories, never seems to have really 'caught fire'. Neither of these languages was built for "concurrency" from the ground up, and that seems to have, to date, inhibited people from using them extensively for this kind of job. My gut feeling is that the need for speed and "concurrency" (or at least handling a lot of concurrent users) will drive adoption of languages heretofore not so popular on the server. Let's have a look at them. Erlang: This is by no means a new language, having been developed in Ericsson in the late 1980ies; and it implements several interesting concepts. First and foremost, concurrency is handled in the form of many small "processes", which are not actually Unix processes at all, but processes internal to the Erlang VM. The Erlang system contains a scheduler that allocates resources to all of these processes, so even if one of them dies or behaves badly, it's not a problem: the system as a whole can continue to function well. The way Erlang is built, the scheduler is preemptive: the internal "processes" don't need to yield to let other processes run. Beyond the scheduler and simple processes, Erlang gives you the tools to create elaborate trees of supervisors and workers that are quite robust to failures in any one portion of the system, as well as giving you the tools to set up a system to run on multiple, distributed computers. This kind of thinking is necessary when you write applications, such as phone switches, where downtime is really, really not ok. Erlang processes comunicate almost exclusively via message passing, meaning that state is not shared. Altogether, this makes for a fast, rock solid system that can easily handle thousands of concurrent connections without breaking a sweat. The computing world being what it is though, Erlang is likely to be more of a Lisp or Smalltalk: it's a trailblazer that did many things years before their time in other languages, but I don't see it as ever quite catching on amongst 'the masses'. It has a wonky syntax, it's a functional programming language, and because it is used in environments where too much experimentation is not good, it does not have a lot of room to break with its own past and innovate in terms of the language itself: it's slow to change and improve, even where the need to is clearly perceived. Node.js: is the opposite, in some ways: being based on Javascript, it draws on a huge number of potential programmers - orders of magnitude more than Erlang. And thanks to design decisions enforcing the use of asynchronous code and callbacks for anything that could block, it deals quite well with concurrent connections, even if the language and libraries don't really give you much in terms of "true" concurrency. This is a simple model that works pretty well, even if, theoretically, all it would take is one "while (1)" loop in a callback to block the entire system. In practice, this doesn't seem to be a big problem, though. More of a problem is writing maintainable code, when everything is a callback. Keeping the network of callbacks straight can be a bit of a chore, and is probably not an optimal model in terms of programmer productivity. That said, people seem to do make due with it, although Node is young enough that we haven't seem projects that are 5 or 6 years old and maintained by people who didn't write them. One of the advantages of being such a popular language is that lots of people have a strong interest in seeing Javascript being very, very performant. That need begat the V8 Javascript engine, from Google, which they were kind enough to release as free software. So one of the advantages that Node has is that the underlying implementation is extremely fast for a dynamic language. For many people who know Javascript, picking up Node.js is also an easy choice, even though people used to browser side programming with Javascript will have to adjust their way of thinking to succesfully tackle server projects. Go language: this is an interesting one, written by some luminaries who work at Google. It can best be described as something akin to C with some updated features, such as garbage collection, that make it more suitable for working on large projects, where things like memory leaks are going to make life very frustrating. It has the feel of a "real language, for real programmers" in that it doesn't stray far too far from what people are used to - it's not going to cause the "what the hell is this?!" reactions that Erlang might in more close-minded circles. Between the big company backing it, and the approachable syntax and concepts, Go looks like it has a good shot at the mainstream. Where it gets interesting is their concurrency model, which is apparently based on something called "communicating sequential processes" which, superficially at least, looks like it has some things in common with Erlang's "actor model" of concurrency. Under the hood, Go apparently hives off its "goroutines" to different OS level threads, but does not have a preemptive scheduler like Erlang: http://code.google.com/p/go/issues/detail?id=543 - although according to this, they may change that in the future. I'm not enough of a computer science guy to comment much on the details of CSP vs Actors, but both seem like valid models with strengths compared to trying to keep threads straight, which always seems to be a source of problems for programmers. Conclusions So, what's actually going to happen? I see Node.js as the clear front runner. It takes a worse-is-better approach that seems to work well enough as people get started. If they encounter difficulties later, they can always rewrite in something else, if needs be, but by "luring people in", Node.js has gathered a large group of users who continue, in turn, to churn out more code for use with the system, making it more attractive to new users. Programming languages are not winner-take-all markets though, so perhaps there is room for a few more languages to have decent followings in this space. Hopefully the competition will lead to ever better tools for those of us utilizing them! What do you think?

Stefano Zacchiroli: bits from the DPL for September 2012

Just posted to d-d-a, bits from the DPL for Septemer 2012.
Heya,
here is the periodic report of DPL activities, this time related to September 2012 (posted here with some delay, as I've been traveling oversea on behalf of Debian for the past few days). Help needed: Google Code-In The Google Code-In (GCI) initiative is about to start again. We don't have a great track record of participating into it, and that's a pity. The initiative revolves around small tasks that other Free Software projects have come to call "easy hacks", showing how effective they're in attracting new volunteers. To participate, we need both mentors and admins. If you're interested see Ana's call for help and please volunteer on the soc-coordination list. Related to this, you've probably seen the report of our participation in GSoC 2012. I'd like to thank all students, mentors, and admins for a very well organized edition. Logo relicensing & other assets The DFSG-relicensing of the Debian logo, which I've mentioned in recent updates, has now happened. The so called Debian "Open Use" logo, in both variants (with and without "Debian") is now dually licensed under LGPL3+ / CC-BY-SA 3.0. The change has been made effective with a resolution of the SPI Board of Directors. Note that the so called "official" logo, which we seem to use very little, is still released under the terms of a non-free license. Discussion is ongoing on -project to stop promoting it. If you're using it or if you've arguments in favor of against that, please participate in the discussion. I've got from SFLC an updated draft of the new proposed trademark policy, implementing most of the changes requested during related August discussions on -project. I'll post it for review there shortly. The Japanese Trademark Office (JPO) has sent us the final confirmation that trademark transfer request (from individuals Debian contributors in the area to SPI) has happened. We've paid the needed fee of 457 CHF to conclude the transaction. We finally settled a domain transfer agreement with the current owner of the debian.eu. Technically, the domain will be transferred to FFIS in the coming weeks. Core teams (non-)news Quite some core teams are in the process of changing their formations these weeks, but most are still pending proper delegation (or equivalent). So here are just a few "teasers": I hope to finalize all the pending tasks above this month. Future events I've spent quite some time to plan my participation in events I'll be attending during October on behalf of Debian, such as the ACM Reflections conference in Urbana-Champaign (at the time of writing, this has already happened), the Ubuntu Developer Summit in Copenhagen, and the LinuxDay event in Turin. Cheers.
PS the day-to-day activity log for September 2012 is available at the usual place master:/srv/leader/news/bits-from-the-DPL.txt.201209

Christian Perrier: Bug #690000

(doh, I nearly had it. I just got #690019, #690020 and #690022 for l10n stuff) Bartek Krawczyk reported Debian bug #690000 on Monday October 8th, against guake. And my friend Sylvestre Ledru, the package maintainer, now has to fix it instead of trying to promote the use of Scilab over proprietary alternatives in the French aerospace research organizations..:-) Bug #680000 was reported as of July 2nd: 3 months and 8 days for 10,000 bugs. This is a VERY significant drop in the bug reporting rate in Debian. Last time, I wrote: "How will the wheezy freeze affect this? We'll see in two months!". We have the answer: the wheezy freeze triggerred an important drop in bug reporting rate in Debian. My general feeling is somehow different: for whatever reason, I feel like the *overall* activity in the project has dropped significantly. I seem to have less mails to read, less bugs reported against my packages, even less heated discussions here and there, as well as several very quiet channels on IRC. Am I pessimistic when feeling that the overall momentum is sliding out of Debian? Maybe I am, so, folks, please make me optimistic and move you fingers out of the place where they are and help releasing that damn penguin. Apart from that, our next milestone (apart from the wheezy release!) will be bug #700000. Remember the bet?. It looks like the probability of Kartik Mistry winning it is now away (he bet for Now 8th 2012) and the best position is hel by David Pr vot (he bet for December 12th). On the other hand, my own chances are increasing if the bug rate drop is confirmed and if bug #700000 is reported in more than 3 months (I bet for February 14th 2013, guess why?). We'll see that in a few weeks!

8 October 2012

Luke Faraone: Where I've gone off to

For those of you back at my university, you may have noticed I'm not there this semester.

Google's 2012 FEP team

I spent this past summer at Google, Inc, developing internal tools for the AdSense team, specifically Google Programmable Ads. Being at Google was great; I loved my team and my intern cohort, the rest of the interns in the Freshman Engineering Practicum.

I'm not currently at Google; my internship ended at the beginning of August. Although it was a blast, all good things must come to an end.

I'm not at Mason, either. I was super excited to return to university, and was just about to buy my books and get ready to move in when I got an email from a former coworker at Ksplice, a startup Oracle acquired while I interned there last year. He was starting a new company which would focus on business communications. I'd be working with a bunch of my former coworkers, and based on what I had heard of the company's plans I was confident in their ability to make an awesome product.

Needless to say, when they decided to offer me a position working there full time, I jumped on it.

From an academic point of view, Mason didn't really have much of a mechanism to support this. Co-ops are uncommon there, and not really supported for more than one semester; a full year away had never been done, according to our career services. My department was fully supportive, however, so we managed to find a way to make it work. This involved filling out some oddly-named forms, such as Special Registration for Graduation Request, which the registrar asserted was the right form, trust us on this one.

Myself and Obey Arthur Liu
at a SIPB hackathon
But that's all neither here nor there. I'm now up in Cambridge, MA, working with awesome people (including but not limited to tabbott, wdaher, jesstess, and keegan), and exploring the city. I'm hanging out with MIT SIPB, helping with the maintenance of Sugar Labs' servers in E15 and spending more time working on various open source projects.

To my friends at Mason: I miss you all. I know regardless of how the next year+ turns out, it'll be one one hell of a ride.

Craig Small: NTP control messages

I have had an opportunity to rework some code to query NTP servers directly in python rather than running ntpq -pn and scraping the result. The over-the-wire protocol format is reasonably straight forward and my little module is now passing all of its nosetests which is wonderful. While its only a single table, ntpq actually does multiple requests to get its results. NTP control messages are all mode 6 which tells the client and server its not time sort of things, but more about queries. A control packet has a sequence number which the server responds with so you can line up your requests with responses. For large responses, the more, offset and count fields work together to knit up a large block of data. The first packet of the response will have the offset field of 0. The count is the size of the data payload in bytes. If the response is too big, the more bit will be set to 1 to say there is more coming. The second packet will have an offset that is the same value as the previous packets count value, so you can stitch them together. The first query is a READSTAT which uses opcode 1. This returns a list of 4 byte responses with the association ID taking the first two bytes and the peer status taking the second. If you look at the output of ntpq you will notice a character in the first column which is the peer selection. The important one for us is asterix, which equates to 110 in the lower 3 bits of the first status byte. This is the system peer which is the main one. There may be others, up to 2, (usually symbol +) which are compared to the system peer. ntpq doesn t really care about the different peers and just displays the status but I want to know what peer the server is synchronised to. Next we need more details about the system peer (or all peers in ntpq). To do this a READVAR or opcode 2 is sent to the server. The association ID is set to the association or peer we are interested in. The response for my setup is sent over two packets which need to be reassembled and it is all in plain ascii which is a comma-separated list with a key=value pair. I use the following python line to split it up.
self.assoc_data.update(dict([tuple(ad.strip().split("=")) for ad in data[header_len:].split(",") if ad.find("=") &gt; -1]))
I m sure people that know python better than I will say I am doing it wrong (it looks a bit klunky to me too) but it does work. From that I can query the various values that are returned by the server about its peers, including the source of its clock.

Jonathan McDowell: KVM + usbmon + Wireshark == win

(This is something I did a few months ago, and I really should have noted down all the details then so I covered everything. However hopefully these notes will remind me enough next time.) When I first wanted to reverse engineer a USB device that only had Windows drivers the "easy" option was to take a Windows machine, install usbsnoop on it and capture the traffic as a bunch of verbose text files. It was a cumbersome procedure. Recently I wanted to do a firmware upgrade of a ZTE 3G modem dongle, partly to provider unlock it and partly to try and enable some voice functionality. I was also hoping to sniff the traffic to see how to drive the voice side of things. These days I don't have a dedicated Windows box, but I do have a Windows 7 KVM virtual machine. I hadn't yet used the USB support in this, but I thought I'd see what it was capable of. Firstly I had to explicitly enable USB2 - the device wasn't happy with the default USB1 only stack that KVM enabled. That involved passing -usb -device usb-ehci,id=ehci to KVM. I also told KVM to grab all the ZTE devices with -device usb-host,bus=ehci.0,vendorid=0x19d2. I dropped a udev rules file into /etc/udev/rules.d to ensure any device nodes created belonged to my normal user. This gave me a Windows setup that could see the USB dongle and install the appropriate drivers. It was also happy to do the firmware update (along with various device resets on the way as it changed USB ID - this is why I needed the udev rule, to ensure every time the device re-appeared it would be seen by the KVM instance without manual intervention). After that was complete I investigated usbmon. modprobe usbmon created the appropriate /dev/usbmon<n> files and I chowned the appropriate bus to my normal user. Once this was done I was able to start Wireshark which rather nicely has full USB decoding support. Firing up the custom app in the Windows KVM guest I could see the traffic going back and forth to each of the device endpoints and work out what was going on. All of this was much more flexible than using a standalone Windows box. Once I figured out that I needed to explicitly enable USB2 I was quite pleased with how simple USB access under KVM was. I also used lvm to create a snapshot of the Windows guest so at the end I could roll back all of the drivers I'd installed for the dongle. And being able to use Wireshark instead of trawling through dense text files helped a lot in seeing the command stream.

7 October 2012

Sune Vuorela: Playing with webstuff

So, the other day, I wrote a blog post asking people to make sure their private hacks become published somehow. So in the sprit of that, I should also publish my recent hacks. I have been toying around as a web dude and created two nice pieces of oldschool webby software. So. Time to introductions: Dodoma is a simple online note taking application. I have created a boring homepage for it on http://sune.vuorela.dk/dodoma and I have a screenshot here:
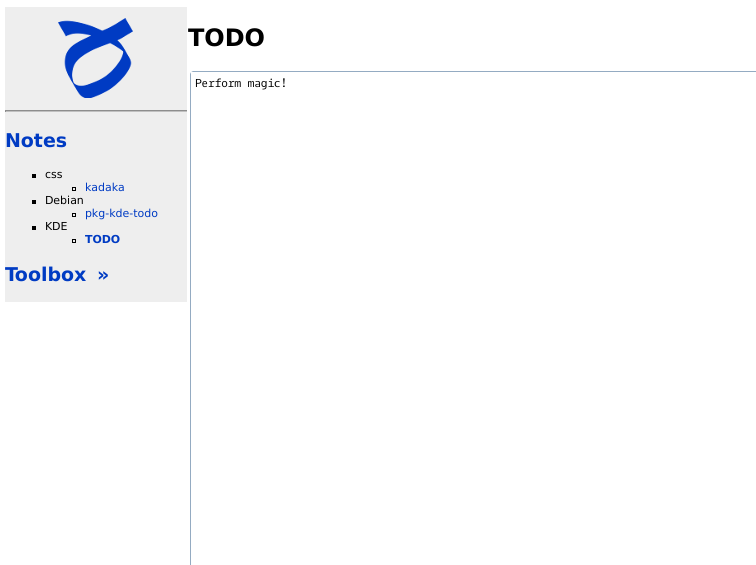
Screenshot of webapp Kadaka is a simple rss reader showing the five newest items from various rss feeds. Has special support for youtube channels.
I have created a boring homepage for it on http://sune.vuorela.dk/kadaka and I have a screenshot here:
Screenshot of kadaka Have fun with those two apps. Patches always welcome. Some of you might wonder where does he get those crazy names from . Well. One of them I found on a map. Thats actually a way I name quite many of my projects. Even those that don t even leave my harddrive. And the other one actually also is on a map, but I saw it on a frequently used bus in Tallin, Estonia. And. I am considering naming my next fancy projects after some of the cool words found on the join the game member page. If you want to be part of that, feel free to Join the game!

6 October 2012

Lars Wirzenius: Obnam 1.2 (backup software)

I've just made release 1.2 of Obnam, my backup program. The NEWS file entry: Bug fixes: This release has been uploaded to my own apt repository on code.liw.fi, for squeeze and unstable. Due to the Debian freeze, I am not uploading this to Debian at this time, though some changes may eventually be uploaded there.

Christian Perrier: [life] Running update

It's been some time since I didn't write in this blog about my running activities. So let's make an update for my international friends. If you don't care about running, you can move to the next post in your feed reader..:-) After a quite busy running activity during DebConf 12 in Nicaragua, as well as during the touristic trip we did afterwards, I went back to my "regular" schedule. Main objectives in September-December are roughly the following: During August, I broke my monthly distance record by running nearly 300km in one month, even achieving 100km in only 5 days, around 24th. That was one of my goals: improve my overall resistance to run repetitions, which is one of the keys for ultra-running. These were achieved with many runs to/back work, with up to 13km in the morning and the same in the evening. Yes, running 26km at about 11km/h (and with some ups and downs in the woods to make it even worse) on a day where one has a normal work activity is quite a challenge. September has been more focused on marathon preparation. This time, no complicated plan with interval running as the month was also a very busy work month, where fitting training sessions during the day would be hard. So, I made an easy plan : run a half-marathon every Sunday and run part of my work-home commute every day (So, 3km run to the train station, 30mn train ride, then 4km run to my work place, then shower....and the same back after work). Out of the 5 half-marathons I ran during these 5 Sundays, two of them were official ones. On the first one, I finally managed to break my personal best on half, with 1h37'14". Only a 14 seconds improvement, but that one is certainly one of my best among personal bests....even better than 3h38'45" on marathon.. All other half-marathons were run at marathon speed, so targeting 5'06"/km, which will be my planned pace on October 21st. The one I ran on Sept. 16th, which was the other official race I ran was finally done quite significantly faster than this. First of all, because I had hard times to run "only" at 5'06"/km because of other runners emulation. And also, because I ran the last 3 kilometers up to nearly 14km/h (so, down to 4'15"/km), just for fun, because I could do it..:-) With all this preparation, I think that I now manage to very well manage my marathon speed. I'll probably do a final test tomorrow by trying to keep running at this speed for 3 rounds of my favourite "Maurepas Marathon" circuit, which is just exactly 1/4 of a marathon. More "funnily", I also did something I never did before during this really crazy month : simply said, I came back from work by running. All the way long. Through woods, forests, along some lakes and finally in the country. 42 kilometers (yes, a marathon). After a work day. Starting at 5:45pm and arriving home after 4h50 minutes. With 2 hours of heavy rain. With 2.5 hours running in the dark (with my headlamp of course). All alone. That was a crazy bet to do....but really great fun achieving this : the GPS trace is here. Really something I have to do again..:-) So, well, now I'm more or less prepared and having fun is just a matter for time..:-). I'll keep you guys posted with those and, guess what? I'm already picking my target races for next year..:-)

5 October 2012

Keith Packard: fd-passing

FD passing for DRI.Next Using the DMA-BUF interfaces to pass DRI objects between the client and server, as discussed in my previous blog posting on DRI-Next, requires that we successfully pass file descriptors over the X protocol socket. Rumor has it that this has been tried and found to be difficult, and so I decided to do a bit of experimentation to see how this could be made to work within the existing X implementation. (All of the examples shown here are licensed under the GPL, version 2 and are available from git://keithp.com/git/fdpassing) Basics of FD passing The kernel internals that support FD passing are actually quite simple POSIX already require that two processes be able to share the same underlying reference to a file because of the semantics of the fork(2) call. Adding some ability to share arbitrary file descriptors between two processes then is far more about how you ask the kernel than the actual file descriptor sharing operation. In Linux, file descriptors can be passed through local network sockets. The sender constructs a mystic-looking sendmsg(2) call, placing the file descriptor in the control field of that operation. The kernel pulls the file descriptor out of the control field, allocates a file descriptor in the target process which references the same file object and then sticks the file descriptor in a queue for the receiving process to fetch. The receiver then constructs a matching call to recvmsg that provides a place for the kernel to stick the new file descriptor. A helper API for testing I first write a stand-alone program that created a socketpair, forked and then passed an fd from the parent to the child. Once that was working, I decided that some short helper functions would make further testing a whole lot easier. Here s a function that writes some data and an optional file descriptor:
ssize_t
sock_fd_write(int sock, void *buf, ssize_t buflen, int fd)
 
    ssize_t     size;
    struct msghdr   msg;
    struct iovec    iov;
    union  
        struct cmsghdr  cmsghdr;
        char        control[CMSG_SPACE(sizeof (int))];
      cmsgu;
    struct cmsghdr  *cmsg;
    iov.iov_base = buf;
    iov.iov_len = buflen;
    msg.msg_name = NULL;
    msg.msg_namelen = 0;
    msg.msg_iov = &iov;
    msg.msg_iovlen = 1;
    if (fd != -1)  
        msg.msg_control = cmsgu.control;
        msg.msg_controllen = sizeof(cmsgu.control);
        cmsg = CMSG_FIRSTHDR(&msg);
        cmsg->cmsg_len = CMSG_LEN(sizeof (int));
        cmsg->cmsg_level = SOL_SOCKET;
        cmsg->cmsg_type = SCM_RIGHTS;
        printf ("passing fd %d\n", fd);
        *((int *) CMSG_DATA(cmsg)) = fd;
      else  
        msg.msg_control = NULL;
        msg.msg_controllen = 0;
        printf ("not passing fd\n");
     
    size = sendmsg(sock, &msg, 0);
    if (size < 0)
        perror ("sendmsg");
    return size;
 
And here s the matching receiver function:
ssize_t
sock_fd_read(int sock, void *buf, ssize_t bufsize, int *fd)
 
    ssize_t     size;
    if (fd)  
        struct msghdr   msg;
        struct iovec    iov;
        union  
            struct cmsghdr  cmsghdr;
            char        control[CMSG_SPACE(sizeof (int))];
          cmsgu;
        struct cmsghdr  *cmsg;
        iov.iov_base = buf;
        iov.iov_len = bufsize;
        msg.msg_name = NULL;
        msg.msg_namelen = 0;
        msg.msg_iov = &iov;
        msg.msg_iovlen = 1;
        msg.msg_control = cmsgu.control;
        msg.msg_controllen = sizeof(cmsgu.control);
        size = recvmsg (sock, &msg, 0);
        if (size < 0)  
            perror ("recvmsg");
            exit(1);
         
        cmsg = CMSG_FIRSTHDR(&msg);
        if (cmsg && cmsg->cmsg_len == CMSG_LEN(sizeof(int)))  
            if (cmsg->cmsg_level != SOL_SOCKET)  
                fprintf (stderr, "invalid cmsg_level %d\n",
                     cmsg->cmsg_level);
                exit(1);
             
            if (cmsg->cmsg_type != SCM_RIGHTS)  
                fprintf (stderr, "invalid cmsg_type %d\n",
                     cmsg->cmsg_type);
                exit(1);
             
            *fd = *((int *) CMSG_DATA(cmsg));
            printf ("received fd %d\n", *fd);
          else
            *fd = -1;
      else  
        size = read (sock, buf, bufsize);
        if (size < 0)  
            perror("read");
            exit(1);
         
     
    return size;
 
With these two functions, I rewrote the simple example as follows:
void
child(int sock)
 
    int fd;
    char    buf[16];
    ssize_t size;
    sleep(1);
    for (;;)  
        size = sock_fd_read(sock, buf, sizeof(buf), &fd);
        if (size <= 0)
            break;
        printf ("read %d\n", size);
        if (fd != -1)  
            write(fd, "hello, world\n", 13);
            close(fd);


void
parent(int sock)
 
    ssize_t size;
    int i;
    int fd;
    fd = 1;
    size = sock_fd_write(sock, "1", 1, 1);
    printf ("wrote %d\n", size);
 
int
main(int argc, char **argv)
 
    int sv[2];
    int pid;
    if (socketpair(AF_LOCAL, SOCK_STREAM, 0, sv) < 0)  
        perror("socketpair");
        exit(1);
     
    switch ((pid = fork()))  
    case 0:
        close(sv[0]);
        child(sv[1]);
        break;
    case -1:
        perror("fork");
        exit(1);
    default:
        close(sv[1]);
        parent(sv[0]);
        break;
     
    return 0;
 
Experimenting with multiple writes I wanted to know what would happen if multiple writes were made, some with file descriptors and some without. So I changed the simple example parent function to look like:
void
parent(int sock)
 
    ssize_t size;
    int i;
    int fd;
    fd = 1;
    size = sock_fd_write(sock, "1", 1, -1);
    printf ("wrote %d without fd\n", size);
    size = sock_fd_write(sock, "1", 1, 1);
    printf ("wrote %d with fd\n", size);
    size = sock_fd_write(sock, "1", 1, -1);
    printf ("wrote %d without fd\n", size);
 
When run, this demonstrates that the reader gets two bytes in the first read along with a file descriptor followed by one byte in a second read, without a file descriptor. This demonstrates that a file descriptor message forms a barrier within the socket; multiple messages will be merged together, but not past a message containing a file descriptor. Reading without accepting a file descriptor What happens when the reader isn t expecting a file descriptor? Does it just get lost? Does the reader not get the message until it asks for the file descriptor? What about the boundary issue described above? Here s my test case:
void
child(int sock)
 
    int fd;
    char    buf[16];
    ssize_t size;
    sleep(1);
    size = sock_fd_read(sock, buf, sizeof(buf), NULL);
    if (size <= 0)
        return;
    printf ("read %d\n", size);
    size = sock_fd_read(sock, buf, sizeof(buf), &fd);
    if (size <= 0)
        return;
    printf ("read %d\n", size);
    if (fd != -1)  
        write(fd, "hello, world\n", 13);
        close(fd);
     
 
void
parent(int sock)
 
    ssize_t size;
    int i;
    int fd;
    fd = 1;
    size = sock_fd_write(sock, "1", 1, 1);
    printf ("wrote %d without fd\n", size);
    size = sock_fd_write(sock, "1", 1, 2);
    printf ("wrote %d with fd\n", size);
 
This shows that the first passed file descriptor is picked up by the first sockfdread call, but the file descriptor is closed. The second file descriptor passed is picked up by the second sockfdread call. Zero-length writes Can a file descriptor be passed without sending any data?
void
parent(int sock)
 
    ssize_t size;
    int i;
    int fd;
    fd = 1;
    size = sock_fd_write(sock, "1", 1, -1);
    printf ("wrote %d without fd\n", size);
    size = sock_fd_write(sock, NULL, 0, 1);
    printf ("wrote %d with fd\n", size);
    size = sock_fd_write(sock, "1", 1, -1);
    printf ("wrote %d without fd\n", size);
 
And the answer is clearly no the file descriptor is not passed when no data are included in the write. A summary of results
  1. read and recvmsg don t merge data across a file descriptor message boundary.
  2. failing to accept an fd in the receiver results in the fd being closed by the kernel.
  3. a file descriptor must be accompanied by some data.
Make X pass file descriptors I d like to get X to pass a file descriptor without completely rewriting the internals of both the library and the X server. Ideally, without making any changes to the existing code paths for regular request processing at all. On the sending side, this seems pretty straightforward we just need to get the X connection file descriptor and call sendmsg directly, passing the desired file descriptor along. In XCB, this could be done by using the xcbtakesocket interface to temporarily hijack the protocol as Xlib does. It s the receiving side where things are messier. Because a bare read will discard any delivered file descriptor, we must make sure to use recvmsg whenever we want to actually capture the file descriptor. Kludge X server fd receiving Because a passed fd creates a barrier in the bytestream, when the X server reads requests from a client, the read will stop sending data after the message with the file descriptor is consumed. Of course, this process consumes the passed file descriptor, and if that call isn t made with recvmsg set up to receive it, the fd will be lost. As a simple kludge, if we pass a meaningless fd with the X request and then the real fd with a following XNoOperation request, the existing request reading code will get the request, discard the meaningless fd and then stop reading at that point due to the barrier. Once into the request processing code, recvmsg can be called to get the real file descriptor and the associated XNoOperation request. I wrote a test for this that demonstrates how this works:
static void
child(int sock)
 
    uint8_t xreq[1024];
    uint8_t xnop[4];
    uint8_t req;
    int i, reqlen;
    ssize_t size, fdsize;
    int fd = -1, *fdp;
    int j;
    sleep (1);
    for (j = 0;; j++)  
        size = sock_fd_read(sock, xreq, sizeof (xreq), NULL);
        printf ("got %d\n", size);
        if (size == 0)
            break;
        i = 0;
        while (i < size)  
            req = xreq[i];
            reqlen = xreq[i+1];
            i += reqlen;
            switch (req)  
            case 0:
                break;
            case 1:
                if (i != size)  
                    fprintf (stderr, "Got fd req, but not at end of input %d < %d\n",
                         i, size);
                 
                fdsize = sock_fd_read(sock, xnop, sizeof (xnop), &fd);
                if (fd == -1)  
                    fprintf (stderr, "no fd received\n");
                  else  
                    FILE    *f = fdopen (fd, "w");
                    fprintf(f, "hello %d\n", j);
                    fflush(f);
                    fclose(f);
                    close(fd);
                    fd = -1;
                 
                break;
            case 2:
                fprintf (stderr, "Unexpected FD passing req\n");
                break;


int
tmp_file(int j)  
    char    name[64];
    sprintf (name, "tmp-file-%d", j);
    return creat(name, 0666);
 
static void
parent(int sock)
 
    uint8_t xreq[32];
    uint8_t xnop[4];
    int i, j;
    int fd;
    for (j = 0; j < 4; j++)  
        /* Write a bunch of regular requests */
        for (i = 0; i < 8; i++)  
            xreq[0] = 0;
            xreq[1] = sizeof (xreq);
            sock_fd_write(sock, xreq, sizeof (xreq), -1);
         
        /* Write our 'pass an fd' request with a 'useless' FD to block the receiver */
        xreq[0] = 1;
        xreq[1] = sizeof(xreq);
        sock_fd_write(sock, xreq, sizeof (xreq), 1);
        /* Pass an fd */
        xnop[0] = 2;
        xnop[1] = sizeof (xnop);
        fd = tmp_file(j);
        sock_fd_write(sock, xnop, sizeof (xnop), fd);
        close(fd);
     
 
Fixing XCB to receive file descriptors Multiple threads may be trying to get replies and events back from the X server at the same time, which means the kludge of having the real fd follow the message will likely lead to the wrong thread getting the file descriptor. Instead, I suspect the best plan will be to fix XCB to internally capture passed file descriptors and save them with the associated reply. Because the file descriptor message will form a barrier in the read stream, xcb can associate any received file descriptor with the last reply in the read data. The X server would then send the reply with an explicit sendmsg call to pass both reply and file descriptor together. Next steps The next thing to do is code up a simple fd passing extension and try to get it working, passing descriptors back and forth to the X server. Once that works, design of the rest of the DRM-Next extension should be pretty straightforward.

Mart&iacute;n Ferrari: KGB 1.16 is out!

It was a surprisingly busy week. The commit notification service CIA was shut down about a week ago, so I spammedsent some messages to announce that KGB could be used as a replacement, and Don Armstrong wrote a great tutorial on how to set it up. As a result, many people came to us to use our bots, or to set-up their own instances. Since then, 14 Debian sub-projects started using our bots, and we know of at least two other bots being run independently. For a small project that was mainly developed and maintained for our own use, this was quite some unexpected popularity! With bug reports and feature requests starting to flow in, Damyan Ivanov (who's basically the one doing most of the work these days) sat down and produced a new release. So, I present you, KGB 1.16! What's new Bug fixes Coming up soon Tags: Planet Debian, KGB

4 October 2012

Rapha&#235;l Hertzog: My Debian Activities in September 2012

This is my monthly summary of my Debian related activities. If you re among the people who made a donation to support my work (1086.48 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. Dpkg I am subscribed to Launchpad s dpkg bug tracker and I was getting annoyed with the amount of noise I got under the form of bug reports that look like package foo failed to install/upgrade: package foo is already installed and configured . Those reports are a combination of a bug in APT and of random other failures (often hardware related like corrupted .deb files, or I/O errors, but sometimes also real problems in other packages) but they always end up assigned on dpkg (because dpkg is outputting an error message complaining about APT s decision to configure something that doesn t have to be configured). I simply don t have the time required to manually process and inspect all those reports, so I decided to filter them at the apport level with a new Ubuntu bug pattern that indicates that those reports are a duplicate of LP#541595. Thanks to this, the dpkg bug count quickly went down from 130 to about 80. Packaging I sponsored a new upstream version of ledgersmb. I quickly updated WordPress to version 3.4.2 since it contains security relevant fixes. I also pushed a small update of nautilus-dropbox fixing #686863 because upstream renamed the binary package that they hand out on their website from nautilus-dropbox to dropbox. Their dropbox package only conflicts with old versions of nautilus-dropbox and not with the version that Debian is shipping and thus I had to add a Conflicts on our side to forbid co-installation of both packages. Testing wheezy s installation I bought a new laptop (Lenovo Thinkpad X230) and used this as an excuse to test Wheezy s installation process. It worked mostly fine except for two things:
  1. First I noticed that it would not accept my passphrase for my encrypted partition during early boot this turned out to be already reported as #619711 but was no longer getting any attention from the package maintainer. After some IRC discussion with Julien Cristau, we prodded Michael Prokop who had apparently already offered to take care of this issue. I tested his updated package and the result got quickly uploaded.
  2. I had weird networking problems that turned out to be related to the lack of the loopback network (i.e. on localhost). This was the result of a broken /etc/network/interfaces: it had been incorrectly modified by NetworkManager. I reported this in #688355. This issue affects people with IPv6 enabled networks.
Debian France There s a resurgence of activity in Debian France. Sylvestre Ledru is leading the organization of a mini-debconf in Paris on November 24-25th. And Tanguy Ortolo is now taking care of some merchandising (Polo shirts, to change from the usual T-Shirt). I might give a talk during this mini-debconf, possibly about multi-arch. Misc It s been a few months that I noticed a 2 second lag of gnome-shell everytime that smuxi (my IRC client) sent a notification. It s very annoying, you have the impression that the entire machine freezes. So I contacted Mirco Bauer on #smuxi and we investigated a bit. It turns out that smuxi is using an old version of the notification protocol where the picture is sent as a bytestream leading to huge dbus messages. This is clearly sub-optimal so smuxi will be fixed to be able to send the path of the picture instead of the picture itself. On the other hand, it s really a bug of gnome-shell that it freezes during the time it takes to handle the bigger-than-usual dbus message. So I also filed a bug on GNOME Shell (Bugzilla #683829) to get this fixed. Librement: funding free software work I started a new project with the goal of helping free software developers to fund their free software work. It s still mostly vaporware for now but I have a public code repository, a nice logo and lots of ideas. If the topic is of interest to you, and you d like to be involved, feel free to get in touch. Otherwise stay tuned. Thanks See you next month for a new summary of my activities.

4 comments Liked this article? Click here. My blog is Flattr-enabled.

Next.

Previous.