Search Results: "zed"

17 June 2021

Enrico Zini: Reimagining Ansible variables

This is part of a series of posts on ideas for an ansible-like provisioning system, implemented in Transilience. While experimenting with Transilience, I've been giving some thought about Ansible variables. My gripes I like the possibility to define host and group variables, and I like to have a set of variables that are autodiscovered on the target systems. I do not like to have everything all blended in a big bucket of global variables. Let's try some more prototyping. My fiddlings First, Role classes could become dataclasses, too, and declare the variables and facts that they intend to use (typed, even!):
class Role(role.Role):
    """
    Postfix mail server configuration
    """
    # Postmaster username
    postmaster: str = None
    # Public name of the mail server
    myhostname: str = None
    # Email aliases defined on this mail server
    aliases: Dict[str, str] = field(default_factory=dict)
Using dataclasses.asdict() I immediately gain context variables for rendering Jinja2 templates:
class Role:
    # [...]
    def render_file(self, path: str, **kwargs):
        """
        Render a Jinja2 template from a file, using as context all Role fields,
        plus the given kwargs.
        """
        ctx = asdict(self)
        ctx.update(kwargs)
        return self.template_engine.render_file(path, ctx)
    def render_string(self, template: str, **kwargs):
        """
        Render a Jinja2 template from a string, using as context all Role fields,
        plus the given kwargs.
        """
        ctx = asdict(self)
        ctx.update(kwargs)
        return self.template_engine.render_string(template, ctx)
I can also model results from fact gathering into dataclass members:
# From ansible/module_utils/facts/system/platform.py
@dataclass
class Platform(Facts):
    """
    Facts from the platform module
    """
    ansible_system: Optional[str] = None
    ansible_kernel: Optional[str] = None
    ansible_kernel: Optional[str] = None
    ansible_kernel_version: Optional[str] = None
    ansible_machine: Optional[str] = None
    # [...]
    ansible_userspace_architecture: Optional[str] = None
    ansible_machine_id: Optional[str] = None
    def summary(self):
        return "gather platform facts"
    def run(self, system: transilience.system.System):
        super().run(system)
        # ... collect facts
I like that this way, one can explicitly declare what variables a Facts action will collect, and what variables a Role needs. At this point, I can add machinery to allow a Role to declare what Facts it needs, and automatically have the fields from the Facts class added to the Role class. Then, when facts are gathered, I can make sure that their fields get copied over to the Role classes that use them. In a way, variables become role-scoped, and Facts subclasses can be used like some kind of Role mixin, that contributes only field members:
# Postfix mail server configuration
@role.with_facts([actions.facts.Platform])
class Role(role.Role):
    # Postmaster username
    postmaster: str = None
    # Public name of the mail server
    myhostname: str = None
    # Email aliases defined on this mail server
    aliases: Dict[str, str] = field(default_factory=dict)
    # All fields from actions.facts.Platform are inherited here!
    def have_facts(self, facts):
        # self.ansible_domain comes from actions.facts.Platform
        self.add(builtin.command(
            argv=["certbot", "certonly", "-d", f"mail. self.ansible_domain ", "-n", "--apache"],
            creates=f"/etc/letsencrypt/live/mail. self.ansible_domain /fullchain.pem"
        ), name="obtain mail.* certificate")
        # the template context will have the Role variables, plus the variables
        # of all the Facts the Role uses
        with self.notify(ReloadPostfix):
            self.add(builtin.copy(
                dest="/etc/postfix/main.cf",
                content=self.render_file("roles/mailserver/templates/main.cf"),
            ), name="configure /etc/postfix/main.cf")
One can also fill in variables when instantiating Roles, making parameterized generic Roles possible and easy:
    runner.add_role(
            "mailserver",
            postmaster="enrico",
            myhostname="mail.enricozini.org",
            aliases= 
                "me": "enrico",
             ,
    )
Outcomes I like where this is going: having well defined variables for facts and roles, means that the variables that get into play can be explicitly defined, well known, and documented. I think this design lends itself quite well to role reuse: I have a feeling that, this way, it may be much easier to create generic libraries of Roles that one can reuse to compose complex playbooks. Since roles are just Python modules, we even already know how to package and distribute them! Next step: Playbooks, host vars, group vars.

16 June 2021

Abhijith PA: Changing LCD screen of car infotainment system

I have a 2013 model used car that I bought two years ago. It came with a 7 inch touch screen infotainment system on its dash board with features like navigation, Bluetooth phone connectivity and a good FM AM radio. Except the radio I rarely use navigation or Bluetooth phone sync. After couple of months the touch started to become non-responsive. Since all important things such as call termination, mute and volume control have physical switches, I was happy with it. During a periodic car check up on a local workshop, mechanic pulled battery terminals making the infotainment system locked. Now it ask for 4 digit pass code. Its one of their ant-theft mechanism and in order to enter those digits you need a touch responsive screen. So now I am completed locked out. I visited service center of this car to get it changed, turns out they don t repair it and only change by the unit. And will cost me Rs 50,000. Considering my usage is restricted to radio. That price is way too much. So my next options were,
  1. Use a normal cheap car radio player. I dropped this plan, since stereo players comes in very small size and I might need plastic placeholders to close rest of the area from the 7 inch screen. This can mess aesthetics of dash board. And it also affect value of the car if I will sell in future.
  2. Use a 7 inch third party infotainment system available in the market. I did enquired with local car accessories shop and I dropped this plan as well because most of them are android and comes with enormous number of pre installed apps which I never gonna use it anyway. And I don t need one more device that need to be connected to the Internet. Also the wiring at the back of these devices are different than what I have already so it need rewiring.
  3. Last option was to change the infotainment system parts my own. I was under the impression that these units are in-house made, tightly assembled and sealed with screws that you never see in your life and you will never able to be open it up, let alone fix parts.
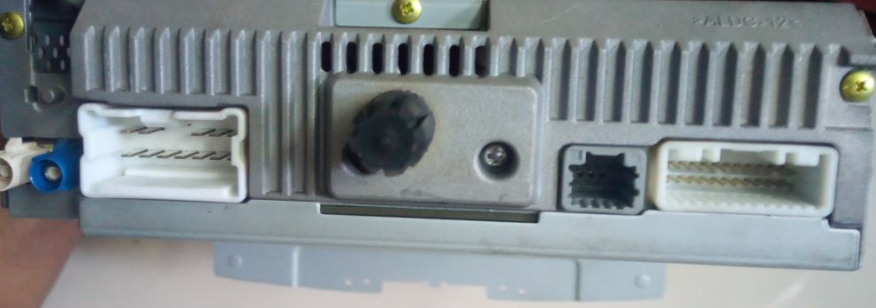
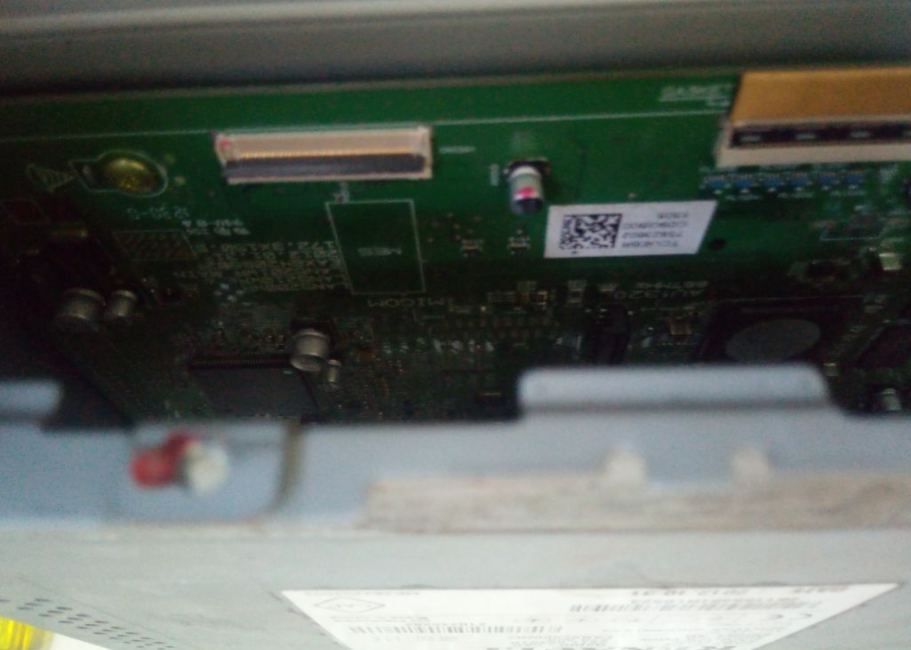
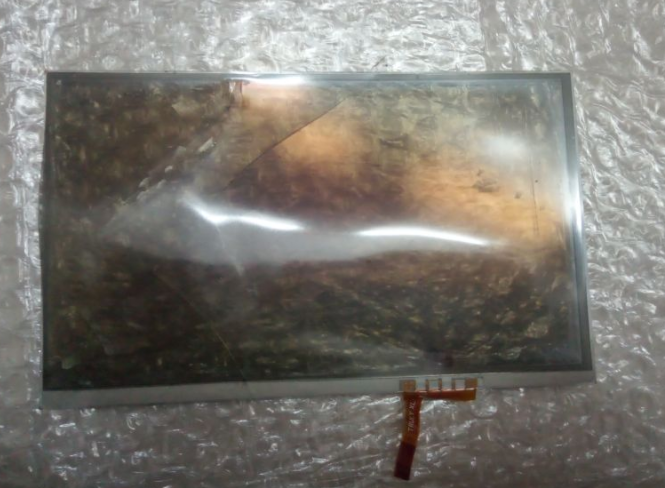
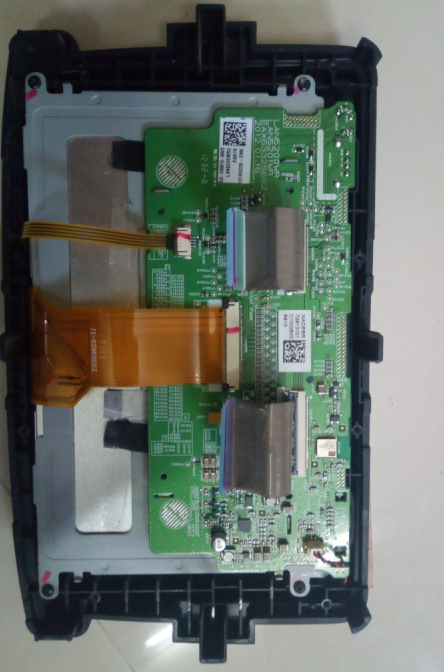
Couple of articles showed me that car infotainment system sizes and wiring at the back are actually standardized. This particular system s OEM is LG After gaining confidence from several youtube videos and articles, I chose the 3rd option and started to disassemble head unit. Luckily all those screw driver heads were with me. After taking everything apart I could see back of touch screen glass bulged and pushing against the display. The back of the display had a label with its manufacturers name Innolux display and its model number AT070TN94. You might know this company from all those raspberry pi displays in the market. Also Tesla car makers use Innolux display in their infotainment unit. I was able to spot an online reseller in Hong Kong. I only need a touch screen display but to be on the safe side I also placed order for display as well(Price difference were negligible) Took 1 month to reach at my hand due to COVID restrictions. I assembled everything together and collected radio pass code the very same day I received the item. Everything is working now. yay! The touch screen + display cost me Rs 6000/-. I can easily get an average android infotainment around this price. But it was the price I paid for avoiding e-waste. So if you have a broken head unit in your pre 2015 era car. Try to change the parts yourself. Its not complicated like our mobile phones. Back of the infotainment system inside infotainment damaged screen After reassembling with new screen Finally

14 June 2021

Jonathan Dowland: Opinionated IkiWiki v1

It's been more than a year since I wrote about Opinionated IkiWiki, a pre-configured, containerized deployment of Ikiwiki with opinions. My intention was to make something that is easy to get up and running if you are more experienced with containers than IkiWiki. I haven't yet switched to Opinionated IkiWiki for this site, but that was my goal, and I think it's mature enough now that I can migrate over at some point, so it seems a good time to call it Version 1.0. I have been using it for my own private PIM systems for a while now. You can pull built images from quay.io, here: https://quay.io/repository/jdowland/opinionated-ikiwiki The source lives here: https://github.com/jmtd/opinionated-ikiwiki A description of some of the changes made to the IkiWiki version lives here: https://github.com/jmtd/ikiwiki/blob/opinionated-doc/README.md

Enrico Zini: Pipelining

This is part of a series of posts on ideas for an ansible-like provisioning system, implemented in Transilience. Running actions on a server is nice, but a network round trip for each action is not very efficient. If I need to run a linear sequence of actions, I can stream them all to the server, and then read replies streamed from the server as they get executed. This technique is called pipelining and one can see it used, for example, in Redis, or Mitogen. Roles Ansible has the concept of "Roles" as a series of related tasks: I'll play with that. Here's an example role to install and setup fail2ban:
class Role(role.Role):
    def main(self):
        self.add(builtin.apt(
            name=["fail2ban"],
            state="present",
        ))
        self.add(builtin.copy(
            content=inline("""
                [postfix]
                enabled = true
                [dovecot]
                enabled = true
            """),
            dest="/etc/fail2ban/jail.local",
            owner="root",
            group="root",
            mode=0o644,
        ), name="configure fail2ban")
I prototyped roles as classes, with methods that push actions down the pipeline. If an action fails, all further actions for the same role won't executed, and will be marked as skipped. Since skipping is applied per-role, it means that I can blissfully stream actions for multiple roles to the server down the same pipe, and errors in one role will stop executing that role and not others. Potentially I can get multiple roles going with a single network round-trip:
#!/usr/bin/python3
import sys
from transilience.system import Mitogen
from transilience.runner import Runner
@Runner.cli
def main():
    system = Mitogen("my server", "ssh", hostname="server.example.org", username="root")
    runner = Runner(system)
    # Send roles to the server
    runner.add_role("general")
    runner.add_role("fail2ban")
    runner.add_role("prosody")
    # Run until all roles are done
    runner.main()
if __name__ == "__main__":
    sys.exit(main())
That looks like a playbook, using Python as glue rather than YAML. Decision making in roles Besides filing a series of actions, a role may need to take decisions based on the results of previous actions, or on facts discovered from the server. In that case, we need to wait until the results we need come back from the server, and then decide if we're done or if we want to send more actions down the pipe. Here's an example role that installs and configures Prosody:
from transilience import actions, role
from transilience.actions import builtin
from .handlers import RestartProsody
class Role(role.Role):
    """
    Set up prosody XMPP server
    """
    def main(self):
        self.add(actions.facts.Platform(), then=self.have_facts)
        self.add(builtin.apt(
            name=["certbot", "python-certbot-apache"],
            state="present",
        ), name="install support packages")
        self.add(builtin.apt(
            name=["prosody", "prosody-modules", "lua-sec", "lua-event", "lua-dbi-sqlite3"],
            state="present",
        ), name="install prosody packages")
    def have_facts(self, facts):
        facts = facts.facts  # Malkovich Malkovich Malkovich!
        domain = facts["domain"]
        ctx =  
            "ansible_domain": domain
         
        self.add(builtin.command(
            argv=["certbot", "certonly", "-d", f"chat. domain ", "-n", "--apache"],
            creates=f"/etc/letsencrypt/live/chat. domain /fullchain.pem"
        ), name="obtain chat certificate")
        with self.notify(RestartProsody):
            self.add(builtin.copy(
                content=self.template_engine.render_file("roles/prosody/templates/prosody.cfg.lua", ctx),
                dest="/etc/prosody/prosody.cfg.lua",
            ), name="write prosody configuration")
            self.add(builtin.copy(
                src="roles/prosody/templates/firewall-ruleset.pfw",
                dest="/etc/prosody/firewall-ruleset.pfw",
            ), name="write prosody firewall")
    # ...
This files some general actions down the pipe, with a hook that says: when the results of this action come back, run self.have_facts(). At that point, the role can use the results to build certbot command lines, render prosody's configuration from Jinja2 templates, and use the results to file further action down the pipe. Note that this way, while the server is potentially still busy installing prosody, we're already streaming prosody's configuration to it. If anything goes wrong with the installation of prosody's package, the role will be marked as failed and all further actions of the same role, even those filed by have_facts() will be skipped. Notify and handlers In the previous example self.notify() also appears: that's my attempt to model the equivalent of Ansible's handlers. If any of the actions inside the with produce changes, then the RestartProsody role will be executed, potentially filing more actions ad the end of the playbook. The runner will take care of collecting all the triggered role classes in a set, which discards duplicates, and then running the main() method of all resulting roles, which will cause more actions to be filed down the pipe. Action conditions Sometimes some actions are only meaningful as consequences of other actions. Let's take, for example, enabling buster-backports as an extra apt source:
        a = self.add(builtin.copy(
            owner="root",
            group="root",
            mode=0o644,
            dest="/etc/apt/sources.list.d/debian-buster-backports.list",
            content="deb [arch=amd64] https://mirrors.gandi.net/debian/ buster-backports main contrib",
        ), name="enable backports")
        self.add(builtin.apt(
            update_cache=True
        ), name="update after enabling backports",
           # Run only if the previous copy changed anything
           when= a: ResultState.CHANGED ,
        )
Here we want to update Apt's cache, which is a slow operation, only after we actually write /etc/apt/sources.list.d/debian-buster-backports.list. If the file was already there from a previous run, we can skip downloading the new package lists. The when= attributes adds an annotation to the action that is sent town the pipeline, that says that it should only be run if the state of a previous action matches the given one. In this case, when on the remote it's the turn of "update after enabling backports", it gets skipped unless the state of the previous "enable backports" action is CHANGED. Effects of pipelining I ported enough of Ansible's modules to be able to run the provisioning scripts of my VPS entirely via ansible. This is the playbook run as plain Ansible:
$ time ansible-playbook vps.yaml
[...]
servername       : ok=55   changed=1    unreachable=0    failed=0    skipped=0    rescued=0    ignored=0
real    2m10.072s
user    0m33.149s
sys 0m10.379s
This is the same playbook run with Ansible speeded up via the Mitogen backend, which makes Ansible more bearable:
$ export ANSIBLE_STRATEGY=mitogen_linear
$ time ansible-playbook vps.yaml
[...]
servername       : ok=55   changed=1    unreachable=0    failed=0    skipped=0    rescued=0    ignored=0
real    0m24.428s
user    0m8.479s
sys 0m1.894s
This is the same playbook ported to Transilience:
$ time ./provision
[...]
real    0m2.585s
user    0m0.659s
sys 0m0.034s
Doing nothing went from 2 minutes down to 3 seconds! That's the kind of running time that finally makes me comfortable with maintaining my VPS by editing the playbook only, and never logging in to mess with the system configuration by hand! Next steps I'm quite happy with what I have: I can now maintain my VPS with a simple script with quick iterative cycles. I might use it to develop new playbooks, and port them to ansible only when they're tested and need to be shared with infrastructure that needs to rely on something more solid and battle tested than a prototype provisioning system. I might also keep working on it as I have more interesting ideas that I'd like to try. I feel like Ansible reached some architectural limits that are hard to overcome without a major redesign, and are in many way hardcoded in its playbook configuration. It's nice to be able to try out new designs without that baggage. I'd love it if even just the library of Transilience actions could grow, and gain widespread use. Ansible modules standardized a set of management operations, that I think became the way people think about system management, and should really be broadly available outside of Ansible. If you are interesting in playing with Transilience, such as: do get in touch or send a pull request! :) Next step: Reimagining Ansible variables.

Enrico Zini: Use ansible actions in a script

This is part of a series of posts on ideas for an ansible-like provisioning system, implemented in Transilience. I like many of the modules provided with Ansible: they are convenient, platform-independent implementations of common provisioning steps. They'd be fantastic to have in a library that I could use in normal programs. This doesn't look easy to do with Ansible code as it is. Also, the code quality of various Ansible modules doesn't fit something I'd want in a standard library of cross-platform provisioning functions. Modeling Actions I want to keep the declarative, idempotent aspect of describing actions on a system. A good place to start could be a hierarchy of dataclasses that hold the same parameters as ansible modules, plus a run() method that performs the action:
@dataclass
class Action:
    """
    Base class for all action implementations.
    An Action is the equivalent of an ansible module: a declarative
    representation of an idempotent operation on a system.
    An Action can be run immediately, or serialized, sent to a remote system,
    run, and sent back with its results.
    """
    uuid: str = field(default_factory=lambda: str(uuid.uuid4()))
    result: Result = field(default_factory=Result)
    def summary(self):
        """
        Return a short text description of this action
        """
        return self.__class__.__name__
    def run(self, system: transilience.system.System):
        """
        Perform the action
        """
        self.result.state = ResultState.NOOP
I like that Ansible tasks have names, and I hate having to give names to trivial tasks like "Create directory /foo/bar", so I added a summary() method so that trivial tasks like that can take care of naming themselves. Dataclasses allow to introspect fields and annotate them with extra metadata, and together with docstrings, I can make actions reasonably self-documeting. I ported some of Ansible's modules over: see complete list in the git repository. Running Actions in a script With a bit of glue code I can now run Ansible-style functions from a plain Python script:
#!/usr/bin/python3
from transilience.runner import Script
script = Script()
for i in range(10):
    script.builtin.file(state="touch", path=f"/tmp/test i ")
Running Actions remotely Dataclasses have an asdict function that makes them trivially serializable. If their members stick to data types that can be serialized with Mitogen and the run implementation doesn't use non-pure, non-stdlib Python modules, then I can trivially run actions on all sorts of remote systems using Mitogen:
#!/usr/bin/python3
from transilience.runner import Script
from transilience.system import Mitogen
script = Script(system=Mitogen("my server", "ssh", hostname="machine.example.org", username="user"))
for i in range(10):
    script.builtin.file(state="touch", path=f"/tmp/test i ")
How fast would that be, compared to Ansible?
$ time ansible-playbook test.yaml
[...]
real    0m15.232s
user    0m4.033s
sys 0m1.336s
$ time ./test_script
real    0m4.934s
user    0m0.547s
sys 0m0.049s
With a network round-trip for each single operation I'm already 3x faster than Ansible, and it can run on nspawn containers, too! I always wanted to have a library of ansible modules useable in normal scripts, and I've always been angry with Ansible for not bundling their backend code in a generic library. Well, now there's the beginning of one! Sweet! Next step, pipelining.

Fran ois Marier: Self-hosting an Ikiwiki blog

8.5 years ago, I moved my blog to Ikiwiki and Branchable. It's now time for me to take the next step and host my blog on my own server. This is how I migrated from Branchable to my own Apache server.

Installing Ikiwiki dependencies Here are all of the extra Debian packages I had to install on my server:
apt install ikiwiki ikiwiki-hosting-common gcc libauthen-passphrase-perl libcgi-formbuilder-perl libcrypt-sslauthen-passphrase-perl libcgi-formbuilder-perl libcrypt-ssleay-perl libjson-xs-perl librpc-xml-perl python-docutils libxml-feed-perl libsearch-xapian-perl libmailtools-perl highlight-common libsearch-xapian-perl xapian-omega
apt install --no-install-recommends ikiwiki-hosting-web libgravatar-url-perl libmail-sendmail-perl libcgi-session-perl
apt purge libnet-openid-consumer-perl
Then I enabled the CGI module in Apache:
a2enmod cgi
and un-commented the following in /etc/apache2/mods-available/mime.conf:
AddHandler cgi-script .cgi

Creating a separate user account Since Ikiwiki needs to regenerate my blog whenever a new article is pushed to the git repo or a comment is accepted, I created a restricted user account for it:
adduser blog
adduser blog sshuser
chsh -s /usr/bin/git-shell blog

git setup Thanks to Branchable storing blogs in git repositories, I was able to import my blog using a simple git clone in /home/blog (the srcdir):
git clone --bare git://feedingthecloud.branchable.com/ source.git
Note that the name of the directory (source.git) is important for the ikiwikihosting plugin to work. Then I pulled the .setup file out of the setup branch in that repo and put it in /home/blog/.ikiwiki/FeedingTheCloud.setup. After that, I deleted the setup branch and the origin remote from that clone:
git branch -d setup
git remote rm origin
Following the recommended git configuration, I created a working directory (the repository) for the blog user to modify the blog as needed:
cd /home/blog/
git clone /home/blog/source.git FeedingTheCloud
I added my own ssh public key to /home/blog/.ssh/authorized_keys so that I could push to the srcdir from my laptop. Finaly, I generated a new ssh key without a passphrase:
ssh-keygen -t ed25519
and added it as deploy key to the GitHub repo which acts as a read-only mirror of my blog.

Ikiwiki config While I started with the Branchable setup file, I changed the following things in it:
adminemail: webmaster@fmarier.org
srcdir: /home/blog/FeedingTheCloud
destdir: /var/www/blog
url: https://feeding.cloud.geek.nz
cgiurl: https://feeding.cloud.geek.nz/blog.cgi
cgi_wrapper: /var/www/blog/blog.cgi
cgi_wrappermode: 675
add_plugins:
- goodstuff
- lockedit
- comments
- blogspam
- sidebar
- attachment
- favicon
- format
- highlight
- search
- theme
- moderatedcomments
- flattr
- calendar
- headinganchors
- notifyemail
- anonok
- autoindex
- date
- relativedate
- htmlbalance
- pagestats
- sortnaturally
- ikiwikihosting
- gitpush
- emailauth
disable_plugins:
- brokenlinks
- fortune
- more
- openid
- orphans
- passwordauth
- progress
- recentchanges
- repolist
- toggle
- txt
sslcookie: 1
cookiejar:
  file: /home/blog/.ikiwiki/cookies
useragent: ikiwiki
git_wrapper: /home/blog/source.git/hooks/post-update
urlalias:
- http://feeds.cloud.geek.nz/
- http://www.feeding.cloud.geek.nz/
owner: francois@fmarier.org
hostname: feeding.cloud.geek.nz
emailauth_sender: login@fmarier.org
allowed_attachments: admin()
Then I created the destdir:
mkdir /var/www/blog
chown blog:blog /var/www/blog
and generated the initial copy of the blog as the blog user:
ikiwiki --setup .ikiwiki/FeedingTheCloud.setup --wrappers --rebuild
One thing that failed to generate properly was the tag cloug (from the pagestats plugin). I have not been able to figure out why it fails to generate any output when run this way, but if I push to the repo and let the git hook handle the rebuilding of the wiki, the tag cloud is generated correctly. Consequently, fixing this is not high on my list of priorities, but if you happen to know what the problem is, please reach out.

Apache config Here's the Apache config I put in /etc/apache2/sites-available/blog.conf:
<VirtualHost *:443>
    ServerName feeding.cloud.geek.nz
    SSLEngine On
    SSLCertificateFile /etc/letsencrypt/live/feeding.cloud.geek.nz/fullchain.pem
    SSLCertificateKeyFile /etc/letsencrypt/live/feeding.cloud.geek.nz/privkey.pem
    Header set Strict-Transport-Security: "max-age=63072000; includeSubDomains; preload"
    Include /etc/fmarier-org/blog-common
</VirtualHost>
<VirtualHost *:443>
    ServerName www.feeding.cloud.geek.nz
    ServerAlias feeds.cloud.geek.nz
    SSLEngine On
    SSLCertificateFile /etc/letsencrypt/live/feeding.cloud.geek.nz/fullchain.pem
    SSLCertificateKeyFile /etc/letsencrypt/live/feeding.cloud.geek.nz/privkey.pem
    Redirect permanent / https://feeding.cloud.geek.nz/
</VirtualHost>
<VirtualHost *:80>
    ServerName feeding.cloud.geek.nz
    ServerAlias www.feeding.cloud.geek.nz
    ServerAlias feeds.cloud.geek.nz
    Redirect permanent / https://feeding.cloud.geek.nz/
</VirtualHost>
and the common config I put in /etc/fmarier-org/blog-common:
ServerAdmin webmaster@fmarier.org
DocumentRoot /var/www/blog
LogLevel core:info
CustomLog $ APACHE_LOG_DIR /blog-access.log combined
ErrorLog $ APACHE_LOG_DIR /blog-error.log
AddType application/rss+xml .rss
<Location /blog.cgi>
        Options +ExecCGI
</Location>
before enabling all of this using:
a2ensite blog
apache2ctl configtest
systemctl restart apache2.service
The feeds.cloud.geek.nz domain used to be pointing to Feedburner and so I need to maintain it in order to avoid breaking RSS feeds from folks who added my blog to their reader a long time ago.

Server-side improvements Since I'm now in control of the server configuration, I was able to make several improvements to how my blog is served. First of all, I enabled the HTTP/2 and Brotli modules:
a2enmod http2
a2enmod brotli
and enabled Brotli compression by putting the following in /etc/apache2/conf-available/compression.conf:
<IfModule mod_brotli.c>
  <IfDefine !TRANSFER_COMPRESSION>
    Define TRANSFER_COMPRESSION BROTLI_COMPRESS
  </IfDefine>
</IfModule>
<IfModule mod_deflate.c>
  <IfDefine !TRANSFER_COMPRESSION>
    Define TRANSFER_COMPRESSION DEFLATE
  </IfDefine>
</IfModule>
<IfDefine TRANSFER_COMPRESSION>
  <IfModule mod_filter.c>
    AddOutputFilterByType $ TRANSFER_COMPRESSION  text/html text/plain text/xml text/css text/javascript
    AddOutputFilterByType $ TRANSFER_COMPRESSION  application/x-javascript application/javascript application/ecmascript
    AddOutputFilterByType $ TRANSFER_COMPRESSION  application/rss+xml
    AddOutputFilterByType $ TRANSFER_COMPRESSION  application/xml
  </IfModule>
</IfDefine>
and replacing /etc/apache2/mods-available/deflate.conf with the following:
# Moved to /etc/apache2/conf-available/compression.conf as per https://bugs.debian.org/972632
before enabling this new config:
a2enconf compression
Next, I made my blog available as a Tor onion service by putting the following in /etc/apache2/sites-available/blog.conf:
<VirtualHost *:443>
    ServerName feeding.cloud.geek.nz
    ServerAlias xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion
    Header set Onion-Location "http://xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion% REQUEST_URI s"
    Header set alt-svc 'h2="xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion:443"; ma=315360000; persist=1'
    ... 
<VirtualHost *:80>
    ServerName xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion
    Include /etc/fmarier-org/blog-common
</VirtualHost>
Then I followed the Mozilla Observatory recommendations and enabled the following security headers:
Header set Content-Security-Policy: "default-src 'none'; report-uri https://fmarier.report-uri.com/r/d/csp/enforce ; style-src 'self' 'unsafe-inline' ; img-src 'self' https://seccdn.libravatar.org/ ; script-src https://feeding.cloud.geek.nz/ikiwiki/ https://xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion/ikiwiki/ http://xfdug5vmfi6oh42fp6ahhrqdjcf7ysqat6fkp5dhvde4d7vlkqixrsad.onion/ikiwiki/ 'unsafe-inline' 'sha256-pA8FbKo4pYLWPDH2YMPqcPMBzbjH/RYj0HlNAHYoYT0=' 'sha256-Kn5E/7OLXYSq+EKMhEBGJMyU6bREA9E8Av9FjqbpGKk=' 'sha256-/BTNlczeBxXOoPvhwvE1ftmxwg9z+WIBJtpk3qe7Pqo=' ; base-uri 'self'; form-action 'self' ; frame-ancestors 'self'"
Header set X-Frame-Options: "SAMEORIGIN"
Header set Referrer-Policy: "same-origin"
Header set X-Content-Type-Options: "nosniff"
Note that the Mozilla Observatory is mistakenly identifying HTTP onion services as insecure, so you can ignore that failure. I also used the Mozilla TLS config generator to improve the TLS config for my server. Then I added security.txt and gpc.json to the root of my git repo and then added the following aliases to put these files in the right place:
Alias /.well-known/gpc.json /var/www/blog/gpc.json
Alias /.well-known/security.txt /var/www/blog/security.txt
I also followed these instructions to create a sitemap for my blog with the following alias:
Alias /sitemap.xml /var/www/blog/sitemap/index.rss
Finally, I simplified a few error pages to save bandwidth:
ErrorDocument 301 " "
ErrorDocument 302 " "
ErrorDocument 404 "Not Found"

Monitoring 404s Another advantage of running my own web server is that I can monitor the 404s easily using logcheck by putting the following in /etc/logcheck/logcheck.logfiles:
/var/log/apache2/blog-error.log 
Based on that, I added a few redirects to point bots and users to the location of my RSS feed:
Redirect permanent /atom /index.atom
Redirect permanent /comments.rss /comments/index.rss
Redirect permanent /comments.atom /comments/index.atom
Redirect permanent /FeedingTheCloud /index.rss
Redirect permanent /feed /index.rss
Redirect permanent /feed/ /index.rss
Redirect permanent /feeds/posts/default /index.rss
Redirect permanent /rss /index.rss
Redirect permanent /rss/ /index.rss
and to tell them to stop trying to fetch obsolete resources:
Redirect gone /~ff/FeedingTheCloud
Redirect gone /gittip_button.png
Redirect gone /ikiwiki.cgi
I also used these 404s to discover a few old Feedburner URLs that I could redirect to the right place using archive.org:
Redirect permanent /feeds/1572545745827565861/comments/default /posts/watch-all-of-your-logs-using-monkeytail/comments.atom
Redirect permanent /feeds/1582328597404141220/comments/default /posts/news-feeds-rssatom-for-mythtvorg-and/comments.atom
...
Redirect permanent /feeds/8490436852808833136/comments/default /posts/recovering-lost-git-commits/comments.atom
Redirect permanent /feeds/963415010433858516/comments/default /posts/debugging-openwrt-routers-by-shipping/comments.atom
I also put the following robots.txt in the git repo in order to stop a bunch of authentication errors coming from crawlers:
User-agent: *
Disallow: /blog.cgi
Disallow: /ikiwiki.cgi

Future improvements There are a few things I'd like to improve on my current setup. The first one is to remove the iwikihosting and gitpush plugins and replace them with a small script which would simply git push to the read-only GitHub mirror. Then I could uninstall the ikiwiki-hosting-common and ikiwiki-hosting-web since that's all I use them for. Next, I would like to have proper support for signed git pushes. At the moment, I have the following in /home/blog/source.git/config:
[receive]
    advertisePushOptions = true
    certNonceSeed = "(random string)"
but I'd like to also reject unsigned pushes. While my blog now has a CSP policy which doesn't rely on unsafe-inline for scripts, it does rely on unsafe-inline for stylesheets. I tried to remove this but the actual calls to allow seemed to be located deep within jQuery and so I gave up. Update: now fixed. Finally, I'd like to figure out a good way to deal with articles which don't currently have comments. At the moment, if you try to subscribe to their comment feed, it returns a 404. For example:
[Sun Jun 06 17:43:12.336350 2021] [core:info] [pid 30591:tid 140253834704640] [client 66.249.66.70:57381] AH00128: File does not exist: /var/www/blog/posts/using-iptables-with-network-manager/comments.atom
This is obviously not ideal since many feed readers will refuse to add a feed which is currently not found even though it could become real in the future. If you know of a way to fix this, please let me know.

10 June 2021

Petter Reinholdtsen: Nikita version 0.6 released - free software archive API server

I am very pleased to be able to share with you the announcement of a new version of the archiving system Nikita published by its lead developer Thomas S dring:
It is with great pleasure that we can announce a new release of nikita. Version 0.6 (https://gitlab.com/OsloMet-ABI/nikita-noark5-core). This release makes new record keeping functionality available. This really is a maturity release. Both in terms of functionality but also code. Considerable effort has gone into refactoring the codebase and simplifying the code. Notable changes for this release include:
  • Significantly improved OData parsing
  • Support for business specific metadata and national identifiers
  • Continued implementation of domain model and endpoints
  • Improved testing
  • Ability to export and import from arkivstruktur.xml
We are currently in the process of reaching an agreement with an archive institution to publish their picture archive using nikita with business specific metadata and we hope that we can share this with you soon. This is an interesting project as it allows the organisation to bring an older picture archive back to life while using the original metadata values stored as business specific metadata. Combined with OData means the scope and use of the archive is significantly increased and will showcase both the flexibility and power of Noark. I really think we are approaching a version 1.0 of nikita, even though there is still a lot of work to be done. The notable work at the moment is to implement access-control and full text indexing of documents. My sincere thanks to everyone who has contributed to this release! - Thomas Release 0.6 2021-06-10 (d1ba5fc7e8bad0cfdce45ac20354b19d10ebbc7b)
  • Refactor metadata entity search
  • Remove redundant security configuration
  • Make OpenAPI documentation work
  • Change database structure / inheritance model to a more sensible approach
  • Make it possible to move entities around the fonds structure
  • Implemented a number of missing endpoints
  • Make sure yml files are in sync
  • Implemented/finalised storing and use of
    • Business Specific Metadata
    • Norwegian National Identifiers
    • Cross Reference
    • Keyword
    • StorageLocation
    • Author
    • Screening for relevant objects
    • ChangeLog
    • EventLog
  • Make generation of updated docker image part of successful CI pipeline
  • Implement pagination for all list requests
    • Refactor code to support lists
    • Refactor code for readability
    • Standardise the controller/service code
  • Finalise File->CaseFile expansion and Record->registryEntry/recordNote expansion
  • Improved Continuous Integration (CI) approach via gitlab
  • Changed conversion approach to generate tagged PDF documents
  • Updated dependencies
    • For security reasons
    • Brought codebase to spring-boot version 2.5.0
    • Remove import of necessary dependencies
    • Remove non-used metrics classes
  • Added new analysis to CI including
  • Implemented storing of Keyword
  • Implemented storing of Screening and ScreeningMetadata
  • Improved OData support
    • Better support for inheritance in queries where applicable
    • Brought in more OData tests
    • Improved OData/hibernate understanding of queries
    • Implement $count, $orderby
    • Finalise $top and $skip
    • Make sure & is used between query parameters
  • Improved Testing in codebase
    • A new approach for integration tests to make test more readable
    • Introduce tests in parallel with code development for TDD approach
    • Remove test that required particular access to storage
  • Implement case-handling process from received email to case-handler
    • Develop required GUI elements (digital postroom from email)
    • Introduced leader, quality control and postroom roles
  • Make PUT requests return 200 OK not 201 CREATED
  • Make DELETE requests return 204 NO CONTENT not 200 OK
  • Replaced 'oppdatert*' with 'endret*' everywhere to match latest spec
  • Upgrade Gitlab CI to use python > 3 for CI scripts
  • Bug fixes
    • Fix missing ALLOW
    • Fix reading of objects from jar file during start-up
    • Reduce the number of warnings in the codebase
    • Fix delete problems
    • Make better use of cascade for "leaf" objects
    • Add missing annotations where relevant
    • Remove the use of ETAG for delete
    • Fix missing/wrong/broken rels discovered by runtest
    • Drop unofficial convertFil (konverterFil) end point
    • Fix regex problem for dateTime
    • Fix multiple static analysis issues discovered by coverity
    • Fix proxy problem when looking for object class names
    • Add many missing translated Norwegian to English (internal) attribute/entity names
    • Change UUID generation approach to allow code also set a value
    • Fix problem with Part/PartParson
    • Fix problem with empty OData search results
    • Fix metadata entity domain problem
  • General Improvements
    • Makes future refactoring easier as coupling is reduced
    • Allow some constant variables to be set from property file
    • Refactor code to make reflection work better across codebase
    • Reduce the number of @Service layer classes used in @Controller classes
    • Be more consistent on naming of similar variable types
    • Start printing rels/href if they are applicable
    • Cleaner / standardised approach to deleting objects
    • Avoid concatenation when using StringBuilder
    • Consolidate code to avoid duplication
    • Tidy formatting for a more consistent reading style across similar class files
    • Make throw a log.error message not an log.info message
    • Make throw print the log value rather than printing in multiple places
    • Add some missing pronom codes
    • Fix time formatting issue in Gitlab CI
    • Remove stale / unused code
    • Use only UUID datatype rather than combination String/UUID for systemID
    • Mark variables final and @NotNull where relevant to indicate intention
  • Change Date values to DateTime to maintain compliance with Noark 5 standard
  • Domain model improvements using Hypersistence Optimizer
    • Move @Transactional from class to methods to avoid borrowing the JDBC Connection unnecessarily
    • Fix OneToOne performance issues
    • Fix ManyToMany performance issues
    • Add missing bidirectional synchronization support
    • Fix ManyToMany performance issue
  • Make List
  • and Set
  • use final-keyword to avoid potential problems during update operations
  • Changed internal URLs, replaced "hateoas-api" with "api".
  • Implemented storing of Precedence.
  • Corrected handling of screening.
  • Corrected _links collection returned for list of mixed entity types to match the specific entity.
  • Improved several internal structures.
If free and open standardized archiving API sound interesting to you, please contact us on IRC (#nikita on irc.oftc.net) or email (nikita-noark mailing list). As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Vincent Bernat: Serving WebP & AVIF images with Nginx

WebP and AVIF are two image formats for the web. They aim to produce smaller files than JPEG and PNG. They both support lossy and lossless compression, as well as alpha transparency. WebP was developed by Google and is a derivative of the VP8 video format.1 It is supported on most browsers. AVIF is using the newer AV1 video format to achieve better results. It is supported by Chromium-based browsers and has experimental support for Firefox.2

Your browser supports WebP and AVIF image formats. Your browser supports none of these image formats. Your browser only supports the WebP image format. Your browser only supports the AVIF image format.

Without JavaScript, I can t tell what your browser supports.

Converting and optimizing images For this blog, I am using the following shell snippets to convert and optimize JPEG and PNG images. Skip to the next section if you are only interested in the Nginx setup.

JPEG images JPEG images are converted to WebP using cwebp.
find media/images -type f -name '*.jpg' -print0 \
    xargs -0n1 -P$(nproc) -i \
      cwebp -q 84 -af ' ' -o ' '.webp
They are converted to AVIF using avifenc from libavif:
find media/images -type f -name '*.jpg' -print0 \
    xargs -0n1 -P$(nproc) -i \
      avifenc --codec aom --yuv 420 --min 20 --max 25 ' ' ' '.avif
Then, they are optimized using jpegoptim built with Mozilla s improved JPEG encoder, via Nix. This is one reason I love Nix.
jpegoptim=$(nix-build --no-out-link \
      -E 'with (import <nixpkgs> ); jpegoptim.override   libjpeg = mozjpeg;  ')
find media/images -type f -name '*.jpg' -print0 \
    sort -z
    xargs -0n10 -P$(nproc) \
      $ jpegoptim /bin/jpegoptim --max=84 --all-progressive --strip-all

PNG images PNG images are down-sampled to 8-bit RGBA-palette using pngquant. The conversion reduces file sizes significantly while being mostly invisible.
find media/images -type f -name '*.png' -print0 \
    sort -z
    xargs -0n10 -P$(nproc) \
      pngquant --skip-if-larger --strip \
               --quiet --ext .png --force
Then, they are converted to WebP with cwebp in lossless mode:
find media/images -type f -name '*.png' -print0 \
    xargs -0n1 -P$(nproc) -i \
      cwebp -z 8 ' ' -o ' '.webp
No conversion is done to AVIF: lossless compression is not as efficient as pngquant and lossy compression is only marginally better than what I get with WebP.

Keeping only the smallest files I am only keeping WebP and AVIF images if they are at least 10% smaller than the original format: decoding is usually faster for JPEG and PNG; and JPEG images can be decoded progressively.3
for f in media/images/**/*. webp,avif ; do
  orig=$(stat --format %s $ f%.* )
  new=$(stat --format %s $f)
  (( orig*0.90 > new ))   rm $f
done
I only keep AVIF images if they are smaller than WebP.
for f in media/images/**/*.avif; do
  [[ -f $ f%.* .webp ]]   continue
  orig=$(stat --format %s $ f%.* .webp)
  new=$(stat --format %s $f)
  (( $orig > $new ))   rm $f
done
We can compare how many images are kept when converted to WebP or AVIF:
printf "     %10s %10s %10s\n" Original WebP AVIF
for format in png jpg; do
  printf " $ format:u  %10s %10s %10s\n" \
    $(find media/images -name "*.$format"   wc -l) \
    $(find media/images -name "*.$format.webp"   wc -l) \
    $(find media/images -name "*.$format.avif"   wc -l)
done
AVIF is better than MozJPEG for most JPEG files while WebP beats MozJPEG only for one file out of two:
       Original       WebP       AVIF
 PNG         64         47          0
 JPG         83         40         74

Further reading I didn t detail my choices for quality parameters and there is not much science in it. Here are two resources providing more insight on AVIF:

Serving WebP & AVIF with Nginx To serve WebP and AVIF images, there are two possibilities:
  1. use <picture> to let the browser pick the format it supports, or
  2. use content negotiation to let the server send the best-supported format.
I use the second approach. It relies on inspecting the Accept HTTP header in the request. For Chrome, it looks like this:
Accept: image/avif,image/webp,image/apng,image/*,*/*;q=0.8
I configure Nginx to serve AVIF image, then the WebP image, and fallback to the original JPEG/PNG image depending on what the browser advertises:4
http  
  map $http_accept $webp_suffix  
    default        "";
    "~image/webp"  ".webp";
   
  map $http_accept $avif_suffix  
    default        "";
    "~image/avif"  ".avif";
   
 
server  
  # [ ]
  location ~ ^/images/.*\.(png jpe?g)$  
    add_header Vary Accept;
    try_files $uri$avif_suffix$webp_suffix $uri$avif_suffix $uri$webp_suffix $uri =404;
   
 
For example, let s suppose the browser requests /images/ont-box-orange@2x.jpg. If it supports WebP but not AVIF, $webp_suffix is set to .webp while $avif_suffix is set to the empty string. The server tries to serve the first existing file in this list:
  • /images/ont-box-orange@2x.jpg.webp
  • /images/ont-box-orange@2x.jpg
  • /images/ont-box-orange@2x.jpg.webp
  • /images/ont-box-orange@2x.jpg
If the browser supports both AVIF and WebP, Nginx walks the following list:
  • /images/ont-box-orange@2x.jpg.webp.avif (it never exists)
  • /images/ont-box-orange@2x.jpg.avif
  • /images/ont-box-orange@2x.jpg.webp
  • /images/ont-box-orange@2x.jpg
Eugene Lazutkin explains in more detail how this works. I have only presented a variation of his setup supporting both WebP and AVIF.

  1. VP8 is only used for lossy compression. Lossless compression is using an unrelated format.
  2. Firefox support was scheduled for Firefox 86 but because of the lack of proper color space support, it is still not enabled by default.
  3. Progressive decoding is not planned for WebP but could be implemented using low-quality thumbnail images for AVIF. See this issue for a discussion.
  4. The Vary header ensures an intermediary cache (a proxy or a CDN) checks the Accept header before using a cached response. Internet Explorer has trouble with this header and may not be able to cache the resource properly. There is a workaround but Internet Explorer s market share is now so small that it is pointless to implement it.

8 June 2021

Enrico Zini: Mock syscalls with C++

I wrote and maintain some C++ code to stream high quantities of data as fast as possible, and I try to use splice and sendfile when available. The availability of those system calls varies at runtime according to a number of factors, and the code needs to be written to fall back to read/write loops depending on what the splice and sendfile syscalls say. The tricky issue is unit testing: since the code path chosen depends on the kernel, the test suite will test one path or the other depending on the machine and filesystems where the tests are run. It would be nice to be able to mock the syscalls, and replace them during tests, and it looks like I managed. First I made catalogues of the mockable syscalls I want to be able to mock. One with function pointers, for performance, and one with std::function, for flexibility:
/**
 * Linux versions of syscalls to use for concrete implementations.
 */
struct ConcreteLinuxBackend
 
    static ssize_t (*read)(int fd, void *buf, size_t count);
    static ssize_t (*write)(int fd, const void *buf, size_t count);
    static ssize_t (*writev)(int fd, const struct iovec *iov, int iovcnt);
    static ssize_t (*sendfile)(int out_fd, int in_fd, off_t *offset, size_t count);
    static ssize_t (*splice)(int fd_in, loff_t *off_in, int fd_out,
                             loff_t *off_out, size_t len, unsigned int flags);
    static int (*poll)(struct pollfd *fds, nfds_t nfds, int timeout);
    static ssize_t (*pread)(int fd, void *buf, size_t count, off_t offset);
 ;
/**
 * Mockable versions of syscalls to use for testing concrete implementations.
 */
struct ConcreteTestingBackend
 
    static std::function<ssize_t(int fd, void *buf, size_t count)> read;
    static std::function<ssize_t(int fd, const void *buf, size_t count)> write;
    static std::function<ssize_t(int fd, const struct iovec *iov, int iovcnt)> writev;
    static std::function<ssize_t(int out_fd, int in_fd, off_t *offset, size_t count)> sendfile;
    static std::function<ssize_t(int fd_in, loff_t *off_in, int fd_out,
                                 loff_t *off_out, size_t len, unsigned int flags)> splice;
    static std::function<int(struct pollfd *fds, nfds_t nfds, int timeout)> poll;
    static std::function<ssize_t(int fd, void *buf, size_t count, off_t offset)> pread;
    static void reset();
 ;
Then I converted the code to templates, parameterized on the catalogue class. Explicit template instantiation helps in making sure that one doesn't need to include template code in all sorts of places. Finally, I can have a RAII class for mocking:
/**
 * RAII mocking of syscalls for concrete stream implementations
 */
struct MockConcreteSyscalls
 
    std::function<ssize_t(int fd, void *buf, size_t count)> orig_read;
    std::function<ssize_t(int fd, const void *buf, size_t count)> orig_write;
    std::function<ssize_t(int fd, const struct iovec *iov, int iovcnt)> orig_writev;
    std::function<ssize_t(int out_fd, int in_fd, off_t *offset, size_t count)> orig_sendfile;
    std::function<ssize_t(int fd_in, loff_t *off_in, int fd_out,
                                 loff_t *off_out, size_t len, unsigned int flags)> orig_splice;
    std::function<int(struct pollfd *fds, nfds_t nfds, int timeout)> orig_poll;
    std::function<ssize_t(int fd, void *buf, size_t count, off_t offset)> orig_pread;
    MockConcreteSyscalls();
    ~MockConcreteSyscalls();
 ;
MockConcreteSyscalls::MockConcreteSyscalls()
    : orig_read(ConcreteTestingBackend::read),
      orig_write(ConcreteTestingBackend::write),
      orig_writev(ConcreteTestingBackend::writev),
      orig_sendfile(ConcreteTestingBackend::sendfile),
      orig_splice(ConcreteTestingBackend::splice),
      orig_poll(ConcreteTestingBackend::poll),
      orig_pread(ConcreteTestingBackend::pread)
 
 
MockConcreteSyscalls::~MockConcreteSyscalls()
 
    ConcreteTestingBackend::read = orig_read;
    ConcreteTestingBackend::write = orig_write;
    ConcreteTestingBackend::writev = orig_writev;
    ConcreteTestingBackend::sendfile = orig_sendfile;
    ConcreteTestingBackend::splice = orig_splice;
    ConcreteTestingBackend::poll = orig_poll;
    ConcreteTestingBackend::pread = orig_pread;
 
And here's the specialization to pretend sendfile and splice aren't available:
/**
 * Mock sendfile and splice as if they weren't available on this system
 */
struct DisableSendfileSplice : public MockConcreteSyscalls
 
    DisableSendfileSplice();
 ;
DisableSendfileSplice::DisableSendfileSplice()
 
    ConcreteTestingBackend::sendfile = [](int out_fd, int in_fd, off_t *offset, size_t count) -> ssize_t  
        errno = EINVAL;
        return -1;
     ;
    ConcreteTestingBackend::splice = [](int fd_in, loff_t *off_in, int fd_out,
                                        loff_t *off_out, size_t len, unsigned int flags) -> ssize_t  
        errno = EINVAL;
        return -1;
     ;
 
It's now also possible to reproduce in the test suite all sorts of system-related issues we might observe in production over time.

2 June 2021

Joachim Breitner: Verifying the code of the Internet Identity service

The following post was meant to be posted at https://forum.dfinity.org/, but that discourse instance didn t like it; maybe too much inline code, so I m posting it here instead. To my regular blog audience, please excuse the lack of context. Please comment at the forum post. The text was later also posted on the DFINITY medium blog You probably have used https://identity.ic0.app/ to log into various applications (the NNS UI, OpenChat etc.) before, and if you do that, you are trusting this service to take good care of your credentials. Furthermore, you might want to check that the Internet Identity is really not tracking you. So you want to know: Is this really running the code we claim it to run? Of course the following applies to other canisters as well, but I ll stick to the Internet Identity in this case. I ll walk you through the steps of verifying that:

Find out what is running A service on the Internet Computer, i.e. a canister, is a WebAssembly module. The Internet Computer does intentionally not allow you to just download the Wasm code of any canisters, because maybe some developer wants to keep their code private. But it does expose a hash of the Wasm module. The easiest way to get it is using dfx:
$ dfx canister --no-wallet --network ic info rdmx6-jaaaa-aaaaa-aaadq-cai
Controller: r7inp-6aaaa-aaaaa-aaabq-cai
Module hash: 0xd4af9277f3e8d26fd8cdc7874a9f47b6456587fbb2a64d61b6b6880d144d3c04
The controller here is the canister id of the governance canister. This tells you that the Internet Identity is controlled by the Network Nervous System (NNS), and its code can only be changed via proposals that are voted on. This is good; if the controller was just, say, me, I could just change the code of the Internet Identity and take over all your identities. The Module hash is the SHA-256 hash of the .wasm that was deployed. So let s follow that trace.

Finding the right commit Since upgrades to the Internet Identity are done via proposals to the NNS, we should find a description of such a proposal in the https://github.com/ic-association/nns-proposals repository, in the proposals/network_canister_management directory.
Github s list of recent NNS proposalsGithub s list of recent NNS proposals
We have to find the latest proposal upgrading the Internet Identity. The folder unfortunately contains proposals for many canisters, and the file naming isn t super helpful. I usually go through the list from bottom and look at the second column, which contains the title of the latest commit creating or modifying a file. In this case, the second to last is the one we care about: https://github.com/ic-association/nns-proposals/blob/main/proposals/network_canister_management/20210527T2203Z.md. This file lists rationales, gives an overview of changes and, most importantly, says that bd51eab is the commit we are upgrading to. The file also says that the wasm hash is d4a c04, which matches what we saw above. This is good: it seems we really found the youngest proposal upgrading the Internet Identity, and that the proposal actually went through. WARNING: If you are paranoid, don t trust this file. There is nothing preventing a proposal proposer to create a file pointing to one revision, but actually including other code in the proposal. That s why the next steps are needed.

Getting the source Now that we have the revision, we can get the source and check out revision bd51eab:
/tmp $ git clone https://github.com/dfinity/internet-identity
Klone nach 'internet-identity' ...
remote: Enumerating objects: 3959, done.
remote: Counting objects: 100% (344/344), done.
remote: Compressing objects: 100% (248/248), done.
remote: Total 3959 (delta 161), reused 207 (delta 92), pack-reused 3615
Empfange Objekte: 100% (3959/3959), 6.05 MiB   3.94 MiB/s, Fertig.
L se Unterschiede auf: 100% (2290/2290), Fertig.
/tmp $ cd internet-identity/
/tmp/internet-identity $ git checkout bd51eab
/tmp/internet-identity $ git log --oneline -n 1
bd51eab (HEAD, tag: mainnet-20210527T2203Z) Registers the seed phrase before showing it (#301)
In the last line you see that the Internet Identity team has tagged that revision with a tag name that contains the proposal description file name. Very tidy!

Reproducing the build The README.md has the following build instructions:

Official build The official build should ideally be reproducible, so that independent parties can validate that we really deploy what we claim to deploy. We try to achieve some level of reproducibility using a Dockerized build environment. The following steps should build the official Wasm image
docker build -t internet-identity-service .
docker run --rm --entrypoint cat internet-identity-service /internet_identity.wasm > internet_identity.wasm
sha256sum internet_identity.wasm
The resulting internet_identity.wasm is ready for deployment as rdmx6-jaaaa-aaaaa-aaadq-cai, which is the reserved principal for this service.

It actually suffices to run the first command, as it also prints the hash (we don t need to copy the .wasm out of the Docker canister):
/tmp/internet-identity $ docker build -t internet-identity-service .
 
Step 26/26 : RUN sha256sum internet_identity.wasm
 ---> Running in 1a04644b544c
d4af9277f3e8d26fd8cdc7874a9f47b6456587fbb2a64d61b6b6880d144d3c04  internet_identity.wasm
Removing intermediate container 1a04644b544c
 ---> bfe6a63a7980
Successfully built bfe6a63a7980
Successfully tagged internet-identity-service:latest
Success! The hashes match. You don t believe me? Try it yourself (and let us know if you get a different hash, maybe I got hacked). This may fail if you have too little RAM configured for Docker, 8GB should be enough. At this point you have a trust path from the code sitting in front of you to the Internet Identity running at https://identity.ic0.app, including the front-end code, and you can start auditing the source code.

What about the canister id? If you payed close attention you might have noticed that we got the module has for canister rdmx6-jaaaa-aaaaa-aaadq-cai, but we are accessing a web application at https://identity.ic0.app. So where is this connection? In the future, I expect some form of a DNS-like nice host name registry on the Internet Computer that stores a mapping from nice names to canister ids, and that you will be able to query that to for which canister serves rdmx6-jaaaa-aaaaa-aaadq-cai in a secure way (e.g. using certified variables). But since we don t have that yet, but still want you to be able to use a nice name for the Internet Identity (and not have to change the name later, which would cause headaches), we have hard-coded this mapping for now. The relevant code here is the Certifying Service Worker that your browser downloads when accessing any *.ic0.app URL. This piece of code will then intercept all requests to that domain, map it to an query call, and then use certified variables to validate the response. And indeed, the mapping is in the code there:
const hostnameCanisterIdMap: Record<string, [string, string]> =  
  'identity.ic0.app': ['rdmx6-jaaaa-aaaaa-aaadq-cai', 'ic0.app'],
  'nns.ic0.app': ['qoctq-giaaa-aaaaa-aaaea-cai', 'ic0.app'],
  'dscvr.ic0.app': ['h5aet-waaaa-aaaab-qaamq-cai', 'ic0.page'],
 ;

What about other canisters? In principle, the same approach works for other canisters, whether it s OpenChat, the NNS canisters etc. But the details will differ, as every canister developer might have their own way of
  • communicating the location and revision of the source for their canisters
  • building the canisters
In particular, without a reproducible way of building the canister, this will fail, and that s why projects like https://reproducible-builds.org/ are so important in general.

30 May 2021

Dirk Eddelbuettel: td 0.0.3 on CRAN: Maintenance release

The still recent-ish td package for accessing the twelvedata API for financial data has been updated on CRAN yesterday, and is now at released version 0.0.3. A few URLs were updated to please the lint checker, and a Depends: on R 4.0.0 or later was added. We then realized (as always just after the release ) that the core issue was an incorrect version comparison which we already fixed in the git repo. The NEWS entry follows.

Changes in version 0.0.3 (2021-05-29)
  • The package now (formally) depends on R (>= 4.0.0) as it uses a recently added R function for the default config file.
  • A few URLs were updated in the README.md file

Courtesy of my CRANberries, there is a comparison to the previous release. For questions or comments use the issue tracker off the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Russ Allbery: Review: The Silver Chair

Review: The Silver Chair, by C.S. Lewis
Illustrator: Pauline Baynes
Series: Chronicles of Narnia #4
Publisher: Collier
Copyright: 1953
Printing: 1978
ISBN: 0-02-044250-5
Format: Mass market
Pages: 217
The Silver Chair is a sequel to The Voyage of the Dawn Treader and the fourth book of the Chronicles of Narnia in original publication order. (For more about publication order, see the introduction to my review of The Lion, the Witch and the Wardrobe.) Apart from a few references to The Voyage of the Dawn Treader at the start, it stands sufficiently on its own that you could read it without reading the other books, although I have no idea why you'd want to. We have finally arrived at my least favorite of the Narnia books and the one that I sometimes skipped during re-reads. (One of my objections to the new publication order is that it puts The Silver Chair and The Last Battle back-to-back, and I don't think you should do that to yourself as a reader.) I was hoping that there would be previously unnoticed depth to this book that would redeem it as an adult reader. Sadly, no; with one very notable exception, it's just not very good. MAJOR SPOILERS BELOW. The Silver Chair opens on the grounds of the awful school to which Eustace's parents sent him: Experiment House. That means it opens (and closes) with a more extended version of Lewis's rant about schools. I won't get into this in detail since it's mostly a framing device, but Lewis is remarkably vicious and petty. His snide contempt for putting girls and boys in the same school did not age well, nor did his emphasis at the end of the book that the incompetent head of the school is a woman. I also raised an eyebrow at holding up ordinary British schools as a model of preventing bullying. Thankfully, as Lewis says at the start, this is not a school story. This is prelude to Jill meeting Eustace and the two of them escaping the bullies via a magical door into Narnia. Unfortunately, that's the second place The Silver Chair gets off on the wrong foot. Jill and Eustace end up in what the reader of the series will recognize as Aslan's country and almost walk off the vast cliff at the end of the world, last seen from the bottom in The Voyage of the Dawn Treader. Eustace freaks out, Jill (who has a much better head for heights) goes intentionally close to the cliff in a momentary impulse of arrogance before realizing how high it is, Eustace tries to pull her back, and somehow Eustace falls over the edge. I do not have a good head for heights, and I wonder how much of it is due to this memorable scene. I certainly blame Lewis for my belief that pulling someone else back from the edge of a cliff can result in you being pushed off, something that on adult reflection makes very little sense but which is seared into my lizard brain. But worse, this sets the tone for the rest of the story: everything is constantly going wrong because Eustace and Jill either have normal human failings that are disproportionately punished or don't successfully follow esoteric and unreasonably opaque instructions from Aslan. Eustace is safe, of course; Aslan blows him to Narnia and then gives Jill instructions before sending her afterwards. (I suspect the whole business with the cliff was an authorial cheat to set up Jill's interaction with Aslan without Eustace there to explain anything.) She and Eustace have been summoned to Narnia to find the lost Prince, and she has to memorize four Signs that will lead her on the right path. Gah, the Signs. If you were the sort of kid that I was, you immediately went back and re-read the Signs several times to memorize them like Jill was told to. The rest of this book was then an exercise in anxious frustration. First, Eustace is an ass to Jill and refuses to even listen to the first Sign. They kind of follow the second but only with heavy foreshadowing that Jill isn't memorizing the Signs every day like she's supposed to. They mostly botch the third and have to backtrack to follow it. Meanwhile, the narrator is constantly reminding you that the kids (and Jill in particular) are screwing up their instructions. On re-reading, it's clear they're not doing that poorly given how obscure the Signs are, but the ominous foreshadowing is enough to leave a reader a nervous wreck. Worse, Eustace and Jill are just miserable to each other through the whole book. They constantly bicker and snipe, Eustace doesn't want to listen to her and blames her for everything, and the hard traveling makes it all worse. Lewis does know how to tell a satisfying redemption arc; one of the things I have always liked about Edmund's story is that he learns his lesson and becomes my favorite character in the subsequent stories. But, sadly, Eustace's redemption arc is another matter. He's totally different here than he was at the start of The Voyage of the Dawn Treader (to the degree that if he didn't have the same name in both books, I wouldn't recognize him as the same person), but rather than a better person he seems to have become a different sort of ass. There's no sign here of the humility and appreciation for friendship that he supposedly learned from his time as a dragon. On top of that, the story isn't very interesting. Rilian, the lost Prince, is a damp squib who talks in the irritating archaic accent that Lewis insists on using for all Narnian royalty. His story feels like Lewis lifted it from medieval Arthurian literature; most of it could be dropped into a collection of stories of knights of the Round Table without seeming out of place. When you have a country full of talking animals and weirdly fascinating bits of theology, it's disappointing to get a garden-variety story about an evil enchantress in which everyone is noble and tragic and extremely stupid. Thankfully, The Silver Chair has one important redeeming quality: Puddleglum. Puddleglum is a Marsh-wiggle, a bipedal amphibious sort who lives alone in the northern marshes. He's recruited by the owls to help the kids with their mission when they fail to get King Caspian's help after blowing the first Sign. Puddleglum is an absolute delight: endlessly pessimistic, certain the worst possible thing will happen at any moment, but also weirdly cheerful about it. I love Eeyore characters in general, but Puddleglum is even better because he gives the kids' endless bickering exactly the respect that it deserves.
"But we all need to be very careful about our tempers, seeing all the hard times we shall have to go through together. Won't do to quarrel, you know. At any rate, don't begin it too soon. I know these expeditions usually end that way; knifing one another, I shouldn't wonder, before all's done. But the longer we can keep off it "
It's even more obvious on re-reading that Puddleglum is the only effective member of the party. Jill has only a couple of moments where she gets the three of them past some obstacle. Eustace is completely useless; I can't remember a single helpful thing he does in the entire book. Puddleglum and his pessimistic determination, on the other hand, is right about nearly everything at each step. And he's the one who takes decisive action to break the Lady of the Green Kirtle's spell near the end. I was expecting a bit of sexism and (mostly in upcoming books) racism when re-reading these books as an adult given when they were written and who Lewis was, but what has caught me by surprise is the colonialism. Lewis is weirdly insistent on importing humans from England to fill all the important roles in stories, even stories that are entirely about Narnians. I know this is the inherent weakness of portal fantasy, but it bothers me how little Lewis believes in Narnians solving their own problems. The Silver Chair makes this blatantly obvious: if Aslan had just told Puddleglum the same information he told Jill and sent a Badger or a Beaver or a Mouse along with him, all the evidence in the book says the whole affair would have been sorted out with much less fuss and anxiety. Jill and Eustace are far more of a hindrance than a help, which makes for frustrating reading when they're supposedly the protagonists. The best part of this book is the underground bits, once they finally get through the first three Signs and stumble into the Lady's kingdom far below the surface. Rilian is a great disappointment, but the fight against the Lady's mind-altering magic leads to one of the great quotes of the series, on par with Reepicheep's speech in The Voyage of the Dawn Treader.
"Suppose we have only dreamed, or made up, all those things trees and grass and sun and moon and stars and Aslan himself. Suppose we have. Then all I can say is that, in that case, the made-up things seem a good deal more important than the real ones. Suppose this black pit of a kingdom of yours is the only world. Well, it strikes me as a pretty poor one. And that's a funny thing, when you come to think of it. We're just babies making up a game, if you're right. But four babies playing a game can make a play-world which licks your real world hollow. That's why I'm going to stand by the play world. I'm on Aslan's side even if there isn't any Aslan to lead it. I'm going to live as like a Narnian as I can even if there isn't any Narnia. So, thanking you kindly for our supper, if these two gentlemen and the young lady are ready, we're leaving your court at once and setting out in the dark to spend our lives looking for Overland. Not that our lives will be very long, I should think; but that's small loss if the world's as dull a place as you say."
This is Puddleglum, of course. And yes, I know that this is apologetics and Lewis is talking about Christianity and making the case for faith without proof, but put that aside for the moment, because this is still powerful life philosophy. It's a cynic's litany against cynicism. It's a pessimist's defense of hope. Suppose we have only dreamed all those things like justice and fairness and equality, community and consensus and collaboration, universal basic income and effective environmentalism. The dreary magic of the realists and the pragmatists say that such things are baby's games, silly fantasies. But you can still choose to live like you believe in them. In Alasdair Gray's reworking of a line from Dennis Lee, "work as if you live in the early days of a better nation." That's one moment that I'll always remember from this book. The other is after they kill the Lady of the Green Kirtle and her magic starts to fade, they have to escape from the underground caverns while surrounded by the Earthmen who served her and who they believe are hostile. It's a tense moment that turns into a delightful celebration when they realize that the Earthmen were just as much prisoners as the Prince was. They were forced from a far deeper land below, full of living metals and salamanders who speak from rivers of fire. It's the one moment in this book that I thought captured the magical strangeness of Narnia, that sense that there are wonderful things just out of sight that don't follow the normal patterns of medieval-ish fantasy. Other than a few great lines from Puddleglum and some moments in Aslan's country, the first 60% of this book is a loss and remarkably frustrating to read. The last 40% isn't bad, although I wish Rilian had any discernible character other than generic Arthurian knight. I don't know what Eustace is doing in this book at all other than providing a way for Jill to get into Narnia, and I wish Lewis had realized Puddleglum could be the protagonist. But as frustrating as The Silver Chair can be, I am still glad I re-read it. Puddleglum is one of the truly memorable characters of children's literature, and it's a shame he's buried in a weak mid-series book. Followed, in the original publication order, by The Horse and His Boy. Rating: 6 out of 10

29 May 2021

Shirish Agarwal: Planes, Pandemic and Medical Devices I

The Great Electric Airplane Race It took me quite sometime to write as have been depressed about things. Then a few days back saw Nova s The Great Electric Airplane Race. While it was fabulous and a pleasure to see and know that there are more than 200 odd startups who are in the race of making an electric airplane which works and has FAA certification. I was disappointed though that there no coverage of any University projects. From what little I know, almost all advanced materials which U.S. had made has been first researched in mostly Universities and when it is close to fruition then either spin-off as a startup or give to some commercial organization/venture to make it scalable and profitable. If they had, I am sure more people could be convinced to join sciences and engineering in college. I actually do want to come to this as part of both general medicine and vaccine development in U.S. but will come later. The idea that industry works alone should be discouraged, but that perhaps may require another article to articulate why I believe so.

Medical Device Ventilators in India Before the pandemic, probably most didn t know what a ventilator is and was, at least I didn t, although I probably used it during my somewhat brief hospital stay a couple of years ago. It entered into the Indian twitter lexicon more so in the second wave as the number of people who got infected became more and more and the ventilators which were serving them became less and less just due to sheer mismatch of numbers and requirements. Rich countries donated/gifted ventilators to India on which GOI put GST of 28%. Apparently, they are a luxury item, just like my hearing aid. Last week Delhi High Court passed a judgement that imposition of GST should not be on a gift like ventilators or oxygenators. The order can be found here. Even without reading the judgement the shout from the right was judicial activism while after reading it is a good judgement which touches on several points. The first, in itself, stating the dichotomy that if a commercial organization wanted to import a ventilator or an oxygenator the IGST payable is nil while for an individual it is 12%. The State (here State refers to State Government in this case Gujarat Govt.) did reduce the IGST for state from 12% to NIL IGST for federal states but that to till only 30.06.2021. No relief to individuals on that account. The Court also made use of Mr. Arvind Datar, as Amicus Curiae or friend of court. The petitioner, an 85-year-old gentleman who has put it up has put broad assertions under Article 21 (right to live) and the court in its wisdom also added Article 14 which enshrines equality of everyone before law. The Amicus Curiae, as his duty, guided the court into how the IGST law works and shared a brief history of the law and the changes happening before and after it. During his submissions, he also shared the Mega Exemption Notification no. 50/2017 under which several items are there which are exempted from putting IGST. The Amicus Curiae did note that such exemptions were also there before Mega Exemption Notification had come into play. However, DGFT (Directorate General of Foreign Trade) on 30-04-2021 issued notification No. 4/2015-2020 through which oxygenators had been exempted from Custom Duty/BCD (Basic Customs Duty. In another notification on no. 30/2021 dated 01.05.2021 it reduced IGST from 28% to 12% for personal use. If however the oxygenator was procured by a canalizing agency (bodies such as State Trading Corporation of India (STC) or/and Metals and Minerals Corporation (MMTC) and such are defined as canalising agents) then it will be fully exempted from paying any sort of IGST, albeit subject to certain conditions. What the conditions are were not shared in the open court. The Amicus Curiae further observed that it is contrary to practice where both BCD and IGST has been exempted for canalising agents and others, some IGST has to be paid for personal use. To share within the narrow boundaries of the topic, he shared entry no. 607A of General Exemption no.190 where duty and IGST in case of life-saving drugs are zero provided the life-saving drugs imported have been provided by zero cost from an overseas supplier for personal use. He further shared that the oxygen generator would fall in the same entry of 607A as it fulfills all the criteria as shared for life-saving medicines and devices. He also used the help of Drugs and Cosmetics Act 1940 which provides such a relief. The Amicus Curiae further noted that GOI amended its foreign trade policy (2015-2020) via notification no.4/2015-2020, dated 30.04.2021, issued by DGFT where Rakhi and life-saving drugs for personal use has been exempted from BCD till 30-07-2021. No reason not to give the same exemption to oxygenators which fulfill the same thing. The Amicus Curiae, further observes that there are exceptional circumstances provisions as adverted to in sub-section (2) of Section 25 of the Customs Act, whereby Covid-19 which is known and labelled as a pandemic where the distinctions between the two classes of individuals or agencies do not make any sense. While he did make the observation that exemption from duty is not a right, in the light of the pandemic and Article 14, it does not make sense to have distinctions between the two classes of importers. He further shared from Circular no. 9/2014-Customs, dated 19.08.2014 by CBEC (Central Board of Excise and Customs) which gave broad exemptions under Section 25 (2) of the same act in respect of goods and services imported for safety and rehabilitation of people suffering and effected by natural disasters and epidemics. He further submits that the impugned notification is irrational as there is no intelligible differentia rule applied or observed in classifying the import of oxygen concentrators into two categories. One, by the State and its agencies; and the other, by an individual for personal use by way of gift. So there was an absence of adequate determining principle . To bolster his argument, he shared the judgements of

a) Union of India vs. N.S. Rathnam & Sons, (2015) 10 SCC 681 (N.S. Ratnams and Sons Case) b) Shayara Bano vs. Union of India, (2017) 9 SCC 1 (Shayara Bano Case) The Amicus Curiae also rightly observed that the right to life also encompasses within it, the right to health. You cannot have one without the other and within that is the right to have affordable treatment. He further stated that the state does not only have a duty but a positive obligation is cast upon it to ensure that the citizen s health is secured. He again cited Navtej Singh Johars vs Union of India (Navtej Singh Johar Case) in defence of right to life. Mr. Datar also shared that unlike in normal circumstances, it is and should be enough to show distinct and noticeable burdensomeness which is directly attributable to the impugned/questionable tax. The gentleman cited Indian Express Newspapers (Bombay) Private Limited vs. Union of India, (1985) 1 SCC 641 (Indian Express case) 1985 which shared both about Article 19 (1) (a) and Article 21. Bloggers note At this juncture, I should point out which I am sharing the judgement and I would be sharing only the Amicus Curiae POV and then the judge s final observations. While I was reading it, I was stuck by the fact that the Amicus Curiae had cited 4 cases till now, 3 of them are pretty well known both in the legal fraternity and even among public at large. Another 3 which have been shared below which are also of great significance. Hence, felt the need to share the whole judgement. The Amicus Curiae further observed that this tax would have to be disproportionately will have to be paid by the old and the infirm, and they might find it difficult to pay the amounts needed to pay the customs duty/IGST as well as find the agent to pay in this pandemic. Blogger Note The situation with the elderly is something like this. Now there are a few things to note, only Central Govt. employees and pensioners get pensions which has been freezed since last year. The rest of the elderly population does not. The rate of interest has fallen to record lows from 5-6% in savings interest rate to 2% and on Fixed Deposits at 4.9% while the nominal inflation rate has up by 6% while CPI and real inflation rates are and would be much more. And this is when there is absolutely no demand in the economy. To add to all this, RBI shared a couple of months ago that fraud of 5 trillion rupees has been committed between 2015 and 2019 in banks. And this is different from the number of record NPA s that have been both in Public and Private Sector banks. To get out of this, the banks have squeezed their customers and are squeezing as well as asking GOI for bailouts. How much GOI is responsible for the frauds as well as NPA s would probably require its own space. And even now, RBI and banks have made heavy provisions as lockdowns are still a facet and are supposed to remain a facet till the end of the year or even next year (all depending upon when we get the vaccine). The Amicus Curiae further argued that the ventilators which are available locally are of bad quality. The result of all this has resulted in a huge amount of unsurmountable pressure on hospitals which they are unable to overcome. Therefore, the levy of IGST on oxygenators has direct impact on health of the citizen. So the examination of the law should not be by what intention it was but how it is affecting citizen rights now. For this he shared R.C.Cooper vs Union of India (another famous case R.C. Cooper vs Union of India) especially paragraph 49 and Federation of Hotel & Restaurant Association of India vs. Union of India, (1989) at paragraph 46 (Federation of Hotel Case) Mr. Datar further shared the Supreme Court order dated 18.12.2020, passed in Suo Moto Writ Petition(Civil) No.7/2020, to buttress the plea that the right to health includes the right to affordable treatment. Blogger s Note For those, who don t know Suo Moto is when the Court, whether Supreme Court or the High Courts take up a matter for public good. It could be in anything, law and order, Banking, Finance, Public Health etc. etc. This was the norm before 2014. The excesses of the executive were curtailed by both the Higher and the lower Judiciary. That is and was the reason that Judiciary is and was known as the third pillar of Indian democracy. A good characterization of Suo Moto can be found here. Before ending his submission, the learned Amicus Curiae also shared Jeeja Ghosh vs. Union of India, (2016) (Jeeja Ghosh Case, an outstanding case as it deals with people with disabilities and their rights and the observations made by the Division Bench of Hon ble Mr. Justice A. K. Sikri as well as Hon ble Mr. Justice R. K. Agrawal.) After Amicus Curiae completed his submissions, it was the turn of Mr. Sudhir Nandrajog, and he adopted the arguments and submissions made by the Amicus Curiae. The gentleman reiterated the facts of the case and how the impugned notification was violative of both Article 14 and 21 of the Indian Constitution. Blogger s Note The High Court s judgement which shows all the above arguments by the Amicus Curiae and the petitioner s lawyer also shared the State s view. It is only on page 24, where the Delhi High Court starts to share its own observations on the arguments of both sides. Judgement continued The first observation that the Court makes is that while the petitioner demonstrated that the impugned tax imposition would have a distinct and noticeable burdensomeness while the State did not state or share in any way how much of a loss it would incur if such a tax were let go and how much additional work would have to be done in order to receive this specific tax. It didn t need to do something which is down the wire or mathematically precise, but it didn t even care to show even theoretically how many people will be affected by the above. The counter-affidavit by the State is silent on the whole issue. The Court also contended that the State failed to prove how collecting IGST from the concerned individuals would help in fighting coronavirus in any substantial manner for the public at large. The High Court shared observations from the Navtej Singh Johar case where it is observed that the State has both negative and positive obligations to ensure that its citizens are able to enjoy the right to health. The High Court further made the point that no respectable person does like to be turned into a charity case. If the State contends that those who obey the law should pay the taxes then it is also obligatory on the state s part to lessen exactions such as taxes at the very least in times of war, famine, floods, epidemics and pandemics. Such an approach would lead a person to live a life of dignity which is part of Article 21 of the Constitution. Another point that was made by the State that only the GST council is able to make any changes as regards to exemptions rather than the State were found to be false as the State had made some exemptions without going to the GST council using its own powers under Section 25 of the Customs Act. The Court also points out that it does send a discriminatory pattern when somebody like petitioner has to pay the tax for personal use while those who are buying it for commercial use do not have to pay the tax. The Court agreed of the view of the Amicus Curiae, Mr. Datar that oxygenator should be taxed at NIL rate at IGST as it is part of life-saving drugs and oxygenator fits the bill as medical equipment as it is used in the treatment, mitigation and prevention of spread of Coronavirus. Mr. Datar also did show that oxygenator is placed at the same level as other life-saving drugs. The Court felt further emboldened as the observations by Supreme Court in State of Andhra Pradesh vs. Linde India Limited, 2020 ( State of Andhra Pradesh vs Linde Ltd.) The Court further shared many subsequent notifications from the State and various press releases by the State itself which does make the Court s point that oxygenators indeed are drugs as defined in the court case above. The State should have it as part of notification 190. This would preserve the start of the notification date from 03.05.2021 and the state would not have to issue a new notification. The Court further went to postulate that any persons similar to the petitioner could avail of the same, if they furnish a letter of undertaking to an officer designated by the State that the medical equipment would not be put to commercial use. Till the state does not do that, in the interim the importer could give the same undertaking to Joint Secretary, Customs or their nominee can hand over the same to custom officer. The Court also shared that it does not disagree with the State s arguments but the challenges which have arisen are in a unique time period/circumstances, so they are basing their judgement based on how the situation is. The Court also mentioned an order given by Supreme Court Diary No. 10669/2020 passed on 20.03.2020 where SC has taken pains to understand the issues faced by the citizens. The court also mentioned the Small Scale Industrial Manufactures Association Case (both of these cases I don t know) . So in conclusion, the Court holds the imposition of IGST on oxygenator which are imported by individuals as gifts from their relatives as unconstitutional. They also shared that any taxes taken by GOI in above scenario have to be returned. The relief to the state is they will not have to pay interest cost on the same. To check misuse of the same, the petitioner or people who are in similar circumstances would have to give a letter of undertaking to an officer designated by the State within 7 days of the state notifying the patient or anybody authorized by him/her to act on their behalf to share the letter of undertaking with the State. And till the State doesn t provide an officer, the above will continue. Hence, both the writ petition and the pending application are disposed off. The Registry is directed to release any money deposited by the petitioner along with any interest occurred on it (if any) . At the end they record appreciation of Mr. Arvind Datar, Mr. Zoheb Hossain, Mr. Sudhir Nandrajog as well as Mr. Siddharth Bambha. It is only due to their assistance that the court could reach the conclusion it did. For Delhi High Court RAJIV SHAKDHER, J. TALWANT SINGH, J. May 21, 2020 Blogger s Observations Now, after the verdict GOI does have few choices, either accept the verdict or appeal in the SC. A third choice is to make a committee and come to the same conclusions via the committee. GOI has done something similar in the past. If that happens and the same conclusions are reached as before, then the aggrieved may have no choice but to appear in the highest court of law. And this will put the aggrieved at a much more vulnerable place than before as SC court fees, lawyer fees etc. are quite high compared to High Courts. So, there is a possibility that the petitioner may not even approach unless and until some non-profit (NGO) does decide to fight and put it up as common cause or something similar. There is another judgement that I will share, probably tomorrow. Thankfully, that one is pretty short compared to this one. So it should be far more easier to read. FWIW, I did learn about the whole freeenode stuff and many channels who have shifted from freenode to libera. I will share my own experience of the same but that probably will take a day or two.
Zeeshan of IYC (India Youth Congress) along with Salman Khan s non-profit Being Human getting oxygenators
The above picture of Zeeshan. There have been a whole team of Indian Youth Congress workers (main opposition party to the ruling party) who have doing lot of relief effort. They have been buying Oxygenators from abroad with help of Being Human Foundation started by Salman Khan, an actor who works in A-grade movies in Bollywood.

27 May 2021

Wouter Verhelst: SReview and pandemics

The pandemic was a bit of a mess for most FLOSS conferences. The two conferences that I help organize -- FOSDEM and DebConf -- are no exception. In both conferences, I do essentially the same work: as a member of both video teams, I manage the postprocessing of the video recordings of all the talks that happened at the respective conference(s). I do this by way of SReview, the online video review and transcode system that I wrote, which essentially crowdsources the manual work that needs to be done, and automates as much as possible of the workflow. The original version of SReview consisted of a database, a (very basic) Mojolicious-based webinterface, and a bunch of perl scripts which would build and execute ffmpeg command lines using string interpolation. As a quick hack that I needed to get working while writing it in my spare time in half a year, that approach was workable and resulted in successful postprocessing after FOSDEM 2017, and a significant improvement in time from the previous years. However, I did not end development with that, and since then I've replaced the string interpolation by an object oriented API for generating ffmpeg command lines, as well as modularized the webinterface. Additionally, I've had help reworking the user interface into a system that is somewhat easier to use than my original interface, and have slowly but surely added more features to the system so as to make it more flexible, as well as support more types of environments for the system to run in. One of the major issues that still remains with SReview is that the administrator's interface is pretty terrible. I had been planning on revamping that for 2020, but then massive amounts of people got sick, travel was banned, and both the conferences that I work on were converted to an online-only conference. These have some very specific requirements; e.g., both conferences allowed people to upload a prerecorded version of their talk, rather than doing the talk live; since preprocessing a video is, technically, very similar to postprocessing it, I adapted SReview to allow people to upload a video file that it would then validate (in terms of length, codec, and apparent resolution). This seems like easy to do, but I decided to implement this functionality so that it would also allow future use for in-person conferences, where occasionally a speaker requests that modifications would be made to the video file in a way that SReview is unable to do. This made it marginally more involved, but at least will mean that a feature which I had planned to implement some years down the line is now already implemented. The new feature works quite well, and I'm happy I've implemented it in the way that I have. In order for the "upload" processing and the "post-event" processing to not be confused, however, I decided to import the conference schedules twice: once as the conference itself, and once as a shadow version of that conference for the prerecordings. That way, I could track the progress through the system of the prerecording completely separately from the progress of the postprocessing of the video (which adds opening/closing credits, and transcodes to multiple variants of the same video). Schedule parsing was something that had not been implemented in a generic way yet, however; since that made doubling the schedule in that way rather complex, I decided to bite the bullet and (finally) implement schedule parsing in a generic way. Currently, schedule parsers exist for two formats (Pentabarf XML and the Wafer variant of that same format which is almost, but not quite, entirely the same). The API for that is quite flexible, and I'm happy with the way things have been implemented there. I've also implemented a set of "virtual" parsers, which allow mangling the schedule in various ways (by either filtering out talks that we don't want, or by generating the shadow version of the schedule that I talked about earlier). While the SReview settings have reasonable defaults, occasionally the output of SReview is not entirely acceptable, due to more complicated matters that then result in encoding artifacts. As a result, the DebConf video team has been doing a final review step, completely outside of SReview, to ensure that such encoding artifacts don't exist. That seemed suboptimal, so recently I've been working on integrating that into SReview as well. First tests have been run, and seem to be acceptable, but there's still a few loose ends to be finalized. As part of this, I've also reworked the way comments could be entered into the system. Previously the presence of a comment would signal that the video has some problems that an administrator needed to look at. Unfortunately, that was causing some confusion, with some people even thinking it's a good place to enter a "thank you for your work" style of comment... which it obviously isn't. Turning it into a "comment log" system instead fixes that, and also allows for better two-way communication between administrators and reviewers. Hopefully that'll improve things in that area as well. Finally, the audio normalization in SReview -- for which I've long used bs1770gain -- is having problems. First of all, bs1770gain will sometimes alter the timing of the video or audio file that it's passed, which is very problematic if I want to process it further. There is an ffmpeg loudnorm filter which implements the same algorithm, so that should make things easier to use. Secondly, the author of bs1770gain is a strange character that I'd rather not be involved with. Before I knew about the loudnorm filter I didn't really have a choice, but now I can just rip bs1770gain out and replace it by the loudnorm filter. That will fix various other bugs in SReview, too, because SReview relies on behaviour that isn't actually there (but which I didn't know at the time when I wrote it). All in all, the past year-and-a-bit has seen a lot of development for SReview, with multiple features being added and a number of long-standing problems being fixed. Now if only the pandemic would subside, allowing the whole "let's do everything online only" wave to cool down a bit, so that I can finally make time to implement the admin interface...

25 May 2021

Thomas Lange: Adding a custom postinst script to the FAI image

The FAIme service now supports uploading a custom shell script. This script is added to the installation ISO and gets executed during the first boot on request. You can upload a plain shell script or a compressed version using gzip. Using the postinst script you can adjust the new installed system to your local needs after FAI has done the initial installation. The FAIme service is a web service, that creates customized installation images by just a few clicks. It's also possible to create custom cloud images via the web interface.

Vincent Bernat: Jerikan+Ansible: a configuration management system for network

There are many resources for network automation with Ansible. Most of them only expose the first steps or limit themselves to a narrow scope. They give no clue on how to expand from that. Real network environments may be large, versatile, heterogeneous, and filled with exceptions. The lack of real-world examples for Ansible deployments, unlike Puppet and SaltStack, leads many teams to build brittle and incomplete automation solutions. We have released under an open-source license our attempt to tackle this problem: Here is a quick demo to configure a new peering:
This work is the collective effort of C dric Hasco t, Jean-Christophe Legatte, Lo c Pailhas, S bastien Hurtel, Tchadel Icard, and Vincent Bernat. We are the network team of Blade, a French company operating Shadow, a cloud-computing product. In May 2021, our company was bought by Octave Klaba and the infrastructure is being transferred to OVHcloud, saving Shadow as a product, but making our team redundant. Our network was around 800 devices, spanning over 10 datacenters with more than 2.5 Tbps of available egress bandwidth. The released material is therefore a substantial example of managing a medium-scale network using Ansible. We have left out the handling of our legacy datacenters to make the final result more readable while keeping enough material to not turn it into a trivial example.

Jerikan The first component is Jerikan. As input, it takes a list of devices, configuration data, templates, and validation scripts. It generates a set of configuration files for each device. Ansible could cover this task, but it has the following limitations:
  • it is slow;
  • errors are difficult to debug;1 and
  • the hierarchy to look up a variable is rigid.
Jerikan inputs and outputs
If you want to follow the examples, you only need to have Docker and Docker Compose installed. Clone the repository and you are ready!

Source of truth We use YAML files, versioned with Git, as the single source of truth instead of using a database, like NetBox, or a mix of a database and text files. This provides many advantages:
  • anyone can use their preferred text editor;
  • the team prepares changes in branches;
  • the team reviews changes using merge requests;
  • the merge requests expose the changes to the generated configuration files;
  • rollback to a previous state is easy; and
  • it is fast.
The first file is devices.yaml. It contains the device list. The second file is classifier.yaml. It defines a scope for each device. A scope is a set of keys and values. It is used in templates and to look up data associated with a device.
$ ./run-jerikan scope to1-p1.sk1.blade-group.net
continent: apac
environment: prod
groups:
- tor
- tor-bgp
- tor-bgp-compute
host: to1-p1.sk1
location: sk1
member: '1'
model: dell-s4048
os: cumulus
pod: '1'
shorthost: to1-p1
The device name is matched against a list of regular expressions and the scope is extended by the result of each match. For to1-p1.sk1.blade-group.net, the following subset of classifier.yaml defines its scope:
matchers:
  - '^(([^.]*)\..*)\.blade-group\.net':
      environment: prod
      host: '\1'
      shorthost: '\2'
  - '\.(sk1)\.':
      location: '\1'
      continent: apac
  - '^to([12])-[as]?p(\d+)\.':
      member: '\1'
      pod: '\2'
  - '^to[12]-p\d+\.':
      groups:
        - tor
        - tor-bgp
        - tor-bgp-compute
  - '^to[12]-(p ap)\d+\.sk1\.':
      os: cumulus
      model: dell-s4048
The third file is searchpaths.py. It describes which directories to search for a variable. A Python function provides a list of paths to look up in data/ for a given scope. Here is a simplified version:2
def searchpaths(scope):
    paths = [
        "host/ scope[location] / scope[shorthost] ",
        "location/ scope[location] ",
        "os/ scope[os] - scope[model] ",
        "os/ scope[os] ",
        'common'
    ]
    for idx in range(len(paths)):
        try:
            paths[idx] = paths[idx].format(scope=scope)
        except KeyError:
            paths[idx] = None
    return [path for path in paths if path]
With this definition, the data for to1-p1.sk1.blade-group.net is looked up in the following paths:
$ ./run-jerikan scope to1-p1.sk1.blade-group.net
[ ]
Search paths:
  host/sk1/to1-p1
  location/sk1
  os/cumulus-dell-s4048
  os/cumulus
  common
Variables are scoped using a namespace that should be specified when doing a lookup. We use the following ones:
  • system for accounts, DNS, syslog servers,
  • topology for ports, interfaces, IP addresses, subnets,
  • bgp for BGP configuration
  • build for templates and validation scripts
  • apps for application variables
When looking up for a variable in a given namespace, Jerikan looks for a YAML file named after the namespace in each directory in the search paths. For example, if we look up a variable for to1-p1.sk1.blade-group.net in the bgp namespace, the following YAML files are processed: host/sk1/to1-p1/bgp.yaml, location/sk1/bgp.yaml, os/cumulus-dell-s4048/bgp.yaml, os/cumulus/bgp.yaml, and common/bgp.yaml. The search stops at the first match. The schema.yaml file allows us to override this behavior by asking to merge dictionaries and arrays across all matching files. Here is an excerpt of this file for the topology namespace:
system:
  users:
    merge: hash
  sampling:
    merge: hash
  ansible-vars:
    merge: hash
  netbox:
    merge: hash
The last feature of the source of truth is the ability to use Jinja2 templates for keys and values by prefixing them with ~ :
# In data/os/junos/system.yaml
netbox:
  manufacturer: Juniper
  model: "~  model upper  "
# In data/groups/tor-bgp-compute/system.yaml
netbox:
  role: net_tor_gpu_switch
Looking up for netbox in the system namespace for to1-p2.ussfo03.blade-group.net yields the following result:
$ ./run-jerikan scope to1-p2.ussfo03.blade-group.net
continent: us
environment: prod
groups:
- tor
- tor-bgp
- tor-bgp-compute
host: to1-p2.ussfo03
location: ussfo03
member: '1'
model: qfx5110-48s
os: junos
pod: '2'
shorthost: to1-p2
[ ]
Search paths:
[ ]
  groups/tor-bgp-compute
[ ]
  os/junos
  common
$ ./run-jerikan lookup to1-p2.ussfo03.blade-group.net system netbox
manufacturer: Juniper
model: QFX5110-48S
role: net_tor_gpu_switch
This also works for structured data:
# In groups/adm-gateway/topology.yaml
interface-rescue:
  address: "~  lookup('topology', 'addresses').rescue  "
  up:
    - "~ip route add default via   lookup('topology', 'addresses').rescue ipaddr('first_usable')   table rescue"
    - "~ip rule add from   lookup('topology', 'addresses').rescue ipaddr('address')   table rescue priority 10"
# In groups/adm-gateway-sk1/topology.yaml
interfaces:
  ens1f0: "~  lookup('topology', 'interface-rescue')  "
This yields the following result:
$ ./run-jerikan lookup gateway1.sk1.blade-group.net topology interfaces
[ ]
ens1f0:
  address: 121.78.242.10/29
  up:
  - ip route add default via 121.78.242.9 table rescue
  - ip rule add from 121.78.242.10 table rescue priority 10
When putting data in the source of truth, we use the following rules:
  1. Don t repeat yourself.
  2. Put the data in the most specific place without breaking the first rule.
  3. Use templates with parsimony, mostly to help with the previous rules.
  4. Restrict the data model to what is needed for your use case.
The first rule is important. For example, when specifying IP addresses for a point-to-point link, only specify one side and deduce the other value in the templates. The last rule means you do not need to mimic a BGP YANG model to specify BGP peers and policies:
peers:
  transit:
    cogent:
      asn: 174
      remote:
        - 38.140.30.233
        - 2001:550:2:B::1F9:1
      specific-import:
        - name: ATT-US
          as-path: ".*7018$"
          lp-delta: 50
  ix-sfmix:
    rs-sfmix:
      monitored: true
      asn: 63055
      remote:
        - 206.197.187.253
        - 206.197.187.254
        - 2001:504:30::ba06:3055:1
        - 2001:504:30::ba06:3055:2
    blizzard:
      asn: 57976
      remote:
        - 206.197.187.42
        - 2001:504:30::ba05:7976:1
      irr: AS-BLIZZARD

Templates The list of templates to compile for each device is stored in the source of truth, under the build namespace:
$ ./run-jerikan lookup edge1.ussfo03.blade-group.net build templates
data.yaml: data.j2
config.txt: junos/main.j2
config-base.txt: junos/base.j2
config-irr.txt: junos/irr.j2
$ ./run-jerikan lookup to1-p1.ussfo03.blade-group.net build templates
data.yaml: data.j2
config.txt: cumulus/main.j2
frr.conf: cumulus/frr.j2
interfaces.conf: cumulus/interfaces.j2
ports.conf: cumulus/ports.j2
dhcpd.conf: cumulus/dhcp.j2
default-isc-dhcp: cumulus/default-isc-dhcp.j2
authorized_keys: cumulus/authorized-keys.j2
motd: linux/motd.j2
acl.rules: cumulus/acl.j2
rsyslog.conf: cumulus/rsyslog.conf.j2
Templates are using Jinja2. This is the same engine used in Ansible. Jerikan ships some custom filters but also reuse some of the useful filters from Ansible, notably ipaddr. Here is an excerpt of templates/junos/base.j2 to configure DNS and NTP servers on Juniper devices:
system  
  ntp  
 % for ntp in lookup("system", "ntp") % 
    server   ntp  ;
 % endfor % 
   
  name-server  
 % for dns in lookup("system", "dns") % 
      dns  ;
 % endfor % 
   
 
The equivalent template for Cisco IOS-XR is:
 % for dns in lookup('system', 'dns') % 
domain vrf VRF-MANAGEMENT name-server   dns  
 % endfor % 
!
 % for syslog in lookup('system', 'syslog') % 
logging   syslog   vrf VRF-MANAGEMENT
 % endfor % 
!
There are three helper functions provided:
  • devices() returns the list of devices matching a set of conditions on the scope. For example, devices("location==ussfo03", "groups==tor-bgp") returns the list of devices in San Francisco in the tor-bgp group. You can also omit the operator if you want the specified value to be equal to the one in the local scope. For example, devices("location") returns devices in the current location.
  • lookup() does a key lookup. It takes the namespace, the key, and optionally, a device name. If not provided, the current device is assumed.
  • scope() returns the scope of the provided device.
Here is how you would define iBGP sessions between edge devices in the same location:
 % for neighbor in devices("location", "groups==edge") if neighbor != device % 
   % for address in lookup("topology", "addresses", neighbor).loopback tolist % 
protocols bgp group IPV  address ipv  -EDGES-IBGP  
  neighbor   address    
    description "IPv  address ipv  : iBGP to   neighbor  ";
   
 
   % endfor % 
 % endfor % 
We also have a global key-value store to save information to be reused in another template or device. This is quite useful to automatically build DNS records. First, capture the IP address inserted into a template with store() as a filter:
interface Loopback0
 description 'Loopback:'
  % for address in lookup('topology', 'addresses').loopback tolist % 
 ipv  address ipv   address   address store('addresses', 'Loopback0') ipaddr('cidr')  
  % endfor % 
!
Then, reuse it later to build DNS records by iterating over store():4
 % for device, ip, interface in store('addresses') % 
   % set interface = interface replace('/', '-') replace('.', '-') replace(':', '-') % 
   % set name = ' . '.format(interface lower, device) % 
  name  . IN   'A' if ip ipv4 else 'AAAA'     ip ipaddr('address')  
 % endfor % 
Templates are compiled locally with ./run-jerikan build. The --limit argument restricts the devices to generate configuration files for. Build is not done in parallel because a template may depend on the data collected by another template. Currently, it takes 1 minute to compile around 3000 files spanning over 800 devices.
Jerikan outputs when building templates
Output of Jerikan after building configuration files for six devices
When an error occurs, a detailed traceback is displayed, including the template name, the line number and the value of all visible variables. This is a major time-saver compared to Ansible!
templates/opengear/config.j2:15: in top-level template code
    config.interfaces.  interface  .netmask   adddress   ipaddr("netmask")  
        continent  = 'us'
        device     = 'con1-ag2.ussfo03.blade-group.net'
        environment = 'prod'
        host       = 'con1-ag2.ussfo03'
        infos      =  'address': '172.30.24.19/21' 
        interface  = 'wan'
        location   = 'ussfo03'
        loop       = <LoopContext 1/2>
        member     = '2'
        model      = 'cm7132-2-dac'
        os         = 'opengear'
        shorthost  = 'con1-ag2'
_ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _ _
value = JerkianUndefined, query = 'netmask', version = False, alias = 'ipaddr'
[ ]
        # Check if value is a list and parse each element
        if isinstance(value, (list, tuple, types.GeneratorType)):
            _ret = [ipaddr(element, str(query), version) for element in value]
            return [item for item in _ret if item]
>       elif not value or value is True:
E       jinja2.exceptions.UndefinedError: 'dict object' has no attribute 'adddress'
We don t have general-purpose rules when writing templates. Like for the source of truth, there is no need to create generic templates able to produce any BGP configuration. There is a balance to be found between readability and avoiding duplication. Templates can become scary and complex: sometimes, it s better to write a filter or a function in jerikan/jinja.py. Mastering Jinja2 is a good investment. Take time to browse through our templates as some of them show interesting features.

Checks Optionally, each configuration file can be validated by a script in the checks/ directory. Jerikan looks up the key checks in the build namespace to know which checks to run:
$ ./run-jerikan lookup edge1.ussfo03.blade-group.net build checks
- description: Juniper configuration file syntax check
  script: checks/junoser
  cache:
    input: config.txt
    output: config-set.txt
- description: check YAML data
  script: checks/data.yaml
  cache: data.yaml
In the above example, checks/junoser is executed if there is a change to the generated config.txt file. It also outputs a transformed version of the configuration file which is easier to understand when using diff. Junoser checks a Junos configuration file using Juniper s XML schema definition for Netconf.5 On error, Jerikan displays:
jerikan/build.py:127: RuntimeError
-------------- Captured syntax check with Junoser call --------------
P: checks/junoser edge2.ussfo03.blade-group.net
C: /app/jerikan
O:
E: Invalid syntax:  set system syslog archive size 10m files 10 word-readable
S: 1

Integration into GitLab CI The next step is to compile the templates using a CI. As we are using GitLab, Jerikan ships with a .gitlab-ci.yml file. When we need to make a change, we create a dedicated branch and a merge request. GitLab compiles the templates using the same environment we use on our laptops and store them as an artifact.
Merge requests in GitLab for a change
Merge request to add a new port in USSFO03. The templates were compiled successfully but approval from another team member is still required to merge.
Before approving the merge request, another team member looks at the changes in data and templates but also the differences for the generated configuration files:
Differences for generated configuration files
The change configures a port on the Juniper device, adds records to DNS, and updates NetBox with the new IP addresses (not shown).

Ansible After Jerikan has built the configuration files, Ansible takes over. It is also packaged as a Docker image to avoid the trouble to maintain the right Python virtual environment and ensure everyone is using the same versions.

Inventory Jerikan has generated an inventory file. It contains all the managed devices, the variables defined for each of them and the groups converted to Ansible groups:
ob1-n1.sk1.blade-group.net ansible_host=172.29.15.12 ansible_user=blade ansible_connection=network_cli ansible_network_os=ios
ob2-n1.sk1.blade-group.net ansible_host=172.29.15.13 ansible_user=blade ansible_connection=network_cli ansible_network_os=ios
ob1-n1.ussfo03.blade-group.net ansible_host=172.29.15.12 ansible_user=blade ansible_connection=network_cli ansible_network_os=ios
none ansible_connection=local
[oob]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
ob1-n1.ussfo03.blade-group.net
[os-ios]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
ob1-n1.ussfo03.blade-group.net
[model-c2960s]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
ob1-n1.ussfo03.blade-group.net
[location-sk1]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
[location-ussfo03]
ob1-n1.ussfo03.blade-group.net
[in-sync]
ob1-n1.sk1.blade-group.net
ob2-n1.sk1.blade-group.net
ob1-n1.ussfo03.blade-group.net
none
in-sync is a special group for devices which configuration should match the golden configuration. Daily and unattended, Ansible should be able to push configurations to this group. The mid-term goal is to cover all devices. none is a special device for tasks not related to a specific host. This includes synchronizing NetBox, IRR objects, and the DNS, updating the RPKI, and building the geofeed files.

Playbook We use a single playbook for all devices. It is described in the ansible/playbooks/site.yaml file. Here is a shortened version:
- hosts: adm-gateway:!done
  strategy: mitogen_linear
  roles:
    - blade.linux
    - blade.adm-gateway
    - done
- hosts: os-linux:!done
  strategy: mitogen_linear
  roles:
    - blade.linux
    - done
- hosts: os-junos:!done
  gather_facts: false
  roles:
    - blade.junos
    - done
- hosts: os-opengear:!done
  gather_facts: false
  roles:
    - blade.opengear
    - done
- hosts: none:!done
  gather_facts: false
  roles:
    - blade.none
    - done
A host executes only one of the play. For example, a Junos device executes the blade.junos role. Once a play has been executed, the device is added to the done group and the other plays are skipped. The playbook can be executed with the configuration files generated by the GitLab CI using the ./run-ansible-gitlab command. This is a wrapper around Docker and the ansible-playbook command and it accepts the same arguments. To deploy the configuration on the edge devices for the SK1 datacenter in check mode, we use:
$ ./run-ansible-gitlab playbooks/site.yaml --limit='edge:&location-sk1' --diff --check
[ ]
PLAY RECAP *************************************************************
edge1.sk1.blade-group.net  : ok=6    changed=0    unreachable=0    failed=0    skipped=3    rescued=0    ignored=0
edge2.sk1.blade-group.net  : ok=5    changed=0    unreachable=0    failed=0    skipped=1    rescued=0    ignored=0
We have some rules when writing roles:
  • --check must detect if a change is needed;
  • --diff must provide a visualization of the planned changes;
  • --check and --diff must not display anything if there is nothing to change;
  • writing a custom module tailored to our needs is a valid solution;
  • the whole device configuration is managed;6
  • secrets must be stored in Vault;
  • templates should be avoided as we have Jerikan for that; and
  • avoid duplication and reuse tasks.7
We avoid using collections from Ansible Galaxy, the exception being collections to connect and interact with vendor devices, like cisco.iosxr collection. The quality of Ansible Galaxy collections is quite random and it is an additional maintenance burden. It seems better to write roles tailored to our needs. The collections we use are in ci/ansible/ansible-galaxy.yaml. We use Mitogen to get a 10 speedup on Ansible executions on Linux hosts. We also have a few playbooks for operational purpose: upgrading the OS version, isolate an edge router, etc. We were also planning on how to add operational checks in roles: are all the BGP sessions up? They could have been used to validate a deployment and rollback if there is an issue. Currently, our playbooks are run from our laptops. To keep tabs, we are using ARA. A weekly dry-run on devices in the in-sync group also provides a dashboard on which devices we need to run Ansible on.

Configuration data and templates Jerikan ships with pre-populated data and templates matching the configuration of our USSFO03 and SK1 datacenters. They do not exist anymore but, we promise, all this was used in production back in the days!
Network architecture for Blade datacenter
The latest iteration of our network infrastructure for SK1, USSFO03, and future data centers. The production network is using BGPttH using a spine-leaf fabric. The out-of-band network is using a simple L2 design, using the spanning tree protocol, as well as a set of console servers.
Notably, you can find the configuration for:
our edge routers
Some are running on Junos, like edge2.ussfo03, the others on IOS-XR, like edge1.sk1. The implemented functionalities are similar in both cases and we could swap one for the other. It includes the BGP configuration for transits, peerings, and IX as well as the associated BGP policies. PeeringDB is queried to get the maximum number of prefixes to accept for peerings. bgpq3 and a containerized IRRd help to filter received routes. A firewall is added to protect the routing engine. Both IPv4 and IPv6 are configured.
our BGP-based fabric
BGP is used inside the datacenter8 and is extended on bare-metal hosts. The configuration is automatically derived from the device location and the port number.9 Top-of-the-rack devices are using passive BGP sessions for ports towards servers. They are also serving a provisioning network to let them boot using DHCP and PXE. They also act as a DHCP server. The design is multivendor. Some devices are running Cumulus Linux, like to1-p1.ussfo03, while some others are running Junos, like to1-p2.ussfo03.
our out-of-band fabric
We are using Cisco Catalyst 2960 switches to build an L2 out-of-band network. To provide redundancy and saving a few bucks on wiring, we build small loops and run the spanning-tree protocol. See ob1-p1.ussfo03. It is redundantly connected to our gateway servers. We also use OpenGear devices for console access. See con1-n1.ussfo03
our administrative gateways
These Linux servers have multiple purposes: SSH jump boxes, rescue connection, direct access to the out-of-band network, zero-touch provisioning of network devices,10 Internet access for management flows, centralization of the console servers using Conserver, and API for autoconfiguration of BGP sessions for bare-metal servers. They are the first servers installed in a new datacenter and are used to provision everything else. Check both the generated files and the associated Ansible tasks.

  1. Ansible does not even provide a line number when there is an error in a template. You may need to find the problem by bisecting.
    $ ansible --version
    ansible 2.10.8
    [ ]
    $ cat test.j2
    Hello   name  !
    $ ansible all -i localhost, \
    >  --connection=local \
    >  -m template \
    >  -a "src=test.j2 dest=test.txt"
    localhost   FAILED! =>  
        "changed": false,
        "msg": "AnsibleUndefinedVariable: 'name' is undefined"
     
    
  2. You may recognize the same concepts as in Hiera, the hierarchical key-value store from Puppet. At first, we were using Jerakia, a similar independent store exposing an HTTP REST interface. However, the lookup overhead is too large for our use. Jerikan implements the same functionality within a Python function.
  3. The list of available filters is mangled inside jerikan/jinja.py. This is a remain of the fact we do not maintain Jerikan as a standalone software.
  4. This is a bit confusing: we have a store() filter and a store() function. With Jinja2, filters and functions live in two different namespaces.
  5. We are using a fork with some modifications to be able to validate our configurations and exposing an HTTP service to reduce the time spent on each configuration check.
  6. There is a trend in network automation to automate a configuration subset, for example by having a playbook to create a new BGP session. We believe this is wrong: with time, your configuration will get out-of-sync with its expected state, notably hand-made changes will be left undetected.
  7. See ansible/roles/blade.linux/tasks/firewall.yaml and ansible/roles/blade.linux/tasks/interfaces.yaml. They are meant to be called when needed, using import_role.
  8. We also have some datacenters using BGP EVPN VXLAN at medium-scale using Juniper devices. As they are still in production today, we didn t include this feature but we may publish it in the future.
  9. In retrospect, this may not be a good idea unless you are pretty sure everything is uniform (number of switches for each layer, number of ports). This was not our case. We now think it is a better idea to assign a prefix to each device and write it in the source of truth.
  10. Non-linux based devices are upgraded and configured unattended. Cumulus Linux devices are automatically upgraded on install but the final configuration has to be pushed using Ansible: we didn t want to duplicate the configuration process using another tool.

Shirish Agarwal: Pandemic, Toolkit and India

Pandemic Situation in India. I don t know from where I should start. This is probably a good start. I actually would recommend Indiacable as they do attempt to share some things happening in India from day to day but still there is a lot thatt they just can t cover, nobody can cover. There were two reports which kind of shook me all inside. One which sadly came from the UK publication Independent, probably as no Indian publication would dare publish it. The other from Rural India. I have been privileged in many ways, including friends who have asked me if I need any financial help. But seeing reports like above, these people need more help, guidance and help than I. While I m never one to say give to Foundations. If some people do want to help people from Maharashtra, then moneylifefoundation could be a good place where they could donate. FWIW, they usually use the foundation to help savers and investors be safe and help in getting money when taken by companies with dubious intentions. That is their drive. Two articles show their bent. The first one is about the Algo scam which I have written previously about the same in this blog. Interestingly, when I talk about this scam, all Modi supporters are silent. The other one does give some idea as to why the Govt. is indifferent. That is going to a heavy cross for all relatives to bear. There has been a lot that has been happening. Now instead of being limited to cities, Covid has now gone hinterland in a big way. One could ask also Praveen as he probably knows what would be good for Kerala and surrounding areas. The biggest change, however, has been that India is now battling not just the pandemic but also Mucormycosis also known as black fungus and its deadlier cousin the white fungus. Mucormycosis came largely due to an ill-advise given that applying cow dung gives protection to Corona. And many applied it due to faith. And people who know science do know that in fact it has that bacteria. Sadly, those of us who are and were more interested in law, computer science etc. has now also have to keep on top of what is happening in the medical field. It isn t that I hate it, but it has a lot of costs. From what I could gather on various social media and elsewhere, a single injection of anti-fungal for the above costs INR 3k/- and that needs to be 5 times in a day and that course has to be for three weeks. So even the relatively wealthy people can and will become poor in no time. No wonder thousands of those went to UK, US, Dubai or wherever they could find safe-harbor from the pandemic with no plans of arriving back soon. There was also the whole bit about FBS or Fetal Bovin Serum. India ordered millions of blood serum products from abroad and continues to. This was quickly shut down as news on Social Media. Apparently, it is only the Indian cow which is worthy of reverence. All other cows and their children are fair game according to those in power. Of course, that discussion was quickly shut down as was the discussion about IGP (Indian Genome Project). People over the years had asked me why India never participated for the HGP (Human Gnome Project). I actually had no answer for that. Then in 2020, there was idea of IGP which was put up and then it was quickly shot down as the results could damage a political party s image. In fact, a note to people who want to join Indian civil services tells the reason exactly. While many countries in the world are hypocrites, including the U.S. none can take the place that India has made for itself in that field.

The Online experience The vaccination process has been made online and has led to severe heartburn and trouble for many including many memes. For e.g.

Daily work, get up, have a bath, see if you got a slot on the app, sleep.
People trying desperately to get a slot, taken from Hindi Movie Dilwale Dulhania Le Jaygenge.
Just to explain what is happening, one has to go to the website of cowin. Sharing a screenshot of the same.
Cowin app. sceeenshot
I have deliberately taken a screenshot of the cowin app. in U.P. which is one of the areas where the ruling party, BJP has. I haven t taken my state for the simple reason, even if a slot is open, it is of no use as there are no vaccines. As have been shared in India Cable as well as in many newspapers, it is the Central Govt. which holds the strings for the vaccines. Maharashtra did put up an international tender but to no effect. All vaccine manufacturers want only Central Govt. for purchases for multiple reasons. And GOI is saying it has no money even though recently it got loans as well as a dividend from RBI to the tune of 99k crore. For what all that money is, we have no clue. Coming back though, to the issue at hand. the cowin app. is made an open api. While normally, people like us should and are happy when an API is open, it has made those who understand how to use git, compile, etc. better than others. A copy of the public repo. of how you can do the same can be found on Github. Now, obviously, for people like me and many others it has ethical issues.

Kiran s Interview in Times of India (TOI) There isn t much to say apart from I haven t used it. I just didn t want to. It just is unethical. Hopefully, in the coming days GOI does something better. That is the only thing we are surviving on, hope.

The Toolkit saga A few days before, GOI shared a toolkit apparently made by Congress to defame the party in power. That toolkit was shared before the press and Altnews did the investigation and promptly shredded the claims. Congress promptly made an FIR in Chhattisgarh where it is in power. The gentleman who made the claims Mr. Sambit Patra refused to appear against the police without evidence citing personal reasons and asking 1 week to appear before them. Apart from Altnews which did a great job, sadly many people didn t even know that there is something called WYSIWYG. I had to explain that so many Industries, whether it is politics, creative industries, legal, ad industries, medical transcription, and imaging all use this, and all the participants use the same version of the software. The reason being that in most Industries, there is a huge loss and issue of legal liabilities if something untoward happens. For e.g. if medical transcription is done in India is wrong (although his or her work will be checked by a superior in the West), but for whatever reason is not, and a wrong diagnosis is put (due to wrong color or something) then a patient could die and the firm who does that work could face heavy penalties which could be the death of them. There is another myth that Congress has unlimited wealth or huge wealth. I asked if that was the case, why didn t they shift to Mac. Of course, none have answers on this one. There is another reason why they didn t want to appear. The Rona Wilson investigation by Arsenal Experts also has made them cautious. Previously, they had a free run. Nowadays, software forensic tools are available to one and all. For e.g. Debian itself has a good variety of tools for the same. I remember Vipin s sharing few years back. For those who want to start, just install the apps. and try figuring out. Expertise on using the tools takes years though, as you use the tool day in night. Update 25/05/2021 Apparently because Twitter made and showcased few tweets as Manipulated Media , those in Govt. are and were dead against it. So they conducted a raid against Twitter India headquarters, knowing fully well that there would be nobody except security. The moment I read this, my mind went to the whole Fruit of the poisonous tree legal doctrine. Sadly though, India doesn t recognize it and in fact, still believes in the pre-colonial era that evidence however collected is good. A good explanation of the same can be found here. There are some exceptions to the rule, but they are done so fine that more often than not, they can t be used in the court of law in India. Although a good RTI was shared by Mr. Saket Gokhale on the same issue, which does raise some interesting points
Twitter India Raid, Saket Gokhale RTI 1
Saket Gokhale RTI query , Twitter India Raid 2
FWIW, Saket has been successful in getting his prayers heard either as answers to RTI queries or then following it up in the various High Courts of India. Of course, those who are in the ruling party ridicule him but are unable to find faults in his application of logic. And quite a few times, I have learned from his applications as well as nuances or whatever is there in law, a judgment or a guideline which he invokes in his prayer. For e.g. the Lalitha Kumari Guidelines which the gentleman has shared in his prayer can be found here. Hence now, it would be upto the Delhi Police Cell to prove their case in response to RTI. He has also trapped them as he has shared they can t give excuses/exemptions which they have tried before. As I had shared earlier, High Courts in India have woken up, whether it is Delhi, Mumbai, Aurangabad, Madhya Pradesh, Uttar Pradesh, Odisha or Kerala. Just today i.e. on 25th May 2021, Justices Bela Trivedi and Justice Kalra had asked how come all the hospitals don t have NOC from the Fire De[partment. They also questioned the ASG (Assistant Solicitor General) as how BU (Building Use Certificate) has been granted as almost all the 400 hospitals are in residential area. To which the ASG replies, it is the same state in almost 4000 schools as well as 6000 odd factories in Ahemdabad alone, leave the rest of the district and state alone. And this is when last year strict instuctions were passed. They chose to do nothing sadly. I will share a link on this when bar and bench gives me  The Hindu also shared the whole raid on twitter saga.

Conclusion In conclusion, I sincerely do not where we are headed. The only thing I know is that we cannot expect things to be better before year-end and maybe even after that. It all depends on the vaccines and their availability. After that ruralindia article, I had to see quite a few movies and whatnot just to get that out of my head. And this is apart from the 1600 odd teachers and workers who have died in the U.P. poll duty. Now, what a loss, not just to the family members of the victims, but a whole generation of school children who would not be able to get quality teaching and be deprived of education. What will be their future, God only knows. The only good Bollywood movie which I saw was Ramprasad ki Teravi . The movie was an accurate representation of most families in and around me. There was a movie called Sansar (1987) which showed the breakup of the joint family and into a nuclear family. This movie could very well have been a continuation of the same. Even Marathi movies which at one time were very progressive have gone back to the same boy, girl love story routine. Sameer, though released in late 2020, was able to see it only recently. Vakeel Saab was an ok copy of Pink . I loved Sameer as, unlike Salman Khan films, it showed pretty much an authentic human struggle of a person who goes to the Middle East without any qualifications and works as a laborer and the trials he goes through. Somehow, Malayalam movies have a knack for showing truth without much of budget. Most of the Indian web series didn t make an impact. I think many of them were just going through the motions, it seems as everybody is concerned with the well-being of their near and dear ones. There was also this (Trigger Warning: This story discusses organized campaigns glorifying and advocating sexual violence against Muslim women.) Hoping people somehow make it to the other side of the pandemic.

24 May 2021

Vincent Bernat: Transient prompt with Zsh

Powerlevel10k is a theme for Zsh. It contains some powerful features, is astoundingly fast, and easy to customize. I am quite amazed at the skills of its main author. Be sure to also have a look at Zsh for Humans, a complete Zsh configuration including this theme. One of the nice features of Powerlevel10k is transient prompts: past prompts are reduced to a more minimal configuration to save space by removing unneeded information.
Demonstration of a transient prompt with Zsh: past prompts use a more compact form
My implementation of a transient prompt with Zsh. Past prompts are compact and include the time of the command execution, the hostname, and the status of the previous command while the complete prompt contains more information like the current directory and the Git branch.
When it comes to configuring my shell, I still prefer writing and understanding each line going into it. Therefore, I am still building my Zsh configuration from scratch. Here is how I have integrated the above transient feature into my prompt. The first step is to configure the appearance of the prompt in its compact form. Let s assume we have a variable, $_vbe_prompt_compact set to 1 when we want a compact prompt. We use the following function to define the prompt appearance:
_vbe_prompt ()  
    local retval=$?
    # When compact, just time + prompt sign
    if (( $_vbe_prompt_compact )); then
        # Current time (with timezone for remote hosts)
        _vbe_prompt_segment cyan default "%D %H:%M$ SSH_TTY+ %Z  "
        # Hostname for remote hosts
        [[ $SSH_TTY ]] && \
            _vbe_prompt_segment black magenta "%B%M%b"
        # Status of the last command
        if (( $retval )); then
            _vbe_prompt_segment red default $ PRCH[reta] 
        else
            _vbe_prompt_segment green cyan $ PRCH[ok] 
        fi
        # End of prompt
        _vbe_prompt_end
        return
    fi
    # Regular prompt with many information
    # [ ]
 
setopt prompt_subst
PS1='$(_vbe_prompt) '

Update (2021.05) The following part has been rewritten to be more robust. The code is stolen from Powerlevel10k s issue #888. See the comments for more details.

Our next step is to redraw the prompt after accepting a command. We wrap Zsh line editor into a function:1
_vbe-zle-line-init()  
    [[ $CONTEXT == start ]]   return 0
    # Start regular line editor
    (( $+zle_bracketed_paste )) && print -r -n - $zle_bracketed_paste[1]
    zle .recursive-edit
    local -i ret=$?
    (( $+zle_bracketed_paste )) && print -r -n - $zle_bracketed_paste[2]
    # If we received EOT, we exit the shell
    if [[ $ret == 0 && $KEYS == $'\4' ]]; then
        _vbe_prompt_compact=1
        zle .reset-prompt
        exit
    fi
    # Line edition is over. Shorten the current prompt.
    _vbe_prompt_compact=1
    zle .reset-prompt
    unset _vbe_prompt_compact
    if (( ret )); then
        # Ctrl-C
        zle .send-break
    else
        # Enter
        zle .accept-line
    fi
    return ret
 
zle -N zle-line-init _vbe-zle-line-init
That s all!
One downside of using the powerline fonts is that it messes with copy/paste. As I am using tmux, I use the following snippet to work around this issue and use only standard Unicode characters when copying from the terminal:
bind-key -T copy-mode M-w \
  send -X copy-pipe-and-cancel "sed 's/ .* /%/g'   xclip -i -selection clipboard" \;\
  display-message "Selection saved to clipboard!"
Copying and pasting the text from the screenshot above yields the following text:
14:21 % ssh eizo.luffy.cx
Linux eizo 4.19.0-16-amd64 #1 SMP Debian 4.19.181-1 (2021-03-19) x86_64
Last login: Fri Apr 23 14:20:39 2021 from 2a01:cb00:3f:b02:9db6:efa4:d85:7f9f
14:21 CEST % uname -a
Linux eizo 4.19.0-16-amd64 #1 SMP Debian 4.19.181-1 (2021-03-19) x86_64 GNU/Linux
14:21 CEST %
Connection to eizo.luffy.cx closed.
14:22 % git status
On branch article/zsh-transient
Untracked files:
  (use "git add <file>..." to include in what will be committed)
        ../../media/images/zsh-compact-prompt@2x.jpg
nothing added to commit but untracked files present (use "git add" to track)

  1. We have to manually enable bracketed paste because Zsh does it after zle-line-init.

22 May 2021

Ritesh Raj Sarraf: Setting Up a Secure Webapp

As a person who prefers full access to data in the simplest format, while at the same time having it useful with latest technologies, my quest for trying things out is an ongoing activity. Earlier, I blogged about my needs of collating news feeds in a simple format, readily accessible offline, while still being useful and aligned with the modern paradigm. In today s age, the other common aspect of our life, is digitization of moments. With the advent of great technology and affordable economics, the world now has access to great devices to capture moments in digital form. Most people, these days, are equipped with smart devices, like mobile phones, that come with pretty good image capturing devices. Our lives, our societies, how we interact; a lot of it is now built around the assumption of smart devices and digital services. A lot of good things have happened of it. We are now able to send messages to people, securely, in a matter of seconds. We are now able to capture moments, which otherwise we d often miss; all thanks to devices like smart mobile phones that most of all carry almost all along with us. In this regard, we are quite indebted to the technology revolution that has improved life styles all over. Of course, like every coin has a flip side, thus too, too much of obsession with digital life, also has its drawbacks. A simple reminder to self should always be about what a human life is designed for and try to live by its rules.
Moments Given the tools general availability, we are all more used to capturing moments. Once upon a time, taking a photo meant going to a photo studio. Then came a generation where we d have personal devices with roll films, to which we captured the moments. And then get it processed from a photo developing service provider. And that is when we d know which all moments came out correct and which ones were spoilt. In such cases, there s always the wish I could have that moment again. Thankfully, now, in our current generation, we have the liberty to take pictures and validate them almost immediately. We also have the flexibility to take multiple shots of the moment and do the filtering later. There s also many intelligent and invasive services, all mostly provided free, to help you organize these moments; at a small cost of keeping an eye on your life activity. In a summary, mankind, now, generates lots and lots of data. So much lot that now even mammoths like Google are forced to make a call whether it is more profitable to sniff user activity while providing them a service for free, or ask people to pay otherwise too.

Privacy Many of us are wary of the amount of personal data we generate, which is our asset; and how the big tech giants want a piece of it in the name of free services. And in such quest, free aside, there s always a lookout for privacy savvy tools that can help us draw a bold line in between Public and Private

Google Photos Google Photos has been a great tool. The way it organizes, siphons and present your data is simply amazing. No good would have been the photos taken, if they weren t easily searchable, organized, annotated, and presented. But Google Photos is proprietary and invasive. The amount of information they have access to should be a concern to all people. For services that invade so much, the world needs Free Services.

PhotoPrism I only came across this project around a month ago, while the project has been around since 2019. So far, in my exploration, this is one of the best Free Software tools to manage and organize my digital photos. The other favorite tool that I regularly depend on is Digikam and it still is a gem. In a gist, PhotoPrism aims to be the equivalent of Google Photos, for the privacy savvy people. As of date, it has a decent list of features available. And for some of the missing ones, I ve come up with a fairly okay workflow with other tools, which is one of the reasons of this blog post. PhotoPrism is a web app, written in the Go Programming Language. Its layout and workflow as a Photo Management application is similar to Google Photos. It is very performant compared to other applications. Since it is a Progressive Web App, access through a Laptop, Tablet or Mobile is almost the same. It uses Google TensorFlow for some of its features and thus you feel like using Google Photos in some regard. Some shortcomings and workarounds
  • Facial Recognition: To date, facial recognition is a planned feature. But this was easy to tackle given that Digikam has pretty solid facial recognition. So I use Digikam to detect, recognize and annotate faces. And then PhotoPrism is happy enough to use those annotations and present relevant data.
  • HTTP Web App: The upstream project has done a good job of making use of Docker container technology in presenting this web app solution. A software solution, the equivalent of a Google Photos, does need a heavyweight config. In free software, it is all about reusing available tools. PhotoPrism makes use of tools like MySQL, Vue.js, TensorFlow, GoLang, GoLibs and strives to provide a single package solution, all thanks to Docker containers.
In its current offering, PhotoPrism is run as a HTTP Web App. I wanted to have an added layer of security on top of it. And thus run an nginx reverse proxy on top of it. Along with it, I run the proxy service on HTTPS, thus making all traffic from clients to the proxy encrypted. I also wanted an added layer of HTTP AUTH on top, so I explored some options and finally settled down with http-auth-digest Also, in the current implementation, PhotoPrism doesn t have a strong notion of normal and private photos in its data organization. I wanted normal photos available under a standard auth realm and private photos under a different realm. And along with a different realm, I also wanted some added security directives for it. So far, it looks like I ve put together a decent solution with the help of nginx.
  • First of all, since the port from the host is forwarded to the docker instance, that needed to be controlled. Instead of the default of listening on all interfaces, I changed it to loopback only. Because my primary and only interface is going to be the nginx reverse proxy
  • Setup nginx with a self-signed certificate to have all communication encrypted.
  • Setup nginx as a reverse proxy to talk to PhotoPrism.
    server  
       listen 80;
       listen [::]:80;
       server_name lenovo;
       return 302 https://$host$request_uri;
       rewrite ^ https://$http_host$request_uri? permanent;    # force redirect http to https
        server_tokens off;
     
    server  
    listen 443 ssl http2 default_server;
    listen [::]:443 ssl http2 default_server;
    ssl_certificate_key /etc/ssl/private/ssl-cert-snakeoil.key;
    ssl_certificate /etc/ssl/certs/ssl-cert-snakeoil.pem;
    server_tokens off;
    server_name lenovo;
    client_max_body_size 500M;
        auth_digest_expires 900s;
        auth_digest_evasion_time 5s;
        auth_digest_replays 500;
    location /private  
        auth_digest 'abc';
        auth_digest_user_file /etc/nginx/htdigest;
        auth_digest_expires 900s;
        auth_digest_evasion_time 5s;
        auth_digest_replays 500;
        proxy_pass http://localhost:2342/private;
     
    location /discover  
        auth_digest 'abc';
        auth_digest_user_file /etc/nginx/htdigest;
        auth_digest_expires 900s;
        auth_digest_evasion_time 5s;
        auth_digest_replays 500;
        proxy_pass http://localhost:2342/discover;
     
    location /  
        proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
        proxy_set_header Host $host;
        proxy_buffering off;
        proxy_http_version 1.1;
        proxy_set_header Upgrade $http_upgrade;
        proxy_set_header Connection "upgrade";
        proxy_pass http://localhost:2342;
          
        auth_basic "Priv";
        auth_basic_user_file /etc/nginx/htpasswd;


  • nginx packaging: I was so happy to see the simplicity of the nginx packaging in Debian. Becuase http-auth-digest is not upstream, it needs to be pulled in separately and compiled. I was happy to see how simple the packaging structure of nginx in Debian is. It was just a matter of putting in the module in the right modules location, which as structured such in the packaging falls under the debian/ packaging sub-folder, that any future upgrades will be quite easy to manage.
  • http-auth-digest: I d love to see http-auth-digest module be part of the upstream package. While I m a web n00b, I felt this module perfect for my use case. From what I ve understood, set up and tested so far, this module fills in all my requirements; which is more of like a session management.
With the combined setup in place, https://host is authenticated with a different set of credentials. On the other hand, https://host/discover and /private get covered with a different set of credentials and policies. While, this will continue to be an ongoing effort and audit of the services that I build, so far now, I feel this is in decent shape that I can use it as my daily driver. The end result is:
nginx auth prompt
nginx auth prompt
PhotoPrism Photo List
PhotoPrism Menu
PhotoPrism Menu

Updates
  • Things can really get frustrating at times. These days, it is Google that contributes to it. https://bugs.chromium.org/p/chromium/issues/detail?id=544244
    • It is is now fair to say that Google is big enough to rewrite all the standards. Or at least break them. Or best, their arrogance of it. This bug report is a fine example of what other ways it could have been dealt.

20 May 2021

Jonathan McDowell: Losing control to Kubernetes

GMK NucBox Kubernetes is about giving up control. As someone who likes to understand what s going on that s made it hard for me to embrace it. I ve also mostly been able to ignore it, which has helped. However I m aware it s incredibly popular, and there s some infrastructure at work that uses it. While it s not my responsibility I always find having an actual implementation of something is useful in understanding it generally, so I decided it was time to dig in and learn something new. First up, I should say I understand the trade-off here about handing a bunch of decisions off to Kubernetes about the underlying platform allowing development/deployment to concentrate on a nice consistent environment. I get the analogy with the shipping container model where you can abstract out both sides knowing all you have to do is conform to the TEU API. In terms of the underlying concepts I ve got some virtualisation and container experience, so I m not coming at this as a complete newcomer. And I understand multi-site dynamically routed networks. That said, let s start with a basic goal. I d like to understand k8s (see, I can be cool and use the short name) enough to be comfortable with what s going on under the hood and be able to examine a running instance safely (i.e. enough confidence about pulling logs, probing state etc without fearing I might modify state). That ll mean when I come across such infrastructure I have enough tools to be able to hopefully learn from it. To do this I figure I ll need to build myself a cluster and deploy some things on it, then poke it. I ll start by doing so on bare metal; that removes variables around cloud providers and virtualisation and gives me an environment I know is isolated from everything else. I happen to have a GMK NucBox available, so I ll use that. As a first step I m aiming to get a single node cluster deployed running some sort of web accessible service that is visible from the rest of my network. That should mean I ve covered the basics of a Kubernetes install, a running service and actually making it accessible. Of course I m running Debian. I ve got a Bullseye (Debian 11) install - not yet released as stable, but in freeze and therefore not a moving target. I wanted to use packages from Debian as much as possible but it seems that the bits of Kubernetes available in main are mostly just building blocks and not a great starting point for someone new to Kubernetes. So to do the initial install I did the following:
# Install docker + nftables from Debian
apt install docker.io nftables
# Add the Kubernetes repo and signing key
curl -s https://packages.cloud.google.com/apt/doc/apt-key.gpg > /etc/apt/k8s.gpg
cat > /etc/apt/sources.list.d/kubernetes.list <<EOF
deb [signed-by=/etc/apt/k8s.gpg] https://apt.kubernetes.io/ kubernetes-xenial main
EOF
apt update
apt install kubelet kubeadm kubectl
That resulted in a 1.21.1-00 install, which is current at the time of writing. I then used kubeadm to create the cluster:
kubeadm init --apiserver-advertise-address 192.168.53.147 --apiserver-cert-extra-sans udon.mynetwork
The extra parameters were to make the API server externally accessible from the host. I don t know if that was a good idea or not at this stage kubeadm spat out a bunch of instructions but the key piece was about copying the credentials to my user account. So I did:
mkdir ~noodles/.kube
cp -i /etc/kubernetes/admin.conf ~noodles/.kube/config
chown -R noodles ~noodles/.kube/
I then was able to see my pod:
noodles@udon:~$ kubectl get nodes
NAME   STATUS     ROLES                  AGE     VERSION
udon   NotReady   control-plane,master   4m31s   v1.21.1
Ooooh. But why s it NotReady? Seems like it s a networking issue and I need to install a networking provider. The documentation on this is appalling. Flannel gets recommended as a simple option but then turns out to need a --pod-network-cidr option passed to kubeadm and I didn t feel like cleaning up and running again (I ve omitted all the false starts it took me to get to this point). Another pointer was to Weave so I decided to try that with the following magic runes:
mkdir -p /var/lib/weave
head -c 16 /dev/urandom   shasum -a 256   cut -d " " -f1 > /var/lib/weave/weave-passwd
kubectl create secret -n kube-system generic weave-passwd --from-file=/var/lib/weave/weave-passwd
kubectl apply -f "https://cloud.weave.works/k8s/net?k8s-version=$(kubectl version   base64   tr -d '\n')&password-secret=weave-passwd&env.IPALLOC_RANGE=192.168.0.0/24"
(I believe what that s doing is the first 3 lines create a password and store it into the internal Kubernetes config so the weave pod can retrieve it. The final line then grabs a YAML config from Weaveworks to configure up weave. My intention is to delve deeper into what s going on here later; for now the primary purpose is to get up and running.) As I m running a single node cluster I then had to untaint my control node so I could use it as a worker node too:
kubectl taint nodes --all node-role.kubernetes.io/master-
And then:
noodles@udon:~$ kubectl get nodes
NAME   STATUS   ROLES                  AGE   VERSION
udon   Ready    control-plane,master   15m   v1.21.1
Result. What s actually running? Nothing except the actual system stuff, so we need to ask for all namespaces:
noodles@udon:~$ kubectl get pods --all-namespaces
NAMESPACE     NAME                           READY   STATUS    RESTARTS   AGE
kube-system   coredns-558bd4d5db-4nvrg       1/1     Running   0          18m
kube-system   coredns-558bd4d5db-flrfq       1/1     Running   0          18m
kube-system   etcd-udon                      1/1     Running   0          18m
kube-system   kube-apiserver-udon            1/1     Running   0          18m
kube-system   kube-controller-manager-udon   1/1     Running   0          18m
kube-system   kube-proxy-6d8kg               1/1     Running   0          18m
kube-system   kube-scheduler-udon            1/1     Running   0          18m
kube-system   weave-net-mchmg                2/2     Running   1          3m26s
These are all things I m going to have to learn about, but for now I ll nod and smile and pretend I understand. Now I want to actually deploy something to the cluster. I ended up with a simple HTTP echoserver (though it s not entirely clear that s actually the source for what I ended up pulling):
$ kubectl create deployment hello-node --image=k8s.gcr.io/echoserver:1.10
deployment.apps/hello-node created
$ kubectl get pod
NAME                          READY   STATUS    RESTARTS   AGE
hello-node-59bffcc9fd-8hkgb   1/1     Running   0          36s
$ kubectl expose deployment hello-node --type=NodePort --port=8080
$ kubectl get services
NAME         TYPE        CLUSTER-IP      EXTERNAL-IP   PORT(S)          AGE
hello-node   NodePort    10.107.66.138   <none>        8080:31529/TCP   1m
Looks good. And to test locally:
curl http://10.107.66.138:8080/

Hostname: hello-node-59bffcc9fd-8hkgb
Pod Information:
	-no pod information available-
Server values:
	server_version=nginx: 1.13.3 - lua: 10008
Request Information:
	client_address=192.168.53.147
	method=GET
	real path=/
	query=
	request_version=1.1
	request_scheme=http
	request_uri=http://10.107.66.138:8080/
Request Headers:
	accept=*/*
	host=10.107.66.138:8080
	user-agent=curl/7.74.0
Request Body:
	-no body in request-
Neat. But my external network is 192.168.53.0/24 and that s a 10.* address so how do I actually make it visible to other hosts? What I seem to need is an Ingress Controller which provide some sort of proxy between the outside world and pods within the cluster. Let s pick nginx because at least I have some vague familiarity with that and it seems like it should be able to do a bunch of HTTP redirection to different pods depending on the incoming request.
kubectl apply -f https://raw.githubusercontent.com/kubernetes/ingress-nginx/controller-v0.46.0/deploy/static/provider/cloud/deploy.yaml
I then want to expose the hello-node to the outside world and I finally had to write some YAML:
cat > hello-ingress.yaml <<EOF
apiVersion: networking.k8s.io/v1
kind: Ingress
metadata:
  name: example-ingress
  annotations:
    nginx.ingress.kubernetes.io/rewrite-target: /$1
spec:
  rules:
    - host: udon.mynetwork
      http:
        paths:
          - path: /
            pathType: Prefix
            backend:
              service:
                name: hello-node
                port:
                  number: 8080
EOF
i.e. incoming requests to http://udon.mynetwork/ should go to the hello-node on port 8080. I applied this:
$ kubectl apply -f hello-ingress.yaml
ingress.networking.k8s.io/example-ingress created
$ kubectl get ingress
NAME              CLASS    HOSTS            ADDRESS   PORTS   AGE
example-ingress   <none>   udon.mynetwork             80      3m8s
No address? What have I missed? Let s check the nginx service, which apparently lives in the ingress-nginx namespace:
noodles@udon:~$ kubectl get services -n ingress-nginx
NAME                                 TYPE           CLUSTER-IP      EXTERNAL-IP   PORT(S)                    AGE
ingress-nginx-controller             LoadBalancer   10.96.9.41      <pending>     80:32740/TCP,443:30894/TCP 13h
ingress-nginx-controller-admission   ClusterIP      10.111.16.129   <none>        443/TCP                    13h
<pending> does not seem like something I want. Digging around it seems I need to configure the external IP. So I do:
kubectl patch svc ingress-nginx-controller -n ingress-nginx -p \
	' "spec":  "type": "LoadBalancer", "externalIPs":["192.168.53.147"] '
and things look happier:
noodles@udon:~$ kubectl get services -n ingress-nginx
NAME                                 TYPE           CLUSTER-IP      EXTERNAL-IP      PORT(S)                 AGE
ingress-nginx-controller             LoadBalancer   10.96.9.41      192.168.53.147   80:32740/TCP,443:30894/TCP   14h
ingress-nginx-controller-admission   ClusterIP      10.111.16.129   <none>           443/TCP                 14h
noodles@udon:~$ kubectl get ingress
NAME              CLASS    HOSTS           ADDRESS          PORTS   AGE
example-ingress   <none>   udon.mynetwork  192.168.53.147   80      14h
Let s try a curl from a remote host:
curl http://udon.mynetwork/

Hostname: hello-node-59bffcc9fd-8hkgb
Pod Information:
	-no pod information available-
Server values:
	server_version=nginx: 1.13.3 - lua: 10008
Request Information:
	client_address=192.168.0.5
	method=GET
	real path=/
	query=
	request_version=1.1
	request_scheme=http
	request_uri=http://udon.mynetwork:8080/
Request Headers:
	accept=*/*
	host=udon.mynetwork
	user-agent=curl/7.64.0
	x-forwarded-for=192.168.53.136
	x-forwarded-host=udon.mynetwork
	x-forwarded-port=80
	x-forwarded-proto=http
	x-real-ip=192.168.53.136
	x-request-id=6aaef8feaaa4c7d07c60b2d05c45f75c
	x-scheme=http
Request Body:
	-no body in request-
Ok, so that seems like success. I ve got a single node cluster running a single actual application pod (the echoserver) and exporting it to the outside world. That s enough to start poking under the hood. Which is for another post, as this one is already getting longer than I d like. I ll just leave some final thoughts of things I need to work out:

Next.

Previous.