Search Results: "spa"

23 June 2024

Sahil Dhiman: How I Write Blogs - June 2024 Edition

I wrote about my blog writing methodology back April 2021. My writing method has undergone a significant shift now, so thought about writing this update. New blog topics are added to my note-taking app quite frequently now. Occasionally going through the list, I merge topics, change order to prioritize certain topics or purely drop ideas which seems not worth a write-up. Due to this, I have the liberty to work on blogs according to mood. Writing the last one was tiring, so I chose to work on an easy one, i.e. this blog now. Topic decided, everything starts on etherpad now. Etherpad has this nice font and sync feature, which helps me write from any device of choice. Actual writing usually happens in the morning, right after I wake up. For most topics, I quickly jot down pointers and keep on expanding them over the course of multiple days at a leisurely pace. Though, sometime it adds too many pieces in the puzzle and takes additional time to put everything in flow. New pointer addition keeps on happening along with writing. Nowadays, pictures too dot my blog, which I rarely use to do earlier. I have come to believe on less usage of external links. These breaks the flow of readers. If someone is sufficiently motivated to learn more about something, finding useful sources isn t. As the first draft comes into being, I run it through LanguageTool for spelling corrections (which typically are many) and fixing grammatical issues. Post that, for the first time I read the complete write-up in one go for formation of coherent storyline, moving paragraphs around for form a structure , adding explainers wherever something new or unexplained is introduced, removing elaborate sentences, making amends wherever required and moving paragraphs around for forming structure. Another round of LanguageTool follows. All set now, I try to space out my final read before publishing, which helps find additional mistakes or loopholes. When everything is set, I do hugo to generate the site and rsync everything to the web server. A final git sync closes the publication part. After a day or two, I come back to read the blog on the website. This entails another round finding and fixing trivial mistakes. After this, it s set for good. Nowadays, in addition to being on my blog, everything is syndicated on Planet FSCI and Planet Debian, which has given it more visibility. As someone who s into infrastructure and Internet as a lot, I do pay attention to logs on my server, but as a disconnected exercise to if the blog is being read or not. More hits on the blog doesn t translate to any gratification for me, at least for writers point of view. Occasionally, people do mention my blog, which does flatter me. Four years and nearly a hundred posts later, I still wonder how I kept on writing for this long.

22 June 2024

Russ Allbery: Review: And the Stars Will Sing

Review: And the Stars Will Sing, by Michelle Browne
Series: The Meaning Wars #1
Publisher: Michelle Browne
Copyright: 2012, 2021
Printing: 2021
ASIN: B0075G7GEA
Format: Kindle
Pages: 85
And the Stars Will Sing is a self-published science fiction novella, the first of a (currently) five book series. I believe it may be Browne's first publication, although I don't have a good data source to confirm. Crystal Weiss is a new graduate from Mars, about to leave the solar system to her first job assignment: installation of a permanent wormhole in the vicinity of Messier 14. Her expertise is the placement calculations. The heavy mathematical lifting is of course done by computers, but humans have to do the mapping and some of the guidance. And the Stars Will Sing is an epistolary novel, told in the form of her letters to her friend Sarah. I feel bad when I stumble across a book like this. I want to stick with my habit of writing a review of each book I read, but it's one thing to pan a bad book by a famous author and another thing to pick on a self-published novella that I read due to some recommendation or mention whose details I've forgotten. Worse, I think this wasn't even the recommended book; I looked up the author, saw that the first of a series was on sale, and thought "oh, hey, I like epistolary novels and I'm in the mood for some queer space opera." This book didn't seem that queer (there is a secondary lesbian relationship but the main relationship seemed rather conventional), but I'll get to the romance in a moment. I was not the reader for this book. There's a reason why most of the books I read are from traditional publishers; I'm too critical of a reader for a lot of early self-published work. It's not that I dislike self-publishing as a concept many self-published books are excellent and the large publishers have numerous problems but publishers enforce a quality bar. Inconsistently, unfairly, and by rejecting a lot of good work, but still, they do. I'm fairly sure traditional publishers would have passed on this book; the quality of the writing isn't there yet. (It's certainly a better book than I could have written! But that's why I'm writing my reviews over in my quiet corner of the Internet and not selling fiction to other people.) The early chapters aren't too bad, although they have a choppy, cliched style that more writing experience usually smoothes out. The later chapters have more dialogue, enough that I started wondering how Crystal could remember that much dialogue verbatim to put into a letter, and it's not good. All of the characters talk roughly the same (even the aliens), the dialogue felt even more cliched than the rest of the writing, and I started getting distracted by the speech tags. Crystal comes across as very young, impulsive, and a drama magnet who likes being all up in her coworkers' business. None of these are objective flaws in the book, but I could tell early on that I was going to find her annoying. She has a heavily-foreshadowed enemies-to-lovers thing with one of her male coworkers. Her constant complaining about him at the start of the story was bad enough, but the real problem is that in the very few places where he has more personality than plastic lawn furniture, he's being obnoxious to Crystal. I'm used to being puzzled by a protagonist's choice in love interests, but this one felt less like an odd personality choice and more a lack of writing skill. Even if the relationship is being set up for failure (not true by the end of this book), you've got to help me understand what the protagonist saw in him or was getting out of the relationship. The plot was so predictable that it ironically surprised me. I was sure that some sort of twist or complication was coming, but no. I will give Browne some credit for writing a slightly more realistic character reaction to violence than most SF authors, but there was nothing in the plot to hold my interest. The world-building was generic science fiction with aliens. It had a few glimmers of promise, but there was some sort of psychic hand-waving involved in siting wormholes that didn't work for me and the plot climax made no sense to me whatsoever. This is the kind of bad book that I don't want to hold against the writer. Twelve years later and with numerous other novels and novellas under her belt, her writing is probably much better. I do think this book would have benefited from an editor telling her it wasn't good enough for publication yet, but that's not how the Kindle self-publishing world works. Mostly, this is my fault: I half-followed a recommendation into an area of publishing that I know from past experience I should avoid without a solid review from an equally critical reader. Followed by The Stolen, a two-story collection. Rating: 3 out of 10

20 June 2024

Daniel Lange: Fixing esptool read_flash above 2MB on some cheap ESP32 boards

esptool, the Espressif SoC serial bootloader utility, tends to dislike cheap Flash chips attached to the various incarnations of the ESP32 chip family. And it seems to dislike them even more when running esptool on Linux than on other OSs. The common error mode is seeing it break at the 2MB barrier when trying to dump (esptool read_flash) a 4MB flash configuration.
esptool -p /dev/ttyUSB0 -b 921600 read_flash 0 0x400000 flash_dump.bin
will fail with
esptool.py v4.7.0
Serial port /dev/ttyUSB0
Connecting....
Detecting chip type... ESP32
Chip is ESP32-D0WD-V3 (revision v3.1)
Features: WiFi, BT, Dual Core, 240MHz, VRef calibration in efuse, Coding Scheme None
Crystal is 40MHz
[..]
Detected flash size: 4MB
[..]
2097152 (50 %)
A fatal error occurred: Failed to read flash block (result was 01090000: CRC or checksum was invalid)
typically at the 2MB barrier. I found the solution in a rather unrelated esptool Github issue: Create an esptool.cfg file in the project directory (from where you will run esptool):
[esptool]
timeout = 30
max_timeout = 240
erase_write_timeout_per_mb = 40
mem_end_rom_timeout = 0.2
serial_write_timeout = 10
The timeout = 30 is the setting that fixed reading flash memory via esptool read_flash for me. When your esptool.cfg is read, esptool will tell you so in its second line of output:
$ esptool flash_id
esptool.py v4.7.0
Loaded custom configuration from /home/dl/[..]/Embedded_dev/ESP-32_Wemos/esptool.cfg
Found 1 serial ports
Serial port /dev/ttyUSB0
Connecting......
[..]
Animated GIF of an ESP32 board Thank you Radim Karnis and wibbit from the Github issue linked above.

19 June 2024

Dirk Eddelbuettel: nanotime 0.3.8 on CRAN: More Maintenance

Leonardo and I are happy to annunce that a new version 0.3.8 of our nanotime package arrived on CRAN today. It is the first release in over 1 1/2 years. nanotime relies on the RcppCCTZ package (as well as the RcppDate package for additional C++ operations) and offers efficient high(er) resolution time parsing and formatting up to nanosecond resolution, using the bit64 package for the actual integer64 arithmetic. Initially implemented using the S3 system, it has benefitted greatly from a rigorous refactoring by Leonardo who not only rejigged nanotime internals in S4 but also added new S4 types for periods, intervals and durations. This release responds to a number of enhancements including a new paramter accurate for POSIXct to nanotime conversions, a vector date converter, a switch to double return value when durations objects are dividded as well as a small battery of CRAN requests for changes and updates. This started with a move away from the now non-API function SET_S4_OBJECT which has been replaced by use of Rf_asS4. We also no longer need a custom compiler flag on Windows (where for some reasons nobody understands or remembers, bitfields are not packed) to small enhancements of manual page formatting and last-but-not-least avoidance of some new UBSAN warnings. The NEWS snippet has the full details.

Changes in version 0.3.8 (2024-06-19)
  • Time format documentation now has a reference to RcppCCTZ
  • The package no longer sets a default C++ compilation standard of C++11 (Dirk initially in #114, and later switched to C++17)
  • New accurate parameter for conversion from POSIXct to nanotime (Davor Josipovic and Leonardo in #116 closing #115)
  • The as.Date() function is now vectorized and can take a TZ argument (Leonardo and Dirk in #119 closing #118)
  • Use of internal function SET_S4_OBJECT has been replaced by API function Rf_asS4 (Leonardo in #121 closing #120)
  • An nanoduration / nanoduration expression now returns a double (Leonardo in #122 closing #117)
  • Bitfield calculations no longer require an Windows-only compiler switch (Leonardo in #124)
  • A simple manual page format nag involving has been addressed (Dirk in #126 fixing #125)
  • An set of tests tickling an UBSAN issue via Rcpp code no longer run unless CI is set (Dirk in #127 fixing #123)

Thanks to my CRANberries, there is a diffstat report for this release. More details and examples are at the nanotime page; code, issue tickets etc at the GitHub repository and all documentation is provided at the nanotime documentation site. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 June 2024

Matthew Garrett: SSH agent extensions as an arbitrary RPC mechanism

A while back, I wrote about using the SSH agent protocol to satisfy WebAuthn requests. The main problem with this approach is that it required starting the SSH agent with a special argument and also involved being a little too friendly with the implementation - things worked because I could provide an arbitrary public key and the implementation never validated that, but it would be legitimate for it to start doing so and then break everything. And it also only worked for keys stored on tokens that ssh supports - there was no way to extend this to other keystores on the client (such as the Secure Enclave on Macs, or TPM-backed keys on PCs). I wanted a better solution.

It turns out that it was far easier than I expected. The ssh agent protocol is documented here, and the interesting part is the extension support extension mechanism. Basically, you can declare an extension and then just tunnel whatever you want over it. As before, my goto was the go ssh agent package which conveniently implements both the client and server side of this. Implementing the local agent is trivial - look up SSH_AUTH_SOCK, connect to it, create a new agent client that can communicate with that by calling NewClient, and then implement the ExtendedAgent interface, create a new socket, and call ServeAgent against that. Most of the ExtendedAgent functions should simply call through to the original agent, with the exception of Extension(). Just add a case statement against extensionType, define some reasonably namespaced extension, and you're done.

Now you need to use this agent. You probably don't want to use this for arbitrary hosts (agent forwarding should only be enabled for remote systems you trust, not arbitrary machines you connect to - if you enabled agent forwarding for github and github got compromised, github would be able to use any private keys loaded into your agent, and you probably don't want that). So the right approach is to add a Host entry to the ssh config with a ForwardAgent stanza pointing at the socket you created in your new agent. This way the configured subset of remote hosts will automatically talk to this new custom agent, while forwarding for anything else will still be at the user's discretion.

For the remote end things are even easier. Look up SSH_AUTH_SOCK and call NewClient as before, and then simply call client.Extension(). Whatever you stick in the contents argument will simply end up being received at the client end. You now have a communication channel between a the remote system and the local client, and what you do with that is up to you. I'm using it to allow a remote system to obtain auth tokens from Okta and forward WebAuthn challenges that can either be satisfied via a local WebAuthn token or by passing the query off to Mac TouchID, but there's fundamentally no constraints whatsoever on what can be done here.

(If you want to do this on Windows and still have everything work with existing clients you'll need to take this into account - Windows didn't really do Unix sockets until recently so everything there is awful)

comment count unavailable comments

Freexian Collaborators: Monthly report about Debian Long Term Support, May 2024 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In May, 17 contributors have been paid to work on Debian LTS, their reports are available:
  • Adrian Bunk did 34.25h (out of 24.0h assigned and 22.0h from previous period), thus carrying over 11.75h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 16.0h (out of 24.0h assigned), thus carrying over 8.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Daniel Leidert did 8.0h (out of 10.0h assigned), thus carrying over 2.0h to the next month.
  • Emilio Pozuelo Monfort did 35.5h (out of 46.0h assigned), thus carrying over 10.5h to the next month.
  • Guilhem Moulin did 13.0h (out of 14.75h assigned and 5.25h from previous period), thus carrying over 7.0h to the next month.
  • Lee Garrett did 11.0h (out of 37.25h assigned and 8.75h from previous period), thus carrying over 35.0h to the next month.
  • Lucas Kanashiro did 10.0h (out of 20.0h assigned), thus carrying over 10.0h to the next month.
  • Markus Koschany did 40.0h (out of 40.0h assigned).
  • Ola Lundqvist did 6.5h (out of 22.5h assigned and 1.5h from previous period), thus carrying over 17.5h to the next month.
  • Roberto C. S nchez did 7.75h (out of 11.0h assigned and 1.0h from previous period), thus carrying over 4.25h to the next month.
  • Santiago Ruano Rinc n did 8.0h (out of 16.0h assigned), thus carrying over 8.0h to the next month.
  • Sean Whitton did 5.5h (out of 5.5h assigned and 0.5h from previous period), thus carrying over 0.5h to the next month.
  • Sylvain Beucler did 10.5h (out of 0.75h assigned and 45.25h from previous period), thus carrying over 35.5h to the next month.
  • Thorsten Alteholz did 14.0h (out of 14.0h assigned).
  • Tobias Frost did 7.75h (out of 10.0h assigned and 2.0h from previous period), thus carrying over 4.25h to the next month.

Evolution of the situation In May, we have released 20 DLAs. Notable security updates in May included:
  • apache2: multiple vulnerabilities which may result in HTTP response splitting, denial of service, or authorization bypass (by Bastien Roucari s, in collaboration with apache2 maintainer Yadd)
  • bind9: two vulnerabilities, called KeyTrap and NSEC3, which may result in denial of service (by Santiago Ruano Rinc n)
  • python-pymysql: potential SQL injection attack (by Chris Lamb)
The aforementioned apache2 was prepared by its Debian maintainer Yadd. This update also involved work on the package test suite in buster, which contributor Bastien Roucari s then forwarded to the apache2 package in unstable. More importantly, a regression in fossil was reported, and Bastien prepared a fix for it. Bastien coordinated the upload of both packages to minimize the introduction of regressions. Contributor Daniel Leidert also prepared an upload of runc to Debian 11 in order fix a number of CVEs still affecting that package. Finally, contributor Thorsten Alteholz prepared uploads for qtbase-opensource-src, libjwt, and libmicrohttpd in Debian 11. Note that Debian 11 will pass into the LTS phase of support in August and these updates will improve the state and long-term supportability of Debian 11. Debian 10 is presently in its final month of LTS support (as announced on the debian-lts-announce mailing list, support will end on June 30th), after which no new security updates will be made available on security.debian.org. However, Freexian and its team of paid Debian contributors will continue to maintain Debian 10 going forward for the customers of the Extended LTS offer. Subscribe right away if you sill have Debian 10 which must be kept secure (and which cannot yet be upgraded).

Thanks to our sponsors Sponsors that joined recently are in bold.

8 June 2024

Reproducible Builds: Reproducible Builds in May 2024

Welcome to the May 2024 report from the Reproducible Builds project! In these reports, we try to outline what we have been up to over the past month and highlight news items in software supply-chain security more broadly. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. Table of contents:
  1. A peek into build provenance for Homebrew
  2. Distribution news
  3. Mailing list news
  4. Miscellaneous news
  5. Two new academic papers
  6. diffoscope
  7. Website updates
  8. Upstream patches
  9. Reproducibility testing framework


A peek into build provenance for Homebrew Joe Sweeney and William Woodruff on the Trail of Bits blog wrote an extensive post about build provenance for Homebrew, the third-party package manager for MacOS. Their post details how each bottle (i.e. each release):
[ ] built by Homebrew will come with a cryptographically verifiable statement binding the bottle s content to the specific workflow and other build-time metadata that produced it. [ ] In effect, this injects greater transparency into the Homebrew build process, and diminishes the threat posed by a compromised or malicious insider by making it impossible to trick ordinary users into installing non-CI-built bottles.
The post also briefly touches on future work, including work on source provenance:
Homebrew s formulae already hash-pin their source artifacts, but we can go a step further and additionally assert that source artifacts are produced by the repository (or other signing identity) that s latent in their URL or otherwise embedded into the formula specification.

Distribution news In Debian this month, Johannes Schauer Marin Rodrigues (aka josch) noticed that the Debian binary package bash version 5.2.15-2+b3 was uploaded to the archive twice. Once to bookworm and once to sid but with differing content. This is problem for reproducible builds in Debian due its assumption that the package name, version and architecture triplet is unique. However, josch highlighted that
This example with bash is especially problematic since bash is Essential:yes, so there will now be a large portion of .buildinfo files where it is not possible to figure out with which of the two differing bash packages the sources were compiled.
In response to this, Holger Levsen performed an analysis of all .buildinfo files and found that this needs almost 1,500 binNMUs to fix the fallout from this bug. Elsewhere in Debian, Vagrant Cascadian posted about a Non-Maintainer Upload (NMU) sprint to take place during early June, and it was announced that there is now a #debian-snapshot IRC channel on OFTC to discuss the creation of a new source code archiving service to, perhaps, replace snapshot.debian.org. Lastly, 11 reviews of Debian packages were added, 15 were updated and 48 were removed this month adding to our extensive knowledge about identified issues. A number of issue types have been updated by Chris Lamb as well. [ ][ ]
Elsewhere in the world of distributions, deep within a larger announcement from Colin Percival about the release of version 14.1-BETA2, it was mentioned that the FreeBSD kernels are now built reproducibly.
In Fedora, however, the change proposal mentioned in our report for April 2024 was approved, so, per the ReproduciblePackageBuilds wiki page, the add-determinism tool is now running in new builds for Fedora 41 ( rawhide ). The add-determinism tool is a Rust program which, as its name suggests, adds determinism to files that are given as input by attempting to standardize metadata contained in binary or source files to ensure consistency and clamping to $SOURCE_DATE_EPOCH in all instances . This is essentially the Fedora version of Debian s strip-nondeterminism. However, strip-nondeterminism is written in Perl, and Fedora did not want to pull Perl in the buildroot for every package. The add-determinism tool eliminates many causes of non-determinism and work is ongoing to continue the scope of packages it can operate on.

Mailing list news On our mailing list this month, regular contributor kpcyrd wrote to the list with an update on their source code indexing project, whatsrc.org. The whatsrc.org project, which was launched last month in response to the XZ Utils backdoor, now contains and indexes almost 250,000 unique source code archives. In their post, kpcyrd gives an example of its intended purpose, noting that it shown that whilst there seems to be consensus about [the] source code for zsh 5.9 in various Linux distributions, it does not align with the contents of the zsh Git repository . Holger Levsen also posted to the list with a pre-announcement of sorts for the 2024 Reproducible Builds summit. In particular:
[Whilst] the dates and location are not fixed yet, however if you don help us with finding a suitable location soon, it is very likely that we ll meet again in Hamburg in the 2nd half of September 2024 [ ].
Lastly, Frederic-Emmanuel Picca wrote to the list asking for help understanding the non-reproducible status of the Debian silx package and received replies from both Vagrant Cascadian and Chris Lamb.

Miscellaneous news strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. This month strip-nondeterminism version 1.14.0-1 was uploaded to Debian unstable by Chris Lamb chiefly to incorporate a change from Alex Muntada to avoid a dependency on Sub::Override to perform monkey-patching and break circular dependencies related to debhelper [ ]. Elsewhere in our tooling, Jelle van der Waa modified reprotest because the pipes module will be removed in Python version 3.13 [ ].
It was also noticed that a new blog post by Daniel Stenberg detailing How to verify a Curl release mentions the SOURCE_DATE_EPOCH environment variable. This is because:
The [curl] release tools document also contains another key component: the exact time stamp at which the release was done using integer second resolution. In order to generate a correct tarball clone, you need to also generate the new version using the old version s timestamp. Because the modification date of all files in the produced tarball will be set to this timestamp.

Furthermore, Fay Stegerman filed a bug against the Signal messenger app for Android to report that their reproducible builds cannot, in fact, be reproduced. However, Fay is quick to note that she has:
found zero evidence of any kind of compromise. Some differences are yet unexplained but everything I found seems to be benign. I am disappointed that Reproducible Builds have been broken for months but I have zero reason to doubt Signal s security in any way.

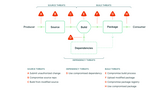
Lastly, it was observed that there was a concise and diagrammatic overview of supply chain threats on the SLSA website.

Two new academic papers Two new scholarly papers were published this month. Firstly, Mathieu Acher, Beno t Combemale, Georges Aaron Randrianaina and Jean-Marc J z quel of University of Rennes on Embracing Deep Variability For Reproducibility & Replicability. The authors describe their approach as follows:
In this short [vision] paper we delve into the application of software engineering techniques, specifically variability management, to systematically identify and explicit points of variability that may give rise to reproducibility issues (e.g., language, libraries, compiler, virtual machine, OS, environment variables, etc.). The primary objectives are: i) gaining insights into the variability layers and their possible interactions, ii) capturing and documenting configurations for the sake of reproducibility, and iii) exploring diverse configurations to replicate, and hence validate and ensure the robustness of results. By adopting these methodologies, we aim to address the complexities associated with reproducibility and replicability in modern software systems and environments, facilitating a more comprehensive and nuanced perspective on these critical aspects.
(A PDF of this article is available.)
Secondly, Ludovic Court s, Timothy Sample, Simon Tournier and Stefano Zacchiroli have collaborated to publish a paper on Source Code Archiving to the Rescue of Reproducible Deployment. Their paper was motivated because:
The ability to verify research results and to experiment with methodologies are core tenets of science. As research results are increasingly the outcome of computational processes, software plays a central role. GNU Guix is a software deployment tool that supports reproducible software deployment, making it a foundation for computational research workflows. To achieve reproducibility, we must first ensure the source code of software packages Guix deploys remains available.
(A PDF of this article is also available.)

diffoscope diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes such as uploading versions 266, 267, 268 and 269 to Debian, making the following changes:
  • New features:
    • Use xz --list to supplement output when comparing .xz archives; essential when metadata differs. (#1069329)
    • Include xz --verbose --verbose (ie. double) output. (#1069329)
    • Strip the first line from the xz --list output. [ ]
    • Only include xz --list --verbose output if the xz has no other differences. [ ]
    • Actually append the xz --list after the container differences, as it simplifies a lot. [ ]
  • Testing improvements:
    • Allow Debian testing to fail right now. [ ]
    • Drop apktool from Build-Depends; we can still test APK functionality via autopkgtests. (#1071410)
    • Add a versioned dependency for at least version 5.4.5 for the xz tests as they fail under (at least) version 5.2.8. (#374)
    • Fix tests for 7zip 24.05. [ ][ ]
    • Fix all tests after additon of xz --list. [ ][ ]
  • Misc:
    • Update copyright years. [ ]
In addition, James Addison fixed an issue where the HTML output showed only the first difference in a file, while the text output shows all differences [ ][ ][ ], Sergei Trofimovich amended the 7zip version test for older 7z versions that include the string [64] [ ][ ] and Vagrant Cascadian relaxed the versioned dependency to allow version 5.4.1 for the xz tests [ ] and proposed updates to guix for versions 267, 268 and pushed version 269 to Guix. Furthermore, Eli Schwartz updated the diffoscope.org website in order to explain how to install diffoscope on Gentoo [ ].

Website updates There were a number of improvements made to our website this month, including Chris Lamb making the print CSS stylesheet nicer [ ]. Fay Stegerman made a number of updates to the page about the SOURCE_DATE_EPOCH environment variable [ ][ ][ ] and Holger Levsen added some of their presentations to the Resources page. Furthermore, IOhannes zm lnig stipulated support for SOURCE_DATE_EPOCH in clang version 16.0.0+ [ ], Jan Zerebecki expanded the Formal definition page and fixed a number of typos on the Buy-in page [ ] and Simon Josefsson fixed the link to Trisquel GNU/Linux on the Projects page [ ].

Upstream patches This month, we wrote a number of patches to fix specific reproducibility issues, including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In May, a number of changes were made by Holger Levsen:
  • Debian-related changes:
    • Enable the rebuilder-snapshot API on osuosl4. [ ]
    • Schedule the i386 architecture a bit more often. [ ]
    • Adapt cleanup_nodes.sh to the new way of running our build services. [ ]
    • Add 8 more workers for the i386 architecture. [ ]
    • Update configuration now that the infom07 and infom08 nodes have been reinstalled as real i386 systems. [ ]
    • Make diffoscope timeouts more visible on the #debian-reproducible-changes IRC channel. [ ]
    • Mark the cbxi4a-armhf node as down. [ ][ ]
    • Only install the hdmi2usb-mode-switch package only on Debian bookworm and earlier [ ] and only install the haskell-platform package on Debian bullseye [ ].
  • Misc:
    • Install the ntpdate utility as we need it later. [ ]
    • Document the progress on the i386 architecture nodes at Infomaniak. [ ]
    • Drop an outdated and unnoticed notice. [ ]
    • Add live_setup_schroot to the list of so-called zombie jobs. [ ]
In addition, Mattia Rizzolo reinstalled the infom07 and infom08 nodes [ ] and Vagrant Cascadian marked the cbxi4a node as online [ ].

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

7 June 2024

Freexian Collaborators: Debian Contributions: DebConf Bursaries, /usr-move, sbuild, and more! (by Stefano Rivera)

Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf Bursary updates, by Utkarsh Gupta Utkarsh is the bursaries team lead for DebConf 24. Bursary requests are dispatched to a team of volunteers to review. The results are collated, adjusted and merged to produce priority lists of requests to fund. Utkarsh raised the team, coordinated the review, and issued bursaries to attendees.

/usr-move, by Helmut Grohne More and more, the /usr-move transition is being carried out by multiple contributors and many performed around a hundred of the requested uploads. Of these, Helmut contributed five patches and two uploads. As a result, there are less than 350 packages left to be converted, and all of the non-trivial cases have patches. We started with three times that number. Thanks to everyone involved for supporting this effort. For people interested in background information of this transition, Helmut gave a presentation at MiniDebConf Berlin 2024 (slides).

sbuild, by Helmut Grohne While unshare mode of sbuild has existed for quite a while, it is now getting significant use in Debian, and new problems are popping up. Helmut looked into an apparmor-related failure and provided a diagnosis. While relevant code would detect the chroot nature of a schroot backend and skip apparmor tests, the unshare environment would be just good enough to run and fail the test. As sbuild exposes fewer special kernel filesystems, the tests will be skipped again. Another problem popped up when gobject-introspection added a dependency on the host architecture Python interpreter in a cross build environment. sbuild would prefer installing (and failing) a host architecture Python to installing the qemu alternative. Attempts to fix this would result in systemd killing sbuild. ischroot as used by libc6.postinst would not classify the unshare environment as a chroot. Therefore libc6.postinst would run telinit which would kill the build process. This is a complex interaction problem that shall eventually be solved by providing triggers from libc6 to be implemented by affected init systems.

Salsa CI updates, by Santiago Ruano Rinc n Several issues arose about Salsa CI last month, and it is probably worth mentioning part of the challenges of defining its framework in YAML. With the upcoming end-of-support of Debian 10 buster as LTS, armel was removed from deb.debian.org, making the jobs that build images for buster/armel to fail. While the removal of buster/armel from the repositories is a natural change, it put some light on the flaws in the Salsa CI design regarding the support of the different Debian releases. Currently, the images are defined like these (from .images-debian.yml):
.all-supported-releases: &all-supported-releases
  - stretch
  - stretch-backports
  - buster
  - bullseye
  - bullseye-backports
  - bookworm
  - bookworm-backports
  - trixie
  - sid
  - experimental
And from them, different images are built according to the different jobs and how they are supported, for example:
images-prod-arm:
  stage: build
  extends: .build_template
  tags:
    - $SALSA_CI_ARM_RUNNER_TAG
  parallel:
    matrix:
      # Base image, all releases, all arches
      - IMAGE_NAME: base
        ARCH:
          - arm32v5
          - arm32v7
          - arm64v8
        RELEASE: *all-supported-releases
The removal of buster/armel could be easily reflected as:
images-prod-arm:
  stage: build
  extends: .build_template
  tags:
    - $SALSA_CI_ARM_RUNNER_TAG
  parallel:
    matrix:
      # Base image, fully supported releases, all arches
      - IMAGE_NAME: base
        ARCH:
          - arm32v5
          - arm32v7
          - arm64v8
        RELEASE:
          - stretch
          - buster
          - bullseye
          - bullseye-backports
          - bookworm
          - bookworm-backports
          - trixie
          - sid
          - experimental
      # buster only supports armhf and arm64
      - IMAGE_NAME: base
        ARCH:
          - arm32v7
          - arm64v8
        RELEASE: buster
Evidently, this increases duplication of the release support data, which is of course not optimal and it is error prone when changing the data about supported releases. A better approach would be to have two different YAML lists, such as:
# releases that have partial support. E.g.: buster is transitioning to
# Debian LTS, and buster armel is no longer found in deb.debian.org
.old-releases: &old-releases
  - stretch
  - buster

.currently-supported-releases: &currently-supported-releases
  - bullseye
  - bullseye-backports
  - bookworm
  - bookworm-backports
  - trixie
  - sid
  - experimental
and then a unified list:
.all-supported-releases: &all-supported-releases
  - *old-releases
  - *currently-supported-releases
that could be used in the matrix of the jobs that build all the images available in the pipeline container registry. However, due to limitations in GitLab, it is not possible to expand the variables or mapping values in a parallel:matrix context. At least not in an elegant fashion. This is the kind of issue that recently arose and that Santiago is currently working to solve, in the simplest possible way. Astute readers would notice that stretch is listed in the fully supported releases. And there is no problem with stretch, because it is built from archive.debian.org. Otto actually has tried to fix the broken image build job doing the same, but it is still incorrect, because the security repository is not (yet) available in archive.debian.org. Additionally, Santiago has also worked on other merge requests, such as:
  1. support branch/tags as target head in the test projects,
  2. build autopkgtest image on top of stable
  3. Add .yamllint and make it happy in the autopkgtest-lxc project
  4. enable FF_SCRIPT_SECTIONS to log multiline commands, among others.

Archiving DebConf Websites, by Stefano Rivera DebConf, the annual Debian conference, has its own new website every year. These are typically complex dynamic web applications (featuring registration, call for papers, scheduling, etc.) Once the conference is over, there is no need to keep maintaining these applications, so we archive the sites off as static HTML, and serve them from Debian s static CDN. Stefano archived the websites for the last two DebConfs. The schedule system behind DebConf 14 and 15 s websites was a derivative of Canonical s summit system. This was only used for a couple of years before migrating to wafer, the current system. Archiving summit content has been on the nice to have list for years, but nobody has ever tackled it. The machine that served the sites went away a couple of years ago. After much digging, a backup of the database was found, and Stefano got this code running on an ancient Python 2.7. Recently Stefano put this all together and hooked in an archive export to finally get this content preserved.

Python 3.x and pypy3 security bug triage, by Stefano Rivera Stefano Rivera triaged all the open security bugs against the Python 3.x and PyPy3 packages for Debian s stable and LTS releases. Several had been fixed but this wasn t recorded in the security tracker.

Linux livepatching support for Debian, by Santiago Ruano Rinc n In collaboration with Emmanuel Arias, Santiago filed ITP bug #1070494. As stated in the bug, more than an Intent to Package, it is an Intent to Design and Implement live patching support for the Linux kernel in Debian. For now, Emmanuel and Santiago have done exploratory work and they are working to understand the different possibilities to implement livepatching. One possible direction is to rely on kpatch, and the other is to package the modules using regular packaging tools. Also, it is needed to evaluate if it is possible to rely on distributing the modules via packages, or instead as a service, as it is done by some commercial distributions.

Miscellaneous contributions
  • Thorsten Alteholz uploaded cups-bjnp to improve packaging.
  • Colin Watson tracked down a baffling CI issue in openssh to unblock several merge requests, removed the user_readenv=1 option from its PAM configuration, and started on the first stage of his plan to split out GSS-API key exchange support to separate packages.
  • Colin did his usual routine work on the Python team, upgrading 26 packages to new upstream versions, and cherry-picking an upstream PR to fix a pytest 8 incompatibility in ipywidgets.
  • Colin NMUed a couple of packages to reduce the need for explicit overrides in Packages-arch-specific, and removed some other obsolete entries from there.
  • Emilio managed various library transitions, and helped finish a few of the remaining t64 transitions.
  • Helmut sent a patch for enabling piuparts to work as a regular user building on earlier work.
  • Helmut sent patches for 7 cross build failures, 6 other debian bugs and fixed an infrastructure problem in crossqa.debian.net.
  • Nicholas worked on a sponsored package upload, and discovered the blhc tool for diagnosing build hardening.
  • Stefano Rivera started and completed the re2 transition. The release team suggested moving to a virtual package scheme that includes the absl ABI (as re2 now depends on it). Adopted this.
  • Stefano continued to work on DebConf 24 planning.
  • Santiago continued to work on DebConf24 Content tasks as well as Debconf25 organisation.

6 June 2024

Paul Wise: FLOSS Activities May 2024

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review
  • Debian BTS usertags: changes for the month

Administration
  • Debian wiki: approve accounts

Communication
  • Respond to queries from Debian users and contributors on the mailing lists and IRC

Sponsors All work was done on a volunteer basis.

5 June 2024

Scarlett Gately Moore: Kubuntu, KDE, Debian: I am still here, in loving memory of my brother.

I am still here, busy as ever, I just haven t found the inspiration to blog. So soon after the loss of my son, I have lost my only brother a couple weeks ago. It has been a tough year for our family. Thank you everyone for you love and support during this difficult time. I will do my best in re-capping my work, there has been quite a bit as I am keeping busy with work so I don t dwell to much on the sadness. KDE Snaps: Trying to debug the unable to save files breakage in the latest Krita builds without luck. KisOpenGLCanvas
Renderer::reportFailedShaderCompilation\[0m: Shad
er Compilation Failure: "Failed to add vertex sh
ader source from file: matrix_transform.vert - Ca
use: "
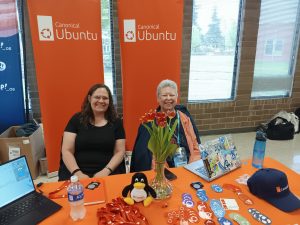
I have implemented everything from https://snapcraft.io/docs/gpu-support , it has worked for years and now suddenly it just stopped. I have had to put it on hold for now, it is unpaid work and I simply don t have time. With the help of my GSOC student we are improving the Qt6 snap MR: https://invent.kde.org/neon/snap-packaging/kde-qt6-core-sdk/-/merge_requests/3 and many improvements on top of that. This exposed many issues with the kf6 snap and the linking to static libs. Those are being worked on now. Updated qt to 6.7.1 Qt6 apps in the works: okular, ark, gwenview, kwrited, elisa Kubuntu: So many SRu s for the Noble release, I will probably miss a few. https://bugs.launchpad.net/ubuntu/+source/ark/+bug/2068491 Ark cannot open 7-zip files. Sadly the patches were for qt6, waiting for a qt5 port upstream. https://bugs.launchpad.net/ubuntu/noble/+source/merkuro/+bug/2065063 Crash due to missing qml. Fix is in git, no upload rights. Requested sponsor. https://bugs.launchpad.net/ubuntu/+source/tellico/+bug/2065915 Several applications no longer work on architectures that are not amd64 due to hard coded paths. All fixed in git. Several uploaded to oracular, several sponsorship has been requested. Noble updates rejected despite SRU, going to retry. https://bugs.launchpad.net/ubuntu/+source/sddm/+bug/2066275 The dreaded black screen on second boot bug is fixed in git and oracular. Noble was rejected despite the SRU. Will retry. https://bugs.launchpad.net/ubuntu/+source/kubuntu-meta/+bug/2066028 Broken systray submenus. Fixed in git and oracular. Noble rejected despite SRU. Will retry. https://bugs.launchpad.net/ubuntu/+source/plasma-workspace/+bug/2067747 Long standing bug with plasma not loading with lightdm. Fixed in git and oracular. Noble rejected will retry. https://bugs.launchpad.net/ubuntu/+source/plasma-workspace/+bug/2067742 CVE-2024-36041Fixed in git and oracular, noble rejected, will retry. And many more I am applying for MOTU in hopes it will reduce all of my uploading issues. https://wiki.ubuntu.com/scarlettmoore/MOTUApplication Debian: kf6-knotifications and kapidox. Will jump into Plasma 6 next week ! Misc: Went to LinuxFest Northwest with Valorie! We had a great time and it was a huge success, we had many people stop by our booth.
As usual, if you like my work and want to see Plasma 6 in Kubuntu it all depends on you! Kubuntu will be out of funds soon and needs donations! Thank you for your consideration. https://kubuntu.org/donate/ Personal: Support for my grandson: https://www.gofundme.com/f/in-loving-memory-of-william-billy-dean-scalf

4 June 2024

Dirk Eddelbuettel: ulid 0.4.0 on CRAN: Extended to Milliseconds

A new version of the ulid package is now on CRAN. The packages provides universally (unique) lexicographically (sortable) identifiers see the spec at GitHub for details on those which offer sorting which uuids lack. The R package provides access via the standard C++ library, had been put together by Bob Rudis and is now maintained by me. Mark Heckmann noticed that a ulid round trip of generating and unmarshalling swallowed subsecond informationm and posted on a well-known site I no longer go to. Duncan Murdoch was kind enough to open an issue to make me aware, and in it included the nice minimally complete verifiable example by Mark. It turns out that this issue was known, documented upstream in two issues and fixed in fork by the authors of those issues, Chris Bove. It replaces time_t as the value of record (constrained at the second resolution) with a proper std::chrono object which offers milliseconds (and much more, yay Modern C++). So I switched the two main files of library to his, and updated the wrapper code to interface from POSIXct to std::chrono object. And with that we are in business. The original example of five ulids create 100 millisecond part, then unmarshalled and here printed as a data.table as data.frame by default truncates to seconds:
> library(ulid)
> gen_ulid <- \(sleep) replicate(5,  Sys.sleep(sleep); generate() )
> u <- gen_ulid(.1)
> df <- unmarshal(u)
> data.table::data.table(df)
                        ts              rnd
                    <POSc>           <char>
1: 2024-05-30 16:38:28.588 CSQAJBPNX75R0G5A
2: 2024-05-30 16:38:28.688 XZX0TREDHD6PC1YR
3: 2024-05-30 16:38:28.789 0YK9GKZVTED27QMK
4: 2024-05-30 16:38:28.890 SC3M3G6KGPH7S50S
5: 2024-05-30 16:38:28.990 TSKCBWJ3TEKCPBY0
>
We updated the documentation accordingly, and added some new tests as well. The NEWS entry for this release follows.

Changes in version 0.4.0 (2024-06-03)
  • Switch two functions to fork by Chris Bove using std::chrono instead of time_t for consistent millisecond resolution (#3 fixing #2)
  • Updated documentation showing consistent millisecond functionality
  • Added unit tests for millisecond functionality

Courtesy of my CRANberries, there is also a diffstat report for this release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

2 June 2024

Colin Watson: Free software activity in May 2024

My Debian contributions this month were all sponsored by Freexian. The bulk of my Debian time this month went towards trying to haul more Python packages up to current versions, but I got a few other bits and pieces done as well. You can support my work directly via Liberapay.

31 May 2024

Dirk Eddelbuettel: RcppArmadillo 0.12.8.4.0 on CRAN: Upstream Bugfix

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1151 other packages on CRAN, downloaded 34.6 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 584 times according to Google Scholar. Conrad released a new upstream bugfix yesterday (to improve views of sparse matrices). We uploaded it yesterday too but it once agfain took a day for the hard-working CRAN maintainers to concur that the two NOTEs from reverse-dependency checking over 1100 packages were in a fact false positves. And so it appeared on CRAN earlier today. We also increased the versioned dependency on Rcpp to match the use of optional entry-point headers Rcpp/Light, Rcpp/Lighter and Rcpp/Lightest. No other changes were made. The set of changes since the last CRAN release follows.

Changes in RcppArmadillo version 0.12.8.4.0 (2024-05-30)
  • Upgraded to Armadillo release 12.8.4 (Cortisol Injector)
    • Faster handling of sparse submatrix views
  • Update versioned Depends on Rcpp to 1.0.8 or later to match use of Light/Lighter/Lightest headers.

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

29 May 2024

Antoine Beaupr : Playing with fonts again

I am getting increasingly frustrated by Fira Mono's lack of italic support so I am looking at alternative fonts again.

Commit Mono This time I seem to be settling on either Commit Mono or Space Mono. For now I'm using Commit Mono because it's a little more compressed than Fira and does have a italic version. I don't like how Space Mono's parenthesis (()) is "squarish", it feels visually ambiguous with the square brackets ([]), a big no-no for my primary use case (code). So here I am using a new font, again. It required changing a bunch of configuration files in my home directory (which is in a private repository, sorry) and Emacs configuration (thankfully that's public!). One gotcha is I realized I didn't actually have a global font configuration in Emacs, as some Faces define their own font family, which overrides the frame defaults. This is what it looks like, before:
A dark terminal showing the test sheet in Fira Mono Fira Mono
After:
A dark terminal showing the test sheet in Fira Mono Commit Mono
(Notice how those screenshots are not sharp? I'm surprised too. The originals look sharp on my display, I suspect this is something to do with the Wayland transition. I've tried with both grim and flameshot, for what its worth.) They are pretty similar! Commit Mono feels a bit more vertically compressed maybe too much so, actually -- the line height feels too low. But it's heavily customizable so that's something that's relatively easy to fix, if it's really a problem. Its weight is also a little heavier and wider than Fira which I find a little distracting right now, but maybe I'll get used to it. All characters seem properly distinguishable, although, if I'd really want to nitpick I'd say the and are too different, with the latter (REGISTERED SIGN) being way too small, basically unreadable here. Since I see this sign approximately never, it probably doesn't matter at all. I like how the ampersand (&) is more traditional, although I'll miss the exotic one Fira produced... I like how the back quotes ( , GRAVE ACCENT) drop down low, nicely aligned with the apostrophe. As I mentioned before, I like how the bar on the "f" aligns with the other top of letters, something in Fira mono that really annoys me now that I've noticed it (it's not aligned!).

A UTF-8 test file Here's the test sheet I've made up to test various characters. I could have sworn I had a good one like this lying around somewhere but couldn't find it so here it is, I guess.
US keyboard coverage:
abcdefghijklmnopqrstuvwxyz 1234567890-=[]\;',./
ABCDEFGHIJKLMNOPQRSTUVWXYZ~!@#$%^&*()_+ :"<>?
latin1 coverage:  
EURO SIGN, TRADE MARK SIGN:  
ambiguity test:
e coC0ODQ iI71lL! 
b6G&0B83  []() /\. 
zs$S52Z%   '" 
all characters in a sentence, uppercase:
the quick fox jumps over the lazy dog
THE QUICK FOX JUMPS OVER THE LAZY DOG
same, in french:
Portez ce vieux whisky au juge blond qui fume.
d s no l, o  un z phyr ha  me v t de gla ons w rmiens, je d ne
d exquis r tis de b uf au kir,   l a  d ge m r, &c tera.
D S NO L, O  UN Z PHYR HA  ME V T DE GLA ONS W RMIENS, JE D NE
D EXQUIS R TIS DE B UF AU KIR,   L A  D GE M R, &C TERA.
Ligatures test:
-<< -< -<- <-- <--- <<- <- -> ->> --> ---> ->- >- >>-
=<< =< =<= <== <=== <<= <= => =>> ==> ===> =>= >= >>=
<-> <--> <---> <----> <=> <==> <===> <====> :: ::: __
<~~ </ </> /> ~~> == != /= ~= <> === !== !=== =/= =!=
<: := *= *+ <* <*> *> <  < >  > <. <.> .> +* =* =: :>
(* *) /* */ [   ]     ++ +++ \/ /\  - -  <!-- <!---
Box drawing alignment tests:


Dashes alignment test:
HYPHEN-MINUS, MINUS SIGN, EN, EM DASH, HORIZONTAL BAR, LOW LINE
--------------------------------------------------


__________________________________________________
Update: here is another such sample sheet, it's pretty good and has support for more languages while being still relatively small. So there you have it, got completely nerd swiped by typography again. Now I can go back to writing a too-long proposal again. Sources and inspiration for the above:
  • the unicode(1) command, to lookup individual characters to disambiguate, for example, - (U+002D HYPHEN-MINUS, the minus sign next to zero on US keyboards) and (U+2212 MINUS SIGN, a math symbol)
  • searchable list of characters and their names - roughly equivalent to the unicode(1) command, but in one page, amazingly the /usr/share/unicode database doesn't have any one file like this
  • bits/UTF-8-Unicode-Test-Documents - full list of UTF-8 characters
  • UTF-8 encoded plain text file - nice examples of edge cases, curly quotes example and box drawing alignment test which, incidentally, showed me I needed specific faces customisation in Emacs to get the Markdown code areas to display properly, also the idea of comparing various dashes
  • sample sentences in many languages - unused, "Sentences that contain all letters commonly used in a language"
  • UTF-8 sampler - unused, similar

Other fonts In my previous blog post about fonts, I had a list of alternative fonts, but it seems people are not digging through this, so I figured I would redo the list here to preempt "but have you tried Jetbrains mono" kind of comments. My requirements are:
  • no ligatures: yes, in the previous post, I wanted ligatures but I have changed my mind. after testing this, I find them distracting, confusing, and they often break the monospace nature of the display
  • monospace: this is to display code
  • italics: often used when writing Markdown, where I do make use of italics... Emacs falls back to underlining text when lacking italics which is hard to read
  • free-ish, ultimately should be packaged in Debian
Here is the list of alternatives I have considered in the past and why I'm not using them:
  • agave: recommended by tarzeau, not sure I like the lowercase a, a bit too exotic, packaged as fonts-agave
  • Cascadia code: optional ligatures, multilingual, not liking the alignment, ambiguous parenthesis (look too much like square brackets), new default for Windows Terminal and Visual Studio, packaged as fonts-cascadia-code
  • Fira Code: ligatures, was using Fira Mono from which it is derived, lacking italics except for forks, interestingly, Fira Code succeeds the alignment test but Fira Mono fails to show the X signs properly! packaged as fonts-firacode
  • Hack: no ligatures, very similar to Fira, italics, good alternative, fails the X test in box alignment, packaged as fonts-hack
  • Hermit: no ligatures, smaller, alignment issues in box drawing and dashes, packaged as fonts-hermit somehow part of cool-retro-term
  • IBM Plex: irritating website, replaces Helvetica as the IBM corporate font, no ligatures by default, italics, proportional alternatives, serifs and sans, multiple languages, partial failure in box alignment test (X signs), fancy curly braces contrast perhaps too much with the rest of the font, packaged in Debian as fonts-ibm-plex
  • Inconsolata: no ligatures, maybe italics? more compressed than others, feels a little out of balance because of that, packaged in Debian as fonts-inconsolata
  • Intel One Mono: nice legibility, no ligatures, alignment issues in box drawing, not packaged in Debian
  • Iosevka: optional ligatures, italics, multilingual, good legibility, has a proportional option, serifs and sans, line height issue in box drawing, fails dash test, not in Debian
  • Jetbrains Mono: (mandatory?) ligatures, good coverage, originally rumored to be not DFSG-free (Debian Free Software Guidelines) but ultimately packaged in Debian as fonts-jetbrains-mono
  • Monoid: optional ligatures, feels much "thinner" than Jetbrains, not liking alignment or spacing on that one, ambiguous 2Z, problems rendering box drawing, packaged as fonts-monoid
  • Mononoki: no ligatures, looks good, good alternative, suggested by the Debian fonts team as part of fonts-recommended, problems rendering box drawing, em dash bigger than en dash, packaged as fonts-mononoki
  • Source Code Pro: italics, looks good, but dash metrics look whacky, not in Debian
  • spleen: bitmap font, old school, spacing issue in box drawing test, packaged as fonts-spleen
  • sudo: personal project, no ligatures, zero originally not dotted, relied on metrics for legibility, spacing issue in box drawing, not in Debian
So, if I get tired of Commit Mono, I might probably try, in order:
  1. Hack
  2. Jetbrains Mono
  3. IBM Plex Mono
Iosevka, Monoki and Intel One Mono are also good options, but have alignment problems. Iosevka is particularly disappointing as the EM DASH metrics are just completely wrong (much too wide). This was tested using the Programming fonts site which has all the above fonts, which cannot be said of Font Squirrel or Google Fonts, amazingly. Other such tools:

27 May 2024

Thomas Koch: Minimal overhead VMs with Nix and MicroVM

Posted on March 17, 2024
Joachim Breitner wrote about a Convenient sandboxed development environment and thus reminded me to blog about MicroVM. I ve toyed around with it a little but not yet seriously used it as I m currently not coding. MicroVM is a nix based project to configure and run minimal VMs. It can mount and thus reuse the hosts nix store inside the VM and thus has a very small disk footprint. I use MicroVM on a debian system using the nix package manager. The MicroVM author uses the project to host production services. Otherwise I consider it also a nice way to learn about NixOS after having started with the nix package manager and before making the big step to NixOS as my main system. The guests root filesystem is a tmpdir, so one must explicitly define folders that should be mounted from the host and thus be persistent across VM reboots. I defined the VM as a nix flake since this is how I started from the MicroVM projects example:
 
  description = "Haskell dev MicroVM";
  inputs.impermanence.url = "github:nix-community/impermanence";
  inputs.microvm.url = "github:astro/microvm.nix";
  inputs.microvm.inputs.nixpkgs.follows = "nixpkgs";
  outputs =   self, impermanence, microvm, nixpkgs  :
    let
      persistencePath = "/persistent";
      system = "x86_64-linux";
      user = "thk";
      vmname = "haskell";
      nixosConfiguration = nixpkgs.lib.nixosSystem  
          inherit system;
          modules = [
            microvm.nixosModules.microvm
            impermanence.nixosModules.impermanence
            ( pkgs, ...  :  
            environment.persistence.$ persistencePath  =  
                hideMounts = true;
                users.$ user  =  
                  directories = [
                    "git" ".stack"
                  ];
                 ;
               ;
              environment.sessionVariables =  
                TERM = "screen-256color";
               ;
              environment.systemPackages = with pkgs; [
                ghc
                git
                (haskell-language-server.override   supportedGhcVersions = [ "94" ];  )
                htop
                stack
                tmux
                tree
                vcsh
                zsh
              ];
              fileSystems.$ persistencePath .neededForBoot = nixpkgs.lib.mkForce true;
              microvm =  
                forwardPorts = [
                    from = "host"; host.port = 2222; guest.port = 22;  
                    from = "guest"; host.port = 5432; guest.port = 5432;   # postgresql
                ];
                hypervisor = "qemu";
                interfaces = [
                    type = "user"; id = "usernet"; mac = "00:00:00:00:00:02";  
                ];
                mem = 4096;
                shares = [  
                  # use "virtiofs" for MicroVMs that are started by systemd
                  proto = "9p";
                  tag = "ro-store";
                  # a host's /nix/store will be picked up so that no
                  # squashfs/erofs will be built for it.
                  source = "/nix/store";
                  mountPoint = "/nix/.ro-store";
                   
                  proto = "virtiofs";
                  tag = "persistent";
                  source = "~/.local/share/microvm/vms/$ vmname /persistent";
                  mountPoint = persistencePath;
                  socket = "/run/user/1000/microvm-$ vmname -persistent";
                 
                ];
                socket = "/run/user/1000/microvm-control.socket";
                vcpu = 3;
                volumes = [];
                writableStoreOverlay = "/nix/.rwstore";
               ;
              networking.hostName = vmname;
              nix.enable = true;
              nix.nixPath = ["nixpkgs=$ builtins.storePath <nixpkgs> "];
              nix.settings =  
                extra-experimental-features = ["nix-command" "flakes"];
                trusted-users = [user];
               ;
              security.sudo =  
                enable = true;
                wheelNeedsPassword = false;
               ;
              services.getty.autologinUser = user;
              services.openssh =  
                enable = true;
               ;
              system.stateVersion = "24.11";
              systemd.services.loadnixdb =  
                description = "import hosts nix database";
                path = [pkgs.nix];
                wantedBy = ["multi-user.target"];
                requires = ["nix-daemon.service"];
                script = "cat $ persistencePath /nix-store-db-dump nix-store --load-db";
               ;
              time.timeZone = nixpkgs.lib.mkDefault "Europe/Berlin";
              users.users.$ user  =  
                extraGroups = [ "wheel" "video" ];
                group = "user";
                isNormalUser = true;
                openssh.authorizedKeys.keys = [
                  "ssh-rsa REDACTED"
                ];
                password = "";
               ;
              users.users.root.password = "";
              users.groups.user =  ;
             )
          ];
         ;
    in  
      packages.$ system .default = nixosConfiguration.config.microvm.declaredRunner;
     ;
 
I start the microVM with a templated systemd user service:
[Unit]
Description=MicroVM for Haskell development
Requires=microvm-virtiofsd-persistent@.service
After=microvm-virtiofsd-persistent@.service
AssertFileNotEmpty=%h/.local/share/microvm/vms/%i/flake/flake.nix
[Service]
Type=forking
ExecStartPre=/usr/bin/sh -c "[ /nix/var/nix/db/db.sqlite -ot %h/.local/share/microvm/nix-store-db-dump ]   nix-store --dump-db >%h/.local/share/microvm/nix-store-db-dump"
ExecStartPre=ln -f -t %h/.local/share/microvm/vms/%i/persistent/ %h/.local/share/microvm/nix-store-db-dump
ExecStartPre=-%h/.local/state/nix/profile/bin/tmux new -s microvm -d
ExecStart=%h/.local/state/nix/profile/bin/tmux new-window -t microvm: -n "%i" "exec %h/.local/state/nix/profile/bin/nix run --impure %h/.local/share/microvm/vms/%i/flake"
The above service definition creates a dump of the hosts nix store db so that it can be imported in the guest. This is necessary so that the guest can actually use what is available in /nix/store. There is an effort for an overlayed nix store that would be preferable to this hack. Finally the microvm is started inside a tmux session named microvm . This way I can use the VM with SSH or through the console and also access the qemu console. And for completeness the virtiofsd service:
[Unit]
Description=serve host persistent folder for dev VM
AssertPathIsDirectory=%h/.local/share/microvm/vms/%i/persistent
[Service]
ExecStart=%h/.local/state/nix/profile/bin/virtiofsd \
 --socket-path=$ XDG_RUNTIME_DIR /microvm-%i-persistent \
 --shared-dir=%h/.local/share/microvm/vms/%i/persistent \
 --gid-map :995:%G:1: \
 --uid-map :1000:%U:1:

Thomas Koch: Using nix package manager in Debian

Posted on January 16, 2024
The nix package manager is available in Debian since May 2020. Why would one use it in Debian? Especially the last point nagged me every time I set up a new Debian installation. My emacs configuration and my Desktop setup expects certain software to be installed. Please be aware that I m a beginner with nix and that my config might not follow best practice. Additionally many nix users are already using the new flakes feature of nix that I m still learning about. So I ve got this file at .config/nixpkgs/config.nix1:
with (import <nixpkgs>  );
 
  packageOverrides = pkgs: with pkgs;  
    thk-emacsWithPackages = (pkgs.emacsPackagesFor emacs-gtk).emacsWithPackages (
      epkgs:
      (with epkgs.elpaPackages; [
        ace-window
        company
        org
        use-package
      ]) ++ (with epkgs.melpaPackages; [
        editorconfig
        flycheck
        haskell-mode
        magit
        nix-mode
        paredit
        rainbow-delimiters
        treemacs
        visual-fill-column
        yasnippet-snippets
      ]) ++ [    # From main packages set
      ]
    );

    userPackages = buildEnv  
      extraOutputsToInstall = [ "doc" "info" "man" ];
      name = "user-packages";
      paths = [
        ghc
        git
        (pkgs.haskell-language-server.override   supportedGhcVersions = [ "94" ];  )
        nix
        stack
        thk-emacsWithPackages
        tmux
        vcsh
        virtiofsd
      ];
     ;
   ;
 
Every time I change the file or want to receive updates, I do:
nix-env --install --attr nixpkgs.userPackages --remove-all
You can see that I install nix with nix. This gives me a newer version than the one available in Debian stable. However, the nix-daemon still runs as the older binary from Debian. My dirty hack is to put this override in /etc/systemd/system/nix-daemon.service.d/override.conf:
[Service]
ExecStart=
ExecStart=@/home/thk/.local/state/nix/profile/bin/nix-daemon nix-daemon --daemon
I m not too interested in a cleaner way since I hope to fully migrate to Nix anyways.

  1. Note the nixpkgs in the path. This is not a config file for nix the package manager but for the nix package collection. See the nixpkgs manual.

Sahil Dhiman: A Late, Late Debconf23 Post

After much procrastination, I have gotten around to complete my DebConf23 (DC23), Kochi blog post. I lost the original etherpad which was started before DebConf23, for jotting down things. Now, I have started afresh with whatever I can remember, months after the actual conference ended. So things might be as accurate as my memory. DebConf23, the 24th annual Debian Conference, happened in Infopark, Kochi, India from 10th September to 17th September 2023. It was preceded by DebCamp from 3rd September to 9th September 2023. First formal bid to host DebConf in India was made during DebConf18 in Hsinchu, Taiwan by Raju Dev, which didn t came our way. In next DebConf, DebConf19 in Curitiba, Brazil, another bid was made by him with help and support from Sruthi, Utkarsh and the whole team.This time, India got the opportunity to host DebConf22, which eventually became DebConf23 for the reasons you all know. I initially met the local team on the sidelines of DebConf20, which was also my first DebConf. Having recently switched to Debian, DC20 introduced me to how things work in Debian. Video team s call for volunteers email pulled me in. Things stuck, and I kept hanging out and helping the local Indian DC team with various stuff. We did manage to organize multiple events leading to DebConf23 including MiniDebConf India 2021 Online, MiniDebConf Palakkad 2022, MiniDebConf Tamil Nadu 2023 and DebUtsav Kochi 2023, which gave us quite a bit of experience and workout. Many local organizers from these conferences later joined various DebConf teams during the conference to help out. For DebConf23, originally I was part of publicity team because that was my usual thing. After a team redistribution exercise, Sruthi and Praveen moved me to sponsorship team, as anyhow we didn t had to do much publicity and sponsorship was one of those things I could get involved remotely. Sponsorship team had to take care of raising funds by reaching out to sponsors, managing invoices and fulfillment. Praveen joined as well in sponsorship team. We also had international sponsorship team, Anisa, Daniel and various Debian Trusted Organizations (TO)s which took care of reaching out to international organizations, and we took care of reaching out to Indian organizations for sponsorship. It was really proud moment when my present employer, Unmukti (makers of hopbox) came aboard as Bronze sponsor. Though fundraising seem to be hit hard from tech industry slowdown and layoffs. Many of our yesteryear sponsors couldn t sponsor. We had biweekly local team meetings, which were turned to weekly as we neared the event. This was done in addition to biweekly global team meeting. Pathu
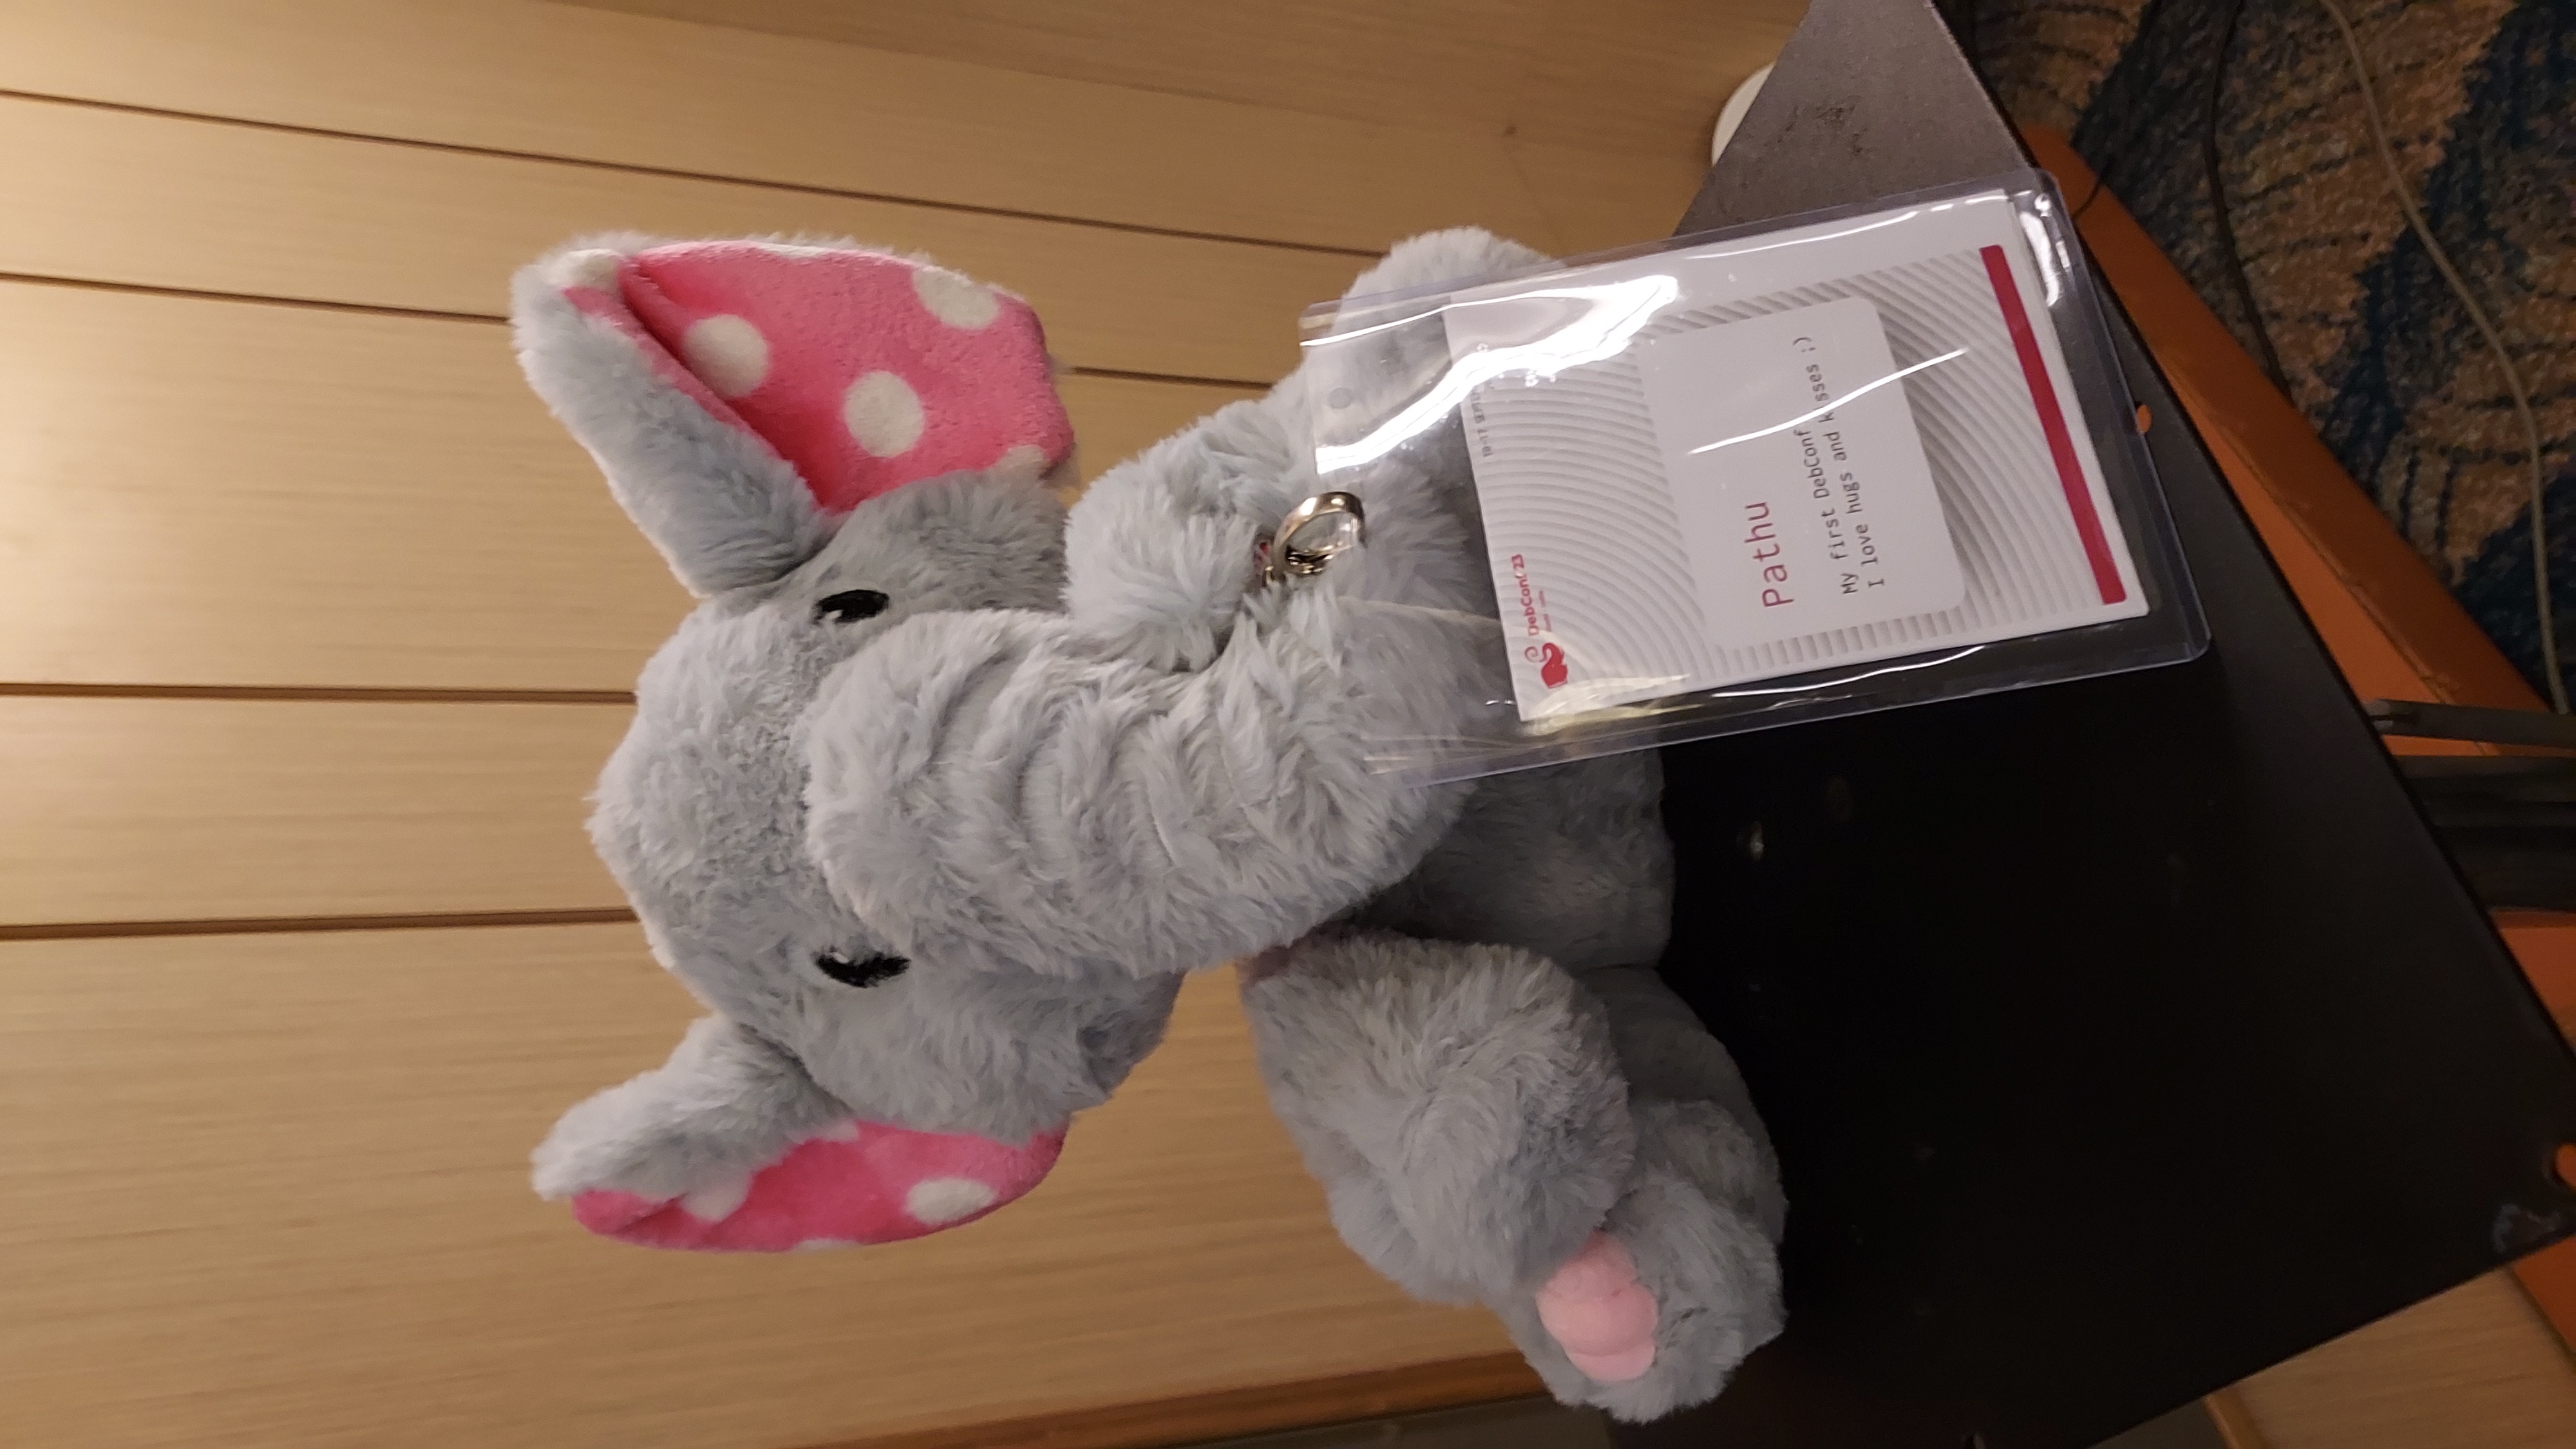
Pathu, DebConf23 mascot
To describe the conference venue, it happened in InfoPark, Kochi with the main conference hall being Athulya Hall and food, accommodation and two smaller halls in Four Point Hotel, right outside Infopark. We got Athulya Hall as part of venue sponsorship from Infopark. The distance between both of them was around 300 meters. Halls were named Anamudi, Kuthiran and Ponmudi based on hills and mountain areas in host state of Kerala. Other than Annamudi hall which was the main hall, I couldn t remember the names of the hall, I still can t. Four Points was big and expensive, and we had, as expected, cost overruns. Due to how DebConf function, an Indian university wasn t suitable to host a conference of this scale. Infinity Pool at Night
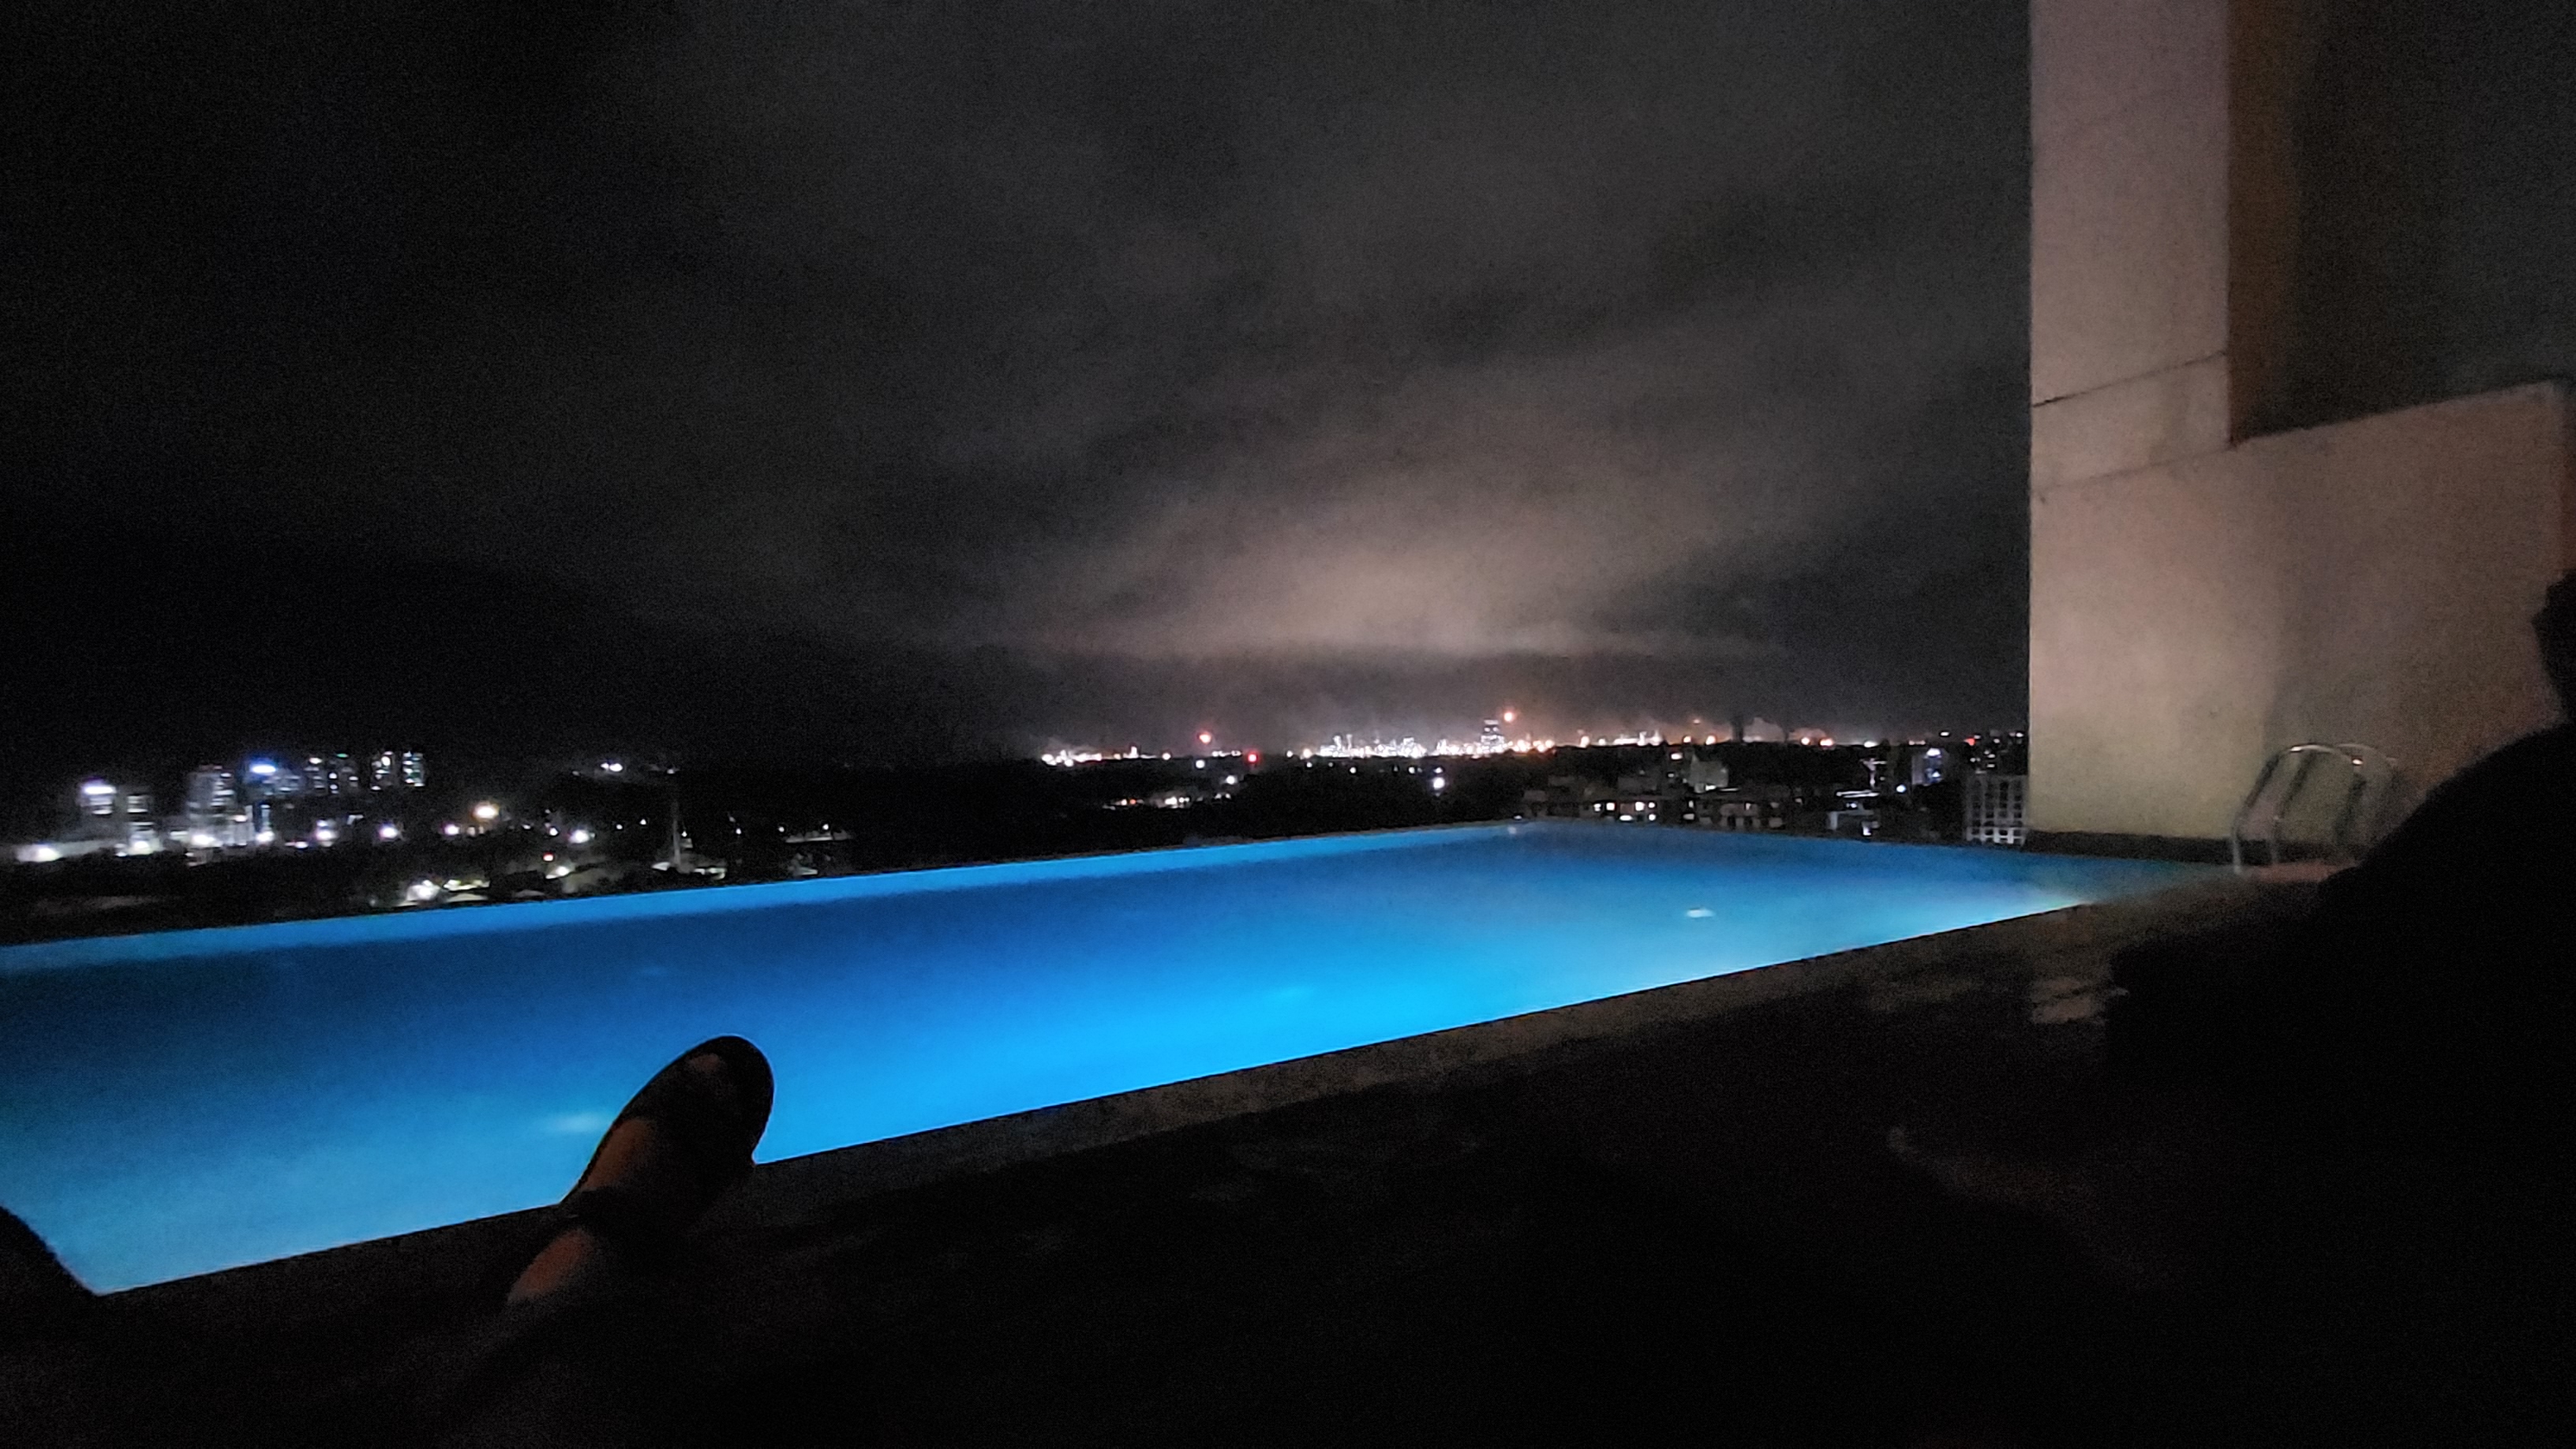
Four Point's Infinity Pool at Night
I landed in Kochi on the first day of DebCamp on 3rd September. As usual, met Abraham first, and the better part of the next hour was spent on meet and greet. It was my first IRL DebConf so met many old friends and new folks. I got a room to myself. Abraham lived nearby and hadn t taken the accommodation, so I asked him to join. He finally joined from second day onwards. All through the conference, room 928 became in-famous for various reasons, and I had various roommates for company. In DebCamp days, we would get up to have breakfast and go back to sleep and get active only past lunch for hacking and helping in the hack lab for the day, followed by fun late night discussions and parties. Nilesh, Chirag and Apple at DC23
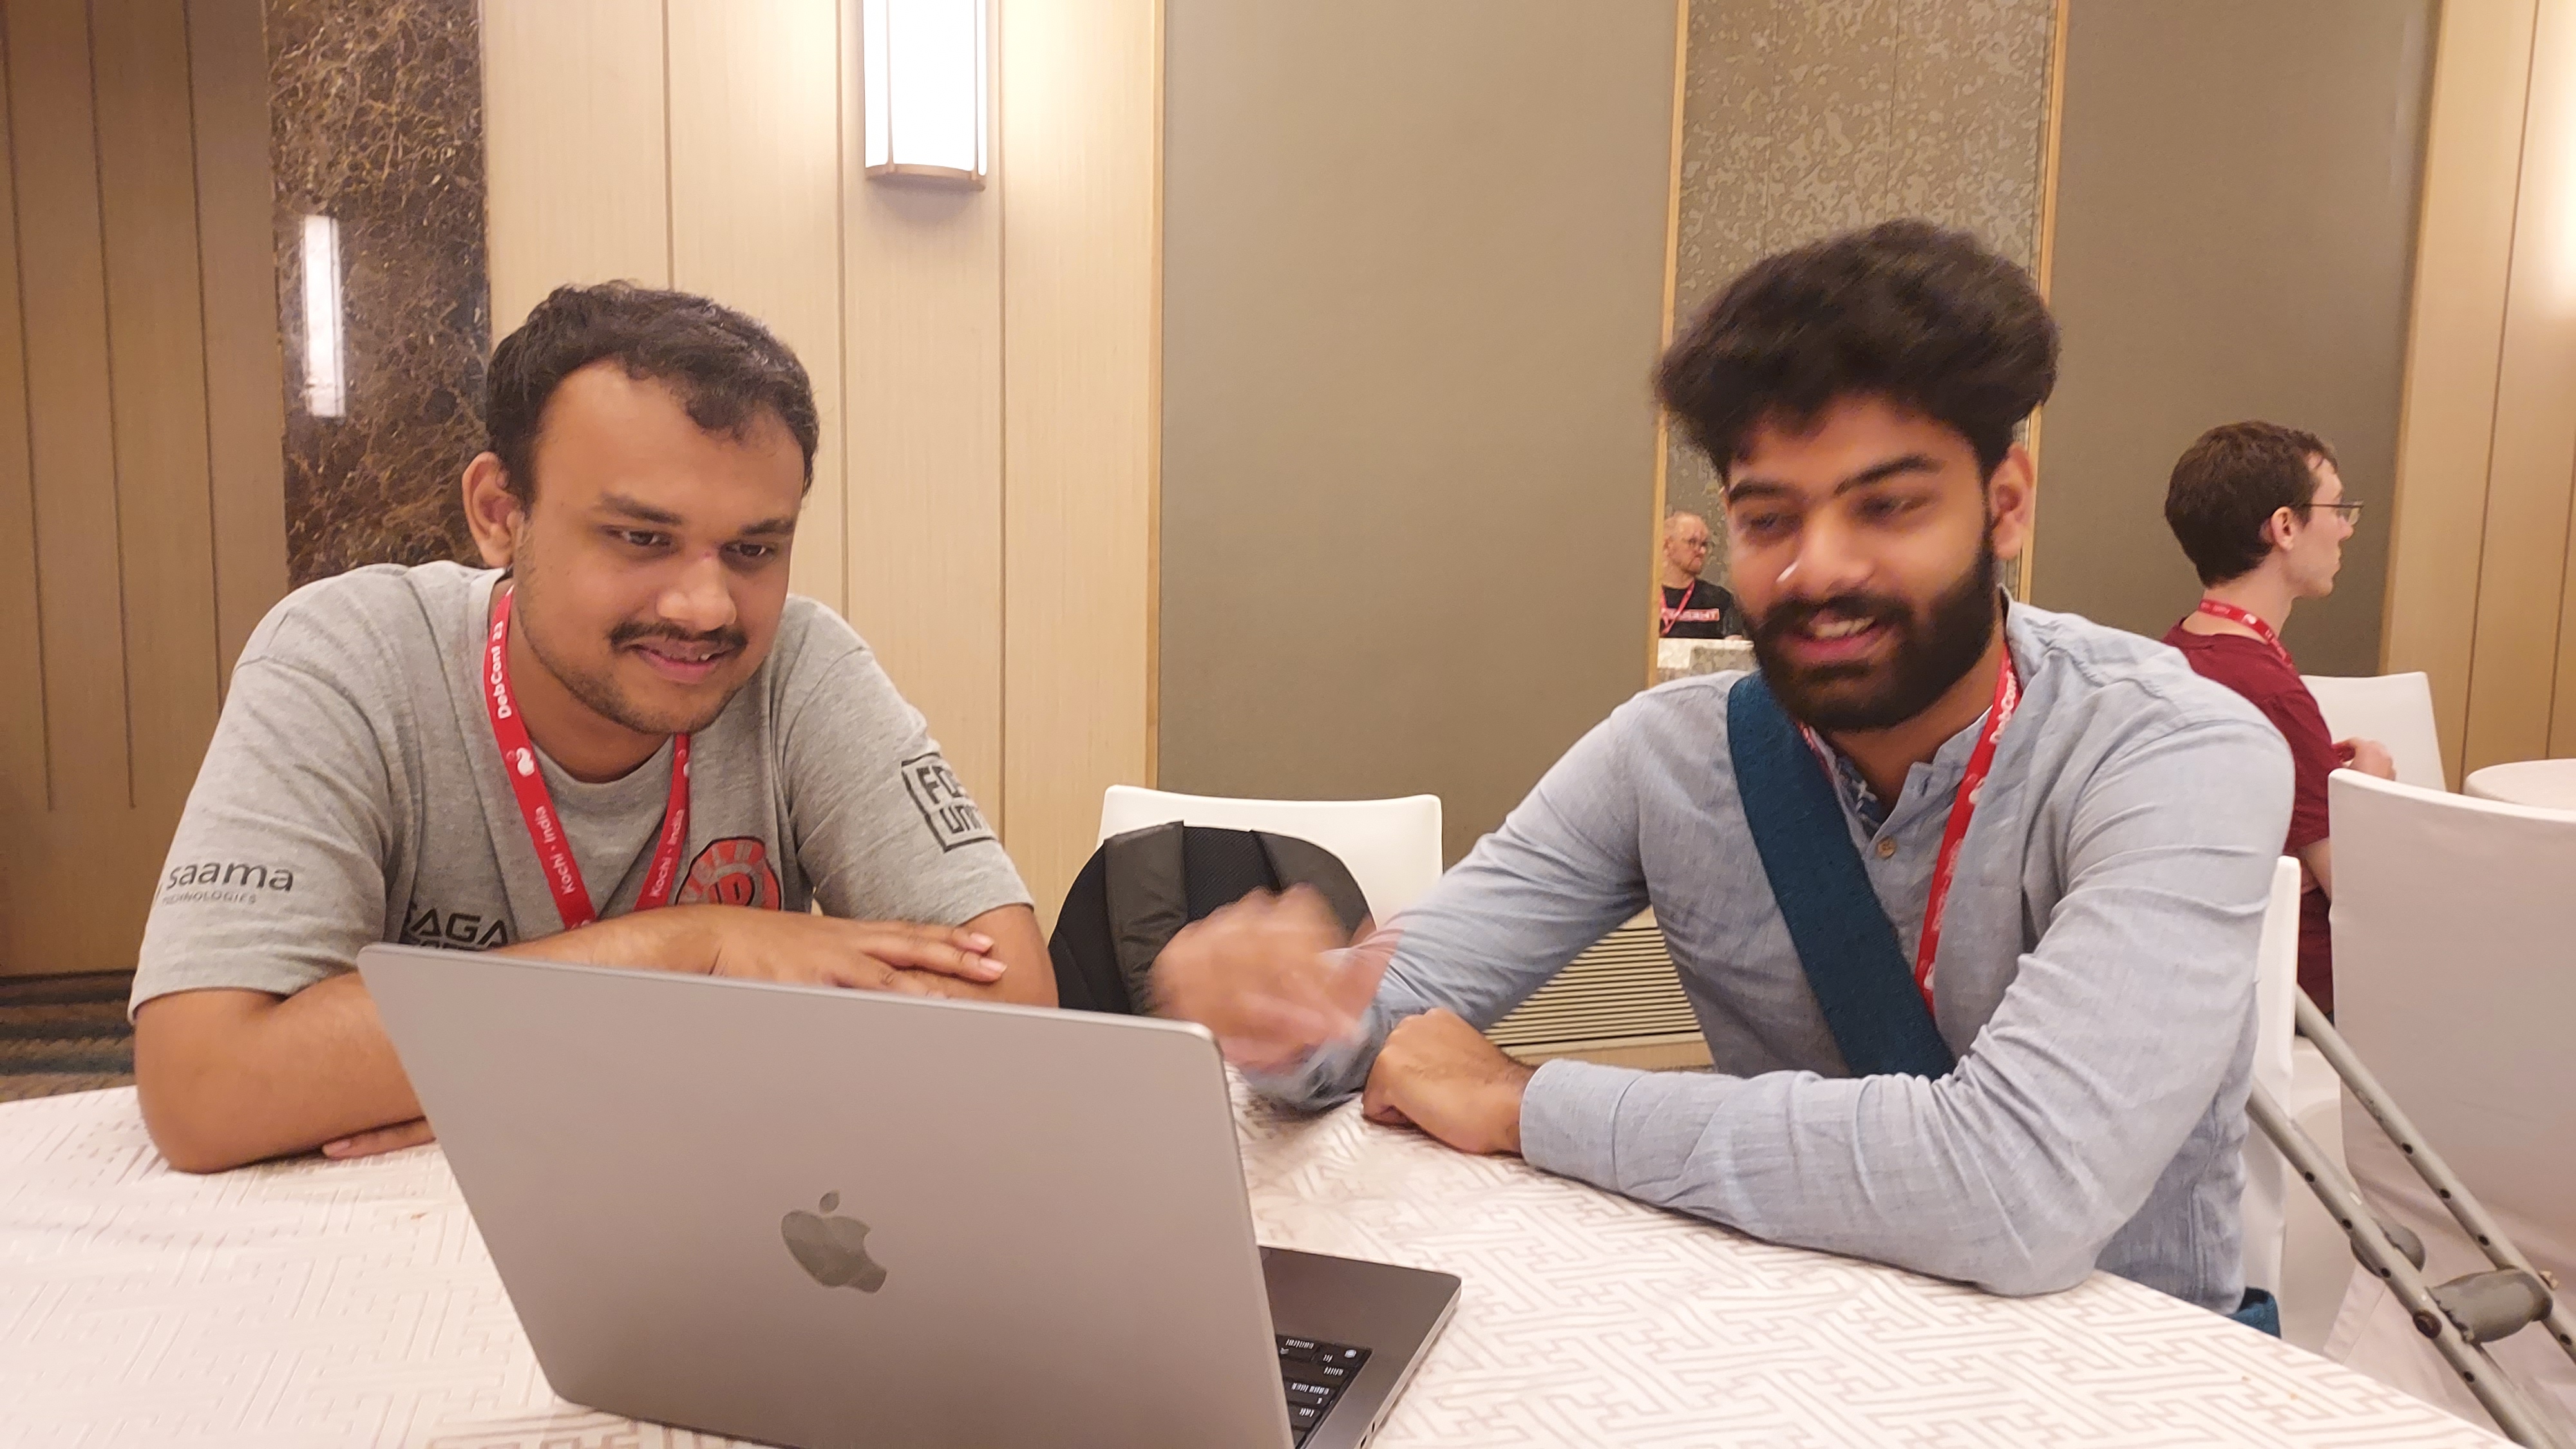
Nilesh, Chirag and Apple at DC23
The team even managed to get a press conference arranged as well, and we got an opportunity to go to Press Club, Ernakulam. Sruthi and Jonathan gave the speech and answered questions from journalists. The event was covered by media as well due to this. Ernakulam Press Club
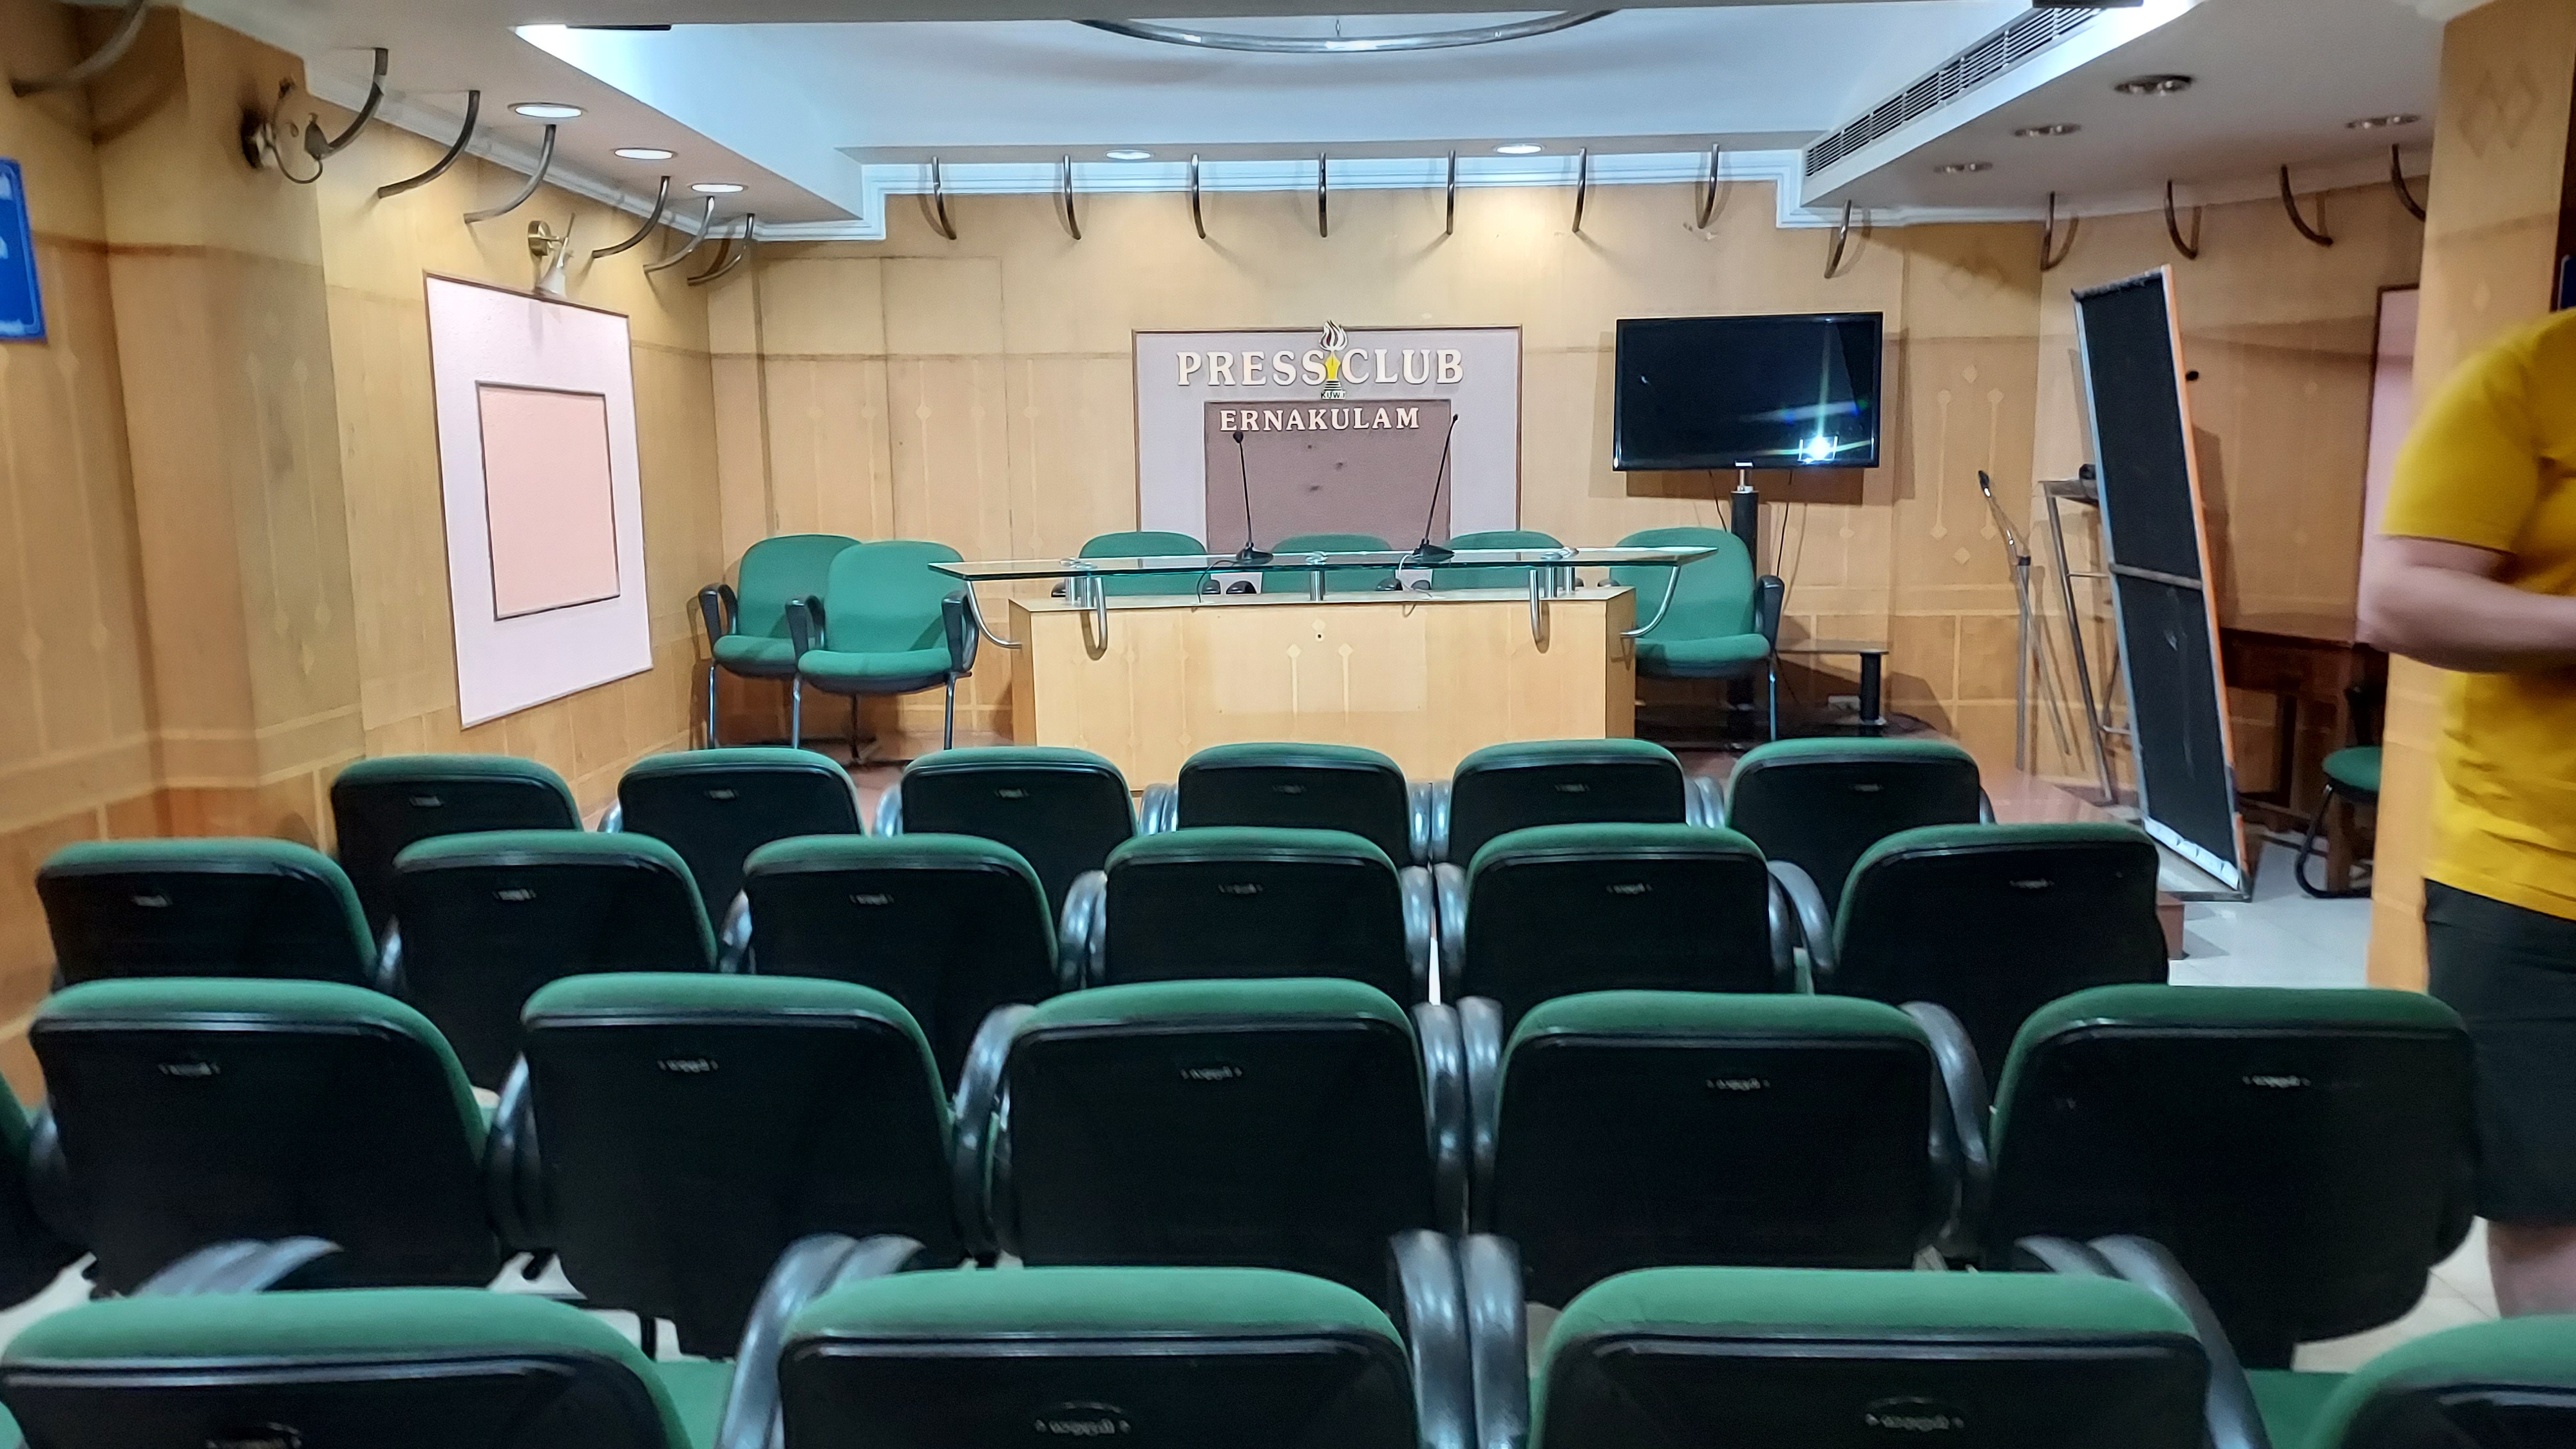
Ernakulam Press Club
During the conference, every night the team use to have 9 PM meetings for retrospection and planning for next day, which was always dotted with new problems. Every day, we used to hijack Silent Hacklab for the meeting and gently ask the only people there at the time to give us space. DebConf, it itself is a well oiled machine. Network was brought up from scratch. Video team built the recording, audio mixing, live-streaming, editing and transcoding infrastructure on site. A gaming rig served as router and gateway. We got internet uplinks, a 1 Gbps sponsored leased line from Kerala Vision and a paid backup 100 Mbps connection from a different provider. IPv6 was added through HE s Tunnelbroker. Overall the network worked fine as additionally we had hotel Wi-Fi, so the conference network wasn t stretched much. I must highlight, DebConf is my only conference where almost everything and every piece of software in developed in-house, for the conference and modified according to need on the fly. Even event recording cameras, audio check, direction, recording and editing is all done on in-house software by volunteer-attendees (in some cases remote ones as well), all trained on the sideline of the conference. The core recording and mixing equipment is owned by Debian and travels to each venue. The rest is sourced locally. Gaming Rig which served as DC23 gateway router
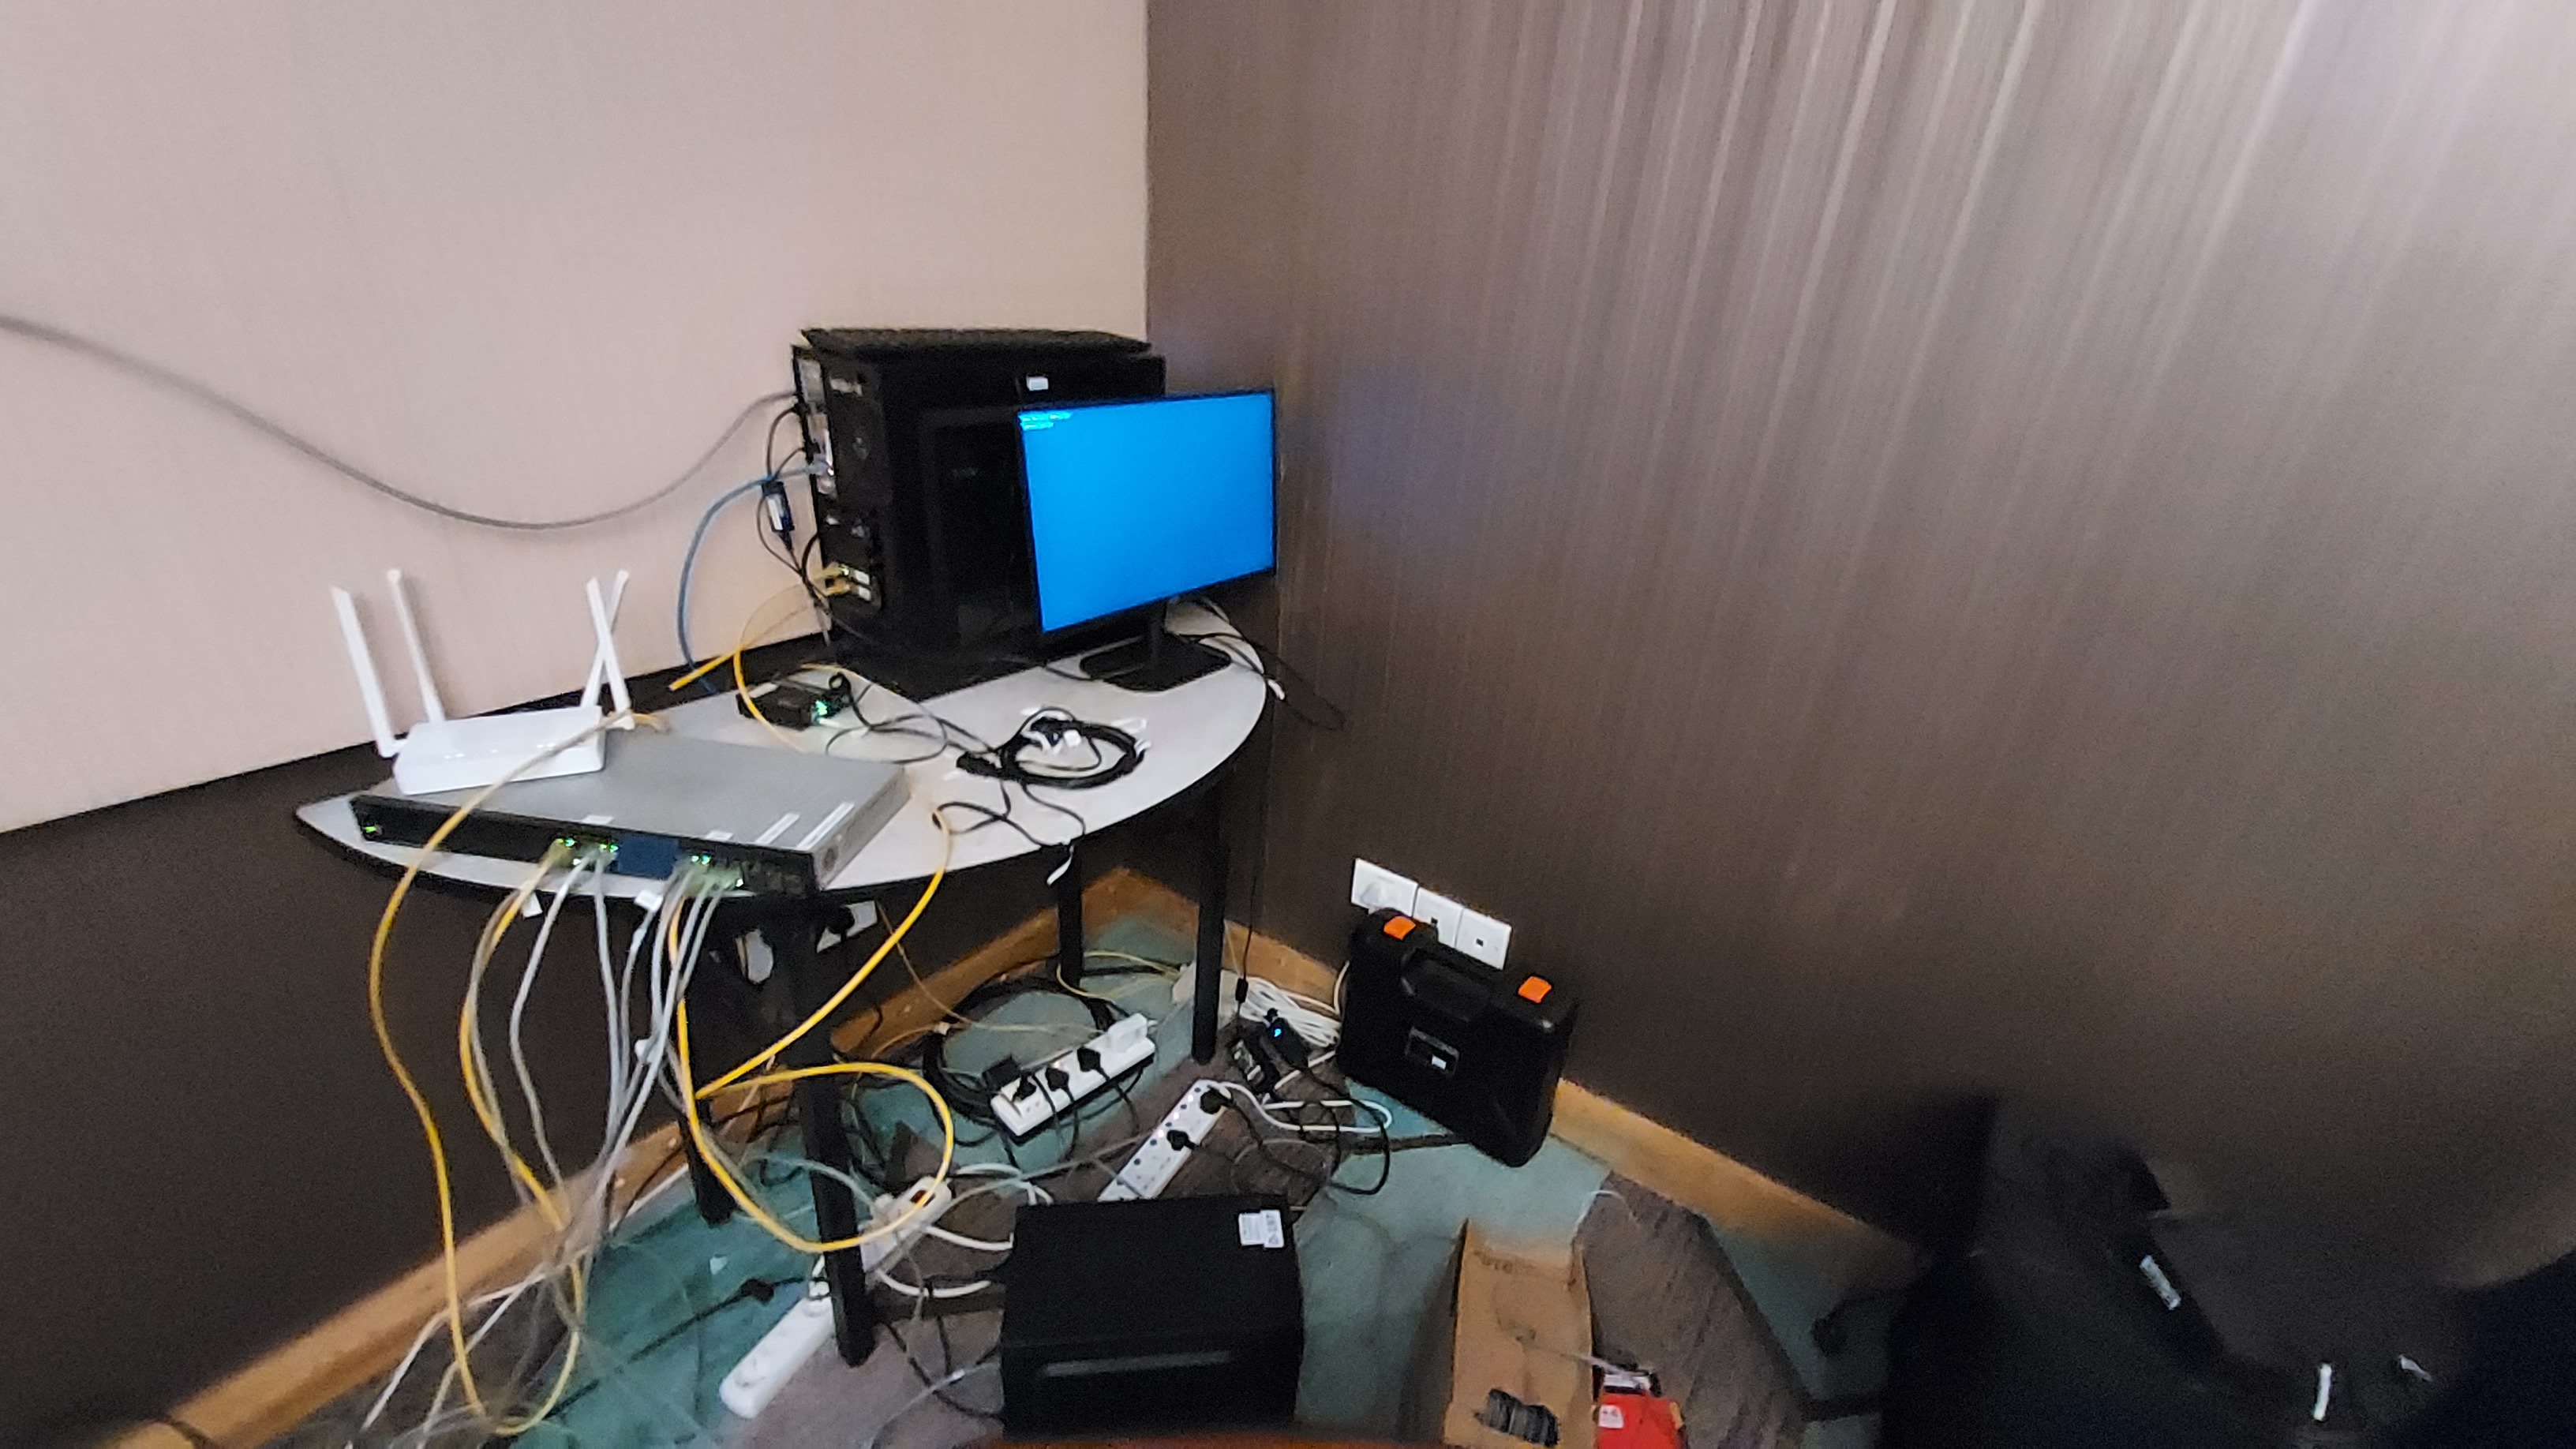
Gaming Rig which served as DC23 gateway router
It was fun seeing how almost all the things were coordinated over text on Internet Relay Chat (IRC). If a talk/event was missing a talkmeister or a director or a camera person, a quick text on #debconf channel would be enough for someone to volunteer. Video team had a dedicated support channel for each conference venue for any issues and were quick to respond and fix stuff. Network information. Screengrab from closing ceremony
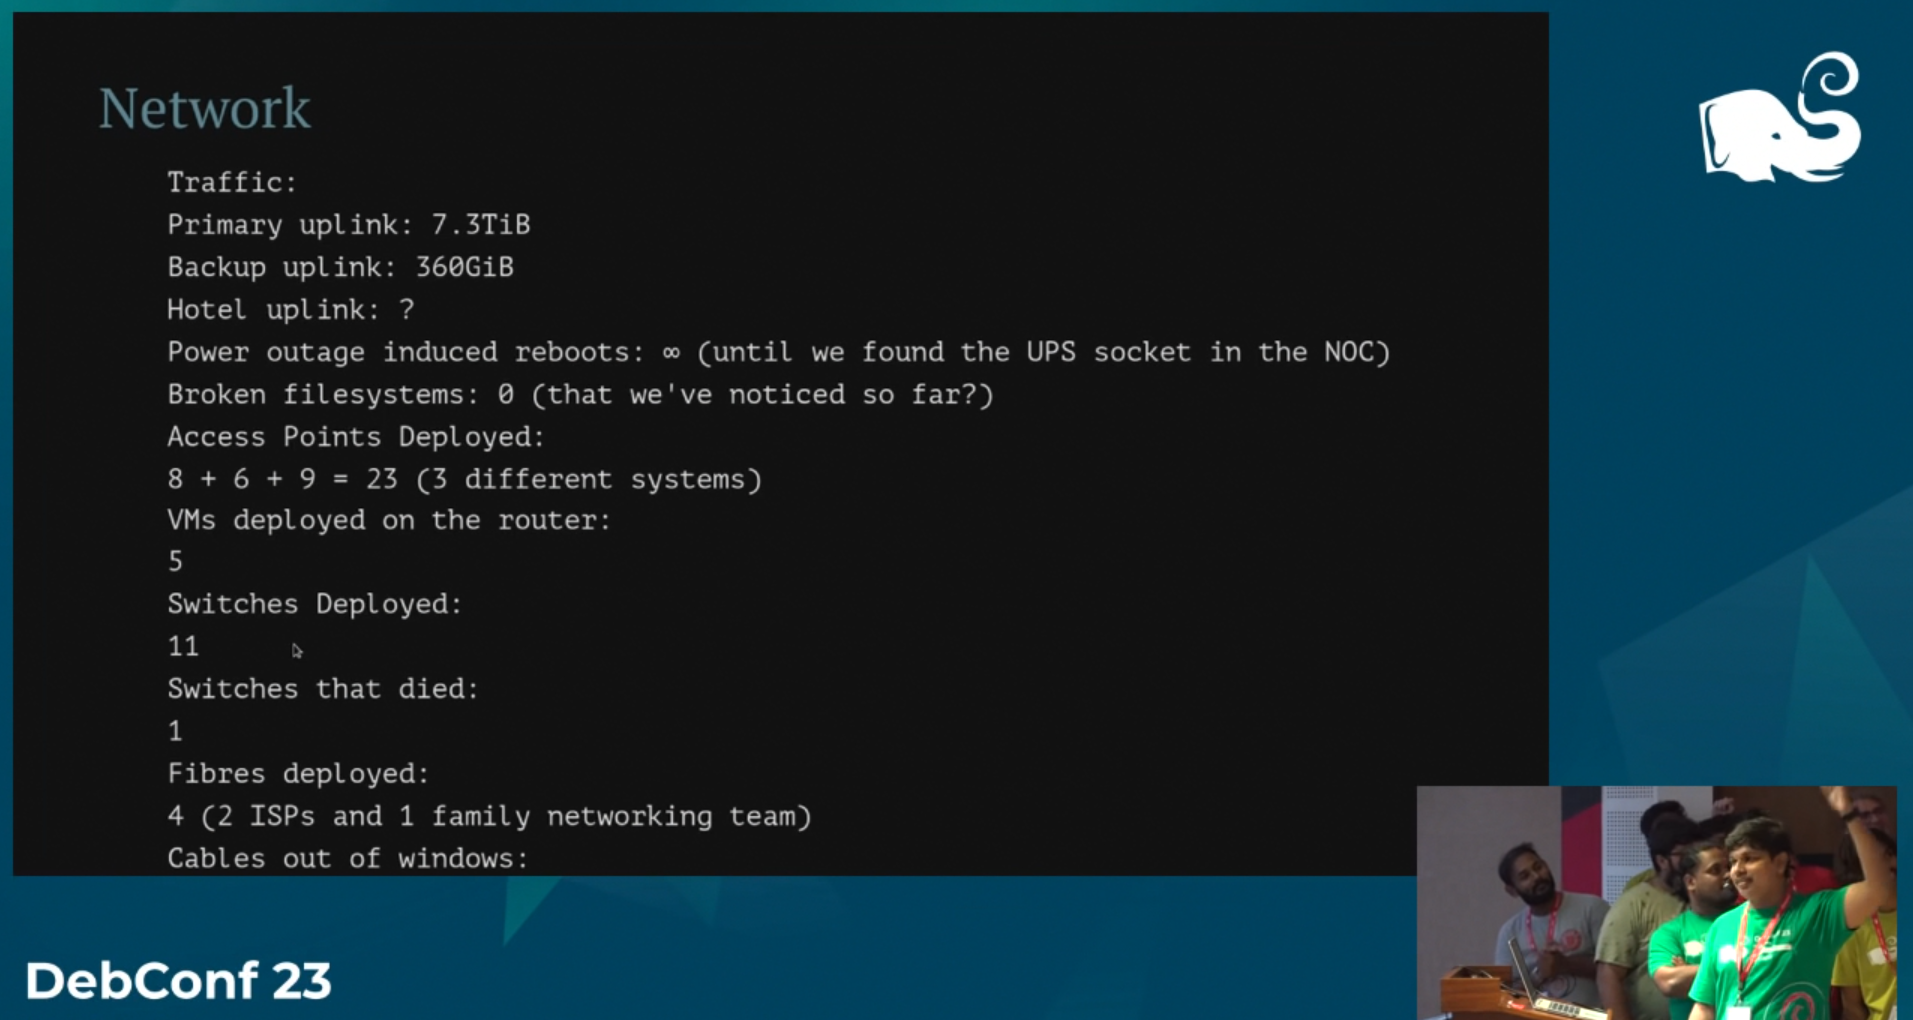
Network information. Screengrab from closing ceremony
It rained for the initial days, which gave us a cool weather. Swag team had decided to hand out umbrellas in swag kit which turned out to be quite useful. The swag kit was praised for quality and selection - many thanks to Anupa, Sruthi and others. It was fun wearing different color T-shirts, all designed by Abraham. Red for volunteers, light green for Video team, green for core-team i.e. staff and yellow for conference attendees. With highvoltage
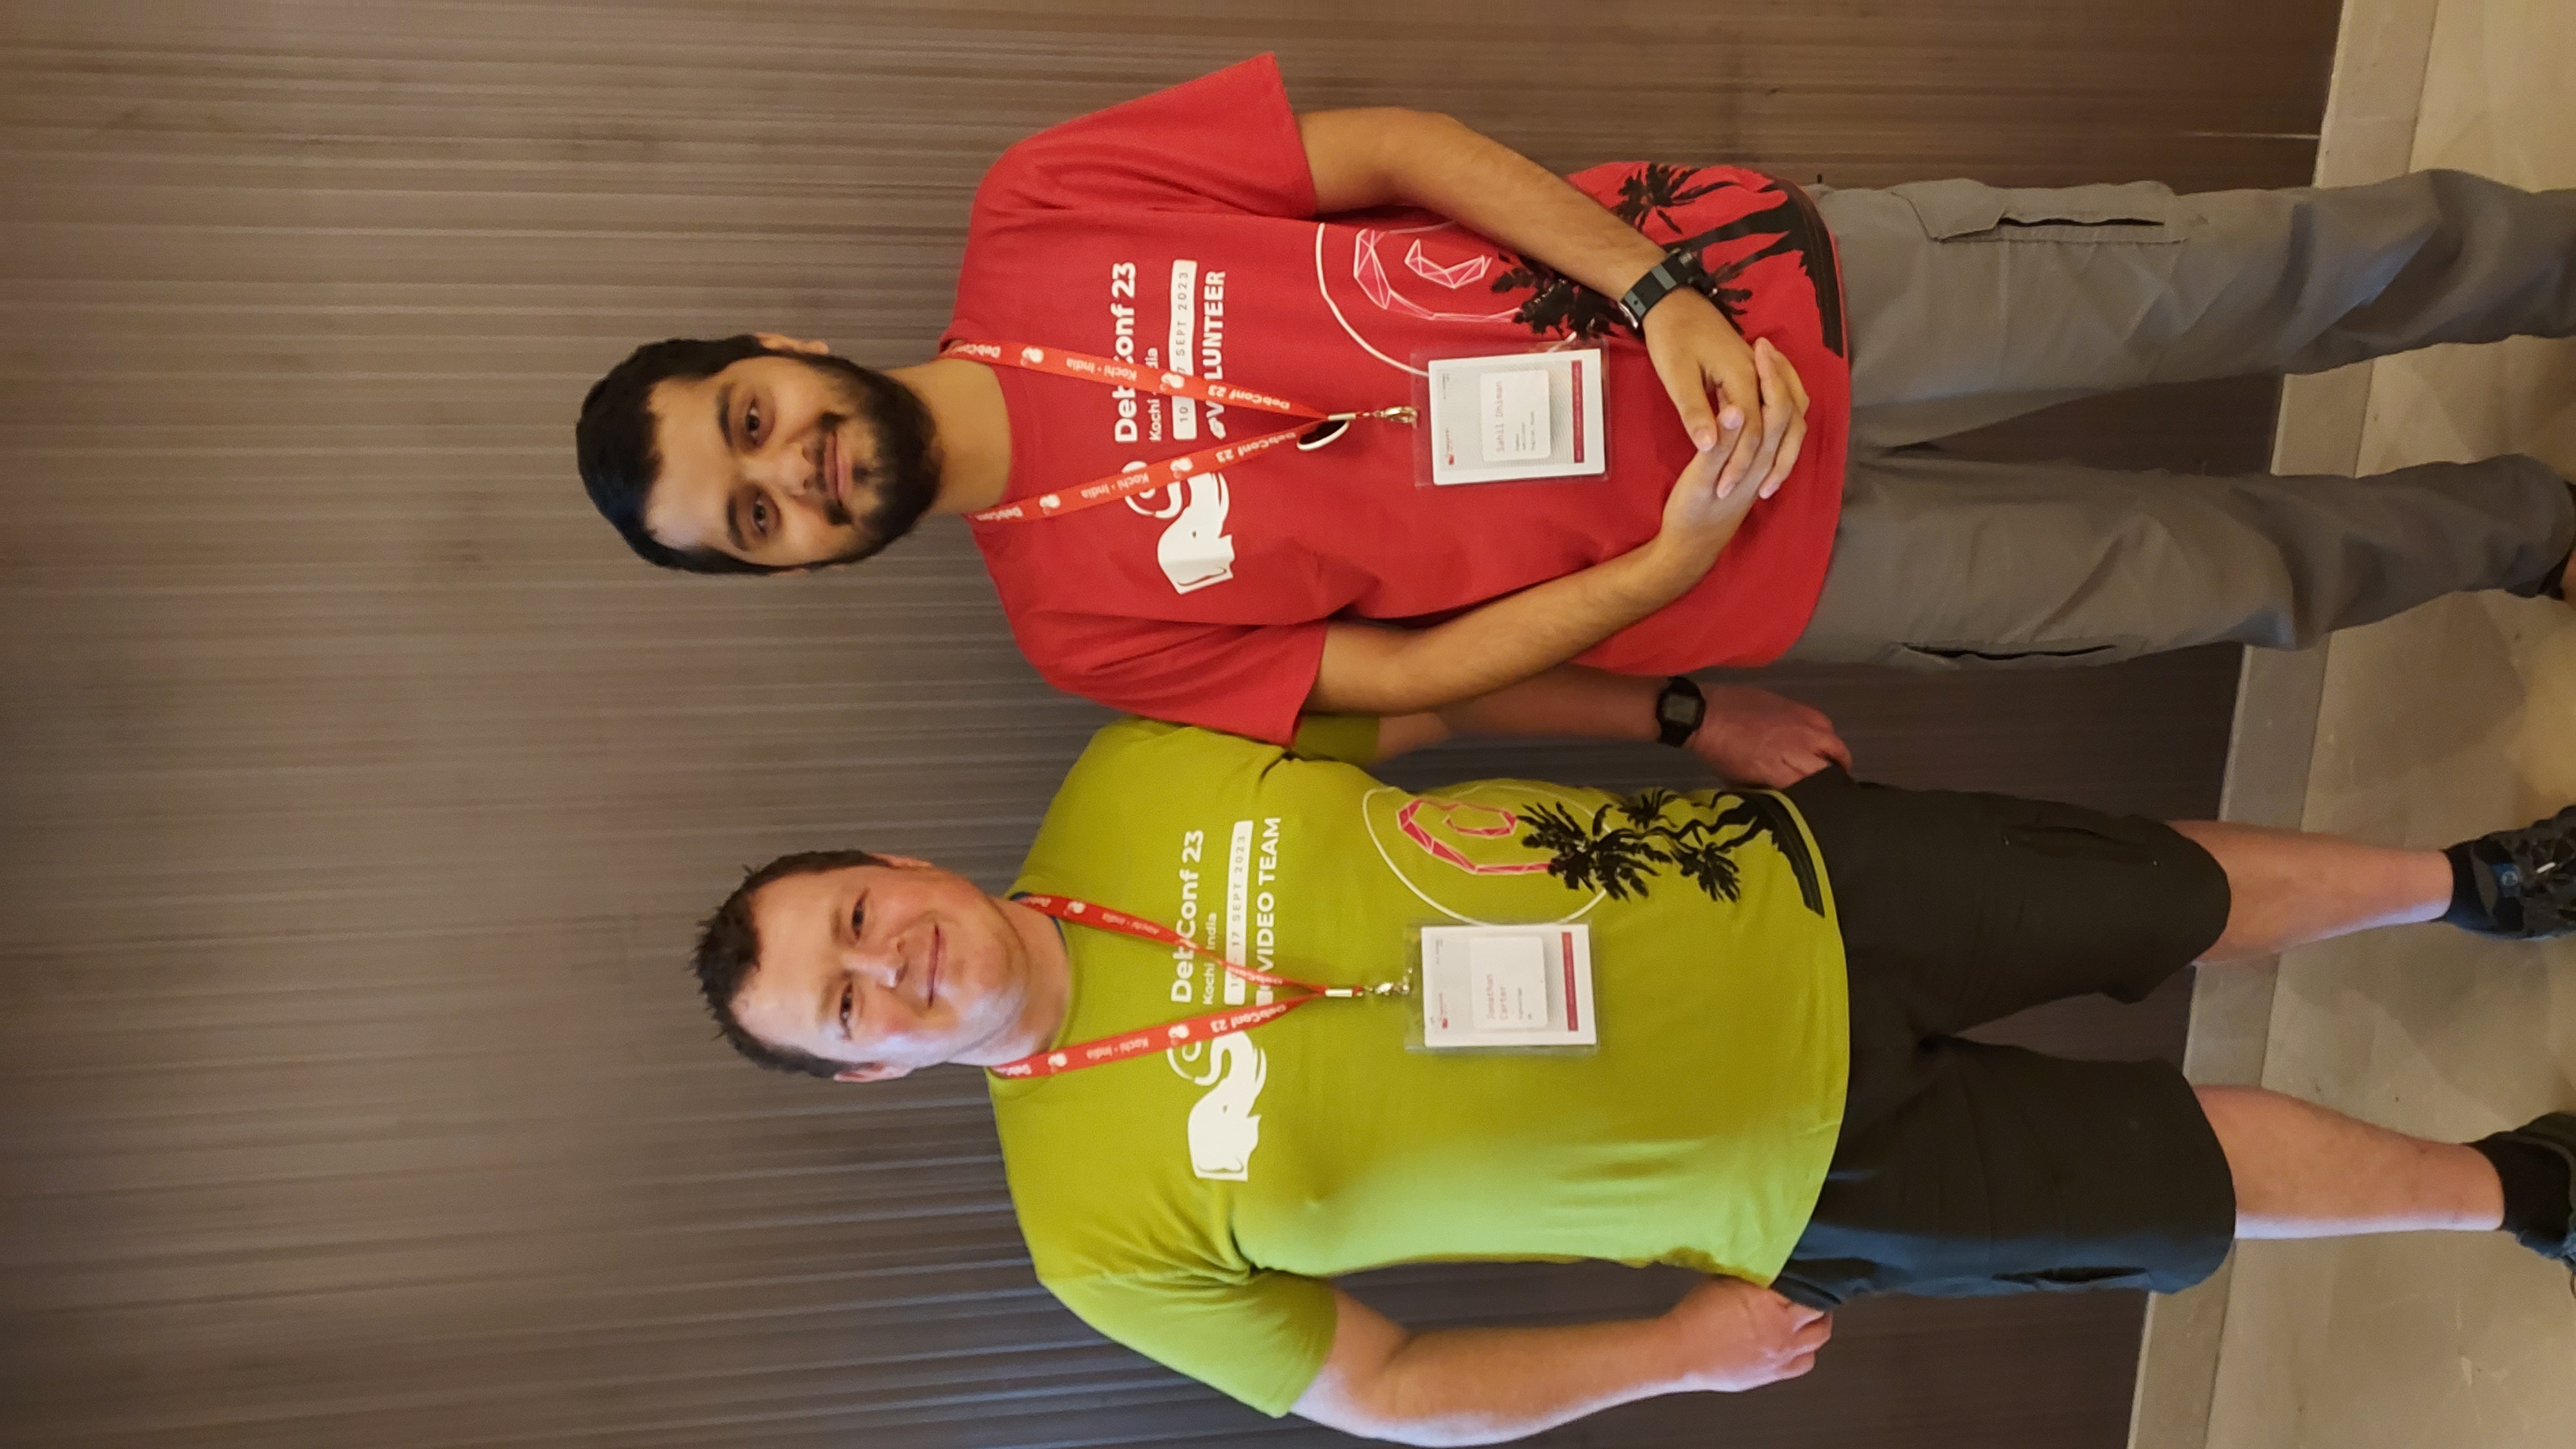
With highvoltage
We were already acclimatized by the time DebConf really started as we had been talking, hacking and hanging out since last 7 days. Rush really started with the start of DebConf. More people joined on the first and second day of the conference. As has been the tradition, an opening talk was prepared by the Sruthi and local team (which I highly recommend watching to get more insights of the process). DebConf day 1 also saw job fair, where Canonical and FOSSEE, IIT Bombay had stalls for community interactions, which judging by the crowd itself turned out to be quite a hit. For me, association with DebConf (and Debian) started due to volunteering with video team, so anyhow I was going to continue doing that this conference as well. I usually volunteer for talks/events which anyhow I m interested in. Handling the camera, talkmeister-ing and direction are fun activities, though I didn t do sound this time around. Sound seemed difficult, and I didn t want to spoil someone s stream and recording. Talk attendance varied a lot, like in Bits from DPL talk, the hall was full but for some there were barely enough people to handle the volunteering tasks, but that s what usually happens. DebConf is more of a place to come together and collaborate, so talk attendance is an afterthought sometimes. Audience in highvoltage's Bits from DPL talk
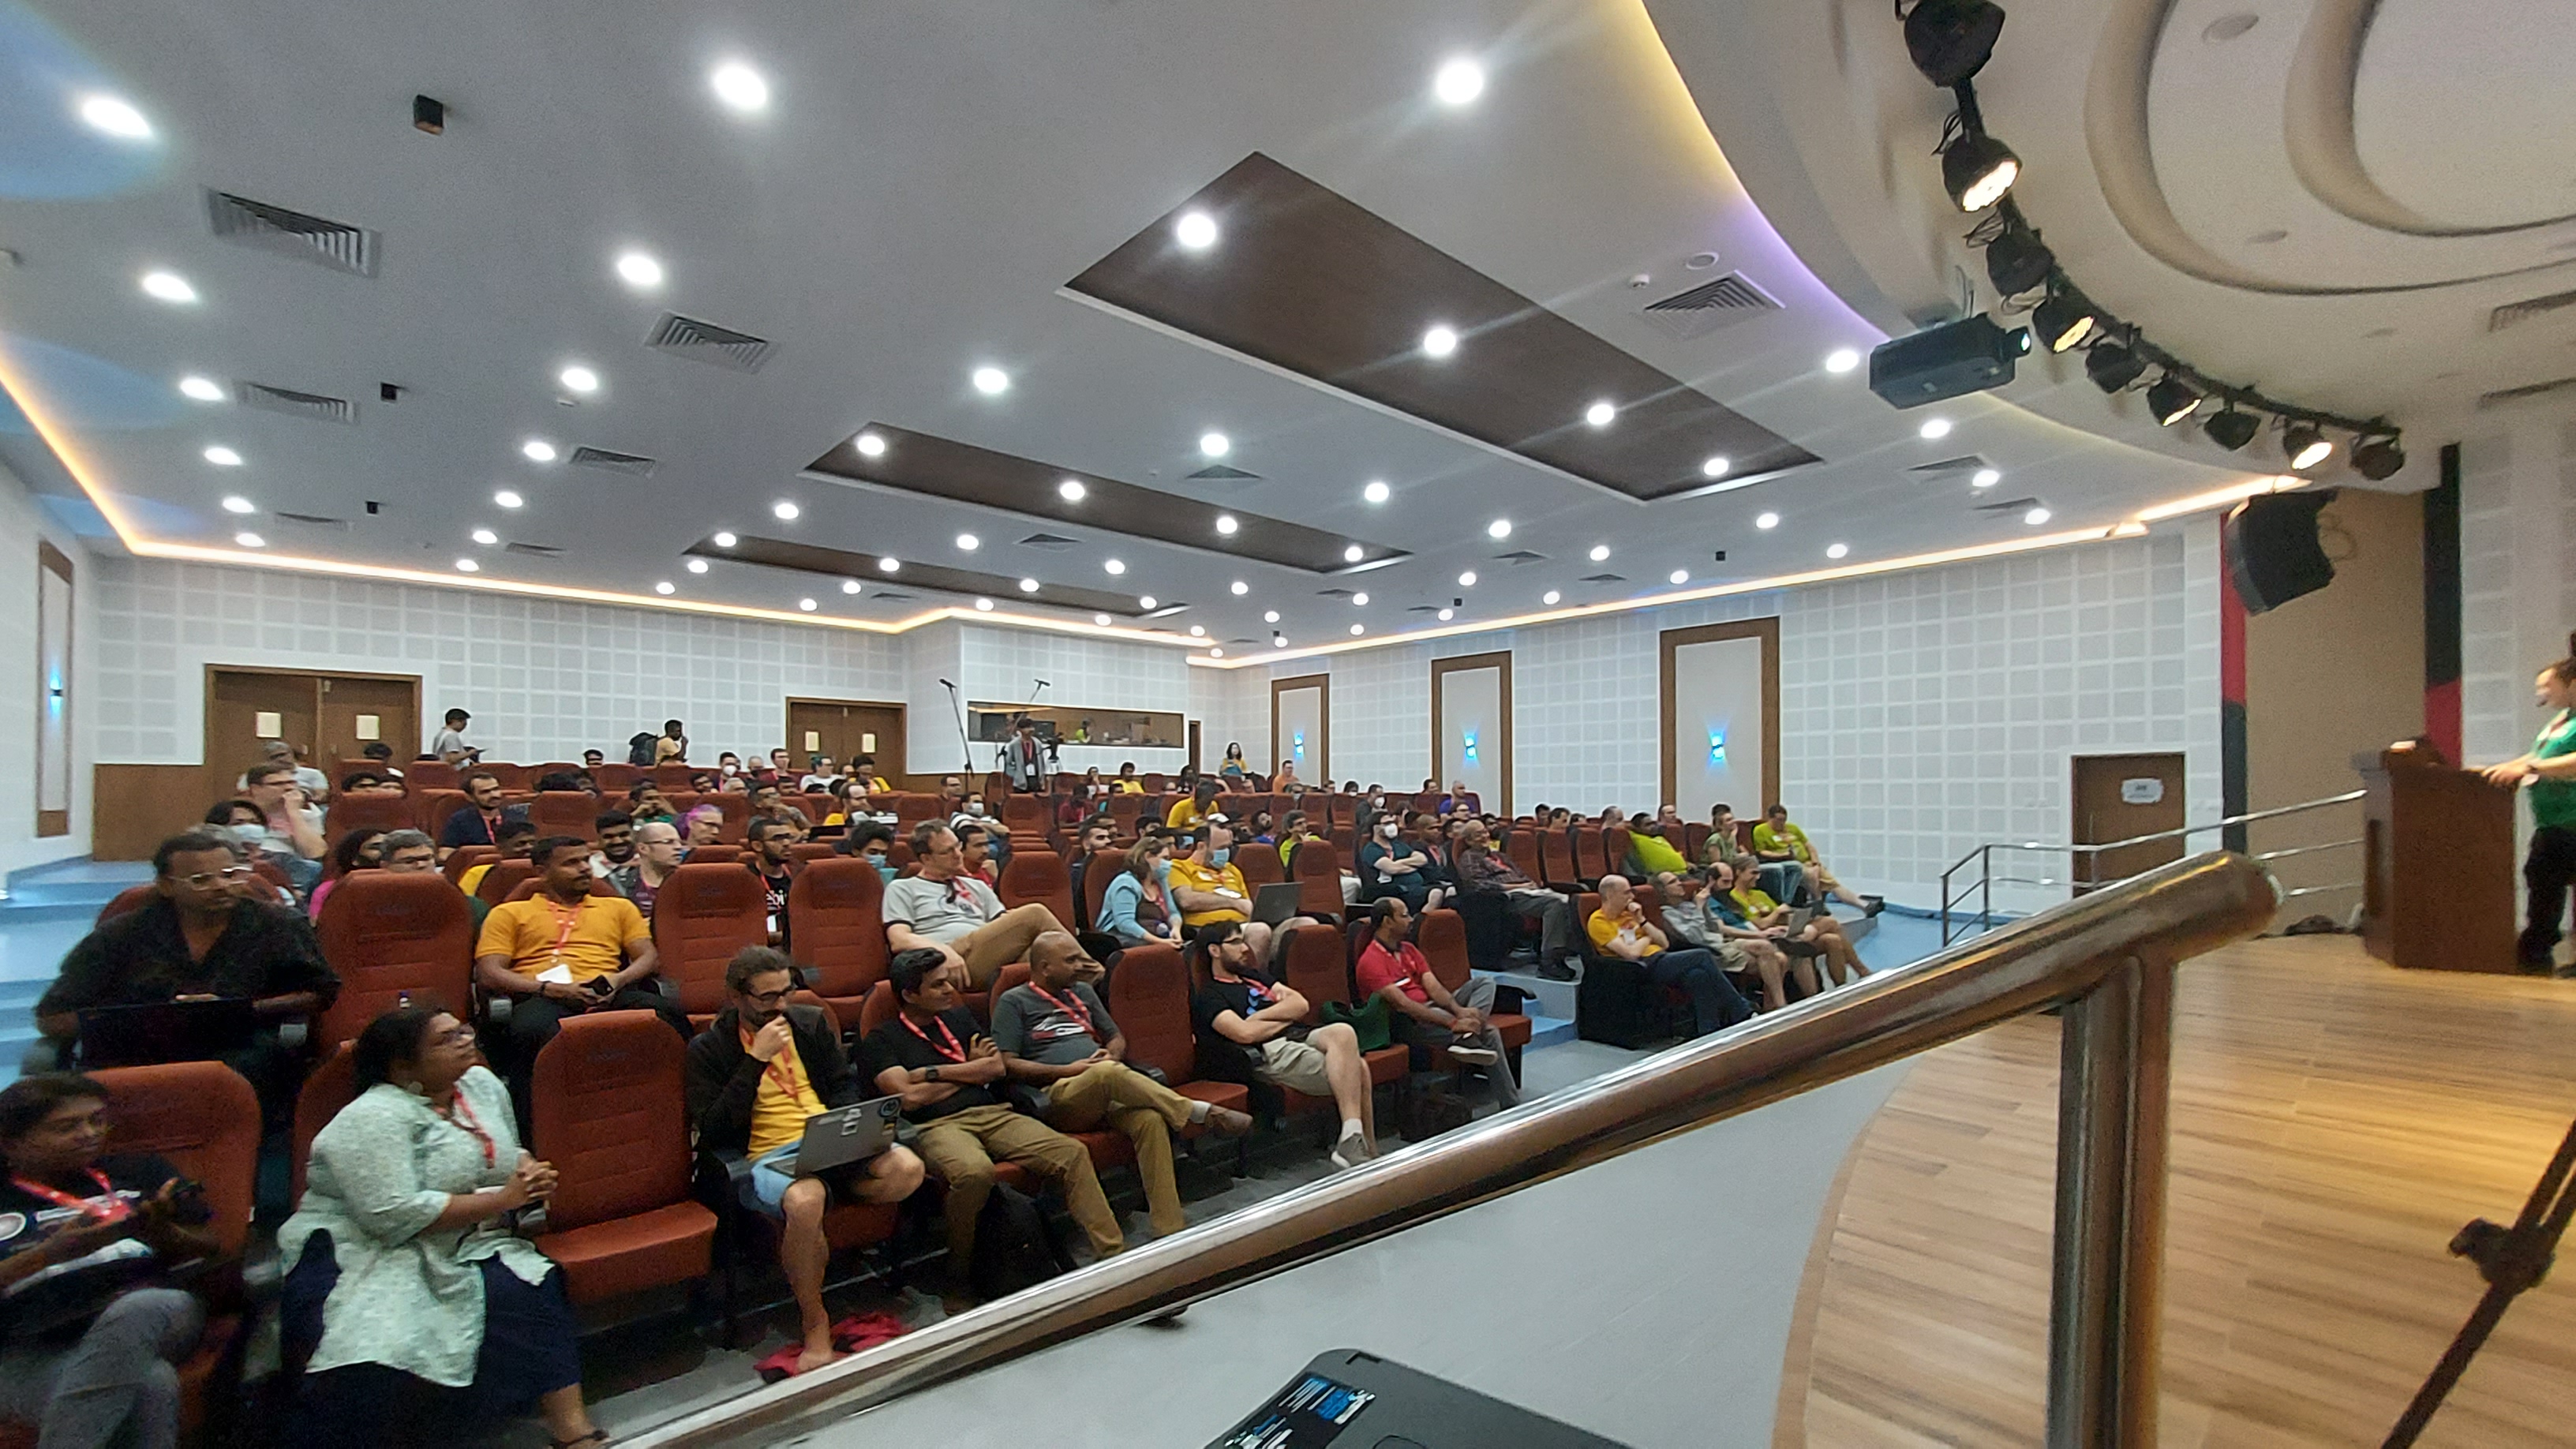
Audience in highvoltage's Bits from DPL talk
I didn t submit any talk proposals this time around, as just being in the orga team was too much work already, and I knew, the talk preparation would get delayed to the last moment and I would have to rush through it. Enrico's talk
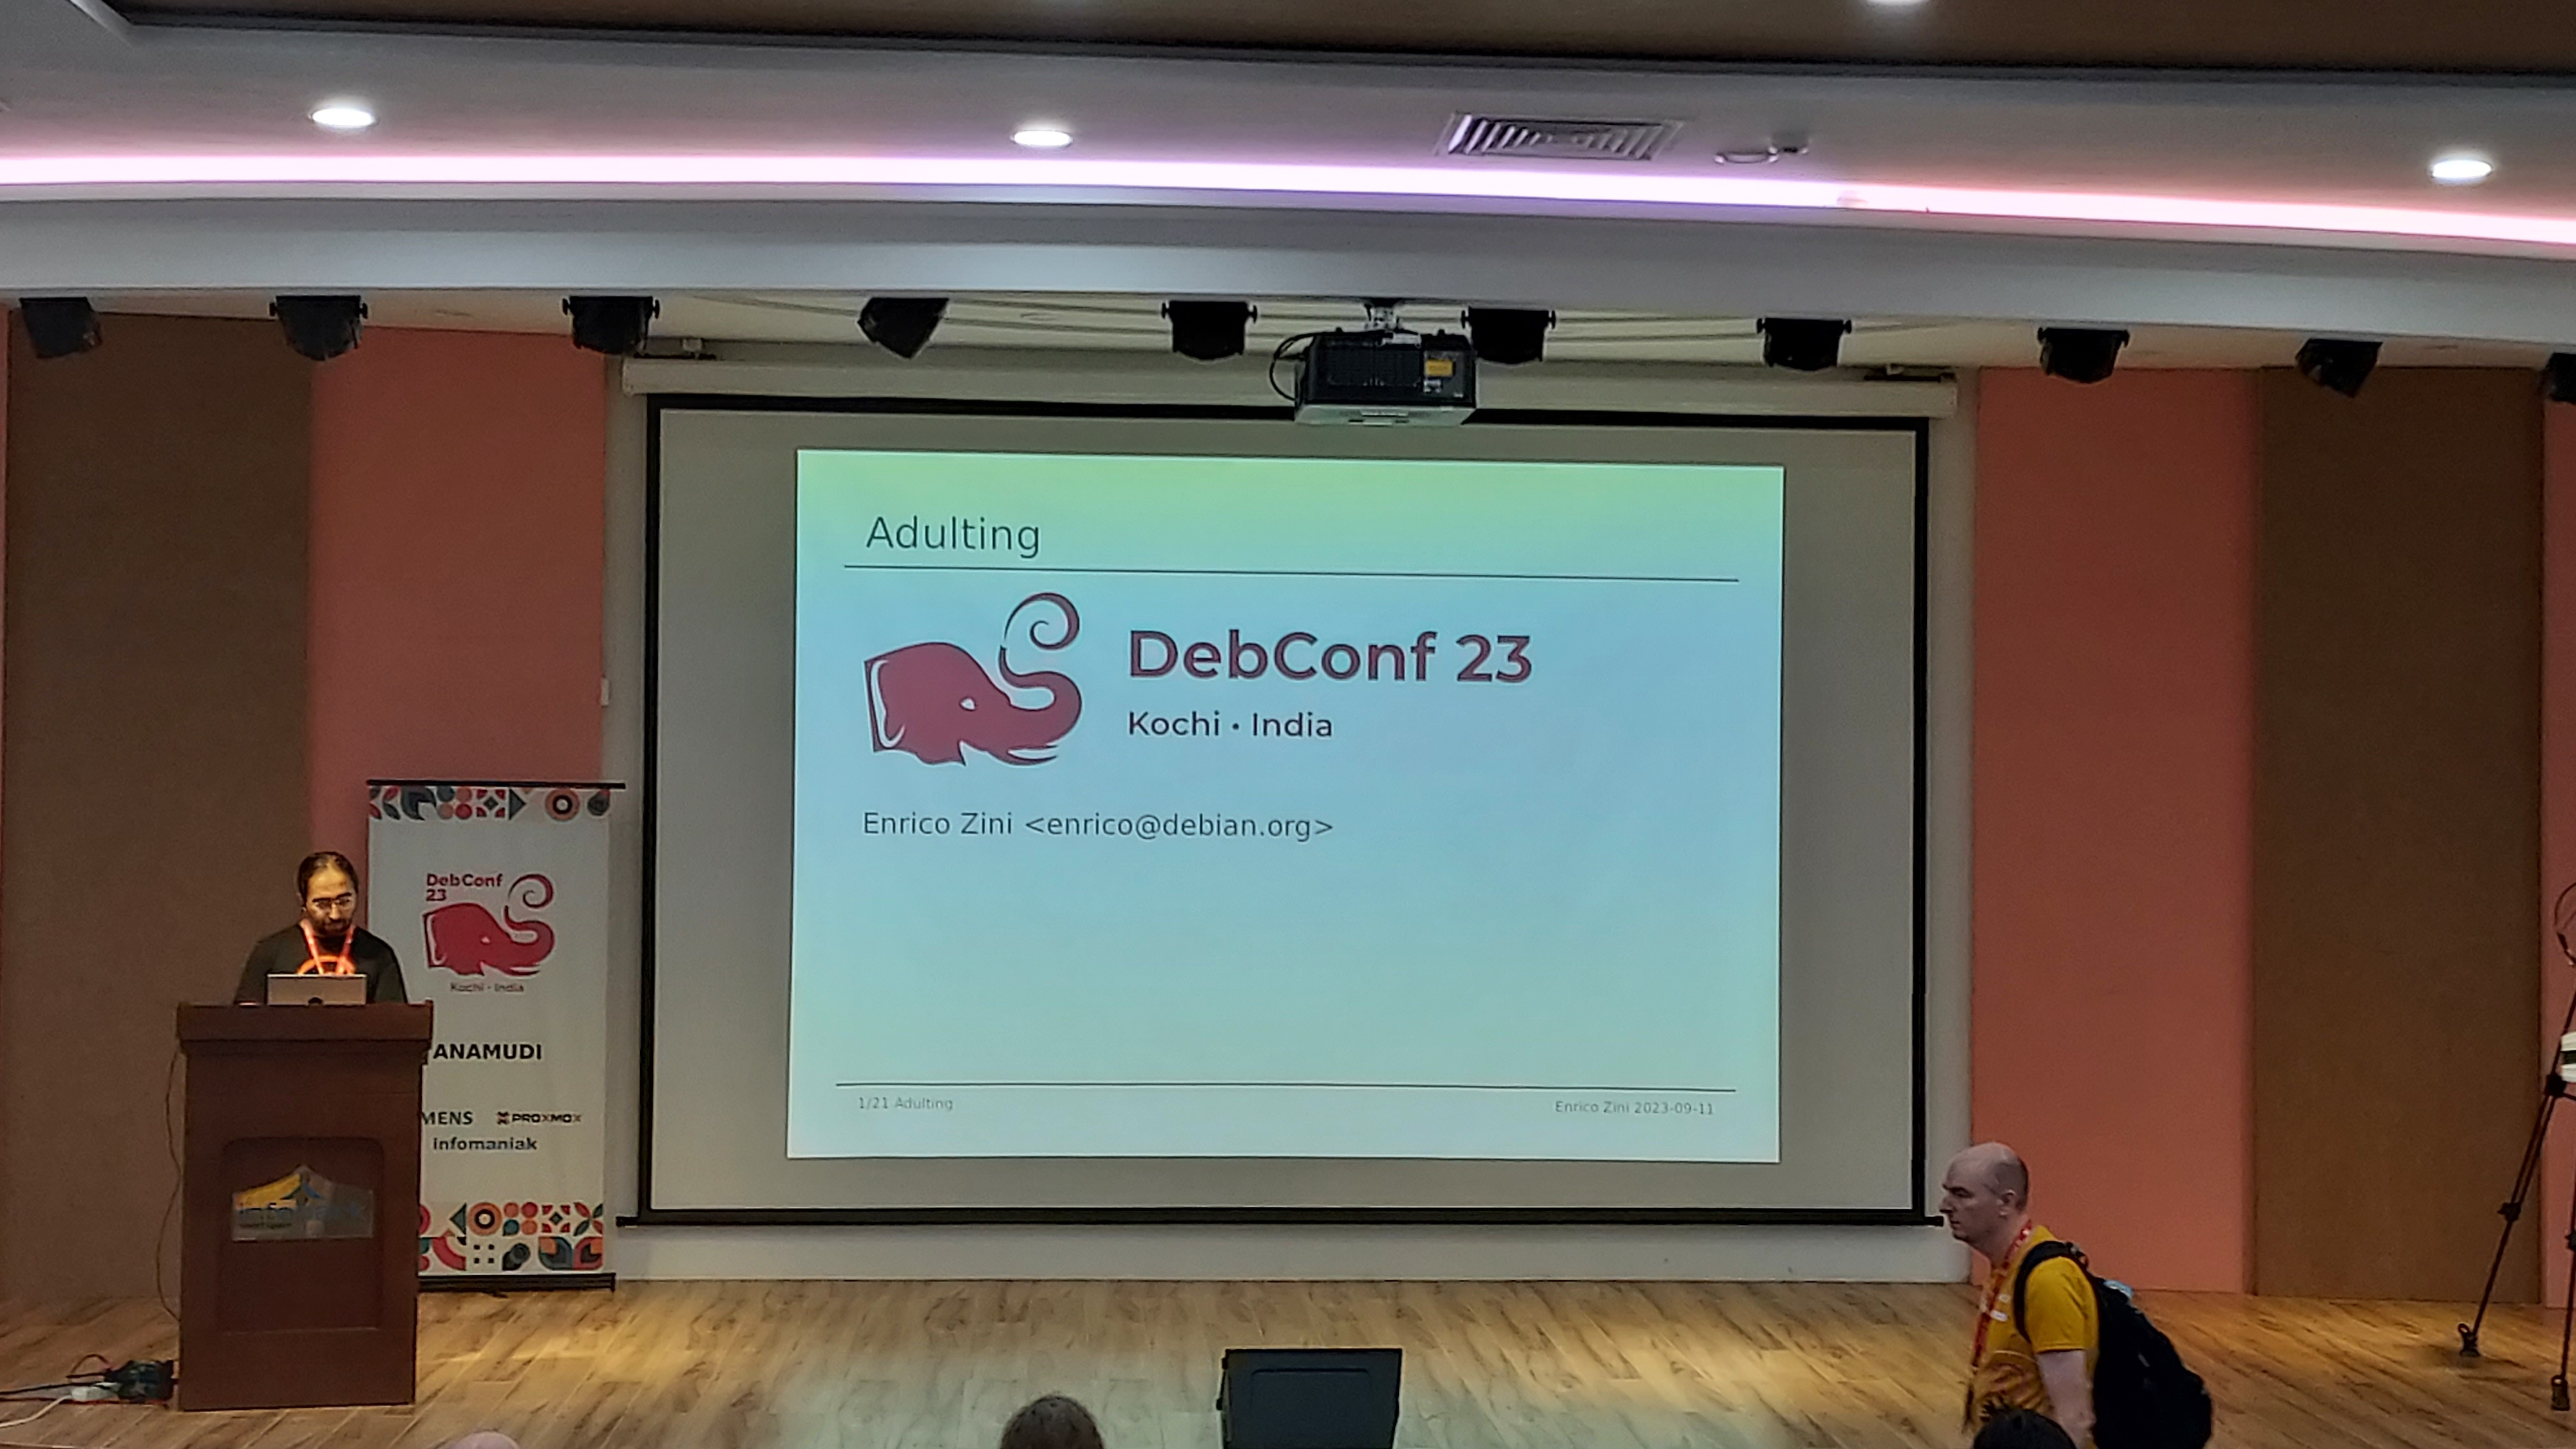
Enrico's talk
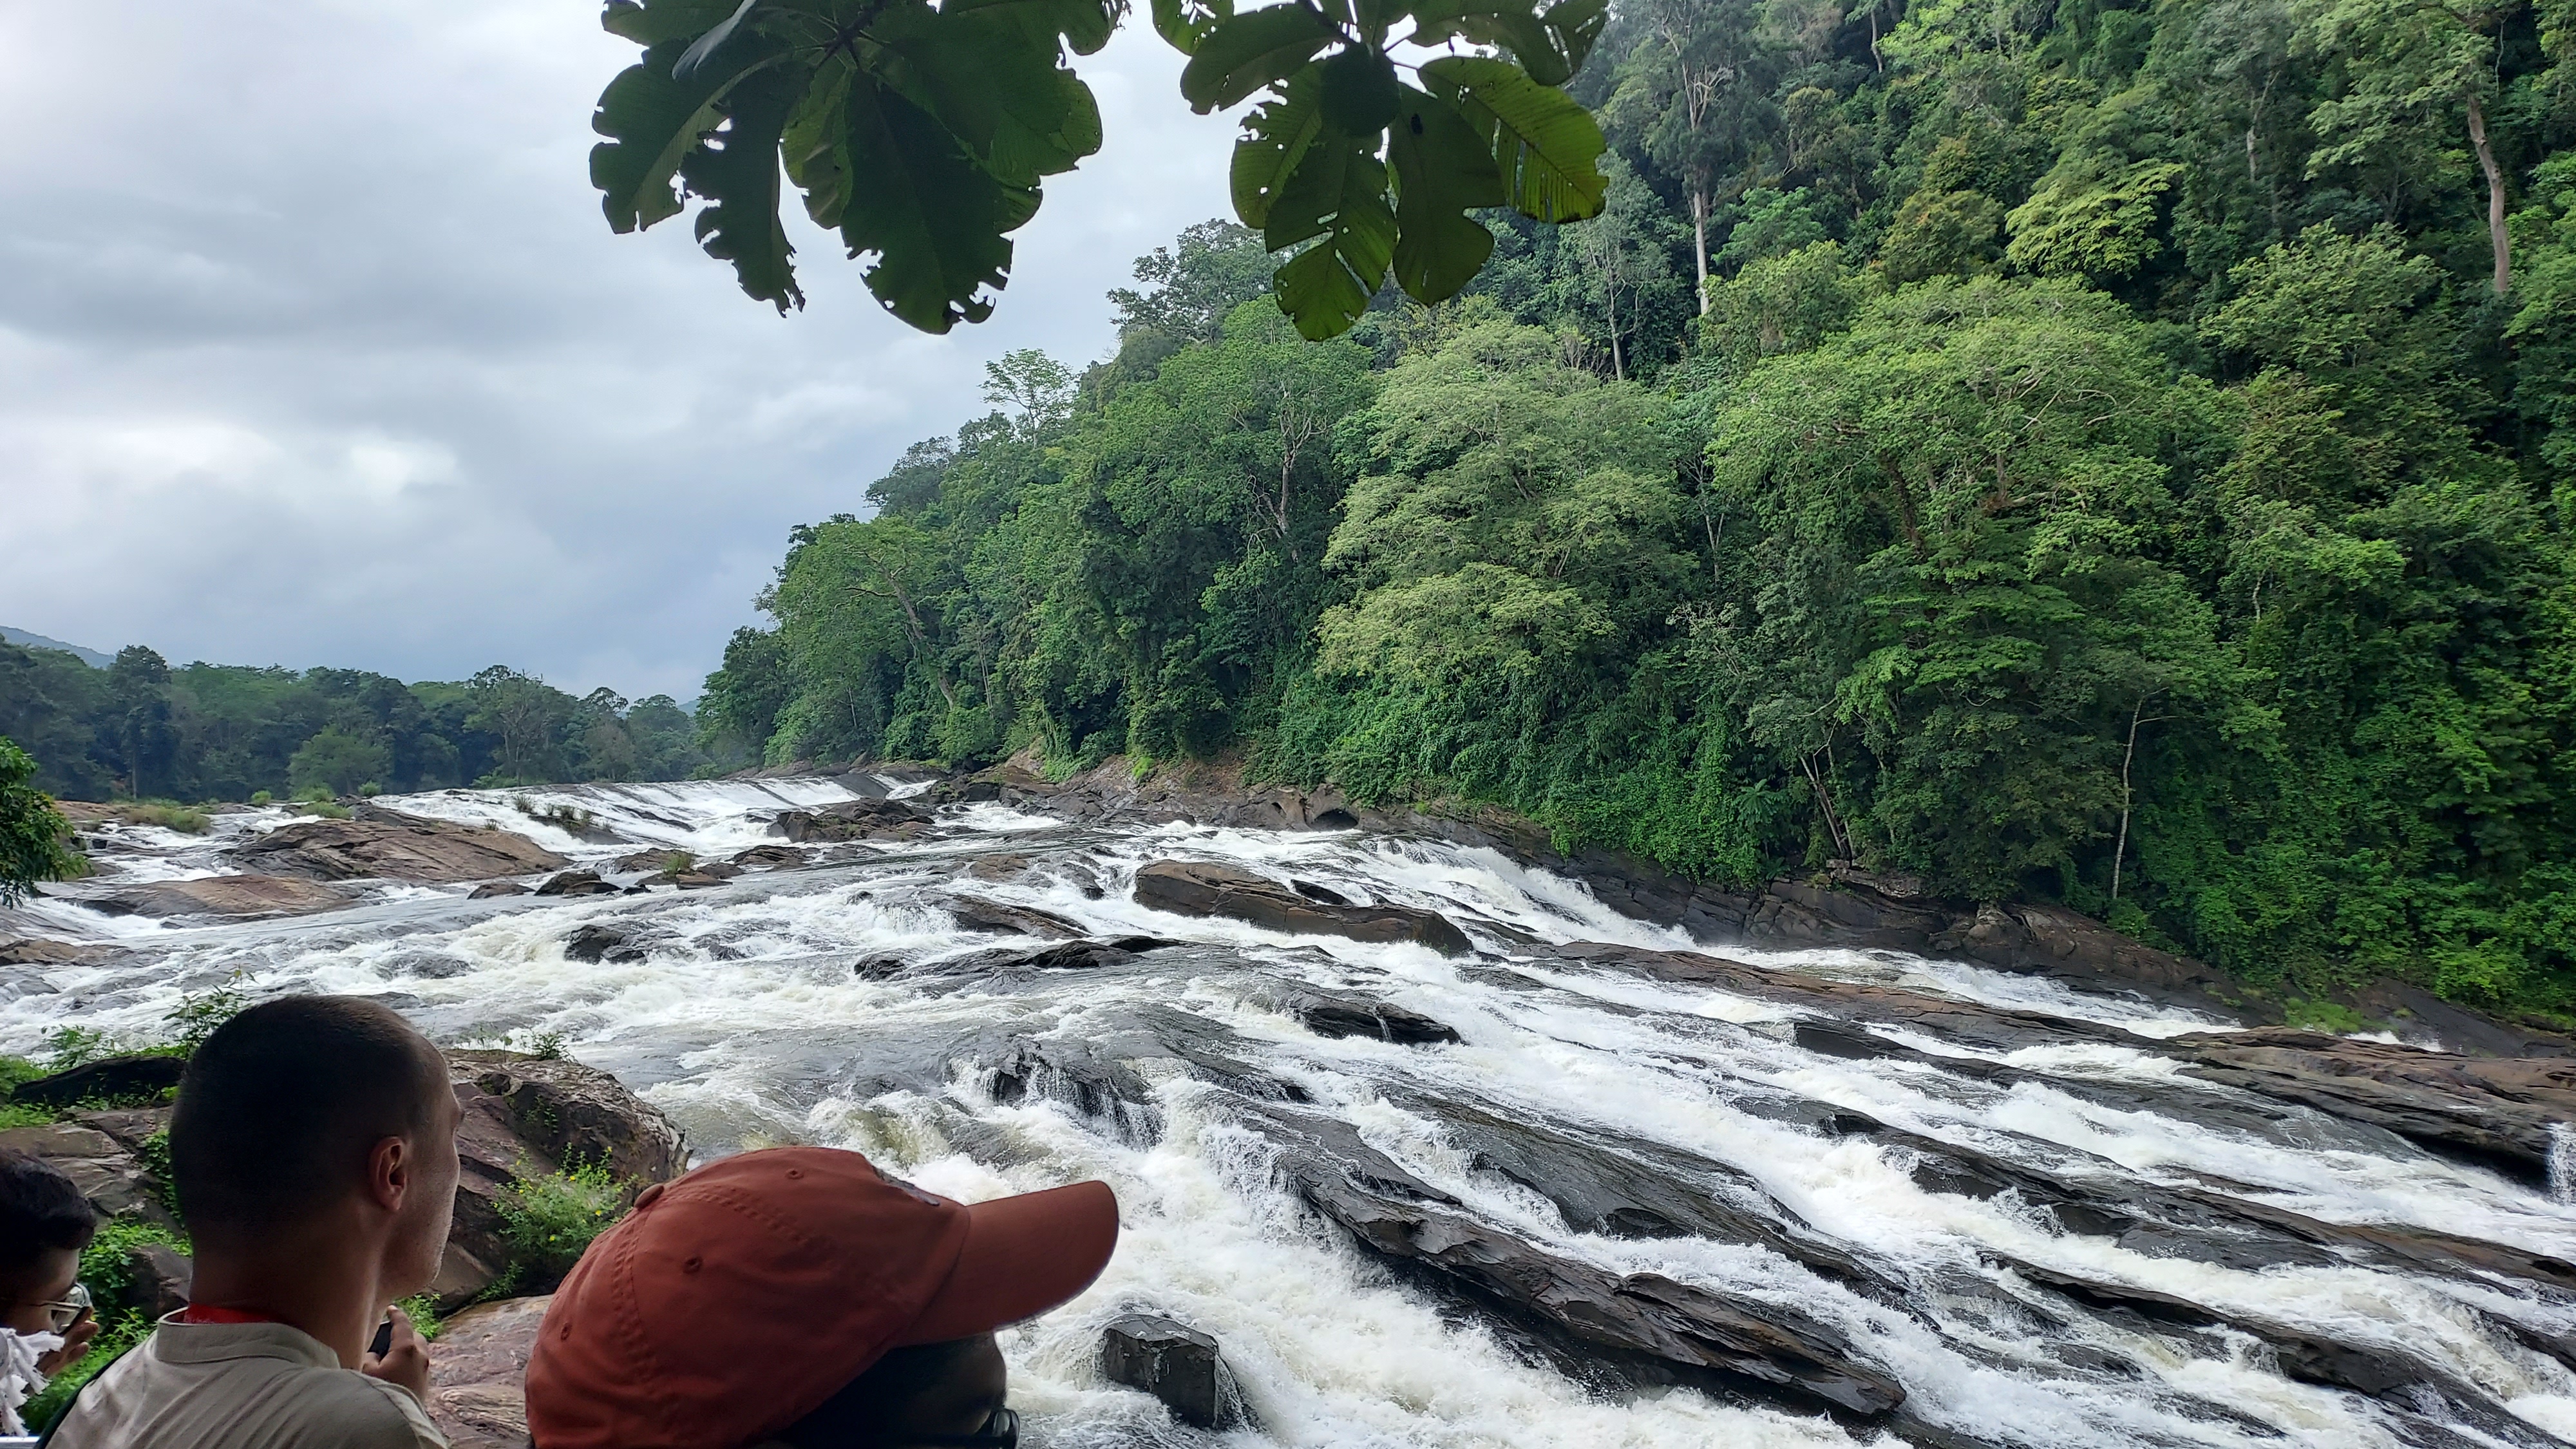
From Day 2 onward, more sponsor stalls were introduced in the hallway area. Hopbox by Unmukti , MostlyHarmless and Deeproot (joint stall) and FOSEE. MostlyHarmless stall had nice mechanical keyboards and other fun gadgets. Whenever I got the time, I would go and start typing racing to enjoy the nice, clicky keyboards. As the DebConf tradition dictates, we had a Cheese and Wine party. Everyone brought in cheese and other delicacies from their region. Then there was yummy Sadya. Sadya is a traditional vegetarian Malayalis lunch served over banana leaves. There were loads of different dishes served, the names of most I couldn t pronounce or recollect properly, but everything was super delicious. Day 4 was day trip and I chose to go to Athirappilly Waterfalls and Jungle safari. Pictures would describe the beauty better than words. The journey was bit long though. Athirappilly Falls
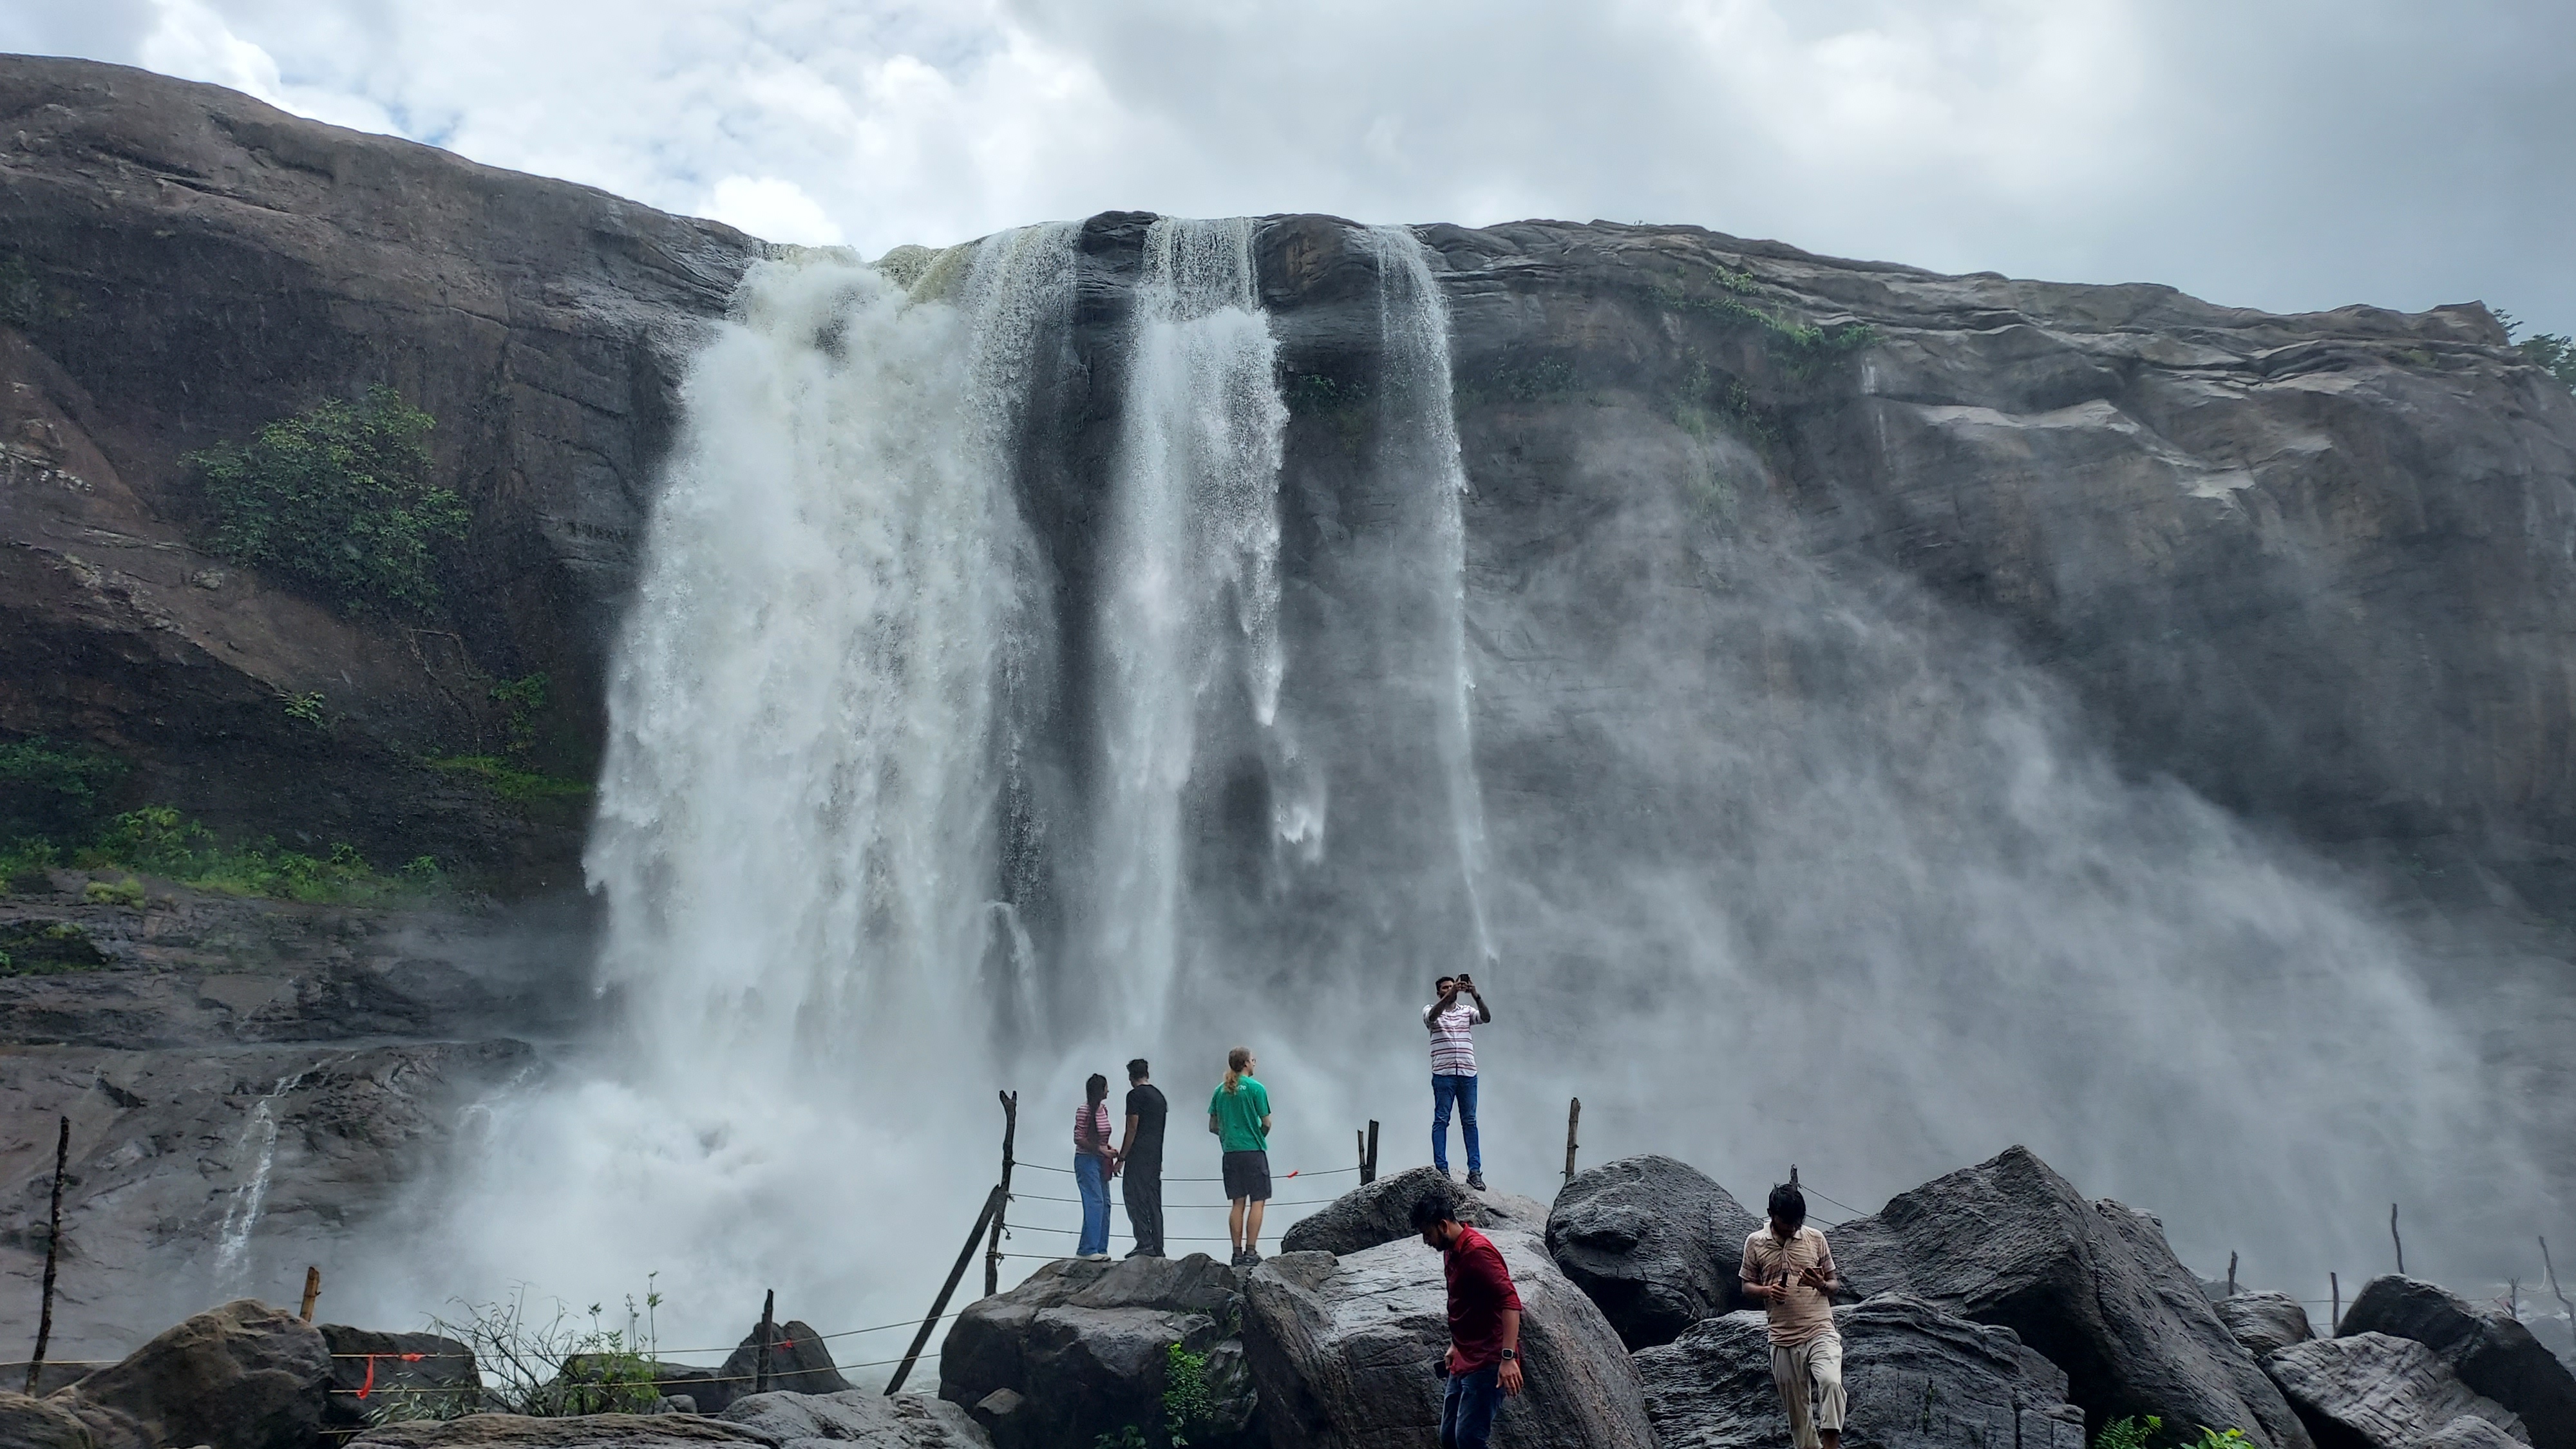
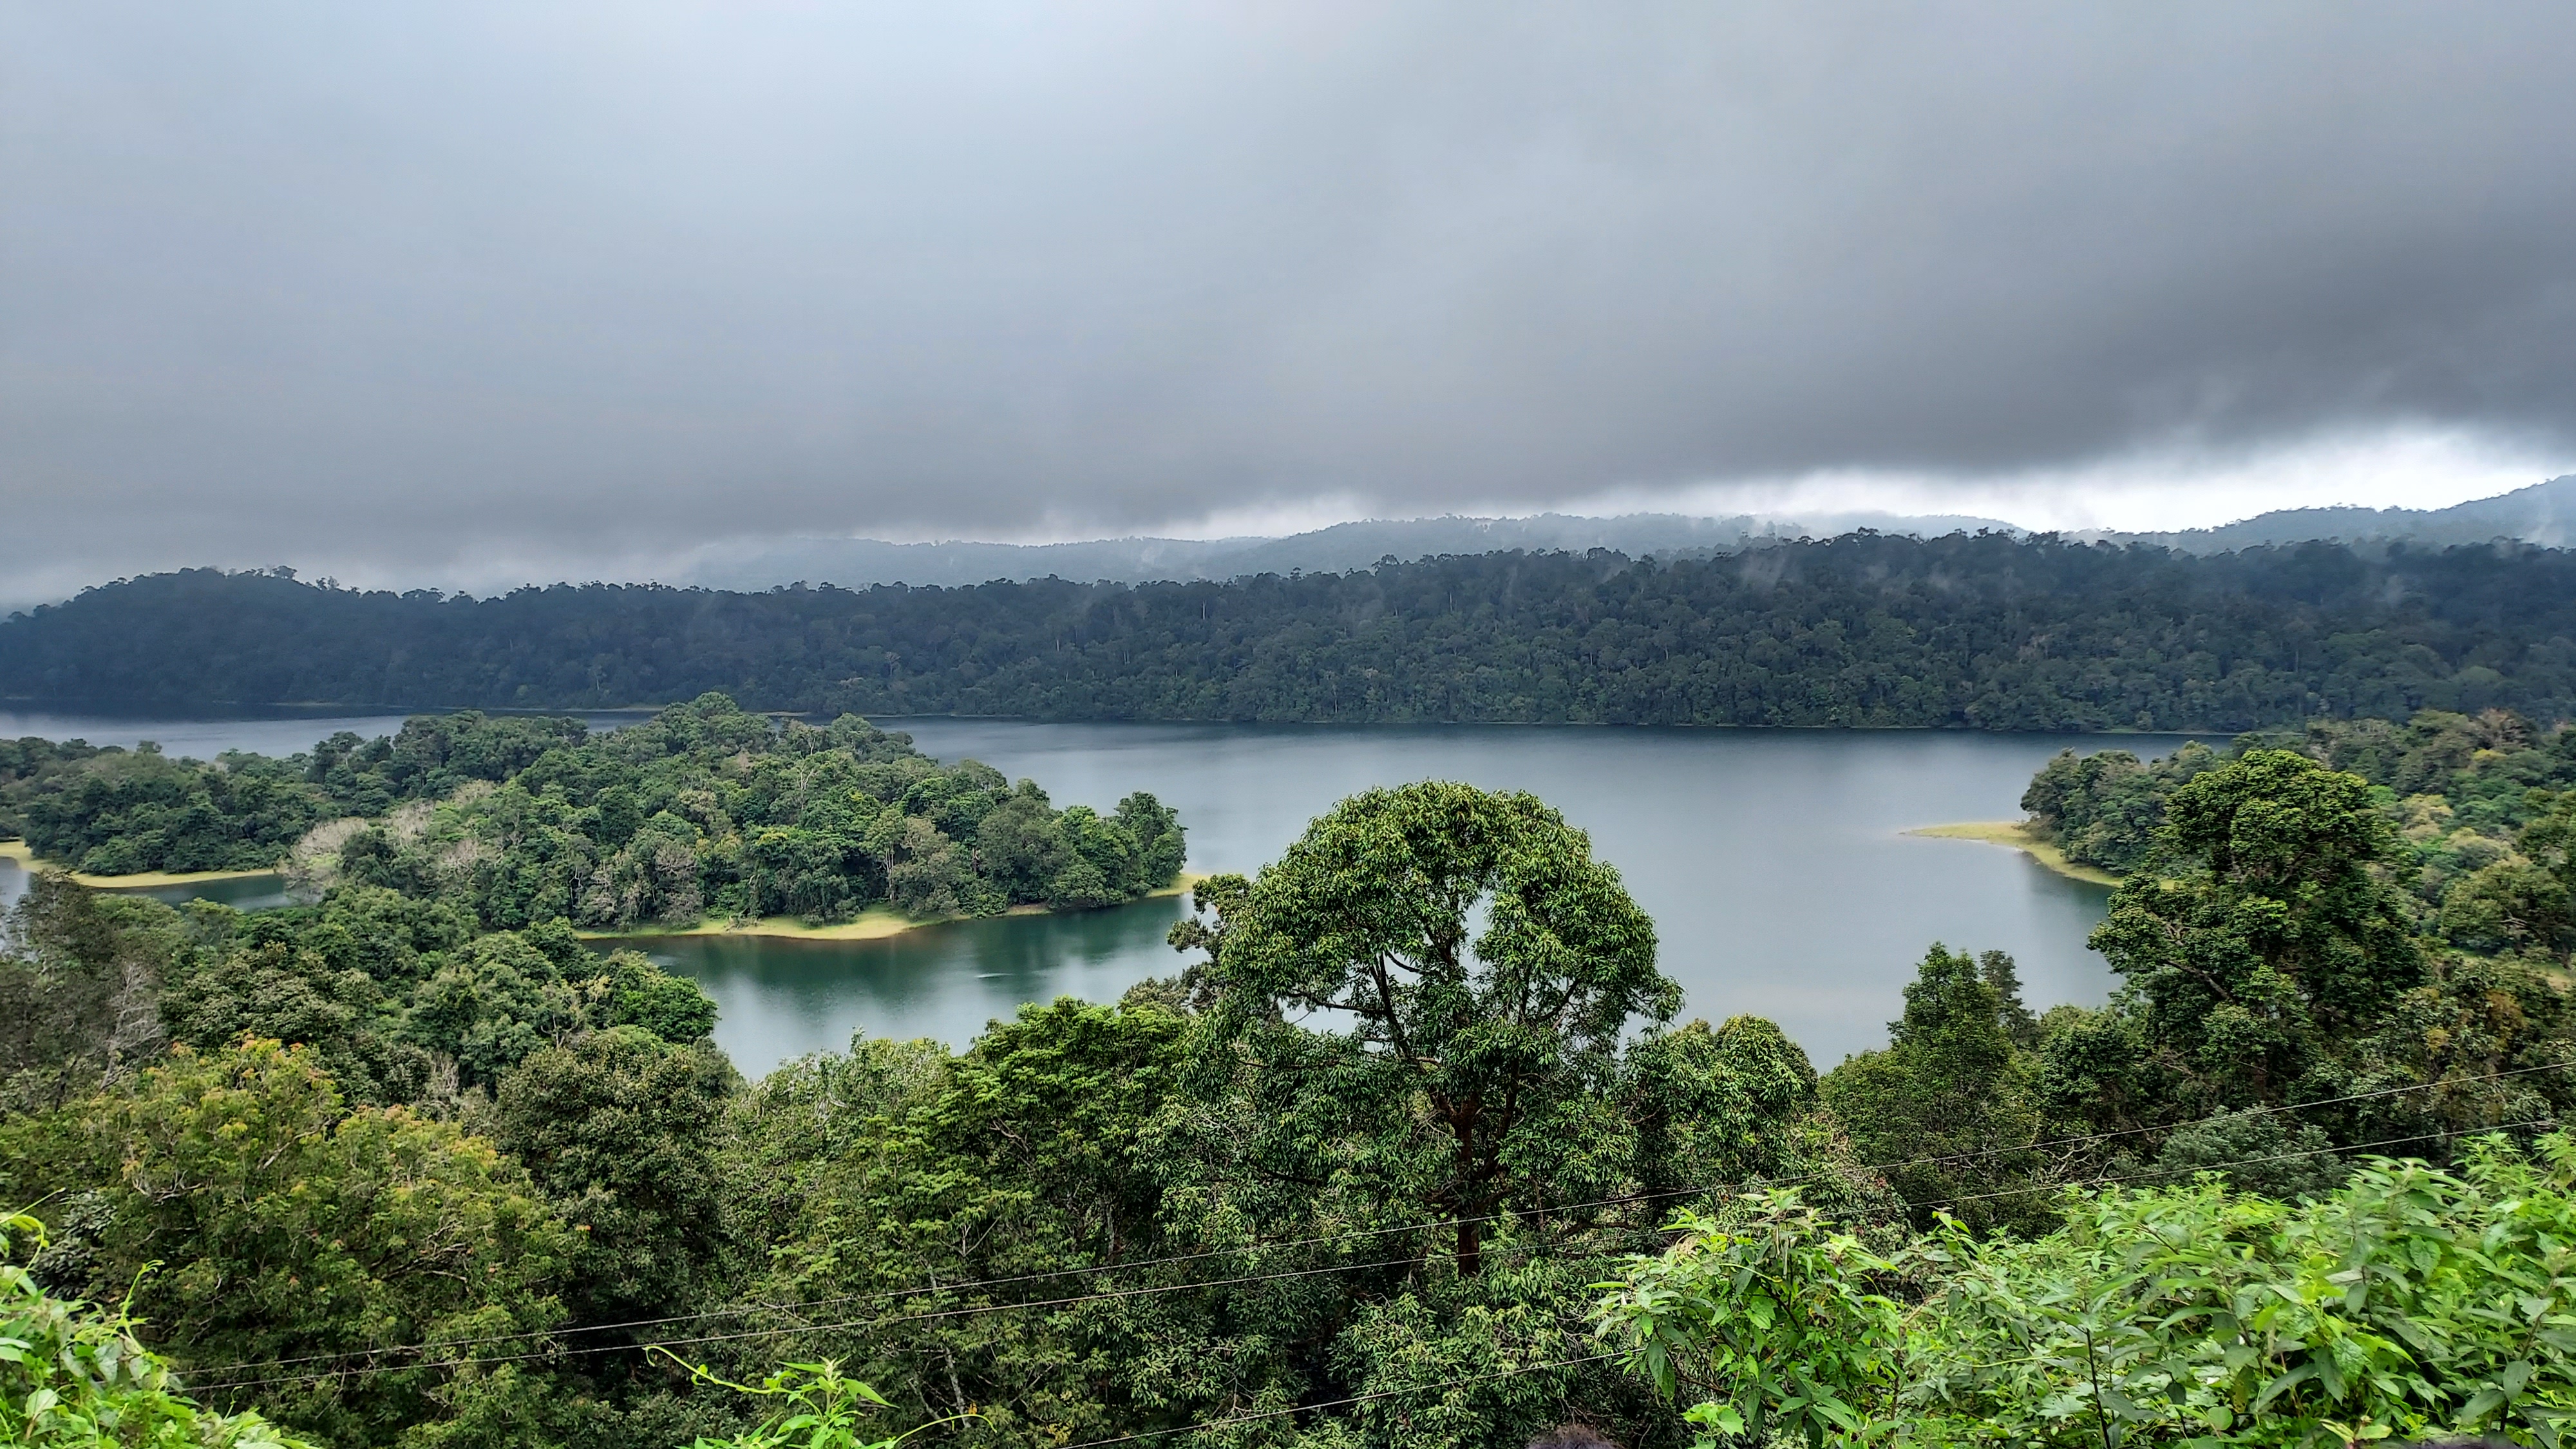
Athirappilly Falls

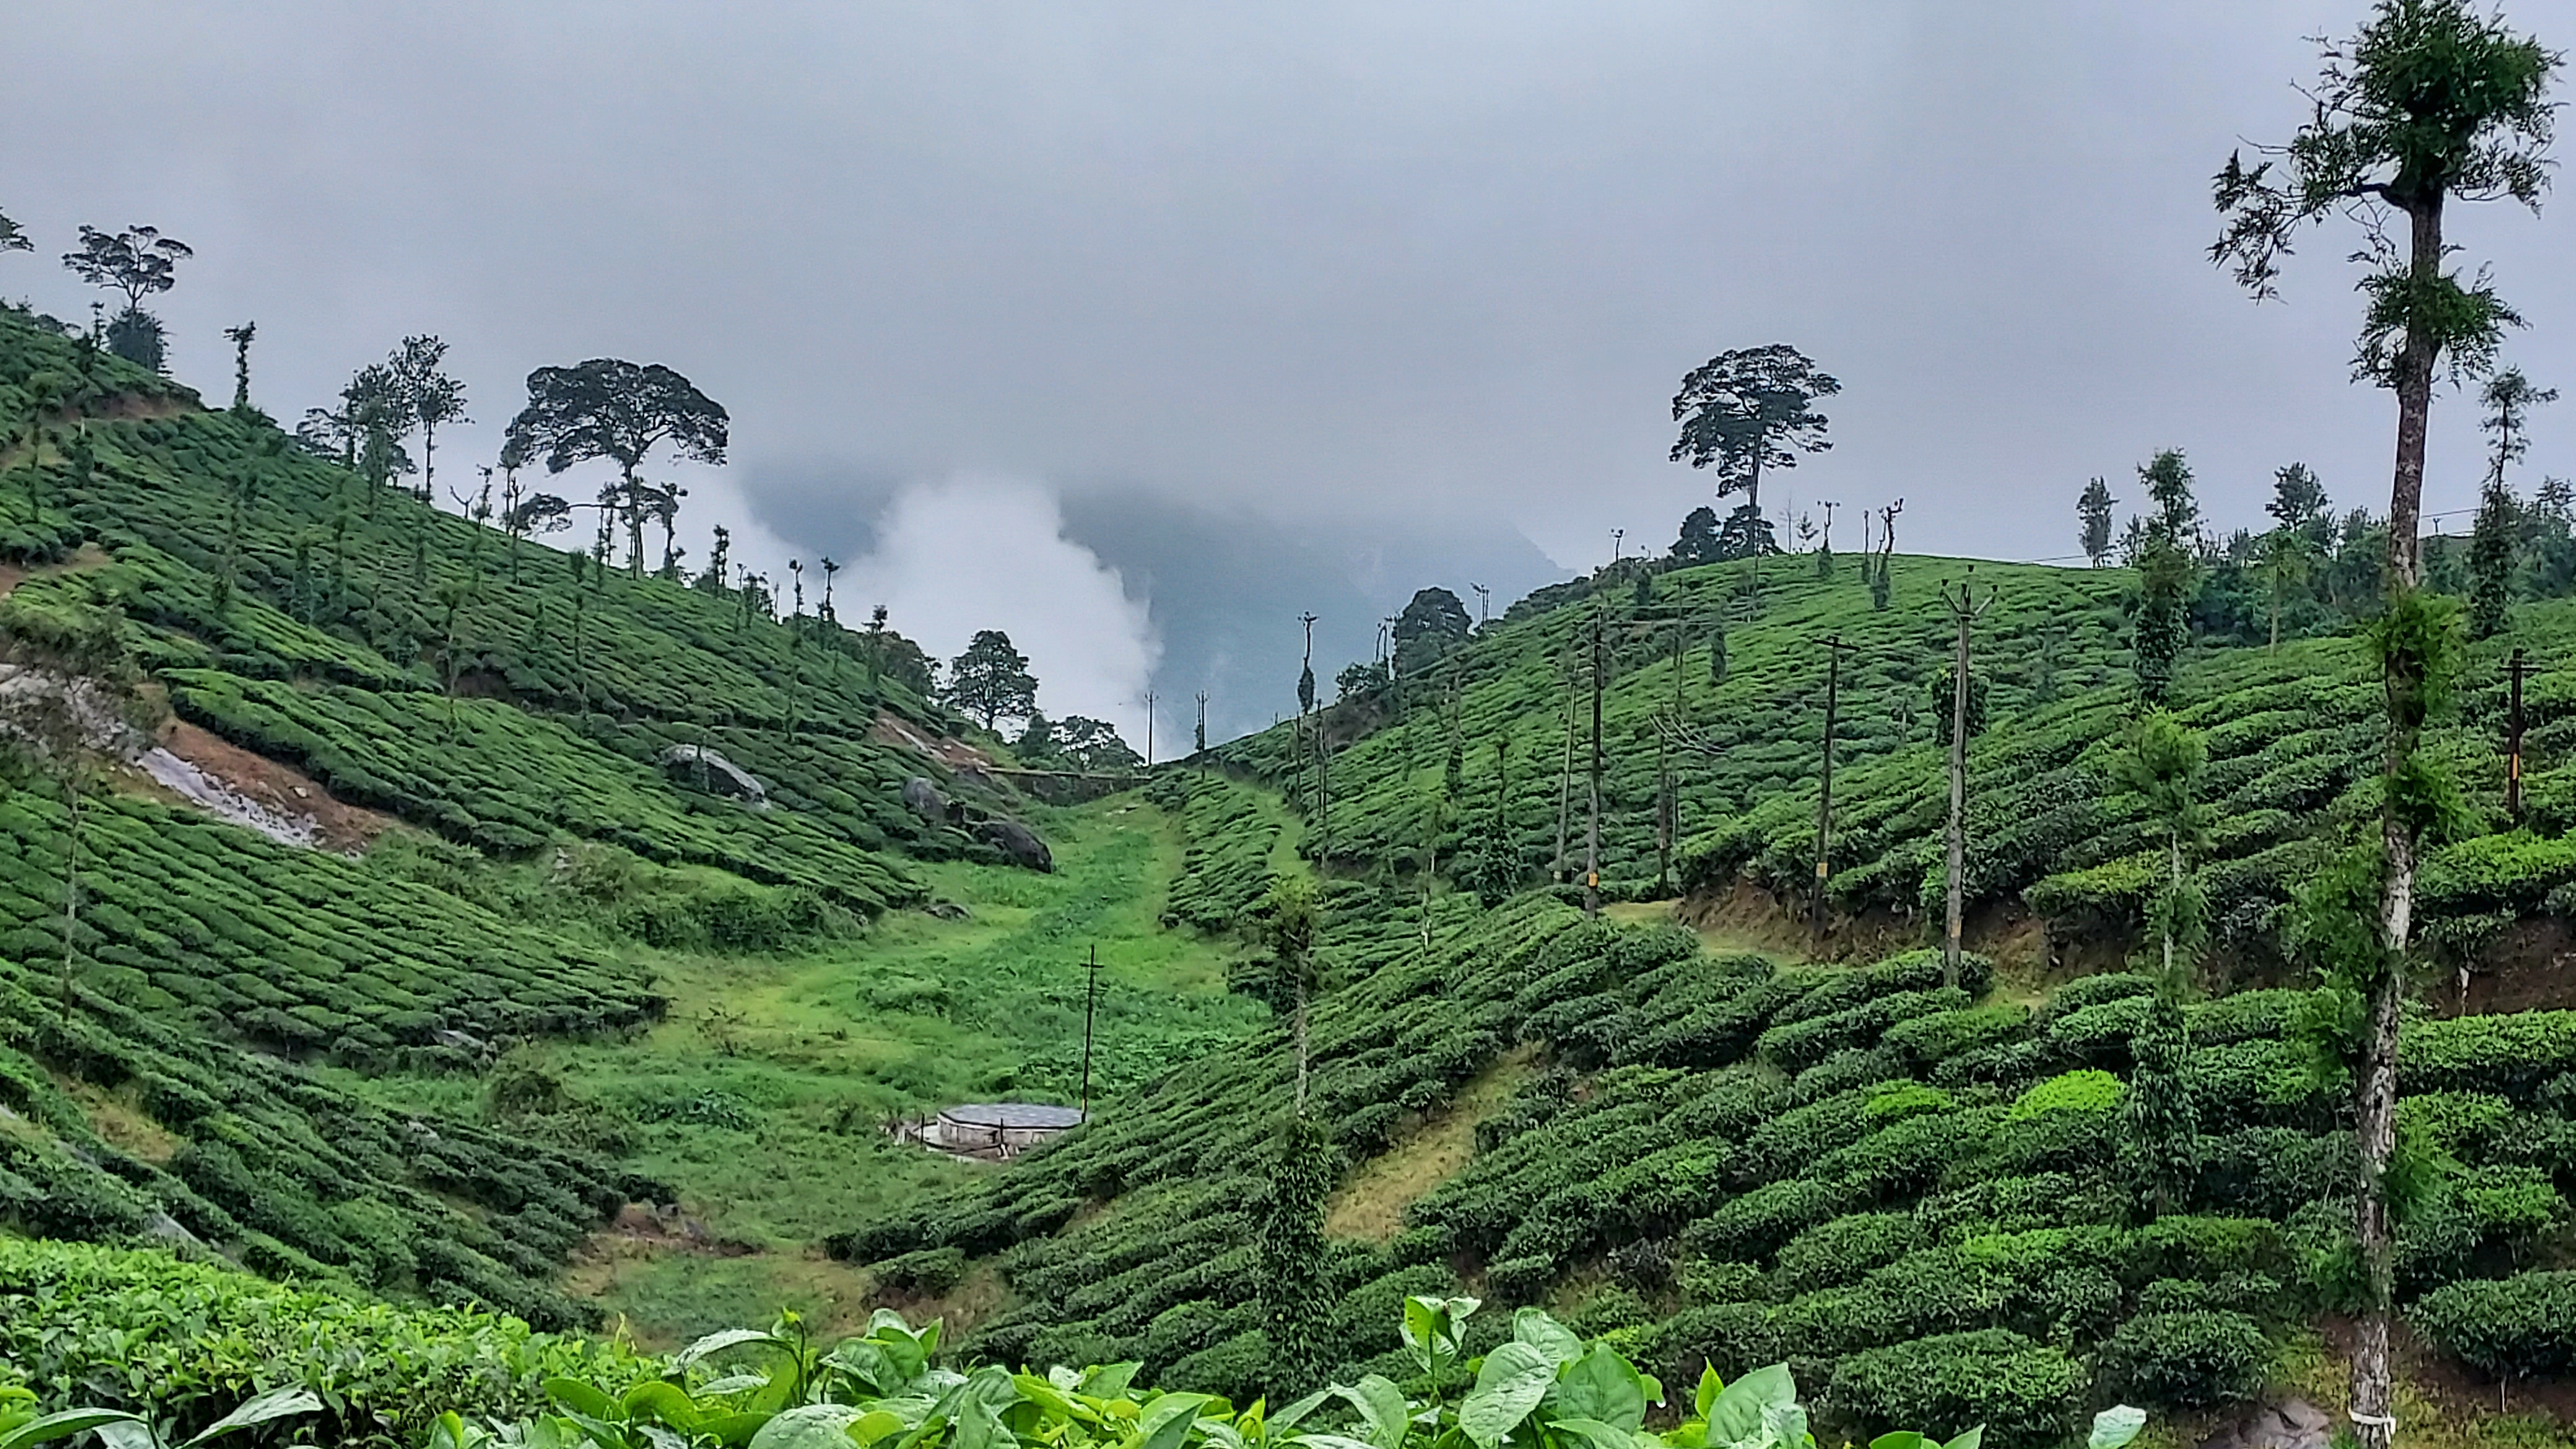
Pathu Pathu Tea Gardens
Tea Gardens
Late that day, we heard the news of Abraham gone missing. We lost Abraham. He had worked really hard all through the years for Debian and making this conference possible. Talks were cancelled for the next day and Jonathan addressed everyone. We went to Abraham s home the next day to meet his family. Team had arranged buses to Abraham s place. It was an unfortunate moment that I only got an opportunity to visit his place after he was gone. Days went by slowly after that. The last day was marked by a small conference dinner. Some of the people had already left. All through the day and next, we kept saying goodbye to friends, with whom we spent almost a fortnight together. Athirappilly Falls
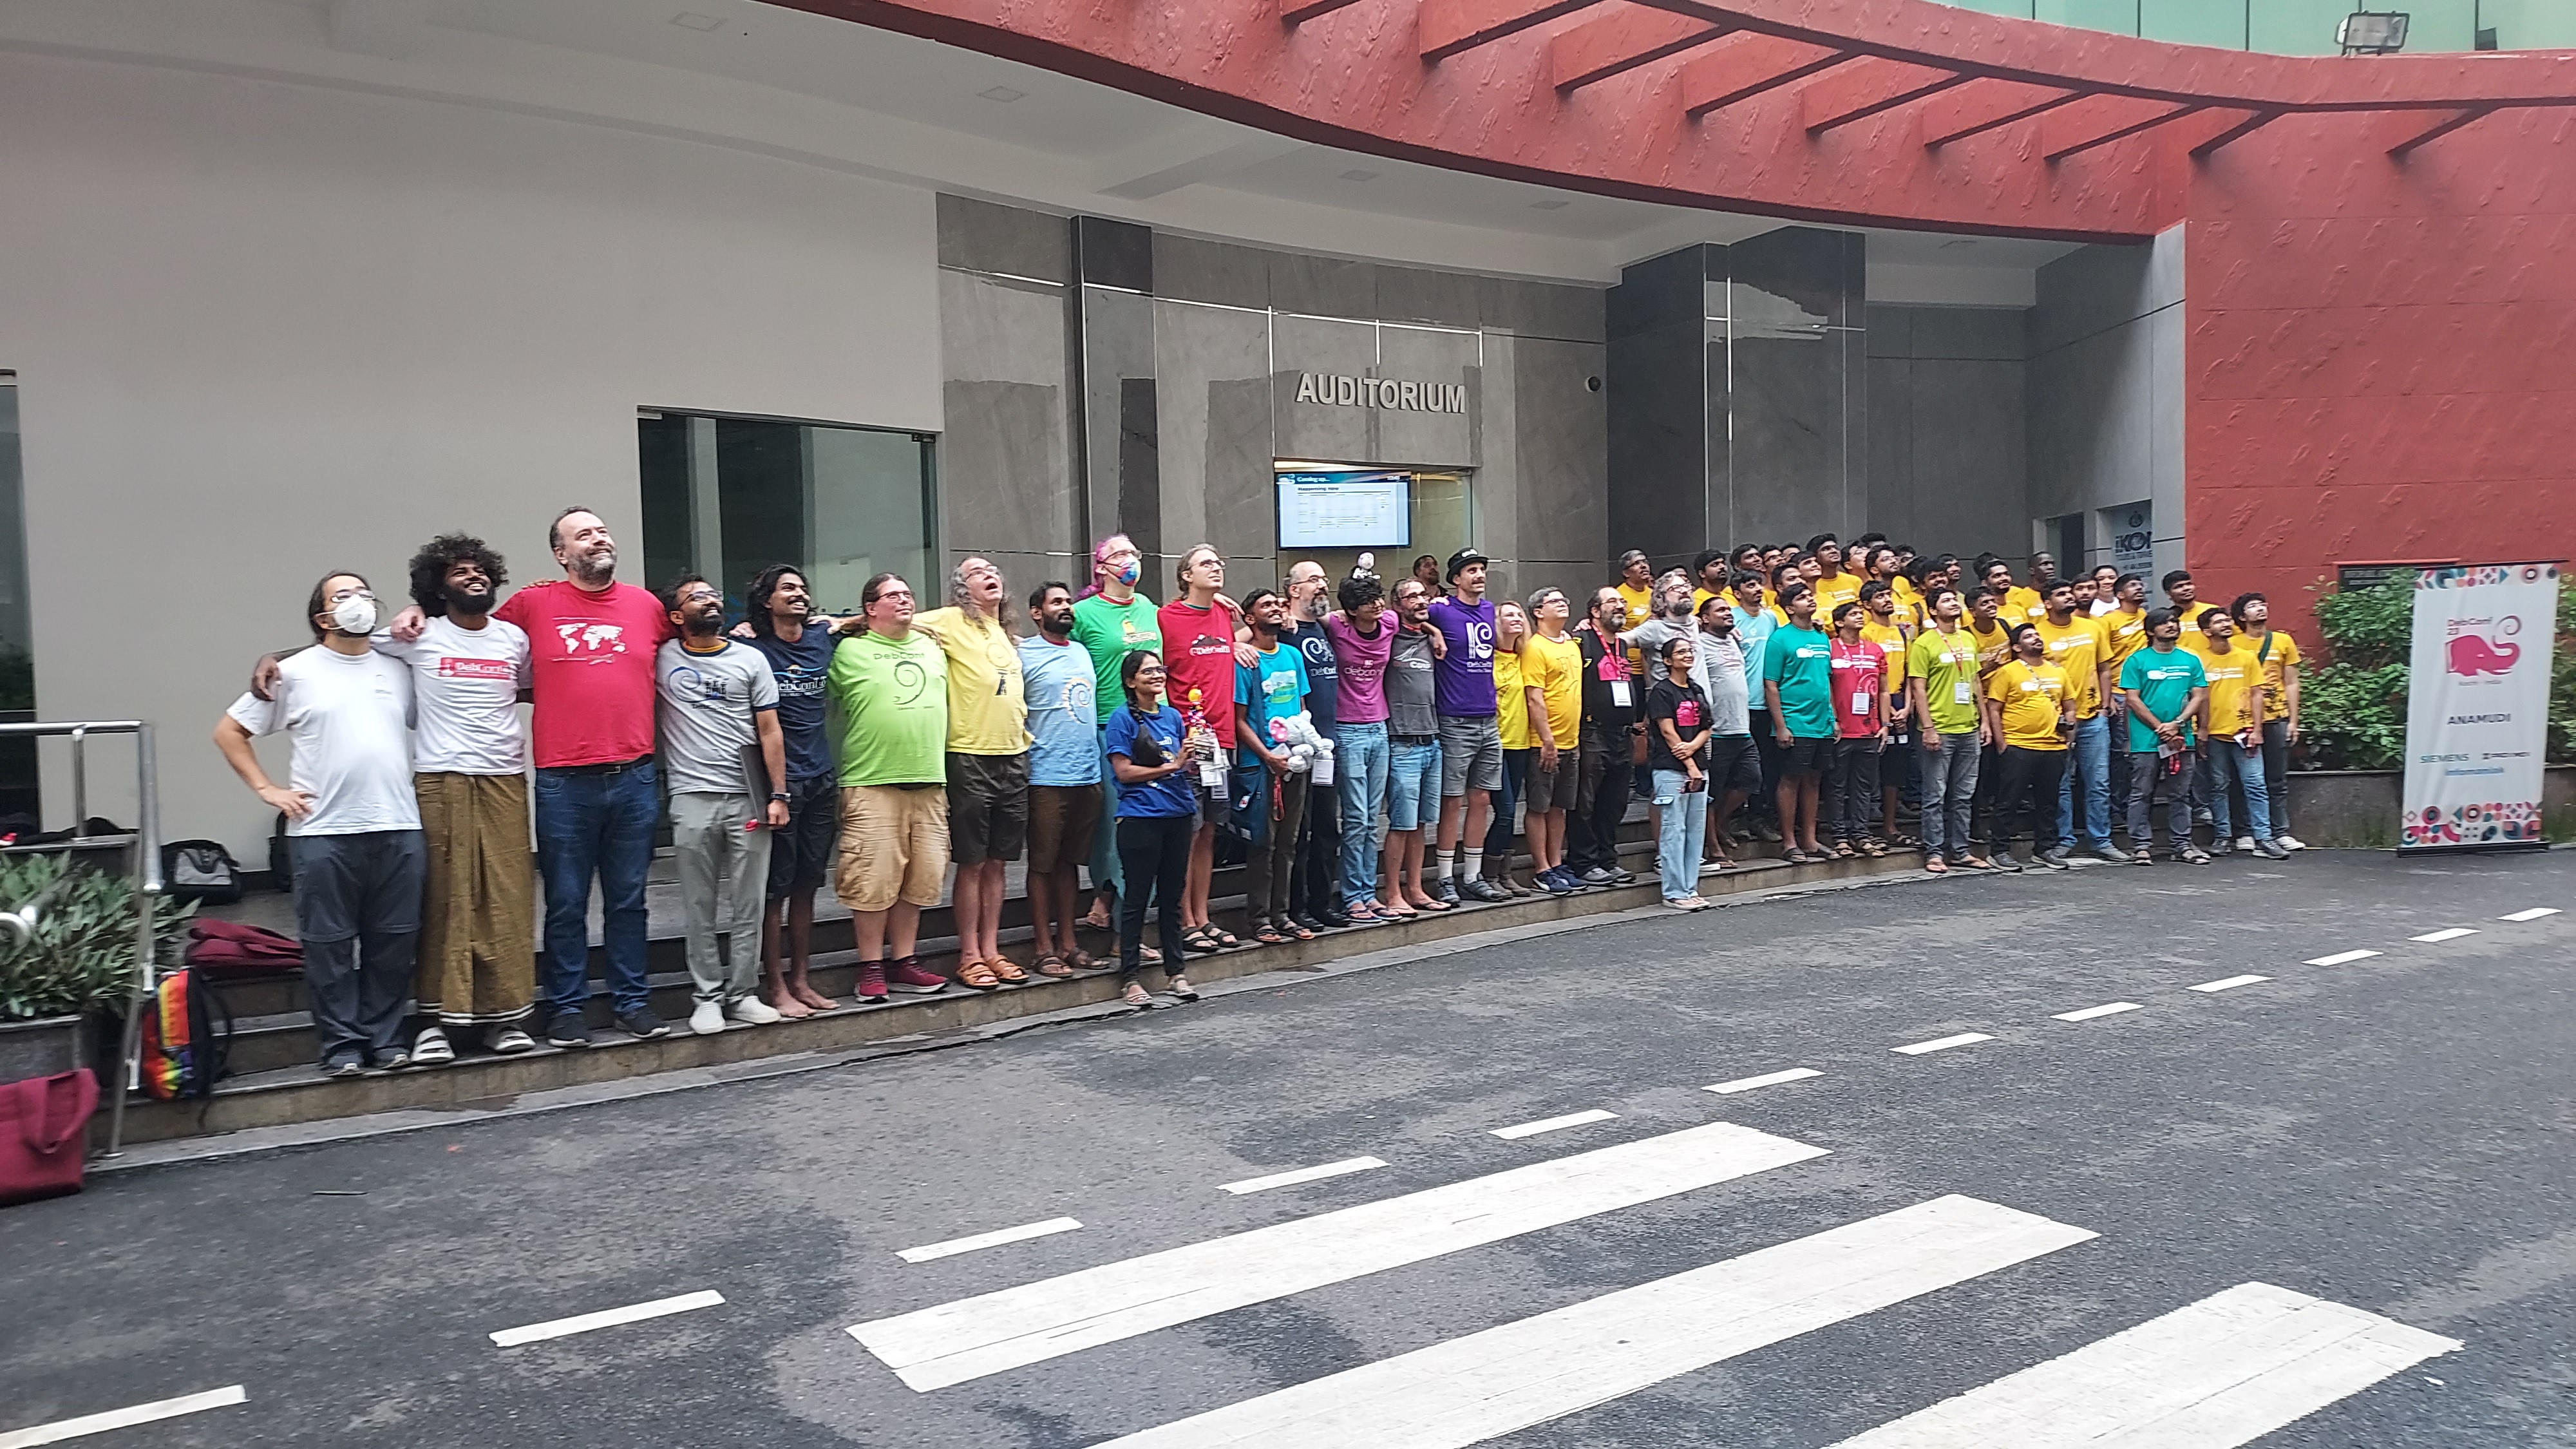
Group photo with all DebConf T-shirts chronologically
This was 2nd trip to Kochi. Vistara Airway s UK886 has become the default flight now. I have almost learned how to travel in and around Kochi by Metro, Water Metro, Airport Shuttle and auto. Things are quite accessible in Kochi but metro is a bit expensive compared to Delhi. I left Kochi on 19th. My flight was due to leave around 8 PM, so I had the whole day to myself. A direct option would have taken less than 1 hour, but as I had time and chose to take the long way to the airport. First took an auto rickshaw to Kakkanad Water Metro station. Then sailed in the water metro to Vyttila Water Metro station. Vyttila serves as intermobility hub which connects water metro, metro, bus at once place. I switched to Metro here at Vyttila Metro station till Aluva Metro station. Here, I had lunch and then boarded the Airport feeder bus to reach Kochi Airport. All in all, I did auto rickshaw > water metro > metro > feeder bus to reach Airport. I was fun and scenic. I must say, public transport and intermodal integration is quite good and once can transition seamlessly from one mode to next. Kochi Water Metro
Kochi Water Metro

Scenes from Kochi Water Metro Scenes from Kochi Water Metro
Scenes from Kochi Water Metro
DebConf23 served its purpose of getting existing Debian people together, as well as getting new people interested and contributing to Debian. People who came are still contributing to Debian, and that s amazing. Streaming video stats
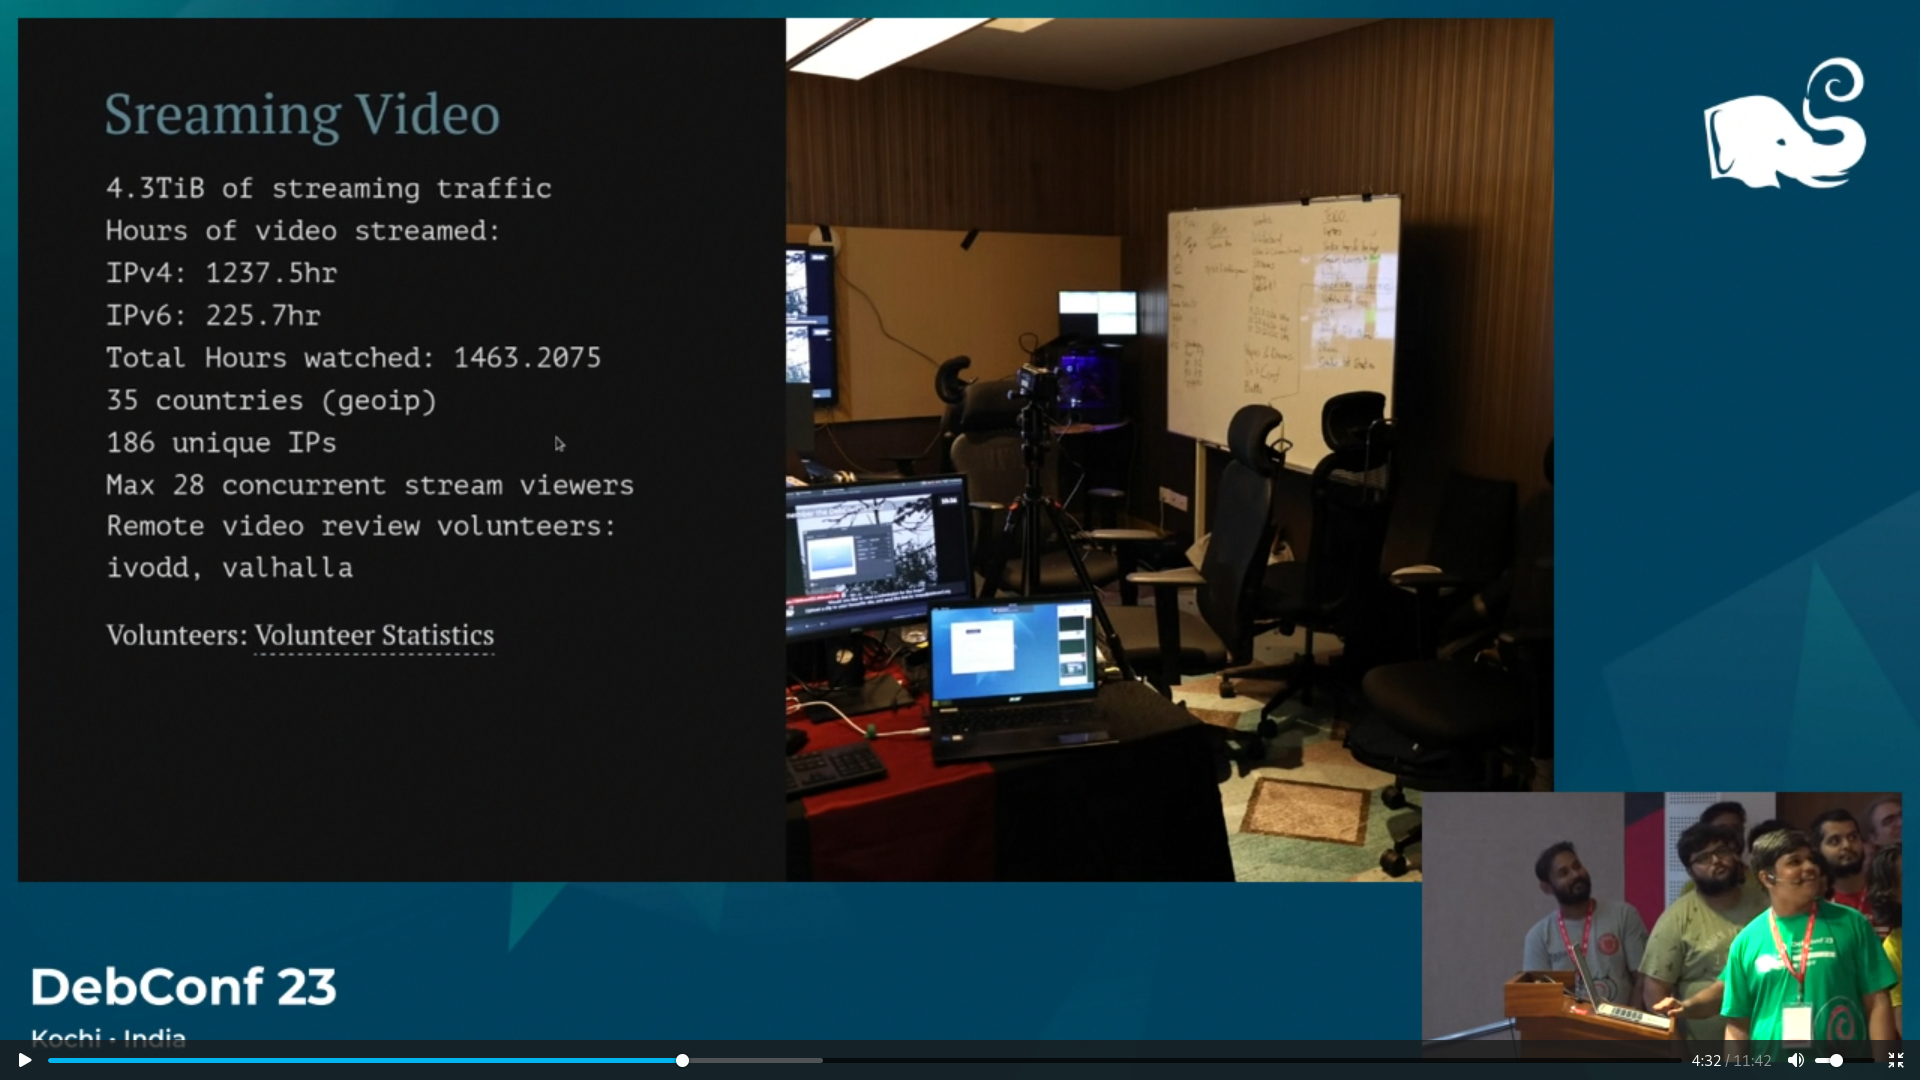
Streaming video stats. Screengrab from closing ceremony
The conference wasn t without its fair share of troubles. There were multiple money transfer woes, and being in India didn t help. Many thanks to multiple organizations who were proactive in helping out. On top of this, there was conference visa uncertainty and other issues which troubled visa team a lot. Kudos to everyone who made this possible. Surely, I m going to miss the name, so thank you for it, you know how much you have done to make this event possible. Now, DebConf24 is scheduled for Busan, South Korea, and work is already in full swing. As usual, I m helping with the fundraising part and plan to attend too. Let s see if I can make it or not. DebConf23 Group Photo
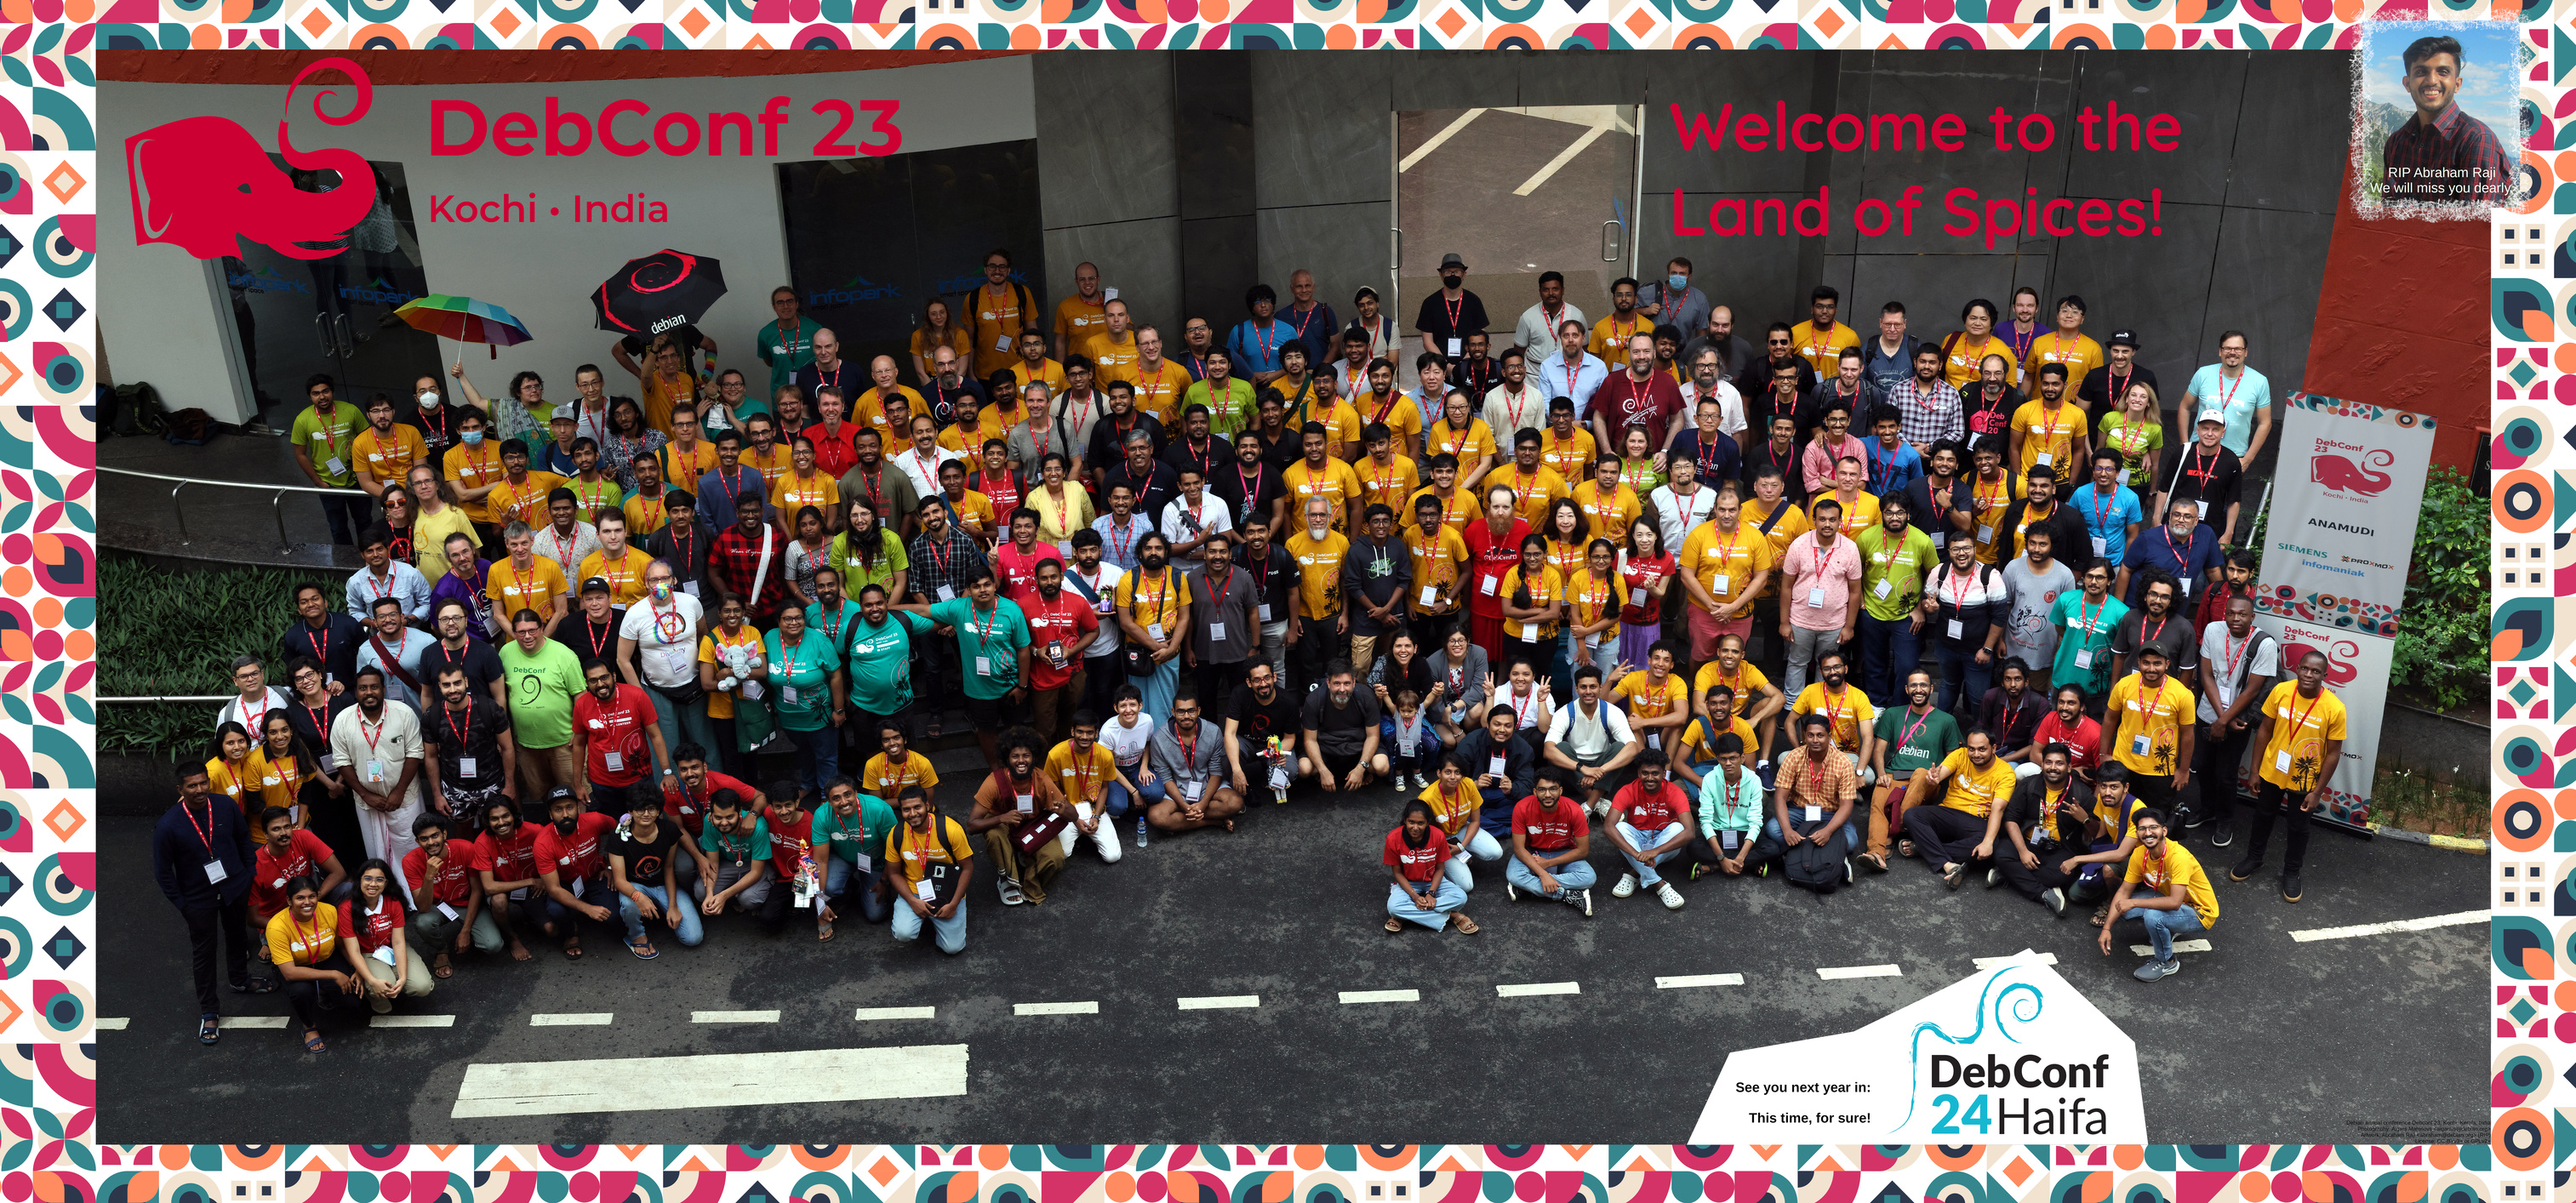
DebConf23 Group Photo. Click to enlarge.
Credits - Aigars Mahinovs
In the end, we kept on saying, no DebConf at this scale would come back to India for the next 10 or 20 years. It s too much trouble to be frank. It was probably the peak that we might not reach again. I would be happy to be proven wrong though :)

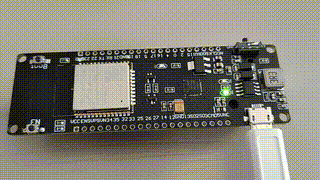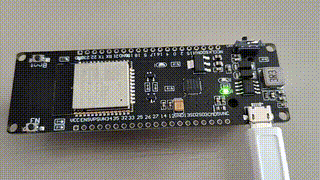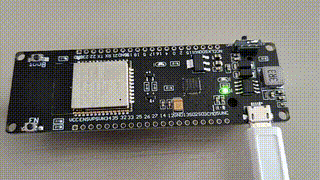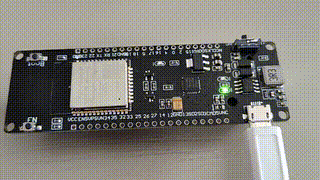
25 May 2024

Gunnar Wolf: How computers make books from graphics rendering, search algorithms, and functional programming to indexing and typesetting

This post is a review for Computing Reviews for How computers make books from graphics rendering, search algorithms, and functional programming to indexing and typesetting , a book published in Manning
If we look at the age-old process of creating books, how many different areas can a computer help us with? And how can each of them be used to teach computer science (CS) fundamentals to a nontechnical audience? This is the premise of John Whitington s enticing book and the result is quite amazing. The book immediately drew my attention when looking at the titles available for review. After all, my initiation into computing as a kid was learning the LaTeX typesetting system while my father worked on his first book on scientific language and typography [1]. Whitington picks 11 different technical aspects of book production, from how dots of ink are transferred to a white page and how they are made into controllable, recognizable shapes, all the way to forming beautiful typefaces and the nuances of properly addressing white-space to present aesthetically pleasing paragraphs, building it all into specific formats aimed at different ends. But if we dig beyond just the chapter titles, we will find a very interesting book on CS that, without ever using technical language or notation, presents aspects as varied as anti-aliasing, vector and raster images, character sets such as ASCII and Unicode, an introduction to programming, input methods for different writing systems, efficient encoding (compression) methods, both for text and images, lossless and lossy, and recursion and dithering methods. To my absolute surprise, while the author thankfully spared the reader the syntax usually associated with LISP-related languages, the programming examples clearly stem from the LISP school, presenting solutions based on tail recursion. Of course, it is no match for Donald Knuth s classic book on this same topic [2], but could very well be a primer for readers to approach it. The book is light and easy to read, and keeps a very informal, nontechnical tone throughout. My only complaint relates to reading it in PDF format; the topic of this book, and the care with which the images were provided by the author, warrant high resolution. The included images are not only decorative but an integral part of the book. Maybe this is specific to my review copy, but all of the raster images were in very low resolution. This book is quite different from what readers may usually expect, as it introduces several significant topics in the field. CS professors will enjoy it, of course, but also readers with a humanities background, students new to the field, or even those who are just interested in learning a bit more.

References
  1. S nchez y G ndara, A.; Magari os Lamas, F.; Wolf, K. B., Manual de lenguaje y tipograf a cient fica en castellano. Trillas, Mexico City, Mexico, 1986, https://www.fis.unam.mx/~bwolf/manual.html
  2. Knuth, D. E. Digital typographyCSLI Lecture Notes: CSLI Lecture Notes. CSLI Publications, Stanford, CA, 1999, https://www-cs-faculty.stanford.edu/~knuth/dt.html

24 May 2024

Julian Andres Klode: Observations in Debian dependency solving

In my previous blog, I explored The New APT 3.0 solver. Since then I have been at work in the test suite making tests pass and fixing some bugs. You see for all intents and purposes, the new solver is a very stupid naive DPLL SAT solver (it just so happens we don t actually have any pure literals in there). We can control it in a bunch of ways:
  1. We can mark packages as install or reject
  2. We can order actions/clauses. When backtracking the action that came later will be the first we try to backtrack on
  3. We can order the choices of a dependency - we try them left to right.
This is about all that we really want to do, we can t go if we reach a conflict, say oh but this conflict was introduced by that upgrade, and it seems more important, so let s not backtrack on the upgrade request but on this dependency instead. . This forces us to think about lowering the dependency problem into this form, such that not only do we get formally correct solutions, but also semantically correct ones. This is nice because we can apply a systematic way to approach the issue rather than introducing ad-hoc rules in the old solver which had a which of these packages should I flip the opposite way to break the conflict kind of thinking. Now our test suite has a whole bunch of these semantics encoded in it, and I m going to share some problems and ideas for how to solve them. I can t wait to fix these and the error reporting and then turn it on in Ubuntu and later Debian (the defaults change is a post-trixie change, let s be honest).

apt upgrade is hard The apt upgrade commands implements a safe version of dist-upgrade that essentially calculates the dist-upgrade, and then undoes anything that would cause a package to be removed, but it (unlike its apt-get counterpart) allows the solver to install new packages. Now, consider the following package is installed:
X Depends: A (= 1)   B
An upgrade from A=1 to A=2 is available. What should happen? The classic solver would choose to remove X in a dist-upgrade, and then upgrade A, so it s answer is quite clear: Keep back the upgrade of A. The new solver however sees two possible solutions:
  1. Install B to satisfy X Depends A (= 1) B.
  2. Keep back the upgrade of A
Which one does it pick? This depends on the order in which it sees the upgrade action for A and the dependency, as it will backjump chronologically. So
  1. If it gets to the dependency first, it marks A=1 for install to satisfy A (= 1). Then it gets to the upgrade request, which is just A Depends A (= 2) A (= 1) and sees it is satisfied already and is content.
  2. If it gets to the upgrade request first, it marks A=2 for install to satisfy A (= 2). Then later it gets to X Depends: A (= 1) B, sees that A (= 1) is not satisfiable, and picks B.
We have two ways to approach this issue:
  1. We always order upgrade requests last, so they will be kept back in case of conflicting dependencies
  2. We require that, for apt upgrade a currently satisfied dependency must be satisfied by currently installed packages, hence eliminating B as a choice.

Recommends are hard too See if you have a X Recommends: A (= 1) and a new version of A, A (= 2), the solver currently will silently break the Recommends in some cases. But let s explore what the behavior of a X Recommends: A (= 1) in combination with an available upgrade of A (= 2) should be. We could say the rule should be:
  • An upgrade should keep back A instead of breaking the Recommends
  • A dist-upgrade should either keep back A or remove X (if it is obsolete)
This essentially leaves us the same choices as for the previous problem, but with an interesting twist. We can change the ordering (and we already did), but we could also introduce a new rule, promotions :
A Recommends in an installed package, or an upgrade to that installed package, where the Recommends existed in the installed version, that is currently satisfied, must continue to be satisfied, that is, it effectively is promoted to a Depends.
This neatly solves the problem for us. We will never break Recommends that are satisfied. Likewise, we already have a Recommends demotion rule:
A Recommends in an installed package, or an upgrade to that installed package, where the Recommends existed in the installed version, that is currently unsatisfied, will not be further evaluated (it is treated like a Suggests is in the default configuration).
Whether we should be allowed to break Suggests with our decisions or not (the old autoremover did not, for instance) is a different decision. Should we promote currently satisified Suggests to Depends as well? Should we follow currently satisified Suggests so the solver sees them and doesn t autoremove them, but treat them as optional?

tightening of versioned dependencies Another case of versioned dependencies with alternatives that has complex behavior is something like
X Depends: A (>= 2)   B
X Recommends: A (>= 2)   B
In both cases, installing X should upgrade an A < 2 in favour of installing B. But a naive SAT solver might not. If your request to keep A installed is encoded as A (= 1) A (= 2), then it first picks A (= 1). When it sees the Depends/Recommends it will switch to B. We can solve this again as in the previous example by ordering the keep A installed requests after any dependencies. Notably, we will enqueue the common dependencies of all A versions first before selecting a version of A, so something may select a version for us.

version narrowing instead of version choosing A different approach to dealing with the issue of version selection is to not select a version until the very last moment. So instead of selecting a version to satisfy A (>= 2) we instead translate
Depends: A (>= 2)
into two rules:
  1. The package selection rule:
     Depends: A
    
    This ensures that any version of A is installed (i.e. it adds a version choice clause, A (= 1) A (= 2) in an example with two versions for A.
  2. The version narrowing rule:
     Conflicts: A (<< 2)
    
    This outright would reject a choice of A (= 1).
So now we have 3 kinds of clauses:
  1. package selection
  2. version narrowing
  3. version selection
If we process them in that order, we should surely be able to find the solution that best matches the semantics of our Debian dependency model, i.e. selecting earlier choices in a dependency before later choices in the face of version restrictions. This still leaves one issue: What if our maintainer did not use Depends: A (>= 2) B but e.g. Depends: A (= 3) B A (= 2). He d expect us to fall back to B if A (= 3) is not installable, and not to B. But we d like to enqueue A and reject all choices other than 3 and 2. I think it s fair to say: Don t do that, then here.

Implementing strict pinning correctly APT knows a single candidate version per package, this makes the solver relatively deterministic: It will only ever pick the candidate, or an installed version. This also happens to significantly reduce the search space which is good - less backtracking. An uptodate system will only ever have one version per package that can be installed, so we never actually have to choose versions. But of course, APT allows you to specify a non-candidate version of a package to install, for example:
apt install foo/oracular-proposed
The way this works is that the core component of the previous solver, which is the pkgDepCache maintains what essentially amounts to an overlay of the policy that you could see with apt-cache policy. The solver currently however validates allowed version choices against the policy directly, and hence finds these versions are not allowed and craps out. This is an interesting problem because the solver should not be dependent on the pkgDepCache as the pkgDepCache initialization (Building dependency tree...) accounts for about half of the runtime of APT (until the Y/n prompt) and I d really like to get rid of it. But currently the frontend does go via the pkgDepCache. It marks the packages in there, building up what you could call a transaction, and then we translate it to the new solver, and once it is done, it translates the result back into the pkgDepCache. The current implementation of allowed version is implemented by reducing the search space, i.e. every dependency, we outright ignore any non-allowed versions. So if you have a version 3 of A that is ignored a Depends: A would be translated into A (= 2) A (= 1). However this has two disadvantages. (1) It means if we show you why A could not be installed, you don t even see A (= 3) in the list of choices and (2) you would need to keep the pkgDepCache around for the temporary overrides. So instead of actually enforcing the allowed version rule by filtering, a more reasonable model is that we apply the allowed version rule by just marking every other version as not allowed when discovering the package in the from depcache translation layer. This doesn t really increase the search space either but it solves both our problem of making overrides work and giving you a reasonable error message that lists all versions of A.

pulling up common dependencies to minimize backtracking cost One of the common issues we have is that when we have a dependency group
 A   B   C   D 
we try them in order, and if one fails, we undo everything it did, and move on to the next one. However, this isn t perhaps the best choice of operation. I explained before that one thing we do is queue the common dependencies of a package (i.e. dependencies shared in all versions) when marking a package for install, but we don t do this here: We have already lowered the representation of the dependency group into a list of versions, so we d need to extract the package back out of it. This can of course be done, but there may be a more interesting solution to the problem, in that we simply enqueue all the common dependencies. That is, we add n backtracking levels for n possible solutions:
  1. We enqueue the common dependencies of all possible solutions deps(A)&deps(B)&deps(C)&deps(D)
  2. We decide (adding a decision level) not to install D right now and enqueue deps(A)&deps(B)&deps(C)
  3. We decide (adding a decision level) not to install C right now and enqueue deps(A)&deps(B)
  4. We decide (adding a decision level) not to install B right now and enqueue A
Now if we need to backtrack from our choice of A we hopefully still have a lot of common dependencies queued that we do not need to redo. While we have more backtracking levels, each backtracking level would be significantly cheaper, especially if you have cheap backtracking (which admittedly we do not have, yet anyway). The caveat though is: It may be pretty expensive to find the common dependencies. We need to iterate over all dependency groups of A and see if they are in B, C, and D, so we have a complexity of roughly #A * (#B+#C+#D) Each dependency group we need to check i.e. is X Y in B meanwhile has linear cost: We need to compare the memory content of two pointer arrays containing the list of possible versions that solve the dependency group. This means that X Y and Y X are different dependencies of course, but that is to be expected they are. But any dependency of the same order will have the same memory layout. So really the cost is roughly N^4. This isn t nice. You can apply various heuristics here on how to improve that, or you can even apply binary logic:
  1. Enqueue common dependencies of A B C D
  2. Move into the left half, enqueue of A B
  3. Again divide and conquer and select A.
This has a significant advantage in long lists of choices, and also in the common case, where the first solution should be the right one. Or again, if you enqueue the package and a version restriction instead, you already get the common dependencies enqueued for the chosen package at least.

Freexian Collaborators: Discover release 0.3.0 of the debusine software factory (by Colin Watson)

Debusine is a Free Software project developed by Freexian to manage scheduling and distribution of Debian-related tasks to a network of worker machines. It was started some time back, but its development pace has recently increased significantly thanks to funding from the Sovereign Tech Fund. You can read more about it in its documentation. For more background, Enrico Zini and Carles Pina i Estany gave a talk on Debusine in November 2023 at the mini-DebConf in Cambridge. We described the work from our first funded milestone in a post to debian-devel-announce in March. We ve recently finished work on our second funded milestone, culminating in releasing version 0.3.0 to unstable. Our focus on this milestone was on new building blocks to allow us to automatically orchestrate QA tasks in bulk. Full details are in our release history document. As usual, debusine.debian.net is up to date with our latest work.

Collections In the previous milestone, debusine could store artifacts and run tasks against those artifacts. However, on its own this required the user to do a lot of manual work, because the only way to refer to an artifact was by its ID. We now have the concept of a collection, which can store references to other artifacts (or indeed to other collections) with some attached metadata. These are structured by category, so for example a debian:suite collection contains references to source and binary package artifacts with their names, versions, and architectures as metadata. This allows us to look up artifacts using a simple query language instead of just by ID. At the moment, the main visible effect of this is that our Getting started with debusine tutorial no longer needs users of debusine.debian.net to create their own build environments before being able to submit other work requests: they can refer to existing environments using something like debian/match:codename=trixie:variant=sbuild instead. We also have a basic user interface allowing you to browse existing collections, accessible via the relevant workspace (such as the default System workspace).

Workflows We ve always known that individual tasks were just a starting point: real-world requirements often involve chaining many tasks together, as many Debian developers already do using the Salsa CI pipeline. debusine intends to approach a similar problem from a different angle, defining common workflows that can be applied at the scale of a whole distribution without being tightly coupled to where each package s code is hosted. In time we intend to define a way for users to specify their own workflows, but rather than getting too bogged down in this we started by building a couple of predefined workflows into debusine. The update_environments workflow is used to create multiple build environments in bulk, while the sbuild workflow builds a source package for all the architectures that it supports and for which debusine has workers. (debusine.debian.net currently has amd64 and arm64 workers, supporting the amd64, arm64, armel, armhf, and i386 architectures between them.) Upcoming work will build on this by adding more workflows that chain tasks together in various ways, such as workflows that build a package and run QA tasks on the results, or a workflow that builds a package and uploads the result to an upload queue.

Next steps Our next planned milestone involves expanding debusine s capability as a build daemon. For that, we already know that there are a number of specific extra workflow steps we need to add, and we ve reached out to some members of Debian s buildd team to ask for feedback on what they consider necessary. We hope to be able to replace some of Freexian s own build infrastructure with debusine in the near future.

Next.

Previous.