Search Results: "jam"

6 December 2010

Jamie McClelland: rm -rf at ~ 500 Mbytes/second

If you ever have the misfortune of accidentally passing the path to a directory containing 177GB of data to the rm -rf command, I'll start by suggesting that you hit ctl-c. The sooner the better. Next, assuming you have some sort of backup, you'll be staring at two monumentally large data sets, wondering exactly what was deleted from the original. With help from dkg, I learned somethings about rm -rf. For one, it deletes one top level directory at a time. So - a comparison of the top level directory listings of the original and backup is a good place to start. Top level directories that are entirely missing in the original are easy to restore. However, the presence of a top level directory in the original doesn't mean it was un-touched. Next, you'll want to figure out which top level directory rm was operating on when you hit ctl-c. dkg discovered that ls -UR will provide a listing in the same order that rm -rf uses. The -U means do not sort. Note - the unsorted listing of the backup directory might not be the same as the unsorted listing of the original, so ls -UR is only really helpful on the original directory. After selecting the first top level directory, rm -rf seems to delete all files in that directory first (presumably in the same order that ls -UR will list them), then it enters the first sub directory (as returned by ls -UR) and repeats the process. With a careful comparison of ls -UR on the original with the directory listings on the backup, you should be able to pinpoint the exact sub directories affected, allowing you to restore only the files and directories that you deleted. Thanks to dkg for technical and blog title suggestions.

28 November 2010

Benjamin Mako Hill: Doppelg nger

/copyrighteous/images/food_network_mako-small.png It's funny, I don't remember donning a cape and making an apperance on the food network.

25 November 2010

Cyril Brulebois: Debian XSF News

Since people seem to like it, I ll be trying to publish some news about ongoing work on the XSF side, on a (possibly) regular basis. Let s have a look at what happened since last time I blogged about X in Debian, mostly by checking what appeared in my =debian-x mailbox. Debian XSF News #1 What are the XSF plans?

15 November 2010

Benjamin Mako Hill: Between the Bars

Almost a year ago, I blogged about Between the Bars -- a project that offers a blogging platform to the 1% of the United States population that is currently incarcerated. The way it works is pretty simple: prisoners send letters through the postal mail. We scan them and put them up on the web. Visitors can transcribe letters or leave comments which are mailed back to the authors. About a month ago, my collaborator Charlie DeTar and I finally finished planning and paperwork and opened the site to bloggers. Over the last few weeks, we've had a bunch of authors sign up. We now have a daily stream of blog posts going up on the site. Please visit the site. Leave comments. Transcribe posts. If you know of prisoners who might like to use the site, let them know. If you want postcard fliers to send to prisoners, let us know.

7 November 2010

Benjamin Mako Hill: Monopedal Sumo

At LCA in Wellington -- immediately after a trip to Japan where I saw sumo for the first time -- a number of us created a game we called "monopedal sumo." Basically, the rules are those of sumo wrestling. Push your opponent either down or out of a ring before they do so to you. Unlike normal sumo, in our game you do so standing only one one leg. If your second leg touches the ground. That also counts as a loss. It's surprisingly entertaining. Try it!

Adnan Hodzic: Ubuntu Developer Summit (UDS-N) Debianized Summary

Last week I was on my first Ubuntu Developer Summit (UDS-N), I wanted to attended this summit for couple of reasons: 1. Developer, I m part of Debian Java, working on Eclipse IDE, and as you re developing Debian, you re automatically developing Ubuntu, no? Nerd 2. DebConf11 main organizer, I really wanted to see how it s all done on corporate level, for instance we re going with hotels instead of student dorms and so on. 3. Migration to Linux infrastructure, make contacts and have some talks on this topic, because after DebConf11 in Bosnia a lot of institution will most probably open doors to open solutions such as Linux. I went to this summit without any expectations or plans, just said I ll play it by ear. This years UDS was held in Orlando, Florida before Orlando I was planning to stay in NYC for couple of days, therefor my whole plan was to get to NYC, then Orlando then head back home Smile I Heart NYC I spent couple of days here with my cousins and friends, as always NYC never fails to surprise me, and I ll always stop by even if it s only for couple of days Wink I wanted to meet up with couple of Debian people as well, but unfortunately my schedule was too tight so Caribe Royale, Orlando Please note that this whole trip was crazy (in a good way) starting from Sarajevo; on my flight from NYC to Orlando I see a guy that s sitting in front of me is wearing Canonical Landscape tshirt, I approach him and it turns he was Jamu Kakar working on Landscape. Since my luggage was late we had conversations from Debian over Ubuntu to Java to everything pretty much. While we were still at the airport, we bump into two more people going to UDS. As we got to hotel, same moment we walked out of cab there he was Jorge Castro, was he there just to smoke a cigarette or whatever doesn t even matter, what matters is that even before walking into hotel building I knew where reception, my tower and bar was, everything I needed to know at that moment High Five! Hotel where everything was held was Caribe Royale and even though I looked at their website I thought there was no way it s all going to be that nice, to my delight it was exact replica. Place is All-Suite Hotel and Convention Center , which meant that both accomodation, venue and everything else was in one place which is Yes 15 minutes later after I checked in, I was at a bar talking to Jim Baker about Java, Jython and Python, exact things I wanted to talk about at that given moment. What I said in these last couple of paragraphs sounds pretty cool eh? Well to me this whole UDS was just like this, everybody was so accessible and open for discussion, from Jono Bacon walking around offering candy to UDS reception staff Michelle, Marianna and others who were always there whether you had a complaint, problem or a praise. I really should stop mentioning names, because I ll forget somebody, and since it s just not fair because I had a feeling everybody was just there for you, whatever it was you needed. Ubuntu Developer Summit (UDS-N) Ubuntu, Debian, DebConf, differences? Even though I said I ll play it by ear, from very beginning I thought I d be complete outsider, being part of Debian and all. Quite contrary, I was everything but outsider, and even more there was plenty of Debian people there, including current DPL Stefano Zacchiroli, Colin Watson, Riku Voipio just to name few. There was also a Debian Healt Check plenary. But overall, there are differences between DebConf and UDS. One of the things is that you can attend UDS remotely I m not sure how much is this doable on DebConf, but then again vast differences are that UDS is filled with BOF s (as we would call it in Debian) meetings of different teams, I attended a lot of these, and most of them end with some kind of conclusion. While each day there was (only?) an hour of lectures on various topics, which on DebConf we would characterize maybe even as speed talks . However, everything was high paced, and it all ended up on You think that s a problem? How do you think we could solve it? . I had a feeling even if I didn t say something out loud that someone would hear me and approach me to discuss it. Everything was straight forward, all in goal to resolve certain issue or a problem, which I absolutely loved. Clap Fun It wasn t all work, even though Orlando doesn t seem to be my kind of city from what I saw, it s way too magical for my taste Party There was a lot of places where you could go to enjoy yourself. Good people at Canonical even offered me free ticket to Disney World, there was a lot of destinations to visit and transpiration was also organized by Canonical. Unfortunately I missed the notorious UDS party on Friday because I had to head home early, but possibly I ll make it next year Razz Even though, hotel was that great and to be honest you didn t have to leave to look for party. My favorite was Universal City Walk, one night I decided to go to see Blue Man Group, best part of it was that I got pulled up on stage by one of the members and was part of one of the acts! ROTFL This is definitely something everyone should see during his life, one moment you re laughing like a lunatic, while other moment you re just having goose bumps from the performance itself. Amazing stuff. After all I wrote here along with the pictures, is there even anything else I need to say? Smile I believe that even if I didn t play it by ear, this whole trip would exceed all my expectations in every possible sense. Because that s really what happened, those three reasons I was going to UDS for? Far more happened than that. All I can say in the end is that I ll move closer to having a part in Ubuntu development, and yea, I ll try to be regular on UDS from now on Smile See you in Budapest? If all these photos weren t enough, you can find official group photo as well as personal set of photos can be found on: UDS-N photos by 2010 Sean Sosik-Hamor

29 October 2010

Colin Watson: libpipeline 1.0.0 released

In my previous post, I described the pipeline library from man-db and asked whether people were interested in a standalone release of it. Several people expressed interest, and so I've now released libpipeline version 1.0.0. It's in the Debian NEW queue, and my PPA contains packages of it for Ubuntu lucid and maverick. I gave a lightning talk on this at UDS in Orlando, and my slides are available. I hope there'll be a video at some point which I can link to. Thanks to Scott James Remnant for code review (some time back), Ian Jackson for an extensive design review, and Kees Cook and Matthias Klose for helpful conversations.

24 October 2010

Benjamin Mako Hill: Sharing an Email Address

I used to think that couples who share a single email address were just too cute. Then I saw this article which imported this whole "keeping each other honest" logic into the practice. Mika and I have never even had accounts on each other's servers.

18 October 2010

Benjamin Mako Hill: Redefining "Realistic"

When talking about free culture or free software, many people suggest that they would love to support free models, but that they don't see how to make it all work. Until they have an alternate model in front of them, they cannot bring themselves to argue for a more ethical alternative. I disagree with this approach. Instead, I say, "this is the world I want to live in and, even though I don't know exactly how to get to there from here, I'm going to refuse to settle for anything short of this ideal." Most people dismiss such thinking as "impractical" and "unrealistic." I think most people are being unimaginative. Robot jockeys are one recent illustrative reason, among many, that I feel comfortable taking this position. Some background is necessary for those that are unfamiliar with the example. A decade ago, several Gulf emirates used thousands of young boys from Sudan and South Asia as jockeys for camel racing. Human rights groups campaigned against the practice and suggested that these boys were at sometimes held as slaves and intentionally underfed to keep their weight low. Despite criticism, camel racers resisted moving away from young boys as jockeys. If they moved to heavier adults instead of young boys, they reasoned, the camels would be much slower. Of course, they were right. But they were being unimaginative in the alternatives they were considering. As the young jockeys became a increasingly unjustifiable public relations disaster for the states that supported it, law-makers in several Gulf states gave in to calls from UNICEF and others and created laws to outlaw the practice. Within three years of UAE passing strict laws against child jockeys, Swiss engineers, funded by racers desperate for an alternative, had created the first robotic camel jockey. Within several years these jockeys were lighter, cheaper, more responsive to the owner, and well on their way to being more effective than any young boy. When forced, by law and by an ethical prerogative, to come up with an alternative to young boys, racers created a solution that was superior, along nearly every axis, to the system they had fought to keep. Although the costs to society of proprietary software cannot be compared to slavery and abuse, the basic same pattern of solution-seeking can be seen in the example of free software. Early free software advocates suggested that most programmers would likely need to take a paycut. As it turned out, vibrant and successful economic models to support free software have supported a large and growing free software industry. But we have free software business models only because a small group of principled individuals refused to settle for what they knew, came up with creative ethical business models that "just might work," and put their own paychecks on the line to try them out. As open source has shown, some of these creative solutions offered models superior to what we had before. In the world of software development, free software redefined "practical" and "realistic." One can think of solving human problems as like searching for the highest point in hilly terrain in thick fog. It's easy to get stuck on the top of the first little hill you walk up (i.e., a local maximum) and then conclude you can never do better. If we refuse to compromise and force ourselves to leave that first little hill, chances are pretty good we'll find a "higher" peak. Of course, it is also possible that we will find the global maximum or the best possible solution to a given problem. In those cases, any change will mean a sacrifice. But when dealing with most most social and legal dilemmas, there are enough variables involved that this seems very unlikely. Indeed, most big problems can be thought of as having many interacting dimensions -- and only some of these will be ethical concerns. In other words, most social problems are more like the problem of child camel jockeys than they are like trying to transcend the laws of physics. Business models and laws for the regulation of technology and knowledge are extremely complicated human creations. Do we really think we cannot create ethical systems to compensate cultural creators that are at least as good as what we have now? If we never force ourselves to be "impractical" and "unrealistic", we will never find out.

15 October 2010

Enrico Zini: Award winning code

Award winning code Me and Yuwei had a fun day at hhhmcr (#hhhmcr) and even managed to put together a prototype that won the first prize \o/ We played with the gmp24 dataset kindly extracted from Twitter by Michael Brunton-Spall of the Guardian into a convenient JSON dataset. The idea was to find ways of making it easier to look at the data and making sense of it. This is the story of what we did, including the code we wrote. The original dataset has several JSON files, so the first task was to put them all together:
#!/usr/bin/python
# Merge the JSON data
# (C) 2010 Enrico Zini <enrico@enricozini.org>
# License: WTFPL version 2 (http://sam.zoy.org/wtfpl/)
import simplejson
import os
res = []
for f in os.listdir("."):
    if not f.startswith("gmp24"): continue
    data = open(f).read().strip()
    if data == "[]": continue
    parsed = simplejson.loads(data)
    res.extend(parsed)
print simplejson.dumps(res)
The results however were not ordered by date, as GMP had to use several accounts to twit because Twitter was putting Greather Manchester Police into jail for generating too much traffic. There would be quite a bit to write about that, but let's stick to our work. Here is code to sort the JSON data by time:
#!/usr/bin/python
# Sort the JSON data
# (C) 2010 Enrico Zini <enrico@enricozini.org>
# License: WTFPL version 2 (http://sam.zoy.org/wtfpl/)
import simplejson
import sys
import datetime as dt
all_recs = simplejson.load(sys.stdin)
all_recs.sort(key=lambda x: dt.datetime.strptime(x["created_at"], "%a %b %d %H:%M:%S +0000 %Y"))
simplejson.dump(all_recs, sys.stdout)
I then wanted to play with Tf-idf for extracting the most important words of every tweet:
#!/usr/bin/python
# tfifd - Annotate JSON elements with Tf-idf extracted keywords
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import sys, math
import simplejson
import re
# Read all the twits
records = simplejson.load(sys.stdin)
# All the twits by ID
byid = dict(((x["id"], x) for x in records))
# Stopwords we ignore
stopwords = set(["by", "it", "and", "of", "in", "a", "to"])
# Tokenising engine
re_num = re.compile(r"^\d+$")
re_word = re.compile(r"(\w+)")
def tokenise(tweet):
    "Extract tokens from a tweet"
    for tok in tweet["text"].split():
        tok = tok.strip().lower()
        if re_num.match(tok): continue
        mo = re_word.match(tok)
        if not mo: continue
        if mo.group(1) in stopwords: continue
        yield mo.group(1)
# Extract tokens from tweets
tokenised = dict(((x["id"], list(tokenise(x))) for x in records))
# Aggregate token counts
aggregated =  
for d in byid.iterkeys():
    for t in tokenised[d]:
        if t in aggregated:
            aggregated[t] += 1
        else:
            aggregated[t] = 1
def tfidf(doc, tok):
    "Compute TFIDF score of a token in a document"
    return doc.count(tok) * math.log(float(len(byid)) / aggregated[tok])
# Annotate tweets with keywords
res = []
for name, tweet in byid.iteritems():
    doc = tokenised[name]
    keywords = sorted(set(doc), key=lambda tok: tfidf(doc, tok), reverse=True)[:5]
    tweet["keywords"] = keywords
    res.append(tweet)
simplejson.dump(res, sys.stdout)
I thought this was producing a nice summary of every tweet but nobody was particularly interested, so we moved on to adding categories to tweet. Thanks to Yuwei who put together some useful keyword sets, we managed to annotate each tweet with a place name (i.e. "Stockport"), a social place name (i.e. "pub", "bank") and a social category (i.e. "man", "woman", "landlord"...) The code is simple; the biggest work in it was the dictionary of keywords:
#!/usr/bin/python
# categorise - Annotate JSON elements with categories
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
# Copyright (C) 2010  Yuwei Lin <yuwei@ylin.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import sys, math
import simplejson
import re
# Electoral wards from http://en.wikipedia.org/wiki/List_of_electoral_wards_in_Greater_Manchester
placenames = ["Altrincham", "Sale West",
"Altrincham", "Ashton upon Mersey", "Bowdon", "Broadheath", "Hale Barns", "Hale Central", "St Mary", "Timperley", "Village",
"Ashton-under-Lyne",
"Ashton Hurst", "Ashton St Michael", "Ashton Waterloo", "Droylsden East", "Droylsden West", "Failsworth East", "Failsworth West", "St Peter",
"Blackley", "Broughton",
"Broughton", "Charlestown", "Cheetham", "Crumpsall", "Harpurhey", "Higher Blackley", "Kersal",
"Bolton North East",
"Astley Bridge", "Bradshaw", "Breightmet", "Bromley Cross", "Crompton", "Halliwell", "Tonge with the Haulgh",
"Bolton South East",
"Farnworth", "Great Lever", "Harper Green", "Hulton", "Kearsley", "Little Lever", "Darcy Lever", "Rumworth",
"Bolton West",
"Atherton", "Heaton", "Lostock", "Horwich", "Blackrod", "Horwich North East", "Smithills", "Westhoughton North", "Chew Moor", "Westhoughton South",
"Bury North",
"Church", "East", "Elton", "Moorside", "North Manor", "Ramsbottom", "Redvales", "Tottington",
"Bury South",
"Besses", "Holyrood", "Pilkington Park", "Radcliffe East", "Radcliffe North", "Radcliffe West", "St Mary", "Sedgley", "Unsworth",
"Cheadle",
"Bramhall North", "Bramhall South", "Cheadle", "Gatley", "Cheadle Hulme North", "Cheadle Hulme South", "Heald Green", "Stepping Hill",
"Denton", "Reddish",
"Audenshaw", "Denton North East", "Denton South", "Denton West", "Dukinfield", "Reddish North", "Reddish South",
"Hazel Grove",
"Bredbury", "Woodley", "Bredbury Green", "Romiley", "Hazel Grove", "Marple North", "Marple South", "Offerton",
"Heywood", "Middleton",
"Bamford", "Castleton", "East Middleton", "Hopwood Hall", "Norden", "North Heywood", "North Middleton", "South Middleton", "West Heywood", "West Middleton",
"Leigh",
"Astley Mosley Common", "Atherleigh", "Golborne", "Lowton West", "Leigh East", "Leigh South", "Leigh West", "Lowton East", "Tyldesley",
"Makerfield",
"Abram", "Ashton", "Bryn", "Hindley", "Hindley Green", "Orrell", "Winstanley", "Worsley Mesnes",
"Manchester Central",
"Ancoats", "Clayton", "Ardwick", "Bradford", "City Centre", "Hulme", "Miles Platting", "Newton Heath", "Moss Side", "Moston",
"Manchester", "Gorton",
"Fallowfield", "Gorton North", "Gorton South", "Levenshulme", "Longsight", "Rusholme", "Whalley Range",
"Manchester", "Withington",
"Burnage", "Chorlton", "Chorlton Park", "Didsbury East", "Didsbury West", "Old Moat", "Withington",
"Oldham East", "Saddleworth",
"Alexandra", "Crompton", "Saddleworth North", "Saddleworth South", "Saddleworth West", "Lees", "St James", "St Mary", "Shaw", "Waterhead",
"Oldham West", "Royton",
"Chadderton Central", "Chadderton North", "Chadderton South", "Coldhurst", "Hollinwood", "Medlock Vale", "Royton North", "Royton South", "Werneth",
"Rochdale",
"Balderstone", "Kirkholt", "Central Rochdale", "Healey", "Kingsway", "Littleborough Lakeside", "Milkstone", "Deeplish", "Milnrow", "Newhey", "Smallbridge", "Firgrove", "Spotland", "Falinge", "Wardle", "West Littleborough",
"Salford", "Eccles",
"Claremont", "Eccles", "Irwell Riverside", "Langworthy", "Ordsall", "Pendlebury", "Swinton North", "Swinton South", "Weaste", "Seedley",
"Stalybridge", "Hyde",
"Dukinfield Stalybridge", "Hyde Godley", "Hyde Newton", "Hyde Werneth", "Longdendale", "Mossley", "Stalybridge North", "Stalybridge South",
"Stockport",
"Brinnington", "Central", "Davenport", "Cale Green", "Edgeley", "Cheadle Heath", "Heatons North", "Heatons South", "Manor",
"Stretford", "Urmston",
"Bucklow-St Martins", "Clifford", "Davyhulme East", "Davyhulme West", "Flixton", "Gorse Hill", "Longford", "Stretford", "Urmston",
"Wigan",
"Aspull New Springs Whelley", "Douglas", "Ince", "Pemberton", "Shevington with Lower Ground", "Standish with Langtree", "Wigan Central", "Wigan West",
"Worsley", "Eccles South",
"Barton", "Boothstown", "Ellenbrook", "Cadishead", "Irlam", "Little Hulton", "Walkden North", "Walkden South", "Winton", "Worsley",
"Wythenshawe", "Sale East",
"Baguley", "Brooklands", "Northenden", "Priory", "Sale Moor", "Sharston", "Woodhouse Park"]
# Manual coding from Yuwei
placenames.extend(["City centre", "Tameside", "Oldham", "Bury", "Bolton",
"Trafford", "Pendleton", "New Moston", "Denton", "Eccles", "Leigh", "Benchill",
"Prestwich", "Sale", "Kearsley", ])
placenames.extend(["Trafford", "Bolton", "Stockport", "Levenshulme", "Gorton",
"Tameside", "Blackley", "City centre", "Airport", "South Manchester",
"Rochdale", "Chorlton", "Uppermill", "Castleton", "Stalybridge", "Ashton",
"Chadderton", "Bury", "Ancoats", "Whalley Range", "West Yorkshire",
"Fallowfield", "New Moston", "Denton", "Stretford", "Eccles", "Pendleton",
"Leigh", "Altrincham", "Sale", "Prestwich", "Kearsley", "Hulme", "Withington",
"Moss Side", "Milnrow", "outskirt of Manchester City Centre", "Newton Heath",
"Wythenshawe", "Mancunian Way", "M60", "A6", "Droylesden", "M56", "Timperley",
"Higher Ince", "Clayton", "Higher Blackley", "Lowton", "Droylsden",
"Partington", "Cheetham Hill", "Benchill", "Longsight", "Didsbury",
"Westhoughton"])
# Social categories from Yuwei
soccat = ["man", "woman", "men", "women", "youth", "teenager", "elderly",
"patient", "taxi driver", "neighbour", "male", "tenant", "landlord", "child",
"children", "immigrant", "female", "workmen", "boy", "girl", "foster parents",
"next of kin"]
for i in range(100):
    soccat.append("%d-year-old" % i)
    soccat.append("%d-years-old" % i)
# Types of social locations from Yuwei
socloc = ["car park", "park", "pub", "club", "shop", "premises", "bus stop",
"property", "credit card", "supermarket", "garden", "phone box", "theatre",
"toilet", "building site", "Crown court", "hard shoulder", "telephone kiosk",
"hotel", "restaurant", "cafe", "petrol station", "bank", "school",
"university"]
extras =   "placename": placenames, "soccat": soccat, "socloc": socloc  
# Normalise keyword lists
for k, v in extras.iteritems():
    # Remove duplicates
    v = list(set(v))
    # Sort by length
    v.sort(key=lambda x:len(x), reverse=True)
# Add keywords
def add_categories(tweet):
    text = tweet["text"].lower()
    for field, categories in extras.iteritems():
        for cat in categories:
            if cat.lower() in text:
                tweet[field] = cat
                break
    return tweet
# Read all the twits
records = (add_categories(x) for x in simplejson.load(sys.stdin))
simplejson.dump(list(records), sys.stdout)
All these scripts form a nice processing chain: each script takes a list of JSON records, adds some bit and passes it on. In order to see what we have so far, here is a simple script to convert the JSON twits to CSV so they can be viewed in a spreadsheet:
#!/usr/bin/python
# Convert the JSON twits to CSV
# (C) 2010 Enrico Zini <enrico@enricozini.org>
# License: WTFPL version 2 (http://sam.zoy.org/wtfpl/)
import simplejson
import sys
import csv
rows = ["id", "created_at", "text", "keywords", "placename"]
writer = csv.writer(sys.stdout)
for rec in simplejson.load(sys.stdin):
    rec["keywords"] = " ".join(rec["keywords"])
    rec["placename"] = rec.get("placename", "")
    writer.writerow([rec[row] for row in rows])
At this point we were coming up with lots of questions: "were there more reports on women or men?", "which place had most incidents?", "what were the incidents involving animals?"... Time to bring Xapian into play. This script reads all the JSON tweets and builds a Xapian index with them:
#!/usr/bin/python
# toxapian - Index JSON tweets in Xapian
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import simplejson
import sys
import os, os.path
import xapian
DBNAME = sys.argv[1]
db = xapian.WritableDatabase(DBNAME, xapian.DB_CREATE_OR_OPEN)
stemmer = xapian.Stem("english")
indexer = xapian.TermGenerator()
indexer.set_stemmer(stemmer)
indexer.set_database(db)
data = simplejson.load(sys.stdin)
for rec in data:
    doc = xapian.Document()
    doc.set_data(str(rec["id"]))
    indexer.set_document(doc)
    indexer.index_text_without_positions(rec["text"])
    # Index categories as categories
    if "placename" in rec:
        doc.add_boolean_term("XP" + rec["placename"].lower())
    if "soccat" in rec:
        doc.add_boolean_term("XS" + rec["soccat"].lower())
    if "socloc" in rec:
        doc.add_boolean_term("XL" + rec["socloc"].lower())
    db.add_document(doc)
db.flush()
# Also save the whole dataset so we know where to find it later if we want to
# show the details of an entry
simplejson.dump(data, open(os.path.join(DBNAME, "all.json"), "w"))
And this is a simple command line tool to query to the database:
#!/usr/bin/python
# xgrep - Command line tool to query the GMP24 tweet Xapian database
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import simplejson
import sys
import os, os.path
import xapian
DBNAME = sys.argv[1]
db = xapian.Database(DBNAME)
stem = xapian.Stem("english")
qp = xapian.QueryParser()
qp.set_default_op(xapian.Query.OP_AND)
qp.set_database(db)
qp.set_stemmer(stem)
qp.set_stemming_strategy(xapian.QueryParser.STEM_SOME)
qp.add_boolean_prefix("place", "XP")
qp.add_boolean_prefix("soc", "XS")
qp.add_boolean_prefix("loc", "XL")
query = qp.parse_query(sys.argv[2],
    xapian.QueryParser.FLAG_BOOLEAN  
    xapian.QueryParser.FLAG_LOVEHATE  
    xapian.QueryParser.FLAG_BOOLEAN_ANY_CASE  
    xapian.QueryParser.FLAG_WILDCARD  
    xapian.QueryParser.FLAG_PURE_NOT  
    xapian.QueryParser.FLAG_SPELLING_CORRECTION  
    xapian.QueryParser.FLAG_AUTO_SYNONYMS)
enquire = xapian.Enquire(db)
enquire.set_query(query)
count = 40
matches = enquire.get_mset(0, count)
estimated = matches.get_matches_estimated()
print "%d/%d results" % (matches.size(), estimated)
data = dict((str(x["id"]), x) for x in simplejson.load(open(os.path.join(DBNAME, "all.json"))))
for m in matches:
    rec = data[m.document.get_data()]
    print rec["text"]
print "%d/%d results" % (matches.size(), matches.get_matches_estimated())
total = db.get_doccount()
estimated = matches.get_matches_estimated()
print "%d results over %d documents, %d%%" % (estimated, total, estimated * 100 / total)
Neat! Now that we have a proper index that supports all sort of cool things, like stemming, tag clouds, full text search with complex queries, lookup of similar documents, suggest keywords and so on, it was just fair to put together a web service to share it with other people at the event. It helped that I had already written similar code for apt-xapian-index and dde before. Here is the server, quickly built on bottle. The very last line starts the server and it is where you can configure the listening interface and port.
#!/usr/bin/python
# xserve - Make the GMP24 tweet Xapian database available on the web
#
# Copyright (C) 2010  Enrico Zini <enrico@enricozini.org>
#
# This program is free software: you can redistribute it and/or modify
# it under the terms of the GNU General Public License as published by
# the Free Software Foundation, either version 3 of the License, or
# (at your option) any later version.
#
# This program is distributed in the hope that it will be useful,
# but WITHOUT ANY WARRANTY; without even the implied warranty of
# MERCHANTABILITY or FITNESS FOR A PARTICULAR PURPOSE.  See the
# GNU General Public License for more details.
#
# You should have received a copy of the GNU General Public License
# along with this program.  If not, see <http://www.gnu.org/licenses/>.
import bottle
from bottle import route, post
from cStringIO import StringIO
import cPickle as pickle
import simplejson
import sys
import os, os.path
import xapian
import urllib
import math
bottle.debug(True)
DBNAME = sys.argv[1]
QUERYLOG = os.path.join(DBNAME, "queries.txt")
data = dict((str(x["id"]), x) for x in simplejson.load(open(os.path.join(DBNAME, "all.json"))))
prefixes =   "place": "XP", "soc": "XS", "loc": "XL"  
prefix_desc =   "place": "Place name", "soc": "Social category", "loc": "Social location"  
db = xapian.Database(DBNAME)
stem = xapian.Stem("english")
qp = xapian.QueryParser()
qp.set_default_op(xapian.Query.OP_AND)
qp.set_database(db)
qp.set_stemmer(stem)
qp.set_stemming_strategy(xapian.QueryParser.STEM_SOME)
for k, v in prefixes.iteritems():
    qp.add_boolean_prefix(k, v)
def make_query(qstring):
    return qp.parse_query(qstring,
        xapian.QueryParser.FLAG_BOOLEAN  
        xapian.QueryParser.FLAG_LOVEHATE  
        xapian.QueryParser.FLAG_BOOLEAN_ANY_CASE  
        xapian.QueryParser.FLAG_WILDCARD  
        xapian.QueryParser.FLAG_PURE_NOT  
        xapian.QueryParser.FLAG_SPELLING_CORRECTION  
        xapian.QueryParser.FLAG_AUTO_SYNONYMS)
@route("/")
def index():
    query = urllib.unquote_plus(bottle.request.GET.get("q", ""))
    out = StringIO()
    print >>out, '''
<html>
<head>
<title>Query</title>
<script src="http://ajax.googleapis.com/ajax/libs/jquery/1.4.2/jquery.min.js"></script>
<script type="text/javascript">
$(function() 
    $("#queryfield")[0].focus()
 )
</script>
</head>
<body>
<h1>Search</h1>
<form method="POST" action="/query">
Keywords: <input type="text" name="query" value="%s" id="queryfield">
<input type="submit">
<a href="http://xapian.org/docs/queryparser.html">Help</a>
</form>''' % query
    print >>out, '''
<p>Example: "car place:wigan"</p>

<p>Available prefixes:</p>

<ul>
'''
    for pfx in prefixes.keys():
        print >>out, "<li><a href='/catinfo/%s'>%s - %s</a></li>" % (pfx, pfx, prefix_desc[pfx])
    print >>out, '''
</ul>
'''
    oldqueries = []
    if os.path.exists(QUERYLOG):
        total = db.get_doccount()
        fd = open(QUERYLOG, "r")
        while True:
            try:
                q = pickle.load(fd)
            except EOFError:
                break
            oldqueries.append(q)
        fd.close()
        def print_query(q):
            count = q["count"]
            print >>out, "<li><a href='/query?query=%s'>%s (%d/%d %.2f%%)</a></li>" % (urllib.quote_plus(q["q"]), q["q"], count, total, count * 100.0 / total)
        print >>out, "<p>Last 10 queries:</p><ul>"
        for q in oldqueries[:-10:-1]:
            print_query(q)
        print >>out, "</ul>"
        # Remove duplicates
        oldqueries = dict(((x["q"], x) for x in oldqueries)).values()
        print >>out, "<table>"
        print >>out, "<tr><th>10 queries with most results</th><th>10 queries with least results</th></tr>"
        print >>out, "<tr><td>"
        print >>out, "<ul>"
        oldqueries.sort(key=lambda x:x["count"], reverse=True)
        for q in oldqueries[:10]:
            print_query(q)
        print >>out, "</ul>"
        print >>out, "</td><td>"
        print >>out, "<ul>"
        nonempty = [x for x in oldqueries if x["count"] > 0]
        nonempty.sort(key=lambda x:x["count"])
        for q in nonempty[:10]:
            print_query(q)
        print >>out, "</ul>"
        print >>out, "</td></tr>"
        print >>out, "</table>"
    print >>out, '''
</body>
</html>'''
    return out.getvalue()
@route("/query")
@route("/query/")
@post("/query")
@post("/query/")
def query():
    query = bottle.request.POST.get("query", bottle.request.GET.get("query", ""))
    enquire = xapian.Enquire(db)
    enquire.set_query(make_query(query))
    count = 40
    matches = enquire.get_mset(0, count)
    estimated = matches.get_matches_estimated()
    total = db.get_doccount()
    out = StringIO()
    print >>out, '''
<html>
<head><title>Results</title></head>
<body>
<h1>Results for "<b>%s</b>"</h1>
''' % query
    if estimated == 0:
        print >>out, "No results found."
    else:
        # Give as results the first 30 documents; also use them as the key
        # ones to use to compute relevant terms
        rset = xapian.RSet()
        for m in enquire.get_mset(0, 30):
            rset.add_document(m.document.get_docid())
        # Compute the tag cloud
        class NonTagFilter(xapian.ExpandDecider):
            def __call__(self, term):
                return not term[0].isupper() and not term[0].isdigit()
        cloud = []
        maxscore = None
        for res in enquire.get_eset(40, rset, NonTagFilter()):
            # Normalise the score in the interval [0, 1]
            weight = math.log(res.weight)
            if maxscore == None: maxscore = weight
            tag = res.term
            cloud.append([tag, float(weight) / maxscore])
        max_weight = cloud[0][1]
        min_weight = cloud[-1][1]
        cloud.sort(key=lambda x:x[0])
        def mklink(query, term):
            return "/query?query=%s" % urllib.quote_plus(query + " and " + term)
        print >>out, "<h2>Tag cloud</h2>"
        print >>out, "<blockquote>"
        for term, weight in cloud:
            size = 100 + 100.0 * (weight - min_weight) / (max_weight - min_weight)
            print >>out, "<a href='%s' style='font-size:%d%%; color:brown;'>%s</a>" % (mklink(query, term), size, term)
        print >>out, "</blockquote>"
        print >>out, "<h2>Results</h2>"
        print >>out, "<p><a href='/'>Search again</a></p>"
        print >>out, "<p>%d results over %d documents, %.2f%%</p>" % (estimated, total, estimated * 100.0 / total)
        print >>out, "<p>%d/%d results</p>" % (matches.size(), estimated)
        print >>out, "<ul>"
        for m in matches:
            rec = data[m.document.get_data()]
            print >>out, "<li><a href='/item/%s'>%s</a></li>" % (rec["id"], rec["text"])
        print >>out, "</ul>"
        fd = open(QUERYLOG, "a")
        qinfo = dict(q=query, count=estimated)
        pickle.dump(qinfo, fd)
        fd.close()
    print >>out, '''
<a href="/">Search again</a>

</body>
</html>'''
    return out.getvalue()
@route("/item/:id")
@route("/item/:id/")
def show(id):
    rec = data[id]
    out = StringIO()
    print >>out, '''
<html>
<head><title>Result %s</title></head>
<body>
<h1>Raw JSON record for twit %s</h1>
<pre>''' % (rec["id"], rec["id"])
    print >>out, simplejson.dumps(rec, indent=" ")
    print >>out, '''
</pre>
</body>
</html>'''
    return out.getvalue()
@route("/catinfo/:name")
@route("/catinfo/:name/")
def catinfo(name):
    prefix = prefixes[name]
    out = StringIO()
    print >>out, '''
<html>
<head><title>Values for %s</title></head>
<body>
''' % name
    terms = [(x.term[len(prefix):], db.get_termfreq(x.term)) for x in db.allterms(prefix)]
    terms.sort(key=lambda x:x[1], reverse=True)
    freq_min = terms[0][1]
    freq_max = terms[-1][1]
    def mklink(name, term):
        return "/query?query=%s" % urllib.quote_plus(name + ":" + term)
    # Build tag cloud
    print >>out, "<h1>Tag cloud</h1>"
    print >>out, "<blockquote>"
    for term, freq in sorted(terms[:20], key=lambda x:x[0]):
        size = 100 + 100.0 * (freq - freq_min) / (freq_max - freq_min)
        print >>out, "<a href='%s' style='font-size:%d%%; color:brown;'>%s</a>" % (mklink(name, term), size, term)
    print >>out, "</blockquote>"
    print >>out, "<h1>All terms</h1>"
    print >>out, "<table>"
    print >>out, "<tr><th>Occurrences</th><th>Name</th></tr>"
    for term, freq in terms:
        print >>out, "<tr><td>%d</td><td><a href='/query?query=%s'>%s</a></td></tr>" % (freq, urllib.quote_plus(name + ":" + term), term)
    print >>out, "</table>"
    print >>out, '''
</body>
</html>'''
    return out.getvalue()
# Change here for bind host and port
bottle.run(host="0.0.0.0", port=8024)
...and then we presented our work and ended up winning the contest. This was the story of how we wrote this set of award winning code.

14 October 2010

Axel Beckert: Thoughts on Gitorious and GitHub plus a useful git hook

When I took over the developement of xen-tools, I looked around for an appropriate git hosting. I especially had a look at GitHub and Gitorious. If you just regard the features, GitHub is definitely more targetted on single developers and Gitorious more towards projects: At GitHub, every repository has its URL under the URL of a user page which makes it nearly impossible to have user independent, official repositories for projects which have more than one official developer. At Gitorious, every hosted repository needs to belong to a project, even if it s only a published configuration. But a project can have more than one git repository. You only seem to be able to have personal repositories if you clone some existing Gitorious repository. So from a feature point of view, the xen-tools git repositories fit way better to Gitorious hosting while the git repositories with zshrc, conkerorrc and desktop configuration files defintely have a more fitting addresses on GitHub, in my case http://github.com/xtaran/$repository. On Gitorious, they are now together under a project called Axel s configuration files at http://gitorious.org/abe which contains git repositories of my on grml s .zshrc based .zshrc, my configuration for Conkeror and all the files necessary for my ratpoison/xmobar based netbook/laptop desktop. I though feel a little bad for giving the project the very short slug name abe instead of abe-config (as I did initially) since abe is IMHO not a proper project name for my configuration files and possibly other projects would have a more reasonable claim for that project name on Gitorious. But that way it suites more its purpose: Gather some of my git repositories which don t belong to a proper project. But there s another important point when comparing Gitorious and GitHub: Free Software needs free tools as Benjamin Mako Hill posted recently on Planet Debian. Despite my (probably well known) distrust against Google and therefore also Google Code, and despite knowing the history of SourceForge becoming non-free, I was not that much aware that GitHub s software is only partially open source and therefore also not free software while Gitorious is both as it s licensed under the GNU Affero General Public License (like StatusNet/identi.ca for example) which is basically GPLv3, but its ideas applied to hosted web applications scenario (where the GPL itself doesn t grasp), too. Initially I just had the xen-tools git repositories on Gitorious and all my small one-repository projects as copies of the repositories on my own git server on GitHub to get some more publicity for them and allow social cloning . After reading Mako s article, I decided to at least have repository clones on Gitorious of all repositories I mirror at GitHub, too. That way I force nobody to use the non-free tools on GitHub for social cloning one of my git repositories. And of course I have copies of my code somewhere on the net as backup. Or to say it with Linus Torvalds (slightly updated) words: Only wimps use tape backup: real men just upload their important stuff on git, and let the rest of the world clone it. ;-) But isn t that tedious to always push your code to three repositories? No, it isn t. I just push my code to git.noone.org where I have configured the according remotes and the following post-receive hook:
#!/bin/sh
                                                                     
read oldrev newrev refname
git push gitorious $ refname:t 
git push github $ refname:t 
The only other thing necessary is to use ssh-agent and SSH agent forwarding to at least the host you re pushing to.

Russell Coker: Links October 2010

Bruce Schneier wrote an insightful post about why designing products for wiretapping is a bad idea [1]. It seems that large parts of the Internet will be easy to tap (for both governments and criminals) in the near future unless something is done. The bad results of criminal use will outweigh any benefits of government use. Sam Watkins wrote an informative post about Android security [2]. Among other things any application can read all stored data including all photos, that s got to be a problem for anyone who photographs themself naked Rebecca Saxe gave an interesting TED talk about how brains make moral judgements [3]. Somehow she managed to speak about the Theory of Mind without mentioning Autism once. The Guardian has an amusing article by Cory Doctorow about security policies in banks [4]. He advocates promoting statistical literacy (or at least not promoting a lack of it) as a sound government policy. He also suggests allowing regulators to fine banks that get it wrong. Steven Johnson gave an interesting TED talk about Where Good Ideas Come From [5]. It s a bit slow at the start but gets good at the end. Adam Grosser gave an interesting TED talk about a fridge that was designed for use in Africa [6]. The core of the Absorption Refrigerator is designed to be heated in a pot of water in a cooking fire and it can then keep food cool for 12 hours. It s a pity that they couldn t design it to work on solar power to avoid the fuel use for the cooking fire. Josh Silver gave an interesting TED talk about liquid filled spectacles [7]. The glasses are shipped with a syringe filled with liquid at each side that is used to inflate the lenses to the desired refractive index. The wearer can just adjust the syringes until they get to the right magnification, as there are separate syringes the glasses work well with people who s eyes aren t identical (which is most people). Once the syringes are at the right spots the user can tighten some screws to prevent further transfer of liquid and cut the syringes off to give glasses that aren t overly heavy but which can t be adjusted any more, I guess that a natural extension to this would be to allow the syringes to be re-attached so that the user could adjust them every year to match declining vision. One thing that this wouldn t do is counter for Astigmatism (where the lens of the eye doesn t focus light to a point), but I guess they could make lenses to deal with a few common varieties of Astigmatism so that most people who have that problem can get a reasonable approximation. The current best effort is to make the glasses cost $19, which is 19 days salary for some of the poorest people in the world. Glasses in Australia cost up to $650 for a pair (or a more common cost of $200 or about $100 after Medicare) which would be about one day s salary. Eben Bayer gave an inspiring TED talk about one of the ways that mushrooms can save the planet [8]. He has designed molds that can be filled with Pasteurised organic waste (seed husks etc) and then seeded with fungal spores. The fungus then grows mycelium (thin fungal root fibers) through the organic waste making it into a solid structure which fits the shape of the mold. This is currently being used to replace poly-styrene foam for packaging and can apparently be used for making tiles that are fire retardant and sound proof for constructing buildings. The main benefits of the material are that it can be cheaply made without petrochemicals and that it is bio-degradable, I m not sure how the bio-degradable part would work with constructing buildings maybe they would just replace the panels every few years. Annie Lennox gave a TED talk about her Sing foundation to care for women and children who are affected by AIDS [9]. She describes the effect of AIDS in Africa as Genocide. Robert Ballard gave a very informative TED talk about exploring the oceans [10]. This was one of the most informative TED talks I ve seen and Robert is also one of the most enthusiastic speakers I ve seen, it s really worth watching! We really need more money spent on exploring the oceans. Jessa Gamble gave an interesting TED talk which suggests that the best thing to do is to go to bed at about sunset and then have a couple of hours of relaxing time during the middle of the night [11]. Apparently the subjects of body-block experiments who live for a month in a bunker without natural light or access to a clock get better sleep in this manner than they ever had in their life and feel fully awake for the first time. World Changing is a blog that has a lot of interesting articles about climate change and related issues [12]. It s worth a read. Cynthia Schneider gave an interesting TED talk about how reality competition TV is affecting reality [13]. Shows that are derived from the American Idol concept are driving a resurgence in some traditional forms of performance art while also promoting equality among other things it s apparent that winning is more important than misogyny. The Ritual of the Calling of an Engineer is an interesting concept [14]. I think it would be good to have something similar for Computer Science. Benjamin Mako Hill wrote an interesting and insightful essay about Piracy and Free Software [15].

13 October 2010

Cyril Brulebois: How many

How many bugs can be filed at once? 55 bugs in a row, so that the desired bug number is reached. It took some time to prepare all those reports, which eventually resulted in 55 successive bug numbers, on top of last-reported #599945 at the time, ta-da! I love it when a plan comes together! Just as a reminder, the main idea behind those bug reports is to get as many FTBFSes as possible reported, as previous mentioned. How many X packages can be uploaded between two dinstall runs? 14 packages. Now that things are settling down a bit on the squeeze front, I managed to have a look at X Server 1.9 (more precisely, 1.9.0.901 aka 1.9.1 rc1), which had already been worked on by Christopher James Halse Rogers (thanks!). Uploaded source packages include: So, what about the major (ati/radeon, intel, and nouveau) drivers? More on that later; if you want to test 1.9 with those, pick xserver-xorg-dev from experimental and build your driver against it. Hopefully only a few days should pass before you get an update on that topic. How many times did this blog go haywire? Possibly none, even though it was recently reworked so that http://ikibiki.org/ and http://blog.ikibiki.org/ are distinct. Some d-i or xorg tags may be added to older posts when time allows, but those shouldn t pop up in planet again. Flattr this!

11 October 2010

Benjamin Mako Hill: Piracy and Free Software

This essay is a summary of my presentation at the workshop Inlaws and Outlaws, held on August 19-20, 2010 in Split, Croatia. The workshop brought together advocates of piracy with participants in the free culture and free software movements.
In Why Software Should Not Have Owners, Richard Stallman explains that, if a friend asks you for a piece of software and the license of the software bars you from sharing, you will have to choose between being a bad friend or violating the license of the software. Stallman suggests that users will have to choose between the lesser of two evils and will choose to violate the license. He emphasizes that it's unfair to ask a user to make such a choice. Over the past few years, pirate parties have grown across much of the developed world. Of course, piracy remains the primary means of distributing media across most of the rest. Advocates of access to information have gathered and organized under the "pirate" banner, representing the choice of sharing with friends over compliance with license terms. The free/libre and open source software (FLOSS) and free culture movements seem to have a confused and conflicted reaction to all this. On one hand, major proponents of several pirate parties are FLOSS and free culture stalwarts and several pirate parties have made FLOSS advocacy a component of their political platforms. Pirate Parties' clear opposition to software patents and DRM resonates with both FLOSS and free culture communities. On the other hand, FLOSS leaders, including Stallman, have warned us about "pirate" anti-copyright policies. Free culture leaders, like Lawrence Lessig, have repeatedly and vociferously denounced piracy, treated even the intimation of an association with piracy as an affront, and systematically distanced themselves and their work from piracy. Should FLOSS and free culture advocates embrace pirates as comrades in arms or condemn them? Must we choose between being either with the pirates or against them? Our communities seem to have no clearly and consistently articulated consensus. I believe that, unintuitively, if you take a strong principled position in favor of information freedom and distinguish between principles and tactics, a more nuanced "middle ground" response to piracy is possible. In light of a principled belief that users should be able to share information, we can conclude there is nothing ethically wrong with piracy. Licenses have the power of the law but they are protected by unjust "intellectual property" laws. That said, principles are not the only reason activists choose to do things. Many political stunts are bad ideas not because they are wrong, but because they won't work and have negative side effects. Tactics matter too. Even though there might not be anything ethically wrong with piracy from the perspective of free software or free culture, it might still be a bad idea. There are at least three such tactical reasons that might motivate free software and culture to not support piracy or participate in pro-piracy movements and politics. First, a systematic disrespect for copyright undermines respect for all licenses which have been of a huge tactical benefit to free software and a increasingly important factor in the success of free culture. Copyleft licenses like the GPL or CC BY-SA have power only because copyright does. As Stallman has suggested, anti-copyright actions are anti-copyleft. That needn't be an argument against attempts to limit copyright. Indeed, I think we must limit and reduce copyright. But we must tread carefully. In the current copyright climate, I believe that copyleft offers a net advantage. Why should others respect our licenses if we don't respect theirs? Looking at the long term, we must weigh the benefits of promoting the systematic violation of proprietary licenses with the benefits of adherence to free software and free culture. Second, piracy is fundamentally reactionary. Part of its resonance as a political symbol comes from the fact that the piracy represents a way that consumers of media can fight back against a set of companies which have attacked them -- with lawsuits, DRM systems, and demonization in propaganda -- for sharing in ways that most consumers think are natural and socially positive. But piracy focuses on reaction rather the fundamental importance of sharing that drives it. As a result, most pirates do not support, or are even familiar with, a principled approach to access to information. As a result, many piracy advocates who speak out against DRM on DVDs will be as happy to use NetFlix to stream DRMed movies for $5 a month as they were to download for free. The best rallying cries do not always translate into be the most robust movements. Third, through its focus on a reaction, a dialog about piracy avoids engagement with the tough questions of what we will replace the current broken copyright system with. A principled position suggests that it is our ethical prerogative to create alternative models. The free software movement has succeeded because it created such a prerogative and then, slowly over time, provided examples of workable alternatives. A principled position on free software did not require that one provide working new systems immediately, but it makes the development of creative, sustainable approaches a priority. Attacking the system without even trying to speak about alternative modes of production is unsustainable. Free software and free culture call for a revolution. Piracy only calls for a riot. Piracy, in these three senses, can be seen as tactically unwise, without necessarily being unethical. By taking a principled position, one can go build on, and go beyond, RMS's comment. On free culture and free software's terms, we can suggest that piracy is not ethically wrong, but that it is an unwise way to try to promote sharing. Without being hypocritical, we can say: "I don't think piracy is unethical. But I also do not support it."

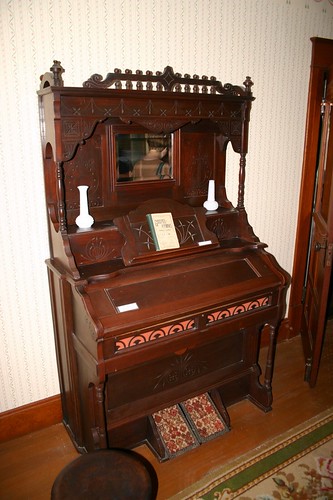
John Goerzen: Pump Organs and Music

Two years ago, I wrote about Elvera Voth and the power of love. Back then I wrote about her memories of seeing of service workers, who would be away from their home for 7 years at a time. Elvera remembered a gathering of people at the train station to see them off, and how they sang some German hymns at the occasion. Elvera s done a lot since, including starting an arts in prison program. And today, she hosted a hymn sing at the pump organ in the Friesen House parlor. img_4305.jpg The Friesen House is nearly 100 years old, and was on my parents property before it got moved to the Mennonite Heritage and Agricultural Museum. We were among maybe 20 people that showed up for the event. We walked in a few minutes early and Elvera was sitting at the organ already, along with a few other early arrivals. Many of the people there were over 70, and the moment we walked in, she said, Oh good! Another generation! And, of course, asked about us, where we live, who we are related to, etc. The announcement in our church bulletin said to bring a copy of Gesangbuch mit Noten if you have one. That was a common hymn book in Mennonite churches in Kansas (songbook with notes and yes, there was one without notes that had only words.) I pulled out my copy, and just opened it up. I saw my grandma s beautiful handwriting saying it belonged to Mr. and Mrs. R. A. Klassen . This I brought along, but was perhaps the only one. Elvera recognized it and was pleased to hear where it came from. We had a great time, and it turned out to feel like the kind of afternoon people around here used to have: time with friends and family visiting and maybe singing on occasion. After some introduction and some stories, we got to the singing and started with hymn #1 in the 1969 (English) Mennonite Hymnal. That song had German words below as well, which we sang: Grosser Gott, wir loben dich! (Holy God, We Praise Thy Name) Elvera played the organ while we all sang. And then we turned to #556, O Have You Not Heard. We read through the German lyrics (to help those that don t speak German):
Ich weiss einen Strom, dessen herrliche Flut
fliesst wunderbar stille durchs Land,
doch strahlet und gl nzt er wie feurige Glut,
wem ist dieses W sser bekannt? O Seele, ich bitte dich: Komm!
Und such diesen herrlichen Strom!
Sein Wasser fliesst frei und m chtiglich,
o glaub s, es fliesset f r dich!
Elvera translated this herself, a much more powerful translation than we usually get in English. And then we sang, this time a cappella. Elvera told the story about the train station to this group, and then, of course, we sang O Power of Love, one of the songs sung on that occasion. For that, she asked us to stand up and form a circle around the organ, and again we sang mostly a cappella. Singing that song with Elvera left few dry eyes in the room for sure. Someone brought up Nun Ist Sie Erschienen, and so of course we sang that. It wasn t in any hymnal, but I suspect we were the only ones there that didn t have it completely memorized. Elvera told us the story of the museum s pump organ; it had been in her family, and she had paid to have it restored and eventually donated it to the museum. It had been used every evening at twilight for singing and devotions in the family. She also told us that the singing at the Newton train station the same one our family uses a few times a year was what inspired her to a career of choral music. In the end, we probably spent more time visiting than singing, but that was just fine. Next the group went over to the Preparatory School, an old schoolhouse also on the museum grounds. There we had a traditional Faspa, an afternoon meal with coffee, Zwieback and jam, cheese, and various cookies. We all visited for awhile longer and then went on our way. It was a wonderful afternoon, and I hope to have a chance to do that sort of thing again.

6 October 2010

Jamie McClelland: Benchmarking PHP

What's the best way to run PHP in Debian in a shared environment? Years ago May First/People Link switched from the old reliable modphp to suPHP because modphp ran all php scripts as the same user, meaning (among other things) that any site could access the database configurations of any other site. suPHP was great, however, after several years we've decided to replace it because: We first turned to fcgid. We tried it out on a couple individual web sites (fcgid can run alongside suPHP), and, after a week without much problems, we implemented it on an entire server. Out of the box, on a shared server with several dozen web sites, the most notable resource utilization difference between fcgid and suPHP is the increase in memory usage. Unlike suPHP which dies after each requests, fcgid gains a performance boost by sticking around (with either 2 or 3 processes living on) to server future requests. If you have several dozen web sites that aren't high traffic sites, it means they may each have up to the three processes staking out memory that would otherwise be free with suPHP. We addressed the memory problem by adding the following to /etc/apache2/mods-available/fcgid.conf:
DefaultMinClassProcessCount 0
IdleTimeout 60
IdleScanInterval 60
These directions tell fcgid to kill processes that have been idle for more than 60 seconds. That means we still get the performance gain from a site getting more than one page view per minute, but otherwise we re-claim the memory. Before switching our remaining servers we decided to do more extensive testing to ensure we would be getting the performance and resource gains we were hoping. Also, we decided to consider mpm-itk, which is a variation of mpm-prefork that runs each virtual host with a per-vhost configured user and group (like suexec, but for the entire virtual host). Since it's a variation of mpm-prefork, it's safe to run it with the more resource friendly mod_php. We used the apache benchmarking tool ab. And we tested on a virtual machine (running on my laptop) with 1GB of RAM. The test web site we used was a copy of the May First/People Link site (we used the home page for the test), which is running Drupal 6. It's a relatively simple Drupal site, however, we turned Drupal caching off to better simulate PHP processing usage likely to be found on our members' sites. We ran tests against the following configurations: The tests were run with: We originally tried, for the last test, 100 requests/25 concurrent but it caused ab to time out on the mpm-worker/fcgid/suexec configuration. We then lowered it to 75/15. Still timed out (load on our test server went way up). The tests paused 120 seconds between testing each environment to give the server load a chance to settle down. And we paused 30 seconds between each test (not enough time for the fcgid processes to be killed, but enough time for all the processes to hopefully complete their requests). The tests are scripted and the full results are available. You can also see the various vhost configurations (test.mouse, test.mouse.itk, test.mouse.suexec.fcgid), and the fcgid.conf. To summarize the report ... if you are running one web site on a server, there's little argument for using anything other than mod_php and mpm-prefork - the performance of this combination far exceeds any other combination. I'm scratching my head over the the vastly different conclusions reached by 2bits. They didn't publish their tests so I'm not sure exactly how to compare. Maybe they have a lot more static content? Or - maybe there's a mistake in our tests? Open to ideas. suPHP seems to be left in the dust compared with either fcgid/suexec or mpm-itk. Given that it's also less flexible, there's not much going for it. And lastly... fcgid/suexec and mpm-itk seem comparable. That was a surprise. We were expecting mpm-itk to perform better because it's running mod_php. Given the similarity in performance, fcgid/mpm-worker seems like a much more well-tested and well-supported approach for a shared server. One side note... originally, out of laziness, we tested against the default Drupal install.php page. Less static content and much less PHP processing. In these tests, with low loads, the results provide different numbers, but the comparisons between environment were similar ... except with the last test. With the 70 requests/10 concurrent test, fcgid/suexec dramatically out-performed everyone (by a factor or more than 2). That's probably because no new cgi processes had to be spawned and the effect of mod_php using APC was reduced because there was very little php code to process.

3 October 2010

Benjamin Mako Hill: AcaMako

As I mentioned recently, I've been writing summaries of academic articles I read over on AcaWiki. You should join me and write summaries of academic articles you read or help improve the summaries other folks have shared! Of course, you can also just read AcaWiki summaries. But while reading summaries takes less time that reading the full articles and books, a 500-1000 word summary is still too much for some very busy people. That's why I created a new microblog on Identica where I post summaries of the summaries I post to AcaWiki. You can subscribe to AcaMako to follow along.

1 October 2010

Benjamin Mako Hill: On Feminism and Microcontrollers

A month or so ago, I published a paper with Leah Buechley that is mostly an analysis of how the LilyPad Arduino has been used. I read an earlier draft last year and loved it so, when the opportunity arose, I was honored to help out as the paper evolved. LilyPad is a microcontroller platform that Leah created a few years back and that is specifically designed to be more useful than other microcontroller platforms (like normal Arduino) in the context of crafting practices like textiles or painting. Leah's design goal with LilyPad was to create a sewable microcontroller that could be useful for making things that were qualitatively different from what most people made with microcontrollers and that, she hoped, would be of interest to women and girls. Our paper tries to measure the breadth of LilyPad's appeal and the degree to which it accomplished her goals. We used sales data from SparkFun (the largest retail source for both Arduino and LilyPad in the US) and a crowd-sourced dataset of high-visibility microcontroller projects. Our goal was to get a better sense of who it is that is using the two platforms and how these groups and their projects differ. We found evidence to support the suggestion that LilyPad is disproportionally appealing to women, as compared to Arduino (we estimated that about 9% of Arduino purchasers were female while 35% of LilyPad purchasers were). We found evidence that suggests that a very large proportion of people making high-visibility projects using LilyPad are female as compared to Arduino (65% for LilyPad, versus 2% for Arduino). Digging deeper, qualitative evidence suggests a reason. LilyPad users aren't just different. The projects they are making are different too. Although LilyPad and Arduino are the same chips and the same code, we suggest that LilyPad's design, and the way the platform is framed, leads to different types of projects that appeal to different types of people. For example, Arduino seems likely to find its way into an interaction design project or a fighting robot. LilyPad seems more likely to find its way into a smart and responsive textile. Very often, different types of people want to make these projects. Leah and I believe that there's a more general lesson to be learned about designing technologies for communities underrepresented in science, technology, engineering, and mathematics (STEM) -- and for women in particular. The dominant metaphor in the discussion on women in computer science is Margolis and Fisher's idea of "unlocking the clubhouse." The phrase provides a good description of the path that most projects aimed at broadening participation of women in computing projects seem to take. The metaphor is based around the idea that computing culture is a boys' club that is unfriendly to women. The solution is finding ways to make this club more accessible to those locked outside. It should go without saying that we share Margolis and Fisher's goal of increasing participation of women in STEM. That's LilyPad's point, after all. It it hopefully also clear that we're supportive of, and involved in, projects working to remove systematic barriers to participation by women and other groups. That work must continue. But I also think that Leah's work with LilyPad suggests another way forward based on addressing issues of self-selection that will affect even the most welcoming technological communities. Here's what we say in our paper:
Our experience suggests a different approach, one we call Building New Clubhouses. Instead of trying to fit people into existing engineering cultures, it may be more constructive to try to spark and support new cultures, to build new clubhouses. Our experiences have led us to believe that the problem is not so much that communities are prejudiced or exclusive but that they're limited in breadth--both intellectually and culturally. Some of the most revealing research in diversity in STEM found that women and other minorities don't join STEM communities not because they are intimidated or unqualified but rather because they're simply uninterested in these disciplines. One of our current research goals is thus to question traditional disciplinary boundaries and to expand disciplines to make room for more diverse interests and passions. To show, for example, that it is possible to build complex, innovative, technological artifacts that are colorful, soft, and beautiful. We want to provide alternative pathways to the rich intellectual possibilities of computation and engineering. We hope that our research shows that disciplines can grow both technically and culturally when we re-envision and re-contextualize them. When we build new clubhouses, new, surprising, and valuable things happen. As our findings on shared LilyPad projects seem to support, a new female-dominated electrical engineering/computer science community may emerge.
I have a strong belief that computing can be an empowering tool and that expanding users' control over technology is a critically important issue. Our paper argues that we should attempt to expand participation in computing by broadening the possibilities of computing, rather than only by broadening participation in extant, computing organizations, projects, and genres. Even if computing and electrical engineering communities were perfectly welcoming (which they are not) most people (both male and female, but disproportionately female) will choose not to participate. Building new clubhouses requires creativity of its proponents and risks charges of reinforcing stereotypes and existing status hierarchies. But, executed carefully and well (as I believe LilyPad has been), it suggests ways to reach the majority of people that no "unlocking" project will ever seem relevant to.

29 September 2010

James Morrison: Weeping Tile

So I never had the chance to see Weeping Tile in Concert, but this year I have managed to see both Luther Wright in concert and Sarah Harmer. That and I found "The show 1995" channel on youtube which does have weeping tile in concert. And Uncle Remus.

Next.

Previous.